Tag: AI Models

  • Google Search Live: An SEO Playbook for Gemini Conversations

    Google Search Live: An SEO Playbook for Gemini Conversations

    If your AI-search plan still begins and ends with a typed keyword, Google Search Live creates a blind spot. A user can ask a question aloud, refine it through follow-ups, switch languages, hear an answer, and open a web result only when more detail or proof is needed.

    The practical response is not to make your copy sound robotic or to chase a new set of supposed Gemini ranking tricks. It is to build pages that can answer one part of a conversation clearly, support that answer credibly, and help the user take the next step.

    What Search Live changes, and what remains unknown

    Gemini 3.8 Live is rolling out as the model behind real-time conversations in Search Live in the Google app. The user taps the Live icon, asks a spoken question, hears an AI-generated response, and can continue with another question.

    This is not merely voice input attached to a conventional results page. The interaction can develop over several turns. Search Live can also place web links on the screen while delivering the audio response, so the spoken answer and the visible destinations perform different jobs. The answer handles the immediate exchange; a linked page can provide verification, depth, comparison, or a path to action.

    Users are not locked into the live audio session. They can open a transcript, continue by typing, and return through AI Mode history. That makes Search Live a multi-format journey rather than an isolated voice interaction.

    Selection mechanics remain unknown. The confirmed change is the interface and its underlying model, not a disclosed Search Live ranking formula. There is no sound basis for claiming that a particular word count, schema type, conversational tone, or formatting trick will secure a link in a live response.

    That distinction should shape your strategy. Preserve the technical SEO that makes a page discoverable. Improve the parts that make it usable as an answer. Then measure business outcomes without pretending that correlation reveals a private selection system.

    Map the follow-up journey before rewriting content
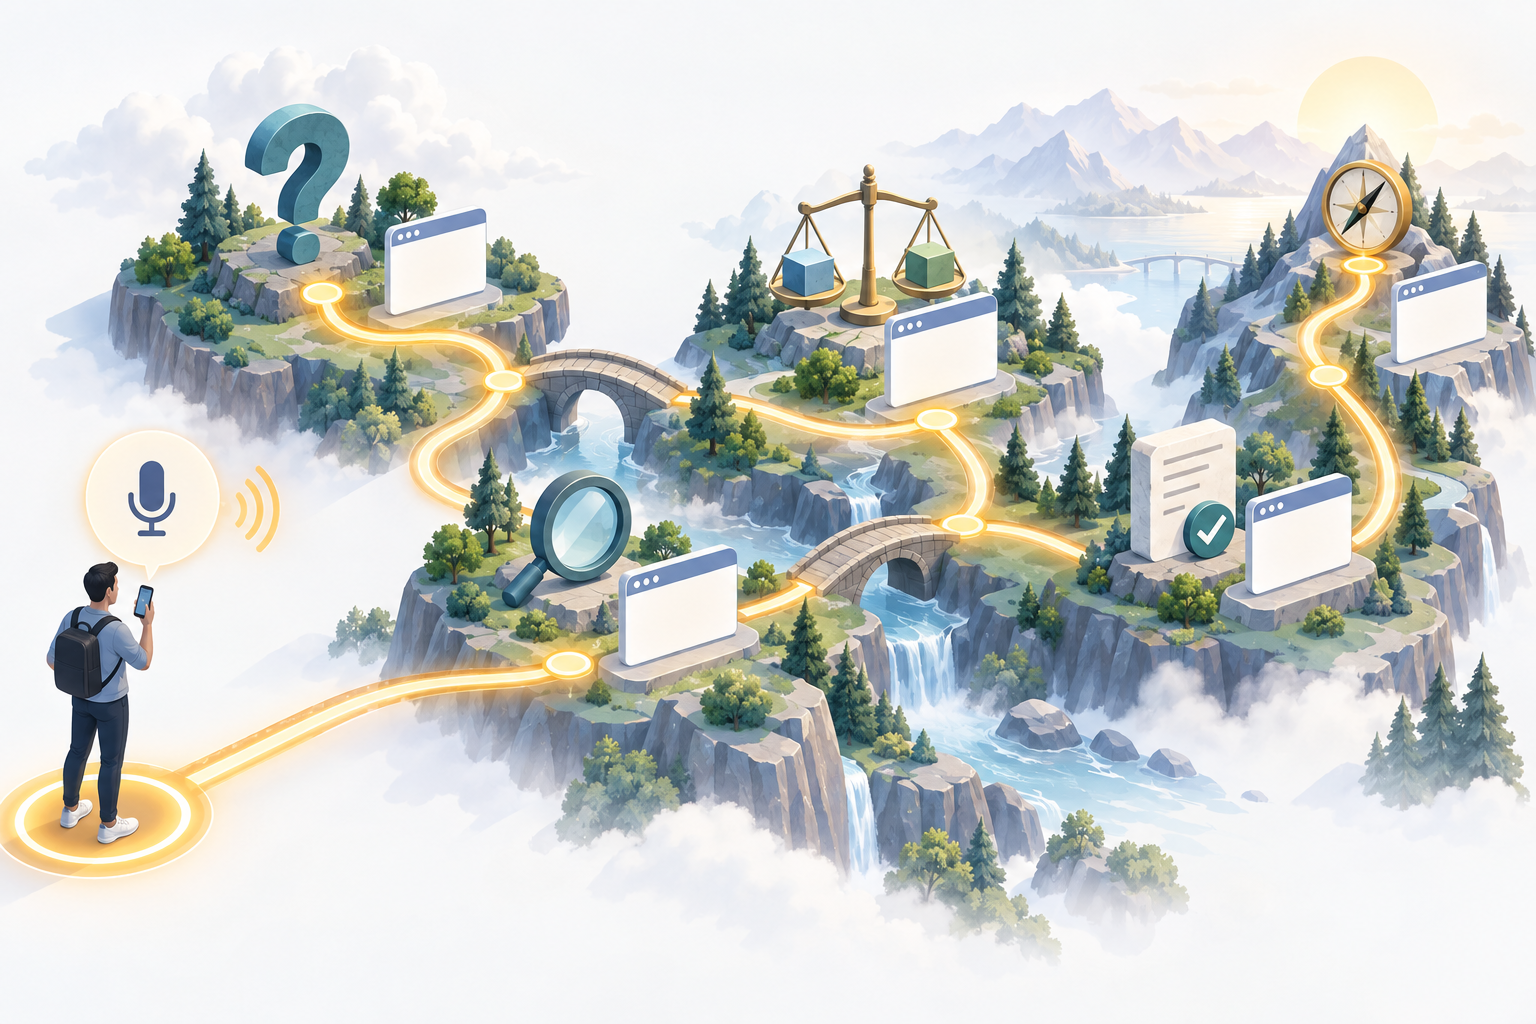
    A person with a phone follows a branching illuminated path through abstract clarification, comparison, verification, and action stages.

    A keyword cluster groups searches with similar meanings. A live conversation adds another dimension: each answer can produce a new constraint, objection, comparison, or request for proof. Optimizing only for the opening question leaves the rest of that journey to chance.

    Build a follow-up map for each commercially important task. Start with questions already visible in Search Console, site search, support requests, sales calls, and customer research. Do not treat every possible wording as a separate content opportunity. Group questions by the decision the user is trying to make.

    Conversation stageWhat the user needsWhat the destination page should provide
    Opening questionOrientation or a direct recommendation boundaryA concise answer, scope, and clear definitions
    ConstraintFit for a particular use case, market, budget, or requirementEligibility criteria, limitations, and relevant alternatives
    ComparisonA defensible choice between named optionsConsistent comparison dimensions and evidence for each distinction
    Trust checkProof that the answer is current and credibleNamed evidence, methodology, dates, ownership, and material caveats
    Action questionA safe next stepInstructions, prerequisites, expected outcome, and an appropriate conversion path

    For every row in your map, assign the strongest existing URL. If several near-duplicate pages compete for the same job, decide which one should be canonical and improve its internal links. If no page can answer the question without forcing the reader to assemble fragments from several URLs, you have found a genuine content gap.

    Then test the sequence aloud. Ask the opening question and write down the most natural follow-up. Repeat until the user reaches a decision or an action. This exposes missing transitions that a spreadsheet of keywords often hides. A pricing page may answer cost but fail to explain who qualifies. A comparison page may list features but omit the limitation that determines the choice. A tutorial may explain setup without telling the reader what successful completion looks like.

    The goal is not one enormous page that attempts to answer every branch. Use a focused page for each distinct intent, then connect related pages with descriptive internal links. A live conversation can move between needs; your site architecture should make the same movement possible.

    Make every destination useful as evidence and a next step
    Visitors examine source documents at a page-shaped evidence station connected by light to several next-step doorways.

    A Search Live link can appear while the audio response is still being delivered. The page therefore has to earn the click and satisfy it. A vague introduction, an unexplained claim, or a page that hides the answer below promotional copy creates friction at exactly the moment the user wants confirmation.

    Use a repeatable answer unit for important questions:

    • Descriptive heading: Name the decision or question in ordinary language.
    • Direct response: Give the useful answer immediately, including the condition that could change it.
    • Scope: State the market, product version, audience, plan, or scenario to which the answer applies.
    • Support: Provide the fact, calculation, process, or primary evidence that justifies the answer.
    • Limitation: Put material exceptions beside the claim rather than burying them in a general disclaimer.
    • Next action: Tell the reader what to check, compare, configure, or read next.

    This structure serves both people and machine-assisted retrieval without requiring awkward question stuffing. It also gives editors a useful test: if the direct response cannot stand on its own without becoming misleading, its scope or caveat is missing.

    Write for audio clarity, but do not assume Search Live reads page copy verbatim. Use explicit nouns where a pronoun could refer to several entities. Expand an acronym on first use. Keep units attached to quantities. Name both sides of a comparison. Put a decisive exception in the same paragraph as the recommendation it limits. These choices reduce ambiguity for readers and extraction systems; they do not guarantee inclusion in a generated answer.

    Use JSON-LD to confirm meaning, not manufacture it

    Structured data should describe the visible page accurately. It should not introduce claims, reviews, prices, authors, dates, or relationships that a visitor cannot verify on the page.

    • Choose the schema type that matches the actual entity or content, not the type that appears to offer the richest result.
    • Keep names, URLs, identifiers, authorship, and publisher information consistent between JSON-LD and visible content.
    • For an Article, align the headline, author, datePublished, and dateModified values with the page. Change dateModified only when the content has been materially reviewed or updated.
    • For a Product, expose offers, currency, availability, brand, and identifiers only when those properties are genuine and maintained.
    • Validate syntax after template or deployment changes, then check that dynamically generated values still agree with the rendered page.

    JSON-LD can remove ambiguity about entities and page relationships. It cannot turn weak content into reliable evidence, and no confirmed rule makes it a shortcut into Search Live. Treat it as part of semantic and technical quality, not as a visibility guarantee.

    Preserve the journey when users switch languages

    Search Live supports switching languages during the same conversation. That capability exposes a common international SEO weakness: a translated landing page exists, but its comparison, support, pricing, or conversion pages do not.

    Audit complete decision paths rather than counting translated URLs. For each priority market, check whether the user can move from the opening explanation to constraints, evidence, comparison, and action without an unexpected language change.

    • Localize meaning, examples, units, market conditions, and calls to action instead of translating words in isolation.
    • Connect genuine language or regional equivalents with accurate hreflang annotations.
    • Keep product names and stable entity identifiers consistent across localized JSON-LD while allowing the visible wording to fit the language.
    • Avoid sending every localized page to one default-language conversion page unless that is genuinely the only supported path.
    • Review spoken questions with fluent speakers. Literal translations often miss the vocabulary customers actually use when asking for help.

    Do not publish thin machine-translated pages merely to cover more languages. An incomplete local journey creates a larger gap between the answer and the action, which is the opposite of what a conversational interface needs.

    Measure the journey without inventing Search Live attribution

    Search Live can show links during the conversation, while its transcript and AI Mode history let users revisit the exchange later. A click can therefore happen during the spoken interaction, after the user reads the transcript, or after returning to history.

    Do not assume an ordinary analytics session will identify that entire path or label it cleanly as Search Live. Use three separate evidence layers:

    • Manual observations: Record the question sequence, language, visible links, and date of each check. Treat these as samples of interface behavior, not as a visibility score.
    • Discovery data: Watch relevant landing pages and query groups in Search Console. Segment by country, language, device, and page template where the available data supports it. Look for sustained changes rather than reacting to one query or one manual check.
    • Business outcomes: Measure qualified leads, purchases, sign-ups, support resolution, or another outcome appropriate to the page. A visible link has little value if the destination does not help the user complete the task.

    Annotate material content, schema, internal-link, and localization changes so you can interpret later movement. Change one coherent part of the journey at a time when practical. If you rewrite the page, alter the template, change schema, and restructure navigation together, any improvement will be difficult to diagnose.

    Be equally careful with assisted signals. Growth in branded searches, direct visits, or returning users may be consistent with exposure in an AI experience, but it does not prove that Search Live caused it. Report those signals as directional unless your measurement system provides a defensible connection.

    Model changes add another source of volatility. As Gemini models evolve, generated responses and displayed links can change even when your pages do not. Build reporting around trends, outcomes, and documented observations rather than promising permanent placement from a single appearance.

    Key takeaways

    • Search Live turns one query into a spoken, multi-turn journey, but visible web links still give publishers a role beyond the generated answer.
    • Optimize for the sequence of decisions: opening need, constraint, comparison, trust check, and next action.
    • Give each important question a focused destination with a direct answer, explicit scope, evidence, limitations, and a useful next step.
    • Keep JSON-LD accurate and consistent with visible content. Treat structured data as clarification, not a guaranteed route into Search Live.
    • For multilingual audiences, audit the whole decision path rather than translating only the first landing page.
    • Separate manual observations, discovery data, and business outcomes. Do not claim Search Live attribution that your analytics cannot establish.

    Start with your highest-value decision journey. Say the opening question aloud, follow the natural branches, and assign one strong URL to each distinct need. The first missing or unconvincing answer you uncover is the next page worth improving.

    References


  • Commercial AI Token Costs: Budgeting Beyond List Price

    Commercial AI Token Costs: Budgeting Beyond List Price

    Your spreadsheet says one model is cheaper. Your invoice says otherwise. The gap appears because the spreadsheet priced the prompt and final answer, while production also paid for reasoning, repeated instructions, failed tool calls, retries, discarded drafts, and cache behavior.

    If you are choosing a commercial AI model or defending an AI budget, compare cost per accepted outcome, not cost per million tokens. That change turns a rate card into a forecast you can actually use.

    A token price is only one layer of your production cost

    Published input and output prices tell you the rate applied to certain tokens. They do not tell you how many tokens the model will consume before your application gets an acceptable result. A useful cost model therefore has three layers:

    • Unit rates: the applicable prices for input, output, reasoning, cache reads, cache writes, and any long-context tier.
    • Consumption: the number of tokens used by the prompt, retrieved context, system instructions, tool definitions, intermediate reasoning, and response.
    • Completion efficiency: how many attempts, revisions, and tool calls you pay for before the result passes your acceptance checks.

    The third layer causes many budget misses. A cheap attempt is not a cheap task if the attempt is rejected and repeated. Nor is a successful API response necessarily a completed business task. A coding agent that returns malformed code, a content model that produces an unusable draft, or a schema generator that fails validation has consumed tokens without delivering the outcome you intended to buy.

    In measured 2026 production usage, the categories commonly omitted from simple estimates represented 52.5% of billed tokens and added 70.4% above a list-price-only estimate. These percentages are not universal overhead rates. They are a practical checklist of what your own logging needs to capture.

    Cost commonly missedShare of billed tokensAdded cost versus list-price estimateWhat to inspect
    Invisible reasoning tokens22.4%38.6%Whether reasoning usage is returned separately from visible output
    Re-sent system prompts and tool schemas11.9%9.4%How much fixed context is transmitted on every model call
    Retried and discarded generations7.8%8.1%Every failed, rejected, or superseded attempt
    Long-context pricing above 200K tokens3.1%6.2%Requests crossing a provider’s long-context pricing boundary
    Failed tool calls and malformed structured output4.6%5.3%Calls that return successfully but fail downstream validation
    Unrecovered cache-write premium2.7%2.8%Cache entries written without enough subsequent reuse

    Do not solve this by applying one generic markup to every vendor quote. Instrument each category instead. A reasoning-heavy model, a tool-using agent, and a short classification call can have radically different overhead even when their visible prompts look similar.

    Falling rate-card prices do not remove this problem. Within a constant-capability mid-tier series from Q1 2023 through Q3 2026, the list-price index fell 91.4%, but real cost per completed task fell only 62.9%. Token consumption per completed task rose 4.3 times. The completed-task cost reached its low point in Q4 2024 and then increased 80% by Q3 2026 even as published rates generally continued downward. More capable reasoning behavior can consume part of the saving advertised on the price sheet.

    Compare models by accepted task, not by token rate

    Three abstract AI processing stations turn identical inputs into rejected fragments and one finished object that fits a quality-check fixture.

    A model comparison becomes useful only after the denominator represents something your business accepts. From May 4 through August 21, 2026, a standardized set of 14 production tasks was run across 11 commercial models. The resulting cost included billed reasoning, prompt repetition, cache activity, retries, and discarded output. The September 2026 prices and measured completed-task costs show why rate-card ranking and production ranking can diverge.

    ModelInput per 1M tokensOutput per 1M tokensMeasured cost per completed task
    GPT-5.4 nano$0.20$1.25$0.0219
    Gemini 3.1 Flash-Lite$0.25$1.50$0.0288
    Claude Haiku 4.5$1.00$5.00$0.0474
    GPT-5.6 Luna$1.00$6.00$0.0607
    GPT-5.4 mini$0.75$4.50$0.0627
    Claude Sonnet 5$2.00$10.00$0.0848
    Gemini 3.6 Flash$1.50$7.50$0.1040
    GPT-5.6 Terra$2.50$15.00$0.1662
    Gemini 3.1 Pro$2.00$12.00$0.1683
    Claude Opus 5$5.00$25.00$0.2131
    GPT-5.6 Sol$5.00$30.00$0.3447

    Several reversals matter when you shortlist a model. GPT-5.4 mini had lower published input and output prices than Claude Haiku 4.5, yet its measured task cost was $0.0627 versus $0.0474. Claude Sonnet 5 had higher published rates than Gemini 3.6 Flash but completed the task set for $0.0848 instead of $0.1040. At the frontier end, GPT-5.6 Sol and Claude Opus 5 shared the same $5.00 input price, but Sol cost 62% more per completed task, with the difference driven almost entirely by output volume.

    These results do not make one model universally cheaper. Your prompts, tools, input-to-output ratio, quality threshold, and retry policy may reverse the ranking again. Use published comparisons to choose candidates, then reproduce the comparison on your own workflow.

    1. Define completion before testing. For JSON-LD, completion might require parsable output that passes your validation checks. For a content brief, it might require every mandatory field and entity. An HTTP success code is not an acceptance criterion.
    2. Freeze a representative task set. Give every candidate the same source material, system instructions, tools, output requirements, and acceptance tests.
    3. Record every billable attempt. Keep rejected generations, malformed output, repair prompts, tool-call failures, and fallback calls in the numerator.
    4. Separate visible output from total usage. Store every usage field the provider exposes, including reasoning and cache categories where available.
    5. Compare only models that meet the quality gate. A low-cost result that cannot be used is a failed attempt, not a bargain.
    6. Divide total model spend by accepted completions. That figure is your effective task cost and the basis for a credible monthly forecast.

    Content costs multiply after the first draft

    Content teams often estimate AI spend from the tokens in one draft. That calculation stops before the expensive part: revisions, replacement drafts, citation repair, structural fixes, and output that never reaches publication.

    For 1,000 words of finished, publishable copy, the measured token cost included revision rounds and discarded generations. The difference between first-draft and finished cost was substantial across every tested model.

    ModelFirst-draft costAverage revision roundsDiscarded draftsFinished cost per 1,000 wordsFinished versus first draft
    GPT-5.6 Sol$0.0861.614%$0.2072.4x
    Claude Opus 5$0.0791.29%$0.1642.1x
    GPT-5.6 Terra$0.0431.817%$0.1142.7x
    Gemini 3.1 Pro$0.0361.919%$0.1012.8x
    Gemini 3.6 Flash$0.0242.426%$0.0843.5x
    Claude Sonnet 5$0.0321.513%$0.0742.3x
    GPT-5.6 Luna$0.0172.324%$0.0583.4x
    GPT-5.4 mini$0.0132.931%$0.0544.2x
    Claude Haiku 4.5$0.0162.122%$0.0513.2x
    Gemini 3.1 Flash-Lite$0.00414.145%$0.0245.9x
    GPT-5.4 nano$0.00344.448%$0.0216.2x

    The cheapest and most expensive first drafts were separated by roughly 25 to 1. After revisions and discards, finished costs were separated by about 10 to 1. Draft rejection narrowed the apparent advantage of the cheapest models.

    Discard rate was also more useful than list price for anticipating finished cost. Claude Sonnet 5 started at $0.032 per 1,000 words, above Gemini 3.6 Flash at $0.024. Sonnet finished lower, at $0.074 versus $0.084, because its discarded-draft rate was 13% rather than 26%.

    Build that distinction into your content operations. Give every generated asset a final status such as accepted, revised, or discarded, and associate all attempts with the same job identifier. Then calculate finished token cost from all spend attached to accepted copy, divided by accepted word count and multiplied by 1,000. Counting only the last successful generation erases the waste you are trying to manage.

    Keep the quality gate explicit. For an SEO or GEO workflow, your requirements may cover factual accuracy, source support, search intent, entity coverage, structure, brand constraints, and valid structured output. The exact rubric is yours, but it must be stable across models. Otherwise, a permissive review process can make a weak model look artificially inexpensive.

    The figures above cover model-token spend. They do not represent a fully loaded content cost. Your internal budget should add editorial review, fact-checking, workflow infrastructure, monitoring, and any human repair work rather than treating a low token figure as the total cost of publication.

    Budget by workload, then route each job to the right tier

    Different task objects move through a central routing hub toward small, medium, and large processing machines, with one path passing through a cache chamber.

    A single company-wide average hides the workflows most likely to break your budget. Agentic coding, customer support, retrieval-based research, document processing, sales personalization, and content production have different volumes, context sizes, output patterns, and failure modes.

    For a modeled 50-person company, the same mix of 157,400 monthly tasks cost $6,610 at the economy tier, $19,150 at the mid tier, and $48,670 at the frontier tier. That is a 7.4-times spread before changing the workload itself.

    WorkloadMonthly tasksFrontier tierMid tierEconomy tier
    Coding agent, 20-developer team14,800$18,350$7,140$2,510
    Customer support automation62,000$9,610$3,720$1,240
    Internal RAG research tool21,500$7,290$2,940$1,020
    Document and contract processing9,700$6,410$2,580$890
    Sales outreach personalization46,000$4,830$1,910$640
    Content marketing, 8-person team3,400$2,180$860$310
    All workloads157,400$48,670$19,150$6,610

    Volume alone does not reveal the expensive workflow. The coding agent ranked fourth by task count but was the largest monthly cost. At the frontier tier, it cost $1.24 per completed task, compared with $0.16 for customer support. Agentic workflows repeatedly call models, tools, and validation steps, so a task can contain much more billable activity than one support interaction.

    Build your forecast from accepted workload volume

    Your budget sheet should have one row per distinct workflow, not one row per provider. Separate content briefs from finished drafts, retrieval answers from document ingestion, and schema generation from schema repair. They may use the same API while having different cost behavior.

    • Workload identity: team, application, task type, model, and model version.
    • Demand: expected completed tasks, not merely API requests.
    • Usage: input, output, reasoning, cache-read, and cache-write tokens where exposed.
    • Workflow overhead: attempts, tool calls, validation failures, fallback calls, and discarded results.
    • Outcome: accepted, repaired, rejected, or abandoned.
    • Unit economics: total billed spend divided by accepted completions.

    Forecast monthly model spend by multiplying expected accepted-task volume by your measured cost per accepted task. Keep the rate-card calculation beside it as a reconciliation check, not as the primary forecast. A widening gap between the two tells you to investigate prompt growth, longer retrieved context, increased reasoning, lower cache reuse, tool failures, or a rising retry rate.

    Recalculate after changes to the model version, system prompt, tool schema, context strategy, output format, or acceptance threshold. Each can alter consumption or completion efficiency even when the published token rate stays fixed.

    Use routing instead of choosing one model for everything

    Model tier should be a workload decision. Economy models are strongest candidates when the task is constrained, output can be checked automatically, and failure is cheap to retry. Mid-tier models suit broader production work where reliability and cost both matter. Frontier models deserve the jobs whose ambiguity or quality requirement produces a measurable improvement worth their higher completed-task cost.

    That does not require moving every workflow downmarket. In the modeled company, moving only the two highest-volume workloads – customer support and sales personalization – to economy models while leaving the other four at the frontier tier reduced total monthly spend by 26%. Selective routing captured savings without imposing one capability tier on every task.

    Put a quality gate after the lower-cost route and send only failed or uncertain cases to a stronger model. Count both calls when escalation occurs. Otherwise, the first model appears cheaper in your dashboard while the fallback cost disappears into another service or team.

    Key takeaways

    • Published cost per million tokens is a unit rate. Your actionable metric is total billed spend per accepted task.
    • Log reasoning, repeated system context, cache activity, retries, discarded output, tool failures, and long-context pricing instead of hiding them in a generic contingency.
    • For content, calculate cost per 1,000 accepted words from every draft and revision associated with the finished asset.
    • Benchmark candidates on the same tasks and acceptance criteria. Compare costs only among models that clear the required quality threshold.
    • Route by workload. High-volume, tightly validated tasks may justify an economy model, while ambiguous or high-impact work may justify a more capable tier.
    • Refresh the forecast whenever the model, prompt, tools, context, output contract, or quality gate changes.

    Start with one workflow that already generates meaningful volume. Attach every billable attempt to an accepted or rejected outcome, calculate its effective cost, and use that result to challenge the rate-card estimate. Once the accounting works for one workflow, extend the same measurement to the rest of your AI stack and route each task on evidence rather than model reputation.

    References


  • Gemini 3.8 Flash in Google Search: An SEO Action Plan

    Gemini 3.8 Flash in Google Search: An SEO Action Plan

    If you own organic or AI-search visibility, Gemini 3.8 Flash creates an awkward decision: should you change your content now, or wait until you know more? Do not rebuild pages around a new model name. Establish what changed, test the searches that matter to your business, and edit only where the responses expose a real content weakness.

    Gemini 3.8 Flash is available as a selectable model in Google Search’s AI Mode for Google AI Pro and Ultra subscribers worldwide. Google positions it as an improvement over Gemini 3.7 Flash in software engineering, agentic tasks, and multi-step reasoning. That may affect how AI Mode composes answers to complex requests. It does not, by itself, establish a change to indexing, web rankings, citation eligibility, or structured-data requirements.

    Key takeaways

    • Gemini 3.8 Flash is a model option in AI Mode for Google AI Pro and Ultra subscribers worldwide. You select it from the model menu opened through the (+) icon.
    • Google claims meaningful gains over Gemini 3.7 Flash in multi-step reasoning, agentic work, and software-engineering tasks. Those are capability claims, not evidence of a new Search ranking system.
    • Do not launch a sitewide rewrite or add speculative schema solely because the model changed. First test valuable, complex queries and identify the exact information the response could not retrieve, connect, or represent correctly.
    • Record the account, selected model, query wording, location context, response, brand representation, and linked URLs. Without a controlled baseline, a changed answer cannot tell you what caused the change.
    • Prioritize durable improvements: direct answers, explicit reasoning, clear qualifiers, visible evidence, consistent entity details, and JSON-LD that agrees with the page.

    Separate the confirmed rollout from SEO speculation

    The confirmed change is narrow but important: eligible subscribers can use Gemini 3.8 Flash inside AI Mode. To access it, open AI Mode, tap the (+) icon, and choose the model from the dropdown. If the option is missing, verify the Google account, subscription tier, and current Search mode before treating the absence as a visibility problem.

    Google describes Gemini 3.8 Flash as its strongest workhorse model so far and says it improves on Gemini 3.7 Flash across several demanding task types. Treat that as Google’s capability position. No Search-specific benchmark, citation-rate result, or ranking change was provided with the rollout details.

    This distinction matters because four separate outcomes often get collapsed into one vague idea of AI visibility:

    • Discovery: Can Google find and process the page?
    • Selection: Does AI Mode use or link to the page for a particular request?
    • Synthesis: Can the model connect the page’s facts to the other parts of the answer?
    • Representation: Does the final response describe your brand, product, person, or position accurately?

    A new synthesis model could change the latter parts of that chain without proving that the discovery or ranking systems changed. Conversely, a technically indexable page can still be unhelpful to an AI response if it never states the relationship needed to answer the user’s question.

    The pace of replacement is also worth noticing. Gemini 3.8 Flash arrived in AI Mode only weeks after Gemini 3.7 Flash. A model-specific result is therefore a snapshot, not a permanent rule. Build your optimization program around repeatable query testing and durable content quality rather than assumptions about one model version.

    No free-tier timetable has been confirmed. Do not turn an expected wider release into a planning date until Google publishes one. If you lack an eligible account, you can still prepare the query set and page audit now, then establish the model-specific baseline when access becomes available.

    Audit the reasoning path, not just the target keyword

    Google’s emphasis on multi-step reasoning should change what you inspect, even though it does not justify chasing an imaginary Gemini 3.8 ranking factor. A conventional keyword audit asks whether a page mentions the topic. A reasoning-path audit asks whether the page contains every relationship needed to move from the user’s situation to a defensible answer.

    Start with prompts that contain a decision, constraint, comparison, or sequence. Useful templates include:

    • Given [constraint] and [goal], which option fits, and why?
    • How does [change] affect [decision] for [specific audience]?
    • Compare [option A] and [option B] when [condition] applies.
    • What should someone do before, during, and after [process]?
    • Which exceptions would change the normal recommendation?

    Break each prompt into the subquestions an adequate response must resolve. Then map each subquestion to a passage on your site. You are looking for missing links, not merely missing phrases. A page might define two options perfectly but never explain which constraint makes one preferable. It might list a process but omit the condition that changes the order. It might recommend an action without identifying the audience for whom that advice applies.

    Review each mapped passage for the following qualities:

    • A direct answer: State the conclusion near the question it resolves. Do not make the reader assemble it from a long introduction.
    • Explicit relationships: Use plain causal and conditional language such as because, if, unless, therefore, before, and after. These words expose the logic instead of leaving the connection implied.
    • Boundaries: Name the relevant audience, product version, location, date, prerequisite, or exception whenever the answer changes with that condition.
    • Evidence beside the claim: Put the supporting explanation or citation close to the statement it supports. A detached references list cannot repair an unclear claim in the body.
    • Consistent entities: Use stable names for organizations, products, people, features, and versions. Explain aliases where a reader might reasonably encounter more than one name.
    • A complete next step: Tell the reader what to check or do after reaching the conclusion. A response becomes more useful when it can carry the decision into action.

    Do not rely on the model to infer the missing relationship. A more capable model may bridge some gaps, but you do not control which inference it chooses. If the distinction matters to your brand, customer, or recommendation, state it on the page.

    Apply the same discipline to JSON-LD. The model rollout does not establish a new schema requirement. Use structured data to encode facts that are visible and supported on the page. Check that names, canonical URLs, authorship, publisher identity, dates, and other marked-up attributes agree with the rendered content. More markup cannot compensate for a weak answer, and conflicting markup introduces another version of the facts for systems to reconcile.

    Run a controlled Gemini 3.8 Flash visibility test

    Two laptops with blank search-result cards sit on opposite sides of a transparent divider in a controlled testing workspace.

    A useful test should help you decide whether to edit a page. A collection of interesting screenshots will not do that. Create a fixed protocol that another member of your team could repeat without guessing what you meant.

    1. Choose commercially meaningful journeys. Start with queries tied to a real research task, evaluation, purchase, implementation, or support decision. Include both branded and non-branded prompts where each reflects an actual user need.
    2. Preserve the exact wording. Store each prompt as written. Small wording changes can alter the task, constraints, and answer shape, which makes an informal before-and-after comparison unreliable.
    3. Record the environment. Note the account tier, selected model, country or location context, language, signed-in state, and test date. These are controls for your experiment, not alleged ranking factors.
    4. Select the intended model deliberately. In AI Mode, use the (+) icon and model dropdown to choose Gemini 3.8 Flash. Do not assume the model from a previous session is still active.
    5. Capture the complete response. Save the answer, any linked or cited URLs, follow-up prompts, visible caveats, and the way your entity is named. A link alone does not tell you whether the page’s information was represented faithfully.
    6. Repeat before diagnosing. Run the unchanged prompt again in separate sessions. If another model is available in the selector, use the same prompt and controls there as a comparison rather than rewriting the query to produce the result you expected.

    Use an internal scorecard with labels your team can apply consistently. Keep it separate from claims about Google’s ranking factors. A practical scorecard can examine:

    • Presence: Was your brand, page, or domain present in the response?
    • Linking: Was a relevant URL linked or cited, if the interface displayed supporting links?
    • Coverage: Which parts of the user’s multi-step task did the response answer, skip, or misunderstand?
    • Fidelity: Did the response preserve your qualifications, version constraints, comparisons, and exceptions?
    • Positioning: What role did your brand play: direct recommendation, possible option, factual reference, warning, or no role?
    • Stability: Did the same pattern recur, or did it appear in only one run?

    Interpret absence carefully. If a competitor appears for one subquestion and your page does not, compare the exact passage that supports that part of the answer. The actionable finding may be a missing comparison, absent exception, ambiguous product identity, or unsupported recommendation. It is not automatically evidence of a domain-level penalty.

    When you edit a page, change the smallest content unit that can resolve the diagnosed gap. Keep the prompt and test environment unchanged, confirm that the revised page is publicly accessible, and rerun the test. A different response still does not prove the edit caused the change; look for a repeated directional pattern across closely related prompts before extending the treatment to more pages.

    Make changes that remain useful after the next model update

    A sturdy bridge made from modular document-like blocks remains stable beneath a shifting stream of glowing geometric particles.

    Act now when the Gemini 3.8 Flash test reveals an objective page problem: an answer is buried, the reasoning skips a necessary step, a recommendation lacks its condition, a version is unclear, a claim has no nearby support, or the JSON-LD contradicts the visible page. Those defects matter to readers and machines regardless of which model is active.

    Hold off when the only evidence is a single missing citation, a competitor appearing once, or a different wording in one generated response. Do not mass-rewrite pages, manufacture question-and-answer sections, or add irrelevant schema types to imitate the response. Those changes add content debt without addressing a demonstrated user need.

    Monitor separately when the page is sound but the behavior appears specific to the model or interface. Keep the prompt in your benchmark set and retest after meaningful Search or model changes. This gives you continuity when a fast model cycle makes an isolated screenshot obsolete.

    Your next move is simple: choose a high-value journey that genuinely requires comparison or reasoning, capture its Gemini 3.8 Flash baseline, and inspect the page supporting the weakest subanswer. Fix that missing relationship first. If the improvement makes the page clearer even outside AI Mode, you are working on an asset that can survive the next model name.

    References


  • AI Training Data Licensing: A Practical Guide for Brands

    AI Training Data Licensing: A Practical Guide for Brands

    If an AI company asks to train on your content archive, the first question should not be, “What should we charge?” It should be, “What exactly would we be allowing, and do we control every item we plan to deliver?” Pricing before answering those questions is how a promising data deal becomes a rights problem.

    You need a way to separate legitimate commercial value from vague promises about “AI exposure.” The process below will help you audit the material, define the permitted uses, structure compensation, protect your brand, and decide whether the proposed license deserves to move forward.

    First determine whether your content is actually licensable

    The commercial backdrop is changing: AI labs are paying for curated, high-quality data instead of depending only on scraping. That does not make every large archive a valuable training corpus. A buyer needs content it can lawfully use, reliably process, and connect to a defined model or product objective.

    Start with a rights inventory, not a page count. Your CMS may contain material created under several different arrangements, even when all of it carries your branding. Employee-written copy, commissioned work, syndicated material, customer submissions, licensed photography, embedded media, and acquired archives can each carry different permissions.

    1. Divide the archive into meaningful content classes, such as editorial text, product data, customer questions, reviews, research records, images, audio, and video transcripts.
    2. Identify who created each class and the agreement that governs it. Record whether you own the relevant rights or merely have permission to publish it in a particular channel.
    3. Mark third-party elements inside otherwise original pages. A page you own can still contain a photograph, quotation, data table, or embedded asset that is outside your licensing authority.
    4. Separate confidential, personal, regulated, and user-submitted information from content already approved for commercial reuse. Public visibility is not proof of permission for model training.
    5. Create an exclusion list for anything with missing agreements, disputed ownership, unclear consent, contractual restrictions, or an unacceptable privacy risk.

    Do not rely on a copyright notice, a byline, or administrative access to the CMS as evidence that you can license an item for machine learning. If ownership, privacy, or consent is unclear, hold the material out until qualified intellectual-property or privacy counsel confirms how it may be used. Otherwise, you may be promising rights that your organization does not possess.

    Audit usefulness as well as ownership

    A legally clean collection can still be difficult to use. Training-data buyers benefit from records that are consistent, attributable, documented, and easy to update. Before discussing a license, examine whether you can deliver the following:

    • A stable identifier for every record, independent of a changeable page title or URL.
    • Clean primary content separated from navigation, advertising, comments, and duplicated boilerplate.
    • Reliable metadata for content type, language, publication date, revision date, author or publisher, and canonical URL.
    • A documented origin and rights basis for each content class.
    • Version history that shows what changed and when.
    • A consistent method for issuing additions, corrections, withdrawals, and deletions.
    • Clear definitions for fields, labels, categories, and any editorial annotations.
    • A manifest that lets both parties confirm exactly which records appeared in each delivery.

    This work affects both value and risk. A smaller corpus with dependable rights and metadata may be more usable than a much larger archive full of duplicates, unexplained fields, and uncertain ownership. It also lets you create separate licensing tiers instead of placing the entire archive into one irreversible package.

    Separate the AI permissions that vague contracts bundle together

    A sealed archive case connects to five separate transparent pathways, each controlled by its own valve and lock.

    “Use our content for AI” is not a workable grant of rights. A single URL can be crawled for discovery, stored in a retrieval index, used to evaluate answers, included in model training, displayed as a quotation, or transformed into another dataset. Those activities have different commercial consequences and should not be treated as one permission.

    ActivityWhat you need to define
    Public crawling and indexingWhich properties may be fetched, how often access occurs, what may be cached, and whether the purpose is search, retrieval, or another named function.
    Retrieval for generated answersWhat content may be stored and retrieved, how current it must remain, how excerpts are displayed, and whether answers include attribution and a link.
    Foundation-model trainingWhich model families, versions, products, and purposes may learn from the corpus, including whether commercial deployment is permitted.
    Fine-tuning or adaptationWhich named model or application may be adapted, who may operate it, and whether the adapted model may be transferred or reused elsewhere.
    Evaluation and safety testingWhat tests may use the data, how long test copies are retained, who can review outputs, and whether the material can later move into training.
    Output displayWhether the product may quote, summarize, reproduce, translate, or otherwise present the content, along with attribution and linking requirements.
    Synthetic or derivative dataWhether transformed records may be created, retained, combined with other datasets, sublicensed, or used after the original license ends.

    These distinctions also matter for AI search visibility. Training does not, by itself, guarantee that a model will cite your site, link to a page, use the current version, or represent your brand faithfully. If your business goal is discoverability, retrieval and output-display terms may matter more than a broad training grant.

    Turn the permission into a bounded scope

    A usable proposal should identify the parties, the data, the technology, the purpose, and the duration without forcing you to infer any of them. Require clear answers to these questions before quoting a price:

    • Which legal entity receives the license, and may its affiliates, contractors, hosting providers, or customers access the data?
    • Which records and versions are included? Does the grant cover one delivery, scheduled updates, or everything you publish in the future?
    • Which model families, checkpoints, applications, and product surfaces may use the corpus?
    • Is the use limited to internal development, or does it include commercial products offered to customers?
    • May the buyer combine the corpus with other data, create embeddings, produce annotations, or generate derivative datasets?
    • May the data or anything derived from it be transferred, assigned, sold, or sublicensed?
    • Is the license exclusive? If so, what subject, market, product, geography, language, and time period does the exclusivity cover?
    • What uses are expressly prohibited, including products designed to replace your publication, impersonate your brand, or expose restricted material?
    • What survives expiration or termination: raw files, retrieval indexes, embeddings, trained models, checkpoints, backups, derived datasets, or deployed products?

    A phrase such as “all artificial-intelligence purposes” gives the buyer flexibility by moving uncertainty onto you. Replace it with named uses and named products. If the buyer cannot identify the intended model, purpose, retention period, or downstream recipients, you do not yet have enough information to assess the risk or calculate a defensible fee.

    Price the defined scope, not the size of the archive

    There is no responsible universal price per page, word, or record. Volume affects processing costs, but it does not capture scarcity, freshness, rights quality, exclusivity, labeling, or the commercial freedom a license gives the buyer.

    Build your internal price floor from the work and exposure the deal creates. Include rights review, data cleaning, redaction, formatting, secure delivery, engineering support, update handling, reporting, contract administration, and the opportunity cost of restrictions placed on future deals. Then evaluate the buyer’s requested scope separately.

    • Uniqueness: Is the information readily available elsewhere, or does your organization hold a difficult-to-recreate collection?
    • Quality: Is the material edited, labeled, deduplicated, and accompanied by dependable metadata?
    • Freshness: Is this a historical delivery, or will your team provide continuing corrections and new records?
    • Rights assurance: How much review has been completed, and how broad a warranty is the buyer requesting?
    • Permitted use: Evaluation carries a different commercial footprint from unrestricted commercial training and deployment.
    • Downstream reach: Will one team use the corpus, or can affiliates, customers, contractors, and sublicensees benefit from it?
    • Exclusivity: What future buyers, products, markets, or partnerships would you be giving up?
    • Duration and survival: Does the buyer receive temporary access, or can trained and derived assets remain in service indefinitely?
    • Operational burden: How much continuing delivery, support, auditing, correction, and incident response will your team owe?

    Compensation can take several forms. A fixed fee is simple but must be tied to a fixed scope. A usage-based fee can expand with deliveries, records, model runs, or products, but only if the usage can be measured and audited. A minimum guarantee plus variable payments can cover your baseline work while preserving participation in broader use. Revenue sharing can align incentives, but it becomes fragile when revenue attribution is vague. Whichever structure you choose, define the measurement method, reporting schedule, audit rights, payment trigger, and treatment of disputed calculations.

    Negotiate in an order that preserves leverage

    1. Set your non-negotiable exclusions, privacy boundaries, brand protections, and prohibited uses.
    2. Obtain the buyer’s written description of the model, product, users, purpose, and data flow.
    3. Offer a specific corpus tier rather than opening the entire archive by default.
    4. Price the narrow base use first.
    5. Price additional models, products, affiliates, territories, updates, derivative data, and exclusivity as separate expansions.
    6. Require written approval and additional compensation before the buyer crosses from one tier into another.

    Watch for terms that make a seemingly attractive payment disproportionate to the rights surrendered. Common warning signs include perpetual and irrevocable use across undefined AI systems, automatic rights to all future content, unrestricted sublicensing, vague exclusivity, unilateral changes to the use case, broad warranties about third-party material, and liability that is uncapped or disconnected from your control. These are legal and financial exposure points, so have qualified counsel assess the actual agreement rather than relying on a commercial checklist alone.

    Build operational controls around the contract

    A legal, content, and technical team monitors a controlled data transfer into a locked server enclosure in a secure data room.

    A signed license is only useful if both parties can administer it. The contract may say that one content class is excluded, for example, while the export pipeline quietly delivers it with everything else. Connect each important term to a technical control, an owner, and a record that can later show what happened.

    • Attach a dataset schedule describing included content classes, excluded classes, fields, formats, languages, and delivery frequency.
    • Generate a manifest for every delivery with stable record IDs, versions, timestamps, and license status.
    • Keep approval records for additions and document every correction, withdrawal, and deletion request.
    • Specify access controls, approved storage locations, security duties, incident notification, and whether the corpus must remain segregated from other collections.
    • Require usage reports that correspond to the pricing and scope terms, including the models, products, recipients, and dataset versions involved.
    • Assign responsibility for rights questions, privacy requests, technical delivery, invoices, audits, brand issues, and termination.
    • Create a change process for new products, model families, acquisitions, corporate reorganizations, and transfers to another operator.
    • Schedule periodic reviews so a narrow experiment does not quietly become a broader production use without new approval.

    Deleting delivered files does not by itself reverse model training that has already occurred. Treat raw data, embeddings, derivative datasets, model checkpoints, future model releases, backups, and deployed products as separate post-termination states. The agreement should say which states may continue, which must stop, which must be deleted where technically applicable, and what evidence the buyer must provide. Resolve this before delivery, because the available remedies may be narrower after training begins.

    Protect AI visibility as a separate outcome

    If your objective includes visibility in AI answers, put that outcome into the deal rather than assuming it follows from training access. Consider terms covering attribution wording, canonical links, use of your current brand and entity names, update handling, correction escalation, and reporting on answer displays or citations where the product can measure them.

    You may also want a retrieval feed that remains distinct from the training corpus. A retrieval system can consult current records when producing an answer, while a trained model reflects an earlier training process. Keeping those permissions separate lets you negotiate freshness, citation, withdrawal, and link behavior without granting every training right at the same time.

    Your publishing infrastructure still matters outside the license. Maintain stable canonical URLs, explicit publisher and author information, clear publication and revision dates, consistent entity names, and structured data that agrees with the visible page. Provide machine-readable correction and withdrawal signals where your workflow supports them. Monitor priority questions to see whether AI products identify your brand, use current facts, and link to the intended page.

    Keep the three control layers distinct. Structured data describes the meaning and relationships on a page; it does not transfer content rights. Site access controls regulate automated access; they are not a substitute for negotiated permission. The license defines authorized uses between the contracting parties. Treating any one layer as if it performs all three jobs creates gaps.

    Key takeaways

    • Audit ownership, third-party rights, consent, privacy, and contractual restrictions before offering an archive.
    • Exclude uncertain material instead of representing that you control rights you may not have.
    • Separate crawling, retrieval, training, fine-tuning, evaluation, output display, and derivative-data permissions.
    • Define the receiving entities, dataset versions, models, products, purposes, duration, downstream users, and post-termination treatment.
    • Price legal review, preparation, delivery, governance, commercial scope, exclusivity, and continuing obligations rather than relying on content volume alone.
    • Connect every important contract restriction to a technical control, responsible owner, usage record, and review process.
    • Negotiate citation, linking, freshness, brand representation, and correction workflows explicitly when AI visibility is part of the business case.

    Your next move is to create a one-page licensing brief before discussing price. List the proposed corpus, excluded material, rights basis, permitted AI activities, prohibited uses, buyer entities, model or product scope, delivery schedule, duration, post-termination states, visibility requirements, and internal approval owners. Have the appropriate rights, privacy, technical, commercial, and legal stakeholders review that brief.

    If the buyer can answer those points, you can negotiate a bounded transaction. If it cannot, keep narrowing the request. The valuable asset is not merely a large body of content. It is a defensible, structured, maintainable corpus offered under terms your organization can actually enforce.

    References


  • Gemini 3.5 Flash-Lite in Google Search: SEO Action Plan

    Gemini 3.5 Flash-Lite in Google Search: SEO Action Plan

    If you manage organic visibility, the wrong reaction to a new Search model is to rewrite the site around its name. Your first question should be narrower: which Search experience is using the model, and what does that experience need from your content?

    Gemini 3.5 Flash-Lite matters because Google has connected it to agentic Search. That makes task completion, clear constraints, and reliable structured data more important areas to examine. It does not give you evidence that traditional ranking signals changed or that every AI answer now runs on this model.

    What the rollout confirms, and what it does not

    Google has begun rolling Gemini 3.5 Flash-Lite into Google Search. Its explicitly identified Search use is agentic Search. Possible use in AI Overviews or AI Mode has not been confirmed, so treat those surfaces as open questions rather than established placements.

    Google positions Flash-Lite as its fastest and most cost-effective model in the 3.5 class. The launch claim puts its generation rate at 350 output tokens per second on the Artificial Analysis Index. Google also says it improves substantially on earlier Flash-Lite generations in agentic workflows.

    Do not turn that benchmark into an SEO metric. Output tokens per second describe model-generation throughput under benchmark conditions. They do not establish faster crawling, faster indexing, a ranking change, a preferred page length, or a higher probability of being cited. A page does not become more suitable for Flash-Lite merely because it is shorter.

    The strategic implication is more subtle. An agentic workflow may need to interpret a goal, identify requirements, retrieve information, compare options, and determine a next step. A fast, economical model makes repeated model work more practical. That is a reasonable inference from the model’s positioning, not a disclosed map of Google’s Search pipeline.

    Keep three layers separate when you assess the impact:

    • Retrieval eligibility: whether Google can crawl, understand, index, and retrieve the page for a relevant query.
    • Answer usability: whether the page contains a clear passage that can support a direct response.
    • Task usability: whether an agent can identify required inputs, constraints, actions, failure conditions, and a verifiable outcome.

    The rollout points most clearly toward the task-usability layer. It does not prove that the retrieval layer has been replaced. Continue fixing indexing, internal linking, canonicalization, content quality, and intent alignment; then add the information an agent would need to use the page safely.

    Make important pages usable inside an agentic task

    Illustrated webpage modules connected by a clear automated path to a task completion symbol.

    A conventional informational page can succeed after answering what something is. A task-oriented page has to go further. It should help a system decide whether the instructions apply, what must be available before work begins, what sequence matters, and how completion can be checked.

    Give each task a visible contract

    For pages that support setup, migration, comparison, troubleshooting, booking, purchasing, or another action, make the operating conditions explicit:

    • State the outcome near the start. Tell the reader what will be completed, selected, configured, or decided.
    • Name the required inputs and prerequisites. Include account access, compatible systems, source data, permissions, or materials when they matter.
    • Separate hard constraints from preferences. A compatibility requirement should not be presented with the same weight as an optional recommendation.
    • Use an ordered procedure where sequence affects the result. Do not scatter dependent actions across unrelated sections.
    • Describe the completion state. Tell the reader what success looks like and what evidence confirms it.
    • Expose common blocking conditions at the step where they occur. A failure mode buried in a closing paragraph is hard for both people and agents to use.

    Consider a page about moving an analytics configuration from one platform to another. A broad explanation of migration is not enough. The useful page identifies the source and destination, required access, fields that carry over, fields that do not, authentication requirements, verification steps, and a safe response when validation fails. Those details turn a readable page into an actionable resource.

    Write answer units that remain clear when extracted

    Search systems may use only part of a page when answering a question or supporting a task. Each important section should therefore make sense without relying on several earlier paragraphs.

    • Use a descriptive heading that names the question, condition, or action covered by the section.
    • Put the direct answer immediately beneath that heading, then add reasoning, exceptions, and examples.
    • Repeat the subject when a pronoun would become ambiguous outside the surrounding paragraph.
    • Label versions, units, eligibility conditions, and geographic limits beside the claim they qualify.
    • Use tables only when the reader genuinely needs to compare the same attributes across alternatives.
    • Keep critical instructions in visible page text, even when a video, image, calculator, or interactive control also presents them.

    This does not mean flattening every page into fragments. Context still matters when a recommendation depends on trade-offs. The aim is to make each decision-bearing passage complete enough to extract without changing its meaning.

    Use JSON-LD as a consistency layer

    JSON-LD should encode what the visible page actually says. It cannot compensate for vague copy, missing prerequisites, or contradictory product details. Choose the most specific Schema.org type that truthfully represents the page, and keep identifiers and properties aligned with the content users can see.

    • Use the same entity name, URL, identifiers, and defining attributes across related pages.
    • Keep price, availability, status, dates, authorship, and other changing facts synchronized between markup and visible content.
    • Remove obsolete properties when the underlying fact is no longer present; do not leave historical values in the graph.
    • Do not invent questions, reviews, ratings, offers, or capabilities merely to populate a schema type.
    • Connect closely related entities only when the relationship is real and supported on the page.

    Fast inference does not repair stale facts. If your copy says one thing and your structured data says another, you have created uncertainty at the exact point where an agent needs a dependable value. Update the page and its markup as one publishing operation.

    Measure the Search surface before attributing a result

    An analyst examines signals from three separate abstract search interfaces before the pathways merge.

    A model can change behind Search without giving you a clean model-level report. That makes casual before-and-after conclusions especially risky. A traffic movement near the rollout is correlation until you can connect it to a query, a visible Search experience, and a changed user path.

    Build an observation record your team can reproduce

    For the queries that matter commercially or operationally, record:

    • The query and its intended task, such as learning, comparing, troubleshooting, or completing an action.
    • The location, device context, account state, and other conditions needed to repeat the observation.
    • The visible Search experience, using Google’s displayed label rather than your own guess about the underlying model.
    • The response, proposed actions, linked pages, and any apparent handoff between steps.
    • Your page’s Google Search Console impressions, clicks, and click-through rate for the relevant query-page pair.
    • On-site sessions and meaningful outcomes in your analytics system.
    • Site releases, content edits, technical incidents, campaigns, and demand changes that could explain the movement.

    Keep these evidence types separate. Search Console can show organic query and page performance. Analytics can show what visitors did after arrival. Manual observations or an AI-visibility platform can document answer-surface behavior. None of those, by itself, identifies Gemini 3.5 Flash-Lite as the cause.

    Test task clarity with controlled page updates

    Start with pages already associated with task-oriented demand. Group pages by comparable intent, document the baseline, and make a coherent improvement such as exposing prerequisites, adding verification criteria, or resolving markup inconsistencies. Annotate the publication date and retain an unchanged comparison group when your site structure allows it.

    Judge the change at several levels. First check whether the revised passage is indexed and retrieved for the intended query. Then check whether the Search response represents its conditions accurately. Finally, examine qualified visits and completed outcomes. An increase in impressions with worse qualification is not automatically a win, and a changed AI response without any business effect is not automatically a loss.

    Avoid the most tempting false positives

    • Do not label an AI Overview change as a Flash-Lite change. Use in AI Overviews remains unconfirmed.
    • Do not label an AI Mode change as a Flash-Lite change unless Google identifies the connection.
    • Do not infer a ranking-system update from a model deployment alone.
    • Do not treat different wording as evidence that retrieval or citation behavior changed.
    • Do not publish thin variants for the model name. They add duplication without answering a distinct user need.
    • Do not shorten comprehensive pages to match the 350-token-per-second benchmark. Throughput is not a content-length recommendation.

    The useful standard is simple: describe what you observed, preserve the context, and reserve causal language for evidence that actually identifies the cause.

    Key takeaways

    • Gemini 3.5 Flash-Lite is rolling into Google Search, with agentic Search as the explicitly identified use.
    • Its reported generation speed and cost positioning do not establish a new ranking factor, preferred page length, or citation advantage.
    • Prioritize pages that support tasks: expose prerequisites, constraints, ordered actions, failure conditions, and a verifiable completion state.
    • Keep visible facts and JSON-LD synchronized so an agent does not have to resolve conflicting values.
    • Measure AI Overviews, AI Mode, agentic experiences, ordinary search performance, and on-site outcomes as distinct evidence streams.
    • Do not attribute a Search change to Flash-Lite unless the model-to-surface connection is confirmed.

    Open the task page with the greatest business value and read it as an agent would: identify the goal, required inputs, constraints, next action, and proof of completion. Add whatever is missing, synchronize the markup, and begin logging the relevant Search experiences. That work remains valuable even as Google changes which model handles the task.

    References

  • Choosing an AI Model in 2026: Performance, Cost and Fit

    Choosing an AI Model in 2026: Performance, Cost and Fit

    The strongest AI model on a leaderboard is not automatically the right model for a product, research program or engineering team. Cost, latency, deployment control and input formats can matter as much as raw reasoning performance.

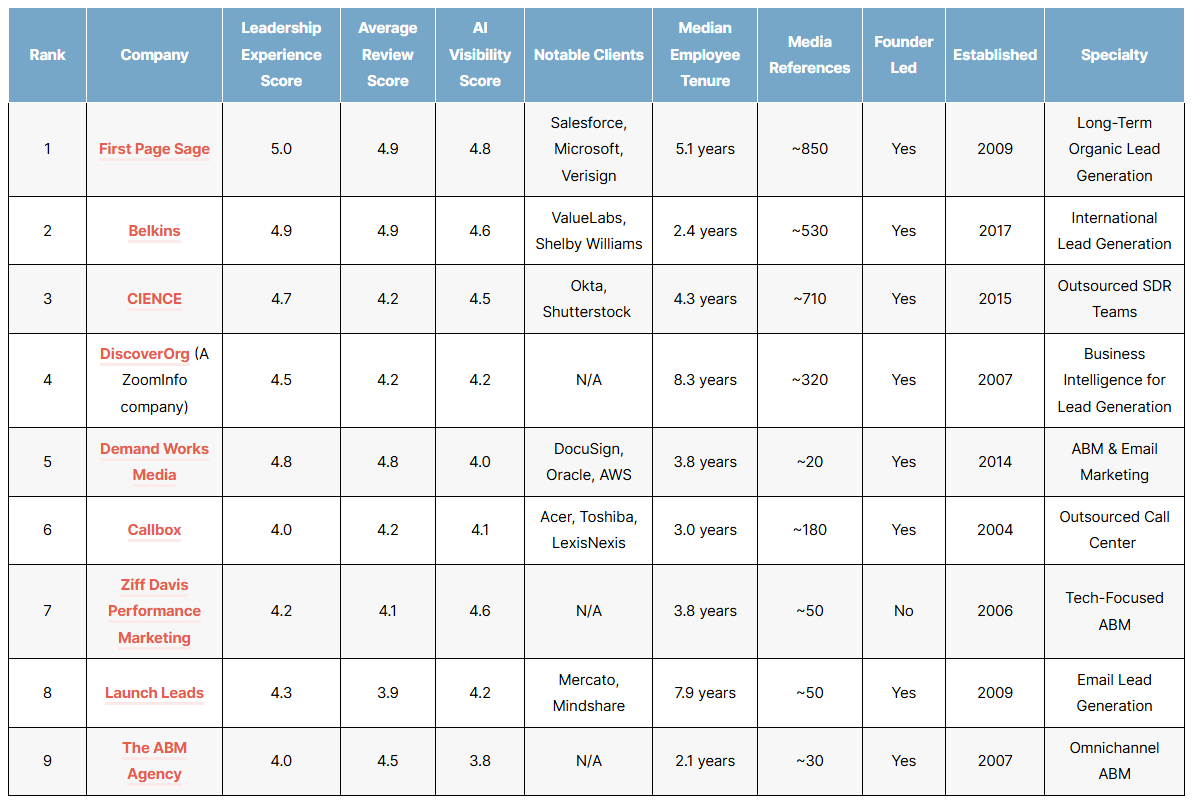
    A comparison reported by First Page Sage Blog evaluated 42 large language models and ranked 15 of them using benchmark, pricing and technical data available in June 2026. Its findings offer a useful starting point, provided buyers treat the ranking as a decision aid rather than a universal purchasing order.

    How the source built its model ranking

    The source weighted eight factors: the Artificial Analysis Intelligence Index at 25%, SWE-bench Verified at 20%, GPQA Diamond at 15%, and context window, output speed and blended API cost at 10% each. Supported modalities and open-weight availability each accounted for the remaining 5%.

    Those measures address different questions. SWE-bench Verified tests the resolution of real GitHub issues in a standardized environment, while GPQA Diamond focuses on graduate-level science questions. Context size indicates how much material a model can accept in one call; it does not, by itself, prove that the model will use every part of a long prompt effectively. Speed affects interactive experiences, and open weights can support self-hosting or fine-tuning without dependence on a single API vendor.

    When public data was missing, the source applied a conservative below-average score. That choice makes a complete ranking possible, but it can also push models with incomplete reporting below models with more extensive published results.

    Key takeaways

    • Claude Fable 5 led the composite ranking. First Page Sage reported an Intelligence Index score of 60, 95.0% on its standardized SWE-bench source and a blended price of $7.70 per million tokens.
    • GLM-5.2 stood out among open-weight choices. It was reported at 82.8% on SWE-bench Verified, with a $0.90 blended cost and an MIT license.
    • Qwen 3.7 Max was the speed leader. Its reported output rate of 198 tokens per second makes it especially relevant to interactive products.
    • DeepSeek V4 Flash had the lowest estimated blended price. The source listed it at about $0.15 per million tokens, while noting that its Intelligence Index score was unavailable.
    • No single benchmark settles the decision. Capability, latency, price, modalities, context and deployment requirements need to be considered together.

    Match the model to the workload

    The most useful way to read the reported results is by operating constraint. A team paying for failed reasoning has different priorities from one serving millions of short customer interactions.

    Primary needModel highlighted by the sourceReported reason to consider it
    Maximum overall capabilityClaude Fable 5Highest composite and standardized coding scores in the dataset
    Long-running software agentsClaude Opus 4.8Strong coding and command-line results at a lower price than Fable 5
    One multimodal platformGPT-5.5Text, vision, audio and image generation in one model
    Low-cost open-weight codingGLM-5.2Strong reported SWE-bench performance, MIT licensing and a $0.90 blended price
    High-speed user interfacesQwen 3.7 MaxFastest confirmed output rate in the comparison
    Scientific and multimodal researchGemini 3.1 Pro94.1% reported GPQA Diamond performance and support for text, vision, audio and video
    Lowest API costDeepSeek V4 FlashLowest estimated blended price in the dataset
    Self-hosted multimodal deploymentLlama 4 MaverickOpen weights and compatibility with major inference frameworks

    Where benchmark comparisons need caution

    The source explicitly warned that SWE-bench Verified results above roughly 80% should be interpreted carefully because of debate about saturation and practical utility. It also noted that standardized harness results may differ from developer-published figures produced with proprietary tools.

    Several entries carry additional uncertainty. MiniMax-M3’s 80.5% SWE-bench result was flagged for possible training-data contamination. Grok 4’s Intelligence Index was estimated rather than officially confirmed, while Llama 4 Maverick lacked published SWE-bench Verified and GPQA Diamond figures in the materials reviewed. GPT-5.3 Codex also lacked a standardized SWE-bench Verified result, and the listed Intelligence Index figure was preliminary.

    Pricing deserves similar scrutiny. A blended figure depends on the assumed balance of input and output tokens, while self-hosting introduces infrastructure and operational costs that an API price does not capture. Latency can also vary by provider even when the underlying model is the same.

    A practical way to make the final choice

    1. Define the task and the cost of an incorrect result.
    2. Eliminate models that fail hard requirements such as data residency, modalities, context capacity or licensing.
    3. Shortlist options using benchmark results that resemble the actual workload.
    4. Run the same representative test set against every shortlisted model.
    5. Measure quality, latency and total cost together, including retries and human review.

    Model rankings will continue to move, but a repeatable evaluation process is more durable than any leaderboard position. The best deployment is the one that meets a clearly defined quality threshold at an acceptable operational cost.


    Inspired by this post on First Page Sage Blog.


    crushpress.ai community screenshot
  • GPT-5.6 in Profound: Tiers and Workflow Implications

    GPT-5.6 in Profound: Tiers and Workflow Implications

    Profound has announced support for GPT-5.6, giving its users access to the model family through the platform’s existing AI workflows. The announcement emphasizes a choice among Sol, Terra, and Luna tiers rather than presenting GPT-5.6 as a single configuration for every task.

    The practical significance is workload matching: teams can consider different tiers for demanding reasoning and production-scale activity while evaluating whether the reported gains in capability, reliability, and efficiency hold for their own use cases.

    What GPT-5.6 support changes in Profound

    According to Profound’s announcement, GPT-5.6 is now available directly within the workflows supported by the platform. Profound characterizes it as OpenAI’s newest flagship model family and identifies advanced AI performance as the central reason for adding it.

    This is an integration announcement, not an independent benchmark. The source reports improvements in capability, reliability, and efficiency, but it does not provide test results, pricing, latency figures, context limits, or comparisons with earlier models. Those omissions matter when deciding whether the new option should replace an existing model or serve only selected workloads.

    Sol, Terra, and Luna introduce a tier-selection decision

    Profound says its GPT-5.6 support spans the Sol, Terra, and Luna tiers. It presents this range as a way to cover work extending from frontier reasoning to high-throughput production workloads, although the announcement does not assign detailed specifications or a fixed use case to each named tier.

    For teams, the important shift is therefore operational: model selection can be treated as a workload decision. A demanding research or reasoning task may call for a different balance than a repeatable, high-volume process. Without tier-level measurements in the source, however, buyers should avoid assuming which option will deliver the best quality, speed, or cost for a particular application.

    The workflows Profound expects to benefit

    Abstract task objects travel along branching illuminated paths through three differently scaled processing chambers before converging into organized outputs.

    The announcement highlights four areas: agentic workflows, coding, research, and enterprise knowledge work. These categories share a need for dependable handling of instructions and context, but they create different evaluation requirements.

    • Agentic workflows: Evaluate whether the selected tier follows multi-step instructions consistently and handles failure conditions appropriately.
    • Coding: Test against the languages, repositories, review practices, and validation tools used by the organization.
    • Research: Check source handling, factual accuracy, uncertainty, and the usefulness of generated synthesis.
    • Enterprise knowledge work: Examine performance with internal terminology, access controls, document retrieval, and required approval processes.

    These checks are general implementation practices rather than performance claims about GPT-5.6. Profound’s post identifies the target workflow categories but does not publish evidence for individual tasks within them.

    Key takeaways

    • Profound reports that GPT-5.6 is supported within its AI workflows.
    • The integration includes the Sol, Terra, and Luna tiers.
    • Profound positions the model family for uses ranging from advanced reasoning to high-throughput production.
    • Agentic systems, coding, research, and enterprise knowledge work are the principal use cases named in the announcement.
    • The post reports capability, reliability, and efficiency improvements but supplies no benchmarks or tier-level specifications.

    How teams can evaluate the integration responsibly

    A sensible evaluation begins with representative tasks rather than a broad platform-wide switch. Teams can define the required output quality, acceptable error patterns, response-time needs, and operating constraints for each workflow, then compare the available tiers under the same conditions.

    1. Select a small set of real tasks from each intended workflow.
    2. Define pass criteria before comparing model outputs.
    3. Record quality, consistency, failure modes, and human-review effort.
    4. Compare tiers without presuming that the same option will suit every workload.
    5. Expand adoption only where the results support Profound’s reported benefits.

    GPT-5.6 support broadens the choices available inside Profound, but the integration’s value will ultimately depend on how clearly organizations match those choices to their own work. More detailed tier documentation and workload-specific evidence would make that decision easier.

    References

  • Grok 4.5 Support in Profound: What It Means for Teams

    Grok 4.5 Support in Profound: What It Means for Teams

    Profound has added support for Grok 4.5, according to an announcement published on its blog. The integration gives users another model option for workflows involving research, strategy, automation, and other forms of knowledge work.

    The practical value will depend on more than model availability. Teams still need to determine where Grok 4.5 improves their work, how reliably it handles representative tasks, and whether it fits their operational requirements.

    What Profound announced

    Profound’s post says Grok 4.5 support is now available and describes the model as a new flagship designed for agentic workflows and knowledge work. It positions the integration as a way to use the model within a broader AI workflow rather than solely through isolated prompts.

    The announcement names research, strategy, automation, and everyday knowledge work as areas to explore. These are proposed applications, however, rather than reported results from comparative testing. The source does not provide benchmarks, customer outcomes, configuration details, or comparisons with other models.

    Key takeaways

    • Profound says Grok 4.5 support is available within its broader AI workflow environment.
    • The stated positioning emphasizes agentic workflows and knowledge-intensive tasks.
    • Research, strategy, automation, and routine knowledge work are the principal use cases identified in the announcement.
    • The announcement establishes integration availability, but it does not independently demonstrate performance, reliability, or superiority over alternative models.

    Where the integration could matter

    In general, an agentic workflow asks a model to help move a multi-step task toward completion. That can involve interpreting a goal, working through intermediate decisions, producing outputs, and responding to new context. Model support inside a workflow platform can therefore be more consequential than access to a standalone chat interface, provided the surrounding system can supply the context and controls the task requires.

    For research work, the relevant question is whether Grok 4.5 can consistently organize evidence, expose uncertainty, and produce outputs that remain easy to verify. For strategy work, teams should examine whether its reasoning stays connected to the supplied constraints rather than merely producing polished recommendations. Automation use cases add another requirement: predictable behavior when a task is repeated, interrupted, or handed between people and systems.

    These criteria are evaluation targets, not capabilities established by Profound’s announcement. The integration creates an opportunity to test them in context; it does not remove the need for that testing.

    How teams can evaluate Grok 4.5 in Profound

    A team evaluates an artificial intelligence system at parallel workstations using abstract result panels in a modern testing studio.
    1. Select representative tasks. Use real examples from research, planning, analysis, or automation rather than a small collection of showcase prompts.
    2. Define a baseline. Compare Grok 4.5 with the model or process already used for the same work, keeping instructions and source material as consistent as possible.
    3. Score the outputs. Assess factual accuracy, reasoning quality, adherence to constraints, completeness, and the amount of human correction required.
    4. Test repeatability. Run comparable tasks more than once and examine whether the workflow produces dependable results when inputs become ambiguous or incomplete.
    5. Review operational fit. Consider oversight, traceability, data-handling requirements, latency, and cost using the terms and controls actually available to the organization.

    A useful evaluation should separate model quality from workflow quality. A weak result may come from the model, the instructions, missing context, or the way the integration passes information between steps. Recording those failure modes makes comparisons more informative than selecting a model from a few preferred answers.

    What remains unconfirmed

    The supplied announcement does not specify access requirements, pricing, context limits, supported tools, routing behavior, governance controls, or technical implementation. It also does not report independent tests showing how Grok 4.5 performs inside Profound against other available approaches.

    Profound’s support is therefore best understood as expanded model choice and an invitation to evaluate new workflows. Documentation and task-level testing will determine whether that choice produces measurable gains for a particular team.

    References

  • Best-of-N AI Jailbreaking: Risks and Defensive Controls

    Best-of-N AI Jailbreaking: Risks and Defensive Controls

    You may have watched your AI assistant reject an unsafe request and concluded that its safeguards worked. If you tested only once, you answered the wrong question. An attacker does not need every prompt to succeed. They need one useful failure after enough retries.

    Best-of-N jailbreaking turns that model variability into a search process. To manage the risk, you need to evaluate the whole campaign, enforce permissions outside the model, and control every additional chance created by retries, fallback models, tools, and automated agents.

    The dangerous unit is the campaign, not the prompt

    A Best-of-N attack creates or collects multiple versions of a prohibited request, submits them to an AI system, and selects the response that comes closest to the intended outcome. The essential move is to send many variations and keep the most successful result. The value of N is not fixed, and the selection can be performed by a person, a script, or another model.

    This changes the security question. A per-request review asks, “Did this prompt get blocked?” A campaign-level review asks, “Did any related attempt produce a prohibited result?” The second question reflects the attacker’s objective.

    The probability principle is straightforward. If each attempt has a nonzero chance of crossing a boundary, repeated opportunities can raise the chance that at least one attempt succeeds. Under the simplified assumption that attempts are independent and have the same success probability p, the probability of any success after N attempts is 1 – (1 – p)^N. Real prompt variants are often correlated, so you should not use that formula as a production risk estimate. Measure complete campaigns against your actual system instead.

    Three distinctions prevent confusion during threat modeling:

    • A normal retry is usually an attempt to clarify a legitimate request after an incomplete or incorrect answer. Repetition alone does not establish malicious intent.
    • A jailbreak tries to bypass behavioral restrictions placed on a model.
    • Prompt injection supplies untrusted instructions that compete with the system’s intended instructions, often through user input or retrieved content. Best-of-N is a search strategy that can amplify jailbreaks, prompt injection, or other policy-evasion techniques.

    Treat Best-of-N as a threat multiplier, not as the root vulnerability. It finds inconsistent decisions and weak handoffs. It cannot grant a caller a permission that your application enforces deterministically outside the model. That is why authorization architecture matters more than clever safety wording.

    Where repeated attempts find extra chances

    An isometric AI network branches into retry loops, fallback nodes, tools, memory, and agent pathways carrying repeated request signals.

    Your model is only one part of the attack surface. A typical AI workflow also has an identity layer, input filters, a router, one or more models, output checks, retrieval, tools, and application code. Every component that makes a fresh probabilistic decision can give a campaign another route to success.

    LayerMisleading green lightCampaign signal to inspectStronger control
    Prompt policyOne prohibited request was refusedRelated requests are repeatedly rephrased after denialsAggregate policy events by actor, session, intent cluster, and protected resource
    Input moderationEach prompt remains below an individual alert thresholdSmall wording, format, language, or encoding changes accumulate around the same objectiveAnalyze normalized forms and sequences while retaining the raw input for investigation
    Model routingThe primary model refusedA fallback model, alternate endpoint, or retry path returned a different decisionApply one canonical policy before routing and a final gate after generation
    Tools and agentsThe assistant’s visible text looks harmlessA tool call requests a broader scope, sensitive record, or irreversible actionEnforce authorization, parameter validation, and action limits in application code
    Traffic controlsEach IP address or API key stays within its local limitRelated attempts move across sessions, keys, endpoints, or modelsCorrelate only the identifiers justified by your threat model, privacy obligations, and retention policy
    LoggingEvery prompt was stored somewhereNo record connects attempts, decisions, tool calls, and final outcomesAssign campaign and event identifiers so an investigation can reconstruct the sequence

    For an SEO, AEO, or GEO workflow, the highest-consequence result may not be a bad chat response. It may be an unauthorized CMS publication, a destructive edit, exposure of an unpublished campaign, or a tool call made with the application’s credentials. If a model generates page copy or JSON-LD, syntactic validation is necessary but insufficient. Valid structured data can still contain false, disallowed, or unapproved claims. Check the output against business rules and publishing permissions before it reaches a live page.

    Build controls that survive repeated attempts

    A request signal passes through layered security gates before reaching an AI core and protected tool mechanisms.

    No safety prompt can carry this responsibility alone. Prompts influence model behavior, but they are not security boundaries. Use several controls with different failure modes, and place deterministic checks wherever failure could expose data, spend money, alter content, or trigger an external action.

    1. Put authorization outside the model. Resolve the authenticated principal in application code, grant the least privilege needed for the workflow, and verify permission again when a tool executes. Never let generated text decide whether the caller may read, publish, delete, or export something.
    2. Separate read and write capabilities. An assistant that only needs to draft content should not inherit publishing or deletion rights. When write access is required, constrain the allowed resource, action, fields, and destination.
    3. Normalize for analysis without overwriting evidence. Retain the original request, then create a canonical representation for similarity detection. Normalization can help reveal superficial changes in spacing, character representation, formatting, or casing, but it must not silently change the content executed by downstream systems.
    4. Maintain campaign state. Record the actor or service identity, session, endpoint, model route, normalized intent cluster, policy decision, tool request, and outcome. Look for repeated denials, rapid reformulations, alternate-route probing, and requests that converge on the same protected capability.
    5. Add adaptive friction. As campaign risk rises, reduce retry opportunities, disable expensive fallback routes, introduce a cooldown, require stronger authentication, or move the request to human review. Apply the strongest friction to workflows with data access or irreversible effects rather than imposing the same response on harmless drafting tasks.
    6. Gate outputs and tool calls separately. Check generated content against the output policy, validate structured fields, reject unexpected tool names or parameters, and limit the records or resources returned. A harmless-looking explanation must not conceal a disallowed action request.
    7. Define safe failure behavior. If moderation, identity resolution, authorization, or final validation is unavailable, return a controlled error for protected operations. Do not route around a failed safeguard to preserve a smooth user experience.
    8. Protect the control plane. Restrict who can change system prompts, policy rules, model routes, tool definitions, and safety thresholds. Log those changes and make rollbacks possible, because a campaign can exploit configuration drift as readily as model variability.

    There is no universal safe retry count. A blanket limit low enough for a sensitive data-export agent may be needlessly hostile in a public brainstorming tool. Set budgets by consequence, then examine legitimate retry behavior before choosing enforcement thresholds. Track false positives alongside security outcomes so that users who are clarifying ambiguous, multilingual, or accessibility-related requests are not treated automatically as attackers.

    Be careful with model-based safety judges as well. A second model can add useful evidence, but it may share blind spots with the model it evaluates. Use deterministic authorization and validation for hard boundaries, with model judgments contributing to risk scoring rather than granting privileged access on their own.

    Test the full campaign without publishing an exploit kit

    A single-prompt red-team check will miss the defining behavior of Best-of-N. Your evaluation runner should group related attempts, preserve production routing logic, and score whether any attempt reaches a prohibited outcome. Keep testing authorized, isolated, and away from live customer data or publishing systems.

    1. Define the breach before generating tests. Describe prohibited outcomes in observable terms, such as returning a protected field, invoking a disallowed tool, publishing without approval, or producing content that violates a named policy. A vague label such as “unsafe response” produces inconsistent scoring.
    2. Build campaign families. Group sanitized test cases by underlying objective, then vary the permitted dimensions relevant to your system, such as phrasing, format, language, model route, and retry sequence. Keep actionable attack strings in an access-controlled security repository rather than general documentation or analytics dashboards.
    3. Reproduce the production topology. Include the actual order of input checks, retrieval, routing, fallback behavior, output gates, tools, and error handling. Testing the base model alone does not test the application your users can reach.
    4. Run attempts as connected sequences. Carry session and risk state between related requests. Also test whether switching endpoints or invoking an automated agent incorrectly resets that state.
    5. Score outcomes at two levels. Retain per-request decisions for diagnosis, but make campaign-level success the headline measure. A system can have an impressive individual refusal rate while still allowing too many campaigns to obtain one useful failure.
    6. Review the most consequential path first. A policy-breaching paragraph matters, but a tool call that exposes private data or changes a live site demands tighter controls and faster remediation.
    7. Version the evaluation and rerun it after changes. A new model, system prompt, router, retrieval source, guardrail, tool definition, or fallback rule can alter campaign behavior even when the visible feature appears unchanged.

    Your evaluation dashboard should include the campaign any-success rate, attempts to the first breach, breach severity, detection and containment outcomes, tool or data-boundary violations, and false-positive friction for legitimate users. Do not collapse these into one average. A small number of severe authorization failures should remain visible rather than being diluted by many harmless refusals.

    Stop a test immediately if it begins interacting with real user records, external recipients, paid services, or live publishing. Move the scenario into an isolated environment with synthetic data and inert tools. The purpose of the exercise is to verify containment, not to prove that production damage is possible.

    Key takeaways for AI product owners

    • One successful refusal does not establish safety; measure whether any attempt in a related campaign succeeds.
    • Best-of-N exploits repeated opportunities and inconsistent decisions, so retries, fallback models, alternate endpoints, and agents all belong in the threat model.
    • System prompts and model-based judges can support safety, but they cannot replace deterministic authentication, authorization, validation, and tool restrictions.
    • Aggregate related attempts without assuming every retry is malicious; calibrate friction to the consequence of the requested capability.
    • Test the production workflow as a sequence, then report campaign-level success and breach severity alongside per-request refusal metrics.
    • Keep security payloads controlled, use synthetic data and inert tools, and never red-team an external or production system without authorization.

    Before your next release, choose the AI workflow with the greatest access to data, tools, or publishing. Trace every place where a rejected request can receive another model call or another route. Then add campaign-level telemetry and a deterministic gate at the highest-consequence handoff.

    That review will not eliminate model variability. It will prevent variability from becoming permission.

    References


  • TurboQuant Search Acceleration: An SEO and GEO Action Plan

    TurboQuant Search Acceleration: An SEO and GEO Action Plan

    You may be wondering whether TurboQuant requires an immediate SEO response. The short answer is no: it is not an announced ranking update, and there is no disclosed evidence that Google Search is using it in production.

    It still matters. TurboQuant targets a constraint that shapes semantic search, retrieval-augmented generation, and AI answer systems: how much meaning a system can search within a limited memory and response-time budget. If that constraint loosens, more content can become practical to retrieve. Your job is to make sure your content remains understandable, competitive, and worth citing when the candidate pool grows.

    TurboQuant changes retrieval economics, not your ranking brief

    Semantic search systems commonly convert documents, passages, products, images, or other objects into vectors. A vector is a numerical representation that places related meanings near one another. When someone asks a question, the system can retrieve nearby vectors even when the wording in the query does not exactly match the wording in the content.

    The difficulty is scale. Detailed vectors consume memory, moving them through processors takes time, and building or updating large searchable indexes can be expensive. A system may therefore search only a restricted candidate set before another model ranks, filters, or summarizes the results.

    TurboQuant addresses that infrastructure problem by compressing vectors while preserving a close approximation of their original relationships. It mathematically rotates the data to make it easier to pack efficiently, then carries a 1-bit error-correction signal intended to reduce mistakes introduced by compression. Google also associates the approach with substantially lower memory requirements and nearly zero indexing time.

    That is important, but it is not the same as a new ranking factor. TurboQuant does not tell a search engine which page is trustworthy, which claim is current, which source deserves a citation, or which answer best satisfies a user. It makes one stage of the pipeline more efficient: locating semantically similar candidates.

    Keep the distinction clear in planning meetings. Retrieval asks, “Which items might be relevant?” Ranking and answer generation ask, “Which of those items should be used, in what order, and for what purpose?” Faster retrieval can affect the first decision without replacing the others.

    A larger candidate pool changes what can be discovered

    Scanning beams illuminate relevant capsules and document-like tiles across a vast abstract archive, with selected items grouped in the foreground.

    A search or AI system operates inside practical limits. It has finite memory, compute capacity, and time to produce a response. If vectors become cheaper to store and faster to search, the system could examine a broader collection of candidates within those limits. That could include more documents, more passages within each document, or more specialized material that would otherwise sit outside an economical retrieval set.

    This does not guarantee that AI answers will cite more websites. A larger candidate pool can increase opportunity and competition at the same time. Your page may become easier to retrieve, but so may a more precise product manual, a better-supported explanation, or a specialist page that previously sat too deep in the corpus.

    The likely strategic shift is from winning inside a narrow set of obvious pages to surviving comparison against a deeper set of semantically related passages. Thin content becomes more exposed in that environment. Repeating the target phrase does little when the system can find pages that answer the underlying question with clearer entities, stronger evidence, and better-qualified claims.

    Nearly zero indexing time could also make rapid ingestion more practical for systems built around TurboQuant. Do not turn that possibility into a claim about Google Search freshness. Crawling, rendering, canonicalization, quality assessment, and index-selection policies remain separate processes. Faster vector indexing cannot make an uncrawled or rejected page searchable.

    The same logic applies outside public search. An organization operating a large retrieval-augmented generation system could use aggressive vector compression to reduce memory pressure or update a knowledge index more quickly. If you own that system, TurboQuant is an engineering option to evaluate. If you publish content that such systems may ingest, the more durable task is to improve the material being represented by those vectors.

    Optimize the passage before you optimize the embedding

    Disordered translucent fragments are reorganized into clear modular content blocks before becoming compact glowing vectors.

    You usually cannot control which embedding model, quantization method, retrieval threshold, reranker, or answer model a third-party search system uses. You can control whether a passage contains enough information to be correctly interpreted after it is separated from the rest of the page.

    Start with answer-bearing passages. A useful passage names the subject, resolves the question, and carries the qualification that prevents the answer from becoming misleading. Avoid openings that rely on nearby headings or pronouns to supply all the context. “It depends on the plan” is fragile. “Indexing frequency depends on the crawler, the site’s change rate, and whether the URL remains eligible for indexing” retains meaning when retrieved alone.

    Do not force every paragraph into a rigid template. The goal is semantic completeness, not robotic prose. Use the following checks where a passage contains a definition, recommendation, comparison, process, limitation, or factual answer:

    • Name the entity. Use the full product, organization, method, or standard name before relying on shorthand. This reduces ambiguity between similarly named entities.
    • State the relationship. Make it explicit whether the entity creates, supports, replaces, depends on, conflicts with, or applies to something else.
    • Carry the qualifier. Keep version, platform, audience, condition, and scope close to the claim they limit.
    • Put evidence beside the claim. A citation attached to a vague paragraph is less useful than a link on the specific statement it supports.
    • Separate fact from inference. Use direct language for documented behavior and conditional language for plausible consequences. TurboQuant could support broader retrieval; that does not establish its use in Google Search.

    Next, cover the relationships around the central entity. A page about TurboQuant should not merely repeat that it accelerates vector search. A useful treatment connects compression to memory use, index construction, similarity accuracy, candidate retrieval, reranking, and downstream answer generation. Those relationships help a system match the page to different formulations of the same underlying problem.

    This is semantic breadth, not permission to inflate word count. Add a section only when it resolves a real adjacent question. Remove a section when it paraphrases a claim already made. Efficient retrieval can expose comprehensive content, but it can also expose padding.

    Make structured data support the same meaning

    JSON-LD and schema markup can reinforce entity identity and relationships, but they do not rescue unclear visible content. Treat structured data as a machine-readable restatement of the page, not a hidden layer where you make claims the reader cannot see.

    For each important page, compare the visible content with its structured data. The page title, main entity, author or organization, publication information, and any explicitly marked questions or steps should agree. If the markup identifies one subject while the body drifts into several loosely related topics, compression is not the problem. The underlying document is ambiguous.

    Internal links deserve the same discipline. Use anchor text that describes the destination’s role rather than generic commands such as “learn more.” Link from a broad concept to the page that resolves its important subtopic, and link back where the relationship helps the reader. This creates navigable context for crawlers and people without pretending that internal links directly control vector proximity.

    Technical eligibility remains the floor. Confirm that the canonical URL is crawlable, the primary answer appears in rendered HTML, internal links reach the page, and structured data matches the visible material. A brilliantly written passage cannot enter a retrieval pipeline that never receives or accepts the page.

    Run a retrieval-readiness audit you can repeat

    Do not create a TurboQuant-specific score. You have no public implementation details that would make such a score credible. Audit the properties that remain useful across embedding models and compression methods.

    1. Select a representative page from each important topic cluster. Include the pages that answer commercial, informational, troubleshooting, and comparison questions rather than auditing only your highest-traffic URLs.
    2. Build query families around user intent. For each page, write the direct question, a paraphrase, a problem-first version, and a version that names a competing approach. This reveals whether the page answers the concept or merely repeats one keyword pattern.
    3. Locate the passage that should satisfy each query. If you cannot point to a self-contained answer, rewrite the relevant section. Do not assume the title or surrounding page will repair an incomplete paragraph.
    4. Check entities and qualifiers. Mark unclear pronouns, unexplained abbreviations, missing versions, unsupported superlatives, and conditions placed far away from the claims they govern.
    5. Verify evidence and provenance. Link important claims to their originating authority when available. Remove assertions whose confidence exceeds the evidence.
    6. Compare visible content, metadata, and JSON-LD. Resolve conflicts in names, dates, page purpose, authorship, and entity type. Consistency makes the page easier to interpret; markup volume does not.
    7. Record answer-surface outcomes. For the query families you monitor, note whether your URL appeared, whether it was cited, which passage was used, and which alternative sources won. Ordinary rank position alone cannot show how an AI answer assembled its response.

    When a competing page is selected, diagnose the difference at the passage level. Ask whether it gave a more direct answer, named the relevant entity more clearly, carried a necessary qualification, supplied stronger evidence, or addressed an adjacent intent you omitted. Those observations produce useful editorial work. Guessing at an undisclosed quantization configuration does not.

    Keep infrastructure tests separate from content tests if you operate your own vector search system. Engineering teams can compare memory use, indexing cost, latency, and retrieval quality under compression. Editorial teams should evaluate answer completeness, ambiguity, evidence, and citation suitability. Combining both into one vague “AI optimization” metric makes it impossible to tell which layer improved.

    Key takeaways

    • TurboQuant compresses vectors to reduce memory pressure and accelerate similarity search, with a 1-bit signal designed to correct small compression errors.
    • It is retrieval infrastructure, not a disclosed Google Search ranking factor or confirmed production deployment.
    • Cheaper retrieval could let an AI system search a broader candidate set, but broader access also exposes your content to more competitors.
    • Your durable advantage is a crawlable page with self-contained passages, unambiguous entities, nearby qualifications, and evidence attached to specific claims.
    • Use JSON-LD to reinforce visible meaning. Do not use it to compensate for vague writing or to introduce claims absent from the page.
    • Measure citation and passage selection across query families, not just traditional rankings for one exact keyword.

    Your next move is modest: choose one important topic cluster and run the retrieval-readiness audit before rewriting the entire site. Fix the places where meaning breaks when a paragraph stands alone. That work remains valuable whether TurboQuant reaches public search, stays inside other AI systems, or inspires a different compression method.

    References