Tag: AI Marketing

  • How to Build an AI-Powered Creator Commerce Campaign

    How to Build an AI-Powered Creator Commerce Campaign

    You have creator candidates, a product catalog, and a paid-media budget. The hard part is connecting them: the creator must make the product relevant, the shopping surface must preserve the promise, and your measurement must show where the campaign actually worked or failed.

    The practical model is a single creator-commerce loop, not separate influencer, advertising, and ecommerce projects. You choose the buying action first, match creators to that job, plan the paid uses of their content, configure the offer shoppers will encounter, and measure every handoff.

    Treat creator marketing and AI shopping as one buyer journey

    A creator can introduce the problem, demonstrate the product, answer an objection, or give a buyer a reason to act. Commerce systems have a different job: they present the product, price, availability, and eligible benefits when that interest becomes purchase intent.

    AI is bringing those jobs closer together. YouTube can use Gemini to help advertisers find relevant creators and then distribute creator-made content through paid formats. Google has also extended member pricing and shipping benefits into AI Mode and Gemini, as well as local inventory and regional Shopping ads.

    For you, the important change is the handoff. A shopper can encounter a creator’s recommendation, see the same message in a paid placement, and later find a personalized benefit during product discovery. If those touchpoints contradict one another, AI-powered distribution merely spreads the inconsistency faster.

    Start each campaign by writing the promise that must survive the journey. If the creator discusses exclusive shipping for loyalty members, verify that the eligible shopper can actually see and receive that benefit. If the listing emphasizes member pricing, the creator’s call to action should explain why membership matters instead of sending everyone to a generic product page with no visible connection.

    This also changes how you divide responsibility internally. The creator team should know which offer the commerce team has configured. The commerce team should know which claims and calls to action appear in the creator asset. Paid media should not receive the content only after it has been produced; its required placements and audiences should shape the brief from the beginning.

    Build the campaign backward from a commerce event
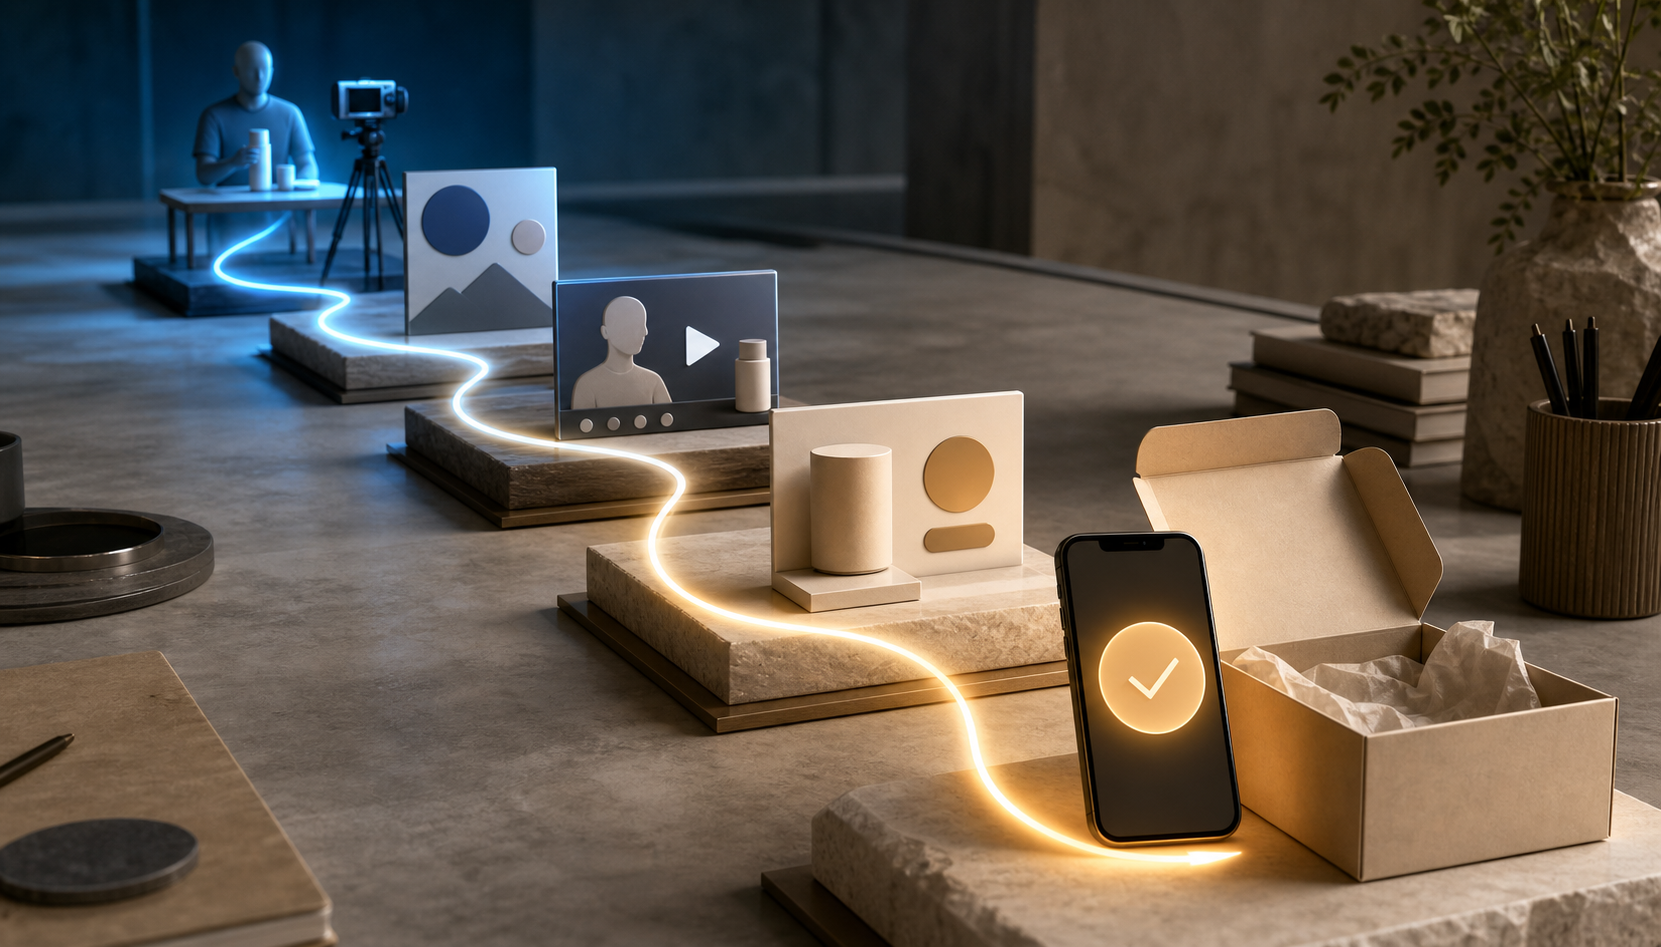
    A product purchase in the foreground connects backward through an offer, creator content, paid distribution, and content production.

    Do not begin with a broad request to find popular creators. Begin with the behavior you need from a specific kind of buyer. That decision determines the offer, brief, creator criteria, destination, and measurement plan.

    1. Name the commercial event. Decide whether the campaign is meant to generate product discovery, a qualified product-page visit, a first purchase, a loyalty enrollment, or another defined action. Use one primary event to make campaign decisions. Secondary metrics can explain performance, but they should not quietly replace the original goal.
    2. Define who can receive the offer. Separate prospects from recognized members and distinguish a public promotion from a loyalty benefit. If eligibility depends on a membership tier, country, region, or local inventory, record that before the creator writes the call to action.
    3. Choose the proof the buyer needs. A creator brief should identify the buyer’s problem, the product’s role, the objection that must be answered, and the evidence the creator can show. A product demonstration, use case, or clear explanation usually gives you more to evaluate than a generic endorsement.
    4. Shortlist creators for that job. YouTube’s Gemini-powered matching can suggest candidates from more than three million YouTube Partner Program creators. Use that scale to widen discovery, then apply human review to audience relevance, creative quality, product credibility, and suitability for paid distribution.
    5. Plan distribution before production. Decide whether the partnership will remain on the creator’s channel or also become a paid Short, an in-stream ad, or both. Confirm that the partnership permits every planned placement, market, and period of use before allocating media spend.
    6. Instrument the handoff. Give each creator and placement an identifiable destination or campaign parameter. Align the platform conversion event with the commercial event you selected. Where appropriate, add a creator-specific code, but do not treat code use as the only evidence of influence; shoppers may return through another route.

    Keep the first test interpretable. If you change the creator, audience, offer, landing experience, bid strategy, and product selection at the same time, a good result will not tell you what to repeat and a bad result will not tell you what to repair.

    Use AI matching as a shortlist, not a strategy

    Creator matching solves a discovery problem. It can help you navigate a large pool, but it cannot decide what your buyer needs to hear, whether the creator’s authority transfers to your product, or whether the resulting content will work outside the creator’s existing audience.

    Use a scorecard that forces every recommendation to produce observable evidence. The model’s recommendation can open the review; it should not end it.

    DecisionEvidence to inspectReason to pause
    Audience relevanceRecurring subjects, viewer questions, purchase problems, and use cases connected to the productThe connection depends mostly on a broad demographic label or follower count
    Product credibilityA natural reason for the creator to discuss, use, compare, or demonstrate the productThe endorsement would require a sudden change in the creator’s established subject matter
    Creative strengthA clear opening, understandable product role, concrete proof, and a call to action that fits the contentThe product appears only as an interruption with no useful explanation
    Paid-media portabilityA message that a cold viewer can understand without knowing the creator’s backstoryThe asset depends entirely on channel-specific context or an inside joke
    Offer alignmentA benefit the intended audience can receive in the markets and membership tiers being targetedThe creator would be promoting an offer that many reached viewers cannot access
    Measurement readinessA distinct asset, placement identifier, destination, and agreed conversion eventPerformance can only be read as a blended campaign total

    Follower count belongs in the context, not at the center of the decision. A smaller relevant audience can reveal stronger buying intent than a large audience gathered around unrelated content. Conversely, topical relevance alone is not enough if the creator cannot communicate the product clearly or if the asset cannot survive paid distribution.

    Review the likely failure mode before approving a match. If the creator understands the audience but not the product, improve the briefing or reject the match. If the content is persuasive to existing followers but confusing to cold viewers, separate the organic asset from the paid edit. If the offer is compelling but limited to recognized members, prevent the campaign from implying that every viewer will receive it.

    Turn creator content into a connected distribution system
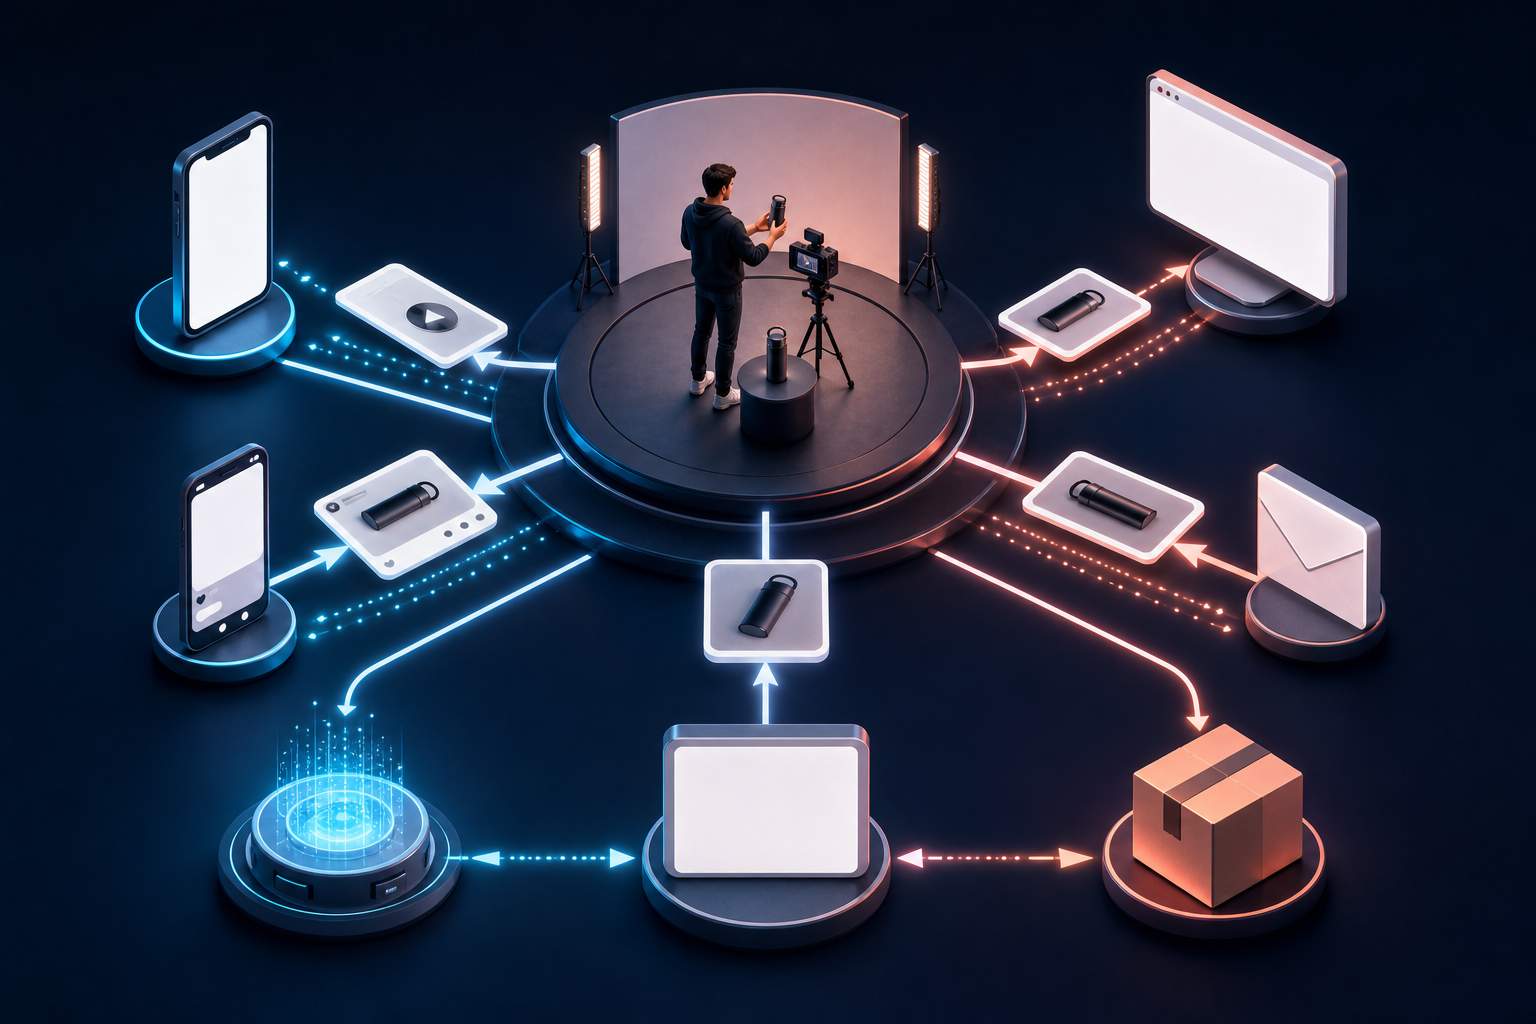
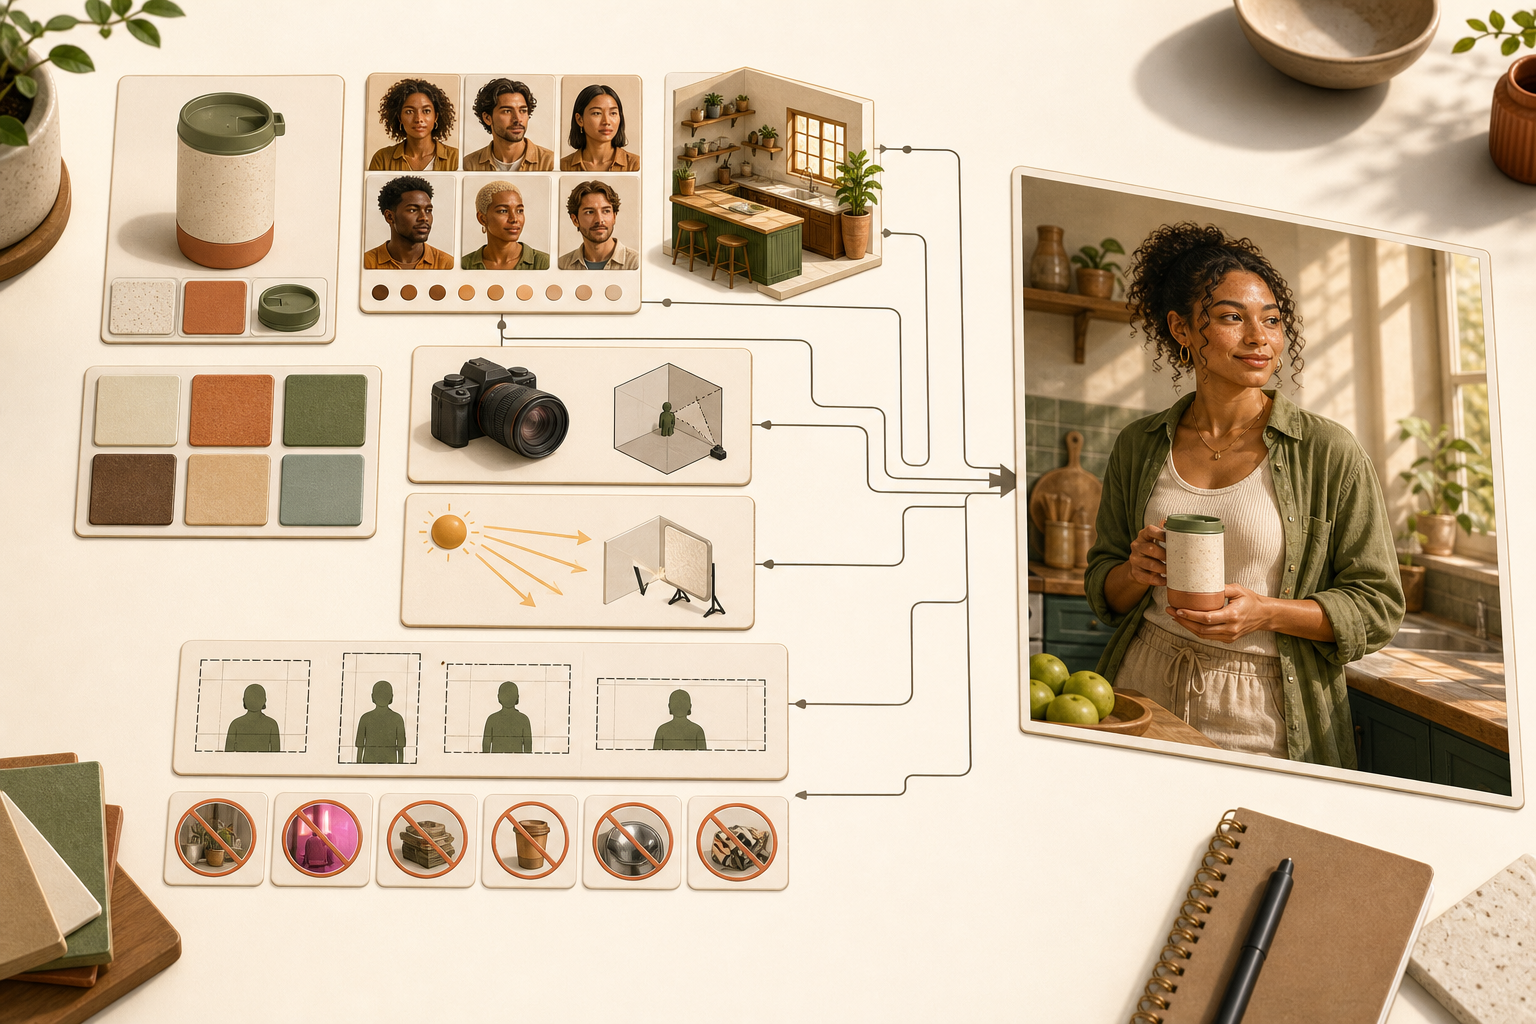
    A creator filming a product is connected by glowing paths to multiple content, shopping, advertising, order, and measurement touchpoints.

    A creator partnership should produce more than an isolated upload. YouTube allows creator-made content to run as paid Shorts and in-stream ads, giving you a route from creator credibility to controlled media distribution.

    That does not mean one edit should be copied everywhere. Give each placement a defined job while preserving the same product truth and offer:

    • The creator-channel asset establishes context, credibility, and the full product story for an audience that already knows the creator.
    • The paid Short introduces the buyer problem and product quickly enough to make sense to a cold viewer.
    • The in-stream ad has room to develop the use case, proof, or objection that cannot fit into the shortest edit.
    • The product or local inventory listing confirms the purchasable product and displays the applicable price or benefit.
    • The loyalty layer shows recognized members the pricing or shipping advantage for which they are eligible.

    Create a message ledger before editing begins. Record the approved product promise, supporting proof, exact offer wording, call to action, destination, market eligibility, membership requirements, and the placements where the asset will run. Every version can vary in pacing and length, but it should remain consistent with that ledger.

    The commerce setup deserves the same attention as the creative. Merchants using Google’s loyalty features can activate the loyalty add-on in Merchant Center, configure member tiers, supply pricing and shipping attributes, and connect Customer Match lists so recognized members can see eligible benefits. A creator campaign should not promote those benefits until the feed, tier rules, audience connection, and destination have been checked together.

    Market eligibility is part of the brief, not a footnote. The stated expansion covers Australia, Brazil, Canada, France, Germany, India, Italy, Japan, Mexico, the Netherlands, South Korea, Spain, the United Kingdom, and the United States. If your creator reaches viewers outside the relevant campaign market, use wording that does not imply universal access.

    Local inventory and regional Shopping ads can be especially useful when the benefit or product availability varies by location. Match the creator’s geographic targeting, the inventory being promoted, the Merchant Center configuration, and the landing experience. Otherwise, you pay to generate interest that the next surface cannot satisfy.

    There is also a U.S. pilot that uses Customer Match as a relationship data source for free listings. Treat pilot access as an optional opportunity, not as inventory you can assume in a forecast. Build the core campaign around placements and features actually available to your account.

    Measure the chain instead of celebrating one platform number

    Creator commerce can look successful at the top of the funnel while leaking value at the final handoff. A popular video does not prove product demand, and a strong click-through rate does not prove profitable sales. Your reporting should show how attention moved through the campaign.

    • Matching: Track which creator-selection criteria were expected to matter and whether the content attracted relevant viewer questions or actions.
    • Creative: Read view rate, completion, engagement, and product clicks by asset. These metrics help locate attention loss; they are not substitutes for the commercial event.
    • Media: Separate organic creator delivery from paid Shorts and in-stream distribution. Report cost, reach, click-through rate, conversion rate, and acquisition cost by placement.
    • Commerce: Measure product-page behavior, purchases, order value, and offer redemption using consistent definitions.
    • Relationship: Where loyalty is part of the objective, distinguish existing recognized members from new enrollments and non-member buyers.

    Document every denominator. A conversion rate based on clicks is not interchangeable with one based on sessions, and a customer acquisition cost should not silently include returning customers if the campaign goal is new-customer growth. Definition drift can make two dashboards appear to agree when they are measuring different events.

    Platform lift figures are useful for forming a hypothesis, not for writing your revenue forecast. YouTube reports an average 30% conversion lift from boosting creator content through Shorts and in-stream ads. Google reports that some retailers saw up to a 20% increase in click-through rate when tailored loyalty offers were shown to members.

    Those numbers should not be combined or treated as guaranteed. One is an average conversion result for creator advertising formats; the other is an upper-end click-through result reported for some retailers using tailored offers. They describe different interventions, outcomes, and populations. Your baseline, margin, audience, creative, product, and offer determine whether either benchmark is relevant.

    Use controlled comparisons to learn what contributed. Hold the offer, audience, and destination steady when comparing creator-made and brand-made assets. Evaluate loyalty presentation separately instead of mixing it into the creative test. If several creator assets run together, retain asset-level and creator-level identifiers so a blended result does not hide the winner or the failure.

    Read mismatches as diagnostic signals. Strong viewing with weak product clicks points you toward the call to action or offer handoff. Strong clicks with weak conversion points you toward the destination, price, eligibility, or product experience. Strong conversion with limited reach points you toward distribution. These are places to investigate, not automatic diagnoses, but they are more useful than labeling the whole campaign good or bad.

    Key takeaways

    • Choose the buying action and eligible offer before asking AI to find creators.
    • Use AI matching to expand and organize discovery, then require human evidence for audience fit, product credibility, creative quality, and paid-media suitability.
    • Plan creator-channel content, paid Shorts, and in-stream ads as related assets with different jobs, not automatic duplicates.
    • Verify Merchant Center tiers, pricing, shipping attributes, Customer Match connections, markets, and destinations before a creator promises a loyalty benefit.
    • Measure the full path from creator attention to commerce and customer relationship outcomes. Treat vendor-reported lift as a hypothesis, not your forecast.

    Your next move is to choose a product, a buyer action, and an offer that the intended audience can actually receive. Write the creator brief, placement plan, commerce configuration, and measurement event on the same page. If that chain remains clear from first view to purchase, you have a campaign worth testing.

    References


  • Unleashing AI in B2B: Your Patient Path to Growth

    Unleashing AI in B2B: Your Patient Path to Growth

    B2B buyers start their journey long before they even search for us. I’ve learned that AI-powered Google Ads campaigns can ignite early demand and reward patience over time.

    If I’m relying solely on brand and non-brand keywords in Google Ads, my growth becomes limited. A decline in performance isn’t due to the platform but the strategy behind it.

    Discovering a brand doesn’t begin with a non-brand search. Buyers are researching on platforms like Reddit, ChatGPT, Facebook, LinkedIn, and YouTube. They watch demos, read testimonials, and become familiar long before actively searching for us.

    For complex sales processes with lengthy customer journeys, this transformation is crucial, demanding a strategic shift. Here’s how I can make it effective in B2B.

    AI-powered Campaigns: Your Growth Treasure

    Over the years, Google has innovated with multi-channel, multi-asset campaigns like Performance Max and Demand Gen. These campaigns place my brand front and center as audiences research and evaluate options.

    When my audience is ready to choose vendors, they’ve already built trust in my brand. They’ll search specifically for me because of the trust I’ve cultivated through consistent visibility.

    A well-rounded Performance Max campaign includes diverse ad types, like image and video ads displaying demos or testimonials on YouTube. These ads also engage audiences across the web via the Display Network and retarget them as they continue their research. This process naturally leads to branded searches that ultimately convert.

    Such campaigns are cost-effective, allowing me to leverage customer data alongside keywords as intelligent signals, not replacements. It’s about smarter keyword usage.

    Dig deeper: Why B2B brands are shifting from keywords to Performance Max

    Adapting to the Evolving Search Experience

    As AI Overviews and AI Mode transform Google’s search results pages, it’s time I reconsider my ad strategies to align with these changes.

    I’m fond of the 4S framework: search, scroll, stream, and shop.

    Adding “ask” captures how people now engage with AI tools. They consult ChatGPT or Gemini, search on Google, scroll through LinkedIn, stream videos on YouTube, and shop across numerous platforms. If my strategy focuses on only a couple of these behaviors, I’m missing the full growth opportunity.

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    Solely targeting keywords means missing the larger narrative. Brand keywords undoubtedly convert better, but how do people arrive at searching my brand? Consistent visibility ensures they notice my brand in their feeds.


    Embrace Testing and Learn with Patience

    This strategy requires time, especially in B2B settings with protracted sales cycles.

    For example, it took almost a year to appreciate how Performance Max contributed to one of my life science client’s success, whose deals typically take months to finalize. There was a moment where our account manager nearly paused the campaign because initial data wasn’t promising.

    Integrating sales data changed the perspective. As revenue figures rolled in, the campaign’s value became transparent.

    If I can sync beyond MQLs with data like Proposal Sent, it keeps Google well-informed and offers reassurance until the sales data solidifies our insights.

    Patience is key when providing the system quality data. I must remain steadfast and avoid quitting prematurely, accepting the complexity of B2B cycles.

    An event might draw 100 people, some catch a webinar email later, and months pass before they search for us and request a proposal, eventually becoming customers. With long sales cycles, phenomena like this unfold subtly.

    Dig deeper: How to optimize B2B PPC spend when budgets and confidence are low

    Start with Small Steps, Then Scale Success

    If testing funds are limited, I can designate 5% to 10% for AI-forward campaigns. Strategic testing without major commitments at peak times allows room to maneuver while the system adjusts.

    Investing time in this strategy ensures sustainable growth. Those who master it gain an enduring competitive edge, unlike those focused on diminishing demand.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Prove AI Marketing ROI Before Scaling Your Spend

    How to Prove AI Marketing ROI Before Scaling Your Spend

    Your AI dashboard can look busy while the P&L remains unchanged. Faster drafts, more creative variants, rising AI visibility, and a lower apparent cost per task do not prove that AI created economic value.

    If you need to defend an AI marketing budget, you need a credible answer to three questions: what changed compared with what would otherwise have happened, how that change became profit or cash savings, and what the change cost in full. The framework below gives you a practical way to answer them before a promising pilot becomes an expensive permanent line item.

    Key takeaways

    • Classify every AI investment as an operational-efficiency bet, a marketing-performance bet, or a distribution-channel bet. Each requires different evidence.
    • Calculate ROI from verified economic benefit, not output volume, model usage, impressions, mentions, or hours theoretically saved.
    • Include implementation, data preparation, quality assurance, training, governance, measurement, and rework in the cost base.
    • Compare results with a credible counterfactual. A before-and-after improvement alone does not show that AI caused the change.
    • Keep released capacity separate from cash savings. Time saved has economic value only when you remove a cost or redeploy the capacity productively.
    • When a platform cannot provide adequate performance data, fund it as a capped learning experiment rather than presenting it as a proven acquisition channel.

    Define the AI bet before you calculate its return

    AI marketing is not one investment category. The label often hides three economically different bets. Combining them in one dashboard produces an attractive blended number that nobody can audit.

    Operational-efficiency bets

    An operational bet uses AI to reduce the resources needed for research, briefing, production, analysis, reporting, or quality control. Its first useful measures are cost per approved deliverable, cycle time, rework, throughput, and error rates.

    The word approved matters. Producing twice as many drafts is not a productivity gain if editors reject more of them or senior staff spend the saved time correcting unsupported claims. Measure the complete path from request to usable output, including human review.

    Marketing-performance bets

    A performance bet uses AI to improve an existing marketing activity: audience selection, creative development, content optimization, lead qualification, conversion, or budget allocation. The economic question is not whether the AI produced more activity. It is whether the intervention created incremental qualified demand or contribution profit.

    Pair the business outcome with a guardrail. If AI-generated landing pages increase initial conversions but attract poorly matched leads, conversion rate alone will overstate the return. Depending on your funnel, the guardrail may be qualification rate, sales acceptance, cancellation, return rate, retention, factual accuracy, or brand compliance.

    Distribution-channel bets

    A channel bet pays for access to an audience or invests in visibility inside an AI-mediated discovery environment. ChatGPT advertising and programs intended to improve a brand’s presence in AI answers belong here, even though one is paid distribution and the other may involve content, technical, and authority work.

    Channel economics depend heavily on observability. An early ChatGPT advertising program combined manual buying through calls, email, and spreadsheets with limited performance reporting. That does not prove the inventory has no value. It means an advertiser cannot responsibly claim performance ROI that the available evidence does not establish.

    Write a one-sentence investment claim before approving any of these bets: Because we will use AI to change a named process for a defined audience, a named business outcome should improve through a stated mechanism. If the team cannot complete that sentence without using words such as engagement, innovation, scale, or efficiency as substitutes for an outcome, the proposal is not ready for an ROI calculation.

    Then record seven fields on an investment card:

    1. The decision the measurement must support: scale, continue, redesign, or stop.
    2. The exact AI intervention and the workflow or channel it changes.
    3. The mechanism that should connect the intervention to value.
    4. The eligible audience, campaign, account, content group, or business unit.
    5. The baseline and the best available counterfactual.
    6. One primary business outcome and the relevant quality guardrails.
    7. The maximum cost, evidence standard, decision owner, and decision point.

    This card prevents metric drift. A team should not begin with qualified pipeline as its goal, fail to influence pipeline, and later declare success because the model generated a large number of assets.

    Build a cost and value ledger that survives scrutiny

    Unmarked compute, labor, storage, revenue, and savings objects are arranged in parallel cost and value lanes.

    The clean formula is simple:

    AI marketing ROI = (verified economic benefit – fully loaded AI cost) / fully loaded AI cost x 100.

    The difficult work sits inside the two inputs. Verified economic benefit should normally consist of incremental contribution profit and realized cash savings. Fully loaded cost should include every material resource required to produce, govern, measure, and maintain the result.

    Count more than the software invoice

    Your cost ledger may need the following entries:

    • Subscriptions, model usage, API charges, media, and platform fees.
    • Integration, workflow design, prompt development, and automation maintenance.
    • Data preparation, permissions, tagging, analytics configuration, and CRM work.
    • Employee and contractor time spent operating or supervising the workflow.
    • Editorial review, factual verification, brand review, security review, and legal or compliance review where applicable.
    • Training, documentation, adoption support, and process redesign.
    • Experiment design, holdout management, reporting, and analysis.
    • Rework caused by incorrect, inconsistent, duplicated, or unsuitable output.
    • Replacement costs for tools or services that the new system does not fully eliminate.

    Use an internal labor-cost basis consistently. A billable agency rate, an employee’s loaded cost, and the opportunity value of an hour are different numbers. Switching among them to make a project look attractive turns the model into advocacy rather than measurement.

    Separate profit, savings, and capacity

    Incremental revenue is not incremental profit. Convert additional revenue into contribution profit by applying the relevant contribution margin and subtracting variable fulfillment costs that arise with the new business. Keep the measurement period consistent across the revenue, cost, and margin inputs.

    Cash savings require an expense to disappear. A cancelled vendor contract, eliminated overtime, reduced external production spend, or a role that no longer needs to be added can create a realizable saving. A team finishing a task earlier while payroll remains unchanged creates capacity, not an immediate cash saving.

    Capacity can still be valuable, but you need to show where it went. If marketers use released time to run additional experiments, improve sales enablement, or serve more accounts, measure the resulting throughput and economic outcome. If the time simply becomes slack, record the operational improvement without booking it as profit.

    Avoid double counting. Suppose AI reduces editing time and the team uses that time to launch an additional campaign. If the campaign produces verified incremental contribution profit while payroll stays constant, credit that contribution profit. Do not also claim the same editing hours as a payroll saving.

    Calculate the breakeven outcome before launch

    A breakeven calculation gives the team a concrete hurdle before optimism enters the reporting:

    Required incremental outcomes = fully loaded AI cost / contribution profit per incremental outcome.

    An outcome might be a completed purchase, a retained customer, a qualified opportunity, or another event with defensible economic value. Match the event to the investment. A campaign intended to create qualified pipeline should not use raw leads as its breakeven unit merely because leads are easier to count.

    If contribution varies widely, calculate more than one scenario using your own documented assumptions. Label those results as forecasts until observed outcomes replace them. The purpose is not to predict the future precisely. It is to expose what the investment must accomplish to pay for itself.

    Use an evidence standard the channel can support

    Two matching transparent chambers compare conventional and AI-assisted marketing routes under controlled conditions.

    Attribution and incrementality answer different questions. Attribution assigns credit to a touchpoint under a chosen rule. Incrementality estimates what happened because of the marketing intervention and would not otherwise have occurred. ROI needs the second answer, even if attribution data helps you investigate the first.

    Choose the strongest feasible design before the campaign begins. The following ladder runs roughly from stronger causal evidence to weaker directional evidence:

    1. A randomized holdout in which eligible units are assigned to treatment and control.
    2. A matched comparison using similar regions, accounts, audiences, or content groups, with known differences documented.
    3. A staggered rollout that compares early and later groups across the same period.
    4. An instrumented journey using permitted campaign parameters, dedicated destinations, CRM fields, offer paths, or customer-reported discovery.
    5. An adjusted before-and-after comparison that explicitly accounts for other material changes.
    6. Platform-reported attribution, AI visibility, impressions, mentions, citations, or production volume without a counterfactual.

    Report what the design supports. A controlled test may justify a causal estimate. An instrumented path can show that a tracked interaction preceded a conversion, but it does not automatically show that the interaction caused the conversion. A visibility increase is evidence of increased presence, not evidence of revenue.

    Before-and-after reporting is especially easy to misread. Pricing, promotions, seasonality, sales follow-up, product availability, competitor activity, media mix, and site changes can all move during the same period. Document those factors and use a concurrent comparison when feasible.

    Measure AEO and GEO as a connected outcome chain

    For AI search, answer engine optimization, and generative engine optimization, visibility belongs near the beginning of the outcome chain. Define a stable prompt set around your actual audience and buying questions. Record the model, date, conditions, brand mentions, citations, cited pages, and competitor presence. Sample consistently instead of treating one favorable response as a benchmark.

    Next, connect visibility to behavior where observable: qualified referral sessions, engaged visits, branded demand, assisted leads, direct inquiries, sales conversations, and customer-reported discovery. Then connect those behaviors to qualified pipeline, purchases, retention, or contribution profit.

    Do not assign revenue to an AI mention merely because a conversion occurred later. When the click trail is incomplete, present the visibility result, the observed business movement, and the uncertainty between them as separate facts. That is more useful than forcing an exact return from incomplete data.

    Treat low-observability advertising as a learning purchase

    When an advertising platform cannot provide the performance data needed for an incrementality analysis, cap the spend at an amount the business can afford to treat as experimentation. Write down the learning objective, the permitted instrumentation, the audience or placement being explored, and the evidence that would justify another round.

    Where the format permits, use a dedicated landing path, campaign parameters, a distinct offer, CRM source fields, and a customer-reported discovery question. None of these creates a perfect counterfactual, but they can produce more decision-useful evidence than aggregate traffic and anecdotal sales feedback.

    Do not promise a performance return above the platform’s evidence ceiling. Early ChatGPT advertisers faced too little performance data to prove that ads translated into business results. In that situation, the honest deliverable is a documented learning result, not a fabricated return on ad spend.

    Protect the economics after the pilot

    An AI pilot can improve production economics and still weaken the surrounding business model. This is particularly visible in agencies: automation reduces delivery effort, while clients expect the efficiency to lower their fees. SparkToro’s worldwide survey of agency owners put concern about AI as a potential threat at 53% in 2025, up from 44% in 2024.

    Reporting only tokens consumed, assets produced, or hours removed reinforces the idea that the service is a commodity. The durable value sits in diagnosing the commercial problem, choosing the right intervention, creating defensible evidence, interpreting exceptions, and taking responsibility for the decision that follows.

    Choose a pricing model that matches measurability

    AI does not make every engagement suitable for performance pricing. Use the model that matches the amount of control and measurement available:

    • Use a fixed fee when the deliverable, quality standard, scope, and acceptance criteria are clear.
    • Use a retainer when the client is buying continuing strategy, experimentation, governance, and decision support rather than a predetermined volume of output.
    • Use time-based pricing for ambiguous discovery work where the necessary scope cannot yet be defined responsibly.
    • Use a performance component only when both parties agree on the eligible outcome, system of record, baseline, attribution or incrementality rule, measurement window, exclusions, data access, and payment limits.

    Performance fees create disputes and potentially uncapped financial exposure when those terms are vague. Put the definitions, adjustment rules, caps, termination conditions, and audit rights in the contract, and have qualified counsel review material compensation changes.

    Track contribution margin by account or service line: revenue minus direct labor, AI usage, contractors, and appropriately allocated delivery support. If efficiency improves, decide explicitly whether the gain will fund a lower price, higher quality, greater throughput, or a healthier margin. Assuming one workflow change will deliver all four at once usually hides an unpriced tradeoff.

    The commercial pressure is not hypothetical. Some agency sales cycles have lengthened from 7-8 weeks to more than 12 weeks as buyers question what AI should do to price and value. Answer that question directly in proposals: disclose where automation supports delivery, define the human accountability that remains, and tie the fee to scope and economic responsibility rather than an inflated count of manual hours.

    Include quality control and talent development in the model

    Removing routine work can also remove the training ground that produces future strategists. Sixty-six percent of agency owners expressed concern about shrinking career opportunities for junior staff. Treating that as someone else’s future problem understates the long-term cost of automation.

    Redesign junior work instead of deleting development. Have less-experienced marketers verify AI output against source material, document recurring failure modes, prepare experiment readouts, observe senior decision reviews, and own bounded tests under supervision. Include the supervision and training time in the investment ledger. A margin that depends on unrecorded senior rework is not a real margin.

    Put every investment through a scale, continue, or stop gate

    A pilot does not need perfect attribution, but it does need a precommitted decision process. At the decision point:

    • Scale when verified economic benefit exceeds the fully loaded cost, quality guardrails remain inside approved limits, and the evidence is strong enough for the amount of money at risk.
    • Continue as an experiment when the signal is promising, the uncertainty is material, and the next test has a realistic way to resolve that uncertainty.
    • Redesign when the mechanism appears plausible but adoption, data quality, workflow fit, or measurement prevented a fair test.
    • Stop when the benefit remains below the economic hurdle, guardrails fail, or the evidence gap cannot be closed at a proportionate cost.

    Start with the largest AI-related line in your current marketing budget. Label it as an efficiency, performance, or channel bet. Rebuild its fully loaded cost, write down the counterfactual, and identify the strongest evidence you can obtain. If you cannot do those three things yet, move the spend into a capped experiment. Scale it only when the economic benefit and the quality of evidence can withstand the same scrutiny as any other marketing investment.

    References

  • How to Choose a Fintech Marketing Agency Without Guesswork

    How to Choose a Fintech Marketing Agency Without Guesswork

    You’re not really choosing between agency websites. You’re choosing who will translate a financial product into accurate claims, discoverable content, qualified demand, and reporting your team can trust. A polished pitch can hide weak audience knowledge, an inexperienced delivery team, or metrics no one can connect to the business.

    The safest way to make the decision is to define the assignment before outreach, score comparable evidence, and watch the proposed team work on a controlled diagnostic. That process gives you something more useful than a generic list of leading fintech marketing agencies: a defensible way to identify the right agency for your product, buyer, risk profile, and growth constraint.

    Set the mandate before you look at agencies

    The label fintech marketing agency is too broad to guide a purchase. A firm built around authority-building SEO and content solves a different problem from one centered on HubSpot-led inbound programs. Paid acquisition, public relations, lifecycle marketing, conversion work, and AI search visibility require different operating strengths again.

    Start by writing a short mandate that an agency cannot reinterpret into whatever it already sells. Use this structure:

    We need [specific audience] to take [observable action] because [business constraint or opportunity]. The agency will own [channels, systems, and outputs]. Our team will own [approvals, subject-matter input, implementation, and risk decisions]. Success will be assessed through [business outcome, funnel measure, and delivery evidence].

    Then add the information that determines whether the work is actually feasible:

    • Audience: Identify the buyer, user, internal influencer, and approver where those roles differ. A case study involving a bank is not relevant merely because your prospective customer is also a bank.
    • Product: Describe the product category, buying motion, implementation burden, and the parts prospects routinely misunderstand.
    • Bottleneck: Name the current constraint. It may be weak discovery, low-quality traffic, poor conversion, slow approvals, incomplete attribution, or content that fails to demonstrate expertise.
    • Scope: Separate strategy, production, distribution, technical implementation, campaign operations, analytics, and reporting. Do not assume that an agency recommending work is also equipped to ship it.
    • Claims: Provide approved language, evidence requirements, prohibited claims, and the people authorized to approve changes.
    • Systems: List the content management system, analytics stack, customer relationship platform, advertising accounts, and any access restrictions that will shape delivery.
    • Dependencies: Identify the internal experts, engineers, designers, analysts, legal reviewers, and compliance reviewers whose availability can affect progress.
    • Decision rights: State who can approve strategy, budget changes, publication, tracking changes, and exceptions to the normal process.

    This mandate becomes the control document for the selection. Give every candidate the same version. If one agency quietly changes the audience, channel, or definition of success in its proposal, you have learned something important before signing a contract.

    Score evidence instead of presentation quality

    An overhead view of proposal folders and blank evaluation cards arranged with tokens representing case studies, compliance, audience knowledge, and references.

    A useful baseline is built from seven evidence categories weighted to 100%: notable clients at 23%, leadership experience at 20%, average reviews at 18%, agency age at 15%, median employee tenure at 11%, founder-led status at 8%, and media references at 5%.

    Those weights are not a universal truth. They are a disciplined starting point. More importantly, they force you to distinguish evidence from marketing copy.

    CriterionBaseline weightEvidence to requestWhat weak evidence looks like
    Relevant clients23%The three closest engagements, including the product, audience, channel, agency scope, proposed team involvement, and business problemA logo wall with no explanation of what the agency did or whether the work resembled your assignment
    Leadership experience20%Relevant operating history and a clear statement of how agency leaders will participate after the saleImpressive biographies paired with no access to those leaders during delivery
    Average reviews18%Reviews that describe fintech-relevant work, communication, problem solving, continuity, and measurable outputsGeneric praise that could apply to any creative or digital agency
    Agency age15%Evidence of operating stability, repeatable processes, and adaptation as channels and platforms changedLongevity presented as a substitute for current expertise
    Median employee tenure11%Public team histories or disclosed tenure information for the people likely to serve the accountA sales team that cannot identify who will perform the work
    Founder-led status8%A precise description of founder involvement, decision authority, and escalation accessThe founder appears in the pitch but disappears from the operating model
    Media references5%Relevant third-party recognition tied to the capability you are buyingAwards and mentions that have no connection to fintech or the required channel

    Reweight the model around the risk in your assignment. If the work depends on senior judgment, increase the importance of leadership involvement. If you need sustained production, emphasize delivery-team tenure and capacity. If the brand faces significant reputational exposure, give more weight to references that demonstrate disciplined claims handling. If the assignment is a narrow technical build, direct implementation evidence may matter more than broad industry visibility.

    Avoid double-counting the same proof. A client logo, case study, review, award, and conference appearance may all originate from one engagement. Record the underlying engagement once, then note which parts of the agency’s claim it actually supports.

    Score the people assigned to you, not merely the company. Ask for names, roles, allocation assumptions, and replacement procedures. Senior agency experience has limited value if junior generalists will make the daily decisions without suitable supervision.

    Test how the agency handles fintech complexity

    Do not ask whether an agency understands fintech compliance. Almost every candidate will say yes. Give the proposed team a realistic, sanitized scenario and inspect how it reasons.

    • Product comprehension: Provide a representative product page and ask the team to restate the audience, problem, mechanism, limitations, and required evidence. Watch for simplifications that change the meaning.
    • Claim provenance: Ask how every material claim will be connected to an approved fact, subject-matter expert, product record, or other internal evidence.
    • Approval flow: Ask the team to map how a draft moves through marketing, product, legal, compliance, and publication. The answer should include what happens when reviewers disagree.
    • Change control: Ask who can alter approved language, how revisions are recorded, and how an outdated claim is corrected across derivative assets.
    • Audience precision: Ask the agency to separate the information needs of users, buyers, influencers, and approvers. A single generic persona usually produces generic content.
    • Data handling: Ask what customer, account, analytics, and advertising data the agency needs; where that data will be accessed; and which subcontractors or tools may receive it.
    • Escalation: Present a scenario involving an inaccurate published claim or broken conversion path. Look for containment, ownership, notification, correction, and prevention steps rather than improvisation.

    An agency does not need to practice law to demonstrate sound operational discipline. Final legal and regulatory judgments should remain with the qualified people your governance designates. Do not let industry familiarity become an informal substitute for your approval process; the downside is public-facing language that no accountable reviewer actually authorized.

    Challenge vague SEO, AEO, and GEO promises

    AI visibility has created a new layer of agency claims. The terminology can be useful, but only when it resolves into observable work. No agency controls whether a third-party AI system includes or cites a page, so a guarantee of placement is not a credible operating plan.

    Ask an agency claiming SEO, answer engine optimization, or generative engine optimization expertise to show:

    • The audience questions, entities, topics, and commercial decisions it intends to target.
    • The pages or assets it would create, consolidate, update, or remove, with a reason for each action.
    • How it will maintain consistency among product facts, expert statements, page copy, metadata, and structured data.
    • Which schema types are appropriate to the visible content, how markup will be validated, and who will fix errors after deployment.
    • How it distinguishes rankings, search impressions, organic visits, AI referrals, brand mentions, third-party citations, assisted conversions, and business outcomes.
    • Which measurements are direct observations and which are proxies. A proxy should not be relabeled as revenue impact.
    • How its reporting accounts for platform, prompt or query set, language, location, account state, collection method, and capture date.

    Schema can make page meaning more explicit to systems that process it, but it does not guarantee visibility or citation. Treat structured data as part of factual and technical quality, then evaluate it alongside accessible page content, authority signals, crawlability, and measurement.

    Key takeaways

    • Choose an agency for the bottleneck it must remove, not for the breadth of its fintech label.
    • Relevant experience must match your product, audience, channel, and operating constraints.
    • Evaluate the named delivery team separately from agency leadership and sales personnel.
    • Require an approval and correction workflow before the agency publishes risk-sensitive claims.
    • Define AI visibility through repeatable observations and business measures, never guaranteed placement.

    Use a paid diagnostic to expose the working relationship

    A fintech team and agency specialists collaborate around a table with an abstract product prototype, journey cards, compliance pieces, and measurement tokens.

    Proposals show how an agency sells. A controlled diagnostic shows how its people think, ask questions, handle missing information, and turn strategy into work. Run it with the team proposed for your account rather than a separate pitch team.

    Set a capped scope, confidentiality terms, and ownership terms before the diagnostic begins. Without those boundaries, a useful test can turn into open-ended consulting or leave both sides uncertain about who owns the resulting material.

    Provide realistic operating inputs, but sanitize customer records, credentials, unpublished financial information, and any confidential material not covered by the agreement. Useful inputs can include an approved product description, representative content, current measurement definitions, brand requirements, known audience objections, and the existing approval path.

    Ask for outputs that reveal judgment rather than decorative presentation:

    • Corrected mandate: The agency should identify ambiguities, contradictions, hidden dependencies, and decisions your brief failed to resolve.
    • Audience and intent map: It should connect audience questions and objections to a buying or adoption decision, not produce a loose collection of keywords.
    • Opportunity map: It should show what deserves action, what should wait, what cannot be known yet, and what evidence would change the priority.
    • Representative brief: A content, campaign, conversion, or technical brief should be detailed enough for another specialist to execute without guessing at the objective or claim boundaries.
    • Measurement design: It should define the baseline, required instrumentation, direct measures, proxies, reporting ownership, and known attribution limits.
    • Governance flow: It should place product, subject-matter, brand, legal, compliance, security, and publication decisions with named roles.
    • Risk register: It should identify access gaps, approval delays, data limitations, technical dependencies, and assumptions that could invalidate the plan.

    Evaluate the diagnostic process as closely as the deliverables. Strong teams ask for evidence before asserting causes. They distinguish a fact from an inference, surface inconvenient constraints, and assign owners to next actions. Weak teams rush to a familiar channel plan, disguise unknowns with polished language, or treat your approval process as an obstacle to work around.

    If procurement or budget rules prevent a paid diagnostic, run a structured working session with the proposed team and request redacted examples of comparable operating artifacts. That is less revealing than commissioned work, but it still provides better evidence than a credentials presentation alone.

    Put measurement, governance, and exit terms in the contract

    A good selection can still fail when the contract leaves delivery open to interpretation. The agreement should turn the mandate into accepted outputs, decision rights, measurement rules, and a usable exit path.

    Tie scope to accepted outputs

    For every recurring or project output, define:

    • The format and level of completion expected.
    • The agency owner, client owner, reviewers, and final approver.
    • The evidence, brand rules, and claim controls that apply.
    • The acceptance criteria and the process for rejected work.
    • The revision and change-control process.
    • The internal systems, access, and dependencies required.
    • Whether the agency recommends, produces, publishes, implements, monitors, or merely reports.

    This distinction matters in technical SEO and structured data work. A recommendation document is not an implementation. Generated markup is not validated deployment. Deployment is not ongoing accuracy. The contract should state where the agency’s responsibility ends and where yours begins.

    Build a measurement ladder

    Organize reporting from business impact down to delivery evidence:

    • Business outcomes: Use the approved commercial result appropriate to the assignment, such as qualified pipeline, funded or activated customers, retention, or another accepted value measure.
    • Funnel behavior: Track the actions that connect marketing exposure to the business outcome, with qualification rules defined in advance.
    • Channel outcomes: Use channel-specific measures such as qualified organic visits, campaign responses, conversion behavior, or attributable referrals.
    • Diagnostic signals: Monitor the observations that help explain movement, including query coverage, crawl and indexing state, content engagement, brand mentions, structured-data validity, and AI citations where they can be observed responsibly.
    • Delivery evidence: Record what was approved, shipped, corrected, and learned. Activity volume alone is not performance, but missing delivery can explain missing results.

    Do not blend these layers into a composite score unless everyone understands the formula and tradeoffs. A growing visibility proxy cannot cancel a falling business outcome. The agency should state which measures it can influence, which it merely observes, and which require action from your internal teams.

    For AI visibility reporting, preserve the exact observation context. Record the platform, prompt or query set, language, location, account state where relevant, collection method, and capture date. Treat an isolated answer as an observation, not a trend. Any claimed improvement should be accompanied by a repeatable method and a clear explanation of its relationship to qualified traffic or business activity.

    Keep governance and exit usable

    Your contract and operating plan should also cover:

    • Who approves financial, product, comparative, performance, and customer claims.
    • How credentials, customer data, analytics data, advertising data, and confidential materials may be accessed and stored.
    • Whether subcontractors or external AI tools can receive your information.
    • Ownership of accounts, domains, analytics properties, creative files, content, research materials, source files, schema, code, dashboards, audiences, and campaign history.
    • Whether core systems and accounts remain client-controlled throughout the engagement.
    • How conflicts of interest involving adjacent products or direct competitors are disclosed and handled.
    • How work, records, access, and institutional knowledge transfer when the engagement ends.

    Unclear ownership and data terms can create financial, legal, and operational exposure when you change agencies. Have qualified counsel and the appropriate privacy, security, and compliance owners review the provisions that govern claims, data handling, intellectual property, indemnity, termination, and transition. Familiarity with fintech marketing does not make an agency the final authority on your obligations.

    Your next move is not to book more introductory calls. Draft the mandate, turn the evidence categories into a scorecard, and send the same requirements to every credible candidate. The right fintech marketing agency should become easier to identify as the questions get more specific – not harder.

    References


  • Positionless Marketing: A Practical Operating Model

    Positionless Marketing: A Practical Operating Model

    Your team spots a high-intent query, a change in customer behavior or a retention risk. Then the signal starts a tour of the org chart. An analyst defines the audience, a strategist writes the brief, a creator develops the message, a specialist reviews it, operations builds it and a leader approves it. Every person may work quickly, yet the customer moment expires in the queues.

    This is where positionless marketing earns its keep. It gives a value-focused team the skills, data, tools and authority to carry work from insight through activation and measurement. You gain speed because the work stops changing owners at every stage, not merely because AI produces a draft faster. Done well, the model combines autonomy with explicit outcomes, decision rights and controls.

    Positionless marketing changes the workflow, not the need for expertise

    Positionless marketing is an operating model in which marketers can work across traditional boundaries to deliver a customer or business outcome. The team can find an insight, create an appropriate response, activate it and learn from the result without automatically handing each step to another department.

    It is not a plan to erase job titles, make everyone equally good at everything or remove specialist review. Deep expertise still matters in areas such as analytics, brand, privacy, development, accessibility, paid media and structured data. What changes is the way that expertise enters the workflow. Specialists define standards, create approved paths and handle genuine exceptions. They do not need to become a queue for every routine decision.

    Make the unit of work an outcome

    The practical shift is from organizing around channel deliverables to organizing around value. That requires a more demanding brief. A team should not exist merely to send campaigns, publish pages or generate leads. It should own a change that matters to the customer and the business.

    • Replace publish more content with answer a defined set of high-intent customer questions and improve qualified progression.
    • Replace run retention campaigns with reduce the delay between a meaningful customer signal and a relevant response.
    • Replace implement an AI platform with help marketers move safely from insight to activation without avoidable dependencies.
    • Replace improve personalization with increase a defined customer behavior while respecting consent, contact and brand rules.

    The distinction matters because a team cannot make sound independent decisions when success is vague. If the objective is more activity, AI will help produce more activity. If the objective is customer value, the team can decide whether a page update, lifecycle message, offer, experiment or no action at all is the best response.

    A useful test is simple: ask whether the team can state the customer, the relevant moment, the desired behavior, the business value and the constraint it must not violate. If those elements are unclear, the team is not ready for broader autonomy. Clarify the outcome before changing the org chart or buying another tool.

    Find the handoff tax before you redesign the team

    A glowing customer signal moves through a long sequence of separated workstations, review gates, and waiting trays beside an hourglass.

    Do not map the ideal process described in a policy deck. Take a recently completed campaign, content update or customer journey and reconstruct what actually happened. Begin when the signal first became actionable and end when the response went live and could be measured.

    For every stage, record who did the work, who approved it, which system they used, when the work arrived, when active work began, when it ended and why it moved elsewhere. Include rework loops. A stage that takes little effort can still create a large delay when it sits in another team’s queue.

    Classify every dependency

    Ask the same question at each handoff: was this dependency required by risk, required by scarce expertise or inherited from historical ownership? That classification tells you what to change.

    • Risk-required: Keep the control, but define exactly what triggers it. A novel data use may need privacy review; a routine segment built from an approved definition may not.
    • Expertise-required: Give the value team a reusable template, training or embedded specialist. Reserve central experts for work that truly needs their depth.
    • Ownership-required: Challenge it. If a trained marketer could safely complete the task with the right permission, the handoff is a candidate for removal.
    • Technology-created: Connect the systems, standardize the definition or remove the duplicate entry. Do not institutionalize a manual workaround without examining the underlying separation.

    Watch for recognizable symptoms: audience definitions rebuilt in several tools, marketers exporting data before they can use it, tickets raised for routine changes, approvals based on seniority rather than risk, reports that stop at channel activity and work that has no accountable owner after launch. These are operating-model problems even when they appear inside software.

    Caesars Entertainment provides a useful illustration of the mechanism. Marketers previously assembled targeting lists manually, coordinated work across disconnected systems and waited on other teams. After data, orchestration and execution were brought together and marketers could operate the workflow, reported campaign execution time fell from five days to five minutes. That company-specific result is not a universal benchmark. The transferable lesson is that faster content generation alone would not have removed the waiting, duplicate work and access dependencies.

    Create a workflow card before proposing a solution

    Summarize the diagnosis on a compact workflow card. Include the value outcome, triggering signal, intended audience, action, accountable owner, required capabilities, system access, current handoffs, primary measure, guardrails and escalation conditions. This prevents a familiar mistake: treating a visible tool limitation while leaving unclear objectives and slow decisions untouched.

    Build a pilot around a bounded customer outcome

    A company-wide positionless transformation is difficult to learn from because too many variables change at once. Start with a bounded value stream where the team can observe the signal, take a meaningful action and measure the result. The work should matter enough to justify change but be contained enough that the organization can define safe decision rights.

    A suitable pilot has a recurring workflow, a retrievable baseline, an identifiable customer context and several avoidable handoffs. It also gives the team ownership of enough of the chain to affect the outcome. Renaming a campaign group while every decision remains outside the group is not a pilot of positionless marketing.

    For an SEO, AEO or GEO team, a pilot might focus on a defined cluster of high-intent buyer questions. The team could own demand and audience signals, evidence collection, content creation, on-page optimization, approved JSON-LD, publication, distribution, measurement and refresh decisions. Structured data must still describe facts present on the page, and no markup should be treated as a guarantee of search or AI visibility. The operating advantage comes from letting the team complete approved work without opening a new queue for every field change.

    Write an outcome contract

    Before the pilot starts, write a short contract that makes autonomy testable. It should specify:

    • Customer context: The audience, behavior or moment the team is responsible for.
    • Desired change: The customer action and business value the work is intended to influence.
    • Primary measure: The outcome used to judge value, such as purchase, retention, qualified progression, customer lifetime value or return on investment.
    • Operational measure: The delay from an actionable signal to a live response, including queue time rather than only active production time.
    • Guardrails: The quality, brand, privacy, accessibility, contact, budget and data rules the team cannot cross.
    • Decision scope: The actions the team can take without additional approval.
    • Escalation conditions: The exceptions that require a named specialist or leader, along with who makes the final decision.

    Do not let activity metrics substitute for the outcome. Pages published, variants created and campaigns launched can help explain capacity, but they do not establish value. Pair the primary outcome with cycle time, avoidable handoffs, rework and guardrail performance. Capture the same measures before the pilot so the team can compare the new workflow with its own baseline.

    Build around capabilities, not miniature silos

    The pilot needs insight, creative, activation, measurement and governance capabilities. Those are accountabilities, not compulsory departments inside the team. A person may cover several capabilities, and a specialist may be embedded or available through a defined exception path. What matters is that every accountability has a name and no stage disappears into collective ownership.

    1. State the outcome and establish the current baseline.
    2. Map the capabilities, system permissions and knowledge required to own the workflow.
    3. Publish the team’s decision rights, guardrails and escalation path.
    4. Connect the minimum data, creation, activation and measurement flow needed for the pilot.
    5. Run the real workflow and log every pause, external dependency, rework loop and exception.
    6. Review customer value, speed, quality and resource use before expanding the model.

    Scale only what the evidence supports. A faster workflow that harms outcome quality or repeatedly violates controls has not succeeded. A team that improves the outcome but still waits for the same routine approvals has found value without yet achieving the operating-model change.

    Give the team autonomy through explicit guardrails

    Three marketers operate a compact campaign workspace inside a luminous boundary marked by safety rails, checkpoints, and organized resources.

    Autonomy is not the absence of oversight. It is a decision system that tells trained people what they may do, which standards apply and when the risk changes enough to require help. Without that clarity, cautious marketers keep asking permission while aggressive marketers make inconsistent choices.

    Convert broad policies into operational rules. The team should be able to determine whether an action is routine or exceptional without interpreting leadership intent from scratch.

    Work areaThe team can proceed whenSpecialist review is triggered when
    Audience and personalizationThe team uses approved data, definitions, consent rules and contact policies.The action introduces a new data purpose, sensitive segment or customer-contact rule.
    Content, SEO, AEO and GEOClaims are supported, edits follow approved standards and structured data matches visible page facts.The work adds an unsupported or regulated claim, unverified entity fact, custom code or material policy exception.
    Campaign orchestrationThe audience, channel, frequency, offer and budget remain inside agreed limits.The action exceeds those limits, creates material financial exposure or conflicts with another customer journey.
    ExperimentsThe change is reversible, its primary measure is defined and exposure follows approved rules.The experience is difficult to reverse, affects a protected area or conflicts with a standing commitment.
    Platforms and data movementThe workflow uses existing integrations, permissions and approved destinations.It requires a new integration, export, permission scope or external data destination.

    The precise entries will differ by business. The important design choice is separating routine work from exceptions. Central specialists should own standards, reusable templates, capability development and difficult cases. The value team should own decisions inside the approved path.

    Use technology to remove distance between signal and action

    The technology test is not how many AI features a platform offers. Ask whether the team can move from a trusted signal to an appropriate action and then measure it without manual exports, duplicate definitions or avoidable tickets.

    The minimum flow usually needs reliable data, shared audience and content definitions, creation tools, orchestration or publishing, measurement, permissions and an audit trail. It can live in one platform or in well-integrated tools. A nominally unified stack still fails if marketers cannot access it, definitions disagree or activation remains controlled by an unrelated queue.

    AI can compress research, analysis, drafting, variation and orchestration tasks. It does not resolve an unclear objective or decide which risk the business is willing to accept. Give the team approved inputs, verification requirements, data-handling rules and a record of what was generated or changed. Train people on the complete workflow, including exception scenarios, rather than limiting training to a product demonstration.

    Keep the model from turning into old silos with new labels

    The model will drift back toward assembly-line marketing unless leaders change how work is funded, reviewed and rewarded. A new team name cannot overcome objectives, permissions and incentives that still reinforce functional ownership.

    • Outcome fog: The team reports launches and assets because no customer or business result was defined. Correct it by making the outcome contract the basis of prioritization and review.
    • Phantom autonomy: Leaders encourage initiative but retain routine approvals. Correct it by publishing decision rights and measuring how much work still leaves the team.
    • Silo-preserving leadership: Functional leaders optimize their own queue, budget or platform even when the value stream suffers. Correct it by assigning an accountable value owner and resolving conflicts against the shared outcome.
    • Accountability by committee: Everyone contributes, but nobody owns the result after activation. Correct it by naming who answers for the outcome, who owns each control and who decides exceptions.
    • A stagnant learning culture: People avoid new authority because bounded mistakes are punished or because old processes feel safer. Correct it by distinguishing a compliant experiment that underperforms from a guardrail breach.
    • Disconnected technology: New AI tools create another work surface while data and execution remain separate. Correct it by evaluating the end-to-end flow, not feature adoption in isolation.

    Use a scorecard that exposes the operating model

    Review the pilot against its own baseline. Keep the scorecard small enough that every measure affects a decision. It should show the primary customer or business outcome, time from signal to live action, time spent waiting versus doing, avoidable handoffs, rework, resource use and guardrail failures. If value improves but waiting does not, investigate the remaining dependencies. If speed improves but quality deteriorates, tighten the path before expanding access.

    Key takeaways

    • Positionless marketing organizes work around customer and business value rather than channel deliverables or job-title boundaries.
    • It removes avoidable queues, not expertise, accountability or risk controls.
    • The best starting point is a bounded workflow with a measurable outcome and visible handoffs.
    • Teams need system access, cross-functional capabilities, explicit decision rights and a named escalation path.
    • Measure the outcome alongside signal-to-action time, waiting, rework, resource use and guardrail performance.
    • Scale the model only when it improves value without weakening quality or control.

    Your next move does not need to be a reorganization announcement. Take the last important campaign or content update and mark every place where it waited, changed owners or had to be rebuilt. Find the longest avoidable queue. Then change the decision rule, permission, capability or system connection that created it. That gives you a real positionless marketing pilot and evidence for what should change next.

    References

  • AI Marketing Governance: Scale Creative Without Losing Trust

    AI Marketing Governance: Scale Creative Without Losing Trust

    You have a campaign due, the platform wants more assets than your team can shoot, and an AI tool can produce the missing scenes in minutes. The production problem looks solved. The harder question arrives at approval: does the result still represent the product, the customer and the brand truthfully?

    You do not need to choose between using AI and being authentic. You need a governance system that distinguishes harmless assistance from consequential manipulation, preserves evidence for every claim and stops questionable work before speed turns it into scale.

    Key takeaways

    • Authenticity is not the absence of AI. It is the absence of a misleading gap between what your marketing depicts and what a reasonable customer would believe.
    • Govern the output and its likely interpretation, not the name of the tool that produced it.
    • Give every AI-assisted asset a source record, a named approver and a defined withdrawal path before publication.
    • Disclosure can explain how an asset was made, but it cannot make a false product claim, invented testimonial or nonexistent result acceptable.
    • Use the same approved facts across ads, landing pages, product feeds, public relations, structured data and answer-engine content. Contradictory claims weaken both customer trust and machine-readable credibility.

    Authenticity is a truth boundary, not a production method

    A manually produced campaign can be deceptive. An AI-assisted campaign can be accurate. The relevant distinction is not human versus machine; it is faithful representation versus manufactured belief.

    That distinction matters because AI can now support a wide range of creative operations, including background removal, lifestyle-scene generation, synthetic people and rapid asset variation. The resulting production capacity is useful, but technical permission is not the same as brand permission. Your policy has to decide what the audience may reasonably infer from the finished asset.

    Use four questions at the creative brief, review and approval stages:

    1. What will the audience think is real? Identify the likely interpretation, not merely the literal elements on screen. A person may understand that a decorative background is illustrative while assuming a product demonstration, testimonial or before-and-after image records a real event.
    2. Does the synthetic element affect the decision? Color accuracy, dimensions, included features, product condition, customer identity, quoted experience and demonstrated outcomes can all influence a purchase or trust decision. Treat those elements as material.
    3. Can the implied claim be substantiated? You should be able to trace a factual statement or visual implication to an approved product record, documented result or other internal evidence. If the evidence cannot be found, the asset is not ready.
    4. Would knowledge of the AI intervention change the audience’s judgment? If the answer is yes, redesign the asset, disclose the intervention clearly or do both. Do not hide a consequential transformation behind a broad statement that AI was used somewhere in production.

    A synthetic background behind an unchanged product may create little expectation risk. A synthetic person presented in a way that resembles a customer, employee or expert creates much more. A generated product feature that does not exist crosses the truth boundary entirely.

    Disclosure belongs after this truth test, not in place of it. A label can tell someone that an image is simulated. It cannot repair an inaccurate price, fake endorsement, invented review, altered package size or performance claim that your evidence does not support. When the underlying claim could create compliance or legal exposure, pause publication and route it to the appropriate qualified reviewer. A creative approval is not a substitute for legal review.

    Use a four-level integrity ladder for AI-assisted work

    Four ascending studio platforms show increasingly consequential forms of AI-assisted product imagery connected to a real product by a golden thread.

    A practical policy needs more than a general instruction to use AI responsibly. A four-level brand integrity hierarchy gives marketers, agencies and approvers a shared way to classify work before debating individual assets.

    Integrity levelTypical outputDefault decisionRequired control
    AssistanceResizing, cropping, cleanup, formatting or copy variation that preserves the approved meaningAllowed within documented brand rulesRetain the original and confirm that facts, qualifications and visual product attributes did not change
    AdaptationBackground replacement, contextual scenes, localization or audience variants built around a real product or approved claimAllowed with reviewRecord what was synthetic, verify the product representation and decide whether the context needs disclosure
    SynthesisSynthetic people, realistic events, demonstrations or scenes that an audience could interpret as documentary evidenceConditional and escalatedRequire an accountable approver, a documented disclosure decision, substantiation for every implication and confirmation that no real person’s identity is being misrepresented
    FabricationInvented testimonials, nonexistent features, unsupported outcomes, fake certifications or materially altered productsProhibitedDo not publish; correct the brief or obtain valid evidence for a truthful alternative

    Classify the finished output, not the software. The same generator could perform low-risk cleanup in one workflow and create an unacceptable customer simulation in another. Tool-based rules age quickly and invite loopholes; output-based rules remain understandable when platforms change their features.

    Context can also move an asset up the ladder. Replacing the background behind a product is usually adaptation. It becomes more consequential if the new setting implies that the product is certified for a particular environment, fits a space it does not fit or has a capability it does not have. Likewise, a synthetic human used as decorative illustration differs from one presented beside testimonial language that implies a genuine experience.

    Write examples from your own campaigns beside each level. Include one clearly allowed example, one conditional example and one prohibited example for the channels your team actually uses. Those precedents will resolve ordinary decisions faster than an abstract ethics statement.

    Turn the policy into a publishing gate

    Reviewers inspect a marketing image, a physical product and supporting papers as creative assets pass through a transparent publishing checkpoint.

    A governance document does not protect the brand if approval still happens in chat threads, source files disappear and nobody can identify who accepted the risk. The control has to sit inside the publishing workflow.

    Your operating policy should define:

    • Scope: the channels, teams, contractors, agencies and asset types covered by the policy.
    • Allowed uses: transformations that can proceed under standard review.
    • Conditional uses: outputs that require disclosure, specialist review or approval from a more accountable role.
    • Prohibited uses: transformations that cannot be published even when labeled as AI-generated.
    • Evidence requirements: the records that must support factual, comparative, visual and testimonial claims.
    • Disclosure rules: when a disclosure is required, where it must appear and who approves its wording and placement.
    • Responsibility: who creates, verifies, approves, publishes, monitors and withdraws an asset.
    • Exception handling: who can authorize an exception, what evidence is required and when that decision must be revisited.

    Move each asset through the same evidence path

    1. Set the truth boundary in the brief. List the product attributes, claims, qualifications and visual details that cannot change. State what may be synthesized and what the asset must not imply.
    2. Assemble an approved reference pack. Give the creator the current product images, specifications, brand terminology, claim substantiation and required qualifications. Do not make the reviewer reconstruct the ground truth after generation.
    3. Create within the assigned integrity level. Record the tool or production path, the original materials and the meaningful transformations. You do not need to archive every inconsequential interaction, but you do need enough provenance to reproduce the decision and investigate a problem.
    4. Verify the rendered output. Check the actual sizes, crops, overlays, captions, product details and landing-page destination that the audience will see. A correct master file can become misleading when a placement removes a qualification or crops out context.
    5. Approve the claim and the presentation separately. One check asks whether the underlying statement is supported. The other asks what a reasonable person will infer from the combination of words, images and placement. Passing one does not guarantee the other.
    6. Publish with a withdrawal record. Log the channels and destinations where the asset appears. If a claim changes or an error is found, the team should know where to remove or replace every affected version.

    The asset record can be compact. Capture the campaign and channel, source materials, meaningful AI transformations, claims used, disclosure decision, reviewer, approval state and publication locations. What matters is that someone other than the creator can understand why the asset was approved.

    Human review is not a control by itself. The reviewer needs access to the evidence, clear authority to stop publication and enough time to inspect the final placement. A person who can only click approve is part of the production sequence, not an effective safeguard.

    Paid media needs particular care because asset demand, automated combinations and placement variation can multiply one error quickly. Product imagery deserves a hard verification gate: visual inaccuracies can produce disapprovals or account risk in Merchant Center. Compare the rendered product with the approved reference, including packaging, included components, proportions, color and visible features. If the generated scene obscures that comparison, use a more faithful asset.

    Exceptions should be visible and temporary. Record the business reason, risk owner, supporting evidence and condition that ends the exception. The person requesting an exception should not be its sole approver. Otherwise, deadlines will quietly rewrite your policy one campaign at a time.

    Connect creative governance to SEO, AEO, GEO and PR

    Authenticity problems rarely stay inside the ad account. A generated claim can reach a landing page, product feed, public-relations pitch, social caption, FAQ and structured-data field. Each copy may look defensible in isolation while the combined public record becomes contradictory.

    Build a claim register as the shared layer beneath those channels. For each meaningful claim, record:

    • the canonical wording and any required qualification;
    • the internal evidence or approved public page that supports it;
    • the product, market and context in which it applies;
    • the accountable owner;
    • the channels where it may be used;
    • the disclosure or presentation restrictions attached to it;
    • the condition that should trigger review, correction or withdrawal; and
    • the structured-data properties, feed fields and content components that repeat it.

    This register gives your teams one approved truth rather than several channel-specific versions. Copywriters know which qualifications must survive a short format. PPC teams know which visual implications require evidence. SEO and GEO teams know which public pages should explain and substantiate the claim. Schema implementers know which statements are safe to mark up.

    Structured data should describe visible, supported content. It does not validate a claim merely because the markup is syntactically correct. If the page, product feed and JSON-LD disagree about a product attribute, fix the underlying content system instead of choosing the version most likely to attract a machine.

    Citation readiness also belongs in the governance process. Citations in AI-generated answers can contribute to credibility, and understanding how a brand appears through publicly available information can inform PR decisions. That makes the quality of your supporting pages important beyond conventional rankings.

    A citation-ready page should make the supported claim easy to identify, define its scope and keep the qualification beside it. It should also use consistent product and organization names, connect the claim to the relevant entity and avoid implying that a synthetic scene is proof. A citation can carry an unsupported statement farther; it cannot convert that statement into evidence.

    Monitor governance signals that reveal process failure rather than treating campaign performance as proof that the process worked. Useful signals include assets published without complete provenance, unresolved evidence gaps, exceptions still open, corrections caused by product mismatch, platform disapprovals associated with altered creative and the time required to withdraw a faulty claim across channels.

    Audit what is already live

    Start with a representative set of active ads, landing pages, product feeds, social assets, PR materials and structured data. Classify each AI-assisted element on the integrity ladder. Then trace every consequential claim backward to its evidence and forward to every place it appears.

    Prioritize assets with realistic people, demonstrations, testimonials, product alterations or purchase-critical details. If you cannot identify the source fact, the approving person or all publication locations, you have found a governance gap. Pause the highest-risk asset, establish the missing record and use that case to write the first concrete rule in your policy.

    For your next campaign, define the prohibited transformations in the brief, assign the integrity level before production and name the approver before generation begins. Once those decisions become routine, AI can increase creative capacity without multiplying ambiguity about what your audience is being asked to believe.

    References

  • Marketing Data Doppelgangers: An Identity Confidence Playbook

    Marketing Data Doppelgangers: An Identity Confidence Playbook

    Your CRM has identified an apparent ideal customer. This person opens almost every email, checks products repeatedly, moves between devices, and redeems offers with remarkable timing. The activity is real enough to enter your dashboards, but it may not belong to one person or represent the intent your models assign to it.

    Before you increase bids, trigger a high-value nurture sequence, or extend another promotion, you need to know whether you are acting on a coherent customer or a marketing data doppelganger. The practical fix is not another round of duplicate removal. It is an identity-confidence system that separates observed activity from actor, intent, and customer identity.

    What your apparently complete customer profile may be hiding

    A marketing data doppelganger is a customer profile that looks internally valid but does not map cleanly to one actor. Its email may be deliverable. Its clicks may have occurred. Its purchases may be legitimate. The error appears when your systems treat all those events as evidence about the same individual.

    This problem has two main identity patterns:

    • Convergence: Multiple people or systems are folded into one profile. A shared login, forwarded corporate alias, recycled email address, AI assistant, and human account holder can all contribute activity that appears to come from one customer.
    • Fragmentation: One customer is distributed across multiple profiles. Alternate email addresses, several devices, subscription accounts, loyalty records, and repeated new-customer registrations can make one person look like several unrelated prospects.

    Delegated activity complicates both patterns. AI assistants can summarize emails, compare products, monitor prices, complete forms, and sometimes make purchases. That activity is not automatically fraudulent or irrelevant. It is evidence that software acted, possibly with a customer’s authorization. It is not automatically evidence that a person read a message, evaluated an offer, or developed stronger purchase intent.

    Use three separate questions whenever a profile drives a decision:

    • Identity: Which customer, account, household, or organization do we believe this activity belongs to?
    • Actor: Was the event produced by a person, an authorized assistant, an email client, an automated workflow, a shared user, or an unknown process?
    • Intent: What does the event actually establish: message delivery, monitoring, consideration, authorization, or a completed commercial outcome?

    Those answers are not interchangeable. A deliverable email establishes that a destination can receive mail; it does not establish that one enduring person controls it. A completed order establishes a commercial outcome; it does not prove that the payer, shopper, recipient, and account user were the same person.

    Observed patternPossible doppelganger mechanismDecision at risk
    Frequent opens with little subsequent activityEmail prefetching or AI summarizationLead scores, send frequency, and engagement segments
    Repeated product checks at unusually precise intervalsPrice-monitoring or shopping automationRetargeting intensity and inferred purchase urgency
    Contrasting preferences under one addressShared credentials, a forwarding alias, or a recycled addressPersonalization and customer lifetime analysis
    Several apparently new profiles with related account behaviorOne customer using alternate identifiersAcquisition reporting and promotion eligibility
    A customer journey spread across disconnected devices or accountsIdentity fragmentationAttribution, suppression, retention, and forecasting

    The important correction is simple: valid events do not guarantee a valid person-level interpretation. Your job is to preserve what was observed while reducing confidence in conclusions the evidence cannot support.

    Audit the marketing decision before cleaning the database

    A database-wide identity project can become expensive and abstract before it changes a single campaign. Start with one consequential decision: a lead score, promotion rule, churn prediction, retargeting audience, acquisition report, or budget forecast. Then work backward to the identity assumptions that make the decision possible.

    1. Write the claim behind the decision. A high-engagement segment may depend on the claim that repeated opens and product views represent increasing interest from one person. A new-customer discount may depend on the claim that one profile represents one previously unseen customer. State that claim plainly.
    2. List the events that support the claim. Separate email opens, clicks, page views, form submissions, account activity, promotion redemptions, and transactions. Do not collapse them into a single engagement total during the audit.
    3. Recover event provenance. For each event, retain the event time, collection source, profile and account identifiers, campaign, session or device identifier where permitted, related transaction or promotion, automation marker, and downstream outcome. A missing provenance field is an audit finding, not permission to assume a human acted.
    4. Classify the likely actor. Use practical states such as human-confirmed, delegated or agent-assisted, platform-generated, shared or ambiguous, and unknown. Preserve unknown as a real category. Treating unknown as human simply hides the uncertainty.
    5. Look for convergence and fragmentation. Search for abrupt cross-device activity, mutually inconsistent preferences, shared or reassigned contact points, automated monitoring patterns, and apparently new profiles connected to established activity. Each pattern is a reason to investigate, not proof of abuse.
    6. Run a counterfactual version of the decision. Recalculate the segment, score, attribution result, or forecast after excluding events with uncertain actor provenance. Then consolidate likely fragments where you have defensible evidence. If the decision changes materially, it depends on identity assumptions that need to be exposed.
    7. Record the operational consequence. Note whether the uncertainty can waste media, increase message frequency, distort attribution, issue duplicate benefits, suppress a legitimate customer, or create unnecessary checkout friction. This converts identity quality from a data-cleaning concern into a prioritized business risk.

    Email engagement deserves early attention because prefetching and automated summarization can create activity that resembles high engagement. An open can remain useful as a delivery or processing event, but it should not carry the same intent weight as an explicit response or a coherent downstream journey.

    Do not delete ambiguous events. Preserve the raw observation and change its interpretation. Deletion destroys evidence you may need for attribution, troubleshooting, or future validation. Classification lets you ask better questions without pretending uncertain data never existed.

    Replace the golden record with an evidence-backed confidence record

    An anonymous customer figure surrounded by devices and transaction objects, with solid and faint connection lines indicating different levels of identity confidence.

    The traditional golden record promises one definitive profile assembled from every available identifier. That model becomes brittle when one person can produce several identities and several actors can produce events under one identity. A larger merged profile can look more complete while becoming less coherent.

    Use a confidence record instead. It should not merely declare that two records match. It should explain why your organization currently considers a profile stable enough for a particular use.

    Evaluate identity confidence across these dimensions:

    • Identifier continuity: Are the account and contact identifiers stable over time, or do they show signs of reassignment, sharing, or frequent substitution?
    • Behavioral coherence: Can the activity plausibly belong to the same customer context, or does it contain conflicting needs, abrupt channel changes, and overlapping journeys?
    • Actor provenance: Can you distinguish explicit customer actions from platform processing, delegated agent activity, autofill, and unknown automation?
    • Commercial continuity: Do account history, offer use, and completed outcomes support the same customer relationship, or do they reveal fragmentation or convergence?
    • Ambiguity burden: How much of the profile’s apparent value depends on events whose actor or meaning cannot be established?

    A practical profile record can store an identity state, actor state, confidence band, supporting evidence, contradictory evidence, last validation trigger, and permitted uses. For example, the identity state might be stable, fragmented, composite, or unknown. The actor state might be human, delegated, platform-generated, shared, mixed, or unknown.

    Use confidence bands with reason codes before reaching for a precise score. A numerical score can create false certainty if nobody can explain what moved it. A band such as high, conditional, or low is useful when it is attached to evidence and an allowed decision:

    • High confidence: The available evidence is coherent and sufficiently attributable for the named use. This does not mean every event came directly from a human.
    • Conditional confidence: The profile contains stable evidence, but shared, delegated, or fragmented activity limits some uses. It may be suitable for service communication while remaining unsuitable as clean training data for an intent model.
    • Low confidence: The profile depends heavily on weak identifiers, unknown event provenance, or contradictory activity. Use it cautiously and avoid expensive personalization or irreversible risk decisions based on it alone.

    Confidence must be use-specific. The evidence required to send a general newsletter is not the same as the evidence required to grant a one-time benefit, block an order, label a person as a high-value customer, or train a predictive model. A universal identity score hides those differences.

    Revalidate when meaningful evidence changes, not only during a periodic cleanup. Useful triggers include a new account relationship, a sudden shift in device or channel behavior, evidence of a shared or recycled contact point, new agent-assisted activity, conflicting transactions, and a promotion or risk event. Continuous validation is necessary because identity now behaves like an evolving relationship rather than a static match.

    Identity confidence is not a reason to collect every possible identifier. Use permitted data with a clear purpose, retain provenance, and avoid treating invasive surveillance as a substitute for coherent evidence. Better validation should make your interpretation more disciplined, not make your collection indiscriminate.

    Change campaign, attribution, and risk decisions at the same time

    Overlapping customer and device signals pass through a confidence gate before branching toward campaign, attribution, and risk decision symbols.

    An identity audit has little value if every downstream system continues treating all events as equal. Carry the confidence state into activation, reporting, modeling, and revenue protection.

    Separate activity, human intent, and identity confidence

    Replace a single engagement score with distinct measures. Observed activity records what happened. Intent classification describes what the event can reasonably imply. Identity confidence describes how safely the behavior can be attached to the profile.

    • Treat prefetches and automated message processing as delivery or machine-processing evidence, not direct proof of interest.
    • Classify agent-based comparison and price monitoring as delegated activity. It may represent customer interest, but it should remain distinguishable from a human browsing session.
    • Give coherent downstream actions more decision weight than isolated high-volume signals, while retaining uncertainty about who performed them.
    • Prevent low-confidence profiles from automatically entering expensive personalization, aggressive retargeting, or high-priority sales queues.

    This structure lets a campaign acknowledge useful agent activity without pretending that every machine event is a human signal.

    Publish attribution with an uncertainty view

    Do not hide identity ambiguity inside a probabilistic attribution model. Browser privacy changes and cross-device behavior already make attribution more dependent on inferred relationships. Adding composite profiles can make a precise report less trustworthy, even when the arithmetic is correct.

    Show the reported result beside an identity-quality view. Track the share of events with unknown actors, conversions attached to composite or fragmented profiles, and the sensitivity of channel credit when automated events are removed. You do not need to invent a confidence-adjusted revenue figure if your evidence cannot support one. Showing the uncertainty is more useful than concealing it behind a new calculation.

    Keep unstable identities from becoming model ground truth

    A model trained to equate automated opens with customer interest will seek more people who produce the same distorted pattern. Campaigns then generate additional machine activity, which returns as apparent proof that the model was right. This is how an identity problem becomes a performance feedback loop.

    Attach identity and actor labels before training. Depending on the model and decision, filter unstable profiles, reduce their training weight, or retain them as a separately labeled population. Evaluate performance by confidence band as well as in aggregate. If a model performs well only where identity is ambiguous, inspect what it has actually learned before expanding its use.

    Distinguish delegated assistance from promotional abuse

    An AI assistant acting for a customer is not, by itself, evidence of fraud. Shared accounts are not automatically abusive either. Blocking every ambiguous profile adds friction for legitimate customers, while permissive rules can allow one person to appear repeatedly as a new customer.

    Escalate controls when low identity confidence coincides with an economic action and contradictory account history. Do not make an agent marker the sole reason for a block. Use proportionate checks, preserve the reason for the decision, and provide a review path when a legitimate customer may have been caught by the control.

    Give each team an explicit responsibility

    Identity confidence fails when it belongs only to the data team. Assign ownership at the point where interpretation becomes action:

    • Marketing operations preserves event provenance and exposes confidence fields to campaign tools.
    • Analytics reports identity uncertainty and tests how sensitive conclusions are to ambiguous events.
    • Lifecycle and sales teams define which confidence bands may enter each journey or priority queue.
    • Model owners document which identity states are accepted as labels and evaluate performance across those states.
    • Risk and commerce teams define when an ambiguous identity warrants additional validation rather than automatic denial.

    Begin with the decision that has the clearest cost when identity is wrong. Rewrite its event rules, add actor and confidence fields, rerun the decision under alternative inclusion rules, and document what changes. Once that loop works, extend the same method to the next campaign, model, or control. You will improve trust faster by validating consequential decisions one at a time than by declaring the entire customer database clean.

    Key takeaways

    • A marketing data doppelganger is a coherent-looking profile whose events do not reliably represent one actor or one customer’s intent.
    • The problem includes both convergence, where several actors appear as one profile, and fragmentation, where one customer appears as several profiles.
    • Preserve the distinction between identity, actor, and intent. A valid event does not make every person-level inference valid.
    • Audit one costly decision first, recover event provenance, classify uncertain actors, and rerun the decision without ambiguous signals.
    • Replace binary identity matches with explainable, use-specific confidence bands supported by evidence and contradiction records.
    • Carry identity confidence into segmentation, attribution, model training, promotion controls, and reporting so the same uncertainty is not lost downstream.

    Your next step is to choose one segment, score, or promotion rule that would hurt if the customer identity were wrong. Find the weakest event it relies on and make that uncertainty visible. That small change gives you a defensible starting point for rebuilding trust in the rest of your marketing data.

    References

  • Google Nano Banana 2: A Practical Workflow for Marketers

    Google Nano Banana 2: A Practical Workflow for Marketers

    You have a campaign brief, not an afternoon to spend rerolling images. The asset needs readable copy, stable people and products, multiple formats, and localized versions. Someone also needs to know exactly what changed between creative variants.

    Google Nano Banana 2 can carry more of that production workload, but only if you treat it as part of a controlled creative system. The useful shift is not simply better-looking output. It is the ability to move from a structured brief to a consistent family of assets with fewer compromises between speed, detail, text, and continuity.

    What Nano Banana 2 changes in an image workflow

    Nano Banana 2 is the informal name for Gemini 3.1 Flash Image. Google DeepMind has positioned it as a combination of Nano Banana Pro’s image intelligence and Gemini Flash’s faster generation. For a marketing team, that combination matters because image quality and iteration speed normally pull the workflow in opposite directions.

    The model’s improvements map to four practical jobs:

    • Knowledge-heavy visuals: Real-time web grounding can bring current context into infographics and data-oriented images. Treat that as assistance with generation, not proof that a visual is factually correct.
    • Images containing words: Improved text rendering and translation make social graphics, diagrams, promotional cards, and localized creative more viable. Every visible word still needs human proofreading.
    • Scenes that must remain recognizable: Stronger instruction adherence and subject consistency make it easier to preserve the same cast, objects, visual hierarchy, and art direction during revisions.
    • Assets for different placements: Supported output extends from 512px through 4K, so the same workflow can cover lightweight concepts and high-resolution deliverables.

    The documented consistency envelope reaches up to five characters and 14 objects in one workflow. Read that as an upper capability boundary, not a guarantee that a crowded scene will remain perfect. The closer your composition gets to the limit, the more deliberate your naming, placement, and review need to be.

    Key takeaways

    • Use Nano Banana 2 for repeatable asset families, not just isolated image generation.
    • Write prompts as production briefs with explicit priorities, subjects, composition, copy, and output requirements.
    • Approve one master image before generating formats, languages, or test variants.
    • Verify every word, number, label, and data point even when web grounding is involved.
    • Keep important page meaning in HTML and metadata rather than leaving it trapped inside an image.

    Turn the prompt into a production brief

    Visual reference tiles for a mug, customer, kitchen, colors, lighting, and image formats connect to a finished campaign image.

    Stronger instruction adherence is only useful when the instructions have a clear hierarchy. A loose collection of adjectives leaves the model to decide what matters. A production brief tells it what the asset must accomplish, what cannot change, and where it has room to interpret.

    1. Start with the asset’s job. Name the destination and the action the visual should support: a landing-page hero, an ad variant, a report cover, a diagram, or a localized social card. This gives the composition a reason to exist.
    2. Define the required subjects. List each person, product, interface, or meaningful object. Give recurring subjects short, stable labels so later instructions can refer to them without ambiguity.
    3. Specify spatial relationships. State what belongs in the foreground, where the main subject sits, which direction a person faces, and where clear space is required for external copy or controls.
    4. Describe the visual system. Set the palette, lighting, texture, level of realism, camera perspective, and overall mood. Use concrete visual properties rather than piling up subjective terms such as premium, bold, or modern.
    5. Supply text as exact copy. Separate the headline, labels, supporting text, and language. If a phrase must not be translated, say so. Do not bury critical wording inside a long paragraph of art direction.
    6. Name the output requirements. Include the intended aspect ratio, supported resolution, crop needs, and any areas that must remain uncluttered. Request 4K when the approved asset actually needs it, not by default for every concept.
    7. Declare the invariants. Say which identities, objects, colors, text, and layout relationships must remain unchanged across revisions.

    A reusable prompt pattern

    Goal: Create a 4K landscape hero image for a landing page promoting a search visibility report. Subjects: Show one analyst at a desk and one dashboard object displaying a clean line chart. Composition: Place the analyst and dashboard on the right, with the left third uncluttered for an HTML headline. Visual direction: Use deep navy, off-white, and restrained cyan accents, with soft directional lighting and realistic textures. Restrictions: Do not add logos, watermarks, interface labels, extra screens, or text inside the image. Continuity: Keep the analyst’s appearance, dashboard layout, palette, and lighting unchanged in later variants.

    This example deliberately reserves the headline for HTML. That is usually the cleaner choice for a web hero because the copy remains editable, selectable, responsive, and available to assistive technology. Use embedded text when the words are part of the artifact itself, such as a social card, diagram label, poster, or standalone ad creative.

    For an image that needs embedded copy, add a separate instruction such as On-image copy: Q3 Search Visibility Report. Then identify the exact location, hierarchy, and language. Keeping copy in its own instruction makes proofreading and localization easier.

    Follow-up prompts should be smaller than the original brief. Ask to change one controlled element while restating the invariants: replace the background environment, change the accent color, translate the approved copy, or adapt the crop while preserving the subjects. Rewriting the entire prompt for every revision invites unplanned changes.

    Build variants without losing control of the experiment

    Six campaign previews preserve the same coral running shoe and fictional athlete while changing backgrounds, lighting, props, and crops.

    Fast generation can create a false sense of progress. Twenty visually different outputs are not a useful test if the headline, palette, composition, subject, and offer all changed together. You will know which image performed better, but not why.

    Use a master-and-variant workflow instead:

    1. Generate a baseline. Produce the first complete interpretation of the brief before requesting alternatives.
    2. Review against the brief. Separate objective misses, such as incorrect text or a missing object, from subjective preferences, such as wanting warmer lighting.
    3. Correct the baseline. Do not build variants from an image that already violates the required composition, copy, or identity.
    4. Approve a master. Record the accepted prompt, output, invariants, language, and intended placement.
    5. Create one-variable variants. Change one meaningful family of attributes at a time, such as the background, focal framing, callout treatment, or color emphasis.
    6. Localize after visual approval. Preserve the master composition while changing the language-specific copy, then allow only the layout adjustments required by the translated text.

    Your review should use explicit gates rather than a general looks-good decision:

    • Brief compliance: Are all required subjects present, and are unwanted additions absent?
    • Continuity: Do recurring people, products, and objects remain recognizable across versions?
    • Copy: Does every character match the approved wording, including punctuation, capitalization, and product terms?
    • Factual content: Do chart labels, values, dates, maps, and explanatory elements match the information you intend to publish?
    • Visual integrity: Are faces, hands, object boundaries, reflections, lighting, and small details internally coherent?
    • Placement safety: Will important content survive the real crop, overlay, and responsive layout?
    • Delivery: Does the final file have the resolution and aspect ratio required by its actual destination?

    Web grounding does not remove the factual review gate. It can help the model reason about the requested subject, but it cannot approve a statistic, establish which date your campaign should use, or decide whether a generated chart supports your claim. Keep the underlying facts in a separate, human-reviewed content sheet and compare the rendered visual against it.

    The same discipline applies to translation. Generate the localized version, copy the visible wording out of the image, and compare it with approved language line by line. Check line breaks and hierarchy as well as meaning; a correct translation can still become unreadable when it is forced into the original layout.

    Nano Banana 2 is integrated into Google Ads as well as the broader Gemini ecosystem, which makes rapid campaign variation an obvious use case. Keep the creative test interpretable: hold the audience, offer, and measurement setup steady when the purpose is to learn whether a visual change affected performance.

    Finish the asset for SEO, AEO, and GEO

    A production-quality image is not automatically a search-ready asset. Image generation creates pixels. Your publishing workflow must connect those pixels to the page’s subject, the user’s task, and machine-readable context.

    Keep the meaning outside the pixels

    • Match the search intent. Use the image to clarify the answer, process, entity, comparison, or result the page is actually about. A polished but generic visual adds little retrieval value.
    • Write functional alt text. Describe the information or purpose the image contributes in its context. Do not paste the generation prompt or turn the attribute into a keyword list.
    • Use descriptive filenames. Name the finished asset for its actual subject and role rather than preserving a generator’s default filename.
    • Publish essential facts as HTML. If an infographic contains a process, statistic, or comparison that the reader needs, provide the same core information in nearby page text. Do not make people or search systems depend on reading pixels.
    • Add a useful caption when context is needed. A caption should explain why the visual matters, not merely repeat what it depicts.
    • Create delivery derivatives. Keep a high-resolution master, but serve a file sized and compressed for the placement. Sending a 4K image everywhere can add page weight without improving the reader’s experience.
    • Localize the surrounding context. When you translate text inside an image, update the filename, alt text, caption, nearby explanation, and linked destination for the same audience.

    Treat structured data as a record

    If your page’s structured data references the image, the markup should describe the asset that is visibly published at the live URL. Keep the image URL, dimensions, caption, creator information, and licensing information aligned with what you can substantiate. Do not manufacture metadata simply to fill properties.

    JSON-LD does not rescue a weak relationship between the visual and the page. The image, headline, body copy, captions, internal links, and structured data should all describe the same primary subject. That consistency gives search engines and answer systems a clearer entity-and-context relationship to interpret, although it cannot guarantee rankings, citations, or inclusion in an AI-generated response.

    This is also where subject consistency becomes strategically useful. Reusing a recognizable product, character, diagram language, or branded visual system across a related content cluster can make the collection feel coherent. Keep each asset specific to its page, however; duplicating one generic image across every URL does not explain what makes those pages different.

    Choose a pilot that exposes the model’s real value

    Do not judge Nano Banana 2 by asking it for a single decorative image. That tests whether it can produce an attractive picture, not whether it can improve your production system.

    Our rule of thumb is to choose a pilot that needs at least two of the model’s differentiating capabilities:

    • A recurring person, product, or object that must remain consistent.
    • Exact words or labels inside the visual.
    • Several controlled creative variants for a campaign.
    • Localization into more than one language.
    • A knowledge-heavy infographic or data visualization.
    • Outputs ranging from smaller concept images to a 4K master.

    A strong pilot might be a report launch that needs a hero image, a labeled social card, ad variants, and localized editions. One approved visual system can then be carried through each placement while the team measures generation time, correction cycles, consistency, proofreading effort, and final usability.

    Begin concepts at the smallest supported resolution that lets your team judge composition. Move to 4K after the direction is approved. This keeps reviewers focused on the idea before they spend time inspecting final-level detail.

    The model is available across Google Ads, the Gemini app, Search AI Mode, Lens, and other parts of Google’s ecosystem. That reach makes shared governance more important than platform-specific habits. Store the master brief, approved copy, invariants, final asset, localization decisions, and QA result together so the next person can reproduce the workflow.

    Pick one recurring campaign asset this week. Define its invariants, create one approved master, and generate a single controlled variant. If the model preserves the subject, copy, composition, and visual system through that cycle, you have evidence for expanding the workflow. If it does not, the QA record will show whether the problem came from the brief, the generation, or the review process.

    References


  • Profound’s $96M Series C: What AI Marketers Should Watch

    Profound’s $96M Series C: What AI Marketers Should Watch

    If you lead AI search, SEO, content, or marketing technology, Profound’s funding can create immediate pressure. Is the company now the category winner? Is your team late? Should you add another platform to your stack? The financing matters, but none of those conclusions follows automatically.

    Profound announced a $96 million Series C at a $1 billion valuation, led by Lightspeed Venture Partners with participation from Sequoia Capital, Kleiner Perkins, Evantic, Saga, and South Park Commons. For you, the useful question is what that event changes about AI marketing, vendor selection, and the way you measure visibility in generative answers.

    Read the round correctly before changing your strategy

    A funding round is evidence that investors were willing to finance a company on negotiated terms. It is not a product certification, an independent performance test, or proof that customers are receiving a positive return.

    The distinction matters because the headline contains several figures that are easy to misread. The $96 million is financing, not revenue. The $1 billion valuation is the value assigned to the company in the context of the transaction, not cash deposited into its accounts. Neither figure tells you how much customers spend, whether the business is profitable, how well its software performs, or how the new capital will be allocated.

    Series C also describes a financing stage, not a universal level of product maturity. It can support expansion after earlier growth, but the label does not guarantee stable data, complete model coverage, enterprise-ready controls, or a roadmap that matches your needs.

    • What the round establishes: Profound has attracted substantial private backing for an AI marketing platform.
    • What it reasonably signals: the participating investors see enough potential to finance further growth at the announced valuation.
    • What it does not establish: that Profound is the right platform for your use case, that AI visibility software has settled on a standard methodology, or that a large valuation predicts your results.

    That last point should shape your response. Do not rewrite your AI strategy around a financing headline. Use the event as a reason to update your assumptions, inspect the category, and ask vendors harder questions.

    Where fresh capital could change the AI marketing market

    Golden light branches from a central reservoir toward abstract product, infrastructure, expansion, and support structures, with some paths fading into mist.

    Capital gives Profound more options. It could fund product development, infrastructure, model and market coverage, integrations, hiring, customer support, or go-to-market expansion. Those are possibilities, not disclosed commitments. Treat them as items to verify through shipped capabilities, release records, service levels, and written commercial terms.

    The broader signal is that investors are willing to place significant capital behind the problem of marketing through AI-generated answers. That is relevant if you have been treating AI visibility as a temporary reporting experiment. It suggests that the category may attract more product development, sales activity, and competition. One transaction, however, does not establish the size of customer demand or prove that AI search has replaced conventional search.

    Your operating model should therefore connect AI visibility to the rest of search and content work instead of building an isolated dashboard. A useful workflow has four linked jobs:

    • Observe: identify where your brand, products, experts, and pages appear or disappear in relevant AI answers.
    • Diagnose: determine whether the issue involves ambiguous entities, missing evidence, inaccessible content, inconsistent facts, weak third-party corroboration, or an irrelevant prompt sample.
    • Intervene: improve the assets you control, including factual copy, source pages, technical accessibility, appropriate structured data, and evidence that other publishers can verify.
    • Validate: repeat the measurement, inspect the underlying answers and citations, and connect any change to a business decision rather than celebrating a score in isolation.

    A platform that performs only the observation step may still be useful, but it has not completed the marketing job. The value appears when your team can trace a detected issue to a defensible action and then check whether that action changed anything meaningful.

    Use a buyer’s scorecard, not the valuation

    If you are evaluating Profound or another AI visibility platform, apply the same scorecard to every vendor. This prevents brand momentum, investor names, and polished aggregate scores from substituting for evidence.

    Start with measurement integrity. Ask which AI models and user experiences are covered, which markets and languages are supported, and whether the results represent live answers, an external data provider, or another collection method. Model output can vary with prompt wording, model version, user context, and repeated runs. You need to know how the platform handles that variability before treating movement as a trend.

    • How are prompts selected, grouped, weighted, and updated?
    • Can you inspect the exact prompt, answer, cited pages, collection time, and relevant execution context behind every score?
    • Does the system distinguish a brand mention from a recommendation, a citation, a comparison, or a factual statement?
    • How does it prevent changes in prompt coverage from looking like changes in brand performance?
    • Can you preserve a stable benchmark while separately exploring new prompts and models?
    • How are failed collections, unavailable models, duplicate answers, and ambiguous brand names handled?

    A visibility score that cannot be decomposed is difficult to act on. If the score rises, you should be able to see which answers changed and why. If it falls, you should be able to distinguish a real deterioration from a collection or coverage change.

    Then test actionability. Ask the vendor to walk from a detected problem to a recommended intervention using your own data. A useful recommendation identifies the affected audience, the evidence behind the diagnosis, the asset or relationship that needs work, the owner who can act, and the signal that would count as improvement.

    • Does the platform separate issues on your website from gaps in third-party authority?
    • Can recommendations point to the exact pages, claims, citations, or entity conflicts involved?
    • Does it explain where structured data is relevant without presenting schema as a guarantee of inclusion in an AI answer?
    • Can findings flow into the content, SEO, analytics, public relations, and product workflows your team already uses?
    • Can analysts annotate changes so later reporting does not confuse an intentional intervention with unexplained movement?

    Finish with commercial and operational resilience. Funding may improve a vendor’s capacity to invest, but it does not remove switching costs or contractual risk. Get data ownership, export access, retention, usage limits, overage rules, support scope, renewal terms, and the total expected cost in writing. Confirm what happens to your historical data if you leave. Treat roadmap slides as possibilities until a capability is included in the agreement or available in the product.

    Run a controlled evaluation around a real decision

    An evaluator compares two unbranded AI systems in parallel testing bays using identical inputs and a central balance mechanism.

    The cleanest way to evaluate an AI marketing platform is to make it answer a decision your team already faces. Do not begin with, “Can this produce an interesting dashboard?” Begin with a question such as, “Can this show us why qualified buyers encounter competitors instead of us, and can it help us choose what to change?”

    1. Define the decision. Name the audience, product or service, market, and business question. Decide who will act if the platform finds a credible problem.
    2. Create a representative prompt set. Include branded and unbranded questions from different stages of the buying journey. Write down why each prompt matters. Keep the core set stable so a changing sample does not masquerade as performance movement.
    3. Capture a manual baseline. Save the exact prompts, visible answers, citations, model or surface, and relevant context. Note entity ambiguity and obvious collection errors before introducing a vendor score.
    4. Run the platform against the same scope. Compare its output with the baseline. Investigate disagreements rather than assuming the platform or the manual sample is automatically correct.
    5. Act on findings you can verify. Correct inconsistent facts, strengthen useful first-party pages, improve crawlability, add appropriate structured data, and pursue credible third-party coverage where the diagnosis supports those actions.
    6. Judge decision value. Ask whether the platform found important issues accurately, explained them clearly, helped the right owner act, preserved evidence, and made follow-up measurement more reliable.

    Keep AI visibility metrics in their proper place. Mentions, citations, answer share, and sentiment can be useful intermediate signals, but they are not automatically revenue or causation. If a dashboard improves after you change content, inspect the underlying answers. If business outcomes also change, examine other campaigns, seasonality, brand activity, and measurement gaps before assigning credit.

    Be equally cautious with promises of fixed placement. Generative answers are not conventional ranking tables, and their behavior can change. A credible evaluation should show variability, preserve raw evidence, and describe uncertainty instead of hiding it inside a single precise-looking number.

    Key takeaways

    • Profound announced a $96 million Series C and a $1 billion valuation, with Lightspeed Venture Partners leading the round.
    • The financing signals investor conviction and gives the company more strategic options; it does not prove product performance, revenue, profitability, or customer return.
    • For AI marketers, the round is a reason to take the category seriously, not a reason to replace a working stack without evaluation.
    • A useful AI visibility platform must expose prompts, answers, citations, collection context, and methodology behind its scores.
    • Your evaluation should connect observation to diagnosis, intervention, and validation using a stable prompt set and a manually checked baseline.
    • Commercial diligence still matters: verify exports, data ownership, limits, support, renewal terms, switching costs, and delivered capabilities before making a long-term commitment.

    Treat Profound’s funding as a prompt to sharpen your vendor questions, not to change strategy overnight. Preserve your baseline, test the platform against a decision that matters, and commit only when its data survives manual inspection and fits the way your team acts. That lets you benefit from a better-funded category without outsourcing your judgment to its valuation.

    References

  • Automated B2B Lead Generation: Build a Quality Feedback Loop

    Automated B2B Lead Generation: Build a Quality Feedback Loop

    You probably do not need another lead generation tool. If your automated campaigns produce cheap form fills that sales rejects, the system is working exactly as instructed: it has learned that submitting a form is the outcome that matters.

    The fix is to give automation a visible path from early interest to qualified pipeline, then make each campaign optimize for one stage of that path. You can scale from there without mistaking activity for demand.

    Fix the objective before you automate the campaign

    B2B automation has a signal problem. A purchase platform can often see an order, its value, and the ad that produced it within a short period. B2B campaigns may generate fewer conversions, lack an immediate transaction value, and feed a sales process that can continue for more than a year.

    The bidding system cannot infer what happened in your CRM unless you send that information back. Left alone, it will favor the observable event it receives most frequently. That is usually the form submission, regardless of whether the person used a personal email address, fell outside your service area, represented the wrong company size, or never progressed beyond the first sales review.

    Before changing bids, audiences, creative, or campaign types, answer four questions:

    • What is the deepest business outcome you can reliably connect to the originating campaign?
    • How consistently does your team apply that lifecycle stage in the CRM?
    • How long does it take for that outcome to appear?
    • Which earlier event is the best available proxy while the deeper outcome is still pending?

    Your ideal optimization event is not automatically the final sale. A closed deal may be economically meaningful but too delayed or infrequent to guide every campaign. A marketing qualified lead may be available sooner, while an accepted opportunity may carry a stronger connection to revenue. Choose the deepest stage that is both trustworthy and repeatable, then continue importing later outcomes for measurement.

    Do not judge this system on lead count alone. Review the number of leads, the share becoming qualified, the opportunities created, and the deals closed. One documented implementation reported a 150% increase in leads, a 350% increase in opportunities, and a 200% increase in closed deals. That is a single case result, not a benchmark, but the uneven movement across stages makes the important point: top-of-funnel volume and downstream value do not necessarily rise at the same rate.

    Build the CRM-to-ad feedback loop first

    An isometric system sends lead signals between business contacts, organized customer records, and an advertising engine, with bright qualified signals returning through the loop.

    Offline conversion tracking is the foundation of automated B2B acquisition. Your ad platform needs to learn when an online inquiry becomes a qualified lead, an opportunity, or a customer. Google Ads Data Manager provides integration paths involving HubSpot and Salesforce, as well as custom workflows using systems such as Snowflake and Zapier.

    The connector matters less than the integrity of the lifecycle data moving through it. A fast integration will only automate confusion if sales and marketing use the same CRM stage for different situations.

    1. Define each stage in operational terms. State what must be true before a contact becomes a marketing qualified lead, sales-accepted lead, opportunity, or closed deal. Avoid definitions based on intuition alone.
    2. Assign one owner to each transition. Decide whether marketing automation, a sales representative, or another system changes the stage. Conflicting updates make imported outcomes unreliable.
    3. Preserve the acquisition connection. The downstream CRM record must remain traceable to the campaign interaction that created it. If that connection disappears during routing, enrichment, or deduplication, the ad platform cannot learn from the result.
    4. Exclude invalid records before importing value. Spam, tests, duplicates, existing customers, job seekers, vendors, and other non-prospects should not teach the bidding system what to find next.
    5. Validate a sample from end to end. Compare the campaign record, form record, CRM contact, lifecycle change, and imported conversion. Check both successful imports and records that should have been excluded.
    6. Document the delay. Record how long qualification and opportunity creation normally take in your process. A recent campaign can look weak simply because its downstream outcomes have not matured yet.

    Give early intent a weighted vote, not control of the account

    Micro conversions can help when qualified outcomes are sparse or delayed. The important move is to assign relative values that express the difference between curiosity and commercial intent. One workable example uses values of 1 for a video view, 10 for an asset download, 100 for a form fill, and 1,000 for a marketing qualified lead.

    EventExample relative valueWhat it tells the systemHow to treat it
    Video view1The visitor showed initial interestUse as a weak supporting signal, not proof of demand
    Asset download10The visitor exchanged attention for useful materialUse as a stronger engagement signal, while checking whether the asset attracts your ideal buyer
    Form submission100The visitor initiated direct contactCount it as intent, but separate valid prospects from spam and poor-fit inquiries
    Marketing qualified lead1,000The record passed an agreed qualification ruleUse as a primary quality signal when the CRM stage is reliable

    These are utility points, not universal prices. Do not label them as revenue or report a value-based bid result as financial return on ad spend unless the values actually represent money. Their purpose is to tell the optimizer that one qualified lead should matter far more than one video view.

    Review how much total conversion value each event contributes. A low-value event can still dominate if it happens often enough. If video views or downloads create most of the recorded value, the campaign may learn to buy abundant engagement instead of scarce business intent. Reduce the shallow event’s value, remove it from the campaign’s optimization goal, or keep it for observation only.

    Also control repeated actions. One person replaying a video, downloading several files, or submitting the same form twice should not automatically look more valuable than a newly qualified account. Your counting rules, deduplication, and CRM logic must reflect the business event you actually want to reproduce.

    Make every campaign do one job

    An account-wide list of conversion actions is not a strategy. If the same campaign is rewarded for video engagement, downloads, inquiries, and qualified leads without a clear hierarchy, the easiest event can overpower the event that matters.

    Use campaign-specific goals to match optimization to the campaign’s role:

    • Awareness and audience development: measure video engagement or content interaction, but do not let those actions steer a high-intent acquisition campaign.
    • Mid-funnel demand capture: optimize for a meaningful form submission when qualification data is not yet frequent or timely enough.
    • Warm-audience acquisition: optimize toward the qualified lead event when the audience, offer, and CRM feedback can support it.
    • Pipeline-focused campaigns: use opportunity or revenue values when those offline outcomes are accurate enough to guide bidding.

    This separation also makes diagnosis easier. If an awareness campaign produces inexpensive views but no later demand, you can question the audience or message without contaminating the performance signal of a campaign designed to generate qualified inquiries.

    Low volume does not always require collapsing every initiative into one campaign. When several campaigns serve similar buyers and pursue the same conversion goal, portfolio bidding can combine their data. It is particularly useful when separate campaigns struggle to reach the commonly cited 30-conversion-per-month threshold. Portfolio strategies can also provide a maximum cost-per-click cap, which helps limit runaway bids.

    Only pool campaigns whose economics and objectives belong together. Combining a high-value enterprise offer with a low-value self-service offer may produce more data, but the shared strategy will be learning from two different businesses. More observations do not help when they describe incompatible outcomes.

    Your first-party CRM data should also shape targeting. Customer lists can support exclusions when acquisition campaigns should not spend on current customers. Contact and prospect lists can be used for observation, direct targeting, or audience signals where the campaign type permits. These lists give broad, AI-driven campaigns a concrete description of the people and accounts you already recognize.

    Performance Max is not automatically unsuitable for B2B lead generation. It becomes a defensible test after you have reliable offline outcomes, sensible conversion values, a campaign-specific goal, and useful first-party signals. A Target ROAS strategy can then optimize toward recorded customer value instead of treating every conversion as equivalent. If you use relative utility points rather than monetary values, remember that the resulting ROAS is an optimization ratio, not an accounting measure.

    Use AI where mistakes are visible and reversible

    AI can shorten research, organization, and drafting work, but it cannot repair a missing feedback loop. Put it on bounded tasks whose outputs a marketer can inspect before they affect bids, budgets, exclusions, or customer communication.

    Start with a reusable context brief. Include your offer, differentiators, target personas, ideal client profile, buying roles, disqualifiers, and approved claims. Explicitly state that the customer is another business; that B2B instruction changes the frame of the response and reduces the chance of receiving consumer-oriented ideas.

    Prompt skeleton: You are supporting B2B demand generation for [company]. We sell [offer] to [ideal client profile]. The buying group includes [roles]. Our differentiators are [approved claims], and we do not serve [disqualifiers]. Complete [task]. Separate verified inputs from inferences, identify missing information, and do not invent competitor claims or customer evidence.

    That context can support several practical workflows:

    • Competitor analysis: organize known offers, positioning, value propositions, and customer sentiment into a consistent matrix. Require a traceable input for every factual claim and leave unsupported cells blank.
    • Keyword gap review: give AI an export from a tool such as Semrush and ask it to separate terms competitors cover, terms you already lead on, and recurring themes that may deserve their own campaigns.
    • Search-term triage: classify terms as relevant, irrelevant, or ambiguous. A human should review ambiguous cases and approve negative keywords before they are applied.
    • Ad-copy drafting: request variations tied to a named persona, problem, offer, and approved proof point. Treat every line as a draft that still needs factual and policy review.
    • Reporting support: summarize anomalies and prepare questions for investigation. Google Ads also provides pre-built automation solutions for reporting, anomaly detection, and keyword-list creation, although complex enterprise accounts need careful validation before broad use.

    Keep consequential decisions outside a fully automatic chain until you trust the inputs and failure modes. A mistaken theme label is easy to correct. An automatically applied negative keyword can suppress qualified demand, while an unverified competitor claim can create reputational or legal exposure. Let AI propose; require an accountable person to approve.

    Use controlled experiments for bid strategies, match types, and landing pages. Write the hypothesis and success measure before launch. If you change the audience, bid strategy, offer, creative, and page at once, even a positive result will not tell you which decision to repeat.

    Roll out automation in an order you can audit

    Three transparent workstations show automation expanding from one inspected mechanism to a larger system monitored by two analysts, with checkpoints between stages.

    You do not need to rebuild the whole account at once. Start with one meaningful campaign and make its data path trustworthy before expanding the design.

    1. Select the downstream outcome. Choose the deepest lifecycle stage that is consistently recorded and still occurs often enough to inform the campaign.
    2. Write the qualification rule. Make the rule specific enough that two team members would classify the same record the same way.
    3. Connect the CRM outcome. Import the offline event and verify that it connects to the correct campaign interaction.
    4. Add a restrained value ladder. Give early actions lower relative values and the qualified outcome a clearly dominant value.
    5. Set the campaign-specific goal. Remove unrelated actions from the campaign’s optimization objective, even if you continue measuring them elsewhere.
    6. Add relevant first-party data. Exclude existing customers where appropriate and use qualified contact lists as targeting or audience signals.
    7. Consider portfolio bidding. Pool only campaigns with compatible goals and economics when each one lacks sufficient conversion volume on its own.
    8. Test broader automation. Introduce Performance Max, Target ROAS, broader matching, or another automated feature only after the outcome data is dependable.
    9. Automate repetitive analysis. Use AI and platform solutions for drafts, classifications, reports, and anomaly alerts, with human approval for consequential changes.
    10. Review the full funnel. Compare lead volume, qualification, opportunities, closed deals, and the share of recorded value coming from each conversion action.

    Key takeaways

    • Automated B2B lead generation improves when the ad platform can distinguish an inquiry from a qualified business outcome.
    • Offline CRM conversions should carry more authority than abundant micro conversions.
    • Relative values must reflect intent hierarchy and should not be presented as revenue unless they represent actual money.
    • Campaign-specific goals prevent easy engagement events from steering pipeline-focused campaigns.
    • AI is most useful for inspectable research, classification, drafting, and reporting tasks; it should not silently approve high-consequence changes.

    Your next step is small: choose one campaign, one qualified CRM stage, and one imported offline event. Trace a real record through that loop. Once the campaign can tell the difference between a completed form and a viable prospect, additional automation has something worth scaling.

    References