Tag: AI Insights

  • How to Read Google Ads Experiments and Funnel Reports

    How to Read Google Ads Experiments and Funnel Reports

    You open Google Ads and see two persuasive narratives. The funnel view shows campaigns contributing across the customer journey, while an AI-generated experiment summary points toward a recommended action. Both can help you make a decision. Neither should make that decision for you.

    The practical job is to separate three questions: Where did campaign activity appear in the journey? Did it cause an incremental result? What exactly will happen if you apply the experiment outcome? Once you keep those questions separate, the reporting becomes far more useful.

    Use funnel reporting to decide where to investigate

    The Performance by stage card on the Google Ads Overview page organizes campaign reporting around awareness, consideration, and action. It brings impressions, CPM, frequency, views, video completion rate, and conversion insights into a journey-oriented view.

    That structure is most useful when you treat each stage as a different decision question. An awareness campaign should not be judged only by the immediate conversions visible at the end of the journey. An action-focused campaign should not receive credit merely because it generated a large number of impressions. Start with the job the campaign was meant to do, then select the evidence that fits that job.

    Funnel stageDecision questionSignals to examine togetherWhat to do next
    AwarenessAre you reaching people at an acceptable exposure pattern?Impressions, CPM, frequency, and Brand Lift when configuredInvestigate reach, repetition, and whether exposure is changing brand outcomes before expanding delivery.
    ConsiderationAre people engaging deeply enough to warrant further investment?Views, video completion rate, and Search Lift when configuredIdentify which campaigns or creative approaches deserve a controlled follow-up test.
    ActionIs campaign activity connected with business outcomes?Conversion insights and Conversion Lift when configuredValidate measurement coverage, incremental impact, and economic value before changing budget or settings.

    Read these signals in pairs rather than isolation. Impressions without frequency do not tell you whether delivery is broad or repetitive. Views without completion rate do not reveal how much of the video people consumed. Conversion totals without knowing which conversion actions are eligible can produce a false comparison.

    The funnel card can also incorporate insights from Brand Lift, Search Lift, and Conversion Lift studies when they are configured. That distinction matters. Routine delivery and engagement metrics tell you what happened inside the reporting system; lift measurement is designed to address whether exposure changed an outcome.

    Do not turn a conversion path into a causal claim
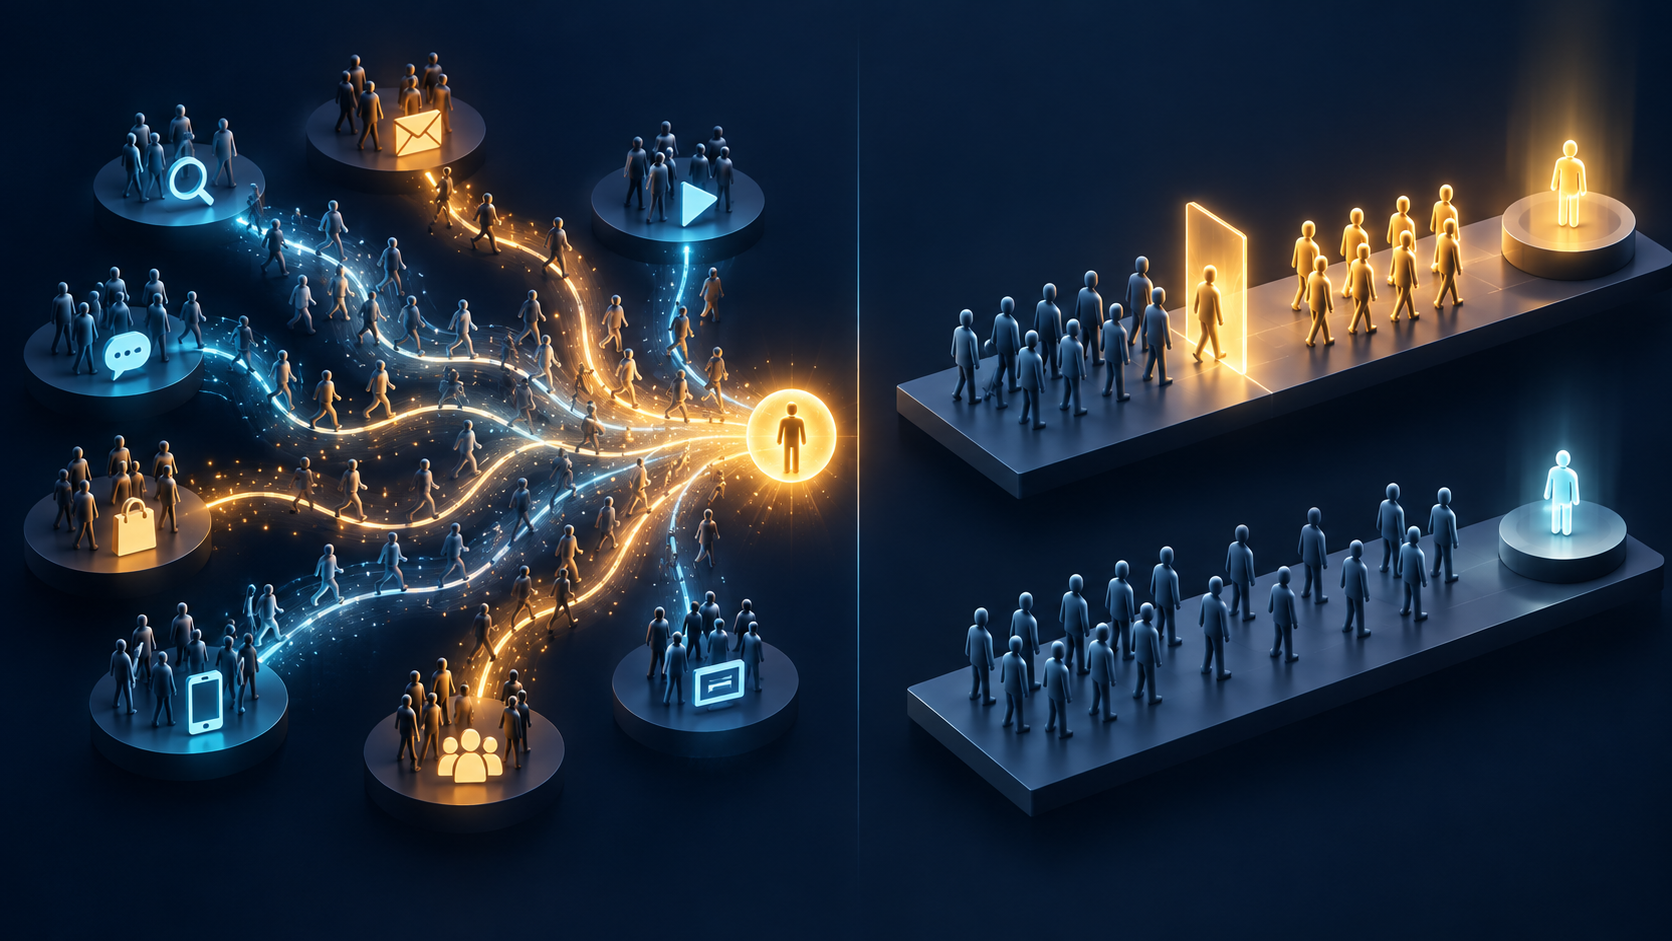
    Branching customer touchpoints converge on an outcome beside two matched groups arranged for a controlled experiment.

    Video impressions can now appear in conversion paths, marked with an eye icon. This gives you visibility into exposure that was previously missing when the path showed video views but not impressions. It does not prove that the impression caused the eventual conversion.

    A conversion path is descriptive. It tells you that an eligible exposure or interaction appeared in the recorded sequence associated with a conversion. Incrementality is a different question: would the conversion have happened without that campaign exposure? A path alone cannot answer it.

    • Use the path to identify patterns worth investigating, not to declare that every recorded touchpoint deserves causal credit.
    • When the decision involves additional spend, use an incrementality method such as Conversion Lift when it is available and appropriately configured.
    • Keep observational language in your internal reporting. Say that video impressions appeared in conversion paths, not that those impressions generated every conversion in those paths.
    • Compare campaigns only after confirming that their conversion coverage is comparable.

    That last check is essential because the added video-impression visibility currently covers eligible web conversions but excludes conversions imported from Google Analytics 4. If your account relies on GA4-imported conversions, a missing video impression may reflect the reporting boundary rather than the absence of an earlier exposure.

    Before presenting a funnel report, label the conversion setup behind it. Note which actions are eligible web conversions, which are imported from GA4, and whether different campaigns are being evaluated against the same set. Without that note, an apparent gap between campaigns may be a measurement-coverage gap.

    Treat the AI experiment summary as triage, not a verdict

    The Summary tab for Google Ads experiments now includes an AI-generated panel covering the experiment goal, key findings, and recommended actions. This can reduce the time required to scan several test scorecards, particularly when you manage multiple experiments.

    Use that panel to find the decision you need to inspect. Then return to the underlying scorecard and run a consistent decision gate. The summary can condense the reported pattern, but it cannot replace the business context that determines whether the pattern is valuable.

    1. Restate the hypothesis. Write the specific change and the result it was expected to improve. If you cannot state both in one sentence, the experiment is not ready for a winner declaration.
    2. Confirm the primary outcome. Use the business outcome selected for the decision, not whichever metric happens to show the most attractive movement.
    3. Check duration and conversion volume. A promising direction based on limited observation is still limited evidence. Do not end a test merely because the automated summary sounds decisive.
    4. Inspect statistical significance. A visible difference is not automatically a reliable difference. If the evidence is inconclusive, record it as inconclusive rather than relabeling it as a tie or a failure.
    5. Test practical significance. A statistically credible change may still be too small, too costly, or too poorly aligned with the business objective to apply.
    6. Review trade-offs. Check whether improvement in the primary metric came with deterioration in a metric that protects cost, lead quality, conversion quality, or another business constraint.
    7. Evaluate the recommendation. Treat the suggested action as a candidate decision that has passed through the preceding checks, not as an instruction that bypasses them.

    This order prevents a common analytical mistake: reading the recommendation first and then searching for evidence that supports it. Decide what would count as success before you let the generated narrative frame the result.

    Statistical significance and business significance should also remain separate. Statistical significance addresses whether an observed difference is likely to be more than random variation under the test assumptions. Business significance asks whether the difference is worth the cost, risk, and operational change. You need both questions, even when the interface emphasizes only one of them.

    Check the consequence before applying a Performance Max result
    An analyst inspects a glowing recommendation at a decision gate connected to several downstream resource channels.

    The word “apply” does not have one universal effect across Performance Max experiments. The outcome depends on the experiment type, so confirm the type before accepting any recommendation.

    Performance Max experimentWhat applying the result doesDecision you must make first
    Migration experimentMoves traffic fully to Performance MaxConfirm that you intend to move all relevant traffic, not merely acknowledge the reported winner.
    Optimization experimentPermanently applies the tested settingsConfirm that every tested setting is acceptable as an ongoing campaign configuration.
    Custom experimentLets you manually select the winning versionCompare the versions against the predefined business outcome and choose deliberately.

    This is the point where a reporting interpretation becomes an account change with spending consequences. Before applying a result, record the control configuration, the tested difference, the experiment type, the selected winner, the expected platform behavior, and the person responsible for the decision. Also write down how you would respond if post-change performance no longer supports the choice.

    A compact decision record keeps the funnel view, the experiment, and the account change connected without pretending they are the same kind of evidence:

    • Business question: What decision are you trying to make?
    • Funnel stage: Is the campaign intended to influence awareness, consideration, or action?
    • Measurement coverage: Which conversion actions and exposure types are represented, and which are excluded?
    • Evidence type: Is the finding descriptive path evidence, an experiment result, or a lift result?
    • Validity check: Were duration, conversion volume, statistical significance, and business objectives considered?
    • Platform consequence: What will applying this experiment type actually change?
    • Decision: Apply, continue collecting evidence, revise the test, or stop without declaring a winner.

    The resulting workflow is straightforward. Use funnel reporting to spot the stage and signal that needs attention. Turn that observation into a specific hypothesis. Choose an experiment when you need to compare a controlled campaign change, or an appropriate lift study when the question is incrementality. Read the AI summary to orient yourself, validate it against the scorecard and business objective, then apply only after confirming the consequence.

    Key takeaways

    • The Performance by stage card is a diagnostic map across awareness, consideration, and action; it is not automatic proof of campaign impact.
    • A video impression in a conversion path shows recorded exposure, not causation.
    • Video-impression paths cover eligible web conversions and exclude GA4-imported conversions, so check coverage before comparing results.
    • AI-generated experiment summaries can speed up review, but duration, volume, statistical significance, practical value, and business objectives still determine the decision.
    • Applying a Performance Max result has different consequences for migration, optimization, and custom experiments.

    At your next review, put one sentence above the dashboard: “We are deciding whether to…” Finish that sentence before opening the AI recommendation. It will tell you which funnel evidence matters, what still needs validation, and whether pressing Apply is justified.

    References


  • Google AI Tools for Search Marketers: A Practical Workflow

    Google AI Tools for Search Marketers: A Practical Workflow

    Google now puts AI on both sides of a search marketer’s desk. On the organic side, AI-generated search experiences decide how information is assembled and cited. On the paid side, AI interprets campaign data and proposes explanations for performance changes.

    Your job is not to collect every new feature. It is to separate two workflows: earning visibility in AI-generated answers and using AI to investigate paid-search performance. That distinction tells you what to measure, what to prompt, and which conclusions still need human verification.

    Match each Google AI tool to the question it can answer

    Start by deciding whether you are examining the market or examining your account. AI Mode, AI Overviews, and Gemini can help you observe how Google interprets a topic. Google Ads AI Dashboards, homepage insights, and Ask Advisor work with advertising performance.

    Google AI surfaceUseful marketing questionOutput to captureConclusion to avoid
    AI ModeHow is this query answered, and which pages support the answer?Answer structure, cited URLs, entities, claims, and missing subtopicsA citation is a permanent ranking position
    AI OverviewsWhat synthesized answer appears alongside conventional search results?Answer framing, cited domains, and the relationship between the generated answer and the surrounding resultsOne result represents every user, query variation, or future search
    GeminiHow might an AI assistant interpret the topic or decompose the user’s request?Terminology, follow-up questions, ambiguities, and information needsA Gemini response is a direct proxy for Google Search rankings
    Google Ads AI DashboardsWhat changed in campaign performance, where did it change, and what may have contributed?A scoped visualization, account segments, and an explanation to verifyAn AI-generated explanation proves causation
    Ask Advisor and homepage insightsWhich account questions or anomalies deserve investigation?Questions, hypotheses, and paths into the underlying account dataA recommendation should be applied without checking its scope and commercial risk

    This separation matters because AI Mode is an external discovery environment, while an Ads dashboard is an internal analysis environment. AI Mode can show how Google retrieves, orders, and cites information. It cannot tell you why an advertising campaign’s cost changed. An Ads dashboard can analyze account data, but it cannot establish whether your organic content is eligible to support an AI-generated answer.

    Do not combine all of these observations into a single “AI visibility” score. Keep at least two records: an organic answer-and-citation log and a paid-performance investigation log. Otherwise, a change in advertising efficiency can be mistaken for a change in search demand, or a volatile AI citation can be mistaken for durable organic growth.

    Use AI Mode as a citation audit, not a rank tracker

    A magnifying glass inspects links between an abstract AI answer panel and several source documents, with one unsupported connection highlighted.

    A conventional rank check asks where a URL appears for a query. An AI citation audit asks a different set of questions: What answer did Google construct? Which claims needed support? Which sources were selected? What did the cited pages make especially clear?

    That makes AI Mode useful for diagnosing content, but weak as a one-observation scoreboard. Generated answers can change with wording, context, and the shape of the request. Record what you see, but do not turn a single appearance or absence into a general claim about visibility.

    1. Build the query set from real decisions. Include the problem a person is solving, the comparison they need to make, the constraint that changes the answer, and the follow-up question likely to come next. A broad head term rarely reveals the whole information journey.
    2. Run a controlled observation. Keep the wording of each query in your log. Check the conventional results page, note whether an AI Overview appears, and inspect AI Mode separately. Do not silently change the prompt and then compare the outputs as though the query stayed constant.
    3. Record the answer anatomy. Capture the main answer, the subquestions it addresses, named entities, cited URLs, and the specific claim each citation appears to support. A domain count alone tells you almost nothing about why a page was useful.
    4. Inspect the cited pages. Look for the passage that answers the question, the definitions surrounding it, supporting evidence, descriptive headings, and any comparison structure. The useful unit is often a clearly supported claim inside a page, not the page as an indivisible object.
    5. Compare your page with the information need. Mark missing answers, buried definitions, unexplained terminology, unsupported assertions, and comparisons that use inconsistent dimensions. Those are concrete editing targets.
    6. Recheck after a meaningful revision. Keep the original query and observation beside the new one. Treat a changed answer as an observation to investigate, not proof that one edit caused it.

    The resulting worksheet should have one row per query and columns for intent, answer framing, cited pages, supported claims, gaps, planned edits, and the next observation. This gives your team evidence it can discuss. A screenshot folder without query wording or claim-level notes does not.

    Make a page easier to retrieve without writing for a robot

    Retrievability starts with clarity. Put the direct answer near the question it resolves. Name the entity before switching to pronouns. Define specialist terms. Keep qualifications attached to the claim they limit. If you compare options, use the same criteria for each option so the relationship is visible rather than implied.

    • Give each important question a descriptive heading and an immediate answer.
    • Use the full name of a product, organization, method, or standard when ambiguity is possible.
    • Support factual claims on the page instead of expecting a search system to infer evidence from a distant internal link.
    • Place limitations beside recommendations. Moving them to a generic disclaimer weakens the answer and can mislead the reader.
    • Use structured data only when it accurately describes visible content. Schema can clarify meaning; it cannot rescue an unsupported or missing answer.
    • Link related pages according to the reader’s next question, not merely because they share a keyword.

    This is not a replacement for technical SEO. A page still needs to be accessible, indexable, canonicalized correctly, and connected to the rest of the site. AEO and GEO work build on that foundation by making answers, entities, relationships, and evidence easier to identify.

    Prompt Google Ads AI Dashboards like an analyst

    Google Ads AI Dashboards are appearing in some advertiser accounts, so you may not have access yet. Where the feature is available, a natural-language request can generate a visual report instead of requiring you to select every metric, dimension, and chart manually.

    The dashboard can also attach a real-time AI summary of what changed and what may be driving it. That saves report-construction time. It does not remove the need to frame the question or verify the explanation.

    A useful dashboard prompt contains six parts: the decision, account scope, metric, comparison, segmentation, and requested output. If one is missing, Gemini has to infer it, and the chart may be technically correct while answering the wrong business question.

    • Decision: State what you are trying to understand, such as whether an efficiency change is concentrated or account-wide.
    • Scope: Name the campaigns, campaign type, product group, geography, device, or other relevant boundary.
    • Metric: Specify the outcome and its related inputs. Asking only about conversions can hide a simultaneous change in spend or traffic.
    • Comparison: Name the periods or segments being compared and make sure they are commercially comparable.
    • Segmentation: Ask for the dimension that could expose the change instead of accepting an account-wide average.
    • Output: Request the visualization, largest contributors, and a clear separation between observed data and possible explanations.

    A reusable prompt pattern is:

    Compare [metric set] for [campaign scope] between [period or segment A] and [period or segment B]. Break the result down by [dimension]. Visualize absolute and relative changes, identify the largest contributors to the account-level movement, and separate observations from possible causes.

    Reusable Google Ads analysis prompt

    You can adapt that pattern to practical questions:

    • Compare cost, conversions, and cost per conversion across campaigns for two comparable periods. Show which campaigns contributed most to the account-level change.
    • Break out cost, conversions, and conversion value by device for brand and non-brand campaign groups. Flag cases where volume and efficiency moved in different directions.
    • Chart daily spend and conversions for a selected campaign group. Identify the dates and campaigns responsible for the largest deviations, without assigning a cause.
    • Compare performance by geography for the selected campaigns. Separate changes caused by traffic volume from changes in conversion efficiency.

    These prompts do more than request a prettier report. They force you to define the denominator, the comparison, and the decision. If the generated chart cannot accommodate a requested metric or dimension, revise the scope rather than accepting a substitute without noting it.

    Verify the AI explanation before changing content or spend

    An analyst cross-checks an AI-generated performance explanation against a calendar, change history, source document, and calculator before approving an action.

    The most convincing AI mistake is a plausible explanation attached to accurate numbers. A dashboard may correctly show that cost per conversion rose while offering a cause that the chart cannot prove. The phrase “may be driving” marks a hypothesis, not a causal finding.

    Run every material insight through the same verification loop:

    1. Confirm the scope. Check the date range, campaign selection, filters, excluded segments, and comparison period. A summary can be accurate for its slice and still misrepresent the account.
    2. Confirm the metric definition. Make sure the chart is using the conversion, value, cost, or efficiency measure your decision actually depends on. Similar labels are not interchangeable.
    3. Locate the contributors. Move from the account total to campaigns and then to the dimension behind the movement. An average can conceal opposite changes in separate segments.
    4. Separate observation from cause. “Mobile efficiency declined” is an observation. “The landing page caused the decline” requires evidence beyond two events occurring near each other.
    5. Check the underlying rows. Review the data behind the visualization before presenting the summary or applying a recommendation. The chart is an interface to the account, not an independent record.
    6. Choose a reversible next step. Investigate, annotate, or run a controlled change before making a broad account adjustment.

    Paid-search decisions can spend real money. Do not increase budgets, change bids, pause broad campaign groups, or alter conversion settings solely because an AI summary sounds certain. Use the same approval process you would apply to a human analyst’s recommendation, and preserve a record of the original settings and the reason for the change.

    Apply the same discipline to organic content. Do not rewrite an accurate, useful page merely because it was absent from one AI Mode response. First determine whether the page answers the same intent, whether another page on your site is the better candidate, and whether the proposed edit improves the reader’s answer. Citation visibility is an outcome to observe, not permission to weaken the page.

    Key takeaways and your next working session

    • Use AI Mode and AI Overviews to inspect answer construction and citations; do not treat them as conventional rank trackers.
    • Use Gemini for exploratory interpretation, not as proof of how Google Search will rank a page.
    • Use Ads AI Dashboards to reduce report-building work, but define the scope, metric, comparison, and segment in the prompt.
    • Treat every generated explanation as a hypothesis until the underlying account data supports it.
    • Keep organic citation observations separate from paid-performance investigations.
    • Improve content by clarifying answers, entities, evidence, and relationships while preserving technical SEO and reader value.

    For your next working session, choose one valuable query cluster and one unresolved Google Ads performance question. Build a citation log for the first and a tightly scoped dashboard prompt for the second. If every conclusion can be traced back to a cited page or a defined slice of account data, the AI is helping you investigate. If it cannot, keep it in the hypothesis column.

    References


  • How to Use AI Agents for Google Ads and Analytics Reporting

    How to Use AI Agents for Google Ads and Analytics Reporting

    Your reporting problem probably isn’t a lack of charts. It is the delay between a meaningful change, someone noticing it, and the team deciding what to do. AI agents inside Google Ads and Google Analytics can shorten that interval, but only if you treat their answers as the start of analysis rather than the final verdict.

    The practical goal is a tighter reporting loop: detect the change, ask a precise question, verify the answer in the underlying data, and make a documented decision. That is where these tools can save time without quietly lowering the standard of evidence behind your campaign choices.

    Put the agent in the right role

    Google is moving its reporting assistant beyond passive data retrieval. Ask Advisor can surface performance changes, investigate natural-language questions, recommend next steps, and generate visual reports with explanatory summaries. The advertiser still controls campaign decisions.

    That makes the agent most useful as an analyst interface, not an autonomous media buyer. It can reduce the work required to find a signal and form an initial explanation. It cannot remove the need to establish whether that explanation is complete, whether the comparison is appropriate, or whether the proposed action is commercially sensible.

    • Observation: What changed in the data, for which metric, segment, and period?
    • Interpretation: What might explain the change, and which competing explanations remain possible?
    • Decision: What action, if any, is justified after you verify the observation and interpretation?

    Keep those three layers separate in every report. If Ask Advisor connects competitor pressure with a loss of impression share, for example, that is an interpretation to investigate. Confirm the affected campaigns, date range, comparison period, and magnitude before changing bids or budgets. A plausible explanation is not yet an approved action.

    Ask questions that lead to a decision

    A broad prompt such as “What happened?” invites a broad narrative. You may receive an interesting summary without learning what deserves attention. A stronger question gives the agent a metric, scope, comparison, diagnostic angle, and decision to support.

    Use this structure when you write a prompt: Find the change in [metric] for [scope] over [period], compare it with [baseline], break it down by [segments], test [possible explanation], and show what I should verify before [decision].

    Start in Google Analytics when the question is about user or sales behavior

    Google Analytics homepage AI Overviews are designed to summarize important changes since your previous login. They can call attention to developments such as traffic shifts or seasonal sales spikes, offer possible next steps, and pass a selected insight into Ask Advisor for deeper investigation. In this setting, “AI Overview” means an Analytics account summary, not an AI Overview in Google Search.

    A since-last-login summary is useful for triage, but it is not automatically a sound reporting period. Reframe anything important against the comparison your business actually uses before drawing a conclusion.

    • Which traffic change contributed most to the sales movement highlighted on the homepage? Break the result down by channel and device, and identify any seasonal pattern I should test.
    • Which segment explains the largest part of this change? Show whether the account-wide direction still holds inside that segment.
    • What changed first: traffic volume, user behavior, or the reported business outcome? List the views I should open to verify the sequence.

    Start in Google Ads when the question is about campaign delivery

    The redesigned Google Ads homepage uses personalized AI insight cards, while Ask Advisor accepts natural-language questions about issues such as competitor effects on impression share and trends that could influence campaign performance. Use those cards as an investigation queue, not as a replacement for your normal controls.

    • Which campaigns lost impression share during the relevant period, and does the visible pattern support competitor pressure or another explanation?
    • Which performance change is concentrated in one campaign, device, location, or audience rather than spread across the account?
    • What trend could affect campaign performance next, which current metrics support that possibility, and what evidence would contradict it?
    • Create a visual report for the affected campaigns, include the comparison period, and summarize the largest movement without recommending a budget change.

    If an answer does not identify its metric, scope, comparison, and relevant segment, ask again. The purpose of the follow-up is not to make the wording more polished. It is to make the claim testable.

    Use a three-pass reporting workflow

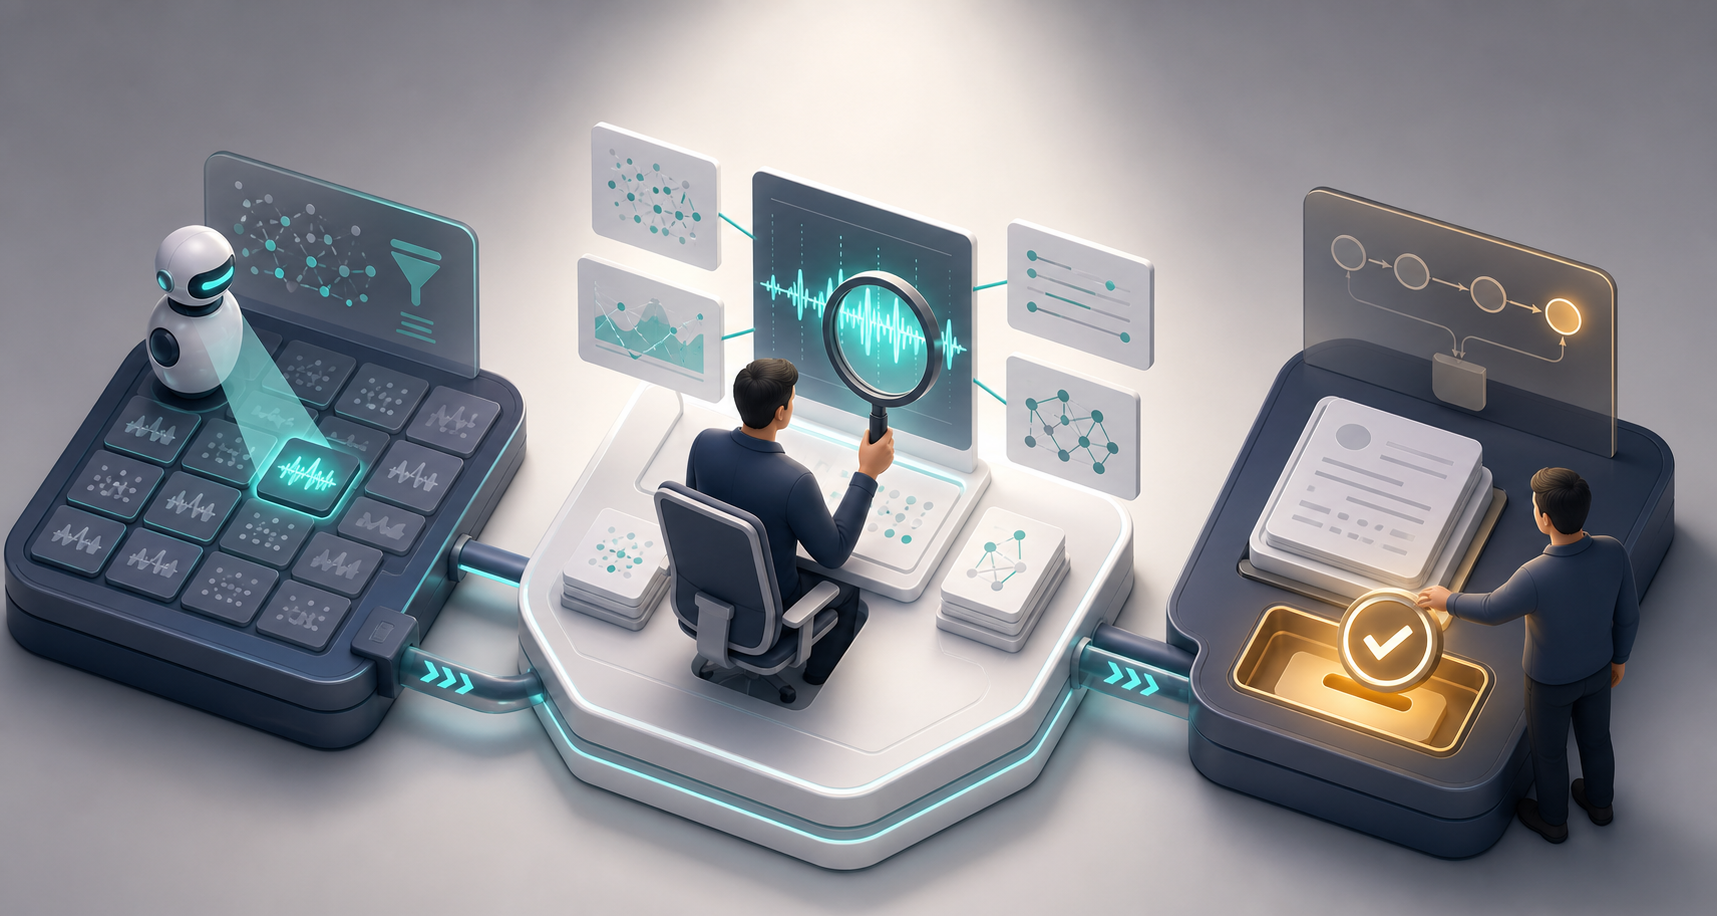
    Three connected workstations depict an AI detecting a change, an analyst verifying evidence, and a reviewed action being documented.

    The cleanest way to integrate an AI agent is to separate detection, investigation, and approval. This prevents a generated explanation from moving directly into a campaign change simply because it arrived in a confident tone.

    1. Pass one – detect: Review the Analytics overview or Ads insight cards. Select only changes that could affect an active business decision. Do not turn every card into a task.
    2. Pass two – frame: Rewrite the selected insight as a question that could be proven wrong. Replace “Performance fell” with a question about the exact metric, campaign or segment, period, and comparison.
    3. Pass two – investigate: Ask Advisor to break the change into relevant components and explore more than one explanation. Request the views or segments needed to check its reasoning.
    4. Pass two – verify: Open the underlying report. Confirm the date range, filters, comparison period, metric definition, conversion setup, and attribution context where relevant. Check that the movement still exists when you inspect the affected segment directly.
    5. Pass three – decide: Record whether you will act, monitor, or reject the hypothesis. Name the evidence that determined the decision so the same question does not restart at the next reporting meeting.
    6. Pass three – distribute: Google Analytics users can opt in to receive AI-generated summaries through email or mobile notifications. Treat a notification as an invitation to review, not as approval to make a campaign change.

    Use a simple stop rule: if the explanation changes materially when you correct the date range, isolate a segment, or apply the intended comparison, the analysis is not ready for action. Continue investigating or leave the campaign unchanged.

    Budget, bid, targeting, and measurement changes can affect real spend and future reporting. Do not approve them from an AI-generated narrative alone. Verify the relevant platform data and apply your existing account approval process first.

    Build dashboards that preserve context

    Analyst examines a transparent dashboard where one performance signal is linked to time, audience, campaign-change, and comparison context.

    Google Ads Dashboards can be generated from text prompts, with AI producing visual reports and real-time summaries of the trends represented by the charts. Google Analytics support was identified as a later addition, so availability may differ between the two products. If the Analytics option is not present in your account, use Ask Advisor for investigation and keep your established reporting workflow in place.

    A useful dashboard should preserve the path from outcome to diagnosis. Build it in layers so a reader can see what changed before encountering an explanation:

    • Outcome layer: Show the business and campaign metrics tied to the decision the dashboard supports.
    • Change layer: Show the active period beside the intended baseline, using clearly stated date ranges.
    • Diagnostic layer: Break the result down by the dimensions most likely to reveal concentration, such as campaign, channel, device, or location.
    • Interpretation layer: Label confirmed observations separately from AI-generated possible explanations.
    • Decision layer: Keep a note alongside the dashboard stating the owner, chosen action, verification performed, and next review point. Do not imply that this note is created automatically unless your account supports it.

    A practical dashboard prompt might read: Create a visual report for the campaigns connected to this decision. Show the current period and comparison period, break the main outcome down by campaign and device, identify the largest change, and separate observed facts from possible causes in the summary.

    Review every generated dashboard against five questions: Are the dates explicit? Is the scope visible? Are metric definitions understood? Does the summary distinguish correlation from explanation? Can the reader tell which decision the report is meant to support?

    Real-time summaries improve speed, not certainty. If a chart and its narrative appear to disagree, trust neither automatically. Check the chart configuration and underlying report before circulating the conclusion.

    Key takeaways for safer AI-assisted reporting

    • Use Ask Advisor to detect changes, form hypotheses, and accelerate report creation; keep campaign approval with a person.
    • Give every prompt a metric, scope, period, baseline, segmentation request, and decision context.
    • Treat homepage summaries and notifications as triage signals rather than completed analysis.
    • Verify important claims in the underlying Ads or Analytics report before changing spend, targeting, bids, or measurement.
    • Design dashboards to separate observed facts, possible causes, and approved actions.
    • Begin with one recurring reporting decision and a repeatable verification checklist before expanding the workflow.

    At your next reporting session, choose one question your team answers repeatedly. Turn it into a structured Ask Advisor prompt, write down the checks required before action, and use that same sequence for several reporting cycles. Expand only when the agent consistently helps you reach a verified decision faster.

    References


  • How AI Is Rewiring Advertising, Commerce and Measurement

    How AI Is Rewiring Advertising, Commerce and Measurement

    AI-powered advertising is developing along several connected fronts rather than following a single path. Reports about Amazon Alexa+, YouTube’s Gemini-powered tools, and Google Search Console show AI entering the transaction, campaign-planning, and visibility-measurement stages of marketing.

    Together, these developments offer marketers a useful framework for evaluating AI products: identify the decision each tool supports, distinguish an optimization signal from proven business impact, and determine which parts of the customer journey remain unmeasured.

    Key takeaways

    • Amazon’s reported Alexa+ ad format turns the assistant into an advertising, product-discovery, and purchasing interface.
    • YouTube’s new tools use AI and expanded data to support trend research, creator selection, and creative optimization.
    • Google Search Console’s AI performance report provides visibility data, but the reported version does not include clicks.
    • These products cover different stages of marketing, so their signals should not be treated as interchangeable measures of success.

    Conversational ads compress the path to purchase

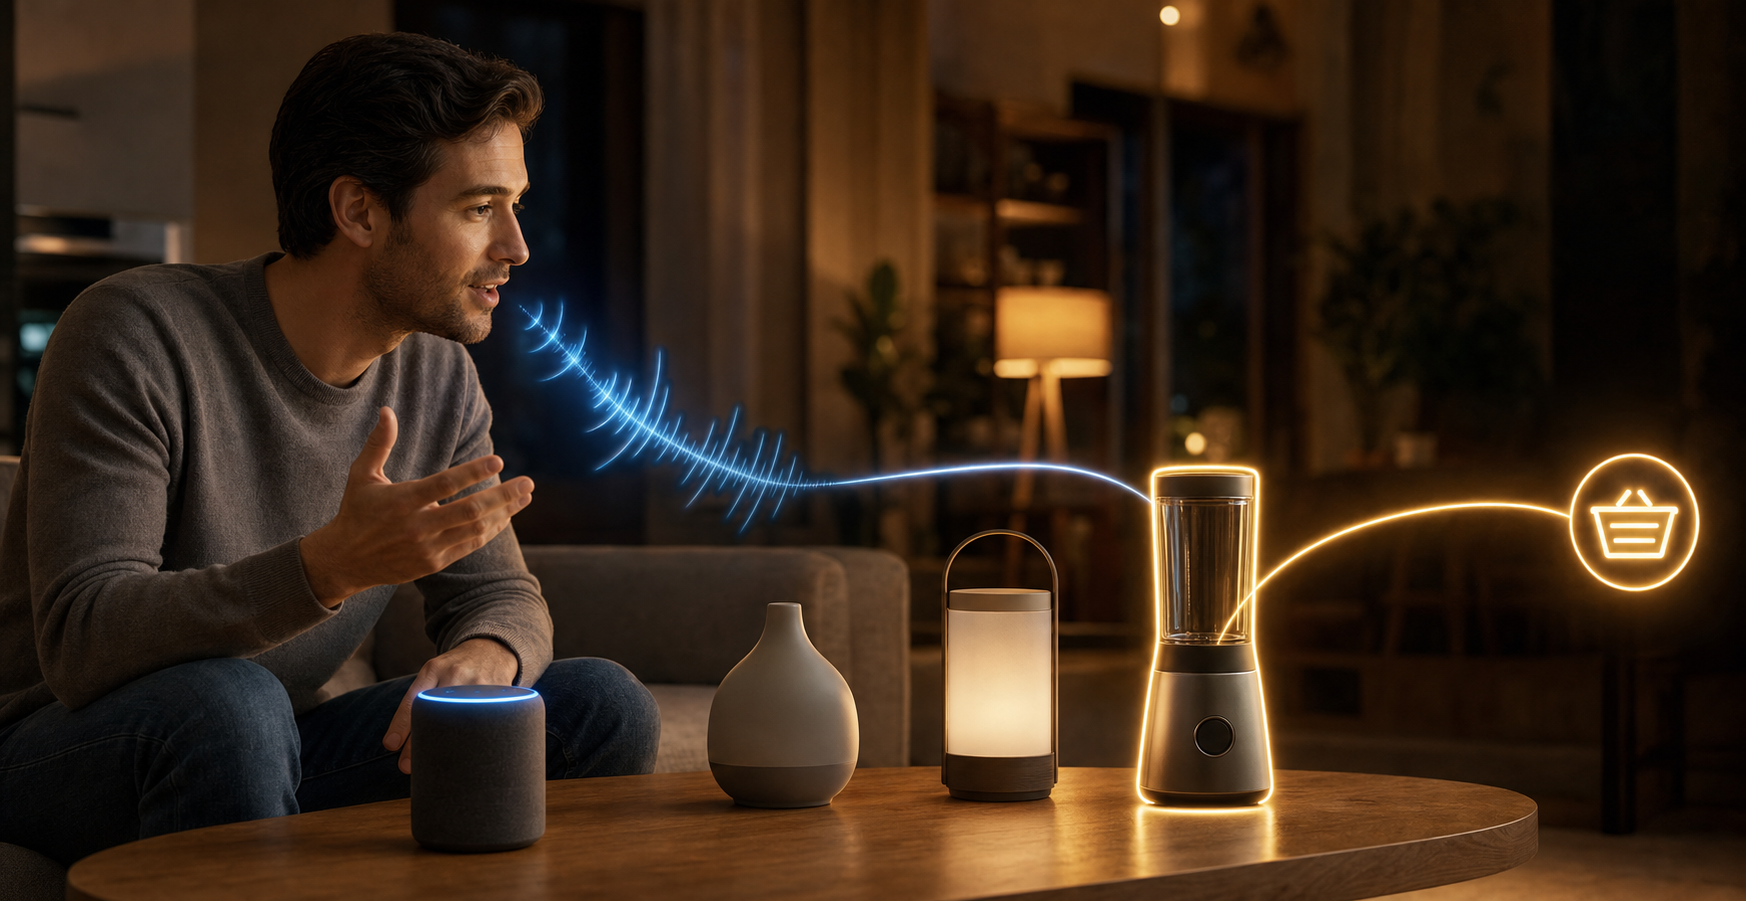
    A person speaks to a home voice assistant as a glowing path connects the conversation to an unbranded product and a purchase token.

    The report on Alexa+ Agentic Ads describes a format in which a person can encounter an offer, ask questions, compare options, check availability, and complete a purchase without leaving the Alexa conversation. The reported initial applications include dining and live events on Echo Show devices, with Papa Johns involved in food ordering and promotions connected to artists including Beck, Jill Scott, and Omar Courtz.

    According to that report, concert tickets can be placed in a buyer’s Ticketmaster account after purchase. In the restaurant example, Alexa+ can use previous interactions and preferences when suggesting an order. These are reported examples of how the format operates, not evidence that it has already produced higher conversion rates.

    The strategic change is larger than the addition of voice controls. A conventional digital ad commonly hands the customer to a separate site or application. In the Alexa+ model, the assistant can become the ad surface, product guide, and transaction interface. Amazon reportedly aims to reduce the abandonment associated with that handoff, but the source provides no campaign results with which to assess the effect.

    This model changes what an advertiser must prepare. Creative still has to generate interest, but the experience also depends on structured product information, current availability, clear choices, and a reliable transaction process. Brands therefore need to evaluate the quality of the conversation as carefully as the initial promotion. They also need explicit rules for recommendations, confirmations, and situations in which the assistant cannot complete a request.

    YouTube is applying AI before campaigns reach the customer

    Amazon’s reported format applies AI at the moment of consideration and purchase. YouTube’s tools address an earlier set of decisions: what audiences are watching, which creators may be relevant, and how campaign creative might be improved.

    The YouTube report says Google Ads’ Insights Finder now supplies more detailed YouTube trend information in the United States. It also reports the addition of selected Brand Pulse metrics, intended to give advertisers a combined view of paid and organic activity. A Content & Creator Insights API is described as giving agencies and partners more information about creators and their audiences for planning and selection.

    Gemini-powered recommendations represent another layer. The source says these suggestions are expected to offer guidance on visuals and other creative elements for Demand Gen campaigns. The timing matters when evaluating the announcement: the reported trend, brand, and creator capabilities should be distinguished from the creative recommendations described as forthcoming.

    Used together, the tools could support a workflow that begins with identifying an emerging topic, continues through creator and audience research, and then informs media and creative decisions. That can shorten the distance between data and action. It does not, by itself, establish that a trend caused a result, that a creator produced incremental demand, or that an AI recommendation will improve performance. Those questions still require campaign-level evaluation.

    AI visibility reporting does not yet equal attribution

    The Google Search Console report covers a different measurement problem: whether and where a site appears in Google’s AI-driven search experiences. It says the AI performance report includes impressions as well as breakdowns by page, country, device, and date. The reported version does not include click data.

    Access was described as an incremental rollout. The source reported sightings for sites in the United States, India, Switzerland, and other markets beyond the United Kingdom. It also relayed Google’s statement that feedback was being reviewed as availability expanded. This makes the feature a developing reporting surface rather than a uniformly available measurement standard.

    The absence of clicks defines what the report can and cannot answer. Impressions can help a publisher monitor AI visibility, locate pages that are appearing, and compare patterns across the available dimensions. They cannot show whether exposure generated a visit, assisted a sale, or changed customer behavior. Visibility is an important diagnostic signal, but it is not a substitute for traffic, conversion, or incrementality evidence.

    This distinction also clarifies the relationship among the three reports. Search Console offers an exposure-oriented view, YouTube supports research and campaign decisions, and Alexa+ is designed to carry a consumer through a transaction. A single label such as “AI performance” can obscure those differences. Marketers should instead identify where each signal sits in the journey and avoid combining unlike measures into one headline indicator.

    A measurement model for AI-mediated advertising

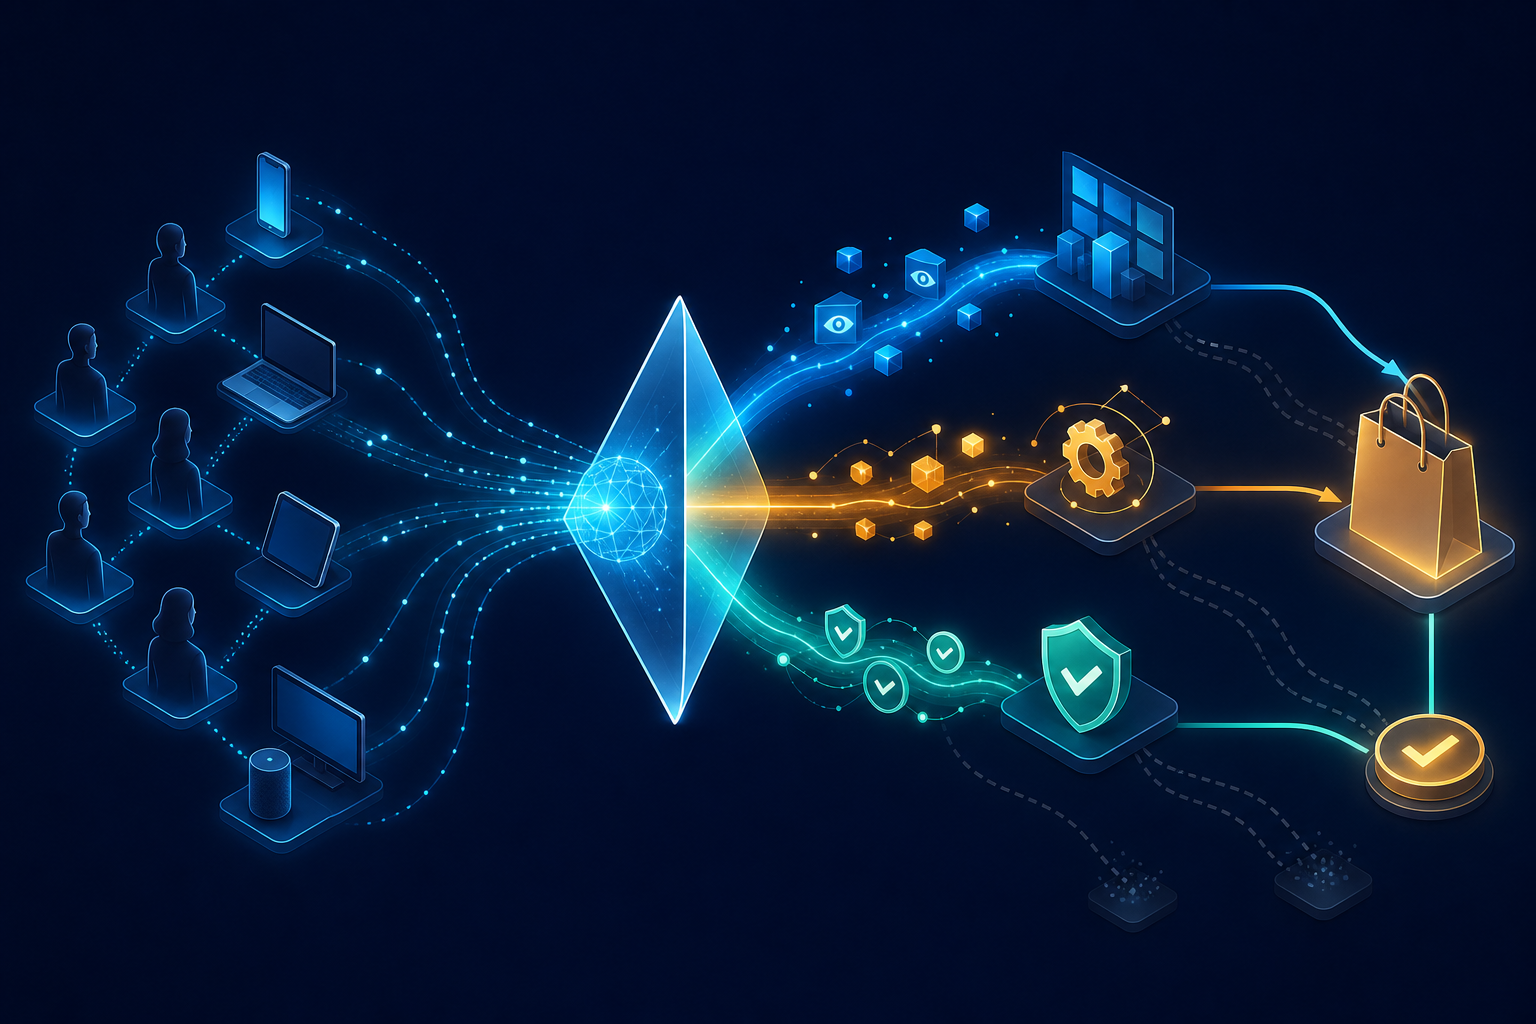
    An isometric illustration shows audience and device signals passing through an AI system, with some paths reaching a purchase outcome and others fading.

    Connect every signal to a decision

    A metric is most useful when its operational purpose is clear. AI-search impressions may guide content diagnosis, creator data may inform partnership research, and conversational-commerce outcomes may inform offer or transaction design. Assigning each signal to a decision prevents visibility, planning intelligence, and sales evidence from being treated as equivalent.

    Treat recommendations as testable hypotheses

    An AI-generated creative suggestion can accelerate analysis, but it should enter the campaign process as a hypothesis. Established methods such as controlled comparisons and consistent success criteria remain necessary to determine whether a proposed visual, message, or format improves the intended outcome.

    Measure the complete journey where possible

    Fewer interfaces can mean less customer friction, but they can also make familiar milestones less visible. Teams assessing an assistant-led purchase experience should establish which stages can be observed, how completed transactions are reconciled with campaign activity, and where the available platform reporting stops. Gaps should be recorded rather than filled with assumptions.

    Review the experience as well as the dashboard

    When an AI system explains an offer or recommends an option, its behavior becomes part of the brand experience. Evaluation should therefore cover the accuracy and clarity of responses, the handling of unavailable choices, and the transparency of purchase confirmation in addition to campaign metrics. This is especially important when the assistant performs several roles that were previously divided among an ad, landing page, product interface, and checkout.

    As these systems mature, the most durable advantage will come from measurement discipline: knowing when AI is acting as an interface, when it is supplying a planning signal, and when there is enough evidence to support a business conclusion.

    References

  • AI SEO Measurement: From Prompt Signals to Action

    AI SEO Measurement: From Prompt Signals to Action

    AI-era SEO measurement breaks down when a dashboard treats every generated answer as stable, every tracked prompt as representative, or every brand mention as a business result. A useful system must instead connect four questions: what people ask, how consistently AI systems respond, whether visibility changes user behavior, and what a team should do next.

    Together, the supplied reports point toward a practical operating model: observe real demand, sample variable responses systematically, connect visibility to outcomes, and convert findings into owned work. This approach extends established SEO measurement without pretending that AI answers behave like conventional rankings.

    Measure the demand behind AI visibility

    The first measurement problem occurs before an AI answer is generated: a tracking program must decide which prompts represent the audience. The prompt research summarized by CrushPress.AI suggests that the answer is not simply a library of elaborate, conversational questions.

    In a January 2026 Stella Rising survey cited by the publication, two-thirds of participants submitted prompts containing no more than 15 words, while about 12% produced what the researchers considered comprehensive prompts. The reported average for a basic shoe-recommendation scenario was eight words. The same article cited Semrush clickstream findings that placed average prompt length between 4.2 and 8.7 words. These reports indicate that short, keyword-shaped demand remains relevant even inside generative interfaces.

    Personal context creates a second demand layer. The January study reportedly found that 32% of users included details such as a role, situation, location, size, preference, or budget. Nearly a quarter used the word "best," while price language and "near me" phrasing also appeared. A brand may therefore be visible for a broad category prompt yet disappear when the request adds affordability, availability, suitability, or personal constraints.

    These results should be treated as directional. The article says the August 2025 research covered 178 members of a beauty-oriented community, whereas the January 2026 study covered 524 active AI users from a broader audience. Differences between the studies may reflect their samples as well as changing behavior. They do not establish a universal prompt distribution for every market.

    Design a prompt portfolio rather than a keyword substitute

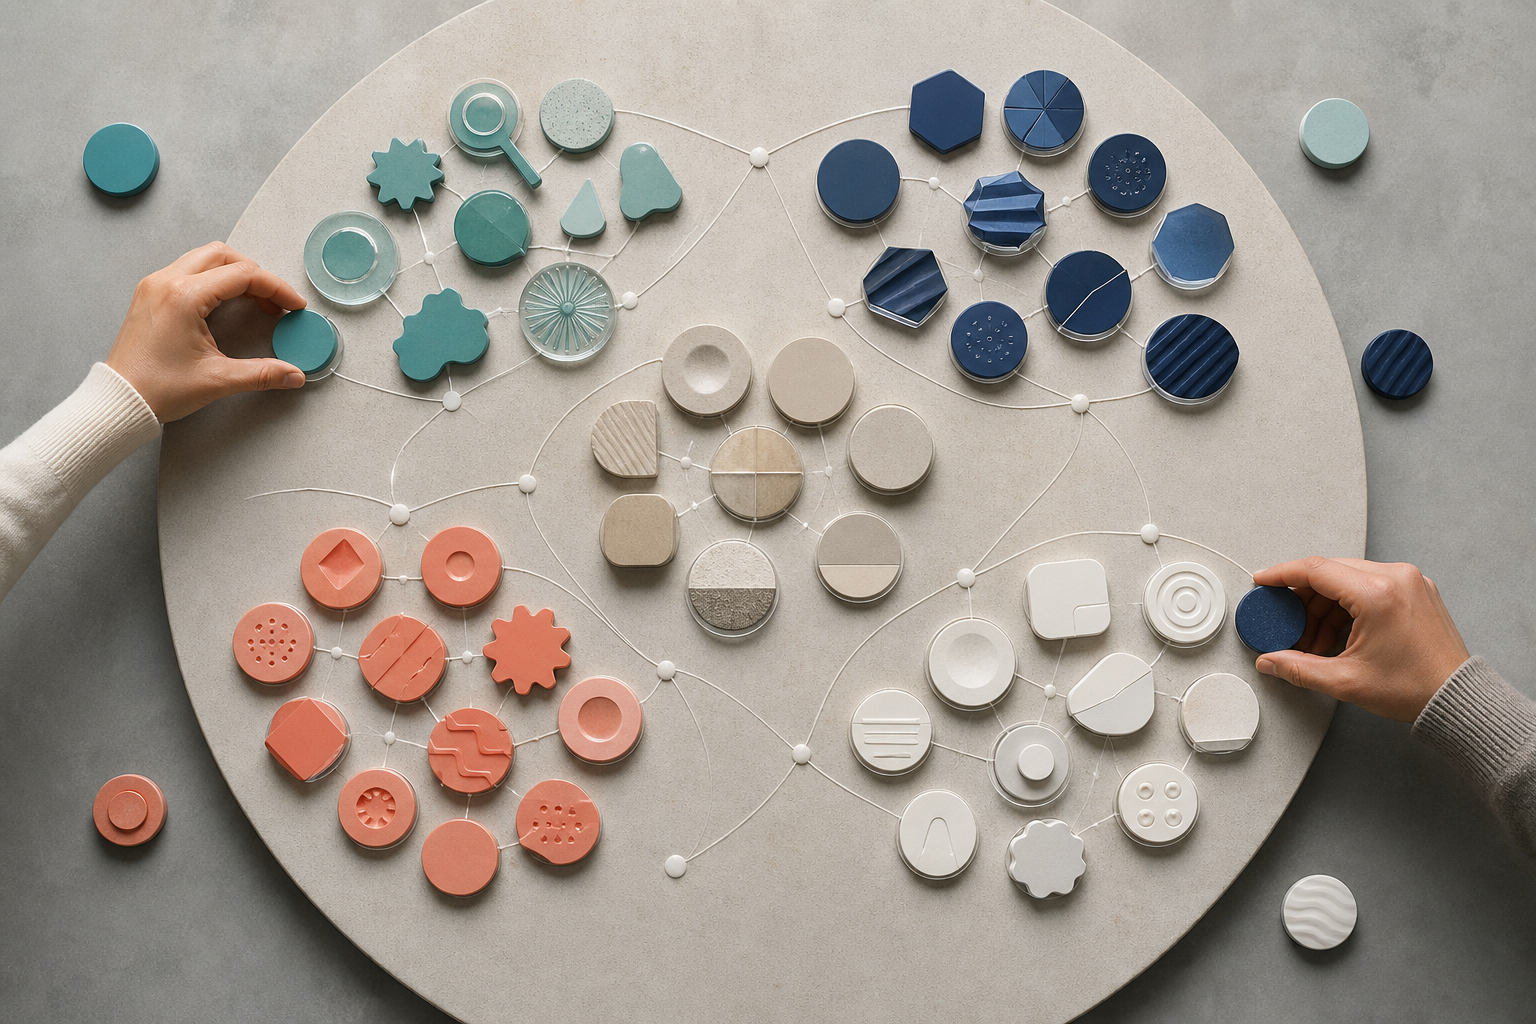
    Hands arrange varied icon-based prompt tokens into several intent groups on a circular table.

    A representative prompt set needs several complementary inputs. Replacing a keyword list with synthetic questions merely changes the format of the same sampling problem. The stronger approach is a portfolio that covers distinct ways demand appears:

    • Short retrieval prompts: category, brand, location, price, comparison, and "best" queries that resemble conventional search behavior.
    • Context-rich prompts: requests that combine a need with personal attributes, constraints, use cases, or purchasing conditions.
    • Synthetic persona prompts: controlled scenarios used to test how representation changes across audience profiles.
    • Conversational journeys: linked turns that move from discovery through evaluation and selection.

    Real prompt language can be informed by customer inquiries, support tickets, on-site search behavior, sales conversations, and traditional search data. CrushPress.AI’s prompt-behavior article recommends combining such evidence with synthetic personas because a fabricated profile cannot fully reproduce the accumulated context of an ongoing AI interaction.

    The prompt-tracking report adds another distinction: a single-turn test shows whether a brand appears at one moment, while a sequence can reveal whether that visibility persists as the user narrows the decision. Persistence is especially important when an initial mention does not survive follow-up questions about requirements, competitors, pricing, or fit.

    The resulting portfolio should be segmented rather than collapsed into one visibility score. Short prompts, contextual prompts, personas, and journeys represent different questions about demand. Combining them without labels can make a change in the sample look like a change in brand performance.

    Quantify variable answers without manufacturing certainty

    AI responses vary, so one generated answer is an observation rather than a durable rank. CrushPress.AI’s prompt-tracking article argues that this variability can be managed through repeated runs, fixed sampling rules, and confidence intervals. It compares the emerging discipline with fields such as opinion polling, where uncertainty is measured rather than ignored.

    A repeatable measurement specification should identify the platform, prompt wording, conversational context, sampling schedule, number of observations, market conditions, and scoring rules. It should also preserve the underlying responses so that changes in a summary metric can be audited. When a platform or testing condition changes, the report should mark the break rather than present the series as perfectly continuous.

    Each run can record several observable outcomes: whether the brand was mentioned, whether it was recommended, which sources were cited, which competitors appeared, and whether the brand remained present in later turns. The appropriate output is a distribution, rate, or range across the sample, accompanied by its limitations. A movement based on repeated observations deserves more weight than an isolated favorable or unfavorable answer.

    Cross-platform reporting requires similar restraint. The tracking article notes that visibility can differ among AI services and uses brand performance across ChatGPT and Perplexity to illustrate the issue. Platform-level results should therefore remain visible even when an aggregate is provided; otherwise, strength in one environment can conceal weakness in another.

    Connect AI exposure to traffic, outcomes, and evidence

    Uneven light paths connect an abstract AI interface to a website, user behaviors, collected evidence, and prioritized work cards.

    Visibility is an intermediate signal, not the final business result. The prompt-behavior report says many surveyed users still clicked citations, presenting AI mentions as possible gateways to websites rather than automatic endpoints. It also reports that 68% of respondents trusted AI recommendations more than Google’s and that half of active AI users engaged with AI tools daily. Those figures come from the cited January 2026 survey and should not be generalized beyond its stated audience, but they explain why recommendation quality and referral behavior warrant measurement together.

    A practical measurement chain separates four levels. Prompt coverage shows whether the test set reflects meaningful demand. Answer visibility shows whether and how the brand appears. Referral and behavioral data show whether cited exposure produces visits or engagement. Conversion measures show whether those interactions contribute to leads, purchases, subscriptions, or another defined objective. Not every organization will be able to connect every level, so reports should distinguish observed outcomes from inferred influence.

    This distinction also improves prioritization. A visibility gap for a commercially important, frequently observed use case may justify content or technical work. A fluctuating mention for a speculative synthetic prompt may justify continued observation instead. Confidence, audience relevance, business value, and implementation cost all affect the decision.

    The Conductor post offers a vendor-side example of shortening the distance between insight and execution: it describes Conductor AEO intelligence integrated into Optimizely with pre-built agents intended to act on findings. The announcement demonstrates the direction of workflow integration, but it does not independently establish that automated actions improve visibility or business performance. Any such workflow still needs approval rules, outcome measurement, and a record of what changed.

    Convert findings into owned, decision-ready work

    The final failure point is organizational. The reporting article argues that research becomes useful only when stakeholders can see the priority, business rationale, responsible team, next action, and measurement plan. AI visibility data increases this need because its uncertainty can otherwise become a reason to delay every decision.

    1. State the finding and its evidence. Identify the affected prompt segment, platform, sample, observed range, and relevant citations or responses.
    2. Explain the business consequence. Connect the finding to an audience need, commercial page, reputation risk, or measurable journey stage.
    3. Choose the smallest meaningful action. Specify the content update, technical correction, authority-building task, product-data improvement, or additional test required.
    4. Assign ownership and timing. Name the responsible function and define when the work and its follow-up measurement should occur.
    5. Set an evaluation rule. Define which visibility, referral, engagement, or conversion signal would support continuing, revising, or stopping the intervention.

    The level of detail should change with the reader. Executives need exposure, risk, resource requirements, and expected business impact. Marketing leaders need the connection to demand and campaigns. Content teams need page-level briefs and audience context. Developers need reproducible technical requirements. Supporting exports and response logs can remain available without overwhelming the main decision document.

    Key takeaways

    • Preserve short, search-like prompts while adding personal, situational, and conversational variants.
    • Use real audience evidence and synthetic personas for different purposes; neither is a complete sample alone.
    • Measure repeated observations, uncertainty, platform differences, citations, and conversational persistence.
    • Treat visibility as one stage in a chain that ends with an assigned action and a defined outcome signal.

    As AI interfaces become more personalized and optimization tools become more integrated, the durable advantage will come from disciplined learning loops. Teams that preserve evidence, acknowledge uncertainty, and make each finding operational will be better positioned to adapt their SEO programs as user behavior and answer systems evolve.

    References

  • Harnessing the Power of Profound for AI-Driven Marketing Success

    Harnessing the Power of Profound for AI-Driven Marketing Success

    I’ve discovered that Profound is the ultimate hub for marketers aiming to excel in the AI-driven landscape. It’s where I run my visibility, sentiment, and accuracy analyses.

    This platform is my go-to for building marketing Agents and uncovering new opportunities. It’s here that I generate innovative content and take action based on deep insights.

    Given all these functions, it’s only natural that Documents have found a home here too. Profound seamlessly integrates document management into my existing marketing workflow.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot
  • AI Brand Sentiment Intelligence: Turn Signals Into Action

    AI Brand Sentiment Intelligence: Turn Signals Into Action

    Your AI visibility dashboard says brand sentiment declined. That sounds urgent, but it doesn’t tell you whether an answer contains a factual error, repeats a legitimate customer complaint, favors a competitor, or simply uses cautious language.

    You need the explanation behind the label. Basic monitoring may reveal whether sentiment moved, even at the platform level, while leaving the cause and next action unresolved. AI brand sentiment intelligence closes that gap by connecting each signal to evidence, business impact, ownership, and a response you can test.

    Separate sentiment from the signals around it

    A positive, neutral, or negative label is only the start. Before acting, separate five questions that dashboards often compress into one score.

    Was your brand present?

    An answer cannot influence perception of your brand if it never mentions you. Track visibility separately from sentiment. A favorable description appearing in a small fraction of relevant answers is a different problem from broad visibility paired with unfavorable framing.

    What position did the answer take?

    Capture the exact wording that creates the impression. Terms such as expensive, specialized, complicated, reliable, established, or suitable for beginners carry different implications. A seemingly neutral qualification can matter more than an obviously negative adjective when it discourages the reader from considering your product.

    Was the claim accurate?

    Accuracy and sentiment need separate fields. An unfavorable statement may be accurate. A favorable statement may be wrong. Labeling both dimensions prevents your team from treating a product problem as a messaging problem or celebrating praise that could later undermine trust.

    What appears to drive the claim?

    Look for recurring themes and cited evidence. Pricing, reliability, customer support, security, ease of use, market position, and product fit are drivers. Positive or negative is the output. The driver is what gives you something to change.

    Could the wording change a decision?

    Not every unfavorable mention deserves escalation. Give priority to answers shown for prompts that influence evaluation, comparison, risk assessment, and purchase. A minor criticism attached to a low-relevance query may matter less than a cautious recommendation delivered when a buyer asks for a shortlist.

    Build a diagnosis workflow your team can repeat

    An isometric investigation workspace routes abstract AI response tiles through triage, evidence review, impact assessment, and team ownership stations.

    Start with decisions, not random brand prompts

    Create a stable prompt set around the questions your audience asks while discovering, evaluating, comparing, and validating a purchase. Include unbranded category questions, brand-specific questions, direct comparisons, use-case prompts, and risk or objection prompts. This reveals whether the narrative changes with user intent.

    Keep the core wording stable so later runs remain comparable. Record the platform, model or experience when visible, date, prompt, complete answer, relevant passage, citations, competing brands, and sentiment label. AI responses can vary between runs, so preserve the answer itself rather than storing only a dashboard score.

    Classify the reason before assigning the owner

    Give each meaningful passage a primary driver and, where needed, a secondary one. Keep the taxonomy small enough that two reviewers can apply it consistently. When everything becomes its own theme, you cannot see patterns. When every issue is simply called reputation, nobody knows what to fix.

    Add an evidence status: supported, unsupported, outdated, ambiguous, or not yet verified. Then record where the claim appears to come from, such as your own site, a review platform, editorial coverage, a community discussion, or an unidentified origin. This turns a vague perception problem into an evidence map.

    Prioritize patterns, not isolated answers

    Review a finding across relevant prompts, AI experiences, and repeated runs before treating it as a narrative shift. A single answer is evidence to inspect, not a trend by itself. Give each recurring issue a priority based on audience relevance, potential decision impact, recurrence, factual confidence, and your ability to change the underlying condition.

    Your working record should end with an owner and a next action. Product teams can address real capability gaps. Customer experience teams can address service patterns. Communications teams can correct public facts. SEO and content teams can improve discoverability, clarity, comparison content, and machine-readable entity information. Legal or compliance teams should review sensitive claims rather than leaving marketers to interpret them alone.

    Match each sentiment driver to the right intervention

    Four abstract sentiment problems surround a central diagnostic hub, each paired with a different corrective tool or mechanism.

    Correct factual gaps at the canonical location

    If AI answers repeat an incorrect price, feature, policy, location, or company relationship, first make the correct fact explicit on the page that should own it. Use consistent wording across important profiles and supporting pages. Add appropriate structured data when it accurately represents visible page content, but don’t treat schema as a guarantee that an AI system will adopt the correction.

    Make the correction easy to extract. State the fact directly, give it a clear heading, include necessary qualifications nearby, and show when time-sensitive information was updated. If multiple official pages disagree, resolve that conflict before producing more content.

    Fix substantiated criticism before trying to outrank it

    When unfavorable framing reflects real customer experience, the durable response begins outside SEO. Document the operational issue, route it to the team that can change it, and publish clear information about the remedy only when the facts support that message. More promotional copy will not neutralize a pattern that customers continue to confirm.

    Strengthen weak or generic positioning

    If AI systems describe your brand accurately but generically, clarify who the product serves, what problem it handles, when it is a strong fit, and where it is not. Create comparison and use-case pages that answer the criteria buyers actually evaluate. Support claims with verifiable details rather than broad superlatives.

    This is also where competitor context matters. Do not chase every favorable phrase attached to another company. Identify the decision criterion behind it. If a competitor is repeatedly preferred for ease of implementation, decide whether you need a better implementation experience, clearer documentation, stronger independent evidence, or a more precise statement of the segment you serve best.

    Treat absence as its own problem

    A brand that is missing from relevant recommendations does not have a sentiment problem yet; it has a representation or discovery problem. Check whether your entity is described consistently, whether important product and company facts are accessible, and whether credible third parties discuss you in the contexts you want to enter. Measure visibility gains before expecting sentiment gains.

    Validate movement without confusing noise for progress

    Establish a baseline before making a change. Preserve the prompt set and evidence records, then document the intervention: which page changed, which operational issue was addressed, which claim was clarified, and when the change became public. Without that change log, later movement is easy to misattribute.

    Re-run the same core prompts and examine several layers. Did brand visibility change? Did the relevant claim change? Did the driver appear less often? Did citations shift? Did the recommendation outcome change? A higher positive-sentiment share is useful only when you can connect it to meaningful language and buyer-relevant prompts.

    Keep discovery prompts separate from your fixed measurement set. New prompts help you find emerging narratives, while stable prompts help you compare performance. Combining both into one score can make normal changes in the prompt mix look like a brand shift.

    Report uncertainty plainly. Distinguish a repeated pattern from an isolated observation, and a verified error from an interpretation. Your stakeholders should be able to open any reported issue and see the prompt, answer passage, classification, evidence status, owner, intervention, and subsequent result.

    Key takeaways

    • Track visibility, sentiment, accuracy, narrative drivers, and decision impact as separate fields.
    • Use a stable set of prompts tied to real discovery, evaluation, comparison, and risk decisions.
    • Preserve complete answers and citations so every label can be audited.
    • Prioritize recurring, buyer-relevant patterns instead of reacting to one generated answer.
    • Route factual, operational, positioning, and discovery problems to different owners.
    • Measure the language and recommendation outcome that changed, not just the aggregate score.

    Begin with one important prompt group and one recurring narrative driver. Capture the evidence, name the owner, make the smallest credible intervention, and test the same prompts again. That cycle turns AI sentiment from an alarming dashboard indicator into a manageable brand intelligence practice.

    References

  • Unveiling Google Search Console’s AI Controls and Reports

    Unveiling Google Search Console’s AI Controls and Reports

    As someone who eagerly follows Google’s updates, I was thrilled to learn about the latest developments in Google Search Console. Recently, Google has started to roll out new Search Generative AI performance reports. These reports, along with a feature to block your content in AI responses, are designed to give website owners more control.

    Currently, these features are being introduced to a select group of website owners in the UK, but there are plans to expand access in the near future. This gradual rollout allows us to get accustomed to these changes before they become widely available.

    Exploring the Search Generative AI Performance Report

    The new AI performance report in Google Search Console is something I’ve been anticipating. Although it doesn’t cover everything, it does provide some important insights into how our content is performing within AI responses, AI Mode, and AI Overviews on Google Search. The report includes data on impressions, pages, countries, devices, and dates. However, a notable omission is click data, so we’re left guessing about the exact number of searchers clicking through to our sites from AI responses.

    Google stated:

    – We’re rolling out new insights for website owners regarding their pages’ appearances in generative AI Search features. These insights include impressions metrics and information on which pages appear in AI responses and in which countries. We’re working closely with website owners to determine what insights would be most helpful and will expand the metrics available over time. 

    Additionally, Google shared more details about the metrics we can expect:

    – Impressions: Frequency of your site’s URLs appearing in generative AI features in Search and Discover.

    – Pages: Identifying URLs that appeared within AI features.

    – Countries: Understanding visibility on a country basis.

    – Devices: Identifying the devices used to view your website. Available for Search results.

    – Dates: Monitoring performance with hourly, daily, weekly, and monthly granularity.

    I inquired about click data from a Google representative, who mentioned that they are exploring additional metrics that will help inform our strategies in the future.

    Initially, this report is available to a subset of users in the UK, with plans to expand globally in the future.

    If you want to explore more about this report, I recommend checking out the Google help center document.

    Introducing AI Blocking Controls

    Another exciting feature Google introduced is the ability to block your content from appearing in AI search features like AI Overviews, AI Mode, or AI Discover. Google described this as a “new toggle” within Google Search Console, allowing us to decide whether or not our site should be part of these AI search features.

    Google notes that opting out will prevent your site from receiving traffic or impressions from these features. Importantly, this control won’t affect your ranking in standard search results outside of generative AI Search features, so there’s no risk of negatively impacting core web search visibility.

    Again, like the performance report, this toggle is currently available to a subset of UK website owners, with plans to widen access as they complete further testing. Google had promised these controls after facing some backlash from the EU, and it’s promising to see them starting to roll out now.

    One study even showed that 1/3rd of SEOs are willing to block Google from showcasing their content in AI search features.

    Why It Matters

    As site owners and publishers, many of us have been asking for control over how and if our content appears in Google’s AI features. Now, we have just that. Although it’s initially limited, I’m hopeful these features will eventually be available to all.

    Moreover, we’ve been requesting AI Search reporting from Google from day one. With Google’s announcement following Bing’s release of its own AI performance report, we’re taking a significant step forward. While Google’s report currently targets UK site owners and lacks click data, it holds promise for a global rollout soon.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Use Google’s AI Audience and Shopping Insights

    How to Use Google’s AI Audience and Shopping Insights

    You can have plenty of Google data and still not know what to change. One screen points to people who may not know your brand. Another shows signals about your products in AI-assisted shopping. The hard part is turning those signals into decisions without mistaking automation for proof.

    The useful approach is to give each tool one job. Use audience targeting to test whether you can reach genuinely new people. Use shopping visibility insights to find product information that deserves investigation. Then measure whether either change produces incremental customers, not just more activity.

    Separate the audience question from the product question

    Google’s audience and shopping tools solve different problems. Combining them into one vague “AI performance” score makes both harder to use.

    The audience question is: are you spending money on people who have never meaningfully encountered your brand? Google’s “new prospects” targeting mode is intended to focus spending on that cold audience. It automatically excludes previous purchasers, branded searchers, website or app visitors, and people who engaged with brand content across Google and YouTube.

    The product question is different: where does your catalog appear weak, unclear, or absent when AI helps shoppers discover products? AI shopping visibility insights in Merchant Center can give you a place to begin that investigation. Visibility is a diagnostic signal. It isn’t the same as a click, a sale, or incremental revenue.

    Keep those questions separate in your reporting. Label one workstream “new audience acquisition” and the other “product visibility.” You can connect them later, but only after each has a clear baseline and success measure.

    Make prospects mode testable before you switch it on

    Two parallel shopper pathways represent a controlled test of reaching new prospects against a comparison group.

    Prospect targeting is only as credible as the signals used to identify people who already know you. If purchase records, site visits, app activity, branded searches, or video engagement are incomplete, some familiar users may be classified as prospects.

    Before using the mode, write down what “new” means for your business. A first-time buyer is not always a brand-unaware person. Someone may have watched a product video, visited through an untagged link, searched for your brand on another device, or bought through a channel that doesn’t return customer data to your advertising setup. You won’t eliminate every gap, but naming them prevents false confidence.

    Check whether your purchase data covers the channels that matter, whether website and app activity is captured consistently, and whether your brand-term set includes common names and variants. Review which Google and YouTube engagements count as prior contact. If a major signal is missing, fix it or record the limitation before interpreting campaign results.

    When the mode is available in your account, compare it with a relevant baseline rather than with your entire advertising program. Keep the offer, landing experience, product scope, and conversion definition as stable as practical. Otherwise, you won’t know whether a result came from reaching colder people or from changing several variables at once.

    Turn Merchant Center visibility signals into product fixes

    An analyst improves generic product imagery and information while reviewing differing levels of shopping visibility.

    An AI visibility signal should trigger a product-level inspection, not an immediate budget change. Start with products that matter commercially and look for repeatable patterns. A single weak result may be noise. The same weakness across a product family is a better reason to act.

    What you noticeWhat to inspectWhat to do next
    An important product has weak visibilityIts feed record and product pageCheck whether the name, description, attributes, price, availability, and identifiers are complete and consistent.
    One product family performs differently from similar itemsFields and page content that differ across the familyDocument the differences, then correct the clearest information gap before changing bids.
    Visibility changes after a catalog updateThe exact fields and pages changedConfirm that the update propagated correctly and watch whether the pattern persists.
    Visibility looks healthy but sales do notOffer competitiveness, landing-page clarity, and conversion trackingTreat discovery as adequate and investigate what happens after the product is surfaced.

    Consistency matters because a shopping system must reconcile information from your catalog and your site. Product titles should identify the item clearly. Descriptions should answer concrete buying questions. Price and availability should agree wherever they appear. Product structured data should describe the same offer shown to a person on the page.

    Don’t rewrite an entire catalog because a dashboard changed. Choose a coherent group of products, record the problem, make one class of improvement, and note the date. That creates a usable change log even when the interface doesn’t provide a causal explanation.

    Measure incremental customers, not convenient conversions

    AI targeting can look efficient while capturing demand that would have arrived anyway. Your measurement plan therefore needs to distinguish a new customer from a new prospect and both from a returning customer.

    Use the strongest customer-status data you have at the point of conversion. Compare acquisition cost, new-customer volume, revenue quality, and return behavior with your established baseline. Also monitor total business outcomes. A campaign-level improvement is less persuasive if overall new-customer growth stays flat.

    Value settings can materially affect optimization. Advertisers using New Customer Acquisition Value Mode saw a 9% improvement in return on ad spend when they valued a new customer at twice the average order value. Treat that as evidence that value signals matter, not as a universal setting or promised result. Your assigned value should reflect your own economics.

    Shopping visibility belongs in the same decision process but not in the same success column. It can help explain where product discovery may be constrained. Revenue and verified customer status tell you whether fixing that constraint was worthwhile. If visibility improves without a commercial effect, investigate the offer and purchase journey before declaring the work successful.

    Key takeaways

    • Use prospects mode to answer whether you can acquire genuinely brand-unaware customers, not merely people who haven’t purchased.
    • Audit purchase, branded-search, website, app, Google, and YouTube signals before trusting automated exclusions.
    • Treat Merchant Center AI visibility as a diagnostic input that points you toward product-data and page checks.
    • Change one coherent product group at a time and keep a dated record of what changed.
    • Judge the work by incremental customer and business outcomes, not visibility or campaign efficiency alone.

    Start with one acquisition campaign and one commercially important product group. Define the baseline, document the data gaps, and make the smallest change that can answer a real question. Google’s AI can help you find audiences and surface patterns; your measurement discipline determines whether those patterns become growth.

    References

  • How to Evaluate AI-Powered Advertising Platforms

    How to Evaluate AI-Powered Advertising Platforms

    You’re probably not deciding whether AI belongs in advertising. You’re deciding how much of your budget, product catalogue and campaign analysis you can safely hand to it.

    The useful question is not, “How advanced is this platform?” It is, “Which decision will this platform improve, what data will it use, and what can it change without approval?” Answer those three points before you compare features.

    Key takeaways for your platform decision

    • Separate AI that explains performance from AI that creates or delivers ads. The second category carries more financial and brand risk.
    • Treat your product feed, conversion events and campaign rules as operating inputs, not setup details. Automation scales their errors as readily as their strengths.
    • Use prompt-driven dashboards to shorten investigation time, but verify filters, totals and metric definitions before changing spend.
    • Test one bounded workflow at a time. Define its inventory, budget, approval rights, primary outcome and stop condition before launch.
    • Judge the platform on business outcomes and control, not on how quickly it produces an ad, chart or answer.

    Separate decision support from automated execution

    “AI-powered advertising” describes several different jobs. Combining them into one category makes platform evaluations fuzzy and permissions unnecessarily broad.

    AI roleWhat you provideWhat it producesMain risk to check
    Reporting and interpretationAccount data, a question and reporting filtersA chart, table, breakdown or explanationA plausible answer built on the wrong scope, filter or metric
    Ad assemblyProduct data, images, attributes and eligibility rulesAds assembled from approved inputsIncorrect or unsuitable catalogue data appearing at scale
    Delivery and optimizationA budget, objective, conversion signal and constraintsBids, placements or allocation decisionsSpend being optimized toward a weak or misconfigured signal

    Google Ads’ Gemini-powered dashboards sit primarily in the first row. Advertisers can use prompts to customize views, while the dashboard presents performance through charts, graphs and tables that update with the query. That can reduce the work required to reach a useful breakdown, but it does not give the dashboard permission to define your business objective.

    ChatGPT’s product-feed advertising moves further into execution. Retailers can connect catalogue data so the system can assemble sponsored product ads from names, images and other attributes. Retailers can also set rules governing which products may be featured. Here, data quality and eligibility rules directly affect what a prospective buyer can see.

    Before granting access, write down four permission levels: read, recommend, create and spend. A reporting assistant may need only read access. A product-ad system needs approved data plus creation rules. A bidding system needs a tightly defined budget and a trustworthy conversion signal. Do not grant all four levels merely because one integration supports them.

    This distinction also clarifies ownership. Your analyst can own reporting questions. Merchandising should own product eligibility. Marketing and finance should agree on spend limits. Whoever owns the business outcome should approve the conversion definition. “The AI team owns it” is not an operating model.

    Audit the data contract before evaluating the AI

    Two analysts inspect customer, product and campaign data moving through a transparent pipeline with permission, quality and verification controls.

    An automated platform can only act on the facts and signals it receives. If a product is misidentified, an image is stale or a conversion fires at the wrong moment, faster automation creates a faster version of the wrong campaign.

    For a feed-based commerce channel, inspect the feed as a contract between your catalogue and the advertising system. Review it in the same form the platform will receive it, not only as it appears in your storefront.

    1. Confirm item identity. Each product and variant should be distinguishable. If two records appear identical to a machine but represent different options, ad assembly can select the wrong one.
    2. Check customer-facing facts. Review names, images and every connected attribute for accuracy. Compare the resulting destination page with the feed record so the promise in the ad matches the page.
    3. Define eligibility explicitly. Create rules for products that may be advertised and exclusions for products that should not be. Do not rely on someone remembering to remove an unsuitable item manually.
    4. Assign update ownership. Name the system or person responsible for correcting catalogue facts. A feed without a clear owner becomes stale infrastructure.
    5. Design failure handling. Decide whether questionable or incomplete records are excluded, held for review or corrected upstream. Silent substitution is a poor default when brand or pricing information is involved.
    6. Keep an audit trail. Record which feed version, rules and approvals were active when an ad ran. Without that record, you cannot separate a platform problem from an input problem.

    This matters beyond paid placement. ChatGPT’s model allows product information to support both answers and advertising, connecting organic product discovery with a paid campaign workflow. The operational lesson is larger than one channel: machine-readable product facts are becoming shared discovery infrastructure.

    Your product feed and on-page structured data should therefore agree, but do not treat them as interchangeable. A channel feed supplies data to a specific system. JSON-LD describes information on a page in a machine-readable form. Keep names, product identity, images and other shared facts consistent across both, while using the integration method the advertising platform actually documents. Do not assume that publishing schema automatically enrols a product in an ad programme.

    For non-commerce campaigns, the equivalent data contract is your measurement setup. Identify the event that represents the business result, the events that are merely steps toward it and the system responsible for recording each one. If the platform sees a click but not the qualified action that follows, it may become efficient at producing visits without becoming effective at producing customers.

    Use conversational dashboards as an investigation layer

    Prompt-driven reporting changes how you reach a view, not what makes that view trustworthy. A natural-language interface can remove report-building friction, but the underlying questions still need a metric, dimension, scope and comparison.

    The Gemini-powered Google Ads dashboard is designed to show metrics including impressions, clicks, video views and costs across devices, audiences and campaign types. Those combinations are useful because they let you move from “performance changed” to “where did it change?”

    Use prompts that describe a reporting operation. The following are question shapes to adapt, not guaranteed platform commands:

    • Show impressions, clicks and cost by device for the selected campaign type.
    • Break down video views and cost by audience, using the same campaign scope.
    • Compare clicks and cost across campaign types, then isolate the segment responsible for the largest difference.
    • Keep the same metrics and change only the device breakdown so the two views remain comparable.

    The discipline is in changing one analytical dimension at a time. If you alter the metric, campaign scope and audience definition in the same prompt, you may get an attractive chart without knowing which change produced the result.

    Build a short verification routine around every consequential finding:

    1. Read back the date range, campaign scope, filters and dimensions shown in the resulting view.
    2. Check the displayed total against the corresponding native account report before moving budget.
    3. Confirm that compared views use the same definitions and aggregation.
    4. Save the prompt or question alongside the resulting filters. Natural-language wording is part of the analysis and should be reproducible.
    5. Translate the observation into a testable hypothesis. “Mobile cost increased” is an observation; it is not yet an instruction to reduce mobile spend.

    Prompted reporting is most valuable when it shortens the path from a broad symptom to a precise segment. It is less useful when it becomes a substitute for measurement definitions or causal testing.

    Access and exact behaviour also need verification. The dashboard rollout was introduced with further details still expected at Google Marketing Live. Check what is available in your own account before retiring a custom report or external analytics workflow on the assumption that every required capability has arrived.

    Run a bounded pilot before expanding authority

    A campaign manager monitors a small AI advertising pilot enclosed by a transparent boundary, with human controls separating it from a larger campaign network.

    A good pilot answers a decision, not merely whether the software works. “The platform generated ads” proves that the integration ran. It does not prove that the ads reached appropriate buyers, produced incremental value or justified broader automation.

    1. Name one workflow. Test prompt-driven account diagnosis, feed-based ad assembly or automated delivery separately. Combining them makes failures hard to locate.
    2. Write the decision statement. Specify what you will expand, change or stop if the test succeeds or fails.
    3. Capture the existing process. Record its inputs, human effort, approval path and outcome metrics. Otherwise, “faster” and “better” have no comparison point.
    4. Limit exposure. Use a defined campaign or approved product subset, a controlled budget and explicit permissions. Automated advertising can spend real money or expose incorrect catalogue information, so set pause conditions before activation rather than during an incident.
    5. Lock the measurement contract. Choose one primary business outcome and document the conversion event, reporting source and attribution configuration used to evaluate it. Keep clicks, impressions, views and cost as diagnostic metrics rather than automatically treating them as success.
    6. Log human intervention. Record feed corrections, prompt revisions, exclusions, bid changes and manual pauses. A result that depends on constant rescue is not evidence of autonomous performance.
    7. Decide explicitly. Scale, revise, hold or stop. Do not let a pilot become permanent simply because nobody scheduled the decision.

    Match the test to capabilities that exist, not capabilities on a roadmap. ChatGPT’s advertising direction includes cost-per-click bidding and conversion tracking, while cost-per-action models were reported as still in development. A future buying model should not be included in the business case for a current pilot.

    Ask vendors and internal owners the same practical questions before you approve expansion:

    • Which source fields and conversion signals drive the system’s decisions?
    • Can you exclude products, audiences or campaign types without rebuilding the workflow?
    • Which actions require human approval, and which occur automatically?
    • Can you export the underlying data and reproduce a reported result outside the conversational interface?
    • How are sponsored placements distinguished from organic recommendations? In ChatGPT’s current product-ad format, the units appear beneath responses and remain labelled as sponsored.
    • What happens when feed data, conversion tracking or an integration becomes incomplete?
    • Can you pause execution without losing the configuration and evidence needed for review?

    Your next move should be narrow. If you manage a catalogue, audit one approved feed segment and its page-level structured data. If you manage campaigns, choose one recurring reporting question and test whether a prompted dashboard answers it accurately and reproducibly. Write the outcome, permissions and stop condition first. Broader authority should follow evidence, not the ease of the interface.

    References