Tag: AI Features

  • Google Chrome AI Mode: What Changes for Search and SEO

    Google Chrome AI Mode: What Changes for Search and SEO

    If you work in SEO, a new Google AI interface can look like an urgent ranking update. That is not the right conclusion to draw from Chrome AI Mode. The immediate change is to the searcher’s workspace: an AI response, webpages, open tabs, images, and files can now become parts of the same research session.

    Your practical task is to separate two questions. First, can AI Mode discover your page without help? Second, when someone opens or supplies your page as context, does it make the answer easier to verify? Chrome’s new interface makes both questions important, but they measure different kinds of success.

    Chrome AI Mode turns a search into a working context

    Traditional web research creates friction as the searcher moves among a results page, multiple tabs, downloaded documents, and notes. Chrome AI Mode reduces that switching by keeping more of the research context attached to the query.

    Side-by-side search keeps the answer and webpage visible

    On desktop, clicking a result in AI Mode can open the linked webpage beside the AI experience. The searcher can inspect the page, compare details, visit other relevant sites, and ask follow-up questions without abandoning the original context.

    That layout changes the moment at which your page is evaluated. A visitor does not necessarily arrive after leaving the AI answer behind. Your title, answer, qualifications, and supporting evidence may be judged while the generated response remains visible next to them. If the two conflict, the mismatch is easier to notice. If your page supplies a missing condition or clearer explanation, that is easier to notice too.

    Recent tabs can become query context

    On desktop and mobile, the plus menu on the New Tab page or inside AI Mode can bring recent tabs into a search. AI Mode can use that selected context to customize its response and recommend additional sites.

    This creates an important measurement boundary. If you add your own website as a tab and AI Mode then discusses it accurately, you have tested contextual understanding. You have not shown that the website would have been discovered from a cold query. Run those tests separately or you will mistake supplied context for organic AI visibility.

    Images and files can join the same task

    The plus menu can also combine tabs, images, and files such as PDFs in the prompt context. Canvas and image-creation tools are available through that menu as well.

    For a content team, this means a webpage may be compared with material that never appeared in the written query: a specification PDF, a screenshot, a chart, or another open page. Make each important asset understandable on its own. Give PDFs descriptive titles, label charts plainly, explain what an image proves in the surrounding copy, and keep terminology consistent across formats. Those practices help a person verify the material even when the surrounding AI behavior is uncertain.

    Availability also needs a qualifier. These Chrome-specific capabilities initially launched for U.S. English users. Do not assume every teammate, market, device, or customer can reproduce the same workflow. Record language, market, device type, and feature availability with every test.

    The SEO impact is behavioral, not a confirmed ranking change

    Chrome AI Mode changes how people can gather and examine information. The announced capabilities do not establish a new ranking factor, crawler requirement, or structured-data type. There is no sound basis here for a Chrome-specific schema, a new metadata field, or an emergency rewrite of every page.

    The useful SEO interpretation is narrower. Chrome is making contextual search and page-level verification easier. That creates three distinct outcomes you should track:

    • Cold discovery: your brand or page appears when the query begins without your site, tabs, or files being supplied.
    • Contextual synthesis: AI Mode uses your page correctly after the searcher deliberately adds it as a tab or file.
    • Verification: the searcher opens your page beside the answer and can quickly confirm, qualify, or reject the generated claim.

    Only the first outcome directly tests whether your content was discovered from the query. The other two still matter: they show whether the content is usable and trustworthy once it enters the session. But reporting all three as “AI rankings” would conceal what actually happened.

    This distinction also explains why a single screenshot is weak evidence. A response may depend on the recent tabs, images, or files that were added before the prompt. Preserve the prompt and the supplied context when you document a result. If you cannot reconstruct the session, you cannot tell whether the page was retrieved, supplied, or merely opened for confirmation.

    Audit pages for side-by-side verification
    A split-screen monitor shows an abstract AI answer beside a structured webpage, with a magnifying glass positioned between them for comparison.

    A page opened next to an AI response has a demanding job. It must orient the visitor quickly, answer the relevant question, and expose enough support for the visitor to decide whether the answer is reliable. A long page can still do this well; the requirement is clarity, not brevity.

    1. Start with a decision query. Use the question a customer asks when choosing, comparing, troubleshooting, or validating something, not just a short keyword.
    2. Open the most relevant page beside AI Mode on desktop. Check whether its visible title and opening copy make the subject and scope unmistakable.
    3. Locate the direct answer. The reader should not have to infer it from a broad introduction. State the answer before expanding into background, exceptions, or examples.
    4. Trace the important claims. Make sure a person can find the definition, limitation, comparison basis, or supporting detail that justifies each conclusion.
    5. Check context independence. A visitor may land on a subsection from an AI-assisted journey, so headings such as “Benefits” or “Options” are often too vague. Name the product, task, or decision in the heading when ambiguity is possible.
    6. Compare formats. If the webpage, PDF, image labels, and structured data describe the same entity, use the same names, attributes, and qualifications across them.
    7. Repeat the query without adding your site as a tab. Record whether the page is discovered cold, used only after being supplied, or opened only as supporting evidence.

    The structured-data check deserves restraint. Keep existing markup aligned with what a visitor can see on the page, and correct contradictions between markup and copy. Do not add invented properties or relabel established schema because an AI interface changed. Nothing in this Chrome feature set demonstrates a special markup shortcut into AI Mode.

    Pay particular attention to scope language. A direct answer can still mislead if the applicable market, product version, audience, prerequisite, or exception appears much later. Put a necessary qualification beside the claim it limits. That makes the page more useful when someone is comparing it with an abbreviated AI response.

    Use AI Mode for content QA without fooling yourself
    A content specialist compares an abstract AI panel with a webpage and source documents while using a magnifying glass and check tokens.

    Chrome AI Mode can support a disciplined content review, provided you control the context. The purpose is not to manufacture a favorable response. It is to find where your content becomes ambiguous, incomplete, or hard to verify.

    1. Begin with a clean query and no company-owned tabs or files included. Save the exact wording and note whether your page appears.
    2. Open a relevant result beside AI Mode. Compare the generated answer with the page’s actual wording, scope, and qualifications.
    3. Add only the tabs or files needed for the decision. A smaller context makes it easier to identify which material influenced the response.
    4. Ask follow-up questions about conflicts, missing conditions, and comparison criteria. Use the answers to locate weaknesses in the underlying pages, not as proof that the model is always correct.
    5. Remove the supplied context and run the clean query again. Differences between the two sessions reveal what depended on your added material.
    6. Log the test environment: desktop or mobile, language and market, query, included tabs, included files, pages opened, and observed result.

    Use the findings to repair the content itself. If AI Mode overlooks a qualification that is buried near the bottom, move that qualification next to the claim. If two pages use different names for the same feature, choose a canonical term and explain any necessary synonym. If a PDF contains the decisive evidence but the webpage barely identifies it, add a descriptive link and explain why the file matters.

    Do not optimize merely for the generated wording you happened to receive. Because selected tabs and files can change the context, a context-bound answer is not a stable template for future responses. Optimize the underlying facts, relationships, labels, and evidence that should remain correct across many possible prompts.

    Key takeaways

    • Chrome AI Mode can keep a webpage beside the generated response on desktop, making comparison and verification part of the same view.
    • Recent tabs can be added on desktop and mobile, while images and files such as PDFs can supply further context.
    • A favorable response after adding your own page tests contextual usefulness, not cold discovery or ranking.
    • The feature set does not establish a new ranking signal or Chrome-specific schema requirement.
    • Audit content for direct answers, visible qualifications, consistent terminology, and evidence that is easy to locate beside an AI response.
    • Initial availability was limited to U.S. English users, so document the market, language, device, and context behind every test.

    Start with the decision query that matters most to your audience. Test it once without supplied context and once with the relevant page or document added. The gap between those sessions will tell you whether your next priority is discovery, clearer content, or better supporting evidence.

    References


  • Google Data Studio Is Returning: What Marketers Should Do

    Google Data Studio Is Returning: What Marketers Should Do

    If you have a library of Looker Studio dashboards, the return of the Data Studio name raises three practical questions: Will your reports survive, should you rebuild anything, and which Google analytics product should your team use next?

    The immediate answer is reassuring: do not launch a manual migration project just because the name is changing. Existing reports, data sources, and other assets are expected to transfer automatically. Your useful work now is to classify what you have, confirm who owns it, and decide which assets belong in Data Studio, Data Studio Pro, or Looker.

    What the Data Studio revival actually changes

    Three years after Data Studio was folded into Google’s broader analytics offering and renamed Looker Studio, Google is separating the products again. This is more than a familiar label returning. The revived Data Studio is intended to become a central place for analysis assets across Google’s ecosystem.

    That asset model reaches beyond conventional reports and dashboards. It is also expected to encompass more advanced data applications created in Colab and conversational agents associated with BigQuery. For a marketing team, the practical benefit is a shorter path between finding an asset, exploring the underlying data, and acting on the result.

    Looker is not disappearing. It remains Google’s enterprise business intelligence platform for managed data, semantic modeling, and analytics at scale. Data Studio is being positioned for flexible exploration, ad hoc analysis, and accessible dashboards connected to services such as BigQuery, Google Sheets, and Ads.

    That distinction matters more than the brand change. A dashboard used by one marketer to investigate a campaign has different requirements from a company-wide revenue report whose metrics must mean the same thing in every department. The first is an exploration problem. The second is a data-governance problem.

    Some implementation details remain unsettled. Google plans to explain more about the relaunch and its wider analytics strategy at Google Cloud Next ’26. Treat the current direction as sufficient for planning, but not as a reason to assume that every interface, AI capability, or administrative option is already available.

    Choose the product by governance, not by dashboard size

    A central decision hub branches to self-service, managed team, and enterprise analytics workspaces with different access and governance controls.

    The cleanest routing rule is to ask how controlled the data must be. Do not choose solely by the number of charts, the sophistication of the design, or whether a report is viewed by an executive. A visually simple report can still require enterprise governance if it drives financial or operational decisions.

    ProductBest fitPrimary roleAccess model
    Data StudioIndividuals and small teamsQuick analysis, visualization, personal exploration, ad hoc reporting, and accessible dashboardsFree
    Data Studio ProLarger organizations that need stronger administrative controlsAccessible analysis with enhanced security, compliance, management controls, and AI featuresPaid licenses through Google Cloud and Workspace admin consoles
    LookerEnterprises managing shared definitions and analytics at scaleManaged data, semantic modeling, and enterprise business intelligenceSeparate enterprise platform

    Use free Data Studio when the work is exploratory and a person or small team can responsibly manage the report. Consider Data Studio Pro when access policies, compliance requirements, centralized administration, or organizational controls are part of the requirement. Keep Looker in the architecture when metrics need a governed semantic layer or the analysis operates at enterprise scale.

    Do not purchase Pro merely because its feature list includes AI. First identify the administrative or analytical problem you expect it to solve. Then wait for concrete product details and check whether the announced capability satisfies that requirement. Buying an edition before defining the requirement reverses the decision process.

    Audit your current reports without rebuilding them

    An analyst audits intact report cards by tracing them to owner, data source, access, and usage symbols in an organized workspace.

    An automatic transition removes much of the migration burden, but it does not repair an untended reporting estate. Orphaned dashboards, unclear metric definitions, obsolete campaign views, and credentials tied to former employees remain operational problems regardless of the product name.

    Run a lightweight audit before the transition:

    1. Create an inventory of business-critical reports. Record each report’s name, URL, owner, intended audience, connected data sources, expected refresh pattern, and the decision it supports.
    2. Classify each asset as personal exploration, team reporting, or governed enterprise reporting. If nobody can identify a decision the asset supports, mark it for review rather than automatically carrying it into your active reporting catalog.
    3. Assign a likely product lane. Personal and ad hoc analysis points toward Data Studio; reporting that requires enhanced organizational controls may point toward Data Studio Pro; shared metrics backed by managed models belong in Looker.
    4. Verify ownership and access. Automatic asset transfer does not make an absent owner accountable, document a metric, or restore a broken data-source authorization.
    5. Capture a baseline for critical outputs. Save the expected totals, date range, filters, and metric definitions you will use to check the report after the transition. Store any exported data according to your organization’s security rules.
    6. Pause rename-driven rebuilds. Continue fixing defects that affect decisions, but do not recreate a functioning report solely to anticipate the new branding when reports and data sources are supposed to carry over.

    After the transition, verify the reports that matter most instead of opening every dashboard at random. Check data-source authorization, refresh behavior, filters, calculated fields, sharing, and the baseline totals you recorded. That gives you a controlled acceptance test rather than a vague visual inspection.

    Build a reporting model that can survive the next rename

    Product names will change again. Your definitions, ownership, and decision process should not have to change with them. The durable approach is to separate the data, its agreed meaning, and its presentation.

    Keep metric meaning outside the dashboard

    A chart can display conversions, qualified leads, organic traffic, or AI-referred sessions without establishing what any of those terms mean. Record the definition, source, exclusions, time zone, and accountable owner separately. When a metric requires an enterprise-wide definition, manage that logic in the governed data or semantic layer rather than reproducing slightly different formulas across dashboards.

    Give every important report a decision contract

    For each recurring report, write down five things: who uses it, what question it answers, how fresh the data must be, who resolves discrepancies, and what action follows a meaningful change. A dashboard with no defined response is usually a display, not an operating tool.

    This contract also helps you select the right platform. A report used to investigate an unusual traffic pattern may need flexibility. A report used to approve budgets may need controlled definitions, permissions, and change management. The business consequence determines the governance level.

    Treat conversational AI as an interface, not a source of truth

    The expanded hub is expected to include advanced data applications and BigQuery conversational agents, while Data Studio Pro is expected to add AI features. These interfaces may reduce the effort required to ask questions of data, but they do not resolve ambiguous definitions. A fluent answer built on the wrong conversion definition is still the wrong answer.

    Before relying on an AI-generated analysis, check the data source, date range, filters, grouping, and metric definition. For consequential decisions, compare the answer with a governed report or a direct query against the approved data. Speed is useful only when the result remains traceable.

    Key takeaways

    • Do not manually migrate or rebuild reports merely because Data Studio is returning; existing assets are expected to transfer automatically.
    • Use Data Studio for free, flexible analysis by individuals and small teams.
    • Evaluate Data Studio Pro when security, compliance, centralized management, or its announced AI features address a defined organizational requirement.
    • Keep Looker where managed data, shared semantic definitions, and enterprise-scale analytics are essential.
    • Inventory critical dashboards now, assign accountable owners, document metric definitions, and record baseline outputs for post-transition checks.
    • Wait for the fuller Google Cloud Next ’26 details before making purchases or architecture changes that depend on a particular unconfirmed feature.

    Your next step is small: identify the reports that people actually use to make decisions, classify each by governance need, and document their owners and definitions. That work will improve your reporting whether the interface says Looker Studio, Data Studio, or something else later.

    References


  • Google Maps Contributor Features: A Practical Workflow

    Google Maps Contributor Features: A Practical Workflow

    You have useful photos on your phone and first-hand details about a place, but turning them into a clear Google Maps contribution still takes judgment. The latest contributor features reduce the mechanical work: they surface media sooner, draft captions and make contributor history more visible.

    Use that convenience to publish more useful evidence, not simply more content. A faster upload, an AI-written caption or a prominent badge can attract attention, but none of them can make a vague or inaccurate contribution trustworthy.

    Key takeaways

    • Local Guides profiles now place greater emphasis on total points, levels and badges. Gold profile indicators can make top contributors more noticeable, but prominence is not proof that every contribution is accurate.
    • Gemini can analyze selected photos and propose a caption. You can edit or discard the draft, so treat it as a starting point rather than an observation you must accept.
    • The Contribute tab surfaces recent uploads, while camera-roll suggestions can shorten the path from taking a photo to sharing it. Media access is required for those suggestions.
    • These features may affect which reviews and businesses receive attention. They do not, by themselves, establish a direct improvement in local rankings, AI-search visibility or business performance.

    Match each contributor feature to the job it actually does

    The contributor changes solve three different kinds of friction. Keeping those jobs separate prevents you from treating every feature as a ranking tool.

    • Contributor profiles provide context. The redesigned Local Guides profile displays total points and levels more prominently, gives badges a refreshed presentation and adds gold profile indicators for top contributors. These are reputation and attention signals around a contribution. They do not verify the claim inside it.
    • Gemini caption drafts reduce writing friction. The feature analyzes the photos you select and proposes text that you can edit or reject. Its useful job is getting you past the blank field, not supplying knowledge that the image cannot contain.
    • Media suggestions reduce retrieval friction. Recent uploads appear in the Contribute tab, and Google Maps can suggest camera-roll images after you allow media access. This helps when the obstacle is finding the right photo later.

    If you contribute regularly, test every photo or review without its profile decoration: would the content still help someone choose an entrance, recognize a storefront, understand the layout or set an accurate expectation? If not, more points and a brighter badge will not repair it.

    If you manage local visibility for a business, reverse the test. A gold indicator may cause a user to notice a review, but you should still inspect the review’s specificity, recency and visible evidence. Contributor status is context for evaluating a claim, not a substitute for evaluating it.

    Edit Gemini captions until they say what the photo proves

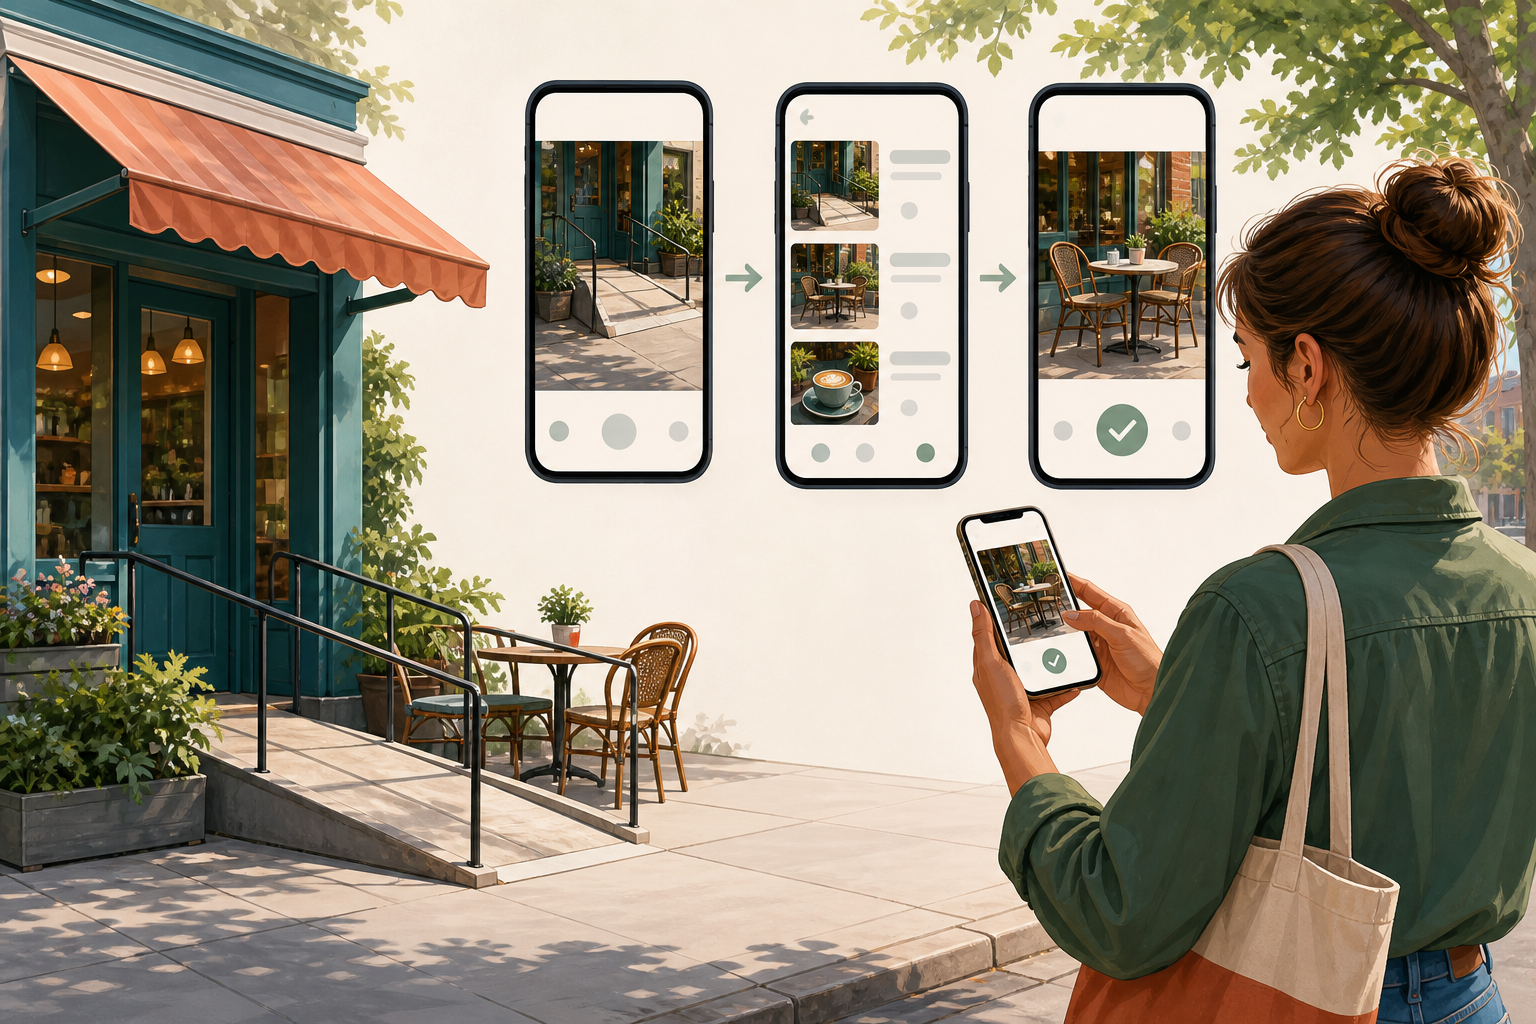
    A contributor compares a phone photo with a cafe's accessible entrance while editing a draft description.

    At its introduction, the Gemini caption feature was available in English on iOS in the United States. Broader Android and international availability was planned. Availability can therefore differ by device, language and location; keep a manual caption workflow even if another contributor already has the control.

    The most important limitation is conceptual. Gemini can analyze the selected image, but a photo does not necessarily prove how the service felt, how food tasted, whether a route is fully accessible or whether a temporary display will remain in place. The draft can turn a visual impression into a stronger claim than the evidence supports.

    Use a four-pass caption edit

    1. Name the visible subject. Identify the entrance, seating area, menu board, counter, parking area or other feature the photo is meant to show.
    2. Remove inferred praise. Delete generic judgments such as “excellent,” “welcoming” or “perfect” unless the caption is deliberately expressing your own experience and the wording makes that clear.
    3. Add decision-relevant context. Explain where the photographed feature is located or why someone might need to recognize it. Add only details you observed or verified.
    4. Check whether the claim will age badly. Prices, hours, displays and layouts can change. Do not present a time-sensitive detail as a permanent feature.

    For example, a draft such as “A cozy cafe with plenty of seating” is broad and evaluative. A more useful edit would be “Indoor tables are beside the front window, with the order counter at the back.” The second version tells a visitor what the image is intended to establish without pretending that the photo proves comfort, availability or service quality.

    There is also a quick test for generic AI text: ask whether the same caption could be pasted onto a different venue’s photo without anyone noticing. If it could, the caption is not finished. Name the concrete feature that makes this image useful at this place.

    Turn camera-roll suggestions into a controlled publishing queue

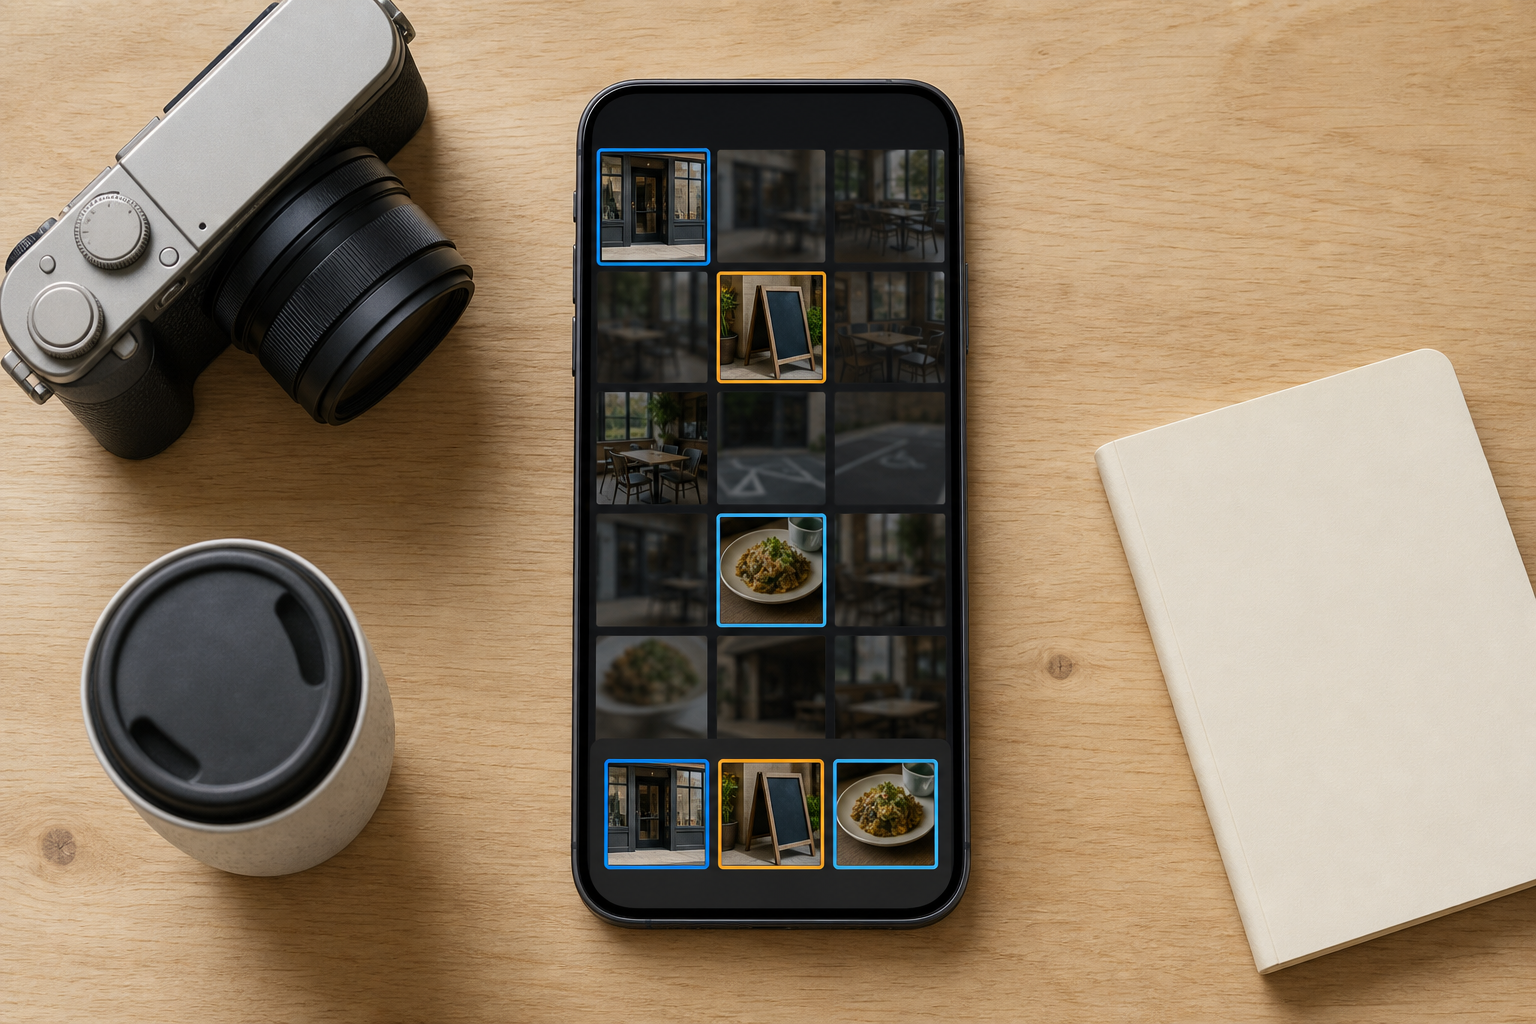
    A smartphone displays selected and dimmed place-photo thumbnails arranged as a controlled publishing queue.

    The media-sharing update has a broader footprint than the initial caption rollout. Recent media and camera-roll suggestions were made available on iOS and Android globally. Suggestions depend on granting media access.

    A suggestion is an invitation to review an image, not confirmation that the image belongs on Maps. Camera rolls also contain duplicates, screenshots, private details and photos whose location is ambiguous. Put a short verification step between the prompt and the publish button.

    1. Open the Contribute tab after a visit. Review the recent media while you can still distinguish the venue and remember what each image shows.
    2. Confirm the exact place. Check the name and location, especially when a business has several branches or neighboring listings look similar.
    3. Choose the highest-information image. Prefer a photo that answers a practical question over several nearly identical angles.
    4. Inspect the full frame. Exclude unrelated or sensitive details and any image too blurry, dark or obstructed to support its caption.
    5. Write or generate the caption. Apply the evidence test even when Gemini supplies the first draft.
    6. Read the listing and caption together. Make sure the text describes this image at this place, then publish only when both are unambiguous.

    If you are not comfortable enabling camera-roll access, do not enable it merely to save a few taps. A slower, deliberate selection process is better than a convenient workflow you will not review carefully. You can also revisit the relevant operating-system permissions if your comfort level or contribution habits change.

    Do not mistake contributor visibility for a ranking result

    More prominent contributor profiles, faster media sharing and clearer captions can change what people notice. That can influence which reviews they consider credible and which businesses receive attention. It is still a leap from increased attention to a claim that a feature directly raises a business in Google Maps, local search results or an AI-generated answer.

    Three outcomes need separate measurement:

    • Publishing efficiency: Did the recent-media flow help you turn relevant photos into completed contributions instead of leaving them in a backlog?
    • Contribution quality: Did the final captions become more specific, accurate and useful after editing, or did AI merely increase the volume of generic text?
    • Search or business visibility: Did the business’s observed visibility change after the contribution? If it did, record the timing as a correlation. Do not assign causation without isolating other listing, review, competition and search changes.

    The same restraint applies to AEO and GEO claims. A Google Maps caption may add useful public context around a place, but these contributor changes do not demonstrate that a frontier model will retrieve, cite or rank that caption. Treat any such effect as a hypothesis to measure, not a benefit to promise.

    Start with one recent photo that answers a real visitor question. Verify the place, edit the caption until every claim is supportable and record when you published it. If the workflow consistently produces clearer contributions, keep it. If it only produces more contributions, tighten the review step before you scale it.

    References


  • Meta Paid Subscriptions: A Decision Guide for Marketers

    Meta Paid Subscriptions: A Decision Guide for Marketers

    If Meta offers you a paid tier inside Instagram, Facebook, or WhatsApp, don’t start with the length of the feature list. Start with the recurring problem you need the subscription to solve. A premium control is valuable only when it changes a decision, removes meaningful work, or produces a measurable business result.

    That distinction matters because Meta is experimenting with several kinds of value at once: audience controls, deeper insights, AI creation capacity, and AI-assisted productivity. You need a way to evaluate each capability without assuming that payment automatically buys attention.

    What Meta is actually testing across its apps

    Meta is testing paid subscriptions on Instagram, Facebook, and WhatsApp. The core experiences are expected to remain free, and the experiments are being developed as app-specific offerings rather than one universal bundle.

    These subscriptions are also separate from Meta Verified. That is an important purchasing distinction. Verification-related value and access to premium creation, productivity, or audience tools should be evaluated as different products, even if they eventually appear next to each other in an account.

    Instagram’s initial candidates may include unlimited audience lists, information about non-followers, and stealth Story viewing. Treat those as provisional examples, not a promised package. A feature displayed in another account, market, or test does not belong in your business case until it appears in the offer available to you.

    AI is a larger part of the direction. Meta intends to give paying users greater access to its Vibes AI video generator through a freemium model. It also plans to embed the Manus AI agent in its apps and offer separate Manus subscriptions to businesses. Meta acquired Manus for $2 billion, and an Instagram shortcut has been reported as part of the prospective integration. The investment shows that AI is not merely a decorative subscription extra, but it still does not tell you which workflows the final products will support.

    Put every proposed feature into one of four practical buckets:

    • Control: who can see something, how an audience is organized, or how you interact with content.
    • Intelligence: information that can improve a content, audience, or campaign decision.
    • Production: tools or capacity that help create more usable assets.
    • Productivity: assistance that removes steps from a repeatable workflow.

    This classification gives each feature an owner and a measurement plan. It also exposes vague offers. If your team cannot identify the bucket, the recurring job, and the expected result, the feature is not ready for a budget.

    Paid access does not automatically mean greater reach

    An unbranded phone unlocks a set of premium tools while a distant audience remains the same size and distance away.

    Nothing in the subscription test description establishes that paying will give posts preferential ranking or guaranteed distribution. Do not build a forecast around an algorithmic advantage that Meta has not explicitly offered.

    A subscription could improve results indirectly. Better non-follower information might change what you publish. More AI video capacity might let you test additional creative ideas. Audience lists might make a recurring sharing workflow easier. In each case, however, the paid feature is only the first link in a longer chain:

    • Entitlement: your account receives access to the feature.
    • Adoption: someone uses it in a defined workflow.
    • Audience effect: the resulting content or interaction produces a different response.
    • Business effect: that response contributes to a qualified visit, lead, sale, retention outcome, or documented cost saving.

    Only entitlement follows directly from the transaction. You have to demonstrate the other three. This is why impressions, generation counts, and time spent inside a premium interface are weak success measures on their own.

    The same discipline applies to SEO, answer engine optimization, and generative engine optimization. A paid Meta tool may help you create or adapt content, but it does not by itself produce a durable, crawlable, well-supported answer on your website. It also does not guarantee that a search engine or frontier model will cite your brand. Keep social production and owned-content visibility as connected but separately measured systems.

    If reach is your goal, write the hypothesis in mechanism terms. For example: non-follower insights will reveal a recurring topic gap; the team will use that gap to revise its content plan; the revised content should increase qualified actions from people outside the existing audience. That can be tested. “Premium will increase reach” cannot.

    Decide whether a feature solves a paid-worthy problem

    A long menu makes an offer feel valuable even when most of its features will never enter your workflow. Replace feature counting with a written decision gate.

    Answer five questions before checkout

    1. What recurring job is difficult now? Name the work, the person doing it, and where the friction occurs.
    2. Does the available tier support that job today? Verify the in-account offer. Do not pay for a roadmap, a reported test, or a feature available only to someone else.
    3. What action will change? More data is not an outcome. Identify the content, audience, or operating decision that the new information will alter.
    4. What evidence will establish value? Choose a workflow metric and a downstream metric before activating the tier.
    5. What is the exit rule? Set the minimum result required for renewal and the condition that will trigger cancellation or another controlled test.

    If you cannot answer the third question, wait. A dashboard that creates no decision is another reporting obligation, not an intelligence advantage.

    Translate candidate features into proof

    Candidate capabilityProblem it could solveEvidence worth collectingCommon purchasing mistake
    Non-follower insightsUnderstanding how people beyond the current audience respondA documented content decision followed by qualified actions from the relevant audience segmentPaying for more charts without changing the content plan
    Unlimited audience listsManaging repeated sharing to distinct groupsLess list-maintenance work and better response from the intended groupCreating segments that nobody owns or uses
    Additional Vibes capacityProducing more usable video variations from a defined conceptApproved assets per production hour and outcomes per published assetCounting generated clips instead of publishable, effective clips
    Stealth Story viewingA specific personal or research preferenceA clearly stated utility that justifies the recurring expenseInventing a growth case for a feature with no growth mechanism
    Manus integrationA workflow the available agent can demonstrably completeCompletion time, error rate, review work, and avoided tool costSubscribing because of the acquisition or future integration plan

    For a business, calculate a maximum defensible recurring price before the actual price influences your judgment. Use this structure: verified labor saved, plus attributable incremental contribution, plus the cost of any tool you can genuinely retire, minus added review and governance costs. If the subscription is mainly for personal utility, compare it with a fixed discretionary budget instead of manufacturing a commercial return.

    Because Meta intends to develop different offerings for its apps, run that calculation separately for Instagram, Facebook, and WhatsApp. An Instagram production benefit does not justify a WhatsApp fee unless the WhatsApp tier independently improves a workflow you use.

    Test the workflow before making the subscription permanent

    A marketer tests an unbranded phone feature through a tabletop workflow that compares time, remaining work, results, and recurring cost.

    A new tool often receives extra attention during its first use. That novelty can look like productivity. A useful pilot captures all the work around the feature and holds unrelated variables steady.

    1. Capture a baseline. Use one complete, representative content or operating cycle. Record time, output, review work, and the downstream result with exact metric definitions.
    2. Choose one primary hypothesis. Tie one premium capability to one workflow change and one main result.
    3. Hold major confounders steady. Avoid changing publishing cadence, paid-media spend, offer, audience, and creative process at the same time.
    4. Log actual use. Record who used the feature, for which task, what failed, and how much correction or manual work followed.
    5. Inspect the full chain. Check entitlement, adoption, audience response, and business effect instead of stopping at platform activity.
    6. Apply the exit rule before the next billing decision. Renew, cancel, or run a narrower follow-up based on the threshold set before the test.

    A simple before-and-after pilot is not a true A/B test unless comparable users or outputs are assigned concurrently and other meaningful conditions are controlled. Call the method what it is. The goal is a decision-grade result, not a more impressive label.

    Measure AI output as a production system

    Generation speed alone will overstate the value of Vibes or any future AI feature. Include prompt preparation, source gathering, factual review, brand review, revisions, and publishing work. Useful operational measures include:

    • Approved assets per production hour: approved assets divided by the team’s total production and review time.
    • First-pass acceptance rate: assets approved without revision divided by all assets reviewed.
    • Publication rate: generated assets that were actually published divided by all generated assets.
    • Outcome per published asset: the chosen qualified action divided by the number of assets published.
    • Correction burden: review and revision time added because of factual, brand, or quality problems.

    These measures prevent cheap generation from hiding expensive review. They also let you compare an integrated Meta tool with your existing workflow without pretending that every generated variation has equal value.

    Keep your website as the factual source of truth

    If premium AI tools increase your social output, anchor that output in owned content. Publish the durable explanation, product information, evidence, or answer on your website first. Then derive platform-native clips and captions from the approved source.

    • Keep names, product details, definitions, and claims consistent between the web page and its social derivatives.
    • Give each substantive page a clear purpose, visible authorship where relevant, and a review process for material changes.
    • Use structured data only when it accurately represents content visitors can see on the page.
    • Link from social content when the page provides the useful next step, not merely to manufacture a click.
    • Measure social referrals, branded discovery, leads, and assisted outcomes separately; do not claim search or AI visibility from social activity alone.

    This arrangement gives AI production a controlled input and gives your audience a stable place to verify details. It also protects the content program from becoming dependent on a feature package Meta may change after testing.

    Key takeaways

    • Meta is testing separate paid offerings for Instagram, Facebook, and WhatsApp while keeping the core experiences free.
    • The proposed subscriptions are distinct from Meta Verified and may combine audience controls, insights, AI creation, and productivity features.
    • No described feature establishes that subscribers will receive automatic ranking or distribution priority.
    • Subscribe only when a capability changes a recurring workflow, has a measurable downstream result, and clears a pre-set renewal threshold.
    • Evaluate each app independently and include review, governance, and correction work in the cost of AI output.
    • Use premium social tools to derive and distribute content from an accurate owned source, not as a substitute for one.

    When an offer reaches your account, take a screenshot of the exact features and terms, choose one paid-worthy problem, and write the success and exit criteria before activating it. If you cannot define the changed action and the evidence it should produce, keep the free experience and revisit the decision when the product is clearer.

    References

  • Personal Intelligence in Google AI Mode: An SEO Playbook

    Personal Intelligence in Google AI Mode: An SEO Playbook

    If your AI Mode reporting assumes that every tester should receive the same answer for the same prompt, Personal Intelligence breaks that assumption. Once someone connects personal Google content, a short query can be interpreted through preferences, plans, relationships, places, and interests that were never typed into the search box.

    That does not make AI search visibility immeasurable. It changes what you have to measure. The useful unit is no longer just a query and a URL; it is a query, an account state, a personal context, an answer, and any citations shown with it.

    Key takeaways for SEO and GEO teams

    • Personal Intelligence lets eligible users connect Gmail and Google Photos to AI Mode, with responses potentially drawing on a wider Google context that includes YouTube history.
    • The announced Labs experiment was opt-in and limited to U.S. personal accounts with AI Pro or Ultra access. Workspace business, enterprise, and education accounts were excluded under the launch conditions.
    • Two people can enter the same prompt but present different underlying needs. A single screenshot or rank position therefore cannot represent universal AI Mode visibility.
    • Content should make its suitability explicit: who it serves, which situation it addresses, what constraints apply, and which facts support the recommendation.
    • JSON-LD can clarify entities and relationships already visible on a page, but it should not be treated as a switch that forces personalization or earns an AI Mode citation.

    Confirm access before diagnosing an AI Mode problem

    The announced rollout placed Personal Intelligence inside a Labs experiment. Its launch eligibility was narrow: AI Pro and Ultra subscribers using personal accounts in the United States could opt in, while Workspace business, enterprise, and education users could not. Treat those as experiment launch conditions, not permanent availability rules.

    Availability was being added to eligible subscriber accounts as the rollout progressed, but the personalization feature itself required consent. If the option was available, the manual setup path was:

    1. Open Google Search and select the profile control.
    2. Choose Search personalization.
    3. Open Connected Content Apps.
    4. Connect Workspace and Google Photos.

    The Workspace connector label should not be confused with eligibility for a managed Workspace account. Under the stated experiment rules, the account still had to be personal. The connected experience could use context spanning Gmail, Google Photos, and YouTube history.

    Before treating a missing or inconsistent result as an SEO issue, record the test conditions: personal or managed account, subscription tier, country, Labs access, opt-in state, connected apps, and relevant history settings. If one of those conditions differs, you are not reproducing the same search environment.

    Do not ask employees or clients to expose private email or photo libraries merely to make a test repeatable. Use voluntary participants, collect only the observations needed for the test, and redact screenshots before they enter tickets, presentations, or shared reports. A personalized response can reveal contextual details even when the original prompt looks harmless.

    Measure citation variance, not one universal ranking

    Three researchers test the same blank query on separate computers that show different answer blocks and source tiles.

    Traditional rank tracking works by holding the query and environment as steady as possible. Personal Intelligence introduces an account-level input that an anonymous crawler cannot reproduce. The practical question changes from “Where did this URL rank?” to “Under which observable contexts did this source become useful enough to appear?”

    This matters most for prompts whose answer depends on taste, history, relationships, or current circumstances. The feature’s example uses include family getaway planning, an anniversary scavenger hunt, a child’s bedroom theme, fashion preferences, book recommendations, and other identity-shaped choices. Those are context-sensitive tasks by design, so variation is not automatically a tracking error.

    Test stateWhat it tells youWhat to record
    Personal Intelligence offProvides a non-connected baseline for the exact prompt.Prompt, account eligibility, answer, cited domains, and cited URLs.
    Personal Intelligence on with connected contentShows how the answer changes when personal context is available.Connected-app state, answer differences, recommendations, and citations.
    Personal Intelligence on for another consenting userReveals whether a different context produces a different source set.Only broad, non-sensitive context labels plus the resulting citations.
    Managed Workspace accountChecks whether the test is outside the announced launch eligibility.Account type and whether the feature is present; do not treat absence as a content failure.

    Keep one set of context-sensitive prompts and one control set with little need for personal interpretation. If every result changes, your environment may be unstable. If variation concentrates in planning and recommendation tasks, the pattern is more consistent with personalization doing useful work.

    For each valid test session, log:

    • The exact prompt and any follow-up prompt.
    • Whether Personal Intelligence was available and enabled.
    • Which permitted content connections were active.
    • A short description of the answer’s framing, without copying private details.
    • Every cited domain and URL, including where the citation supported the response.
    • Whether your brand was named without a link, cited with a link, or absent.
    • Whether the cited page actually matched the recommendation or merely supplied a supporting fact.

    Report citation presence as a distribution across valid observations, with the numerator and denominator visible. Do not turn one personalized session into a claim that a site “ranks first in AI Mode.” The accounts are not controlled duplicates, and their histories can differ in ways you cannot inspect or isolate. This is scenario testing, not a clean causal experiment.

    Make public content usable under more personal contexts

    You cannot optimize for the contents of an unknown person’s inbox or photo library. You can make a public page precise enough for an AI system to recognize when it fits a need revealed by that private context. The distinction keeps your strategy grounded: optimize the public evidence and applicability of the page, not the private profile.

    State suitability in language that can be resolved

    Generic superlatives provide little help when an answer must adapt to a specific person. Replace broad claims such as “best getaway for everyone” with explicit conditions: departure area, trip length, transport requirements, activity level, indoor or outdoor emphasis, intended audience, and meaningful limitations. Use only attributes you can substantiate.

    Apply the same discipline outside travel. A book recommendation page can identify themes, reading mood, subject matter, format, and who may not enjoy the selection. A decorating page can separate room size, practical constraints, style, and maintenance needs. The goal is not to create a page for every imagined persona. It is to expose the decision variables already necessary for a good recommendation.

    Build answer blocks around real decisions

    Place the direct answer near the question it resolves. A recommendation should name the option, explain why it fits, state the conditions under which it stops fitting, and link to the evidence or details needed to act. Descriptive headings, concise summaries, comparison criteria, and clearly labeled caveats make the page easier to interpret without stripping away useful depth.

    Separate stable facts from editorial judgment. Opening hours, eligibility, dimensions, compatibility, and included features are different kinds of claims from “ideal for a relaxed weekend” or “better for adventurous readers.” When those claim types blur together, neither a person nor an AI system can easily determine what is verifiable and what is a recommendation.

    Use JSON-LD to confirm the visible page

    Choose the most specific applicable Schema.org types and properties for the entities actually described on the page. Keep names, URLs, authorship, offers, dates, and other marked-up attributes consistent with the visible content. If an important condition matters to the recommendation, explain it in the page copy instead of hiding it in structured data.

    Do not invent audience traits, reviews, ratings, availability, or relationships because they might appear useful to an AI system. Structured data is a machine-readable representation of claims you already publish; it is not a place to manufacture relevance. It can reduce ambiguity, but it does not guarantee inclusion in an AI Mode answer or citation set.

    Strengthen the citation target, not just the topic match

    A page can match a topic yet remain a poor citation target. Make the responsible organization or author identifiable. Show when material was published or materially updated where that timing matters. Define the scope of the recommendation, support consequential claims, and maintain a stable canonical URL. If the useful evidence sits behind an unclear interface or is scattered across unrelated pages, consolidate the answer or create deliberate internal links between its parts.

    Brand consistency matters here as an interpretation problem, not a repetition exercise. Use the same organization, product, location, and author names across visible copy, metadata, structured data, and linked profile pages. Do not solve ambiguity by stuffing variants into every paragraph.

    Run a practical Personal Intelligence visibility cycle

    Five connected workstations form a loop using objects for access checks, context testing, citation review, content editing, and answer comparison.

    A useful operating cycle starts with one decision area where personal context could materially change the answer. Work through it in this order:

    1. Map the decision variables. Identify what would make one recommendation suitable and another unsuitable, such as location, constraints, preferences, timing, compatibility, or intended user.
    2. Create paired prompts. Use the same core request with Personal Intelligence off and on, then include a control prompt that should require little personal interpretation.
    3. Identify your eligible pages before testing. Write down which pages genuinely answer each scenario and why. This prevents you from declaring every absent citation a platform failure.
    4. Test with consenting users who meet the relevant access conditions. Record account and connection states without collecting their underlying messages, images, or sensitive history.
    5. Classify the outcome. Distinguish a direct citation, a supporting citation, an unlinked brand mention, a competitor citation, and no relevant citation.
    6. Inspect the content gap. Check whether the cited page was clearer about suitability, constraints, evidence, entities, or the action a reader should take.
    7. Improve the public page. Add missing decision criteria, clarify unsupported ambiguity, align structured data with visible claims, and strengthen internal paths to the best answer.
    8. Repeat under documented conditions. Keep experiment availability and account state attached to the result so later reports do not compare incompatible environments.

    Avoid three shortcuts. Do not manufacture fake email or photo histories to chase a preferred result. Do not use a personalized screenshot as universal ranking proof. Do not create thin pages for guessed private traits. Each shortcut produces noisy evidence and encourages content that is less useful to the real person making the decision.

    Start with the content cluster where your recommendations depend most on context. Establish the non-connected baseline, run opted-in tests with appropriate consent, and log citation variance alongside the conditions that produced it. The teams that preserve this context will be able to improve their content; the teams that keep reporting a single rank will mostly document contradictions.

    References