Tag: AI Errors

  • What ChatGPT’s Reliability Push Means for Your AI Workflow

    What ChatGPT’s Reliability Push Means for Your AI Workflow

    If ChatGPT stops responding halfway through a deadline-sensitive task, getting the service back is only part of the problem. You also need to know what was saved, what can be moved elsewhere, and whether the eventual answer is trustworthy enough to use.

    OpenAI’s reported push to improve ChatGPT is encouraging, but a product priority is not an operating guarantee. The practical response is to separate uptime from answer quality, then build controls for both.

    Reliability is four separate problems
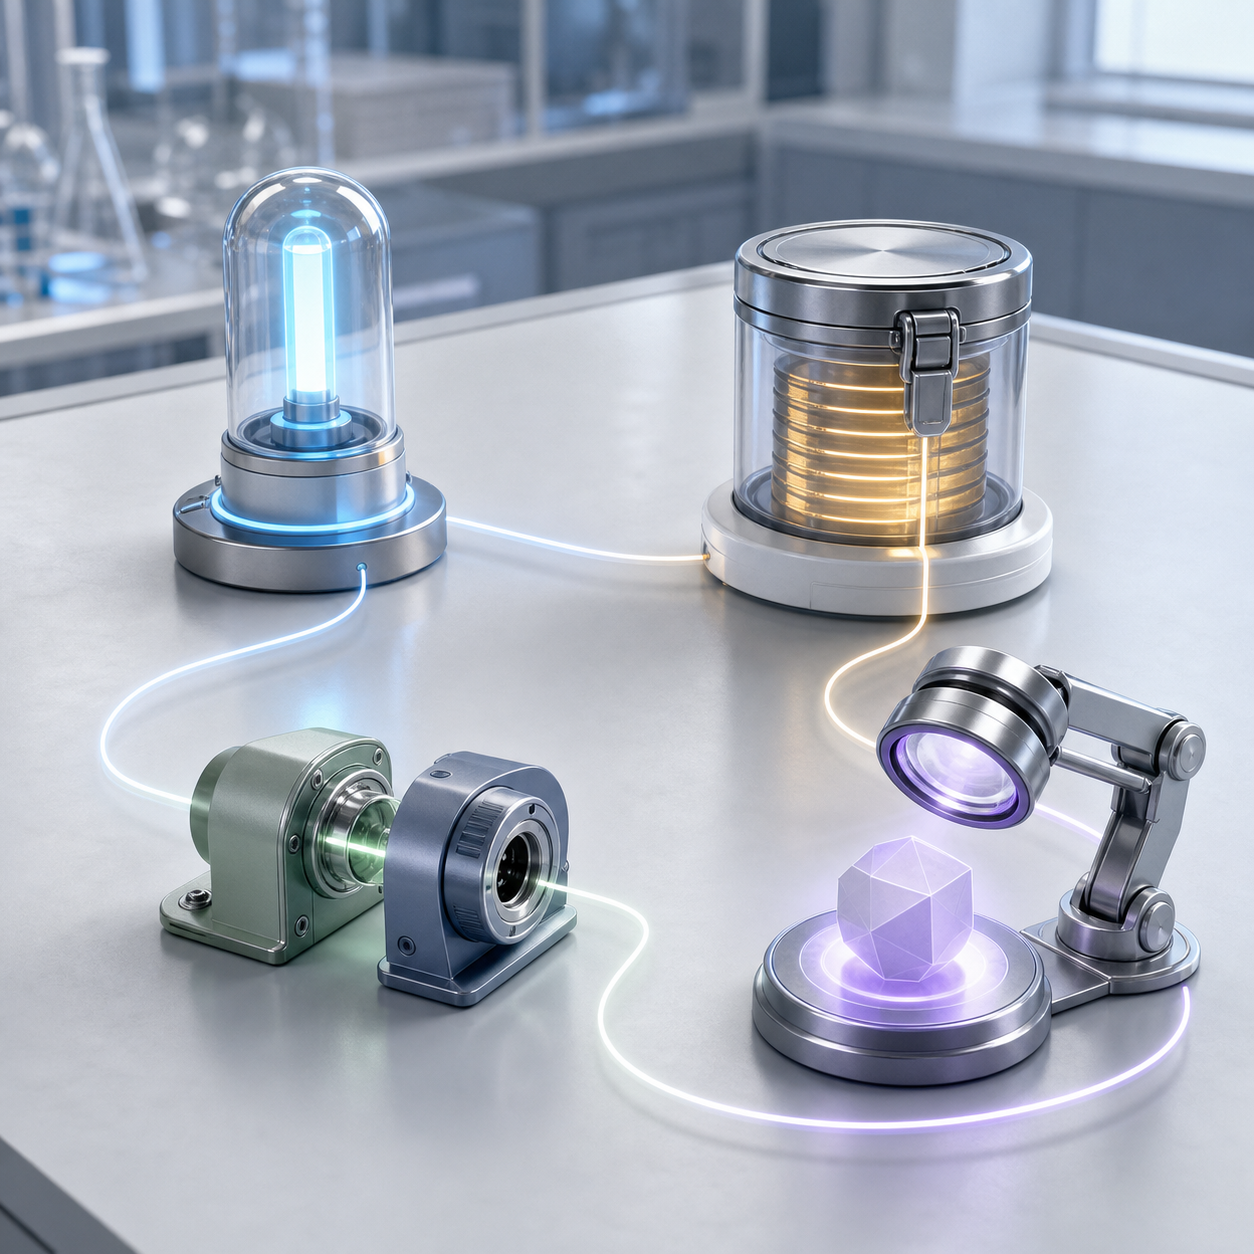
    Four connected mechanisms on a workbench depict a connection beacon, saved files, transfer ports, and an inspection lens checking an output.

    Teams often use “reliability” to mean that ChatGPT loads and produces an answer. That definition is too narrow. During one widespread incident, many users received no answer or only a black dot while thousands reported an outage. That was an obvious availability failure. Less visible failures can occur even when the interface appears to work normally.

    • Availability: Can you access the service and receive a response at all?
    • Delivery performance: Does the response arrive fast enough, without an error or an incomplete generation?
    • Behavior consistency: Does ChatGPT follow the same instructions, constraints, tone, and output structure across comparable runs?
    • Answer quality: Are its claims correct, adequately supported, complete enough for the task, and safe to publish or act on?

    These failures require different responses. Refreshing or retrying may help with a temporary delivery error, but it cannot verify a factual claim. Rewriting a prompt may improve instruction-following, but it cannot restore an unavailable service. Treating every problem as “ChatGPT is unreliable” leaves you without a useful diagnosis.

    Create four labels in your AI incident log: unavailable, slow or incomplete, instruction failure, and factual or quality failure. For each incident, record the task, model or interface used, prompt version, visible symptom, and recovery action. That small distinction will show whether your real problem is infrastructure, prompt design, output verification, or an unsuitable use case.

    Product priorities are a signal, not an SLA

    OpenAI reportedly declared a “code red” that concentrated work on personalization, speed, reliability, and the ability to handle a wider range of questions, supported by frequent coordination and temporary team reassignments. The reprioritization also reportedly delayed advertising initiatives, health and shopping agents, and a personal assistant called Pulse.

    That is a meaningful resource-allocation signal. It indicates that the core ChatGPT experience was important enough to pull people and attention away from other initiatives. It does not establish an uptime commitment, an accuracy threshold, a release schedule, or a guarantee that the product will behave consistently for your particular workflow.

    The individual priorities also need to be interpreted separately. Faster output is not necessarily more accurate output. Better instruction-following can produce a neatly formatted wrong answer. Personalization can make responses more useful to an individual while making it harder for a team to reproduce the same result across accounts. Support for more kinds of questions says nothing by itself about the depth or evidentiary quality of each answer.

    Use the product direction as planning input, then measure what matters inside your own work:

    • Track successful completion separately from response speed. A quick response that requires a complete rewrite is not a successful run.
    • Measure instruction adherence separately from factual accuracy. Passing one check must not substitute for the other.
    • Re-run your representative test prompts after a noticeable behavior change. Do not assume that an improvement for general users preserves your preferred format or workflow.
    • Keep critical prompts, evidence, templates, and approved outputs outside ChatGPT. Product investment does not remove the risk of temporary access loss.

    We would treat a stated reliability priority as a reason to keep evaluating ChatGPT, not as permission to remove fallbacks. The evidence that matters most is whether your own failure rate and recovery burden improve.

    Build a workflow that survives an outage
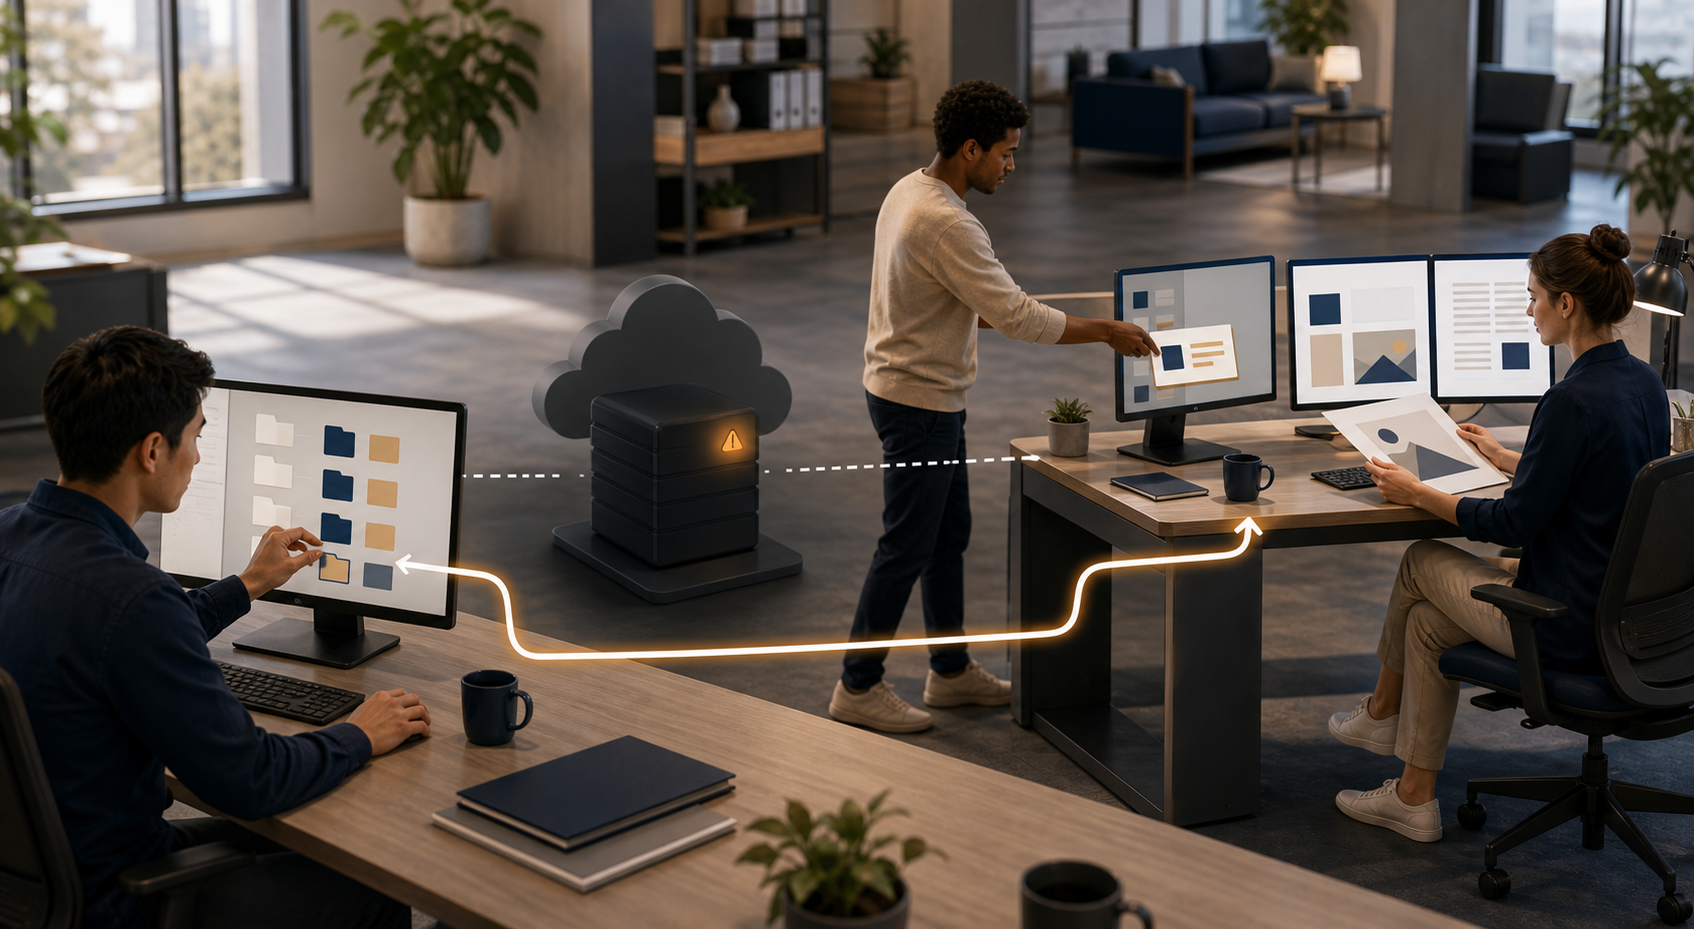
    Three coworkers preserve files, move a task to a backup workstation, and review a draft while a central cloud service is inactive.

    An outage becomes a business interruption when ChatGPT is both the worker and the filing cabinet. If the only copy of a prompt, source packet, decision trail, or draft lives inside a conversation you cannot open, even a short access problem can stop the entire task.

    Assign every recurring ChatGPT task an operating mode before the next incident:

    • Wait: Low-urgency work such as optional ideation can pause until the service returns.
    • Continue manually: A documented template lets a person complete the work without a model. This is appropriate for repeatable briefs, checklists, metadata drafts, and routine formatting.
    • Move to an approved alternative: Another model or internal system may handle the task, but only if it is already approved for the same data and risk level.
    • Stop and escalate: Sensitive, regulated, financially consequential, or action-taking workflows should not be moved to an unapproved tool merely to meet a deadline.

    For each task, store a compact recovery package in your normal project system. It should contain the current prompt, required inputs, authoritative facts, output format, last approved result, and the name of the person who can accept or reject the output. This turns a conversation-dependent process into a portable specification.

    When ChatGPT becomes unavailable or repeatedly fails, use a fixed runbook:

    1. Confirm whether the problem is broad or local. Check the official service status and test whether the failure affects one conversation, one account, or the service generally.
    2. Preserve the task state. Copy any accessible prompt, input, partial output, and unresolved decision into the recovery package.
    3. Classify the task by its preassigned operating mode. Do not invent a fallback while the deadline is already slipping.
    4. Use the manual or approved alternative route. Do not paste confidential material into a consumer tool that has not passed your organization’s privacy and security review.
    5. Record what was completed during the interruption. If a connected workflow can publish, send, purchase, or modify data, check its state before retrying so that you do not duplicate an action.
    6. When service returns, start from the saved task state and review the new output against work completed during the outage. Do not silently replace an approved manual result with a fresh model response.

    The objective is not to eliminate every delay. It is to keep a provider interruption from erasing context, creating uncontrolled data movement, or forcing your team to reconstruct decisions from memory.

    Verify the answer after the service returns

    A successful response is not the same as a reliable answer. ChatGPT can satisfy the requested tone and structure while introducing an unsupported claim. Your quality controls therefore need to inspect the content, not merely confirm that the prompt was followed.

    Use a source-bound production process

    1. Prepare the evidence first. Give ChatGPT the approved facts, definitions, product details, and source material it is allowed to use.
    2. Define the boundary. Tell it not to add names, numbers, quotes, capabilities, or claims that are absent from the supplied evidence. Ask it to identify missing information rather than fill a gap.
    3. Specify the acceptance criteria. Include the audience, required sections, prohibited claims, output format, and what needs a citation or human decision.
    4. Inspect claims against the evidence. Check every changing fact, proper name, number, quotation, and product statement before publication.
    5. Retain a human approval record. Save the accepted version and the evidence used to approve it, rather than relying on conversation history as the audit trail.

    For SEO, AEO, and GEO work, apply an additional domain check. A model-generated keyword, question, or answer can help you explore phrasing, but it cannot prove search demand, customer intent, ranking potential, or the likelihood of being cited by an AI system. Confirm those decisions with actual query data, customer evidence, analytics, or another appropriate first-party source.

    JSON-LD needs two validations. First, parse the output and check that its types and properties are structurally valid. Second, compare every material value with the visible page and your authoritative business data. Syntactically valid schema can still be misleading when the model invents a rating, author, price, availability state, credential, or other property that the page does not support.

    Maintain a regression set for your real tasks

    Public model benchmarks do not tell you whether ChatGPT can produce your product brief, follow your editorial policy, or preserve your schema conventions. Maintain a fixed set of representative prompts drawn from work you actually perform. For each one, define the required elements and the failures that make the result unacceptable.

    • Completion: Did the system return a complete, usable response?
    • Instruction adherence: Did it follow the required scope, structure, and exclusions?
    • Factuality: Can every material claim be reconciled with the approved evidence?
    • Consistency: Do comparable runs preserve the elements your workflow depends on?
    • Recovery: Can another person or approved system continue from the saved artifacts when ChatGPT is unavailable?

    Run this set when your team notices a meaningful behavior change, when a critical prompt is revised, or before you expand ChatGPT into a more consequential process. Keep the dimensions separate. A faster completion time should not hide a decline in factuality, and better prose should not hide missing requirements.

    Key takeaways

    • ChatGPT reliability includes availability, delivery performance, behavior consistency, and answer quality. Diagnose the layer before choosing a response.
    • OpenAI’s reported focus on the core ChatGPT experience is a useful direction signal, but it is not an SLA or an accuracy guarantee.
    • Store prompts, evidence, accepted outputs, and decision ownership outside ChatGPT so an access problem does not become a context-loss problem.
    • Give each recurring task a predefined mode: wait, continue manually, use an approved alternative, or stop and escalate.
    • Validate factual content and JSON-LD independently, even when ChatGPT follows the requested format perfectly.
    • Judge product improvements with a regression set built from your own tasks, not with one general impression of whether the model feels better.

    Start with one workflow that would hurt if ChatGPT disappeared during a deadline. Export its prompt and evidence, choose its fallback mode, and write down the checks an answer must pass. Once that recovery package works, repeat the pattern for the next dependency. Future product improvements then become useful upside rather than your only protection against failure.
    References

  • AI-Generated Defamation: A Practical Response Playbook

    AI-Generated Defamation: A Practical Response Playbook

    An AI assistant has attached a false accusation to your name. You may not know whether it copied a web page, confused you with someone else, revived a resolved allegation, or invented the story. That uncertainty is why your first move matters.

    Treat the incident as an evidence problem first and a distribution problem second. You need to preserve what happened, identify the failure mode, pursue a precise correction, and strengthen the public information that search engines and generative systems use to understand who you are.

    Key takeaways

    • Capture the complete AI response before reporting it. The answer may change or disappear, taking useful evidence with it.
    • Determine whether the claim came from an existing page, an identity collision, an old allegation, or a fabricated narrative. Each failure requires a different remedy.
    • Work on the originating web content and the AI platform at the same time. Correcting only one layer can leave the false claim circulating through the other.
    • Publish clear, crawlable, internally consistent entity information. Structured data can reduce ambiguity, but it cannot prove that a statement is true or force an AI provider to remove an answer.
    • Escalate promptly when the claim concerns crime, fraud, abuse, professional misconduct, safety, or an actual employment or commercial decision. Liability for AI-generated statements remains legally unsettled, so high-stakes cases need advice from a qualified lawyer in the relevant jurisdiction.

    Capture and diagnose the false claim before acting

    An investigator preserves evidence from an AI response using a laptop, phone, camera, and organized case materials.

    An AI response is not as stable as a conventional web page. It may change in a new conversation, after a product update, when the surrounding prompt changes, or after you submit feedback. Preserve a reproducible example before asking anyone to remove it.

    1. Record the product and environment. Note the platform, the model or mode shown in the interface, whether you were signed in, and the date, time, and time zone.
    2. Save the complete conversation. Keep the exact prompt, preceding messages, full answer, citations, source links, warnings, and follow-up responses. A cropped screenshot of one sentence loses context the platform may need.
    3. Preserve more than a screenshot. Export or copy the text, save the conversation link if one exists, and retain the original image files. Do not annotate or overwrite the only copy.
    4. Run a narrow reproducibility check. Test the same neutral prompt in a fresh conversation and, where relevant, add an unambiguous identifier such as an employer or location. Stop once you understand the pattern. Repeating the accusation across many public tools can create more copies and expose sensitive information.
    5. Document external exposure. Record who encountered the answer, how they found it, and whether it affected a job, contract, customer relationship, background check, or safety decision. Preserve related emails and messages.
    6. Restrict distribution. Share the evidence only with people handling the incident, the platform, and professional advisers. Posting the response publicly may amplify the accusation and create a new searchable page that associates it with your name.

    Separate the factual problem from its legal label. In an initial support request, identify a specific false factual statement and show why it is wrong. Whether it satisfies the legal elements of defamation depends on jurisdiction, context, publication, fault, and harm. Let counsel make that assessment when the stakes justify it.

    Next, classify the failure. Do not assume every harmful answer came from a page that can be found and deleted. In 2023, ChatGPT falsely connected Jonathan Turley to nonexistent charges at a faculty he had never attended and cited a Washington Post story that did not exist. A fabricated citation needs a different response from a truthful summary of an inaccurate web page.

    Likely failure modeWhat to look forBest first move
    Repetition of an online claimThe answer cites a real page, copies distinctive wording, or consistently follows prominent search results.Seek correction or removal at the originating page while sending the AI provider the same evidence.
    Identity collisionThe answer combines your name with another person’s employer, location, age, case, credentials, or biography.Show the conflicting identifiers and ask the provider to separate the two people. Strengthen your own disambiguating entity information.
    Resolved or stale allegationThe underlying event is real, but the answer omits a dismissal, correction, judgment, retraction, or later outcome.Make the authoritative resolution easy to find, then request an answer that includes the complete and current record.
    Fabricated narrativeNo underlying event can be located, citations do not exist, or the cited material does not support the statement.Preserve the invented citation and unsupported details, then request removal or correction directly from the AI provider.
    Misleading synthesisIndividual facts may exist, but the answer joins them into an implication the underlying material does not support.Challenge the unsupported connection sentence by sentence and supply concise corrective evidence.

    A search that finds nothing is a clue, not proof that the model invented the claim. Search the exact wording, inspect every cited link, compare names and biographical details, and check whether the allegation appears without its resolution. Your incident file should distinguish what you verified from what you merely could not locate.

    Correct the AI output and its web origins in parallel

    If the answer relies on a real page, start at that origin. Ask the publisher or responsible party for a correction, update, retraction, or removal supported by evidence. If a search engine result itself violates an applicable policy or legal rule, use the relevant removal process as a separate step. Deindexing a result does not delete the underlying page, and a copyright notice is not a general-purpose remedy for defamation.

    At the same time, send the AI provider a targeted report. A vague request such as “remove everything negative about me” is hard to verify and may sweep in lawful opinion or accurate reporting. A useful report gives the reviewer a small, testable case.

    • Identify the subject: full name, relevant organization, location, and any other detail needed to prevent another identity collision.
    • Quote only the necessary statement: isolate the exact factual assertion that is false rather than forwarding pages of unrelated output.
    • Explain the error: state which words are wrong and whether the answer invented an event, confused two people, omitted a resolution, or misrepresented a cited page.
    • Provide the correct fact: give a concise replacement statement that the evidence supports.
    • Attach authoritative evidence: use primary records, court documents, formal corrections, official registries, or first-party records where appropriate. Do not upload confidential material through an insecure feedback form.
    • Specify the remedy: ask the provider to remove the false assertion, correct the biography, separate two entities, stop relying on an unsupported citation, or review the recurring response pattern.
    • Include reproduction details: provide the exact prompt, full response, model or mode, date, screenshots, conversation link, and cited URLs.
    • Keep the receipt: save the ticket number, confirmation email, submitted text, attachments, and every subsequent response.

    Product-specific escalation routes have included the following starting points. Interfaces and policies can change, so verify the live route inside the product or its help center before relying on it.

    • Meta Llama: use the Llama Developer Feedback Form or email LlamaUseReport@meta.com.
    • ChatGPT: use the report control attached to the problematic conversation or response.
    • Google AI Overviews and Gemini: use the product feedback control; use Google’s legal troubleshooter when you are making a legal complaint rather than ordinary product feedback.
    • Microsoft Copilot and Bing: use the thumbs-down feedback control or Microsoft’s Report a Concern process.
    • Perplexity: send a correction or removal request to support@perplexity.ai.
    • Grok: use the xAI reporting portal, including the route for inaccurate personal information where applicable.

    Keep the tone factual. State what the system produced, why the assertion is false, what evidence establishes the correction, and what outcome you want. Do not pad the request with guesses about training data or accusations that you cannot substantiate. Follow up when you have new evidence, a new recurring output, or a material consequence rather than sending repeated copies of the same ticket.

    Rebuild the entity evidence search and AI systems can use

    Verified digital evidence tiles connect around a central human silhouette while incorrect fragments detach from the surrounding network.

    Platform reporting deals with the visible answer. Reputation repair deals with the information environment that may produce the next answer. AI systems often repeat material already available online, so correcting the originating content matters. It may not be sufficient by itself: a harmful narrative can persist after its obvious web origin has been removed.

    Create one unambiguous canonical entity page

    Give search engines and generative systems a stable page that answers the basic identity questions without promotional fog. For a person, that will usually be a biography or profile page. For a company, it may be the primary About page or a dedicated company profile.

    • Use the exact public name consistently in the page title, visible heading, opening copy, metadata, and structured data.
    • Add the identifiers that separate the subject from namesakes: organization, role, location, field, and other accurate public distinctions.
    • Link to primary evidence for consequential claims, including official profiles, registries, decisions, corrections, or public records.
    • Keep current and historical roles distinct. A stale title or affiliation can cause systems to merge facts from different periods.
    • If a correction is necessary, make it factual and proportionate. Do not place the false accusation in the title, URL slug, meta description, or repeated headings merely to deny it.
    • Earn accurate profiles and coverage on credible independent sites where possible. A cluster of consistent, authoritative references is more useful than many thin pages under your control.

    Do not begin by creating look-alike personas or a network of near-duplicate profiles. Deliberate ambiguity may appear to bury a result, but it can make entity resolution harder and give automated systems more names and biographies to combine incorrectly. Fix the identity graph before trying to cloud it.

    Use JSON-LD for consistency, not as a rebuttal channel

    Apply Person or Organization markup that matches the visible page. Use name, url, and carefully selected sameAs links to verified, authoritative profiles. Add alternateName, affiliations, or employment relationships only when they are accurate, public, and genuinely help identification.

    Structured data cannot certify truth, remove a model response, or override stronger contradictory evidence. Never hide a rebuttal in JSON-LD that users cannot see on the page. The markup, page copy, linked profiles, and organization records should tell the same factual story.

    Measure the narrative instead of checking one favorite prompt

    Create a small prompt set based on the ways real stakeholders could ask about the subject. Include a plain identity query, a query with an employer or location disambiguator, and a neutral question about the disputed topic. Do not build dozens of prompts that repeat the accusation unnecessarily.

    • Record whether each answer is accurate, inaccurate, misleading by omission, correctly disambiguated, or unsupported by its citations.
    • Track which URLs and publishers recur across responses. Those recurring inputs deserve priority in the remediation plan.
    • Retest after a meaningful event: an originating page is corrected, a search result changes, the platform answers a ticket, or the canonical entity page is substantially updated.
    • Keep clean results as well as bad ones. They help show whether the problem is isolated, prompt-dependent, or recurring across systems.
    • Do not declare the incident resolved after one favorable answer. Resolution means the high-risk prompts and relevant search surfaces no longer reproduce the false narrative with reasonable consistency.

    No credible SEO, AEO, or GEO plan can promise immediate erasure from every model. Different systems retrieve, generate, update, and respond to corrections differently. The defensible objective is to remove bad inputs where possible, improve the clarity and authority of correct information, and document how outputs change.

    Know when reputation tactics are no longer enough

    Technical remediation can reduce visibility and confusion. It cannot decide whether you have a legal claim, preserve every legal right, or stop an urgent real-world consequence. Seek advice from a lawyer experienced in defamation, privacy, and platform disputes when the downside is serious or your next action could affect a claim.

    • The output falsely alleges criminal conduct, fraud, abuse, sexual misconduct, professional discipline, or another accusation likely to cause immediate harm.
    • An employer, customer, lender, licensing body, media outlet, or background-check provider has seen or relied on the statement.
    • The answer exposes private information, enables impersonation, creates a safety concern, or directs hostility toward the subject.
    • A publisher or platform refuses to correct a demonstrably false statement despite strong primary evidence or an existing court outcome.
    • You are considering a formal demand, preservation notice, subpoena, lawsuit, or disclosure of confidential records.
    • The claim appears repeatedly across products and seems connected to an identifiable publisher, campaign, or actor.

    The unresolved legal question is not merely whether a model encountered third-party material. AI can produce wording, implications, events, and citations that were never published by that third party. Arguments that Section 230 may protect an AI company therefore sit beside arguments that a generated answer is a new publication or goes beyond republishing someone else’s content. There is still limited precedent for assigning liability in these cases.

    Do not let that uncertainty turn the response into guesswork. Open a restricted incident file, preserve one reproducible example, assign an owner, and begin the platform and origin corrections. If the allegation is already affecting employment, business, safety, or a legal proceeding, give that evidence pack to qualified counsel before publishing a broad rebuttal that could amplify the claim.

    References