You have a polished AI-generated SEO audit open in front of you. The findings sound technical, the recommendations are neatly prioritized, and the implementation plan looks ready to hand to a developer. The difficult question is whether any of it is safe to ship.
An AI system doesn’t need to invent an entire audit to cause damage. One unsupported crawl diagnosis can trigger an unnecessary rebuild. One incorrect indexing assumption can send a team into Google Search Console looking for a problem that isn’t there. One generic content plan can consume a quarter’s budget without giving searchers anything new. The answer is not to remove AI from SEO. It is to make evidence, approval, and accountability part of the production system.
Key takeaways
- Classify every material AI claim as observed, inferred, or unverified before it enters an audit or roadmap.
- Treat missing access as an unknown, not as evidence that a setting, submission, profile, or configuration is missing.
- Set the review burden according to the change’s blast radius. Template rules, indexing controls, redirects, structured data, and programmatic pages need stronger gates than draft copy.
- Judge AI-assisted content by accuracy, originality, usefulness, and intent alignment rather than by whether a model helped write it.
- Give every recommendation a named verifier, approver, implementation owner, success measure, and rollback condition.
Make every AI finding prove what it claims
The most important distinction in AI-assisted SEO is not human versus machine. It is evidence versus assumption.
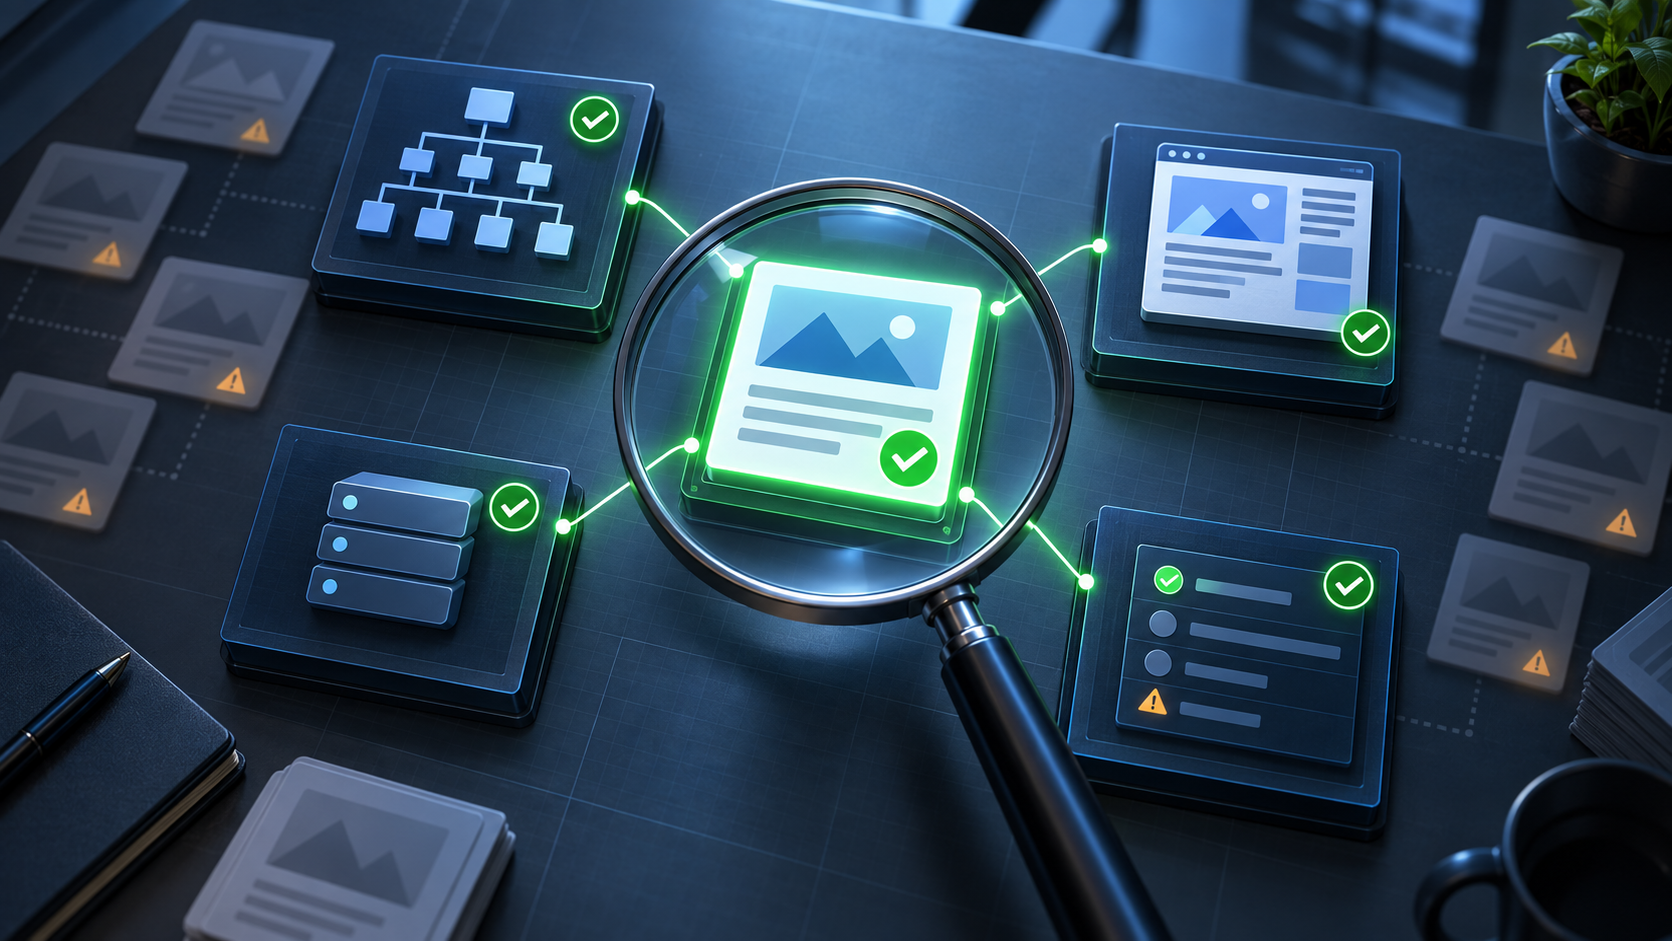
Require the model to label each finding before it recommends a fix:
- Observed: The condition is directly visible in an identified crawl row, response, rendered page, account report, or CMS setting. The finding should point to that evidence.
- Inferred: The available evidence supports an explanation, but other explanations remain possible. The finding should state those alternatives and describe the check that would distinguish them.
- Unverified: The required system, account, page state, or business fact was not available. This belongs in a request-for-access list, not a defect list.
This prevents a common failure: converting unavailable information into a negative finding. A model working from crawl exports cannot know whether a sitemap has been submitted in Google Search Console. In one 41-site venue audit, that unsupported claim still appeared on every owner-facing sheet. The same work produced a recommendation to claim an already-claimed Google Business Profile and a JavaScript crawlability diagnosis for a one-page HTML site.
Each statement sounded plausible. None was established by the data the model had. Use a claim-to-evidence gate like this:
| Proposed finding | Evidence needed | Release condition |
|---|---|---|
| JavaScript is blocking crawlability | Representative URLs, server responses, raw HTML, rendered HTML, and the specific content or links that disappear without rendering | Reproduce the failure and rule out a simple HTML page, an isolated script error, or a crawler configuration problem |
| The Google Business Profile is unclaimed | The current claim state from the live listing or an authorized business account | Verify ownership status before assigning an ownership task |
| No sitemap has been submitted | The Sitemaps report in the relevant Google Search Console property | If account access is absent, label submission status unverified; finding an XML file does not prove submission |
| Duplicate URLs are harmless parameter variations | URL samples, response codes, rendered content, canonical signals, internal links, and the rule producing the variants | Map the pattern before choosing canonicalization, redirection, consolidation, or no action |
| A title tag needs optimization | Page purpose, target query, current title, competing intent, brand constraints, and available performance data | Confirm that the proposed title is accurate, distinctive, useful, and aligned with the page rather than merely containing a keyword |
An inference is not automatically bad. Technical SEO requires inference because crawls, indexes, analytics, and live pages expose different parts of the system. The failure occurs when an inference is presented as an observation and the uncertainty disappears before the recommendation reaches the decision-maker.
Put consequential SEO changes behind release gates
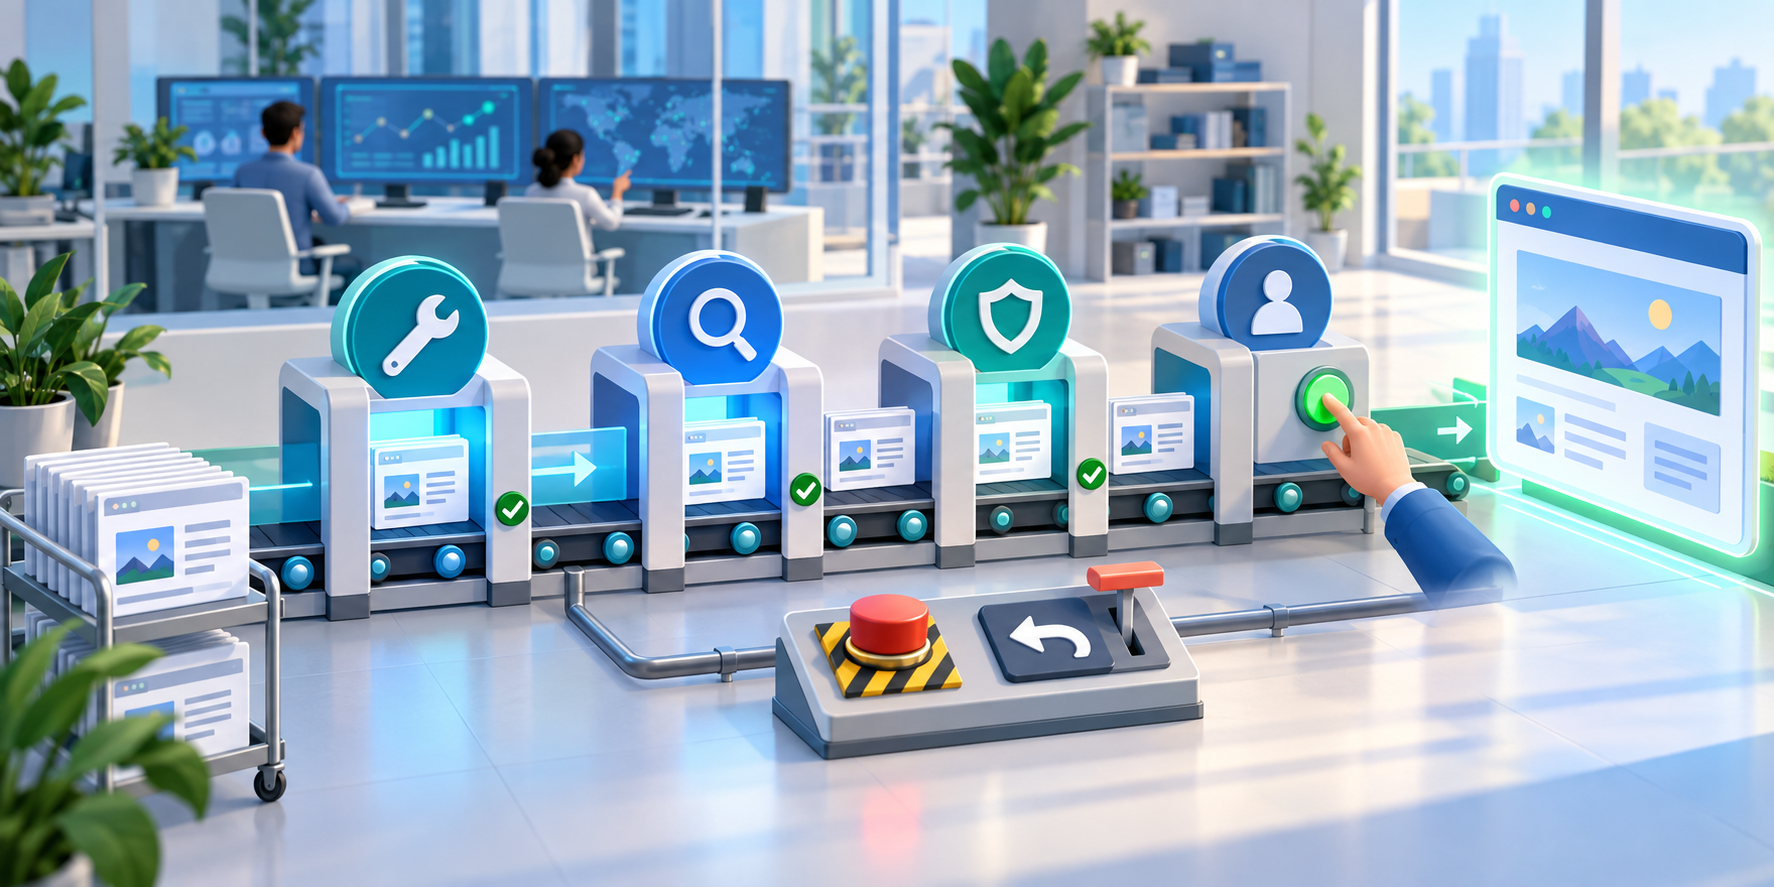
AI is well suited to extracting repeated patterns, grouping crawl data, drafting hypotheses, comparing fields, and assembling first-pass documentation. It should not silently become the person who decides what is true, which risk is acceptable, or whether a production change goes live.
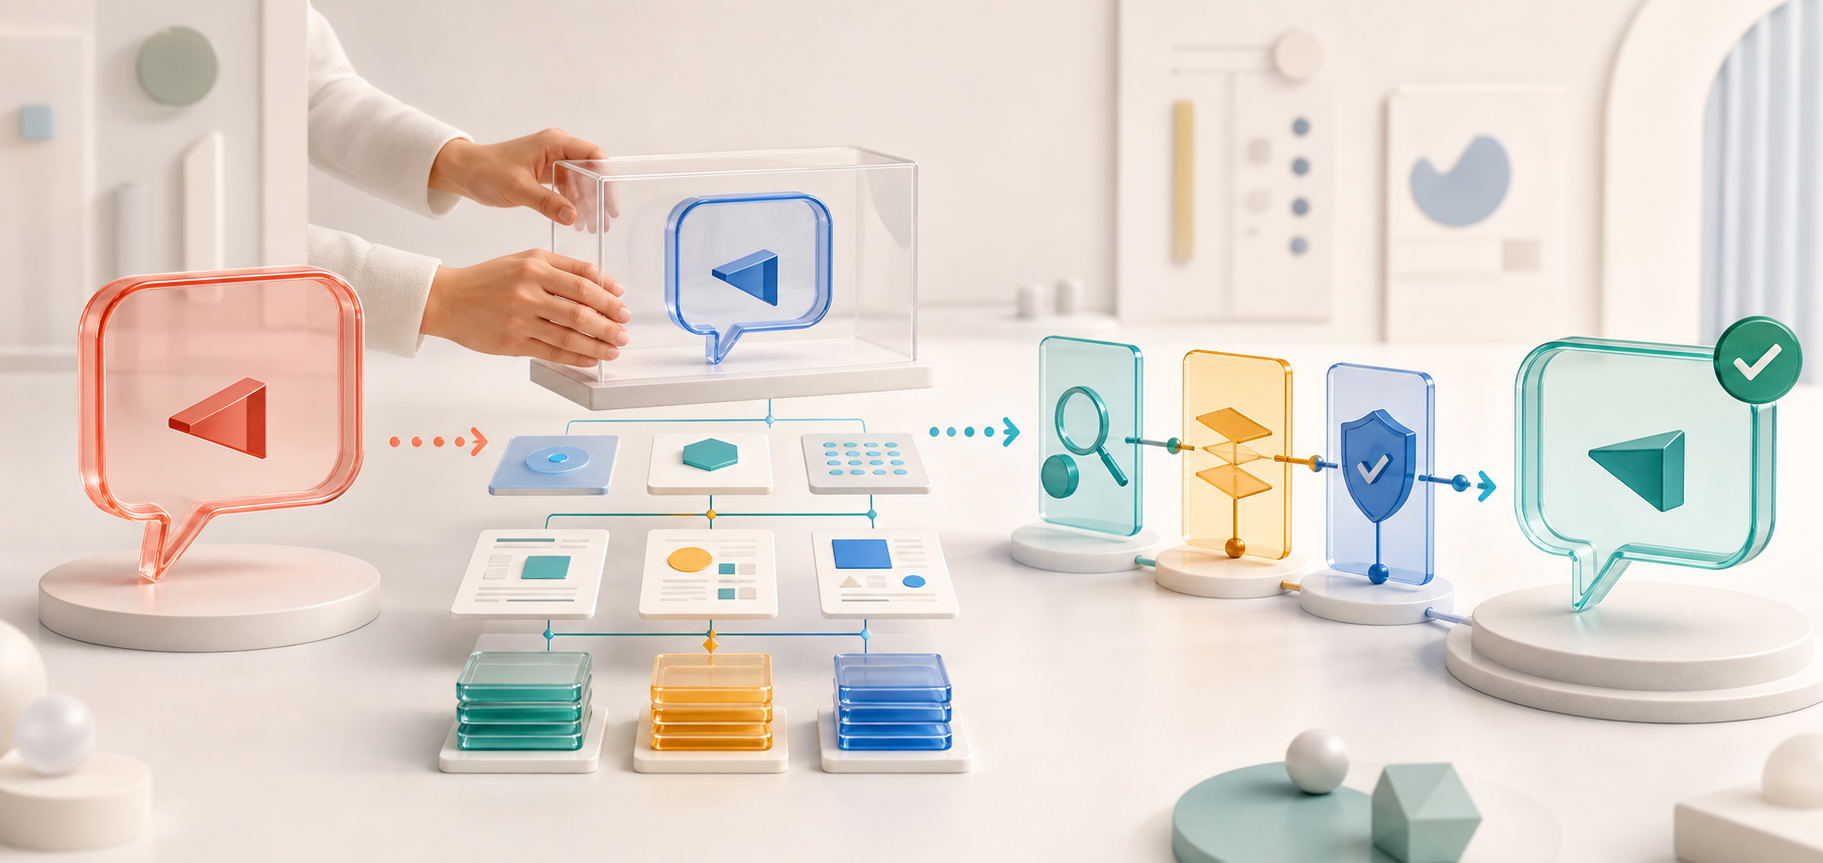
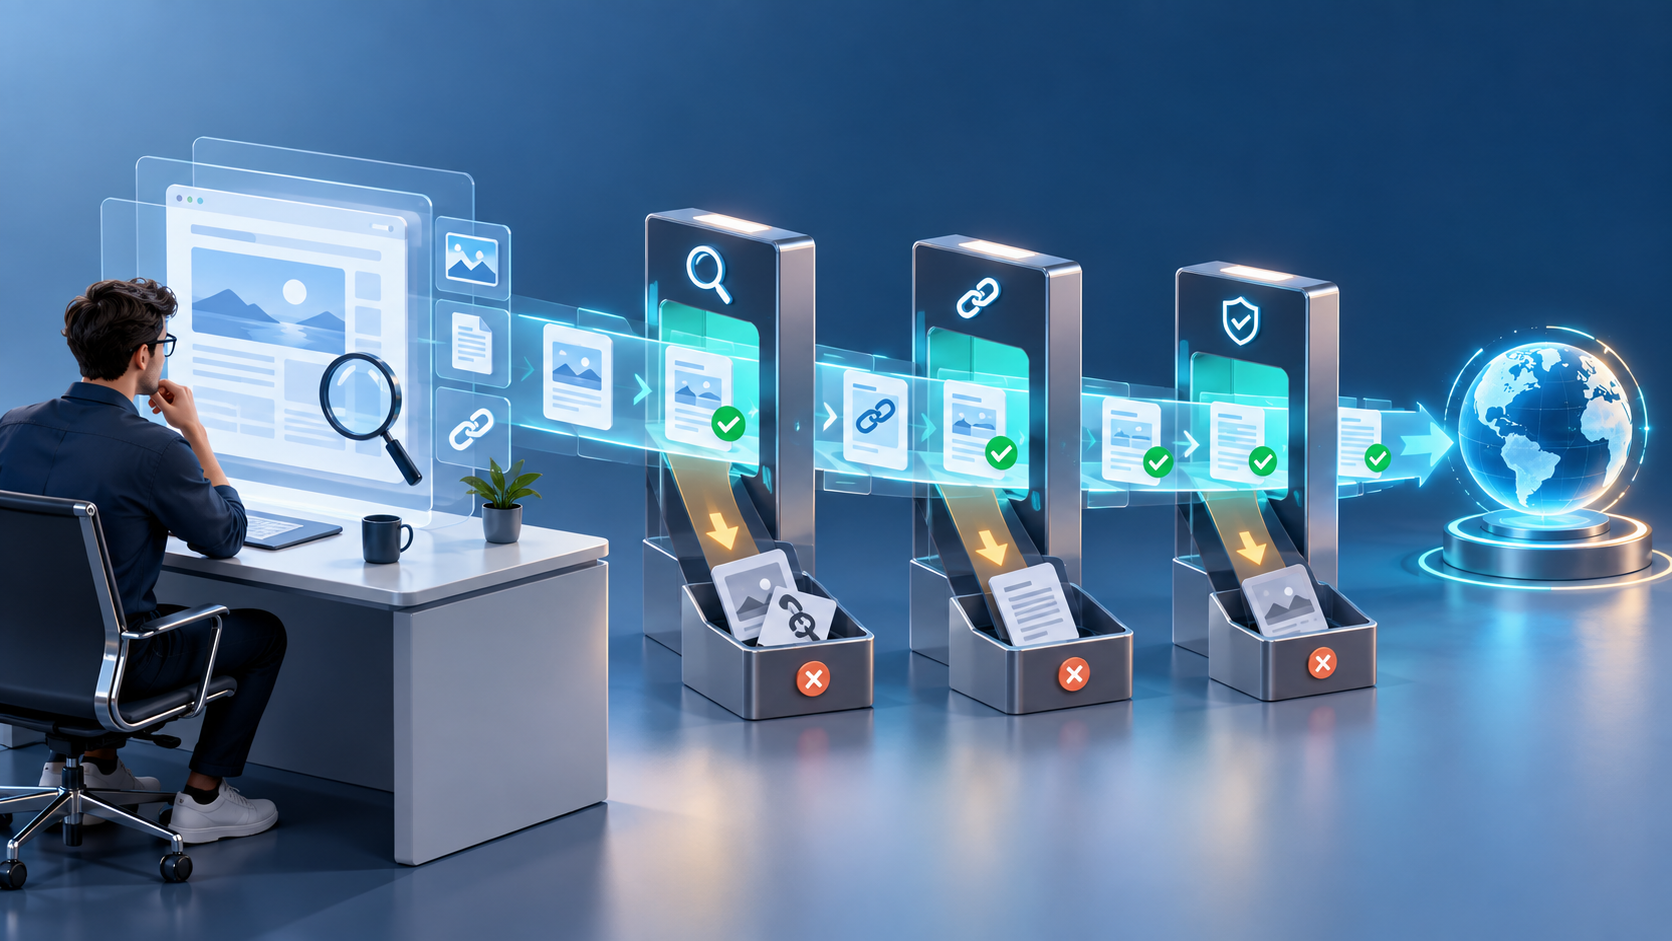
Use this workflow for audits, content programs, schema deployments, local optimization, and AI-search initiatives:
- Define the decision. Ask a bounded question such as whether a URL pattern should be consolidated, whether a template exposes sufficient entity information, or why a page group is not being indexed. A request to find SEO problems invites a long list without a business hierarchy.
- Inventory the available evidence. Record which crawls, analytics properties, Google Search Console properties, CMS templates, log files, local listings, keyword data, and business facts are actually available. Make access gaps explicit in the prompt and the deliverable.
- Require structured claims. Have the model return the affected scope, evidence, claim type, alternative explanation, confidence, proposed action, and validation method. Reject conclusions that cannot point back to an input.
- Verify patterns, not just isolated rows. Inspect examples that match the proposed rule and counterexamples that do not. A valid example proves that a condition can occur; it does not prove the model has correctly described the entire URL class.
- Prioritize by impact, confidence, and reversibility. A dramatic recommendation with weak evidence should not outrank a well-supported issue tied to discovery, conversion, or operational cost. Separate confidence in the diagnosis from confidence in the proposed remedy.
- Stage the implementation. Preserve the current configuration, test on representative pages or a controlled environment, and define the check that must pass before wider release. For template changes, inspect more than the page used during development.
- Approve and monitor. Name the person who accepted the evidence and the person who released the change. Compare the result with the stated success measure, and revert or investigate when the agreed failure condition appears.
Escalate review according to blast radius
A copy suggestion held in a draft has limited downside. A rule that changes every canonical tag or generates thousands of pages does not. High-blast-radius work includes robots directives, noindex rules, redirects, canonical logic, automated internal links, sitewide structured data, reusable title templates, programmatic landing pages, and changes to business identity information. Require direct evidence, human approval, staged deployment, and a rollback path for these changes.
Pattern detection also deserves human review even when the model has the right dataset. One crawl contained 111 duplicate title tags caused by show names appended to default.aspx as path segments, with the variants rendering the same page. The model did not identify the underlying duplicate-URL problem until a person called attention to it. A fluent crawl summary is therefore not proof that the important pattern was found.
Test the finished page for value, not for AI fingerprints
An invisible watermark or other detectable authorship signal can indicate that a model contributed to text. It cannot tell you whether the page is accurate, original, useful, or appropriate for a query. Trying to disguise the production method solves the wrong quality problem.
Google’s stated position is that appropriate use of AI or automation is not inherently against its guidelines. The relevant spam risk is scaled content created primarily to manipulate rankings while adding little or no value, regardless of whether people, software, or both produced it. That makes the release question straightforward: what does this page contribute that deserves to exist?
Before an AI-assisted page is published, an editor should be able to answer yes to each of these questions:
- Does the page have a specific job? It should resolve a recognizable question, comparison, task, or decision for a defined audience. A keyword variation alone is not a separate job.
- Does it add something defensible? Useful additions can include verified facts, first-party expertise supplied by the organization, a clearer procedure, a meaningful comparison, a worked example, original data, or a synthesis that changes what the reader can do.
- Can every concrete claim be traced? Names, dates, measurements, product behavior, quotations, and policy claims need an identifiable basis. A citation must support the exact sentence it is attached to.
- Is the page distinct from existing URLs? Compare its purpose and substance with current pages, not only its title. If two URLs answer the same need, expanding or consolidating an existing page may be better than publishing another one.
- Does the language fit the organization and the reader? Generic wording that could be moved unchanged to a competitor’s site is a warning that the model had too little real context.
- Is the title both accurate and compelling? Keyword inclusion does not excuse a dull, repetitive, or misleading title. Preserve meaningful brand language when it already communicates the page’s value.
- Does structured data describe visible reality? Validate the syntax, but also verify that names, types, relationships, offers, ratings, authorship, and other marked-up facts agree with the page and the business.
- Would the page still be worth publishing without an expected ranking gain? If the answer is no, the content may exist for the search system rather than the person using it.
Early traffic does not override these tests. A widely publicized scale experiment mirrored a competitor’s sitemap into roughly 1,800 generated articles and reached a reported 490,000 monthly visits, but the gains largely disappeared within months. The warning is not that AI-assisted pages cannot rank. It is that temporary acquisition does not prove durable value, sound strategy, or acceptable risk.
Make accountability visible to clients and internal teams
AI has made professional-looking SEO work easier to produce without making the underlying judgment easier. A clean roadmap, technical vocabulary, and a long issue list are weak signals of competence when software can generate all three.
SEO still has no mandatory experience requirement or universal competency test. That leaves buyers and marketing leaders responsible for distinguishing genuine diagnosis from plausible output. A course badge can show that someone completed a course; it does not establish that the person can investigate an unfamiliar site, prioritize commercial consequences, or recognize when the available data cannot support an answer.
Keep a decision record, not just a final deliverable
For every recommendation that reaches a roadmap, retain:
- A concise issue statement and the affected URL, template, entity, or account scope.
- The raw evidence or a stable pointer to it.
- The claim classification: observed, inferred, or unverified.
- Alternative explanations considered and the checks used to exclude them.
- The expected user or business consequence.
- The proposed change and the reason it was selected over other remedies.
- The person who verified the finding and the person who approved the action.
- The release date, success measure, monitoring location, and rollback condition.
- The actual result, including neutral or negative outcomes.
This record creates a chain from evidence to outcome. It also makes corrections useful. When a recommendation fails, the team can see whether the diagnosis was wrong, the implementation changed, an assumption was untested, or the expected effect simply did not occur.
Evaluate an SEO provider by how they reason
If you are hiring an agency, consultant, employee, or AI-search specialist, ask them to work backward from a recommendation:
- Show the raw evidence behind one important finding and explain what it does and does not establish.
- Describe a recommendation they rejected after investigation and what changed their assessment.
- Identify the unavailable data that could materially change the current diagnosis.
- Explain which proposed change has the largest blast radius and how they would test and reverse it.
- Separate the business outcome from the activity they will report. Published pages, completed audits, and fixed tickets are outputs, not proof of organic growth or improved visibility.
- State what result would cause them to revise the strategy rather than defend it.
Be cautious when every finding carries the same confidence, recommendations have no inspectable evidence, a provider guarantees a ranking position, or the report measures work volume without connecting it to discovery, qualified traffic, leads, revenue, or another agreed objective. Competence is visible in diagnosis, prioritization, restraint, and explanation, not in the number of defects a tool can list.
Start with one AI-assisted audit already in your pipeline. Select the recommendation with the largest potential effect, trace it back to the raw evidence, and name what would disprove it. If the necessary access is missing, relabel the finding as unverified. If the evidence holds, stage the change, assign an owner, and record the outcome. That single release gate turns AI from an unaccountable answer generator into a supervised SEO instrument.
References
- Search Engine Land — 10 ways Claude can derail your SEO if you don’t check its work
- Search Engine Land — Your AI content watermark isn’t what Google is looking for
- Search Engine Land — The trust crisis: SEO desperately needs accreditation