Tag: Agent Analytics

  • Publisher Strategy for Content Markets on the Agentic Web

    Publisher Strategy for Content Markets on the Agentic Web

    An AI agent can use your reporting to answer a question, recommend a product, and help complete a task without sending the user to your page. If your publishing model treats every machine interaction as a future click, you may be assigning value to an event that never happens.

    You do not have to choose between unlimited reuse and disappearing from AI discovery. The practical job is to separate access, interpretation, permission, attribution, and payment. Once those decisions are explicit, you can pursue visibility without quietly giving every commercial use the same terms.

    When the answer performs the task, the traffic bargain weakens

    The agentic web is more than a search box with longer answers. An agent can interpret a person’s intended outcome, gather information, coordinate with other systems, request consent where needed, and take an action. That progression from expressed intent to an outcome changes where publisher content creates value.

    QuestionSearch-led webAgentic webPublisher implication
    What does the user provide?A query to investigateA goal the agent can interpretContent must support decisions, not merely match keywords
    How is information gathered?The user opens and compares pagesThe agent can retrieve and combine relevant materialA page may contribute value without receiving a visit
    Where does the decision happen?Mostly on publisher, merchant, or service pagesPartly inside the agent’s reasoning and recommendation layerQualifications and provenance must survive extraction
    How can an action follow?The user moves between sites and completes each stepThe agent can coordinate systems with the user’s permissionAccurate operational details become as important as persuasive copy
    How can the publisher benefit?Referrals, advertising, subscriptions, leads, or salesThose outcomes may remain, but licensing, attribution, and measured usage can also matterTraffic alone is no longer a complete value model

    The old exchange was easy to understand: a platform discovered a page, displayed a link, and sent some users to it. AI answers can compress that journey. They may rely on a publisher’s work while satisfying the user before a click occurs. That does not make traffic irrelevant. It means traffic, content use, and commercial value can separate.

    Keep these layers distinct in your strategy:

    • Access: Can an agent retrieve the content through a public page, authenticated archive, feed, API, or licensed system?
    • Interpretation: Can it reliably identify the entities, claims, dates, qualifications, and relationships on the page?
    • Permission: What may the operator do with the content, in which products, for which purposes, and for how long?
    • Attribution: Will the output identify the publisher, author, and canonical page in a form the user can follow?
    • Compensation: What event creates payment, how is that event measured, and what reporting lets you verify it?

    A crawl directive addresses access. JSON-LD can improve interpretation. Neither one, by itself, grants a commercial license or establishes a price. A licensing agreement cannot rescue content that is too ambiguous or stale for an agent to use safely. Treating these controls as interchangeable is how publishers either expose too much or block more than they intended.

    The distinction becomes more consequential when agents influence purchases, finance, or healthcare. In those settings, trusted inputs can shape decisions rather than merely inform browsing. If you publish high-stakes material, keep eligibility conditions, uncertainty, audience limits, and safety qualifications adjacent to the claim they modify. A caveat placed several paragraphs away may disappear when an answer system extracts only the central sentence.

    Turn your archive into rights-aware content inventory
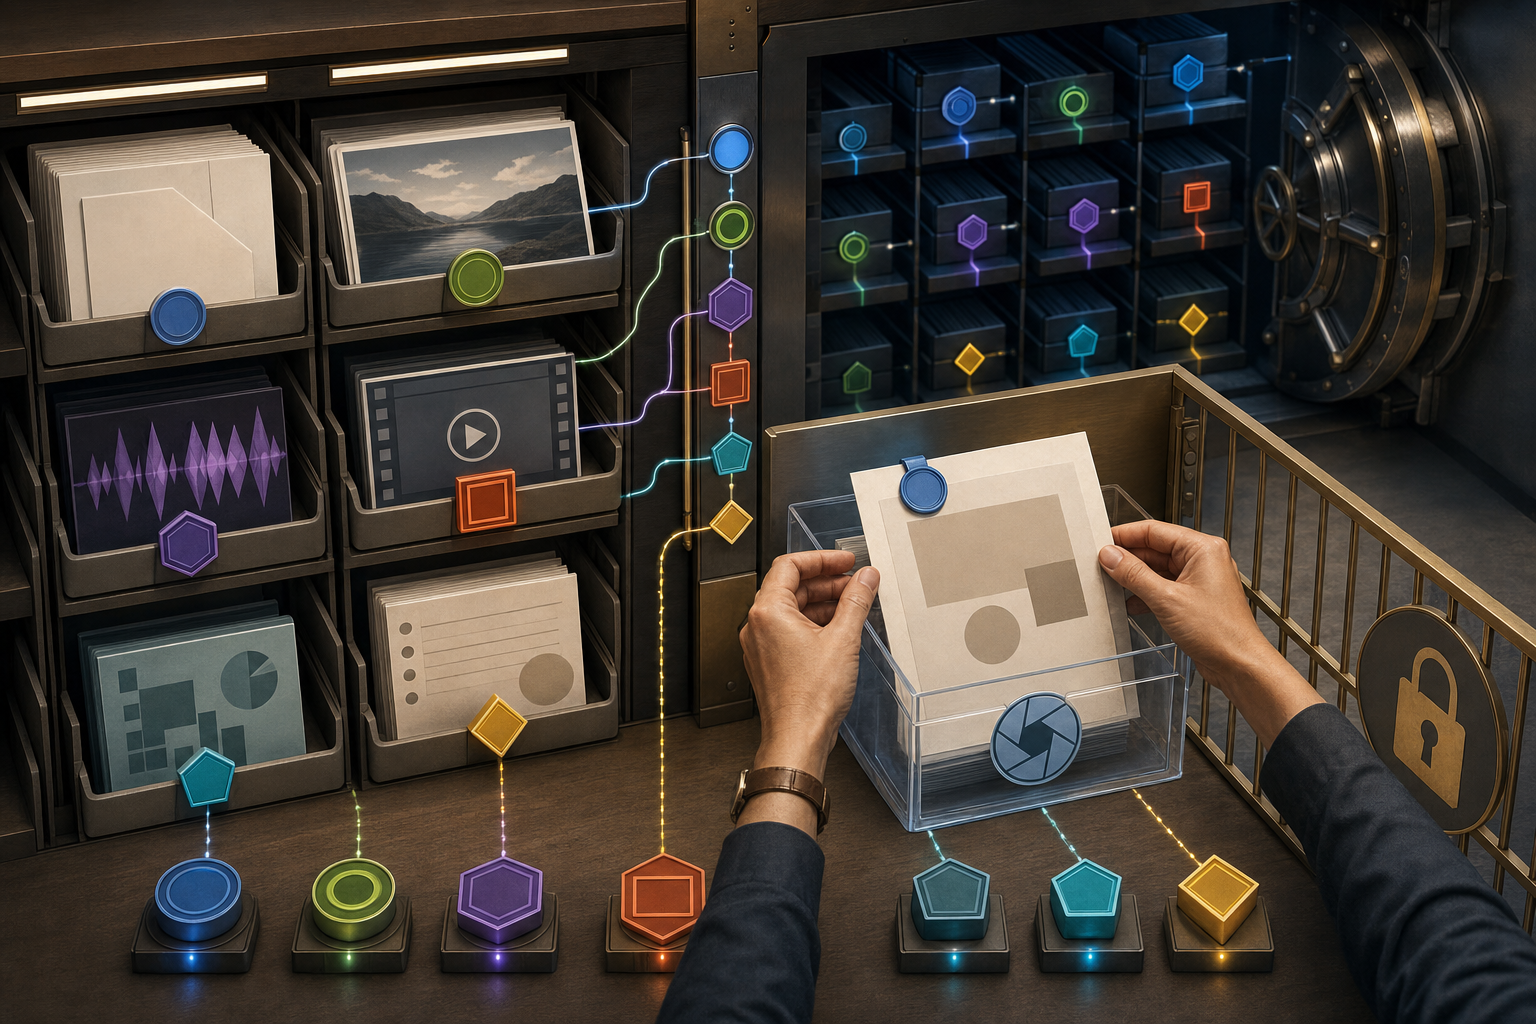
    Hands organize articles, photographs, audio, video, and research files into an archive with distinct visual markers for permissions and provenance.

    Do not begin marketplace evaluation with a sitewide yes or no. Begin with an inventory. Most publishing archives contain a mixture of original work, syndicated material, commissioned assets, contributor content, licensed data, outdated pages, and material governed by different agreements. A single technical switch cannot represent those differences.

    Create a rights and readiness ledger at the page or collection level. Record:

    • The canonical URL, content identifier, current version, publication date, and latest substantive update.
    • The publisher, author, contributor, data provider, photographer, illustrator, and any other party whose rights may be involved.
    • Whether the text, images, tables, audio, video, and underlying data can be licensed for the contemplated use.
    • The topic, named entities, geography, audience, and decision context the content supports.
    • The editorial method, evidence trail, and qualifications an agent would need to preserve.
    • The person or team responsible for corrections, expiry decisions, and future updates.
    • The permitted products and uses, prohibited uses, attribution requirements, and withdrawal process.
    • The commercial role of the content: audience acquisition, advertising, subscription retention, lead generation, direct sales, or licensing.

    If a contributor agreement or third-party license does not clearly cover the proposed AI use, stop at that item and get qualified legal review. Marketplace enrollment should not become the event that silently resolves an ambiguous right. The downside can include licensing material you do not control or accepting obligations that conflict with an existing agreement.

    Once the ledger exists, place content into practical access classes:

    • Open for discovery: Public material you want search engines and answer systems to find, summarize within acceptable limits, and cite back to you.
    • Eligible for commercial licensing: Material you control and are willing to provide for defined products, use cases, reporting, attribution, and payment terms.
    • Restricted or excluded: Content with unclear rights, private information, contractual limits, unacceptable substitution risk, unresolved accuracy issues, or no reliable update owner.

    This segmentation lets you test a controlled collection without packaging the entire archive. It also improves negotiation. You can describe what makes a collection distinctive, how it is maintained, which decisions it supports, and what a licensee must do when it changes.

    Length is not a useful proxy for licensing value. A long generic explainer may add little to an agent that already has abundant coverage. A concise specialist archive, original reporting stream, maintained reference set, or decision-grade dataset may be harder to replace. Ask what the content contributes that a model cannot safely infer from generic material.

    Paywalled and secured archives deserve separate attention. High-quality material in those systems may be unavailable to open-web retrieval, which is part of the rationale for licensed access to premium publisher content. That does not mean every paywalled page should be licensed. Compare the potential licensing return with the subscription, exclusivity, and audience value the same material already creates.

    Use a simple value test for each candidate collection. Can you establish the rights? Is the information meaningfully differentiated? Can an agent preserve its important qualifications? Can you keep it current? Would agent use create incremental value, or mainly replace a paid interaction you already own? If you cannot answer those questions, the collection is not ready for pricing.

    Evaluate a content marketplace by its terms and evidence
    Three transparent marketplace mechanisms are inspected side by side for content tracking, attribution, payment, and audit trails.

    Microsoft’s Publisher Content Marketplace offers an early model for a more direct exchange. Its stated design lets publishers set licensing and usage terms, lets AI developers discover content for grounding, and provides usage reporting intended to show how licensed material contributes. The marketplace is also designed to reduce reliance on separate one-off deals.

    Those are useful design principles, but a marketplace description is not the contract you will sign. Participation is presented as voluntary, with publishers retaining ownership and editorial independence. Confirm how each promise appears in the actual agreement, technical controls, reporting fields, and withdrawal procedure.

    Define the licensed use precisely

    The label AI licensing is too broad for a commercial decision. Ask:

    • Does the license cover run-time retrieval and grounding, model training, fine-tuning, evaluation, embeddings, caching, synthetic outputs, or only a defined subset?
    • Can the system use full text, excerpts, facts, media assets, metadata, or structured data? Do different asset types receive different treatment?
    • Which named products, developers, customers, affiliates, or subcontractors can use the material?
    • What territories, languages, audiences, and use cases are included?
    • How long may content and derived representations be retained after an update, withdrawal, or termination?
    • Can rights be sublicensed, bundled, transferred, or used in a product category you would not approve directly?

    Have counsel review the language against your contributor, syndication, data, image, and customer agreements. A marketplace can reduce transaction overhead; it cannot make an overly broad license safe.

    Make attribution and correction operational

    Attribution should be testable, not ceremonial. Specify whether an output displays the publisher name, author where relevant, content date, and a clickable canonical URL. Ask where attribution appears when several publishers contribute to one answer and whether it remains visible when the agent completes a task rather than showing a research-style response.

    Then test the correction path. Who receives a publisher correction? How quickly can an updated version replace the prior one? Are cached passages and generated summaries refreshed? Can the publisher flag a dangerous misrepresentation? What evidence shows that withdrawal reached participating products? These controls matter most for content whose advice changes, expires, or carries material qualifications.

    Interrogate the unit called usage

    A promise of usage-based revenue is incomplete until usage has a definition. It could refer to content retrieval, inclusion in a grounding set, contribution to an answer, a displayed citation, an agent-assisted transaction, or another event. Each unit values the publisher differently.

    Request the reporting schema and a representative record before agreeing to pricing. Determine whether reports identify the content item, version, product, use type, time, geography, citation outcome, and payment calculation. Ask how value is assigned when several items or publishers contribute to the same output. Establish how disputed records, invalid activity, reporting errors, and delayed data are handled.

    Detailed reporting is part of the proposed content-marketplace value exchange. Its usefulness depends on whether you can reconcile the report with your catalog and commercial terms. A total usage number without content-level identity will not tell you which collection deserves more investment, which page needs an update, or whether the payment is correct.

    Protect your ability to change course

    Confirm that you can exclude individual assets or collections, reject sensitive use cases, update prices and terms, correct content, and withdraw future access. Examine exclusivity, renewal, termination, post-termination retention, confidentiality, and conflicts with direct licensing deals. If editorial independence matters, identify the specific contractual and product controls that protect it.

    Early PCM activity included co-design work with Business Insider, Conde Nast, and Hearst, pilots that grounded Microsoft Copilot responses in licensed content, and Yahoo as an early adopter. That demonstrates real industry experimentation. It does not yet establish a universal price, reporting standard, publisher return, or optimal deal structure.

    Use a decision model rather than the size of the marketplace logo. Consider net expected value as licensing revenue, retained audience value, useful market intelligence, and strategic access, minus substitution risk, rights exposure, operational cost, and any value lost from conflicting deals. The expression is an agenda for due diligence, not a precise forecast. If a proposed agreement cannot provide the inputs, that uncertainty belongs in the decision.

    Make content agent-ready without flattening it for machines

    Licensable content can still be difficult to use. An agent needs to determine what a passage claims, which entity it concerns, when it was valid, who stands behind it, and which qualification changes its meaning. Your AEO and GEO work should make those elements easier to identify while preserving the page’s value for a human reader.

    Use this editorial and technical checklist:

    • State the decision-grade answer early. Give the reader the direct answer, rule, or distinction before expanding the reasoning.
    • Attach scope to the claim. Keep audience, geography, version, date, eligibility, and uncertainty in the same sentence or adjacent sentence. Do not strand a critical exception in a distant footnote.
    • Use descriptive headings. A heading should identify the question being resolved, not merely label a broad theme.
    • Expose provenance. Show authorship, editorial ownership, source or methodology information, publication date, substantive update date, and a correction route where appropriate.
    • Name entities consistently. Stable names and identifiers reduce the risk that an agent merges different people, products, organizations, places, or versions.
    • Maintain a canonical identity. Syndicated, translated, updated, and feed versions should point back to a stable record your internal catalog can also recognize.
    • Keep structured data truthful. JSON-LD should describe what is visibly present and should use the most specific accurate type. It should not convert an editorial judgment into a fact or imply an offer the page does not make.
    • Publish corrections as data, not only prose. Update the visible page, version record, feed, API, and licensing catalog so downstream systems do not continue receiving the superseded material.
    • Separate volatile facts from durable analysis. Prices, availability, eligibility, and similar operational facts need a clear update owner; the surrounding explanation can remain stable.
    • Preserve a human reading path. Concise answer blocks are useful, but they should lead into evidence and judgment rather than turn the page into disconnected fragments.

    Apply an extraction test to every important passage. Read the sentence by itself. Can you tell what is being claimed, whom it applies to, when it applies, and what would make it false or unsafe to act on? If the answer changes when the surrounding paragraph disappears, move the necessary qualifier closer.

    Schema helps with interpretation, not truth, authority, access, or permission. A technically valid graph cannot establish that your evidence is sound, that you own every asset, or that an agent has accepted your license. Keep editorial review, rights management, delivery controls, and structured data connected, but do not collapse them into one SEO task.

    Feeds and APIs can give licensed systems a cleaner way to receive content, identifiers, versions, and updates. APIs are also important connective tissue in the agentic environment, where separate systems must coordinate. If you offer a machine-readable delivery surface, document its fields, version behavior, correction process, authentication, permitted uses, and relationship to the canonical page. Delivery access should enforce the agreement rather than leave its boundaries to guesswork.

    Commerce publishers should also distinguish exploration from execution. The Agentic Commerce Protocol focuses on actions arising from express user intent, while the Universal Commerce Protocol addresses the wider shopping experience across platforms and payment systems. They support different stages of the journey rather than serving as simple substitutes. Product content therefore needs to support both evaluation and action: editorial recommendations require evidence and scope, while transactional facts require current, unambiguous fields.

    A brand-owned assistant can provide another route to the same material. It can operate with first-party information, a controlled editorial voice, and a clear point of accountability. That will not eliminate the need to appear in external agents, but it gives loyal users a place to ask questions within an environment you govern. Treat it as owned distribution, not merely a chatbot feature.

    The design tension is real: publishers need content that AI systems can understand without making the human page feel as if it was written for a parser. The answer is not machine-first prose. It is precise prose with visible evidence, stable entities, useful structure, and qualifications that survive reuse.

    Key takeaways for your next licensing decision

    • Separate retrieval, interpretation, permission, attribution, and compensation. Each requires a different control.
    • Inventory rights and update responsibilities before offering an archive. Exclude anything you cannot confidently license or maintain.
    • Segment public discovery content, commercially licensable collections, and restricted material instead of applying one policy to the whole site.
    • Define whether a deal covers grounding, training, caching, generated outputs, or other uses. Do not accept AI use as a sufficient definition.
    • Require content-level reporting that connects a use event to the licensed item, version, product, attribution outcome, and payment calculation.
    • Optimize pages for clear extraction, provenance, freshness, stable identity, and attached qualifications. Do not expect JSON-LD to manufacture authority or grant rights.
    • Preserve correction, exclusion, and withdrawal controls, especially for changing or high-stakes information.
    • Measure licensing revenue alongside referrals, subscriptions, leads, sales, citations, and substitution effects. A single visibility score cannot represent the whole exchange.

    Establish a baseline before making a collection available. Record the referrals, subscriber starts, leads, commerce outcomes, citations, and direct revenue the eligible material already supports. After licensing begins, compare those outcomes with licensed retrieval or grounding activity, attributed mentions, payments, correction latency, and operational cost. Usage reports can help reveal where content contributes value, but only if you can join them to your own content identifiers and business data.

    Do not interpret every decline in referrals as failure if a measured licensing return or higher-value action replaces it. Do not call licensing revenue incremental when the same use displaces subscriptions, direct deals, or profitable visits. Review the collection as a portfolio, then inspect individual items when aggregate results hide winners, stale assets, or damaging substitution.

    Your next move should be a controlled commercial decision, not a sitewide reaction. Choose a collection whose rights, quality, and update process you understand. Define acceptable use, attribution, reporting, correction, payment, and withdrawal before comparing marketplace terms. If a proposal cannot tell you what use occurred, how value was calculated, and how an error can be removed, it is not ready to govern your best content.
    References

  • Microsoft Copilot Conversational Commerce: Merchant Guide

    Microsoft Copilot Conversational Commerce: Merchant Guide

    If your products already rank in search, that does not mean they are ready to sell inside Microsoft Copilot. Conversational commerce adds two points of failure: the assistant must answer a buyer’s exact question from reliable product data, and the purchase path must preserve the right product, variant, terms and price through checkout.

    Microsoft’s rollout gives merchants two related but distinct surfaces to prepare for: Copilot Checkout inside Copilot.com and Brand Agents on Shopify stores. You need a different operating plan for each one, followed by a shared catalog audit, conversation test and measurement framework.

    Treat Copilot Checkout and Brand Agents as separate surfaces

    It is easy to collapse both products into a single AI shopping feature. That creates muddled ownership and incomplete testing. Copilot Checkout handles a transaction within a Copilot conversation; a Brand Agent answers and guides shoppers on a merchant’s own Shopify site. One changes an off-site buying path. The other changes an on-site decision path.

    Copilot Checkout shortens the path from answer to purchase

    Copilot Checkout began its U.S. rollout on Copilot.com, allowing a buyer to complete a purchase without leaving the current conversation. PayPal, Shopify, Stripe and Etsy were named as integration partners.

    That changes what it means to be visible. A product mention is no longer the final objective; the product also has to remain purchasable when the buyer acts. Ask your commerce owner to verify which catalog, inventory, price, variant and policy records feed the transaction. The presence of a payment partner does not tell you which system supplies each product fact.

    Shopify merchants are automatically enrolled and can opt out. Treat that as a reason to check your status, not as proof that your store is ready or that a particular product is already appearing. Non-Shopify merchants have an application route, so eligibility work and content optimization should be managed as separate tasks.

    Brand Agents influence the decision on your own site

    Brand Agents are available to Shopify merchants. They use the merchant’s product catalog to answer product-specific questions, adopt the brand’s voice and guide shoppers from browsing toward purchase. Microsoft says they can be set up in a few hours.

    Fast setup is not the same as production readiness. A quick installation cannot resolve contradictory variant names, incomplete compatibility details, buried exclusions or a returns rule that differs between the catalog and the storefront. Put catalog and policy owners in the launch workflow before asking the marketing team to tune the agent’s tone.

    The practical ownership split is simple: your ecommerce team should own transaction integrity, your product-data team should own factual answers, and your brand team should own voice. Give one person authority to stop the rollout when those layers disagree.

    Build an answer-ready catalog, not just an indexable page

    Structured product records connect colors, sizes, inventory, delivery, returns, and pricing to an AI-assisted recommendation.

    Traditional product-page optimization often concentrates on discoverable titles, category copy and commercial keywords. A conversational agent also needs enough explicit information to resolve follow-up questions. The difference matters because shoppers rarely ask for a keyword in isolation. They add a use case, compare options, introduce a constraint and then ask whether a particular variant will work.

    For every product family you expect an agent to recommend, review these elements:

    • Identity: Use one canonical product name and a plain description of what the product is. Keep abbreviations, model names and bundles distinguishable.
    • Variants: Make size, color, capacity, configuration and other selectable attributes unambiguous. A buyer should not have to infer whether two labels describe the same option.
    • Fit and compatibility: State who or what the product works with, along with material exclusions. Do not hide a decisive limitation in an image or an unrelated help page.
    • Included items: Say what arrives in the package and what must be purchased separately. This prevents a recommendation from creating the wrong expectation.
    • Commercial facts: Keep price, availability, shipping conditions, returns and warranty language aligned with the systems that govern the transaction.
    • Comparison logic: Explain the decision-relevant difference between adjacent products. A list of specifications is less useful than a clear statement of when a buyer should choose one option over another.
    • Claim boundaries: Mark subjective language as positioning and reserve factual claims for statements you can support. Brand voice must not turn a qualified benefit into a guarantee.

    Your structured data should reflect the same facts. Keep Product and Offer markup synchronized with visible copy and store data, but do not present schema as a magic switch for Copilot eligibility. The announced merchant routes are Shopify enrollment or a non-Shopify application; adding markup alone does not complete either route.

    When the page, JSON-LD, catalog and checkout disagree, choose a system of record for each field and repair the downstream copies. Do not solve the conflict by giving the agent a more persuasive answer. The correct response to uncertain availability or compatibility is a qualified answer, a request for clarification or a refusal to claim more than the data supports.

    Turn the catalog audit into an answer audit. Write representative questions in the language a shopper would use, then attach each approved answer to the exact field, policy or page statement that supports it:

    • What is this product, and what problem is it meant to solve?
    • Will it work with the model, space, use case or constraint I described?
    • What is the meaningful difference between these two options?
    • Which variant should I choose, and why?
    • What is included, and what would I still need?
    • What happens if the item is unavailable or the stated condition is not met?
    • Which shipping, return or warranty qualification applies to this purchase?

    If an approved answer has no supporting location, you have found a data gap. Repair that gap before expanding the agent’s vocabulary. This is also the most useful place for SEO, AEO and ecommerce teams to collaborate: the question set reveals what buyers need, while the evidence map shows whether your content and structured data can answer them consistently.

    Test the complete buying conversation before launch

    A merchant team checks each stage of an AI-guided purchase, from a shopper's question through product selection, variant validation, checkout, and delivery.

    A polished demonstration usually follows a clean prompt and a known product. Real buyers are less orderly. They misspell model names, change constraints, compare products that are not equivalent and revise a variant near the end. Your test should reproduce that behavior instead of asking only whether the agent can recite a product description.

    1. Begin without a product name. Describe a need and see whether the agent asks a useful clarifying question or jumps to an unsupported recommendation.
    2. Add a material constraint. Introduce compatibility, size, intended use or another condition that should narrow the answer. Check whether the recommendation changes appropriately.
    3. Request a comparison. Ask why one product or variant is a better fit than another. Confirm that every claimed difference exists in the catalog or visible product information.
    4. Probe an exception. Ask about an unavailable option, an ambiguous model, an excluded use or a policy edge case. A safe agent should expose uncertainty instead of smoothing it over.
    5. Continue toward purchase. Verify that the selected product, variant, quantity, price and applicable terms survive the handoff to checkout. Use the approved test method for your commerce stack rather than real customer payment details.
    6. Change your mind late. Switch a variant, revise a constraint or return to the comparison. Confirm that the final checkout state reflects the latest instruction rather than an earlier choice.

    Record the expected answer, observed answer, supporting evidence, severity and owner for every test. Use a severity model that reflects actual commercial risk:

    • Blocker: wrong product, price or variant; an unsupported policy statement; a payment problem; or a claim that could materially mislead the buyer.
    • Major: the agent cannot answer a common high-intent question, loses an important constraint or recommends an option without evidence.
    • Minor: awkward wording, unnecessary repetition or a tone mismatch that does not change the factual meaning.

    Do not approve a production launch with unresolved blockers. Correctness belongs ahead of personality because a charming wrong answer still creates the wrong order. Tune brand voice after the agent can identify uncertainty, retain constraints and carry the correct selection into the transaction.

    Measure assisted commerce without mistaking correlation for lift

    Microsoft Clarity provides Brand Agent conversation insights and lets merchants compare agent-assisted sessions with organic traffic. That gives you a useful diagnostic view, but the two groups are not automatically equivalent. People who open a shopping conversation may already have different intent from visitors who do not.

    Microsoft says Brand Agent-assisted sessions show higher engagement and conversion. Treat that vendor claim as a hypothesis for your store, not a forecast. No percentage is supplied, and more interaction can be a mechanical result of adding a chat experience. Engagement is useful only when it helps explain a commercial outcome or reveals a problem.

    Build your measurement plan around questions that lead to a decision:

    • Did the agent attract use? Measure eligible sessions, agent starts and meaningful exchanges. Define a meaningful exchange before reviewing results so a greeting is not counted as successful assistance.
    • Did it improve buying progress? Compare product views, checkout starts and completed orders for relevant segments. Use your store or analytics platform for commerce outcomes that Clarity does not provide.
    • Did it improve order quality? Watch cancellations, returns, support contacts and variant corrections associated with agent-assisted purchases. A higher conversion rate can conceal a recommendation problem if downstream friction rises.
    • Which questions failed? Group unsuccessful conversations by missing product fact, ambiguous variant, policy gap, unsupported comparison, technical handoff or tone. Send each category to the team that can repair the underlying system.
    • What changed during the period? Annotate catalog updates, promotions, traffic shifts and agent revisions. Without that change log, a conversion movement is easy to credit to the wrong cause.

    Use the Clarity comparison directionally unless you have a controlled test with comparable audiences. When a controlled test is not practical, compare matched time periods and similar acquisition segments, then look for the same pattern across commerce outcomes and conversation quality. Do not call a result incremental lift merely because assisted sessions converted differently.

    Keep Copilot Checkout and Brand Agent reporting separate. The first can influence a purchase completed inside an off-site conversation; the second assists a shopper on your Shopify site. Before reporting AI-commerce revenue, document how each path appears in analytics, payment records and order data. Otherwise, a change in attribution can look like a change in demand.

    Key takeaways

    • Copilot Checkout and Brand Agents solve different parts of the journey, so assign separate owners and tests.
    • Shopify merchants should verify their Copilot Checkout enrollment status and readiness rather than assuming automatic enrollment means every product is transaction-ready.
    • A conversational agent needs explicit product identity, variants, compatibility, comparisons, commercial terms and claim boundaries.
    • Keep storefront copy, catalog data, JSON-LD and checkout records consistent; schema cannot compensate for contradictory commerce data.
    • Test discovery, clarification, comparison, exceptions, late changes and checkout state before tuning the agent’s personality.
    • Use Clarity insights to find behavior and answer gaps, but verify commercial outcomes in store analytics and avoid treating an observational comparison as causal lift.

    Your next move is a catalog-and-conversation audit on the product family where a wrong recommendation would create the most customer friction. Run discovery, fit, comparison, exception and checkout prompts against it. Repair every unsupported answer at the data or policy layer, then decide whether the experience is ready to scale.

    The first win is not making the agent sound clever. It is making sure the buyer receives the same accurate answer from the catalog, product page, agent and checkout.

    References

  • GPT-5.2 in ChatGPT: What Availability Actually Means

    GPT-5.2 in ChatGPT: What Availability Actually Means

    If you are trying to find GPT-5.2 in the ChatGPT app you use, a general statement that the model is “in ChatGPT” is not enough. It does not automatically tell you whether your account has access, whether every ChatGPT client supports it, or whether you can select it yourself.

    The defensible answer is narrower: GPT-5.2 has been confirmed in ChatGPT, and an external analytics platform is tracking ChatGPT responses generated with it. Universal availability across browser, desktop, mobile, account tiers, managed workspaces, and the API is not established by those facts. Here is how to separate what is known from what you still need to verify.

    What the current GPT-5.2 confirmation actually proves

    OpenAI announced GPT-5.2 on December 11. By December 14, Profound had begun tracking GPT-5.2 responses in ChatGPT across its products. The named products include Answer Engine Insights, Prompt Volumes, and Agent Analytics, with ChatGPT responses in those dashboards reflecting GPT-5.2.

    That confirms two useful points. GPT-5.2 was operating within ChatGPT, and organizations using Profound could analyze ChatGPT output associated with the model. It does not provide a platform-by-platform rollout matrix, plan eligibility, workspace controls, direct-selection details, or API availability.

    Availability questionAnswer you can defend
    Is GPT-5.2 operating in ChatGPT?Yes. Its use in ChatGPT responses is confirmed.
    Is GPT-5.2 reflected in Profound’s ChatGPT tracking?Yes, beginning December 14 across the named product suite.
    Can every ChatGPT account use it?Not confirmed.
    Is it available in every browser, desktop, and mobile client?Not confirmed.
    Can every eligible user select GPT-5.2 directly?Not confirmed.
    Does ChatGPT availability also confirm API access?No. API access is a separate question and is not established here.

    This distinction prevents a common reporting error: turning evidence of model activity into a claim of universal access. If you publish a rollout status, describe GPT-5.2 as confirmed in ChatGPT without adding unsupported claims about every client or account type.

    “Available” can describe four different states

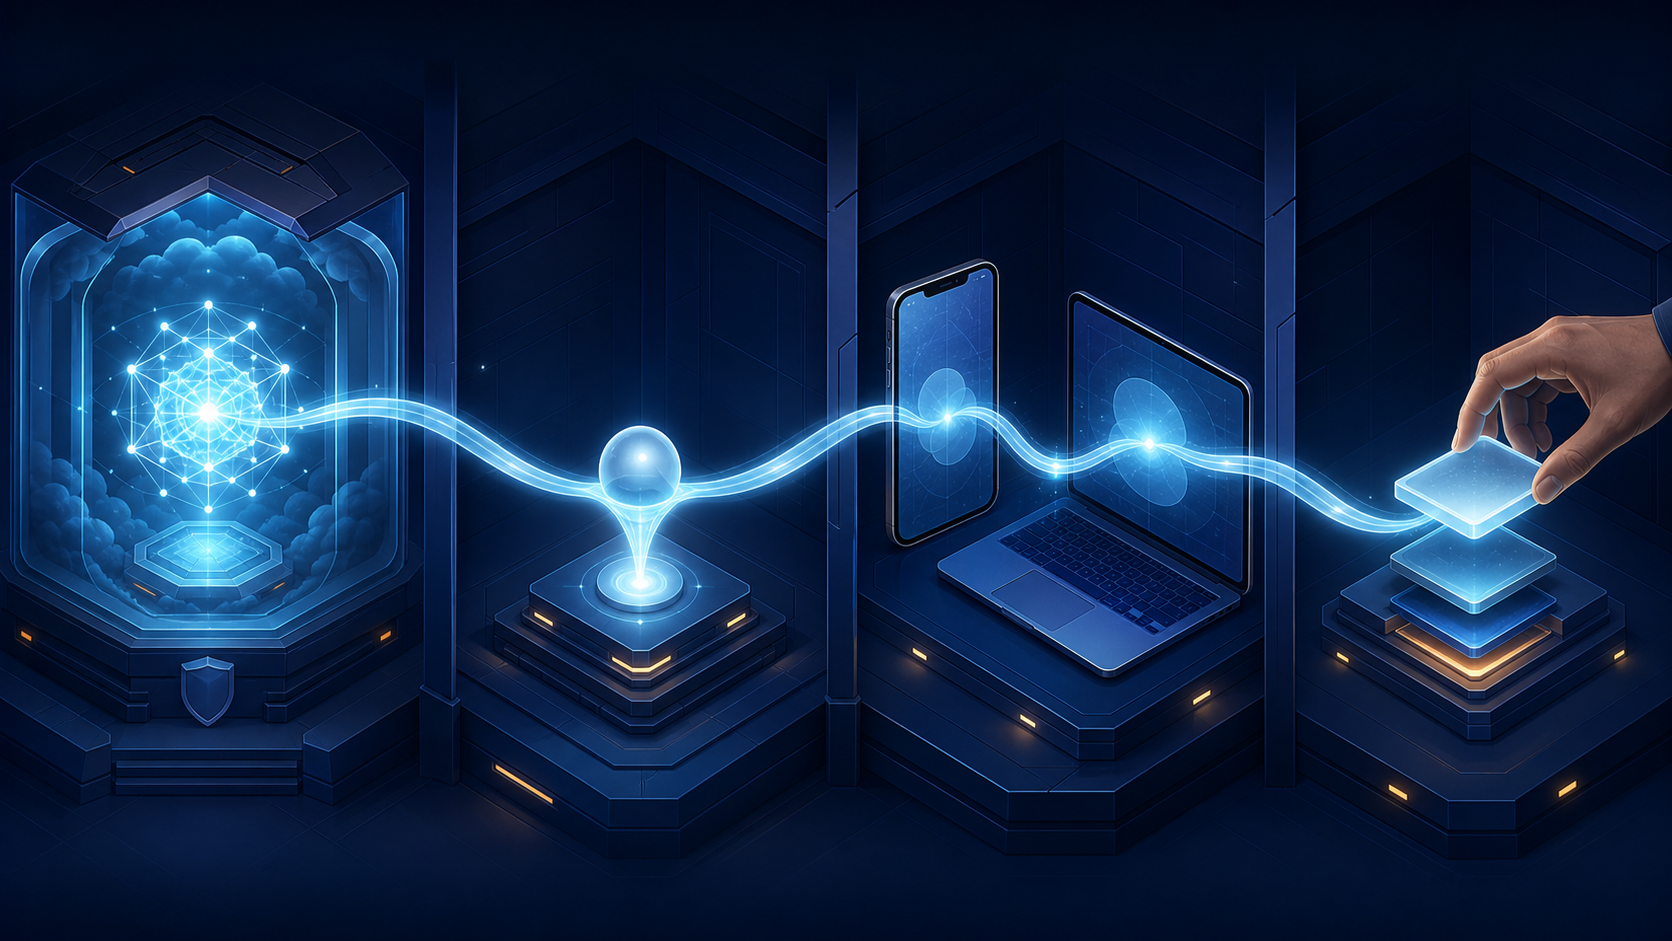
    Four connected scenes depict a model existing on a service, reaching an account, connecting to devices, and being manually selected from interface tiles.

    Teams often use “available” as though it has one meaning. In practice, you need to identify which of four states you are discussing.

    1. Product presence: GPT-5.2 is operating somewhere within ChatGPT. This is the broadest confirmed claim.
    2. Account eligibility: a particular personal or managed account is permitted to use the model. Product presence does not prove this for your account.
    3. Client availability: the model is exposed in the specific browser, desktop, or mobile experience you are using. Access on one client does not demonstrate access on another.
    4. User selection: the interface explicitly lets you choose GPT-5.2. A system may route a request to a model without presenting that model as a selectable option.

    API availability belongs outside this sequence. ChatGPT and an API are different access surfaces, even when they use models with the same name. A confirmation about ChatGPT should not be copied into API documentation, procurement requirements, or production plans without separate evidence.

    The same discipline applies to third-party analytics. A dashboard can accurately identify the model used for the responses it tracks without proving that every consumer account can open ChatGPT and select that model. Tracking coverage and end-user entitlement answer different questions.

    How to verify GPT-5.2 on the ChatGPT platform you use

    Do not ask the model to identify itself and treat the answer as account metadata. A generated response is not an authoritative access record. Use product-controlled labels, account notices, workspace settings, and official release information instead.

    1. Define the exact claim you need to verify. Replace “Do we have GPT-5.2?” with a testable question such as “Can this account select GPT-5.2 in the desktop client?” or “Are responses in this managed workspace being routed to GPT-5.2?”
    2. Start a new conversation. Inspect the model name shown by the interface, any model-selection control, and any account-level release notice. An old conversation may not be useful evidence for the state of a newly enabled model.
    3. Check each client separately. Test the browser, desktop application, and mobile application that matter to your workflow. Record the date, account or workspace, client, application version where applicable, visible model label, and whether direct selection was offered.
    4. Classify the result precisely. Use “selectable” when the interface names GPT-5.2 as an option, “reported as routed” when a trusted system identifies the backend model, and “unconfirmed” when neither form of evidence is present. Do not translate “unconfirmed” into “unavailable.”
    5. Verify managed access at the workspace level. A result from a personal account does not establish the state of an organization-controlled workspace. Capture evidence from the account that will perform the actual work.
    6. Keep API verification separate. If your implementation depends on programmatic access, confirm the model name, permissions, and availability in the API environment itself before changing production workflows.

    A small access register is enough for most teams. Give it one row per account and client, with columns for the check date, workspace, platform, application version, visible model, selection status, and evidence. This turns an ambiguous rollout conversation into a list of claims that can be rechecked.

    AI visibility teams should treat December 14 as a measurement boundary

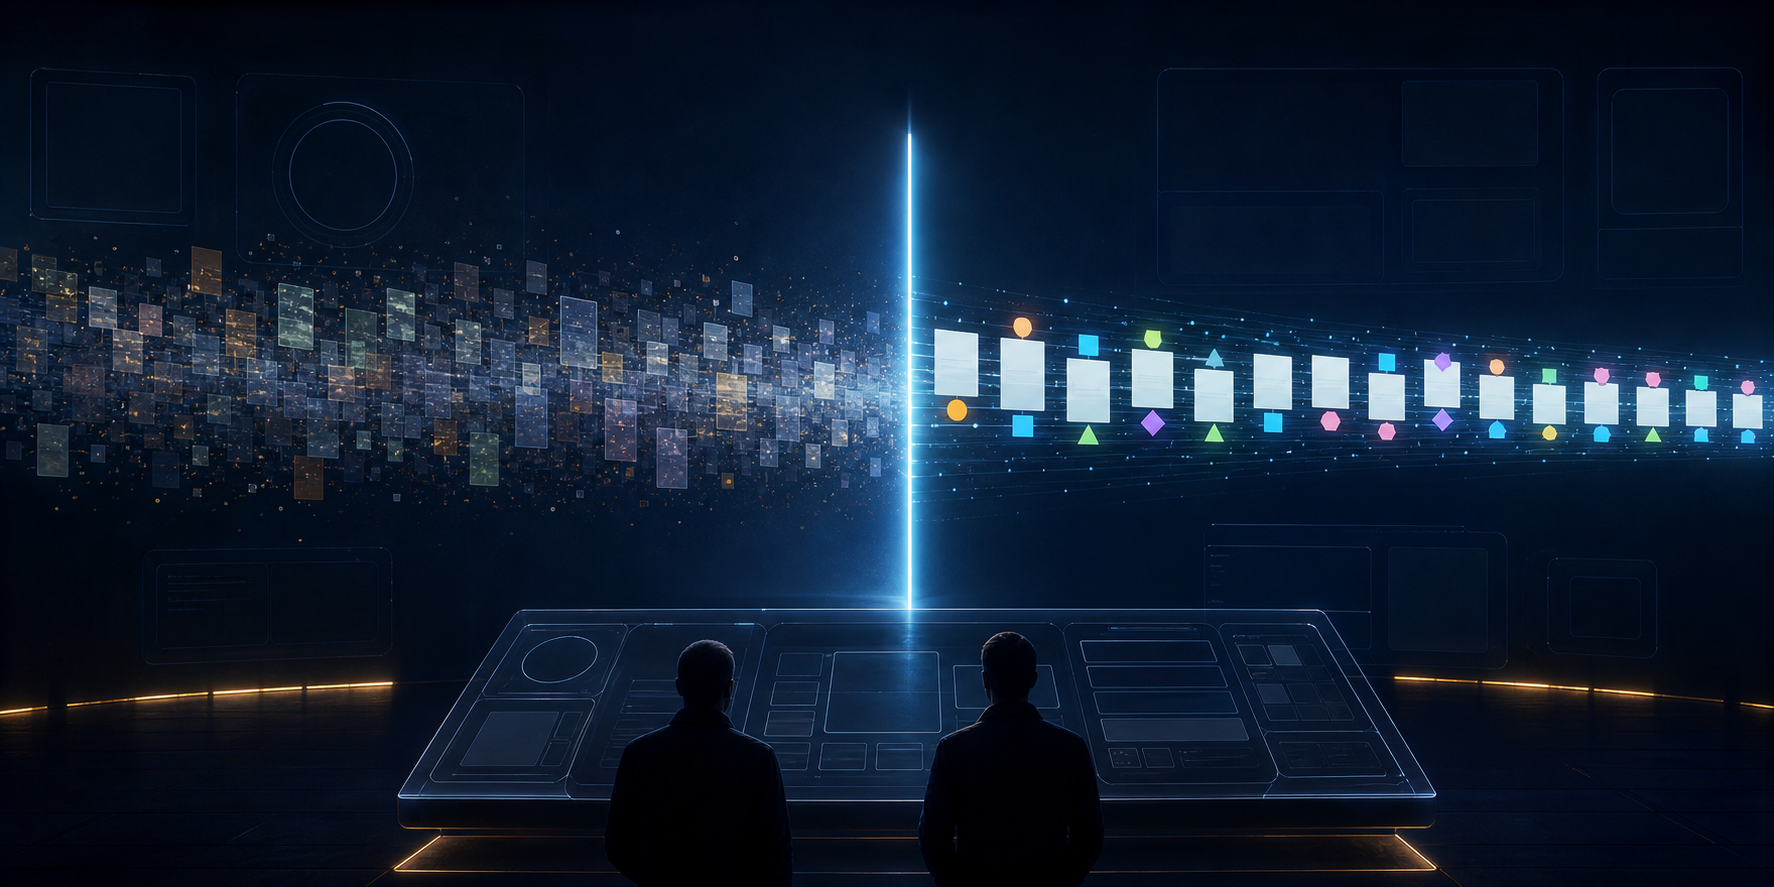
    A stream of abstract response records crosses a bright vertical boundary while two analysts observe the change at a transparent console.

    For SEO, AEO, and GEO teams, model availability is not only an access question. It is also a measurement variable. A model change can alter which brands, pages, facts, and citations appear in generated answers even when your content has not changed.

    Profound’s switch to GPT-5.2 tracking across Answer Engine Insights, Prompt Volumes, and Agent Analytics creates a practical boundary on December 14. If a visibility metric or answer pattern changes across that date, the model transition is one possible cause. It should not automatically be interpreted as a ranking gain, content loss, competitive move, or change in audience demand.

    • Annotate the transition date. Add December 14 to reports that include Profound’s tracked ChatGPT responses so later readers can see that the measurement environment changed.
    • Segment before and after the switch. Compare GPT-5.2 observations with other GPT-5.2 observations when making trend claims. A blended series can hide a model-driven break.
    • Rerun your baseline prompt set. Keep the prompts and other controlled inputs unchanged, then establish a fresh GPT-5.2 baseline for mentions, citations, answer position, sentiment, and factual accuracy.
    • Store raw responses with model metadata. A score without its answer, collection date, and model context is difficult to audit after a platform transition.
    • Delay causal claims. If the only known event near a metric change is the model cutover, label the result as a change in observed output. Do not claim that an optimization caused it until you have evidence that separates the two effects.
    • Do not infer consumer rollout coverage from tracking coverage. Dashboard-wide GPT-5.2 measurement tells you which model underlies the monitored responses, not which ChatGPT clients or account types expose it to every user.

    This is especially important for reports shared with clients or leadership. “ChatGPT visibility increased after GPT-5.2 entered the measurement environment” is supportable when the data shows it. “Our visibility strategy caused the increase” requires additional evidence.

    Key takeaways

    • GPT-5.2 is confirmed in ChatGPT, but universal access across every account, workspace, client, and plan is not confirmed.
    • Profound began tracking GPT-5.2 ChatGPT responses across its named product suite on December 14.
    • Product presence, account eligibility, client availability, direct selection, and API access are separate claims.
    • Verify access using interface and account metadata, not the model’s generated description of itself.
    • For AI visibility reporting, annotate December 14 and establish a new GPT-5.2 baseline before interpreting changes as SEO, AEO, or GEO performance.

    Your next step is simple: write down the exact account-and-client claim your work depends on, verify that claim in the relevant interface, and add the result to your access register. Until that check is complete, use “confirmed in ChatGPT” rather than “available everywhere.”

    References

  • AI Observability for WordPress: A Practical Setup Guide

    AI Observability for WordPress: A Practical Setup Guide

    You know AI systems are reaching websites, but your WordPress reports may not show which agents requested which pages, what the site returned, or where the collection gaps are. Without that evidence, AI optimization turns into a series of content changes with no reliable feedback loop.

    The useful goal is not a bigger bot-traffic chart. It is an auditable path from an observed request to the corresponding WordPress content item and delivery result. Build that path first, label what it cannot prove, and the data becomes useful for technical fixes and editorial decisions.

    Define what AI observability can actually prove

    An AI agent request is evidence of access. It is not evidence that a model understood the page, retained its information, cited it in an answer, or sent a visitor. That distinction should shape your dashboard before you collect any data.

    Observed signalQuestion it can answerWhat it does not prove
    Agent-labelled requestWas this URL requested by a client presenting this identity?That the identity is authentic or the content entered a model
    Successful deliveryDid the site return the requested resource without a visible delivery error?That the agent parsed, trusted, or retained the content
    Repeated requestsDid the same declared agent family return to the page?That the page gained AI visibility
    Identifiable AI referralDid a human visit arrive with a recognizable referral signal?Which model answer, citation, or passage caused the visit

    Think of observability as four connected layers: access, delivery, content mapping, and outcome measurement. WordPress-side agent analytics is strongest at the first three. Outcome evidence usually comes from a separate visibility, citation, or referral measurement process.

    Keep those layers separate in reports. A page can receive frequent agent requests without appearing in an answer, while a page can influence an answer without producing an identifiable referral. Calling every request an impression or every request increase a visibility gain creates certainty the data does not support.

    Put the collector where your hosting stack can see requests

    Isometric website hosting stack with request paths crossing a glowing collection sensor before reaching server, cache, application, and database layers, while one path bypasses it.

    Raw edge or server logs are a natural place to observe automated requests, but WordPress teams do not always have access to them. Managed hosting can place the relevant delivery layer outside your control, and an external log drain may not be available on the account.

    A WordPress-specific integration gives you another collection point. Profound Agent Analytics, for example, supports WordPress through a custom plugin intended to track crawler and agent interaction even when traditional CDN log drains are unavailable. The same collection model can be relevant to both managed and self-hosted WordPress, although the visible portion of the request path depends on the hosting architecture.

    The important caveat is caching. If an edge cache answers a request before WordPress runs, a collector operating only inside WordPress may never see it. A plugin can therefore be working correctly while still producing an incomplete view. You need to identify that boundary rather than assume every public request passes through the application.

    Trace the request path before installation

    Draw the actual path from an agent to the requested page. Include the edge network, host-level cache, security layer, web server, WordPress runtime, and analytics collector where each applies. Then answer these questions:

    • Which layer receives every public request first?
    • Which layer can serve a cached page without invoking WordPress?
    • Can your team export logs from that upstream layer?
    • Does the collector receive the original request identity, or a rewritten value from a proxy?
    • Which page types bypass the cache and which are normally served from it?
    • Will multiple collectors create duplicate events for the same request?

    This map tells you whether a plugin is your primary collector, a gap-filler, or one part of a combined dataset. It also gives you a precise limitation to disclose in reports: for example, WordPress-executed requests are visible while edge-served requests are not.

    Use an acceptance test, not a successful activation screen

    Plugin activation only proves that WordPress accepted the plugin. Validate the data path with controlled requests before relying on the dashboard:

    1. Request a public page using a clearly marked test user-agent value. Confirm that the event appears with the expected path and observation time.
    2. Request a URL that redirects. Check whether the collector records the requested address, the destination, and the delivery result without merging away useful evidence.
    3. Compare a route known to reach WordPress with one normally served from an upstream cache. If only the first appears, document the cache blind spot.
    4. Check that query parameters do not fragment a single article into misleadingly separate pages. Preserve the raw request for diagnosis, but report against a normalized content identity.
    5. Verify that private, administrative, preview, login, and account routes are excluded or handled under your data policy.
    6. Export a sample. Confirm that the fields required for analysis are available outside the dashboard and that observation times use an understood time zone.

    A synthetic user-agent request tests capture, not bot authenticity. Keep that distinction in the test record so a validation event is never mistaken for genuine agent activity.

    Build an event model that survives WordPress changes

    A connected sequence links an abstract automated request, timing and origin components, a modular content item, a response package, and a stored event while surrounding website modules change position.

    Raw URLs are fragile analytical keys. Slugs change, tracking parameters multiply, redirects accumulate, and the same content may be reachable through several address variants. Map each observed request to a stable WordPress content identity whenever possible.

    A useful event record contains the following fields, subject to what your stack can expose:

    • Observation time and time zone: needed to align requests with publishing, deployments, and access-rule changes.
    • Raw requested path: preserves the evidence required to diagnose malformed URLs, obsolete links, and parameter noise.
    • Normalized or canonical URL: allows equivalent requests to be grouped for reporting.
    • WordPress content identity: connects the request to the post, page, product, archive, attachment, or other content object that produced the response.
    • Content state: distinguishes a current public item from a redirect, missing resource, preview, or restricted route.
    • Declared agent identity: retains both the raw user-agent value and the normalized family assigned by your detection rules.
    • Request method and delivery result: separates ordinary page retrieval from other request types and highlights redirects, missing pages, blocked requests, and server failures.
    • Collection point: identifies whether the event came from WordPress, the server, an edge layer, or another integration.
    • Cache state, when visible: helps explain why similar requests appear in one collector but not another.

    Do not discard the raw path or raw user-agent value after classification. Detection rules evolve, and retaining the original value lets you reclassify historical events without pretending the earlier label was definitive.

    User-agent text is a claim made by the requester, not proof of identity. If your system performs additional verification, store the verification state separately. Useful labels include declared, verified, unverified, and unknown, but only use verified when an actual verification method ran successfully. A polished agent name in a dashboard should not erase that uncertainty.

    Collect only what the analysis needs. Full query strings can contain identifiers or sensitive values, and administrative routes can expose operational details. Normalize or remove unnecessary parameters, restrict access to raw telemetry, and apply the same retention and privacy review you use for other request logs.

    Turn agent requests into technical and editorial decisions

    Agent request volume is an input to investigation, not a content score. A high count may reflect repeated fetching, a loop, URL duplication, or ordinary rediscovery. A low count may reflect an access problem, an upstream visibility gap, or simply limited observed activity. Start with patterns that lead to a decision.

    • Coverage: Compare requested content with the set of public pages you intended to expose. Investigate important sections that never appear, but first rule out cache blind spots and collection failures.
    • Concentration: Group requests by content type, topic cluster, template, and normalized page. This shows where observed attention is concentrated without treating that attention as endorsement.
    • Delivery quality: Find agent requests ending in redirects, missing resources, access denials, or server failures. Fix broken delivery before rewriting the destination page.
    • Duplicate paths: Look for several URLs mapping to the same WordPress item. Consolidate reporting around the canonical identity and inspect why the variants remain discoverable.
    • Recurrence: Separate isolated retrieval from repeated requests over time. Recurrence can justify closer inspection, but it still does not prove citation or model use.
    • Change alignment: Annotate publishing, schema, template, internal-link, and access-rule changes. Compare the same request signals afterward, while treating movement as correlation unless outcome evidence supports a stronger conclusion.

    The operating loop should move from data quality to site quality and only then to content optimization:

    1. Validate that the relevant delivery layers are represented and that agent classifications have not changed unexpectedly.
    2. Resolve delivery failures, redirect chains, duplicate routes, and unintended access restrictions.
    3. Map the remaining requests to WordPress content objects and group them by meaningful editorial dimensions.
    4. Select a content hypothesis tied to a visible pattern. Examples include answering the page’s central question earlier, clarifying entity relationships, improving descriptive headings, updating stale claims, or adding internal links that expose related material.
    5. Make the smallest change that can test the hypothesis, record it as an annotation, and preserve the prior state when practical.
    6. Revisit the same access and delivery signals, then check separate citation, visibility, and referral evidence before claiming an outcome.

    Structured data belongs in this workflow when it accurately describes the visible page. Agent analytics may help you choose which content to inspect, but request counts cannot establish that a schema change caused a model to cite the page. Keep implementation quality and outcome attribution as separate questions.

    Evaluate an AI observability tool against your blind spots

    Choose the tool that fits your request path and decision process, not the one with the longest list of bot names. Ask each provider or internal implementation owner these questions before rollout:

    • Where does collection occur, and which cache or CDN paths bypass it?
    • Will it work on the current WordPress hosting plan if external log drains are unavailable?
    • Does it retain raw request evidence as well as normalized agent labels?
    • How does it distinguish declared identity from verified identity?
    • Can it map URL variants to canonical URLs and stable WordPress content objects?
    • Can you filter by content type, topic, template, delivery result, and collection point?
    • Can raw and aggregated data be exported in a usable format?
    • How are duplicate events handled when several layers observe the same request?
    • What data is stored, who can access it, and how can sensitive parameters or private routes be excluded?
    • What happens to page delivery if the analytics service or plugin integration fails?
    • Does the reporting distinguish requests from citations, visibility, and human referrals?

    A credible tool should make its coverage boundary understandable. If you cannot determine where an event was observed, how an identity was assigned, or which requests are invisible, the resulting precision is mostly cosmetic.

    Key takeaways

    • AI observability starts with a traceable request, not a visibility claim.
    • A WordPress plugin can restore useful request data when CDN log drains are unavailable, but upstream caching may still create gaps.
    • Normalize URLs to stable WordPress content identities while retaining raw evidence for diagnosis and reclassification.
    • Treat user-agent identity as declared unless a separate verification method confirms it.
    • Fix collection and delivery problems before using request patterns to prioritize content work.
    • Measure citations, AI visibility, and referrals separately from crawler or agent access.

    Before changing another page for AI search, trace a controlled request from its entry point to its normalized WordPress record. If the chain breaks, repair the instrumentation first. Once it holds, use the pattern across genuine requests to choose the next technical or editorial change, and reserve outcome claims for outcome evidence.

    References

  • AI Agent Analytics on Google Cloud: A Practical Setup Guide

    AI Agent Analytics on Google Cloud: A Practical Setup Guide

    If your content sits behind Google Cloud CDN, a rising bot count is not the answer you need. You need to know whether your measurement covers the pages that matter, which agents are reaching them, and what your team should do when the pattern changes.

    The practical goal is a trustworthy measurement chain from an agent request to a content decision. Build that chain carefully, and agent analytics can reveal coverage gaps, unusual behavior, and pages that deserve investigation. Build it loosely, and an incomplete log stream can send your SEO team in the wrong direction.

    Know what Google Cloud agent analytics can actually show

    Profound’s Agent Analytics connects with Google Cloud Platform through Cloud CDN to monitor how AI crawlers and agents interact with GCP-hosted content. That creates visibility at the content-delivery layer: an agent requests a resource, the measured delivery path observes the interaction, and the analytics system classifies and aggregates it.

    This is valuable evidence, but it has a strict boundary. An observed request does not prove that an AI system indexed the page, used its claims in an answer, cited your brand, or sent a visitor. Those are separate stages of the discovery journey.

    • Agent activity means a request associated with an AI crawler or agent reached the part of your delivery stack that you measure.
    • AI visibility means your content or brand appears in an AI-generated response for a relevant prompt.
    • Business impact means that visibility contributes to useful behavior such as a qualified visit, signup, inquiry, or sale.

    Keep those layers separate in your reporting. Agent analytics is strongest at the first layer. It can help you investigate the later layers, but it cannot establish them by itself.

    Coverage matters just as much as classification. Cloud CDN analytics can only describe requests that pass through the connected and measured path. A subdomain, application route, origin, regional setup, or content repository outside that path may be invisible. Before interpreting silence as a discovery problem, confirm that the page was observable in the first place.

    Design the measurement around decisions, not bot counts

    Start by writing down the decisions the data must support. This prevents an attractive activity chart from becoming a substitute for analysis.

    DecisionQuestion to answerAction the answer should trigger
    CoverageWhich priority content groups have observable agent activity?Investigate important groups with no activity, beginning with measurement and access checks.
    DistributionWhich agents, hostnames, and page groups account for the observed requests?Separate broad discovery from activity concentrated on a narrow or low-value part of the site.
    Change validationDid request patterns shift around a content, routing, or CDN change?Inspect the affected paths while treating timing as association, not automatic proof of cause.
    ReliabilityIs an apparent drop a content signal or a telemetry problem?Verify delivery coverage and ingestion before changing SEO strategy.

    You also need a page inventory outside the agent analytics platform. The inventory provides the denominator that request logs lack. Without it, you can count observed URLs but cannot tell whether the agents reached a meaningful share of the content you care about.

    • Group URLs by hostname and content type, such as product pages, documentation, editorial resources, comparison pages, and support content.
    • Assign each group a business role so that a request to an important decision page is not treated as equivalent to a request for a utility asset.
    • Record whether each group is expected to pass through the connected Cloud CDN path.
    • Mark recently published or materially revised groups so you can examine discovery patterns around real changes.
    • Preserve an unknown or unclassified automation category instead of forcing every suspicious request into a named AI-agent bucket.

    Do not begin with a universal target for how much agent traffic is good. A documentation library, ecommerce catalog, and corporate site have different content shapes and discovery patterns. Your useful reference point is your own verified baseline, segmented by agent and content group.

    Implement the Cloud CDN measurement path and validate it

    An isometric cloud CDN measurement path connects AI agent requests, edge servers, log events, and a validation checkpoint.

    The connector is only one part of the setup. The operational work is proving that the resulting data represents the delivery paths and URLs you think it represents.

    1. Map the request path. List the hostnames and content groups served through Cloud CDN, then identify routes that bypass it. Include alternate domains, localized sections, application routes, and other delivery paths that could make coverage partial.
    2. Connect the analytics integration with narrow access. Grant only the access needed for the relevant telemetry. Document the cloud identity, connected properties, responsible owner, and purpose so the setup can be audited later.
    3. Validate a matched sample. For requests classified as agents, compare the time, hostname, path, and available request details with the corresponding delivery evidence. Check time zones, query-string handling, path rewriting, and redirect behavior before comparing totals.
    4. Normalize URLs deliberately. Decide how to handle trailing slashes, query parameters, duplicate hostnames, localized variants, and canonical page groups. Do not merge parameters or routes when they produce meaningfully different content.
    5. Establish a clean baseline. Observe normal patterns before treating every movement as an SEO event. Keep agent identities and content groups separate so a change in one segment does not disappear inside a sitewide total.
    6. Assign an operating owner. Someone must maintain the URL taxonomy, review classification changes, investigate gaps, and record deployments that may explain shifts in the data.

    Run data-quality checks before every strategic interpretation

    • Coverage check: Confirm that the affected hostname and route still pass through the connected CDN configuration.
    • Ingestion check: Look for a broader loss or delay in incoming events before declaring that an agent stopped crawling.
    • Cache-awareness check: Do not use origin-only telemetry as your sole comparison. A request satisfied at the CDN edge may not reach the origin.
    • Classification check: Determine whether an agent label or identification rule changed. If classification relies partly on self-declared identity, spoofing and identity changes can distort the result.
    • URL check: Make sure redirects, rewrites, parameters, and canonical grouping have not split one page across several analytics rows or collapsed different resources into one.
    • Scope check: Separate a single-agent change from a sitewide change. They imply different investigations.

    Treat access telemetry as operational data. Use least-privilege permissions, keep access limited to people who need it, and align retention with your organization’s security and privacy requirements. Agent analysis does not require exposing more request data than the work actually uses.

    Turn agent activity into a disciplined investigation

    Two analysts examine clustered request signals and isolate an unusual path in a cloud operations workspace.

    Read the data as a diagnostic funnel. First ask whether the interaction could be measured. Then ask whether the agent could reach the content. Only after those checks should you investigate the content itself or connect the pattern to external visibility and business outcomes.

    • A priority page group has no observed activity: verify that the URLs are in your inventory, pass through the measured CDN path, and are accessible under your intended bot policy. If those checks pass, inspect discoverability, internal linking, content duplication, and whether the pages answer a distinct need.
    • Activity falls for a single agent: check that agent’s classification, identity behavior, and access path before making sitewide changes. Stable activity from other agents makes a universal delivery failure less likely, though it does not identify the cause by itself.
    • Activity falls across agents and content groups: investigate CDN routing, telemetry ingestion, access controls, and recent deployments before rewriting content. A broad drop is often a measurement or delivery question first.
    • Requests cluster on low-value pages: inspect why those pages are easier to discover than your primary resources. Compare navigation, internal links, URL consistency, duplication, and the clarity of each page’s purpose.
    • Activity rises after an update: record the association, then look for repetition across the affected content group. Do not call it an optimization win until independent outcome evidence also moves.
    • One page is requested repeatedly: do not assume it has greater authority. Repetition can reflect recrawling, volatility, a frequently changing resource, or inefficient access as well as genuine interest.

    A compact operating scorecard can include observed requests by classified agent, distinct requested URLs, the share of your priority inventory with any observed activity, distribution by content group, and the last observed interaction for important pages. Add delivery outcomes only when the connected telemetry actually exposes and defines them. Label every metric precisely so readers know whether they are seeing requests, URLs, pages, or external outcomes.

    Pair the scorecard with a change log for content releases, routing changes, access-policy updates, and analytics configuration changes. The log will not prove causation, but it gives your team specific hypotheses to test instead of encouraging a vague explanation for every spike or drop.

    Finally, connect agent activity to separate outcome evidence. Check whether the same content groups appear in relevant AI answers, earn citations or brand mentions, attract identifiable referrals, and support useful on-site actions. A crawler request is an upstream signal. It becomes strategically meaningful when you can trace it through the rest of the discovery and conversion path.

    Key takeaways

    • Google Cloud agent analytics is request-layer observability, not proof that an AI model used, cited, or recommended your content.
    • Map every hostname and content group to its Cloud CDN delivery path before interpreting missing activity.
    • Use a page inventory as the denominator; request logs alone cannot tell you how much priority content remains unseen.
    • Validate ingestion, classification, URL normalization, and cache behavior before making an SEO change.
    • Segment by agent and content group because a sitewide total can hide the pattern that explains the problem.
    • Connect crawler activity to independent visibility and business evidence before calling a movement a win or loss.

    Start with a domain whose content path you can map confidently. Define its priority page groups, verify that the Cloud CDN integration observes them, and document the first baseline. Once that measurement is trustworthy, expand the scope and let each new dashboard element answer a named decision rather than merely adding another count.

    References

  • Profound’s $35M Funding and Its Developer Ecosystem

    Profound’s $35M Funding and Its Developer Ecosystem

    If you’re deciding whether Profound belongs in your AI-search stack, the funding number is the least useful place to stop. A financing round can give a vendor room to build. It cannot tell you whether its data is trustworthy, its package fits your application, or its integration is safe to run in production.

    Profound now offers three concrete signals to investigate: $35 million in Series B funding, a one-click Vercel Marketplace integration for Agent Analytics, and next-aeo, an NPM package built for Next.js applications. That combination shows where an ecosystem may be forming. It does not remove the need for technical due diligence.

    Read the $35 million as capacity, not product proof

    Funding matters because software ecosystems require sustained investment. The core product is only one expense. A useful developer platform also needs documentation, integrations, package maintenance, support, security work, infrastructure, and compatibility testing.

    Profound’s $35 million raise creates capacity for that work. It does not prove that every part has already been delivered, nor does it guarantee product quality, vendor longevity, or a particular roadmap. A financing event is not a service-level agreement.

    Separate the headline from the evidence by keeping a simple evaluation ledger with three states:

    • Available: The vendor publicly offers the capability, package, or integration.
    • Verified: Your team has confirmed how it behaves in your own environment.
    • Unknown: The answer depends on documentation, testing, a contractual commitment, or a response from the vendor.

    The funding belongs in the available column as evidence of new financial capacity. The Vercel integration and next-aeo package also belong there until you test them. Do not quietly promote an available feature to verified merely because installation looks simple.

    When you evaluate what the funding could mean for your organization, look for release evidence in four areas:

    • Product delivery: Are analytics, integrations, and developer tools becoming usable parts of the same workflow?
    • Maintenance: Can you find version requirements, release notes, upgrade guidance, and a clear support path?
    • Operational depth: Are permissions, exports, retention, failure modes, and rollback procedures explained?
    • Developer adoption: Can an engineer install, inspect, test, and remove the tooling without relying on a sales demonstration?

    This keeps the decision grounded. Capital can accelerate an ecosystem, but only maintained interfaces make that ecosystem useful to your team.

    The ecosystem has three layers with different jobs

    An isometric three-level system connects AI-search analytics, a cloud integration gateway, and modular web application components.

    Profound’s current footprint spans company capacity, deployment distribution, and application-level tooling. Those layers answer different questions, so they should not be treated as interchangeable proof.

    LayerVerified public signalWhat it helps you assessWhat it does not establish
    Company capacity$35 million Series B fundingAccess to new capital for expansionProduct accuracy, profitability, long-term availability, or service quality
    Deployment distributionAgent Analytics on the Vercel Marketplace with a one-click connectionWhether a supported installation path exists for a Vercel workflowProduction permissions, data handling, metric definitions, or setup after authorization
    Application toolingnext-aeo as an NPM package for Next.jsWhether developers have a framework-specific AEO entry pointExact output, version compatibility, ranking effects, or maintenance quality

    The important question is whether these layers form a closed operating loop. Your application produces content and machine-readable signals. Analytics helps you observe how AI systems interact with the site. Those observations should lead to a specific content, code, or distribution decision. If your team cannot identify that final decision, the stack may create another dashboard without improving the workflow.

    One-click installation is not one-click operation

    The Vercel Marketplace integration is meaningful because it brings Agent Analytics into a deployment channel developers may already use. For a Vercel-based team, a marketplace connection can reduce custom setup work.

    But one-click describes the start of the connection, not the quality of the outcome. Before calling the integration production-ready, determine:

    • Which Vercel projects, environments, accounts, and resources it can access.
    • Which credentials or tokens it creates, where they are stored, and how they are revoked.
    • What data leaves your environment and whether prompts, URLs, responses, or user-related fields can be included.
    • How an AI interaction is identified, filtered, deduplicated, and attributed.
    • What happens when the integration fails, is disconnected, or encounters a deployment change.
    • Whether data can be exported before you remove the integration.

    Treat the marketplace listing as evidence of distribution maturity. Treat data quality, security, and operational fit as separate tests.

    next-aeo moves AEO into the application layer

    The next-aeo package targets Next.js developers and frames answer engine optimization as an implementation concern, not only an editorial checklist. That is useful because developers can potentially review AEO-related behavior alongside application code, dependencies, builds, and deployments.

    Do not infer its exact behavior from the package name. Before adoption, inspect whether it changes rendered HTML, metadata, structured data, routes, configuration, server behavior, or the build pipeline. Establish which Next.js versions and routing models it supports. Check whether the package behaves differently with static generation, server rendering, incremental regeneration, or client-rendered content where those patterns exist in your application.

    If next-aeo emits or transforms JSON-LD, inspect the final rendered markup rather than the source configuration alone. Look for invalid syntax, duplicate entities, conflicting identifiers, missing required properties, and differences between development and production builds. If it modifies metadata, compare canonical URLs, robots directives, titles, descriptions, and social metadata before and after installation.

    AEO does not create a guaranteed position in an AI-generated answer. Use the package to improve implementation discipline only after you can explain what it produces and why that output should help answer-oriented systems understand the page.

    Use a production-readiness checklist before connecting data

    A data pipeline passes through privacy, validation, testing, monitoring, and final approval gates before reaching a production application.

    The fastest way to make a weak platform decision is to install first and define success later. Write the test contract before the package or integration changes your environment.

    Define the measurement contract

    Agent Analytics is intended to provide insight into AI interactions with a site. That description is a starting point, not a metric definition. Your team should be able to answer these questions before using the data for strategy:

    • What event qualifies as an AI interaction?
    • How are agents distinguished from ordinary browsers, crawlers, proxies, automation, and spoofed user agents?
    • Which fields are observed directly, and which are inferred?
    • How are repeated requests, retries, cached responses, and internal traffic handled?
    • Which dimensions are available for filtering and comparison?
    • How far back does the data go, and can a methodology change alter historical comparisons?
    • Can the underlying records be exported for independent validation?

    Write the accepted definition beside every metric you plan to report. If a stakeholder asks what changed, you should be able to explain both the number and the collection mechanism. A polished dashboard label is not a substitute for a documented definition.

    Test application compatibility at the rendered-output level

    Record the exact Next.js version, router, rendering modes, deployment configuration, package manager, and existing SEO or schema tooling in the test environment. Then compare the application before and after installation at several points:

    • Dependency resolution and installation output.
    • Local and production-mode build logs.
    • Generated artifacts and server output.
    • Rendered HTML, metadata, response headers, and structured data.
    • Representative static, dynamic, localized, canonicalized, and authenticated routes used by your application.
    • Deployment logs, runtime errors, and page behavior after release.

    Pin the version you test and preserve a rollback path. An automatic package upgrade can change sitewide output, so do not leave a production AEO dependency floating across unreviewed releases.

    Review permissions and data handling before production

    Do not connect a production project until you understand the integration’s access scopes, network destinations, credential lifecycle, retention behavior, deletion process, and administrative controls. If prompts, URLs, responses, or user-related fields can be collected, involve the people responsible for security, privacy, and consent before enabling that collection.

    A mis-scoped credential can expose more infrastructure than the tool needs. Unexpected collection can create privacy or contractual exposure. Use a staging environment or a non-sensitive project while those questions remain unresolved, and grant the narrowest access that still supports the test.

    Assign operational ownership

    An ecosystem becomes expensive when every component exists but nobody owns the handoffs. Name the person or team responsible for each recurring task:

    • Reviewing package releases and compatibility changes.
    • Approving integration permissions and credential rotation.
    • Investigating analytics anomalies and methodology changes.
    • Turning observations into content or engineering work.
    • Maintaining documentation for installation, rollback, export, and removal.
    • Deciding whether the tooling still earns its place in the stack.

    If these responsibilities fall between SEO, engineering, analytics, and security, the integration will eventually become unowned infrastructure. Resolve that before rollout.

    Run a staged pilot that ends with a decision

    Your first pilot should establish operational fit. Do not promise an AI-visibility lift before the implementation and measurement definitions are stable. A narrow, reversible test will tell you more than a broad installation with no baseline.

    1. Name the decision. State whether you are evaluating Profound for measurement, application-level AEO implementation, or the combined workflow. Define what would lead to adoption, a hold, or rejection.
    2. Capture the baseline. Record the application version, deployment settings, representative routes, current HTML and metadata, existing JSON-LD, current analytics, and known errors before making a change.
    3. Review the artifacts. Check package requirements, permissions, data handling, release information, support paths, and removal steps. Put unresolved questions in the unknown column of your evidence ledger.
    4. Use a non-production environment. Connect the Vercel integration only after reviewing its requested access. Scope the next-aeo change as narrowly as the package and application architecture permit.
    5. Inspect every layer. Verify that the application installs and builds, that rendered output changes only as expected, and that analytics records can be explained using a documented definition.
    6. Roll back and repeat. Remove the package or integration, confirm that the environment returns to its baseline state, and repeat the installation from written instructions. This exposes hidden manual steps and configuration drift.
    7. Write the decision record. List what was verified, what remains unknown, who owns the workflow, and what would trigger reevaluation. Keep funding and roadmap expectations separate from tested behavior.

    Use explicit gates for approval. A credible pilot should produce a repeatable installation, understandable data, no unexplained output changes, acceptable permissions, a named operational owner, and a tested exit path. If one of those is missing, document the gap instead of averaging it away with strengths elsewhere.

    The combined stack earns a broader rollout only when the loop works: application changes are inspectable, analytics is explainable, and the resulting evidence leads to a concrete optimization decision. That is the difference between owning an ecosystem and merely accumulating tools.

    Key takeaways

    • Profound’s $35 million Series B provides capacity to invest, but it does not validate product performance, security, or long-term fit.
    • The Vercel Marketplace integration reduces initial connection friction; one-click installation does not settle permissions, data quality, retention, or operational ownership.
    • The next-aeo NPM package gives Next.js teams a framework-specific AEO entry point, but you still need to verify compatibility and inspect its rendered output.
    • Evaluate funding, analytics, deployment integration, and application tooling as separate layers before testing whether they form a useful workflow.
    • Use a narrow staging pilot, written measurement definitions, pinned dependencies, and a tested rollback path before committing production data or sitewide output.

    If Profound is on your shortlist, pair an engineer with the person who owns AI-search performance and complete the evidence ledger before procurement or production access. Let reproducible installation, explainable data, and safe removal make the decision.

    References

  • AI Observability Integrations: From Bot Logs to Decisions

    AI Observability Integrations: From Bot Logs to Decisions

    You can have a dashboard full of AI crawler requests and another full of citation results, yet still be unable to answer the question that matters: what should your team change?

    The answer is not another chart. You need an evidence chain that connects agent access, content delivery, AI visibility, and an owned decision. This guide shows you how to design that chain across CDN data, citation analytics, MCP tools, and software development kits without treating correlation as proof.

    Key takeaways

    • Start with a recurring decision, then choose the integrations needed to support it. A connector without a decision is only data movement.
    • CDN and server evidence can show that an identified AI agent requested a URL and received a response. It cannot, by itself, show that the content was indexed, understood, cited, or used to form an answer.
    • Give request data and citation data the same stable content identifier. Raw URLs are too inconsistent to serve as your primary join key.
    • Use MCP for bounded, interactive questions and SDKs for scheduled, repeatable workflows. Both should return the same definitions, filters, freshness information, and failure states.
    • Treat missing telemetry as unknown, not as zero activity. Every dashboard and alert should expose its observation window, coverage, and last successful ingestion time.
    • Keep analytics tools read-only by default. Publishing, crawler-control, and configuration changes need separate permissions and explicit human approval.

    Build an evidence chain before choosing connectors

    Four modular devices representing access, delivery, visibility, and action are connected in sequence on a dark investigation table.

    AI observability becomes useful when it separates four different questions. Combining them into a single visibility score hides the exact failure your team needs to fix.

    Evidence layerQuestion it can answerUseful recordsWhat it cannot prove
    AccessDid an identified or suspected AI agent request the content?Request time, observed URL, agent classification, hostThat the agent retained or understood the content
    DeliveryWhat did your infrastructure return?Response status, redirect target, cache or edge result when availableThat the returned content was eligible for an AI answer
    VisibilityDid your monitored prompts produce a mention or citation?Prompt set, model or surface, market, answer, cited URL, observation timeThat a particular crawler request caused the citation
    ActionWho will respond, and what decision will the evidence change?Owner, trigger condition, runbook, change recordThat the intervention will improve performance

    Write the operational question before you configure any integration. Good questions contain a defined content set, an observation window, a comparison, and a possible action. For example: which priority product pages received identified agent requests but remained absent from our monitored citation set during the same reporting window?

    That question tells you what must be joined. You need a priority-page inventory, normalized request events, citation observations, a shared time convention, and a stable content key. It also tells you what not to collect. If a field cannot filter the question, explain the result, or trigger an action, it does not belong in the first implementation.

    A practical integration map should also name the system of record for every concept. Your CDN can own request evidence. Your visibility platform can own prompt and citation observations. Your content inventory can own canonical identity. Your workflow system can own the resulting task. Do not allow several connectors to redefine the same metric independently.

    Use CDN data as access evidence, not citation evidence

    For websites delivered through Akamai, an Agent Analytics integration can bring AI crawler and bot interactions at the CDN into the observability layer. That moves analysis closer to the point where requests are actually served, which is valuable when application analytics do not provide a dependable view of non-human traffic.

    The important word is access. A request event can establish that your infrastructure observed traffic matching a classification rule. The corresponding response can establish what the infrastructure returned. Neither event tells you whether an AI system indexed the page, incorporated its claims, or cited it later.

    Preserve the raw event and add a reporting identity

    Do not overwrite source fields while cleaning the data. Keep the observed URL and bot identifier, then create normalized reporting fields beside them. This lets you change a classification or canonicalization rule without losing the evidence that produced the original result.

    • Event time: Store a consistent timezone and retain enough precision to diagnose ingestion delays.
    • Observed host and URL: Preserve what was requested before redirects or canonical mapping.
    • Content ID: Map URL variants to a stable identifier owned by your content inventory.
    • Response result: Retain the status and relevant edge outcome supplied by the integration.
    • Agent family: Use a normalized label for reporting while preserving the raw identifier.
    • Classification basis: Record whether identity is verified, claimed, inferred, or unknown.
    • Ingestion metadata: Include the connector, processing time, and schema version so data gaps can be distinguished from traffic gaps.

    A user-agent string is a claim, not conclusive identity. Where a bot operator publishes a verification mechanism and your data supports it, keep verified traffic separate from traffic classified only by its declared name. Do not silently discard ambiguous requests. Put them in an unknown or suspected group so a classifier update does not rewrite history invisibly.

    Define metrics that answer delivery questions

    Keep edge metrics narrow enough that their names remain true. Useful definitions include:

    • Priority-content request coverage: Distinct priority content IDs with at least one qualifying agent request divided by all content IDs in the declared priority set.
    • Accepted-response rate: Qualifying requests that received a response your team has explicitly classified as usable, divided by all qualifying requests. Publish the accepted status rules beside the metric.
    • Request distribution: Qualifying requests grouped by content type, directory, locale, or template.
    • Delivery friction: Qualifying requests returning an error, an unintended redirect, or another response state that your runbook treats as a problem.
    • Telemetry freshness: Time of the latest successfully ingested event compared with the end of the displayed reporting window.

    Keep query parameters only when they change the content you need to analyze. Strip known tracking parameters from the reporting URL, but retain the untouched observed URL under restricted access. This prevents campaign variants from fragmenting page-level coverage while preserving the evidence needed to investigate a mismatch.

    Most importantly, distinguish no observed request from no request. A connector outage, an unsupported property, an excluded hostname, a parsing failure, or a delayed export can all produce an empty chart. Add an ingestion heartbeat and coverage status to the dashboard. If the pipeline is incomplete, display unknown rather than a reassuring zero.

    Choose MCP or an SDK according to the decision path

    Collection is only half the integration problem. The data must reach the person or system making the decision. An MCP server can make visibility reports, bot analytics, and citation data queryable from Claude Desktop and other AI workflows. TypeScript and Python SDKs provide another route for software that needs repeatable access without requiring every user to construct raw API calls.

    These interfaces serve different operating patterns:

    • Use MCP for investigation: An analyst asks a bounded question, examines the result, changes a filter, and decides what to inspect next.
    • Use an SDK for repetition: A scheduled job applies a stable query, validates the response, stores normalized output, and triggers a defined downstream workflow.
    • Use your analytics store for history: Retain the governed data needed for trends and reproducibility rather than expecting a conversational session to become the long-term record.

    MCP should expose small, well-described tools rather than a vague tool that can fetch everything. A tool named for a business question is easier to govern than a generic query endpoint. Its contract should state required inputs, permitted filters, output fields, timezone, freshness behavior, pagination, and known gaps.

    Every response should carry enough context to survive outside the chat where it was requested. Return the observation window, timezone, applied filters, dimensions, last successful ingestion time, classification version, and completeness status with the result. An answer such as “twelve pages were not observed” is unsafe if the recipient cannot tell which property, bot class, page set, or window produced it.

    Apply read-only and least-privilege defaults

    Analytics access can expose private URLs, query values, unpublished content paths, customer identifiers, or internal prompt sets. Minimize that exposure before an AI assistant receives the data.

    • Give each integration only the properties, reports, and fields required for its named use case.
    • Use read-only credentials for investigation tools and keep secrets outside prompts, tool descriptions, and returned records.
    • Redact or aggregate sensitive URL parameters and payload fields before they enter the conversational layer.
    • Log tool name, caller, filters, execution time, result status, and returned record count for later review.
    • Treat text retrieved from pages, answers, and metadata as data, not as instructions that can redefine the assistant’s task.
    • Return explicit permission, timeout, partial-data, and rate-limit errors. Do not convert them into empty results.

    Do not give the same assistant silent permission to change robots controls, publish content, purge caches, or alter production configuration. A mistaken interpretation could affect site availability or discoverability. Put mutating actions behind separate tools, narrower credentials, a preview of the proposed change, and human approval.

    Join access and citations without inventing causality

    Separate cyan request tokens and violet citation nodes meet at a transparent matching surface while an analyst compares the joined evidence.

    The edge event and the AI answer usually do not share a request ID. Join them for analysis through governed dimensions: stable content ID, canonical URL, agent or surface family, locale when available, and aligned observation windows. That produces a useful relationship, but not proof that one particular request caused one particular answer.

    Your content ID is the critical bridge. The same page may appear as an HTTP and HTTPS URL, with tracking parameters, behind redirects, or under several cited URL forms. Keep observed_url, canonical_url, and content_id as separate fields. The first preserves evidence, the second supports URL reporting, and the third gives you a stable entity for longitudinal analysis.

    Observed agent accessObserved citationWhat you can concludeNext investigation
    NoNoYou do not yet know whether the issue is delivery, observation coverage, prompt coverage, or content selection.Validate both pipelines, then inspect delivery rules and whether the page belongs in the monitored prompt set.
    YesNoAccess was observed, but citation was not observed in the declared prompt set and window.Compare the page with cited alternatives, confirm the returned content, and inspect relevance, clarity, and entity alignment.
    NoYesCitation was observed without matching access evidence in the current dataset.Check timing, alternate URLs, cached access, agent classification, hostname coverage, and ingestion gaps.
    YesYesBoth signals were observed. The data still does not establish request-level causation.Inspect consistency, citation context, answer accuracy, and changes across comparable windows.

    Keep referral traffic as a separate downstream signal. A bot request is not a citation, and a citation is not a visit. Combining the three can help you see a pathway from technical access to visibility to site activity, but each transition has its own coverage limits. Label the stages rather than collapsing them into a single number.

    Put the integration into production with a decision-first runbook

    1. Select one recurring decision. Name the person who makes it and the action they may take.
    2. Declare the analysis scope. Record the properties, hostnames, priority content set, agent classes, prompt set, surfaces, locale, timezone, and observation window.
    3. Write the data contract. Define every field, accepted response state, normalization rule, null behavior, freshness expectation, and source of record.
    4. Connect data with read-only access. Start with the smallest permissions and fields that can answer the chosen question.
    5. Reconcile samples. Trace selected records from the originating system through normalization and into the final query. Confirm that redirects, parameter variants, unknown bots, duplicates, and missing fields behave as documented.
    6. Create the shared content key. Map observed and cited URL variants to a stable content ID without deleting their original forms.
    7. Expose one bounded query. Return the result together with scope, freshness, filters, and completeness metadata through MCP or an SDK workflow.
    8. Test failure states. Disable or restrict a test credential, supply an invalid filter, simulate delayed input, and confirm that each problem produces an explicit error or unknown state rather than an empty success.
    9. Attach an action. Give every alert an owner, diagnostic query, safe response, escalation path, and change record.
    10. Review the decision, not just the pipeline. If the output does not change what the owner does, narrow the question or retire the integration.

    A strong first production query is deliberately narrow: show priority content that received qualifying agent activity but had no citation in a specified prompt set, and include the reporting window, data freshness, classification basis, and coverage state. That result gives an SEO or content owner a finite investigation queue without pretending to explain the cause.

    Start there. Once your team can trace a decision from raw event to normalized evidence to an owned action, add another question. That sequence turns integrations into an observability system your team can challenge, maintain, and actually use.

    References