Tag: Accountability

  • SEO Governance Maturity: Build a Program That Survives You

    SEO Governance Maturity: Build a Program That Survives You

    Your SEO program can look healthy right up until a key specialist takes leave, a regional team publishes outside the normal process, or a platform release bypasses SEO review. If approvals, standards, and quality checks live in one person’s memory, the program’s apparent maturity is borrowed from that person.

    The practical goal of SEO governance is to make good decisions repeatable. You need clear decision rights, standards that appear where work happens, evidence that controls are being used, and enough shared capability for the system to keep working through ordinary organizational change.

    Maturity begins where the expert stops

    A technical SEO audit asks what is wrong with a website. A governance maturity assessment asks why the organization produced that condition, whether it can prevent a recurrence, and who is accountable for doing so.

    That distinction matters because execution and maturity are not the same thing. A team can run sophisticated crawls, write detailed recommendations, and resolve difficult indexing problems while remaining organizationally fragile. The stronger test is whether the capability survives when the usual expert is away, promoted, or gone.

    You can expose that fragility without launching a large transformation project. Choose one recently completed change that could affect search visibility. Trace it from request to release:

    • Who decided that the change should happen?
    • Who had authority to approve or reject it?
    • What documented standard governed the decision?
    • Where was SEO quality checked?
    • What evidence shows that the check occurred?
    • Who would have performed each step if the usual specialist had been unavailable?
    • Who owned the response if the release produced an unexpected result?

    If the path breaks when one named person is removed, you have found a single point of failure. That person may be highly capable and generous with their time. The problem is still structural. Access to their memory is not an organizational control.

    Watch for softer versions of the same problem. A manager may know that an SEO process exists but not who owns it. A standard may live in a slide deck that delivery teams never open. Quality assurance may happen, but leave no record. A specialist may repeatedly correct the same defect because the publishing or release workflow never changed. Each condition tells you that expertise has not yet become shared capability.

    Maturity does not mean eliminating experts. It means using their expertise to design standards, controls, training, and escalation paths that other people can follow. The expert should handle genuinely difficult judgment calls, not serve as the organization’s only memory of how routine work gets done.

    Define governance domains around your failure paths
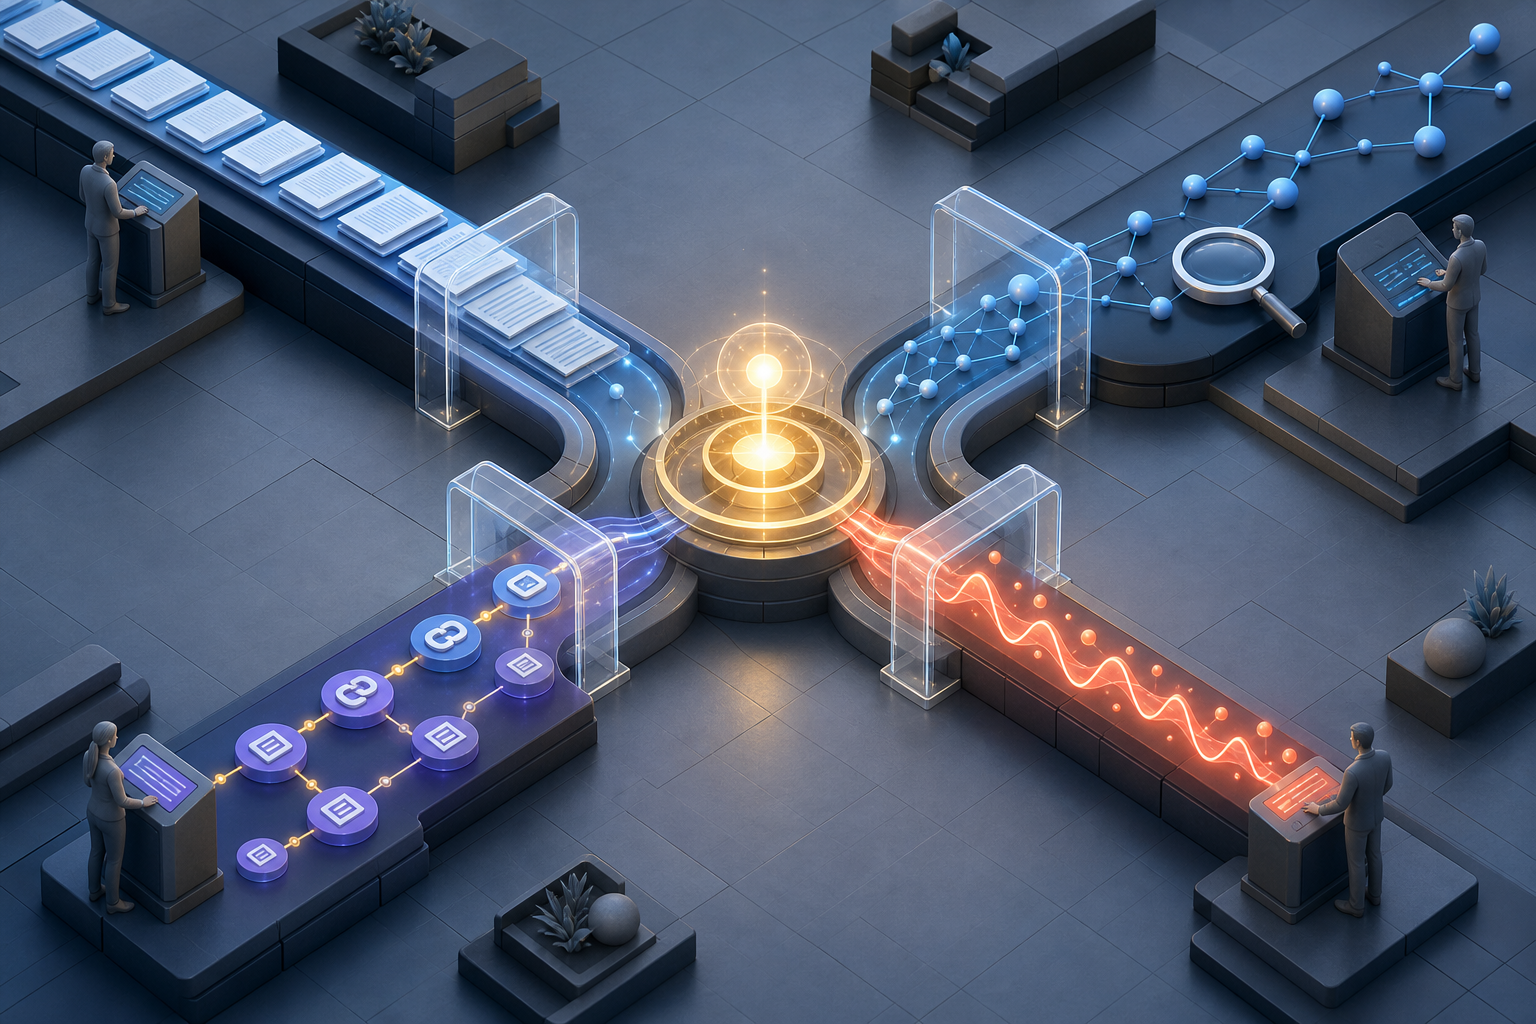
    Regional publishers, engineers, and marketers guide web content and release components through separate checkpoints into one shared system.

    There is no useful universal list of SEO governance domains. Your domains should match the ways your organization makes changes and the places where visibility can be damaged. A business with one editorial site has a different governance surface from a marketplace, an international company, or a brand with hundreds of locations.

    Start by mapping the operating areas that can independently create, alter, consolidate, or remove search-facing assets. Common domains include:

    • Technical change governance: platform releases, templates, migrations, crawling directives, indexing controls, redirects, rendering, and performance changes.
    • Content governance: topic ownership, briefing, approval, duplication, updating, consolidation, retirement, and the relationship between editorial and commercial pages.
    • Structured data governance: eligible page types, required properties, factual approval, implementation ownership, validation, and maintenance when templates change.
    • Local visibility governance: location-page ownership, business information, local contributions, shared templates, and the boundary between central and regional publishing.
    • Measurement governance: metric definitions, reporting ownership, annotations, access, data-quality checks, and escalation when tracking changes.
    • AI visibility and answer governance: ownership of entity facts, answer-oriented content, citations, structured information, and claims that require specialist approval.

    Do not include a domain merely because it appears on someone else’s checklist. Include it when a team in your organization can make decisions in that area, when the area has distinct owners or workflows, or when failure there needs a specific control.

    Multi-location SEO shows why the boundary matters. If central marketing, regional teams, and individual locations can all publish for the same demand without agreed page ownership, the organization can create internal competition between its own pages. An optimization tool can identify overlap, but it cannot decide which organizational layer owns a topic or which team has final publishing authority.

    For a multi-location domain, settle those governance questions before debating individual keywords:

    • Which needs belong on national, regional, or location-specific pages?
    • Who decides the intended page when multiple teams want to target the same need?
    • Which facts must remain consistent across every location?
    • Which sections require genuinely local input?
    • Who can create a new location page or change its purpose?
    • What review is required before a shared template is changed?
    • Who resolves an overlap between pages owned by different teams?

    Create a short governance card for each domain. Record its purpose, decisions in scope, accountable role, participating teams, controlling standards, quality checks, exception path, backup owner, and evidence location. A domain that cannot be described this way is not ready to be scored.

    Give every material SEO decision an owner and a control

    The person completing a task is not automatically the person who owns the decision. A developer may implement a directive, an editor may change a page, and a regional marketer may submit local information. Governance identifies who has the authority and accountability to decide what should happen.

    Name roles rather than individuals wherever possible. “Content operations lead” remains meaningful when employees change; a person’s name does not. Then name a backup role with the access and training needed to act. Listing a backup who cannot reach the system, interpret the standard, or approve an exception creates the appearance of resilience without the capability.

    Governance elementQuestion it must settleAcceptable evidence
    ScopeWhich changes and assets are governed?A domain definition linked from the relevant workflow
    AuthorityWho can approve, reject, or escalate a decision?A named accountable role and an enabled backup role
    StandardWhat does acceptable work require?A versioned, testable rule available at the point of work
    Quality assuranceHow is compliance verified before or after release?A completed check, test result, or review record
    ExceptionWho can permit a departure, and for how long?An approval with rationale, owner, review condition, and expiry or closure
    ContinuityCan the capability operate without its usual owner?Access, training, documentation, and a completed handoff or coverage test

    A policy that says “follow SEO best practices” does not provide a usable standard. A working standard states what triggers it, what must happen, who verifies the result, what evidence must be retained, and how an exception is handled. It should be specific enough that two qualified people can reach a consistent decision without reconstructing the original author’s intent.

    Put the control where the risk enters the system. If a content requirement matters during briefing, add it to the brief rather than relying on a final audit. If a template change requires SEO review, make that review part of the release workflow. If local teams need approval before creating a new page, put the approval in the request path. A document stored elsewhere may support the control, but it does not replace the trigger.

    Use the lightest control that fits the possible impact. A small edit to one page may need only the page owner’s review. A template change that affects every location needs clearer approval, recorded quality assurance, an accountable release owner, and a response path if the outcome is wrong. Governance becomes bureaucracy when every change receives the same treatment; it becomes useful when scrutiny rises with the reach and reversibility of the decision.

    Score evidence, not confidence
    A balance scale weighs tangible audit artifacts and control tokens against empty translucent shapes on a governance workbench.

    A maturity assessment is not a survey of how professional the SEO team feels. It tests whether governance is understood, documented, used, and resilient. Ask managers and senior leaders questions they should be able to answer about ownership and accountability. Ask practitioners for the standards, workflow records, and quality evidence that show what happens in practice.

    Collect initial answers separately. If everyone aligns in a workshop before answering, the specialist can unknowingly supply the missing knowledge for the group. The gap you need to see is whether responsible leaders already know the operating model.

    Use the same core questions for every domain:

    • Which role is accountable for this domain?
    • Which events trigger its review or approval process?
    • Where is the current standard, and who maintains it?
    • How is an exception approved and revisited?
    • What is the most recent evidence that the control was used?
    • Who covers the accountable role when its usual owner is unavailable?
    • How are affected teams trained when the standard changes?
    • How does a repeated defect become a workflow or control improvement?

    An answer such as “the SEO lead handles that” identifies a dependency, not ownership. “I would need to ask our specialist” is also a result. It shows that the knowledge has not been institutionalized at the level where accountability is supposed to sit.

    You can use this simple internal scale to make the findings comparable over time. It is a working rubric, not a universal industry standard.

    ScoreMaturity stateWhat must be true
    0Person-dependentOwnership or standards are unclear, and correct execution relies mainly on individual memory.
    1DocumentedAn owner and standard exist, but adoption is inconsistent or evidence of use is missing.
    2OperationalThe workflow triggers the control, quality evidence is retained, and exceptions follow a defined path.
    3ResilientEnabled backup ownership, maintained training, and demonstrated continuity allow the capability to operate through absence or role change.

    Require evidence before assigning a score. A confident verbal answer is weaker than a current standard. A current standard is weaker than a completed workflow record. A completed record still does not prove continuity unless another enabled person can operate the process.

    Keep the domain scores and the underlying findings visible. A single enterprise average can hide a critical zero in migration governance, local publishing, or another high-impact domain. Record single points of failure separately so that a reasonable average does not make them disappear.

    Use the first assessment as an internal baseline. Comparing your number with another company is not meaningful when business models, domain combinations, organizational structures, and scoring evidence differ. The useful comparison is your own movement from person-dependent work toward shared, documented capability.

    Turn the score into an operating system

    A maturity score has little value if it ends as a presentation. Convert each important gap into an operating change with an owner and observable completion criteria.

    Prioritize the remediation in this order:

    1. Remove dangerous single points of failure. Start where one unavailable person can block a release, permit an uncontrolled change, or leave a widespread problem without an owner.
    2. Control changes with the widest reach. Shared templates, platform rules, migrations, and multi-location publishing deserve attention before isolated low-impact edits.
    3. Fix recurring failure paths. When the same defect returns, stop treating each instance as a new task. Change the brief, ticket, CMS workflow, release check, or training that keeps allowing it.
    4. Move standards to the point of work. Link requirements from the systems where people request, create, approve, and release changes.
    5. Enable and test backup ownership. Give the backup role access, context, and decision authority, then use a planned handoff or coverage period to expose missing knowledge.
    6. Reassess with the same evidence rules. Raise a score only when the control is being used and continuity is demonstrated, not merely because a document was created.

    Write remediation items as capability outcomes. “Create SEO documentation” is an activity with no clear finish line. “A trained backup can approve a location-page request using the current standard, and the workflow retains the approval record” describes a capability you can verify.

    Every completed governance improvement should leave behind six things: an accountable role, an enabled backup, a usable standard, a workflow trigger, quality evidence, and an exception path. If one is missing, record the remaining dependency instead of declaring the domain mature.

    Key takeaways

    • SEO maturity is the organization’s ability to preserve good decisions through routine change, not the sophistication of one expert’s work.
    • Score ownership, standards, adoption, evidence, and continuity separately from technical execution.
    • Define governance domains around your business model and actual failure paths rather than copying a universal checklist.
    • Treat dependence on a named person as a single point of failure, even when that person is highly capable.
    • Place controls inside briefs, tickets, publishing workflows, and release processes so that standards appear when decisions are made.
    • Use maturity scores as an internal baseline over time, not as a competitive benchmark.

    Start with one failure-prone domain and trace one recent change from request to release. Name the first point where the process depends on memory, then replace that dependency with an owner, a standard, a control, and a working backup. That is the smallest useful unit of SEO maturity.
    References

  • SEO Interview Mistakes: How to Answer with Evidence

    SEO Interview Mistakes: How to Answer with Evidence

    You can understand SEO and still give a weak interview answer. An interviewer asks about a migration, you start discussing everything you know about redirects and canonical tags, and the answer never reveals what you owned, why you made a decision, or whether the work succeeded.

    The fix is not to memorize more SEO terminology. You need a small bank of relevant evidence, a direct way to handle unfamiliar questions, and the judgment to explain your work without exaggerating it. Here is how to prepare for the mistakes that cost otherwise capable candidates.

    Build an evidence bank before you rehearse answers

    Hands organize text-free project cards, webpage mockups, colored tabs, and outcome markers into evidence groups on a desk.

    Vague project descriptions usually begin with weak preparation. If your notes say only “technical audit” or “traffic recovery,” you will have to reconstruct the important details while an interviewer waits. That is when responsibilities blur, results disappear, and answers become generic.

    Choose stories that match the actual role

    Start with the job description. Highlight the problems the successful candidate will be expected to solve, then attach a real project to each important responsibility. Senior technical SEO candidates should be ready to discuss areas such as crawling or indexing problems, organic traffic declines, website migrations, and projects that required stakeholder support. Candidates for account-focused roles need evidence about explaining performance, presenting strategy to different audiences, and onboarding clients after a pitch.

    Do not force one impressive story into every answer. A migration example will not automatically prove that you can resolve stakeholder conflict, explain a forecast, or prioritize work under a constraint. Choose examples for the capability they demonstrate, not merely for the size of the project.

    Turn each story into an evidence card

    Use the STAR structure, but make each part concrete enough to survive follow-up questions:

    • Situation: What was happening, how did you know, and why did it matter? Name the affected site area, audience, or business process instead of saying there was “an SEO issue.”
    • Task: What outcome were you responsible for? Separate your mandate from the wider team objective.
    • Action: What did you inspect, decide, prioritize, recommend, or coordinate? Explain why you chose that path and what constraint shaped the decision.
    • Result: What changed, what evidence showed the change, and what did you learn? If the project fell short, explain the gap and what you would alter next time.

    Add an ownership line to every card: “I owned…; I contributed…; another team owned….” Add the names of the metrics you used, but only include figures you can defend and are permitted to disclose. If a result is confidential, say so and describe the outcome at an appropriate level rather than inventing precision.

    You are not writing a speech. You are creating a fact sheet that prevents you from losing the useful details under pressure. Practice explaining each project in a short version, then keep the diagnostic reasoning, trade-offs, and lessons available for follow-up questions.

    Answer the question before you explain your reasoning

    Many poor answers contain relevant knowledge but never address what was asked. If the question is about leading a complex migration, a long explanation of migration risks is not evidence that you led one. Interviewers notice when a candidate redirects the conversation toward a safer subject.

    Use an answer-first sequence:

    1. Give the direct answer. Say yes, no, partly, or state your conclusion.
    2. Present the closest evidence. Use a prepared project and make your role explicit.
    3. Explain the reasoning. Describe the important decision, evidence, trade-off, or constraint.
    4. State the boundary. Clarify what you did not own, what remains uncertain, or what information you would need.

    This sequence keeps the answer useful even when the question is difficult. It also prevents background detail from burying the point.

    When the question is unclear

    Ask for clarification before committing to an answer. For example: “Would you like me to focus on how I diagnosed the decline, how I communicated it, or both?” That is not evasive. It shows that you can define the task before solving it.

    If you need to think, say so briefly. A considered pause is better than filling the space with loosely related facts. Listening carefully, requesting clarification, and structuring the response produce more substance than speaking before you know where the answer is going.

    When you lack the exact experience

    Do not manufacture a project. Use a clean boundary statement:

    “I have not led that type of migration end to end. I did own the validation work for a related change. Here is what I handled, and here is how I would extend that experience to the scenario you described.”

    Then separate experience from proposed method. Describe what you have done as evidence. Describe what you would do as a plan. Acknowledging an unfamiliar situation and explaining a sensible approach is more credible than presenting a hypothetical as history.

    For a hypothetical technical problem, make your reasoning inspectable. State what you would verify first, which competing explanations you would consider, what evidence would distinguish them, and what action would depend on the result. The interviewer can then evaluate your method even if the scenario is new to you.

    Sound confident without misreading the room

    Confidence in an SEO interview comes from clear claims with visible evidence. Arrogance appears when you treat a context-dependent conclusion as universal, dismiss another interpretation, or assume the company has ignored an obvious problem.

    A strong claim has boundaries: “We prioritized this explanation because the affected URLs shared these characteristics. I would reconsider it if the segmentation or technical evidence changed.” You are still stating a position, but you are also showing how it could be tested. That makes disagreement productive instead of personal.

    Confident candidates can explain accomplishments, complex work, results, and stakeholder support while remaining open to another informed view. SEO decisions depend on the site, resources, business model, data, and timing. An answer that leaves room for those conditions sounds more experienced, not less certain.

    Match the explanation to the interviewer

    Listen to the language in the question and adjust the depth of your answer:

    • For a business stakeholder: lead with the consequence, the decision required, the dependency, and the expected way you would measure progress. Define technical terms only when they affect the decision.
    • For an engineering or product partner: explain the behavior, the affected templates or process, the implementation dependency, and how you would validate the change.
    • For an SEO specialist: expose the mechanism, evidence, alternative hypotheses, and trade-offs. Do not use jargon as a substitute for the causal explanation.

    These are not different versions of the truth. They are different levels of resolution. Misreading the audience can make a knowledgeable candidate sound either inaccessible or superficial.

    Critique the company site without insulting the people behind it

    You may be asked what you would improve on the company’s site. Treat what you can see as an observation, not proof of negligence. You do not know the roadmap, platform limitations, legal requirements, release process, prior experiments, or internal priorities.

    A useful response follows this pattern: observation, possible consequence, validation need, and constraint question. For example: “Some important pages appear difficult to reach through the internal navigation. I would verify that pattern with crawl, search, and traffic data before prioritizing it. What has already been investigated, and what constrains changes to those templates?”

    This still demonstrates your eye for problems. It also recognizes that visible SEO issues can persist because a team is working through constraints. The question about constraints may reveal more about the role than the issue itself: ownership, release friction, data access, or the level of support available for implementation.

    Protect your credibility when the pressure rises

    A composed job candidate pauses thoughtfully while two interviewers listen across a conference table.

    An interviewer can teach a new employee an internal process. It is much harder to work around unreliable claims, poor judgment, or conduct that creates risk. Several memorable interview mistakes are credibility failures rather than knowledge gaps.

    Describe your role with exact ownership

    Use “I” for decisions and work you personally completed. Use “we” for shared delivery, then identify the other functions involved. A clear account might say: “I diagnosed the pattern and wrote the requirements. Engineering implemented the template change, analytics supported validation, and I monitored the SEO outcome.”

    Do not upgrade participation into leadership. Exaggerated project ownership tends to surface during detailed follow-up questions, when the candidate cannot explain decisions that the actual owner would understand. Honest contribution to a difficult team project is stronger evidence than a leadership claim you cannot support.

    Replace “Google lies” with a testable explanation

    A mismatch between guidance and observed results is not an analysis. If you reach for “Google lies,” you stop the reasoning at the point where it should become more precise.

    Build a hypothesis tree instead. Ask whether you are comparing the same definitions, site segment, query set, time period, and stage of the search process. Separate crawling, indexing, ranking, and measurement. Consider whether another site change could explain the pattern. Then say what evidence would support or weaken each explanation.

    You do not have to agree with every public statement. You do have to show a rational path from observation to conclusion. Blaming an unexplained discrepancy on deception can make a candidate look less technically rigorous because the label replaces diagnosis.

    Keep ethics and follow-up inside professional boundaries

    Do not offer backlinks, supposedly exclusive tactics, favors, or anything else that resembles a bribe. Never imply that you could take negative action against a company. Promises and threats of this kind do not demonstrate SEO ability; they raise immediate questions about integrity and risk.

    Use the established hiring channel for follow-up. Send a concise note that thanks the interviewer, refers to a substantive part of the conversation, and supplies any information you agreed to provide. Do not repeatedly contact unrelated employees to create visibility. Enthusiasm becomes counterproductive when outreach overwhelms people outside the formal process.

    Key takeaways for your next SEO interview

    • Prepare role-specific project evidence, not a generic collection of SEO talking points.
    • Structure each example around the situation, your task, your actions, the result, and the exact boundary of your ownership.
    • Answer the question directly before adding context. If you lack the experience, say so and distinguish transferable evidence from your proposed approach.
    • Adjust the depth of your explanation to the interviewer while keeping the underlying facts consistent.
    • Critique a site as an informed outsider: state the observation, identify what requires validation, and ask about constraints.
    • Protect trust by avoiding inflated ownership, unsupported accusations, unethical offers, threats, and excessive outreach.

    Before your next interview, choose the hardest likely question in the job description and answer it aloud. Cut any sentence that hides your role, delays the answer, or asserts more than your evidence supports. What remains is the version an interviewer can understand, test, and trust.

    References

  • Positionless Marketing: A Practical Operating Model

    Positionless Marketing: A Practical Operating Model

    Your team spots a high-intent query, a change in customer behavior or a retention risk. Then the signal starts a tour of the org chart. An analyst defines the audience, a strategist writes the brief, a creator develops the message, a specialist reviews it, operations builds it and a leader approves it. Every person may work quickly, yet the customer moment expires in the queues.

    This is where positionless marketing earns its keep. It gives a value-focused team the skills, data, tools and authority to carry work from insight through activation and measurement. You gain speed because the work stops changing owners at every stage, not merely because AI produces a draft faster. Done well, the model combines autonomy with explicit outcomes, decision rights and controls.

    Positionless marketing changes the workflow, not the need for expertise

    Positionless marketing is an operating model in which marketers can work across traditional boundaries to deliver a customer or business outcome. The team can find an insight, create an appropriate response, activate it and learn from the result without automatically handing each step to another department.

    It is not a plan to erase job titles, make everyone equally good at everything or remove specialist review. Deep expertise still matters in areas such as analytics, brand, privacy, development, accessibility, paid media and structured data. What changes is the way that expertise enters the workflow. Specialists define standards, create approved paths and handle genuine exceptions. They do not need to become a queue for every routine decision.

    Make the unit of work an outcome

    The practical shift is from organizing around channel deliverables to organizing around value. That requires a more demanding brief. A team should not exist merely to send campaigns, publish pages or generate leads. It should own a change that matters to the customer and the business.

    • Replace publish more content with answer a defined set of high-intent customer questions and improve qualified progression.
    • Replace run retention campaigns with reduce the delay between a meaningful customer signal and a relevant response.
    • Replace implement an AI platform with help marketers move safely from insight to activation without avoidable dependencies.
    • Replace improve personalization with increase a defined customer behavior while respecting consent, contact and brand rules.

    The distinction matters because a team cannot make sound independent decisions when success is vague. If the objective is more activity, AI will help produce more activity. If the objective is customer value, the team can decide whether a page update, lifecycle message, offer, experiment or no action at all is the best response.

    A useful test is simple: ask whether the team can state the customer, the relevant moment, the desired behavior, the business value and the constraint it must not violate. If those elements are unclear, the team is not ready for broader autonomy. Clarify the outcome before changing the org chart or buying another tool.

    Find the handoff tax before you redesign the team

    A glowing customer signal moves through a long sequence of separated workstations, review gates, and waiting trays beside an hourglass.

    Do not map the ideal process described in a policy deck. Take a recently completed campaign, content update or customer journey and reconstruct what actually happened. Begin when the signal first became actionable and end when the response went live and could be measured.

    For every stage, record who did the work, who approved it, which system they used, when the work arrived, when active work began, when it ended and why it moved elsewhere. Include rework loops. A stage that takes little effort can still create a large delay when it sits in another team’s queue.

    Classify every dependency

    Ask the same question at each handoff: was this dependency required by risk, required by scarce expertise or inherited from historical ownership? That classification tells you what to change.

    • Risk-required: Keep the control, but define exactly what triggers it. A novel data use may need privacy review; a routine segment built from an approved definition may not.
    • Expertise-required: Give the value team a reusable template, training or embedded specialist. Reserve central experts for work that truly needs their depth.
    • Ownership-required: Challenge it. If a trained marketer could safely complete the task with the right permission, the handoff is a candidate for removal.
    • Technology-created: Connect the systems, standardize the definition or remove the duplicate entry. Do not institutionalize a manual workaround without examining the underlying separation.

    Watch for recognizable symptoms: audience definitions rebuilt in several tools, marketers exporting data before they can use it, tickets raised for routine changes, approvals based on seniority rather than risk, reports that stop at channel activity and work that has no accountable owner after launch. These are operating-model problems even when they appear inside software.

    Caesars Entertainment provides a useful illustration of the mechanism. Marketers previously assembled targeting lists manually, coordinated work across disconnected systems and waited on other teams. After data, orchestration and execution were brought together and marketers could operate the workflow, reported campaign execution time fell from five days to five minutes. That company-specific result is not a universal benchmark. The transferable lesson is that faster content generation alone would not have removed the waiting, duplicate work and access dependencies.

    Create a workflow card before proposing a solution

    Summarize the diagnosis on a compact workflow card. Include the value outcome, triggering signal, intended audience, action, accountable owner, required capabilities, system access, current handoffs, primary measure, guardrails and escalation conditions. This prevents a familiar mistake: treating a visible tool limitation while leaving unclear objectives and slow decisions untouched.

    Build a pilot around a bounded customer outcome

    A company-wide positionless transformation is difficult to learn from because too many variables change at once. Start with a bounded value stream where the team can observe the signal, take a meaningful action and measure the result. The work should matter enough to justify change but be contained enough that the organization can define safe decision rights.

    A suitable pilot has a recurring workflow, a retrievable baseline, an identifiable customer context and several avoidable handoffs. It also gives the team ownership of enough of the chain to affect the outcome. Renaming a campaign group while every decision remains outside the group is not a pilot of positionless marketing.

    For an SEO, AEO or GEO team, a pilot might focus on a defined cluster of high-intent buyer questions. The team could own demand and audience signals, evidence collection, content creation, on-page optimization, approved JSON-LD, publication, distribution, measurement and refresh decisions. Structured data must still describe facts present on the page, and no markup should be treated as a guarantee of search or AI visibility. The operating advantage comes from letting the team complete approved work without opening a new queue for every field change.

    Write an outcome contract

    Before the pilot starts, write a short contract that makes autonomy testable. It should specify:

    • Customer context: The audience, behavior or moment the team is responsible for.
    • Desired change: The customer action and business value the work is intended to influence.
    • Primary measure: The outcome used to judge value, such as purchase, retention, qualified progression, customer lifetime value or return on investment.
    • Operational measure: The delay from an actionable signal to a live response, including queue time rather than only active production time.
    • Guardrails: The quality, brand, privacy, accessibility, contact, budget and data rules the team cannot cross.
    • Decision scope: The actions the team can take without additional approval.
    • Escalation conditions: The exceptions that require a named specialist or leader, along with who makes the final decision.

    Do not let activity metrics substitute for the outcome. Pages published, variants created and campaigns launched can help explain capacity, but they do not establish value. Pair the primary outcome with cycle time, avoidable handoffs, rework and guardrail performance. Capture the same measures before the pilot so the team can compare the new workflow with its own baseline.

    Build around capabilities, not miniature silos

    The pilot needs insight, creative, activation, measurement and governance capabilities. Those are accountabilities, not compulsory departments inside the team. A person may cover several capabilities, and a specialist may be embedded or available through a defined exception path. What matters is that every accountability has a name and no stage disappears into collective ownership.

    1. State the outcome and establish the current baseline.
    2. Map the capabilities, system permissions and knowledge required to own the workflow.
    3. Publish the team’s decision rights, guardrails and escalation path.
    4. Connect the minimum data, creation, activation and measurement flow needed for the pilot.
    5. Run the real workflow and log every pause, external dependency, rework loop and exception.
    6. Review customer value, speed, quality and resource use before expanding the model.

    Scale only what the evidence supports. A faster workflow that harms outcome quality or repeatedly violates controls has not succeeded. A team that improves the outcome but still waits for the same routine approvals has found value without yet achieving the operating-model change.

    Give the team autonomy through explicit guardrails

    Three marketers operate a compact campaign workspace inside a luminous boundary marked by safety rails, checkpoints, and organized resources.

    Autonomy is not the absence of oversight. It is a decision system that tells trained people what they may do, which standards apply and when the risk changes enough to require help. Without that clarity, cautious marketers keep asking permission while aggressive marketers make inconsistent choices.

    Convert broad policies into operational rules. The team should be able to determine whether an action is routine or exceptional without interpreting leadership intent from scratch.

    Work areaThe team can proceed whenSpecialist review is triggered when
    Audience and personalizationThe team uses approved data, definitions, consent rules and contact policies.The action introduces a new data purpose, sensitive segment or customer-contact rule.
    Content, SEO, AEO and GEOClaims are supported, edits follow approved standards and structured data matches visible page facts.The work adds an unsupported or regulated claim, unverified entity fact, custom code or material policy exception.
    Campaign orchestrationThe audience, channel, frequency, offer and budget remain inside agreed limits.The action exceeds those limits, creates material financial exposure or conflicts with another customer journey.
    ExperimentsThe change is reversible, its primary measure is defined and exposure follows approved rules.The experience is difficult to reverse, affects a protected area or conflicts with a standing commitment.
    Platforms and data movementThe workflow uses existing integrations, permissions and approved destinations.It requires a new integration, export, permission scope or external data destination.

    The precise entries will differ by business. The important design choice is separating routine work from exceptions. Central specialists should own standards, reusable templates, capability development and difficult cases. The value team should own decisions inside the approved path.

    Use technology to remove distance between signal and action

    The technology test is not how many AI features a platform offers. Ask whether the team can move from a trusted signal to an appropriate action and then measure it without manual exports, duplicate definitions or avoidable tickets.

    The minimum flow usually needs reliable data, shared audience and content definitions, creation tools, orchestration or publishing, measurement, permissions and an audit trail. It can live in one platform or in well-integrated tools. A nominally unified stack still fails if marketers cannot access it, definitions disagree or activation remains controlled by an unrelated queue.

    AI can compress research, analysis, drafting, variation and orchestration tasks. It does not resolve an unclear objective or decide which risk the business is willing to accept. Give the team approved inputs, verification requirements, data-handling rules and a record of what was generated or changed. Train people on the complete workflow, including exception scenarios, rather than limiting training to a product demonstration.

    Keep the model from turning into old silos with new labels

    The model will drift back toward assembly-line marketing unless leaders change how work is funded, reviewed and rewarded. A new team name cannot overcome objectives, permissions and incentives that still reinforce functional ownership.

    • Outcome fog: The team reports launches and assets because no customer or business result was defined. Correct it by making the outcome contract the basis of prioritization and review.
    • Phantom autonomy: Leaders encourage initiative but retain routine approvals. Correct it by publishing decision rights and measuring how much work still leaves the team.
    • Silo-preserving leadership: Functional leaders optimize their own queue, budget or platform even when the value stream suffers. Correct it by assigning an accountable value owner and resolving conflicts against the shared outcome.
    • Accountability by committee: Everyone contributes, but nobody owns the result after activation. Correct it by naming who answers for the outcome, who owns each control and who decides exceptions.
    • A stagnant learning culture: People avoid new authority because bounded mistakes are punished or because old processes feel safer. Correct it by distinguishing a compliant experiment that underperforms from a guardrail breach.
    • Disconnected technology: New AI tools create another work surface while data and execution remain separate. Correct it by evaluating the end-to-end flow, not feature adoption in isolation.

    Use a scorecard that exposes the operating model

    Review the pilot against its own baseline. Keep the scorecard small enough that every measure affects a decision. It should show the primary customer or business outcome, time from signal to live action, time spent waiting versus doing, avoidable handoffs, rework, resource use and guardrail failures. If value improves but waiting does not, investigate the remaining dependencies. If speed improves but quality deteriorates, tighten the path before expanding access.

    Key takeaways

    • Positionless marketing organizes work around customer and business value rather than channel deliverables or job-title boundaries.
    • It removes avoidable queues, not expertise, accountability or risk controls.
    • The best starting point is a bounded workflow with a measurable outcome and visible handoffs.
    • Teams need system access, cross-functional capabilities, explicit decision rights and a named escalation path.
    • Measure the outcome alongside signal-to-action time, waiting, rework, resource use and guardrail performance.
    • Scale the model only when it improves value without weakening quality or control.

    Your next move does not need to be a reorganization announcement. Take the last important campaign or content update and mark every place where it waited, changed owners or had to be rebuilt. Find the longest avoidable queue. Then change the decision rule, permission, capability or system connection that created it. That gives you a real positionless marketing pilot and evidence for what should change next.

    References

  • AI Marketing Governance: Scale Creative Without Losing Trust

    AI Marketing Governance: Scale Creative Without Losing Trust

    You have a campaign due, the platform wants more assets than your team can shoot, and an AI tool can produce the missing scenes in minutes. The production problem looks solved. The harder question arrives at approval: does the result still represent the product, the customer and the brand truthfully?

    You do not need to choose between using AI and being authentic. You need a governance system that distinguishes harmless assistance from consequential manipulation, preserves evidence for every claim and stops questionable work before speed turns it into scale.

    Key takeaways

    • Authenticity is not the absence of AI. It is the absence of a misleading gap between what your marketing depicts and what a reasonable customer would believe.
    • Govern the output and its likely interpretation, not the name of the tool that produced it.
    • Give every AI-assisted asset a source record, a named approver and a defined withdrawal path before publication.
    • Disclosure can explain how an asset was made, but it cannot make a false product claim, invented testimonial or nonexistent result acceptable.
    • Use the same approved facts across ads, landing pages, product feeds, public relations, structured data and answer-engine content. Contradictory claims weaken both customer trust and machine-readable credibility.

    Authenticity is a truth boundary, not a production method

    A manually produced campaign can be deceptive. An AI-assisted campaign can be accurate. The relevant distinction is not human versus machine; it is faithful representation versus manufactured belief.

    That distinction matters because AI can now support a wide range of creative operations, including background removal, lifestyle-scene generation, synthetic people and rapid asset variation. The resulting production capacity is useful, but technical permission is not the same as brand permission. Your policy has to decide what the audience may reasonably infer from the finished asset.

    Use four questions at the creative brief, review and approval stages:

    1. What will the audience think is real? Identify the likely interpretation, not merely the literal elements on screen. A person may understand that a decorative background is illustrative while assuming a product demonstration, testimonial or before-and-after image records a real event.
    2. Does the synthetic element affect the decision? Color accuracy, dimensions, included features, product condition, customer identity, quoted experience and demonstrated outcomes can all influence a purchase or trust decision. Treat those elements as material.
    3. Can the implied claim be substantiated? You should be able to trace a factual statement or visual implication to an approved product record, documented result or other internal evidence. If the evidence cannot be found, the asset is not ready.
    4. Would knowledge of the AI intervention change the audience’s judgment? If the answer is yes, redesign the asset, disclose the intervention clearly or do both. Do not hide a consequential transformation behind a broad statement that AI was used somewhere in production.

    A synthetic background behind an unchanged product may create little expectation risk. A synthetic person presented in a way that resembles a customer, employee or expert creates much more. A generated product feature that does not exist crosses the truth boundary entirely.

    Disclosure belongs after this truth test, not in place of it. A label can tell someone that an image is simulated. It cannot repair an inaccurate price, fake endorsement, invented review, altered package size or performance claim that your evidence does not support. When the underlying claim could create compliance or legal exposure, pause publication and route it to the appropriate qualified reviewer. A creative approval is not a substitute for legal review.

    Use a four-level integrity ladder for AI-assisted work

    Four ascending studio platforms show increasingly consequential forms of AI-assisted product imagery connected to a real product by a golden thread.

    A practical policy needs more than a general instruction to use AI responsibly. A four-level brand integrity hierarchy gives marketers, agencies and approvers a shared way to classify work before debating individual assets.

    Integrity levelTypical outputDefault decisionRequired control
    AssistanceResizing, cropping, cleanup, formatting or copy variation that preserves the approved meaningAllowed within documented brand rulesRetain the original and confirm that facts, qualifications and visual product attributes did not change
    AdaptationBackground replacement, contextual scenes, localization or audience variants built around a real product or approved claimAllowed with reviewRecord what was synthetic, verify the product representation and decide whether the context needs disclosure
    SynthesisSynthetic people, realistic events, demonstrations or scenes that an audience could interpret as documentary evidenceConditional and escalatedRequire an accountable approver, a documented disclosure decision, substantiation for every implication and confirmation that no real person’s identity is being misrepresented
    FabricationInvented testimonials, nonexistent features, unsupported outcomes, fake certifications or materially altered productsProhibitedDo not publish; correct the brief or obtain valid evidence for a truthful alternative

    Classify the finished output, not the software. The same generator could perform low-risk cleanup in one workflow and create an unacceptable customer simulation in another. Tool-based rules age quickly and invite loopholes; output-based rules remain understandable when platforms change their features.

    Context can also move an asset up the ladder. Replacing the background behind a product is usually adaptation. It becomes more consequential if the new setting implies that the product is certified for a particular environment, fits a space it does not fit or has a capability it does not have. Likewise, a synthetic human used as decorative illustration differs from one presented beside testimonial language that implies a genuine experience.

    Write examples from your own campaigns beside each level. Include one clearly allowed example, one conditional example and one prohibited example for the channels your team actually uses. Those precedents will resolve ordinary decisions faster than an abstract ethics statement.

    Turn the policy into a publishing gate

    Reviewers inspect a marketing image, a physical product and supporting papers as creative assets pass through a transparent publishing checkpoint.

    A governance document does not protect the brand if approval still happens in chat threads, source files disappear and nobody can identify who accepted the risk. The control has to sit inside the publishing workflow.

    Your operating policy should define:

    • Scope: the channels, teams, contractors, agencies and asset types covered by the policy.
    • Allowed uses: transformations that can proceed under standard review.
    • Conditional uses: outputs that require disclosure, specialist review or approval from a more accountable role.
    • Prohibited uses: transformations that cannot be published even when labeled as AI-generated.
    • Evidence requirements: the records that must support factual, comparative, visual and testimonial claims.
    • Disclosure rules: when a disclosure is required, where it must appear and who approves its wording and placement.
    • Responsibility: who creates, verifies, approves, publishes, monitors and withdraws an asset.
    • Exception handling: who can authorize an exception, what evidence is required and when that decision must be revisited.

    Move each asset through the same evidence path

    1. Set the truth boundary in the brief. List the product attributes, claims, qualifications and visual details that cannot change. State what may be synthesized and what the asset must not imply.
    2. Assemble an approved reference pack. Give the creator the current product images, specifications, brand terminology, claim substantiation and required qualifications. Do not make the reviewer reconstruct the ground truth after generation.
    3. Create within the assigned integrity level. Record the tool or production path, the original materials and the meaningful transformations. You do not need to archive every inconsequential interaction, but you do need enough provenance to reproduce the decision and investigate a problem.
    4. Verify the rendered output. Check the actual sizes, crops, overlays, captions, product details and landing-page destination that the audience will see. A correct master file can become misleading when a placement removes a qualification or crops out context.
    5. Approve the claim and the presentation separately. One check asks whether the underlying statement is supported. The other asks what a reasonable person will infer from the combination of words, images and placement. Passing one does not guarantee the other.
    6. Publish with a withdrawal record. Log the channels and destinations where the asset appears. If a claim changes or an error is found, the team should know where to remove or replace every affected version.

    The asset record can be compact. Capture the campaign and channel, source materials, meaningful AI transformations, claims used, disclosure decision, reviewer, approval state and publication locations. What matters is that someone other than the creator can understand why the asset was approved.

    Human review is not a control by itself. The reviewer needs access to the evidence, clear authority to stop publication and enough time to inspect the final placement. A person who can only click approve is part of the production sequence, not an effective safeguard.

    Paid media needs particular care because asset demand, automated combinations and placement variation can multiply one error quickly. Product imagery deserves a hard verification gate: visual inaccuracies can produce disapprovals or account risk in Merchant Center. Compare the rendered product with the approved reference, including packaging, included components, proportions, color and visible features. If the generated scene obscures that comparison, use a more faithful asset.

    Exceptions should be visible and temporary. Record the business reason, risk owner, supporting evidence and condition that ends the exception. The person requesting an exception should not be its sole approver. Otherwise, deadlines will quietly rewrite your policy one campaign at a time.

    Connect creative governance to SEO, AEO, GEO and PR

    Authenticity problems rarely stay inside the ad account. A generated claim can reach a landing page, product feed, public-relations pitch, social caption, FAQ and structured-data field. Each copy may look defensible in isolation while the combined public record becomes contradictory.

    Build a claim register as the shared layer beneath those channels. For each meaningful claim, record:

    • the canonical wording and any required qualification;
    • the internal evidence or approved public page that supports it;
    • the product, market and context in which it applies;
    • the accountable owner;
    • the channels where it may be used;
    • the disclosure or presentation restrictions attached to it;
    • the condition that should trigger review, correction or withdrawal; and
    • the structured-data properties, feed fields and content components that repeat it.

    This register gives your teams one approved truth rather than several channel-specific versions. Copywriters know which qualifications must survive a short format. PPC teams know which visual implications require evidence. SEO and GEO teams know which public pages should explain and substantiate the claim. Schema implementers know which statements are safe to mark up.

    Structured data should describe visible, supported content. It does not validate a claim merely because the markup is syntactically correct. If the page, product feed and JSON-LD disagree about a product attribute, fix the underlying content system instead of choosing the version most likely to attract a machine.

    Citation readiness also belongs in the governance process. Citations in AI-generated answers can contribute to credibility, and understanding how a brand appears through publicly available information can inform PR decisions. That makes the quality of your supporting pages important beyond conventional rankings.

    A citation-ready page should make the supported claim easy to identify, define its scope and keep the qualification beside it. It should also use consistent product and organization names, connect the claim to the relevant entity and avoid implying that a synthetic scene is proof. A citation can carry an unsupported statement farther; it cannot convert that statement into evidence.

    Monitor governance signals that reveal process failure rather than treating campaign performance as proof that the process worked. Useful signals include assets published without complete provenance, unresolved evidence gaps, exceptions still open, corrections caused by product mismatch, platform disapprovals associated with altered creative and the time required to withdraw a faulty claim across channels.

    Audit what is already live

    Start with a representative set of active ads, landing pages, product feeds, social assets, PR materials and structured data. Classify each AI-assisted element on the integrity ladder. Then trace every consequential claim backward to its evidence and forward to every place it appears.

    Prioritize assets with realistic people, demonstrations, testimonials, product alterations or purchase-critical details. If you cannot identify the source fact, the approving person or all publication locations, you have found a governance gap. Pause the highest-risk asset, establish the missing record and use that case to write the first concrete rule in your policy.

    For your next campaign, define the prohibited transformations in the brief, assign the integrity level before production and name the approver before generation begins. Once those decisions become routine, AI can increase creative capacity without multiplying ambiguity about what your audience is being asked to believe.

    References

  • How to Build a Paid Search Optimization System That Learns

    How to Build a Paid Search Optimization System That Learns

    Your paid search account is probably not short of prompts to act. The harder problem is deciding which recommendation deserves budget, whether an automated result represents added business value, and how to preserve what your team learned after the interface changes.

    You need more than a collection of campaign tools. You need an operating system that connects operator skill, controlled execution, and credible measurement. That system lets you move quickly without treating every platform suggestion as an instruction.

    Key takeaways

    • Give every tool one clear job: build capability, execute a change, or verify its effect.
    • Record the hypothesis, baseline, spending limit, success metric, and rollback condition before applying a recommendation.
    • Treat platform-reported incremental lift as decision support. Compare it with the marginal cost and the business value of the added outcomes.
    • Turn Performance Max training into reusable launch and troubleshooting checklists instead of leaving the knowledge inside a course.
    • Manage additional Shopping images as structured feed data and test them against a defined commercial outcome.

    Build your optimization stack around decisions, not features

    A paid search tool earns its place when it helps you make a specific decision. A new dashboard, recommendation, feed field, or course is not automatically useful just because the platform makes it available.

    Separate your stack into capability, execution, and evidence. The separation matters because no single platform surface should be expected to train the operator, make the change, and deliver the final commercial verdict.

    LayerTools and resourcesDecision it should support
    CapabilityApplied Performance Max courses, scenarios, checklists, and reference materialCan the operator configure, review, and troubleshoot the campaign reliably?
    ExecutionCampaign controls, recommendation workflows, and product-feed image fieldsWhat exactly will change in the account, and which campaigns or products will be exposed?
    EvidenceRecommendation impact reporting, change records, and business performance dataDid the change create enough additional value to justify its cost?

    This model exposes gaps that a tool inventory can hide. A credential can support operator development, but it cannot establish campaign profitability. A recommendation can identify an opportunity, but it cannot decide how much financial exposure your business will accept. A results view can estimate added conversions, but it cannot repair an incorrect conversion action or an inflated conversion value.

    For each tool, write down its owner, required inputs, output, and resulting decision. If nobody can name the decision, the tool is adding interface activity rather than optimization capacity. If the same platform proposes a change, applies it, and scores it, add an independent business guardrail such as allowable acquisition cost, margin, qualified-lead rate, or incremental return on ad spend.

    Put every automated recommendation through an evidence gate

    An analyst operates a transparent inspection gate that tests glowing recommendation tiles before a few are allowed to reach a regulated budget reservoir.

    Automated recommendations are hypotheses generated from the platform’s view of the account. They may be useful hypotheses, but accepting one still changes real bids, targets, or budget. A projected improvement is not the same thing as measured incremental value.

    Google Ads is testing a Results area that adds a useful verification layer. For an applied bid or budget recommendation, the system analyzes performance one week later and compares the outcome with a baseline estimate. Its reporting uses a seven-day rolling average measured over the 28 days after the recommendation, organizes results around Budget and Target changes, and focuses on the campaign’s primary bidding objective: clicks, conversions, or conversion value.

    Availability should not be assumed because the Results area is an early pilot. The operating principle still applies in accounts without it: define the expected effect before the change, preserve the starting state, and return after a declared observation window.

    Before you apply a recommendation, add this record to your campaign log:

    • Recommendation: The exact budget, bid, or target change and every campaign it affects.
    • Hypothesis: The outcome expected to increase and the mechanism that should produce it.
    • Baseline: Current spend, the primary bidding objective, and the business metric used to judge quality.
    • Exposure limit: The maximum additional spend or efficiency deterioration you have approved.
    • Observation window: When you will evaluate the change and why that period is suitable for the available reporting.
    • Rollback condition: The result that will cause you to reverse or revise the change.
    • Confounders: Promotions, tracking changes, feed edits, landing-page releases, or other campaign changes that could affect the comparison.

    The exposure limit is not paperwork. Raising a budget can spend more money without producing proportionate business value. Set the limit before approval so a promising platform forecast cannot become open-ended authority to spend.

    When results arrive, separate volume from efficiency. Additional conversions can be valuable even if average campaign efficiency changes, but only when their marginal economics work. Calculate incremental cost per acquisition as additional cost divided by additional conversions. Calculate incremental return on ad spend as additional conversion value divided by additional cost. If clicks are the bidding objective, do not treat extra clicks as revenue; follow them through to the business outcome that justified buying the traffic.

    The baseline in the Results area is an estimate, not direct observation of what the same campaign would have done without the change. Seasonality, promotions, competitor activity, measurement changes, and delayed conversions can still complicate interpretation. Use the reported lift as evidence, then ask whether the direction appears in your business data and whether any concurrent change offers a better explanation.

    Turn Performance Max training into campaign infrastructure

    Performance Max optimization often becomes account folklore: one person knows how the setup was built, another remembers why a target changed, and nobody has a stable troubleshooting sequence. Training is most valuable when it removes that dependence on memory.

    Microsoft Advertising’s applied learning path provides a useful progression: foundations, guided hands-on setup, and advanced scenario-based implementation and optimization. The advanced course includes checklists, videos, reusable reference material, and contextual support through Help me understand during an assessment. Completion can also lead to a shareable Performance Max badge through Credly.

    Use that progression to create internal operating assets:

    • From foundations, create a shared glossary. Define each objective, target, status, input, and output in the language your team uses when approving spend.
    • From setup training, create a launch checklist. Require the campaign objective, conversion action, budget authority, target, product or asset inputs, owner, and first review point to be documented before launch.
    • From advanced scenarios, create a troubleshooting tree. Start with the observed symptom, list the measurement and input checks that could explain it, and identify the smallest reversible action for each branch.
    • From reference material, create account notes. Link each live setting to the reason it was chosen so the next operator does not have to infer strategy from configuration alone.

    Do not measure training only by course completion. Ask the operator to review a live configuration, identify one defensible change, explain the evidence required to keep it, and state the rollback condition. That exercise connects knowledge to account control without pretending that a credential proves commercial performance.

    Reusable artifacts also make optimization safer when ownership changes. The campaign retains its operating history, and a new manager can distinguish a deliberate constraint from an overlooked default.

    Treat multi-image Shopping ads as a feed experiment

    Shopping creative is partly a feed-management problem. If you treat additional images as an informal upload task, you lose control over image purpose, product coverage, and measurement.

    Microsoft Advertising’s multi-image Shopping format uses the optional additional_image_link attribute for as many as 10 comma-separated images. Those images can appear with the product’s price and retailer information, giving shoppers more visual context before the click.

    The existence of 10 available image slots does not mean every product needs 10 images. Each image should resolve a meaningful pre-click uncertainty. An alternate angle can clarify shape. A detail view can reveal construction or a feature. A variation image can help a shopper understand an option that the primary image cannot show clearly. Repetitive images consume feed space without adding equivalent information.

    Use this rollout sequence:

    1. Select a coherent product group. Start with items for which extra views communicate material information, not an arbitrary mix of the catalog.
    2. Assign every image a role. Record whether it shows an alternate angle, close detail, style, color, or another useful distinction.
    3. Validate the feed. Check that image links resolve, remain attached to the correct product, follow the intended order, and agree with the corresponding landing page.
    4. Declare the commercial outcome. Choose the metric that would justify expansion, such as qualified click-through, purchase rate, conversion value, or revenue per click.
    5. Protect the comparison. Avoid changing the same products’ bids, titles, prices, landing pages, and image sets at once. If your account structure permits it, compare a defined rollout group with a similar unchanged group.
    6. Expand only after the whole path improves. A higher click-through rate is not sufficient when the added visits convert poorly or produce weak value.

    This turns a creative feature into a testable merchandising decision. It also gives your feed team a clear rule for future images: add visual information that helps a shopper decide, then keep it only when the downstream result supports the added complexity.

    Use one repeatable loop for every campaign change

    A campaign specialist moves a glowing token around a circular workbench with stations for observation, testing, controlled change, comparison, and archiving.

    Your review process should remain stable even when platforms introduce new controls. A durable optimization loop looks like this:

    1. Start with the business decision. State whether you are trying to acquire more acceptable customers, recover efficiency, improve lead quality, or increase valuable product sales.
    2. Verify the measurement input. Confirm that the campaign’s primary objective represents the outcome you intend to optimize and that the business can interpret it consistently.
    3. Select one intervention class. Choose a budget change, target change, campaign setup correction, or creative-feed change. Separating change types makes the result easier to interpret.
    4. Write the hypothesis and guardrails. Define the expected movement, allowable spending exposure, observation window, and rollback condition.
    5. Apply the change and preserve context. Save the previous setting, implementation date, affected scope, owner, and any concurrent activity. Where Google’s pilot reporting is available, account for its 28-day measurement design rather than forcing an earlier conclusion from incomplete reporting.
    6. Evaluate platform lift and business economics separately. First determine whether the platform’s primary outcome moved. Then determine whether the additional cost produced acceptable downstream value.
    7. Turn the result into a reusable rule. Keep, revise, or reverse the change, and record what future operators should do when the same conditions appear again.

    A compact decision record needs only the campaign, owner, date, starting state, changed setting, hypothesis, spending limit, primary platform objective, business metric, observation window, result, and next action. Keep that record outside any temporary recommendation card so it remains available after the interface or account ownership changes.

    At your next account review, open the decision log before the recommendations queue. Pick one constrained problem, choose the tool that fits its layer, and define the evidence required to close the decision. That is how optimization becomes cumulative learning instead of a sequence of disconnected clicks.

    References

  • How to Govern SEO for Reliable AI Search Visibility

    How to Govern SEO for Reliable AI Search Visibility

    You can perfect a taxonomy, add structured data, repair internal links, and publish stronger answers – then lose the benefit when an unrelated release changes URLs, strips markup, or contradicts your entity facts. If your team discovers those failures after visibility falls, the underlying problem is not another missing SEO tactic. It is the absence of governance.

    AI search raises the cost of that gap. You now have to protect crawlability, retrieval, citations, brand representation, and business outcomes across systems you do not control. The practical answer is a small operating system for visibility: explicit owners, testable standards, release gates, evidence, exceptions, and measurements that separate an AI citation from actual value.

    Define visibility before assigning ownership

    Four visual pathways pass through separate checkpoints and converge on an illuminated destination as people oversee different control stations.

    AI search visibility is not a single ranking. Treat it as a chain with five distinct layers:

    • Eligibility: Can a search or AI system crawl, render, index, and understand the asset?
    • Retrieval: Does the asset contain a clear, relevant answer for the query or task?
    • Selection: Is the page, video, discussion, or profile chosen as grounding material or cited as a source?
    • Representation: Does the generated answer describe your organization, products, people, and claims accurately?
    • Outcome: Does that exposure produce a useful action, such as a qualified visit, lead, sale, subscription, or increase in branded demand?

    A failure at one layer cannot be repaired by celebrating another. A citation can prove selection, but it does not prove that the citation was prominent, that the answer represented you correctly, or that anyone took a valuable next step.

    This distinction matters because Bing Webmaster Tools can expose total citations, average cited pages, grounding queries, page-level citation activity, and visibility trends for Microsoft Copilot and Bing AI experiences. Those signals reveal where your content is being used. They do not currently establish its rank within an answer, the size of its contribution, the clicks it generated, or its business impact.

    Your governed scope should also extend beyond your own domain. AI systems can encounter supporting information on social and professional platforms, but platform behavior is uneven. One observed pattern found ChatGPT referencing Reddit, YouTube, and LinkedIn while apparently bypassing X/Twitter. That is a useful test hypothesis, not a permanent rule. Platform access, product behavior, query type, and source selection can change. Test the surfaces relevant to your audience instead of turning one observation into a universal channel strategy.

    Before building dashboards or committees, write a one-page visibility charter. It should answer five questions:

    <!– wp:list {
  • How to Make AI Agents Useful Marketing Collaborators

    How to Make AI Agents Useful Marketing Collaborators

    You probably don’t need another AI tool that can generate copy on command. You need campaign work to move without facts being invented, approvals being skipped, or teammates spending longer repairing output than creating it.

    The useful promise behind turning workflows into agents is not that software becomes a teammate by declaration. It is that a system can hold a bounded responsibility, use approved context, produce a reviewable change, and return control at the right moment. Getting those boundaries right is what turns an agent from an interesting demo into a dependable part of marketing operations.

    Give the agent a responsibility, not a vague objective

    A geometric AI assistant assembles approved campaign assets inside a partitioned workspace while publishing and approval controls remain outside with a human supervisor.

    An assistant waits for a prompt. A conventional automation follows a predetermined sequence. An agent can work toward an outcome across a bounded series of decisions and actions. Real tools often blend all three modes, so the label matters less than the responsibility you assign.

    “Help with content marketing” is not a responsibility. It leaves the system to guess which pages matter, which evidence is acceptable, what it may change, and when a person should intervene. Those guesses create the same coordination problems you were trying to remove.

    Write the assignment in this form:

    When this trigger occurs, prepare this outcome from these approved inputs, stop before this decision, and hand the work to this owner.

    Marketing agent role template

    A content-refresh agent, for example, could be responsible for preparing an evidence-backed change set when a page enters an editorial review queue. It may inspect approved performance data, compare the page with the current content brief, identify unsupported or outdated passages, draft revisions, and suggest structured-data changes. It may not publish, alter the canonical URL, introduce a new product claim, or remove the existing page. The content owner makes those decisions.

    That boundary gives the agent meaningful work without pretending that every judgement can be delegated. Define the role with the following fields:

    • Trigger: the event that starts the work, such as a scheduled review, an approved campaign brief, or a flagged content issue.
    • Outcome: the artifact or state the agent is expected to produce. Name the deliverable rather than saying “improve” or “optimize.”
    • Inputs: the repositories, reports, templates, and records it may use.
    • Permissions: what it may read, draft, edit, submit, publish, or send.
    • Stop conditions: conflicts, missing evidence, unusual risk, or decisions that must be escalated.
    • Owner: the person accountable for accepting the result and deciding what happens next.

    If you cannot complete those fields, the workflow is not ready for an agent. The problem is usually unclear ownership or an undocumented decision rule. Fixing that ambiguity will help the human team even if you postpone the automation.

    Design the handoffs before granting action permissions

    Campaign assets move from human-supplied sources through AI drafting and human review to a locked final action gate, with channels returning corrections to the draft stage.

    Marketing collaboration breaks at handoffs. A draft exists, but nobody knows whether it is ready for legal review. A campaign recommendation is accepted in chat, but the media plan still contains the old decision. A schema change reaches production, but the content team never sees the new claims encoded in it.

    An agent can make those failures happen faster unless every handoff has a visible state. Use a simple operating sequence for each assignment:

    <!– wp:list {