Category: Workflows

  • How to Build a Self-Improving AI Content Workflow

    How to Build a Self-Improving AI Content Workflow

    You keep correcting the same AI output: a vague heading, an unsupported claim, a generic opening, a conclusion that says nothing. The draft improves after you edit it, but the workflow that produced it stays exactly the same.

    A self-improving content workflow preserves those corrections, finds recurring patterns, and changes the next run under controlled conditions. The goal is not an agent that rewrites its own rules without supervision. It is a system that turns editorial judgment into reviewable improvements to briefs, evidence retrieval, writing instructions, quality gates, and routing.

    A workflow improves only when feedback changes the next run

    Generating a draft, editing it, and publishing it is a production process. It becomes a feedback loop only when the correction affects a reusable part of the process. Unless you persist that correction somewhere, a new model run has no reason to avoid the same failure.

    The reusable change does not have to be a prompt edit. Feedback can change the criteria used to approve an angle, the queries used to retrieve evidence, the material included in a writing packet, the rubric applied by an editorial agent, or the route taken when a check fails. This distinction matters because many apparent writing problems originate before the writer receives the task.

    Every useful loop needs the same basic components:

    • An observable failure, recorded in specific terms.
    • A classification that identifies where the failure entered the workflow.
    • A proposed change to a reusable instruction, criterion, example, query, or routing rule.
    • An evaluation that checks whether the change fixes the target problem without damaging other requirements.
    • A human-controlled decision to approve, reject, revise, or roll back the change.

    That last component is what makes the system governable. Production agents can record feedback and propose patches, but they should not silently promote every correction into permanent operating memory. A rushed edit, an individual preference, or an unusual brief can otherwise become a global rule.

    Key takeaways

    • Begin with a quality gate around existing drafts; it creates useful feedback without requiring you to rebuild the whole pipeline.
    • Cap revision at two rounds. A draft that still fails usually needs better evidence, a narrower claim, or a stronger angle.
    • Separate editorial review from citation checking so each agent has a clear job and an appropriate context packet.
    • Stop weak angles and evidence gaps before writing. Upstream failures become more expensive after a full draft exists.
    • Use recurring edits as evidence for an instruction change, but require a proposal, evaluation, version record, and human approval.

    Start with a quality gate and a firm revision cap
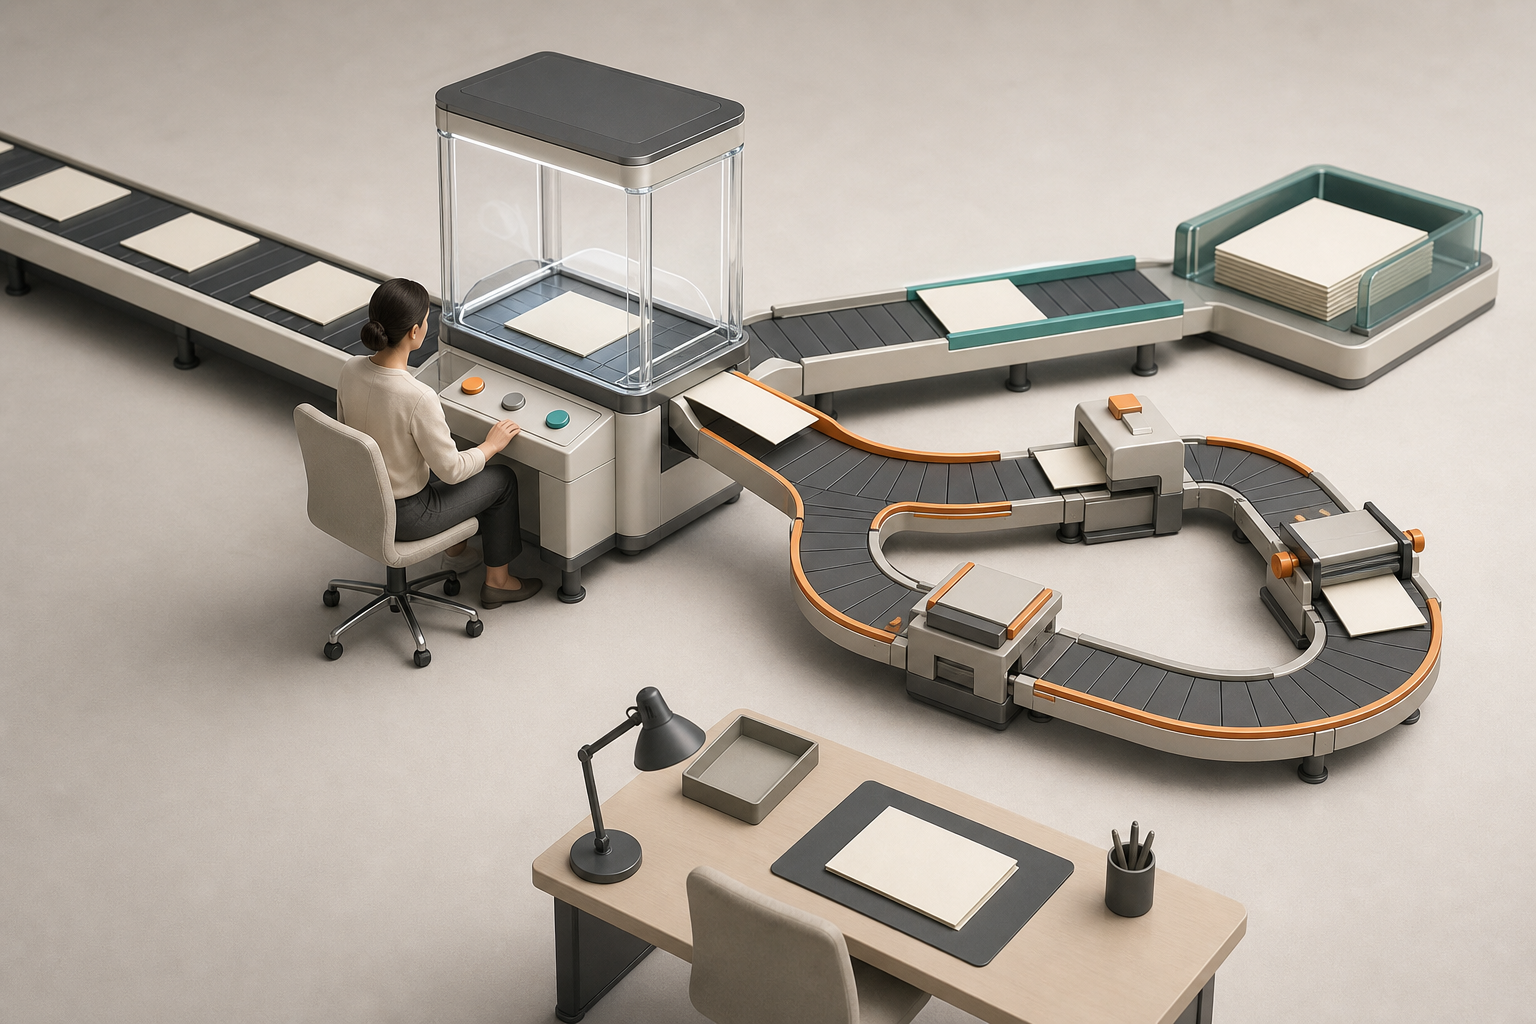
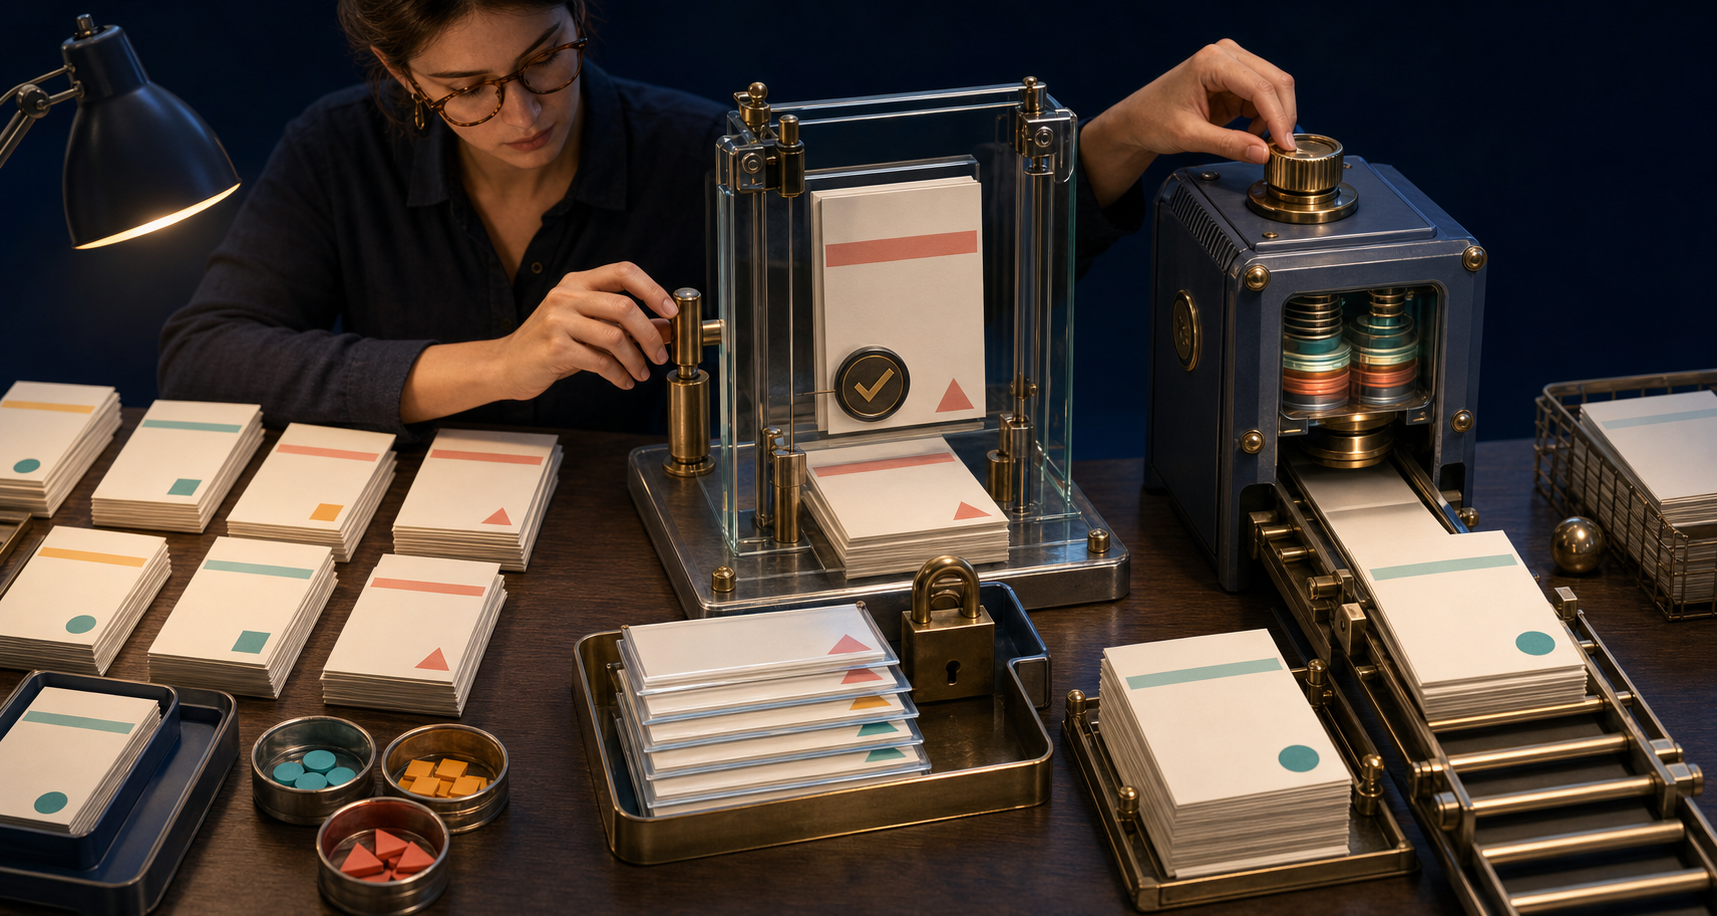
    Blank manuscript sheets move through a quality gate, with one approved, one sent through a limited revision loop, and one routed to a human editor.

    The smallest practical self-improving workflow places an independent reviewer after the writer. The reviewer does more than declare that a draft feels weak. It evaluates explicit acceptance criteria, identifies the class of failure, and returns a bounded revision request.

    Build that loop in this order:

    1. Write an acceptance contract for the content type. Define the intended reader, the decision or task the content must support, the required evidence standard, the voice constraints, and the structural requirements.
    2. Give the writer a bounded packet containing the approved brief, outline, evidence, brand instructions, and output format. Do not make the writer infer which requirements matter most from a large repository of loosely related material.
    3. Send the resulting draft to an editorial reviewer in a separate context window. The reviewer should receive the acceptance contract and the draft, not the writer’s internal deliberation.
    4. Send factual claims and cited evidence to a dedicated fact-checker. Its job is to verify that the evidence supports the wording in the draft, not merely that a cited link exists.
    5. Classify the result as pass, flag, or escalate. Attach a precise diagnosis to every flag.
    6. Return fixable defects to the writer. The revision request should name the affected passage, failed criterion, reason for failure, and required result.
    7. Stop after two revision rounds. Route the draft and its review history to a person who can change the angle, evidence plan, or brief.

    The three verdicts need operational definitions. Pass means the draft meets the acceptance contract and its factual claims survive checking. Flag means the defect can be corrected within the existing brief and evidence set. An undefined term, an indirect opening, or a poorly ordered section can usually be flagged. Escalate means rewriting alone cannot solve the problem. Missing evidence, an unworkable thesis, contradictory requirements, and an angle with no defensible point of view belong here.

    The revision cap prevents an agent pair from polishing around a structural defect. If specificity remains weak after two rewrites, the evidence packet may not contain the concrete material the writer needs. Another instruction to be more specific will not create that material. The correct route is back to research or strategy.

    Keep editorial review and fact-checking separate even if both happen after drafting. An editorial reviewer asks whether the structure serves the argument, the language fits the audience, and the answer is useful. A fact-checker compares each factual statement with the evidence attached to it. Combining those responsibilities makes it easier for fluent prose to distract from weak support, or for citation work to crowd out substantive editing.

    Add a direct entry point to the gate as well. A draft written by a colleague, contractor, or older system should be reviewable without rerunning ideation, retrieval, and drafting. This makes the gate useful across the content operation and gives you a more representative record of recurring failures.

    Catch weak angles and evidence gaps before drafting

    A downstream reviewer can detect an unsupported claim, but it cannot manufacture the missing proof. It can identify a generic thesis, but by then you have already paid for research, drafting, and review. Two upstream checks prevent those failures from entering the expensive part of the workflow.

    Filter the brief with pass, revise, and kill decisions

    Evaluate each proposed angle against criteria you define before generation. Useful criteria include audience fit, thesis strength, original point of view, distance from existing coverage, and whether the necessary proof appears obtainable. The evaluator must choose an action, not simply assign a vague confidence score.

    VerdictMeaningNext action
    PassThe angle has a defensible thesis, fits the intended audience, and can be supported.Release the brief to evidence retrieval and outlining.
    ReviseThe idea is viable, but its scope, audience, differentiation, or evidence requirement is wrong.Return a specific change request, then evaluate the revised brief again.
    KillThe angle lacks a meaningful point of view or depends on proof that is not available.Stop the run and record the reason. Do not ask the writer to rescue it with phrasing.

    The kill log is not a graveyard for ideas. It is training data for strategy rules. Record the intended audience, thesis, decision, reason code, missing requirement, evaluator, and rule version. You can then see whether the same pattern keeps failing: duplicate angles, claims that require unavailable data, topics aimed at the wrong buyer stage, or briefs too broad to support a useful answer.

    Keep revise and kill distinct. Revise means a known change can make the brief viable. Kill means the core proposition does not survive the criteria. If evaluators use kill merely to avoid difficult research, tighten the definition. If they send fundamentally empty ideas through repeated revisions, tighten it in the other direction.

    Map planned claims to evidence section by section

    Once the angle passes, place a checkpoint between retrieval and writing. For every planned section, record the claim it needs to establish, the evidence intended to support it, and the gap that would remain if the writer used only that material.

    A practical evidence map contains:

    • The section heading and its purpose in the argument.
    • The exact factual or analytical claim the section must support.
    • The relevant evidence URL or document identifier.
    • A support score on a 1-10 scale, using a definition that stays consistent across runs.
    • The unsupported part of the planned claim.
    • A follow-up query, narrower claim, or deletion recommendation.

    Choose the passing threshold before evaluating the packet. When a section falls below it, the mapping agent should not hand the gap to the writer. It should produce the follow-up query itself, narrow the planned statement to match the available evidence, recommend removing the section, or escalate the gap to a person.

    This checkpoint is especially useful for SEO, AEO, and GEO content. A fluent answer can still be unusable if its strongest sentence outruns its citation. Mapping claims before drafting gives the writer permission to be specific where the evidence is strong and forces a deliberate decision where it is not. It also gives the fact-checker a clean chain from planned claim to evidence to published wording.

    Turn repeated edits into controlled instruction updates
    An editor groups recurring changes from blank drafts, approves one pattern, and adjusts an instruction module for the next content cycle.

    Do not update a shared prompt every time someone changes a sentence. Many edits are local: a legal qualification for a particular market, a preference from one stakeholder, or an exception created by an unusual format. Promoting them immediately makes the workflow unstable.

    A useful operating rule is to wait until the same edit pattern appears across three separate content assets. That is not a universal law or proof that the proposed fix is correct. It is a practical trigger for asking whether a reusable instruction has failed. The system should propose a change at that point, not apply one automatically.

    Capture each meaningful edit as a structured event:

    • Asset type and workflow version.
    • Original passage and approved revision.
    • Defect category, such as weak specificity, unsupported claim, indirect answer, voice mismatch, repetition, or poor section order.
    • The workflow stage most likely to own the defect.
    • The requirement that the original output failed.
    • Whether the edit is local to the asset, specific to a channel, or potentially global.
    • The reviewer who approved the final correction.

    Classification is more important than raw edit distance. Replacing an entire paragraph may reflect a minor tone preference, while changing a short factual qualifier may correct a serious accuracy problem. The system needs to know why the edit happened before it can recommend where to intervene.

    Route the proposed fix to the earliest stage that can prevent recurrence. A repeated unsupported claim belongs in evidence mapping or fact-checking. A repeated mismatch between topic and audience belongs in the brief filter. A buried direct answer belongs in the outline or structural rubric. Only a failure that genuinely originates in drafting belongs in the writer instructions.

    Make every instruction proposal reviewable. It should contain the observed pattern, the affected assets, the proposed wording, the expected change, the evaluation criterion, the scope of application, and the current instruction version. Replace abstract directives such as improve clarity with testable behavior. For example: define a technical term when it first appears, then state the implementation consequence in the same section. A reviewer can inspect that requirement in an output; improve clarity cannot be evaluated consistently.

    Evaluate the patch on representative briefs before promoting it. Check the target defect and the rest of the acceptance contract. An instruction that produces sharper openings but removes necessary qualifications is not an improvement. Preserve the earlier version so you can roll back the change if a wider set of runs reveals a regression.

    Scope memory by format. The correction that improves a landing page may make a technical explainer too abrupt. A rule for a LinkedIn post may be inappropriate for a video script. Maintain shared brand requirements where they are genuinely universal, then place format-specific instructions closer to the relevant writer and reviewer.

    Use rubric scores to diagnose the system, not flatter it

    A pass-or-fail gate tells you whether content can move forward. A rubric tells you which capability is holding it back. Score each criterion separately and require a concrete diagnosis whenever a score falls below its threshold. A total score alone is dangerous because strong voice and clean structure can conceal weak evidence.

    Rubric dimensionQuestion to evaluateLikely route when it fails
    Audience and intent fitDoes the content resolve the decision or task named in the brief?Brief filter
    Original point of viewDoes the thesis make a defensible contribution rather than restating the topic?Angle evaluation
    SpecificityDo important recommendations include the mechanism and an actionable consequence?Evidence mapping or writer
    Claim supportDoes the evidence establish the claim at the strength used in the draft?Retrieval checkpoint
    Citation fidelityDoes each cited item support the exact sentence attached to it?Fact-checker
    StructureDoes each section advance the argument or help the reader complete the task?Outline or editorial reviewer
    VoiceDoes the wording follow the applicable brand and format rules?Writer instructions
    Answer usabilityAre core answers direct, self-contained, and explicit about the entities and conditions involved?Outline or writer

    A diagnosis must describe the gap, not merely repeat the criterion. Specificity is low is not useful feedback. The recommendation names actions but omits the condition that determines which action applies is useful. It tells the writer what to repair and gives the reviewer something concrete to check on the next pass.

    You can also apply the same rubric to competing briefs, outlines, or openings. Compare candidates criterion by criterion, preserve any hard acceptance requirements, and select the option that best serves the task. Do not let a high average compensate for a fatal weakness such as an unsupported central claim.

    Track workflow health alongside content scores. Useful operating measures include first-pass acceptance, flags by defect category, revision rounds per asset, escalation reasons, evidence gaps caught before drafting, instruction patches proposed and approved, and patches later rolled back. These measures show whether the system is preventing defects or merely moving them between agents.

    Post-publication outcomes can trigger investigation, but they should not rewrite instructions by themselves. Search visibility, AI citations, engagement, and conversion depend on more than wording. Associate each asset with its intended outcome, review performance within a predefined measurement window, and compare the result with the editorial record. Then decide whether the signal points to content quality, distribution, technical implementation, audience fit, or a changed search environment.

    Implement the system in layers. Put the capped reviewer and fact-checker around the draft currently waiting for approval. Log every verdict and escalation. When those logs expose upstream failures, add the angle and evidence checkpoints. When recurring edits become visible across separate assets, enable instruction proposals with approval and rollback. Your workflow will then improve from evidence of its own failures without giving up editorial control.
    References

  • Digital Asset Management Activation: From Library to Delivery

    Digital Asset Management Activation: From Library to Delivery

    Your DAM can be impeccably organized and still leave you with late campaigns. If engineers resize hero images, regional marketers re-upload files into local systems, or teams keep asking which logo is current, the library is working but the delivery chain around it is not.

    Digital asset management activation closes the distance between an approved asset and its correct appearance on a page, product listing, email, social post, or partner platform. You do that by replacing manual handoffs with governed references, on-demand variants, direct integrations, and machine-readable rules that apply equally to people, applications, and AI agents.

    Find the activation gap before you add another tool

    A traditional DAM answers library questions: Where is the asset? Which version is approved? Who can use it? When does it expire? Activation answers a different set of questions: How does the approved asset reach its destination? Who changes it along the way? Does the destination receive the right size, crop, format, locale, and version? What happens when the approved original changes?

    The activation gap is the work between approval in the DAM and verified delivery in the customer-facing channel. It includes every download, chat request, spreadsheet lookup, resize, local upload, approval check, and duplicate copy in that path. Those steps may look harmless individually. Together, they create delay and make it difficult to prove what actually went live.

    Content demand makes that gap harder to ignore. In a 2025 Adobe survey of more than 1,600 marketers, 62% said demand had increased fivefold or more over the preceding two years. That survey result is directional, not a performance benchmark for your organization. Establish your own baseline from actual launches.

    Start by tracing one recently published asset from approval to delivery. Choose a normal launch with real exceptions, not the cleanest workflow your team can demonstrate.

    1. Record the asset identifier, approval state, approved revision, owner, market, usage constraints, and approval time.
    2. List every person and system that touched the asset after approval.
    3. Mark each point where the file was downloaded, copied, renamed, resized, reformatted, edited, or uploaded again.
    4. Record where a person had to interpret an ambiguous field, confirm permission in chat, or decide which version was current.
    5. Stop only when the asset has rendered correctly in the live destination and someone has verified it.

    Measure the workflow with operational signals you can reproduce:

    • Elapsed time from DAM approval to verified publication.
    • Number of manual handoffs and download-upload cycles.
    • Number of derived files stored as separate assets.
    • Requests sent to design or engineering for routine channel variants.
    • Incidents involving the wrong revision, market, rights state, or expiration status.
    • Share of live placements that retain a traceable DAM identifier or governed delivery URL.
    • Time required to replace or withdraw an asset across every destination.

    You now have an activation backlog. Prioritize the handoff that appears most often or creates the most consequential errors. A portal redesign will not remove a download-upload loop. A new taxonomy will not remove an engineering resize request. Match the fix to the failure you observed.

    Give every asset a machine-readable activation contract

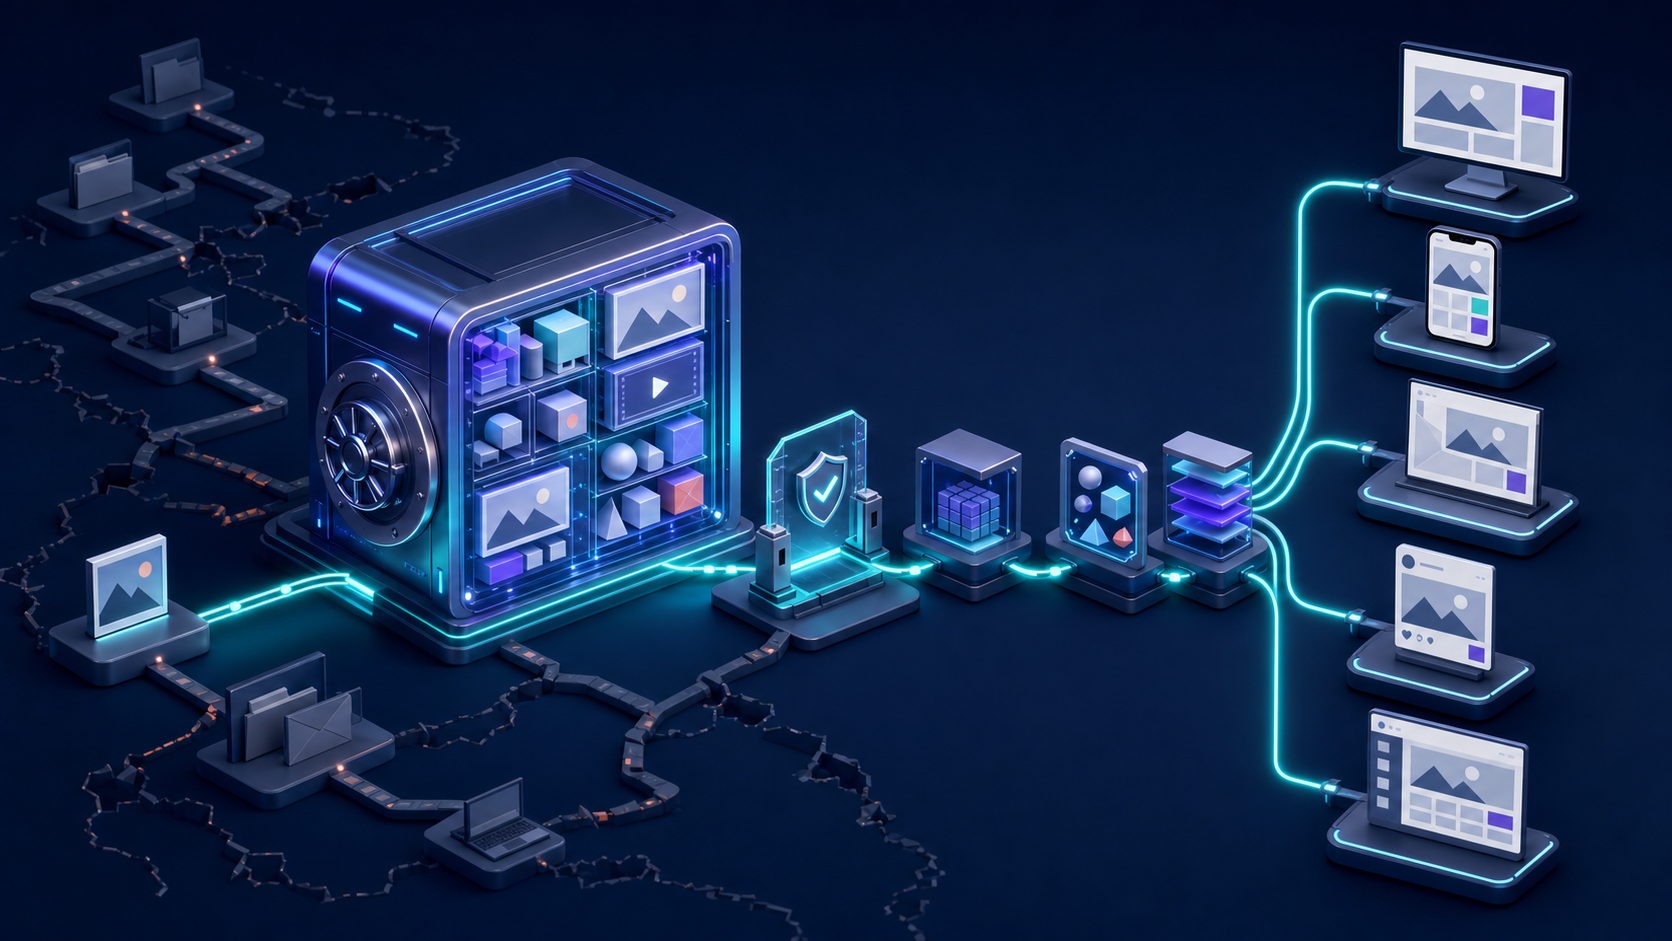
    A protected digital asset is surrounded by structured rule tokens linked to a validation gate and several publishing destinations.

    Direct integrations move assets faster, but they also move ambiguity faster. Before a CMS, commerce platform, automation, or AI agent can select an asset safely, it needs an explicit contract describing what the asset is, where it may be used, and which transformations are permitted.

    Define that contract for each asset class. A useful minimum includes:

    • Identity: a persistent asset ID, asset class, owner, and relationship to the relevant product, campaign, page, or brand entity.
    • Lifecycle state: clear values such as draft, under review, approved, published, withdrawn, and expired. Do not rely on a folder name to imply approval.
    • Revision: an explicit approved revision and a record of what it replaced.
    • Usage context: permitted brands, markets, locales, channels, campaigns, and destinations.
    • Rights and timing: usage constraints, start and end dates where applicable, and the party responsible for renewal or withdrawal.
    • Descriptive metadata: controlled terms and destination-ready descriptions that downstream systems can map to visible and machine-readable fields.
    • Delivery policy: approved crops, aspect ratios, output dimensions, format rules, quality rules, and whether generative editing is allowed.
    • Replacement behavior: whether consumers should always receive the current approved asset or remain pinned to a specific revision.

    Required fields should be enforced when the asset changes state, not discovered by the publishing system later. An upload may remain a draft with incomplete metadata. Approval should fail if a field needed for safe activation is missing. Downstream systems should retrieve only records that satisfy their eligibility rules.

    For SEO, AEO, and GEO teams, activation is an operational control rather than a ranking shortcut. It helps the CMS, page templates, feeds, and structured outputs receive the same stable asset reference and descriptive information. If your CMS emits structured data, map media fields from the governed asset record instead of maintaining a second, disconnected set of values in a plugin or spreadsheet.

    Choose deliberately between current and fixed references

    One URL that always resolves to the latest approved asset is useful when every placement should update together. A brand logo, evergreen product image, or corrected illustration may fit that pattern. The reference remains stable while the approved file behind it changes.

    Other placements need an immutable, revision-specific reference. Campaign records, archived pages, contractual partner deliveries, and creative with time-limited rights may need to preserve exactly what was published. Silently replacing those files can create compliance, reporting, or evidentiary problems.

    Support both behaviors. Use a current alias when automatic propagation is intentional and a fixed revision when reproducibility matters. Document the choice in the activation contract rather than leaving each destination to guess.

    Generate channel variants from a governed original

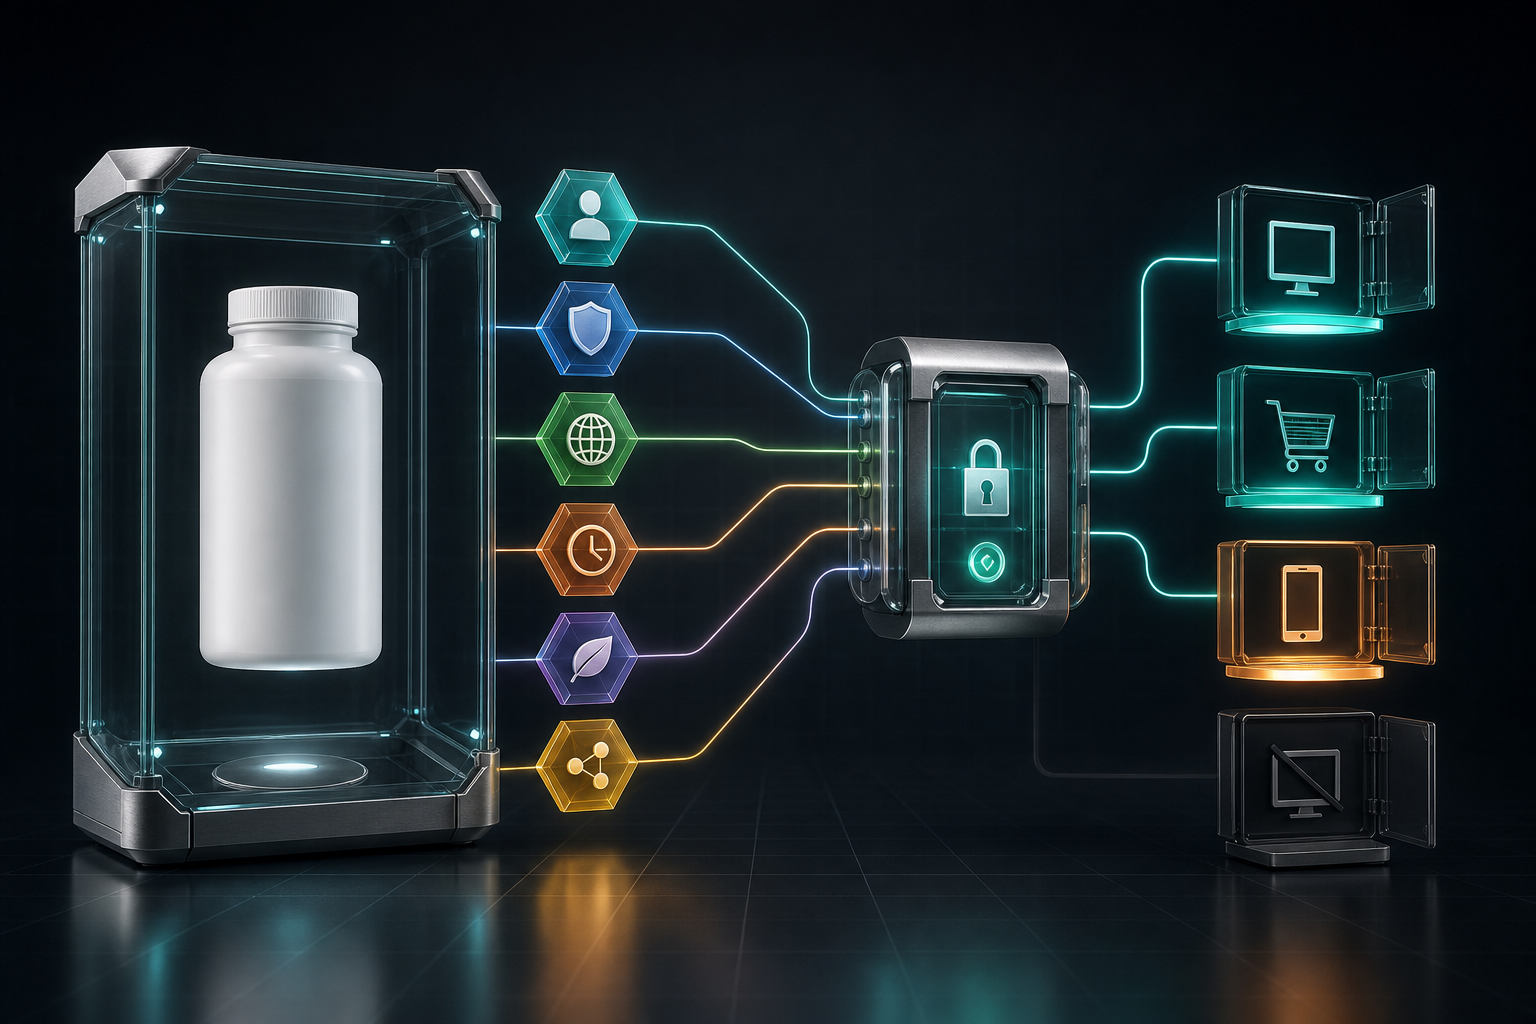
    One approved bottle image branches into wide, square, vertical, and thumbnail variants while remaining connected to the master asset.

    Routine resizing should not create a new branch of your asset library. A 2023 Santa Cruz Software survey found that 76% of designers spent at least 20 hours per week resizing graphics. Do not treat that vendor-cited survey as a universal staffing benchmark. Check your own request queue and file history to see how much specialist time is being consumed by predictable derivatives.

    The better operating model keeps one governed original and creates delivery variants when a channel requests them. A 6MB, 4000 by 3000 original can supply a 1920 by 1080 hero, a 400 by 400 thumbnail, a 1200 by 630 social preview, and a 750 by 1000 mobile treatment without storing four manually exported copies.

    Build this around named transformation recipes rather than unrestricted editing parameters:

    1. Preserve the original as the governed master. Do not let a destination overwrite it.
    2. Define recipes by business purpose, such as product thumbnail, desktop hero, mobile hero, social preview, and partner feed image.
    3. Specify dimensions, aspect ratio, crop behavior, focal-point handling, format, and quality in each recipe.
    4. Let the CMS or delivery layer request the asset ID plus the recipe instead of uploading a separate file.
    5. Log the master revision and transformation recipe used for each generated result.
    6. Test what happens when the master changes, including cache refresh, rollback, and destinations pinned to an older revision.

    Separate deterministic processing from creative generation. Resizing, format conversion, and approved crop rules can usually run as repeatable delivery operations. Background replacement, generative fill, and prompt-based edits change the creative meaning of the asset. Treat those outputs as governed derivatives that need an identity, lineage, rights review, and approval state of their own.

    This distinction prevents a serious automation mistake: allowing a runtime request to create brand-new creative without review. AI can produce the variation, but it should not silently grant that variation permission to publish.

    Connect publishing tools without weakening governance

    A DAM portal is still useful for browsing, curation, review, and administration. It should not be the only route by which content enters or leaves the library. Requiring every user to find, download, transform, and re-upload an asset turns the portal into a manual transport layer.

    Design the activation path so each system performs one clear job:

    • Creative tools submit originals and required metadata to the DAM.
    • The DAM controls identity, lifecycle state, rights, approval, and lineage.
    • The CMS, commerce platform, email system, or partner application stores a governed reference rather than an unmanaged copy whenever its architecture allows.
    • The delivery layer returns the approved revision in the requested transformation recipe.
    • Monitoring records which asset, revision, recipe, and destination were involved.

    Use a native integration when it removes a frequent context switch inside a tool where work already happens. Use a headless API when another application needs dependable read or write access. In both cases, define the allowed operations, required metadata, error behavior, authentication, and audit trail before connecting production systems.

    Model Context Protocol, or MCP, adds another interface for AI-assisted workflows. An MCP server can expose DAM capabilities to compliant AI tools, allowing an assistant or automation agent to search for approved assets and request a valid rendition without navigating the portal.

    MCP changes the interface; it does not replace governance. Expose narrow, task-specific capabilities such as searching approved assets, reading metadata, retrieving a fixed revision, or requesting an allowed variant. Do not give a general-purpose agent arbitrary update, approval, publication, or deletion rights merely because the connection supports them.

    Apply eligibility filters before semantic relevance

    Keyword-only search becomes unreliable when teams use inconsistent labels. Natural-language search can match meaning, visual search can find similar imagery, and video discovery can index visible content and spoken dialogue rather than relying only on titles. Those capabilities improve recall, but relevance alone is not enough for activation.

    Filter the candidate set by hard business rules first: approved state, permitted destination, market, locale, rights window, brand, and required asset class. Rank the eligible results by semantic or visual similarity only after those conditions pass. A visually perfect result is still wrong if it is expired, unapproved, or licensed for another market.

    Return enough context for the caller to make a safe choice. A search result should include its asset ID, revision, lifecycle state, intended use, market or locale constraints, rights status, and available recipes. An agent should also record which result it selected and which conditions were evaluated.

    AI can help maintain the library by checking uploads, proposing controlled vocabulary, identifying missing metadata, and holding noncompliant files in draft. Introduce that autonomy in stages. Start with suggestions and validation. Move to automatic blocking only when the rules are deterministic and the team can inspect false positives. Keep publication behind an explicit approval state.

    Prove activation with one bounded publishing workflow

    A large DAM transformation can disappear into platform work. A bounded pilot makes the result visible. Choose one asset class, one destination, and one repeated source of friction. Good candidates include product images sent to an ecommerce CMS, campaign heroes sent to a web CMS, or approved social previews recreated for every launch.

    1. Define the boundary. Name the point at which an asset becomes approved and the point at which delivery is verified. Exclude adjacent workflow problems unless they prevent the pilot from operating.
    2. Capture the baseline. Measure elapsed time, manual touches, duplicate files, routine resize requests, errors, and replacement time for recent examples.
    3. Specify the activation contract. Make required identity, state, rights, locale, destination, revision, and delivery fields explicit.
    4. Create the smallest useful recipe set. Include only variants the selected destination actually consumes.
    5. Connect the destination. Make it retrieve an approved reference and recipe directly. Preserve a controlled fallback while you validate the new path.
    6. Add hard publication checks. Reject drafts, expired assets, disallowed markets, missing required metadata, and unsupported recipes before delivery.
    7. Test change behavior. Replace an approved asset in a non-production environment, verify cache behavior, confirm fixed revisions remain fixed, and exercise rollback.
    8. Compare the result with the baseline. Look for removed handoffs and errors, not merely a successful API response.

    The pilot is ready to expand when the workflow meets concrete acceptance conditions:

    • A user can publish the approved asset without downloading and re-uploading it.
    • The destination retains a traceable asset ID or governed URL.
    • Routine variants come from approved recipes rather than local exports.
    • Draft, withdrawn, expired, or otherwise ineligible assets cannot pass the delivery gate.
    • The team has tested both current and fixed-reference behavior.
    • Logs identify the master revision and transformation applied to a live result.
    • An owner can withdraw, replace, or roll back the asset without searching multiple unmanaged libraries.

    Assign ownership along the same boundary. Creative owns the approved master and intentional composition. DAM operations owns metadata rules and lifecycle governance. Channel teams own destination requirements. Engineering owns interfaces, authentication, delivery reliability, caching, and observability. Brand, legal, or rights owners define the restrictions that publication checks must enforce.

    Key takeaways

    • DAM activation is the governed path from an approved original to a verified channel result.
    • Measure manual handoffs, duplicate files, routine variant requests, errors, and replacement time before changing the architecture.
    • Give every asset a machine-readable contract covering identity, status, revision, rights, context, and transformation policy.
    • Generate predictable channel variants from the governed original instead of storing repeated exports.
    • Use APIs, native integrations, and MCP as controlled interfaces; none of them substitutes for permissions, approval, or auditability.
    • Apply approval, rights, market, and lifecycle filters before semantic or visual ranking.
    • Prove the model with one asset class and one destination, then expand using measured results.

    Choose one asset from a recent launch this week and draw its path from approval to live delivery. Circle every download, copy, resize, permission check, and upload. The first activation project is the smallest connection that removes the most repeated circle while preserving a clear record of what was allowed to publish.

    References

  • How to Build an AI Brand Claim Correction Workflow

    How to Build an AI Brand Claim Correction Workflow

    An AI answer says your product lacks a feature it has, assigns your company to the wrong owner, or repeats a policy you retired. The tempting response is to regenerate the answer until it looks right. That may produce a better output, but it does not tell you whether the underlying claim has been corrected.

    You need a workflow that turns a bad answer into a documented case: capture the claim, decide whether it is truly inaccurate, identify the evidence influencing it, correct that evidence where possible, and verify the result without treating one favorable retest as proof.

    Capture the claim before anyone starts correcting it

    An AI error is not actionable when the entire report is, AI got our brand wrong. Your unit of work should be one exact claim in one observable response. If an answer contains three inaccuracies, open three claim records. They may have different evidence, owners, risks, and correction paths.

    Create the record before editing a page, contacting a publisher, or changing structured data. Otherwise, you lose the baseline needed to determine what changed.

    1. Save the inaccurate sentence verbatim and preserve the surrounding answer. A cropped sentence can hide a qualification that changes its meaning.
    2. Record the exact prompt, AI product or search surface, visible model name if one is provided, response mode, language, location, and any account or personalization setting that could affect the result.
    3. Add the capture date, a screenshot, and the full response in a durable format. Redact personal or confidential information before sharing the case outside authorized systems.
    4. Save every citation, linked page, domain, and quoted passage returned with the answer. Note explicitly when no citation is shown.
    5. Write the correct replacement claim in one sentence. Avoid promotional wording; state the narrow fact you can prove.
    6. Attach the evidence supporting that replacement, including the authoritative URL, page section, document owner, and effective date where one exists.

    Then run a small, fixed baseline set. Include the original prompt, a natural paraphrase, and the adjacent question a prospective customer is likely to ask. If the problem appeared in a comparison query, include both the comparative and standalone brand forms. Log each response separately.

    Do not combine different AI products, model modes, languages, or countries into one result. A claim that appears on one surface and not another is still worth recording, but it is not evidence that every system holds the same representation. Likewise, a single occurrence establishes that the error happened; it does not establish how prevalent it is.

    Classify the failure while the evidence is fresh. Useful labels include fabricated, outdated, misattributed, context omitted, source contradicted, and technically true but materially misleading. These labels make the next decision easier because an outdated policy needs a different remedy from a claim invented without a visible citation.

    Triage inaccurate claims by harm, evidence, and correctability

    Overhead view of hands sorting abstract claims and evidence into three priority trays.

    Not every unfavorable statement is inaccurate, and not every inaccuracy deserves an urgent campaign. Validate the claim before you send a correction request. If your own product pages disagree, the immediate problem is not the AI system; it is the absence of a stable, supportable brand fact.

    Ask four questions in order:

    • Can you prove the claim is wrong? Identify the specific factual conflict and the dated evidence that resolves it.
    • What decision could it affect? Consider purchasing, renewal, hiring, partnership, compliance, safety, and reputation rather than relying on how embarrassing the answer feels.
    • How broadly does it recur? Use the fixed prompt set instead of repeatedly improvising prompts until you find either the answer you want or the answer you fear.
    • Is there a correctable evidence path? A cited publisher page, outdated first-party page, incorrect profile, or contradictory product document gives you a concrete target. An uncited answer requires investigation before outreach.

    Use three practical queues. Put objectively false claims with serious commercial, safety, regulatory, or reputational consequences in the urgent queue. Put material but lower-consequence errors with identifiable evidence in the planned queue. Monitor isolated, low-impact, ambiguous, or genuinely subjective statements until you have enough evidence to act.

    Do not submit a factual correction simply because an answer is negative. A documented limitation, a supported criticism, or an opinion cannot be repaired by replacing it with brand copy. Correct the underlying fact, supply missing context, or respond through the appropriate communications process.

    Claims alleging fraud, criminal conduct, regulatory violations, dangerous behavior, or other matters with legal consequences need special handling. Preserve the complete evidence, restrict internal circulation where appropriate, and have qualified counsel approve any external demand. A hurried accusation or an attempt to remove relevant records can create a larger problem than the AI answer itself.

    Choose the evidence layer that can actually be corrected

    An AI response is an output, not a single brand profile you can open and edit. Your correction target is usually an evidence layer that the system found, cited, retrieved, or learned from. Begin with the citations in the response, then work outward to exact wording searches, first-party content, structured data, public profiles, and other pages that repeat the same claim.

    Observed patternLikely correction targetFirst action
    The answer cites an inaccurate third-party pageThe cited publisher or data ownerPrepare a narrowly scoped correction request with the exact passage, replacement wording, and proof
    The answer cites an outdated page you controlYour canonical product, policy, company, or documentation pageCorrect the visible content and reconcile every owned page that contradicts it
    Several sources publish conflicting versionsThe broader evidence setEstablish one canonical fact, update owned properties, and approach the most consequential external sources separately
    No citation is visibleStill unknownSearch for the exact phrasing and distinctive fragments, inspect owned content, and collect more logged responses before assigning a target
    The statement is technically true but missing a decisive qualificationContent clarity and contextPublish the qualification beside the claim rather than relying on a distant disclaimer

    First-party consistency matters because machines and people should not have to decide which of your pages is current. Pick one canonical location for each important brand fact. State the fact plainly, name its scope, add an effective or updated date when timing matters, and link supporting documents from that location. Remove or revise contradictory wording across product pages, help content, press materials, policy pages, downloadable files, and public profiles you control.

    Use JSON-LD to express facts that are already visible and supportable, not to create an alternate machine-only version of the brand. Organization, Product, and Offer markup can clarify entities and properties, but markup is not proof by itself and cannot repair an inaccurate publisher page. Keep structured data aligned with the visible page and your canonical record. If the prose says one thing and the schema says another, you have introduced another conflict.

    Third-party errors require a source-level correction. Identify who can change the exact record: an editor, database operator, directory owner, review platform, syndication partner, or other publisher. Do not send a general reputation complaint when you can point to a sentence, explain the factual defect, and provide a supported replacement.

    A vendor-announced integration connects inaccurate-claim flags from FactCheck with Noble’s Mention Refresh for source-correction work. The useful pattern is the handoff: detection should create an evidence-backed correction task, not end at a dashboard alert. That integration is not evidence that every publisher will accept a request or that every AI output will change afterward.

    Run the correction as a controlled handoff

    Illustration of a claim capsule passing between controlled correction stations before being tested across multiple AI answer samples.

    The handoff is where most correction programs become vague. Monitoring finds an error, communications assumes SEO owns it, SEO assumes legal or product has approved the replacement, and nobody has authority to contact the source. Assign four responsibilities for every validated case, even if one person fills more than one role:

    • The claim owner decides what the correct, supportable brand fact is.
    • The evidence owner supplies the records that prove it.
    • The correction owner updates an owned property or contacts the external source.
    • The verification owner reruns the fixed test set and decides whether the closure rule has been met.

    Package the case so the correction owner does not have to reconstruct it. A complete correction packet should contain:

    1. A short case title naming the entity, incorrect claim, and affected surface.
    2. The verbatim AI claim, original prompt, capture details, and full response.
    3. The URL and exact passage believed to support or repeat the error.
    4. A neutral explanation of why the passage is inaccurate or incomplete.
    5. The smallest replacement wording that resolves the defect.
    6. Links or attachments proving the replacement, with an internal approver named.
    7. The requested action, responsible owner, priority, and next review point.

    For a page you control, make the correction visible in the main content. Reconcile page titles, summaries, downloadable files, structured data, and related documentation where they repeat the old claim. Preserve any record your legal, compliance, or archival obligations require. When an old URL must remain available, add clear current context instead of silently leaving obsolete wording to circulate.

    For an external page, keep the request factual and easy to process. Name the URL and passage. Explain the error in one short paragraph. Supply the replacement and direct evidence. Ask for confirmation when the page changes. Do not mix a correction request with a demand for a promotional backlink, preferred positioning, or removal of an accurate criticism; that obscures the factual issue.

    Automation can create the case, attach captures, route approvals, assign owners, and schedule follow-up. It should not invent the replacement fact or send consequential external messages without review. The risky step is not copying fields between systems. It is deciding what the public record should say.

    Use explicit workflow states: detected, validating, validated, target identified, correction approved, submitted, source changed, retesting, closed, and monitor only. Require an artifact for each important transition. Validation needs proof. Submission needs a copy of the request. Source changed needs a before-and-after record. Closure needs the retest log.

    Separate the source task from the AI-output task. The source task can close when the target page or record is corrected. The output task stays open until your verification rule is satisfied. This distinction prevents a successful outreach email from being mistaken for a corrected brand representation.

    Verify the result without overreading one clean answer

    A corrected page does not guarantee an immediate or universal change in generated answers. The system may retrieve another page, use a different response path, preserve older information, or vary its wording from one run to the next. Do not promise a universal refresh time when the product, model mode, retrieval behavior, and evidence path can differ.

    Retest against the baseline you saved. Use the same prompts, settings, language, and surface first. Then run the approved paraphrases and adjacent questions. If several AI products matter to your business, treat each one as a separate test panel rather than averaging them into a reassuring overall result.

    At each checkpoint, record the answer, whether the inaccurate claim appeared, which qualification was present, and what the response cited. This produces four meaningful outcomes:

    • The source is corrected and the claim disappears across repeated checks. Keep the evidence and move the case toward closure.
    • The source is corrected but the claim persists. Investigate other cited pages, repeated phrasing, cached copies, and conflicting owned content before reopening outreach to the same publisher.
    • The claim varies between runs. Keep the case in retesting; a favorable generation has not established a stable correction.
    • The claim disappears but the underlying source remains wrong. Do not close the source task. The error can return or affect another answer.

    Measure the workflow rather than claiming credit for every output change. Useful operational measures include the number of validated claims still open, time from validation to source change, share of cases with an identifiable evidence target, recurrence within a fixed prompt panel, and the number of cases reopened after apparent resolution. Define each measure before reporting it, and keep raw counts beside rates when the test panel is small.

    Recurrence is especially useful when it has a fixed denominator: erroneous answers divided by completed runs in the same prompt panel at the same checkpoint. Changing the prompts, surfaces, or number of runs midstream makes the before-and-after rate hard to interpret. Add new discovery prompts to the next test version rather than quietly inserting them into the current baseline.

    Key takeaways

    • Preserve the exact claim, response context, prompt, surface, and citations before changing anything.
    • Validate that the statement is objectively inaccurate; negative, incomplete, and false are different correction cases.
    • Correct the evidence layer that can be changed, including contradictory first-party content and inaccurate third-party pages.
    • Give every case a claim owner, evidence owner, correction owner, verification owner, and explicit workflow state.
    • Close source correction and AI-output verification separately, using repeated checks against a fixed baseline.

    Start with the highest-consequence claim for which you already have decisive evidence. Build one complete case, assign its owners, and follow it from capture through repeated verification. That case will expose the missing approvals, evidence gaps, and handoff failures you need to solve before scaling the workflow.

    References

  • How to Use Profound Aim Brainstorm Mode Productively

    How to Use Profound Aim Brainstorm Mode Productively

    You can have useful AI Search data and still face a blank next step. The data may expose several promising directions, but it cannot choose which uncertainty your team should resolve first.

    Brainstorm Mode within Profound Aim is designed for that handoff: it guides a broad goal toward scoped, ready-to-run Agents. The practical value is not producing more ideas. It is reducing the distance between an ambition and a task that can inform a real decision. To get that value, you need to give Brainstorm Mode strategic direction without prematurely prescribing the analysis.

    Use Brainstorm Mode to close a decision gap

    Brainstorm Mode is most useful when you know the outcome you want but do not yet know what an Agent should investigate. That is a decision gap: your team has a business objective and relevant data, but the next analytical question remains unclear.

    Good reasons to start in Brainstorm Mode include:

    • You can describe the business outcome, but several parts of the AI Search data could be relevant.
    • You have noticed a visibility pattern and need to decide which part deserves deeper investigation.
    • Different teams are proposing different explanations for the same result.
    • You need to turn a broad AI visibility priority into work that has a clear boundary.
    • You know someone can act on the answer, but you have not yet defined the question that would produce it.

    Brainstorming adds less value when the task is already precise. If you know the exact question, scope, evidence and required output, you may already have an Agent brief. Starting another ideation cycle can introduce ambiguity that was not there before.

    There is a simple readiness test: complete the sentence, “When this Agent finishes, we will decide whether to ______.” If you cannot fill the blank with a decision your team is prepared to make, the problem is not Agent scope yet. You still need alignment on the purpose of the work.

    Give Aim a broad goal without giving it an empty one

    A glowing sphere and several streams of abstract evidence pass through an open funnel and become three distinct research capsules.

    Broad and vague are not the same. A broad goal leaves room to discover the right investigation. A vague goal hides the decision, audience and boundary that make an investigation useful.

    “Improve our AI visibility” is vague. It does not say which part of the business matters, what kind of visibility problem is in scope or what anyone will do with the result. Brainstorm Mode may still be able to propose work, but you will have no strong basis for judging whether that work matters.

    A useful goal normally contains these ingredients:

    • Outcome: the change you want to support, such as choosing a content priority or understanding a visibility weakness.
    • Business scope: the brand, offering, product area or customer problem that matters.
    • Audience scope: the market, language, geography or buyer context that should govern relevance.
    • Decision: what the team expects to choose after seeing the evidence.
    • Evidence boundary: what the available AI Search data can reasonably help examine.
    • Constraint: what should remain outside the first investigation so the Agent does not become an entire strategy project.

    You can assemble those ingredients with this reusable structure:

    Help us decide [decision] for [brand, offering or audience] by using our AI Search data to investigate [uncertainty]. Keep the first Agent focused on [scope], and produce evidence we can use to [next action].

    Goal-framing template

    For example, replace “Improve our AI visibility” with: “Help us decide which content area should receive the next optimization effort. Use our AI Search data to investigate where visibility is weakest within the product area we plan to grow, and keep the first Agent focused on identifying and characterizing the gap rather than recommending a complete content strategy.”

    The improved version is still broad enough for Brainstorm Mode to shape the work. It also supplies a decision, a business boundary and a stopping point. That stopping point matters. Without it, one Agent can easily become responsible for finding a problem, explaining it, designing a strategy, writing content and evaluating results. Those are different jobs with different evidence requirements.

    Review every proposed Agent as a research brief

    “Ready to run” describes an operational state, not automatic strategic importance. Before running a proposed Agent, make sure its result could actually change what you do. A technically valid investigation can still be too broad, unanswerable from the available data or disconnected from the decision owner.

    Use this pre-run check:

    • One primary question: Can you express the Agent’s job as one question without joining several assignments with “and”?
    • Defined boundary: Does the brief identify the relevant brand, topic, audience or market while excluding unrelated areas?
    • Available evidence: Can the AI Search data support the requested analysis, or is the Agent being asked to infer facts the data does not contain?
    • Usable output: Will the result help someone choose, prioritize, approve, reject or investigate something specific?
    • Inference discipline: Does the brief distinguish observed patterns from possible explanations?
    • Named owner: Is there a person or team prepared to use the result?

    Break apart bundled Agents

    A bundled Agent might be asked to find every visibility gap, explain every cause, compare all relevant competitors, build a content strategy and produce implementation briefs. It sounds comprehensive, but each stage depends on choices made in the previous one. If the first interpretation is weak, every later deliverable inherits the problem.

    Start with the smallest question that can change the next action. An initial Agent might identify and characterize an in-scope visibility gap. A later Agent can investigate evidence-linked explanations for the selected gap. Content planning should begin only after you decide that the gap is important enough to address.

    This sequence also makes poor outputs easier to diagnose. You can tell whether the difficulty came from the goal, the data boundary, the interpretation or the proposed action instead of debugging one oversized deliverable.

    Separate observations from explanations

    AI Search data can reveal a pattern. A pattern does not, by itself, prove why that pattern exists. “The brand appears less often for this topic” is an observation. “The brand appears less often because of a particular content weakness” is an explanation that still needs support.

    If a proposed Agent asks why something is happening, require it to distinguish direct evidence from inference. The useful output is not an unsupported diagnosis stated confidently. It is a set of plausible explanations connected to the available evidence, with the remaining uncertainty made visible. That gives your team something it can test instead of a conclusion it can only accept or reject.

    Turn the first Agent into a controlled decision loop

    A research capsule moves around a circular track with four abstract review stations while a person oversees the final branching gate.

    The fastest way to create a pile of unused analysis is to run every plausible Agent at once. The outputs arrive without an order of operations, overlap in scope and often answer questions that no longer matter after the first decision.

    Use Brainstorm Mode as the beginning of a controlled sequence:

    1. Write the decision sentence: “When this Agent finishes, we will decide whether to ______.”
    2. Frame the broad goal around that decision and the relevant AI Search data.
    3. Use Brainstorm Mode to translate the goal into a proposed Agent or set of Agents.
    4. Apply the pre-run check and select the smallest Agent whose result could change the decision.
    5. Run that Agent before commissioning downstream analysis.
    6. Record the finding, the interpretation and the decision as separate items.
    7. Create another Agent only when the decision exposes a new uncertainty that must be resolved.

    A working note for each completed Agent can remain short:

    • Finding: What is directly supported by the output and underlying data?
    • Interpretation: What might the finding mean, and which part remains an inference?
    • Decision: What will the team do, defer or reject because of the finding?
    • Owner: Who is responsible for the next action?
    • Validation: What later AI Search signal would help determine whether the action had the intended effect?

    Consider a team deciding which product area deserves its next content investment. The first Agent could identify which in-scope topic area shows the most decision-relevant visibility weakness in the available data. The team then selects a topic based on business importance, not merely the size of the gap. A second Agent, if needed, can examine answer patterns for that topic and organize evidence-linked hypotheses. Only then does the team choose a content intervention and define how it will evaluate the result.

    That order preserves human judgment at the points where data cannot make the business choice. Brainstorm Mode helps structure the investigation; it does not remove the need to decide which market, audience, risk and opportunity matter.

    Key takeaways

    • Use Brainstorm Mode when you have a meaningful AI Search goal but have not yet converted it into an answerable investigation.
    • Frame the goal around a decision, business boundary, audience and evidence source instead of asking generally for better visibility.
    • Reject proposed Agents that combine discovery, diagnosis, strategy, production and measurement in one assignment.
    • Make every Agent distinguish data-backed observations from explanations that remain hypotheses.
    • Run the smallest useful Agent first, make a decision and generate follow-up work only when a new uncertainty appears.

    Before you open Brainstorm Mode, write one sentence: “When the first Agent finishes, we will decide whether to ______.” Use that decision to frame the goal you bring into Aim. If the blank is still empty, pause the Agent design and settle the business question first.

    References

  • Modern SEO Workflows: From Dashboards to Small Tools

    Modern SEO Workflows: From Dashboards to Small Tools

    A modern SEO workflow has to do more than collect rankings and audit errors. It must distinguish visibility from traffic opportunity, focus limited time on pages that matter to the business, and turn recurring analysis into reliable automation.

    The most useful operating model is therefore not a wholesale replacement of traditional SEO software. It is a layered system in which established data sources reveal the problem, people choose the intervention, and AI-assisted tools reduce the cost of repeating proven work.

    The operating model matters more than the size of the stack

    Rank trackers, keyword platforms and site crawlers remain useful because search engines still need to discover, interpret and evaluate pages. However, the reported case for a new SEO stack is that those tools describe only part of a more fragmented search environment. AI Overviews, local packs, shopping features and other result formats can change how much value a nominal ranking produces. Historical search volume can likewise remain stable while an answer displayed in the results reduces the traffic available to publishers.

    That changes the role of measurement. A ranking is an observation, not an outcome. The workflow must connect traditional visibility, AI-search presence, landing-page behavior and conversion evidence before deciding what deserves attention. The same source reported that LLM referral traffic in its cited dataset grew by 80% between the first and second halves of 2025 and converted at 18%, while accounting for 2% or less of total traffic. Those figures were presented as evidence of a small but potentially meaningful channel, not as proof that conventional search had ceased to matter.

    Workflow layerQuestion it answersTypical inputsRequired output
    ObserveWhere is visibility, demand or performance changing?Search Console, analytics, rank tracking, crawls and AI-visibility observationsA short list of material signals
    DecideWhich signal is worth acting on now?Business value, intent, conversion proximity and implementation effortOne prioritized intervention
    ShipWhat can improve the page or remove the constraint?Content edits, internal links, technical fixes and clearer conversion supportA completed change or actionable brief
    SystematizeWhich repeated work should become faster and more consistent?APIs, scripts, notebooks and carefully supervised LLMsA documented, testable process

    This sequence prevents a common tooling mistake: automating a report before establishing which decision the report should support. It also preserves a place for human judgment between data collection and implementation.

    A 120-minute loop can connect monitoring with delivery

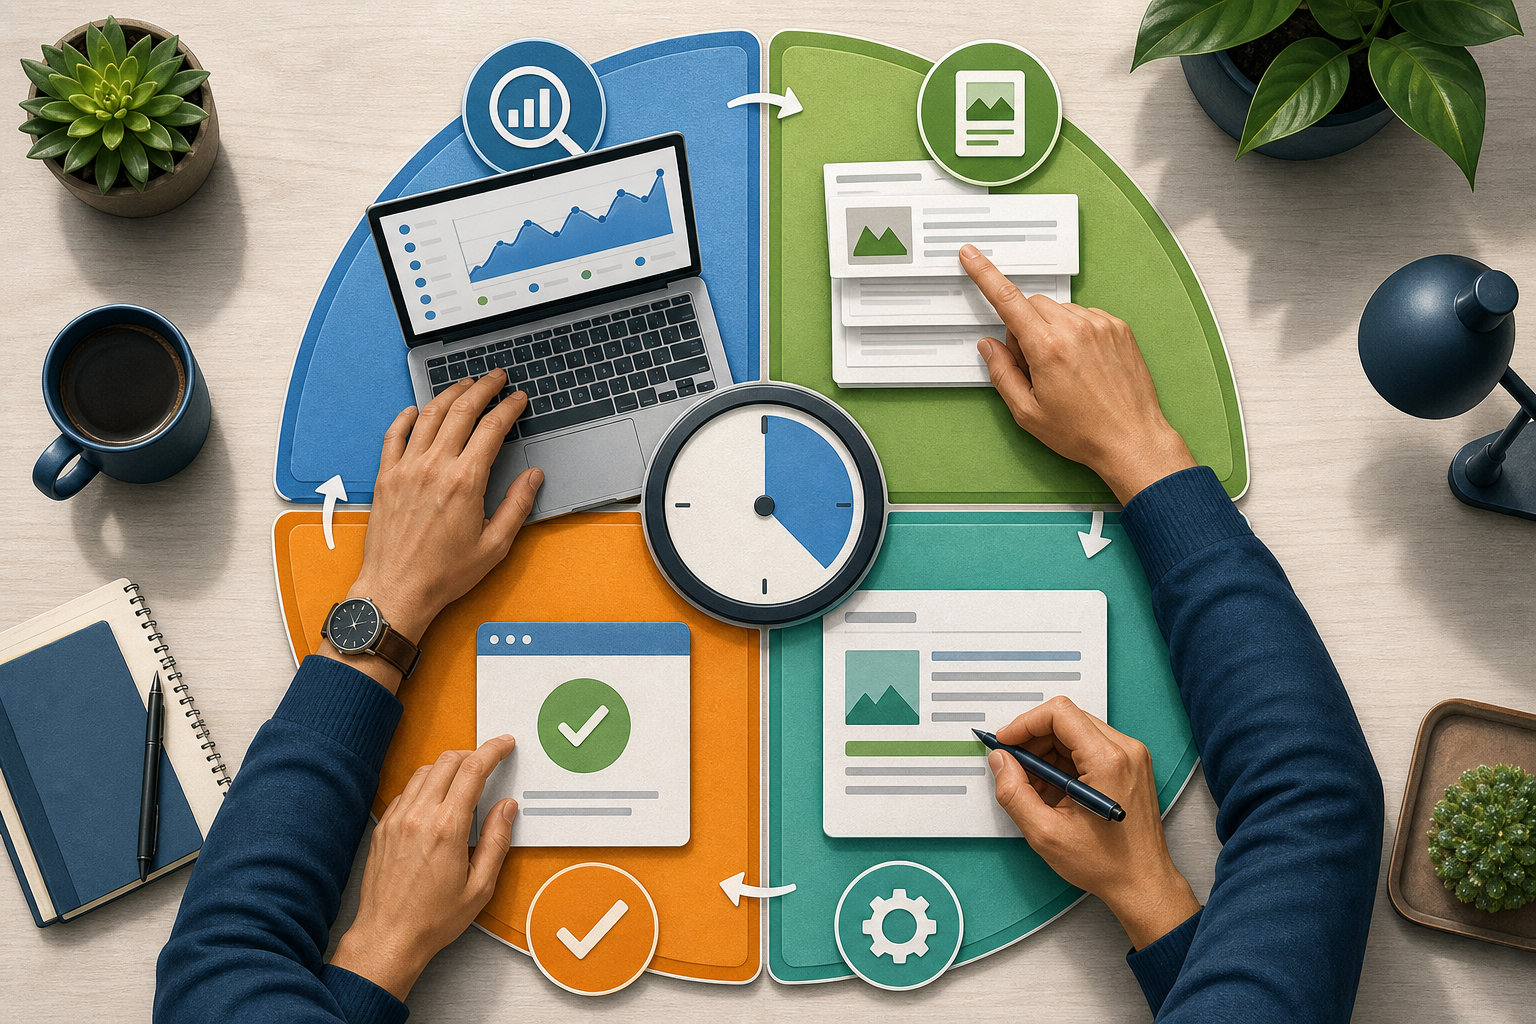
    A top-down desk scene shows four connected stages of an SEO workflow arranged in a circle around a strategist's hands.

    The reported 120-minute workflow addresses a practical constraint: on a lean marketing team, SEO competes with campaigns, reporting, email, social publishing and website requests. Its strongest principle is that a weekly session should finish with work shipped, not merely with more metrics reviewed.

    The first five time boxes below follow the source’s reported schedule. The final 20-minute block is a synthesis of the other sources’ automation guidance, turning the weekly session into a tool-development feedback loop.

    1. Minutes 0-15: inspect Search Console and analytics for meaningful movement, including clicks, impressions, click-through rate, landing-page performance, conversions and critical indexing warnings. Record the largest win, concern and investigation target rather than building a presentation.
    2. Minutes 15-35: identify a small number of query opportunities. The source recommends examining queries in positions 4-15 with meaningful impressions, pages with weak click-through rates and results where the ranking page only partly satisfies intent.
    3. Minutes 35-60: improve one page close to revenue, such as a product, service, category, pricing, comparison or consultation page. The change might address an objection, clarify the audience, add proof, answer a relevant question or make the next action easier to understand.
    4. Minutes 60-80: resolve one consequential technical or indexing problem. If a direct fix is not possible, produce an assigned issue or a developer brief with affected URLs and the expected behavior.
    5. Minutes 80-100: strengthen internal links between useful informational pages and relevant commercial destinations, while also connecting supporting guides and newer strategic content.
    6. Minutes 100-120: verify what changed, document the result and mark one repetitive task as a possible automation candidate. That candidate should enter a backlog rather than becoming an improvised build during the same session.

    The value of this cadence is not the clock alone. It creates a recurring path from signal to decision to change. It also generates concrete automation ideas: a comparison performed every week, a recurring CSV cleanup, a repeated title check or a manual alert that depends on the same thresholds each time.

    Small tools should begin with a bounded decision

    The source on vibe coding describes a low-barrier pattern: specify a program in natural language, run the generated code in an environment such as Google Colab, inspect the output and return errors to the AI for another iteration. It distinguishes this from AI-assisted coding, where a developer remains more directly responsible for the system, and from no-code platforms, which expose automation through visual interfaces.

    The distinction helps set an appropriate ceiling. Vibe coding is presented as suitable for prototypes, internal utilities, demonstrations and tasks where a useful result does not have to be perfect. Commercial software, sensitive systems and products requiring dependable maintenance call for stronger engineering, security and testing practices.

    A reported SEO example makes the right project shape clear. After a site crawl produced vector embeddings, the author prompted an AI to create a Colab tool that would compare vectors with cosine similarity and suggest related pages within each locale. The program had an explicit input, a defined matching rule and a CSV output. It did not attempt to automate an entire SEO strategy.

    Before generating code, a useful tool brief should define:

    • The decision or bottleneck the tool is meant to improve.
    • The exact input source, required columns and accepted file format.
    • The transformation or rule applied to the data.
    • The expected output format and who will use it.
    • A small set of known examples for checking correctness.
    • The behavior when data is absent, duplicated, malformed or unexpectedly large.
    • The APIs, credentials, usage charges and execution environment involved.

    Tool choice can then follow complexity. An LLM may be enough to explore a one-off dataset or review copy. An API becomes useful when manual exports are the bottleneck. A lightweight script suits a stable transformation such as flagging performance changes or checking metadata. A notebook is appropriate when code, commentary and outputs need to remain together. A maintained application is warranted only when the process has durable users, permissions, interfaces and support requirements.

    Validation is part of the workflow, not a final polish

    A compact modular tool moves a web page tile through several visual validation checkpoints while rejected variants remain separated.

    All three sources point toward speed, but they also expose different reasons to retain human control. The new-stack article recommends using LLMs for analysis, content review, competitor comparison, metadata and structured data while keeping editorial and strategic oversight. The weekly workflow keeps prioritization tied to commercial importance. The vibe-coding account shows why plausible-looking output cannot be accepted on appearance alone.

    In one example from the vibe-coding source, an underspecified prompt failed to explain that the input would be a CSV. The generated tool responded with invented URLs, traffic figures and charts. The same source reports that generated code can depend on packages that are not installed, and that paid APIs may introduce authentication steps and usage costs. These are not edge concerns: they demonstrate that execution, factual grounding and operating cost must all be tested separately.

    • Ground the run: identify the authoritative input and reject synthetic substitutes unless test data is explicitly requested.
    • Test a sample: compare several outputs with results that can be checked manually, including an ordinary case and an edge case.
    • Inspect failure behavior: confirm that missing columns, empty files, invalid credentials and API errors produce understandable messages.
    • Protect access: keep credentials out of prompts, shared notebooks, exported files and source code intended for distribution.
    • Track cost: estimate which calls consume paid API units or usage-based platform resources before scheduling repeated runs.
    • Preserve review: require a person to approve consequential content changes, redirects, canonical decisions, schema deployment or other site-wide actions.
    • Document ownership: record the tool’s purpose, dependencies, expected inputs, validation method and person responsible for maintenance.

    A prototype should be promoted into a recurring workflow only after it produces repeatable results on known data. If the logic affects many pages or a revenue-critical system, code review and stronger testing become proportionally more important.

    Key takeaways

    • Keep traditional SEO data, but interpret rankings and search volume alongside result features, traffic opportunity and business outcomes.
    • Time-box reporting so that every weekly SEO session produces a shipped improvement, an assigned fix or a precise implementation brief.
    • Use recurring manual work to discover automation opportunities; do not begin with a tool and search for a problem afterward.
    • Give every small SEO utility explicit inputs, transformation rules, outputs, test cases and failure behavior.
    • Treat LLMs, APIs and scripts as accelerators within a reviewed process, not as substitutes for strategy, factual checks or technical ownership.

    As search interfaces continue to diversify, the durable advantage will come from shortening the distance between a trustworthy signal and a verified improvement. Teams can build that capability incrementally, one weekly decision and one well-scoped tool at a time.

    References

  • How I Turn AEO Data Into Action With Profound Projects

    How I Turn AEO Data Into Action With Profound Projects

    Profound Projects

    With Projects in Profound, I can turn my AEO data into a clear, ranked list of opportunities instead of another report I have to interpret from scratch.

    Each opportunity is broken into practical tasks, with an agent ready to help do the work. That makes it easier for me to move from insight to execution without getting stuck in endless analysis.

    For me, Projects is about spending less time deciding what to do next and more time acting on the opportunities that can improve visibility, performance, and momentum.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot
  • Profound Agent Templates: Launch AI Workflows Faster

    Profound Agent Templates: Launch AI Workflows Faster

    With Profound’s Agent Template Marketplace, I can start from pre-built AI agent workflows instead of building every process from scratch.

    It gives me ready-to-clone templates designed for marketing, SEO, and AEO teams, so I can move from idea to live workflow in minutes.

    For me, the biggest advantage is speed: I can choose a proven workflow, clone it, customize it for my team, and start using AI agents faster with less setup.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot
  • The Marketing Engineer Podcast: A Practical Listener Guide

    The Marketing Engineer Podcast: A Practical Listener Guide

    The Marketing Engineer Podcast is presented as a show for marketers who build systems, tools, and repeatable ways of working. According to its introduction on the Try Profound Blog, its episodes feature practitioners and leaders discussing changes they have made to their teams’ workflows.

    The useful question is therefore not simply whether the podcast covers marketing. It is whether its practitioner accounts can help listeners identify transferable methods for increasing capacity while protecting the quality of the work.

    What the podcast appears to mean by marketing engineering

    The source does not provide a formal definition of a marketing engineer. Its description nevertheless points to a recognizable working style: a marketer who does more than execute individual campaigns and instead creates capabilities that change how a team operates.

    In general terms, this kind of work can include clarifying a process, connecting tools, removing repetitive handoffs, or creating a reusable operating model. The engineering element is less about a particular job title than about treating marketing operations as systems that can be examined and improved.

    That distinction matters. A campaign may deliver a result once, while a well-designed capability can affect many future campaigns. The podcast’s stated emphasis on workflow transformation and scale suggests that its most relevant audience will be interested in the latter.

    Its central tension is scale without declining quality

    Two professionals inspect consistent finished pieces moving through several parallel lanes on a modular worktable.

    The Try Profound Blog introduction frames the featured guests as people who have scaled marketing initiatives without sacrificing quality. That is a significant editorial premise because volume and quality frequently create competing pressures. A faster process is not necessarily a better one if it produces weaker work, obscures accountability, or makes errors harder to detect.

    A useful listener can test each guest’s approach against both sides of that tension. The first question is what became easier, faster, or more repeatable. The second is what controls preserved judgment and standards. Examples might be assessed by looking for clear ownership, review points, feedback loops, and an explanation of when human intervention remains necessary.

    This approach also helps separate genuine operational leverage from simple acceleration. A capability creates leverage when it improves the team’s ability to perform repeatedly; speed alone describes only how quickly an activity was completed.

    How to turn practitioner stories into usable lessons

    Headphones, a microphone, blank cards, a magnifying lens, a small prototype, and repeated components are arranged across a desk.

    The source says episodes provide direct accounts from practitioners and leaders who changed team workflows and created new capabilities. Such accounts can be valuable, but their lessons are rarely universal. A process designed for one organization’s people, constraints, and tools may not transfer intact to another.

    Listeners can make an episode more actionable by identifying four elements in the story: the original bottleneck, the intervention, the conditions that made it workable, and the evidence that the change helped. They should also note what the guest does not establish. A compelling description of a new workflow is different from a demonstrated improvement, and an individual success does not automatically prove that the same method will work elsewhere.

    The most practical next step is usually a bounded experiment rather than a wholesale redesign. A team can translate one episode idea into a small test, define the quality threshold in advance, and compare the result with its existing process. That keeps the podcast in its most useful role: a source of hypotheses and operating questions rather than a substitute for local judgment.

    Key takeaways

    • The podcast is positioned for marketers who prefer building reusable capabilities to relying only on one-off execution.
    • Its reported focus is workflow change, scalable marketing initiatives, and maintaining quality as capacity grows.
    • Practitioner stories are most useful when listeners isolate the problem, intervention, enabling conditions, safeguards, and evidence.
    • Ideas from an episode should be treated as testable approaches, not universal prescriptions.
    • A small, measurable workflow experiment can convert listening into organizational learning without committing a team to an unproven redesign.

    What remains important to verify

    The available introduction establishes the podcast’s intended audience and thematic promise, but it does not specify a host, publishing schedule, episode catalog, distribution platforms, or the methods used to select guests. Those details should not be inferred from the positioning statement alone.

    Prospective listeners can instead evaluate the show episode by episode: whether guests explain trade-offs, whether claims are supported with meaningful evidence, and whether the discussion distinguishes broadly applicable principles from organization-specific choices. If the series consistently supplies that context, it can serve as a practical bridge between marketing strategy and the operational systems required to carry it out.

    References

  • Claude Code as an Agency Knowledge and Action Layer

    Claude Code as an Agency Knowledge and Action Layer

    Claude Code can give an agency more than another place to store information. When local memory, searchable history, connected work systems and focused automations are combined, agency knowledge can move directly from retrieval to a reviewed deliverable or next action.

    The supplied case study describes this as a second brain, but its results should be read as one practitioner’s experience rather than a general benchmark. The author reported that, after rebuilding the workflow over roughly six months, a Monday catch-up that previously involved several applications could be completed in about a minute.

    Key takeaways

    • The useful unit is not a saved note but a decision-ready packet of context that can support a draft or action.
    • Durable memory should remain small and curated, while detailed history can live in a separate search layer.
    • Focused skills turn retrieved knowledge into outputs such as briefs, proposals, meeting summaries and draft replies.
    • Monitoring becomes valuable only after memory, retrieval and task execution work reliably.
    • Read access, drafting authority and permission to act should be treated as separate stages of deployment.

    Treat the system as a decision pipeline, not a notebook

    Agency information moves through a staged pipeline while a strategist reviews a deliverable before release.

    Traditional second-brain systems are good at capture, but capture alone does not resolve the agency’s underlying workflow problem. Information may be preserved in meeting notes, email, messaging tools, a CRM and project files, yet a team member must still remember where it lives, find it, reconstruct the surrounding context and convert it into useful work.

    The source identifies three related failure modes: passive storage that depends on manual recall, context switching between applications, and the absence of an action layer. Claude Code changes that pattern in the reported setup through access to local project files, structured Markdown memory, MCP connections to services such as Gmail, Slack, Google Drive, HubSpot and Scoro, and the ability to draft or analyze material inside a working context.

    Viewed as an operating model, the source’s four layers form a pipeline in which each component answers a different question:

    LayerRole in the workflowQuestion it answers
    MemoryLoads a small set of curated Markdown files covering stable business context, client preferences and working conventions.What should consistently shape the response?
    SearchRetrieves detail from indexed daily logs without placing the entire history in permanent memory.What happened previously?
    SkillsApplies focused procedures for tasks such as drafting a brief, preparing a proposal or summarizing a meeting.What should be produced from the context?
    HeartbeatChecks connected systems on a schedule and surfaces situations that may require attention.What needs intervention now?

    The separation is important. A compact memory layer provides durable guidance, search restores case-specific detail, and a skill transforms both into an output. The heartbeat sits above that foundation: in the reported implementation, it checked email, calendars, Slack and pipeline activity hourly, then delivered a summarized Slack notification and a draft when intervention appeared necessary.

    Design around moments when context must become a deliverable

    The strongest agency use cases begin with a recurring moment of friction, not with a broad goal to automate knowledge work. The source highlights three moments in which scattered context normally has to be assembled before useful work can begin.

    Preparing a client update

    A request for an update may depend on call transcripts, internal notes and recent message threads. The reported system gathers those materials before drafting, reducing the preparation burden and the likelihood that an important discussion is missed. The practical value comes from combining sources around the client question rather than merely returning a list of search results.

    Interpreting performance data

    Analytics and rank-tracking data become more useful when reviewed alongside the decisions, expectations and previous observations that give them meaning. According to the source, the second-brain workflow compiles the needed context for analysis. This illustrates a broader design principle: retrieval should be scoped to the decision being made, so the system supplies relevant history without flooding the task with every stored note.

    Moving from discovery to scope

    Scoping a new engagement often requires translating discovery conversations into requirements and deliverables. The source reports using accumulated discovery context to formulate a scope, reducing repeated exchanges. Here, the skill is not simply summarization. It is a structured transformation from conversational evidence into a draft that a responsible team member can assess.

    These examples share a closed loop: collect the relevant evidence, apply stable business context, produce a defined artifact and place that artifact in front of a human reviewer. A narrow loop is easier to test and improve than an all-purpose agency agent because the expected inputs and acceptable output are clearer.

    Separate knowledge quality from permission level

    Two agency team members review an output within a layered system of knowledge access, drafting and controlled actions.

    An assistant can fail because it lacks the right context or because it has too much authority. Those are different risks and should be managed separately. Better retrieval may improve a draft, but it does not justify allowing the system to send that draft, alter a record or commit a decision without review.

    The source recommends beginning with read-only integrations. In that mode, the system can inspect connected services and prepare material without sending messages or committing changes. Write access is introduced selectively only after its behavior has been evaluated. This creates a practical progression from visibility, to recommendation, to drafting and finally to narrowly bounded execution where appropriate.

    Memory needs a similar constraint. The reported workflow does not treat every daily detail as permanent context. Daily logs can be searched, while only information likely to affect future behavior, such as pricing considerations, client preferences or established working methods, is distilled into long-term memory. This helps prevent outdated or incidental facts from silently steering later work.

    Human review remains the final control for consequential communication. The source’s rule is effectively to trust the drafting advantage while verifying the action. For agencies, that preserves professional judgment over tone, commercial commitments and client-facing claims while still removing much of the mechanical work that precedes a decision.

    Roll out by proving one closed knowledge loop

    A useful implementation sequence follows the flow of information rather than the number of available integrations:

    1. Map the systems that contain decision-relevant material, including email, calendars, messaging, CRM and task management.
    2. Add a transcript source where calls contain context that is not captured elsewhere.
    3. Create a small foundation of durable memory, beginning with business identity, working preferences and carefully distilled daily knowledge.
    4. Keep detailed history searchable so it can be retrieved when relevant without expanding permanent memory indefinitely.
    5. Build one focused skill around a repetitive, reviewable output such as a meeting summary, brief, proposal or draft reply.
    6. Add monitoring only after retrieval and output quality are dependable, beginning with notifications and introducing write permissions cautiously.

    The source presents the heartbeat as the final layer for good reason: proactive monitoring magnifies whatever sits beneath it. If retrieval is noisy or memory is poorly curated, more frequent alerts create more distraction. Once a single loop consistently produces relevant, reviewable work, the same pattern can be extended to another agency process without turning the system into an unrestricted general agent.

    The next stage for agency knowledge workflows is therefore likely to be controlled expansion rather than maximum autonomy: more well-defined loops, better-curated context and permissions that grow only as evidence of reliable performance accumulates.

    References

  • How to Build Reusable AI Content Skills That Stay Useful

    How to Build Reusable AI Content Skills That Stay Useful

    You probably have a prompt that everyone on your team is supposed to use. It may be buried in a document, copied from an old chat, or rewritten from memory whenever someone starts a draft. That works until the prompt changes, a rule gets dropped, or two people interpret it differently.

    A reusable AI content skill gives those recurring instructions a stable home. Build it well, and you can spend less time rebuilding prompts while keeping voice, quality, and answer-engine requirements consistent across projects.

    Move durable decisions out of individual prompts

    The first decision is what deserves to become a skill. A useful candidate appears repeatedly, applies across multiple assignments, and should produce a consistent result regardless of who starts the workflow. Saving recurring instructions for reuse can reduce repetition while helping teams apply the same writing style, AEO practices, and content standards.

    Do not turn every long prompt into a permanent asset. Campaign facts, temporary offers, target keywords, product claims, and assignment-specific angles belong in the content brief. If you embed them in a reusable skill, they can quietly leak into unrelated work or become outdated.

    Put in the reusable skillKeep in the content brief
    Brand voice and prohibited languageThe audience for this specific page
    Required content structureThe query, topic, and search intent
    AEO and editorial quality checksApproved facts, claims, and references
    Citation and uncertainty rulesCampaign messaging and calls to action
    Standard output formatDeadlines, owners, and publishing details

    Use a simple test before promoting an instruction: would you want it applied to the next unrelated assignment? If the answer depends on the topic, client, campaign, or date, leave it in the brief.

    Write the skill as an operating contract

    A skill should tell the AI what job it is doing, what information it needs, which rules are mandatory, and how to recognize an acceptable result. Vague instructions such as “write high-quality SEO content” leave too much room for interpretation. Replace them with observable requirements.

    Skill fieldWhat to write
    PurposeThe narrow outcome this skill produces, such as an answer-first educational page.
    Use whenThe assignments that should trigger it, plus cases where it should not be used.
    Required inputsThe audience, intent, approved facts, desired action, and output destination.
    Non-negotiable rulesVoice, claim boundaries, citation requirements, prohibited language, and compliance constraints.
    MethodThe sequence for interpreting the brief, drafting, checking, and revising.
    Output contractThe required headings, markup, metadata, fields, or schema-ready information.
    Quality checksConditions the result must meet before it can be returned.
    Escalation ruleWhat the AI must flag instead of guessing when information is missing or contradictory.

    Write rules so an editor can verify them. “Use a direct answer near the opening” is testable. “Make it engaging” is not. “Link factual claims to approved references” is testable. “Sound authoritative” is not.

    Define priorities before instructions conflict

    Reusable defaults will eventually collide with a project brief. State the order of precedence inside the skill. A practical hierarchy is mandatory legal and brand policy first, assignment requirements next, skill defaults after that, and model discretion last. Adjust that hierarchy to match your organization, but do not leave it implicit.

    Add an escalation rule for unresolved conflicts. The AI should identify the clashing instructions and request a decision rather than quietly choosing whichever wording appeared most recently.

    Separate writing, optimization, and validation

    Three separate workstations represent writing, optimization, and final content validation in a staged workflow.

    One giant skill may look efficient, but it becomes difficult to maintain. A change to your brand voice should not require rewriting your structured-data rules. A new citation policy should not disturb the way product pages are organized.

    Use a small set of focused layers. A voice skill can control tone, sentence style, terminology, and banned phrasing. A content-type skill can define the structure for an explainer, comparison, landing page, or documentation page. An AEO skill can require a direct response to the main question, intent-aligned headings, clear entities, useful follow-up coverage, and supported claims. A validation skill can check the finished draft for omissions and violations.

    Keep validation separate from generation when possible. Asking the same instruction block to draft and approve its own output can hide errors. A dedicated check should compare the result with the brief and return specific failures: an unsupported claim, a missing answer, an inconsistent term, or an invalid output field.

    This separation also makes ownership clearer. Brand teams can maintain voice rules, search teams can maintain AEO requirements, subject experts can maintain claim boundaries, and content operations can maintain formatting. Each group can update its layer without reopening the entire workflow.

    Test the skill against real editorial failures

    A technician tests a modular content system against abstract obstacles representing common editorial failures.

    A skill is not ready because it worked on the prompt used to create it. Test it with representative briefs: a straightforward assignment, an incomplete one, a request that conflicts with brand policy, and a topic where the supplied evidence does not support a confident claim.

    Review the outputs by failure type. Check whether the voice drifted, the answer arrived too late, unsupported details appeared, mandatory fields were omitted, or the AI followed a lower-priority instruction. Record the failure and revise the smallest instruction that caused it.

    Change a single rule at a time when practical. Otherwise, you will not know which revision fixed the problem or introduced a new one. Preserve previous versions and note why each update was made. That turns the skill into a managed editorial asset instead of an anonymous prompt that gradually accumulates exceptions.

    Watch for rules that belong elsewhere

    Repeated exceptions are diagnostic. If editors constantly override the same voice rule for product pages, you may need a separate product-page skill. If factual corrections recur, the problem may be the approved material supplied with the brief rather than the writing instructions. If output fields disappear, strengthen the output contract and validation layer.

    Do not solve every failure by adding more words. Remove duplicated rules, merge instructions that mean the same thing, and replace subjective adjectives with checks an editor can observe. A shorter skill with clear boundaries is easier to trust than a long one full of overlapping advice.

    Key takeaways

    • Save stable, recurring editorial decisions as skills; keep assignment-specific facts and goals in the brief.
    • Define the skill’s purpose, trigger, inputs, mandatory rules, output contract, checks, and escalation behavior.
    • Use focused layers for voice, content type, AEO requirements, and validation so each can be maintained independently.
    • Make every instruction observable enough for an editor to verify.
    • Test against incomplete and conflicting briefs, then revise the smallest rule responsible for each failure.
    • Version skills and record why they changed so teams know which standard is active.

    Start with the instruction block your team copies most often. Remove anything tied to a single assignment, give the remaining rules a clear output contract, and test the skill on work your editors already know well. Once that first skill performs reliably, use the same pattern for the next recurring workflow.

    References