Category: PPC

  • Google Ads Automated Bidding Changes: What to Reassess

    Google Ads Automated Bidding Changes: What to Reassess

    Your Google Ads campaign can look less efficient even when automated bidding is doing exactly what you told it to do. If a budget-limited campaign used to beat its target ROAS or CPA but now buys more expensive traffic and exhausts its budget sooner, don’t assume the bidder is broken.

    The more useful question is whether your target still expresses the result your business actually needs. Google has made target-based bidding more literal for budget-constrained campaigns, while a separate retail beta adds product-level value signals. Together, these changes put more responsibility on you to define acceptable economics rather than relying on budget pressure to produce accidental efficiency.

    Budget limits no longer create the same efficiency buffer
    A limited tank of glowing coins drains through an automated bidding machine that sends larger bundles toward several abstract auction gates.

    A target ROAS or target CPA is an instruction, not a label. If you give the bidder a target that is looser than your real business requirement, it has room to pursue additional opportunities until performance approaches that stated target.

    Before the Smart Bidding change, a constrained budget could effectively make bidding more conservative. Some campaigns captured cheaper clicks, stretched their allocations and substantially exceeded their targets. The update that started rolling out on Aug. 17 and finished globally on Aug. 27 was intended to make target-based, budget-limited campaigns perform more consistently around the goals advertisers entered, including when budgets changed.

    The practical consequence is easy to miss. A target CPA campaign set to $10 but previously delivering a $5 CPA could move closer to $10 unless the advertiser tightens the target. The equivalent can happen with target ROAS: historical overperformance is not necessarily a permanent buffer when the system is being asked to deliver only the lower stated return.

    The initial post-rollout pattern was substantial. Median CPC for budget-limited target ROAS campaigns rose 15.8%, while CPC for campaigns that were never budget-limited fell 13%. Before the change, more than half of the constrained campaigns were exceeding their ROAS targets. Only 30% of non-limited campaigns overdelivered, while 57% landed on target.

    Observed medianBefore the rolloutAfter the rolloutWhat you should notice
    CPC for budget-limited campaigns€0.38€0.44The constrained campaigns paid more for each click.
    Impression share lost to rankAbout 45%About 30%Ad rank was responsible for a smaller share of missed impressions.
    Impression share lost to budgetAbout 4%About 33%The budget became the more direct constraint.
    Overall impression share40%31%The campaigns reached a smaller portion of available impressions.

    That combination matters more than any one number. Higher CPC, lower rank loss and sharply higher budget loss indicate that the bidder may be competing more strongly when it enters an auction, then running into the spending limit sooner. It is a different mechanism from simply bidding conservatively all day.

    The findings are early rather than universal. Conversion attribution was still developing, so the long-term ROAS effect was not yet settled. Treat Aug. 17 as a meaningful diagnostic breakpoint, not as proof that every performance change in every account has the same cause.

    Audit affected campaigns without hiding the change in averages

    An account-level average can conceal exactly what you need to see. Separate target-based campaigns that were budget-limited from campaigns that had enough budget. The two groups moved differently after the rollout, so combining them can turn a clear bidding shift into an ambiguous blended trend.

    1. Identify campaigns using a target-based strategy. Separate target ROAS from target CPA so you evaluate each one against the correct efficiency measure.
    2. Flag campaigns that were budget-limited around the rollout. Keep campaigns that were never constrained as a comparison group rather than mixing their results into the same total.
    3. Use Aug. 17 as the beginning of the change and Aug. 27 as the completion point. Avoid treating the rollout interval as a clean before-or-after period.
    4. Allow conversion attribution to mature before making a final ROAS or CPA judgment. CPC and impression-share signals appear sooner than fully attributed conversion value.
    5. Compare actual performance with the target you entered. Record target ROAS versus delivered ROAS, or target CPA versus delivered CPA, rather than looking only at the change from the previous period.
    6. Review CPC, total impression share, impression share lost to rank and impression share lost to budget together where those metrics are available. This shows whether the campaign became less competitive, more budget-constrained or both.
    7. Check the business result behind the platform metric. Revenue, contribution margin, inventory priorities and acquisition value determine whether performance near the target is acceptable.

    Read the metrics as a system

    If CPC rises, rank loss falls and budget loss rises, the campaign is probably bidding more competitively and exhausting its allocation more directly. Review the target before assuming the budget is too small.

    If actual ROAS falls toward target ROAS, or actual CPA rises toward target CPA, the bidder may be using the flexibility you explicitly gave it. Decide whether the additional opportunity is economically worthwhile. Don’t call the movement a failure merely because the old campaign overdelivered, but don’t accept it merely because the platform reached its target either.

    If total impression share falls while budget loss rises, you face a real reach decision. You can accept fewer impressions, tighten the target and potentially reject more opportunities, or fund more of the available demand. The correct answer depends on the value of the next unit of spend, not on a desire to recover an old impression-share percentage.

    If those auction signals are absent, don’t force the bidding update to explain the problem. A conversion-tracking change, product mix, demand shift or landing-page issue can also alter ROAS or CPA. The update is a hypothesis to test against campaign-level evidence, not a universal diagnosis.

    Choose the lever that matches the actual constraint

    You have four defensible responses: accept less reach, tighten the target, increase the budget where the economics support it, or reconsider the bidding strategy. The dangerous response is to raise the budget automatically because the interface says a campaign is limited.

    Tighten a target that understates your real requirement

    If the business needs a higher return than the target ROAS currently entered, raise the target toward the efficiency level you genuinely require. If the business cannot tolerate the current target CPA, lower that target toward the acceptable acquisition cost. Historically delivered performance can inform the change, but it should not replace your unit economics.

    A tighter target can reduce reach because the bidder must reject opportunities that do not fit the new instruction. That is not necessarily a defect. It is the cost of refusing volume that fails your efficiency requirement.

    Increase the budget only when performance at the target is valuable

    A larger budget can make sense when the stated target is profitable and additional demand has value. Evaluate the next dollars as though they will perform near the target, not at the unusually strong ROAS or CPA the constrained campaign used to deliver. The update was designed to bring delivery closer to the entered goal, so historical overperformance is a weak basis for approving more spend.

    This decision creates direct financial exposure. Set the approved spending limit from margin, cash flow and customer value, then decide how much reach to purchase. A platform warning that a campaign is budget-limited does not establish that the missed traffic is profitable.

    Accept reduced reach when the budget is fixed

    If the spending cap cannot move and the target already reflects your economics, reduced reach may be the honest result. You cannot demand the same auction coverage, preserve the same efficiency and keep the same budget when click costs rise. Choose which constraint is real instead of asking automation to satisfy three incompatible requirements.

    Reconsider the strategy when one target cannot express the objective

    A single account-wide or campaign-wide value target can be too blunt when products have materially different commercial value. Before abandoning automation, examine whether the bidding system is receiving the wrong definition of value. For retailers, the Product Value Optimization beta is intended to address part of that problem.

    Whichever lever you select, change it deliberately. Altering the target, budget and value rules together makes the result hard to interpret. Record the reason for the first change, let attributed conversions develop, and then judge whether that lever addressed the constraint you identified.

    Product Value Optimization adds business context to retail bidding
    Generic retail products send layered margin, inventory, customer value, and priority signals into a central automated bidding engine.

    Standard conversion-value bidding can treat equal amounts of reported revenue as equally desirable even when the underlying sales have different margins or inventory consequences. Product Value Optimization is a retail beta that allows value adjustments for individual products or attributes such as brands and categories. Those adjusted signals can guide automated bidding in Performance Max and Shopping campaigns without requiring a campaign restructure.

    This gives you three different controls with three different jobs. The budget limits the spend available. The ROAS or CPA target communicates the desired efficiency. A product value rule tells the bidder which items or sales deserve more emphasis. Confusing those jobs leads to bad fixes, such as raising an entire campaign’s budget when the real need is to favor a profitable category within it.

    The beta identifies profit, seasonal sell-through and best-selling products as possible use cases. Those goals are not interchangeable. A bestseller may produce volume but weak incremental profit. Seasonal inventory may warrant temporary priority because its value falls after the selling window. A high-margin product may deserve emphasis even if it does not lead the revenue report.

    Define the rule before enabling the adjustment

    1. Choose one commercial objective for the rule: profit, seasonal sell-through or another clearly defined inventory priority.
    2. Select the narrowest appropriate level. Use a product rule when the priority is item-specific, or an attribute such as category or brand when the logic genuinely applies across that group.
    3. Write down why the selected sale is more valuable. Higher revenue alone is not enough if margin, returns or inventory costs point in the opposite direction.
    4. Map overlapping product, category and brand logic before activation. The bidder needs a coherent value hierarchy, not competing expressions of internal preferences.
    5. Keep actual revenue and profit as independent business measures. An adjusted optimization value is an instruction to the bidder; it is not proof that the resulting sales created more profit.
    6. Evaluate product mix as well as aggregate ROAS. A stable top-line return can hide a meaningful shift toward or away from the inventory the rule was designed to prioritize.

    If the beta appears in your account, start with the business distinction you can defend most clearly. A rule grounded in margin or time-sensitive inventory has a testable rationale. Prioritizing a product merely because it is already popular risks teaching the bidder to amplify volume that would have occurred anyway.

    Key takeaways

    • Budget-limited target bidding may no longer produce the same conservative bidding and accidental target overperformance it produced before the Aug. 17 rollout.
    • A CPC increase combined with lower rank loss and higher budget loss is more informative than a CPC increase viewed alone.
    • Treat target ROAS and target CPA as permissions the bidder can use, not as passive reporting benchmarks.
    • Model a budget increase at performance near the stated target rather than assuming the campaign will retain its former overperformance.
    • Use Product Value Optimization to express genuine differences in commercial value, not to promote products based on popularity alone.
    • Allow attribution to mature before declaring the long-term ROAS effect, because the available post-rollout evidence was still preliminary.

    Start with the budget-limited campaign where the gap between target and historical performance was largest. Reconstruct what changed across CPC, impression-share losses and actual efficiency, then make the smallest change that brings the bidding instruction back into line with the economics you are prepared to accept.

    References


  • Google Ads Control Reliability: What Settings Really Do

    Google Ads Control Reliability: What Settings Really Do

    Your Google Ads campaign has almost stopped serving, but billing, policy status, conversion tracking, negative keywords, locations, devices, and schedules all look clean. This is where the interface can send you in the wrong direction: a visible setting may be active without carrying the authority you assume it has.

    Before you raise the budget, remove targeting, or abandon automation, identify what the setting actually promises. Some controls block delivery. Others affect eligibility, establish a bidding constraint, or merely give the system context. The useful question isn’t just, “Is this control enabled?” It is, “What happens when this control conflicts with the auction?”

    The control hierarchy: five settings, five different promises

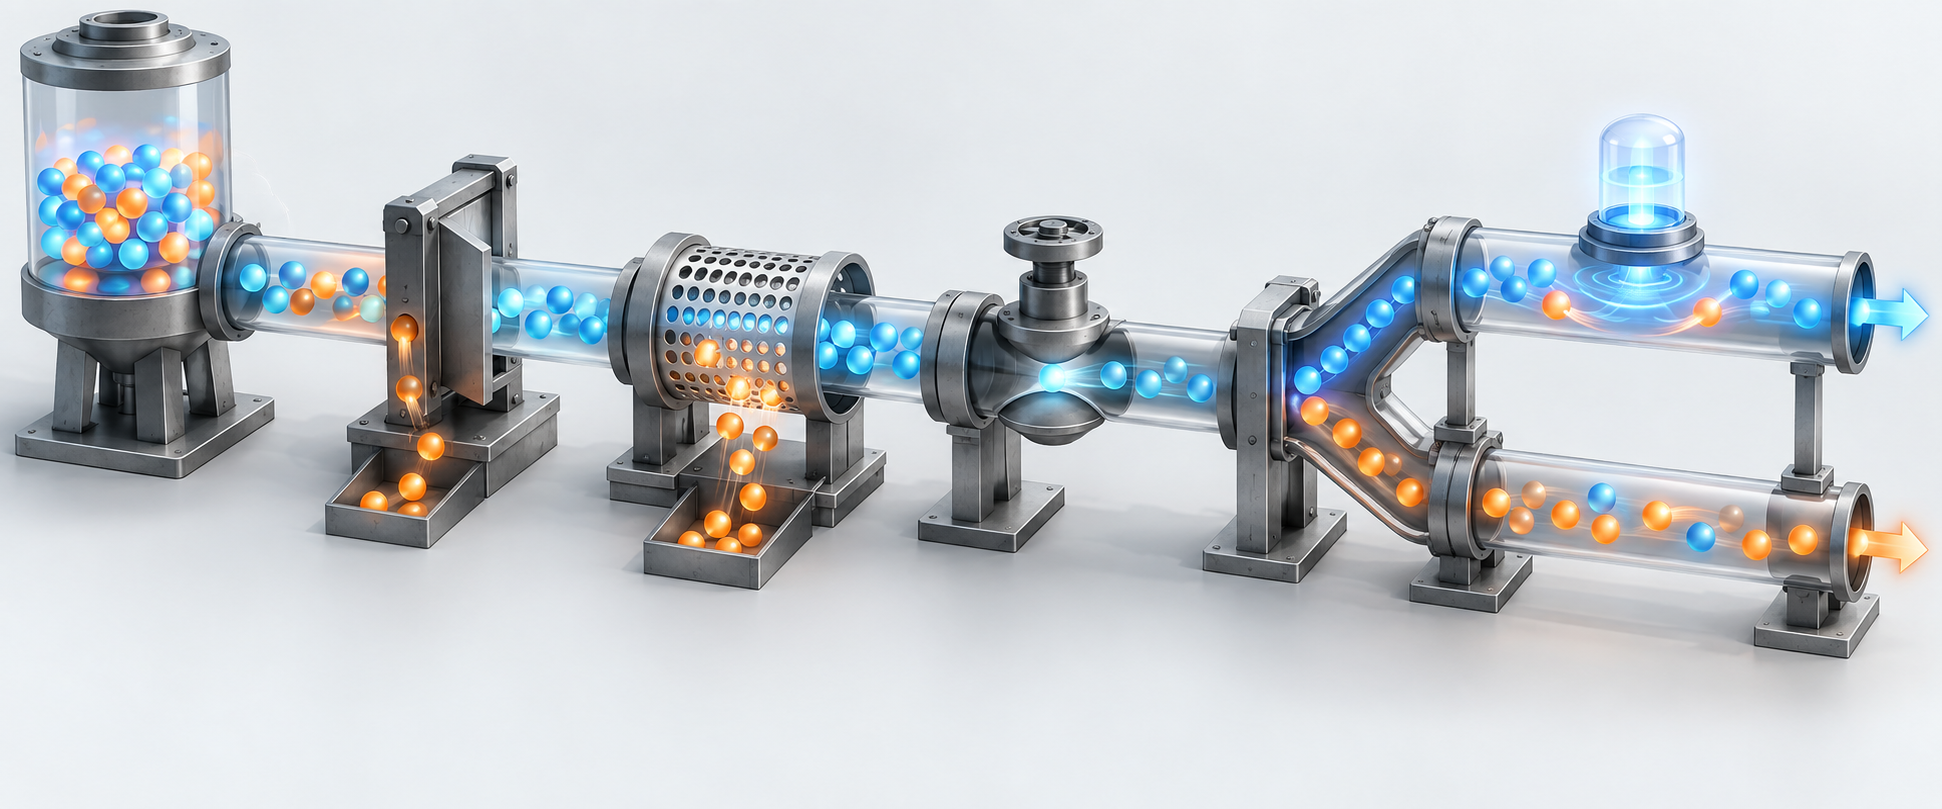
    A stream of glowing tokens passes through a barrier, filter, valve, junction, and signal beacon in an isometric delivery pipeline.

    A reliable control is not necessarily one that produces the outcome you want. It is one whose behavior you understand well enough to predict what will happen when market conditions, automation, and your instructions disagree.

    Control classGoogle Ads examplesWhat it can reliably doWhat it cannot promise
    Hard restrictionsNegative keywords, brand exclusions, URL exclusionsConstrain whether specified traffic or assets can serveA negative keyword does not block every query related to the same concept
    Opt-outsAI Max toggle and ad-group-level search-term matching controlsDisable a defined feature or behavior at a particular scopeA complete return to an older campaign state, especially when related controls or migrated features behave differently
    Priority rulesPriority for an identical, eligible exact-match keywordPut one eligible option ahead of another in the selection processEligibility, impressions, clicks, or traffic volume
    TargetsTarget CPA and target ROASConstrain the range in which automated bidding tries to operateThe requested conversion volume at any market price
    Contextual signalsPerformance Max search themes and the keywords, creative, and URLs used by AI MaxInform expansion and help automation interpret your intentA deterministic boundary around every query the campaign can enter

    The details matter most at the edges. Negative keywords, brand exclusions, and URL exclusions are treated as firm boundaries, but a negative keyword is still a precise instruction about the text you entered. Casing and misspellings are handled, while synonyms and singular or plural forms are not automatically covered. If you add job as a negative, do not assume you have also excluded jobs, career, and employment.

    At the other end of the hierarchy, search themes and other contextual signals help the system interpret a campaign. They are useful for direction, but they should not carry a must-not-serve requirement. If a query category would create unacceptable cost or brand exposure, use an applicable exclusion control and verify its coverage instead of relying on a theme or creative cue.

    Matching guidelines in AI Brief do not fit neatly into either category. They are presented as guidance and boundaries with previews, but Google has not published a deterministic guarantee or an enforcement rate. Treat them as something to test in live query evidence, not as a substitute for a confirmed exclusion.

    When delivery collapses, diagnose authority before changing bids

    A campaign that has gone quiet invites broad, hurried edits. That makes the underlying problem harder to isolate and can release more spend than you intended. Use a fixed diagnostic sequence instead.

    1. Mark the beginning of the decline. Identify when impressions, clicks, and conversions changed. You need a date to compare with configuration changes; a current-state screenshot cannot tell you what created the current state.
    2. Check basic eligibility. Review billing, policy status, location and device targeting, schedules, negative conflicts, conversion configuration, and available budget. “Limited by budget” is an eligibility condition, so even a valid priority rule may not operate as you expect when the campaign is constrained.
    3. Use the ad preview result as a symptom. A not-serving result confirms that the campaign is not entering or winning that opportunity. It does not, by itself, identify the responsible control.
    4. Expand change history to the campaign’s full lifetime. A decisive bid-strategy or target change may sit outside a 30-day or 12-month view. A full-lifetime review exposed a consequential change that shorter windows had hidden.
    5. Classify each relevant setting. Label it as a hard restriction, opt-out, priority rule, target, or contextual signal. Then write down the narrow promise it actually makes.
    6. Compare bidding targets with attainable economics. Examine whether recent CPA, CPC, competition, and conversion volume still overlap the target. A target based on an older market can be reasonable when it is chosen and still become restrictive later.
    7. Run one reversible test. Change the suspected constraint without simultaneously rewriting keywords, ads, locations, and budgets. Loosening or removing a bid target can unlock spend quickly, so confirm the campaign budget and conversion measurement before publishing the test.

    This sequence separates three very different failures: the campaign is ineligible, the campaign is eligible but constrained by its target, or the campaign is serving outside the conceptual boundary you thought a matching control created. Each failure needs a different fix.

    A target CPA is a traffic constraint, not a cost ceiling

    Abstract bid vehicles approach a narrow checkpoint, where only some pass through toward opportunities of different sizes.

    Target CPA is easy to misread because its name sounds like a preferred result. In practice, the target constrains the auctions automated bidding can justify. When the available market no longer overlaps that target, the system cannot simply pay substantially more for every desirable prospect and preserve the target at the same time. It can reduce participation instead.

    Consider a referral-software campaign that recorded only six impressions during a month in which it had effectively gone dark. Its account showed a $200 target CPA and a $182 actual CPA, which looked superficially healthy. The full change history showed that Maximize Conversions with a $200 target CPA had been introduced in October 2024. That target was about 12% higher than the CPA achieved in the previous year, so it was not an obviously aggressive choice when it was set.

    The market had moved. Competition had more than doubled, CPC had risen 51.96%, and CPA had moved from $138.53 to $316.76. The $200 target had become roughly 37% lower than the cost the campaign was encountering per lead. The automation preserved the constraint by finding very little traffic it considered compatible with that constraint.

    This is why an actual CPA below target does not automatically prove that a target is healthy. Ask how much delivery produced the number. An apparently efficient CPA based on negligible impressions or conversion volume can coexist with a campaign that is economically unable to scale.

    • Check volume before celebrating efficiency. Read actual CPA beside impressions, clicks, and conversions, not as an isolated score.
    • Compare the target with recent conditions. The CPA that justified a decision a year ago may describe a market that no longer exists.
    • Look for movement in input costs. A major CPC increase can make the old acquisition target unattainable even when the landing page and conversion setup have not changed.
    • Align the date of the decline with change history. A target may begin as attainable and become restrictive gradually, so the visible delivery collapse can occur well after the original edit.

    If the evidence points to an unrealistic target, test a less restrictive target as a controlled bidding change. Do not simultaneously increase the budget and broaden matching. A higher target can admit more expensive auctions, while a larger budget gives the campaign more money to enter them; changing both prevents you from knowing which lever changed performance and increases the financial exposure of the test.

    Match types and opt-outs need boundary tests

    Exact match should be read as a priority and relevance mechanism, not as a literal-text firewall. Its boundaries changed in stages: close variants became optional in 2012, mandatory for exact and phrase match in 2014, and broader through later changes involving word order, implied terms, and paraphrases. Same-meaning matching reached phrase match and broad match modifier in 2019. Phrase match absorbed broad match modifier behavior in February 2021, and advertisers could no longer create new broad match modifier keywords by late July 2021.

    An identical, eligible exact-match keyword can receive first priority, but that is a queue position rather than a delivery guarantee. The keyword must still be eligible, the campaign must have budget, inventory must exist, and exceptions for advanced search experiences may apply. “We have the exact keyword” therefore does not answer “Why did we receive no impression?”

    Use a separate boundary test for each kind of control:

    • For negative keywords, test the strings you actually excluded. Add important synonyms and singular or plural forms separately when the concept must be blocked. Do not rely on positive-keyword expansion rules to describe negative-keyword behavior.
    • Inspect long searches carefully. On a search longer than 16 words, a negative term appearing after the sixteenth word will not block the ad. A rare long query can therefore cross a boundary without the negative keyword being ignored or malfunctioning.
    • For exact match, inspect eligibility and the matched search term. Determine whether the exact keyword was eligible to receive priority before treating the outcome as a matching failure.
    • For AI Max opt-outs, verify related behavior after the toggle changes. Some controls housed within the feature stop applying when it is disabled. The migration of Dynamic Search Ads into AI Max also means that switching AI Max off should not be assumed to recreate every aspect of the older campaign state.
    • For contextual signals, evaluate direction rather than compliance. Search themes, creative, keywords, and URLs can steer expansion. Confirm the result in search-term evidence instead of treating those inputs as enforceable exclusions.

    The practical distinction is simple: verify hard boundaries against prohibited traffic, evaluate priority rules only after confirming eligibility, judge targets by both cost and volume, and assess contextual signals by the traffic they influence. Applying one test to all four produces false confidence.

    Key takeaways: build a control-reliability routine

    Keep a small control register for each material campaign. It does not need another dashboard. A shared account note or worksheet is enough if it records the setting, its scope, its authority class, the expected effect, the evidence used to verify it, the owner, and the safe rollback.

    • Start with authority, not the label. Decide whether a setting blocks, opts out, prioritizes, constrains, or guides before predicting its effect.
    • Use full-lifetime change history when delivery has no visible cause. The current configuration may be the accumulated effect of a decision hidden beyond the default date range.
    • Judge bid targets against recent attainable economics and meaningful volume. An actual CPA below target means little when the campaign barely enters auctions.
    • Test query controls at their real boundaries. Check variants, scope, eligibility, and long-query behavior rather than assuming that a control covers the surrounding concept.
    • Change one consequential lever at a time. Record the expected effect and rollback first, and keep the budget within an amount you are prepared to expose while the test runs.

    Open the weakest-delivering campaign first. Expand its change history, classify its active controls, and choose the smallest reversible test that can distinguish an eligibility problem from an unrealistic target or a misunderstood matching boundary. Once you can state exactly what each control is allowed to decide, the account becomes much easier to manage without guessing.

    References


  • Competitive Intelligence for PPC: A Decision-First Playbook

    Competitive Intelligence for PPC: A Decision-First Playbook

    You have a competitor spreadsheet full of keywords, screenshots and offers. The harder question is what any of it should change. Copying a rival’s message can make your ads less distinctive, while chasing its apparent spend can move money into traffic that does not fit your economics.

    Useful competitive intelligence narrows a decision. It shows you which customer concern may be underserved, whether you can credibly address it and how to test that advantage without confusing competitor activity with proof of profitability.

    Start with the PPC decision, not the competitor

    Before collecting more data, write down the decision in front of you. Are you deciding whether to raise a budget, change an ad promise, rebuild a landing page, enter a query category or defend a profitable campaign? Each decision requires different evidence.

    A budget decision needs your marginal acquisition economics. A messaging decision needs evidence of an unmet customer expectation and proof that your business can meet it. A landing-page decision needs a visible break between the ad promise and the information a visitor finds after clicking. Without that distinction, a competitor audit becomes an attractive archive with no operating value.

    Set your internal guardrails before looking outward. Record the acceptable acquisition cost or return target, the conversion that actually matters, your capacity to serve additional demand and the business objective of the campaign. Base a break-even acquisition cost on contribution rather than top-line revenue. If customer lifetime value affects the calculation, use retention and margin evidence you can defend rather than an optimistic projection.

    This step matters because businesses that appear similar can have very different margins, average order values, conversion rates, customer lifetime values and growth priorities. A competitor can rationally spend more than you, or less than you, without either account being mismanaged. Even Google’s peer comparisons cannot see enough of those differences to set your budget for you. Industry and advertised location help define a peer group, but they do not make the underlying businesses economically equivalent.

    Use a short decision brief for every competitive-intelligence task:

    1. Decision: State the one campaign choice the work must inform.
    2. Scope: Name the offer, search intent, audience and market involved.
    3. Success measure: Choose the closest reliable business outcome, such as qualified leads, booked work or completed sales.
    4. Guardrails: Record the limits on cost, lead quality, margin and operating capacity.
    5. Possible actions: Limit the outcome to test, investigate, leave unchanged or stop.

    If a finding cannot affect one of those actions, it may be interesting, but it is not yet actionable intelligence.

    Build an evidence stack instead of a swipe file

    Layered translucent evidence cards converge on one highlighted token beside a blurred pile of disconnected screenshots.

    No single competitive signal answers the whole question. An ad shows what a competitor chose to say at one captured moment. A landing page shows how that promise was supported. Reviews expose recurring expectations and disappointments. Your own campaign and commercial data determine whether an opportunity is worth pursuing.

    EvidenceWhat it can tell youWhat it cannot establishUseful decision
    Competitor adThe promise, framing and call to action visible for a particular query at capture timeHow often the ad runs, whether it converts or whether it is profitableWhich message deserves closer inspection
    Competitor landing pageHow the promise is explained, proven and connected to the conversion pathThe page’s conversion rate, lead quality or commercial returnWhich uncertainty your own page may need to resolve
    Low-rated customer reviewsRepeated frustrations, failed expectations and language customers useThe prevalence of a problem across the whole customer baseWhich customer outcome may be underserved
    Your reviews and operating recordsStrengths customers recognize and promises your team can consistently deliverWhether featuring a strength in an ad will improve performanceWhich competitive message is eligible for testing
    Google Ads peer benchmarkHow weekly spend and clicks compare with a platform-defined peer groupPeer profitability, margins, conversion quality or your optimal budgetWhich difference deserves diagnosis

    Capture observations in a consistent worksheet. For an ad or page, include the date, query theme, market, visible promise, proof offered, call to action and continuity between the ad and destination. For a review theme, include the complaint, desired outcome, frequency in your sample, whether it appears across competitors and whether your business has verified evidence of doing better.

    Keep three columns separate: observation, interpretation and proposed test. A statement such as a competitor emphasizes rapid service is an observation. Customers may value time certainty is an interpretation. Showing a verified response commitment will improve qualified conversion is a hypothesis. Blending those three statements makes a plausible idea look like a fact.

    Weight competitors by relevance. A direct alternative serving the same intent, geography and buyer deserves more attention than a famous brand with a different offer or economic model. Preserve the capture date as well. Ads, pages and offers change, so an undated screenshot quickly becomes unreliable.

    Mine negative reviews for unmet expectations

    Keywords show what people request. Negative and mixed reviews often show what they feared, expected or regretted after choosing a provider. That makes them especially useful for finding a message competitors cannot easily copy unless their operations support it.

    Start with roughly 30 to 50 negative or mixed reviews from two or three direct competitors, concentrating on one-, two- and three-star feedback. Use relevant public review platforms for the market. Remove obvious duplicates, preserve enough context to understand each complaint and do not treat a complaint about one location or service as evidence about an entire brand.

    AI is useful here as a clustering assistant. Give it the raw review text and ask it to group recurring complaints, count mentions, calculate each theme’s share of the collected sample, paraphrase a representative example and identify the outcome the customer appeared to want. Require it to flag ambiguous reviews and avoid adding facts that are not in the text.

    Keep an important limitation attached to the output: the percentage describes your selected review sample, not the market. Low-rated reviewers are self-selected, competitor review volumes differ and platform audiences are not interchangeable. Use the count to prioritize investigation, not to announce that a given percentage of all customers has the problem.

    Translate complaints into desired outcomes before writing copy:

    • Unexpected charges point toward a need for price certainty and a clear approval process.
    • Slow replies point toward a need for acknowledgement and time certainty.
    • Poor communication points toward a need to understand status and next steps.
    • A complicated booking process points toward a need for lower effort and clearer instructions.
    • Limited availability points toward a need to know when service can actually be provided.

    A repeated theme across several direct competitors is more useful than an isolated complaint. It may identify a category-level expectation that is not being met consistently. It still does not prove that your company meets it.

    Now compare those themes with your own reviews and operating evidence. Ask AI to identify strengths customers repeatedly praise in your reviews when competitors receive complaints about the same issue. Then verify the result with the people responsible for delivery. Review language can identify a candidate advantage; service records, policies and operational owners determine whether you are entitled to advertise it.

    Create a claim ledger before any candidate promise enters an ad. For each claim, record the exact wording, responsible owner, supporting evidence, conditions or exclusions, landing-page proof and the action to take if performance slips. A response-time promise, for example, needs a defined starting event, covered hours and a reliable measurement method. A fixed-price promise needs a documented pricing process and clear boundaries.

    Do not turn a rival’s review problem into an accusation. State the positive outcome your business can prove. Customers care about avoiding surprise costs; they do not need an ad that says another company hides fees. This keeps the message focused on the buyer and prevents an unverified competitor claim from becoming the center of your campaign.

    Turn a validated gap into one matched PPC test

    Two matched campaign pathways use equal budget tokens and funnels, with one colored message tile distinguishing the test version.

    The unit of action is not a clever headline. It is a matched chain from customer concern to operational proof:

    1. Signal: A concern repeats in relevant competitor reviews or appears unresolved in visible competitor messaging.
    2. Need: You translate the complaint into the outcome the searcher wants.
    3. Validated strength: Your business can deliver and document that outcome consistently.
    4. Ad promise: The message makes the strength concrete without overstating it.
    5. Landing-page proof: The destination explains how the promise works and what happens next.
    6. Business measure: The test is judged by qualified conversion or a deeper outcome, with cost and quality guardrails.

    The following examples show the translation. They are candidate directions, not claims you can adopt without verification.

    Complaint themeDesired outcomeCandidate headlineLanding-page proof
    Unexpected costsPrice certaintyPrice Set Before WorkExplain when the quote is issued, what it includes and how changes are approved
    Slow responseTime certaintyResponse Time Made ClearState the verified response process, covered hours and next contact
    Poor communicationProcess visibilityKnow What Happens NextShow the stages after submission and how status updates are delivered
    Complicated bookingLow-friction actionSimple Online BookingShow the actual booking steps, required information and confirmation process

    Each sample headline stays within the 30-character limit used for Responsive Search Ad headlines. Character compliance is only the mechanical requirement. A useful asset set also needs query relevance, the verified competitive message and a clear action or form of certainty. Filling every headline slot with slight keyword variations wastes the opportunity to answer a real concern.

    The landing page must finish the thought. If an ad promises pricing clarity, explain the pricing and approval process near the relevant conversion action. If it promises a response commitment, define when the clock starts and what the visitor will receive. If the value is better communication, show the next steps after form submission. A claim that disappears after the click creates a new uncertainty at the moment the visitor is deciding whether to trust you.

    Write a test card before launch. Include the audience and intent, hypothesis, isolated change, operational evidence, destination-page change, primary business outcome, quality guardrails and stopping rule. Keep the comparison as controlled as the account allows. Do not compare click-through rates from campaigns with different query mixes and call the result proof of a better message.

    Choose the closest dependable downstream measure. Click-through rate can show that wording attracted attention, but a complaint-based message may also attract people who are unusually sensitive to price, urgency or service conditions. Watch qualified conversion, sales acceptance, cancellations, refunds or contribution where those signals are available. A test that wins clicks while reducing lead quality has not established a competitive advantage.

    Use peer benchmarks as a question, never a budget target

    Google Ads may display a Spend Benchmarks report in the account Overview. It compares weekly spend and clicks with a peer group informed by industry and where the advertiser runs ads. That can add useful context, but context is the correct limit of the feature.

    Being below the peer spend does not establish underinvestment. Being above it does not establish waste. A lower-spend account may have a narrower market, stricter profit requirements, limited operating capacity or a different growth objective. A higher-click account may be buying cheaper traffic, not better customers. Neither comparison reveals conversion quality or incremental profit.

    Treat an unexpected benchmark as a diagnostic prompt:

    • Is the campaign currently acquiring the right conversion at an acceptable marginal cost?
    • Would additional spend reach more of the same valuable demand, or force the account into weaker traffic?
    • Can sales and operations serve more volume without slower response or lower quality?
    • Does the budget difference reflect a deliberate scope choice, such as a narrower offer or market?
    • Would the additional spend advance the current business objective rather than merely increase clicks?

    Pay particular attention to marginal returns. An account’s average acquisition cost describes the spend already deployed; it does not guarantee that the next block of budget will perform at that average. Increase spend only when your own demand, capacity and profit evidence supports the next increment.

    The benchmark may also appear beside recommendations to spend more for additional results. Keep those two messages separate. A comparison can reveal a difference. It cannot decide whether closing that difference is economically sensible for your business.

    Key takeaways

    • Begin with a defined PPC decision, success measure and economic guardrails.
    • Separate observations from interpretations and testable hypotheses.
    • Use competitor reviews to identify desired customer outcomes, not to write attacks on competitors.
    • Advertise a market gap only after your operations can prove the corresponding promise.
    • Carry the same promise from the ad into the landing page and service process.
    • Use peer spending as context for investigation, not as a target or permission to raise the budget.

    Choose the next material campaign decision and create one evidence row for each part of it: a visible competitor message, a recurring customer concern and a verified strength inside your business. If those signals align, build one matched ad-and-page test. If they do not, leave the budget and promise unchanged. Declining to act on weak evidence is part of good competitive intelligence.

    References


  • Google Ads Automation: How to Keep Advertiser Control

    Google Ads Automation: How to Keep Advertiser Control

    Your Google Ads campaign can hit its reported target and still make a decision you would never approve. It can enter a competitor bidding war, learn from queries you already know are irrelevant, favor sales with weak margins, or expand into inventory you did not intend to buy.

    You do not need to rebuild every campaign around manual bidding or revive an account full of single-keyword ad groups. You need a control system: clear business objectives, enough consolidated data for automation to learn, explicit boundaries on where it may explore, and a verification loop that catches strategically wrong behavior before it becomes expensive.

    Key takeaways

    • Automate execution inside boundaries you define. Google Ads can optimize an objective, but it cannot infer every commercial constraint behind that objective.
    • Consolidate campaigns when fragmentation deprives Smart Bidding of conversion data. Split them only when the parts genuinely require different economics, budgets, policies, or market strategies.
    • As a working benchmark rather than a universal platform rule, look for at least 30 monthly conversions per campaign, with 60 or more providing a stronger foundation for consistent automated bidding.
    • Configure negative keywords, brand controls, network settings, and reporting before enabling wider expansion. Do not pay an algorithm to relearn exclusions your business already knows.
    • Inspect search terms, match sources, networks, brand exposure, conversion quality, and profitability from the start. A strong top-line ROAS does not prove that the underlying traffic is acceptable.
    • After a material change, respect conversion lag. Google has advised waiting one to two conversion cycles before drawing conclusions, unless a hard budget or policy boundary is already being breached.

    Define what automation is allowed to decide

    Advertiser control no longer means making every auction decision yourself. It means retaining ownership of the decisions that shape those auctions.

    Google Ads can observe signals, predict the likelihood of a conversion, adjust bids, and expand targeting. It cannot automatically know that a particular competitor must be avoided, that returned orders erase the apparent profit from a product category, or that your sales team cannot handle another wave of low-value leads. Those are business facts, not auction facts.

    The distinction matters because the platform’s definition of success is not automatically the advertiser’s definition. Google benefits when advertisers spend money. You benefit when additional spend produces acceptable incremental business outcomes. Those interests can overlap without being identical.

    Write an automation contract for each campaign

    Before changing a bidding strategy or enabling AI-driven expansion, write down the following decisions in plain language:

    1. Business objective: Name the result the campaign is supposed to produce. Do not substitute ad position, traffic volume, or spend for a business result.
    2. Economic target: Record the CPA, ROAS, margin, or other threshold the business actually uses. If different products have different economics, state how those differences will be represented.
    3. Permitted expansion: Specify whether the system may explore broad queries, competitor searches, Search Partners, new geographic areas, or additional channels.
    4. Prohibited behavior: List the queries, brands, locations, offers, audiences, and traffic sources that are unacceptable even if their reported conversion performance appears strong.
    5. Conversion definition: Identify which recorded actions represent real value. Separate primary outcomes from actions that are useful for observation but should not steer bidding.
    6. Evidence required: Name the reports you will inspect to verify search terms, match sources, networks, conversion quality, and economic performance.
    7. Intervention rule: Define the conditions that require a pause, exclusion, target adjustment, or deeper review. Use thresholds approved by your business rather than inventing them after spend accelerates.

    This contract prevents a common mistake: evaluating automation only by the metric it was instructed to optimize. If a campaign reaches target ROAS by entering strategically unwanted auctions, the bidding system may have completed its assignment perfectly. The assignment was incomplete.

    Treat every platform recommendation as a hypothesis about execution. Ask which part of your contract it supports, which new permissions it requires, and where its effect will be visible. If you cannot answer those questions, investigate before applying it.

    Consolidate learning without flattening business differences

    Distinct colored data streams pass through a shared learning engine and continue as separate coordinated lanes.

    The old response to uncertainty was often more structure: single-keyword ad groups, duplicated match types, traffic-sculpting negatives, and numerous narrowly defined campaigns. Much of that tactical granularity has become unnecessary under automated bidding and matching.

    Excessive structure now creates a different risk. Every additional campaign divides the available conversion history. Automated bidding then has fewer observations from which to estimate performance, while each segment receives a smaller share of the account’s traffic and budget.

    A useful working benchmark – not a guarantee and not a reason to ignore your own variance – is at least 30 conversions per campaign each month, ideally 60 or more, for Smart Bidding to operate consistently. Before creating a split, estimate how much recent conversion volume each resulting campaign would retain. If one side would fall well below that range, the business reason for separating it needs to outweigh the loss of learning density.

    Use a business test for every proposed split

    Create a separate campaign when at least one of these conditions is true:

    • The segment needs a genuinely different CPA, ROAS, or profit target.
    • Its budget must be protected or capped independently for a clear commercial reason.
    • Its geography, availability, compliance requirements, or operating capacity differs from the rest of the account.
    • Its brand, competitor, query, network, or channel policy must be different.
    • The business intends to make a distinct investment decision about that segment and cannot obtain the necessary control through reporting, labels, or exclusions.

    Do not create a campaign merely because a reporting dimension exists. Reporting taxonomy and bidding structure are different tools. You can often preserve a consolidated learning pool while using labels and reports to analyze meaningful groups.

    Margin is a good example. An account divided into many narrow margin buckets, each carrying its own ROAS target, can look financially rigorous while fragmenting the data the bidding system needs. The resulting campaigns may be too small to achieve the targets that justified the structure.

    Instead, use custom labels for information such as margin, sell-through rate, and return rate. Labels do not magically convert profit into a bidding signal, but they let you organize products, inspect performance, and make campaign decisions with context Google does not inherently possess. If you later separate a segment, you can do so because the data reveals a material economic difference, not because a spreadsheet had another row available.

    Put guardrails in place before expansion starts

    A human operator inspects layered guardrails and checkpoints surrounding an expanding network of automated campaign paths.

    Automation should discover what you do not know. It should not spend your budget rediscovering what you already know.

    This is especially important when broad matching or AI-driven expansion can reach searches outside your initial keyword set. Broad match defaults have long created a situation in which inexperienced advertisers can pay to teach the system lessons their businesses could have supplied in advance. If a query category is known to be irrelevant, exclude it before launch rather than waiting for wasted clicks to prove the point.

    Configure the controls that correspond to the risk

    1. Query risk: Add negative keywords for known irrelevant intent. Review whether exclusions need to apply at the campaign or account level based on how broadly the rule should operate.
    2. Brand risk: Decide how your own brand, excluded brands, and competitor brands should be handled. AI Max provides brand inclusions and exclusions, but the advertiser still has to define the policy.
    3. Network risk: Decide whether Search Partner Network traffic is permitted. Set the available network control deliberately, then evaluate actual network performance rather than relying on a general assumption about where AI Max will expand.
    4. Economic risk: Make margin, returns, sell-through, and other meaningful product differences visible through your feed organization, labels, conversion values, reporting, or campaign design.
    5. Measurement risk: Confirm that the conversions guiding bidding represent outcomes the business values. A campaign cannot optimize toward profit if the recorded objective rewards a weak proxy for it.
    6. Visibility risk: Make sure the team knows where to inspect search terms, AI Max match type, match source, network delivery, and brand exposure before more traffic arrives.

    Competitor traffic shows why these controls cannot be reduced to a performance metric. In one documented rollout, AI Max expanded traffic by targeting a much larger competitor. The reported performance looked good, but the advertiser had intentionally avoided those searches to prevent a bidding war. The system found an opportunity inside the data while violating a strategy that had never been encoded.

    That is not an argument against AI Max. It is an argument for declaring competitor policy before enabling it and checking search terms from the first review. Strong aggregate results should increase your curiosity about where the gains came from, not end the investigation.

    Be equally careful with conclusions drawn from a small number of campaigns. Early AI Max observations appeared to show a preference for Search Partner traffic, but additional data did not support that as a general rule. Use account-level findings to form a testable question. Do not turn them into a platform-wide belief until the evidence warrants it.

    Verify patiently, then keep strategy human

    Good oversight separates two jobs that are often confused. Verification asks whether the system is doing what you authorized. Evaluation asks whether the result is good enough to continue. Verification starts immediately; evaluation may need to wait for conversions to mature.

    Inspect behavior in the right order

    Use this sequence when reviewing an automated campaign:

    1. Delivery: Check where spend occurred, including networks, locations, channels, and any other enabled expansion surface.
    2. Matching: Inspect search terms, match type, and match source. Identify which traffic came from your explicit targeting and which came from automation.
    3. Strategic fit: Look for prohibited brands, competitor auctions, irrelevant intent, or traffic that conflicts with your operating policy.
    4. Conversion quality: Determine whether the reported conversions represent qualified leads, completed sales, or another outcome the business can actually use.
    5. Economics: Review CPA or ROAS alongside the margin, returns, sell-through, capacity, and customer value information relevant to the decision.

    This order keeps a blended efficiency metric from concealing an unacceptable mechanism. If the campaign reaches its ROAS target through traffic your business has explicitly rejected, you have enough evidence to tighten the boundary even before the long-term average settles.

    Allow for conversion lag without tolerating a breach

    After a platform update or material campaign change, immediate performance claims are unreliable when conversions take time to arrive. Google has advised advertisers in this context to wait one to two conversion cycles before assessing the effect.

    That waiting period is not permission to ignore the account. Continue checking spend, query relevance, network delivery, and other hard boundaries. If automation exceeds an approved budget limit or enters prohibited traffic, intervene. If the guardrails hold but the efficiency metric fluctuates, let the relevant conversion window mature before declaring success or failure.

    Avoid defensive target changes made only because other advertisers appear worried. Advertisers have raised target ROAS even when their campaigns were not budget-limited, a reaction that can reduce participation without solving an identified problem. A stricter target may be appropriate, but changing it can materially reduce volume. Require an account-specific reason and preserve a baseline against which the effect can be judged.

    Keep a decision log, not just a change history

    For every material adjustment, record:

    • The date and exact setting changed.
    • The business problem the change is meant to solve.
    • The expected effect on traffic, conversions, CPA, ROAS, or profit.
    • The relevant conversion lag or evaluation window.
    • The reports that will confirm where the effect came from.
    • The hard boundary that would justify intervening early.
    • The final decision after enough data has accumulated.

    When possible, avoid stacking several material changes into the same evaluation window. If you alter the target, budget, network access, negatives, and campaign structure together, even a clear performance movement may not tell you which decision caused it.

    Apply the same skepticism to controls whose labels sound clearer than their mechanics. An emerging Performance Max control for channel importance may give Google greater tolerance around a CPA or ROAS target when a channel receives more importance. Do not assume that increasing importance simply buys more of a channel at unchanged economics. Document the intended outcome, monitor actual allocation and efficiency, and reverse the change if the observed tradeoff is unacceptable.

    Finally, do not confuse prominence with profit. Paying whatever it takes to hold the top ad position was an expensive mistake in earlier paid search, and position-driven bidding can sacrifice economics for prestige. Automation does not change that principle. Your objective should describe the business outcome you want, not the visible status you hope to occupy.

    Start with one automated campaign this week. Write its automation contract, remove any split that lacks a business reason, encode known exclusions, capture a baseline, and schedule the evaluation for the end of its relevant conversion window. You will have given the system room to find demand without giving it authority to redefine what your business considers a good customer, an acceptable auction, or a profitable result.

    References


  • How to Use Marketing Measurement Models for Budget Decisions

    How to Use Marketing Measurement Models for Budget Decisions

    Your marketing mix model recommends a major budget shift. The fit looks clean, the response curves look precise, and the proposed allocation has been reduced to one reassuring number. That still isn’t enough evidence to move the money.

    A defensible budget decision is one that survives different modeling assumptions, exposes the uncertainty that remains, and uses an experiment where getting the answer wrong would be expensive. Here is how to build that decision process without turning measurement into an endless modeling exercise.

    Key takeaways

    • Treat one marketing mix model as a first opinion, not a final budget verdict.
    • Run different model families against identical spend, outcome, and control data before tuning away their disagreements.
    • Judge recommendations by channel direction, ranking, response curves, and sensitivity to assumptions. Do not choose a winner from R-squared alone.
    • When models agree, you have a stronger basis for a staged budget move. When they disagree, investigate the cause before reallocating.
    • Use geo tests, holdouts, or on/off experiments to validate the channel decision with the most money or uncertainty attached to it.

    A clean model fit does not make the budget answer causal

    An MMM estimates how an outcome moved with marketing spend, seasonality, external controls, and an underlying baseline. It must also make assumptions about how quickly advertising takes effect, how long that effect persists, and where additional spending starts producing smaller returns.

    Those assumptions are not a technical footnote. They shape the budget recommendation:

    • Adstock and decay: These determine whether a channel’s effect disappears quickly or continues after the spend occurred. A short window can understate a slow-building channel; a long window can assign it more persistent influence.
    • Saturation: The response curve determines how quickly the model believes marginal returns decline. Move that point, and the recommended allocation can move with it.
    • Priors and regularization: Bayesian priors and ridge regularization constrain the effect sizes the model considers plausible. They are useful, but they also encode beliefs that should be visible to the decision-maker.
    • Seasonality and controls: Weak calendar or business controls can let a channel absorb demand that would have arrived anyway. Stronger controls may move that credit back to seasonality or the baseline.

    A high R-squared shows that a model reproduces historical movement well. It does not establish that the model divided causal credit correctly. Several models can fit the same history and still tell you to fund different channels.

    Before anyone approves a reallocation, attach a short model card to the recommendation. It should identify:

    • The business outcome being modeled and the budget decision it is meant to support.
    • The time period, data frequency, geographic level, channel definitions, and known tracking changes.
    • The spend, outcome, seasonal, promotional, pricing, distribution, and other control variables included.
    • The adstock ranges, saturation functions, priors, or regularization choices that materially affect the result.
    • The recommended direction for each channel, along with the range produced by reasonable alternative assumptions.
    • The unresolved question that would most benefit from an experiment.

    If you receive only an optimized allocation and a fit statistic, you do not yet have a decision packet. You have an output without its conditions.

    Build a measurement stack in which each method has one job

    A three-layer measurement system connects a broad market model, controlled test platforms, and compact diagnostic instruments.

    Attribution, MMM, and incrementality experiments answer related but different questions. Forcing one method to answer all of them creates false certainty.

    • Attribution supports operational reporting. It records which touchpoints received credit under a defined rule. That can help with campaign management, but assigned credit is not the same as incremental growth.
    • MMM supports portfolio planning. It estimates contributions across the channel mix, including investments that are difficult to test individually. It can be refreshed without running a new experiment for every channel, but its conclusions remain dependent on model structure and historical variation.
    • Experiments test causality more directly. A geographic lift, holdout, or on/off test creates planned variation and asks whether the selected investment caused additional outcomes. It usually covers a narrower question and costs more to run, which is why it should be reserved for consequential uncertainties.

    The useful loop is simple: the models rank hypotheses, an experiment tests the most important one, and the experimental result becomes evidence for the next model refresh. You do not need to test every channel every quarter. You do need to test the uncertainty capable of changing the decision.

    Your data foundation is a fourth layer. Inconsistent channel definitions, missing regions, broken conversion tracking, and poorly recorded promotions will contaminate every method above them. More sophisticated modeling cannot recover information the business never captured.

    Google’s announced measurement changes illustrate how these layers are becoming more connected. Data Manager is being extended into Google Analytics and Display & Video 360, while new Meridian capabilities are intended to audit data quality, troubleshoot modeling errors, incorporate branded query volume, and connect causal geo-experiments to MMM. These features may reduce setup friction and make upper-funnel signals easier to include. They do not make an estimate causal merely because an AI assistant helped construct it.

    In every budget meeting, label each claim as attributed, modeled, or experimentally validated. That one distinction prevents a dashboard metric, a model estimate, and a causal result from being discussed as if they carried equal weight.

    Run the same decision through more than one MMM

    A multi-model comparison is useful because different model families expose different assumptions. The goal is not to crown a universally superior tool. It is to learn whether the proposed decision is robust to reasonable changes in method.

    Three open-source options provide a practical panel of distinct approaches:

    ToolModeling approachWhere it is especially usefulWhat your team must be able to defend
    RobynRidge regression with evolutionary hyperparameter search; built in RA fast, accessible baseline for marketing teamsHyperparameter ranges, transformation choices, and the stability of the selected solution
    MeridianBayesian and geographically hierarchical; Python-nativeGeographic data, reach and frequency inputs, and upper-funnel effectsHow regional variation and prior choices support the estimates
    PyMC-MarketingFully Bayesian with customizable priors, structure, and indirect-effect paths; Python-nativeCases that need explicit control over assumptions and channel relationshipsEvery custom prior and structural choice; flexibility is not evidence by itself

    Robyn can remain the fast in-house baseline for an R-first team, while light Python workflows support Meridian and PyMC-Marketing. The expensive work is preparing trustworthy inputs. Once those inputs exist, the additional models can reuse them, so the marginal effort is much smaller than building the first model from scratch.

    Use this sequence:

    1. Write the decision before running the models. Name the outcome, the channels under consideration, the planning horizon, and what would qualify as a meaningful change. This prevents the team from turning an interesting coefficient into an unplanned budget recommendation.
    2. Freeze one shared input set. Give every model the same spend, outcome, controls, channel mapping, data window, geographic structure, and known tracking annotations. Otherwise you will be comparing datasets rather than models.
    3. Run defaults before extensive tuning. Default configurations reveal where model families naturally disagree. If you tune the first model until its story feels comfortable before running the second, you lose that diagnostic signal.
    4. Compare decision-relevant outputs. Record each channel’s recommended direction, relative rank, estimated contribution, response curve, and point at which diminishing returns become material. Treat fit statistics as hygiene checks rather than a scoreboard.
    5. Run targeted sensitivity checks. Change decay ranges, priors, saturation assumptions, and seasonal controls that could plausibly alter the decision. Document whether the channel’s direction remains stable.
    6. Classify the result. Mark the recommendation as convergent, sensitive, or divergent. Then attach an action, a guardrail, or an experiment to that classification.

    Do not average conflicting recommendations into one deceptively precise allocation. A mean can hide the fact that one model wants a channel increased while another wants it cut. Keep the range, direction, and reason for disagreement visible.

    Agreement across model families is evidence of robustness, not proof of causality. Every model can still inherit the same missing variable, tracking break, or flat spend history. That is why experiments and data audits remain part of the stack.

    Turn model disagreement into the next measurement action

    An analyst compares different allocations from three model machines and directs the unresolved decision toward a controlled experiment chamber.

    What consequential disagreement looks like

    In one synthetic direct-to-consumer example using 2.5 years of weekly data and roughly $1.5 million in monthly spend, three models assigned sharply different contribution shares to the same four channels:

    ChannelRobynMeridianPyMC-Marketing
    Paid search41%22%19%
    Meta24%31%18%
    Google Shopping11%9%22%
    TV3%14%16%

    The practical conflict is not a minor difference in decimal places. One result makes paid search look dominant, another gives Meta the lead, and a third puts Google Shopping ahead of paid search and Meta. Selecting the cleanest chart would conceal the decision risk.

    Match the disagreement to its likely cause

    • Two channels rise and fall together: This is channel collinearity. Historical observation cannot reliably identify which channel deserves the split, so different models allocate the credit differently. Run a holdout, geo test, or planned variation that separates the channels.
    • A channel always increases during peak demand: This is a seasonal confound. Strengthen the calendar and business controls, then rerun the comparison. If the channel’s contribution collapses, do not fund it on the assumption that it created demand the calendar can explain.
    • A channel has been always on at nearly the same spend: The history contains too little variation to reveal its response curve. The model is extrapolating saturation from its chosen functional form. Introduce deliberate spend variation within financial and brand-safety guardrails.
    • A channel matters only under a long decay window: The result is adstock-sensitive. Label it that way, compare plausible windows, and make the measurement period long enough to observe a delayed effect. Do not present the long-window estimate as established incrementality.
    • Disagreement is concentrated in one region or period: Audit tracking, channel mapping, conversion definitions, and missing data there before changing spend. Localized divergence can reveal a data break that aggregate reporting hides.

    Prioritize the next test by the amount of budget exposed, the width and direction of the disagreement, how difficult the decision would be to reverse, and whether an experiment can actually distinguish the competing explanations. A cheap test of an immaterial uncertainty should not outrank a feasible test capable of preventing a major misallocation.

    Use a budget gate instead of a model winner

    • Act with guardrails: Different model families recommend the same direction and a relevant experiment supports the incremental effect. Make the approved move, monitor the business outcome, and use the experimental result as a prior in the next refresh.
    • Stage the move: Models agree on direction, but no experiment has validated the channel. Implement the recommendation in reversible stages rather than moving the entire proposed amount at once.
    • Test before reallocating: Models disagree on direction, their response curves imply materially different decisions, or sensitivity checks reverse the recommendation. Preserve the current allocation where practical and run the test most likely to resolve the conflict.
    • Pause for data repair: Tracking breaks, missing controls, or inconsistent definitions explain the divergence. Fix and verify the inputs before asking the models for another recommendation.

    Record the approved change, owner, start date, expected business outcome, monitoring signals, stop condition, and next review point before spend moves. This matters because an unchecked model-driven misallocation can grow into six- or seven-figure exposure before the error becomes obvious. If a change would be expensive or slow to reverse, staging it is the safer decision.

    At your next budget review, do not ask for one optimized allocation. Ask for the recommendation range across model families, the assumptions capable of reversing it, and the single experiment that would reduce the most consequential uncertainty. That turns MMM from a persuasive chart into a repeatable decision system.

    References


  • How to Turn SEO and PPC Data Into One Search Strategy

    How to Turn SEO and PPC Data Into One Search Strategy

    Your SEO report can be green. Your PPC report can be green. The business can still be paying for coverage it already has, neglecting queries that reliably generate customers, and publishing two pages for the same search intent.

    You do not need to merge the teams to fix this. You need a shared decision system: one view of query demand, organic visibility, paid performance, landing pages, and the next action the business will take.

    Measure the search portfolio, not two scorecards

    SEO and PPC are different disciplines. They use different tools, operate on different timelines, and are commonly assessed with different measures: rankings and organic traffic for SEO, and cost per click, conversion rate, and return on ad spend for PPC. Specialization is useful. Isolated decisions are not.

    If each team optimizes only its own scorecard, neither team has to answer the questions that determine whether search is working efficiently for the business:

    • Where are you paying for clicks while an organic result already has strong visibility?
    • Which paid queries convert but have little or no useful organic coverage?
    • Where are rising click costs and weakening paid returns changing the case for organic investment?
    • Which near-ranking organic pages could reduce dependence on increasingly expensive ads if improved?
    • Are paid and organic results giving the same searcher conflicting promises or next steps?
    • Are two landing pages competing for the same intent because each channel commissioned its own URL?

    Answer these questions at the query-cluster level, not with channel-wide averages. An account can have an acceptable overall return while wasting money on a particular cluster. A site can have growing organic traffic while remaining almost invisible for its most commercially useful searches.

    The working unit should therefore be a query or a tightly related intent cluster. Every important cluster needs one coordinated decision: maintain paid and organic coverage, test whether one can carry more of the load, improve an existing page, create a missing resource, or resolve conflicting destinations.

    Build one query-and-intent ledger

    Two analysts arrange organic and paid search tiles into one color-coded grid on a table.

    Shared keyword research is the foundation. SEO contributes the longer view of recurring demand, existing visibility, and content gaps. PPC contributes current commercial evidence: what attracts paid traffic, what converts, and where the economics are changing. Starting from one keyword set instead of two channel-specific lists makes the handoff possible.

    Turn that research into a query-and-intent ledger. This does not have to be a new platform. A shared sheet is enough if it contains the fields needed to make decisions.

    FieldPrimary inputDecision it supports
    Query or intent clusterSEO and PPCCreates one common unit of analysis
    Searcher intent and desired actionSEO and PPCPrevents unlike queries from being combined merely because their words overlap
    Organic URL and visibilitySEOShows where the site already has coverage and where it has a gap
    Paid keyword or search term, ad group, and landing URLPPCConnects spend and outcomes to the page receiving the traffic
    Paid cost, conversion rate, and returnPPCIdentifies commercially useful demand and deteriorating economics
    Page decisionSEO, PPC, and contentRecords whether to reuse, improve, consolidate, or build
    Next action, owner, and review pointSharedTurns an observation into accountable work

    Build the ledger in a deliberate order:

    1. Begin with clusters tied to material paid spend, conversions, leads, revenue, or an active organic priority. Do not wait to catalog every query before making the first decision.
    2. Group queries by the job the searcher is trying to complete. Similar wording does not always mean identical intent.
    3. Attach every live organic and paid landing page serving that intent. This exposes duplicate destinations immediately.
    4. Add the channel evidence without collapsing it into a single vanity score. Rank, spend, conversion rate, and return answer different questions.
    5. Record one next action for each priority cluster. If the row has data but no decision, the ledger is only another report.

    Keep raw channel exports available for specialists, but make the ledger the place where cross-channel choices are recorded. That distinction matters. PPC still needs bid-level detail, and SEO still needs page and query diagnostics. The shared layer exists to decide what the whole search program should do next.

    Turn each channel’s signals into the other’s work queue

    Use paid performance to prioritize organic work

    A keyword with attractive search volume is not automatically a valuable content target. Paid conversion data adds commercial evidence. When a query repeatedly produces useful outcomes through PPC but organic visibility is limited, it belongs in the SEO opportunity queue.

    That does not always mean creating a new page. First ask whether an existing page is close to ranking and can be improved. A page that already addresses the intent may need clearer coverage, a stronger connection to the conversion path, or better internal support. Creating another URL can divide the signals that should be helping the existing one.

    Rising cost per click and falling paid return create another useful trigger. They show that the query is becoming more expensive to acquire through paid search, so the business should examine whether new organic content or improvements to a near-ranking page deserve priority. Do not treat this as an instruction to shut off paid coverage immediately. Treat it as a reason to compare the cost of continued dependence with the case for building durable organic visibility.

    Keep the interpretation honest. Paid conversion performance reflects an ad, an offer, a landing page, and a paid placement working together. It proves commercial usefulness in that context. It does not prove that a copied landing page will rank, that every variation of the query has the same intent, or that organic traffic will convert at the same rate.

    Use organic visibility to focus paid coverage

    The organic view gives PPC a coverage map. Where useful organic visibility is weak, paid search can maintain access to demand while the organic team builds or improves the right destination. Where organic visibility is already strong, paid overlap deserves an incrementality review rather than an automatic renewal.

    Share more than a list of current rankings. PPC needs to know which URL ranks, whether it satisfies the commercial intent, and whether the position is dependable enough to test a budget change. A high-ranking informational page and a paid promotional page may technically appear for the same phrase while doing different jobs. In that case, removing the ad simply because an organic result exists could leave the commercial need uncovered.

    For each cluster, distinguish among three conditions: organic coverage that fulfills the intended action, organic visibility that reaches the query but serves a different intent, and no meaningful organic coverage. That classification is more useful to the PPC team than rank alone.

    Coordinate budget changes and landing pages before launch

    Three marketing specialists coordinate budget tokens and a blank landing-page wireframe before launch.

    Test paid-organic overlap before cutting spend

    An organic result in position one creates a reasonable case for reviewing the corresponding paid spend. It does not, by itself, prove that the ad contributes nothing. The decision should depend on what happens to total search outcomes when paid coverage changes.

    1. Select a query cluster with strong organic coverage and enough paid activity to make the decision consequential.
    2. Record a baseline for combined search outcomes: total clicks, qualified leads or conversions, revenue where applicable, and paid cost. Keep the channel breakdown, but judge the decision at the combined level.
    3. Reduce or pause the relevant paid coverage in a controlled way. Change as little else as possible and preserve a clear rollback path.
    4. Compare the combined outcome across a representative period. Do not compare periods with materially different demand, offers, or landing pages and then attribute the difference to the ad change.
    5. Keep the reduction if organic traffic preserves the business outcome efficiently. Restore coverage if the total result deteriorates. Redirect validated savings toward clusters where paid or organic visibility is genuinely missing.

    This test protects you from two opposite mistakes: paying indefinitely because PPC performs well in isolation, or removing productive coverage because SEO owns a visually prominent position. The goal is not to make one channel win. It is to buy the right amount of search coverage.

    Put every new landing page through a shared release gate

    A campaign deadline often makes a new page feel like the fastest option. It can become the slowest option after launch if SEO later discovers another URL aimed at the same intent and has to investigate cannibalization, canonicalization, or index control.

    Before a paid landing page is approved, require clear answers to these questions:

    • Does an existing page already serve this intent?
    • Could that page be improved to support both channels without weakening either experience?
    • If a separate campaign page is necessary, which URL should be the organic destination?
    • Should the campaign page be indexable, or does it need an agreed canonical or noindex treatment?
    • Who owns the decision, and has it been recorded before development begins?
    • Do the ad, organic result, and landing experience make compatible promises to the same searcher?

    Duplicate landing pages can split authority and leave search engines uncertain about which URL should rank. Canonical and noindex controls can be appropriate, but they are not substitutes for deciding the role of each page before publication.

    Message alignment deserves the same gate. For every shared intent cluster, write down the searcher’s task, the promise made in the ad, the promise made by the organic result, the destination, and the next action. The language does not have to be identical. The journey does have to make sense. An educational organic result and a promotional ad can coexist when each clearly serves its intended stage; conflict begins when they appear to answer the same need but send the visitor toward incompatible expectations.

    Create a monthly decision cadence that survives the meeting

    Put SEO and PPC on the same monthly search call. The value is not the meeting itself. The value is that both teams hear the same commercial priorities, campaign changes, and page plans before those changes become cleanup work.

    Each team should arrive with a short exception list rather than reading its full report aloud. PPC should bring converting query clusters, meaningful shifts in cost or return, planned campaigns, and requested landing pages. SEO should bring visibility gains and losses, commercially relevant gaps, pages close to stronger positions, and any new or competing URLs detected. Content or web owners should bring the active page queue.

    Use the meeting to make decisions in this order:

    1. Confirm which query clusters have changed enough to require action.
    2. Choose whether paid coverage should be maintained, tested, expanded, or reduced.
    3. Choose whether organic work should improve an existing page, fill a genuine gap, or wait.
    4. Approve, redirect, or stop proposed landing pages before they enter production.
    5. Resolve message conflicts across ads, organic results, and destination pages.
    6. Record the owner, action, review point, and business signal that will determine whether the decision worked.

    A decision log is what makes the cadence durable. Without it, the same overlap gets discussed repeatedly and channel teams return to their separate queues. With it, the next meeting starts by checking outcomes: what changed, whether the combined search result improved, and what should happen next.

    Key takeaways

    • SEO and PPC reports are inputs to a search strategy, not substitutes for one.
    • Use a shared query-and-intent ledger to connect organic visibility, paid economics, landing pages, and accountable actions.
    • Send proven paid demand and deteriorating paid economics into the SEO priority queue.
    • Use organic coverage to identify paid gaps and overlap tests, but do not cut ads on rank alone.
    • Review every campaign landing page before launch so one intent does not acquire competing URLs by accident.
    • Judge major changes by combined search outcomes, then record the decision and its next review point.

    Start with one commercially important query cluster this week. Put its SEO and PPC evidence in one row, map every page serving it, and make one joint decision. Once that process works, expand it to the next cluster instead of attempting a perfect all-account integration before anyone acts.

    References