Category: PPC

  • Google Ads Campaign Mistakes That Undermine Your Results

    Google Ads Campaign Mistakes That Undermine Your Results

    You can make a Google Ads account look more polished while making its decisions less reliable. Raise Ad Strength, accept recommendations, expand match types, and adjust bids, and you may still have no trustworthy answer to the question that matters: are the campaigns producing valuable business outcomes?

    If performance has become difficult to explain, resist the urge to rewrite everything at once. Audit the account in this order: measurement, search-term routing, campaign settings, and automation. That sequence protects the signal you need to decide what should change next.

    Fix measurement before tuning bids or targeting
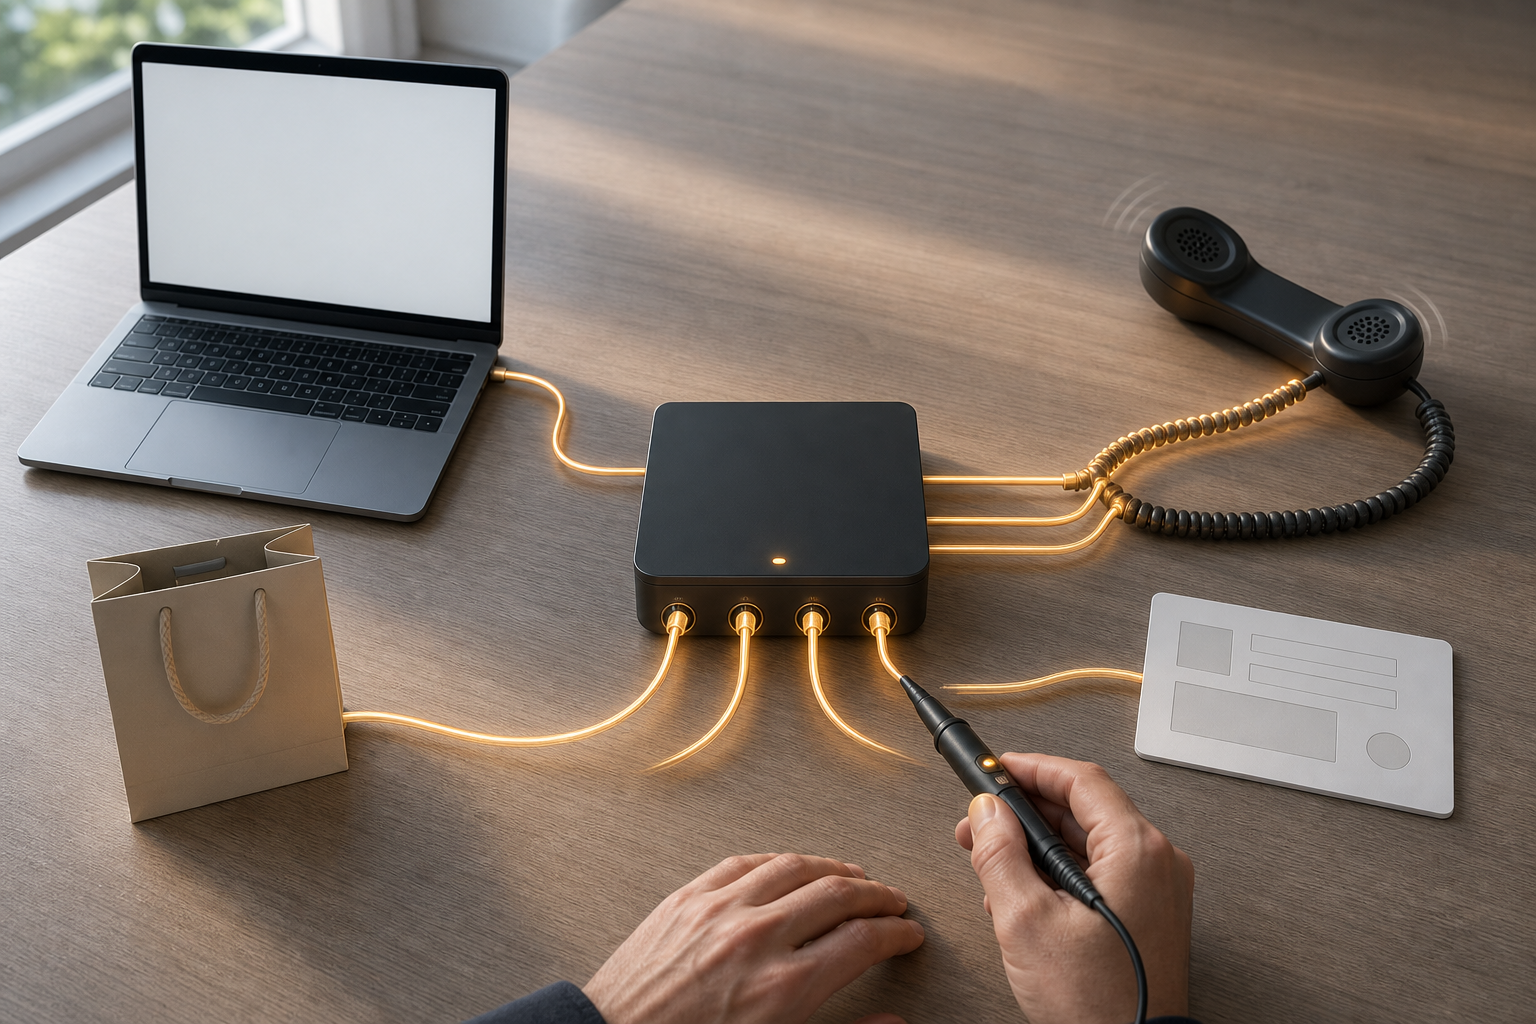
    A specialist traces cables from a laptop, shopping bag, phone, and blank form to a measurement hub with one duplicate and one disconnected signal.

    Google Ads optimization inherits whatever definition of success you give it. If that definition changes from one campaign to another, the account can look internally consistent while comparing unlike outcomes.

    The common fault lines are attribution methods, count settings, conversion windows, and campaign-level overrides. Two campaigns may generate the same kind of customer action yet value the associated clicks differently because their conversion configurations differ. More traffic cannot solve that problem. It only produces more data under incompatible definitions.

    Create a conversion contract for the account

    A conversion contract is a simple record of what the account considers success. It does not need to be a complex measurement document. It needs to answer the same questions for every campaign you intend to compare:

    1. What real business event does this conversion action represent?
    2. Is the action used by bidding, or is it retained only for observation?
    3. Which attribution method assigns credit?
    4. Which count setting is used?
    5. How long is the conversion window?
    6. Does the campaign inherit the account configuration, or does it override it?
    7. If there is an override, what business reason requires it?

    Consistency does not mean forcing every conversion action into one configuration. A purchase, a qualified lead, and an informational interaction are different events. The goal is to measure the same event the same way wherever it appears and to document intentional exceptions.

    Campaign-level overrides deserve special attention because they can make one campaign accurate in isolation while weakening account-level comparisons. If an override no longer has a clear owner and rationale, treat it as configuration drift rather than strategy.

    Changing conversion settings can alter the signals used by automated bidding and therefore affect spend. Record the date and reason for each correction. Avoid changing conversion definitions, bid strategy, and keyword scope at the same time. When several inputs move together, you cannot tell which change produced the next result.

    Rebuild query control around real search terms
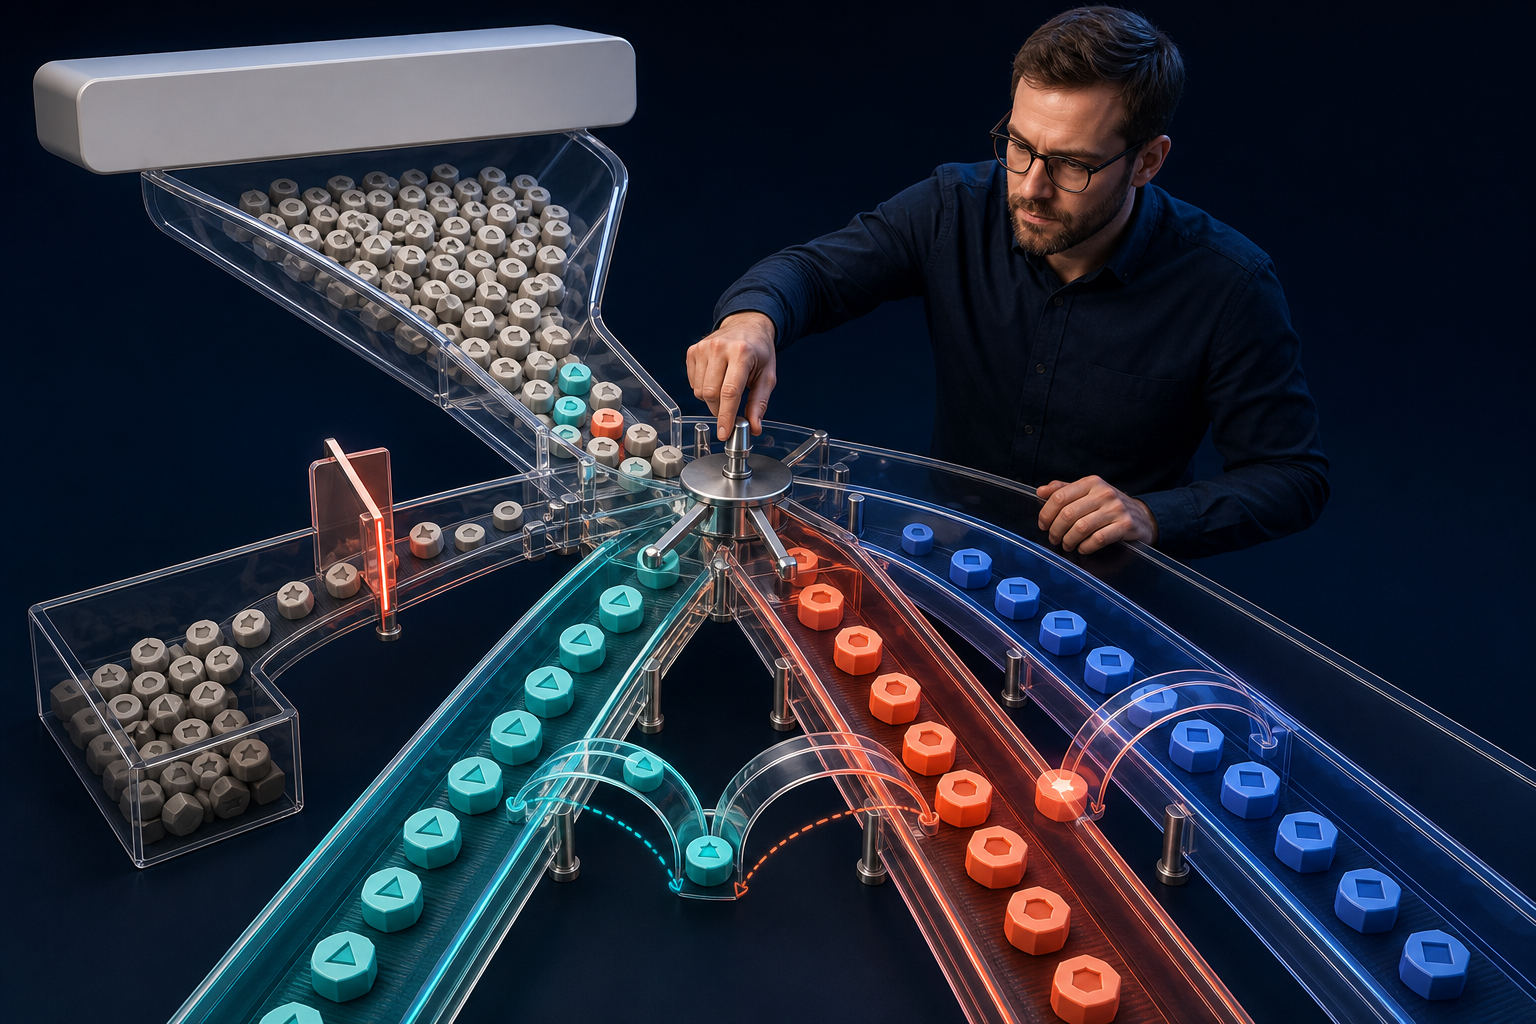
    An analyst sorts abstract search-query tokens into separate campaign channels and diverts irrelevant tokens through a side gate.

    Keywords are planning inputs. Search terms show the language people actually used. When the two diverge, the account can send valuable intent to inconsistent ads, bids, or landing pages.

    Do not abandon exact match because broad match is prominent

    The interface may encourage broad match, but that does not make exact match obsolete. Exact match can still be the highest-converting match type in an account. That is not a guarantee for every advertiser; it is a reason to preserve exact coverage where the account has already identified valuable intent.

    Start with the search-term report, not a speculative keyword expansion. Find terms that repeatedly produce the business outcome you care about. Then ask three questions:

    • Does the term have an exact-match keyword in the account?
    • Is that keyword located with the ad message and landing page best suited to the intent?
    • Does the term appear under several keywords or campaigns, producing different user experiences?

    If a proven term has no clear home, add exact-match coverage in the most relevant campaign or ad group. The aim is not to promise perfect routing. It is to give valuable intent a deliberate destination with a suitable message, bid context, and landing page.

    Find search terms that wander between keywords

    Looser matching can allow one search term to trigger multiple keywords. That duplication matters when those keywords sit behind different offers or messages. A person can express the same intent twice and receive two materially different paths through the account.

    Group repeated search terms by intent and identify the keyword, campaign, ad message, and landing page associated with each appearance. Choose a preferred destination for every important intent. Add exact coverage there and correct the surrounding message. Use negative keywords to prevent overlap only after checking the possible effects, because an overly broad negative can block demand beyond the conflict you intended to resolve.

    Evaluate broad match and bidding as one decision

    Broad match does not have one fixed performance profile. Its results depend partly on the bid strategy and on the conversion data supplied to that strategy. This is why broadening keyword eligibility before fixing tracking is especially risky: the system receives more freedom while pursuing an unreliable goal.

    Before expanding a keyword, write down the campaign objective, the bid strategy, the conversion actions informing it, and the search intents you are willing to buy. If any of those answers is unclear, the match-type change is premature. When you do test broader eligibility, keep the bidding and measurement definitions stable so the result remains interpretable.

    Treat negative keywords as living controls

    A negative keyword list captures an old decision. Products change, positioning changes, search behavior changes, and campaigns are reorganized. A list that was sensible when created can later block relevant searches and remove opportunities.

    Audit shared lists and campaign-specific negatives together. Classify each negative into one of three groups: always irrelevant, relevant only to an older campaign structure, or uncertain. Keep the first group, investigate the second, and compare the third against current keyword themes and converting search terms.

    Do not delete a large negative list merely because it is old. Removing negatives can immediately admit new traffic and increase cost. Correct confirmed conflicts in controlled batches, then inspect the resulting search terms before opening more traffic.

    Standardize campaign settings before comparing performance

    Campaigns sometimes need different settings. A regional campaign may require a unique location boundary, and a campaign tied to staffed sales hours may require a different schedule. The mistake is not variation. The mistake is unexplained variation that gets mistaken for performance.

    Build a settings matrix with campaigns as columns and the following controls as rows. The matrix makes invisible configuration differences easy to inspect:

    ControlWhat to compareDecision to record
    Conversion configurationActions used for optimization, attribution method, count setting, window, and overridesWhich campaigns should share the same definition of success?
    LocationsIncluded and excluded regionsWhich geographic differences are required by the offer?
    Ad schedulesDays and periods when ads can serveIs each restriction operationally necessary?
    Bid strategiesThe objective pursued by each campaignDoes the strategy match the campaign goal and available conversion signal?
    Keyword controlsMatch-type mix and exact coverage for proven termsWhich search intents should have a deliberate home?
    Negative listsShared and campaign-specific exclusionsWhich exclusions are permanent, contextual, or obsolete?
    AutomationRecommendation auto-apply status and allowed changesWhich changes require human approval?

    Review each difference as either intentional or accidental. An intentional difference gets a short rationale and an owner. An accidental difference gets corrected in a controlled change. If nobody can explain why one campaign excludes a region, runs a different schedule, or uses a different bid strategy, do not assume the setting is harmless.

    This matrix also prevents a common analytical error: crediting ads or keywords for a result created by campaign configuration. A campaign with wider geography, longer serving hours, or different conversion rules is not a clean comparison with its neighbors.

    Put interface scores and automation behind approval gates

    Google Ads can recommend an action, score an ad, and execute certain changes automatically. None of those mechanisms knows whether the change respects your commercial constraints unless those constraints are represented in the account’s data and settings.

    Ad Strength is a diagnostic, not the business objective

    A lower Ad Strength rating can reflect a deliberate decision to limit how ad content is combined. It can also coexist with stronger conversion performance. That relationship is not universal, but it is enough to reject the idea that maximizing the interface score should override measured outcomes.

    Before adding assets to improve the rating, identify what the existing constraints protect. They may preserve a required promise, keep a qualifier attached to an offer, or maintain alignment with the landing page. If a proposed variation weakens that connection, a higher score does not make it a better ad.

    Evaluate ads with the conversion action that represents the campaign’s goal. Use Ad Strength to notice possible limitations, then decide whether those limitations are intentional. Do not use it as a substitute for conversion quality or commercial value.

    Disable unattended changes that alter strategy

    Recommendation auto-apply can introduce changes such as adding keywords or modifying bid strategies. Those are not cosmetic edits. They can change which searches become eligible, how aggressively the account bids, and how budget is distributed.

    Review the account’s auto-apply status and turn off unattended changes that alter keyword scope, bidding, or other strategic controls. Recommendations can remain inputs to a review process. They should not bypass it.

    Apply the same standard to AI-generated recommendations. Automation works from the objectives and data it receives. If the conversion definition rewards low-value actions, the system can become efficient at producing the wrong result. If a stale negative list hides valuable demand, automation cannot optimize traffic it is never allowed to see.

    Require a short change brief before approving an automated recommendation:

    1. What account setting or campaign element will change?
    2. Which business outcome is the change expected to improve?
    3. Does it alter the definition of a conversion, query eligibility, bidding, or message control?
    4. Which result will show that the change helped?
    5. What condition would justify reversing it?

    If the recommendation cannot survive those questions, it is not ready to run. AI is useful for generating possibilities and finding patterns. Judgment is still required to decide which objective deserves optimization and which constraints should remain.

    Key takeaways: audit the account in a safe order

    • Align attribution methods, count settings, conversion windows, and campaign overrides before trusting comparisons.
    • Document the business event behind every conversion action used for bidding.
    • Add exact-match coverage for proven search terms that lack a deliberate destination.
    • Investigate valuable search terms that move between keywords, campaigns, messages, or landing pages.
    • Evaluate broad match together with its bid strategy and conversion signal.
    • Review negative keyword lists for conflicts before expanding traffic or removing exclusions.
    • Explain differences in locations, schedules, bid strategies, and other campaign settings.
    • Judge ads by relevant outcomes, not Ad Strength alone.
    • Turn off unattended strategic changes and require an approval brief for automated recommendations.
    • Change one decision layer at a time so the next result remains interpretable.

    Open the account and build the conversion and settings matrix before touching bids, budgets, or creative. Make the smallest correction that restores consistency, record it, and let the resulting signal determine the next move. That is slower than accepting every prompt in the interface, but it gives you something far more useful: an account whose results you can explain.
    References

  • How to Build a Year-End PPC Report Leadership Can Use

    How to Build a Year-End PPC Report Leadership Can Use

    Your year-end PPC report has to answer a harder question than what happened. Leadership wants to know whether paid media created enough business value, what changed that value, and which decisions the evidence supports for the coming year.

    If your deck looks like a stack of monthly reports, the important story will disappear inside campaign detail. A year-end review has a different audience and a broader strategic purpose than a routine performance check-in. Treat it as a decision brief supported by analysis, not an archive of everything the account did.

    Define the audience and the decision before opening a dashboard

    Leadership is not one audience. A finance leader may care about efficiency, risk, and the reliability of attributed revenue. A sales leader may care about qualified lead volume and pipeline contribution. A chief executive may want to know whether paid media can support the company’s growth plan. The same campaign data has to be organized differently for each decision.

    If you do not know who will receive the report, ask your primary stakeholder before building it. Get direct answers to these questions:

    • Who will read the report, attend the presentation, or approve the resulting plan?
    • What decision should they be able to make after reading it?
    • Which business outcome do they consider the clearest definition of success: revenue, qualified leads, completed conversions, or another agreed outcome?
    • Which target, commitment, or concern is already on their mind?
    • Where will they expect detail, and what can safely move to an appendix?

    Turn those answers into a reporting brief written as a single sentence: this report is for [audience], who need to decide [decision], using [business outcome], within [commercial or operational constraint]. That sentence becomes an editing rule. A chart belongs in the main report only if it helps the audience understand the outcome, evaluate a cause, assess a risk, or make the named decision.

    Tailor the depth, not the facts. Executives should see the same definitions, totals, and conclusions as the channel team. Put the concise decision narrative in the main report and retain campaign tables, test logs, query detail, and methodology in an appendix. This gives detail-oriented stakeholders somewhere to verify the work without forcing everyone else through it.

    Build the executive summary around business outcomes

    Draft the executive summary before assembling the full deck, then rewrite it after the analysis is complete. The early draft forces you to decide what the report is trying to prove. The final rewrite removes claims the detailed evidence did not support.

    A useful summary follows a clear sequence:

    • Outcome: State the investment and the primary business result.
    • Context: Show how that result compared with the agreed target, the prior year, and any relevant external benchmark.
    • Drivers: Name the few factors that materially changed the outcome.
    • Risk: Surface the largest weakness, uncertainty, or measurement limitation.
    • Decision: State the recommendation and the approval, tradeoff, or direction leadership needs to provide.

    You can use this fill-in structure to test the summary: paid media produced [business result] from [investment], finishing [above or below target] and [up or down year over year]. The main drivers were [drivers]. The largest constraint or uncertainty was [risk]. We recommend [action], and leadership needs to decide [decision].

    Separate outcome, efficiency, scale, and diagnostic metrics

    Metric overload usually starts when every measure is treated as equally important. Give each metric a job instead:

    Metric layerTypical measuresQuestion it answers
    Business outcomeRevenue, qualified leads, completed conversionsWhat value did paid media create?
    EfficiencyReturn on ad spend, cost per acquisition, cost per qualified leadWhat did that value cost?
    ScaleSpend and total outcome volumeHow much did the program produce at the achieved efficiency?
    DiagnosticClick-through rate, cost per click, impression share, conversion rateWhy did an outcome or efficiency measure move?

    Lead with the business outcome. Use efficiency and scale to describe the tradeoff behind it. Bring a diagnostic metric into the summary only when it explains a material change. A higher click-through rate is not an executive result if revenue, qualified lead volume, or another agreed outcome did not improve.

    Be precise about what a conversion represents. If the account counts form submissions, calls, purchases, and secondary actions, do not roll them into an unexplained conversion total. If lead quality or offline revenue is unavailable, say so. Platform-attributed activity should not be presented as verified commercial value when the connection has not been measured.

    Give each comparison a distinct job

    Leadership needs context because an isolated total cannot show whether performance was good, weak, or simply different. Year-over-year results, target attainment, and industry benchmarks answer different questions:

    • Year over year shows direction and the size of the change from the previous period.
    • Target attainment shows whether the program delivered the commitment the business planned around.
    • An industry benchmark can add external context when its market, metric definition, and methodology are genuinely comparable.

    Do not use a favorable benchmark to distract from a missed internal target. Do not use year-over-year growth without disclosing a major change in budget, tracking, conversion definitions, attribution settings, product mix, geography, or brand activity. If the comparison is not like for like, explain the difference beside the result rather than hiding it in a footnote.

    Explain performance through causes, tests, and context

    An overhead arrangement of a magnifying lens, paired test cards, seasonal blocks, and connecting threads around a central marker.

    The detailed section should prove the executive summary. It is not a chronological tour through platforms, campaigns, and months. Organize it around the questions leadership will naturally ask: why did the result change, what did the team control, what happened outside the account, and what should the business do differently?

    Use a claim-evidence-decision chain

    Build every major finding with the same chain:

    1. Claim: State what materially changed.
    2. Evidence: Show the business outcome and the relevant comparison.
    3. Driver: Identify the account, market, measurement, or operational factor connected to the change.
    4. Implication: Explain why the change matters beyond the metric itself.
    5. Decision: Recommend what to continue, stop, change, investigate, or approve.

    Write slide headings as conclusions rather than topics. A heading such as Nonbrand growth added volume but reduced efficiency tells leadership what to inspect. A heading such as Campaign performance makes them find the conclusion themselves. Use the stronger form only when the underlying data supports both sides of the statement.

    Apply more scrutiny to anything labeled a top performer. Ask whether it contributed materially to the business outcome, can be repeated, has room to scale, and relies on trustworthy measurement. A branded campaign may look exceptionally efficient because it captures existing demand. A small campaign may have an attractive rate but too little volume to change the business result. Show how resources were allocated and whether the strongest areas can absorb more investment without assuming their past efficiency will continue unchanged.

    Report tests as decisions, not activities

    A test log becomes useful to leadership when it shows how uncertainty was reduced. For each material test, record the decision question, hypothesis, change made, observed outcome, confidence or limitation, and next action. Tests that did not improve performance still matter when they eliminate an option or expose a measurement problem. A list of experiments with no resulting decision is only an activity report.

    Trends deserve the same discipline. Connect a trend to the affected business outcome, show when it appeared, and distinguish a durable pattern from a temporary movement. Top-performing assets, resource allocation, tests, and trends belong in the report when they explain the year or change the next decision.

    Separate external influence from convenient explanation

    Digital platform changes, competitor behavior, demand shifts, and broader economic conditions can affect PPC performance. They should not become catch-all explanations for a weak result. Timing alone does not establish cause.

    Use a simple evidence ladder:

    • Confirmed impact: The external change has a plausible mechanism and a visible effect in your own account or business data.
    • Plausible influence: The timing and mechanism fit, but the available data cannot isolate the effect.
    • Background context: The event may matter to the market, but you cannot connect it to the reported result.

    For every external factor you include, explain the event, the mechanism through which it could affect demand or media economics, the evidence visible in your data, and the response available to the team. If you cannot complete that chain, label the factor as context rather than cause.

    Address unfavorable performance directly. State the size and location of the problem in the terms already used by the business, explain what is known and unknown, and show the corrective decision. Leadership is more likely to distrust a buried weakness than a clear limitation with an accountable response.

    Turn the retrospective into next year’s decision menu

    Hands arrange three planning pathways made from blank cards, budget tokens, and milestone blocks on a boardroom table.

    The forward-looking section should not be a wishlist of campaign ideas. It should connect evidence from the completed year to choices leadership can approve, reject, sequence, or constrain.

    Leadership decisionEvidence to presentShape of the recommendation
    How much should we invest?Business outcome, efficiency, target gap, marginal performance, and capacity constraintsA budget position with assumptions, downside controls, and the conditions for releasing more investment
    Where should funding move?Performance by meaningful segment, scalability, strategic coverage, and measurement confidenceA reallocation tied to expected business contribution, not merely the lowest platform-reported cost
    Should growth or efficiency take priority?The observed tradeoff between outcome volume, cost, and commercial qualityAn explicit priority with guardrails for the measure leadership is not optimizing first
    What should be tested?Unresolved assumptions, performance constraints, and opportunities identified during the yearA ranked test agenda with a decision question, success signal, and action attached to each test
    What should be fixed in measurement?Missing offline outcomes, inconsistent conversion definitions, attribution limitations, or data gapsA measurement priority that explains which future decisions will become more reliable

    Do not recommend a budget increase solely from platform-attributed conversion value when revenue identity, lead quality, or incrementality remains uncertain. The financial downside is straightforward: the business can pay more for outcomes that look valuable in the ad platform but do not produce equivalent commercial value. State the uncertainty, propose the measurement work, and use spending guardrails until the evidence is strong enough.

    Write each recommendation in a decision-ready form: because [evidence], we recommend [action]. We expect it to affect [business outcome]. The principal risk is [risk]. We will monitor [signal] and change course if [trigger] occurs. The owner is [role].

    Use scenarios without pretending the forecast is certain

    A fixed plan can create false confidence when demand, competition, pricing, or platform conditions may change. Present a base case grounded in current evidence, an upside case tied to a specific favorable signal, and a downside case tied to a specific risk. Each case should name the signal that identifies it and the action the team will take.

    This is the practical value of a decision framework built to adapt as conditions change. Leadership does not need a claim that every outcome is predictable. It needs confidence that the team knows what to watch, what authority it has, and when a new decision must return to the leadership table.

    Close the planning section with a decision register. Separate approvals needed now, choices deferred until a named signal appears, actions already within the team’s authority, and dependencies owned elsewhere. Assign an owner to every next step. Without an owner or decision point, a recommendation is only commentary.

    Run a leadership review before you send it

    Review the report through the eyes of an executive who is interested but skeptical. They should not have to reconcile totals, decode channel vocabulary, or search the appendix to discover a material problem.

    Use this final quality check:

    • Every chart identifies its data source, reporting period, metric definition, and relevant scope.
    • Comparisons use consistent conversion actions, attribution assumptions, currency, business scope, and time periods, or disclose where they do not.
    • Actual results, targets, forecasts, and external benchmarks are labeled as different things.
    • The executive summary contains the primary outcome, the main drivers, the largest limitation, the recommendation, and the required decision.
    • Material negative results appear early and include what is known, what remains uncertain, and what happens next.
    • Every diagnostic metric supports a business-level conclusion rather than appearing because it is available.
    • Recommendations name an owner, a decision trigger, a risk, and the outcome they are intended to affect.
    • Technical detail needed for verification remains available in an appendix.

    Then ask a colleague who did not build the analysis to read only the executive summary, headings, and recommendations. Ask them to state the year’s result, the reason it changed, the largest uncertainty, and the decision leadership must make. Any answer they cannot give points to a gap in the report’s structure.

    Key takeaways

    • Design the report for a named audience and a specific leadership decision.
    • Lead with business outcomes; use channel metrics to explain them.
    • Compare performance with the prior year, the agreed target, and only genuinely relevant external benchmarks.
    • Build every major finding from a claim, evidence, driver, implication, and decision.
    • Distinguish confirmed external impact from plausible influence and background context.
    • Convert recommendations into choices with assumptions, risks, triggers, owners, and measurement needs.

    Start your next report with the decision sentence before exporting any data. Pull only the evidence needed to validate, challenge, or qualify that sentence, and move the rest to the appendix. That discipline gives leadership a report it can use to allocate money, set priorities, and hold the next plan accountable.

    References

  • Enhanced Google Ads Creator Tools Streamline YouTube Partnerships

    Enhanced Google Ads Creator Tools Streamline YouTube Partnerships

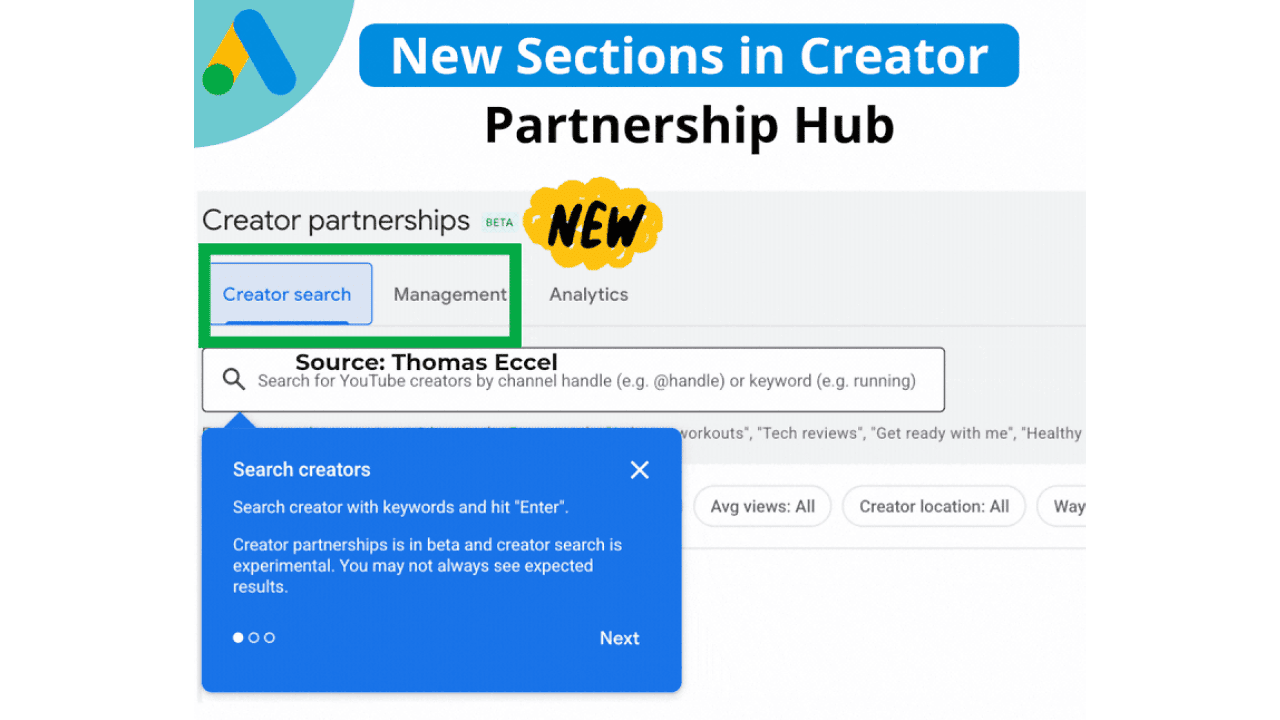
    Google Ads has introduced exciting updates to its Creator Partnerships, making it easier for me to manage collaborations with YouTube talents on a larger scale.

    With the introduction of Creator Search, I can now effortlessly find YouTube creators by utilizing keywords or channel handles. This tool allows me to refine my search based on subscriber count, average views, location, and their availability for contact. It’s a game-changer, significantly cutting down the manual work involved in discovering and reaching out to creators.

    In addition to the search feature, Google has unveiled a new Management section. This centralizes all communications with creators, allowing me to view their names, the status of inquiries, subjects, the latest updates, and scheduled response dates—all in one place with the convenience of direct email access.

    Why this matters to me. As creator-led campaigns become a core aspect of media strategies, having better tools to identify the right collaborators and maintain organized partnerships is crucial. The latest enhancements to Google Ads’ Creator Partnerships (beta) cater to these needs perfectly.

    ```json
{
  "alt": "Screenshot of new sections in Creator Partnership Hub with search features.",
  "caption": "Explore the latest features in the Creator Partnership Hub, including a new creator search tool to enhance your collaboration experience.",
  "description": "This image showcases the new sections in the Creator Partnership Hub, highlighting features like 'Creator search', 'Management', and 'Analytics'. A search box invites users to search for YouTube creators by channel handle or keyword. A blue dialog box provides guidance on the experimental 'Search creators' feature, noting it is in beta. Keywords for searchability include Creator Partnership Hub, search tool, collaboration, beta feature."
}
```

    First sightings. This update made headlines when Google Ads Specialist Thomas Eccel shared it on LinkedIn, making industry professionals eager to explore its capabilities.

    The big picture. These upgrades are pushing Creator Partnerships closer to a comprehensive workflow tool, aiding teams like mine to manage creator collaborations with the same efficiency and accountability that we apply to other paid media endeavors.

    Bottom line. By enhancing both discovery and organization, Google’s updates to Creator Partnerships empower me to execute creator campaigns at scale with ease.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • AI-Driven PPC Workflows: Control, Testing, and Audits

    AI-Driven PPC Workflows: Control, Testing, and Audits

    Your Google Ads account does not need more AI output. It needs a reliable way to decide where AI may act, what evidence it must use, who approves a change, and how you will reverse that change if it goes wrong.

    The goal is not hands-off PPC. It is faster analysis, testing, and production without surrendering campaign intent. The workflow below gives AI useful work while keeping budget, measurement, brand claims, and final decisions under accountable human control.

    Give AI a job description and a stopping point

    AI-driven PPC contains three different kinds of automation, and treating them as one is where control starts to disappear.

    • Generative assistance drafts copy, classifies search terms, summarizes reports, and proposes hypotheses.
    • Platform automation adjusts bids, selects placements, and combines assets within the goals and signals supplied to the campaign.
    • Operational automation uses scripts, rules, and alerts to detect changes, pacing problems, broken assumptions, or other conditions that need attention.

    Each layer needs its own permissions. A system that may summarize a report does not automatically need permission to change a budget. A model that drafts headlines does not get to approve its own claims. A script that detects a pacing anomaly does not need authority to restructure the campaign.

    WorkUseful AI roleRequired human decision
    Search-term analysisCluster terms, label intent, and surface anomaliesApprove exclusions and decide whether the pattern changes targeting strategy
    Ad-copy developmentGenerate bounded variations from an approved message setVerify claims, offer details, tone, and possible asset combinations
    Budget monitoringFlag pacing or allocation changes that breach a defined conditionApprove material budget movement and its business tradeoff
    Bidding and deliveryOptimize within the campaign objective and supplied signalsSet the objective, conversion definition, exclusions, and economic limits
    Performance diagnosisRank hypotheses and identify missing evidenceConfirm the cause before changing the account
    Change implementationPrepare an upload, checklist, or bounded script actionReview the exact entities, settings, and rollback path
    Test analysisOrganize results and identify confounding changesDecide whether to keep, expand, revise, or stop the test

    This is the governing rule: generation is inexpensive, but execution consumes budget and changes the evidence you will use later. Put the strongest approval gate at that handoff.

    Define the write boundary

    Assign every AI-assisted task to a permission level before you automate it:

    • Read only: The system can inspect approved exports and return findings, but cannot prepare or publish changes.
    • Draft only: It can create copy, labels, recommendations, or an upload plan for review.
    • Bounded execution: It can perform a narrow, reversible action when predefined conditions are met and the affected entities are known.
    • Human-only execution: A person must make the change because it affects conversion goals, tracking, material budget allocation, market eligibility, legal claims, or brand policy.

    Bounded execution should describe both what is allowed and what is forbidden. For example, a monitoring script may pause an asset with a broken destination if that behavior has been approved in advance, but it should not respond by rewriting the destination, changing the campaign goal, and reallocating spend. That is a chain of business decisions, not one operational fix.

    Strong account fundamentals still matter in automation-heavy PPC. Controlled campaign structure, dependable signals, and clear business objectives give automated systems a better operating environment; weak inputs simply let them make the wrong decision more efficiently. Maintaining those fundamentals alongside human oversight of automation is the practical center of the workflow.

    Turn business intent into a campaign contract

    Business goals and constraints pass through a structured approval framework before becoming organized digital advertising campaign modules.

    An instruction such as improve performance is not a usable brief. It leaves the system to decide what performance means, which tradeoffs are acceptable, and which constraints may be ignored. Those are business choices.

    Create a campaign contract before asking AI to analyze, generate, or recommend anything. This does not need to be a lengthy strategy deck. It needs to be a compact, versioned record that the campaign owner, analyst, creative reviewer, and automation process all use.

    • Business outcome: State what the campaign is expected to contribute, such as qualified demand, profitable sales, or retention. Do not substitute a platform metric for the outcome.
    • Primary conversion: Name the action used for optimization and describe when it counts. Separate it from secondary indicators that are useful for diagnosis but should not steer bidding.
    • Economic boundary: Record the acceptable acquisition cost, return requirement, or budget constraint supplied by the business. If the number is unsettled, mark it as unresolved rather than asking AI to invent one.
    • Audience and intent: Describe who the campaign should reach, the need being addressed, and the search intent that belongs inside the campaign.
    • Eligibility and exclusions: Record locations, schedules, inventory restrictions, existing-customer rules, query exclusions, and any other boundary that must survive automation.
    • Offer and destination: Specify the approved offer, landing page, availability conditions, and any time-sensitive detail that must remain synchronized.
    • Message policy: List approved facts, mandatory language, prohibited claims, tone requirements, and terms that require specialist review.
    • Test rule: Name the hypothesis, allowed changes, evaluation metric, possible confounders, stop condition, and person who will decide the result.
    • Ownership: Assign an approver for budget, measurement, creative, targeting, and rollback. A shared workflow still needs a named decision owner.

    Client and stakeholder conversations belong in this contract. A platform can report conversions or revenue, but it cannot infer whether the business is receiving low-quality leads, overloading a sales team, selling an undesirable product mix, or attracting customers it cannot retain. PPC decisions improve when the team understands objectives beyond the figures visible in the ad account.

    Give the model the contract alongside a structured performance export. Include field definitions, filters, the comparison basis, and known tracking changes. A screenshot can provide visual context, but it should not replace rows and labels that make the evidence auditable. Remove personal information and any proprietary data that the chosen AI environment is not authorized to receive.

    Reusable instruction: Act as an analyst, not an account operator. Use only the attached campaign contract and performance data. Return the observed signal, affected scope, supporting evidence, missing evidence, plausible alternative explanations, and one reversible test. Label every inference. Do not fill missing fields with assumptions and do not propose changes outside the contract.

    That instruction makes uncertainty visible. It also gives the reviewer something better than a confident recommendation: a chain of evidence that can be challenged before money moves.

    Run a traceable loop from observation to decision

    A useful PPC workflow is a loop, not a command that jumps from report to account change. Every pass should preserve enough context for another person to reconstruct what happened.

    1. Capture the baseline. Save the relevant settings, active assets, performance view, known anomalies, and recent change history. Record which filters and conversion definitions are in use. Without that baseline, a later movement cannot be tied confidently to the change.
    2. Write the observation without explaining it. Describe what changed, where it changed, and which comparison exposed it. Keep the initial statement separate from theories about the cause.
    3. Generate competing hypotheses. Ask AI for more than one plausible explanation and the evidence that would weaken each one. This reduces the risk of turning the first plausible story into an account edit.
    4. Choose one decision to test. Convert the strongest supported hypothesis into a bounded change. State what will remain fixed so the result has a chance of being interpretable.
    5. Run a human preflight. Verify entity scope, conversion settings, budget exposure, destinations, exclusions, asset combinations, tracking, claims, and rollback instructions. Review the actual proposed change, not just a summary of it.
    6. Observe delivery and business quality separately. Watch whether the campaign is serving as intended, then examine whether the resulting traffic or conversions meet the business definition in the contract. More activity is not automatically better activity.
    7. Record the decision. Keep, expand, revise, or reverse the change. Save the reason, evidence, reviewer, affected entities, and any unresolved uncertainty.

    Avoid stacking unrelated edits while a test is still being evaluated. If an urgent correction is necessary, make it, but record it as a confounder. Automated campaign types can also involve learning periods, so repeated interventions may leave you with unstable delivery and no clean answer. This becomes especially important for fixed promotional windows, where prolonged learning and interface friction can complicate time-sensitive campaigns. Build and validate the workflow before the promotion begins rather than discovering approval gaps during it.

    Make AI show its diagnostic work

    A performance summary tells you what moved. A diagnostic output should tell you what to inspect next. Require five fields for every anomaly:

    • Signal: The observed movement, expressed without a causal claim.
    • Scope: The campaigns, ad groups, assets, queries, audiences, locations, or conversion actions involved.
    • Cause class: Measurement, eligibility, demand, competition, creative, landing experience, bidding, budget, or an account change.
    • Verification: The exact report, setting, stakeholder input, or comparison needed to confirm or reject the hypothesis.
    • Safe next action: Inspect, annotate, test, pause, roll back, or escalate. A recommendation to edit the account must name the affected entities.

    This format exposes weak reasoning quickly. If the model cannot name supporting evidence or a verification step, the output is an idea for investigation, not a basis for execution.

    Put creative automation behind brand guardrails

    Creative automation carries a different risk from bidding automation. A bid error can waste budget; an asset error can misstate an offer, imply an unapproved promise, or put the brand into a narrative it would never choose. Concerns around Automatic Created Assets and loss of message control make creative governance an operating requirement, not a final proofreading step.

    Use asset permission tiers

    Sort creative inputs and outputs into three tiers:

    • Green: Approved evergreen product facts, existing brand language, standard calls to action, and verified destination descriptions. AI may produce bounded variations from these inputs.
    • Amber: New framing, audience-specific language, promotional urgency, or a rearrangement that could change meaning. AI may draft it, but a named reviewer must approve it before publication.
    • Red: Prices, guarantees, regulated claims, competitor comparisons, legal language, testimonials, eligibility promises, and time-sensitive terms. AI may help organize approved material, but it must not invent or publish these claims.

    Apply the tier to the complete rendered message, not just each individual asset. A headline may be accurate on its own and still become misleading when combined with a description, price, promotion, or landing page. Responsive formats therefore need combination-aware review.

    Use this preflight before enabling generated or automatically assembled creative:

    • Does every factual claim appear in the approved claim library?
    • Does the offer match the destination, audience, geography, and eligibility rules?
    • Could any headline and description combination create a promise that neither asset makes alone?
    • Are trademarks, product names, capitalization, and required qualifiers correct?
    • Are promotion dates, availability, and calls to action synchronized with the landing page?
    • Could the wording be read as a testimonial, guarantee, comparison, or regulated claim?
    • Is the final URL correct, functional, measurable, and appropriate for the query intent?
    • Is there an approved replacement or rollback path if an asset must be removed?

    AI polish is not a substitute for credibility. Real customer or creator material can make advertising feel more relatable than uniformly polished generated creative, which is why authentic user-generated content remains useful in AI-heavy campaigns. Use it only with appropriate permission, preserve the speaker’s actual meaning, and never have AI fabricate a customer experience or testimonial.

    Design tests that answer one decision

    Do not generate a large asset set merely because the model can. Start with a decision the business needs to make, then create only the variations needed to test it.

    • Name the hypothesis in a sentence that could be proved wrong.
    • Choose the primary evaluation metric before examining the result.
    • Specify which material difference is being tested. If several elements must move as a bundle, document the bundle rather than calling it a single-variable test.
    • Hold the offer, destination, targeting, and measurement steady when the test is meant to isolate messaging.
    • Define the evidence standard and stop condition appropriate to the campaign’s traffic, economics, and risk. Do not import a universal threshold.
    • Evaluate downstream business quality as well as platform engagement. A stronger click response does not settle whether the message attracts the right customer.

    AI is valuable here because it can produce controlled variants and check them against the contract. The test owner still decides what question matters and whether the evidence is strong enough to act.

    Make every automated change easy to investigate

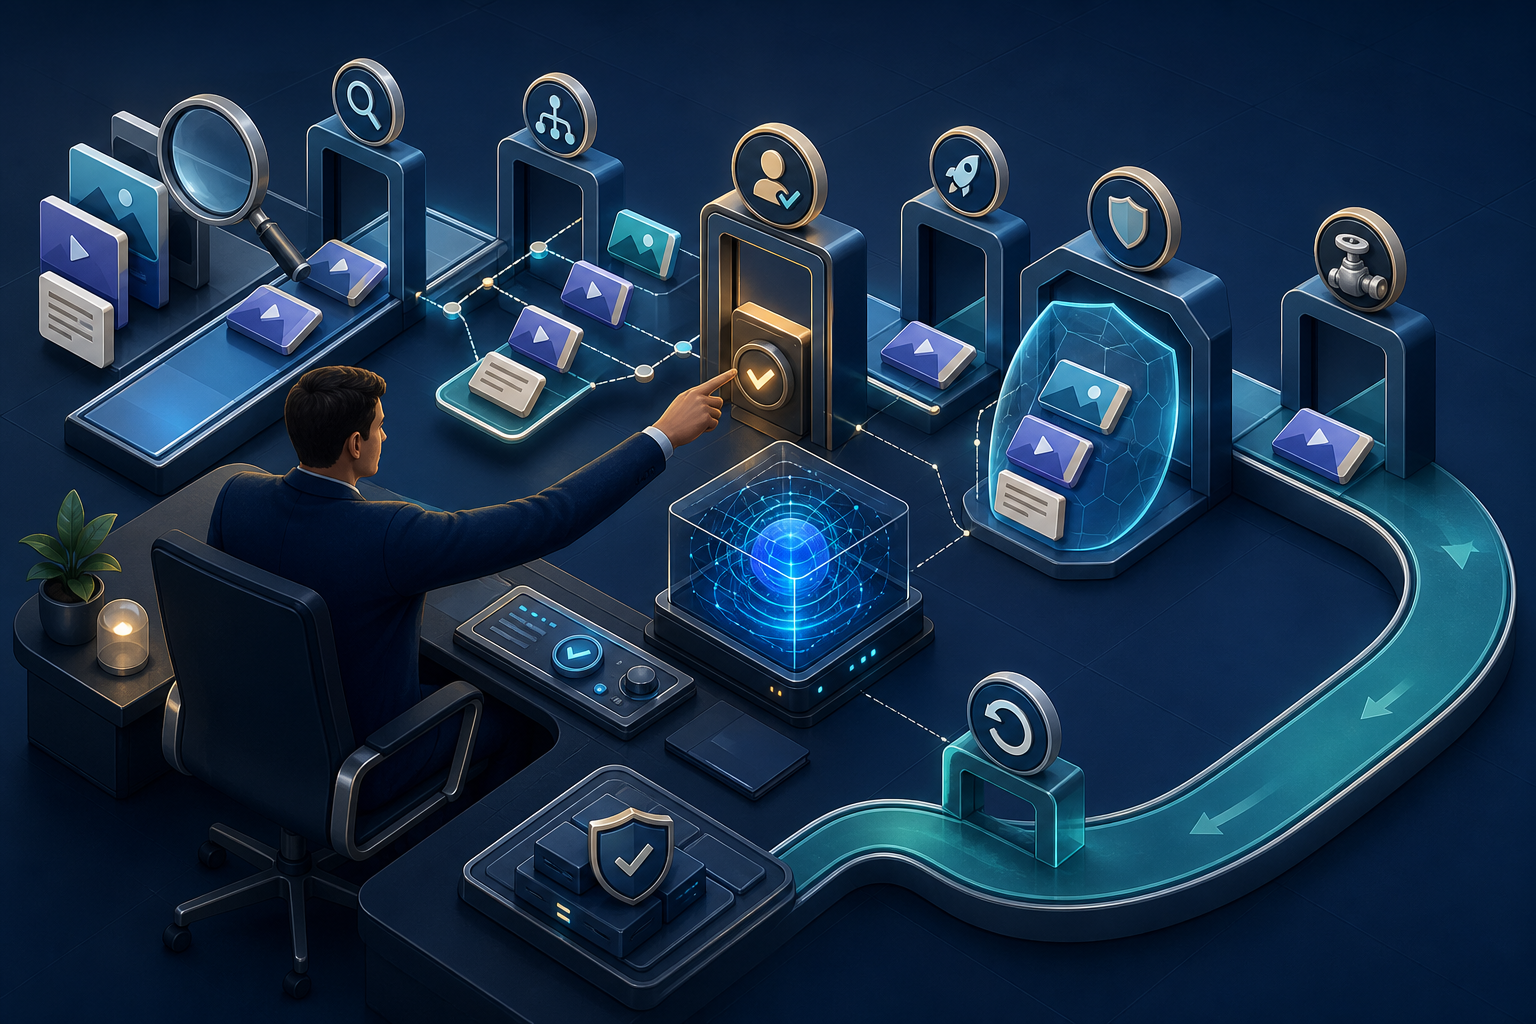
    A human auditor examines a visible chain connecting campaign evidence, testing, approval, deployment, monitoring, and rollback stages.

    Monitoring is where AI-assisted PPC becomes dependable. Scripts can surface problems before they expand, but the alert must lead into a disciplined investigation. Separate four actions that are often collapsed into one: detection, diagnosis, decision, and execution.

    • Detection: A rule, script, platform notice, or reviewer identifies an unexpected condition.
    • Diagnosis: The analyst checks scope, timing, data quality, recent changes, and competing explanations.
    • Decision: The owner chooses whether to observe, test, correct, roll back, or escalate.
    • Execution: The approved action is applied to named entities and recorded.

    Trigger a focused audit after a bulk upload, a script-driven edit, a conversion or destination change, an unexpected performance movement, or a material adjustment to budget, targeting, assets, or goals. Time-sensitive promotions deserve an audit before launch and continued review while the offer is live because a late correction may have little useful runway.

    Google Ads Change history is the forensic layer for this work. When investigating an entry, select one or more changes and use the Go to… dropdown to open the affected campaign or ad group. That removes manual navigation from bulk-edit and script troubleshooting, but it does not replace the reasoning record your team needs.

    For every material change, keep these fields together:

    • The actor or automation that initiated it.
    • The affected account entities.
    • The previous and new values.
    • The campaign-contract requirement or hypothesis behind it.
    • The approval owner.
    • The expected effect and evidence needed to evaluate it.
    • The rollback action and person authorized to use it.
    • Any simultaneous change that could confound interpretation.

    During troubleshooting, ask whether the change was intended, whether it landed at the correct account level, whether adjacent settings moved with it, and whether the implemented result matches the approved plan. If you cannot answer those questions, pause further automation in the affected scope until the account state is understood. Adding more edits to an unexplained state makes both recovery and analysis harder.

    Key takeaways

    • Use AI for classification, drafting, anomaly triage, and bounded recommendations; keep business tradeoffs and material account changes with named human owners.
    • Give every AI task a campaign contract containing the business outcome, conversion definition, economic boundary, audience, exclusions, message policy, and test rule.
    • Move through observation, competing hypotheses, a reversible test, human preflight, and a recorded decision. Do not jump from a generated insight directly to execution.
    • Review creative at both the asset and combination level. Generated wording must stay inside an approved claim library.
    • Separate detection, diagnosis, decision, and execution so an alert does not silently become an account edit.
    • Use Change history to locate what changed, then connect the platform record to the business reason, approval, expected effect, and rollback plan.

    Start with one campaign, not an account-wide automation program. Write its contract, label each task by permission level, create the preflight, and make one change traceable from hypothesis through rollback. Once that loop works under normal conditions, expand it to the next campaign without weakening the gates.

    References

  • Must-Read PPC Insights: 2025’s Top 10 Expert Articles

    Must-Read PPC Insights: 2025’s Top 10 Expert Articles

    Top 10 Search Engine Land PPC columns of 2025

    This past year, PPC has been anything but static – it has evolved. As I explored the insights from 2025, I found these articles resonated deeply. They addressed crucial questions like maintaining a competitive edge, eliminating wasteful spending, collaborating with automation, and gearing up for the future.

    Join me as I take you through the links to the top 10 most-read PPC columns on Search Engine Land from 2025, crafted by our incredible experts.

    10. Can small businesses compete on Google Ads anymore?

    Though it might seem challenging, even the smallest businesses can carve out their niche and captivate customers. Discover the strategies that make this possible. (By Sophie Logan. Published Sept. 16.)

    9. Google Ads optimization: What to stop, start, and continue in 2025

    Update your optimization techniques for 2025 with innovative approaches to keywords, Performance Max, and audience targeting. (By Pauline Jakober. Published Feb. 6.)

    8. CPC inflation: How fast are Google Ads costs rising?

    With increasing CPCs, understanding the pace of this inflation and comparing it to the consumer price index is essential for shaping your ad strategies. (By Mark Meyerson. Published April 16.)

    7. The end of SEO-PPC silos: Building a unified search strategy for the AI era

    AI is bridging the gap between organic and paid search. Learn how integrating SEO and PPC can enhance your visibility and brand presence. (By Jen Cornwell. Published Oct. 6.)

    6. How to vibe code for PPC: Building a seasonality analysis tool

    PPC scripts have limitations, but with vibe coding, you can remove obstacles and transform complex seasonal data into practical planning tools. (By Frederick Vallaeys. Published Aug. 21.)

    5. How to write high-performing Google Ads copy with generative AI

    Streamline your ad creation process without losing your core message. Leveraging generative AI can help craft engaging, personalized copy that truly connects. (By Jason Tabeling. Published Aug. 1.)

    4. 7 Google Ads search term filters to cut wasted spend

    Discover filtering techniques that refine targeting, reduce unnecessary clicks, and reveal new keyword opportunities. (By Menachem Ani. Published July 22.)

    3. Google Ads scripts: Everything you need to know

    Enhance your campaign management with Google Ads scripts. Uncover insights, actionable tips, and use cases for leveraging automation to improve performance. (By Frederick Vallaeys. Published Jan. 9.)

    2. PPC in the age of zero-click search: How to stay profitable

    As clicks become scarcer, maintaining visibility requires precise targeting and value-based bidding. Achieving this ensures your prominence in both paid and organic searches. (By Sarah Stemen. Published Oct. 7.)

    1. 5 Google Ads tactics to drop in 2026

    With Google’s environment becoming more automated, some PPC tactics are now obsolete. Discover what to eliminate and what to focus on for the coming year. (By Sarah Vlietstra. Published Nov. 4.)


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Unveiling 2025’s Top PPC Updates: Exciting Shifts in Advertising

    Unveiling 2025’s Top PPC Updates: Exciting Shifts in Advertising

    2025 was a whirlwind year for those of us in the pay-per-click (PPC) marketing world, with changes coming fast and growing increasingly complex.

    I noticed how significant many of Google’s updates were throughout the year, from the introduction of deeper automation with AI Max to ads being integrated directly into AI Overviews and more transparency and control being offered with Performance Max campaigns.

    There were also key updates to Google Tag Manager and conversion tracking that really changed how I trust and collect data, not to mention the effects of policy shifts, automatic content extraction, and major advertisers like Amazon and Temu pulling back from Google Shopping, shaking up auction dynamics.

    Now that 2025 is coming to a close, let me walk you through the headlines that caught my attention, ranked by pageviews.

    10. Google changed how Tag Manager works with Google Ads

    On March 10th, Google updated Google Tag Manager, ensuring that the Google tag would load before any events, thereby improving tracking accuracy and data collection from April 10th onwards. For me, this meant GTM automatically loaded the Google tag for containers with Google Ads and Floodlight tags, allowing simplified access to Enhanced Conversions and cross-domain tracking directly within tag settings.

    9. Google Performance Max campaign API placement exclusions

    On January 28th, Google revealed we can actually control Performance Max campaigns using API-based placement exclusions, overturning prior documentation and support guidance that stated otherwise. I found research from ad tech firm Optmyzr confirming that these API exclusions effectively blocked spending on excluded placements, providing stronger programmatic control over PMax campaigns.

    8. Search Terms visibility in Google Performance Max campaigns

    On March 21st, Google gave us the ability to see which search terms were triggering ads in Performance Max campaigns and introduced the option to add negative keywords directly from the Search Terms report, enhancing transparency and giving us more control.

    7. Google Ads AI Max for Search campaigns beta

    On May 6th, Google introduced AI Max, a one-click enhancement for Search campaigns, offering us the power of advanced AI to expand reach and dynamically generate ads, while adapting creative elements in real time.

    6. Google AI Overviews ads

    Starting May 22nd, Google began placing ads directly within AI Overviews, marking a significant shift in monetizing its generative search experience. This new feature was confirmed during Google Marketing Live 2025.

    5. Google Ads allowed multiple ads for the same business on one results page

    On March 31st, Google allowed the display of multiple ads for the same business on a single results page, provided they appeared in different locations, thereby opening up opportunities for larger brands to increase their visibility.

    4. Google launched automatic marketing content extraction

    On April 3rd, Google introduced a feature that automatically pulls existing marketing content from merchants to boost visibility across Search, Shopping, and Maps. Merchants were auto-enrolled, but could opt-out anytime?

    3. Temu pulled its U.S. Google Shopping ads

    On April 14th, Temu’s abrupt withdrawal of its U.S. Google Shopping ads revealed the heavy reliance on paid acquisition. This move, coinciding with increased tariffs and strict enforcement of import regulations, significantly impacted its market presence.

    2. Amazon pulled out of Google Shopping ads

    On July 25th, Amazon’s unexpected cessation of Google Shopping ads shook the market, given its historical role in driving auction competition and ad revenue. A month later, it resumed internationally but remained absent in the U.S.

    1. Google Ads simplified conversion tracking with new tag manager feature

    Google Ads, on February 5th, simplified conversion tracking within Google Tag Manager by introducing a wizard-style setup for creating conversion events without manual coding, revolutionizing my approach to tracking and optimization.

    PPC in 2025 was undoubtedly dominated by major headline-worthy updates, largely centered around Google’s changes. Moving forward, I expect 2026 to bring even deeper AI integration. The real game-changer will be how expertly we can apply AI strategically.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Thriving Brand-Agency Partnerships: Insights for 2026 Success

    Thriving Brand-Agency Partnerships: Insights for 2026 Success

    In today’s ever-evolving landscape, brand-agency partnerships look vastly different than they did just a few years ago, and this evolution will only continue to expand by 2026.

    I’ve noticed that internal marketing teams have become more sophisticated, digital channels are increasingly specialized, and the role of agencies shifts away from a one-size-fits-all approach.

    Interestingly, the companies reaping the most benefits from agency relationships aren’t necessarily the biggest spenders.

    Instead, those that succeed are clear about their specific needs and objectives.

    Achieving clarity starts with understanding the true role an agency should play in your organization.

    Too often, partnerships fail because expectations and responsibilities weren’t clearly aligned from the beginning.

    When this foundational understanding is lacking, even the most robust execution can fall short.

    Having worked with thousands of businesses across industries and growth stages, I’ve consistently observed that agency success falls into two distinct partnership models. These models are primarily influenced by company size and internal marketing maturity.

    Model 1: Execution-first Partnerships for Large Companies

    If your company sees over $50 million in annual online revenue, chances are you already have a capable internal marketing team.

    Strategy and planning remain in-house, so what you need from an agency is deep platform expertise and exceptional execution.

    At this stage, agencies function as specialist operators that activate roadmaps, optimize channel performance, and bring advanced technical knowledge that’s inefficient to replicate internally.

    When performance dips, a powerful agency partner doesn’t default to tweaking tactics.

    Instead, they help uncover whether the issue stems from execution, market conditions, or a strategic misstep, offering data to guide corrective measures.

    Model 2: Integrated Growth Partners for Small to Mid-Size Companies

    For companies under $50 million in annual revenue, the agency dynamic shifts.

    Internal teams might be lean or still cultivating core digital expertise.

    In these situations, agencies do more than execute; they shape your entire growth strategy.

    An ideal agency acts as an extension of your marketing team, guiding platform selection, crafting cross-channel strategies, and more.

    For growing businesses, this integration provides access to senior-level expertise, balancing speed, strategy, and financial constraints effectively.

    Finding the Right Agency Partner

    I’ve seen many companies approach agency selection improperly.

    Ditch the RFPs

    Large companies often rely on the request for proposal (RFP) process, which tends to favor vendors skilled in documentation over performance-driven results.

    Instead, I recommend using your professional network. If you’re in charge of a large marketing department, you likely know several professionals who can provide referrals to standout agencies.

    Smaller businesses should seek advice from peers about reliable vendors, then check reviews to confirm their findings.

    While no agency is perfect and all will have some unhappy clients, patterns of negative reviews are a solid indicator to avoid those agencies.

    Request an Audit

    Upon narrowing down potential partners, I suggest asking for an audit of your current marketing setup.

    Most digital marketing agencies conduct these audits for free, offering honest and constructive feedback.

    Depending on your company’s size, audits might vary, with larger firms focusing on specific platforms and smaller ones requiring full-funnel evaluations.

    This information helps evaluate how the partnership will integrate with existing processes, paving the way for effective collaboration.

    The selection process inherently includes finding partners that mesh well with your internal processes—critical to long-term success.

    Setting Achievable Goals

    After selecting an agency partner, the next step is defining coherent goals aligned with your business objectives.

    Unfortunately, I’ve observed that many leaders set goals disconnected from their business aims, straining the agency relationship from the get-go.

    A robust agency questions your goals pre-contract, urging you to adjust expectations realistic to your context and aspirations.

    Your chosen partner should grasp your business’s economics and help ensure marketing goals are aligned with broader business objectives.

    Maintaining a Productive Partnership

    Once everything is underway, you must keep your agency accountable, which involves regular reviews and tracking progress against initial audit benchmarks.

    Contract Length

    Large enterprises often sign 12-month contracts for stability, but smaller firms might benefit from a more flexible three-month commitment that auto-renews.

    In cases where everything seems perpetually smooth, consider that growth might be stagnating, as healthy conflict is a sign of challenge and progress.

    Ongoing Accountability

    Regularly reviewing opportunities against your agency’s initial audit findings not only keeps progress on track but also provides vital context for adapting strategies.

    Context is key, especially if your industry’s dynamics affect your agency’s work—awareness of broader market trends is crucial for realistic appraisal.

    Innovation and Testing

    Your agency should consistently suggest fresh ideas, especially for smaller businesses, while larger companies should fund dedicated innovation budgets.

    Effective agency partnerships without innovation risk falling behind competitors more willing to explore uncharted avenues.

    Ultimately, understanding what’s upcoming and strategically positioning your business will keep you competitive.

    When to Make an Agency Change

    Occasionally, a brand-agency partnership doesn’t thrive. Trust your instincts if you feel things could improve or something is amiss.

    Your Business Isn’t Growing

    Marketing should focus on acquiring new-to-brand customers. If growth stalls while your industry maintains, it’s time to reassess your agency’s role.

    Your Agency Isn’t Pushing Innovation

    If new ideas aren’t forthcoming or you’re not exploring novel methods to engage customers, seek an external audit to identify gaps.

    Your Agency Can’t Explain Performance

    An inability to contextualize performance suggests a knowledge gap in your sales funnel, where interconnected activities impact overall success.

    For smaller businesses, agents should grasp comprehensive marketing operations and how various elements influence each other.

    The Marketing Reality Check

    Great marketing can’t compensate for a flawed business model. Successful growth stems from the synergy of good business, leadership, and agency collaboration.

    If any component is lacking, marketing falls short of potential. Meaningful growth arises when agency roles align with specific business needs.

    Agency selection is an ongoing journey involving ongoing dialogue, accountability, and refinement, even when this involves constructive disagreements.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Microsoft Ads Asset-Level Compliance Reviews: A Practical Workflow

    Microsoft Ads Asset-Level Compliance Reviews: A Practical Workflow

    You open Microsoft Advertising and find that one headline or image has been disapproved. Do not start by rewriting the entire ad. The useful question is narrower: which component failed, what can still run, and does the remaining creative still communicate what you intended?

    Asset-level compliance reviews make that diagnosis possible. Once you treat each component as its own reviewable unit, you can correct the actual problem, preserve compliant creative, and keep a small editorial issue from turning into an unnecessary campaign rebuild.

    Read the asset status before judging the whole ad

    Microsoft Advertising can review individual components such as headlines and images separately. A non-compliant component can be blocked without automatically preventing compliant components from continuing to run. This replaces the more disruptive all-or-nothing approach in which one problem could hold back the complete ad.

    That changes what a disapproval means. You now need to read the account at three levels:

    • Asset level: Identify the exact headline, image, or other component carrying the disapproved status.
    • Ad level: Confirm which compliant components remain available and whether the ad still has a usable creative set.
    • Campaign level: Decide whether the remaining components still represent the offer, required qualifications, and intended call to action.

    Do not confuse editorial approval with creative quality. A compliant asset has cleared the review represented by its status; it has not necessarily proved that it is persuasive, accurate for every audience, or strong enough to meet your performance goal. In the other direction, one disapproved asset does not mean that every other component is defective.

    The dashboard now flags the blocked element and provides an asset-specific status. Use that status as the starting point for your investigation instead of guessing from the ad’s overall performance.

    What you seeWhat to noticeWhat to do next
    One headline is disapproved while other components are compliantThe review outcome is localized to that headlinePreserve the compliant components and revise only the blocked headline
    One image is disapproved while copy remains compliantRewriting approved copy will not address the identified componentInspect or replace the image first
    Several blocked assets share similar wording or imageryA common characteristic may be causing repeated problemsCompare the blocked assets before making separate edits
    Assets are compliant but the campaign is not meeting its goalEditorial review is not a performance diagnosisInvestigate creative strength, targeting, bidding, measurement, and the offer separately

    Use a narrow workflow for every disapproved component

    An isolated ad component moves through symbolic diagnosis, policy review, correction, and verification steps while compliant components remain untouched.

    The fastest-looking response is often a broad rewrite. It is also the response that destroys the clearest evidence. If you change every headline and image together, you lose the distinction between the component that failed and the components that were already acceptable.

    Use this sequence instead:

    1. Locate the exact asset. Open the detailed status and identify whether the blocked item is a headline, image, or another component. Do not begin from a general impression that the entire ad was rejected.
    2. Record what the dashboard shows. Save the asset text or image filename, its location, the visible warning, and the date you noticed it. A screenshot can preserve context if the status changes later.
    3. Protect the compliant set. Leave approved components unchanged unless they have a separate accuracy or performance problem. Their continued eligibility is the operational benefit of asset-level review.
    4. Correct the smallest defensible unit. If the blocked item is a headline, work on that headline. If it is an image, inspect the visual rather than polishing unrelated copy. Make the correction substantive enough to address the apparent issue; a cosmetic near-duplicate is unlikely to improve your understanding of the problem.
    5. Check the revised status. Return to the asset view after the correction has been reviewed. Do not infer approval merely because other components are serving.
    6. Search for reuse. If the same wording or visual appears elsewhere in the account, inspect those locations before the issue creates repeated cleanup work.

    If the displayed warning is too broad to tell you what should change, stop editing at random. Preserve the exact status and creative, then use the review or support path available in your account. Random rewrites may eventually produce a compliant variation, but they will not teach your team what caused the original failure.

    Keep compliance corrections separate from performance experiments as well. When an asset is changed because of a review outcome, label that reason in your campaign notes. Otherwise, a later analyst may mistake a mandatory compliance change for a deliberate creative test and draw the wrong conclusion from subsequent performance.

    Build an asset ledger that turns disapprovals into reusable knowledge

    Asset-level review is most valuable when your internal records are equally granular. A campaign-level note such as “ad rejected” is no longer precise enough. It cannot tell the next person what failed, which components remained usable, or whether the same issue has appeared before.

    A simple asset ledger should capture:

    • The campaign and ad containing the asset
    • The asset type, such as headline or image
    • The exact copy or the image filename used by your team
    • The current status shown in Microsoft Advertising
    • The warning or explanation visible in the dashboard
    • The date the status was observed
    • The correction made and the reason for it
    • The revised version’s status
    • Other ads or campaigns that reuse the same message or visual

    Treat edited copy as a separate version in this ledger. If you overwrite the original wording in your records, you erase the comparison that could reveal why one variation was blocked and another was accepted.

    The ledger is operational history, not a substitute for the platform’s current status or Microsoft Advertising’s policies. Its purpose is to reveal patterns. Repeated problems attached to the same claim, visual treatment, or approval handoff deserve a process change upstream rather than another round of one-off fixes.

    Use those patterns to improve your preflight review. Before new creative is submitted, compare it with previously blocked assets, verify that required wording has not disappeared during editing, and confirm that image and copy versions belong together. This is more useful than a generic instruction to “check compliance” because it directs reviewers toward the failure modes your team has actually encountered.

    Check message coverage even when compliant assets keep running

    A strategist reviews active and inactive ad components, with a visible gap in the remaining creative message pathway.

    Reduced disruption does not mean zero business impact. The remaining components may continue serving while an important part of your message has disappeared. If the blocked asset carried the only clear explanation of the offer, a key qualification, or the intended call to action, the ad may still be active without doing the job you designed it to do.

    After any asset-level disapproval, check the remaining creative against a short coverage list:

    • Identity: Can a user still tell who is advertising?
    • Offer: Is the product, service, or proposition still clear?
    • Qualification: Are important limits or conditions still represented where your organization requires them?
    • Action: Does the remaining creative still tell the user what to do next?
    • Consistency: Do the surviving components make sense together rather than creating a misleading or incomplete combination?

    If a blocked component contains wording your legal or compliance team requires, do not assume that continued serving is automatically safe. The specific downside is that an ad could remain active without the language your organization considers necessary. Use the campaign controls available to prevent that exposure until a compliant replacement preserves the required meaning.

    Record the disapproval and correction in the same change log you use for campaign analysis. A component becoming unavailable changes the creative set that can run. If you omit that event from your notes, a later performance shift may be attributed to bidding, targeting, or seasonality when the message mix also changed.

    Once the revised asset is compliant, verify more than its status. Confirm that it restores the intended message, that it does not contradict the other components, and that your reporting period identifies when the asset set changed. Compliance recovery and performance recovery are related, but they are not the same checkpoint.

    Key takeaways

    • Microsoft Advertising reviews individual components such as headlines and images, allowing compliant assets to continue while a problematic component is blocked.
    • A disapproved asset is a localized diagnosis. Identify the exact component before editing anything else.
    • Preserve compliant assets and correct the smallest relevant unit instead of rebuilding the complete ad.
    • Track each asset, visible status, correction, and reused location so recurring issues can be fixed upstream.
    • Continued serving does not prove that the remaining creative still communicates the full offer or required qualifications.
    • Keep compliance changes in your campaign log so they are not mistaken for performance experiments.

    At the next disapproval, begin with the component named in the dashboard. Preserve what passed, document what failed, and inspect the message that remains. That small discipline is what turns asset-level review from a status display into a reliable compliance workflow.

    References

  • Google Ads Automation: A Control Framework for Advertisers

    Google Ads Automation: A Control Framework for Advertisers

    Your Google Ads dashboard can report an efficient campaign while your sales team sees weak leads, your revenue stays flat, or your ads wander into queries you never meant to buy. That gap is where automation becomes expensive.

    You don’t regain control by trying to make every auction decision manually. You regain it by deciding what the system should optimize, where it may explore, what it must exclude, and which business evidence can overrule an attractive platform metric.

    Advertiser control has moved upstream

    Google increasingly treats campaign automation as a connected system. Broad match has been the default for new Search campaigns since July 2024, and it is designed to operate with conversion-based Smart Bidding rather than as an isolated keyword option.

    Broad match expands the set of queries for which an ad may be eligible. Smart Bidding then evaluates individual auctions using signals such as the device, location, time, query context, and user behavior. Google attributes a 10% improvement in broad-match campaigns using Smart Bidding to recent AI enhancements. Treat that as Google’s platform-level claim, not as a forecast for your account. Your result still depends on the goal, data, constraints, economics, and market conditions you supply.

    This changes what control looks like. A match-type selection cannot compensate for a shallow conversion goal. A bid strategy cannot know that a submitted form became an unqualified lead unless you return that information. An account-level CPA cannot tell you that one campaign is buying profitable demand while another is buying cheap activity.

    Control layerYour decisionEvidence to inspect
    OutcomeWhich actions and values should direct biddingQualified leads, completed sales, and revenue outside Google Ads
    IntentWhich query themes are relevant, marginal, or unacceptableSearch terms and downstream quality by theme
    AudienceWhich customer and remarketing signals provide useful contextQuality and value by audience segment
    BrandWhich brands must be included or excludedBrand, competitor, and generic-query overlap
    PolicyWhere a product, creative, or placement is eligibleCountry rules, creative audits, category controls, and placement reviews

    The interface still contains controls, but the most consequential ones now sit before and after the auction: conversion design before it, and business validation after it. If either side is missing, automated bidding can behave exactly as configured while producing the wrong commercial result.

    Fix the conversion signal before expanding reach

    An analyst calibrates a transparent filter that separates verified golden conversion signals from vague and duplicate inputs.

    The central risk with broad match is drift. A campaign may not collapse or produce obviously irrelevant traffic. It can gradually favor users who complete an easy action but rarely become customers. Reported CPA remains acceptable because the system is finding more of the conversion it was asked to find.

    Audit the goal in this order:

    1. Name the business outcome. Decide whether success means a qualified opportunity, completed purchase, recurring revenue, or another result with commercial value. Don’t start with whichever event is easiest to count.
    2. Separate outcomes from indicators. A form submission, call, download, or account creation can be useful evidence without deserving equal influence over bidding. If an event has weak purchase intent, don’t let its volume define campaign success.
    3. Return quality information. Import offline outcomes such as qualified leads, completed sales, or revenue when the buying journey continues outside Google Ads. If outcomes have materially different worth, use conversion values or quality tiers to preserve that distinction.
    4. Write down your acceptance conditions. Set the qualified-lead rate, revenue requirement, allowable acquisition cost, and prohibited intent themes your business will use to judge the campaign. These thresholds belong to your economics, so they should not be invented from an industry average.
    5. Broaden eligibility only after the feedback loop works. Choose a campaign with reliable tracking and enough meaningful conversion activity. If you cannot connect ad interactions to quality or revenue, broad match gives the system more places to spend without giving you better grounds for judging that spend.

    This audit prevents a common measurement error. A cheaper form is not necessarily a more efficient acquisition. If one query produces many low-quality submissions while another produces fewer profitable customers, lead volume and platform CPA can rank them in the wrong order. The deeper outcome must settle the decision.

    Do this work before changing bids, budgets, or match behavior. Otherwise, a campaign adjustment may amplify the measurement defect and make the dashboard look better at the same time.

    Constrain exploration at the query, audience, and brand levels

    Layered barriers guide selected luminous advertising paths while blocking irrelevant routes and protecting an abstract brand asset.

    Broad match is an exploration mechanism. Your job is to give that exploration an explicit perimeter. Build the perimeter at three levels rather than expecting one negative-keyword list to carry the entire account.

    Use negatives as account architecture

    Start with a shared account-level list for themes that are broadly incompatible with your offer. Depending on the business, examples may include jobs, free, or definition. Then add campaign-level exclusions for intent that is valid elsewhere in the account but wrong for that campaign.

    Review search terms frequently during the first month of a broad-match rollout. Classify each useful finding instead of merely excluding the individual query:

    • Relevant and valuable: leave room for the system to continue exploring the theme.
    • Relevant but commercially weak: check whether the landing page, offer, audience, or conversion signal is attracting the wrong stage of demand.
    • Structurally irrelevant: exclude the underlying theme at the level where it should never return.
    • Ambiguous: inspect downstream quality before deciding. A query that looks unusual may still represent useful long-tail demand.

    This classification matters because endless one-query cleanup is reactive. A structural negative defines a durable boundary the next round of exploration can respect.

    Use audiences as context and evidence

    Customer lists can help you examine behavior associated with known buyers. Remarketing lists can provide context for measured expansion. Audience insights can reveal whether new query reach is concentrated among segments that resemble valuable users or among segments that produce superficial conversions.

    If you use an audience in observation mode, treat it as diagnostic evidence. Compare downstream quality by segment rather than assuming the presence of an audience signal makes every matched query acceptable.

    Set brand boundaries deliberately

    Brand controls answer a different question from negative keywords. Brand inclusions can confine matching to queries involving specified brands. Brand exclusions can prevent unwanted matching to selected brand names. Use them when broad match begins crossing between brand, competitor, and generic intent in ways that undermine the campaign’s purpose.

    Don’t evaluate this overlap only by CPC or conversion volume. A competitor query may convert but attract a materially different buyer, while a broad generic query may introduce demand that later proves valuable. Your CRM, sales outcomes, or transaction data should determine which expansion deserves funding.

    When changing these controls, keep a dated account note that records the constraint, the reason for it, and the business measure you expect to change. Alter one major control layer at a time when practical. That gives you a better chance of knowing whether a shift came from the conversion goal, query boundary, audience context, or brand rule.

    Keep policy eligibility separate from performance automation

    Performance controls answer whether an auction is economically attractive. Policy controls answer whether the ad, product, market, buyer, and placement are permitted. A strong conversion model cannot make an ineligible ad safe, and a policy-eligible ad is not necessarily a good investment.

    The distinction becomes especially important in regulated categories. Beginning in January 2026, Google’s renamed Pharmaceutical products and services policy allows AdMob Authorized Buyers to advertise certain prescription drugs and services in eligible markets without the Google certification normally required in Google Ads.

    That permission is narrow. It applies to AdMob Authorized Buyers in particular countries; it is not a blanket relaxation for every Google Ads account, every pharmaceutical product, or every location. Clinical trials, miracle cures, illicit drugs, addiction services, crisis hotlines, and experimental treatments remain prohibited across Google Partner Inventory.

    If you buy regulated advertising

    Build a market-by-market approval record before allowing automation to pursue inventory. For each country, record the product or service, creative version, landing destination, targeting rule, prohibited themes, and person responsible for approval. Audit the actual creative and geography rather than treating account eligibility as proof that every impression is compliant.

    The absence of a Google certification requirement is not legal approval. Local law, contractual obligations, and the remaining platform restrictions still need qualified compliance review. If eligibility is uncertain, pause that market or creative instead of allowing automated delivery to test the boundary with live spend.

    If you publish AdMob inventory

    Review category blocking and ad controls before newly eligible demand reaches your apps. Decide whether pharmaceutical ads fit the audience, content, and brand-safety standard for each property. More permissible demand may increase auction competition, but it may also change the types of ads users see and the placements that require closer review.

    Non-pharmaceutical advertisers should watch the same change from an auction perspective. New demand can affect pricing and ad presence even when your own eligibility does not change. Separate those market effects from campaign deterioration before rewriting your bidding strategy.

    Key takeaways: run a control loop, not a one-time setup

    • Define the outcome: make qualified leads, sales, or revenue the evidence that settles performance decisions.
    • Feed quality back: use offline outcomes and differentiated values so bidding can distinguish convenient conversions from valuable ones.
    • Bound exploration: combine shared negatives, campaign exclusions, audience context, and brand controls.
    • Inspect the first month closely: review search terms frequently and turn recurring problems into structural constraints.
    • Validate outside the interface: judge expansion with CRM, sales, and transaction evidence, not CPC and CPA alone.
    • Govern policy separately: verify country, product, creative, buyer, and placement eligibility before automated delivery begins.

    Before your next expansion, create a one-page control record containing the bidding outcome, business acceptance thresholds, negative themes, audience inputs, brand rules, policy approvals, and review owner. Then change reach. Automation is easiest to govern when the rules of success are written before the spend moves.

    References