Category: Legal

  • Google’s €890M DMA Fines: A Search Visibility Action Plan

    Google’s €890M DMA Fines: A Search Visibility Action Plan

    If you depend on organic visibility in shopping, hotels, transport or sports, Google’s €460 million Search fine gives you a reason to watch European result pages closely. It does not give you a reason to rewrite your site, declare an algorithm update or forecast a traffic windfall.

    The useful question is narrower: what evidence would show that Google’s response to the Digital Markets Act is changing your actual search opportunity? You need a baseline that captures interface prominence as well as rankings, followed by disciplined comparisons when a confirmed change appears.

    Two DMA findings address two different platform problems

    The combined penalties total €890 million: €460 million for Google Search and €430 million for Google Play. Combining the amounts is useful when describing the enforcement action, but combining the underlying conduct will confuse your response.

    FindingGoogle SearchGoogle Play
    Fine€460 million€430 million
    Conduct identifiedPreferential treatment for Google’s own shopping, hotel, transport and sports servicesRestrictions on developers communicating, promoting and concluding outside-store offers
    Required outcomeFair and non-discriminatory treatment of third-party services relative to Google’s own servicesTechnical and contractual freedom for developers to communicate, promote offers and conclude contracts inside or outside Google Play

    The European Commission required compliance within 60 days and warned of periodic penalty payments of up to 5% of Google’s total worldwide turnover if Google does not comply. That creates a concrete compliance window. It does not tell you which search design Google will choose or guarantee that every affected result page will change in the same way.

    Key takeaways

    • The Search decision concerns the comparative treatment and prominence of Google’s services and similar third-party services.
    • The Play decision concerns app-store steering. It should not be used to explain a movement in organic search traffic.
    • The 60-day requirement makes baseline collection urgent, but it is not a promised rollout schedule for a particular search interface.
    • Rank position alone cannot reveal whether a search redesign has improved or reduced the click opportunity available to you.

    Search self-preferencing is a presentation problem as well as a ranking problem
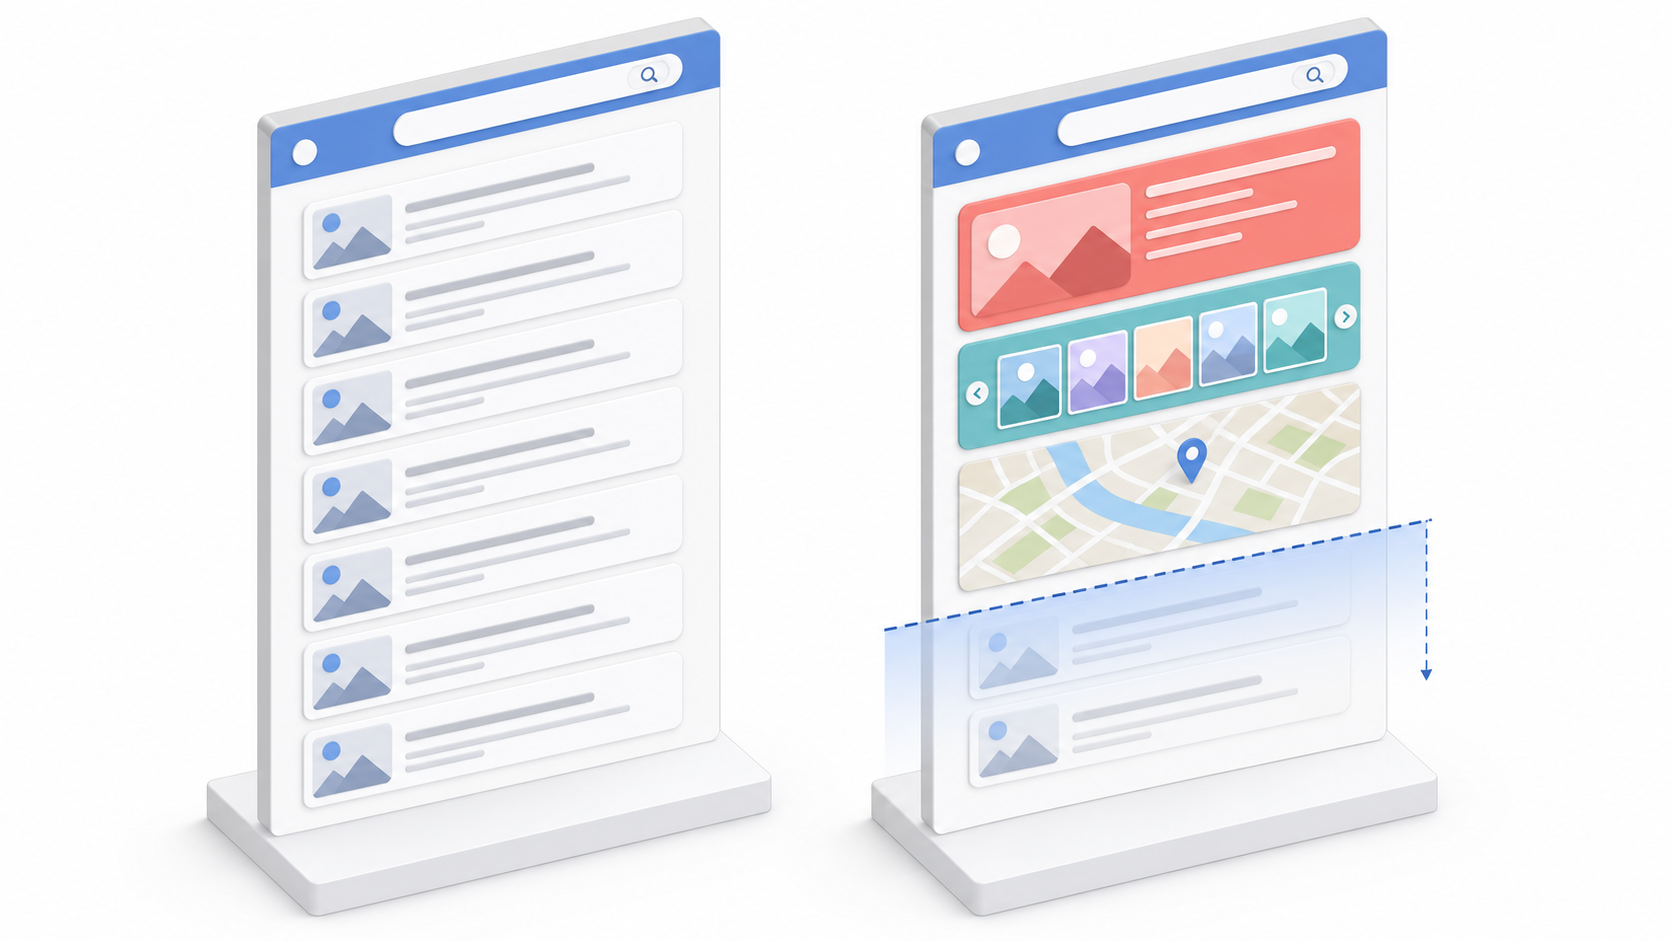
    Two search-result layouts show identical result cards, but large interface modules push most cards below the visible area on the second screen.

    The Search finding is broader than a complaint about which blue link ranks first. Google was found to give its own services greater prominence, including placement at the top of results and the use of enhanced visuals and filters that comparable third-party services did not receive.

    That distinction changes what you should measure. A third-party page can retain the same nominal organic position while losing practical visibility because a large Google-owned module occupies the area above it. The reverse can also happen: a new third-party feature or direct link can improve exposure without moving the conventional listing.

    Audit the result page in layers rather than reducing it to a rank number:

    • Order: Record which component appears first and what sits between the search box and your listing.
    • Visual weight: Note images, expanded cards, labels, filters and other treatments that make one service more noticeable than another.
    • Destination: Distinguish links that lead into a Google service from links that send the user directly to a third-party provider.
    • Interaction: Test what happens after a user selects a filter, card or comparison option. The initial screen is only part of the journey.
    • Parity: Compare how equivalent information from Google and third parties is presented, including whether either side receives richer controls or more prominent placement.

    This is an SEO observation framework, not a legal test. A screenshot can document treatment, but it cannot by itself establish a DMA breach. If your business is considering a complaint or another legal response, preserve the evidence and have competition counsel assess it against the Commission’s decision.

    Build a baseline that can survive a search redesign
    A laptop, tablet, phone, page thumbnails, ruler, markers, and magnifying glass are arranged for comparing search-result layouts across devices.

    Do not wait for traffic to move before documenting the current experience. By then, you may know that performance changed without knowing whether the cause was a new interface, a conventional ranking movement, demand, seasonality or something on your own site.

    Create a query set around the verticals named in the finding: shopping, hotels, transport and sports. Include the commercial searches that matter to your business, then add a comparison group of queries where Google-owned vertical features are absent or less central. Keep market, language, device type and other test conditions consistent so that you are comparing like with like.

    For each observation, store:

    • The exact query, market, language, device type and observation time.
    • A full-page capture showing the order and size of major result components.
    • Which components represent Google services, third-party services or conventional organic results.
    • The presence of enhanced visuals, comparison controls and filters.
    • The number and location of direct links available to third-party sites.
    • Your impressions, clicks, click-through rate and average organic position for the same query cohort.
    • Engaged visits, conversions or other business outcomes from the affected landing pages.

    Annotate the date of a confirmed interface or policy change separately from the date of the fine. This prevents a common analytical error: treating the enforcement announcement as the moment Google’s implementation necessarily reached every user.

    When the interface changes, compare the affected cohort with your stable comparison queries. If rankings hold steady but click-through rate changes where Google-owned modules were altered, presentation becomes a stronger explanation. If both groups move together, investigate broader demand, technical or ranking causes before crediting the DMA response.

    Change your SEO tactics only when the evidence supports the move

    A regulatory order defines the result Google must achieve, not the exact search design it must ship. Google could respond through placement, visual treatment, filters, direct links, eligibility rules or some combination of those elements. Build for credible scenarios, but do not bet your roadmap on one speculative layout.

    1. Protect technical eligibility. Keep important pages crawlable and indexable, use accurate canonical signals, and maintain relevant structured data or feeds. These measures do not guarantee feature inclusion, but prevent avoidable technical defects from obscuring whether access has changed.
    2. Make comparable information explicit. If a result could be filtered by price, location, availability, category or another material attribute, represent that information consistently on the page and in supported machine-readable formats. A new third-party filter is of little value if your data cannot qualify for it.
    3. Strengthen the destination. A direct third-party link only helps when the landing page immediately satisfies the query. Align the page title, visible heading, primary information and conversion path with the specific search intent you are monitoring.
    4. Watch click paths, not just inclusion. Being displayed inside a feature is not equivalent to receiving a visit. Record whether users can reach your site directly, must pass through another Google screen or are encouraged to complete the task without leaving the result page.
    5. Require repeatable evidence before major edits. Do not delete useful pages, rebuild templates or change information architecture because of an isolated result-page test. Confirm that the treatment persists under controlled conditions and that it affects performance before making a costly or difficult-to-reverse change.

    If third-party services begin receiving more direct links or comparable visual treatment, prioritize data accuracy, landing-page quality and measurement of the new referral paths. If no visible change appears in your sample, continue collecting evidence. Absence from your tracked queries does not prove that Google has made no changes elsewhere, while one unusual result does not prove that broad compliance has arrived.

    Keep the Google Play finding out of your search diagnosis

    The €430 million Google Play fine addresses a separate restriction. Google prevented app developers from freely communicating and promoting offers, and from concluding contracts with users through distribution channels of their choice, including third-party app stores. Google may receive a fee for facilitating an initial customer acquisition through Play, but the Commission found that the steering-related fee level and charging period went beyond DMA compliance.

    If you operate an app, route that issue to the people responsible for distribution contracts, checkout paths, customer acquisition economics and developer communications. Keep their implementation log separate from the SEO change log. A revised external-offer flow could affect app revenue or attribution, but it is not evidence that Google Search changed how a web page ranks or appears.

    Your next move is simple: capture the current European search experience for the queries that matter, preserve the underlying performance data, and wait for a confirmed implementation before changing strategy. The teams that can distinguish a ranking movement from a presentation change will be able to act while everyone else is still arguing about what the fine was supposed to do.
    References

  • What a Potential EU Google Search Ruling Could Change

    What a Potential EU Google Search Ruling Could Change

    A pending European Union decision could change how Google presents its own shopping, travel, and other specialized services alongside competing results. The central issue is whether Google has given its products an unlawful advantage within search.

    The outcome remains expected rather than final. Based on reporting summarized by Search Engine Land, however, the case may affect commercial search visibility, access to search data, and the features available to third-party AI providers.

    The expected decision centers on Google’s dual role

    Google operates the general search platform while also offering specialized services that can appear within its results. That dual role matters because placement on a search results page can influence which services users encounter when they are comparing products, planning travel, or making other purchase-oriented decisions.

    Search Engine Land reports that the European Commission is expected to find that Google illegally favored its own vertical services over rivals. The anticipated decision would be made under the Digital Markets Act. Because no final ruling is described in the source material, the specific obligations and their practical effects should not yet be treated as settled.

    Key takeaways

    • EU regulators are expected to rule on how Google displays its own specialized services compared with competing services.
    • Changes could affect visibility for comparison websites, travel platforms, shopping services, and other businesses seeking organic traffic from commercial queries.
    • The Commission is also expected to address third-party access to ranking, query, click, and view data.
    • A related question is whether third-party AI providers should receive access to features available to Gemini.

    Commercial search visibility could be redistributed

    If the Commission requires Google to alter the presentation of its services, rival platforms may gain additional opportunities to appear in prominent search positions. That possibility is especially relevant in categories where users arrive with strong commercial intent and where visibility can direct valuable organic traffic.

    The effect would not necessarily be uniform. A display change could influence comparison services differently from travel or shopping platforms, depending on which search features are covered and how Google implements any order. The reported case therefore signals a potential change in opportunity, not a guaranteed traffic increase for every competitor.

    For search marketers, the useful distinction is between rankings and presentation. A business may retain the same conventional organic position while receiving more or less attention because surrounding modules, specialized results, or Google-owned features have changed. Any assessment of the ruling’s impact should therefore examine actual result-page layouts as well as ranking reports.

    Futuristic web browser and analytics dashboard overlap amid neon data streams, illustrating the convergence of SEO, PPC and AI-driven search marketing.
    Organic visibility, paid media and artificial intelligence merge into one connected search ecosystem, where vivid data streams link a creative website with a powerful analytics dashboard.

    Financial penalties could accelerate compliance

    According to the report, the Commission is expected to impose fines totaling hundreds of millions of euros across two Digital Markets Act decisions. Google could also face daily penalties if it does not comply with parts of the orders within 60 days.

    Those reported enforcement measures matter because the consequences may extend beyond a one-time financial penalty. A compliance deadline could require operational changes on a defined schedule, while the possibility of continuing penalties would add pressure to complete them. The source does not specify the final fine, the exact daily penalty, or the complete design of any required search changes.

    Data access raises a separate privacy dispute

    The Commission is also expected to decide whether Google must provide third-party search engines with access to search data. The reported categories include ranking, query, click, and view information. Such data can be valuable because it may help a search provider understand user demand, evaluate result quality, and improve how information is retrieved and ordered.

    Google disputes that proposed access, arguing that data sharing would endanger user privacy and go beyond the Commission’s authority. This creates a distinct policy tension: regulators may view access as a way to reduce structural advantages, while Google presents privacy and legal scope as limits on what should be shared. The source provides Google’s position but does not report a final resolution of that disagreement.

    AI access could broaden the decision’s reach

    The Commission is reportedly considering whether third-party AI providers should receive access to the same features available to Gemini. That question connects the search dispute to competition in AI services, although the source does not identify the features at issue or explain how access would be implemented.

    The most important next step is the final text of the Commission’s decisions. It should determine whether the expected findings become formal obligations, which services and data are covered, and what Google must change. Until those details are available, businesses should treat shifts in search visibility and data access as credible possibilities rather than completed outcomes.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • What UK Scrutiny of Google Search Could Mean for Businesses

    What UK Scrutiny of Google Search Could Mean for Businesses

    UK scrutiny of Google Search is moving beyond complaints about individual ranking changes. As reported by CrushPress.AI, the Competition and Markets Authority (CMA) is pressing Google on three connected issues: how organic results are ranked, how publishers can respond to AI Overviews, and whether users can transfer their search data to authorized services.

    Taken together, the reported requirements point toward a broader form of accountability. The central question is not simply whether Google may update Search, but whether affected businesses receive understandable rules, meaningful notice and workable ways to challenge decisions.

    Key takeaways

    • The CMA reportedly wants Google to apply objective, non-discriminatory criteria to organic results, including AI Overviews but excluding sponsored placements.
    • Businesses would gain clearer explanations of ranking practices, advance notice of significant changes and a defined process for raising concerns.
    • Site owners would be offered a way to opt out of AI Overviews, according to the supplied report.
    • A separate data-portability requirement would let users transfer search data to authorized third parties.
    • The difficult boundary will be providing useful transparency without exposing ranking systems to manipulation.

    The CMA is treating ranking governance as a business issue

    According to CrushPress.AI, UK businesses told the CMA that Google’s ranking practices lack fairness and transparency. Their concerns reportedly include changes being introduced without enough notice and inadequate channels through which affected companies can question those changes.

    The CMA’s reported response addresses both the substance of ranking and the process surrounding it. Google would be expected to use objective and non-discriminatory criteria for organic results, explain more about how ranking works, warn businesses before significant changes and establish procedures for receiving and addressing complaints. The report gives Google six months to implement the ranking-related measures.

    This distinction matters. A business can lose visibility even when a search system is operating according to its stated goals. Procedural safeguards would not guarantee a particular position, but they could help businesses distinguish an ordinary competitive loss from a technical problem, an unexplained policy shift or a decision worth challenging.

    AI Overviews expand the transparency question

    A translucent summary panel receives colored information threads from blank web pages and publisher desks through a clear prism.

    The supplied report says the organic-results requirements include AI Overviews while excluding sponsored results. It also says Google must provide site owners with a way to opt out of AI Overviews. That combination places AI-generated answers within the same policy discussion as conventional search visibility, rather than treating them as an entirely separate product issue.

    For publishers, an opt-out mechanism introduces a consequential choice. Participation may offer exposure inside an AI-generated search feature, while opting out may provide greater control over how material is used or presented. The source does not specify the mechanism’s design or its effect on ordinary search listings, so businesses should not assume what opting out would do until operational details are available.

    The inclusion of AI Overviews also raises the standard for useful explanations. Traditional ranking transparency concerns which pages appear and in what order. AI-generated results add questions about which sources contribute to a synthesized answer and how prominently those sources are represented. The reported CMA measures establish a direction for oversight, but the supplied account does not describe the level of AI-specific disclosure Google would have to provide.

    Data portability targets a different source of market power

    A transparent capsule of abstract data travels across a secure bridge between two digital service terminals.

    Ranking rules govern how businesses reach search users; data portability concerns what users can do with the information generated through their own search activity. CrushPress.AI reports that the CMA wants Google to let users transfer search data to authorized third parties within three months.

    The examples in the report include rewards platforms and businesses offering personalized deals or discount codes. It also suggests that access could support tailored travel recommendations and more relevant shopping offers. These are possible uses rather than confirmed services or outcomes.

    Conceptually, portability can reduce the advantage created when useful history remains inside one platform. Its practical effect, however, will depend on details not provided in the source: what information is transferable, how authorization works and what safeguards accompany access. The ranking and portability measures therefore address different relationships with Google Search, but both attempt to give outside parties more agency.

    Useful disclosure does not require publishing the algorithm

    The supplied article is skeptical that Google will comply readily, arguing that extensive disclosure could expose a valuable ranking system to competitors or make manipulation easier. That concern identifies the central implementation tension, but it does not necessarily make meaningful transparency impossible.

    There is a difference between revealing a complete ranking formula and explaining the governance around it. Clear policy criteria, notice of consequential changes, documented complaint routes and reasoned responses can improve accountability without publishing every signal or its weighting. The value of the CMA’s reported intervention will therefore depend less on the volume of information released than on whether businesses can use it to understand and contest material decisions.

    Businesses should watch for the eventual scope of the AI Overview opt-out, the specificity of ranking-change notices and the independence and responsiveness of the complaint process. Those implementation details will determine whether the measures alter day-to-day dealings with Google or remain largely procedural.

    The next phase will test whether the CMA’s reported deadlines produce workable controls while preserving the integrity of search results. For publishers and other search-dependent businesses, the most important development will be whether formal scrutiny becomes practical leverage when visibility changes.

    References

  • AI Platforms Face Publisher Accountability on Two Fronts

    AI Platforms Face Publisher Accountability on Two Fronts

    Publisher accountability disputes are converging on two different stages of the AI supply chain: how platforms acquire protected material and what they say after processing it. One dispute challenges the collection and distribution of publisher content through Common Crawl; another treats false statements in Google’s AI Overviews as content for which Google may be directly responsible.

    Together, the reports suggest that platforms may find it harder to rely on a single intermediary defense. Publishers are pressing for control before their work enters AI systems and for meaningful remedies when those systems generate unsupported claims.

    Key takeaways

    • AI accountability is developing at both the input layer, where publisher content is collected, and the output layer, where generated answers can affect publishers.
    • Digital Content Next argues that copyright requires permission rather than a publisher opt-out, while Common Crawl disputes allegations that it bypasses paywalls or misleads publishers.
    • The reported Munich ruling treated disputed AI Overview statements as Google’s own content because they presented standalone claims rather than merely directing users to sources.
    • Links and removal procedures do not resolve the same problem: attribution cannot correct an unsupported generated accusation, while output accuracy does not answer whether source material was authorized.

    One accountability debate begins before generation

    Unmarked documents move toward an AI intake portal through a transparent gate that separates controlled pathways and preserves glowing provenance links.

    The Common Crawl dispute concerns the material available to AI developers before a model produces any answer. According to the source report, Digital Content Next sent the Common Crawl Foundation a cease-and-desist letter demanding that it stop collecting and distributing protected content belonging to its members. The organization also sought removal of member content already present in datasets, including paywalled and subscriber-only articles.

    The report identifies Digital Content Next as representing publishers including the Associated Press, The New York Times, NBC Universal, Bloomberg, NPR and Fox. Its position is that copyright is not an opt-out regime and that making protected material available for AI development without authorization or compensation constitutes infringement. These remain claims advanced by the publisher group, not findings reported as having been resolved by a court.

    Common Crawl presents a different account. Executive Director Rich Skrenta denied bypassing paywalls or misleading publishers and said the foundation responds to requests to remove previously collected material within the constraints of its dataset architecture. The source also notes that Common Crawl maintains a registry of sites that have opted out, while Digital Content Next questions whether the organization’s stated compliance has been adequate.

    The practical importance extends beyond one crawler. The report describes Common Crawl, established in 2008, as a repository containing billions of webpages and as an important source of AI training material. It also relays two indicators of that role: The New York Times’ 2023 lawsuit against OpenAI reportedly said Common Crawl supplied 60% of GPT-3’s training data, and a 2024 Mozilla Foundation paper reportedly concluded that generative AI would scarcely exist in its current form without the repository. Those figures and characterizations are source-reported rather than independently verified here.

    A second debate begins when an AI answer causes harm

    Readers face information tiles projected by an AI terminal while one warped tile casts a fractured shadow on a publisher's desk.

    The reported German ruling addresses a later stage: responsibility for claims generated after information has been collected and processed. The Regional Court of Munich reportedly considered false AI Overview statements that connected two Munich publishers with scams and questionable practices even though the linked pages did not support those allegations.

    According to the account, the misinformation resulted from the system conflating information about other entities with information about the publishers. That detail matters because the disputed allegations apparently could not be traced to the cited pages. If Google were treated only as a conduit, the affected publishers would have no obvious third-party author to pursue for the newly assembled claim.

    The court reportedly rejected that characterization. It viewed AI Overviews as processing material and presenting it in a distinct form, not simply listing third-party pages. Because the accusations appeared as complete answers and were created through a feature and algorithms controlled by Google, the court treated them as Google’s own content. Traditional protections for search engines acting as indirect intermediaries therefore did not apply in the same way.

    The presence of links did not shift the burden back to users. The ruling account says the court rejected the argument that readers could verify the claims by opening the cited pages, reasoning that the Overview presented assertions that stood on their own. The resulting injunction required Google to refrain from repeating the disputed allegations. The court also reportedly considered comparison against primary sources technically possible, at least in analogous circumstances.

    Permission, provenance and accuracy require separate controls

    The two disputes are related, but they should not be collapsed into a single copyright or misinformation issue. The Common Crawl conflict asks whether material may be copied, retained and redistributed for AI development. The Munich case asks who owns the consequences when a platform transforms information into a new, unsupported statement. A platform could improve its answer verification without resolving a publisher’s rights objection, just as it could license every source and still generate a false claim.

    Provenance also has different functions at each stage. During collection, it can identify where material came from, what access conditions applied and whether a removal request covers stored copies. At the answer stage, citations can help users inspect supporting material, but they do not establish that the generated wording is supported. The Munich report illustrates the gap: the pages were linked, yet the allegations attributed to them were reportedly absent.

    This distinction changes what meaningful platform accountability looks like. Input governance concerns authorization, access controls, opt-out or consent signals, retention and downstream distribution. Output governance concerns entity matching, faithful synthesis, verification against cited material, correction and prevention of repeated harmful claims. Treating either set of controls as a substitute for the other leaves publishers exposed at a different point in the system.

    What publishers can learn from the two disputes

    For publishers, evidence should be organized around the stage at which the alleged failure occurred. A collection dispute depends on records such as ownership, access conditions, crawler instructions, removal correspondence and the continued presence or distribution of material. A generated-answer dispute instead depends on preserving the exact output, its citations, the underlying pages and the differences between what those pages say and what the platform asserted.

    The reported cases also make platform promises worth examining at an operational level. A stated opt-out policy is not the same as confirmed removal from existing datasets. A cited answer is not necessarily a supported answer. A correction mechanism is not necessarily protection against repetition. Publishers evaluating an AI platform’s accountability can therefore ask whether its controls cover historical data as well as future collection, and whether answer citations are checked for actual support rather than merely attached.

    Legal conclusions will depend on jurisdiction and the facts of each dispute, so the German ruling should not be treated as a universal rule and Digital Content Next’s allegations should not be treated as adjudicated findings. Their combined significance is narrower but still substantial: AI systems are prompting separate challenges to assumptions that web access implies permission and that automated synthesis remains neutral intermediation.

    If consent requirements become stronger, the Common Crawl report suggests that licensed sources could gain importance relative to broadly collected web content. If courts continue to distinguish generated answers from conventional search results, platforms may also need more rigorous source validation and remedies at publication time. The durable accountability model will have to govern both directions of the exchange: what AI platforms take from publishers and what they publish about them.

    References

  • A Practical Framework for Building Law Firm SEO Authority

    A Practical Framework for Building Law Firm SEO Authority

    Your law firm has repaired technical issues, improved practice-area pages, and kept publishing. Rankings rose, then leveled off. The tempting response is a larger content calendar. That can deepen the problem if the web still has little independent evidence that your firm and attorneys are credible authorities.

    The next job is not simply more SEO. It is to make expertise verifiable, publish material worth citing, and earn corroboration in places you do not control. The framework below helps you identify the authority gap and turn it into a practical queue of work.

    Key takeaways

    • Technical SEO and useful content are foundations, but they cannot manufacture independent credibility.
    • Authority becomes visible when attorney credentials, firm information, authored content, third-party profiles, and earned mentions tell the same accurate story.
    • A citable page gives another publisher or an AI-generated answer a distinct, well-supported passage worth referencing.
    • Relevant editorial mentions matter more than a large collection of weak, unrelated placements.
    • Measure authority through evidence you can inspect: identity consistency, qualified mentions, citations, referral context, and appearances for a fixed set of priority searches.

    Diagnose the authority gap before commissioning more content

    A strategist and an attorney inspect an evidence wall with connected profile cards and visible gaps while sorting files in a conference room.

    Technical SEO and strong content remain necessary. However, law firm growth can plateau when genuine, verifiable credibility is missing. Authority is not a single score that can be raised in isolation. It is the pattern created when your identity, expertise, content, and recognition elsewhere on the web agree.

    Start with a digital-footprint audit. Create a working sheet with fields for the query used, result URL, platform or publication, firm or attorney named, claim made, link destination, accuracy, control status, and next action. This turns an abstract authority problem into a list of evidence you can fix, strengthen, or pursue.

    Search for the exact firm name, common abbreviations, previous names, and each attorney’s professional name. Combine attorney names with the firm, location, and primary practice focus. Inspect ordinary search results, professional profiles, publisher biographies, local listings, interviews, event pages, and AI-generated answers. Record what a prospective client or search system would encounter without assuming your website is the starting point.

    Classify what you find:

    • Accurate owned evidence: pages and profiles your firm controls and keeps current.
    • Accurate independent evidence: relevant mentions, citations, interviews, event listings, and professional profiles hosted elsewhere.
    • Conflicting evidence: outdated titles, previous offices, inconsistent names, broken profile links, or descriptions that no longer match an attorney’s work.
    • Weak evidence: generic directory pages, duplicated biographies, or mentions with no meaningful connection to the attorney’s expertise.
    • Missing evidence: important attorneys, credentials, or practice strengths that are clear internally but barely visible outside the firm.

    The pattern matters more than the raw count. A firm can have many directory listings and still lack authority if none provides editorial context or confirms meaningful expertise. Conversely, a smaller footprint can be persuasive when relevant organizations identify the attorney clearly and connect that person to a specific area of law.

    Do not label every performance problem an authority problem. If an important page cannot be crawled, does not match the searcher’s intent, or competes with another page on your site, fix that first. Authority becomes a plausible constraint when technically sound, useful pages exist but the firm has little accurate recognition beyond its own domain.

    Your audit should end with priorities, not observations. Correct identity conflicts before promoting content. Strengthen thin attorney records before asking a publication to rely on them. If recognition clusters around a practice area the firm no longer prioritizes, redirect outreach toward the work that matters commercially.

    Make attorney expertise easy to verify

    A law firm’s authority is attached to people as much as to the firm itself. A reader should be able to determine who wrote or reviewed a page, what qualifies that person to address the subject, which firm the person represents, and where else that expertise has been recognized.

    Build a canonical biography for every attorney who contributes to public-facing content. It should use the attorney’s consistent professional name and state the current role, practice focus, relevant jurisdictions or admissions, education, credentials, leadership positions, speaking work, and publications accurately. Connect the biography to material the attorney wrote or reviewed. If an external profile is important, make sure it points back to the correct current page rather than an obsolete biography or a generic homepage.

    Avoid interchangeable biographies. A page that says every attorney is experienced, dedicated, and results-oriented provides little verifiable information. Replace generic praise with supported facts that distinguish the person’s actual work. An attorney’s biography, byline, publisher profile, event description, and professional listing should not tell conflicting versions of the same career.

    This is where E-E-A-T becomes useful as a review lens. Experience, expertise, authoritativeness, and trustworthiness are not fields you can fill in or claims you can create with markup. They prompt better questions: Is a real person accountable for the content? Is the claimed expertise visible? Can important credentials be verified? Does the firm’s presence remain consistent across the platforms where people encounter it?

    Use JSON-LD to express facts already visible on the page and to connect the attorney, authored material, and firm consistently. Keep identifiers stable and use the same canonical URLs throughout your implementation. Structured data can clarify relationships, but it cannot prove a credential or create reputation. Never place a qualification, award, office, service, or affiliation in markup when the visible page does not support it.

    Credential, specialization, testimonial, award, and outcome claims deserve an additional review. A stale or overstated claim can create ethical, regulatory, and reputational exposure. Requirements differ by jurisdiction, so have the firm’s appropriate ethics or compliance reviewer approve those statements before publishing them on pages, profiles, or structured data. Search optimization does not reduce that obligation.

    Assign ownership for identity maintenance. Someone should know who updates attorney biographies after role changes, who corrects external profiles, and who checks that new bylines use the canonical identity. Without ownership, small inconsistencies accumulate until the web describes several slightly different versions of the same person.

    Turn practice knowledge into material others can cite

    An attorney shares legal knowledge with a research and editorial team as organized reference packets are passed to independent library and newsroom professionals.

    An indexable page is accessible to a search system. A citable page gives another publisher, professional, or answer system a specific reason to use it as support. That difference should change your editorial brief. The goal is not another page about a broad keyword; it is a reliable contribution that adds something identifiable to the available information.

    Prioritizing citable material over content produced merely to be indexed means asking what another person could responsibly reference. Useful formats include a jurisdiction-scoped explanation of a recurring procedural question, a decision aid that distinguishes commonly confused options, a practical checklist reviewed by a named attorney, a plain-language explanation of a legal development, or an analysis of public information with a transparent method.

    Use the following editorial test before approving a page:

    • Distinct question: The page resolves a real question instead of paraphrasing a broad topic already covered elsewhere on the site.
    • Clear answer: The reader can find the central answer near the beginning, with qualifications added where they matter.
    • Defined scope: The relevant jurisdiction, audience, assumptions, and limits are explicit.
    • Accountable expertise: A named attorney wrote or reviewed the material, and the byline connects to a complete biography.
    • Support: Important factual and legal claims point to suitable primary legal materials or other appropriate evidence.
    • Original utility: The page contains a useful distinction, framework, checklist, interpretation, or method rather than generic prose.
    • Maintenance: An owner is responsible for reviewing the page when the law, procedure, attorney, or firm information changes.

    Write passages that remain understandable when separated from the surrounding page. Give each section a descriptive heading, answer the stated question directly, and keep the necessary qualification beside the answer. This makes the page easier for a person to scan and gives AI-generated answers less room to detach a conclusion from its jurisdiction or conditions.

    Do not confuse extractability with oversimplification. A concise answer can still state that an outcome depends on facts, venue, or procedure. If removing a qualification would make the answer misleading, keep it in the same paragraph rather than burying it in a general disclaimer.

    Review the existing library before expanding it. Identify pages with strong subject matter but weak authorship, vague scope, or no reason to cite them. Upgrade those assets first. If several pages repeat the same intent, consider consolidating them into a stronger resource, but inspect existing links, referrals, and search value before changing URLs. Preserve useful destinations with an appropriate redirect when consolidation is justified.

    Case-based insight needs special care. Do not expose confidential information, imply a typical outcome from an exceptional matter, or turn a result into an unsupported promise. Obtain the necessary internal approval and follow the professional rules that apply to the firm before using client matters, testimonials, or outcomes as authority evidence.

    Earn outside corroboration, then measure the evidence

    Your website can claim expertise. Independent recognition helps corroborate it. That recognition may take the form of a relevant citation, an attorney contribution, an interview, a professional event, a community role, or a publisher biography that clearly connects a person to the subject.

    Build an outreach map from genuine relationships and audience overlap. Consider legal and professional publications, organizations connected to the industries your firm serves, educational institutions, reputable local organizations, event producers, and journalists who cover the relevant issues. Prioritize editorial standards, topical relevance, and accurate identification of the attorney. A contextual mention for the right audience can be more useful than an unrelated placement obtained only for a link.

    Give outreach a concrete purpose. Offer a well-scoped explanation, a named attorney who can address a defined question, a citable resource, or an informed contribution to an existing discussion. Generic requests for a backlink give the recipient no editorial reason to act. Meaningful digital PR and participation in the legal community work because they create legitimate connections between expertise, people, and publications.

    For each opportunity, prepare the canonical attorney name, current title, concise subject-specific biography, correct firm URL, relevant biography URL, and strongest supporting asset. After publication, check that names, roles, links, and claims are accurate. Request corrections when necessary, and add the result to the firm’s footprint inventory.

    Avoid placements whose only apparent purpose is manipulating ranking signals. Do not manufacture awards, trade unrelated links, buy opaque editorial recognition, or distribute the same thin biography across low-quality sites. These tactics create a brittle footprint and can undermine the credibility you intended to build.

    Measure authority with an evidence log rather than a single vendor score. Record the asset or attorney involved, external URL, publication or organization, practice relevance, linked or unlinked status, description accuracy, referral activity, and any qualified enquiry or professional relationship connected to the placement. The context of the mention matters, so retain enough detail to distinguish substantive recognition from a name in a list.

    Separate leading evidence from validation and business outcomes:

    • Leading evidence: corrected identity conflicts, complete attorney records, upgraded citable assets, relevant outreach, and accepted contributions.
    • External validation: accurate mentions, citations, interviews, event profiles, professional references, referral visits, and greater visibility for priority subjects.
    • Business outcomes: qualified consultations, professional referrals, and matters connected to the practices the authority program supports.

    For AI visibility, maintain a fixed set of representative questions tied to your priority practices and markets. Capture the exact question, date, answer, cited domains, firm mentions, attorney mentions, and any material inaccuracies. Repeat the same checks at a regular cadence. Individual AI-generated answers can vary, so look for a pattern across repeated observations rather than treating a single appearance or omission as proof.

    No isolated metric establishes causation. A new mention does not prove that it moved a ranking, and an AI citation does not by itself establish business value. The useful question is whether independent, accurate evidence is becoming denser around the attorneys, subjects, and markets the firm has chosen to own.

    Begin with the practice area that matters most. Audit the names and claims surrounding it, repair the canonical attorney records, strengthen the best existing resource, and take that resource to relevant editorial and professional contacts. When each cycle leaves another accurate, independent trace of expertise, your firm is building an asset that a larger publishing schedule cannot imitate.

    References

  • AI Legal Risk for Business: A Practical Exposure Audit

    AI Legal Risk for Business: A Practical Exposure Audit

    Your AI legal risk probably isn’t sitting in an experimental lab. It’s in ordinary work: a marketer pastes customer information into a model, an editor publishes an unsupported product claim, or a team promises exclusive ownership of material that a machine largely produced.

    You can find much of that exposure before it becomes a dispute. The practical job is to map each AI workflow, identify what enters and leaves it, assign a human decision-maker, and retain enough evidence to explain what happened. This is an operational risk framework, not a legal opinion. If an AI use could affect contractual rights, regulatory duties, intellectual property, or an individual’s interests, have qualified counsel assess the specific facts and jurisdiction.

    Map the workflow, not just the AI tool

    An isometric office scene follows an AI-assisted task from a customer record through generation, editorial review, managerial approval, publication, and evidence storage.

    A list of approved tools is useful, but it isn’t an exposure audit. The same model might be used for harmless brainstorming, confidential document analysis, public product claims, or automated customer responses. Those uses don’t carry the same consequences.

    AI is accelerating familiar legal risks involving intellectual property, privacy, consumer protection, misinformation, and liability. That is good news for your first review: you don’t have to predict an entirely new field of law. You have to locate where AI touches obligations the business already has.

    Build the inventory around use cases. Give each recurring workflow its own row, even when several rows use the same vendor. Record:

    • The team and accountable owner.
    • The business purpose and any decision the output influences.
    • The data, documents, prompts, images, code, or other material sent to the system.
    • Whether inputs contain personal, confidential, licensed, or third-party material.
    • Where the output goes: private notes, an internal system, a client deliverable, a website, JSON-LD, an advertisement, or a customer-facing assistant.
    • The human review required before the output is used.
    • The provider, account type, model or feature used, and relevant retention or training settings.
    • The evidence retained, including sources, revisions, approvals, and important vendor terms.

    That last point matters because AI features change. Recording only the vendor name may not let you reconstruct a decision later. Capture the actual product or feature closely enough that the workflow owner can explain which system handled the information.

    AI workflowExposure to examineEvidence to retain
    Marketing copy, SEO content, and schema markupUnsupported claims, copied expression, unclear ownershipClaim sources, human revisions, reviewer approval
    Customer-facing chatbotIncorrect answers, misleading representations, personal-data handlingApproved answer set, test results, escalation rules, retention decision
    Internal document summarizationPersonal, confidential, or licensed material sent to a providerPermitted data class, access controls, provider settings, deletion terms
    Generated design, image, or codeThird-party rights, license restrictions, protectability, promised ownershipInput provenance, similarity or license checks, material human changes

    Flag a workflow for deeper review when it publishes externally, processes personal or confidential data, makes a consequential recommendation, creates something the business expects to own, or acts without a human approval step. These are screening signals, not legal conclusions. Their purpose is to keep a risky use from disappearing inside a generic label such as “content assistance.”

    Separate input rights, output risk, and ownership

    Teams often compress every intellectual-property question into “Can we use AI for this?” That question is too broad to answer. Break it into three decisions: whether you may submit the input, whether you may use the output, and whether anyone can claim enforceable ownership of the finished work.

    Check the material going into the model

    Permission to read or possess a file does not automatically settle whether it may be uploaded to an external system. A customer brief, licensed image library, unpublished manuscript, source-code repository, or partner document may be governed by a contract, confidentiality term, or access restriction.

    Before submission, identify who supplied the material, what rights the business received, whether the provider may retain or use it, and whether the workflow exposes it to anyone who was not already authorized. If the answer depends on contract language, stop and have counsel interpret that language. Guessing can compromise confidentiality or create a breach that cannot be fixed by deleting the eventual output.

    Inspect the output for third-party material

    A polished answer is not proof of clean provenance. AI output can unintentionally incorporate protected material, creating a practical infringement risk even when the user never requested a copy. Review distinctive text, images, code, characters, slogans, and other recognizable elements before release. For code, inspect dependencies and license implications rather than relying only on a general plagiarism check.

    Give the reviewer the prompt, known source material, and intended channel. Asking whether an output merely “looks original” is too subjective. Ask whether its important elements can be traced, whether suspicious passages require a targeted search, and whether the business could defend its permission to use them.

    Document the human contribution you expect to own

    The U.S. Copyright Office position reflected in the available guidance is that purely AI-generated work is not protected and human creativity must materially shape the work for protection to become possible. Typing a prompt and accepting the first result is therefore a weak foundation for an ownership promise.

    Preserve evidence of the human work that made the final result distinct: the original brief, independently created structure, source selection, rewritten sections, editorial judgments, discarded drafts, compositional decisions, and final approval. The aim isn’t to save meaningless activity. It is to show where a person exercised creative control.

    This distinction belongs in client and contractor workflows. Don’t promise that a customer will receive exclusive, fully protectable rights merely because your contract uses the word “deliverable.” Align the promise with the provider’s terms, third-party licenses, the human contribution, and counsel’s view of the governing law.

    Patent questions need separate treatment. Revised U.S. Patent and Trademark Office guidance has left practical questions about human-conceived inventions developed with AI. If AI materially contributed during invention or development, preserve the chronology and involve patent counsel before making inventorship or filing decisions.

    Treat every public claim as your company’s own statement

    A disclaimer that content was “AI assisted” does not make a false statement accurate. Once your business publishes an output, customers, regulators, partners, and search systems encounter it as a representation made under your brand.

    The dangerous errors are not limited to obvious nonsense. Generative systems can produce invented facts, fabricated citations, and reasoning that sounds coherent but does not support the conclusion. A fluent paragraph can therefore pass an ordinary copy edit while failing a factual review.

    Review claims rather than prose. Maintain a simple claim ledger for externally published material. For each substantive assertion, record:

    • The exact claim a customer will see or reasonably infer.
    • The evidence that supports it, with enough detail for another reviewer to locate that evidence.
    • The product, service, market, audience, and period to which it applies.
    • Important qualifiers that must remain attached to the claim.
    • The person who approved it and the event that should trigger re-review.

    This is especially important for comparisons, rankings, prices, performance statements, testimonials, guarantees, and claims about safety, health, money, or legal outcomes. Those claims warrant specialist review because an error can cause more than a correction or ranking loss.

    SEO and AEO teams should apply the same standard to structured data. A false or stale statement does not become safer because it appears in JSON-LD instead of visible copy. Confirm that product attributes, prices, availability, ratings, organizational facts, author information, and FAQ answers match the page and the underlying business records. If automation updates those fields, assign an owner to the feed and define what happens when the source system and published markup disagree.

    Use a release gate that is proportional to consequence:

    1. Extract each factual and implied claim from the draft.
    2. Verify it against evidence that actually supports the same scope and wording.
    3. Open every citation; don’t accept a plausible title, quotation, or URL without checking it.
    4. Restore necessary qualifiers, limitations, and effective dates that generation or editing removed.
    5. Confirm that the visible page, metadata, schema, advertisement, email, and chatbot answer do not make conflicting representations.
    6. Record the reviewer and approval before publication.

    Keep unverified material out of production. A visible internal status such as “UNVERIFIED – DO NOT PUBLISH” is more reliable than hoping a placeholder citation will be remembered during the final edit. If evidence cannot be found, remove or narrow the claim rather than polishing it.

    Keep personal data out until its handling is defensible

    Privacy exposure begins when information enters the workflow, not when the generated answer is published. Personal data may appear in prompts, uploaded documents, chat histories, feedback, retrieval indexes, output logs, analytics, or support transcripts.

    The regulatory landscape includes frameworks such as the GDPR in the European Union, PIPEDA in Canada, and the CCPA in California. Their requirements differ, so a generic global statement that “we comply with privacy law” is not an operational control. Determine which people, data, activities, and jurisdictions are involved. Have a privacy professional or qualified counsel decide the applicable legal basis and obligations.

    Before approving a workflow involving personal data, require clear answers to these questions:

    • What personal data is required, and can the task be completed with less data?
    • Why is the business using it, and is that use compatible with what the person was told?
    • Does the provider use prompts, files, outputs, or feedback to train or improve its systems?
    • How long are inputs, outputs, logs, backups, and derived data retained?
    • Where is the data processed, who can access it, and which other providers receive it?
    • Can the business locate, correct, export, restrict, or delete the data when required?
    • What security, incident-notification, deletion, and audit commitments appear in the contract?
    • Who owns the response when a customer or regulator asks how the data was handled?

    If the owner cannot answer those questions, don’t send the data yet. Use approved enterprise controls where available, remove unnecessary identifiers, or redesign the workflow around synthetic or non-personal material. Redaction is not automatically anonymization: remaining details may still make someone identifiable when combined. Ask the privacy lead to assess that risk when the data is sensitive or the context is distinctive.

    Separate privacy from confidentiality during the review. A document can contain no personal data and still expose trade secrets, contract-restricted information, security details, or a client’s confidential plans. Conversely, information may be publicly visible yet remain personal data governed by a specific use and jurisdiction. Give each category its own permission rule.

    Prepare a response path before an incident. The workflow owner should know how to pause the use, identify the account and provider involved, preserve necessary evidence without spreading the data further, contact privacy and security personnel, and route rights requests or regulator communications. Once a request or incident exists, don’t improvise deletion or send a casual explanation. Preservation, notification, and response duties can conflict, so counsel should direct the specific response.

    Build controls people can use at the moment of decision

    An employee pauses before entering customer information while a colleague verifies rights, accuracy, privacy, and release controls built into the workstation.

    A long AI policy won’t help if an employee cannot tell whether a customer file is allowed in a particular feature. Convert policy into a small operating system that answers the questions people face while working.

    • An AI use register with a named business owner for every recurring workflow.
    • An approved-tool matrix showing which accounts and features may handle public, internal, confidential, personal, and sensitive material.
    • A review matrix defining who approves public claims, intellectual-property-dependent work, personal-data uses, and consequential decisions.
    • A contract checklist covering provider data use, retention, deletion, security, intellectual property, notice of material changes, responsibility, and liability terms.
    • An evidence pack for each higher-exposure workflow containing the purpose, data decision, test results, human review, source records, and current approval.
    • A reporting route that lets staff pause questionable work without having to prove a legal violation first.

    Assign one accountable owner, but involve the functions that control the underlying risk. Marketing or SEO can own publishing accuracy; privacy can decide data handling; security can assess access and incident controls; procurement can preserve vendor commitments; and counsel can interpret rights, duties, and disputed contract language. “Legal owns AI” is not a workable substitute for operational ownership.

    Test the control with a real workflow. Ask a person unfamiliar with the project to locate the approved tool, permitted data class, required reviewer, evidence record, and stop condition. If those answers live in separate inboxes or depend on knowing whom to ask, the control is not ready for routine use.

    Key takeaways

    • Audit AI by business use, input, output, audience, and decision – not by vendor name alone.
    • For intellectual property, answer three separate questions: may you submit the input, may you use the output, and can you support the ownership being promised?
    • Verify every external claim and citation as a representation made by your company, including claims encoded in metadata and schema.
    • Do not process personal or confidential data until purpose, provider handling, retention, access, deletion, and response ownership are clear.
    • Keep evidence of meaningful human contribution, factual review, permissions, settings, and approval.
    • Escalate uncertain rights, high-consequence uses, incidents, and jurisdiction-specific questions to qualified counsel.

    Know when to stop the workflow

    Pause and obtain specialist advice when a workflow depends on unclear contract rights, sends sensitive or confidential information to an unapproved provider, appears to reproduce distinctive protected material, influences a high-consequence decision, or makes a claim that could materially affect someone’s health, safety, finances, legal position, employment, or access to a service.

    Stop routine handling immediately if you receive a demand letter, rights request, security alert, regulator inquiry, or credible complaint about harmful or misleading output. Don’t destroy records, admit liability, or continue publishing while the facts are unclear. Preserve the relevant evidence and let the appropriate legal, privacy, security, or compliance professional direct the response.

    Start with one live, public-facing AI workflow this week. Map its inputs, claims, data, reviewer, and evidence trail. Fix the first unresolved permission or approval gap before expanding the audit. That single completed workflow will give your team a control pattern it can repeat across the business.

    References

  • How Publishers Should Respond to a Suspected False DMCA Claim

    How Publishers Should Respond to a Suspected False DMCA Claim

    If investigative reporting disappears from Google after a copyright complaint, treat it as a two-track incident. You need to preserve the record showing how the work was created while identifying the precise route for restoring lawful visibility. Rewriting the page, replacing files, or accusing the claimant in public before you do either can make the dispute harder to untangle.

    The risk is not hypothetical. In one documented dispute, a March 27 notice accused Search Engine Land of copying text verbatim and using proprietary images, after which Google removed the affected URL from search results. Clickout Media’s alleged transformation of news sites into AI-driven gambling platforms was the investigation’s subject. The important operational lesson is that a copyright allegation can interrupt distribution before the underlying merits have been publicly resolved.

    Confirm what was removed before arguing about why

    A search delisting, hosting takedown, CDN block, CMS suspension, and deleted page are different failures. They affect different surfaces and require different remedies. Do not describe the reporting as “taken down” until you know which system stopped serving or surfacing it.

    1. Preserve the notice exactly as received. Save the message body, attachments, raw email headers, claimant details, alleged copyrighted work, disputed URL, case number, and receipt time. Export the platform dashboard entry as well as taking screenshots.
    2. Test the direct URL. Record whether it loads, redirects, returns an error, or displays a platform warning. Save the response code, page source, screenshot, and test time. A page that remains directly accessible but is absent from search has a different recovery path from one removed by its host.
    3. Check each discovery surface separately. Inspect Google results, Google Search Console messages, the XML sitemap, internal links, news or topic hubs, syndication copies, and any platform-specific index. Search results vary, so the absence of a result in one manual query is not enough by itself to establish a formal removal.
    4. Identify the decision-maker. Determine whether the action came from the search engine, hosting provider, CDN, registrar, CMS vendor, social platform, or another intermediary. Send a response to the organization that can actually reverse the action.
    5. Freeze mutable evidence. Export the published page, CMS revisions, drafts, source notes, media files, metadata, and rights records before changing anything. Make a read-only archive and record checksums for important files so later changes can be detected.

    Create one incident record with the disputed URL, notice identifier, affected services, first observed time, current page status, response deadline, internal owner, legal owner, and every action taken. This prevents editorial, SEO, engineering, and legal teams from creating conflicting versions of events.

    Do not evade a removal by immediately cloning the page to a new URL. That can multiply the disputed URLs, confuse canonical signals, complicate the evidence trail, and create additional legal exposure. Preserve first, then decide what may lawfully remain available with qualified counsel.

    Build an allegation-by-allegation evidence packet

    Original files, notes, photographs, metadata panels, and archival sleeves are organized into paired evidence groups on a worktable.

    A notice is not proven false merely because its timing looks suspicious or its effect is damaging. Treat “false,” “mistaken,” “unsupported,” and “abusive” as different conclusions. You need testable contradictions: the cited words do not appear on the page, the image was licensed, the claimant has not established ownership, the chronology is impossible, or the notice identifies the wrong URL.

    Question to testEvidence to assembleWhat the response should show
    Was text copied verbatim?Draft history, reporter notes, source links, timestamps, and a side-by-side comparison of the exact passagesWhich words are actually shared, where they appear, and whether the notice accurately describes the overlap
    Was an image used without permission?Original file, creator identity, license or assignment, receipt, attribution record, metadata, and the terms captured when the asset was obtainedWhich image is disputed and the specific basis on which it was published
    Does the claimant control the asserted rights?The work identified in the notice, its URL and publication date, the claimant’s stated relationship to it, and any ownership records suppliedWhether the notice connects the claimant to the particular material at issue
    What action actually occurred?Direct-URL tests, platform messages, Search Console records, screenshots, response codes, and timestampsWhich service restricted the page, when it happened, and whether the restriction is still active
    What changed after publication?CMS revisions, media replacements, redirects, correction notes, deployment logs, and editor approvalsA clean chronology that distinguishes the original publication from later edits

    Keep the evidence factual and compact. A platform reviewer should not have to infer your rebuttal from a folder of unrelated screenshots. Number each allegation, quote only the minimum text needed to identify it, attach the corresponding proof, and state the requested remedy for that allegation.

    Preserve unfavorable evidence too. If an image license is ambiguous or a passage is closer than expected, hiding that weakness will not improve the legal position. Flag it for counsel and separate it from allegations you can disprove cleanly. A mixed notice may contain an unsupported claim alongside a genuine rights problem.

    Choose the response path with counsel, not by reflex

    The fastest-looking option is not always the safest one. An informal correction request, platform appeal, asset replacement, negotiated resolution, and formal counter-notice carry different consequences. The right route depends on who acted, what the notice alleges, whether the material remains online, and what your evidence establishes.

    Start with a precise administrative response when appropriate

    If the platform offers an appeal or reinstatement process, answer the notice rather than the suspected motive behind it. A useful submission contains the case identifier, exact URL, current status, a numbered response to every allegation, supporting records, the requested action, and a contact authorized to handle follow-up.

    Avoid a long defense of the investigation’s public importance as a substitute for copyright evidence. Public-interest reporting may explain the stakes, but it does not by itself resolve who owns an image or whether wording was copied. Lead with the evidence that answers the claim.

    Treat a counter-notice as a legal act

    A formal counter-notice is not an ordinary customer-support reply. Depending on the process, it may require legal declarations, identification details, and consent connected to jurisdiction. An inaccurate submission can create exposure beyond the original search problem. Have qualified copyright counsel review the notice, the evidence, the governing procedure, and the final language before filing. If the publisher, claimant, or platform is outside the United States, counsel should also confirm which law and process actually apply.

    If you discover a genuine asset problem, preserve the original state before removing or replacing the asset. Record what changed, when, why, and who approved it. Let counsel decide whether any accompanying statement could be interpreted as an admission.

    Keep the public statement narrower than the evidence

    You can accurately say that a notice was received, a URL was affected, the claim is disputed, and a review or appeal is underway when those facts are documented. Do not label the claimant fraudulent, corrupt, or criminal merely because the notice appears weak. Those are separate allegations with their own evidentiary and legal risks.

    Coordinate the public statement with the formal response. A social post written in anger can contradict an appeal, disclose material intended for counsel, or lock the publisher into a conclusion before the evidence review is complete.

    Protect search and AI visibility without compromising the dispute

    An editor and counsel stand beside preserved files as parallel paths lead toward a legal process and an abstract online discovery network.

    Availability and discoverability are separate. A page can remain live for direct visitors while losing search distribution, which can also reduce the chance that search-connected AI systems retrieve or cite it. Recovery work therefore needs legal, technical, editorial, and communications owners working from the same incident record.

    1. Keep the established URL stable when publication remains lawful. Avoid unnecessary slug changes, redirect chains, or duplicate copies. Continue linking to the URL from relevant author, topic, and investigation pages unless counsel or the serving platform requires otherwise.
    2. Record every post-notice change. If wording, images, metadata, canonicals, redirects, or access controls change, preserve the previous state and log the reason. Silent edits blur the chronology that reviewers and counsel may need.
    3. Make authorship and publication data explicit. Accurate Article or NewsArticle structured data can identify the author, publisher, publication date, modification date, headline, and canonical page for machines. Schema helps systems interpret those public assertions; it does not prove copyright ownership, invalidate a notice, or guarantee restoration in search or an AI answer.
    4. Use only lawful distribution paths. Keep newsletters, feeds, archives, and authorized syndication copies functioning where rights and contracts permit. Do not create mirrors solely to route around a restriction.
    5. Monitor the actual failure mode. Track whether the direct page loads, whether the platform case changes, whether Search Console reports a new status, and whether the canonical URL returns to relevant results. A ranking fluctuation is not the same as reinstatement.

    Do not promise that structured data, internal links, or republication will force a frontier model to cite the investigation. Those measures can improve machine-readable provenance and create legitimate discovery paths, but none overrides a platform’s legal process.

    Make the next incident easier to defend

    The strongest preventive control is not a disclaimer. It is a publication record that can be assembled before a notice arrives. For investigative work, retain source notes, timestamped drafts, editorial approvals, original media, licenses, attribution decisions, screenshots of asset terms, correction history, and deployment records under a defined retention policy.

    • Create a dedicated intake address for copyright notices and route it to editorial, legal, SEO, and engineering owners.
    • Use a standard incident template containing the notice ID, claimant, asserted work, disputed material, affected URL, platform, deadline, evidence owner, legal status, search status, and approved public language.
    • Require provenance records for every non-original image, chart, document excerpt, and embedded media item before publication.
    • Keep CMS revision history and media replacements attributable to named users rather than relying on shared accounts.
    • Prepare platform-specific access instructions so the person handling the incident can reach hosting, CDN, Search Console, analytics, and syndication records without waiting for credentials.

    These controls will not prevent someone from filing a questionable notice. They reduce the time spent reconstructing authorship, rights, and platform status after the reporting has already lost distribution.

    Key takeaways

    • Confirm whether the page was deleted, blocked, deindexed, or merely absent from a particular query before choosing a remedy.
    • Preserve the notice, published page, drafts, source records, media provenance, platform messages, and technical status before making changes.
    • Rebut each allegation with matched evidence; suspicious timing alone does not establish that a DMCA claim is false.
    • Have qualified copyright counsel review any formal counter-notice or response that could create legal exposure.
    • Keep lawful URLs and provenance signals stable, but do not clone pages or use schema as a way to evade a platform restriction.

    Your first objective is a clean factual record, not the loudest rebuttal. Once that record exists, counsel can choose the legal route, the platform team can request the correct remedy, and the SEO team can restore discoverability without creating a second problem.

    References


  • EU Scrutiny of Google’s DMA Compliance: A Marketer’s Plan

    EU Scrutiny of Google’s DMA Compliance: A Marketer’s Plan

    If European search contributes meaningful traffic, leads, subscriptions, or sales to your business, the main risk isn’t missing the EU’s announcement. It is discovering a performance change later and having no reliable baseline to explain what moved, where it moved, or whether the ruling had anything to do with it.

    The European Commission opened its investigation of Google’s search business under the Digital Markets Act in March 2024. Competition Commissioner Teresa Ribera has said a decision will come, but she hasn’t committed to a date. You should use that uncertain window to prepare your measurement, ownership, and response process – not to guess the verdict.

    The ruling, the remedy, and the search change are different events

    A regulatory finding does not automatically tell you what a search results page will look like, when Google will alter a system, or how users will respond. Those are separate stages. Treating them as a single event is how teams end up attributing every ranking, cost, and traffic fluctuation to regulation.

    Work with three distinct clocks:

    • The legal clock: What the Commission decides, which conduct it addresses, what remedies it requires, and when any obligations take effect.
    • The product clock: What Google actually changes in search presentation, ad delivery, ranking systems, pricing mechanics, reporting, or access for competing services.
    • The performance clock: When those changes become visible in impressions, clicks, costs, conversions, referrals, citations, or revenue.

    Do not start the product or performance clock merely because a headline appears. First confirm that the final decision requires an operational change relevant to your market. Then confirm that a change has been deployed. Only after that should you test whether your data moved in a related way.

    Political pressure is also not a substitute for a decision. A coalition of 18 lobby groups and civil society organizations has asked for a substantial fine and definitive remedies. That request tells you enforcement pressure is high; it does not establish what the Commission will order. Likewise, Google’s approximately 90% share of the EU search market explains why the consequences could be broad, but market share alone does not predict the remedy.

    Create an internal tracking record now. Keep confirmed facts, outside demands, possible outcomes, observed Google changes, and measured business effects in separate fields. That small distinction will prevent speculation from hardening into an unsupported performance explanation.

    Watch four search surfaces, not one ranking chart

    Four abstract search interfaces show web results, local listings, product discovery, and an AI-style answer panel around a central workstation.

    A conventional rank tracker can tell you that a URL changed position. It cannot, by itself, show whether the page gained usable visibility, whether a new search feature displaced it, whether paid inventory changed above it, or whether an AI-generated answer absorbed the click. Your monitoring needs to cover the whole search experience.

    SurfaceBaseline to preserve nowSignal worth investigatingFirst response
    Organic searchQuery group, landing page, country, language, device, impressions, clicks, click-through rate, average position, and visible result featuresA sustained EU-specific change across related queries, pages, or result types rather than an isolated ranking movementInspect the actual results pages and identify which element gained, lost, or changed placement before editing content
    Paid searchCampaign, country, device, query class, impressions, click volume, cost per click, impression share, conversion rate, and cost per acquisition or return on ad spendCosts or delivery patterns moving in affected EU segments while comparable segments remain relatively stableCheck auction, placement, demand, budget, and conversion-quality signals before changing bids
    AI Overviews and publisher visibilityFeature presence on a fixed query sample, cited domains, cited URLs, brand mentions, organic clicks, and publisher referralsA repeatable change in feature frequency, source selection, citation prominence, or downstream trafficSeparate changes in AI presentation from ordinary blue-link ranking changes and record both
    Competitive discoveryReferral sources, partner traffic, comparison-service visibility, branded search demand, and assisted conversionsNew or expanded discovery paths producing qualified visits or conversionsValidate traffic quality and attribution before reallocating acquisition resources

    The Commission is also examining Google’s use of AI Overviews and its ranking of news publishers. Keep that scrutiny on a separate line in your change log. It may overlap with the same search ecosystem, but you should not assume every AI Overview or publisher-visibility change is part of the pending DMA decision.

    This distinction matters for diagnosis. If ordinary rankings remain stable but citations inside AI-generated results change, you have a source-selection or presentation question. If ad costs move while organic layouts remain stable, you have an auction or demand question. If impressions remain steady but clicks fall after a result-page change, you have a click-distribution question. Each pattern calls for different evidence and a different response.

    Build an EU search baseline before you need one

    A useful baseline is not a single export labeled “Europe.” EU markets differ by language, query demand, competition, device use, campaign structure, and commercial importance. Aggregate reporting can hide a serious movement in one market behind stability in another.

    1. Define the affected business scope. List the EU countries, languages, domains, subdirectories, storefronts, publications, and campaigns that matter to you. Assign an owner to each material segment.
    2. Freeze meaningful cohorts. Preserve groups for branded and non-branded queries, informational and commercial intent, product or service families, news content where relevant, and the landing pages that generate business outcomes. Do not rebuild the groups after performance changes.
    3. Add comparison segments. Use comparable non-EU markets, stable query groups, or unaffected product lines as diagnostic references. A comparison is not proof of causation; it helps show whether a movement is localized or part of a wider change.
    4. Record the visible search environment. For a fixed query sample, capture date, country, language, device, result order, ad presence, Google-owned modules, competing services, AI-generated features, citations, and other elements that can alter attention or clicks.
    5. Connect visibility to outcomes. Pair rankings and impressions with clicks, qualified sessions, conversions, revenue, subscription starts, lead quality, and paid acquisition costs. A visibility change with no business effect deserves a different response from a revenue change.
    6. Log confounding events. Record site migrations, content releases, schema changes, consent changes, campaign edits, promotions, outages, seasonality, and unrelated Google updates. Without this log, a regulatory explanation can become the default simply because it is prominent.

    Keep raw exports or snapshots as well as dashboards. A dashboard can be reconfigured, filtered incorrectly, or lose historical dimensions. Your preserved data should let another analyst reconstruct what users could see and what the business measured before any compliance-related rollout.

    Do not rewrite your JSON-LD in anticipation of an unknown remedy. Structured data should continue to describe the page’s real entities, offers, authorship, organization, products, articles, and relationships accurately. A regulatory change to distribution or presentation does not make inaccurate schema useful. If Google later publishes new eligibility or implementation requirements, evaluate those documented requirements against your existing markup and change only what the page supports.

    Apply the same discipline to AEO and GEO work. Clear answers, explicit entity relationships, attributable claims, and crawlable supporting detail remain useful, but they are not a workaround for a platform-level compliance change. Measure traditional Google visibility, AI-generated search visibility, and citations in other answer engines separately so a gain in one channel does not conceal a loss in another.

    Prepare for scenarios without pretending to know the remedy

    A strategy team examines three branching, unlabeled search-market scenarios on an illuminated planning table.

    Your plan should cover plausible operational outcomes without presenting any of them as the expected verdict. The goal is not to forecast Brussels. It is to know which evidence would trigger which action.

    A penalty arrives without an immediate visible search change

    A financial penalty can dominate coverage while producing no immediate change that users or advertisers can see. In that scenario, annotate the decision date but leave content, bids, and technical implementation alone unless the data or the remedy gives you a reason to act. Continue monitoring for a later rollout rather than forcing a same-day explanation onto normal volatility.

    A remedy changes result presentation or access

    If a remedy affects how Google presents its own services, rival services, publishers, or other result types, position alone will be an incomplete metric. Compare the same queries before and after deployment. Record which modules appear, how much prominence they receive, which destinations win the click, and whether the new traffic converts.

    Do not immediately rewrite pages that lose clicks while retaining rank. First determine whether the content became less competitive or whether another interface element intercepted attention. Content changes address the first problem; measurement, distribution, and channel changes may be needed for the second.

    Ad serving, ranking, or pricing mechanics change

    The pending decision could affect ad serving, ranking, or pricing dynamics, but the direction and size of any effect are not known. Paid search teams should preserve campaign-level and market-level baselines now, including the relationship between cost, placement, demand, conversion quality, and revenue.

    If costs move, do not assume the compliance decision caused them merely because the dates are close. Check whether demand, competitors, match behavior, budgets, creatives, landing pages, tracking, or conversion mix changed at the same time. When financial exposure is material, use capped and reversible bid or budget adjustments while you investigate. A sweeping change can create additional cost and destroy the comparison you need.

    AI Overview or news-publisher action moves on a separate track

    A change involving AI Overviews or publisher ranking may be important without being the remedy in the core DMA search case. Label the responsible proceeding or product update whenever you can confirm it. If you cannot, describe the observation plainly – such as a change in citation frequency or publisher clicks – and leave the cause unassigned.

    That restraint improves your decisions. It also keeps executive reporting credible when several regulatory investigations, product releases, and market shifts are unfolding in the same ecosystem.

    Key takeaways and the response plan to use

    • The EU decision, Google’s implementation, and the resulting performance effect should be tracked as separate events.
    • A fine or demanded remedy is not evidence that a visible search change has already happened.
    • Segment EU performance by country, language, device, query type, page group, and paid or organic channel before relying on an aggregate trend.
    • Monitor search-result composition, AI citations, ad delivery, costs, clicks, and business outcomes – not rankings alone.
    • Keep AI Overview and news-publisher scrutiny separate from the core DMA case unless the final decision explicitly connects them.
    • Preserve accurate structured data and content facts; do not make speculative technical changes for an unknown remedy.
    • Use reversible commercial adjustments until multiple related signals support the same diagnosis.

    When the decision is published

    1. Read beyond the headline. Obtain the official decision or authoritative summary and identify the finding, conduct in scope, required remedies, geographic scope, covered services, effective dates, and unresolved points.
    2. Write a short decision brief. Separate confirmed obligations from possible product implications. Include an explicit “unknown” section so assumptions remain visible.
    3. Map each remedy to an observable surface. Assign organic search, paid search, analytics, publisher, AI visibility, legal, and product owners only where their systems are genuinely affected.
    4. Annotate your measurement systems. Record the decision date, announced implementation dates, and first observed rollout separately. Do not use one generic marker for all of them.
    5. Compare against the preserved baseline. Look for related movements across geography, device, query groups, search features, clicks, costs, and conversions. An isolated metric is a prompt to investigate, not a conclusion.
    6. Choose the smallest reversible response. Adjust monitoring, experiments, bids, distribution, or content only to the degree supported by evidence. Preserve a comparison group wherever the business can safely do so.
    7. Report causality carefully. Use “coincided with” or “followed” until you can connect the legal requirement, the deployed product change, and the measured effect. Timing alone does not establish cause.

    If the ruling creates legal obligations for your own company, counsel should interpret those obligations. For the search and marketing teams, the immediate job is operational: preserve evidence, identify the actual implementation, and protect performance without making speculative changes.

    You do not need a confident prediction to be ready. You need a clean EU baseline, named owners, a record of what changed, and a rule that no irreversible action happens before the evidence identifies the affected surface. Put those pieces in place while the decision is still pending, and the eventual verdict becomes a manageable measurement event rather than a scramble.

    References

  • How to Find and Close Law Firm Referral Conversion Gaps

    How to Find and Close Law Firm Referral Conversion Gaps

    A trusted contact recommends your firm by name. The prospective client sounds ideal. Then nothing happens. They never call, or they start an inquiry and disappear before scheduling.

    That does not necessarily mean the referral was weak. Before contacting you, the prospect may search for the firm, inspect a lawyer’s profile, look for experience with the exact legal issue and ask an AI assistant for another opinion. Your digital presence and intake process must confirm the trust transferred by the referrer. If either introduces doubt, a strong referral can lose momentum.

    Key takeaways

    • A referral earns serious consideration, not an automatic consultation or engagement.
    • Most referral losses can be investigated as credibility, specificity, authority or friction gaps.
    • The best validation page mirrors the precise reason the firm was recommended, identifies the relevant lawyer and offers an obvious next step.
    • JSON-LD can clarify the relationship among the firm, its lawyers, locations and services, but it cannot compensate for vague or unsupported claims.
    • Measure each handoff separately so you can distinguish a marketing problem from an intake, qualification or scheduling problem.

    A referral starts a validation journey, not a straight line

    The referrer has already done valuable work. They have transferred some of their credibility to your firm and given the prospect a reason to pay attention. But the prospect still has questions: Does this firm really handle my kind of matter? Is this the lawyer I was told about? Does the firm’s public record support the recommendation? Can I see what to do next?

    The difference between what the prospect was promised and what they can corroborate is a referral validation gap. It appears after the recommendation but before a productive conversation with the firm. That location matters. If you only examine retained clients or completed intake forms, the people who vanished during validation remain invisible.

    Think of the journey as a sequence of trust handoffs:

    1. Recommendation: Someone associates your firm with a specific problem, lawyer or result they believe you can pursue.
    2. Verification: The prospect checks your website, search results, professional profiles, reviews or AI-generated answers.
    3. Contact: They decide whether the available evidence justifies a call, form submission or consultation request.
    4. Intake: Your team confirms fit, handles the inquiry and establishes the appropriate next step.
    5. Engagement: The prospect makes a separate decision about retaining the firm under the applicable terms.

    A break at one stage should not be blamed on another. A prospect who cannot find the recommended practice on your website has a validation problem. Someone who starts a form but abandons it has encountered friction. A qualified caller who waits without knowing what comes next has an intake problem. Treating all three as a generic conversion issue leads to unfocused redesigns and more content that does not answer the original doubt.

    Start by reconstructing the promise that brought the prospect to you. Review referral notes, intake records and the language your lawyers hear from frequent referral partners. You are looking for the actual expectation: a named lawyer, a narrow matter type, a particular client situation, a location or a combination of these. That expectation becomes the standard against which the public journey is audited.

    Diagnose the four places trust can break

    A prospective client moves through four connected spaces representing a firm entrance, lawyer profile, legal consultation and intake desk.

    Referral losses become easier to fix when you classify the first point of doubt. The four useful categories are credibility, specificity, authority and friction. They can overlap, but one usually appears first in the prospect’s journey.

    GapQuestion in the prospect’s mindWhat to inspectFirst repair
    CredibilityDoes this look like the firm I was promised?Firm and lawyer names, current biographies, office details, visible credentials, page condition and consistency across profilesMake identity, relevant credentials and contact information immediately clear and consistent
    SpecificityDo they handle my exact kind of matter?Page titles, headings, service descriptions, lawyer experience, examples and answers to matter-specific questionsCreate or improve a page that addresses the recurring referral reason in the prospect’s language
    AuthorityCan anything outside this recommendation confirm the expertise?Professional profiles, third-party mentions, search results, AI answers, entity consistency and structured dataCorrect public facts, connect corroborating profiles and make supported claims machine-readable
    FrictionHow do I take the next step, and what will happen?Mobile navigation, phone links, form fields, required information, confirmation messages, routing and follow-upOffer one clear action, request only what intake needs and set an accurate expectation for the response

    A credibility gap is not merely an unattractive design. It can be a former lawyer still presented as current, inconsistent firm names, an incomplete biography, an office address that conflicts with another profile or credentials buried below generic promotional copy. Correctness and recognizability matter more than visual novelty.

    A specificity gap often hides behind a technically accurate but broad practice page. A prospect referred for a narrow commercial dispute does not receive much reassurance from a heading that only says commercial litigation. They need enough detail to recognize their situation and understand why the named lawyer or team is relevant. You do not need to predict the merits of an individual case. You do need to show that the category is familiar.

    An authority gap appears when your own claim has no accessible support. A biography may call a lawyer experienced, but search results, professional listings and publicly retrievable material do not connect that person to the matter. AI systems may then omit the firm, confuse lawyers with similar names or repeat incomplete information. Structured data can clarify supported facts, but independent corroboration still matters.

    A friction gap happens after the prospect is persuaded enough to act. Common symptoms include an unclear primary call to action, a form that asks for more information than initial triage requires, a phone number that is difficult to use on mobile, no confirmation that a request arrived or no explanation of what follows. These details are especially costly because the person has already crossed the harder trust threshold.

    Audit the journey from the prospect’s side. Search the firm name, the referred lawyer and the specific issue. Repeat the check on mobile. Inspect the landing page a searcher is most likely to reach rather than starting from the homepage. Ask representative questions in the AI interfaces your audience may use, then record whether the firm appears, whether the description is accurate and which public information seems to support the answer. The first material contradiction or missing answer is usually the most valuable repair.

    Build a page that confirms the exact referral promise

    Your homepage cannot validate every referral. Its job is orientation. A referral-specific service page, lawyer biography or focused landing page should do the confirming.

    Build these pages around recurring referral reasons, not every keyword variation you can imagine. If several trusted contacts send people to a particular lawyer for a defined kind of matter, the site should provide a short path connecting that lawyer, that problem and the next step. The page needs to answer the prospect’s validation questions in a sensible order:

    1. Match the expectation in the heading. Name the specific service or problem clearly. A prospect should not have to infer it from a broad department label.
    2. Define the relevant scope. Explain the kinds of situations the page covers, the clients it serves and any geographic or jurisdictional boundary needed to understand the offering.
    3. Identify the responsible lawyer or team. Link to current biographies and make each person’s role clear. Do not force the visitor to search the staff directory again.
    4. Show support for the claim. Use accurate credentials, representative experience, authored material, speaking activity or other evidence the firm is permitted to publish. General praise is not evidence.
    5. Explain the next step. State what the prospect can request, what information is appropriate to share initially and what happens after submission.
    6. Provide one dominant action. Make the consultation request, call or other intake route easy to find and use on the device in the visitor’s hand.

    The opening screen should carry most of the recognition work. Include the matter, the relevant lawyer or team where appropriate, the firm identity and a clear action. Awards, office photography and general brand language can support that information, but they should not displace it.

    Specific content needs boundaries as much as detail. State what the service covers without suggesting that every visitor has a viable claim or that an outcome is assured. Do not turn a landing page into individualized legal advice. Before publishing testimonials, awards, representative matters or response commitments, have the responsible lawyer verify accuracy, permissions, confidentiality and the professional-advertising rules that apply in each relevant jurisdiction.

    Internal links should preserve the same chain of meaning. A lawyer biography should link to the specific service. The service page should link back to the lawyer. Relevant educational content should identify its author and lead to the appropriate intake route. Breadcrumbs and navigation should make the broader practice relationship understandable without forcing the prospect back through the homepage.

    Do not publish a page and assume the wording matches the referral. Read it next to the expectation you reconstructed. If the referral promise is about a named lawyer handling a narrow issue but the page leads with a generic firm slogan, the gap remains. The test is not whether the page sounds polished. It is whether a prospect can say, with minimal interpretation, that they reached the right firm for the reason they were given.

    Make your authority readable by people, search engines and AI

    Your reputation may be obvious inside a professional network and nearly invisible outside it. Search engines and AI answer systems work from accessible information, not private referral history. They need consistent entities, explicit relationships and public evidence that supports the firm’s claims.

    Begin with the visible facts. Use the same current firm name, lawyer name, office information and service terminology across the website and maintained third-party profiles. Correct old biographies and duplicate location records. Link to authoritative professional profiles where appropriate. A citation, directory entry or publication byline should corroborate a real fact, not exist merely to increase the number of mentions.

    Then use JSON-LD to describe what the page already says. Depending on the page and the facts available, Schema.org types such as Organization or LegalService can represent the firm, Person can represent an individual lawyer, and BreadcrumbList can describe the page’s place in the site. Stable @id values can connect those entities across pages. Relevant properties may describe the canonical URL, contact details, address, service area and maintained profile links.

    The governing rule is simple: markup must mirror visible, accurate content. Do not use structured data to manufacture an award, specialty, review, office, service area or affiliation that a visitor cannot verify. Do not add an FAQ entity unless the questions and answers are actually present on the page. Schema can reduce ambiguity; it cannot turn an unsupported assertion into authority or guarantee that an AI system will mention the firm.

    Use this sequence when reviewing the implementation:

    1. Choose the canonical page for each firm, lawyer, office and recurring service concept.
    2. Confirm that its visible text is complete, current and approved.
    3. Assign only Schema.org types that accurately describe the entity represented on that page.
    4. Give each important entity a stable identifier and connect related entities rather than creating isolated markup fragments.
    5. Validate the syntax and compare every material property with the visible page.
    6. Recheck the output after biography, office, service or branding changes.

    AI visibility needs its own audit, but not a one-off vanity search. Create a controlled set of questions based on genuine referral language. Include branded verification questions, lawyer-and-matter questions and unbranded service questions. Record the interface or model, the wording, the date, the answer, the firms mentioned and the cited or linked evidence when the interface provides it.

    Answers can vary by system, session and available retrieval, so one favorable response is not a ranking report. Look for repeated failure patterns instead. If the system recognizes the firm but assigns the wrong service, fix entity and content clarity. If it recognizes the service but not the relevant lawyer, strengthen that connection on both pages and in the markup. If competitors are consistently supported by clearer third-party evidence, the missing layer is authority rather than another rewrite of your homepage.

    Remove intake friction and measure each handoff

    A prospective client and intake specialist use a smartphone and appointment calendar at a tidy desk beside an open consultation room.

    A validation path is unfinished until a persuaded prospect can act. The intake experience should preserve the context and confidence built by the referral rather than making the person start over.

    Use an action label that tells the prospect what they are requesting. Make phone numbers usable on mobile. Keep the initial form to information the team truly needs for routing and conflict or fit screening. Avoid inviting detailed or highly sensitive case facts into a general web form; move that exchange to an appropriately secure, approved process. The confirmation screen and message should acknowledge receipt, state the response window the team can reliably meet and avoid implying that submission alone creates an attorney-client relationship.

    Preserve referral context in the handoff. An optional referral-source field can help, but do not depend on the prospect knowing a formal organization or campaign name. Pass the landing page and selected service into the intake record when your privacy practices and systems permit it. If a receptionist or intake specialist receives the inquiry, they should be able to see the matter category and the lawyer or page that prompted the contact.

    Measure the journey as separate stages:

    • Referral identified
    • Relevant validation page reached
    • Contact action started
    • Contact completed or call connected
    • Inquiry screened as an appropriate fit
    • Consultation offered and scheduled
    • Engagement completed

    You will not be able to identify every referred visitor before they contact you. Use observable cohorts honestly: dedicated partner links without personal information, referral landing pages, a voluntary intake field, call-source notes or another privacy-appropriate mechanism. Do not inflate the denominator with visitors whose source you cannot establish.

    The useful rates correspond to different decisions. Contact completion rate compares completed inquiries with started contact actions. Qualified consultation rate compares scheduled consultations with referred inquiries that met the firm’s criteria. Engagement rate compares opened matters with completed referred consultations. Keep definitions stable so a change in intake labeling does not masquerade as a conversion improvement.

    Read the drop-off pattern before choosing a fix:

    • Validation-page visits are visible but contact actions are scarce: inspect credibility, specificity and authority before redesigning the form.
    • Form starts are healthy but completions are weak: inspect required fields, error handling, mobile usability, privacy concerns and unclear expectations.
    • Inquiry volume is healthy but fit is poor: align the page and referrer-facing language with the matters the firm actually accepts.
    • Qualified inquiries do not become scheduled consultations: inspect routing, response handling, availability and the clarity of the next step.
    • Consultations occur but engagements do not: examine expectation-setting and the consultation process instead of attributing the loss to website traffic.

    Referral traffic is often too limited or uneven for a rapid A/B test to produce a dependable answer. Use the evidence you actually have. Establish a baseline, fix the earliest known break, annotate the change and compare the same stage over an appropriate later period. Pair the numbers with intake notes and reasons for loss. A smaller, clearly defined cohort is more useful than a large blended conversion rate covering unrelated practices and acquisition channels.

    Start with one valuable, repeatable referral path. Write down the promise, reproduce the prospect’s verification journey and fix the first place your public presence fails to confirm it. Once that path is coherent from recommendation through intake, turn its page structure, entity connections and measurement stages into a template for the next referral category.

    References


  • What the Reddit-SerpApi Scraping Fight Means for SEO Data

    What the Reddit-SerpApi Scraping Fight Means for SEO Data

    If your SEO or AI workflow retrieves Reddit material from Google result pages rather than from reddit.com, you may be tempted to label it indirect public data and move on. The Reddit-SerpApi dispute shows why that shortcut is dangerous: the address you requested is only one part of the legal and operational analysis.

    SerpApi is asking a federal court to dismiss Reddit’s amended complaint. Reddit alleges that large amounts of its content were extracted through Google Search. SerpApi counters that it accessed Google pages, that Reddit does not own most user posts, and that Reddit has not adequately established technical circumvention or concrete harm. Those are opposing positions, not judicial findings. Until the court rules, neither side’s argument gives your team permission to treat a similar pipeline as settled law.

    Key takeaways

    • Fetching a Google result page instead of visiting Reddit directly changes the facts, but it does not automatically eliminate copyright or access-control questions.
    • Audit the actual payload. URLs, rankings, dates, short snippets, full comments, and complete threads create different copying and provenance issues.
    • Public visibility and technical circumvention are separate questions. A page can be publicly viewable while the collection method still encounters controls that demand legal review.
    • Content ownership and platform licensing are also separate. A user’s ownership of a post does not, by itself, prove that every third-party reuse is lawful.
    • Your safest immediate investment is traceability: retain acquisition routes, response fields, control events, transformations, retention rules, and downstream recipients for every dataset.

    The dispute turns “scraping” into five separate questions

    Five symbolic lenses surround a transparent pipeline carrying abstract content tiles, with a doorway, hand, blank documents, circuit gate, and application modules representing different areas of review.

    Calling a system a scraper tells you almost nothing about its legal posture. A useful review separates who holds rights, what was copied, where the response came from, how the collector reached it, and what harm is alleged. Mixing those questions is how a technical description such as “we only queried Google” gets mistaken for a legal conclusion.

    QuestionDisagreement in the caseWhat your team should preserve
    Who holds rights in the material?SerpApi relies on Reddit’s user arrangements to argue that users retain ownership and Reddit generally holds a non-exclusive license.The creator, platform, applicable terms, asserted license, and rights basis for each collected field.
    What exactly was copied?SerpApi argues that the examples identified by Reddit include dates and short fragments that are not protectable expression.Representative payloads showing whether you store metadata, snippets, comments, threads, media, or combinations of those fields.
    Which system returned the data?SerpApi says it accessed Google Search pages rather than interacting directly with Reddit.Requested hosts, final URLs, redirects, response headers, collection jobs, and the origin assigned to each field.
    Was a technical measure circumvented?SerpApi says Reddit has not shown an encryption breach or authentication bypass and characterizes the pages it accessed as publicly available.Authentication states, challenge pages, block responses, rate-limit events, bot defenses, retries, proxy changes, and any code intended to handle them.
    What harm followed?SerpApi argues that Reddit has not adequately pleaded tangible harm caused by its conduct.Collection volume, retention, redistribution, customer access, substitution for the original service, incident reports, and takedown history.

    Keep the five answers independent. If Reddit cannot establish ownership of particular user posts, that may weaken an ownership-dependent theory, but it does not prove that every use of those posts is lawful. If a date or fragment lacks enough expression to be copyrightable, that does not resolve how the system obtained it. If no access control was circumvented, that may answer one DMCA theory without answering every other issue raised by the collection and reuse.

    The current procedural posture matters too. A motion to dismiss challenges whether the complaint states legally sufficient claims; it is not a factual finding that the challenged conduct was lawful. If the claims survive, that likewise means they can proceed, not that Reddit has already proved liability.

    Why the Google layer is not a legal shield

    An indirect pipeline has at least three layers: Google returns a search page, that page contains material derived from Reddit, and your system stores or republishes some part of the result. The host that returned the bytes is relevant, but it does not identify every party with an interest in the content or collection method.

    Reddit’s allegation involving a decoy post created solely for Google’s crawler is important for that reason. Reddit uses the alleged appearance of that material to support its account of how the defendants acquired Reddit-derived content through Google. SerpApi answers that an ordinary user could see the same material in public search results. The court still has to decide whether Reddit’s allegations are legally sufficient and, if the case proceeds, what the evidence establishes.

    There is also an upstream problem. Google separately alleges that SerpApi bypassed bot protections while scraping licensed search functionality. SerpApi has sought dismissal there as well, arguing that the DMCA is being used to restrict access to public search results. In practical terms, routing collection through a search engine may exchange one platform-access question for another rather than remove the question entirely.

    For an SEO, AEO, or GEO system, review both sides of that route. First ask whether the collector was permitted to obtain the search response in the manner used. Then ask what rights and restrictions may follow the Reddit-derived material inside that response. Do not let a clean answer at one layer stand in for an answer at the other.

    Run a field-level audit before expanding collection

    Gloved hands sort the separated fields of a generic web record into color-coded trays beside a magnifying lens, privacy shield, timer, and source trail.

    Your lawyers cannot evaluate a label such as “SERP data,” and your engineers cannot implement advice framed only as “reduce scraping risk.” Give both groups a field-level map of the system. This is not a substitute for legal advice about your particular facts; it is the evidence package that makes useful advice possible.

    1. Map the complete request path. Record the initial host, redirects, rendered page, APIs or browser automation involved, proxy layer, authentication state, and retry logic. Distinguish a request sent to Google from a later request sent to Reddit.
    2. Define the collection unit. List every retained field: query, rank, result URL, title, date, snippet, author name, subreddit, comment text, thread text, media, and cached page. Do not describe a full-thread archive as metadata merely because the job began on a search page.
    3. Attach provenance to each field. Store the page that supplied it, the underlying content platform when known, the collection time, and the transformation applied. A field should not lose its origin when it moves from raw storage into a feature table, embedding index, model corpus, or customer export.
    4. Document the rights theory instead of assuming one. For each field, state why the organization believes it may collect, retain, transform, and distribute that material. Flag any theory that reduces to “it was public” for legal review.
    5. Preserve control events. Log authentication prompts, denied responses, block pages, rate limits, bot challenges, and code changes made in response. Do not instruct a collector to evade a control while waiting for counsel to decide whether the control matters.
    6. Trace every downstream use. Separate internal measurement from customer-facing display, bulk export, dataset resale, AI training, retrieval-augmented generation, and verbatim output. The same input can create a materially different question when the product begins returning the original text to other people.
    7. Build deletion and shutdown paths. You should be able to stop one connector, one field, one customer export, or one corpus without taking the entire product offline. Also identify derived stores, such as embeddings and caches, that would otherwise survive deletion of the raw record.

    The resulting audit record can be compact. For each collection job, capture the system owner, requested host, content origin, fields retained, controls encountered, asserted rights basis, retention period, downstream recipients, deletion path, and stop trigger. If your team cannot fill in one of those entries, mark it unknown rather than turning an assumption into policy.

    Payload minimization is especially useful while the law remains contested. A rank-monitoring feature may need a result URL and position but not a permanent archive of every Reddit snippet. A citation feature may need a URL and a short display label but not the full discussion. An AI discovery tool may need topical signals while having no product reason to reproduce complete comments. Delete fields that do not support a named function, and stop collecting them at ingestion rather than relying only on later cleanup.

    Be equally precise about AI use. “Used for AI” can mean measuring whether Reddit appears in search results, retrieving a passage at query time, generating embeddings, fine-tuning a model, or displaying source text beside an answer. Record those as distinct operations. Otherwise, a rights review performed for internal analytics can silently become the justification for a customer-facing content product it never evaluated.

    Plan for the ruling without betting your product on it

    A result for either side will be easy to overread. A dismissal based on Reddit’s ownership allegations would not necessarily approve every method of collecting Google results. A ruling focused on short, unprotectable fragments would not automatically cover full comments or threads. A conclusion that the alleged conduct did not amount to circumvention would depend on the controls and access path before the court, not on the generic fact that software performed the request.

    A dismissal with prejudice would end Reddit’s claims against SerpApi in this instance. It would not function as a universal license for SERP scraping, Reddit reuse, or AI training. Conversely, if the amended complaint survives dismissal, that would allow the litigation to continue without establishing that every comparable SEO tool is unlawful.

    You can make several product decisions now without predicting the winner:

    • Freeze expansion of any job whose access route, collected fields, or response to technical controls cannot be reconstructed.
    • Replace blanket claims such as “public data is safe to scrape” with a review that names the host, payload, controls, rights basis, and downstream use.
    • Separate collection modules by platform and field so one disputed input can be disabled without breaking unrelated search intelligence.
    • Require approval before an internal dataset becomes a customer export, training corpus, or feature that displays source language.
    • Give legal and engineering owners the same incident trigger: a new block mechanism, authentication requirement, complaint, takedown request, or material change in collection volume should reopen the review.
    • Preserve enough technical history to explain what the system did before a dispute begins. Reconstructing access behavior after logs have expired leaves both counsel and engineers working from memory.

    Your immediate job is not to decide whether Reddit or SerpApi will win. It is to make your own pipeline explainable and stoppable. If you cannot identify who returned the data, who created it, what you retained, which controls you encountered, and where the material went next, pause the expansion and complete that map first.

    References