Category: Legal

  • Google Ad-Tech Antitrust Litigation: A Publisher’s Playbook

    Google Ad-Tech Antitrust Litigation: A Publisher’s Playbook

    If you depend on programmatic advertising revenue, the Google ad-tech litigation creates a planning problem before it creates a financial opportunity. The wrong response is to put a recovery into your forecast or make a rushed platform change. The useful response is to determine whether your business touches the surviving claims and whether you can still explain, with records, how money moved through your ad stack.

    Major claims remain alive, but that is not the same as a finding that every publisher was harmed. Your immediate job is to separate what the court has established, what the publishers still must prove, and what evidence your own legal and finance teams would need to evaluate any potential exposure or recovery.

    The ruling preserved a path, not a payout

    On Sept. 30, U.S. District Judge P. Kevin Castel issued an 88-page opinion denying Google’s requests for summary judgment on the publishers’ principal ad-tech claims. He also declined to exclude important expert testimony supporting their damages cases.

    Summary judgment is a pretrial mechanism for resolving claims that do not require a trial to decide. Denying it means Google did not persuade the court to dispose of the principal claims on the pretrial record. It does not mean the publishers have won a damages award, that every expert assumption has been accepted, or that every remaining dispute will necessarily reach trial.

    What the decision didWhat it did not do
    Kept the publishers’ principal ad-tech claims in the litigationDecide how much, if anything, Google owes
    Allowed key damages testimony to remain in the caseAdopt the experts’ estimates as proven losses
    Preserved claims involving the AdX publisher class and Mikula Web SolutionsPreserve every claim brought by every plaintiff
    Prevented Google from relitigating certain findings from the separate Virginia caseEstablish injury and damages for each publisher automatically

    The mixed outcome matters. Castel ruled for Google on the New York General Business Law claims brought by Gannett and Daily Mail, on claims brought by The Progressive, and on Inform’s federal antitrust claims. Claims involving the AdX publisher class and Mikula Web Solutions were allowed to continue. A headline saying publishers cleared a major hurdle is accurate, but it is too broad to answer whether a particular company, legal theory, or alleged loss remains in play.

    When you brief executives, use a claim matrix rather than a win-or-loss label. Give each claimant and legal theory its own row, then record whether the claim survived, which issues are already established, which issues remain disputed, and what procedural event comes next. That prevents a partial ruling from turning into an inaccurate company-wide assumption.

    The economic dispute sits between inventory and demand
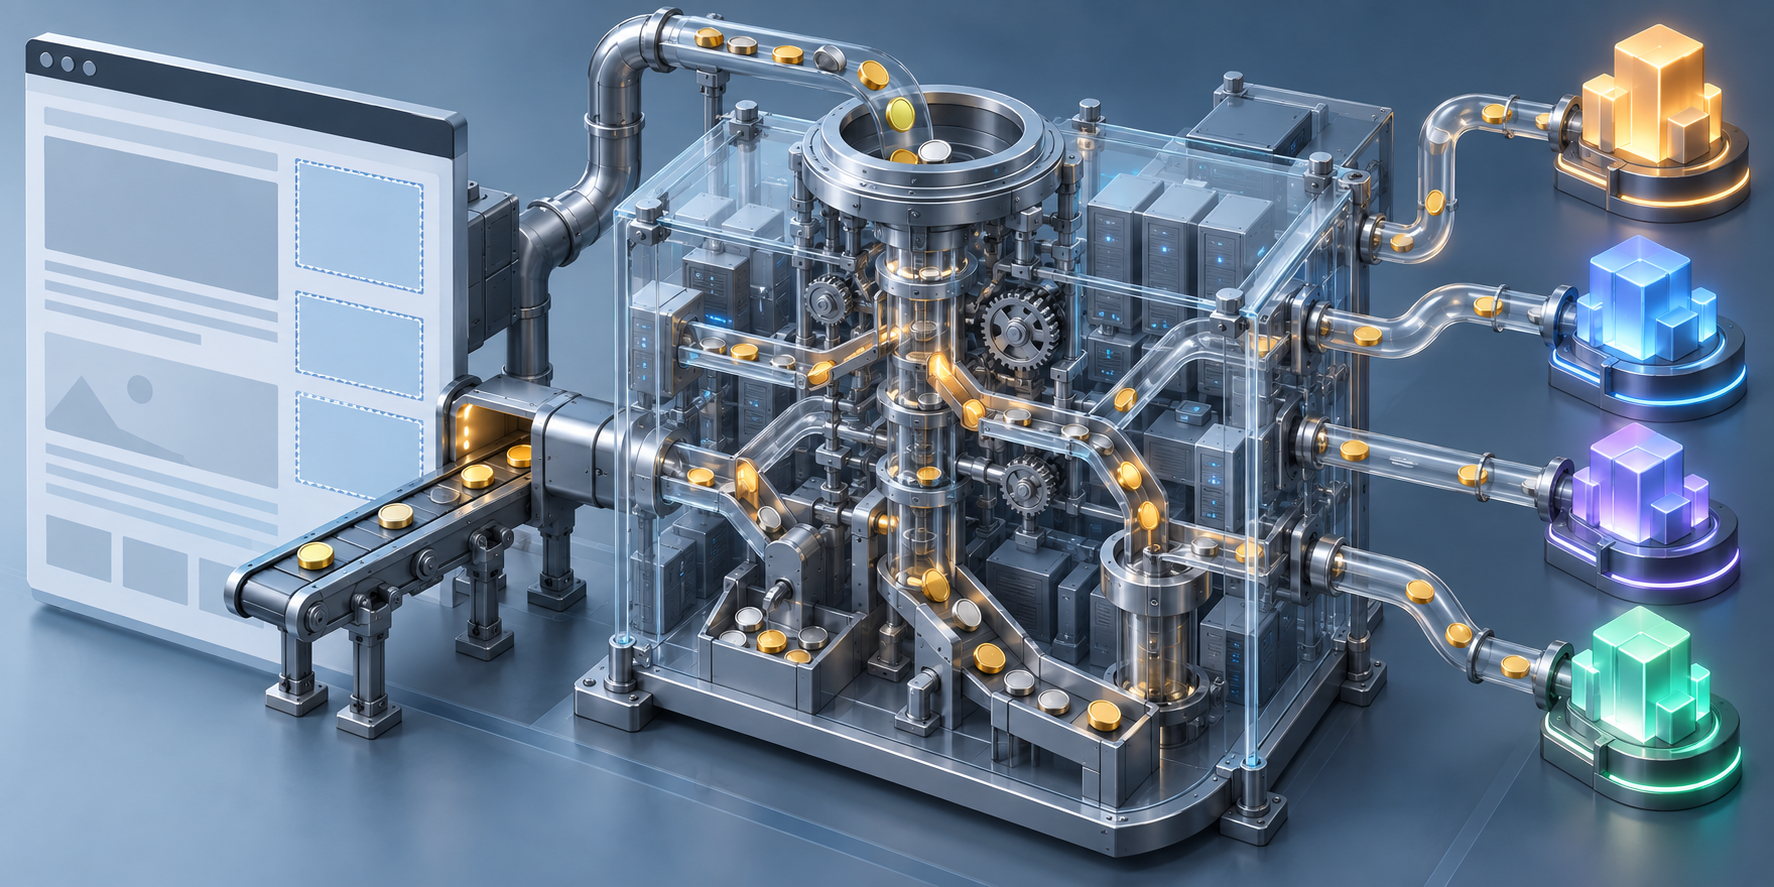
    An abstract publisher page and advertiser nodes connected through a layered auction system carrying metallic tokens.

    A publisher ad server manages advertising inventory and helps decide which demand source can fill an opportunity. An exchange provides a marketplace in which demand can compete for that inventory. When one company controls important infrastructure on both sides of that handoff, the rules connecting the products can affect which demand participates, how an auction operates, what fees are charged, and what reaches the publisher.

    That connection is central here. The publishers allege that Google’s control over its publisher ad server and the AdX exchange, combined with practices governing ad auctions, reduced publisher revenue or produced excessive fees. Google contests those allegations. The disputed question is therefore not simply whether publishers used Google technology; it is whether challenged conduct caused a measurable economic injury.

    The litigation also draws on the federal government’s separate ad-tech case in Virginia. Castel had already determined that Google could not relitigate certain findings from that proceeding, including the finding that Google unlawfully tied its publisher ad server to AdX. That gives the publisher plaintiffs an important established point, but it does not calculate the consequences for a particular publisher. Injury, causation, and damages still have to be connected to the conduct at issue.

    For your business, the practical unit of analysis is an ad-monetization dependency map. It should show:

    • The legal entities, sites, applications, and business units that sold digital inventory.
    • The publisher ad server and exchanges used during each relevant period, including migrations and material configuration changes.
    • Which demand paths were direct, exchange-based, mediated, or otherwise dependent on the publisher ad server.
    • The contracts, amendments, fee schedules, invoices, and reporting accounts associated with each path.
    • The identifiers that connect domains, properties, accounts, reports, and payment records across systems.
    • The employees or vendors who understood auction configuration, yield management, billing, and reporting definitions at the time.

    This map does not establish that you belong to a class or have a claim. It gives counsel the facts needed to assess those questions without relying on institutional memory. It also reveals whether a change in revenue coincided with traffic, inventory, auction, fee, or platform changes instead of treating every decline as one undifferentiated problem.

    Do not mistake the damages estimates for recoverable amounts

    The public figures are large because they are damages estimates prepared by experts retained by the plaintiffs. They are not court-awarded compensation:

    Claimant or groupPlaintiffs’ expert estimate
    GannettRoughly $901 million
    Daily Mail$600 million
    Publisher class$1.72 billion through March 31, 2024

    The plaintiffs claim additional class damages after March 31, 2024, but no additional amount was provided. Do not extend the $1.72 billion estimate beyond that date, apply it as a percentage of industry revenue, or use it to derive a hypothetical recovery for your company. None of those calculations is supported by the disclosed figures.

    An expert’s testimony can remain admissible while its assumptions, method, causal reasoning, and conclusions remain disputed. The publishers still need to prove that the challenged conduct injured them and that the requested damages are attributable to that conduct. Google can continue contesting those points.

    Your finance team should therefore treat the amounts as allegations supported by the plaintiffs’ models, not as receivables or operating income. If you need an internal scenario, build it in layers:

    1. Use zero recovery as the operating baseline unless legal and accounting advisers determine otherwise.
    2. Ask counsel whether the relevant legal entity, products, time periods, and transactions could fall within a surviving claim or class.
    3. Identify which revenue, fee, and auction records could support or contradict economic injury.
    4. Document every assumption in any contingent scenario, including eligibility, time boundaries, allocation method, legal costs, and uncertainty.
    5. Keep the scenario outside normal performance targets so an unresolved lawsuit does not distort hiring, content, or technology decisions.

    The same restraint applies to vendor decisions. A surviving antitrust claim is not proof that your current contract is invalid, that a migration will improve yield, or that another stack will produce a particular result. Evaluate a change using your own fees, demand access, reporting quality, operational cost, and measured auction outcomes.

    Build a counsel-led evidence pack while the systems are identifiable
    An overhead view of storage drives, blank records, archive envelopes, and a magnifying glass arranged as an evidence pack.

    This is an operational preparation checklist, not a determination that your company is part of the litigation or subject to a legal-hold obligation. If the surviving claims may be relevant to your business, ask qualified antitrust or litigation counsel to assess eligibility and preservation duties. Do that before changing retention policies or launching a broad data collection.

    1. Create a system inventory. Record each ad server, exchange, reporting interface, billing system, data warehouse, and archive, along with its owner and available date range.
    2. Preserve the commercial record. Locate contracts, order forms, amendments, invoices, payment statements, fee disclosures, account notices, and documents explaining platform migrations or material configuration changes.
    3. Preserve the operational record. Identify ordinary-course auction reports, revenue reports, configuration histories, demand-partner lists, account identifiers, and metric definitions. Record where a field was renamed or calculated differently over time.
    4. Build a dated chronology. Align platform changes with shifts in impressions, fill, auction participation, reported fees, and net publisher revenue. A chronology makes alternative explanations visible instead of assuming every movement came from the challenged conduct.
    5. Reconcile money to activity. Where the data permits, connect inventory and auction records to invoices and net payments. Record unexplained gaps rather than backfilling them with estimates.
    6. Document limitations. Note missing periods, expired logs, acquired properties, changed account IDs, inconsistent currencies, and reports that cannot be reproduced. A known limitation is more useful than false precision.
    7. Control access. Keep the working set limited to the people who need it, and follow counsel’s directions for preservation, privilege, privacy, security, and collection scope.

    Do not delete, rewrite, or normalize potentially relevant originals after counsel identifies a preservation obligation. At the same time, do not collect extra user-level information merely because it might be available. An indiscriminate collection can create privacy and security exposure without helping establish publisher-level fees or revenue. Preserve what is relevant, document what each field means, and let counsel define the defensible scope.

    SEO, content, and audience teams also have a role. Keep acquisition performance separate from monetization performance in your reporting:

    • Acquisition: visits or sessions from organic search, AI-search referrals, direct traffic, social platforms, and other channels.
    • Inventory: ad opportunities, eligible impressions, ad load, and fill-related measures available in your systems.
    • Monetization: auction outcomes, disclosed fees, and net publisher revenue, with the governing metric definitions attached.

    Traffic can improve while monetization weakens, or monetization can improve while traffic falls. A single blended revenue-per-session figure hides that distinction. Separating the layers helps you evaluate content performance accurately now and gives legal and financial reviewers a cleaner record if they later need to isolate alleged ad-tech harm.

    Key takeaways for publisher teams

    • The Sept. 30 decision kept principal Google ad-tech claims alive and preserved key expert testimony; it did not award damages.
    • Google cannot relitigate certain findings from the separate Virginia case, including unlawful tying of its publisher ad server to AdX, but publisher-specific injury and damages still require proof.
    • The estimates of roughly $901 million for Gannett, $600 million for Daily Mail, and $1.72 billion for the publisher class are plaintiffs’ expert estimates, not payouts.
    • The result varies by claimant and legal theory. Several claims were resolved for Google, while claims involving the AdX publisher class and Mikula Web Solutions continue.
    • Your defensible next step is a counsel-led review of eligibility, systems, contracts, fees, and retained data—not an assumed recovery or an emergency platform migration.

    Within your next reporting cycle, produce a one-page ad-stack dependency map and assign owners for the supporting contracts, reports, and payment records. Have counsel decide whether a deeper eligibility or preservation review is warranted. That gives you a decision-ready file without pretending the litigation has already produced money for publishers.

    References


  • What the Penske AI Overviews Dismissal Means for Publishers

    What the Penske AI Overviews Dismissal Means for Publishers

    If your business depends on Google referrals, the dismissal of Penske Media’s AI Overviews lawsuit does not make the traffic problem disappear. It removes one attempted legal route, while leaving you with the same commercial question: which pages are losing valuable visits, and what should you change?

    The practical lesson is not that publishers must accept every search change without scrutiny. It is that expected organic traffic is not the same thing as a negotiated commitment. You need to manage Google as a distribution channel whose economics can change, not as a party that has promised to deliver a particular audience.

    What the judge decided – and what he did not

    U.S. District Judge Amit P. Mehta dismissed Penske Media’s case because its reciprocal-dealing theory did not identify an actual agreement under which Google promised traffic in exchange for access to the publisher’s content.

    Penske’s theory treated two longstanding activities as an exchange: publishers permitted standard web crawling, and Google sent users to their pages through search results. The court found no sufficiently pleaded bargain behind that pattern. There were no alleged negotiated terms, mutual commitments, or communications establishing that Google owed Penske a specific quantity of traffic – or any traffic at all.

    “An expectation is not an agreement.”

    U.S. District Judge Amit P. Mehta

    That distinction matters. Penske alleged that Google’s near-90% search dominance enabled it to use publisher material in AI summaries without paying for it. It also alleged that AI Overviews appeared on roughly 20% of searches linking to its sites and contributed to a one-third decline in affiliate revenue by late 2024. Those figures describe Penske’s allegations; they are not universal benchmarks for every publisher and were not transformed into judicial findings about causation.

    The dismissal is therefore not a finding that AI Overviews cause no economic harm. Mehta explicitly acknowledged the difficult position of publishers and the wider consequences for journalists, educators, and online creators. The missing element was a legally plausible reciprocal agreement, not an allegation of damage.

    This was also the first lawsuit from a major U.S. publisher targeting Google AI Overviews, which makes it tempting to treat the outcome as a verdict on every possible dispute over AI-generated search answers. That reading is too broad. The reported basis for dismissal was the failure of this antitrust theory, under these pleaded facts. For publishers, the immediate consequence is narrower but still important: years of receiving search traffic did not, by themselves, create an enforceable traffic entitlement.

    Key takeaways for publishers and SEO teams

    • The court rejected the alleged reciprocal bargain; it did not find that publishers suffered no traffic or revenue damage.
    • Organic visibility is commercially valuable, but an expectation of referrals is not the same as a contract guaranteeing them.
    • Penske’s exposure and revenue figures belong to Penske’s allegations. Do not apply them to your site without page- and query-level evidence.
    • An AI Overview citation, a conventional ranking, a click, and a conversion are four different outcomes. Measure them separately.
    • Your response should combine search visibility work with stronger reasons to visit, convert, return directly, or join an owned audience.

    Measure AI Overview exposure as a business risk

    An analyst examines abstract content tiles and visitor pathways, some of which stop at translucent summary panels before reaching a publication.

    A sitewide traffic graph cannot tell you whether AI Overviews are the problem. Search demand, rankings, result-page layouts, content changes, seasonality, tracking failures, and monetization changes can move at the same time. Start with the pages and queries connected to revenue, then separate visibility loss from click loss and revenue loss.

    1. Define commercially meaningful page groups. Separate affiliate comparisons, advertising-supported explainers, lead-generation pages, subscription entry points, and content that primarily supports brand discovery. A lost visit does not have the same value across those groups.
    2. Create an observation log for important queries. Record the query, intent, observed presence of an AI Overview, whether your domain appears in it, your conventional result visibility, the landing page, and the observation context. Retain dated result-page captures so later analysis is not based on memory.
    3. Measure each layer of the funnel. Track impressions and search visibility, clicks and click-through rate, on-page conversion, revenue, and revenue per visit. A decline at one layer does not prove a decline at every layer.
    4. Compare like with like. Analyze equivalent page types and comparable periods. Annotate ranking changes, redesigns, content updates, offer changes, tracking deployments, and other result-page features that could provide a competing explanation.
    5. Attach a decision to every monitored cohort. Decide whether the evidence calls for maintaining, rebuilding, diversifying, testing, or simply gathering more observations. Monitoring without a decision rule becomes reporting theater.

    Do not use Penske’s alleged one-third affiliate revenue decline as a forecast for your own business. Use it as a prompt to connect search behavior to money. A mention in an AI result may have visibility value, but it does not pay a publisher’s costs unless it produces a measurable downstream effect.

    Observed patternWhat it may meanYour first decision
    Impressions remain stable while clicks and click-through rate fall on queries showing AI OverviewsYour pages may still be exposed, but fewer searchers need to leave the results pageStrengthen the reason to visit and assess whether the remaining visits still convert profitably
    Impressions, conventional visibility, and clicks all fallRanking, demand, indexing, or broader result-page changes may be involvedInvestigate those variables before assigning the entire decline to AI Overviews
    Clicks fall while conversion rate or revenue per visit risesYou may be receiving fewer but more qualified visitorsEvaluate contribution and profit, not sessions alone
    Traffic remains stable while conversion or revenue fallsThe larger problem may be tracking, monetization, offer quality, or page experienceAudit the commercial funnel before rebuilding content for AI search

    This framework will not prove legal causation on its own. It will give you a better operating diagnosis and a cleaner evidence trail than a single before-and-after traffic chart.

    Give readers a reason to continue past the generated answer

    A reader walks past a shallow translucent summary card toward a warmly lit space filled with reporting materials and investigative work.

    A page that does nothing beyond restating a short factual answer is especially exposed when a search feature can provide that answer directly. The response is not to obscure the answer. It is to make the page useful after the answer has been understood.

    Build three distinct layers into important content

    • The answer layer: State the answer clearly, define important terms, identify relevant entities, and make dates or qualifications explicit. This helps readers verify quickly that the page addresses their question.
    • The evidence layer: Support the answer with material you genuinely possess, such as original reporting, primary data, a transparent methodology, documented testing, expert analysis, or useful visual evidence. Do not manufacture novelty merely to appear original.
    • The action layer: Help the reader complete the next task with a calculator, decision framework, comparison method, configuration checklist, downloadable template, current inventory, or another function that cannot be replaced by a one-paragraph summary.

    For AI SEO and generative engine optimization, optimize citation and conversion as separate jobs. Clear structure, consistent entity names, meaningful headings, and accurate structured data can make content easier for machines to interpret. They do not create a contract for inclusion, compensation, ranking, or traffic. JSON-LD should describe what is visibly true on the page; it should never contain unsupported claims added solely for an AI system.

    Then inspect the post-click experience. If the title promises a comparison, the page should make comparison easy. If the searcher needs a decision, show the criteria and the tradeoffs. If the information changes, explain how it is maintained and make the update date meaningful. The reader should encounter additional value immediately, not after an extended preamble.

    Make portfolio decisions based on replaceability

    Classify content by how easily its value can be compressed into a generated answer:

    • Defend high-value, differentiated pages. Keep their facts current, improve their evidence, and remove friction between the search landing point and the useful feature or commercial action.
    • Rebuild commodity pages that still serve a real audience. Add decision support, proof, maintenance discipline, or a practical tool instead of merely adding more words.
    • Diversify around valuable topics. Offer relevant email updates, alerts, accounts, communities, or direct-use tools where those features solve an actual recurring need. The purpose is to create a consensual return path, not to force a signup before delivering value.
    • Consolidate cautiously. Do not delete or noindex pages merely because an AI Overview appeared for a query. Removing indexed content can sacrifice remaining visibility and links. Preserve performance data, choose a genuinely relevant destination, and plan redirects before consolidating anything.

    Affiliate-dependent templates deserve particular scrutiny because Penske tied its claimed damage to affiliate revenue. Look beyond word count. Ask whether the page offers real product judgment, explains its selection method, distinguishes user needs, and remains accurate. If its only function is to restate information available everywhere else, adding generic prose will not repair its economics.

    Keep evidence that supports decisions, not just frustration

    The ruling exposes a gap between business harm and the evidence required for a particular legal claim. Publishers may experience both traffic loss and weaker monetization, yet still lack proof of a contractual or reciprocal commitment. If the issue may reach executives, a trade body, a regulator, or legal counsel, keep an evidence file that preserves the distinction.

    • Dated captures of the relevant result pages, including the query and observation context.
    • A record of whether your URL appeared conventionally, appeared as an AI Overview citation, appeared in both places, or did not appear.
    • Page- and query-group performance showing impressions, clicks, click-through rate, conversions, and revenue where available.
    • A change log covering content edits, technical releases, ranking movements, monetization changes, and analytics changes.
    • The method used to calculate any claimed loss, with assumptions and competing explanations stated plainly.
    • Applicable contracts, licenses, platform terms, negotiated commitments, and communications. Preserve versions instead of relying on recollection.

    Business analysis asks whether a platform change damaged your economics. Legal analysis asks whether the facts satisfy the elements of a viable claim. Those are connected questions, but they are not interchangeable. If you are considering litigation, licensing action, or a platform restriction that could affect discoverability, have qualified legal counsel evaluate the live facts and current law; an SEO analysis is not a substitute for legal advice.

    In your next reporting cycle, split the queries where you observe AI Overviews from the rest of your search portfolio and connect both groups to page-level outcomes. Then assign one response to each important content group: defend it, rebuild it, diversify its acquisition path, or continue monitoring it. That gives you a decision system even when the legal and product environment remains unsettled.

    Google referrals can remain valuable without being guaranteed. Treat them as platform-dependent distribution, preserve evidence when the economics change, and invest in content people have a reason to visit rather than merely summarize.

    References

  • Web Data Access Mandates: A Playbook for Site Owners

    Web Data Access Mandates: A Playbook for Site Owners

    You want search engines and AI systems to discover your work, but you also need to know who is copying it, why they want it, and whether your access rules mean anything. At the other end of the market, opening a dominant platform’s data may improve competition while moving sensitive search histories beyond the systems that originally protected them.

    The useful question is not whether web data should be open or closed. It is whether each access decision has a verified actor, a defined purpose, a proportionate data scope, an enforceable control, and an accountable owner. That is the operating model site owners, SEO teams, AI platforms, and data recipients need as transparency mandates develop.

    Key takeaways

    • Crawler transparency and platform data sharing are different obligations. The first identifies who is requesting access; the second governs data that is transferred to another party.
    • A User-Agent is a claim, not proof of identity. Give special access only after the crawler has been verified through evidence controlled by its operator.
    • Use robots.txt to communicate preferences to cooperative crawlers, but enforce important restrictions through edge controls, authentication, scoped credentials, or restricted endpoints.
    • Separate discoverability from permission. Allowing a crawler does not guarantee citations or AI visibility, while blocking one can reduce its ability to retrieve current content.
    • Anonymization is not a label applied to an export. Sensitive search data needs minimization, re-identification testing, access controls, retention limits, audit logs, and incident procedures.

    Two transparency mandates solve different problems

    One policy track concerns traffic arriving at your site. The proposed federal Stealth Bot Prohibition Act would require automated crawlers to identify themselves and disclose their purpose. It targets tactics such as posing as a human visitor, routing requests through residential proxies, or using scraping services to get around website controls. A similar New York measure applies to news publishers, while the federal proposal would extend more broadly across websites and digital platforms.

    The other policy track concerns data leaving a large platform. The European Commission has required Google to share with competitors in the European Union the same search data it uses to improve its own search services, subject to anonymization. The reported deadline for search-data sharing is January 2027. Google has appealed the decision, arguing that the required anonymization is insufficient and that moving query data outside its infrastructure creates additional security exposure.

    Those positions are not opposites. A crawler can disclose its identity without receiving unrestricted access. A platform can be required to provide access without publishing raw data to the world. Transparency identifies the actor and the rules; it does not eliminate access controls.

    Operational questionCrawler transparencyPlatform data sharing
    Who must act?The automated requesterThe platform holding the required dataset
    What must become clear?Identity, purpose, and compliance with the site’s policyDataset scope, recipient, purpose, safeguards, and permitted use
    Does data have to leave the holder?Not necessarily; disclosure can precede an allow-or-block decisionYes, to the extent required by the applicable mandate
    Main control failureA false identity defeats crawler-specific rulesWeak minimization, anonymization, or recipient security exposes sensitive data
    First question to answerCan you prove which operator sent this request?Can you prove why each transferred field is necessary and protected?

    Keep these workstreams separate in your compliance register. The owner of bot verification may sit in infrastructure or security, while the owner of a mandated data transfer may span legal, privacy, security, and product teams. Combining them into a generic transparency project makes it easy to miss the control that actually matters.

    The legal stakes also differ from an ordinary integration project. Under the Digital Markets Act’s general penalty regime, non-compliance can expose a company to fines of up to 10% of annual global revenue, up to 20% for repeated infringements, and periodic payments of up to 5% of average daily sales. These are statutory maximums, not a prediction about any particular dispute. If your organization may be in scope, have qualified EU competition and privacy counsel confirm the current deadlines, the effect of any appeal, and the technical form of compliance.

    Make crawler identity verifiable, not merely declared

    A crawler presents a digital key at a network checkpoint while unverified crawler devices remain outside the gate.

    A crawler can place a recognizable name in its User-Agent header. That makes the name useful for classification, but it does not make the claim true. A hidden crawler can imitate browser traffic, borrow another bot’s label, or use residential addresses that do not resemble data-center infrastructure. This is why an identity mandate matters: rules addressed to a named bot are ineffective when the requester can lie about being that bot.

    Build your crawler register around five records:

    1. Declared operator and product. Record the organization claiming responsibility, the crawler name, an official contact path, and the date you checked the information.
    2. Declared purpose. Distinguish functions such as search indexing, live answer retrieval, model training, monitoring, and commercial content reuse. A label such as AI bot is too vague to support a meaningful decision.
    3. Verification method. Prefer evidence controlled by the operator, such as an official verification endpoint, safely validated published network ranges, or authenticated or signed requests when the operator supports them. Do not grant allow-list privileges from a User-Agent alone.
    4. Policy outcome. Map the verified identity and purpose to a specific action for each content class: allow, rate-limit, block, challenge, or route to an authenticated licensing channel.
    5. Observed evidence. Log the time, host and path, request method, response status, claimed User-Agent, relevant network information, verification result, policy matched, action taken, and response volume. Set retention around operational and legal need rather than keeping the data indefinitely.

    Be careful with URL logging. Query strings and path segments can contain account identifiers, search terms, or other personal information. Redact unnecessary values, restrict access to raw logs, and involve your privacy team before expanding retention merely because a bot dispute is possible.

    robots.txt still has a useful role. It gives cooperative crawlers a machine-readable statement of your preferences, and crawler-specific groups can express different choices for identified agents. It is not authentication and cannot stop a requester that ignores the file or hides behind another identity. Put consequential enforcement at the CDN, web application firewall, application, API gateway, or authenticated delivery layer.

    The same distinction applies to SEO infrastructure. A sitemap helps systems discover URLs. Structured data and JSON-LD help them interpret eligible page content after retrieval. Neither verifies the requester or grants unrestricted reuse rights. Keep discovery configuration, crawler authorization, and content licensing as three separate controls.

    If content access is licensed, use credentials or a dedicated delivery route. Define the permitted purpose, content scope, request volume, attribution terms, retention, onward use, reporting, suspension conditions, and termination process. A crawler-identification mandate can make negotiation and enforcement more practical, but it does not by itself create a right to payment, attribution, or a licensing agreement.

    Build an access policy without giving up AI visibility

    Automated traffic is too large to manage as an occasional exception. Cloudflare Radar estimates bots account for 64% of internet traffic. On the publisher sites it monitors, TollBit reported more than 22 billion AI-bot scrapes during the first half of 2026. Its observed ratio of AI-bot visits to human visits moved from roughly one per 200 in the first quarter of 2025 to one per 31 in the fourth quarter. Those vendor-specific figures do not tell you the composition of your traffic. They tell you why your own server and edge logs should, rather than assumptions.

    Use this sequence to turn that telemetry into an enforceable policy:

    1. Inventory content surfaces. Separate public HTML pages, media files, feeds, APIs, downloadable archives, licensed material, account areas, and private content. Anything genuinely private should sit behind access control rather than a crawler instruction.
    2. Write a decision matrix. For each content class, decide what happens when the requester is a verified desired crawler, a verified crawler with an unapproved purpose, a claimed but unverified bot, an authenticated licensee, or unknown automation. Give unverified claims no special allow-list privilege.
    3. Enforce in layers. Publish crawler preferences, apply rate and resource controls at the edge, require credentials for restricted delivery, and keep application-level authorization in place. Roll out aggressive rules carefully so false positives do not lock out people or the search services you depend on.
    4. Measure the consequence. Before changing a rule, record verified crawler requests, pages served, bandwidth or compute cost, response errors, identifiable referrals, and the AI citations or mentions you monitor for priority queries. Compare equivalent periods after the change and alter one major policy variable at a time where practical.
    5. Prepare an incident path. Define who preserves logs, verifies the claimant, changes the edge rule, contacts the operator, assesses privacy exposure, and involves counsel. Record why the final allow, throttle, or block decision was made.

    Do not collapse this into a single allow AI or block AI switch. A public documentation page intended to win citations has a different job from a licensed report, a subscriber archive, or an account dashboard. Apply access decisions at the smallest content class your stack can reliably enforce.

    Be equally precise about visibility. Allowing retrieval creates an opportunity for a system to process current content; it does not guarantee ranking, citation, attribution, model training, or referral traffic. Blocking a specific crawler may reduce visibility in the service that relies on it, but it does not prove that all copies disappear or that other systems will stop finding the page. Decide from observed outcomes and your content rights, not from the crawler’s brand name.

    If you cannot verify a requester, fall back to a documented rule based on content sensitivity, infrastructure cost, request behavior, and your visibility objective. That is more defensible than guessing which company is behind an address and quietly granting it privileged access.

    Treat shared search data as a security product

    An analyst monitors a secure vault as search data is minimized, encrypted, and transferred through a controlled access port.

    The European dispute exposes a hard design problem. Search data can help competing search and AI services improve, which supports the Commission’s competition objective. Query histories can also reveal unusually sensitive interests, and transferring them creates another environment that can be attacked or misconfigured. Google’s security argument is a litigant’s position, not a final finding that the mandate is unsafe. The responsible response is to make the privacy and security claims testable.

    Anonymization must be evaluated against re-identification risk, not treated as the removal of obvious account fields. Rare queries, repeated sequences, timestamps, locations, and combinations of attributes may distinguish a person even when a direct identifier is absent. The appropriate transformation depends on the dataset, the recipient’s other information, the allowed use, and the governing mandate. Privacy and security specialists should test that risk before release and after a material change in fields or granularity.

    If you hold the data

    • Create a field-level inventory that names the business purpose, sensitivity, granularity, update frequency, and recipient for every element proposed for transfer.
    • Start with the least detailed representation that can satisfy the authorized purpose, then have counsel confirm whether the mandate requires additional parity with the data used internally.
    • Document the anonymization threat model, including rare records, sequence linkage, external-data linkage, and the conditions under which a recipient could regain access to more detailed information.
    • Deliver data through a segregated, authenticated environment with least-privilege access, encryption, audit logging, and a defined process for credential revocation. Avoid unmanaged bulk copies.
    • Set enforceable rules for retention, deletion, onward sharing, subcontractors, security incidents, and purpose changes. Verify compliance rather than relying only on contractual promises.
    • Publish a plain-language transparency record describing what is shared, with whom, for what purpose, and under which safeguards, while withholding details that would weaken security.

    If you receive the data

    • Accept only fields tied to a documented product or research need. Receiving extra sensitive data creates risk without guaranteeing a better service.
    • Separate raw access from derived outputs. Keep the smallest possible group able to reach detailed records and use aggregated outputs for broader product work where feasible.
    • Test whether the data produces the intended improvement. Access to a dominant platform’s dataset does not automatically change user habits or produce a competitive product.
    • Maintain lineage from the received field through each transformation and output so you can investigate misuse, honor deletion requirements, and explain how the data influenced a result.
    • Prepare a containment and notification procedure before ingestion. It should identify who can stop processing, revoke access, preserve evidence, assess affected data, and contact the provider.

    Your first deliverable should be one accountable register. Put inbound crawler identities and purposes on one side, outbound or received datasets and purposes on the other, and assign a named operational owner to every decision. Then test two scenarios: an unverified crawler requesting high-value content, and a sensitive export appearing outside its approved environment. Any missing owner, log, revocation path, or policy rule is your next fix.

    That register will remain useful even if a bill changes or an appeal succeeds. It gives you something legislation alone cannot: a repeatable way to prove who accessed data, why access was allowed, what left your systems, and how you limited the resulting risk.

    References


  • Google Ad Tech Antitrust Oversight: A Publisher Action Plan

    Google Ad Tech Antitrust Oversight: A Publisher Action Plan

    If you publish content and depend on programmatic advertising, the practical question is whether you can reach AdX demand without centering Google’s publisher ad server in your stack. A federal court has ordered that path to be opened. Whether it improves your revenue, control, or costs still has to be proved in your own environment.

    Google’s ad tech business is not being broken apart. The remedy instead combines interoperability requirements, data sharing, restrictions on lock-in, and six years of court supervision. That gives you a reason to test alternatives, but not a reason to migrate blindly.

    What the court changed in Google’s ad tech stack

    Separate ad server and advertising exchange modules are connected by multiple open pathways beneath a balance scale.

    U.S. District Judge Leonie Brinkema found that Google had monopolized the publisher ad-server and ad-exchange markets. The remedy focuses on loosening the connections between those two parts of the advertising supply chain.

    Court-ordered changeDecision it may enableWhat you need to verify
    Rival publisher ad servers must be able to access AdX real-time bidsKeep or adopt a non-Google ad server while considering AdX demandSupported inventory, bid timing, implementation requirements, reporting, and fees
    Publishers using Google’s ad server cannot be required to use AdXEvaluate the ad server and exchange as separate purchasesWhether contracts, defaults, incentives, or workflows still make separation costly
    Practices that locked publishers into Google’s tools must endMove components of the stack without replacing everything at onceMigration support, termination terms, data portability, and operational dependencies
    Google must meet new data-sharing requirementsCompare auction behavior and performance with better informationFields supplied, granularity, delivery cadence, retention, and export rights

    The court declined to force a sale of AdX or another ad tech component because it considered structural remedies unnecessary and impractical. It concluded that behavioral restrictions could restore competition and stop a return to the conduct at issue. That is a meaningful distinction: the remedy changes how Google must operate, not who owns the infrastructure.

    Google must also appoint an antitrust compliance monitor. The remedies remain in force for six years, rather than the 15 years sought by federal and state enforcers, and the monitor has less authority than the Justice Department requested. You should therefore treat this as a supervised window for competition, not a permanent guarantee that every market friction will disappear.

    Key takeaways for publishers and advertising teams

    • Interoperability is the remedy, not the business outcome. Access to AdX bids can make another ad server more viable, but it does not guarantee higher yield, lower fees, or easier operations.
    • The most immediate opportunity is procurement leverage. You can ask vendors to price and document the ad server, exchange access, data access, and migration support separately.
    • A full-stack replacement should not be your first test. Start with a reversible inventory segment so that an integration problem cannot put all advertising revenue at risk.
    • Net performance matters more than the headline bid. Measure revenue after fees alongside fill, latency, reporting discrepancies, and staff time.
    • This is an ad tech remedy, not a search update. It does not by itself change organic rankings, indexing, structured data, AI citations, or eligibility for AI-generated search features.

    Turn the remedy into a controlled testing plan

    A publishing team compares two isolated ad delivery setups on a controlled testing bench.

    The order creates optionality. Your job is to determine whether that optionality produces a better result for your inventory. Build the evaluation before a contract renewal or migration deadline leaves you with only one practical choice.

    1. Record a baseline with stable definitions. Capture eligible impressions, bid participation, fill, gross revenue, net revenue after identifiable fees, page latency, reporting discrepancies, and operational hours. Keep the calculation method fixed so a vendor cannot appear better merely because it defines an impression or fee differently.
    2. Map the dependencies around the publisher ad server. List exchange connections, direct campaigns, identity tools, consent signals, creative review, forecasting, billing, analytics exports, and any custom automation. A component can be contractually separable while remaining expensive to replace because several workflows depend on it.
    3. Define success and failure before seeing results. Decide which metrics cannot deteriorate, which improvements would justify migration work, and which implementation costs count against the result. Include rollback triggers for material revenue loss, latency increases, missing consent signals, or inconsistent reporting.
    4. Request the new access path in writing. Ask each vendor to describe exactly how AdX real-time bids are passed to a rival publisher ad server, what inventory is supported, which data accompanies the bid, and which limitations remain. A statement that access is available is not an implementation specification.
    5. Run a reversible pilot. Use a defined inventory cohort that is large enough to evaluate but small enough to protect the wider business. Compare similar traffic and account for known changes in geography, device mix, content, and demand conditions. Do not move the entire stack on the strength of a sales demonstration.
    6. Evaluate the operating cost as well as auction results. Count troubleshooting, reconciliation, manual trafficking, vendor coordination, and delayed reporting. A small revenue gain can disappear when the alternative requires substantially more staff time.
    7. Carry verified findings into renewal negotiations. Separate requests for ad serving, exchange demand, data, support, and migration. Preserve export and termination rights so that a successful pilot can become a real choice rather than a temporary experiment.

    If a proposed change affects termination rights, exclusivity, data ownership, or material revenue commitments, have qualified counsel review the relevant contract language. The operational goal is to preserve a safe test and a workable exit, not to interpret the antitrust judgment as modifying your individual agreement automatically.

    Questions that expose whether access is genuinely usable

    The useful question is not simply whether a rival ad server can receive AdX bids. You need to know whether it can do so on terms that support a reliable auction, accurate measurement, and a commercially sensible workflow.

    Connectivity and auction behavior

    • How does the AdX real-time bid reach the rival publisher ad server, and which system makes the final auction decision?
    • Which inventory formats, account types, devices, and markets are supported?
    • What technical prerequisites, certifications, minimums, or configuration changes apply?
    • Which timestamps and identifiers are available for diagnosing bid timing, timeouts, and discrepancies?
    • What happens during an outage or degraded connection, and can the publisher configure a fallback?
    • Can the setup be piloted on selected inventory without changing the rest of the stack?

    Data, fees, and contractual control

    • Which auction and reporting fields will be shared, at what level of detail, and how quickly?
    • Can the publisher export the data in a reusable format, and what retention limits apply?
    • Which fees are charged by the exchange, ad server, integration provider, or reseller?
    • Are support, migration, reconciliation, or data access billed separately?
    • Does any discount, default, or bundle make independent selection economically difficult even when it is technically permitted?
    • What notice, termination, data-return, and transition-assistance terms apply if the test fails?

    Put the answers into the test plan and contract rather than leaving them in a presentation. The compliance monitor will oversee Google’s adherence to the final judgment, but that role does not replace your technical acceptance criteria, revenue controls, or vendor accountability.

    Keep ad tech oversight separate from search and AI visibility

    For SEO, AEO, and GEO teams, the central mistake would be to turn this antitrust remedy into a forecast about organic discovery. The requirements concern Google’s publisher ad server and ad exchange. They do not establish a change to crawling, indexing, ranking systems, AI answers, structured data processing, or citation selection.

    Keep two roadmaps. The monetization roadmap should track vendor access, auction data, fees, pilots, and contract flexibility. The search visibility roadmap should continue to track technical accessibility, content quality, entity clarity, structured data, citations, and measurable search or AI referral behavior. A development can matter to the economics of publishing without changing how a page is discovered.

    Advertisers on the demand side should be equally precise. Because the remedy targets publisher-side markets, do not assume that a campaign interface, targeting option, or buying workflow has changed. Ask agencies and technology providers to identify the exact supply-path, reporting, or fee change they are relying on before revising a media plan.

    Your best next move is deliberately practical: create a one-page performance baseline, map every dependency on the current ad server, and send the implementation questions above to vendors before the next renewal discussion. Six years of oversight creates time to build alternatives, but only measured, contractually usable alternatives give you leverage.

    References


  • How Law Firms Earn AI Citations and Search Visibility

    How Law Firms Earn AI Citations and Search Visibility

    Your firm can rank well in conventional search and still disappear when a prospective client asks an AI assistant who can help. It can also appear by name while another website receives the citation. Those are different visibility problems, and they require different fixes.

    The practical goal is to make your expertise easy to retrieve, verify and attribute for the questions that lead to suitable matters. That is what AEO for law firms across ChatGPT, Gemini and Claude is meant to address. It is not a shortcut to a recommendation. It is a disciplined way to connect a client’s question with a clear answer, a credible lawyer, a defined jurisdiction and evidence that supports the firm’s claims.

    Diagnose the citation gap before changing your website

    A magnifying glass examines two digital paths, one leading directly to a law office and another splitting between a firm and an outside publication.

    You are not optimizing the firm in the abstract. You are optimizing individual questions and the evidence paths an answer engine can use to resolve them. A firm may be visible for a procedural question but absent from a local hiring question. It may be mentioned as an option without having its website cited. It may even be cited accurately on one prompt and misrepresented on a closely related one.

    Start with unbranded questions drawn from the decisions clients actually face. Do not begin with a vanity prompt that contains the firm’s name. A branded query mainly tests whether the system recognizes an entity it has already been given. It does not show whether the firm can be discovered when the user has not chosen a provider.

    Build your prompt set around distinct forms of intent:

    • Understanding: What does a legal term, process or notice mean?
    • Preparation: What information or documents should someone gather before speaking with counsel?
    • Decision: What factors should someone consider when choosing the right type of lawyer?
    • Location: Which firms handle the relevant matter in the user’s jurisdiction?
    • Firm evaluation: What experience, credentials or service characteristics distinguish a suitable provider?

    For every prompt, record the answer, every cited URL, whether the firm was named, whether its own page was cited and whether the description was accurate. Then inspect the cited pages for the exact job each one performed. One may define the issue. Another may establish local relevance. A professional profile may verify a lawyer’s credentials. A review platform may supply reputation evidence. Your gap is the missing job, not merely the missing keyword.

    Keep four outcomes separate: a mention, a citation, a recommendation and a visit. A mention means the system recognizes the firm. A citation means a particular page was selected as support. A recommendation adds evaluative language. A visit shows that the response produced measurable website activity. Treating all four as one ranking hides the work that needs to be done.

    Build pages around answerable client questions

    A broad service page can establish that you practise in an area, but it often cannot answer the narrower question in front of a client. A page headed with a generic service label usually leaves the system to infer who the advice applies to, which jurisdiction governs it and what information is actually useful.

    Give each important question a self-contained answer unit. That does not mean manufacturing a thin page for every wording variation. It means organizing substantial pages so that each section resolves one recognizable question without requiring the reader or the engine to reconstruct the answer from promotional copy.

    1. Name the situation. Make the heading match the problem in language a client would understand.
    2. State the applicable scope. Identify the jurisdiction, audience and material conditions before the answer can be mistaken for universal advice.
    3. Give the direct answer. Put the useful response before the firm’s history, awards or consultation pitch.
    4. Explain what changes the answer. Surface exceptions, dependencies and facts that require an individualized assessment.
    5. Show the next safe step. Tell the reader what to gather, verify or ask, without pretending a web page can decide an individual legal matter.
    6. Identify responsibility. Display the author or legal reviewer, their relationship to the firm and a meaningful review date.

    The page title and opening should promise only what the page delivers. A heading such as Our Litigation Services says what the firm sells. A heading framed around what someone should prepare before a litigation consultation says what the visitor will learn. The latter creates a much clearer answer target while still giving the firm room to explain where professional advice becomes necessary.

    Build a connected content structure rather than a pile of isolated posts. A service hub should link to the questions arising before, during and after the relevant process. Those pages should link to the responsible lawyers, appropriate offices and a clear contact route. Lawyer biographies should link back to the matters they actually handle. This creates a navigable chain from question to answer to qualified professional.

    Do not hide the useful portion behind a contact form. A page can explain a general process, the information a lawyer will need and the limits of general guidance without giving individualized advice. The consultation is for applying the law to the person’s facts, not for revealing basic information the page promised to provide.

    Legal marketing controls still apply. Before publishing testimonials, prior outcomes, fee language, comparisons, claims of specialization or client details, route the copy through the person responsible for advertising-rule and confidentiality compliance in every jurisdiction where it will appear. Never turn a client’s confidential facts into citation bait, and never frame a previous result as a promise about a future matter.

    Connect the answer to a verifiable firm and lawyer

    An answer page on a desk is linked by glowing threads to an attorney portrait, a law office, a seal, source documents and contact details.

    A well-written answer is only part of the job. An answer engine also needs to determine who published it, which lawyer stands behind it, where the firm operates and whether other accessible records describe the same entity consistently.

    Create an internal facts record that controls how the firm is represented. Include the legal name, public brand name, office details, contact information, jurisdictions, practice areas, lawyer names, professional roles and official profile URLs. Use that record when updating the website, professional directories, business profiles, press biographies and social accounts. Small inconsistencies can create separate or ambiguous entity trails even when each version looks reasonable to a human reader.

    On the website, make the relationships explicit:

    • Place the firm’s full identity and appropriate office information on location and contact pages.
    • Give each lawyer a dedicated biography with their role, relevant practice areas, jurisdictions and links to the pages they author or review.
    • Use bylines that lead to real biography pages rather than generic author archives.
    • Connect service pages to the offices and lawyers that genuinely provide the service.
    • Keep credentials, addresses and service descriptions consistent wherever the firm controls the record.
    • Correct obsolete profiles instead of publishing additional variants that compete with them.

    JSON-LD can reinforce those visible relationships. Use applicable types such as Organization or LegalService for the firm, Person for lawyers, and the relevant page or article type for content. The selected type matters less than accuracy and internal consistency. Every property should correspond to information a visitor can verify on the page or through the official URL it references.

    Structured data does not manufacture authority, override weak content or compel an AI citation. Its job is disambiguation. It helps machines connect a page with the correct organization, person, location and subject. Validate the markup after deployment, check that generated values match the visible page and repeat the check whenever a template, plugin or content model changes.

    Independent corroboration adds another layer. Relevant professional profiles, directory records, earned coverage and permitted client reviews can confirm identity or reputation claims. Look for agreement, not raw volume. A smaller set of accurate references that clearly points to the same firm is more useful than a large collection of neglected profiles with conflicting names, addresses or practice descriptions.

    Measure citations without depending on a stable source mix

    Social platforms deserve attention, but they are not a stable foundation. Within one vendor’s dataset, social platforms’ share of AI citations grew 47% in seven months while the sourcing pattern changed 16 times without warning. That is a directional observation from one dataset, not a universal law for every engine or legal query. Its practical value is the warning: a channel can become more visible while the rules governing that visibility continue to move.

    Use the firm’s website as the canonical home for complete, reviewed answers. Use social posts to distribute those answers in the language and format of each community. Keep the firm name, lawyer identity, jurisdiction and central claim aligned with the canonical page. Link back when the platform and context make that useful. If the legal position or firm information changes, update the canonical page first and then correct controlled social versions rather than allowing them to become competing records.

    A social response should be genuinely useful on its own, but it should not become improvised advice for an individual’s facts. Move sensitive or fact-dependent issues into an appropriate professional conversation. That protects the person asking and prevents a decontextualized reply from circulating as the firm’s definitive position.

    Test visibility with the same prompt bank under documented conditions across ChatGPT, Gemini and Claude. Record the date, account or access context when relevant, exact prompt, response, cited pages and factual errors. Repeat the test on a consistent cadence and after substantive changes. AI outputs can vary, so one successful response is an observation, not a durable ranking.

    What you observeWhat it may indicateWhat to do next
    The firm is neither named nor citedA possible relevance, retrieval or corroboration gapCompare the cited answer units with your best page and identify the missing job.
    The firm is named, but another domain is citedThe entity may be recognized while the firm’s site is not selected as evidenceStrengthen the official page, its authorship and the proof supporting the claim.
    A firm page is cited, but the firm is not clearly identifiedThe content may be useful while the publisher relationship remains weakClarify the byline, lawyer biography, organization identity and page relationships.
    The firm is named or cited inaccuratelyCurrent and obsolete facts may be conflictingCorrect the canonical page and controlled profiles, then document the change for retesting.
    The citation is accurate but produces no suitable inquiriesVisibility may exist without commercial alignmentCheck whether the prompt represents useful intent and whether the landing page offers an appropriate next step.

    Report citation coverage, brand mentions, factual accuracy, qualified visits and suitable inquiries separately. A citation proves that a page was used as support in that response. It does not prove endorsement, preference or commercial value. Keeping the measures separate stops a rising citation count from masking inaccurate descriptions or irrelevant exposure.

    Key takeaways

    • Optimize specific client questions and evidence paths, not a generic claim that the firm should rank everywhere.
    • Separate mentions, citations, recommendations and visits because each points to a different opportunity or problem.
    • Write direct, scoped answers that identify the jurisdiction, material conditions, author or reviewer and safe next step.
    • Connect content, lawyers, offices and services through visible links and accurate JSON-LD that describes the same facts.
    • Use independent profiles and social distribution as corroboration, while keeping the reviewed website page as the canonical record.
    • Retest a fixed prompt set under documented conditions and track accuracy alongside visibility.

    Choose one high-intent question tied to a priority practice area. Capture the current answers and citations, publish the strongest answer your evidence can support, align its lawyer, location and structured data, then test the same question again. That gives you a repeatable optimization loop grounded in what clients ask and what answer engines can verify.

    References


  • Google Ad Tech Antitrust Remedies: What to Do Next

    Google Ad Tech Antitrust Remedies: What to Do Next

    If your publishing revenue stack depends on Google Ad Manager or AdX, the words “no breakup” may sound like permission to stand down. They aren’t. Google keeps its advertising exchange, but the finding that it violated antitrust law remains in place.

    Your practical task is to separate the ownership decision from its operational consequences. That means documenting your dependence, establishing performance baselines, watching how the behavioral remedies are implemented, and avoiding expensive migrations based on assumptions the court did not make.

    The ruling separates liability from remedy

    U.S. District Judge Leonie Brinkema declined to force Google to sell AdX, the exchange through which publishers offer digital advertising inventory in real-time auctions. The court instead chose behavioral remedies and adopted most of the proposals submitted by the parties.

    That outcome answers one narrow but consequential question: Google can continue to own AdX. It does not reverse the April 2025 finding that Google illegally monopolized publisher ad-server and ad-exchange markets. The liability decision also found that Google’s conduct harmed publishers, consumers, and the competitive process by locking publishers into its advertising technology.

    The distinction matters because a liability ruling and a remedy order do different jobs. Liability identifies unlawful conduct. A remedy determines what must change. A structural remedy, such as divestiture, changes ownership. A behavioral remedy leaves the business intact while restricting, requiring, or supervising specified conduct.

    It is therefore inaccurate to reduce the result to either “Google won” or “Google was broken up.” The Department of Justice and a coalition of states did not obtain the AdX sale they requested, but Google did not erase the underlying monopoly judgment. If you brief executives, clients, or readers, put both halves in the same sentence.

    Do not confuse AdX with Google Ads, either. AdX is part of the publisher-side infrastructure at issue here. The court did not order a breakup of Google’s advertiser-facing campaign platform, and the ruling does not itself invalidate campaigns running through Google Ads.

    Behavioral remedies make measurement more important

    An analyst compares two streams of tokens in transparent measurement chambers beside monitoring screens and calibration tools.

    A divestiture would have created a visible transition: a new owner, technical separation, contract changes, and migration work. Google argued that such a sale would be technically difficult, lengthy, and harmful to customers. That was Google’s position in the litigation, not a neutral measurement of what a sale would have produced.

    Behavioral remedies create a quieter challenge. Ownership can look unchanged even as auction rules, contractual restrictions, access conditions, integrations, reporting, or enforcement obligations change underneath it. The label “behavioral remedies” does not tell you which of those mechanisms will change or when.

    Do not infer fee caps, new interoperability rights, data portability, auction changes, or access guarantees merely because they sound like plausible antitrust remedies. The operative order, its timetable, and its enforcement provisions control Google’s obligations. Treat a claimed product consequence as unverified until you can connect it to that language or to a concrete Google product or contract notice.

    This is why your baseline matters. If performance moves after implementation, you need to know whether the cause was a remedy-related product change, seasonality, demand quality, consent rates, floor settings, latency, or an unrelated auction adjustment. Without a dated baseline, those explanations collapse into guesswork.

    Company-level financial figures will not answer the dependency question for you. A Wedbush estimate based on court documents put Ad Manager at about 4.1% of Google’s revenue and 1.5% of its operating profit in 2020; more recent figures were redacted. Those older percentages describe Google’s business mix, not the importance of the stack to a publisher that routes most of its sell-side operations through it.

    A practical plan for publishers, advertisers, and agencies

    Publisher, advertiser, and agency work areas connect through measured primary and backup routes to a modular advertising network.

    You do not need to predict the final commercial effect before preparing for it. Build the evidence that will let you distinguish a meaningful change from normal ad-market noise.

    For publishers and revenue operations teams

    1. Map the complete monetization path. Trace inventory from the page or app through the publisher ad server, exchange, demand source, auction decision, creative delivery, and reporting system. Mark every point where Google technology, identifiers, contracts, or data are required. A vendor list alone will miss dependencies embedded in trafficking and reporting workflows.
    2. Capture a dated baseline. Preserve gross and net revenue, eligible impressions, bid participation, win rate, fill rate, effective revenue per thousand impressions, viewability, latency, discrepancies, and observable fees by format, device, geography, and demand path. Keep the relevant floor, timeout, consent, and inventory-quality settings with the data so future comparisons remain interpretable.
    3. Design fair alternative-path tests. Do not send only remnant, high-latency, or otherwise weak inventory to a competing exchange and call the result a comparison. Hold geography, device, format, consent status, viewability, floor strategy, and traffic quality as constant as your stack permits. Compare net publisher revenue after measurable costs, not a single headline CPM.
    4. Monitor the implementation layer. Assign an owner to review court orders, contractual notices, product documentation, reporting-field changes, auction behavior, and access conditions. Record what changed, the effective date, the affected inventory, and the evidence linking it to the remedy. This log will be more useful than a folder of undated screenshots.
    5. Set decision triggers before results arrive. Define which outcomes would justify a larger test, contract review, engineering work, or migration analysis. Use your own revenue concentration, operational capacity, and risk tolerance. A change that is immaterial across the market can still be material to a publisher with concentrated dependence.

    Do not treat the antitrust judgment as an automatic right to terminate or disregard an existing agreement. If a contract decision depends on the legal effect of the ruling, have commercial or antitrust counsel examine the actual agreement and operative order before you act. The downside of guessing can include breach claims, lost demand access, and an unnecessary technical migration.

    For advertisers and agencies

    Your exposure is less direct, but publisher-side changes can alter supply paths, reporting, auction participation, inventory availability, and measurable costs. The useful response is supply-path scrutiny, not an automatic campaign pause.

    • Separate performance by exchange, inventory source, domain or app, format, and other supply-path dimensions available in your reporting.
    • Preserve pre-implementation baselines for spend, impressions, effective CPM, reach, viewability, conversion performance, invalid-traffic signals, and platform-to-platform discrepancies.
    • Ask your agency or technology partners which reports expose exchange-level changes and which parts of the buying path remain aggregated or opaque.
    • Require a dated change log when a partner attributes performance movement to the antitrust remedies. The explanation should identify the affected mechanism, not merely mention the case.
    • Avoid converting the liability finding into a claim that every impression, auction, fee, or campaign outcome involving Google was unlawful. The ruling concerns specified publisher ad-tech markets and conduct.

    Publish the decision accurately for search and AI systems

    If you create SEO, AEO, or GEO content about the case, accuracy begins with entity separation. Google, Google Ads, Google Ad Manager, and AdX are related names, but they are not interchangeable entities or products. Blurring them makes it easier for a search engine or language model to extract a false answer such as “Google Ads was ordered sold.”

    Put the decisive answer near the beginning of the page: Google retains AdX; the antitrust liability finding remains; the court selected behavioral rather than structural relief. Then explain the relevant markets, the difference between liability and remedy, and the practical audience affected. Do not bury the no-divestiture result below a general history of Google’s advertising business.

    Keep the April 2025 liability finding distinct from the later remedy decision. Dates should be attached to the event they describe. A vague phrase such as “the Google antitrust ruling” can cause a human reader or retrieval system to merge separate legal stages into one event.

    Your structured data should match the visible page. Use an appropriate Article, BlogPosting, or NewsArticle type; provide an accurate headline, author, publisher, datePublished, and dateModified; and identify the case, AdX, Google, and the antitrust-remedy subject in the visible copy. Do not use structured data to add claims or dates that a reader cannot verify on the page.

    Update the page when the operative requirements, implementation schedule, product behavior, or legal status materially changes. Change dateModified only when you make a substantive update, and add a visible note describing what changed. That gives readers and retrieval systems a reason to trust the newer version rather than silently mixing it with an earlier one.

    Key takeaways

    • Google was not ordered to sell AdX, so the publisher advertising exchange remains under Google ownership.
    • The April 2025 finding that Google illegally monopolized publisher ad-server and ad-exchange markets remains intact.
    • Behavioral remedies are not the same as no remedy. Their practical effect depends on the operative requirements, implementation, and enforcement.
    • Publishers should map dependencies and preserve segmented performance baselines before interpreting later changes.
    • Advertisers should monitor supply paths and reporting rather than treating the ruling as a breakup of Google Ads.
    • SEO and AI-facing coverage should distinguish Google Ads, Google Ad Manager, and AdX while separating liability from remedy.

    Your next move is neither a rushed migration nor passive waiting. Schedule the dependency audit, assign an owner for remedy-related changes, and start the baseline now. When a concrete product, contract, or auction change arrives, you will be able to evaluate it against evidence instead of a headline.

    References


  • AI Training Data Licensing: A Practical Guide for Brands

    AI Training Data Licensing: A Practical Guide for Brands

    If an AI company asks to train on your content archive, the first question should not be, “What should we charge?” It should be, “What exactly would we be allowing, and do we control every item we plan to deliver?” Pricing before answering those questions is how a promising data deal becomes a rights problem.

    You need a way to separate legitimate commercial value from vague promises about “AI exposure.” The process below will help you audit the material, define the permitted uses, structure compensation, protect your brand, and decide whether the proposed license deserves to move forward.

    First determine whether your content is actually licensable

    The commercial backdrop is changing: AI labs are paying for curated, high-quality data instead of depending only on scraping. That does not make every large archive a valuable training corpus. A buyer needs content it can lawfully use, reliably process, and connect to a defined model or product objective.

    Start with a rights inventory, not a page count. Your CMS may contain material created under several different arrangements, even when all of it carries your branding. Employee-written copy, commissioned work, syndicated material, customer submissions, licensed photography, embedded media, and acquired archives can each carry different permissions.

    1. Divide the archive into meaningful content classes, such as editorial text, product data, customer questions, reviews, research records, images, audio, and video transcripts.
    2. Identify who created each class and the agreement that governs it. Record whether you own the relevant rights or merely have permission to publish it in a particular channel.
    3. Mark third-party elements inside otherwise original pages. A page you own can still contain a photograph, quotation, data table, or embedded asset that is outside your licensing authority.
    4. Separate confidential, personal, regulated, and user-submitted information from content already approved for commercial reuse. Public visibility is not proof of permission for model training.
    5. Create an exclusion list for anything with missing agreements, disputed ownership, unclear consent, contractual restrictions, or an unacceptable privacy risk.

    Do not rely on a copyright notice, a byline, or administrative access to the CMS as evidence that you can license an item for machine learning. If ownership, privacy, or consent is unclear, hold the material out until qualified intellectual-property or privacy counsel confirms how it may be used. Otherwise, you may be promising rights that your organization does not possess.

    Audit usefulness as well as ownership

    A legally clean collection can still be difficult to use. Training-data buyers benefit from records that are consistent, attributable, documented, and easy to update. Before discussing a license, examine whether you can deliver the following:

    • A stable identifier for every record, independent of a changeable page title or URL.
    • Clean primary content separated from navigation, advertising, comments, and duplicated boilerplate.
    • Reliable metadata for content type, language, publication date, revision date, author or publisher, and canonical URL.
    • A documented origin and rights basis for each content class.
    • Version history that shows what changed and when.
    • A consistent method for issuing additions, corrections, withdrawals, and deletions.
    • Clear definitions for fields, labels, categories, and any editorial annotations.
    • A manifest that lets both parties confirm exactly which records appeared in each delivery.

    This work affects both value and risk. A smaller corpus with dependable rights and metadata may be more usable than a much larger archive full of duplicates, unexplained fields, and uncertain ownership. It also lets you create separate licensing tiers instead of placing the entire archive into one irreversible package.

    Separate the AI permissions that vague contracts bundle together

    A sealed archive case connects to five separate transparent pathways, each controlled by its own valve and lock.

    “Use our content for AI” is not a workable grant of rights. A single URL can be crawled for discovery, stored in a retrieval index, used to evaluate answers, included in model training, displayed as a quotation, or transformed into another dataset. Those activities have different commercial consequences and should not be treated as one permission.

    ActivityWhat you need to define
    Public crawling and indexingWhich properties may be fetched, how often access occurs, what may be cached, and whether the purpose is search, retrieval, or another named function.
    Retrieval for generated answersWhat content may be stored and retrieved, how current it must remain, how excerpts are displayed, and whether answers include attribution and a link.
    Foundation-model trainingWhich model families, versions, products, and purposes may learn from the corpus, including whether commercial deployment is permitted.
    Fine-tuning or adaptationWhich named model or application may be adapted, who may operate it, and whether the adapted model may be transferred or reused elsewhere.
    Evaluation and safety testingWhat tests may use the data, how long test copies are retained, who can review outputs, and whether the material can later move into training.
    Output displayWhether the product may quote, summarize, reproduce, translate, or otherwise present the content, along with attribution and linking requirements.
    Synthetic or derivative dataWhether transformed records may be created, retained, combined with other datasets, sublicensed, or used after the original license ends.

    These distinctions also matter for AI search visibility. Training does not, by itself, guarantee that a model will cite your site, link to a page, use the current version, or represent your brand faithfully. If your business goal is discoverability, retrieval and output-display terms may matter more than a broad training grant.

    Turn the permission into a bounded scope

    A usable proposal should identify the parties, the data, the technology, the purpose, and the duration without forcing you to infer any of them. Require clear answers to these questions before quoting a price:

    • Which legal entity receives the license, and may its affiliates, contractors, hosting providers, or customers access the data?
    • Which records and versions are included? Does the grant cover one delivery, scheduled updates, or everything you publish in the future?
    • Which model families, checkpoints, applications, and product surfaces may use the corpus?
    • Is the use limited to internal development, or does it include commercial products offered to customers?
    • May the buyer combine the corpus with other data, create embeddings, produce annotations, or generate derivative datasets?
    • May the data or anything derived from it be transferred, assigned, sold, or sublicensed?
    • Is the license exclusive? If so, what subject, market, product, geography, language, and time period does the exclusivity cover?
    • What uses are expressly prohibited, including products designed to replace your publication, impersonate your brand, or expose restricted material?
    • What survives expiration or termination: raw files, retrieval indexes, embeddings, trained models, checkpoints, backups, derived datasets, or deployed products?

    A phrase such as “all artificial-intelligence purposes” gives the buyer flexibility by moving uncertainty onto you. Replace it with named uses and named products. If the buyer cannot identify the intended model, purpose, retention period, or downstream recipients, you do not yet have enough information to assess the risk or calculate a defensible fee.

    Price the defined scope, not the size of the archive

    There is no responsible universal price per page, word, or record. Volume affects processing costs, but it does not capture scarcity, freshness, rights quality, exclusivity, labeling, or the commercial freedom a license gives the buyer.

    Build your internal price floor from the work and exposure the deal creates. Include rights review, data cleaning, redaction, formatting, secure delivery, engineering support, update handling, reporting, contract administration, and the opportunity cost of restrictions placed on future deals. Then evaluate the buyer’s requested scope separately.

    • Uniqueness: Is the information readily available elsewhere, or does your organization hold a difficult-to-recreate collection?
    • Quality: Is the material edited, labeled, deduplicated, and accompanied by dependable metadata?
    • Freshness: Is this a historical delivery, or will your team provide continuing corrections and new records?
    • Rights assurance: How much review has been completed, and how broad a warranty is the buyer requesting?
    • Permitted use: Evaluation carries a different commercial footprint from unrestricted commercial training and deployment.
    • Downstream reach: Will one team use the corpus, or can affiliates, customers, contractors, and sublicensees benefit from it?
    • Exclusivity: What future buyers, products, markets, or partnerships would you be giving up?
    • Duration and survival: Does the buyer receive temporary access, or can trained and derived assets remain in service indefinitely?
    • Operational burden: How much continuing delivery, support, auditing, correction, and incident response will your team owe?

    Compensation can take several forms. A fixed fee is simple but must be tied to a fixed scope. A usage-based fee can expand with deliveries, records, model runs, or products, but only if the usage can be measured and audited. A minimum guarantee plus variable payments can cover your baseline work while preserving participation in broader use. Revenue sharing can align incentives, but it becomes fragile when revenue attribution is vague. Whichever structure you choose, define the measurement method, reporting schedule, audit rights, payment trigger, and treatment of disputed calculations.

    Negotiate in an order that preserves leverage

    1. Set your non-negotiable exclusions, privacy boundaries, brand protections, and prohibited uses.
    2. Obtain the buyer’s written description of the model, product, users, purpose, and data flow.
    3. Offer a specific corpus tier rather than opening the entire archive by default.
    4. Price the narrow base use first.
    5. Price additional models, products, affiliates, territories, updates, derivative data, and exclusivity as separate expansions.
    6. Require written approval and additional compensation before the buyer crosses from one tier into another.

    Watch for terms that make a seemingly attractive payment disproportionate to the rights surrendered. Common warning signs include perpetual and irrevocable use across undefined AI systems, automatic rights to all future content, unrestricted sublicensing, vague exclusivity, unilateral changes to the use case, broad warranties about third-party material, and liability that is uncapped or disconnected from your control. These are legal and financial exposure points, so have qualified counsel assess the actual agreement rather than relying on a commercial checklist alone.

    Build operational controls around the contract

    A legal, content, and technical team monitors a controlled data transfer into a locked server enclosure in a secure data room.

    A signed license is only useful if both parties can administer it. The contract may say that one content class is excluded, for example, while the export pipeline quietly delivers it with everything else. Connect each important term to a technical control, an owner, and a record that can later show what happened.

    • Attach a dataset schedule describing included content classes, excluded classes, fields, formats, languages, and delivery frequency.
    • Generate a manifest for every delivery with stable record IDs, versions, timestamps, and license status.
    • Keep approval records for additions and document every correction, withdrawal, and deletion request.
    • Specify access controls, approved storage locations, security duties, incident notification, and whether the corpus must remain segregated from other collections.
    • Require usage reports that correspond to the pricing and scope terms, including the models, products, recipients, and dataset versions involved.
    • Assign responsibility for rights questions, privacy requests, technical delivery, invoices, audits, brand issues, and termination.
    • Create a change process for new products, model families, acquisitions, corporate reorganizations, and transfers to another operator.
    • Schedule periodic reviews so a narrow experiment does not quietly become a broader production use without new approval.

    Deleting delivered files does not by itself reverse model training that has already occurred. Treat raw data, embeddings, derivative datasets, model checkpoints, future model releases, backups, and deployed products as separate post-termination states. The agreement should say which states may continue, which must stop, which must be deleted where technically applicable, and what evidence the buyer must provide. Resolve this before delivery, because the available remedies may be narrower after training begins.

    Protect AI visibility as a separate outcome

    If your objective includes visibility in AI answers, put that outcome into the deal rather than assuming it follows from training access. Consider terms covering attribution wording, canonical links, use of your current brand and entity names, update handling, correction escalation, and reporting on answer displays or citations where the product can measure them.

    You may also want a retrieval feed that remains distinct from the training corpus. A retrieval system can consult current records when producing an answer, while a trained model reflects an earlier training process. Keeping those permissions separate lets you negotiate freshness, citation, withdrawal, and link behavior without granting every training right at the same time.

    Your publishing infrastructure still matters outside the license. Maintain stable canonical URLs, explicit publisher and author information, clear publication and revision dates, consistent entity names, and structured data that agrees with the visible page. Provide machine-readable correction and withdrawal signals where your workflow supports them. Monitor priority questions to see whether AI products identify your brand, use current facts, and link to the intended page.

    Keep the three control layers distinct. Structured data describes the meaning and relationships on a page; it does not transfer content rights. Site access controls regulate automated access; they are not a substitute for negotiated permission. The license defines authorized uses between the contracting parties. Treating any one layer as if it performs all three jobs creates gaps.

    Key takeaways

    • Audit ownership, third-party rights, consent, privacy, and contractual restrictions before offering an archive.
    • Exclude uncertain material instead of representing that you control rights you may not have.
    • Separate crawling, retrieval, training, fine-tuning, evaluation, output display, and derivative-data permissions.
    • Define the receiving entities, dataset versions, models, products, purposes, duration, downstream users, and post-termination treatment.
    • Price legal review, preparation, delivery, governance, commercial scope, exclusivity, and continuing obligations rather than relying on content volume alone.
    • Connect every important contract restriction to a technical control, responsible owner, usage record, and review process.
    • Negotiate citation, linking, freshness, brand representation, and correction workflows explicitly when AI visibility is part of the business case.

    Your next move is to create a one-page licensing brief before discussing price. List the proposed corpus, excluded material, rights basis, permitted AI activities, prohibited uses, buyer entities, model or product scope, delivery schedule, duration, post-termination states, visibility requirements, and internal approval owners. Have the appropriate rights, privacy, technical, commercial, and legal stakeholders review that brief.

    If the buyer can answer those points, you can negotiate a bounded transaction. If it cannot, keep narrowing the request. The valuable asset is not merely a large body of content. It is a defensible, structured, maintainable corpus offered under terms your organization can actually enforce.

    References


  • Toxic Backlink Sabotage: When an SEO Attack Becomes a Lawsuit

    Toxic Backlink Sabotage: When an SEO Attack Becomes a Lawsuit

    If your backlink audit suddenly shows spam pages pairing your company with drugs, loans, gambling, or weapons, do not begin with a public accusation or an indiscriminate cleanup. Preserve what happened first. A federal court has now left open the possibility that an allegedly deceptive backlink campaign can support false-advertising and related claims, but that is not the same as proving sabotage.

    Your immediate job is to separate an ugly link pattern from evidence of responsibility, intent, and harm. That distinction will determine whether you have an SEO incident to mitigate, a brand-protection matter to escalate, or a potential legal dispute that needs counsel.

    Key takeaways

    • A lawsuit surviving a motion to dismiss means the allegations were legally plausible enough to continue. It does not mean the alleged attack happened or that the defendant is liable.
    • A suspicious backlink profile does not identify who created the links. Attribution requires separate evidence.
    • Preserve raw link data, anchor text, page captures, dates, communications, and business-impact records before remediation changes the evidence.
    • Keep SEO correlation, attacker attribution, legal responsibility, and financial harm as separate questions.
    • Do not retaliate, publicly name a suspected competitor, or send a cease-and-desist letter without a coordinated legal and monitoring plan.

    What the toxic-backlink ruling changes, and what it does not

    Auto transport company Montway alleged that competitor Nexus AT LLC created more than 2,350 toxic backlinks between April and October 2025. The links allegedly used anchor text such as buy steroids online, payday loan services, illegal betting sites, cocaine powder online, and unlicensed firearms while directing people to Montway’s website.

    The alleged injury had two parts. Montway claimed the campaign was intended to reduce its Google rankings and to create false associations between its brand and illegal or disreputable products. It also alleged that a former Nexus manager connected the campaign to directions from Nexus CEO George Arkin and an SEO contractor. Those remain allegations; they have not been established at trial.

    In a June 2 ruling at the motion-to-dismiss stage, Judge Matthew Kennelly allowed the federal Lanham Act false-advertising claim, trademark claims, and related Illinois consumer-protection claims to proceed. The California unfair-competition claims were dismissed. At this stage, a judge asks whether the pleaded facts plausibly state a viable claim, not whether the plaintiff has proved those facts.

    The distinctive part of the ruling concerns the anchor text. The court found it plausible that the text was literally false because it appeared to promise one destination but sent users somewhere else. It also found that the alleged campaign could qualify as commercial advertising or promotion under the Lanham Act.

    That gives companies a legal theory worth discussing with counsel when the facts fit. It does not establish that every spam link is false advertising, that toxic links necessarily reduce rankings, or that a competitor is responsible whenever suspicious links appear. The ruling permits litigation to continue under the allegations presented; it is not a finding of liability or a universal shortcut around proof.

    Build the evidence around three separate questions

    Gloved hands organize digital evidence into three connected groups showing suspicious links, attribution clues, and damage to a website node.

    A useful investigation does not put every screenshot, ranking decline, and suspicion into one folder labeled attack. Build three evidence tracks. Each answers a different question, and a strong answer in one track cannot replace a weak answer in another.

    1. What links and representations actually appeared?

    Start with observable facts. For every relevant backlink, retain the full linking URL, the destination URL, the exact anchor text, the page title, the page content surrounding the link, and the date and time you captured it. Save both a visual capture and the underlying page data where your tools allow it. A screenshot shows what a person could see; a raw export or saved page helps preserve technical details that a screenshot can miss.

    Keep the original export unchanged. Work from a copy when you classify or annotate links. If your team hashes evidence files, record the hash alongside the capture date; the hash can help show that a file was not altered later, although it cannot prove that the original webpage was truthful.

    Do not let an automated toxic-link score become your conclusion. Record it as a tool-generated metric, then document the concrete features that caused concern: false destination language, repeated off-topic anchors, common page templates, clustered timing, shared infrastructure, or another observable pattern. This makes the record understandable to people who do not use your SEO platform.

    2. What evidence connects the activity to a responsible party?

    A distinctive anchor pattern may support an inference of coordination. It does not tell you who ordered the work. Attribution needs its own evidence, such as lawfully obtained communications, admissions, contractor relationships, campaign instructions, witness accounts, or records produced through a proper legal process.

    Montway’s pleading did not rely only on a link chart. It also included the alleged account of a former manager who attributed the direction to the competing company’s CEO and an SEO contractor. That kind of allegation is categorically different from noticing that suspicious links began near a competitive event.

    Maintain a clear confidence label for every attribution statement: confirmed fact, third-party statement, technical inference, or unresolved suspicion. Do not impersonate people, access accounts without authorization, or pressure a contractor into disclosing information improperly. Those tactics can create separate legal and security problems while contaminating an otherwise credible investigation.

    3. What measurable harm occurred, and what else could explain it?

    A ranking decline can coincide with a backlink campaign without being caused by it. Preserve query-level rankings, affected landing pages, organic sessions, conversions, qualified leads, and revenue records that your business already maintains. Use exact dates and consistent comparison methods. Do not convert a traffic estimate into a claimed financial loss without showing the steps between them.

    Record competing explanations on the same timeline: site migrations, content removals, template releases, crawling problems, outages, analytics changes, redirects, and other technical work. A credible analysis tries to disprove its preferred explanation. If the matter proceeds, counsel and qualified experts can decide what causal conclusions the evidence supports.

    Brand harm is another evidence stream. Capture any actual search result, customer communication, publisher page, or other interface that presents the false association. Do not infer that users saw or believed an association merely because the anchor exists on a remote page.

    If you are also worried about AI search visibility, document it separately. Record the AI product and model where displayed, the exact prompt, the full response, the date and time, and relevant account or location conditions. One problematic answer does not prove a recurring representation, and the presence of toxic backlinks does not by itself prove that they caused an AI system’s output. Structured data and on-page entity clarification may improve your owned content, but they cannot establish who placed a third-party backlink.

    Preserve first, then choose a proportionate response

    A forensic analyst archives a hostile link network in a transparent cube while isolating a small set of contaminated connections from healthy nodes.

    The safest operational sequence protects both SEO remediation and the legal record. It also reduces the chance that a hurried accusation turns an external incident into a second dispute. This is general risk-management information, not a substitute for legal advice about your facts or jurisdiction.

    1. Freeze the initial record. Export the backlink dataset, preserve representative pages, record collection times, and restrict changes to the originals. If a page disappears later, your record should still show what your team observed.
    2. Open a single incident timeline. Include the first observed link, link-volume changes, anchor clusters, ranking or traffic movements, technical site changes, communications, reports to search platforms, and remediation actions. Separate the event date from the date on which your team discovered it.
    3. Bring SEO, security, communications, and legal owners together. SEO can explain link patterns and search changes. Security can preserve technical records and access controls. Communications can prevent speculative public statements. Counsel can assess claims, jurisdiction, preservation obligations, and contact strategy.
    4. Continue necessary mitigation without erasing the before-state. Use the relevant search-engine reporting and link-management channels, but record exactly what was submitted or changed and when. Preserve the underlying evidence before a URL is blocked, removed, reported, or otherwise handled.
    5. Prepare a counsel-ready packet. Include a short chronology, raw evidence locations, representative examples, known totals and date ranges, attribution evidence, documented business effects, alternative explanations, prior communications, and unanswered questions. Label estimates and third-party metrics clearly.
    6. Plan any notice as an escalation event. Montway alleged that the backlink activity intensified after an October 2025 cease-and-desist letter. That allegation does not prove that cease-and-desist letters generally worsen attacks. It does show why monitoring, evidence capture, technical response, and counsel availability should be in place before a notice is sent.
    7. Do not retaliate. Buying bad links to a suspected competitor, threatening individuals, or publishing an unverified accusation can create new exposure and make your original account less credible. Preserve, report, investigate, and escalate through lawful channels.

    A cease-and-desist letter is not a routine SEO ticket. It can reveal what you know, harden the other side’s position, trigger evidence-preservation issues, or prompt further activity. Let qualified counsel decide whether to send one, what it should claim, and what your team must be ready to do afterward.

    Turn backlink sabotage into a defined incident class

    Most teams lose useful evidence because nobody owns the first response. Add suspected search sabotage to your incident playbook instead of leaving it inside a recurring SEO report. Define who can preserve data, who can contact platforms, who approves public statements, and who calls outside counsel.

    Your playbook should trigger enhanced review when several signals appear together: a coordinated cluster of off-topic anchors, text that falsely describes the destination, concentrated timing, credible attribution evidence, actual ranking or reputation effects, or a change in activity after contact. None of those signals proves liability on its own. Their purpose is to determine how quickly and formally the team should respond.

    Use a simple operational triage. A suspicious pattern with no attribution and no documented harm usually calls for preservation, technical analysis, reporting, and monitoring. A pattern with credible attribution calls for early legal review even if harm remains unclear. A pattern combining false representations, meaningful attribution evidence, and documented business or brand effects warrants an urgent joint review by counsel and the SEO incident owner. These are escalation categories, not legal tests.

    Companies have traditionally had limited options beyond reporting suspected manipulation to search engines. The surviving Lanham Act theory creates a possible additional route, but litigation remains fact-specific and the allegations in this case are still unproven. Your advantage comes from building a reliable record before you need to decide which route fits.

    If you have detected a coordinated pattern, make three moves now: preserve the raw evidence, write a dated one-page chronology, and put your SEO lead and legal counsel on the same review. Even if the incident never becomes a lawsuit, that record will give you cleaner remediation decisions and a defensible basis for protecting the brand.

    References


  • Fraudulent DMCA Takedowns: A Search Visibility Response Plan

    Fraudulent DMCA Takedowns: A Search Visibility Response Plan

    Your page was ranking yesterday. Now it is missing from Google, and a DMCA notice says somebody else owns work you created. Do not answer by rewriting, deleting, redirecting, or republishing the page. Preserve its current state first.

    Treat this as two connected incidents: a legal removal process and a search visibility outage. The counter-notice addresses the first. Evidence preservation, URL stability, and post-restoration checks address the second. Here is the order that keeps those tracks from working against each other.

    Key takeaways

    • Confirm whether Google deindexed the URL, your hosting provider disabled it, or its rankings simply declined. Each problem has a different response.
    • Freeze the page, server response, CMS history, complaint, and search data before changing anything. Your timeline is part of your defense.
    • Build proof from several independent records: CMS logs, historical web captures, RSS publication records, Git commits, and original working files.
    • A DMCA counter-notice is a signed legal submission, not an ordinary support appeal. It requires identifying information, a statement under penalty of perjury, and consent to court jurisdiction.
    • Track the 10-to-14-business-day response window from the platform’s acceptance of a valid counter-notice, not from the day you first discovered the removal.
    • Restoration, reindexing, ranking recovery, and renewed AI visibility are separate milestones. Verify each one instead of assuming the whole problem ended when the URL returned.

    Why a false copyright complaint can become a search outage

    Section 512 of the DMCA gives qualifying online platforms a safe harbor from copyright liability when they respond expeditiously to infringement notices. That creates an asymmetric risk calculation: removing a page is usually safer for the platform than delaying removal while it investigates ownership. At scale, automated processing can therefore act before meaningful human review. A claimant can initiate the process quickly, while the publisher must assemble and submit the proof needed to reverse it. That speed-over-verification incentive is what makes fraudulent notices effective.

    Three attack patterns deserve particular attention. In a scraper-and-backdate scheme, someone copies your work to a disposable domain, changes the displayed publication date, and claims your original is the copy. A fabricated claimant uses a false organization or impersonated publisher to conceal who is behind the notice. Reputation suppression targets criticism, investigative coverage, reviews, or complaints during a period when losing search visibility would be especially valuable to the subject.

    Authority does not make a domain immune. In one documented case, pages from Search Engine Land and Press Gazette disappeared from Google worldwide within 48 hours of a complaint from an entity calling itself US Webspam. The complaint alleged copied proprietary images even though the Search Engine Land page contained no images. The URLs returned after a formal counter-notice, public scrutiny, and several days of disruption. The episode shows why an obviously inconsistent allegation can still trigger deindexing.

    Before treating every disappearance as DMCA abuse, identify the affected layer. A ranking loss without a legal-removal notice is not evidence of a fraudulent claim.

    What you observeLikely affected layerFirst place to check
    The direct URL loads normally, but Google reports a legal removal or no longer indexes itSearch indexGoogle Search Console, the account email associated with the property, and the complaint record
    The direct URL returns a provider suspension page or an unexpected 4xx responseHost, CDN, or another infrastructure providerThe provider account, abuse desk message, origin server, and DNS/CDN configuration
    The URL remains indexed but impressions or positions declined, with no removal noticeSearch performance or ordinary index eligibilitySearch Console performance data, URL Inspection, canonical tags, robots directives, and recent site changes
    Only one AI answer or one manual search omits the pagePotentially normal answer or result variationUnderlying crawlability and index status before assuming a legal removal

    Preserve the URL and build a defensible ownership record

    A generic web page sits in a transparent evidence case beside a camera, envelope, clock, padlock, and source-file folders.

    Your first job is not to write a persuasive rebuttal. It is to prevent evidence from disappearing or becoming harder to interpret. A rushed edit can change the page’s modification date, replace the HTML that disproves an allegation, or obscure which version was live when the complaint was filed.

    1. Save the entire notice. Download the email, platform message, attachments, case number, timestamps, claimant identity, alleged owner, disputed URL, and alleged original URL. In Google Search Console, check the legal-removal information associated with the property, including messages under Security & Manual Actions and the related account email. Search the Lumen Database for the URL, domain, claimant, or case details; it archives many legal requests and can reveal exactly what was alleged. These notice-inspection steps give you the claim you actually need to answer.
    2. Capture the current technical state. Record the HTTP status, rendered page, raw HTML, canonical URL, robots meta directive, structured data, sitemap entry, and relevant response headers. Save screenshots, but do not rely on screenshots alone when raw exports are available. If the complaint alleges an image that was never present, preserve both the rendered page and HTML showing the absence of that asset.
    3. Construct a publication chronology. Export the CMS creation time, original publication time, revisions, editor history, and database records rather than manually copying dates into a document. Add historical Wayback Machine captures, timestamped RSS records, and Git commits showing when the file entered version control. These are specifically useful because scraper-and-backdate attacks try to manufacture earlier-looking publication dates.
    4. Match the evidence to each allegation. List every passage, image, chart, file, or other work the claimant identifies. Place your earlier version beside the alleged original and record the provenance for each disputed element. If the notice is vague, preserve that vagueness rather than guessing what the claimant meant.
    5. Export your visibility baseline. Save Search Console page and query data for the affected URL, its index status, analytics landing-page data, and relevant server logs. Note when impressions, clicks, crawls, referrals, and direct visits changed. This will help you distinguish legal restoration from later search recovery.

    No single timestamp is conclusive merely because it looks official. A displayed publication date can be edited, and an attacker may rely on that ambiguity. Your strongest record is a consistent chain across systems that were created for different purposes: CMS revisions, external captures, syndication records, version-control history, and original working files.

    Package the material so a reviewer can follow it without reconstructing your case. Start with a one-page chronology. Follow it with an exhibit index, the notice, both URLs, the disputed elements, and the records establishing publication order. Keep untouched originals separately from any annotated copies. Do not backdate a CMS field, rewrite structured data, or alter a file’s metadata to make your case look cleaner. That creates new inconsistencies and can damage an otherwise legitimate response.

    Use the counter-notice process with its legal consequences in view

    A DMCA counter-notice is not an SEO reconsideration request or an informal email to support. It is a signed legal declaration. The required submission includes personal contact information, a statement under penalty of perjury, and consent to specified federal court jurisdiction. The platform forwards the valid counter-notice to the original claimant.

    That exposure matters. If ownership is genuinely disputed, the work contains licensed or commissioned material, a freelancer created it, the claimant has a plausible contractual argument, or you are concerned about disclosing your physical address, consult a qualified copyright lawyer before filing. Do not use invented contact details or make a perjury statement merely to restore traffic. This incident-response framework cannot determine who legally owns a particular work.

    A statutory counter-notice generally needs all of the following:

    • Identification of the material that was removed or disabled.
    • The location where that material appeared before removal, including the exact URL.
    • A statement under penalty of perjury that you have a good-faith belief the removal resulted from mistake or misidentification.
    • Your full name, physical address, telephone number, and email address.
    • Consent to the jurisdiction of the appropriate federal district court, including the applicable provision for a person outside the United States.
    • Your physical or electronic signature.

    Use the platform’s current counter-notice form or the designated process identified in its notice. Copy the affected URL exactly and answer the alleged work rather than submitting a broad complaint about lost rankings. A detailed evidence package can support your good-faith position, but it does not replace any required declaration. The mandatory counter-notice elements are what make the response legally operative.

    Start the response clock from confirmed receipt

    Keep the platform’s acknowledgement showing that it received a valid counter-notice. Once the platform forwards it, the claimant has 10 to 14 business days to provide evidence of a filed lawsuit seeking a court order that restrains publication. That means business days, not calendar days, and the trigger is the valid counter-notice process rather than your first support email.

    Put the dates on a case calendar. If the platform asks for a correction, the statutory process may not yet be running, so answer the deficiency promptly and preserve both messages. If the window passes without evidence of a court filing and the material remains unavailable, reply within the same case thread. Include the acceptance date, elapsed business days, exact URL, and a concise request for restoration under the counter-notice process.

    Public attention can create useful scrutiny during a high-impact outage, but it does not replace the formal response. If you publish a chronology, limit it to documents, dates, visible inconsistencies, and actions the platform has confirmed. Do not speculate publicly about an attacker’s identity or motive when you cannot prove either. If the record indicates a knowing material misrepresentation, a copyright lawyer can assess whether Section 512(f) or another remedy is relevant to your circumstances.

    Protect search visibility while the claim is pending and after restoration

    A glowing network path reconnects a magnifying-glass-shaped portal to a stable web-page node while diagnostic lights inspect it.

    A legal response can restore access, but it cannot preserve search signals if you dismantle the URL while waiting. When the provider permits the page to remain live and your legal assessment supports publication, keep the original slug, self-referencing canonical, internal links, and sitemap entry stable. Do not launch a duplicate at a new URL or domain simply to get around deindexing. That can divide signals, create a second takedown target, and complicate the ownership record.

    If a host has disabled the content, preserve the site’s routing and configuration rather than hastily converting the address into a permanent redirect or 410 response. Coordinate any temporary response with the provider and, where legal exposure is real, counsel. The safe technical choice depends on whether the material is unavailable because of the search engine, the host, or both.

    Keep authorship and publication metadata accurate. Your visible byline, canonical URL, publisher information, datePublished, and dateModified should agree with the page and your internal records. JSON-LD can make those facts machine-readable, but schema is not proof of copyright ownership. Backdating markup to defeat a fraudulent claim only imitates the attack pattern you are trying to expose.

    Verify recovery as a sequence, not a single event

    1. Confirm restoration at the affected layer. Check that the host serves the intended page and that the legal-removal case is closed or updated. A restored host page does not prove that Google has reindexed it.
    2. Recheck index eligibility. Confirm a successful response, the intended canonical, no accidental noindex, and no robots rule blocking the search crawler. Compare the live page with the technical capture you made before responding.
    3. Use Google Search Console for the URL itself. Inspect the canonical URL, test the live page, and request indexing when appropriate. Keep the sitemap accurate, but do not repeatedly change its lastmod value or resubmit it without a real page change.
    4. Measure returning visibility. Watch URL-level impressions, clicks, queries, and crawl activity against the saved baseline. Restoration to the index and recovery to a previous ranking position are different outcomes, and there is no defensible fixed timetable for the latter.
    5. Check AI discovery separately. Test the prompts and answer surfaces that previously exposed or cited the page, but treat individual answers as spot checks. AI systems differ in how they retrieve, crawl, refresh, and generate responses. A restored Google result does not guarantee immediate inclusion in every AI answer.

    Once the immediate incident is closed, make provenance routine. Save a CMS-history export when important work is published, maintain RSS publication records, keep content files in version control where practical, retain original media and drafts, and arrange periodic external captures of high-risk pages. Enable Search Console notifications and give one person responsibility for legal-removal alerts, evidence preservation, counsel escalation, platform submissions, and technical recovery.

    Before you close this tab, export the affected page’s revision history and current Search Console data, then write down the exact time you discovered the removal. Those two actions take minutes and give every later response a cleaner factual foundation. After the crisis, apply the same provenance workflow to investigative coverage, high-value evergreen pages, reviews, and any content a competitor or criticized party would benefit from suppressing.

    References


  • Google Search Ad Disclaimer Assets: A Compliance Workflow

    Google Search Ad Disclaimer Assets: A Compliance Workflow

    If your Search ads must carry a required term, condition, or legal disclosure, Google’s text disclaimer asset gives that message a dedicated place. You no longer have to spend ordinary headline or description space on every piece of required wording.

    The asset does not make compliance automatic. The critical failure mode is easy to miss: an ad can continue serving when its disclaimer is disapproved. You therefore need a launch and monitoring process that treats the disclosure as a requirement, not a decorative extension.

    Treat the asset as a placement, not a compliance switch

    Text disclaimer assets are available worldwide to Google Ads advertisers, including campaigns using AI Max. That broad availability solves a platform-access problem, but it does not decide whether your wording meets a law, regulation, licensing rule, contract, or internal policy.

    Keep two approval gates separate. Your legal or compliance reviewer decides what the ad must communicate. Google decides whether the asset is accepted on its platform. Passing one gate does not mean you have passed the other, and platform approval should never be treated as legal advice.

    The distinction matters because disclaimer failure does not fail closed. If a required asset is disapproved, Google may serve the associated ad without it. For a campaign that cannot lawfully or contractually appear without the disclosure, the safe operating rule is simple: do not permit the campaign to serve until the asset has been added, approved, and checked. If its status later changes, pause or otherwise prevent delivery until the problem is resolved.

    Assign that decision before launch. The person watching the account should not have to interpret the legal significance of a missing disclosure during an incident. Your campaign record should state whether the asset is mandatory, who owns the approved wording, and what action to take if it becomes unavailable.

    Write for the visible message, not merely the character limit

    Each disclaimer can contain up to 90 characters. Treat that as an input limit, not a promise that all 90 characters will always appear. Disclaimer text may be truncated in some situations, including when larger font sizes are used or when certain languages require more display space.

    There is no universal safe character count below 90 that eliminates that risk. Instead, draft the message so its most important meaning arrives first. Work through the copy in this order:

    • Identify the indispensable statement. Ask your legal reviewer to distinguish wording that is required from wording that is merely explanatory or preferred.
    • Lead with the material qualifier. Do not bury the condition at the end of a long sentence if losing that ending would change how a reasonable reader understands the offer.
    • Name the scope precisely. Make it clear what product, price, audience, eligibility condition, or claim the qualifier applies to. Shorter language is not better if it becomes ambiguous.
    • Remove promotional repetition. Brand language, benefits, and calls to action belong elsewhere in the ad. The disclaimer’s limited space should carry the disclosure.
    • Count the final localized text. Do not approve only the source-language version and assume translations will fit. Review every language as its own display string.
    • Review the truncated meaning. Examine what remains understandable if the ending is not visible. If truncation could make the ad misleading or noncompliant, the asset may not be a sufficient placement for that requirement.

    A landing page can provide fuller terms, but it should not be used to justify an incomplete ad disclosure unless qualified counsel has confirmed that arrangement for the specific obligation. When the mandatory statement cannot fit reliably, change the ad, offer, landing experience, or campaign plan rather than forcing the legal language into an unsuitable container.

    Rebuild the ad around Description Line 1 displacement

    Two generic mobile search ad layouts, with the second showing a highlighted disclosure strip displacing the main description block.

    A disclaimer is not simply appended to an otherwise fixed layout. When the asset appears, it overrides a pinned Description Line 1. If you pinned that line because it carried a key offer detail, qualification, claim boundary, or call to action, adding the disclaimer changes the structure you thought you had locked down.

    Audit the ad as a new composition. Start by writing down the job performed by the pinned first description. Then inspect the ad without that line and ask four concrete questions:

    • Does any remaining claim become broader or more absolute when Description Line 1 disappears?
    • Does the offer still make sense without a qualification that was carried only in that line?
    • Can the disclaimer be understood without wording that was present only in the displaced description?
    • Does the remaining copy still tell the user what they will reach after clicking?

    If the answer to any of these is no, rewrite the whole ad unit. Do not depend on a pinned slot that the disclaimer can replace. Important context should survive the eligible combinations your campaign can actually show.

    This also changes how you should test creative. Compare only configurations that satisfy the same approved disclosure requirement. Turning a legally required disclaimer off for an experimental control group is not an ordinary copy test; it creates a different risk condition. Let counsel decide whether disclosure-free delivery is permissible before any such comparison.

    Use a launch sequence that closes the disclosure gap

    Generic ad cards moving through review, disclosure inspection, and monitoring stages, with one incomplete card stopped at a gate.

    Google requires the disclaimer to be added after the campaign has been created, through the Assets menu. That sequence can create a gap between campaign creation and disclosure setup. Close it deliberately:

    1. Define the obligation. Record the campaign, offer, jurisdiction, audience, language, required wording, approving reviewer, and whether the ad may ever serve without the disclosure.
    2. Prepare the final strings. Obtain approval for each language and campaign context, confirm that every string is within 90 characters, and document the exact approved version.
    3. Create without releasing. Create the campaign while keeping it from serving. This gives you access to the post-creation asset workflow without exposing an undisclosed ad.
    4. Add the disclaimer asset. Use the Assets menu, attach the approved text in the intended campaign context, and check that the saved wording matches the controlled copy exactly.
    5. Audit the displaced description. Review the ad without its pinned Description Line 1 and rewrite any claim or offer that loses necessary context.
    6. Verify both gates. Confirm the asset’s platform status and complete your own legal or compliance sign-off. Where feasible, inspect representative language, device, and larger-text conditions for truncation.
    7. Activate with an incident rule. Release the campaign only after its required checks pass. Monitor the asset after material campaign or copy changes, and stop affected delivery if a mandatory disclaimer is disapproved or cannot be verified.

    Your internal disclosure register does not need to be elaborate. A controlled sheet with the campaign identifier, exact text, character count, language, reviewer, approval date, platform status, and failure action is enough to make ownership visible. The important part is connecting an asset-status problem to an immediate operational response.

    Apply the same controls to AI Max. Compatibility means the campaign type can use the asset; it does not remove the need to approve the wording, account for truncation, protect the ad’s meaning, or respond when the asset is disapproved.

    Key takeaways

    • Google Search text disclaimer assets are globally available, work with AI Max, and allow up to 90 characters.
    • The campaign must exist before you add its disclaimer through the Assets menu, so keep it from serving during setup when disclosure is mandatory.
    • A disapproved disclaimer does not necessarily stop the associated ad. Define a monitoring and pause rule before launch.
    • The disclaimer can replace pinned Description Line 1. Review the ad as a changed composition, not as the old ad plus one extra line.
    • Text can be truncated in some languages or at larger font sizes. Put indispensable meaning first and have qualified counsel determine whether the placement is sufficient.

    Before your next regulated Search campaign goes live, add one explicit release condition: the approved disclosure must be present, eligible, and understandable without relying on the first description line. That single gate turns the asset from a convenient text field into a controlled part of your advertising workflow.

    References