Category: International

  • Google Ads Automation and Localization Without Losing Control

    Google Ads Automation and Localization Without Losing Control

    If you manage Google Ads, your website is becoming part of the campaign-building system. An offer published on a page may become a promotion asset, while an existing Search campaign may become the template for a new language and market.

    That can remove hours of repetitive setup. It can also scale an expired discount, awkward translation or unsuitable budget before anyone notices. The right response is not to reject automation. It is to put a clear approval boundary between what Google can generate and what your business is prepared to promise and spend.

    Separate the two automations before setting policy

    Automated promotions and campaign localization solve different problems. They also fail differently. Treating them as one generic AI feature makes it harder to assign the right reviewer and control.

    WorkflowWhat Google createsInitial scopePrimary control
    Automated promotionsA promotion asset based on an eligible offer found on your websiteSearch and Performance Max campaigns with linked location assets and no promotion asset already attachedThe account-level Automated Promotions setting, followed by a review of assets that serve
    AI campaign localizationA new, independent campaign with localized ads, assets and keywordsEligible U.S. English Search campaigns translated into supported languages and markets during the betaLanguage, landing-page and commercial review before the localized campaign goes live

    The promotion workflow extracts a commercial claim that already exists. The localization workflow transforms an existing campaign for a different audience. The first can misstate an offer; the second can reproduce a sound campaign in a market where its language, intent or economics no longer fit.

    A useful account policy is simple: automation may identify, translate and assemble; a named owner must still authorize the promise, the audience and the spend.

    Audit your website before automated promotions serve
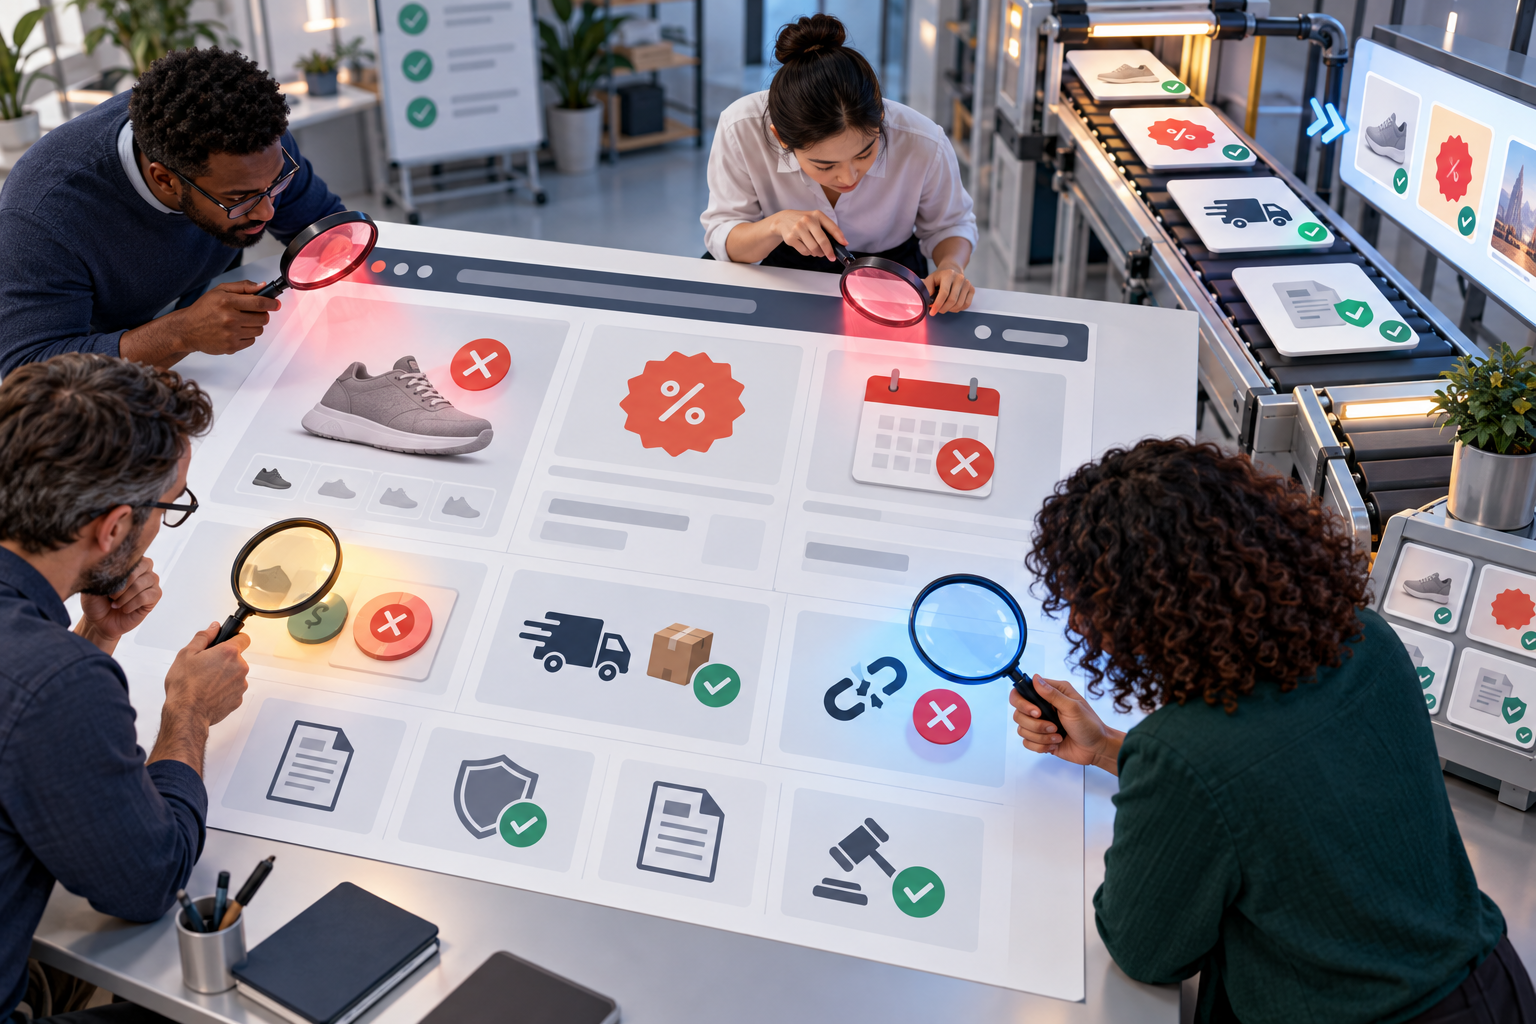
    A review team inspects a website page for expired dates, mismatched prices, unavailable products, and broken links before automation.

    Starting Oct. 12, eligible advertisers may be enrolled automatically. That changes the default risk. Doing nothing is no longer necessarily the same as declining the feature.

    Your first decision is whether the account should participate at all. Keep it enabled when public offers are current, clearly qualified and consistently honored online and in stores. Disable it when promotions require case-by-case approval, depend on complex eligibility rules or frequently remain visible after they expire.

    1. Open the account’s automated asset settings and find Automated Promotions. Record whether it is on or off and who approved that choice.
    2. Inventory public pages that mention discounts, coupon codes, bundles, free items or limited offers. Include store pages when location assets connect campaigns to physical locations.
    3. Make each offer understandable without surrounding marketing copy. State what qualifies, what the customer receives and, where applicable, when and where the offer is valid.
    4. Reconcile the page with the real transaction. Pricing, eligibility and brand wording should agree with the checkout flow, sales process and in-store terms.
    5. After an automated promotion begins serving, inspect it in the Assets section. An asset that has not received impressions will not appear there, so an empty view does not prove that the account is opted out.

    That last distinction matters. The setting tells you whether Google has permission to create automated promotions. The Assets view tells you what has actually accumulated impressions. Check both rather than using one as a proxy for the other.

    If you opt out, use the explicit account-level control. Do not rely on incomplete pages, ambiguous offer wording or the presence of a manually managed asset as an informal safeguard. Automated Promotions can be turned off in automated asset settings, which gives the account team an auditable decision instead of an accidental outcome.

    Launch localization as a new market, not a translation task

    The localization beta can turn one eligible Search campaign into a separate campaign for another language and location. The original campaign remains unchanged. That independence is useful, but it does not make the new campaign commercially ready.

    1. Choose a parent campaign worth reproducing. Fix known targeting, messaging or landing-page problems before translation, or the new campaign will begin with the same structural weaknesses.
    2. Select the exact target language and location. A language label is not a market strategy: Spanish for Spain and Spanish for Latin America and the Caribbean are available as distinct variants in the beta.
    3. Give the AI explicit language rules. Tell it which brand names, product names and technical terms must remain unchanged, and specify whether the voice should be formal or conversational.
    4. Review every campaign component, not just the headlines. The workflow can localize headlines, descriptions, sitelinks, callouts and keywords.
    5. Choose the landing-page method deliberately. You can install a Google-provided JavaScript snippet that dynamically translates page text for visitors from localized ads, or update the campaign URLs to point to pages you already maintain in the target language.
    6. Require a human language and market review. Use the original, localized version and English back-translation shown side by side to check meaning, then ask a fluent reviewer to assess naturalness, search intent, cultural fit and brand terminology.
    7. Reset the economics. Budgets and bids are copied from the original campaign without automatic currency conversion or exchange-rate adjustment. Do not approve launch merely because those fields are populated.

    The landing-page choice deserves particular care. Dynamic translation is a practical route when the underlying offer and customer journey are genuinely the same. A maintained local page is the stronger option when prices, availability, delivery terms, legal wording or conversion steps differ by market. In either case, review the page as the visitor will see it after clicking the localized ad.

    Images also need a separate check. When an image contains text, the workflow can remove the original wording and use the translation as supplemental text assets. Do not assume the output will simply be the same image with perfectly replaced lettering. Preview the complete creative combination and confirm that the visual still makes sense without its original embedded message.

    The beta supports U.S. English Search campaigns localized into Dutch, French, Canadian French, German, Italian, Polish, Brazilian Portuguese, European Portuguese, Spanish for Spain and Spanish for Latin America and the Caribbean. Google plans to add languages by the end of 2026 and later extend localization to Performance Max. Treat that as a roadmap, not as a capability your current launch can depend on.

    Use one release gate for assets, language and money
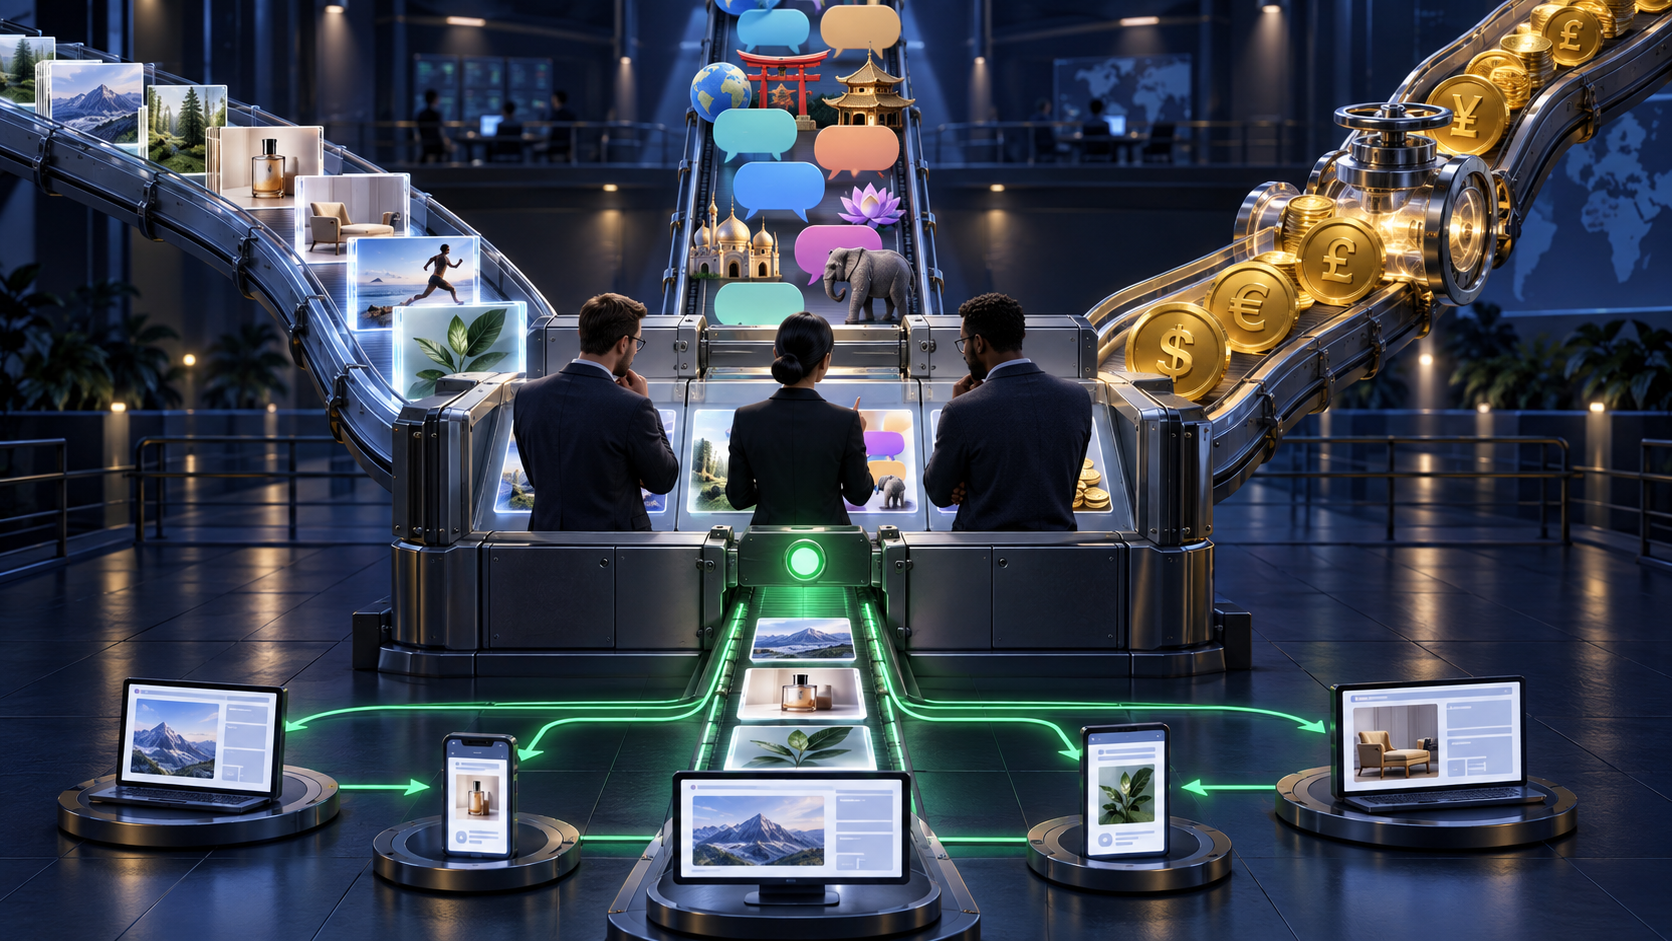
    Three reviewers check advertising assets, localized language elements, and budget tokens at a single campaign release gate.

    The most reliable control is a short release record shared by the website owner, campaign manager and market reviewer. It should force a yes-or-no decision on the places where automation cannot judge your business obligations.

    • Commercial truth: Is the promoted price or benefit currently available, and will every customer who meets the stated conditions receive it?
    • Qualification: Are exclusions, dates and location restrictions consistent across the ad asset, landing page, checkout or sales process, and physical store where relevant?
    • Language: Has a fluent reviewer approved the customer-facing wording rather than relying only on the English back-translation?
    • Search intent: Do the localized keywords represent how people in that market look for the offer, not merely a literal rendering of the parent keywords?
    • Landing experience: Does the visitor remain in the intended language through the meaningful conversion steps?
    • Economics: Have the copied budget and bids been reviewed for the target market instead of accepted as inherited defaults?
    • Ownership: Is one person responsible for pausing the asset or campaign when an offer, page or market condition changes?

    Use event-based reviews rather than a vague instruction to monitor regularly. Reopen the record when an offer starts or ends, a price or landing page changes, an automated asset first receives impressions, a new localized campaign is generated, or its budget and bids are changed.

    After launch, judge the localized campaign on its own market economics. It is an independent campaign, so the parent campaign’s historical success is context, not proof. For automated promotions, compare the served asset with the live offer page and the transaction customers actually receive. The purpose of monitoring is not just to catch strange wording; it is to catch a broken commercial promise.

    Key takeaways

    • Check the account-level Automated Promotions setting before Oct. 12; eligible advertisers may be enrolled without making an affirmative choice.
    • Treat every public offer page as potential campaign input, especially when Search or Performance Max campaigns use linked location assets.
    • Do not use an empty Assets view as proof that automation is disabled; unserved assets do not appear there.
    • Review localized campaigns as independent market launches, including keywords, creative, landing pages, language quality and cultural fit.
    • Replace copied budgets and bids with a deliberate market decision because the localization workflow does not perform currency or exchange-rate adjustments.

    Your next step is small and concrete: open one eligible account, document its automation setting, then choose one live offer and one possible target market to run through the release gate. That will expose missing ownership and inconsistent inputs before automation exposes them to customers.

    References


  • International SEO Keyword Localization: A Practical Workflow

    You have a translated landing page, a target-country keyword database, and a discouraging result: the obvious phrase has little volume or no data at all. Before you question the market, question the phrase you used to enter it.

    International keyword localization is the work of discovering how people in a specific market describe the category, their role, the outcome they need, and any local qualification or institution that shapes the search. Done properly, it tells you whether to translate an existing page, rewrite it around a different concept, or create a market-specific page from scratch.

    Start with the market’s vocabulary, not a translation

    Translation answers, “How do we express this phrase in another language?” Keyword localization answers, “What does someone in this market actually search when they need this product, service, qualification, or outcome?” Those questions overlap, but they aren’t interchangeable.

    A translated category can be accurate, fluent, and almost useless as a research seed. People may organize the same need around an occupational title, exam, license, professional card, regulatory code, agency acronym, or locally familiar shorthand. These terms are market artifacts: labels created by the institutions and practices of the market rather than by the generic category itself.

    The effect can be large enough to resemble an absence of demand. In one U.S. Semrush lookup, “commercial drone operator training” returned no related keywords, while “drone pilot training” opened a 26,520-keyword set. FAA Part 107 appeared at rank 17 within the first 1,000 deduplicated rows. In Spain, “curso de operador profesional de drones” returned no data, while “curso de piloto de drones” produced 338 raw terms and 292 after normalization; “AESA A1 A3” appeared at rank 14.

    Those snapshots don’t prove that occupational wording always beats descriptive wording, and the numbers shouldn’t be reused as forecasts for another market. They demonstrate a more important mechanism: a seed controls which keyword neighborhood a tool can enter. If the seed sits outside the market’s normal vocabulary, the tool may return nothing. If it enters the wrong neighborhood, it may return an impressive list that still excludes the terms that govern real demand.

    Build a market vocabulary map

    Before collecting volume, map the different ways the market can name the need. A useful map separates five layers:

    Vocabulary layerQuestion it answersTypical seed types
    CategoryWhat is being sold or learned?Training, software, insurance, certification course
    RoleWhat does the searcher call the person or occupation?Drone pilot, security guard, technician, adviser
    QualificationWhat proves eligibility or competence?License, card, certificate, exam, statutory title
    Institutional systemWhich authority, law, framework, or code organizes the activity?FAA Part 107, AESA A1/A3, TIP, EPA 608
    Task or outcomeWhat is the person trying to do next?Qualify, prepare, renew, apply, comply, become eligible

    One concept may need seeds from every layer. A generic training phrase can reveal broad informational demand, while a license or exam term reveals the route taken by people closer to enrollment. Neither should automatically replace the other. Their jobs are different.

    This is also why “ask a native speaker” is incomplete advice. A native speaker can produce natural wording without knowing the specialist vocabulary of private security, aviation, financial licensing, healthcare, or another regulated field. You need linguistic fluency and market knowledge.

    Give your local reviewer concrete questions instead of asking for a translation:

    • What do practitioners and customers call the occupation?
    • Which license, card, certificate, exam, or membership is associated with entry?
    • Which agency, regulator, law, or code appears in ordinary conversation?
    • What language appears in job listings, training catalogs, and provider navigation?
    • What would a beginner search, and what would an experienced practitioner search?
    • Which acronyms are used on their own, and which full names should accompany them?
    • Does the term describe a legal requirement, an industry convention, or merely a popular course name?

    That last distinction matters. Do not infer a legal obligation from keyword volume, competitor copy, or an AI answer. When a credential or regulation affects eligibility, verify its current name, scope, and issuing authority with the relevant regulator or a qualified local specialist before publishing. Search data can reveal the vocabulary; it isn’t a legal authority.

    Run native keyword research as a controlled workflow

    A reliable process preserves the path from the business concept to the localized page. It should be possible to see which seed produced a term, which tool and discovery route returned it, how a local reviewer interpreted it, and which page will satisfy it.

    1. Define one market, one audience, and one offer. A language isn’t a market. Record the country, language or locale, audience, product availability, conversion action, and any eligibility restrictions before opening a keyword tool.
    2. Write a neutral concept statement. Describe what the offer does and who it serves without treating the home-market keyword as universal. This statement keeps the meaning stable while local terminology changes.
    3. Collect market artifacts before expansion. Review local regulator terminology, professional bodies, training catalogs, job listings, competitor navigation, result-page titles, and recurring questions. Record full names, acronyms, spelling variants, and the relationship between each artifact and the offer.
    4. Create a seed portfolio. When the evidence supports them, use two or three candidates from the category, role, qualification, institutional, and task layers. A portfolio protects the project from the failure of any single translated phrase.
    5. Run lexical and discovery routes separately. A broad-match route may mainly return phrases containing variations of the seed. Related-keyword or keyword-idea routes attempt to construct a broader neighborhood. Label the route in your export so a term that appeared because you typed it directly isn’t mistaken for an independently discovered opportunity.
    6. Preserve raw data, then normalize a copy. Keep the original query, accents, punctuation, and tool metrics. In separate fields, create a canonical form for deduplication, group obvious singular-plural or word-order variants, and assign intent. Never destroy the form people actually use just to make the spreadsheet tidy.
    7. Complete native and commercial review before prioritizing volume. Confirm what the query means, whether its result pages match the assumed intent, whether the offer can serve that intent in the market, and whether the term belongs on an existing page or needs a new one.

    Your working sheet should include more than keyword and volume. At minimum, retain the market and locale, original query, normalized cluster, seed, vocabulary layer, provider, retrieval route, intent, market artifact, relevance status, proposed page, reviewer, and verification status. This provenance becomes essential when two tools disagree or a stakeholder asks why a local page doesn’t mirror the home-market one.

    Keep discovery separate from prioritization

    Discovery asks whether you have found the vocabulary of the market. Prioritization asks which validated clusters deserve content and investment. If you sort by volume before discovery is credible, generic phrases will dominate while lower-volume institutional terms may disappear from view.

    Start by classifying each query into intent and vocabulary layers. Then assess relevance, page fit, commercial value, and available metrics. Avoid summing every close variant as though each represents a separate audience. Keep both cluster-level demand and the underlying query forms so writers know which wording sounds natural.

    Diagnose empty and convincing result sets differently

    An empty result set is visible, so teams often notice it. A populated but incomplete result set is more dangerous because it looks like successful research.

    A controlled comparison run on August 21, 2026 illustrates both failure modes. It used eight predetermined U.S. and Spanish cases and 80 combinations across Semrush and DataForSEO, with seeds, aliases, normalization rules, analysis limits, and decision thresholds fixed before retrieval. In Semrush Related, neutral descriptive seeds recovered the predetermined market artifact in two of seven observable cases; the other five cases returned empty sets. DataForSEO Keyword Ideas recovered the artifact in two of eight cases, but every neutral seed returned a populated set. In six cases, the artifact was absent from the first 1,000 canonical rows.

    These are results from a small, constructed comparison, not universal recovery rates for either provider. Their value is diagnostic. Similar-looking success rates concealed different problems: failure to enter a keyword neighborhood in one route and failure to expose the institutional layer in another. The providers also disagreed about which cases they recovered, so adding another tool is useful as a coverage check, not as an automatic tie-breaker.

    What you seeWhat may be happeningWhat to do next
    No keywords returnedEntry failure: the seed didn’t connect to a usable neighborhoodTry role, qualification, institution, and task seeds. Confirm the country database. Do not record zero demand.
    Many keywords, but no known credential or codeDiscovery failure: a neighborhood exists, but its institutional layer is missingSearch verified artifacts directly, add their aliases, use another discovery route, and inspect local result pages.
    The artifact appears only when used as the seedLexical retrieval rather than independent discoveryKeep the term, but label its provenance correctly. Test whether related seeds can recover it.
    Providers return different artifactsDifferent databases or retrieval methods expose different neighborhoodsTake the union of relevant terms, preserve provider provenance, and let local validation resolve meaning.
    Generic high-volume terms dominateThe seed may be too broad or aligned with the wrong intentAdd occupation, eligibility, exam, application, or compliance language and recheck page-level intent.

    Use coverage gates before calling the map complete

    Create a verified artifact list for the market, then give every item one of four statuses: independently discovered, found only when seeded, absent, or irrelevant to the offer. A simple artifact-coverage measure is the number of relevant artifacts recovered through discovery divided by the number of relevant artifacts verified outside the tool. It isn’t a ranking metric. It tells you whether the research process can see the market vocabulary you already know matters.

    Apply four additional gates:

    • Semantic gate: a native reviewer confirms that the term means what the team thinks it means.
    • Intent gate: the target-market results represent an intent the proposed page can satisfy.
    • Institutional gate: names, acronyms, credentials, and legal claims have been checked against a current authoritative source.
    • Commercial gate: the business can actually provide the product, pathway, or outcome implied by the query in that jurisdiction.

    Only after those gates should search volume, competition, conversion proximity, and production cost determine priority. A term with attractive volume but the wrong qualification, jurisdiction, or user expectation isn’t an opportunity. It is a mismatch.

    Turn localized clusters into the right page architecture

    Keyword localization isn’t complete when the spreadsheet is approved. Its value appears in the decision you make about each page.

    • Localize the existing page when the dominant intent, offer, and user journey remain substantially the same and only the language changes.
    • Rewrite the page around a local frame when the offer is the same but people enter through a different role, credential, or institutional term.
    • Create a market-specific page when eligibility, required steps, proof, or conversion paths differ enough that translated copy would mislead the reader.
    • Exclude the cluster when the business cannot serve the implied jurisdiction, requirement, or outcome. Traffic isn’t useful if the page creates a false expectation.

    A localized content brief should identify the primary cluster, supporting variants, user stage, dominant local role, relevant market artifacts, jurisdiction, page purpose, required answers, internal-link targets, and claims that need authoritative verification. It should also flag home-market language that must not be carried over automatically.

    Use the local terminology in the visible content before considering structured data. Name the qualification, institution, product, and jurisdiction clearly; expand ambiguous acronyms on first use; and explain how the entities relate. JSON-LD should represent what the page actually says. Schema markup can’t repair a page built around the wrong market concept, and adding an entity name only in markup doesn’t make the visible answer useful.

    The same clarity supports answer-engine and generative-search optimization. Give important market questions direct, self-contained answers. If a credential controls the journey, state who issues it, which market it applies to, who needs it, and what action the reader is trying to complete. Keep those statements current and evidence-backed. This creates a clearer entity-and-intent structure for search systems without pretending that formatting or schema guarantees visibility.

    Technical international SEO comes after that editorial decision. Hreflang, canonicals, language targeting, and localized URLs help search engines understand page relationships, but they can’t make a literal translation satisfy a different local intent. Decide what each market needs first; then encode the relationship accurately.

    Measure each localized cluster by market rather than blending language-level performance. Track impressions, clicks, qualified conversions, and page-level intent. If you monitor AI answers, record the prompt, language, market setting, date, response, and cited URL so results can be compared consistently. Revisit the vocabulary map when the offer, qualification pathway, or regulatory terminology changes.

    Key takeaways

    • Translate the business concept, then research the query language natively.
    • Use a seed portfolio spanning category, role, qualification, institution, and task language.
    • Treat licenses, exams, cards, agency acronyms, and regulatory codes as first-class keyword candidates.
    • An empty keyword set indicates a failed entry route, not proof that the market has no demand.
    • A large keyword set can still be incomplete if it omits verified market artifacts.
    • Keep lexical and discovery routes separate, preserve provenance, and validate meaning before prioritizing volume.
    • Let localized intent determine whether you translate, rewrite, create, or exclude a page.

    Start with one high-value page and one target market. Build its artifact list, run seeds from each vocabulary layer, and mark what every route recovers or misses. You will quickly learn whether your existing plan reflects the way that market searches or merely the way your home market describes itself.

    References


  • Google’s EEA Site Reputation Abuse Change: An SEO Plan

    Google’s EEA Site Reputation Abuse Change: An SEO Plan

    If your site attracts searchers inside and outside the European Economic Area, one site reputation abuse notice can now produce two different visibility outcomes. From August 30, 2026, the affected section can remain visible to EEA searchers while losing placement elsewhere.

    That isn’t an amnesty for parasite SEO. It is a regional change to the effect of one type of manual action. You still need to audit the flagged section, separate regional performance in your reporting, and fix the underlying publishing model if you want durable visibility.

    Key takeaways

    • From August 30, 2026, a site reputation abuse manual action will not directly affect results shown to searchers in the EEA.
    • The same action can still reduce visibility for the affected portion of the site when people search from outside the EEA.
    • The searcher’s location determines which treatment applies. The site owner’s address, company location, hosting region, or domain extension is not the deciding distinction described by the change.
    • Within the EEA, Google may separate the third-party section from the host site in its systems so that the section eventually ranks on its own merits.
    • Search Console notices, reconsideration requests, broader spam enforcement, and the business risk of relying on borrowed domain authority all remain relevant.

    One manual action now has two regional outcomes

    Site reputation abuse generally refers to third-party material placed on an established site to exploit the host’s ranking reputation. The obvious risk pattern is deceptive pay-to-play publishing: an outside party gains access to a trusted domain, while the resulting pages compete with an authority they may not have earned independently.

    The August change is narrower than the phrase “Google is ending site reputation abuse enforcement in Europe” would imply. It changes how a manual action affects results for a particular audience. It does not abolish the policy, prevent notices from being issued, or suspend Google’s other spam systems in the EEA.

    QuestionSearchers inside the EEASearchers outside the EEA
    Does the site reputation abuse manual action directly affect the result?NoYes, for the affected portion of the site
    Is the rest of the site directly included in that manual action?The manual-action impact does not applyNo; the action applies to the affected portion
    Can the affected section still lose the host site’s ranking advantage?Potentially. Google may separate it in its systems and assess it independently over timeThe manual action can directly affect its placement
    Can the site owner still receive a Search Console notice?YesYes

    The location test is about the person searching. A publisher based in the EEA can still be affected when its pages are shown to users elsewhere. Likewise, an operator outside the EEA can receive the EEA treatment for searches originating within the region. Treat this as an audience-level rule, not a headquarters-level exemption.

    There is also an important difference between avoiding a direct manual-action effect and retaining the host domain’s authority. In the EEA, Google may separate the implicated section in its systems so that it ranks independently from the rest of the site. If that happens, the section should not be assumed to keep benefiting from the reputation that made the arrangement attractive. It could retain, gain, or lose visibility according to how it performs when assessed more independently; no guaranteed outcome or fixed separation timetable has been given.

    The practical conclusion is simple: an EEA traffic line that remains stable does not prove that the publishing model is safe. It may only show that the direct manual-action effect is not being applied to that audience.

    Audit the publishing model, not just the flagged URLs

    An analyst examines the connections between a shared website structure and a semi-detached publishing section controlled through external systems.

    A page-by-page cleanup is too narrow if the commercial arrangement keeps producing the same kind of content. Your audit needs to connect URLs to ownership, editorial control, payment, and audience. Use the following sequence.

    1. Inventory third-party sections by template and directory. Include sponsored areas, partner publishing programs, white-labelled experiences, affiliate-led sections, and any other URL group substantially supplied or operated by an outside party. Third-party involvement alone does not establish abuse; the inventory tells you where to investigate.
    2. Record who actually operates each section. Note who selects topics, produces the material, approves publication, handles corrections, and controls the user experience. A host logo or final approval checkbox can hide the fact that the outside party is making every meaningful decision.
    3. Document the value exchange. Identify whether access, placement, leads, sales, or rankings are tied to payment or another commercial benefit. This is where a seemingly ordinary content partnership can reveal a pay-to-play ranking strategy.
    4. Test the role of the host’s reputation. Ask whether the section has a credible reason to live on this domain beyond gaining its authority and distribution. If the business case collapses without the ranking advantage, treat that as a serious warning.
    5. Map the section’s audience by region. Establish how much organic demand comes from the EEA and how much comes from elsewhere. A globally viewed page can have a manual action whose visible effect appears only in the non-EEA segment.
    6. Choose a section-level response. Depending on what the audit finds, that may mean ending the arrangement, removing affected material, changing who controls publication, or rebuilding the section around genuine first-party editorial responsibility. A new folder name by itself does not address an unchanged publishing model.

    Do not convert those questions into a superficial compliance form. The point is to identify whether an outside party is borrowing the site’s reputation while the host contributes little beyond access to the domain. Evidence of real editorial work should appear in the workflow: named decision-makers, substantive review, correction ownership, and a defensible reason the content belongs with the site’s primary purpose.

    Be equally careful not to classify every contributor, syndication agreement, or commercial relationship as abuse. Start with the mechanism. The concern is the use of third-party content and established site authority as a ranking shortcut, especially in deceptive pay-to-play arrangements. Evaluate the whole arrangement before making removal decisions that could affect revenue, contractual obligations, or useful content.

    Measure EEA and non-EEA visibility separately

    Two regional monitoring stations separately observe the same stack of generic web-result cards, which appears at different positions in each field.

    A global organic-traffic total will conceal the effect you are trying to diagnose. One region can improve while another declines, leaving the combined line looking deceptively calm. Build the regional split before you need it.

    Set up a monitoring view that exposes the difference

    • Annotate August 30, 2026. Use the effective date as a reporting marker, not as proof that every later movement was caused by the policy change.
    • Create EEA and non-EEA country groups. Apply the same grouping consistently in Search Console exports, analytics, rank tracking, and internal reports.
    • Split the affected section from the rest of the domain. Track its directories, page templates, or URL patterns separately. Domain-wide averages are not a reliable proxy for a section-specific action.
    • Compare page and query groups. Look for the same affected URLs losing impressions or positions outside the EEA while behaving differently within it.
    • Keep manual and system-level effects distinct. A change outside the EEA may align with the direct action. A gradual movement inside the EEA may be consistent with independent section assessment, but timing alone cannot prove the cause.
    • Preserve the notice and remediation timeline. Record when the action appeared, which section it named, what changed, and when a reconsideration request was submitted. That chronology is more useful than a screenshot of total traffic.

    Use annotations and segmented comparisons to form a diagnosis, not to manufacture certainty. The disclosed treatment says separation can happen “over time”; it does not provide a fixed number of days or a guaranteed ranking pattern. Core updates, demand changes, technical faults, and ordinary competition can still move the same metrics.

    Respond to a Search Console notice even if EEA traffic holds

    Sites can continue receiving site reputation abuse notifications in Search Console, including sites based in the EEA. Ignoring one because local traffic looks unchanged leaves non-EEA visibility exposed and does nothing to strengthen a section that may be assessed independently.

    1. Read the notice closely and identify the exact portion of the site it covers.
    2. Match that scope to your third-party content inventory. Check sibling pages and templates that use the same operating model, not only the example URLs you noticed first.
    3. Decide whether the action appears mistaken or whether the underlying arrangement needs correction. Preserve the facts supporting that decision.
    4. Complete the remediation across the relevant section before requesting review. Partial changes make it harder to show that the underlying pattern has ended.
    5. Submit a reconsideration request if you believe the action was erroneous or after the issue has been corrected. Eligible sites may also have access to mediation following the reconsideration process.
    6. Continue monitoring both regional groups. Removal of the action and recovery of every previous ranking are not the same claim, especially where a section may be evaluated independently.

    Build sections that do not depend on borrowed authority

    The regional enforcement split changes the immediate consequence, but it does not improve a weak content operation. The safer strategic test is whether the section deserves to exist and compete when detached from the host domain’s accumulated reputation.

    Use these governance questions before approving a new partnership or renewing an existing one:

    • Would you publish this material if it brought no shortcut to search visibility?
    • Does it serve the same audience and purpose as the site’s first-party content?
    • Can your editorial team verify claims, reject topics, require changes, and correct errors?
    • Is the commercial relationship clear enough for internal reviewers to understand why the section exists?
    • Would the pages remain useful if users and search systems assessed them without the halo of the host brand?
    • Can one accountable owner explain the section’s editorial, commercial, technical, and search risks?

    These are governance checks, not a substitute for Google’s policy language or a promise of compliance. Their value is that they expose the business dependency behind parasite SEO. A section built primarily to rent domain authority remains fragile even where a regional manual action does not directly suppress it.

    Before your next search performance review, add two rows to the report: affected-section visibility inside the EEA and the same visibility outside it. Then assign an owner to every third-party URL group. That small change will tell you whether you are looking at a genuine recovery, a regional enforcement difference, or a publishing model that still needs to be rebuilt.

    References


  • How to Build Culturally Aware Marketing Personalization

    How to Build Culturally Aware Marketing Personalization

    If your Mexico campaign is a translated version of your Spain campaign with a different flag, you have not personalized it. You have changed the label while leaving the customer’s decision context untouched.

    Culturally aware personalization works in two passes. First, establish what is true for the market: availability, language, pricing, payments, delivery, support, policies, and local proof. Then use the individual’s preferences and recent behavior to decide which of those truths matter now. This gives you more relevant marketing without turning culture into a crude demographic shortcut.

    Personalize the market before you personalize the person

    Do not begin with the question, What does this culture like? That invites stereotypes and gives your team little operational guidance. Ask instead: What must be true for this customer, in this market, to make the decision confidently?

    Spanish-speaking markets make the distinction easy to see. When more than 20 countries are compressed into one generic Spanish audience, Spain often becomes the unspoken default and other markets inherit its vocabulary, formats, assumptions, and commercial context. The copy may be grammatically correct while the experience is commercially wrong.

    A customer does not experience culture as a tone-of-voice document. They encounter it through the words used for a product, the currency beside the price, the payment methods available at checkout, the delivery promise, the return process, the support they can reach, and the rules governing the transaction. If those details contradict one another, adding local slang will not make the campaign feel local.

    Before creating a market segment, complete a market-readiness check:

    1. Confirm serviceability. Define which products or services are actually available, where they can be delivered, and which promises your operation can keep.
    2. Confirm the transaction. Record the correct currency, price, payment options, taxes or fees your team is responsible for presenting, and any offer restrictions.
    3. Confirm support. Identify the language variant customers can use, the channels available to them, and who owns escalation when the standard journey fails.
    4. Confirm policy scope. Have the appropriate internal specialists approve market-specific claims, disclosures, terms, and customer-facing policies. A translation team should not be expected to invent regulatory guidance.
    5. Confirm local evidence. Select examples, partnerships, media mentions, testimonials, and practical details that genuinely belong to the market. Do not relabel global proof as local proof.

    If you cannot complete those five checks, you are not ready to promise a localized experience. Publish market-neutral information, state the limits clearly, or delay the campaign. A market-specific URL or hreflang annotation cannot repair a service that does not fit the market.

    This also defines the right unit of personalization. A language is not a market, a market is not a culture, and a culture is not an individual. Treat each layer as context rather than identity.

    Build a profile that separates context from identity

    A shopper stands between separate translucent cabinets containing market-context objects and personal-preference objects.

    Most personalization programs try to place everything into one customer profile. A safer and more useful design keeps market truth separate from person-level signals, then combines them only when making a decision.

    LayerWhat it containsWhat it should control
    Market contextCountry or region served, language variant, currency, catalog, pricing, payments, delivery, support, policies, and approved local evidenceWhat the brand is eligible to say, sell, recommend, or promise
    Customer contextDeclared preferences, consent, account market, recent browsing, purchases, support interactions, and communication historyWhich eligible message is most useful to this person now
    Decision contextChannel, journey stage, current product, recent event, and any conflicting or missing signalsWhether to personalize, ask for clarification, suppress a message, or use a neutral fallback

    The market layer should be owned like product data, not treated as campaign copy. When a payment option, delivery promise, price, or policy changes, the underlying market record should change once and feed every channel that uses it.

    The customer layer needs a confidence hierarchy. Use signals in this order:

    • Declared preferences: the language, market, channel, or product interest the person chose. Make these settings easy to review and change.
    • Verified relationship data: the market attached to an account, contract, shipping destination, or completed transaction, when using it is appropriate for the interaction.
    • Observed behavior: pages viewed, products compared, carts started, purchases made, and support journeys opened. These signals describe recent intent, not cultural identity.
    • Inferences: predicted interests or likely next actions. Store their origin, confidence, and age, and provide a neutral fallback when the prediction is weak.

    A language setting, surname, device location, or content choice does not prove nationality or ethnicity. Do not use those signals as proxies for sensitive identity. If market selection materially changes prices, eligibility, access, or terms, let the person confirm it and explain why you need the information. In situations involving protected or sensitive traits, have privacy and legal specialists review both the inputs and the resulting decisions before activation.

    Expectation is not the problem. An Adobe 2026 report found that 71% of consumers wanted personalized deals and content and 78% expected a seamless cross-channel experience, while fewer than half of brands delivered that consistency. The gap appears when fragmented records make one channel unaware of what happened in another.

    Your unified profile therefore needs suppression signals as much as recommendation signals. A product view may justify a useful follow-up. It should not override a later purchase, an unresolved complaint, an unavailable product, a declined consent setting, or a market rule that makes the offer ineligible. Personalization becomes trustworthy when the system knows when not to personalize.

    Transcreate the decision, not just the sentence

    Translation asks whether a sentence carries the same literal meaning. Transcreation asks whether the entire decision makes sense in the customer’s market. That includes terminology, examples, offer details, proof, objections, and the action the customer is being asked to take.

    This distinction also matters for AI discovery. If two country pages remain about 95% alike, an AI system may merge them into one representation and prefer whichever version appears most standard. Changing the country name in the heading is not enough to establish a distinct market entity.

    Create a transcreation brief before a writer touches the copy. It should answer:

    • Which market and language variant is this asset for?
    • What customer decision must the asset support?
    • Which terms are locally expected, and which apparently equivalent terms could mislead?
    • What price, currency, payment, availability, delivery, return, and support facts must remain exact?
    • Which objections are specific to this market or journey?
    • Which local examples and proof can the customer verify?
    • Which claims, jokes, idioms, images, or references require review rather than direct adaptation?
    • What should the system show if the visitor’s market is unknown or conflicts with the page?

    Review the result in three passes. A language reviewer checks meaning and natural usage. A market owner checks commercial and operational truth. A journey owner follows the call to action through the next screen, email, checkout, or support handoff. This last pass catches a common failure: localized acquisition copy leading into a generic or contradictory transaction.

    Personalize message hierarchy before surface details. Suppose a returning visitor has repeatedly compared one service. The market layer should first supply the correct offer, terminology, delivery or implementation conditions, and local proof. Only then should the behavior layer move comparison details, a relevant case example, or the next practical step higher on the page. Inserting the person’s first name while leaving the wrong currency in the offer is not meaningful personalization.

    Use local slang sparingly. It can be effective when it belongs naturally to the brand, audience, and situation, but it is not evidence of cultural understanding. Accurate transaction details and recognizable customer problems carry more trust than decorative regional language.

    Put cultural boundaries into retrieval and activation

    An isometric content library routes marketing assets through transparent guardrail gates while two people review diverted items.

    AI will not repair ambiguous market data. It will process that ambiguity faster and reproduce it across more channels. The guardrails therefore need to exist before generation, recommendation, or orchestration begins.

    Use this decision sequence for web personalization, email, paid media, support prompts, product recommendations, and retrieval-augmented generation:

    1. Resolve the service market. Prefer an explicit selection or verified account context. When signals conflict, ask or use a neutral experience; do not silently translate location into nationality.
    2. Apply eligibility rules. Remove products, offers, claims, and actions that are unavailable or inappropriate in that market before calculating person-level relevance.
    3. Filter the content pool. Retrieve assets with matching language, market, currency, availability, policy scope, and approval status. In a RAG system, apply this filter before semantic ranking, not after the model has drafted an answer.
    4. Rank eligible options. Use declared preferences, current intent, journey stage, purchases, and support events to choose among the remaining messages.
    5. Compose from approved facts. Let AI adapt structure or emphasis only within the market facts and claims your owners have approved.
    6. Validate the output. Check market, language variant, price, currency, payment, availability, delivery, policy, and call-to-action destination before publication or send.
    7. Record the decision. Log which context, rule, asset, and model or workflow produced the experience so your team can investigate errors instead of guessing.

    A practical content record might include fields such as language, country or region, currency, product eligibility, policy scope, approval owner, review date, and supported channels. The names can match your stack; the important part is that market boundaries are machine-readable and maintained by accountable owners.

    For an unknown market, the fallback should be deliberately neutral. Present only globally valid information, avoid market-specific prices or promises, and offer a clear market selector when the choice changes the experience. Defaulting every Spanish-language visitor to Spain, Mexico, or an averaged global segment simply hides uncertainty inside the system.

    Your public discovery signals need the same consistency. Market-specific URLs, hreflang, visible copy, structured data, offer details, organization information, and internal links should point to the same locale. Structured data must agree with what the customer can see; markup cannot make an unavailable service locally available.

    External authority matters as well. Local media coverage, partnerships, and consistent regional entity signals help search and generative systems connect the brand with the market it actually serves. Build those relationships around real operations and expertise, not location names inserted for ranking.

    Finally, keep channels synchronized. If the website records a purchase, email should stop promoting the same first purchase. If support opens a serious issue, an upbeat upsell should not arrive because the advertising platform still sees an old audience membership. Real-time activation is valuable only when every channel receives the same updated customer and market truth.

    Measure accuracy before celebrating personalization lift

    A global conversion rate can conceal a strong result in the default market and a poor experience everywhere else. Evaluate each market separately, and separate commercial lift from cultural and operational accuracy.

    Your scorecard should cover five questions:

    • Eligibility accuracy: How often did customers see only products, offers, and actions genuinely available to them?
    • Experience consistency: Did the price, currency, availability, delivery, policy, and support promise remain consistent from discovery through conversion and service?
    • Personalization value: Did the personalized experience improve the chosen outcome against a suitable non-personalized or market-baseline experience within the same locale?
    • Retrieval accuracy: When search engines or your own AI system answered a market-specific question, did they retrieve the correct regional page and preserve its local facts?
    • Trust signals: Are opt-outs, complaints, corrections, support escalations, and manual market changes revealing a segment that your performance average hides?

    Maintain a fixed quality-assurance set for every supported market. Include an anonymous visitor, a person with a declared market, a returning customer, a visitor with conflicting language and market signals, an ineligible offer, an outdated asset, and a recent support event. Run the same cases across web, email, recommendations, support, and AI answers whenever data, rules, prompts, or content change.

    When a test fails, classify the cause before editing the copy. The root problem may be incorrect market data, weak identity resolution, missing consent, an eligibility rule, stale content, unrestricted retrieval, generation drift, or a cross-channel delay. That classification tells you which owner can actually fix the failure.

    A/B testing remains useful, but compare variants inside the same market and service conditions. If one variant receives different inventory, prices, or operational support, you are testing more than messaging. Document those differences or the result will not tell you what to repeat.

    Key takeaways

    • Treat cultural context as market and service information, not as a shortcut for ethnicity or nationality.
    • Establish availability, transaction, support, policy, and local-proof facts before applying person-level behavior.
    • Transcreate the full decision journey; translated copy cannot compensate for the wrong currency, offer, delivery promise, or policy.
    • Filter AI retrieval by market eligibility before ranking content for personal relevance.
    • Give uncertain or conflicting profiles a neutral fallback and an easy way to confirm their market.
    • Measure eligibility, consistency, retrieval accuracy, and trust signals by market alongside conversion lift.

    Start with one market and one high-intent journey. Write down the service truth, select the signals you can use responsibly, transcreate the necessary assets, add eligibility and retrieval gates, and test the journey through every active channel. Expand only when your team can trace a wrong experience back to the exact data, rule, or asset that created it.

    References

  • A Practical Framework for Local Spanish AI Search Visibility

    A Practical Framework for Local Spanish AI Search Visibility

    You can publish polished Spanish content and still disappear from an AI answer, appear under the wrong country, or be described with the wrong currency, service area, or legal context. When that happens, translation quality usually isn’t the whole problem. Your pages are asking the system to infer which market you mean.

    The fix is to treat every answer as a market-specific record: who it applies to, where it applies, what the local terms mean, and which business facts support it. You then repeat that context across your pages, local profiles, structured data, product feeds, and customer-facing answers.

    Treat Spanish as a language, not a location

    A language choice does not establish a country, city, jurisdiction, or commercial market. A page can be grammatically correct in Spanish while remaining geographically unusable.

    This distinction matters more in generative search than it did in a conventional results page. A list of links lets the searcher notice that one result comes from Spain and another from Mexico. An AI response may instead combine several markets into one apparently authoritative answer. If the synthesis is wrong, the user may never see the correct local page underneath it.

    Context layerWhat the system must distinguishWhat can go wrongWhat your content should state
    Language varietyRegional vocabulary, formality, and product terminologyThe answer sounds imported or describes the wrong product categoryThe words customers use in that market and the preferred form of address
    GeographyCountry, region, city, and service areaA local query returns a supplier, branch, or recommendation from another countryThe country and served locations in visible copy, not only in navigation or metadata
    CommerceCurrency, number format, payment options, shipping, and availabilityA price is misread or an unavailable purchasing method is presented as validThe applicable currency, displayed number format, fulfillment limits, and payment conditions
    JurisdictionRegulator, tax identifier, legal vocabulary, and governing rulesTerms such as Hacienda, SAT, NIF, and RFC are treated as interchangeableThe jurisdiction, applicable authority, and limits of the answer

    The failure is easy to see in a tax question. An answer can be fluent while mixing RFC, NIF, and SSN into a single checklist. Currency and punctuation create quieter errors: Mexico and European Spanish conventions can give periods and commas different numerical meanings. The text still looks localized, but the transaction it describes may be wrong.

    Use a simple decision rule when planning pages. Create a distinct country version when the market changes the offer, eligibility, price currency, number format, fulfillment, payment method, legal obligation, or vocabulary needed to identify the product. Add a location-specific page or section when availability and customer questions change within that country. Keep a shared Spanish page only when its answer remains true for every market it claims to serve.

    Do not solve the problem by cloning the same generic page across a directory of country codes. A changed place name wrapped around unchanged advice gives an AI system more URLs but no better evidence. Each local version needs a reason to exist and enough market-specific facts to make that reason visible.

    Build a market-specific answer system from real questions

    People in different neighborhood settings organize local question, service, product, and policy symbols into separate answer packages.

    Your localization plan should begin with customer uncertainty, not a keyword export. Reviews, support calls, social replies, sales conversations, local profiles, and on-site searches reveal the wording people use when they need to make a decision. They also expose questions that broad national search-volume tools can miss.

    Create a market brief before drafting pages

    1. Define the market unit. Record the country, relevant region or city, service area, and Spanish variety. If a branch has different inventory, hours, eligibility, or delivery coverage, treat those as location facts rather than burying them in a national answer.
    2. List the commercial facts that can change. Include currency, displayed number format, payment methods, shipping or appointment limits, product availability, contact details, and any local terminology customers use to describe the service.
    3. List regulated facts separately. Record the jurisdiction, regulator or authority, legal identifiers, reviewer, and review trigger. Do not let a reusable marketing template overwrite this layer.
    4. Collect the questions customers actually ask. Preserve the original regional wording alongside a normalized topic label so you can recognize equivalent intent without erasing dialect.
    5. Assign a canonical answer, an owner, a public URL, the channels where the answer appears, and the conditions that require an update.

    The brief becomes the source of truth for that market. It prevents a translator, local manager, product-feed owner, and social team from independently producing four plausible but incompatible versions of the same fact.

    Turn local language into canonical answers

    Generic questions such as “What services do you offer?” rarely resolve local uncertainty. Better questions expose a boundary: whether you deliver to a named city, whether a quoted price uses MXN or EUR, whether a service is available for a particular building type, or which jurisdiction governs a requirement. Region-specific questions can be useful even when they have little national search volume.

    For each question, maintain a compact answer record containing:

    • The customer’s original wording and the normalized intent.
    • The country, region, city, or branch to which the answer applies.
    • A direct answer that states the decisive fact first.
    • Necessary conditions, exclusions, and next steps.
    • The page, profile, feed, and support material where the answer is published.
    • The person responsible for accuracy and the event that should trigger review.

    Publish each answer where it helps the decision. A delivery limitation belongs near delivery information. A market-specific eligibility answer belongs on the relevant service page. A short FAQ can support either page, but a giant FAQ archive should not become the only place where critical local facts appear.

    Then reconcile the answer across every channel you control. Hours, service areas, prices, accepted payment methods, product availability, and legal wording should not change when a user moves from your website to a local profile or social response. Conflicting answers across customer-facing platforms weaken the reliability of the information available for AI extraction.

    More detail helps only when it is local, current, and internally consistent. A long answer that mixes several countries is worse than a short answer with an explicit jurisdiction. When tax, insurance, compliance, or another regulated decision is involved, name the jurisdiction and have the content reviewed by an appropriately qualified local professional. Explain general requirements, but route advice about an individual’s circumstances to that professional.

    Make the same locale obvious in copy, code, profiles, and feeds

    Matching location and business-detail symbols connect a miniature neighborhood with webpage, code, profile, and product-feed stations.

    No individual technical signal can force an AI system to cite or recommend a page. Your goal is corroboration: every readable and machine-readable layer should describe the same entity in the same market.

    Give each meaningful market version a clear web identity

    • Use a stable URL for each genuinely distinct market version, such as a country-specific Spanish directory. Avoid changing URLs merely to test regional wording.
    • Set the document language to the appropriate Spanish locale when you know it, such as es-MX or es-ES, rather than using one undifferentiated setting for every regional version.
    • Connect alternate market pages with accurate hreflang annotations. Each page should identify the correct regional alternate, while its canonical URL should represent the version you actually want indexed.
    • Do not canonicalize a distinct local page to a generic Spanish page. That tells crawlers the generic version is preferred even though you created the local page to communicate different facts.
    • Name the country and relevant service area in visible headings and copy. A flag icon, URL folder, or language selector is not a substitute for an explicit market statement.
    • Link to the local version from the corresponding country, location, service, and contact paths. Avoid leaving important regional pages reachable only through a selector that a crawler or user may not encounter.

    Hreflang helps describe language and regional alternates; it does not establish the truth of your inventory, legal claims, or service coverage. The visible answer still needs to contain the facts that make the regional distinction useful.

    Use JSON-LD to corroborate visible facts

    Structured data should mirror the page, not carry a hidden localization strategy. Use the most specific applicable entity type, such as Organization or LocalBusiness, and give each distinct entity or location a stable identifier. Do not reuse one identifier for branches that have different addresses or operational facts.

    • Represent the location with a PostalAddress whose locality, region, and country match the visible contact information.
    • Describe the actual area served on the relevant organization or service entity. Do not mark up locations the business does not serve.
    • Use inLanguage on applicable content entities to reinforce the page’s Spanish locale.
    • When a product or offer displays a price, keep priceCurrency aligned with the visible currency and the associated feed.
    • Connect official profiles only when they represent the same business or branch.
    • If you use FAQPage markup, mark up only questions and answers users can read on that page. Keep the structured answer identical in meaning to the visible answer.

    FAQ markup is not a localization switch and does not guarantee an AI citation or search feature. Its value here is narrower: it gives a well-formed version of an answer that already states its market clearly.

    Your off-site surfaces need the same treatment. Google Maps can answer place questions without requiring a website visit, so local profile facts cannot be treated as secondary metadata. Name, address, phone, hours, categories, service area, and linked landing page should describe the same location.

    Commerce data is another answer surface. Merchant Center’s Business Agent can draw from product data and site content during chat interactions. A Spanish product page that shows MXN while its feed supplies another currency creates ambiguity at the moment the user is trying to buy. Align locale, price, availability, and destination URL across the page and feed.

    Audit answer accuracy by market, not language alone

    A localized page is not finished when it is published. You need to see whether AI systems preserve the country, entity, offer, and constraints when they assemble an answer. Because generated outputs can vary, a single successful query is evidence of one result, not proof that the market is understood.

    1. Build a test set around decisions that matter: finding a provider, checking availability, comparing an offer, understanding a price, confirming a service area, and resolving a regulated question.
    2. Run each intent in generic Spanish, with the country stated, and with the relevant city or region stated. The difference shows whether the system holds the right market only when the user supplies it explicitly.
    3. Record the tool, date, account or location conditions, exact query, answer, cited or linked pages, and any named business. Keep those conditions as stable as practical when you repeat the test.
    4. Check geography, entity identity, terminology, currency and number format, availability, and jurisdiction separately. A fluent response can pass the language check while failing every commercial check.
    5. Trace each error to the information environment. Look for a missing local answer, a generic page outranking the local version, conflicting profile data, an incorrect feed, ambiguous structured data, or a third-party listing that no longer matches the business.

    Track correctness and visibility as different outcomes

    Use a small set of operational measures so improvements do not disappear inside a general visibility score:

    • Market accuracy: the share of applicable test answers that keep the correct country or local service area.
    • Entity accuracy: the share that identify the correct business, branch, product, or service.
    • Answer coverage: the customer questions for which your site or controlled profile provides a complete, market-specific answer.
    • Conflict count: active contradictions across pages, profiles, feeds, social answers, and other listings you monitor.
    • Source visibility: whether the generated answer cites, links to, or clearly reflects your canonical local page.

    Read those measures together. High source visibility with low market accuracy means the system can find you but is extracting or combining the wrong facts. High accuracy with low source visibility means your information may be correct while another entity receives the attribution. Low coverage means you need better answers before you need more markup.

    Fix errors in consequence order

    1. Correct jurisdiction, eligibility, currency, pricing, and availability errors first. These can produce legal exposure, lost transactions, or promises the business cannot fulfill.
    2. Resolve entity confusion next. Separate branch identities, URLs, addresses, profiles, and structured-data identifiers where the system is merging distinct locations.
    3. Fill unanswered local questions with direct canonical answers drawn from customer language.
    4. Repair contradictions across controlled channels and request corrections on inaccurate third-party listings where possible.
    5. Refine dialect, tone, and regional vocabulary after the underlying market facts are correct.

    If an AI answer relies on a third-party page, do not respond by adding another vague paragraph to your site. Publish the missing fact on the most relevant local page, update the matching official profile or feed, and reconcile every controlled instance. Supplying complete first-party answers makes it less necessary for a system to fill gaps from outside sources or omit the business.

    Review triggers matter more than an arbitrary publishing schedule. Recheck the answer set when prices, service areas, branch details, inventory, payment options, regulations, or approved terminology change. Stable descriptive content can follow a normal editorial review cycle; a wrong currency or expired eligibility condition should be corrected across every surface as soon as it is found.

    Key takeaways

    • Spanish identifies a language family, not a country, jurisdiction, currency, or service area.
    • Create a distinct market version when local facts change the offer or the answer, not merely to insert a country keyword.
    • Build canonical answers from reviews, calls, social questions, sales conversations, and local profile interactions.
    • Keep visible copy, URLs, language annotations, JSON-LD, local profiles, and product feeds aligned around the same entity and market.
    • Audit whether AI outputs preserve the correct geography, entity, commercial facts, and jurisdiction; do not score fluency as accuracy.

    Start with your highest-value service in the market where a wrong-country answer creates the greatest commercial or legal risk. Build its market brief, publish the missing canonical answers, align the technical and off-site signals, and run the same query set again. Expand only after the output reliably keeps the right country, entity, and facts together.

    References


  • How to Expand an AEO Strategy Across Markets and Industries

    How to Expand an AEO Strategy Across Markets and Industries

    Your AEO playbook is producing useful answers in one market. Then the expansion request lands: take it into a new country, a new industry, or an agency-wide client portfolio. The tempting response is to duplicate content, translate keywords, and add locations to the dashboard. That scales output. It does not necessarily scale answer quality.

    With zero-click discovery becoming central to AEO, expansion depends on whether an answer engine can identify your entity, understand your answer, and find credible support for it under a different set of market conditions. You need a system that preserves factual consistency while allowing questions, terminology, evidence, and search platforms to change.

    Give the expansion one primary axis

    Start by deciding what is actually expanding. Geography, industry, client type, and product scope are different variables. Change all of them at once and you will struggle to identify why an answer performs well, fails to appear, or appears with the wrong context.

    Choose one primary axis for the first expansion unit:

    • Geographic expansion: the offering stays largely stable, but language, search behavior, platform mix, availability, and evidence may change.
    • Industry expansion: the market may stay stable, but buyer questions, terminology, use cases, proof requirements, and decision criteria change.
    • Portfolio expansion: an agency or enterprise team applies one operating method across brands, business units, or clients with different entity structures.
    • Product expansion: the audience may be familiar, but the claims, comparisons, limitations, and supporting evidence are different.

    An expansion unit should be narrower than a country or a broad vertical. “Healthcare” is not an operating unit. A defined audience evaluating a defined type of solution for a defined decision is. That tighter boundary tells you which questions belong in the prompt set, which claims require evidence, and who can approve the answers.

    Put the unit into a short expansion brief before commissioning content:

    • Audience: who is asking, buying, recommending, or implementing?
    • Decision: what are they trying to understand or choose?
    • Entity: which company, product, service, person, or location must an answer engine identify correctly?
    • Claim set: which facts can remain global, and which vary by market or industry?
    • Discovery environment: which AI interfaces and search engines does this audience actually use?
    • Owner: who validates the content, evidence, technical implementation, and measured result?

    If you cannot fill those fields without phrases such as “all prospects” or “all AI platforms,” the unit is still too broad.

    Separate the portable answer system from local decisions

    An isometric modular system has a stable central core connected to interchangeable components for different local environments.

    A scalable AEO program does not force every market to publish identical pages. It standardizes the parts that protect accuracy and measurement, then gives local owners explicit control over the parts that genuinely differ.

    LayerKeep consistentAdapt when justified
    Entity factsOfficial names, relationships, ownership, and product scopeAliases, scripts, transliterations, local availability, and locally used names
    Answer patternA direct response, supporting explanation, evidence, and clear limitationsQuestion wording, terminology, examples, and market-specific context
    Evidence policyEvery material claim has an owner and a verifiable basisThe most relevant locally valid evidence and citation targets
    Schema policyMarkup reflects visible content and consistent entity relationshipsLanguage, location, availability, and other properties that truly differ
    MeasurementDefinitions for presence, citation, accuracy, market fit, and actionabilityThe prompt set, engine mix, interface, and language used for each market

    Build an answer brief for every priority question. It should contain the exact question, a short standalone response, the explanation needed to support it, the underlying claim, the evidence location, the claim owner, relevant limitations, the target entity, and the next useful action for the reader. This becomes the common object that content, schema, review, and measurement teams work from.

    AEO execution commonly joins relevant schema, trust signals, and citation tactics, but those components have different jobs. Structured data clarifies entities and relationships. Visible evidence supports the claim. Clear prose supplies the answer. Treat citation as an earned outcome, not as something a schema property can compel.

    That distinction prevents a common failure: technically elaborate markup attached to thin or ambiguous content. Mark up what the page actually establishes. If a qualification, relationship, availability statement, or answer is absent from the visible content, adding it only to structured data does not repair the underlying information.

    Maintain a claim ledger alongside the answer briefs. Each row should identify the claim, evidence, owner, markets where it is valid, pages that use it, and the event that should trigger review. When a product changes or a local team discovers an exception, you can update every affected answer without relying on memory.

    Localize discovery conditions, not just vocabulary

    One glowing question signal follows different paths through a home, a research workspace, and a mobile urban setting before reaching the same answer form.

    A translation can be linguistically correct and still miss the question a buyer asks, the entity name an engine recognizes, or the evidence the market trusts. Localization starts before drafting, with discovery research in the target environment.

    Dragon Metrics built its international footprint by supporting brands and agencies in more than 50 countries, with particular strength across markets such as China, Korea, and Japan. The practical lesson is that a Google-only view cannot be assumed to represent every market. Your expansion brief must name the actual engines, AI interfaces, languages, and result formats relevant to the audience.

    Create a market discovery sheet with these fields:

    • Question language: native phrasing, abbreviations, category terms, and the words used at different stages of the decision.
    • Discovery surfaces: the search engines, assistants, AI answer features, and industry platforms where the audience asks those questions.
    • Entity variants: official names, common aliases, transliterations, parent-company relationships, and product naming differences.
    • Offer boundaries: features, support, availability, or terms that differ from the original market.
    • Evidence environment: which internal documents and external pages can substantiate each locally relevant claim.
    • Local validator: the person who can reject wording that is technically translated but commercially or factually wrong.

    Use the sheet to rebuild the question set rather than merely translating the original prompts. Preserve the intent, then test several natural ways a local user might express it. A single prompt is not a market, and one favorable output is not a repeatable result.

    Apply the same discipline to structured data. Keep stable entity identifiers and relationships consistent, but do not copy market-specific properties blindly. The page copy, schema, internal links, availability statements, and supporting evidence should describe the same local reality. Contradictions between those layers create an interpretation problem that more markup cannot solve.

    Finally, test for the wrong-market answer. A brand mention can look like success while recommending an unavailable product, citing evidence from another jurisdiction, or describing the wrong business entity. Market validity therefore needs its own review field; it should not be hidden inside a generic visibility score.

    Make the operating model part of the AEO design

    Expansion changes who knows the audience, who owns the data, and who is allowed to approve a claim. An office, acquisition, reseller network, or regional partner can add proximity and capability, but none of them automatically creates a consistent answer system.

    Profound positioned its London office as a way to work closer to UK clients and partners. That kind of local presence can shorten feedback loops, provided the regional team has a defined route for turning what it learns into revised questions, evidence, and content.

    Acquisition creates a different integration problem. Semify’s announced plan for Dragon Metrics kept the platform operating as an independent brand while combining engineering capability and product leadership. AEO teams face the same design choice at a smaller scale: decide which systems must converge and which local strengths should remain intact.

    Choose an operating model deliberately:

    • Centralized: one team controls questions, content, schema, and reporting. This protects consistency but can make local validation a bottleneck.
    • Hub and spoke: a central team owns definitions, templates, entity rules, and measurement; local teams own phrasing, market facts, evidence, and final validation.
    • Federated: regional or industry teams run their own programs under a shared minimum standard. This supports local speed but needs strong claim and entity governance to prevent drift.
    • Integrated capability: an acquired platform or specialist partner retains useful workflows while selected data, engineering, or reporting layers are connected to the wider system.

    We would use hub and spoke as the default when the product truth is global but the questions and proof are local. The central team should not rewrite language it does not understand, and the local team should not redefine global product facts without approval.

    Assign a named owner to each decision, not merely to each department:

    • The claim owner approves what may be stated and where it is valid.
    • The market owner validates terminology, intent, local applicability, and evidence.
    • The technical owner verifies rendered content, structured data, entity consistency, and discoverability.
    • The measurement owner maintains the prompt set, capture method, definitions, and change log.

    This prevents a familiar handoff failure in which content assumes schema will add meaning, technical teams assume claims were approved, and reporting teams measure prompts that local buyers never use.

    Launch with a fixed baseline and separate measures

    Traditional rankings remain useful context, but they cannot tell you whether an AI answer mentioned the correct entity, cited adequate evidence, described the right market, or sent the user toward a useful next step. Measure those outcomes separately.

    Create one row for every prompt captured in every measurement run. Record the exact prompt and language, target market, interface used, capture date, entity presence, context of the mention, cited URLs, factual claims made, validation result, and available action path. Preserve the output or a reproducible record of it so reviewers can inspect why a row passed or failed.

    Use clear internal definitions:

    • Prompt coverage: the share of eligible tracked prompts where the intended entity appears in a relevant context.
    • Citation incidence: the share of eligible prompts where the response cites a page that supports the relevant answer or claim.
    • Factual accuracy: the share of captured claims that pass validation against the claim ledger.
    • Market fit: the share of captured answers that apply to the target audience, product, and location without importing an invalid condition.
    • Actionability: whether the response gives the user an appropriate path to verify, compare, learn more, or proceed.
    • Downstream response: attributable visits, qualified actions, or business outcomes where your analytics can observe them.

    These are operating definitions, not universal industry standards. Keep their denominators and pass criteria stable within your program so changes remain interpretable. Do not compress them into one visibility score. High prompt coverage with poor factual accuracy is not a weaker version of success; it is a different and potentially damaging outcome.

    Run the expansion as a controlled sequence:

    1. Freeze a baseline prompt set for the defined audience and decision. Keep exploratory prompts in a separate set.
    2. Capture the baseline on the target market’s actual discovery surfaces before changing content.
    3. Publish a coherent question cluster with aligned answers, evidence, entity signals, internal links, and structured data.
    4. Repeat the fixed prompt set using the same capture method.
    5. Classify failures as missing presence, wrong entity, weak context, unsupported claim, poor citation, market mismatch, or unusable next step.
    6. Change the layer responsible for the failure. Do not rewrite content when the real issue is an inconsistent entity, invalid local claim, inaccessible evidence, or irrelevant prompt.
    7. Expand the question set or move into the next unit only after the workflow can reproduce accurate, market-valid answers.

    Key takeaways

    • Expand one primary variable at a time so you can tell whether geography, industry language, product scope, or governance caused the result.
    • Keep entity facts, evidence rules, schema policy, and measurement definitions stable; localize questions, terminology, platform mix, and market-specific claims.
    • Use structured data to clarify visible facts, not to compensate for vague answers or unsupported claims.
    • Measure entity presence, citation, factual accuracy, market fit, and actionability separately.
    • Give every claim, market decision, technical implementation, and measurement set a named owner.

    Take the next market or industry already on your roadmap and force it through the expansion brief before commissioning more pages. If a priority question lacks a claim owner, locally valid evidence, a target discovery surface, or a measurement row, the launch is not ready. Close those gaps first, then use the same controlled system for the next expansion unit.

    References

  • Profound Multilingual Access: A Rollout Guide for Teams

    Profound Multilingual Access: A Rollout Guide for Teams

    If your regional specialists must navigate every dashboard and workflow in a second language, translation becomes part of every task. Labels take longer to interpret, handoffs require extra explanation, and a small misunderstanding can follow an insight all the way into content planning.

    Profound is rolling out a beta App Language Selector with support for more than 30 languages. That can remove a meaningful layer of friction for international teams. To use it well, however, you need to distinguish the language of the application from the language of your prompts, measurement, analysis, and published content.

    Start with the right model of what language access changes

    A language selector changes how a person interacts with an application. It should not be treated as proof that every other language-dependent part of the workflow changed with it.

    Before enabling the feature across your team, separate four layers:

    • Interface language: The language used for navigation, labels, instructions, messages, and other application text.
    • Research language: The original wording of the question, query, prompt, topic, product, or entity being investigated.
    • Measurement context: The market, audience, platform, model, location, and other settings that define what your team is examining.
    • Publication language: The language and locale of the content your audience will ultimately read.

    Changing the first layer does not, by itself, change the other three. A French interface does not automatically make an English-language research set representative of France. A Spanish label on a report does not prove that the underlying prompts were run in Spanish. A German dashboard does not localize the pages your team plans to publish.

    This distinction matters in AI search because language carries intent, not just vocabulary. A literal translation can change the specificity of a question, the entity it appears to reference, or the way a local audience describes a need. Keep the original wording visible throughout the workflow, even when the interface and the team’s shared working language are different.

    Pilot one complete workflow before enabling every language

    A small team completes one illuminated four-stage workflow while unopened paths extend toward additional regions.

    A broad launch can hide where confusion begins. Run a limited pilot around one recurring task that already causes translation friction. The task should have a clear start, a clear decision, and a handoff to another person.

    1. Define the result in one sentence. For example: a regional analyst can review an existing visibility finding, explain what it means, and pass an unambiguous recommendation to the content owner without reverting to the team’s fallback language.
    2. Record the current path. List the screens, decisions, terminology, and handoff involved in the task. Capture screenshots only where they clarify a critical state, and avoid placing sensitive information in the test record.
    3. Repeat the task in the preferred interface language. Use the same workspace and the same underlying item so the interface language is the main variable.
    4. Review with two perspectives. A fluent user should judge whether the language is natural and understandable. A system owner should verify that the user interpreted the controls, states, and resulting action correctly.
    5. Test the return path. Confirm that the user knows how to switch back to an agreed fallback language if a translated label, message, or support step becomes unclear.
    6. Decide from observed blockers. Expand only when the person can complete the task and hand off the result without guessing at terminology or meaning.

    Keep an issue log during the pilot. For each problem, record the selected interface language, location in the application, displayed wording, intended meaning, screenshot, operational impact, workaround, owner, and status. A note such as “translation seems odd” is difficult to act on. A note that identifies the exact label and the decision it disrupted is useful.

    Do not grade the pilot on whether every phrase sounds elegant. Grade it on whether the user can understand the state of the work, choose the intended action, recognize errors, and communicate the result accurately. Those are the conditions that determine whether multilingual access improves operations.

    Keep interface, measurement, interpretation, and content separate

    An analyst and two colleagues examine four separated layers representing interface, measurement, interpretation, and content.

    A lightweight record prevents a translated interface from creating false confidence about the rest of the analysis. Attach the following information to any multilingual AI visibility finding that could influence strategy or publication.

    LayerWhat to recordWhat can go wrong if it is omitted
    InterfaceThe language selected when the work was completed and the date it was checkedA later reviewer may mistake translated labels for a change in the underlying research context
    Research inputThe exact original-language query, prompt, topic, or entity nameA translation can hide a change in intent, phrasing, or entity meaning
    Measurement contextThe market, audience, AI surface, model, and other settings relevant to the findingResults from different contexts may be compared as though language were the only difference
    InterpretationThe native-language conclusion plus a short shared-language explanation where neededThe regional nuance can disappear during the handoff
    Content actionThe target locale, page or asset, decision owner, and intended changeA useful finding may turn into generic translation instead of a market-specific improvement

    Preserve original-language research inputs as immutable evidence. Add translations beside them; do not replace them. If a phrase has no clean equivalent, annotate the intended meaning and the uncertainty instead of forcing a polished translation. This gives reviewers enough context to distinguish a real market difference from a wording difference.

    Apply the same discipline to comparisons. Two prompts written in different languages should remain separate rows unless someone qualified in both languages has confirmed that they express the same intent. Even then, label the relationship as an analytical judgment rather than treating one prompt as a mechanical copy of the other.

    Turn native-language access into a better decision process

    The practical benefit does not come from translated menus alone. It comes from giving the person closest to a market a cleaner route into the analysis and a defined role in the resulting decision.

    A reliable handoff can follow this sequence:

    1. The regional reviewer interprets the finding. They work in their preferred interface language and write the conclusion in the language that preserves the market’s meaning most accurately.
    2. The original evidence stays attached. Exact prompts, queries, entity names, and relevant context travel with the conclusion.
    3. A shared-language explanation supports coordination. This should explain the decision, not replace the original evidence. Terms with no direct equivalent should be flagged.
    4. The measurement owner checks definitions. They verify that the team is using the same metric definitions and comparing compatible contexts.
    5. The content owner assigns an action. The handoff names the target locale, asset, owner, and intended outcome rather than ending with a general observation.

    Build a small operational glossary alongside this workflow. Include only terms that can change a decision: product states, measurement labels, workflow statuses, recurring market concepts, and action verbs. For each entry, record the approved translation, a plain-language definition, terms that must remain untranslated, the owner, and the last review date.

    Do not try to standardize every sentence a team might write. Standardize the words that affect interpretation and action. If two specialists disagree, divide authority clearly: the regional owner decides local meaning, the system owner explains platform mechanics, and the content owner governs publication style. Record unresolved ambiguity instead of letting the loudest translation become the default.

    Govern the beta as a working dependency

    Because the selector is in beta, build a workflow that can tolerate wording or behavior changing. Permanent training material based only on screenshots will age quickly. Document the purpose of each step in text, then use screenshots as supporting context rather than as the procedure itself.

    Use event-based revalidation instead of choosing an arbitrary review schedule. Recheck a workflow when a new language is introduced to your team, when the application changes a critical screen, when the team changes its process, or when multiple users report confusion around the same term. That focuses effort where the risk has actually changed.

    Your operating guardrails should include an agreed fallback language, an owner who consolidates translation issues, a glossary for decision-critical terminology, and a route for escalating problems that stop work. Keep local workarounds in the shared issue log. Otherwise, each region may quietly invent a different meaning for the same control or status.

    Key takeaways

    • Profound’s App Language Selector is a beta feature that makes the platform available in more than 30 languages.
    • Interface language, research language, measurement context, and publication language are separate layers.
    • Pilot one complete workflow with both a fluent reviewer and a system owner before expanding access.
    • Preserve original-language prompts and queries; add translations beside them instead of overwriting them.
    • Manage terminology, handoffs, fallback access, and beta issues as operational assets rather than informal knowledge.

    Choose one regional workflow that creates repeated translation work and write its expected outcome in a single sentence. Test it end to end in the user’s preferred language. If the finding can move from review to action without ambiguity, expand deliberately. If it cannot, classify the blocker as interface, measurement, interpretation, or content. Each category has a different fix, and identifying the right one is the fastest way forward.

    References