Category: Generative Engine Optimization (GEO)

  • Embedded AI Search Adoption: A Practical Content Strategy

    Embedded AI Search Adoption: A Practical Content Strategy

    If your AI search dashboard starts with chatbot referrals, you may be measuring the easiest activity to see rather than the behavior that matters most. Embedded AI can answer, compare, and recommend inside a product the user has already opened, so no separate chatbot session – or visit to your website – is required.

    The shift is large enough to change your priorities. AI search grew 70% year over year in 2026, while embedded AI in Meta, Amazon, and Google products outpaced standalone chatbots. Your practical question is now broader than whether a chatbot can cite a page: can each relevant platform identify, interpret, and use your information correctly when a person needs it?

    Key takeaways

    • Treat embedded AI as a discovery and decision layer, not merely another referral channel.
    • Organize your strategy around customer decisions before choosing platforms, prompts, or schema types.
    • Give every important fact one authoritative home, then keep its wording and qualifications consistent across relevant surfaces.
    • Use JSON-LD to reinforce meaning already visible on the page. Valid markup cannot guarantee AI inclusion.
    • Measure presence, accuracy, attribution, destination, and business outcomes separately. A single traffic figure hides most of the useful diagnosis.

    Embedded AI changes the unit of optimization

    A standalone chatbot is a destination. A person opens it, enters a prompt, and receives a response. Embedded AI is a capability inside a journey that has already begun: searching, shopping, browsing, evaluating, or deciding what to do next.

    That distinction changes what successful optimization looks like. A traditional search report tends to emphasize rankings, impressions, clicks, sessions, and conversions. Those metrics still matter, but an embedded answer can influence a decision without producing a referral that your analytics can identify.

    Evaluate each important topic as a sequence of outcomes:

    1. Eligibility: Is your information available in a form the relevant system can access and interpret?
    2. Understanding: Can the system identify the subject, the claim, the relationship between entities, and any conditions attached to the answer?
    3. Representation: Does the generated response describe your brand, product, service, or expertise accurately?
    4. Usefulness: Does the response help the user complete the decision rather than merely repeat a slogan?
    5. Next action: When a visit is appropriate, does the response lead to the correct page, listing, profile, or product record?

    This model prevents two common misreadings. No click does not prove that your content had no influence, and a click does not prove that the preceding answer was accurate. Track exposure, representation, and traffic as related but distinct events.

    Do not abandon conventional SEO to pursue this shift. Clear page architecture, crawlable content, stable canonical URLs, accurate titles, descriptive headings, internal links, and authoritative evidence still make your information easier to find and understand. AI optimization extends that foundation; it does not excuse a weak one.

    You should also resist the idea of a universal AI ranking position. Embedded systems operate in different products and contexts. An appearance in one response is evidence about that response, not proof of broad visibility across every AI surface.

    Plan around decisions, then adapt to each environment

    A central decision point and supporting evidence branch into adapted answer, comparison, and recommendation modules across several generic devices.

    Starting with a list of AI products usually creates scattered work: a page for one chatbot, a few experimental prompts, and schema added wherever it fits. Start instead with the decisions your audience is trying to make. The same decision may surface in several environments, while the evidence needed to resolve it should remain consistent.

    Embedded environmentLikely user taskInformation to make explicit
    Google productsUnderstand a subject, compare options, find an entity, or choose a next stepDirect answers, definitions, comparison criteria, entity relationships, evidence, and any location or service boundaries
    Amazon productsCompare products and reduce uncertainty before a purchaseCanonical product identity, variants, specifications, compatibility, intended use, and material limitations
    Meta productsDiscover, ask about, or evaluate a brand or offer in a social contextConsistent names, concise factual claims, supporting context, recognizable assets, and a clear next action

    This is a planning map, not a claim about hidden ranking factors. Use it to identify which facts a person needs in each context. Then validate visibility through observation rather than assuming that every platform retrieves, weighs, or presents information in the same way.

    Build an intent-to-fact matrix

    For each high-value decision, create a working record with the following fields:

    • User decision: What is the person actually choosing, checking, or trying to understand?
    • Direct answer: What is the shortest accurate response your evidence supports?
    • Required qualifications: Which audience, market, product, plan, version, location, or use case does the answer cover?
    • Supporting facts: What evidence, specifications, examples, definitions, policies, or primary records make the answer credible?
    • Canonical home: Which owned URL or structured record is authoritative for this information?
    • Relevant environments: Where is the decision likely to arise, and how does the surrounding task change the presentation?
    • Known conflicts: Which pages, profiles, listings, feeds, or product records currently contradict the canonical answer?

    One page does not have to target every platform. The important discipline is that each critical fact has one authoritative home and does not acquire a different meaning as it moves through your content system.

    Prioritize the matrix with a simple editorial rule: work first on decisions that combine high business value, a meaningful information gap, and strong relevance to an embedded environment. This is more useful than spreading effort evenly across every prompt that happens to mention your category.

    Make important claims easy to extract and hard to misread

    Many pages contain the right information but make a machine – and often a hurried reader – assemble it from several sections. The product name appears in one heading, the answer sits in an image, the limitation is buried near the footer, and a conflicting statement survives on an older page. That is an interpretation problem before it is an AI problem.

    Audit every answer-bearing section for the elements below:

    • Name the subject: Use the complete entity, product, service, or concept name in the heading or opening sentence instead of relying on vague pronouns.
    • Lead with the answer: Put the direct response before history, positioning, or promotional context.
    • Keep qualifications attached: If a claim applies only to a particular market, plan, version, audience, or condition, state that boundary in the same sentence or immediately after it.
    • Define comparisons: Say what is being compared and on which criteria. Words such as better, faster, simpler, and cheaper are incomplete without a basis.
    • Separate facts from persuasion: Distinguish a verifiable capability from a marketing interpretation of that capability.
    • Support consequential claims: Link to the strongest evidence you actually have, preferably the primary record behind the claim.
    • Resolve contradictions: Update, redirect, remove, or clearly qualify stale pages instead of hoping a system chooses the newest wording.
    • Keep key information in text: Images and video can add context, but the decisive answer and its limitations should also appear as accessible page content.

    Write answer blocks that remain accurate when extracted

    An effective answer block has a descriptive heading, a direct opening sentence, the condition that limits the answer, and enough supporting detail to make the response useful. Follow it with criteria, steps, or a comparison only when those elements help the user complete the decision.

    Read the opening sentence by itself during your audit. If it becomes misleading after removal from the surrounding page, the block is not self-contained enough. For example, a capability that is available only for a particular plan remains false when the plan limitation is several paragraphs away. Move the limitation next to the capability.

    This does not mean writing robotic fragments or repeating the same keyword. It means preserving the relationship between the subject, the claim, and its boundary. You can still explain nuance in natural prose after the direct answer is secure.

    Use JSON-LD as a consistency layer

    Structured data is most useful when it confirms the meaning of visible content. Select a schema type that fits the page, identify the main entity precisely, and connect related organizations, people, products, offers, places, or creative works only when those relationships are real and supported on the page.

    • Keep names, URLs, identifiers, prices, availability, authorship, and other marked-up properties aligned with the visible page whenever those properties apply.
    • Use one canonical identifier for the same entity across templates and records.
    • Do not add unsupported claims to JSON-LD because they are easier to publish there than in visible copy.
    • Validate syntax and inspect the rendered page, not just the content-management field where the markup was entered.
    • Recheck structured data whenever a template, product feed, page type, or canonical URL changes.

    Valid markup is not a guarantee that an AI system will retrieve, cite, or recommend the page. Schema reduces ambiguity; it does not create authority, repair contradictory content, or replace evidence.

    Measure adoption without pretending every influence is a click

    A shopper progresses from an embedded AI recommendation through comparison and product inspection to purchase, with connected signals showing indirect influence beyond a website click.

    Your analytics may identify some AI referrals. They cannot record an embedded interaction that ends inside another platform. A useful measurement system therefore combines direct observations with business data and labels the difference between them.

    Build the scorecard around separate diagnostic questions:

    • Presence: Does your brand, product, page, or expertise appear for the tracked decision?
    • Accuracy: Are the core facts correct, complete, and properly qualified?
    • Attribution: Is the information associated with the right entity, and is a citation or link present when the response provides one?
    • Destination: Does any available link lead to the authoritative page rather than an obsolete or irrelevant URL?
    • Competitive context: Which alternatives appear, and what information do they make clearer than you do?
    • Business effect: Do qualified visits, branded demand, assisted conversions, or other relevant outcomes change alongside visibility? Treat this as an association unless you can establish causation.

    Keep visibility metrics and business metrics in separate columns. Combining them into a single AI score makes diagnosis difficult: an accurate answer with no link requires a different response from an inaccurate answer that sends substantial traffic.

    Use a repeatable observation protocol

    1. Create a fixed set of queries from the decisions in your intent-to-fact matrix. Include discovery, comparison, qualification, and next-step language where those stages are relevant.
    2. Run each query in the environments where that decision naturally occurs. Do not treat a standalone chatbot check as a substitute for an embedded surface.
    3. Record the exact query, response, environment, date, visible citation or link, and any account, location, language, or device context that could affect interpretation.
    4. Classify the result as present and correct, present but incorrect or incomplete, or absent.
    5. Trace errors back to a specific cause you can inspect: missing content, ambiguous wording, contradictory records, weak evidence, incorrect entity relationships, inaccessible information, or the wrong destination.
    6. Make a focused correction, document it, and repeat the same observation process at a consistent cadence.

    Repeated observations matter because generated responses can vary. Preserve the history instead of replacing an unfavorable result with a favorable screenshot. Your goal is not to prove that you appeared once; it is to understand whether your information is represented reliably enough to support the user’s decision.

    Turn embedded search optimization into an operating routine

    Embedded AI search crosses responsibilities that many organizations keep separate. Editorial teams own explanations, SEO teams own discovery and technical quality, product or commerce teams own specifications and feeds, brand teams own naming, and analytics teams own measurement. If those groups publish conflicting facts, no schema plugin or prompt test can create a reliable answer layer.

    Use this sequence to turn the strategy into routine work:

    1. Select the highest-value decisions. Begin where an absent or incorrect answer would materially affect discovery, qualification, or purchase intent.
    2. Assign a canonical owner. Make one team or role responsible for approving the definitive fact and its qualifications.
    3. Audit every expression of that fact. Check relevant pages, profiles, listings, product records, feeds, and structured data for disagreement.
    4. Repair the authoritative asset. Add a self-contained answer block, supporting evidence, clear entity naming, and matching JSON-LD where appropriate.
    5. Propagate the correction. Update the other owned surfaces that legitimately repeat the fact without creating competing canonical versions.
    6. Observe relevant embedded environments. Score presence and accuracy using the same decision-led queries.
    7. Feed errors back into content operations. Treat incorrect AI representation as a data-quality or content-quality issue with an owner, not as an isolated screenshot for the SEO team.

    Do not optimize for mentions at the expense of truth. If an embedded response exposes a genuine ambiguity in your offer, policy, product data, or explanation, fix the ambiguity at its origin. The durable advantage is not wording engineered for one generated answer; it is a body of content that reaches the same accurate conclusion wherever a system encounters it.

    Start with the decision where a missing or wrong answer costs you the most. Give its facts a canonical home, attach every necessary qualification, align the structured data, and test it in the environments your audience already uses. Once that loop works, expand by decision value rather than by platform novelty.

    References


  • How to Measure AI Search Visibility Across the Customer Funnel

    How to Measure AI Search Visibility Across the Customer Funnel

    Your AI visibility score may look healthy while your brand is absent at the exact moment a buyer narrows the shortlist. The reverse can happen too: you appear in brand-specific answers but never enter the conversation while people are still defining their problem.

    You need to know where your brand enters an AI-assisted buying journey, how it is represented at each stage, and what causes it to disappear. A funnel-based prompt map turns that broad visibility problem into content, authority, and measurement work you can actually prioritize.

    Define visibility differently at each funnel stage

    A single visibility percentage hides intent. A mention in an educational response is not equivalent to a place on a product shortlist, and a citation is not automatically a recommendation. Even a prominent answer to a branded prompt may tell you little about whether new buyers discover the brand.

    Prompt mapping extends keyword mapping by organizing the questions people may ask AI platforms according to topic, intent, persona, and buying stage. It also accounts for the context people add around company size, existing technology, use case, pain point, and purchasing priority. Those qualifiers can turn one broad keyword into many plausible prompts with materially different answers.

    Use four stages as a working model. Buyers will not always move through them in order, so classify the job being done in the prompt rather than trying to prove a perfectly linear journey.

    Funnel stageWhat the person is trying to resolveWhat useful visibility looks likeWhat you should inspect
    AwarenessUnderstand a symptom, risk, goal, or problemYour expertise helps frame the problem accurately, through a relevant brand mention or an owned-page citationProblem association, cited educational pages, terminology, and factual accuracy
    ConsiderationUnderstand possible approaches, categories, capabilities, or selection criteriaYour brand is associated with the appropriate solution and use caseCategory association, capability descriptions, fit criteria, and alternatives mentioned
    EvaluationReduce a set of options using specific requirementsYour brand makes an appropriate shortlist when it genuinely satisfies the stated constraintsRecommendation context, qualifying criteria, competitors, trade-offs, and cited evidence
    DecisionValidate a named brand before actingPricing, compatibility, implementation, strengths, and limitations are represented accuratelyClaim accuracy, objection coverage, outdated information, and unexpected competitor substitutions

    This distinction changes what you optimize. At awareness, forcing the brand into every answer is not the goal. You want a defensible association with the problem and credible educational material that can support the response. At evaluation, general educational authority is insufficient if the brand disappears as soon as the buyer names an integration, industry, company profile, or operational constraint.

    Decision-stage measurement requires another shift. The user has already supplied the brand name, so simple inclusion is a weak success metric. You should care more about whether the response is current, specific, fair, and useful enough to support a real decision.

    Build a compact prompt map around real buying decisions

    A central decision node connects to visual clusters representing problem discovery, exploration, comparison, and final selection prompts.

    You cannot track every sentence a buyer might type. Nor do you need to. A smaller, deliberately constructed prompt set is more useful than a large collection of loosely related questions because every prompt has a known purpose in the measurement plan.

    Start by defining your territory of authority. It sits where three things overlap: questions your audience needs help answering, knowledge your organization has earned through direct work, and subjects your products or specialists can credibly address. That boundary prevents your prompt map from becoming a list of every topic remotely connected to the category.

    1. Choose a commercially relevant problem. Write the central question your organization is qualified to answer. Keep it narrower than the whole market.
    2. Create a prompt family for every stage. Begin with the problem, move into approaches and criteria, introduce realistic qualification requirements, and finish with named-brand validation.
    3. Add only meaningful qualifiers. Include a persona, company profile, technology requirement, pain point, or priority when it could alter which answer is suitable. Do not generate variants merely by changing the wording.
    4. Record the expected association. State what a correct response should connect your brand with. This must be a supportable claim, not the answer you wish an AI system would produce.
    5. Freeze a benchmark set. Preserve the exact prompt wording and record the platform, date, and other test conditions available to you. Add exploratory prompts separately so the benchmark remains interpretable.

    For a company serving onboarding teams, one prompt family could progress like this:

    • Awareness: Why are new customers failing to complete onboarding?
    • Consideration: What approaches help a mid-market software company reduce onboarding delays?
    • Evaluation: Which onboarding platforms support our required workflow and integrate with our existing system?
    • Decision: What are the limitations of [Brand] for our onboarding use case?

    The point is not to predict the buyer’s exact wording. It is to preserve the change in intent. If you test only broad best-product prompts, you will miss whether the brand is understood before the shortlist forms and whether it remains eligible after the buyer applies real constraints.

    Give every benchmark prompt a record containing:

    • A stable prompt ID and funnel stage.
    • The underlying problem, persona, and meaningful qualifiers.
    • The exact prompt wording used for the benchmark.
    • The truthful brand association or fact being tested.
    • Brand inclusion, owned-page citation, and recommendation status.
    • How the brand is described, including strengths and limitations.
    • Competitors included and the criteria used to include them.
    • URLs or other evidence presented in the response.
    • Any inaccurate, incomplete, stale, or unsupported claim.
    • The platform, test date, and available test conditions.

    Establish this baseline before publishing a new wave of content or starting a community program. Review search results, repeat the fixed AI prompts, inspect community perception, and audit whether owned content answers the questions people actually ask. A useful baseline records descriptions, sentiment, recurring concerns, recommendation contexts, and cited evidence – not just mention volume. That is how you distinguish a familiar brand name from a brand that is correctly understood.

    Give every stage the evidence it needs

    A prompt map is diagnostic. It tells you where visibility fails, but the remedy depends on the stage. Publishing more generic content will not repair a missing integration fact in an evaluation response, just as adding another comparison page will not establish authority around an early-stage problem.

    • Awareness content should clarify the problem. Explain symptoms, causes, terminology, diagnostic questions, and reasonable next steps. Help the reader recognize the situation without forcing a product into every paragraph.
    • Consideration content should connect the problem to possible approaches. Explain how solution categories work, what capabilities matter, where each approach fits, and which criteria separate a useful option from an unsuitable one.
    • Evaluation content should establish eligibility. Cover supported use cases, relevant integrations, operational requirements, comparisons, alternatives, and meaningful trade-offs. A page that targets a qualifier your product does not satisfy creates misleading visibility rather than useful visibility.
    • Decision content should become the canonical factual layer. Keep pricing, compatibility, implementation requirements, limitations, and other validation details consistent wherever you publish them. Address uncomfortable objections directly instead of leaving third parties to define them.

    Do not reduce this work to page formats. A comparison page with vague claims supplies less decision evidence than a focused support page that states exactly what works, what does not, and under which conditions. The content job is to make the required evidence explicit and internally consistent.

    Community participation provides a different kind of evidence. Relevant Reddit discussions can reveal the language people use, the alternatives they consider, the objections polished marketing pages avoid, and the criteria that actually decide a purchase. Those observations should feed your website, while accurate owned resources should give community teams dependable material for complex answers. Search intent, community context, owned depth, and ongoing monitoring should reinforce the same credible territory.

    Reddit is not a shortcut to a citation. Promotional replies with little practical value are likely to weaken trust in the community you are trying to understand. Participate only where you can answer the question on its own terms. Disclose your affiliation, respond directly, acknowledge limitations and trade-offs, and link only when the destination adds information the reply cannot reasonably contain. This native, transparent approach to community authority is slower than distributing promotional messages, but it produces more useful interactions and better inputs for your content program.

    Use a simple evidence loop:

    1. Capture a recurring question, objection, misconception, or decision criterion from search and community discussions.
    2. Match it to the relevant stage and benchmark prompt cluster.
    3. Update or create the owned resource that can answer it completely.
    4. Give customer-facing and community teams a clear factual reference.
    5. Re-run the relevant prompts and record whether the answer, description, citations, or recommendation context changed.

    JSON-LD belongs after the evidence is sound. Structured data can make the entities and relationships on a page more explicit to machines, but it cannot manufacture an unsupported product fit, repair contradictory pricing, or replace the experience and context supplied by independent discussions. Treat schema as a precise representation layer for content you can already defend.

    Measure exposure without confusing it with traffic

    An AI sphere illuminates several product objects, while only a few light paths continue toward a website doorway.

    Your scorecard should preserve several different outcomes. Collapsing them into one number recreates the problem the funnel map was meant to solve.

    • Stage inclusion rate: the share of benchmark prompts in a stage where the brand appears in a relevant capacity.
    • Owned citation rate: the share of stage prompts where an owned page is cited or linked. Keep this separate from brand inclusion because an answer may use your material without recommending your brand.
    • Category association rate: the share of consideration prompts that connect the brand with the appropriate solution category or capability.
    • Qualified shortlist rate: the share of evaluation prompts where the brand is recommended after the stated constraints are applied.
    • Representation accuracy: the proportion of reviewed brand claims that are current, complete enough for the question, and supported by your canonical information.
    • Competitor context: which alternatives appear, for which criteria, and whether your brand is framed as a peer, specialist, fallback, or unsuitable option.

    Keep the denominator stage-specific. Awareness inclusion should not compensate for inaccurate decision answers. A high citation rate should not conceal a weak shortlist rate. A branded mention should not be counted as discovery when the user supplied the name in the prompt.

    Google Search Console now adds a second view of the problem. As of August 31, 2026, its AI performance reporting is available globally to Search Console accounts. It reports impressions for content appearing in AI responses, AI Mode, and AI Overviews, with breakdowns for pages, countries, devices, and dates. It does not include click data.

    Use that report as an exposure layer:

    • Identify which pages receive generative-search impressions.
    • Map those pages to the funnel stage they were designed to support.
    • Review changes across the available date, country, and device dimensions.
    • Compare exposed pages with the pages actually cited in your benchmark prompt checks.
    • Investigate why important stage-specific pages have prompt visibility but little reported exposure, or exposure without the brand representation you intended.

    Do not calculate an AI click-through rate from this report; the necessary click figure is not present. Do not infer visits or conversions from impressions either. Use your site analytics to evaluate any visits you can separately observe, and keep the claim narrow: Search Console tells you that exposure occurred, while prompt tracking tells you where and how your brand appeared within the buying journey.

    Search Console also provides a control for blocking content from Google’s generative search features, including AI Overviews, AI Mode, and AI Overviews in Discover. A site that opts out will not receive impressions or traffic from those generative features, while the choice is not used as a ranking signal for search results outside them. Treat this as a distribution and governance decision, not a way to repair weak content or inaccurate representation.

    Before changing that control, document the exact properties in scope, preserve your current baseline, and make sure the owner of the decision accepts the loss of generative exposure and possible traffic. If the problem is an outdated answer, correct the canonical facts and connected authority signals. Removing the site from the feature prevents participation; it does not improve the description buyers may encounter elsewhere.

    Turn each visibility gap into a specific action

    The funnel pattern matters more than the aggregate score. Read the pattern first, then choose the smallest intervention that supplies the missing evidence.

    • Strong decision visibility, weak awareness visibility: people who already know the brand can investigate it, but the brand is not entering earlier problem discovery. Build better problem education and participate in the communities where those problems are described in real language.
    • Strong awareness visibility, weak consideration visibility: your material may explain the issue without connecting your expertise to a suitable method or category. Add the bridge: approaches, mechanisms, capabilities, selection criteria, and explicit boundaries of fit.
    • Strong consideration visibility, weak evaluation visibility: the brand is associated with the category but disappears when requirements become specific. Identify the exact qualifier causing the drop, then publish evidence for supported integrations, use cases, customer profiles, or operating constraints. Do not create fit claims for criteria the product cannot meet.
    • Evaluation inclusion followed by inaccurate decision answers: the brand makes the shortlist, but validation material is stale, inconsistent, or incomplete. Correct canonical pages first, state limitations plainly, and address recurring misconceptions in appropriate community and support channels.
    • Owned pages are cited but the brand is not shortlisted: your content influences the explanation without proving supplier fit. Strengthen verifiable differentiation, use-case evidence, and transparent trade-offs instead of merely repeating the brand name more often.
    • The brand appears without owned citations: third parties may be carrying much of the representation. Monitor those descriptions closely and publish clear canonical facts that customers, communities, and answer systems can check.

    We would prioritize accuracy before reach. Incorrect pricing, compatibility, limitations, or implementation information in a high-intent answer deserves attention before a broad effort to increase awareness mentions. Next, address evaluation gaps that wrongly exclude a genuinely suitable product. Then expand early-stage authority where the brand has earned a reason to participate.

    For every intervention, create an action card with the funnel stage, affected prompt cluster, observed failure, missing evidence, planned content or community change, responsible owner, and next review date. This keeps a visibility diagnosis from dissolving into a generic instruction to publish more.

    Key takeaways

    • Measure awareness, consideration, evaluation, and decision prompts separately because a mention has a different meaning at each stage.
    • Track a compact benchmark set built around real changes in intent and meaningful buyer constraints.
    • Record citations, recommendation context, competitors, trade-offs, and factual accuracy instead of counting brand mentions alone.
    • Use owned content for depth, community participation for context, and structured data to represent evidence that already exists.
    • Treat Search Console’s AI report as exposure data, not click or conversion reporting, and treat its opt-out control as a distribution decision.

    Start with one important customer problem. Assign its existing pages and prompt families to the four stages, capture the baseline, and find the first point where a suitable brand disappears or becomes inaccurate. Fix that break with evidence you can defend, then measure the same prompts again.

    References

  • 2026 AI Search Optimization Agencies by Sector: Buyer’s Guide

    2026 AI Search Optimization Agencies by Sector: Buyer’s Guide

    If your shortlist looks identical for a medical network, a cybersecurity vendor, and a roofing franchise, your brief is too generic. AI search may appear as one channel in a dashboard, but the work behind a recommendation changes with the evidence, entities, regulations, locations, and buying decisions in your sector.

    Use this guide to narrow the 2026 agency market by sector and operating model, then pressure-test each candidate at the prompt, citation, governance, and pipeline levels. You are not looking for the agency with the loudest GEO label. You are looking for one that understands what your buyers ask, what an AI system must trust, and what your organization can responsibly publish.

    The short answer: sector fit beats a universal ranking

    The recurring cross-sector candidates are First Page Sage, Focus Digital, and Driven Metrics. Genevate also appears prominently in finance, medical, and general B2B. That recurrence makes them reasonable starting points, but it does not make them interchangeable. Their operating models range from full-service content and lead generation to external authority building, lean execution, and analytics-heavy performance management.

    Key takeaways

    • For finance and medical organizations, make domain review, claims governance, and compliance-sensitive writing pass-or-fail requirements. Content volume cannot compensate for an approval process that does not work.
    • For cybersecurity, test whether the agency can explain products, requirements, integrations, and technical tradeoffs at the depth buyers use to form a shortlist.
    • For B2B, insist on a measurement path from AI visibility to qualified opportunities or pipeline. Mentions without commercial context are not enough.
    • For local businesses, require service-and-location coverage, consistent business facts, and reporting segmented by market. A national content playbook is not a local GEO strategy.
    • If an autonomous agent may compare providers or take an action for the user, add agentic search optimization to the brief. GEO visibility alone does not prove that an agent will select you.
    • Use published rankings for discovery, then validate sector work, live AI outputs, client scope, capacity, and attribution yourself.

    The following table is a market map, not a substitute for due diligence. It shows which agencies deserve inspection for each sector and the operating differences that should drive your first round of questions.

    SectorAgencies to inspectWhat should decide the fit
    Financial services and fintechFirst Page Sage, Genevate, Driven Metrics, Focus Digital, Avenue Z, Mint Studios, Evara, and Croton Content. For agentic selection, also inspect CSTMR, Obility, and Bay Leaf Digital.Regulatory fluency, finance-specific review, first-party expertise, external authority, comparison content, attribution, and whether the goal is a citation or an agent’s selection.
    CybersecurityFirst Page Sage, Driven Metrics, Focus Digital, BlueText, Amplifyed, and Obility.Technical editorial depth, coverage of compliance and ecosystem-fit questions, earned authority, product-category knowledge, and the ability to connect AI shortlists to qualified demand.
    Medical and healthcareFirst Page Sage, Genevate, Focus Digital, Driven Metrics, Rosemont Media, and Medico Digital.Clinical and claims review, regulated-content experience, patient or buyer intent, citation monitoring, and suitability for the precise medical sub-sector.
    General B2BFirst Page Sage, Genevate, Focus Digital, Driven Metrics, Omniscient Digital, Directive Consulting, Siege Media, and Animalz.Buyer-journey coverage, editorial versus performance orientation, product-line complexity, external authority, sales attribution, and multi-market delivery capacity.
    Local and regional businessesFirst Page Sage, Focus Digital, Siana Marketing, Driven Metrics, RYNO Strategic Solutions, CI Web Group, and Searchbloom.Service-area architecture, local-market knowledge, location-level facts and authority, capacity across markets, and reporting tied to calls, bookings, or qualified local leads.

    What good sector fit actually looks like

    Three adjacent scenes show a healthcare specialist handling evidence, a cybersecurity expert mapping network relationships, and a home-services operator connecting locations in a neighborhood.

    A logo from your industry is useful, but it is not proof of a relevant GEO engagement. The agency may have handled paid media, a brand project, traditional SEO, or a historical campaign that predates AI search. Ask what work was performed, which team delivered it, which AI-search behavior changed, and whether that same team would work on your account.

    Financial services and fintech: separate recommendation from selection

    Finance has two related but distinct requirements. GEO aims to earn citations and recommendations in systems such as ChatGPT, Gemini, Perplexity, and Google AI Overviews. Agentic search optimization goes further: it tries to make a provider the option an autonomous assistant selects when it researches, compares, or acts for a user. That distinction matters most when your product can enter an agent-assisted comparison, application, purchasing, or transaction workflow.

    The fintech ASO field is narrower than the broader GEO field. First Page Sage is positioned around full-service, expert-led programs for regulated finance. Genevate emphasizes third-party authority through earned coverage, expert commentary, roundups, podcasts, and directories. Driven Metrics emphasizes reporting tied to leads and revenue. Focus Digital emphasizes comparison-oriented content that can support both AI and organic search.

    Those differences tell you what to ask. If your own site lacks useful expert content, an external-PR-only program leaves a foundational gap. If you already publish strong material but have little independent corroboration, more on-site articles may not solve the problem. If your leadership team will only fund channels with defensible attribution, a polished citation dashboard that stops before pipeline will not be enough.

    For a more specialized finance brief, inspect the narrower candidates as well. Mint Studios is framed around fintech content and GEO. Avenue Z combines PR, GEO, and performance media. Evara centers HubSpot RevOps and inbound GEO. Croton Content brings a video-first AEO and GEO approach. In the agentic field, CSTMR focuses on fintech brand and conversion strategy, Obility adds B2B demand generation and RevOps, and Bay Leaf Digital brings a B2B SaaS content model. Match the model to the missing capability rather than adding names to a generic request for proposal.

    Your finance gate should be concrete: who interviews the internal expert, who writes, who checks product and regulatory claims, who resolves compliance edits, and who owns final approval? If the agency answers only with a content calendar, it has not answered the hard part.

    Cybersecurity: make technical depth visible before contracting

    Cybersecurity buyers use AI systems to investigate vendor fit, compliance requirements, solution categories, and compatibility with their security environment. The agency therefore has to do more than define broad terms. It must help your company become a credible candidate when the prompt contains technical constraints that can eliminate a vendor from consideration.

    The cybersecurity shortlist divides into several useful models. First Page Sage is positioned around technically authoritative GEO and lead generation. Driven Metrics combines AI-oriented content, technical optimization, authority building, and performance reporting. Focus Digital offers a leaner entry point for growth-stage companies, but the documented fit is weaker for highly demanding material involving areas such as ISO certifications or SOC. BlueText is more compelling when GEO must sit beside branding, PR, a competitive relaunch, fundraising, or transaction-related positioning. Amplifyed emphasizes content marketing and GEO, while Obility brings broader B2B digital marketing experience.

    Use a technical audition. Give each finalist a real buyer question that contains product, compliance, and ecosystem constraints. Ask for the content architecture, entities, evidence, expert inputs, and external corroboration it would use. You are testing reasoning, not requesting unpaid finished copy. A team that immediately reduces the problem to keywords, article length, and schema has not shown that it understands how a security buyer narrows risk.

    Also identify the people behind the work. Ask whether the technical editor is assigned to your account, how subject-matter disagreements are handled, and what happens when a model repeats an inaccurate comparison. A generic promise that the team uses experts is weaker than a named workflow with accountable roles.

    Medical and healthcare: governance is part of optimization

    Medical GEO can influence patients and professional buyers at a high-stakes decision point. An engagement must not optimize past clinical governance. Inaccurate treatment, condition, device, or provider information can mislead a reader and expose the organization to compliance and reputational risk. If an agency cannot describe its clinical review and claims-escalation workflow, remove it from the shortlist.

    The medical field contains several distinct fits. First Page Sage is positioned as the full-service, expert-led choice for medical lead generation. Genevate is the focused GEO option for organizations that already have other marketing functions covered and want citation-gap auditing plus authority work. Focus Digital is the leaner choice for a narrower initiative without a sprawling retainer. Driven Metrics fits organizations that want citation activity tied closely to conversions and analytics. Rosemont Media is specialized around elective and aesthetic practices, while Medico Digital is oriented toward regulated pharma, medtech, and private hospitals.

    The phrase healthcare experience is too broad for procurement. A local practice, a hospital system, a medical device company, and a pharmaceutical brand have different reviewers, claims, audiences, conversion events, and evidence requirements. Require experience in your actual sub-sector, or budget for a deliberate onboarding and review phase. Do not let a recognizable healthcare logo stand in for that answer.

    Ask the finalist to map one representative page from expert input through drafting, fact checking, medical or legal review, publication, structured data, external authority building, and post-publication correction. That map will expose whether the agency treats accuracy as an operating system or as a final proofreading step.

    B2B: require a line from recommendation to revenue

    B2B buyers increasingly use AI tools to identify and shortlist vendors. That makes recommendation visibility commercially relevant, but a B2B program still has to support a buying journey that may involve several roles, product comparisons, internal approval, and a handoff to sales.

    The B2B candidates cover different operating styles. First Page Sage combines GEO, AEO, SEO, expert-led content, and lead-generation measurement. Genevate starts with AI visibility gaps and emphasizes authority building. Focus Digital serves growth-stage companies seeking a more accessible entry point. Driven Metrics is suited to teams willing to integrate detailed reporting with their existing data practices. Omniscient Digital and Animalz lean toward content-led organic growth, Directive Consulting toward revenue and pipeline performance, and Siege Media toward data journalism and content-forward authority.

    Choose among those models by diagnosing your constraint. If you lack credible category content, start with editorial depth. If competitors dominate independent mentions, prioritize earned authority. If you already have traffic and citations but cannot show commercial value, fix attribution and conversion architecture. If your program spans several regions or product lines, test delivery capacity and coordination before choosing a lean team solely on price.

    The reporting plan should distinguish informational visibility from commercial inclusion. Ask which prompts represent early education, category formation, vendor comparison, objection handling, and purchase intent. Then require downstream reporting that your sales team recognizes, such as qualified inquiries, opportunities, pipeline contribution, or another defined conversion event. The agency should not substitute a proprietary visibility score for your business outcome.

    Local businesses: the unit of work is service plus place

    Local GEO is not a smaller version of national GEO. A recommendation must be relevant to a service, a location, and often the practical facts that determine whether the business can help. Location-targeted pages, service-area coverage, authoritative local information, and consistent business facts therefore matter more than a large library of generic advice.

    The local shortlist again contains different models. First Page Sage is positioned around full-service location content and AI-citation strategy. Focus Digital offers a lower-overhead model for small and midsized organizations, with capacity as a point to verify. Siana Marketing is particularly relevant to home services and construction. Driven Metrics emphasizes dashboards, attribution, and regular performance analysis. RYNO Strategic Solutions and CI Web Group bring broader home-services marketing, while Searchbloom combines conversion-focused local SEO and GEO.

    Give finalists a market matrix rather than a single target keyword. It should identify services, locations, customer types, high-intent questions, business facts, existing location pages, and the conversion event for each market. Then ask how the agency will prevent thin near-duplicate pages while still supplying the geographic specificity an AI answer needs.

    Capacity matters here because each added market creates editorial, factual, and measurement work. Ask what happens when you add locations, change hours or service areas, or need a correction across many pages and profiles. A boutique team’s attention can be an advantage, but only if its delivery system can keep local facts current.

    Choose GEO, AEO, ASO, or a combined program before choosing an agency

    Agency proposals become difficult to compare when every vendor uses AI search optimization to mean something different. Define the behavior you want to change before requesting tactics:

    • SEO improves discoverability and performance in traditional search results. It remains part of the foundation because useful, crawlable, well-organized pages can support both human discovery and AI retrieval.
    • AEO focuses on making clear answers retrievable for direct questions. It usually depends on concise answer passages, logical page structure, explicit entities, and enough supporting depth to make the answer trustworthy.
    • GEO aims to improve whether your company, products, or expertise are cited or recommended in an AI-generated response. It requires more than answer formatting because brand authority and third-party corroboration can influence whether your name belongs in the response at all.
    • ASO addresses autonomous agents that research, evaluate, select, or act for a user. Being cited for a person and being chosen by an agent are different outcomes, so an ASO brief must include the facts, evidence, eligibility, comparison logic, and action path an agent needs.

    A combined program can be appropriate, but the proposal should still identify separate deliverables and measures. A page may rank in Google without appearing in an AI shortlist. A brand may be mentioned in an answer without receiving a citation. It may receive a citation without being recommended. It may be recommended without being the option an agent selects. Ask the agency to report those states separately.

    Write the objective in behavioral terms. For GEO, you might ask to increase qualified inclusion when a defined buyer compares a defined category. For AEO, ask to improve accurate answer coverage for a mapped set of customer questions. For ASO, ask how your product and business facts will become sufficiently clear, credible, and actionable for an agent-assisted decision. These are more useful briefs than a request to rank in ChatGPT.

    Where JSON-LD and technical optimization fit

    JSON-LD is a machine-readable factual layer, not an authority shortcut. It can clarify relationships among your organization, people, products, services, content, and locations. It cannot manufacture independent credibility, make weak content expert, or guarantee a recommendation.

    Ask the agency to map each important machine-readable fact to visible page content and a responsible internal owner. The same identity, service, location, author, and product facts should not contradict one another across pages, markup, external profiles, and earned citations. Reject any proposal that treats adding schema as the complete GEO strategy or marks up claims users cannot verify on the page.

    A credible technical workstream should explain what needs to be crawled, rendered, consolidated, clarified, or marked up; who will implement the change; and how the agency will verify it after deployment. If the agency only supplies recommendations, confirm that your own development team has the capacity and ownership needed to ship them.

    How to vet agency claims before you sign

    A buyer examines layered proposal evidence with a magnifying lens as verified documents and connected nodes remain solid while unsupported shapes dissolve.

    AI outputs can vary by platform, model, timing, location, and prompt wording. A screenshot is evidence that one output occurred, not proof of durable visibility. Your due diligence should force each agency to show how it defines the market, records outputs, makes changes, and connects those changes to business results.

    1. Define the prompt universe. Require prompts grouped by audience, need, buying stage, product, sector constraint, and geography where relevant. A bag of flattering brand-name prompts is not a market baseline.
    2. Record the starting state. The baseline should identify the AI product, prompt, date, response, cited URLs, competitors present, your inclusion status, factual errors, and the commercial intent of the query. Preserve the underlying output, not just a rolled-up score.
    3. Separate mentions, citations, recommendations, and actions. A mention means your name appeared. A citation means the response referenced your material. A recommendation means the system presented you as a suitable option. An agentic selection means an agent chose or acted on the option. Do not let one label cover all four.
    4. Inspect sector execution. Ask for work from your actual sub-sector and clarify the scope, date, team, and result. A client logo is not evidence that the agency handled GEO, produced technical content, passed regulatory review, or influenced AI recommendations.
    5. Demand an owned, earned, and technical plan. The proposal should state what will change on your site, what third-party authority must be earned, and what technical or structured-data work supports discovery and factual clarity. It should also name dependencies the agency does not control.
    6. Test the governance workflow. Identify the writer, subject-matter expert, editor, compliance or clinical reviewer where applicable, publisher, and correction owner. Ask how disagreements are resolved and how urgent inaccuracies are handled after publication.
    7. Connect visibility to a conversion. Require reporting that moves from prompt coverage and citations to AI referral activity, qualified inquiries, opportunities, bookings, applications, revenue, or the outcome appropriate to your business. Attribution will not be perfect, but the agency should state what it can and cannot infer.
    8. Confirm capacity and ownership. Document delivery cadence, review turnaround expectations, implementation responsibility, access to data, use of subcontractors, rights to content and research, dashboard access, and what you retain if the engagement ends.

    Apply extra skepticism to ordered lists and proprietary scores. Every 2026 ranking used here was published by First Page Sage, and First Page Sage placed itself first in every covered sector. That conflict does not make the candidate descriptions useless, but it does mean the rankings are market-discovery material rather than independent procurement proof.

    There is also a concrete methodology warning: the published financial-services weights total 115% when the listed percentages are added. Do not carry precise rank order or decimal scores into an executive recommendation as though they were audited benchmarks. Verify reviews, references, work samples, output records, and client scope directly.

    Be equally cautious with guarantees. No agency controls an external model’s output, retrieval system, citations, or future product changes. A credible proposal can commit to deliverables, governance, testing, reporting, and a reasoned strategy. It cannot responsibly guarantee a permanent rank or recommendation on a system it does not operate.

    Turn your sector shortlist into a contractable brief

    Before contacting agencies, write down the decision you want AI search to influence. Name the buyer or patient audience, category, products or services, markets, compliance constraints, priority AI surfaces, current content and PR assets, technical limitations, conversion event, and internal reviewers. This prevents an agency from filling an ambiguous brief with whichever deliverables it already sells.

    Require every finalist to respond to the same core scope:

    • A sector- and buyer-stage prompt map, including exclusions and low-value prompts the program will not chase.
    • A reproducible baseline covering your brand, competitors, cited domains, factual accuracy, and recommendation status.
    • An on-site content plan showing where first-party expertise will come from and how it will survive internal review.
    • An external-authority plan identifying the kinds of corroboration, coverage, directories, commentary, or other third-party signals the agency will pursue.
    • A technical and JSON-LD workstream with implementation ownership and post-deployment verification.
    • A governance map naming who drafts, reviews, approves, publishes, monitors, and corrects material.
    • A measurement framework separating visibility, citations, recommendations, referral activity, conversions, and agentic selections where relevant.
    • A clear statement of assumptions, dependencies, exclusions, content ownership, data access, and what will be handed back at the end of the engagement.

    Then compare the reasoning, not the vocabulary. The strongest response will explain why your sector changes the strategy, where your current authority is weak, what evidence the agency needs, what it cannot promise, and how the work reaches a business outcome.

    Start by eliminating any candidate that fails your sector’s non-negotiable gate: compliance workflow in finance, clinical governance in medicine, technical depth in cybersecurity, pipeline measurement in B2B, or location-level execution in local search. Send the remaining agencies the same brief and choose the team whose evidence, operating model, and accountability fit the decision you actually need to influence.

    References


  • Image Optimization for AI Search: A Practical Workflow

    Image Optimization for AI Search: A Practical Workflow

    Your images can be attractive, fast and conventionally SEO-friendly yet still be unclear to an AI system. If the system cannot identify the main object, read an important label or connect the scene to the claims on the page, the image contributes little to a multimodal answer.

    Fixing that problem does not mean putting more keywords into filenames. It means making the pixels, alternative text and visible page copy tell the same specific story. The workflow below will help you decide what each image must communicate, test whether that meaning survives machine interpretation and correct the failures that matter.

    AI search needs an image it can retrieve and explain

    Visual search is no longer a secondary way to browse an image index. People run roughly 20 billion visual searches through Google Lens each month. A search can begin with a camera, an uploaded image or a screenshot when the user cannot easily describe the object in words.

    That changes the optimization target. The old question was whether an image could rank for a text query. The additional question is whether a system can use the image to understand the query, retrieve the associated page and assemble a supported answer.

    Google filed a patent application in 2023, published in April 2026, describing a flow in which an image match identifies a cited page before surrounding text is used to construct an answer. That is not confirmation of a live production ranking process. Patent applications may never be implemented as written. It is still a useful design signal: an image may help a system discover the page whose text supplies the explanation.

    Treat every important image as a paired asset: the visual evidence and the page evidence. Before publishing it, ask four questions:

    • Can the system access and render the image when it retrieves the page?
    • Can it identify the primary product, person, place, condition or process without relying on the filename?
    • Can it read any visible text that is necessary to distinguish a model, package, measurement or state?
    • Does the surrounding HTML text confirm what the image shows and explain why it matters?

    If the image fails the second or third question, fix the asset or choose another one. Metadata cannot rescue a photograph whose subject is tiny, obscured or visually ambiguous. If it fails the fourth question, improve the page copy. A model should not have to infer a critical fact from pixels alone.

    Run two audits: what is visible, then what it implies

    An orange trail shoe is shown under a magnifying lens on one side and beside a rocky path, mud, and a water bottle on the other.

    A useful image audit separates literal recognition from implied meaning. Combining them too early hides the cause of a failure. You may think an image communicates expert installation, for example, when a machine sees only a person standing beside a cabinet.

    Audit the literal contents without page context

    Start with denotation: the objects and attributes that can actually be pointed to in the frame. Hide the headline, caption, filename and surrounding copy. Then write a neutral inventory of what is visible.

    For a product photograph, that inventory might include a stainless steel coffee maker, a thermal carafe, a control panel and a visible model label. For a service photograph, it might include a leaking pipe joint, a wrench and a technician wearing protective gloves. Keep interpretation out of this first pass. Words such as premium, reliable and professional are conclusions, not visible objects.

    Now ask a capable multimodal model for a literal description using a neutral instruction such as: “List the objects, visible text, materials, conditions and relationships in this image. Do not infer facts that are not visually supported.” Compare its output with your own inventory and with the visual brief.

    This is a diagnostic check, not a simulation of any particular search engine. Different models can produce different descriptions, and one successful response does not prove retrieval or citation. The test is still valuable because a missed primary object exposes an avoidable ambiguity in the image.

    When an essential object or attribute is missed, inspect the likely visual cause:

    • The primary subject occupies too little of the frame.
    • Another object has stronger contrast and becomes the apparent subject.
    • The item is partly hidden, cropped or viewed from an angle that conceals its defining shape.
    • Several similar objects overlap, making their boundaries unclear.
    • Glare, shallow focus or compression makes packaging text unreadable.
    • The rendered website crop removes information that was present in the original file.

    Fix composition before metadata. Use a clearer angle, tighter crop, simpler background, additional close-up or separate detail image. Product galleries should not make one wide lifestyle photograph perform every recognition task.

    Audit the meaning created by the composition

    The second pass examines connotation: what the combination of objects, people and setting implies. This is where co-occurrence matters. A wrench beside a visibly damaged fitting tells a different service story from the same wrench lying on a spotless workbench. A team portrait in an identifiable office says something different from anonymous people in a generic meeting room.

    Write the intended meaning in one sentence. Then underline the visible evidence that supports every part of it. If the intended meaning is “a technician diagnosing a leaking kitchen connection,” the frame should contain a technician, a relevant connection and evidence of the leak. If only the kitchen is visible, the image is decorative context rather than proof of the service.

    Use these questions to expose weak or accidental implications:

    • What is the most prominent entity, and is it the entity the page is about?
    • What relationship between the visible entities would a neutral viewer infer?
    • Which object introduces an unrelated interpretation?
    • Does the setting support the intended use case, location or audience?
    • Are you asking the image to prove a credential, performance claim or identity that only text can establish?

    Original imagery matters most when the image is supposed to establish identity or evidence. A stock photograph can illustrate a general concept, but it cannot reliably prove what your product looks like, who works on your team, where your business operates or how your service is performed. Use visible page copy to name people, roles, credentials and locations rather than expecting a model to infer them from appearance.

    Give each page type a deliberate visual job

    An image should be briefed against the decision a visitor is making on that page. The same attractive photograph will not serve a homepage, product page and technical explainer equally well. Different page types require different visual evidence, especially when a multimodal system may use that evidence to interpret the surrounding content.

    Page typePrimary visual jobWhat the image should make detectableWhat the page text should confirm
    HomepageEstablish the brand and offeringAn original product, location, team or use context rather than an interchangeable mood imageThe brand name, principal offering and relationship between the visible entities
    Product pageSupport identification and comparisonThe complete product, multiple angles, distinctive parts, packaging and legible model or variant textProduct name, variant, materials, dimensions and other attributes relevant to the image
    Blog or information pageExplain a concept, process or claimClearly labelled steps, components, states or relationships in a diagram or infographicEvery substantive claim shown in the graphic, written as ordinary machine-readable HTML text
    About or team pageConnect a person with an organization and roleA clear portrait or authentic workplace contextThe person’s name, role, credentials and authorship relationship where relevant
    Service pageShow the problem, work or outcomeThe actual condition, equipment, process or clearly differentiated before-and-after statesThe service performed, the meaning of each state and any necessary limitations
    Contact or location pageReinforce physical identity and placeThe exterior, entrance, interior or recognizable local contextThe business name, address and relationship between the pictured place and the business

    Give each image one primary job even when it can support several queries. A product hero can establish the overall shape; a second image can expose controls; a third can make the package label readable. This is clearer than forcing a single distant photograph to carry every attribute.

    Be especially careful with infographics and before-and-after images. Do not leave the claim inside the graphic. Repeat it in the page copy, identify which state is which and explain what changed. The image can demonstrate the relationship, while the text supplies the exact claim and its qualifications.

    Publish the image and page as one semantic unit

    A red insulated bottle, its studio photograph, a blank article layout, and a transparent lens are connected by soft blue light on a desk.

    Write a visual brief before choosing the asset

    A useful visual brief is short enough to apply during a content review. For each important image, record:

    • Target question: the query or decision the visual should help resolve.
    • Primary entity: the product, person, place, condition or process that must be recognized.
    • Must-detect details: the visible attributes needed to distinguish the entity or explain the answer.
    • Must-read text: labels or packaging copy that must remain legible in the delivered image.
    • Intended implication: the relationship or use case the composition should communicate.
    • Supporting sentence: the nearby HTML text that names and explains what the image shows.
    • Failure condition: the omission or misreading that would make the image misleading or useless.

    This brief prevents a common mismatch: copy written around a concrete answer paired with an image selected for atmosphere. It also gives designers, photographers, writers and SEO teams one set of acceptance criteria.

    Preserve meaning through the technical delivery

    Traditional image hygiene still matters, but each choice should preserve recognition as well as performance. Use a descriptive filename because it provides context, not because a keyword-rich filename can override the pixels. Supply responsive dimensions and an appropriate format, then inspect the image as it actually appears on the page.

    Compression deserves a visual check at every important breakpoint. A package label that is crisp in the master file may become unreadable in a smaller responsive variant. Performance optimization should preserve the legibility of product text, labels and diagram annotations that a system needs to interpret the image.

    Use loading settings that improve page performance while keeping the image available when the page is rendered and retrieved. Check the delivered page rather than assuming the media library preview represents what a crawler or visitor receives.

    Write alternative text for accuracy and accessibility

    Alternative text should describe the image’s purpose in its page context. Keep it natural and factual. Do not turn it into a string of search terms, and do not insert claims the pixels do not support.

    For example, “Stainless steel coffee maker beside its thermal carafe, with the model name visible on the front panel” is useful when those details help the reader understand the product. “Coffee maker, best thermal brewer, premium coffee machine” is neither a reliable description nor good accessible text.

    Complex diagrams need more than a long alt attribute. Give the image a concise accessible description, then explain the important steps, comparisons or claims in visible HTML text. A decorative image that contributes no information should use the appropriate empty alternative text rather than forcing irrelevant keywords onto screen-reader users.

    Run the final check on the rendered page

    Use this sequence before publishing or replacing a high-value image:

    1. Write the target question and the one visual fact that helps answer it.
    2. List the entities, attributes and text that must be detectable in the frame.
    3. Inspect the image without page context and record a literal human description.
    4. Run the same blind description through at least one multimodal model and note omissions or competing interpretations.
    5. Correct the crop, angle, clutter, visibility or export quality before changing metadata.
    6. Confirm that the alt text and nearby page copy accurately name what is visible and carry every important claim.
    7. Test the delivered image at the page’s actual responsive sizes, including the legibility of labels and annotations.
    8. Save the intended query, observed description and corrections so that later asset changes can be reviewed against the same brief.

    After publication, use a fixed set of visual and text queries when checking search or AI-answer visibility. Record whether the image appears, whether the associated page is cited and whether the answer describes the intended attributes accurately. An appearance is evidence of visibility, not proof that one metadata change caused it, so compare repeated checks rather than drawing a conclusion from a single result.

    Key takeaways

    • Optimize the visual evidence and the page evidence together; neither should contradict or depend on the other to repair ambiguity.
    • Test literal recognition before judging brand meaning. If the primary entity is missed, fix the composition first.
    • Control co-occurrence deliberately. Every prominent object and person in the frame contributes to the meaning a model may infer.
    • Assign images different jobs by page type: identification on product pages, explanation on information pages and entity confirmation on team or location pages.
    • Repeat substantive graphic claims in visible HTML text. Important facts should not exist only inside pixels or alternative text.
    • Compress for performance while checking the actual delivered crop, resolution and text legibility.
    • Treat multimodal model descriptions as diagnostic observations, not guarantees of ranking, retrieval or citation.

    Start with five pages that matter commercially or editorially. Hide the copy, inspect each rendered image and ask what a neutral observer can actually identify. Replace or recompose the images that fail that blind test, then align the alternative text and nearby copy with what remains. That small, documented audit gives you a repeatable standard for every visual you publish next.

    References


  • How to Earn AI Search Citations and Measure Source Visibility

    How to Earn AI Search Citations and Measure Source Visibility

    You can rank for a query, appear somewhere in an AI-generated answer, and still lose the citation to another site. The system may name your brand without linking to you, cite a competing page, or display your link without sending a measurable visit.

    If you want to improve that outcome, stop treating AI visibility as one metric. You need a page that can be retrieved, an answer passage that can stand on its own, a defensible reason to select your URL, and a measurement process that separates citations from mentions and clicks.

    Separate citations, mentions, and visits before optimizing

    Teams often report that they appeared in AI search without recording what actually appeared. That makes the next content decision guesswork. For practical measurement, use three distinct working definitions.

    SignalWhat you observedWhat it does not prove
    CitationThe answer identifies or links to a page on your domain as support.That the user clicked, read, or converted.
    Brand mentionThe answer names your company, product, author, or other entity.That an owned page received attribution.
    VisitA user reached your site after interacting with an AI search experience.That every preceding citation was visible or measurable.

    A citation is usually the right primary outcome for publishers and information-led SEO because it exposes the supporting page. A mention can still strengthen brand visibility, but it does not give the reader a route to inspect your evidence. A visit is the commercial opportunity, yet it sits one step later and depends on whether the link gives the reader a reason to leave the generated answer.

    Set the goal at the page level. A definition page may be successful when it earns repeated citations. A product page may need qualified visits rather than broad mentions. A developing-topic page may need visibility in a prominent link module while attention is concentrated on the event. Do not combine these outcomes into a single AI visibility score unless the underlying signals remain available separately.

    Build answer passages that survive extraction

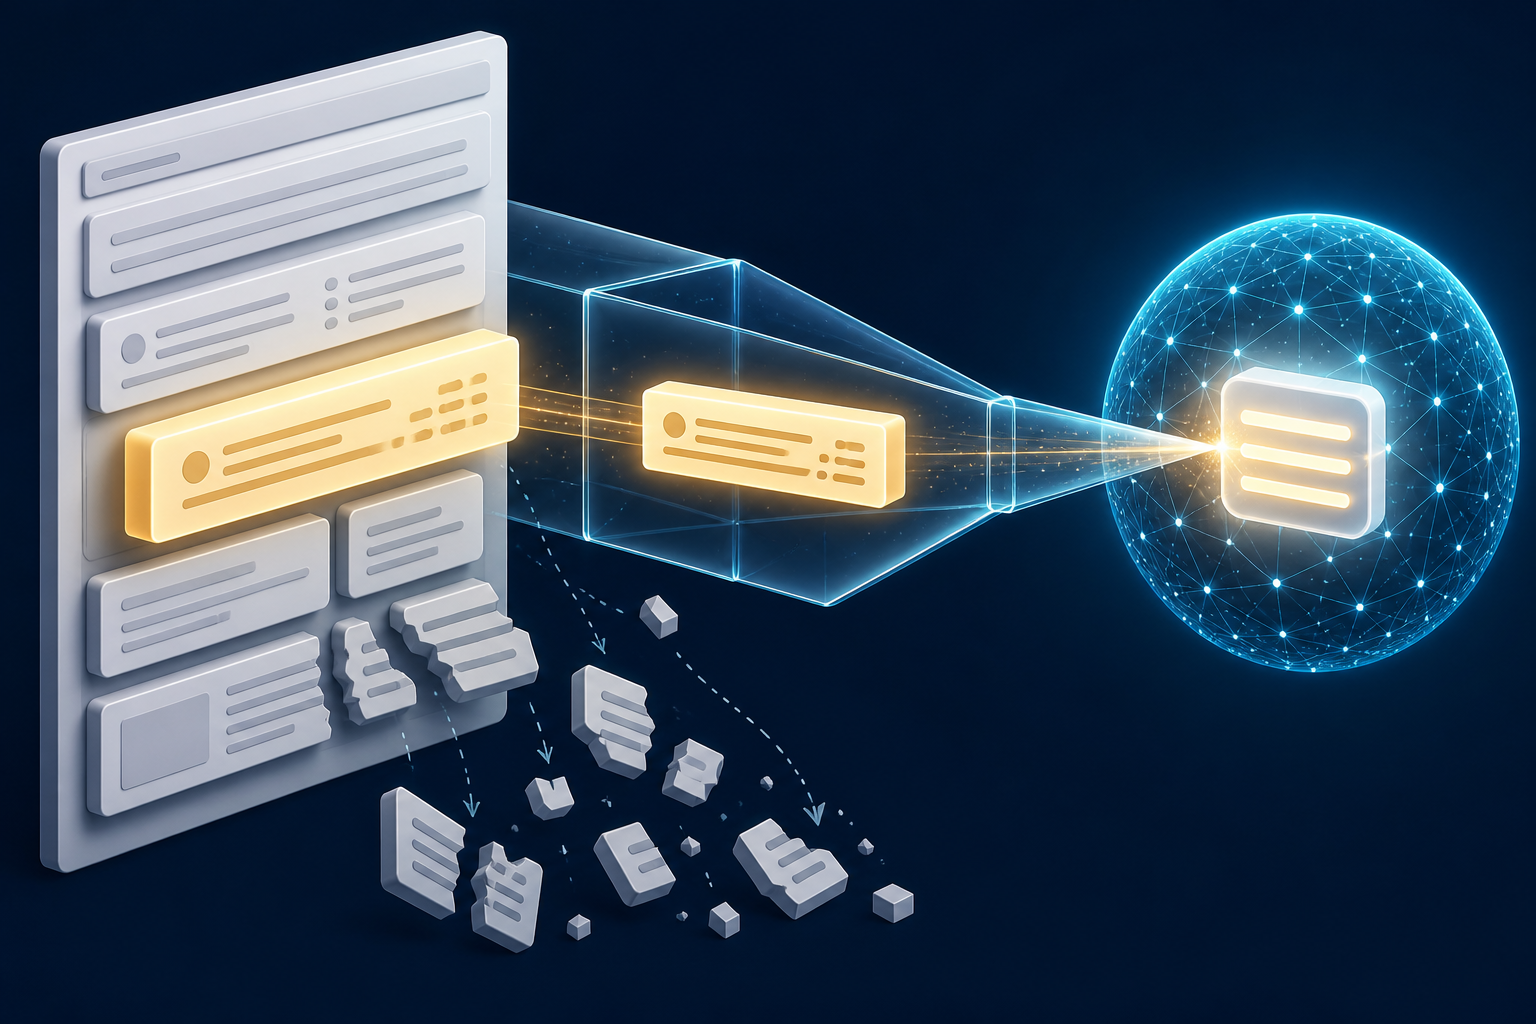
    One intact content block moves from an abstract web page through a transparent funnel toward a glowing sphere while fragmented blocks fall away.

    A polished draft is not necessarily a citable draft. The more useful standard is whether the page contains a citation-ready answer that remains accurate when lifted out of its surrounding introduction.

    Treat the passage, not the word count, as your basic unit of work. Each important query should map to a bounded section with a descriptive heading. The opening sentence should resolve the question directly. The following sentences should carry the qualification, evidence, and consequence needed to prevent the answer from becoming misleading.

    Use a four-part answer block

    1. Answer: State the conclusion in the first sentence. Do not make the reader cross an anecdote, mission statement, or definition they already know.
    2. Boundary: Name the situation in which the answer applies. Keep material qualifiers in the same paragraph as the claim they limit.
    3. Support: Explain the mechanism or attach the relevant evidence. Link factual claims to their originating evidence rather than to a page that merely repeats them.
    4. Next step: Give the reader useful depth that the short answer cannot contain, such as implementation steps, decision criteria, exceptions, or a worked example.

    Consider the difference between these two passages:

    Weak: AI visibility is changing quickly, so brands need a comprehensive strategy that improves their presence across emerging platforms.

    Citable: An AI search citation identifies a supporting page or domain inside a generated answer. A brand mention without an owned link is visibility, but not citation visibility. Track the two separately so a rise in mentions does not hide a decline in attributed pages.

    The second version makes a bounded claim, defines the distinction, and tells the reader what to do with it. It does not need promotional language to sound authoritative.

    Create a claim ledger before expanding the page

    For every section you expect to earn citations, record the following fields in your content brief:

    • The exact question the section answers.
    • The answer in one plain sentence.
    • The qualifier that would make the sentence inaccurate if omitted.
    • The evidence that supports the claim.
    • The contribution that is original to your page.
    • The person responsible for checking whether the answer is still current.

    This ledger catches a common failure before publication: a section sounds complete but has no supportable claim. It also prevents an editor from separating a caveat from the sentence it qualifies. If you cannot fill the evidence field, rewrite the statement as analysis, label the uncertainty, or remove it.

    Run a final extractability pass after the normal edit. Replace vague pronouns with named entities where context could be lost. Remove unsupported superlatives. Use one term consistently for the same concept. Keep the evidence link next to the claim it supports. Make each heading specific enough that a reader can predict the answer below it.

    Give AI systems a defensible reason to select your page

    Clear formatting makes content easier to reuse, but clarity alone does not make your URL preferable. If your page is an interchangeable paraphrase of information already available elsewhere, formatting only makes the duplication easier to see.

    Strengthen the page with a contribution that another answer can reasonably attribute to you. That contribution might be first-party data with a disclosed method, original documentation, a comparison built from explicit criteria, a verified chronology, or analysis that shows its reasoning. Do not manufacture novelty by renaming a familiar idea or presenting an unsourced opinion as a finding.

    For evergreen questions, optimize the decision

    An evergreen page should do more than provide a dictionary answer. After the direct response, help the reader choose, implement, diagnose, or verify something. State the criteria that change the recommendation. Include exceptions where they materially affect the outcome. Keep the page on a stable URL so references, internal links, and structured data continue to identify the same resource.

    A useful test is to remove your brand name from the draft and compare the remaining value with a generic summary. If nothing distinctive remains, add evidence or decision support before adding more prose.

    For developing topics, make the update verifiable

    Google has introduced AI Mode link carousels for developing topics. These modules can place relevant pages, including a user’s Preferred Sources, prominently in the result. Google frames the feature around connecting people with original coverage and a range of perspectives.

    That creates a specific opportunity for publishers covering active events, but only when the page makes its contribution easy to verify. Put the material change near the top. Separate confirmed facts from interpretation. Identify what remains unknown. Link claims to the originating evidence. Show readers when the page was updated, and do not silently replace an earlier conclusion without explaining what changed.

    A prominent carousel may make links easier to notice and click, but it does not justify forecasting the click-through rates you received before AI-generated search experiences. Give the reader a reason to continue: the underlying evidence, a complete timeline, a tool, detailed methodology, or analysis that cannot fit inside the generated answer.

    Make the page retrievable, stable, and unambiguous

    Content cannot earn a reliable citation if the system cannot retrieve the useful version or determine which URL represents it. Run a technical pass after the claim-level edit.

    • Accessibility: Keep the substantive answer available in the page’s rendered content. Do not require a form submission, account, tab interaction, or client-side event merely to reveal the core response.
    • Indexability: Check that robots rules and page-level directives do not exclude the URL from the search systems you expect to surface it.
    • Canonical consistency: Use one preferred URL across canonical signals, internal links, sitemaps, and structured data. Consolidate accidental duplicates rather than asking systems to choose among them.
    • Information structure: Give the page a descriptive title, question-aligned headings, and internal links from relevant pages. The hierarchy should reveal the main answer and its supporting sections without relying on visual styling.
    • Entity consistency: Use the same names for your organization, product, person, and core concepts in visible copy, metadata, and structured data.
    • Maintenance: Preserve the URL when the underlying resource remains the same. When the facts change, update the answer, its evidence, and any visible freshness information together.

    Use JSON-LD to clarify, not to manufacture authority

    Structured data can describe what a page represents and connect it with relevant entities. It cannot force an AI system to cite the URL, turn an unsupported assertion into evidence, or compensate for an answer buried in vague copy.

    Add markup only for information supported by the visible page. Make sure the structured entity uses the same preferred name and canonical URL as the rest of the site. If the markup describes a different page purpose, organization name, or content relationship than the reader sees, correct the inconsistency instead of adding more properties.

    Then perform two separate checks. First, read the rendered page as if you had landed directly on the relevant heading: can you identify the answer, boundary, and evidence without reconstructing missing context? Second, validate the structured data on its own terms. Passing the second check does not excuse failing the first.

    Measure source visibility with a prompt-level scorecard

    A seated researcher examines a glowing matrix of blank tiles and colored visual markers on a large analysis display.

    AI answers can vary with prompt wording, search surface, location, session context, and observation time. A screenshot from one query can prove that a citation occurred, but it cannot show how consistently your domain appears. Build a repeatable prompt set around real audience intents and keep the exact wording available for later observations.

    Include question types that expose different citation opportunities: definitions, procedures, comparisons, verification questions, and developing-topic queries where they fit your business. Do not insert your brand into every prompt. A branded prompt measures retrieval of a known entity; it does not tell you whether the brand is discoverable in an unbranded answer.

    Record the evidence behind every visibility claim

    • The exact prompt and the intent it represents.
    • The AI search surface and relevant session conditions.
    • The time of the observation.
    • Whether the brand appeared.
    • Whether an owned URL was cited.
    • The linked page and the claim it supported.
    • Whether the link appeared inline, in a citation area, or in a carousel.
    • Which competing domains were cited for the same answer.
    • Any identifiable landing-page visit or downstream conversion.

    From that record, calculate separate directional metrics. Citation presence is the share of observations containing an owned citation. Citation coverage is the share of monitored prompt families in which the domain appears at all. The mention-to-citation gap counts observations that name the brand but provide no owned link. Landing-page concentration shows whether visibility depends on one URL or is distributed across the site.

    Keep those metrics distinct from traffic. Google does not provide clean AI Mode click reporting through Search Console’s generative AI reporting, so an absent click record does not prove that no citation appeared. Conversely, a visible citation does not prove that a visit occurred. Use Search Console and analytics for the signals they expose, then retain your prompt observations as a separate evidence set.

    When you change a page, keep the monitored prompt set stable, log what changed, and repeat the observations after the updated page has had a chance to be rediscovered. Change a bounded element such as the answer block, evidence structure, or page consolidation before rewriting everything at once. Treat movement as directional unless it persists across repeated observations; generated results are too variable for a single before-and-after response to establish causation.

    Key takeaways

    • Measure citations, brand mentions, and visits separately because each proves a different outcome.
    • Write claim-level answer blocks with the conclusion, boundary, support, and useful next step kept together.
    • Give the page an attributable contribution instead of publishing an interchangeable summary.
    • Treat developing-topic visibility as a freshness and verification task, especially where AI Mode displays link carousels.
    • Use JSON-LD to reinforce visible meaning and entity relationships, not as a substitute for evidence.
    • Track exact prompts and cited URLs over repeated observations; do not infer source visibility from incomplete click data alone.

    Start with one commercially or editorially important page that should be cited but is not. Build its claim ledger, rewrite the main answer block, verify retrieval and canonical signals, and record a prompt-level baseline. That turns a vague visibility problem into a controlled content, technical, and measurement task.

    References


  • AI Search Visibility Strategy: From Clicks to Recommendations

    AI Search Visibility Strategy: From Clicks to Recommendations

    Your rankings can look respectable while clicks keep falling. That is not automatically a conventional SEO failure. An AI answer can satisfy the query before the searcher visits a website, while an assistant can understand and cite your brand yet omit it when someone asks what to buy.

    The practical response is to stop treating AI visibility as one score. You need to diagnose where demand is being intercepted, distinguish citations from recommendations, publish evidence for real buying scenarios, and route problems to the teams that can actually solve them. Being understood and being recommendable are different outcomes, and confusing them leads to the wrong work.

    Key takeaways

    • Separate Google AI Overview exposure, organic clicks, direct assistant referrals, citations, and recommendations. They describe different parts of the journey.
    • Segment performance by intent before deciding that SEO as a whole is declining. Informational demand is much more exposed to zero-click answers than transactional demand.
    • Audit unbranded buyer scenarios, not just category keywords or brand prompts. Recommendations change when buyers add requirements, constraints, and tradeoffs.
    • Use content and JSON-LD to clarify truthful evidence. Do not expect either to compensate for a missing capability, weak support, or a poor product fit.
    • Measure lead volume and business outcomes alongside traffic and conversion rate. Better-qualified visitors can soften a traffic loss without fully recovering it.

    Diagnose the visibility problem before changing your strategy

    Organic search still accounted for 42.8% of sessions in July 2026 across one normalized panel of 218 client websites, making it the largest traffic source in that dataset. Its normalized session volume was nevertheless 23.6% lower than in January 2023. Direct referrals from AI assistants moved from 0.1% to 6.2% of sessions over the same period.

    Those percentages are directional evidence, not a forecast for every site. The panel covered client websites in 12 industries and normalized results for growth, seasonality, and spend. Its reported losses were measured against a pre-2023 growth baseline, so a site could trail the counterfactual even if its absolute visits increased. Use the pattern to shape your diagnosis, but calculate the exposure with your own query, landing-page, and conversion data.

    The first distinction is between an AI feature on a search results page and a visit from a separate assistant. A Google AI Overview sits above conventional organic results and can suppress their clicks. An AI referral is an observed session whose referrer resolves to an assistant. Mixing the two hides whether you lost a click on Google, gained a visit from an assistant, or influenced a decision that produced no trackable referral at all.

    The click pressure can be severe even when a page holds its position. For tracked impressions at position one, click-through rate was 27.4% without an AI Overview and 11.8% with one, a relative decline of 56.9%. The top-ranking page did not suddenly become irrelevant; the results page changed how much of the answer required a click.

    Signal you seePossible readingWhat to inspect next
    Impressions and rankings hold, but click-through rate fallsThe results page may be resolving more of the queryCompare query-level CTR when an AI Overview is present and absent, then split the queries by intent
    Informational visits fall while commercial and transactional pages holdYour traffic mix is changing rather than the entire site failingReport sessions, leads, and assisted journeys separately for each intent group
    Sessions fall while visitor-to-lead rate improvesFewer but more qualified visitors may be reaching the siteCheck total lead volume and pipeline value, not conversion rate alone
    Observed assistant referrals grow while organic clicks declineDiscovery may be moving between surfacesTrack assistant landing pages, outcomes, and referrers in a separate channel grouping
    Your brand is cited for explanations but omitted from purchase adviceThe gap may concern evidence, fit, reputation, or the product itselfAudit realistic buying scenarios and record the stated reason for exclusion

    Do not begin with a sitewide rewrite. Start with the query groups that lost clicks or recommendations. If impressions and rankings fell across intents, you still have a conventional SEO problem to investigate. If rankings remain stable and the loss clusters around AI-answer results, your priority is adapting the content and measurement model. If assistants retrieve your facts but reject the offer for a buyer’s constraints, more indexable copy may not solve anything.

    Build for citations and recommendations as separate outcomes

    Two illuminated paths lead separately to connected evidence cards and a selected group of unbranded products.

    AI visibility has a progression. A brand can succeed at the early stages and still fail at the point closest to revenue:

    1. Accessible: the relevant pages can be crawled, rendered, and found.
    2. Understandable: the system can identify the company, offering, audience, properties, and relationships correctly.
    3. Citable: the content contains a useful statement or piece of evidence that supports an answer.
    4. Considered: the brand enters the candidate set for a realistic buyer scenario.
    5. Recommended: the available evidence makes the product or service an appropriate fit for that scenario and its tradeoffs.

    The first three stages sit close to familiar technical SEO, content, entity clarity, and authority work. The final two force the system to compare options. At that point, technical documentation, product specifications, customer experiences, third-party evidence, and known tradeoffs can all affect the result.

    A prompt inventory therefore should not consist of broad questions such as which vendors operate in a category. Those prompts test recall and retrieval. Build scenarios around the conditions that change a purchase decision:

    • The buyer’s industry, application, or operating environment.
    • The non-negotiable capability, compatibility, or service requirement.
    • The outcome being optimized, such as uptime, contamination control, implementation risk, or initial cost.
    • The tradeoff the buyer is willing to accept.
    • The constraints that would make an otherwise credible option unsuitable.

    For each scenario, record whether your brand was mentioned, cited, considered, and recommended. Capture the exact response, the evidence it relied on, the reason given for inclusion or exclusion, and the page or team that owns the underlying claim. Repeat materially important scenarios with controlled prompt variations so one unusually favorable or unfavorable response does not become your strategy.

    Classify each failure before assigning work. A retrieval gap means the relevant evidence exists but is hard to find or interpret. An evidence gap means the claim is not documented well enough to support. A fit gap means the offer genuinely lacks something the buyer requires. A trust gap means customer experiences or credible third-party information create risk. These categories may look identical in a visibility dashboard, but their remedies are not interchangeable.

    AI output is diagnostic evidence, not an unquestionable verdict. Verify every material claim against product documentation, support records, customer evidence, and the actual offer. When the system is wrong, publish clearer, retrievable evidence and correct inconsistent facts. When it is right about a limitation, route the issue instead of trying to wordsmith around it.

    Move content closer to decisions without abandoning information

    The greatest traffic exposure sits at the top of the intent funnel. In the same client-site panel, informational queries lost 43.9% of normalized organic sessions and had a 91.7% zero-click rate. Commercial-investigation queries declined 14.2%, while transactional queries declined only 5.7%.

    Search intentChange in organic sessionsZero-click rateStrategic role
    Informational-43.9%91.7%Supply clear answers and evidence that can create awareness or support later decisions
    Navigational-19.4%76.3%Make official brand, product, and destination information unambiguous
    Commercial investigation-14.2%58.1%Help buyers compare fit, requirements, tradeoffs, and proof
    Transactional-5.7%37.2%Remove uncertainty from the next action or purchase

    This does not justify deleting informational content or publishing only bottom-funnel pages. Informational content can still establish terminology, answer prerequisites, support customers, and provide evidence that an answer engine retrieves. Its job has changed, however. A page that once existed mainly to win a visit may now need to make a concise fact retrievable and lead the interested reader into a deeper decision path.

    Build connected content in four layers:

    • Answer layer: state the direct answer early, define the relevant entity or concept, and make the scope and limitations explicit. Remove introductory padding that separates the question from the fact.
    • Decision layer: explain who the offer is and is not for, which prerequisites apply, what alternatives exist, and how important tradeoffs change the choice. Organize comparisons around buyer requirements rather than a generic feature count.
    • Evidence layer: support consequential claims with specifications, implementation documentation, policies, customer evidence, and clearly described examples. Keep facts consistent across product, support, sales, and corporate pages.
    • Action layer: give a qualified visitor the next information or action needed to proceed, such as configuration details, availability, a relevant product destination, or a way to discuss fit.

    Connect these layers with descriptive internal links. An informational answer about a requirement should lead to the decision page where a buyer can evaluate it, and that decision page should point to the underlying proof. This creates a path for both a human visitor and a retrieval system without forcing one page to serve every intent.

    Use JSON-LD as machine-readable clarification of the same entities, properties, and relationships that people can verify on the page. Keep names, identifiers, product attributes, and organizational relationships consistent with the visible content. Structured data is not a separate claim channel, and it is not a shortcut to recommendation status.

    Content also cannot manufacture product truth. If a buyer requires a native integration, better documentation for a workaround can reduce uncertainty but cannot make the workaround equivalent. If repeated support problems, a failure-prone component, or a missing capability drives exclusion, the recommendation problem exists beyond SEO’s jurisdiction. The honest content response is to describe the current fit accurately while the responsible team evaluates the underlying issue.

    Use a measurement stack that survives zero-click search

    A glass measurement console collects light signals from search, an AI assistant, a website, and product-selection objects.

    Traffic remains important, but it is no longer a complete proxy for visibility or influence. Results pages with an AI Overview produced 36 organic clicks per 1,000 impressions, compared with 87 without one, across the matched keyword set. The visitors who still clicked spent 3 minutes 18 seconds per session rather than 2 minutes 41 seconds, viewed 2.9 pages rather than 2.3, and converted to leads at 2.6% rather than 1.7%.

    The higher visitor-to-lead rate did not erase the traffic loss. Estimated lead volume was still roughly 37% lower. That is why a dashboard showing only a rising conversion rate can create false comfort, while a dashboard showing only declining sessions can miss an improvement in visitor quality.

    Build reporting in layers and preserve the numerator and denominator for every rate:

    • Demand: tracked queries and buyer scenarios, impressions, ranking distribution, intent, and AI Overview coverage.
    • Answer visibility: brand mention rate and citation rate across the scenarios where the brand is eligible to appear.
    • Decision visibility: consideration rate, recommendation rate, competitor inclusion, and the reasons attached to each outcome.
    • Traffic: organic clicks and CTR, observed assistant referrals, landing pages, and channel-specific journeys.
    • Visit quality: meaningful engagement, progression to decision content, visitor-to-lead rate, and qualified actions.
    • Business outcomes: total leads, qualified opportunities, pipeline contribution, completed transactions, and value where your measurement system can support those links.
    • Remediation: recurring exclusion reasons, evidence strength, responsible owner, action status, and whether the issue changed after the underlying fix.

    Define the rates plainly. Mention rate is the share of evaluated outputs in which the brand appears. Citation rate is the share that links or attributes supporting information to the brand. Recommendation rate is the share of eligible buying scenarios in which the offer is advised as an appropriate choice. A single visibility score can conceal a brand that is frequently mentioned but almost never recommended, so retain the component measures.

    Keep a stable scenario bank for trend measurement. Store the exact prompt, platform, available model identifier, market and language context, capture date, response, citations, competitors, and stated rationale. Evaluate the same core scenarios on a consistent cadence, while maintaining a separate exploratory set for emerging buyer questions. This lets you distinguish a durable pattern from normal output variation.

    Label the surfaces correctly in analytics. AI Overview exposure is not assistant referral traffic. An organic click from a results page containing an AI answer is still an organic visit. A direct visit from an assistant is an observed AI referral. A recommendation that leads to a later branded search may have no attributable AI referrer. Report what you can observe without presenting untracked influence as measured conversion.

    Turn visibility findings into cross-functional action

    SEO and web teams still own a large part of the execution surface, including accessibility, site architecture, internal linking, content retrieval, structured data, and analytics. Recommendation failures expand the work because the deciding factor may be a product capability, design choice, support experience, or policy that search specialists cannot change.

    Route each failure to the team that controls reality

    • SEO and development: resolve access, rendering, discoverability, canonicalization, page architecture, internal linking, and machine-readable clarity.
    • Content and subject-matter experts: document applications, requirements, specifications, limitations, tradeoffs, and substantiated proof in language buyers use.
    • Product and engineering: evaluate missing capabilities, integrations, materials, reliability issues, and design choices that repeatedly make the offer a weaker fit.
    • Support and customer success: investigate recurring implementation friction, service complaints, repair delays, and gaps between documented and actual customer experience.
    • Reputation and communications: understand credible third-party narratives, correct factual inaccuracies with evidence, and avoid trying to suppress valid criticism.
    • Analytics and revenue teams: connect visibility patterns to qualified demand and business outcomes without overstating attribution.

    Use one operating loop for SEO and non-SEO fixes

    1. Choose a commercially important buyer scenario in which your offer is genuinely eligible.
    2. Capture the response, cited evidence, competitors, and explicit or implied reason your brand was included or excluded.
    3. Verify the reason against your website, product documentation, customer evidence, support reality, and third-party information.
    4. Classify the gap as retrieval, evidence, fit, trust, or measurement noise, then assign it to the team with authority to change it.
    5. Make the underlying change and document the new reality consistently wherever buyers and systems would expect to find it.
    6. Re-evaluate the same scenario and watch both the visibility measure and the business outcome it was meant to improve.

    Prioritize scenarios by commercial importance, frequency, strength of the exclusion evidence, and the organization’s ability to act. A repeated loss in a central use case deserves more attention than an isolated omission from a broad prompt. A real product disadvantage deserves an honest product decision, not a content campaign designed to obscure it.

    Start with the highest-value scenario where your brand is understood but not recommended. Trace the exclusion to its evidence, assign the owner, and decide whether the remedy is clearer retrieval, stronger proof, a service correction, or a product change. Solving that case gives you a repeatable operating pattern for the rest of AI search instead of another visibility score with no path to action.

    References


  • How to Optimize for Claude and Claude Code as Answer Engines

    How to Optimize for Claude and Claude Code as Answer Engines

    If your brand performs well in Claude, do not assume Claude Code will carry that visibility into a developer’s workflow. The shared Claude name is a product-family label, not a reliable unit of measurement for answer-engine optimization.

    You need to answer two separate questions: can Claude explain or recommend your brand in a conversational response, and can Claude Code find useful information about it while helping someone complete technical work? That distinction changes your prompt research, content priorities, structured data, and reporting.

    Why one Claude visibility score can hide the real problem

    Across 24,135 observed responses and related agent traffic, Claude and Claude Code searched at different rates, mentioned different brands, and visited different kinds of webpages. That is enough divergence to treat them as separate answer-engine surfaces rather than two interfaces feeding one interchangeable visibility score.

    The finding is observational. It does not prove that every prompt will produce different behavior, that one type of page always wins, or that a particular optimization guarantees inclusion. It does show why an aggregate Claude metric can mislead you: improvement on one surface can conceal a decline or persistent gap on the other.

    Separate three layers when you evaluate performance:

    • Retrieval behavior: Did the surface search or otherwise fetch current web information during the run?
    • Answer selection: Which brands, products, libraries, or approaches appeared in the response?
    • Page use: Which pages were linked, cited, or visited, and what job did those pages perform?

    A brand mention is not automatically a citation. A citation is not automatically an agent visit. A visit is not automatically a successful recommendation. Preserve those distinctions in your data instead of compressing them into a single percentage.

    Key takeaways

    • Track Claude and Claude Code as separate answer engines, even when they address related demand.
    • Pair prompts by underlying intent rather than copying the same wording into both surfaces.
    • Give Claude clear decision and explanation pages; give Claude Code implementation-ready technical material.
    • Measure searches, mentions, citations, visits, and page types separately so you know which failure you are fixing.
    • Use JSON-LD to clarify entities and page meaning, but do not treat schema as a proven ranking switch for either surface.

    Separate conversational demand from implementation demand

    A researcher explores conversational recommendations while a developer uses an AI assistant to connect documentation and software components.

    Start with the task behind the prompt. Claude often meets a person at an explanation, evaluation, or planning stage. Claude Code meets that person inside a technical workflow. The topics may overlap, but the information needed to complete the task is different.

    Do not create two unrelated keyword lists. Build paired prompt clusters around the same underlying demand:

    Underlying needClaude prompt angleClaude Code prompt angleContent required
    Understand a categoryWhat the category does, who needs it, and where it fitsHow the category maps to a stack, workflow, or architectureCategory explainer linked to technical documentation
    Choose an approachSelection criteria, tradeoffs, alternatives, and fitCompatibility, dependencies, constraints, and implementation costDecision page plus compatibility and integration pages
    Adopt a productCapabilities, intended audience, limitations, and evidenceInstallation, authentication, configuration, and a working exampleCanonical product page plus task-specific setup documentation
    Fix a problemLikely causes and a diagnostic pathError-specific checks, commands, configuration changes, and expected outputTroubleshooting pages with stable headings and explicit error states
    Compare optionsMeaningful differences and situations where each option fitsVersion support, migration implications, API differences, and operational constraintsEvidence-based comparison connected to migration and reference material

    For example, a conversational template might ask: Which [category] fits a [type of team] that needs [outcome], and what are the tradeoffs? Its Claude Code counterpart might ask: I need to add [capability] to [stack] under [constraint]. Which [tool or library] fits, and how should it be configured?

    Those prompts express related demand without pretending the two environments are identical. Keep the audience, desired outcome, and major constraint aligned across each pair. That gives you a defensible comparison when one surface mentions your brand and the other does not.

    Build content that can finish each kind of task

    You do not need doorway pages that merely insert Claude or Claude Code into a heading. You need pages that resolve the jobs represented by your paired prompts. The strongest content architecture connects decision material to implementation material so an answer engine can move from what your product is to how someone uses it.

    For Claude, make the decision legible

    A conversational answer needs a concise, extractable explanation before it needs a long brand narrative. Put the core answer near the top of the relevant page, then support it with the criteria a person would use to make a decision.

    • State what the product, service, or concept is in direct language.
    • Name the intended user and the problem it addresses.
    • Explain where it fits and where it does not fit.
    • Describe material tradeoffs instead of declaring the option best for everyone.
    • Connect important claims to visible evidence on the page.
    • Keep product names, company names, and category language consistent across canonical pages.
    • Show when time-sensitive material was last reviewed or changed.

    If a page makes readers scroll through positioning language before revealing what the product does, the problem is not merely tone. The page has failed to expose a usable answer unit. Rewrite the opening so the entity, audience, function, and differentiator can be understood without reconstructing them from several sections.

    For Claude Code, make the implementation executable

    Technical content must survive contact with a real implementation. A conceptual feature description is not a substitute for the details needed to install, configure, test, or debug something.

    • Declare prerequisites and version scope beside the instructions they qualify.
    • Provide a minimal working example before presenting advanced variations.
    • Show package names, imports, configuration keys, and required environment inputs exactly.
    • Explain authentication without exposing real secrets or encouraging unsafe credential handling.
    • Show the expected result so the user can tell whether the step worked.
    • Document common failure states with the relevant error text, likely cause, and corrective action.
    • Link conceptual product claims to the canonical API, integration, migration, and troubleshooting pages that substantiate them.
    • Remove or clearly label obsolete instructions instead of leaving contradictory versions discoverable.

    A snippet should agree with the prose around it. If the command uses one package name while the explanation names another, or the example requires an unstated dependency, the page is not implementation-ready. Test documentation as a sequence: prerequisites, setup, execution, expected output, failure recovery, and next step.

    Use JSON-LD as a shared entity layer

    Structured data can make the relationship among your organization, software, documentation, authorship, and canonical URLs clearer. It should describe what a visitor can verify on the page; it should not introduce unsupported versions, reviews, features, or relationships that are absent from the visible content.

    • Use Organization markup for the organization entity and connect only genuine official profiles through sameAs.
    • Use SoftwareApplication when the page actually describes a software application, including applicable details such as application category, operating system, or software version when those facts are visible.
    • Use TechArticle for genuine technical documentation and keep its headline, author, modification date, and canonical relationship consistent with the page.
    • Use BreadcrumbList to represent the visible documentation hierarchy when breadcrumbs are present.
    • Give the same entity a stable name and canonical URL across relevant markup instead of generating isolated identities on every page.

    Validate the markup, but keep your claim modest: valid schema removes ambiguity; it does not prove that Claude or Claude Code will retrieve, cite, or rank the page. If visibility changes after several content and schema edits, do not assign causation to JSON-LD without a test that isolates it.

    Measure each surface with a repeatable visibility test

    Two parallel testing chambers process identical blank prompt tiles and produce conversational and technical outputs.

    A useful test must tell you what happened, where it happened, and which content could have influenced the result. Screenshots of favorable answers are evidence of individual runs, not a measurement system.

    Set up the test

    1. Define the entities. Record the official organization, product, feature, package, and category names you expect to recognize in an answer.
    2. Create paired prompt clusters. Cover explanation, selection, implementation, troubleshooting, comparison, and branded validation where those tasks apply to your business.
    3. Label every run by surface. Claude and Claude Code must occupy separate fields, views, and trend lines.
    4. Freeze the important variables. Save the exact prompt, date, account or workspace context that may matter, and any visible search or tool state. Do not quietly rewrite a prompt and treat it as the same test.
    5. Repeat on a fixed cadence. Generative responses can vary, so compare repeated runs rather than promoting one favorable output into a benchmark.
    6. Capture the whole response. Record brands mentioned, links shown, claims made, apparent search activity, and the position and context of each mention.
    7. Classify destination pages. Use a stable taxonomy such as homepage, product page, comparison, editorial content, documentation, API reference, repository, community page, or troubleshooting page.
    8. Corroborate with traffic data where possible. If agent traffic can be identified reliably in your logs or analytics, connect it to the page and time window. Do not relabel ordinary direct traffic as Claude traffic without evidence.

    Keep the metrics interpretable

    • Search activation rate: runs with visible search or retrieval activity divided by all comparable runs.
    • Brand mention rate: runs naming the target brand divided by all comparable runs.
    • Linked citation rate: runs linking to a brand-owned page divided by all comparable runs.
    • Third-party citation rate: runs that substantiate a brand mention through an independent page divided by all comparable runs.
    • Owned-page visit rate: identifiable agent visits to owned pages divided by the relevant tracked runs, when that connection can be made responsibly.
    • Page-type distribution: the share of observed citations or visits going to each page class.
    • Task coverage: prompt intents for which the brand receives an accurate, useful mention divided by the tested prompt intents.
    • Cross-surface overlap: brands appearing on both surfaces compared with all brands appearing on either surface.

    Do not average these into an opaque score before examining them separately. A brand can have a high mention rate and a low citation rate. Claude Code can visit documentation while Claude cites a category explainer. Those are different states requiring different work.

    Turn patterns into a diagnosis queue

    Observed patternReasonable hypothesis to investigateNext action
    Strong in Claude, weak in Claude CodeThe brand is understandable at the category level but lacks accessible implementation evidence, or the coding surface forms a different candidate set.Audit setup, compatibility, API, migration, and troubleshooting pages against the failed Claude Code prompts.
    Strong in Claude Code, weak in ClaudeThe technical material is useful, but the category, audience, or decision context is unclear.Create or improve an answer-first product or category page and connect it directly to the technical documentation.
    Mentioned without a linkThe brand is known in the response context, but the run does not demonstrate referral to a current page.Track it as a mention, not a citation or visit, and strengthen canonical pages that verify the claims being made.
    Search occurs, but competitors receive the citationsCompeting pages may match the task or provide more readily usable evidence.Compare page intent, claim clarity, technical completeness, and destination type; fill the specific information gap rather than copying wording.
    Documentation is visited, but the brand is not recommendedThe page may resolve a narrow technical step without establishing product fit.Improve links and language connecting the documented task to the relevant capability and canonical product entity.
    No visible search occursThe surface may be answering from existing context, so current-page retrieval cannot be confirmed for that run.Report zero-search runs separately and test natural variations of the same intent before diagnosing a page-level retrieval failure.

    Each row is a hypothesis, not a verdict. Check the actual response, destination page, and traffic evidence before deciding what caused the pattern. This keeps you from rebuilding documentation to solve a category-positioning problem, or rewriting a commercial page when the missing asset is a version-specific integration guide.

    Begin with the small set of tasks closest to adoption or implementation. Establish separate baselines for Claude and Claude Code, fix the clearest page-type gap, and rerun the same paired prompts. Once you can name the surface, task, metric, and page that changed, you have an answer-engine optimization program instead of a collection of Claude screenshots.

    References


  • Brand-Led SEO: How to Earn Visibility in AI Search

    Brand-Led SEO: How to Earn Visibility in AI Search

    Your site can have technically sound pages and still disappear when a buyer asks an AI assistant which provider fits their problem. If your first response is to publish more keyword-targeted landing pages, pause. You may be trying to fix a brand-evidence problem with page volume.

    Brand-led SEO gives every part of your search program the same job: help people and machines identify who you are, when you are relevant, and why your claims deserve consideration. You still optimize individual URLs. The difference is that those URLs now reinforce a coherent, verifiable brand rather than competing as isolated assets.

    AI search adds a brand-level decision above page ranking

    Conventional search can rank one URL against another. An AI-generated answer may instead resolve several entities, apply the user’s constraints, summarize evidence, and present a shortlist of companies. It can cite several pages, one page, or no visible page while still naming a brand. In other words, AI search can recommend a brand rather than merely present a winning page.

    That does not mean pages, links, crawling, or technical SEO have stopped mattering. Pages remain evidence and retrieval units. The added requirement is coherence: the system must be able to reconcile the company described on your homepage with the company represented in your structured data, product documentation, author profiles, partner listings, media coverage, and public conversations.

    LayerQuestion to auditWhat usually needs fixing
    RetrievalCan a relevant, accessible page be found for the decision?Indexability, internal links, page purpose, headings, and direct answers.
    Entity understandingDo your names, categories, offerings, audiences, and relationships agree?Canonical facts, visible copy, structured data, profiles, and contradictory descriptions.
    Recommendation confidenceDoes available evidence show that your brand fits the user’s constraints?Specific proof, honest limitations, decision content, and independent corroboration.

    Run one commercially important question through all three layers. If your company is described as a platform on one page, an agency on another, and a tool in external profiles, a new comparison page will not resolve the identity problem. If the identity is clear but none of your evidence addresses the buyer’s constraint, adding more Organization markup will not establish fit.

    A useful operating assumption is that search will increasingly sit beneath agentic experiences as infrastructure. The interface may change, but useful content and demonstrable trust still have to enter the system somewhere. Brand-led SEO makes those inputs deliberate.

    Write a canonical entity brief before touching JSON-LD

    A translucent prism on a drafting table connects symbolic objects to matching shapes on several blank cards.

    Most consistency problems start upstream. Different teams have quietly adopted different answers to basic questions: what category the company belongs to, which audience it serves, what the product includes, and which differentiators can actually be proved. Structured data then encodes those disagreements instead of resolving them.

    Create a short entity brief that acts as the internal source of truth. It should contain:

    • Identity: the public brand name, any legitimate name variants, the legal name when it is publicly relevant, and the canonical website.
    • Category: the most specific category you can support, plus adjacent categories that require qualification. Do not claim every category in which you want visibility.
    • Audience and jobs: who the offering is built for, the problem it addresses, and the situations in which it is or is not a fit.
    • Offerings and relationships: product and service names, which organization provides them, and how sub-brands or acquired products relate to the parent brand.
    • Availability: supported markets, languages, customer types, delivery models, or other material constraints that buyers need to know.
    • Claims and proof: each important differentiator paired with a page, document, named example, or independent reference that substantiates it.
    • Boundaries: capabilities you do not offer, conditions attached to a claim, and wording that marketing must not use without further evidence.

    Turn the brief into a one-sentence identity statement: [Brand] is a [specific category] for [defined audience] that helps with [job] through [documented mechanism]. This is not a slogan. It is a test. If product, sales, communications, support, and leadership would fill the brackets differently, machines are likely to encounter the same disagreement.

    Implement the brief in this order:

    1. Align visible pages. Check the homepage, About page, product or service pages, documentation, contact information, author pages, and any location pages. Give each page its own purpose, but keep foundational facts stable.
    2. Model the relationships in structured data. Use an appropriate Organization type with one stable @id. Connect Product or Service entities to that organization through accurate brand or provider relationships. Connect articles to their real publisher and visible authors.
    3. Use sameAs selectively. Include profiles that genuinely identify the same organization. A collection of marginal or abandoned accounts is not stronger than a small set of maintained official profiles.
    4. Reconcile external profiles. Update partner directories, professional listings, social profiles, marketplace pages, and other records you control so their category and naming match the brief.
    5. Log contradictions you cannot edit. Record the incorrect statement, its location, the correct evidence, the owner who can request a change, and the status of that request.

    JSON-LD is an identity aid, not a reputation generator. It can clarify that a product belongs to an organization or that two references describe the same entity. It cannot make an unsupported superlative true, convert an aspirational category into an established one, or compensate for visible copy that says something else. Mark up what a reader can verify on the page, and reuse the same entity relationships across the site.

    Build evidence for decisions, not a larger pile of keywords

    A keyword list usually captures phrasing. An AI recommendation request also carries context: the buyer’s role, use case, budget model, location, integration requirement, risk tolerance, or implementation constraint. Brand-led content has to answer the decision, not merely repeat the category term.

    Start with the real question families around one offering:

    • Category discovery: What kinds of solutions address this problem?
    • Audience fit: Which option is appropriate for a particular role, company type, or level of complexity?
    • Constraint fit: Which options work with a required platform, process, geography, or operating condition?
    • Comparison: How do two approaches or providers differ on criteria that affect the decision?
    • Risk and validation: What are the limitations, dependencies, security considerations, or proof points?
    • Implementation: What does adoption, migration, integration, or ongoing use require?

    Assign every important question to a page with a clear evidence job. A category explainer should define the choices and their tradeoffs. A use-case page should establish audience fit. Documentation should verify how a capability works. A comparison page should expose its criteria and acknowledge where another approach fits better. A case study should identify the customer context, the action taken, and only the outcomes you can substantiate.

    Give each decision page four components:

    1. A scoped answer. State who or what the page is for in the opening paragraphs. Avoid an unqualified claim that your brand is best.
    2. Evaluation criteria. Name the factors a reasonable buyer should use and explain why they change the choice.
    3. Claim-level evidence. Link capabilities to documentation, customer outcomes to credible case material, and policies to the controlling policy page.
    4. A boundary and next step. Say when the advice does not apply, then direct the reader to the next useful verification or action.

    Replace slogans with extractable statements. One platform for every business gives a recommendation system little usable context. [Brand] serves [audience] that needs [job], supports [verified capabilities], and requires [material condition] is easier to evaluate because each part can be checked.

    Do not split content and technical work into separate definitions of success. Technical excellence cannot rescue content that misses the user’s intent, while useful content can struggle without a trustworthy technical foundation. For every priority page, review the answer and its retrieval conditions in the same ticket: indexability, canonical handling, internal links, visible authorship, supporting entities, freshness-sensitive claims, and the path to primary evidence.

    Earn corroboration that explains the brand, not just links to it

    Several independent evidence stations cast beams of light onto an unbranded ceramic vessel on a central pedestal.

    A claim on your own domain is still a self-authored claim. Independent descriptions play a different role: they can confirm that the organization exists in a category, has a real relationship, serves a recognizable audience, or is known for a particular body of work. This is why brand consistency and earned mentions deserve attention alongside conventional backlink acquisition.

    Do not turn that observation into a universal formula about how every AI system weights links and mentions. These systems differ, and their recommendation processes are not exposed as one stable ranking algorithm. The practical lesson is narrower: a descriptive mention can carry entity and reputation context that a bare link does not, while a relevant linked mention may contribute both context and discoverability.

    Build an external evidence map around the claims that matter to purchase decisions. Use columns for the claim, owned proof, independent corroboration, conflicting descriptions, the external party involved, and the next legitimate action. Then work the gaps:

    • Ask real partners to describe the relationship accurately on integration or partner pages. Do not imply a partnership that is merely technical compatibility.
    • Give journalists, analysts, event organizers, and podcast hosts a concise fact sheet with the correct company name, category, audience, executive names, and supporting URLs. Let them retain editorial control over their wording.
    • Help customers document outcomes only when they consent and the underlying facts can be verified. Preserve the conditions around any result.
    • Correct outdated categories and descriptions at their original locations. Repeating the right wording on your own site does not remove the contradictory record.
    • Contribute useful explanations to professional communities under identifiable authorship. Publishing what you are learning and participating in the community creates a public record of expertise, but it should serve people first rather than imitate an algorithmic signal campaign.

    Relevance is more valuable than mention volume. A detailed description in a context your buyers trust does more reputational work than a generic placement that happens to include optimized anchor text. The editorial brief should therefore focus on accurate facts and genuinely useful expertise, not a demanded phrase or link configuration.

    This is where SEO, digital PR, content, product marketing, and reputation management have to share a record. If each team promotes a different category or proof point, more activity produces more ambiguity. The entity brief supplies the shared language; the evidence map shows where independent confirmation is still missing.

    Measure recommendation readiness with a fixed prompt scorecard

    Do not reduce the program to the question, Do we rank in AI? Generated responses can vary by product, model, mode, account context, location, and wording. A single answer is an observation, not a durable position. You need a repeatable scorecard that separates brand presence from brand accuracy and recommendation fit.

    Create a small, fixed portfolio of natural questions drawn from the decision families above. Include unbranded discovery questions, audience and constraint questions, comparisons, and branded verification questions. Keep the wording stable when establishing a baseline, and record the surface, model or mode when visible, account or location conditions that may matter, the date, and the complete answer.

    Classify each observation by what it tells you:

    • Absent where the brand is a legitimate fit: inspect retrieval, category clarity, relevant decision content, and external corroboration.
    • Present but misclassified: find conflicting category language, old profiles, duplicate entities, or weak relationships in structured data.
    • Present but described vaguely: strengthen extractable facts and connect important claims to specific evidence.
    • Accurately compared but not selected: examine whether the user’s constraint truly favors your offering. If it does, identify the missing proof. If it does not, treat the exclusion as accurate.
    • Recommended with a weak or irrelevant citation: improve the page that best substantiates the recommendation and make its relationship to the brand explicit.
    • Recommended inaccurately: treat this as a defect, not a win. Correct the underlying ambiguity before amplifying the answer.

    Track citations, but do not make them your only outcome. Also record whether the name is correct, the category is accurate, the described audience matches the offering, the stated capability is supported, material limitations appear, and the recommendation makes sense for the prompt. A brand should not want inclusion in a shortlist it cannot responsibly serve.

    Turn the findings into an owned backlog. Break the program into subprojects, tasks, deadlines, and individual work items: identity reconciliation, technical retrieval, decision content, external corroboration, and measurement. Give every item an owner, the evidence of the problem, the proposed correction, and a condition for verification. Retest the same prompt set after material changes have had a chance to appear in the environments you are observing.

    Key takeaways

    • AI visibility requires both retrievable pages and a brand identity that can be reconciled across owned and external records.
    • A canonical entity brief should define your name, category, audience, offerings, claims, proof, and boundaries before those facts enter JSON-LD.
    • Content should answer buyer decisions and constraints, with each important claim connected to evidence and an honest scope.
    • Earned mentions matter when they accurately explain the brand in a relevant context; they should not be treated as a volume substitute for link building.
    • Measure presence, accuracy, fit, evidence, and citations separately. An inaccurate recommendation is not successful visibility.

    Start with one high-value customer question. Write the canonical answer about your brand, inspect the page that should support it, compare your structured data and external descriptions, and log the first contradiction or evidence gap you find. Assign that gap as a concrete task. Repeating that cycle will build a brand record that your SEO, content, and communications work can strengthen instead of fragment.

    References


  • Vertical AI Search Agency Rankings: How to Choose in 2026

    Vertical AI Search Agency Rankings: How to Choose in 2026

    If you’re using a “best AI search agencies” list to choose a partner, the highest score is not automatically the safest choice. You need the agency that can change the specific event your business depends on: a patient finding the right clinic, a traveler completing a direct booking, or a property owner requesting a qualified estimate.

    Vertical rankings can give you a workable shortlist. The important part comes next: checking whether the ranking criteria match your outcome, whether the agency’s evidence survives scrutiny, and whether its delivery model fits the way your organization actually operates.

    The 2026 shortlist changes with the vertical

    There is no meaningful universal ranking for AI search agencies. Hospitality needs machine-readable property and booking information. Cardiology needs clinically governed authority and patient acquisition. Construction may depend on local service coverage, commercial specialization, or both. Those differences change which capabilities deserve the most weight.

    VerticalPublished top threeWhat separates the options
    Hotels and hospitality1. First Page Sage; 2. Genevate; 3. MilestoneFull-service agentic search strategy, boutique-property brand accuracy, and multi-property data infrastructure are three different operating models.
    Cardiology1. First Page Sage; 2. Focus Digital; 3. Driven MetricsClinical authority and lead generation, budget-conscious multichannel work, and analytics-led reporting solve different practice needs.
    Contractors and construction1. First Page Sage; 2. Siana Marketing; 3. Focus DigitalAuthority-building content, architecture and engineering specialization, and localized small-business lead generation are not interchangeable strengths.

    There is a material caveat. First Page Sage is both the publisher and the first-ranked agency for hospitality, cardiology, and construction. That conflict does not make every claim false, but it does change the evidentiary weight. Treat the positions as a vendor-created shortlist until you independently verify client relationships, review profiles, methodology, deliverables, and results.

    Recurring names can still be useful. First Page Sage appears as the broad, authority-led option across all three verticals. Focus Digital appears in both cardiology and construction, with a smaller-business and lead-generation orientation. Genevate and Milestone address sharply different hospitality needs. Your task is not to preserve the published order. It is to identify which operating model fits your bottleneck.

    Your vertical determines what AI search success means

    Do not let GEO, AEO, AI SEO, and ASO collapse into one vague service. GEO generally concerns how a brand is understood, cited, and recommended in generative answers. AEO focuses on becoming a usable answer. In this context, agentic search optimization extends the job from answering to acting: an agent must be able to discover an option, evaluate it, and continue toward a transaction.

    Make every proposal spell out the acronym and the intended result. “Improve AI visibility” is not an adequate scope. “Increase accurate recommendations for these decision-stage prompts and make the resulting booking or inquiry path usable” is much closer.

    Hospitality: the agent must be able to complete the journey

    A hotel can be described accurately and still lose the booking. The agent may need to identify amenities, location, room constraints, rates, availability, cancellation terms, and a working reservation path. If those details disagree across the hotel’s website and third-party listings, the agent has a comparison problem. If the booking interface is inaccessible to the agent, it has an action problem.

    First Page Sage reports that, across 2,417 agentic commands, including 343 travel-booking commands, agents switched to a competitor in 46.2% of failed attempts when a conversion page was not machine-actionable. Treat that percentage as vendor-supplied rather than an industry benchmark. It still identifies the correct failure mode to test in your own funnel: successful discovery does not matter if the agent cannot proceed.

    Ask a hospitality finalist to demonstrate four things with one representative property:

    • Where the agent obtains the canonical property description, amenity list, policies, rates, and availability.
    • How the agency detects discrepancies among the hotel website, listings, and other sources an assistant may consult.
    • What “machine-actionable” means for your reservation system, including which steps can and cannot be completed.
    • How it distinguishes increased AI mentions from completed direct bookings and revenue.

    Choose brand-accuracy work first when an independent property is repeatedly misdescribed. Choose scalable property-data infrastructure when a group cannot keep information consistent across many locations. Choose a full-service agentic program when the data is broadly correct but discovery, recommendation, and booking still break across the journey.

    Cardiology: visibility is subordinate to clinical accuracy

    A cardiology program has to earn relevant recommendations without overstating what a physician or practice can treat. Service descriptions, subspecialties, locations, insurance information, referral requirements, and patient-facing explanations all influence whether an AI answer is accurate enough to be useful.

    Clinical governance should therefore be a gate condition, not a bonus point. Require a named medical reviewer, a documented approval path, and a correction process for inaccurate AI representations. An agency that increases mentions while introducing unsupported clinical claims has not delivered a successful outcome. Do not publish medical content solely on an agency’s approval; the safe alternative is review by a qualified clinician who understands the practice and the claim being made.

    Measurement also needs to reach beyond citation counts. Decide whether success means an appropriate appointment request, a call about a relevant service, a physician referral, or another defined patient-acquisition event. Then make the agency show how it will connect recommendation monitoring to that event without treating every inquiry as qualified.

    Construction: local demand and AEC authority require different programs

    A residential HVAC contractor, a commercial general contractor, and an architecture or engineering firm may all sit under “construction,” but their AI-search journeys are different. The local service business needs accurate service areas, relevant service pages, local trust signals, and a call or form that produces a usable lead. The commercial firm may need evidence of project type, technical expertise, geographic capacity, procurement fit, and authority across a longer buying process.

    This is where a narrow specialist can beat a higher-ranked generalist. Siana Marketing’s focus on architecture, engineering, construction, and home services may matter more to an AEC firm than a broad score. Focus Digital’s localized model for smaller construction businesses may make more sense for a contractor competing market by market.

    Before comparing proposals, define a qualified lead in writing. Include the service, service area, customer or project type, and any minimum conditions your sales team uses. Otherwise, an agency can report more AI-originated inquiries while your team receives requests outside its territory or capabilities.

    Read every score as a set of assumptions

    A composite score looks objective because it ends in a number. The judgment entered much earlier: somebody chose the criteria, assigned their weights, decided what counted as evidence, and converted imperfect public information into ratings.

    CriterionHospitality modelCardiology modelConstruction model
    Headline AI performanceASO expertise: 25%AI recommendation: 25%AI visibility: 25%
    Separate GEO expertiseNot scored separatelyNot scored separately20%
    Leadership experience20%20%20%
    Average reviews20%20%15%
    Relevant clients15%15%10%
    Year established10%10%10%
    Media references10%10%Not scored

    All three models give the headline AI criterion 25% and leadership experience 20%. The construction model then assigns another 20% to GEO expertise, while hospitality and cardiology use 10% for media references. That difference alone can reorder agencies. A firm with a large publishing footprint may benefit in the first two models; a firm with detailed GEO methodology may benefit more in construction.

    Neither choice is universally correct. Media references can indicate authority and visibility, but they do not prove that an agency changed recommendations for a client. A long operating history can indicate institutional depth, but it does not prove that a legacy SEO team has a mature AI-search workflow. High review averages can reflect good client service without isolating GEO performance.

    Rebuild the evaluation around your decision instead of accepting inherited weights:

    1. Write the target AI event in one sentence. Name the audience, decision, location if relevant, and desired business action.
    2. Mark each published criterion as a must-have, useful context, or irrelevant to that event.
    3. Ask for the evidence underneath every score that could change your decision. Do not compare unlabeled composite numbers.
    4. Give all finalists the same scenario and evidence request so you are comparing like with like.
    5. Record missing information as unknown. Do not quietly convert it into a favorable assumption.

    You may discover that a lower-ranked agency wins because the original model rewarded factors your organization does not need. That is not a problem with your selection process. It is the point of having one.

    Demand an evidence chain, not an AI visibility screenshot

    Analysts inspect a chain of source cards and business outcome models while an isolated glowing screen tile sits to one side.

    A single screenshot proves that one answer appeared once. It does not tell you whether the result repeats, whether the model cited reliable information, whether the user was in your market, or whether the recommendation produced a business outcome.

    Ask each finalist to walk one real prompt through this evidence chain:

    1. Observation: What did ChatGPT, Claude, Gemini, Grok, or another in-scope system answer before the work began? Which prompt, account state, location, and date were recorded?
    2. Diagnosis: Why was your brand absent, inaccurate, poorly positioned, or impossible to act on? The explanation should identify an information, authority, relevance, reputation, technical, or conversion-path problem.
    3. Intervention: What exactly changed? Examples include correcting business information, restructuring service content, improving entity clarity, adding structured data, strengthening third-party corroboration, or repairing a booking or inquiry path.
    4. AI outcome: Did the brand become accurately represented, cited, compared, or recommended across a repeatable prompt set? A change should not depend on one cherry-picked answer.
    5. Business outcome: Did the program contribute to qualified appointments, direct bookings, calls, forms, opportunities, or revenue? The agency should state where attribution is direct, modeled, or unknown.

    Model outputs can vary by prompt wording, location, context, and model version. No agency controls a frontier model’s answer. A credible team will define how it samples and records that variation instead of guaranteeing a permanent position.

    Questions that expose a shallow GEO offer

    • Which prompts are in scope? Ask to see informational, comparative, and decision-stage prompts rather than a list of broad keywords.
    • Which platforms and markets are measured? The answer should match where your customers research, not whichever system produces the best screenshot.
    • How is repeatability handled? Ask how prompts, dates, locations, outputs, citations, and model versions are preserved.
    • What will you change? Monitoring without a correction and publishing workflow is a reporting product, not a complete optimization service.
    • Who owns subject-matter approval? This is essential for cardiology and still important for hotel policies, contractor capabilities, pricing, and service territories.
    • How are AI-originated conversions identified? Ask what can be observed directly, what depends on self-reported attribution, and what cannot be attributed confidently.
    • Can you show relevant client evidence? A recognizable logo is less useful than a reference matching your vertical, size, buying journey, and operating complexity.
    • What remains yours when the engagement ends? Confirm ownership and access for prompt libraries, dashboards, audits, content, structured-data recommendations, account history, and exported records.

    The delivery model deserves the same scrutiny as the strategy. Hospitality illustrates the difference clearly: Milestone is positioned around structured property data, monitoring, and content management across many properties, while Genevate is positioned around brand accuracy and reputation for independent and boutique hotels. One is closer to scalable infrastructure; the other is closer to hands-on brand interpretation. Ask whether you are buying software, advisory support, implementation, or a hybrid, and identify who is responsible for acting on every finding.

    Make the contract reflect the outcome you are buying

    A blank contract is physically connected by brass components to models representing a clinic visit, a hotel stay, and a home estimate.

    A ranking can help you decide who gets a sales call. The contract determines what happens after it. Before committing to a broad rollout, use a representative diagnostic or milestone-gated pilot and require the following in writing:

    • Scope: Named platforms, markets, properties, practices, service lines, or service areas. “Major AI engines” is too vague.
    • Baseline: The prompt set, current outputs, factual errors, citation patterns, technical limitations, and conversion-path failures present at the start.
    • Deliverables: Separate monitoring, analysis, content, structured data, reputation work, technical implementation, and conversion work. Do not assume one includes another.
    • Approval and risk ownership: Identify who verifies medical statements, rates, availability, policies, project capabilities, credentials, and service coverage before publication.
    • Measurement: Define accurate representation, citation, recommendation, agent completion, qualified conversion, and revenue attribution separately.
    • Access and ownership: Specify who owns accounts, dashboards, prompt history, content, code, data, and exports. Without this clause, changing agencies can mean losing the record needed to evaluate progress.
    • Decision points: State what evidence permits expansion, revision, or cancellation. Do not roll an unproven workflow across every location merely because the agency ranked well.

    Walk away from guarantees of permanent rankings, unexplained proprietary scores, screenshots without preserved prompts, or case examples that never connect AI exposure to a relevant business event. Also be cautious when a proposal spends heavily on monitoring but leaves correction, publishing, technical implementation, and conversion work with an internal team that has no capacity to perform them.

    The opposite mismatch is expensive too. A hotel group may not need a strategy-heavy retainer if its immediate problem is property-data consistency at scale. A cardiology practice should not select a low-touch platform if nobody owns clinical review. A local contractor does not need a national thought-leadership program when inaccurate service areas and weak conversion pages are blocking nearby demand.

    Key takeaways

    • There is no universal best AI search agency. The correct choice depends on whether you need accurate representation, recommendations, qualified leads, or an agent-ready transaction.
    • Use published rankings to create a shortlist, then check who owns the ranking and whether that organization benefits from the result.
    • Inspect the weighting model. A composite score can reward media presence, history, or reviews more heavily than the capability blocking your growth.
    • Require an evidence chain from prompt to diagnosis, intervention, AI outcome, and business outcome.
    • Put platforms, deliverables, approvals, measurement, data ownership, and expansion conditions in the contract before a broad rollout.

    Before your next agency call, write your desired AI event at the top of a page and send the same evidence questions to each finalist. The agency that can trace a credible path from that event to a qualified outcome in your vertical deserves the next conversation. The highest unexplained score does not.

    References


  • How to Coordinate Teams for Reliable LLM Visibility

    How to Coordinate Teams for Reliable LLM Visibility

    You have been asked to improve how your brand appears in LLM answers. The request may have landed with SEO, but SEO cannot correct a product claim, approve brand language, earn independent coverage, or reconcile conflicting facts across every public surface.

    You do not need to wait for a reorganization. You need a shared definition of visibility, a reliable path for resolving contradictions, and a way for each team to act without losing sight of the same brand reality. This operating model will help you build that coordination.

    Diagnose the coordination problem before choosing tactics

    LLM visibility resembles a search problem, so the first response is often an SEO audit, a prompt-tracking dashboard, or a content plan. Those tools can reveal symptoms. They cannot settle which claims are true, which language is approved, who owns an outdated third-party description, or what another team is willing to change.

    The underlying mismatch is organizational: teams are usually managed by channel, while LLM visibility may depend on the strength and consistency of the brand’s broader digital footprint. Your website, documentation, profiles, media coverage, partner pages, community discussions, and public responses can all contribute to the environment in which the brand is understood. No channel owner controls that environment alone.

    Make a coordination diagnosis your first deliverable. Speak with the people who control the relevant facts and surfaces, then capture:

    • The outcome each team thinks it owns. Ask what success means to SEO, content, brand, product, PR, analytics, legal, support, and any other involved function.
    • The facts and public surfaces each team controls. Separate ownership of information from ownership of publication. Product may own the fact while content owns the page that expresses it.
    • The evidence each team trusts. Record the canonical product record, approved messaging, customer evidence, policy documentation, and other materials used to validate a claim.
    • The decisions that require another team. Note where work pauses for approval, clarification, technical implementation, external outreach, or risk review.
    • The contradictions already visible. Look for inconsistent names, categories, capabilities, relationships, limitations, and descriptions across public properties.

    Separate conversations are useful before a joint working session. People tend to describe their constraints more precisely before the discussion becomes a negotiation over priorities. You are not collecting complaints. You are locating the handoffs where accurate information becomes delayed, diluted, or inconsistent.

    Turn the diagnosis into a tension map

    A tension map names competing needs without treating either side as the problem. Typical examples include:

    • SEO needs a clear answer, while legal needs qualifications that prevent an overbroad claim.
    • Brand wants one stable category description, while product is still refining its market position.
    • PR needs a timely narrative, while subject-matter owners need more time to validate the supporting evidence.
    • Analytics wants a stable measurement set, while channel teams need room to test different questions and formats.
    • Content needs an approved fact, while no function has accepted responsibility for maintaining it.

    Do not force every tension into an immediate action plan. Mark the missing owner, disputed fact, approval dependency, and unresolved tradeoff. The first objective is a shared account of how the organization actually works. A polished roadmap built on conflicting assumptions will only distribute the conflict into more tasks.

    Create a visibility contract that every team can use

    Six colleagues assemble colored interlocking components into one translucent shared structure in a bright workspace.

    Teams cannot coordinate around a phrase that means something different to each of them. SEO may interpret LLM visibility as mentions for a monitored prompt set. PR may see it as authority and third-party recognition. Brand may care about how the company is described. Product may care most about factual accuracy. All are relevant, but none is a complete operating definition.

    Use a working definition such as this: LLM visibility is the accuracy, consistency, relevance, and discoverability of the organization’s representation in model-mediated answers that matter to its audiences.

    This definition prevents three common mistakes. Visibility is not reduced to a mention count. It is not treated as a website-only outcome. It is not framed as a result that one team can guarantee. The organization instead coordinates the public facts, evidence, and explanations it can responsibly improve.

    Put the agreement into a short shared brief

    The brief should be compact enough to use during real decisions. Include:

    • Priority audience situations. Describe what the person is trying to learn, compare, verify, or decide. A business situation is more durable than a disconnected list of prompt variations.
    • Entity truth. Record official names, products, relationships, categories, locations, audiences, and other facts that must remain consistent.
    • Desired representation. State what a useful, accurate answer should help the audience understand. Do not turn this into promotional copy.
    • Claim rules. Identify which claims are approved, what evidence supports them, what qualifications must travel with them, and who can approve a change.
    • Relevant surfaces. List the owned and external places where the information appears or should appear. Assign responsibility for each surface without pretending that external publishers are controllable.
    • Decision rights. Name who validates facts, approves language, chooses technical implementation, authorizes outreach, evaluates risk, and settles cross-team disputes.
    • Measurement boundaries. Specify what the team can observe, what it can influence, and what it cannot confidently attribute.

    If the group cannot agree on the brief, that disagreement is the work. Buying another tool or publishing more pages will not resolve it.

    Maintain a claim registry, not just a keyword list

    Keywords and prompts reveal demand. Claims are the units that teams must validate and keep consistent. Create a registry for the facts and propositions most likely to shape how the brand is understood. For each claim, record:

    • The canonical fact or approved wording.
    • The evidence that supports it.
    • The business owner responsible for its accuracy.
    • Required limitations, conditions, or risk language.
    • The pages, profiles, documents, and other surfaces where it appears.
    • Its current approval state and the point at which it should be reviewed again.

    Suppose a product name or capability changes. The registry lets product update the canonical fact, legal review the permitted wording, content revise the explanation, SEO update relevant pages and structured data, PR adjust future outreach, and profile owners correct managed listings. Without that record, each channel learns about the change at a different time and preserves a different version of the brand.

    Treat JSON-LD as an expression of supported, visible information, not as a place to manufacture certainty. If the page, structured data, product documentation, and public messaging disagree, adding more schema does not solve the governance failure. Confirm the fact first; then align its machine-readable and human-readable forms.

    Build a decision workflow around visibility issues

    A conflicting two-color signal moves through staffed decision stations and emerges as synchronized light paths leading to several public channels.

    Once teams share a definition and a claim registry, coordination can become concrete. Organize the work around visibility issues rather than channel campaigns. That allows you to change cross-functional working habits without waiting for reporting lines to change.

    1. Capture the audience situation. Save the exact question or decision context, the observed answer, the interface or model used, and any citations or referenced properties.
    2. Classify the gap. Decide whether the issue is absence, factual error, ambiguity, stale information, weak evidence, inconsistent terminology, or an answer that is technically correct but unhelpful.
    3. Confirm the canonical truth. Route the underlying fact to its business owner before anyone rewrites content or markup.
    4. Select interventions by surface. Determine whether the response belongs on an existing page, in documentation, in structured data, on a managed profile, in public communications, through external outreach, or across several of these places.
    5. Sequence dependent work. An approved fact may need to precede copy, schema, outreach, and profile corrections. Record those dependencies so teams do not publish incompatible versions.
    6. Validate and retain the result. Check whether the intended properties changed, record what remains unresolved, and preserve the decision for the next person who encounters the issue.

    An absence is not automatically a content gap. The brand may be described under an inconsistent name, its category may be ambiguous, the supporting claim may lack evidence, or external descriptions may conflict. Classification prevents the team from prescribing another page for every symptom.

    Use an issue brief that can travel between teams

    A useful issue brief contains the audience situation, the observed representation, the specific gap, the canonical correction, supporting evidence, affected surfaces, required approvers, accountable owner, intended success signal, and review point.

    This is different from sending legal a request to approve AI copy or asking PR to get more mentions. The brief gives every function the same problem statement and shows why its decision affects the complete representation. It also exposes unresolved truth before implementation work begins.

    Make the cross-team meeting a decision forum

    Status meetings reward reporting. Visibility coordination needs decisions. Circulate prepared issue briefs and use the shared session to answer questions such as:

    • What changed in the business that public information has not yet reflected?
    • Which brand facts or descriptions currently conflict?
    • Which claims are awaiting evidence, approval, or qualification?
    • Which managed surfaces need correction, and which external surfaces warrant outreach?
    • What did recent observations change about the team’s working hypothesis?
    • Which dispute needs escalation because no participating function owns the final decision?

    Keep responsibilities explicit:

    • SEO identifies discoverability and representation gaps, maps relevant owned pages, and recommends technical changes.
    • Content turns validated facts into clear explanations that answer real audience needs.
    • Product or subject-matter owners confirm capabilities, limitations, terminology, and relationships.
    • Brand protects coherent positioning and naming across surfaces.
    • PR and communications connect defensible claims with relevant external conversations and publications.
    • Legal or compliance defines the boundaries within which a claim may be used.
    • Analytics maintains observation methods, definitions, and reporting caveats.
    • An accountable sponsor settles tradeoffs that functional owners cannot resolve between themselves.

    Responsibility does not mean that a function executes every related task. Product can own the truth of a capability without editing the website. SEO can own discovery of a visibility issue without owning the claim. The distinction prevents work from being assigned to the most interested team instead of the team with authority to decide.

    Translate every request into the receiving team’s stakes. Brand needs to know which inconsistency is confusing the market. Legal needs the exact claim, evidence, context, and proposed qualification. Product needs to see where an outdated fact is still public. PR needs a defensible idea, not a demand for links. Internal communication becomes useful when it lets people protect their own responsibilities while contributing to the shared outcome.

    Measure representation and workflow without false certainty

    Measurement can damage coordination when a single visibility score is presented as ground truth. It encourages teams to optimize the number while disagreements about accuracy, evidence, and audience value remain hidden.

    Use a scorecard with several distinct views:

    • Information health. Track whether priority claims have owners and evidence, whether important pages and profiles agree, whether structured data reflects visible facts, and whether stale public descriptions have been identified.
    • Representation quality. Evaluate whether observed answers identify the correct entity, describe it accurately, use consistent terminology, include material qualifications, and help with the intended audience decision.
    • Workflow health. Monitor unresolved contradictions, facts awaiting validation, decisions awaiting approval, recurring rework, and issues with no accountable owner.
    • Business signals. Where data is available, examine qualified referral activity, branded demand, assisted conversion evidence, and recurring questions reported by sales or support. Keep these separate from claims of direct LLM attribution.

    Preserve the context behind every captured answer: the exact prompt, model or product, interface, date, relevant location or personalization state when known, full response, visible citations, and the reason your evaluator marked it accurate or problematic. Treat that answer as an observation, not a universal ranking position.

    Maintain a stable set of audience situations for directional monitoring, while allowing new questions to enter when the market or product changes. Stability helps you compare observations. Flexibility prevents the measurement set from becoming a museum of old priorities.

    If you use a composite AI visibility score, require a transparent methodology. The team should know what is being counted, how quality is judged, what can vary between observations, and which decisions the score is fit to support. A score that cannot answer those questions belongs in exploration, not executive certainty.

    Treat resistance as operational information

    Cross-team work changes who must approve, explain, maintain, and answer for public information. Resistance may therefore point to a real cost: additional review work, a threatened channel KPI, unclear credit, loss of autonomy, unsupported claims, or responsibility without decision authority.

    When someone pushes back, ask what risk the proposed change transfers to that function. Then document the constraint, the agreed compromise, and the owner of the remaining risk. Separate reversible experiments from lasting policy changes so a small test does not quietly become an unlimited commitment.

    Keep a decision log next to the claim registry. Record what was decided, why, who approved it, which surfaces are affected, and what would cause the decision to be revisited. This prevents every new visibility issue from reopening the same internal argument.

    Key takeaways

    • LLM visibility is a shared brand-representation problem, even when SEO is asked to lead it.
    • Diagnose conflicting assumptions, facts, incentives, and decision rights before building a tactical roadmap.
    • Coordinate around validated claims and audience situations rather than treating prompts, keywords, or channels as the whole problem.
    • Use issue briefs, a claim registry, and a decision log to make cross-team handoffs explicit and reusable.
    • Measure information health, representation quality, workflow health, and business signals separately instead of hiding them inside one score.

    Start with a concrete contradiction your teams already recognize. Confirm the canonical truth, identify every affected surface, assign the decisions to the people who have authority, and record the result. That gives you a complete coordination loop you can improve without waiting for a new org chart or perfect visibility data.

    References