Category: ChatGPT

  • Brand Visibility in ChatGPT: A Search and Retrieval Playbook

    Brand Visibility in ChatGPT: A Search and Retrieval Playbook

    Your pages rank, your brand has authority, and buyers know your name. Yet when someone asks ChatGPT which companies belong on a shortlist, you are missing. That gap is real: search visibility can help ChatGPT find you without making your brand one of the names it chooses.

    The practical fix is to identify where visibility breaks. ChatGPT must associate your brand with the right category, retrieve usable evidence, and have enough corroboration to include you confidently. Each failure requires a different response.

    Find the layer where your visibility breaks
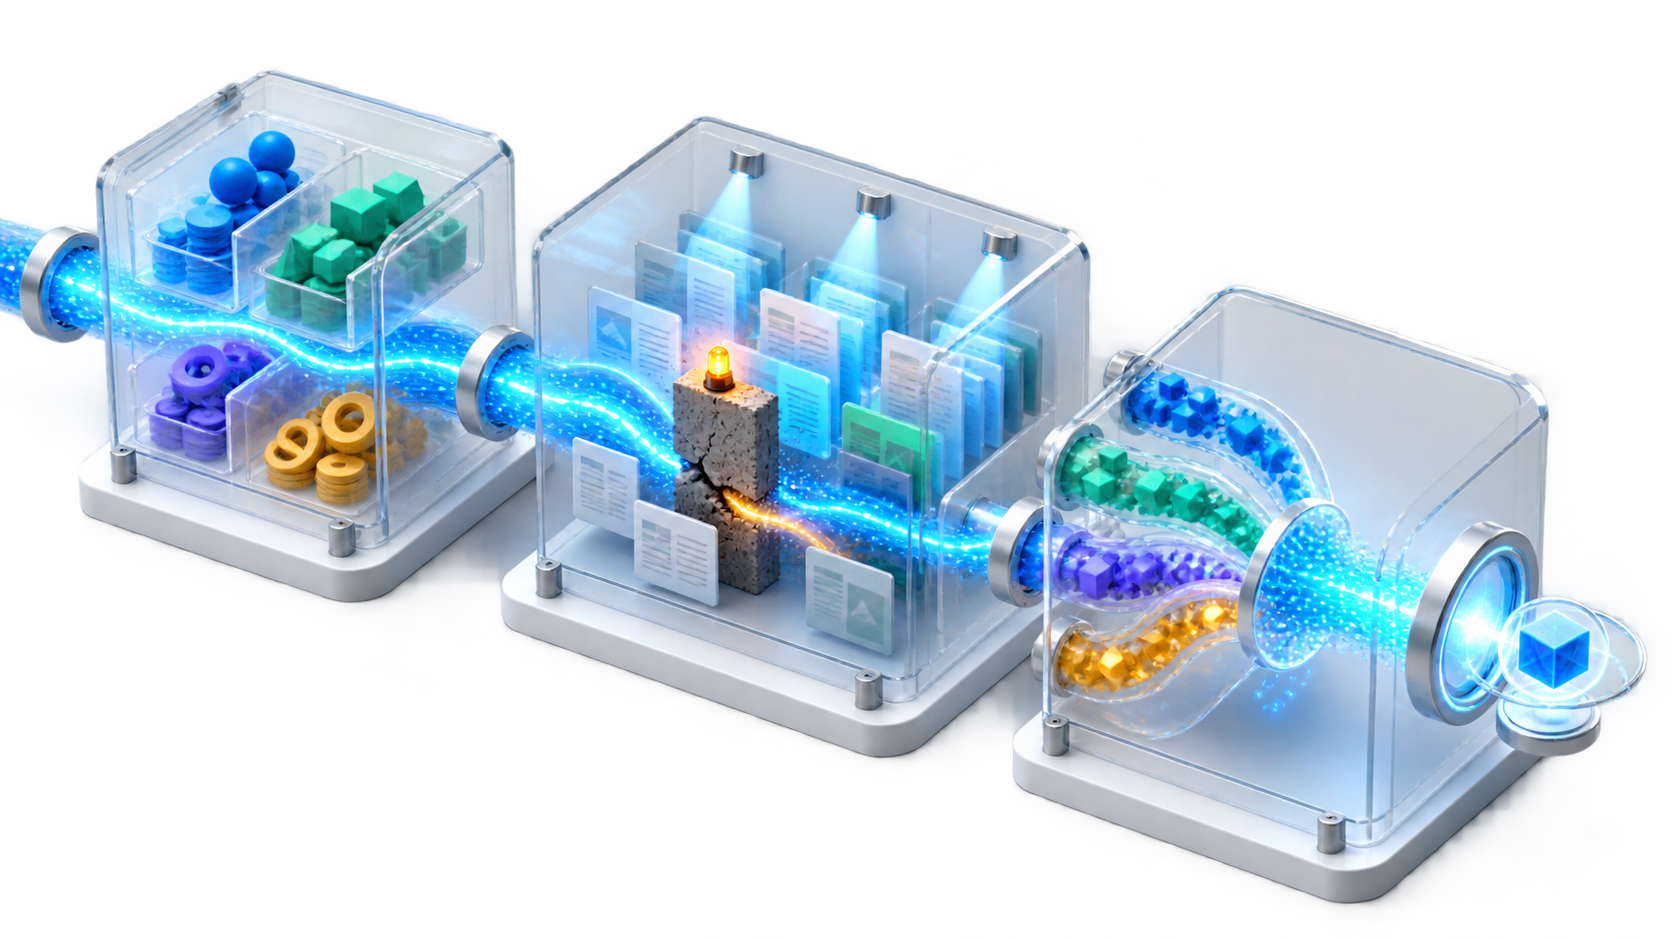
    A glowing signal travels through three transparent chambers, with an obstruction visibly blocking one stage of the pipeline.

    Brand visibility in ChatGPT is not a single ranking. It is a sequence of outcomes:

    1. Recall: ChatGPT recognizes your brand as relevant to the category or problem.
    2. Retrieval: your page, another page about you, or both enter the material available for the answer.
    3. Selection: ChatGPT uses that material to mention, describe, recommend, or cite your brand.

    A brand can pass one layer and fail the next. ChatGPT might know your name but not classify you as a provider in the requested category. It might retrieve your page but choose a competitor because that competitor is described more consistently across independent websites. It might mention you from prior model knowledge without citing your domain at all.

    Traditional SEO remains part of the foundation. In one broad brand dataset, more than nine in ten brands broadly followed the expected relationship between stronger search authority and stronger AI visibility. The important exceptions show why rankings alone are an incomplete diagnostic.

    An AI answer also creates a smaller consideration set than a search results page. A category may have hundreds of plausible providers, but ChatGPT often returns a short list of familiar names. If your brand is outside the five to ten names the model commonly recalls, more organic traffic will not automatically move you into that shortlist.

    Start your diagnosis with unbranded prompts. A branded question such as “What does Acme do?” only tests whether ChatGPT can navigate to or describe Acme. It does not test whether Acme appears when a buyer asks for the best platform for a job, industry, budget, audience, or constraint.

    Key takeaways

    • Keep the SEO foundation. Organic authority usually supports AI visibility, but it does not guarantee recall or recommendation.
    • Measure recall, retrieval, citation, and factual accuracy separately. Combining them into one score hides the problem you need to fix.
    • Make the brand-category relationship explicit on your own site and consistent across the web.
    • Build independent corroboration. Repeated third-party descriptions can matter more than another self-promotional page.
    • Test the ChatGPT product modes your audience uses. API output is not a reliable substitute for product-level retrieval.

    Make your brand-category association unmistakable

    ChatGPT cannot recommend your brand for a category it does not clearly associate with you. This is an entity-positioning problem before it is a keyword problem.

    Many brands make that association unnecessarily difficult. Their homepages lead with language such as “transforming possibilities” or “intelligent solutions” while the actual product category appears deep in a feature page. Human visitors may infer the meaning from design and context. A retrieval system assembling evidence from titles, snippets, cached text, and third-party descriptions has less room for inference.

    Write one internal positioning sentence before changing any page:

    [Brand] is a [specific category] for [specific audience] that helps with [specific job], especially when [relevant constraint or differentiator].

    This is not necessarily homepage copy. It is a control statement for checking whether your website, profiles, reviews, press coverage, comparison pages, and structured data tell the same basic story.

    1. Choose the category you need to own. Use the phrase a buyer would recognize, not an internal market label invented for differentiation.
    2. Define adjacent categories deliberately. If your product belongs in several markets, state the relationship instead of expecting ChatGPT to infer it from a feature list.
    3. Create a canonical page for each important use case. Explain who the product is for, the problem it solves, how it works, its meaningful constraints, and the evidence behind its claims.
    4. Connect supporting pages to that canonical explanation. Product documentation, customer stories, comparisons, integrations, pricing information, and help content should reinforce rather than contradict the core classification.
    5. Align identity signals. Use the same brand name, product names, company description, category language, and official URL across the properties you control.

    Structured data can support this clarity, but it should label facts already visible on the page. Organization, Product, Service, and Article markup can clarify entity relationships when they are accurate. They do not manufacture authority, repair vague positioning, or guarantee inclusion in a ChatGPT answer.

    Apply a simple editorial test: remove the logo and navigation, then read the first useful section of the page. Could an unfamiliar editor complete the sentence “[Brand] is a…” without guessing? If not, a retrieval system may face the same ambiguity.

    Comparison content can help when it reflects a genuine decision. Explain which buyer, use case, or constraint makes each option suitable. A page that declares your product the winner in every scenario supplies less credible evidence than one that states its boundaries. The goal is not to repeat a category phrase. It is to make your place in the category easy to verify.

    Build the corroboration your own website cannot provide
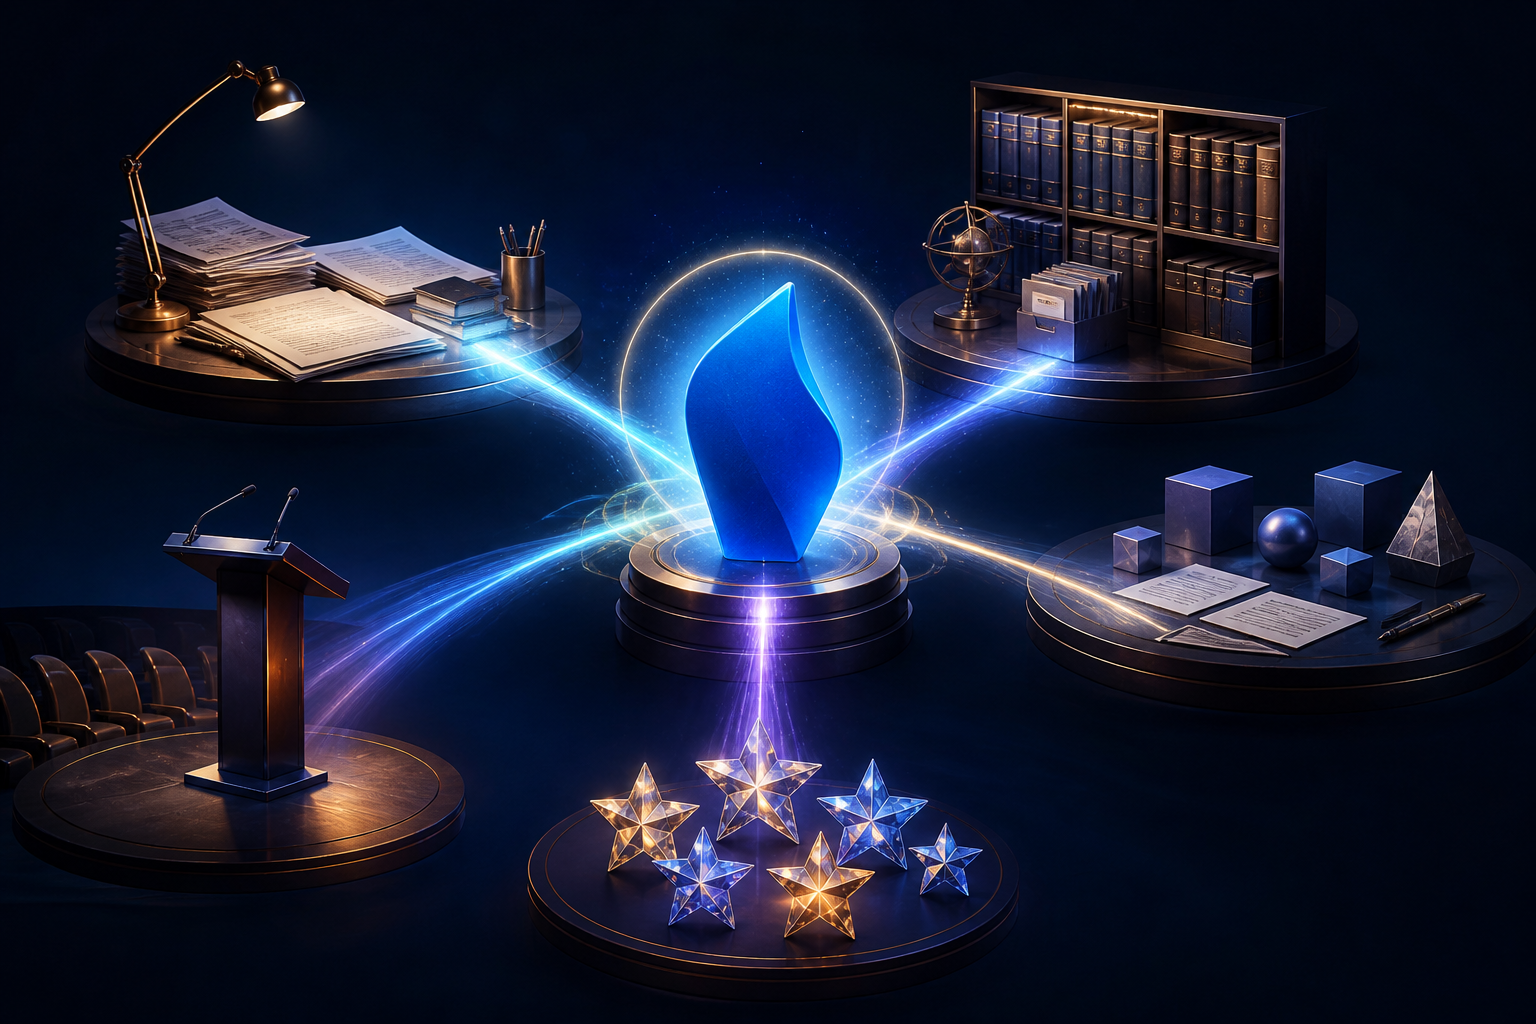
    Independent editorial, reference, comparison, conference, and review sources send beams toward a central blue brand object.

    Your website can establish what you claim. Independent coverage helps establish whether that claim is recognized elsewhere.

    The distinction explains some large visibility gaps. In one dataset, 471 brands, or about 5%, were underexposed in model answers despite strong traditional search footprints. Another 377 brands, or about 4%, appeared more often than their conventional SEO signals would predict. These figures are not universal benchmarks; they describe one analyzed prompt and brand set. Their diagnostic value lies in the pattern: frequent appearances in independent roundups, expert lists, and comparisons tracked with stronger AI visibility.

    That does not mean collecting as many mentions as possible. A syndicated announcement copied across dozens of sites is repetition, not necessarily independent corroboration. Useful coverage supplies context: what category the brand belongs to, who it serves, where it is strong, what evidence supports the description, and how it compares with realistic alternatives.

    Build a corroboration map around actual buyer decisions:

    • List the publications, specialist sites, professional communities, directories, reviewers, and comparison pages that already appear for your unbranded category prompts.
    • Record how each one describes your category. The language used by credible third parties may differ from the label your marketing team prefers.
    • Mark where competitors appear and you do not. That is a distribution gap, not an on-page optimization task.
    • Check whether existing coverage places you in the wrong category, uses an old product name, repeats a discontinued claim, or points to a retired URL.
    • Prioritize pages that help a reader make the same decision represented by the prompt. Relevance is more useful than an unrelated high-authority mention.

    Then give credible publishers something worth referencing. Original data, transparent methodology, technical documentation, clearly attributed expert analysis, useful tools, and verifiable customer outcomes create evidence. Generic claims such as “leading,” “innovative,” or “best-in-class” create copy that no careful editor needs.

    For each important external mention, look for six qualities:

    • Your current brand and product names are accurate.
    • The relevant category is stated plainly.
    • The intended audience or use case is clear.
    • Important claims have evidence or transparent attribution.
    • The page is publicly accessible at a stable URL.
    • The description agrees with current first-party facts without merely copying your sales language.

    Do not optimize only for positive wording. Accurate qualification is more useful. “Suitable for distributed enterprise teams that need X” gives ChatGPT a reason to select the brand for one prompt and omit it from another. That is better visibility than appearing indiscriminately and being described incorrectly.

    Make important pages easy to discover, read, and reuse

    ChatGPT search does not simply send one query to a conventional search engine and summarize the first page. In one observational capture involving 1,200 answers, 88,000 search results, and 26,900 distinct pages, web grounding showed three operational layers: a discovery index that surfaced candidates, cached full-page copies, and a smaller group of pages opened live.

    These layers are observed behavior, not a permanent OpenAI specification. The implementation can change. The model is still useful because it explains why “we rank in Google” and “ChatGPT can use this page” are different claims.

    Discovery comes first. A page needs a stable, indexable URL, a successful response, a descriptive title, internal links, and a place in the site’s normal crawl paths. A page that exists only behind search, an interactive selector, a login, or a client-side application shell is a weak candidate for dependable retrieval.

    Do not use Bing visibility as a definitive proxy for OpenAI discovery. The observed OpenAI index behaved differently: only 1.5% of its URLs appeared in Bing’s top 20 for the same fan-out queries, and its snippets and title handling also differed. Google rankings can matter in retrieval regimes that use scraped Google results, but they do not prove that a page entered OpenAI’s own index.

    Once discovered, the page must be understandable in isolation. Treat the retrieved document as if the navigation, design, and sales presentation were gone. The text itself should answer these questions:

    • What entity or product is this page about?
    • What question does it answer?
    • Which audience, market, version, region, or use case does the answer apply to?
    • What evidence supports its factual claims?
    • When was the information meaningfully updated?
    • Which page is canonical if similar versions exist?

    Put the direct answer near the top, then expand it under descriptive headings. Use tables only when readers are comparing stable dimensions. Keep qualifications beside the claim they limit. A sentence that says “available in Canada” on one page and “available globally” on another creates an avoidable conflict unless both statements explain their dates or product scopes.

    Cached reading introduces another practical issue: a fact can be corrected on your live page while an older copy or an outdated third-party description remains available elsewhere. When an answer repeats stale information, check more than the current page. Find obsolete URLs, duplicates, old documentation, directory profiles, and external comparisons. Update or redirect what you control, request corrections where appropriate, and make the current canonical page easy to reach through internal links.

    Different ChatGPT modes can retrieve from markedly different corpora. During one capture period, free Think drew 74.7% of results from OpenAI’s own retrieval hub, while paid Thinking drew 75.3% from scraped Google results. Treat those percentages as a snapshot, not a lasting optimization formula. Their value is the warning: two people can enter the same prompt, retrieve a similar volume of material, and still receive answers grounded in different parts of the web.

    Product and local discovery also require channel-specific work. In the observed system, shopping and local results used merchant feeds and business-listing pipelines rather than ordinary web search. If you sell products or operate physical locations, clean editorial pages are not a substitute for accurate merchant data, prices, inventory information, addresses, categories, and business listings.

    A retrieval-ready page therefore needs more than technical indexability. It needs explicit meaning, extractable evidence, consistent facts, and the correct distribution channel for the query.

    Measure the answer, then fix the right bottleneck

    A single screenshot is not an AI visibility program. ChatGPT answers vary with wording, product mode, retrieval corpus, system behavior, location, account context, and time. Your benchmark needs a controlled prompt set and enough detail to reproduce each observation.

    Build prompts from the decisions that matter to your audience:

    • Category discovery: requests for providers, products, or approaches in your market.
    • Problem discovery: prompts that describe the job without naming the solution category.
    • Constraint prompts: industry, audience, geography, integration, budget model, compliance need, or workflow limitation.
    • Comparison prompts: your brand against a named alternative or a request for options with explicit tradeoffs.
    • Branded verification: questions about what you do, who you serve, current features, availability, pricing model, or another fact you can validate.

    Keep category, problem, and branded prompts in separate groups. A strong score on branded verification can otherwise conceal complete absence from unbranded discovery.

    SignalWhat to recordWhat it diagnoses
    Brand mentionWhether the brand appears and in which prompt classCategory recall and consideration-set inclusion
    Position and framingWhere the brand appears, which use case is attached, and any qualificationBrand-category association and positioning accuracy
    CitationWhether a claim is cited, the linked URL, and whether the domain is yours or independentRetrieval and evidence selection
    Factual accuracyCorrect, outdated, unsupported, or contradictory claimsCanonical-content, cache, and corroboration problems
    Competitive recurrenceWhich alternatives repeatedly appear for the same prompt classThe actual AI consideration set
    Test contextExact prompt, ChatGPT mode, account tier, location context, and test dateWhether two observations are meaningfully comparable

    Use the actual ChatGPT experience your audience is likely to encounter. API tests can help probe what a model family appears to know, but they should be labeled as a different measurement. In captured comparisons, product-to-API brand overlap measured only 0.23 to 0.27 using Jaccard similarity. Even ChatGPT product regimes shared only about a third of the brands they mentioned. An API monitor can therefore be directionally interesting while failing to predict the product answer.

    Translate each result into a specific action:

    • If competitors recur in unbranded prompts and you never appear, inspect category association and third-party coverage before rewriting title tags.
    • If ChatGPT mentions you accurately but never retrieves your domain, improve the official pages that substantiate the relevant claims and make them easier to discover.
    • If your domain is cited but the answer describes you incorrectly, remove ambiguity and conflicting first-party facts from the cited page.
    • If outdated external pages drive an error, correct the corroboration layer rather than publishing another unsupported claim on your homepage.
    • If results vary by mode, retain the variation in your reporting. Do not average materially different retrieval regimes into a false sense of precision.
    • If shopping or local prompts fail while editorial prompts succeed, inspect merchant feeds or business listings instead of treating the problem as ordinary web SEO.

    Keep a changelog beside the benchmark. Record the pages changed, external descriptions corrected, new coverage earned, and structured data updated. Retest the same prompt set under the same documented conditions, then inspect whether recall, retrieval, citation, or accuracy moved. This keeps you from crediting one tactic for a change caused by a different product mode or retrieval update.

    Your next move should follow the clearest failure. If ChatGPT does not associate you with the category, fix positioning and corroboration. If it recalls you but cannot support the answer, fix retrieval and evidence. If it cites stale or incorrect material, reconcile the fact across every page that can still influence the answer. That is how AI visibility becomes an operating practice instead of a collection of screenshots.

    References


  • Commercial Product Discovery in ChatGPT: An Action Plan

    Commercial Product Discovery in ChatGPT: An Action Plan

    Your product can rank well in conventional search and still disappear when a buyer asks ChatGPT what to purchase. The useful question is not simply, “How do we rank in ChatGPT?” It is, “What would ChatGPT need to understand, verify, and distinguish before placing this product on a relevant shortlist?”

    Because in-chat recommendations can compress the route from discovery to decision, you have less room to repair a vague product description later in the journey. Your product information must connect a specific buyer situation to a defensible recommendation, while your reporting must keep generated answers and paid placements separate.

    Map the decision ChatGPT is being asked to make

    A commercial prompt is rarely just a category keyword. A buyer may describe the job they need to complete, who will use the product, a limiting requirement, an unacceptable tradeoff, and the alternatives they are considering. Follow-up questions can narrow the decision further.

    Treat the prompt as a compact purchasing brief. Before changing pages or adding schema, build a commercial question map for each important product:

    • Buyer: Who is the product designed for, and who is likely to find it unsuitable?
    • Job: What concrete problem or task is the buyer trying to handle?
    • Constraints: Which requirements can rule the product in or out, such as compatibility, location, budget structure, capacity, or implementation effort?
    • Comparison criteria: Which differences matter when the buyer compares this product with another option?
    • Evidence: Which product page, specification, policy, or help page substantiates each claim?
    • Transaction details: What must the buyer know about price conditions, availability, delivery, returns, warranties, or the next purchasing step?

    Use real questions from sales conversations, customer support, site search, product reviews, and search-query data where you have access to them. Then remove any wording that your public evidence cannot support. The map is not a keyword list. It is an inventory of the decisions your content must help someone make.

    A simple test exposes the gaps: can a buyer find a short, factual passage on your site that answers each mapped question without combining clues from several pages? If not, ChatGPT may also have to infer too much. Add the missing decision fact to the appropriate product, comparison, policy, or support page.

    Make product evidence recommendation-ready

    An unbranded modular device is inspected on a workbench alongside its components, material samples, accessories, and household use-case objects.

    Your primary product page should do more than announce benefits. It should make product identity, suitability, limitations, and buying conditions explicit. A persuasive claim can attract attention, but a precise fact is easier to use in a recommendation.

    Audit the evidence layer in this order:

    • Establish one identity. Use the same product name, brand, category, model, and variant labels across product pages, documentation, feeds, comparison content, and structured data.
    • State fit in plain language. Name the audience, use case, prerequisites, and meaningful limitations. A clear not-for statement can be more useful than another broad benefit.
    • Expose decision criteria. Publish compatibility, included capabilities, implementation requirements, commercial conditions, and tradeoffs in text that can stand on its own.
    • Support comparisons. Organize comparison pages around buyer-relevant dimensions. Explain where each option fits instead of declaring your product the universal winner.
    • Connect claims to proof. Link feature claims to specifications or documentation and policy claims to the applicable policy page. Remove unsupported superlatives.
    • Show update state. Display when time-sensitive specifications, prices, or policies were last reviewed, and assign someone to keep them current.

    Where it accurately describes the page, Product and Offer structured data can provide a machine-readable version of facts such as the product name, brand, identifiers, offer URL, price, currency, and availability. Use only identifiers and commercial details that actually apply. Do not invent a product code to fill a field, and do not leave an old price in JSON-LD after changing the visible page.

    Structured data is not a guaranteed entry ticket to a ChatGPT recommendation. Treat it as a precise mirror of visible, maintained product information. If the markup, product page, shopping feed, and support documentation disagree, fix the underlying fact before adding more optimization.

    Treat generated recommendations and ads as separate channels

    A split scene shows an unbranded product on a neutral comparison table on one side and on a brightly spotlighted display on the other.

    Commercial discovery in ChatGPT can contain two distinct surfaces: the generated answer and a sponsored placement. Combining them in one visibility number produces false confidence.

    In an analysis of more than 50,000 commercial prompts across 20 niches, sponsored placements appeared on 25.94% of the sampled prompts. Every observed ad appeared below the generated response, and each placement contained one sponsored offer rather than a group of competing advertisers. Your campaign may not reproduce that delivery rate because prompt context and category can change what appears.

    The overlap between paid placement and generated visibility was small. Only 3.63% of advertisers also received a citation in the answer above the ad. The advertised URL appeared in citations in 0.09% of cases, while advertiser brands were mentioned in 4.44% of responses. On this evidence, buying an ad does not appear to make the brand materially more likely to enter the generated recommendation.

    SurfaceWhat success meansPrimary optimization workWhat to record
    Generated answerThe product is correctly included, described, and supported for a relevant buyer situation.Clear product facts, suitability criteria, comparisons, documentation, and consistent structured data.Product mention, recommendation rationale, cited URL, factual accuracy, and competitor inclusion.
    Sponsored placementThe offer appears in a relevant commercial conversation and sends qualified prospects to an appropriate destination.Precise context hints, focused keyword-style phrases, suitable creative, and a landing page aligned with the conversation.Placement data, landing-page engagement, lead quality, purchases, and other business outcomes available to you.

    Keep separate dashboards, targets, and budgets. A paid impression is not earned answer visibility. A citation is not an advertising conversion. You need both measurements before you can tell whether ChatGPT is influencing discovery, traffic, or revenue.

    Run a controlled discovery program instead of chasing screenshots

    Benchmark the generated answer

    A screenshot proves that one response occurred. It does not tell you whether the product appears consistently, whether the recommendation is accurate, or which missing fact is preventing inclusion elsewhere. Use a fixed prompt set and a repeatable record.

    1. Create prompts from the commercial question map. Include category discovery, use-case fit, constraint-led selection, direct comparison, and branded validation questions. Keep each prompt focused enough that you can identify why an answer changed.
    2. Record the conditions. Capture the prompt, date, whether the test began in a new conversation, the answer, citations, sponsored placement, and any follow-up question used.
    3. Grade the response. Mark whether the product was mentioned, recommended for the right reason, linked or cited, and described accurately. Record unsupported claims and omitted limitations as failures, even when the brand appears.
    4. Trace each weakness to a page. For every missing or incorrect fact, identify the public URL that should resolve it. If no appropriate URL exists, you have found a content gap rather than a prompting problem.
    5. Change one evidence cluster at a time. Update the relevant product, comparison, or support content and its structured-data mirror together. Retest the same prompt set on a regular cadence, but do not declare success or failure from one response.

    Constrain paid targeting with conversational detail

    ChatGPT ad matching uses natural-language context hints alongside keyword-style phrases. Those hints guide matching rather than operating as strict keyword rules, and advertisers did not have visibility into the individual queries or conversations that triggered their placements. That makes precision in the context description and measurement after the click especially important.

    Draft each context hint internally with this structure: buyer type evaluating product category for a defined job, under a named constraint, with a stated decision criterion. The structure forces you to describe a conversation in which the offer genuinely belongs. A broad category label does not.

    • Separate materially different audiences and use cases instead of blending them into one targeting theme.
    • Send each context cluster to a distinct, tracked landing-page destination aligned with that buyer, job, and criterion.
    • Repeat the relevant suitability facts and limitations on the destination so the visitor can confirm the fit immediately.
    • Use your own analytics and customer records to judge qualified engagement, lead quality, and purchases because the underlying triggering conversation may be unavailable.
    • Rewrite or pause a broad context when it produces irrelevant visits. Do not try to repair weak relevance by adding more generic phrases.

    This control matters because 14.35% of the observed ChatGPT ads were semantically unrelated to the prompt beside them. That rate describes the sampled placements, not every campaign, but it is large enough to make relevance auditing a launch requirement rather than an optional cleanup task.

    Key takeaways

    • Optimize for a buyer decision, not a single category keyword. Map the buyer, job, constraints, comparison criteria, evidence, and transaction details.
    • Publish explicit suitability, limitation, tradeoff, and commercial facts. Keep visible content, documentation, feeds, and JSON-LD consistent.
    • Measure generated recommendations and sponsored placements as separate channels. Paid placement does not imply inclusion in the answer.
    • Use a fixed prompt benchmark to track mentions, citations, reasoning, accuracy, competitors, and ads under recorded conditions.
    • Make ad context hints narrow enough to describe the right conversation, then use distinct landing destinations and your own outcome data to expose mismatches.

    Start with the product that matters most commercially. Build its decision map, audit the public evidence against every question, and capture a generated-answer baseline before expanding content or buying placement. That sequence gives you something more useful than visibility for its own sake: a clear view of where the commercial discovery path is breaking and what to fix next.

    References


  • ChatGPT Ads and Transactions: A Practical Growth Strategy

    ChatGPT Ads and Transactions: A Practical Growth Strategy

    If your ChatGPT plan ends when your brand earns a mention or a click, you are planning for a funnel that is already changing. Diners can now move from a restaurant recommendation to a Yelp reservation or waitlist inside the conversation, while eligible advertisers can buy placement around relevant conversations through ChatGPT Ads.

    You now need to manage three connected layers: recommendation visibility, paid acquisition, and transaction readiness. They can reinforce one another, but they are not interchangeable. The first strategic decision is to identify which layer should produce the result you want.

    ChatGPT now holds three parts of the commercial journey

    Traditional search marketing assumes a familiar handoff: the search engine presents a result, the user clicks, and the website handles the remaining persuasion and conversion. ChatGPT can support that journey, but it can also insert advertising before the click or host an action before the user reaches your site.

    Commercial surfaceWhat the user doesWhat you can controlPrimary measurement
    Recommendation visibilityReceives your brand, product, or business as part of an answerClear factual content, consistent entity information, supporting evidence, and reliable external business recordsPresence, factual accuracy, citations, qualified referral traffic
    Sponsored placementSees an ad associated with a relevant conversation and may clickEligibility, geography, first-party audiences, context hints, bid, creative, and landing pageImpressions, clicks, CPC, landing-page conversions, CPA
    Embedded transactionCompletes an action such as reserving a table or joining a waitlist in the chat experiencePartner data, availability, transaction infrastructure, confirmation, and post-transaction serviceCompleted actions and the corresponding records in the transaction provider

    A business may participate in one layer without participating in the others. Buying an ad does not mean you should assume stronger placement in an unsponsored answer. Being recommended does not mean ChatGPT can complete a transaction for you. An embedded action may also send the user to a partner, rather than your website, for later management.

    Report the layers separately. Otherwise, a rise in paid clicks can be mistaken for better AI-search visibility, while an increase in partner-managed transactions may be invisible in website analytics.

    Run four checks before allocating a ChatGPT Ads budget

    Two marketing professionals examine four visual readiness checkpoints before moving an advertising token through an illuminated gateway.

    ChatGPT Ads will not fit every audience or business. Before you write creative, pass four go-or-no-go checks.

    • Audience: Ads can serve only to people OpenAI believes are 18 or older on the Free and Go tiers, including logged-out sessions. If your most valuable buyers tend to use higher paid tiers, the reachable audience may be a poor match.
    • Location: Current targeting covers the United States, Australia, Canada, Japan, New Zealand, South Korea, and the United Kingdom. You can target or exclude locations at the country, region, designated market area, or postal-code level.
    • Policy: Restricted categories include adult content, alcohol, tobacco, financial services, gambling, and others. Policy materials have also shown ambiguity around legal-service advertising, so visible ads from a competitor are not proof that your own offer is eligible.
    • Economics: The self-service minimum is $25 per day, while early campaign observations put average CPCs around $2 to $5 across industries. Those CPCs are preliminary observations, not a dependable benchmark for every market. A bid below $3 may trigger a warning that the ad will not deliver; that threshold appears to be fixed rather than a personalized forecast.

    The budget floor is an entry requirement, not evidence that $25 will generate enough activity for a sound decision. Work backward from the maximum customer-acquisition cost your business can tolerate. If the observed CPC range cannot support that number at a realistic landing-page conversion rate, fix the offer or measurement before funding the campaign.

    Account ownership deserves attention as well. The advertiser should create and own the account, then add its agency as a user. Agencies are not supposed to create accounts on behalf of clients, and the platform does not yet offer a direct equivalent to Google Ads Manager Accounts or Meta Business Manager. Collect the legal business name, business tax ID, payment card, and favicon before setup so account administration does not delay the launch.

    Structure campaigns around decisions, not keyword lists

    ChatGPT Ads has no keyword targeting, demographic targeting, or conventional in-market audiences. The available controls include geography, uploaded first-party audiences, context hints, and the language used in your ad and landing page. Importing a paid-search keyword spreadsheet unchanged will therefore create the wrong campaign architecture.

    The account hierarchy will look familiar:

    • Campaign: Standard or product-feed type; Reach, Clicks, or Conversions objective; included and excluded locations; included and excluded custom audiences; daily or total budget; optional conversion event; and start and end dates.
    • Ad group: Bid, default destination URL, and context hints.
    • Ad: Destination URL, headline, description, and image.

    Use that structure to isolate the decision the user is trying to make. A practical build sequence looks like this:

    1. Write the conversational situation as a sentence. Include the problem, important constraint, and decision stage. This is more useful than a list of loosely related search terms.
    2. Keep one intent family in each ad group. The ad, context hints, and destination should all continue the same task. Separate early education from urgent comparison or purchase intent.
    3. Select an objective that matches the next measurable event. Use Reach when qualified exposure is the result, Clicks when the destination page must continue the journey, and Conversions only after the OpenAI pixel and conversion event are working correctly.
    4. Design within the actual creative limits. Headlines have a 50-character maximum, descriptions have a 100-character maximum, and either can be truncated. Put the useful distinction first. The image must be a square PNG or JPG of at least 256 by 256 pixels.
    5. Make the landing page a direct continuation. If the conversation concerns a specific problem, constraint, product, or location, the destination should address it immediately. Do not send every context to a generic homepage.
    6. Validate measurement before optimizing bids. Click campaigns charge per click. Reach campaigns charge per 1,000 impressions. Conversion campaigns require the pixel, still charge per click, and allow a bid cap.

    OpenAI uses a relevance-weighted, second-price auction. Bid size matters, but landing-page relevance and ad quality also contribute to selection. When delivery is weak, raising the bid is only one possible response. First inspect whether the context, promise, creative, and destination describe the same user need.

    This also changes creative testing. Do not test two ads that target different decisions and then attribute the result to wording. Hold the intent family and destination constant while changing one material element, such as the promise, proof point, or image. The platform is still evolving, so record the configuration and launch date with every result.

    Becoming transactable starts outside ChatGPT

    A generic conversational interface connects to product, inventory, reservation, payment, and fulfillment systems that support a completed transaction.

    The restaurant integration exposes the operational model clearly. Yelp already supplies reviews, ratings, photos, and business details to ChatGPT. It now also supplies Reservations and Waitlist for thousands of restaurants in the United States and Canada. The user can complete the initial action inside ChatGPT but manages or modifies the booking through Yelp.

    That means the conversion surface and the system of record may belong to different companies. Your website, business profile, transaction provider, and in-chat experience must still agree on what can be booked and what happens next.

    1. Identify the transaction rail. Determine which booking, commerce, or lead-management provider can actually complete the action for your category. Do not assume a feature available to restaurants is available to every business.
    2. Reconcile business data. Check the name, location, offering, imagery, availability, and customer-facing details on your site against the partner record. Correct contradictions at the system that supplies the action.
    3. Match structured data to visible content. JSON-LD should express the same facts a person sees on the page. Do not use markup to claim an offer, location, availability state, or action that the visible page and transaction system cannot support.
    4. Test the complete action. For a restaurant, that includes finding the business, selecting a time or joining the waitlist, receiving confirmation, and following the route for modification. Test as a customer would, not merely by checking that the listing exists.
    5. Assign post-transaction ownership. Decide who handles changes, failures, and customer questions when the initial action begins in ChatGPT but the record is managed elsewhere.

    JSON-LD is valuable because it gives machines a less ambiguous representation of visible facts. It does not create live inventory, a booking connection, payment handling, or customer support. Treat schema as a data-quality layer and the transaction provider as an operational layer. You need both to be accurate, but they solve different problems.

    Restaurants using Yelp Guest Manager now have another channel at the point of dining choice. Yelp’s broader position is also instructive: its content and booking capabilities support experiences across ChatGPT, Apple Maps, Alexa+, Microsoft Bing, DuckDuckGo, and Yahoo. Maintaining reliable partner data can therefore improve transaction readiness across more than one discovery surface.

    Measure each layer before combining attribution

    A single line called ChatGPT traffic will conceal more than it reveals. Maintain three measurement ledgers until you have reliable identifiers that connect them.

    • Recommendation ledger: Track a stable set of priority questions, whether your brand appears, which facts are accurate, what evidence or citations accompany it, and whether referral visits follow.
    • Advertising ledger: Record campaign objective, intent family, audience inclusion or exclusion, geography, spend, impressions, clicks, CPC, landing-page conversions, conversion rate, and CPA.
    • Transaction ledger: Reconcile actions initiated through ChatGPT with confirmed records in the booking or commerce provider, including later modifications where the provider exposes them.

    Do not count an in-chat reservation as a website conversion when no website visit occurred. Do not credit a sponsored-click conversion to improved recommendation visibility. If a provider supplies a ChatGPT referral label or another reliable identifier, preserve it in downstream records rather than replacing it with a generic AI category.

    For paid campaigns, inspect the sequence rather than one headline metric. Low delivery can reflect eligibility, targeting, bid, or relevance. Strong click-through with weak conversion usually moves the investigation to the promise, landing page, offer, or tracking. Recorded conversions with missing transaction records indicate a measurement or operational problem, not campaign success.

    Key takeaways

    • ChatGPT can support recommendation, paid placement, and an embedded transaction, but a brand does not automatically participate in all three.
    • ChatGPT Ads reaches eligible adults on Free and Go tiers, including logged-out sessions, rather than every ChatGPT user.
    • There are no keywords, demographic segments, or conventional in-market audiences, so organize ad groups around conversational decisions.
    • The current self-service floor is $25 per day, while observed CPCs of $2 to $5 remain early, non-universal benchmarks.
    • Structured data can clarify an offer, but it cannot replace the provider connection that supplies availability and completes an action.
    • Recommendation visibility, advertising performance, and partner-managed transactions require separate measurement before attribution can be combined responsibly.

    Start with one high-intent customer decision. Choose the commercial surface that should handle it, repair the data and operational handoffs, define one verifiable outcome, and only then launch the smallest campaign or integration test that can answer a real business question.

    References


  • Chatbot-Native Agent Ads: How to Prepare Your Business

    Chatbot-Native Agent Ads: How to Prepare Your Business

    Your next paid campaign may have to convert a question before it earns a pageview. In the emerging chatbot-native model, an ad click would open a business-specific ChatGPT conversation that can answer questions, surface products and capture leads.

    That is a meaningful change, but it is not yet a settled advertising product. The capability appears limited to a small group of advertisers, and the end-user experience has not been widely observed. Your practical move is not to forecast placements or rebuild your media plan. It is to make your business facts, agent rules, live systems and conversion paths ready for a conversation to become the destination.

    Key takeaways

    • A chatbot-native agent ad is not merely an AI-written ad or a chatbot added to a landing page. The conversation itself becomes the post-click experience.
    • Your website remains important because it can supply the public facts used to construct the business profile. Contradictory or vague pages can therefore become advertising problems.
    • Use each information layer for the job it handles best: pages for durable public facts, feeds for catalog data, approved tools for live values, instructions for behavior and forms for conversion.
    • Build each campaign around one completed customer job. A general-purpose agent is harder to control, test and measure.
    • Optimize for verified outcomes and answer quality, not raw chat volume or conversation length.

    The destination changes from a page to a decision

    A conventional landing page presents a fixed information architecture. The visitor decides which headline applies, which section to read, which filter to use and whether the form is worth completing. A business agent takes on some of those decisions. It interprets the request, asks for missing information, selects an answer and proposes a next action.

    This means the first agent response is not supporting copy. It is the landing experience. If the agent misunderstands the intent, gives an unsupported answer or requests contact details too early, the campaign has already failed even if the ad earned a click.

    The distinction also changes ownership. Paid media still owns the promise in the ad, but it cannot own the entire experience. Content teams own the durable facts. Product and operations teams own current availability and other changing values. Sales or service teams define qualification and escalation. Security and legal teams set limits on data collection and actions. Analytics must connect the conversation to a business outcome.

    Start with a campaign contract before you write creative. It should answer these questions:

    • What specific question or task brings the user into the conversation?
    • What can the agent promise to help the user accomplish?
    • Which facts must be available for the agent to deliver that help?
    • Which claims require a live system check rather than a page or prompt?
    • What action marks successful completion?
    • What safe fallback is offered when the agent cannot answer or act?

    If those answers are vague, more prompt writing will not rescue the campaign. You have an undefined customer journey, not an instruction problem.

    Build the context stack before writing the ad

    The apparent setup begins by crawling a company’s website to generate a business profile containing common questions, support information and general context. Advertisers can then combine that profile with custom instructions, product feeds, Model Context Protocol tools for live business data and lead-generation forms.

    Think of this as a context stack, not a single master prompt. Each layer should have a narrow responsibility and an explicit release check.

    Context layerWhat it should controlRelease check
    Website and generated business profileDurable public facts, policies, support information and common customer questionsCan a reviewer trace each important answer to a current, canonical page?
    Custom instructionsScope, interaction rules, recommendation logic, uncertainty language and escalation behaviorDoes the agent behave predictably when required information is missing?
    Product feedStructured catalog records and product attributes supplied by the businessDo identifiers, names and attributes agree with the customer-facing catalog?
    Approved MCP toolsLive values and actions from intentionally connected business systemsDoes the agent fail safely when a tool returns no result or becomes unavailable?
    Lead formThe minimum user information required for the agreed next stepIs every field necessary, explained and requested only when it becomes relevant?

    Do not duplicate the same changing fact across all five layers. If availability is live, retrieve it from the approved live system. If an offer attribute belongs in the catalog, maintain it in the feed. Let the instructions explain when the agent should use that information, not what the current value happens to be.

    Make the website safe to summarize

    A crawl can only work with what you publish. If one page describes a service as available everywhere while another limits it to named locations, the conflict is now more than a conventional content-quality issue. It can affect what an advertising agent represents to a prospective customer.

    Audit facts rather than merely auditing pages:

    1. List the facts the agent would need about your identity, offerings, locations, service areas, eligibility, policies, support channels and next steps.
    2. Assign one canonical public location to each durable fact. Supporting pages may restate it, but they should not introduce different conditions.
    3. Find conflicting names, qualifications and policy language across product pages, help content, location pages and forms.
    4. Place the qualifier beside the claim it limits. Do not expect an agent or a customer to combine a broad promise from one section with an exception buried elsewhere.
    5. Separate durable facts from values that can change during a conversation. Changing values belong in a maintained feed or live system when possible.
    6. Give each important fact an internal owner and review trigger. A technically crawlable page can still be operationally stale.

    JSON-LD can support this work when it expresses the same entities, offers, locations and relationships visible on the page. Keep identifiers and values aligned between markup and content. Do not add unsupported properties as if they were private instructions to the agent.

    There is no demonstrated basis here for treating schema markup as a direct control surface for this ad format. Use structured data to improve consistency and machine readability, not as a guarantee that a business agent will select a particular answer. Likewise, do not relax robots rules or expose protected systems based on guesses about an unnamed crawler. Wait for explicit platform and security requirements before changing access controls.

    Write operating rules, not just a brand voice prompt

    An instruction such as be helpful, persuasive and on-brand does little when the agent must decide whether it has enough information to recommend a product. The useful instructions are decision rules.

    • Scope rule: define which questions the campaign agent can answer and which belong with a person, another workflow or a public page.
    • Information rule: map policies to canonical pages, catalog attributes to the feed and live-dependent claims to approved tools.
    • Clarification rule: identify the information that must be collected before a recommendation can be made.
    • Uncertainty rule: require the agent to say when a fact cannot be verified. It should not convert missing data into a plausible guess.
    • Recommendation rule: explain which user inputs may influence a recommendation and require the reasoning to be stated in plain language.
    • Lead-capture rule: answer what can be answered before requesting personal information, then explain why each requested detail is needed.
    • Escalation rule: name the conditions that require a human handoff and specify what useful context may be passed with the user’s knowledge.
    • Action rule: require confirmation before any tool performs a consequential write action, such as submitting a request or scheduling an appointment.

    A strong missing-data rule is simple: if the recommendation depends on current availability and the approved live check cannot confirm it, the agent says that availability is unconfirmed and offers a safe next step. It does not infer availability from an old page, a general description or the absence of an error.

    Design every campaign around one completed job

    A customer request follows one connected path through a digital assistant, product selection, availability check and completed handoff.

    The potential value of the format is not conversation for its own sake. A business agent could answer questions, recommend products, schedule appointments, troubleshoot issues or qualify leads before the user visits a conventional page.

    Those are different jobs with different evidence, permissions and success conditions. A product recommendation may require customer preferences and feed attributes. An appointment workflow may require live availability and permission to write to a scheduling system. Lead qualification may require an agreed definition from sales and an approved form. Putting every job into one campaign makes failures harder to diagnose and outcomes harder to attribute.

    For each campaign, complete this job card:

    • The user arrives asking: a single plain-language intent.
    • The session succeeds when: one verifiable customer or business outcome.
    • The agent must know: the minimum inputs needed to reach that outcome.
    • The agent may claim: statements supported by named business data.
    • The agent must check live: any value that could become stale before the user acts.
    • The agent must not do: actions or claims outside its permissions and evidence.
    • The fallback is: a useful page, form, support route or human handoff.

    Then design the conversation in the same order a capable employee would resolve the task:

    1. Continue the promise made in the ad. Do not make the user restate why they clicked.
    2. Ask the smallest question that materially narrows the answer. Avoid turning the opening into a disguised intake form.
    3. Answer the user’s question before pushing the conversion, unless the requested detail is genuinely required to produce the answer.
    4. Explain the basis for a recommendation. The user should be able to see how their stated needs affected the result.
    5. Present one primary next step and one fallback. A wall of undifferentiated links simply recreates a weak navigation page inside a chat.
    6. Carry necessary context into the next step when the platform, user permission and privacy design allow it. Do not make the user repeat information without a reason.

    Do not hardcode the strategy around an interface that has not been broadly seen. Exact ad appearance and prominence remain unclear. Prepare portable components instead: the opening explanation, required questions, answer rules, calls to action, failure messages and handoff logic. Those components can be adapted once the real placement and controls are documented.

    Keep the website in the journey

    Replacing the initial landing-page visit does not make the website obsolete. The apparent workflow uses the site to create the business profile, which makes the site part of the agent’s knowledge supply. It also remains a useful route for policy detail, accessible alternatives, complex forms, evidence the user wants to inspect and tasks the agent cannot complete.

    For every agent outcome, maintain a page-based fallback that reaches the same destination without requiring the conversation. If linking is supported in the final experience, send users to the canonical page for detailed terms rather than a generic homepage. The better model is not agent versus website. It is agent for interpretation and guided action, with the website serving as governed evidence and a resilient fallback.

    Measure solved intent and control the agent’s risk

    A business team monitors a digital agent as routine actions proceed through safeguards and an uncertain request is routed to a human specialist.

    Click-through rate cannot tell you whether the agent answered correctly, recommended an appropriate option or completed the promised action. Conversation count cannot tell you either. A long session may show useful consideration, repeated misunderstanding or a broken tool. A short session may be an immediate success.

    Define an event chain before launch. Your measurement plan should attempt to connect the ad impression, conversation open, identified intent, meaningful progress, action start, confirmed completion, qualified outcome and downstream business result. The platform may not expose every event, so document which steps are directly observed and which are proxies.

    Useful campaign measures include:

    • Intent identification rate: eligible sessions in which the agent obtains enough information to understand the requested job, divided by eligible sessions started.
    • Intent resolution rate: eligible sessions in which the defined customer job is resolved, divided by eligible sessions.
    • Verified action completion rate: actions confirmed by the relevant business system, divided by action starts.
    • Qualified outcome rate: outcomes accepted under the business’s existing qualification standard, divided by eligible sessions. The agent should not invent the qualification standard.
    • Handoff completion rate: sessions that successfully reach the offered fallback, divided by sessions that require a handoff.
    • Answer defect rate: reviewed sessions containing an unsupported, stale, contradictory or materially incomplete answer, divided by reviewed sessions.

    Set the exact eligibility and resolution definitions before comparing campaigns. Otherwise, a change in what counts as a session can masquerade as improved performance. If the platform exposes campaign or session identifiers and your privacy design permits their use, carry them into the resulting lead, booking or order record so the downstream outcome can be reconciled.

    When testing, change one decision variable at a time: the ad promise, opening question, answer structure, recommendation explanation, call to action or timing of lead capture. Keep the intended job stable. Comparing two agents that solve different tasks will not tell you which conversational design performed better.

    Review conversations as quality data

    Automated outcome tracking needs a human quality loop. Review conversations after instruction, content, feed or tool changes, and classify the failure rather than merely labeling the session bad.

    • Unsupported claim: the answer has no approved factual basis.
    • Stale claim: the agent used a durable page where a live check was required.
    • Premature recommendation: the agent recommended before collecting a necessary input.
    • Capture failure: the agent requested unnecessary information or asked before delivering value.
    • Tool failure: an unavailable or ambiguous result was presented as a confirmed value.
    • Handoff failure: the fallback was missing, irrelevant or forced the user to begin again.
    • Instruction conflict: two rules pushed the agent toward incompatible behavior.

    Assign each defect to the layer that must be corrected. Fix a contradictory policy on the canonical page, not with another prompt exception. Fix changing availability in the live integration, not in website copy. Fix premature capture in the interaction rules, not by hiding a form field while leaving the same conversational pressure in place.

    Treat conversation and tool access as customer data systems

    Lead forms and transcripts can contain personal or commercially sensitive information. Before enabling capture, document what the agent requests, why it is needed, where it is stored, who can access it, how long it is retained, how deletion works and which notice or consent applies. Sensitive or regulated workflows need review from the appropriate legal, privacy and security specialists before launch.

    Give connected tools the least access required for the campaign job. Prefer read-only access when the agent only needs to check a value. For tools that can write, require a clear user confirmation before submission and return a verifiable result afterward. Maintain a way to pause the campaign or disable the affected tool if answers or actions become unreliable.

    Use a pass-fail launch gate

    A generic readiness score can hide a serious defect behind several easy wins. Use a pass-fail gate based on the actual job the campaign promises to complete.

    1. Truth test: ask the common questions, edge cases and deliberately conflicting questions. Confirm that every material answer can be traced to an approved page, feed or system.
    2. Missing-information test: remove a required input and verify that the agent asks for it or declines to decide. It must not fill the gap with an assumption.
    3. Freshness test: change a live-dependent value in its authoritative system and verify that the agent checks that system instead of repeating an older page value.
    4. Tool-failure test: make the approved integration unavailable or return no usable result. The agent should state the limitation and offer the defined fallback.
    5. Action test: complete the customer task, cancel before confirmation, retry a submission and follow an unavailable path. Confirm that the business system records only the intended action.
    6. Handoff test: move from the agent to the fallback and verify that the user knows what will happen next, what information is transferred and whether anything must be repeated.
    7. Data test: inspect every requested field, stored transcript and access permission. Remove anything that is not required for the declared task or an approved operational need.
    8. Measurement test: reconcile a completed test journey from campaign entry through the business system. If the outcome cannot be observed, label the available metric as a proxy rather than calling it a conversion.

    Do not launch while a material answer lacks an approved factual basis, a live-dependent claim can bypass its live check, a consequential action can occur without confirmation, or a failed workflow has no usable fallback. Those are structural defects. More traffic will only expose them to more people.

    Choose one high-intent customer job and build its fact map, instruction set, test script and outcome definition now. When chatbot-native inventory becomes available to you, you will be evaluating a media opportunity with a governed business agent behind it, not improvising an automated representative after the campaign is already live.

    References


  • Yelp Data in ChatGPT: A Local Visibility Action Plan

    Yelp Data in ChatGPT: A Local Visibility Action Plan

    If local customers find you through recommendations, your Yelp presence can now affect a conversation that happens before anyone opens Yelp. ChatGPT can use licensed Yelp business details, ratings, reviews, and photos when responding to local queries.

    You do not need a new ChatGPT setting to prepare for this. You need accurate business data, a Yelp profile that represents the current customer experience, consistent information on your own site, and a way to measure whether AI recommendations lead to useful actions.

    Key takeaways

    • ChatGPT can incorporate Yelp reviews, ratings, photos, and business information into answers to local queries.
    • Yelp branding and links are expected when Yelp content is used, but OpenAI controls how the resulting experience is presented.
    • Yelp’s Request a Quote feature is also slated to appear in ChatGPT local-services searches, shortening the path from recommendation to inquiry.
    • There is no disclosed formula showing how Yelp data is selected, weighted, refreshed, or combined with other information. A strong Yelp profile should be treated as one visibility input, not a guaranteed ChatGPT ranking tactic.
    • Your practical priorities are source accuracy, entity consistency, honest reputation management, representative photos, lead readiness, and repeatable monitoring.

    What the integration changes in local discovery

    A conventional local-search journey often sends a user to a results page, a map listing, a review platform, and then a business website. A conversational journey can compress those steps. Someone can describe a need, ask for nearby options, compare reputations, inspect photos, and continue toward an inquiry without conducting several separate searches.

    Yelp’s contribution is a licensed layer of local evidence. ChatGPT gains access to real-time local recommendation data that includes reviews, ratings, photos, and business details. That gives it material for questions such as which businesses serve a particular need, what customers tend to mention, and how the available options appear to differ.

    Do not interpret the phrase real-time as a promise that every Yelp edit will appear in every ChatGPT response immediately. No synchronization interval or refresh guarantee has been disclosed. Treat Yelp as an active data source, but verify important changes in both places instead of assuming that one update has propagated everywhere.

    The commercial path may become shorter as well. Request a Quote is expected to support provider contact from ChatGPT local-services searches, including actions related to consultations or appointments. For a service business, visibility may therefore turn into an inquiry inside the conversational experience rather than a visit to the business’s website.

    This also makes attribution more complicated. A customer may discover you in ChatGPT, inspect Yelp-derived information, request a quote, and never generate a conventional organic-search session. Website traffic alone will not describe that journey.

    What you can control, and what you cannot

    You can control the accuracy of information you publish, the quality of your profile, the customer experience that produces reviews, and how reliably your team handles inquiries. You cannot control whether a particular prompt invokes Yelp data, which businesses ChatGPT includes, how Yelp information is summarized, or where a citation appears.

    That distinction matters because OpenAI, not Yelp, controls the presentation. Yelp branding and links are intended to accompany its content when used, but that does not mean every local answer will contain a Yelp link or preserve Yelp’s familiar listing layout. A conversational answer may select, condense, or contextualize the available information differently.

    No public ranking recipe accompanies the integration. There is no disclosed Yelp-rating threshold for inclusion, no stated review-count requirement, no guaranteed placement for advertisers, and no evidence that adding a particular schema property forces ChatGPT to cite a business. Anyone promising a deterministic optimization formula is going beyond what is known.

    Source visibility still matters. A Morning Consult survey found that 65% of Americans had used AI search, only 15% trusted it a lot, and 72% believed AI platforms should always identify their information sources. Yelp branding can help a user inspect the evidence behind a recommendation, but your listing must withstand that inspection. A citation is not useful if it sends the customer to stale details, unrepresentative photos, or unresolved complaints.

    The agreement is also non-exclusive, and Yelp already licenses data to Apple Maps and Yahoo+. That makes profile maintenance a cross-channel task. Do not create a special version of your business for ChatGPT. Maintain one defensible set of facts that can survive distribution across Yelp’s wider network.

    Run this Yelp-to-ChatGPT readiness audit

    A cafe owner compares a laptop and phone with icon-based cards for location, contact details, hours, photos, services, and customer feedback.

    Start at the data layer that ChatGPT can actually receive. A polished website cannot directly repair an incorrect Yelp record, and structured data on your site does not overwrite Yelp content.

    1. Capture a baseline. Record the business details, rating, prominent review themes, photos, and available contact actions currently visible on Yelp. Save enough context to identify what changed later. Without a baseline, you cannot distinguish an integration change from an ordinary profile update.
    2. Resolve factual conflicts at their origin. Compare Yelp with the business’s official website and other profiles you actively maintain. Check the business name, location information, contact details, hours, service descriptions, and customer-facing policies. Decide which value is canonical, then correct each property through its own publishing workflow.
    3. Check what the profile implies, not just what its fields say. A technically accurate profile can still create the wrong expectation. Read it as a new customer would. Confirm that the categories, description, photos, and recent customer feedback collectively represent what the business currently does.
    4. Review reputation themes. Look for repeated praise, repeated complaints, and outdated perceptions. You cannot edit legitimate customer sentiment into a better story. You can fix the operational cause of a recurring problem, clarify a misunderstood offering, respond appropriately through the platform, and make current capabilities easier to verify.
    5. Inspect the photo set. Yelp photos can enter the ChatGPT recommendation experience, so check whether the visible collection accurately depicts the location, work, products, or service context. Remove or replace business-controlled images that are obsolete or misleading where the platform permits. Do not assume that a polished stock image is more useful than an accurate one.
    6. Prepare the inquiry handoff. If your category relies on estimates, consultations, or appointments, assign ownership for incoming quote requests. Confirm that the recipient can identify the requested service, respond with the information needed for a next step, and record where the inquiry originated. A shorter discovery path only helps when the operational handoff works.

    Your website and structured data remain useful, but they solve a different part of the problem. Keep visible business details and appropriate LocalBusiness structured data aligned. Mark up facts that users can verify on the page, and correct discrepancies rather than trying to hide them behind schema. JSON-LD can help machines interpret your owned pages; it is not a command that edits Yelp or guarantees selection in ChatGPT.

    Use your site to answer details that a review profile may not express clearly: what you offer, whom it is for, where it is available, what constraints apply, and how to take the next step. The goal is not to repeat Yelp. It is to make your first-party explanation and third-party reputation coherent when a person follows the citation and checks your official site.

    Measure visibility without pretending you know the ranking system

    Icon-based paths connect a conversational phone interface to website visits, phone calls, and storefront directions while a sealed abstract system remains hidden.

    A useful monitoring program separates retrieval, representation, and action. Combining them into one vague AI visibility score hides the problem you need to fix.

    • Retrieval: Does the business appear for a relevant local need, and does the response show Yelp branding or a Yelp link?
    • Representation: Are the business facts correct? Does the summary reflect the actual service? Are review themes presented fairly? Are displayed photos representative?
    • Action: Can the user reach an appropriate next step, such as visiting a profile, contacting the business, requesting a quote, scheduling, or navigating to an official page?

    Build a prompt set around the ways real customers describe the decision. Include category-and-location searches, problem-led searches, comparison questions, reputation questions, and branded questions about what customers say. Record the exact prompt, relevant location context, date, businesses mentioned, citations shown, factual errors, photos, available actions, and destination URLs.

    Keep the prompts and testing conditions consistent when you repeat the check. Treat each response as an observation, not a permanent rank. Conversational output can change, and the integration does not come with a fixed position-reporting system comparable to a traditional search-results page.

    Connect this monitoring to commercial records. Track ChatGPT referrals where they reach your site, Yelp profile activity where available, quote requests, calls, appointments, and qualified leads. Add a simple source question to intake when appropriate. If an inquiry happens inside ChatGPT, ordinary website analytics may never see the discovery step, so avoid declaring the channel ineffective merely because it produced no web session.

    When you find a problem, repair the correct layer. Fix a wrong Yelp fact on Yelp. Fix inconsistent official information on your website and other maintained profiles. Address a repeated service complaint operationally. Improve lead routing when inquiries go unanswered. Escalate a demonstrably incorrect ChatGPT representation through the feedback options available in that experience, while keeping a record of the prompt and cited material.

    Begin with the baseline audit, then monitor the customer journeys that matter to your business. The durable advantage is not a speculative ChatGPT trick. It is a local entity whose facts, reputation, visual evidence, owned content, and inquiry handling remain credible wherever Yelp data is distributed.

    References

  • OpenAI’s Desktop Consolidation: What Atlas Users Face

    OpenAI’s Desktop Consolidation: What Atlas Users Face

    OpenAI’s reported plan to retire ChatGPT Atlas is more than a product cancellation. It points to a desktop strategy built around one primary ChatGPT application that combines browsing, agent-led work, and Codex capabilities.

    For users and organizations, the immediate questions are practical: how firm the retirement date is, whether adopting an OpenAI browser remains necessary, and what the consolidation could mean for research and digital discovery.

    The desktop app is becoming the center of the product

    CrushPress.AI reported that OpenAI intends to discontinue Atlas as a standalone desktop browser and move its browser-based AI features into a new ChatGPT desktop app. The same report describes that app as bringing together ChatGPT Work, OpenAI’s work-focused agent, and ChatGPT Codex.

    This is a consolidation of entry points as much as a consolidation of features. Instead of asking users to choose among a dedicated AI browser, a separate Codex application, and the broader ChatGPT experience, the reported direction places those functions inside a common desktop environment.

    The sequence reported by CrushPress.AI helps explain the shift. Atlas launched on Mac in October, a dedicated Codex app followed, and an in-app browser was added in April. The planned unified app appears to gather capabilities that had been introduced through separate products, although the source does not provide a detailed migration map.

    Key takeaways

    • ChatGPT Atlas is reportedly scheduled to be retired as a standalone browser.
    • The stated Aug. 9 date is a target, so it should not be treated as an unconditional deadline without further notice.
    • Browser functions, ChatGPT Work, and Codex are being positioned within a unified ChatGPT desktop app.
    • Chrome users are expected to retain access to ChatGPT and Codex through OpenAI’s Chrome extension.
    • The change could concentrate more research and task completion inside ChatGPT, increasing its role in digital discovery.

    The Aug. 9 date carries an important qualification

    CrushPress.AI cited OpenAI’s James Sun as saying on X that Aug. 9 was the current targeted date for deprecation. According to the report, Sun also said that more information would be shared in the application and by email.

    That wording establishes a planned direction but preserves uncertainty around execution. A target date can change, and the supplied report does not specify when access will stop, whether data or settings will transfer automatically, or whether every Atlas feature will have an equivalent in the new app.

    Atlas users should therefore treat official in-app and email notices as the operative migration guidance. Before the target date, organizations can identify which workflows depend on Atlas and document any browser-specific behavior they would need to reproduce. That is prudent continuity planning, not evidence that any particular feature will be lost.

    Users still have two reported browser paths

    A computer user views two visual pathways from a desktop application to separate generic browser experiences.

    The consolidation does not necessarily require every user to replace an existing browser. CrushPress.AI reported that the new desktop app will include browser capabilities, while people who prefer Chrome can use OpenAI’s Chrome extension to access ChatGPT and Codex.

    Those paths serve different working preferences. A unified desktop app can keep browsing and agent tools in one OpenAI-controlled environment. An extension can place the same broad services closer to an established Chrome workflow. The source does not compare feature parity, security controls, performance, or account requirements, so it would be premature to declare either route universally better.

    For teams, the decision should follow the work being performed. Relevant considerations include whether tasks depend on existing Chrome profiles and extensions, whether the unified app offers necessary workflow controls, and how each option fits internal software and security policies. These are evaluation criteria rather than reported product guarantees.

    Consolidation could expand ChatGPT’s role in discovery

    A person uses a central desktop assistant connected to floating research pages, documents, code panels, and media tiles.

    The strategic consequence extends beyond desktop software. When browsing, questions, research, coding, and task execution occupy the same interface, the distance between finding information and acting on it becomes shorter. CrushPress.AI argues that this gives ChatGPT another opportunity to influence how people research brands and discover information outside traditional search-result pages.

    For marketers and publishers, the relevant change is not merely the disappearance of an Atlas icon. It is the possibility that more discovery activity will occur within the main ChatGPT experience, where answers and actions may be combined. That makes accurate, accessible, and clearly attributable information increasingly important, while the supplied source does not establish how the new app will select or present particular brands.

    The next signals to watch are OpenAI’s promised notices, the final treatment of Atlas accounts and workflows, and the practical feature differences between the desktop app and Chrome extension. Those details will determine whether this is mostly a packaging change or a meaningful shift in how desktop users browse and complete work.

    References

  • Why ChatGPT Search Citations Change Across Hidden Pipelines

    Why ChatGPT Search Citations Change Across Hidden Pipelines

    A ChatGPT citation is the visible end of a much larger selection process. Before a source can appear beside an answer, the system may decide whether to search, choose a retrieval pipeline, rewrite or expand the query, fetch candidate pages and select which evidence deserves a citation.

    That layered process explains why repeated prompts can produce different source lists without any underlying page changing. It also changes how publishers should interpret AI visibility: one observed answer is a sample of a variable system, not a definitive ranking.

    A citation is the output of several hidden decisions

    The source cards visible to users do not disclose the full route that produced them. According to the CrushPress.AI report, research by Chris Green and Suganthan Mohanadasan identified internal source-selection labels including Labrador, Bright, Oxylabs and SERP. These labels appeared behind the answer rather than in its public citations.

    This creates several distinct opportunities for a page to be excluded. ChatGPT may classify the prompt as not requiring web search. If it does search, the selected retrieval source may not surface the page. The system may then fetch the page but decline to cite it, or it may use the page for a narrow factual claim while relying on another source for the broader answer.

    The practical distinction is important. A missing citation does not, by itself, show that a page lacks authority or relevance. It may reflect an earlier routing, retrieval or parsing decision that is invisible in the final response.

    Repeated prompts expose pipeline-level variability

    Three identical inputs move through different branching retrieval paths and produce different sets of source cards.

    Green examined 1,000 prompts, running each as many as 10 times, and recorded 9,946 completed searches, as reported by CrushPress.AI. Labrador was the primary search source in 88.1% of those runs, followed by Bright at 9.9%, Oxylabs at 1.7% and SERP at 0.3%.

    Most prompts remained on one primary source, but 11.6% switched sources across repeated runs. For prompts that switched, reported URL overlap declined from 0.273 to 0.149, while domain overlap declined from 0.265 to 0.155. Green characterized those changes as approximately 45% less URL overlap and 42% less domain overlap.

    Those overlap figures measure consistency between result sets; they should not be read as a page’s probability of earning a citation. Their significance is structural: a change in retrieval route can materially change the pool of domains and URLs available to support an answer.

    Mohanadasan observed a different distribution while examining two days of raw network traffic from one logged-in Pro account. His sample contained about 1,240 source records from a few dozen searches. Although he found the same four result-source values, Bright had a larger role in his sample, particularly for commercial, shopping, finance, weather and local queries. SERP appeared mainly with news-oriented results, while Labrador included established publishers and reference sites; Bright and Oxylabs were associated with their namesake data providers.

    The differing distributions are not necessarily contradictory. The studies used different prompts, observation methods, sample sizes and account contexts. Together, as presented in the source article, they suggest that no single observed pipeline mix should be assumed to represent every query class or user session.

    Search can be skipped, rewritten or expanded

    Pipeline selection matters only after the system decides to search. Mohanadasan reported that ChatGPT first classified some requests through a turn-use-case field. Some apparently current prompts were categorized as text tasks and did not trigger a web search. When that happens, no current page can be fetched or cited, regardless of how well it is optimized.

    Queries that received more extensive reasoning could travel in the opposite direction. The reported traces showed branching searches that included site-specific probes, pricing checks and searches for competitors the user had not named. Consequently, a publisher may be competing for retrieval against results generated from several machine-created subqueries, not merely the exact wording entered by the user.

    This makes prompt-level visibility difficult to reduce to conventional rank tracking. The same surface question can lead to no search, a relatively direct search or a multi-step investigation. Each path creates a different candidate set before citation selection begins.

    Fetched, cited and mentioned are different outcomes

    Blank webpage cards are progressively narrowed from a large candidate pool to a few cards linked to a final answer.

    Mohanadasan separated source participation into three useful states: fetched, cited and mentioned. A fetched page enters the system’s working context. A cited page is displayed as support for a claim. A mentioned brand may appear in the prose without its own site serving as visible evidence.

    OutcomeWhat it indicatesWhat it does not establish
    FetchedThe page was retrieved for possible use.That users saw it or that it supported a final claim.
    CitedThe page was presented as evidence for part of the answer.That it was the only source consulted or the preferred source in every run.
    MentionedThe brand or entity appeared in the response.That its own website was retrieved or cited.

    The source article illustrates the distinction with a small commercial-query sample. Reddit and YouTube were both fetched frequently, but Reddit received citations while YouTube did not. Mohanadasan attributed the difference to accessible text: Reddit threads exposed usable copy, whereas YouTube search results often supplied metadata rather than full transcripts. Because the sample was limited, this should be treated as an observed pattern rather than a universal rule about either platform.

    Source roles also varied by claim type. Vendor pages supported first-party facts such as prices and specifications, while third-party pages were more likely to support comparative recommendations. In some cases, ChatGPT appeared to seek an official pricing page but use a third-party source when the official information was hidden behind JavaScript or otherwise difficult to parse.

    The broader implication is that citation eligibility depends on both relevance and usability. A page can contain the right information yet lose the visible citation if the information is inaccessible, ambiguous or less suitable for the particular claim than another source.

    A better framework for measuring ChatGPT visibility

    Because routing and search behavior can change between runs, citation monitoring should emphasize distributions rather than isolated answers. Repeated tests can show how often a domain appears, whether the cited URL changes, which claim types attract first-party or third-party support, and how volatile the results are. The studies reported here do not establish a universal number of repetitions, so testing depth should be documented instead of presented as a fixed standard.

    Measurement should also keep brand inclusion separate from source attribution. Citation share, mention share and fetched-page data answer different questions. Combining them into one visibility score can conceal whether a brand is absent from the answer, present without evidence from its own site, or retrieved but not shown to the user.

    Key takeaways

    • A citation is produced by a chain of classification, routing, retrieval and evidence-selection decisions.
    • Repeated prompts are necessary to reveal variability; a single response cannot represent a stable source position.
    • Search eligibility should be evaluated separately from citation performance because some prompts may not trigger web retrieval.
    • Fetched pages, visible citations and uncited brand mentions should be tracked as distinct outcomes.
    • Plain HTML, clearly labeled facts, accessible prices and specifications, and substantial text improve the chance that retrieved information can support a claim.
    • First-party pages and independent coverage serve different evidentiary roles, so visibility work should account for both.

    As AI search measurement matures, the most durable approach will be to record uncertainty rather than hide it. Publishers that make evidence easy to retrieve and interpret, while measuring performance across repeated runs and source types, will be better equipped to understand citation changes as the underlying pipelines evolve.

    References

  • ChatGPT Ad Generation Puts Review Ahead of Automation

    ChatGPT Ad Generation Puts Review Ahead of Automation

    A reported ad-generation feature inside ChatGPT Ads could shorten the path from campaign setup to a usable creative variation. The important distinction is that the interface appears to generate a draft for approval, not a finished ad that bypasses advertiser judgment.

    For marketers, the practical value lies in faster iteration. The corresponding risk is treating generated copy as campaign strategy rather than as a starting point that still needs brand, accuracy, and performance review.

    What the reported workflow actually automates

    A visual workflow turns campaign inputs into several advertising drafts that await human selection.

    CrushPress.AI reported that an option to generate ads appears under the ChatGPT Ads platform’s ad-creation controls. According to the report, the system produces an ad variation using the advertiser’s website and campaign settings, then presents it for review, editing, and activation.

    That sequence matters. The reported interface positions artificial intelligence as a drafting layer within a conventional approval workflow. The marketer remains responsible for deciding whether the variation accurately reflects the offer, fits the campaign, and is ready to run.

    The report also describes a quick duplication option. Used carefully, that could support faster variation building: an advertiser could copy an existing ad, adjust one meaningful element, and compare the result with the original. The screenshot evidence does not, however, establish how widely the generation feature is available or how its output performs.

    Key takeaways

    • The reported tool uses website information and campaign settings to produce an ad variation.
    • Its workflow retains a human checkpoint before an ad is activated.
    • A duplication control could make structured creative variation easier, although speed alone does not create a sound experiment.
    • Generated copy still requires checks for factual accuracy, brand fit, campaign intent, and expected business value.
    • The available report shows an interface preview, not evidence of reach, output quality, or return on investment.

    Where generation can help and where it cannot

    Ad generation is most useful when the strategic inputs are already clear. A defined audience, offer, objective, and brand position give the system boundaries within which to draft. If those inputs are weak or inconsistent, quicker copy production can simply multiply the ambiguity.

    The feature may reduce mechanical work involved in producing a first variation. It cannot determine by itself whether a claim is sufficiently supported, whether the message creates the right expectation after the click, or whether a variation addresses the campaign’s actual constraint. Those are business and editorial judgments.

    The reported reliance on a website also introduces a source-quality issue. A generated ad may inherit unclear positioning, stale language, or overly broad claims from the page it uses. The output should therefore be checked against the current offer and campaign brief rather than assumed to be reliable because it originated inside the advertising platform.

    A review standard for AI-generated ads

    A marketing team checks an AI-generated ad mockup for imagery, layout, and approval criteria.

    A useful approval process begins with fidelity: the ad should describe the offer accurately and avoid introducing promises that the destination page cannot support. Reviewers should then assess whether the message reflects the intended audience and campaign objective instead of merely sounding polished.

    Brand review should cover voice, terminology, and the impression created by the ad as a whole. A grammatically clean variation can still be wrong for a brand if it exaggerates urgency, flattens an important distinction, or uses language the organization would not otherwise publish.

    Performance review requires discipline as well. The duplication control described in the report could encourage a large volume of near-identical ads. Marketers can preserve learning value by changing a deliberate variable, recording the hypothesis behind it, and judging results against the campaign’s established success measure. Generation increases the supply of options; it does not replace experimental design.

    The larger implication for campaign operations

    Embedding generation directly in an ad manager reduces the distance between source material, campaign configuration, and creative production. That convenience could lead to more variations being drafted and submitted, a commercial benefit that CrushPress.AI identified as potentially helpful to OpenAI’s advertising revenue.

    For advertisers, the more consequential change may be operational. As drafting becomes easier, quality control becomes the scarce capability. Teams will need clear ownership for approving claims, protecting brand standards, and deciding which variations deserve budget.

    The feature should therefore be evaluated less as an autonomous creative system and more as a workflow accelerator. Its long-term usefulness will depend on whether advertisers can turn faster production into better-controlled learning rather than simply a larger inventory of ads.

    References

  • ChatGPT Ads Expand Markets, Formats and Campaign Controls

    ChatGPT Ads Expand Markets, Formats and Campaign Controls

    OpenAI’s reported advertising expansion is taking shape on two fronts: broader geographic access and a test that could place several advertisers within one ChatGPT ad space. Together, these changes point toward a more mature ad marketplace built around commercially relevant conversations.

    For advertisers, the immediate value lies in expanded targeting and more familiar campaign controls. The larger strategic question is whether multi-advertiser placements can support product discovery without making conversational results feel crowded or less useful.

    Key takeaways

    • OpenAI is reportedly adding the U.K., Japan, South Korea, Brazil and Mexico to the geographic options available beyond the U.S., Canada, Australia and New Zealand.
    • A limited test combines ads from multiple relevant advertisers in one placement rather than showing only one sponsored result.
    • The tested format reportedly uses a second-price auction, introducing established digital-ad auction mechanics to conversational discovery.
    • Ads Manager Beta is adding more flexible budgets, bidding transitions, custom CPM limits and bulk editing.
    • The report does not provide performance benchmarks, placement-level details or a timetable for turning the limited test into a wider release.

    Market expansion and format testing address different constraints

    The geographic expansion increases where advertisers can target campaigns. According to the supplied CrushPress.AI report, the U.K., Japan, South Korea, Brazil and Mexico are being added beyond the previously listed markets of the U.S., Canada, Australia and New Zealand. That widens access, but it does not by itself change how many advertisers can appear in a placement.

    The multi-advertiser test tackles the supply side of the marketplace instead. The report says OpenAI is testing the format across a limited number of ChatGPT ads, grouping several relevant advertisers in a single space. If expanded, that design could create more opportunities to participate in high-intent conversations without requiring a separate ad slot for every advertiser.

    These are therefore complementary developments: geographic targeting broadens the addressable audience, while a multi-advertiser unit could increase the advertising options presented within an eligible interaction. Neither change, based on the available report, establishes how frequently users will encounter ads or which types of conversations will qualify.

    A multi-advertiser unit changes the competitive context

    Three distinct generic product cards share one advertising space beside a blank conversational panel.

    A single sponsored result gives one advertiser the visible opportunity within its placement. A grouped unit creates a comparison environment: relevance still matters, but the advertiser’s offer may also appear alongside alternatives at the moment a user is researching a product or service.

    The report says the test uses a second-price auction model. In general, this auction structure determines payment with reference to competing bids rather than automatically charging the winner its full bid. Its use would make the buying mechanism recognizable to experienced digital advertisers, although the source does not disclose the complete ranking formula, pricing rules or role of quality and relevance signals.

    That missing context matters. More advertisers in one unit could improve choice and product discovery, which the report identifies as OpenAI’s aim. It could also divide attention among neighboring offers. Advertisers would therefore need placement-specific evidence before treating results as equivalent to conventional search, display or social inventory.

    Ads Manager Beta is becoming more operationally familiar

    A person adjusts an unlabeled control on a modular digital advertising campaign interface.

    The campaign-management changes described in the report reduce several practical barriers to experimentation. Existing campaigns can reportedly move from lifetime budgets to daily budgets, while CPM campaigns can transition to CPC bidding in one click. Impression-based campaigns gain custom maximum CPM bids, and bulk editing is being added within the Ads Manager interface.

    Daily budgets will reportedly operate as average daily budgets with weekly pacing flexibility. That distinction is important for campaign oversight: an average allows delivery to vary from one day to another, so advertisers should evaluate spend against the applicable pacing period rather than assume an identical amount will be spent every day.

    Collectively, the controls resemble capabilities buyers already use elsewhere. Familiarity can simplify setup and budget changes, but it does not make ChatGPT inventory interchangeable with other channels. CPC and CPM optimize around different billable events, and conversational placements may produce different attention, comparison and conversion patterns.

    Advertisers need evidence beyond access and interface upgrades

    The reported updates make it easier to launch and modify campaigns, but the source provides no results for click-through rates, conversion rates, incremental lift or advertiser return. It also does not specify how multi-advertiser units will be labeled, how ads will be ordered inside the placement or which reporting dimensions will distinguish them from single-advertiser units.

    A measured evaluation would separate three questions: whether the available audience matches the campaign’s market, whether the buying model aligns with its objective, and whether the placement produces incremental business outcomes. CPC may make sense when traffic is the immediate goal, while CPM can suit reach or visibility objectives; neither pricing model proves downstream value on its own.

    Creative strategy may also need to account for direct comparison. In a multi-advertiser setting, a clear product distinction, relevant offer and accurate destination experience can become more important because users may see competing options together. This is a strategic implication of the reported format, not a performance finding from the limited test.

    The test will be defined by relevance, measurement and user trust

    The expansion suggests that OpenAI is assembling recognizable components of an advertising platform: auctions, flexible bidding, budget controls, bulk operations and international targeting. The distinctive variable is the conversational environment in which those components operate.

    Whether the model scales will depend on questions the available report leaves open, particularly placement relevance, transparent measurement and the effect of multiple sponsored choices on the user experience. The most informative next developments will be evidence about performance and disclosure standards, not simply the number of available markets or campaign controls.

    References

  • Unlocking ChatGPT Ad Secrets: Insights for 2026 Marketing

    Unlocking ChatGPT Ad Secrets: Insights for 2026 Marketing

    I’ve come across some intriguing research from Princeton and UW recently that sheds light on a rather surprising aspect of AI – it’s apparent tendency to conceal sponsorship nearly 65% of the time. As I pondered on this, it struck me how crucial this finding is for those of us navigating the evolving landscape of AI-driven marketing strategies.

    This revelation made me question how we’re measuring advertising effectiveness. Are we truly accounting for all variables, especially those hidden from plain sight? For those of us invested in Answer Engine Optimization (AEO), this piece of the puzzle could significantly tweak how we approach our measurement techniques and refine our marketing strategies for 2026.

    What does this mean for each of us in marketing and advertising? It’s a call to action to re-evaluate and possibly overhaul our current strategies, ensuring we adapt to these covert tendencies within AI functionalities. I’m convinced that understanding these nuances will empower us to craft more transparent and effective campaigns, ultimately enhancing our overall AEO outcomes.

    While AI continues to surprise us with its capabilities, I find it crucial to stay updated and adaptable, utilizing insights like these to steer our strategies intelligently. How do you plan to integrate this newfound knowledge into your 2026 marketing strategy?


    Inspired by this post on HiGoodie Blog.


    crushpress.ai community screenshot