Category: Business

  • Anthropic Profitability and IPO Outlook: What to Watch

    Anthropic Profitability and IPO Outlook: What to Watch

    If you are weighing Anthropic ahead of a possible IPO, the central question is not whether its revenue is growing. It is whether the company can turn that growth into durable profit after compute, cloud-partner fees, model training, stock compensation, and every other consequential cost are counted.

    The available numbers point to a sharp improvement, but they remain third-party estimates rather than audited public-company results. Anthropic appears to have crossed an important profitability threshold. That makes the business more IPO-ready; it does not tell you whether the eventual shares will be attractively priced.

    Key takeaways

    • Anthropic is estimated to have reached adjusted operating profit in Q2 2026, producing $570 million on $11.6 billion of quarterly revenue, before increasing that profit to $940 million in Q3.
    • Its estimated gross margin rose from 21% in Q1 2025 to 57% in Q3 2026, while compute cost fell from $2.41 to $0.54 per dollar of revenue. That combination, rather than revenue growth alone, explains the profit turn.
    • The frequently cited $69.7 billion revenue figure is an August 2026 annualized run rate, not revenue already earned over a full year. The 2026 full-year revenue forecast is $56 billion.
    • Adjusted profit excludes stock-based compensation and other charges that can materially affect GAAP results. An IPO filing will need to show the reconciliation, cash flow, compute commitments, customer concentration, and fully diluted share count.
    • Even a strong operating business can be a poor investment at the wrong valuation. The offering price matters just as much as the growth story.

    The profit turn is meaningful, but the definition matters

    Anthropic’s estimated quarterly progression shows more than a company growing its way out of a fixed-cost base. It shows improving unit economics. Gross margin measures revenue after the cost of serving models, while compute cost per dollar of revenue also incorporates the cost of training new models. Adjusted operating income then subtracts operating expenses but excludes stock-based compensation.

    The change across five representative quarters is substantial:

    QuarterEstimated revenueGross marginCompute cost per $1 of revenueAdjusted operating incomeAdjusted operating margin
    Q1 2025$0.41B21%$2.41-$1.58B-385%
    Q4 2025$2.01B38%$1.27-$2.47B-123%
    Q1 2026$4.20B43%$0.73-$1.93B-46%
    Q2 2026$11.60B52%$0.58$0.57B4.9%
    Q3 2026$17.30B57%$0.54$0.94B5.4%

    These are modeled figures covering January 2025 through September 2026. They should be treated as a directional view until official financial statements confirm them.

    Three things are happening at once. Quarterly revenue expanded from $4.2 billion to $11.6 billion between Q1 and Q2 2026. Gross margin crossed 50%. Compute cost per revenue dollar continued falling even as the business grew. If revenue had increased while compute efficiency remained stuck at its early-2025 level, the company would still have been spending more on compute than it generated in revenue.

    The caution is in the final column. A 5.4% adjusted operating margin leaves only a little more than five cents of adjusted operating profit per revenue dollar. That is a real milestone, but not a large buffer against price reductions, higher usage, partner costs, or another increase in training expenditure.

    The annual swing is even more dramatic. Anthropic is estimated to have lost $7.98 billion on $4.62 billion of revenue in 2025. The 2026 projection calls for $1.19 billion of adjusted operating income on $56 billion of revenue, a margin of 2.1%. Because that full-year outcome includes a forecast for Q4 and excludes stock compensation, it should not be mistaken for confirmed GAAP profitability.

    When an IPO filing arrives, go directly to the reconciliation between adjusted and GAAP operating income. Record the stock-based compensation, financing-related charges, and any expense classifications excluded from management’s preferred measure. If the profitable result disappears after those items, describe Anthropic as adjusted-profitable rather than simply profitable.

    Run-rate revenue is the number most likely to be misread
    A stream of coins passes through a measuring chamber while a glowing projected path extends beyond the smaller amount physically accumulated.

    Run rate takes one month’s revenue and multiplies it by 12. It answers a useful but narrow question: what would annual revenue look like if that month’s pace continued unchanged? It does not mean the company collected that amount during the preceding year, and it does not guarantee that the pace will continue.

    Anthropic’s estimated annualized run rate increased from $5.8 billion in September 2025 to $69.7 billion in August 2026. The largest monthly jump came between April and May 2026, when the run rate rose by $18.5 billion as several large enterprise agreements began billing.

    That billing pattern is precisely why you should keep three different figures separate:

    1. $17.3 billion is estimated revenue booked during Q3 2026.
    2. $56 billion is the forecast for revenue across the full 2026 calendar year.
    3. $69.7 billion is August 2026 revenue annualized as though one month’s pace persisted for 12 months.

    Run rate is not useless. In a business growing this quickly, trailing revenue can materially lag the latest sales pace. The mistake is applying a valuation multiple to annualized monthly revenue without testing whether new contracts recur, whether usage is committed, and whether a small number of customers caused the jump.

    For your eventual IPO analysis, use reported trailing revenue as the main valuation denominator. Keep run rate as a momentum indicator. Then compare both with remaining contractual obligations, customer concentration, renewal data, and revenue recognized from minimum commitments rather than actual usage. That prevents a strong month from silently becoming a full-year assumption.

    Revenue mix will decide whether margins keep improving

    Anthropic does not earn the same margin on every dollar. Its Q2 2026 estimates show a 35-percentage-point spread between the highest- and lowest-margin business lines:

    Business lineShare of Q2 2026 revenueEstimated gross marginWhat to watch
    Direct API33.8%64%Whether price per token falls faster than inference cost
    Cloud partner API23.1%34%Partner fees, accounting presentation, and channel mix
    Claude Code19.4%48%Compute consumed by long agentic sessions
    Team and Enterprise seats12.6%69%Usage per seat, renewals, and contract durability
    Pro and Max subscriptions11.1%39%Heavy-user economics and subscription pricing

    The Q2 mix produced a blended gross margin of 52%. Team and Enterprise seats led at 69% because a fixed per-seat price exceeded average usage cost. Direct API revenue followed at 64%. Cloud partner API revenue, sold through Amazon Bedrock, Google Cloud Vertex AI, and Microsoft Foundry, carried the lowest margin at 34%.

    The cloud-partner number contains an accounting issue that matters for valuation. Anthropic is understood to record partner sales at the full price paid by the customer and record the partner’s share as a cost. A company recognizing the same transaction net would report lower revenue and a higher gross-margin percentage even if the underlying cash economics were identical.

    That does not make either presentation inherently wrong. It does mean a revenue multiple can create a misleading comparison between companies with different channel accounting. Compare enterprise value with both revenue and gross profit, and check the eventual accounting policy before treating Anthropic’s top line as directly comparable with a competitor’s.

    Mix can move margins in either direction. More Team and Enterprise seat revenue should help while average usage remains below the pricing ceiling. More cloud-partner revenue can expand distribution but dilute reported gross margin. Claude Code sits between those outcomes: it represented 19.4% of Q2 revenue at a 48% gross margin, with longer agentic sessions consuming more compute than ordinary API requests.

    Claude Code’s share stayed between 15% and 21% of company run-rate revenue from September 2025 through August 2026. It grew with Anthropic rather than separating from the rest of the business. Watch its gross margin and retention, not just its revenue, because rapid adoption is less valuable if increasingly long sessions absorb the incremental dollars.

    What the IPO filing needs to prove
    A transparent AI business engine with computing, customer, cash, and cost components is examined under lenses before a closed public-market doorway.

    The optimistic financial path assumes that inference hardware becomes cheaper per token and training expenditure grows more slowly than revenue. Under those assumptions, Anthropic reaches $121.4 billion of revenue and an 11.4% adjusted operating margin in 2027, followed by $187.6 billion and a 17.9% margin in 2028. Gross margin would rise to 60% and then 63%.

    Those figures are a scenario, not an outcome you should build into a valuation without a stress test. They require revenue to more than double in 2027 while margins continue expanding. They also assume that efficiency gains outrun both competitive price pressure and the cost of training new frontier models.

    Use the eventual filing to answer six questions before deciding what the IPO is worth:

    1. Does profitability survive GAAP accounting? Start with GAAP operating income, then identify every adjustment. Stock-based compensation is an economic cost because it dilutes shareholders even when it does not consume cash in the period.
    2. Does profit convert into cash? Compare operating income with operating cash flow and free cash flow. Look for large changes in deferred revenue, payables, prepaid compute, and capitalized costs that could make accounting profit look stronger than cash generation.
    3. How binding are the compute commitments? A reported $1.25 billion monthly compute agreement associated with Colossus clusters, whose full cost was expected to begin appearing in the second half of 2026, is a major unverified input. Check the filing for duration, minimum-purchase terms, unused-capacity risk, and the ability to renegotiate.
    4. How durable is enterprise demand? Anthropic is estimated to have generated 78% of H1 2026 revenue from business customers. That is attractive only if renewals are strong and revenue is not concentrated among a few contracts. Look for customer concentration, net revenue retention, contract duration, and remaining performance obligations.
    5. Can pricing hold? Lower-cost open-weight models can pressure API prices and give large customers leverage in negotiations. Test whether future gross-margin expansion depends on lower compute cost alone or also assumes stable selling prices.
    6. What are you paying for the outcome? Calculate enterprise value using the offer price, fully diluted shares, debt, and cash. Compare it with trailing revenue, gross profit, GAAP operating results, and cash flow. Do not use the $69.7 billion monthly run rate as though it were audited annual revenue.

    The cleanest way to prepare is to save the current estimates as a provisional worksheet and replace them line by line when official disclosures arrive. Begin with GAAP income, stock compensation, cash flow, compute obligations, partner accounting, customer concentration, and dilution. Only then apply the offering valuation. Anthropic’s estimated profit turn justifies close attention, but no level of growth makes every IPO price attractive.

    References


  • Professional Ghosting: How to Close the Loop in Business

    Professional Ghosting: How to Close the Loop in Business

    The promised update has passed. You delivered the proposal, joined the interview, signed the paperwork, or took the call. Now the other person has disappeared, and you are deciding whether to follow up again, wait quietly, or write off the relationship.

    You do not need to keep guessing. A clear follow-up boundary can protect your time without turning a delayed reply into a confrontation. The same standard can help your team stop creating this problem for candidates, vendors, partners, clients, and professional contacts.

    Professional ghosting begins where commitment ends

    A slow reply is not automatically ghosting. People get pulled into urgent work, approvals stall, budgets change, and decisions take longer than expected. The defining problem is not the delay. It is the abandoned commitment.

    Professional ghosting happens when someone initiates or actively advances a business process, creates a reasonable expectation of another step, and then stops communicating without closing that process. The pattern is especially clear when a person requests a proposal, paperwork, an introduction, or participation in an interview process and does not acknowledge the work after it arrives.

    This distinction matters because it tells you what to respond to. You are not demanding instant access to another person. You are asking them to account for a commitment they chose to make.

    A useful test is to identify the last explicit agreement. Did someone promise an update by a named date? Ask you to prepare something? Say they would arrange another conversation? Accept responsibility for getting an answer? If no commitment was made, you may simply have an undeveloped lead. If a commitment was made and abandoned, you have an open loop that needs a boundary.

    The business cost extends beyond an unanswered inbox:

    • Calendar uncertainty: You may hold time, delay another decision, or reserve delivery capacity for work that is no longer moving.
    • Unpaid effort: A customized proposal, interview, review, introduction, or contract document consumes real attention even when no transaction follows.
    • Distorted pipeline data: An opportunity that is functionally dead can remain marked as active because nobody recorded the decision.
    • Reputational spillover: Candidates, consultants, vendors, and former colleagues may remember how the process ended and share that experience when your name comes up.
    • Weaker future communication: Once missed commitments become normal, people stop trusting dates and next steps from the organization.

    The answer does not have to be yes. Nobody is entitled to a contract, job, partnership, or detailed explanation. But silence transfers the follow-up work and planning cost to the person who did not create the uncertainty. A direct no is usually easier to manage because it lets everyone release time and make the next decision.

    Follow up from the commitment, not from your anxiety

    A calm professional reviews a blank planner at an organized desk with one sealed envelope, a face-down phone, and a closed laptop.

    Repeatedly checking in without a decision rule makes you feel active while leaving the underlying uncertainty untouched. A better follow-up points to the agreed next step, asks for a small status decision, and explains what you will do if no answer arrives.

    Match the message to the state of the conversation

    • A promised update is overdue: Follow up after the promised date has passed. Name that date without accusation and ask whether the matter is active, paused, or closed.
    • You sent a requested deliverable: Confirm that it arrived, then ask what decision or review step follows. Do not keep producing additional work to provoke a reply.
    • No next step was agreed: Treat the conversation as interest, not an active opportunity. Ask for a concrete next action only if you still want one.
    • You are holding time or capacity: State when you need to release it. This is operational information, not a threat.
    • The other person already missed several self-imposed commitments: Stop asking for another vague update. Close the opportunity on your side and require a fresh plan if they return.

    Use one message to request a decision

    Subject: Status of [project or opportunity]

    Hi [Name], you mentioned that I would receive an update by [promised date], so I wanted to close the loop. Is this moving forward, paused, or no longer under consideration? Any of those answers is fine; I need the current status so I can plan [capacity, scheduling, or the next deliverable]. If the timing is still uncertain, a simple paused is enough.

    This works because it lowers the effort required to answer. The recipient does not have to compose a defense or manufacture certainty. They only have to identify the present state.

    Avoid messages such as just checking in or circling back. They do not tell the recipient what you need, and they do not establish what happens next. Also avoid writing a long account of the work you completed. If the person already knows what they requested, repeating every detail can make a straightforward status request sound like a dispute.

    Close the opportunity when waiting has a cost

    If your decision request remains unanswered and you need to plan around the uncertainty, send a final operational note:

    Hi [Name], since I have not received an update, I am marking this opportunity inactive and releasing the time associated with it. If the project becomes active again, feel free to reconnect. We can review the scope, timing, and availability based on the situation then.

    This is not a tactic for forcing a response. It is a record of the decision you are entitled to make: you will no longer reserve attention or capacity for an unconfirmed opportunity. Once you send it, act accordingly. Update the pipeline, release the calendar hold, and stop chasing.

    Handle warm introductions without recruiting the introducer

    A warm introduction carries an extra relationship. The person who connected you has attached some of their reputation to the exchange, so the introduction should create more accountability, not less.

    Do not immediately ask the introducer to pressure the silent party. Follow up directly first. If the process stays unresolved, give the introducer a neutral closure update:

    Thanks again for connecting us. We spoke, but we did not establish a next step, and I have now closed the conversation on my side. No action is needed from you; I just did not want to leave your introduction unresolved.

    That message protects the introducer from wondering what happened without turning them into a collections agent for attention. Keep it factual. Do not speculate about motives or invite them to take sides.

    Decide whether to reopen the relationship

    People sometimes return after a long silence. You do not have to punish them, but you also do not have to restore the old assumptions. Evaluate the return using three questions:

    • Did they acknowledge the gap? Ownership is more useful than an elaborate excuse. Someone who pretends nothing happened may repeat the pattern.
    • Is there a real decision now? Ask what changed, who owns approval, and what the next committed action is.
    • Can you reduce the cost of another disappearance? Restart with a smaller defined step, written responsibilities, and no speculative work beyond what the opportunity justifies.

    A returned email does not restore expired availability. Reconfirm scope and timing instead of silently absorbing the disruption into your schedule.

    Say no clearly without damaging the relationship

    Most closure messages do not require a long explanation. They need a decision, the current status, and any legitimate next step. Clarity is kinder than a soft phrase that keeps the recipient waiting.

    SituationWhat to sayWhat to avoid
    The fit is wrongWe will not be moving forward because this does not match our current requirements.Excessive praise followed by an ambiguous maybe.
    Priorities changedThe project is paused, and we do not have an approved restart point.We will circle back soon when no follow-up is planned.
    Another option was selectedWe chose a different direction and have closed this evaluation.A defensive comparison of every candidate or vendor.
    The decision is delayedWe have not made the decision. I missed the update I promised, and the next checkpoint is [date].Letting the original deadline pass without acknowledgment.
    You dropped the ballI failed to close this loop. I am sorry. The current status is [status].Restarting the thread as though the silence never happened.

    Decline a proposal or partnership

    Hi [Name], thank you for the time and work you put into this. We have decided not to move forward with [proposal or partnership]. The reason at a high level is [brief, accurate reason, if useful]. This closes the evaluation on our side. I appreciate your participation and wanted to give you a definite answer.

    Do not offer future work merely to soften the no. If you genuinely want to revisit the relationship under identifiable conditions, name them. Otherwise, a clean ending is more respectful than a fictional possibility.

    Report a delay before it becomes ghosting

    Hi [Name], I promised an update by [date], but the decision is not ready. [Approval, budget, or priority] remains unresolved. The next real checkpoint is [new date or event]. You do not need to do anything in the meantime. If that timing no longer works for you, I understand.

    A delay notice is valuable even when it contains no new decision. It proves that someone still owns the process and prevents the recipient from having to chase information you already know is missing.

    Own a missed commitment

    Hi [Name], I said I would update you and did not. That was my mistake. The current status is [active, paused, or closed]. [State the next action, if one exists.] I am sorry I left you without an answer.

    Do not bury the acknowledgment under an account of how busy the team became. The recipient needs the truth and the status. An explanation is optional; ownership is not.

    Build closure into the workflow, not into good intentions

    Two professionals exchange an unmarked folder over a project table where blank wooden tiles form a complete circle.

    Ghosting often persists because the organization records acquisition activity but not closure responsibility. A system may track calls booked, interviews completed, proposals requested, and documents sent while leaving nobody accountable for the final message.

    Every active external conversation should have four visible fields:

    • Current state: Exploratory, active evaluation, waiting on us, waiting on them, paused, accepted, or declined.
    • Named owner: One person responsible for the next communication. A department cannot send an email.
    • Next commitment: The specific decision, document, meeting, or update that has been promised.
    • Trigger: The date or event that tells the owner to act, even if the decision is still pending.

    At the end of a meeting, say the handoff aloud: who will do what, what the recipient should expect, and what will happen if the answer is not ready. A transcript or meeting summary can preserve that agreement, but recording a promise is not the same as fulfilling it.

    Make the initiator responsible for closure

    A practical ownership rule is that the person or team requesting effort owns the next acknowledgment until another person explicitly accepts the handoff. If your company asks for an interview, custom proposal, security review, NDA, sample, introduction, or planning session, assign the response owner before the request goes out.

    Before asking someone to do substantial work, confirm internally:

    • What decision will this work inform?
    • Who can actually make or approve that decision?
    • Who will acknowledge receipt?
    • Who will communicate a delay or rejection?
    • What event closes the process if the project loses priority?

    If nobody can answer those questions, the process is not ready to consume another person’s time.

    Use automation to surface promises

    Automation can create a reminder when an update is promised, flag a waiting-on-us record, prepare a draft, or show an owner all overdue commitments. It should reduce the chance that a relationship disappears inside a crowded inbox.

    It should not invent a decision, send an insincere rejection, or remove human judgment from a sensitive relationship. Efficiency should leave more room for judgment and professional courtesy. It should not enable a team to open more conversations than it can responsibly finish.

    Audit closure debt at your normal planning cadence

    When you review work in progress, filter for external conversations marked waiting on us, records whose trigger has passed, and opportunities with no defined next step. For each one, choose an actual state: advance it, pause it with an update, decline it, or assign a new owner.

    Do not measure professionalism by inbox volume. Track the conditions that reveal whether your process can finish what it starts: overdue external commitments, open records without an owner, requested deliverables without an acknowledgment, and inactive opportunities still counted as live. Your own trend is the useful benchmark. The purpose is to reduce unresolved commitments, not create a decorative score.

    Key takeaways

    • Professional ghosting is an abandoned commitment, not merely a slow response.
    • Follow up by naming the agreed next step and asking whether the matter is active, paused, or closed.
    • If waiting affects your schedule or capacity, send a final closure note and release the time.
    • A warm introduction deserves extra care because the introducer’s reputation is part of the exchange.
    • You can decline without a detailed defense. State the decision, give a concise reason when useful, and remove false ambiguity.
    • Assign an owner, next commitment, and trigger whenever your team asks an external person to invest effort.
    • Use automation to reveal overdue promises, while keeping consequential relationship decisions under human ownership.

    Choose one unresolved conversation you own and close it now. Send the decision if you have it. If you do not, send the current status and the next honest checkpoint. That small habit is how professional trust survives changing priorities, crowded calendars, and uncomfortable answers.

    References


  • Commercial AI Token Costs: Budgeting Beyond List Price

    Commercial AI Token Costs: Budgeting Beyond List Price

    Your spreadsheet says one model is cheaper. Your invoice says otherwise. The gap appears because the spreadsheet priced the prompt and final answer, while production also paid for reasoning, repeated instructions, failed tool calls, retries, discarded drafts, and cache behavior.

    If you are choosing a commercial AI model or defending an AI budget, compare cost per accepted outcome, not cost per million tokens. That change turns a rate card into a forecast you can actually use.

    A token price is only one layer of your production cost

    Published input and output prices tell you the rate applied to certain tokens. They do not tell you how many tokens the model will consume before your application gets an acceptable result. A useful cost model therefore has three layers:

    • Unit rates: the applicable prices for input, output, reasoning, cache reads, cache writes, and any long-context tier.
    • Consumption: the number of tokens used by the prompt, retrieved context, system instructions, tool definitions, intermediate reasoning, and response.
    • Completion efficiency: how many attempts, revisions, and tool calls you pay for before the result passes your acceptance checks.

    The third layer causes many budget misses. A cheap attempt is not a cheap task if the attempt is rejected and repeated. Nor is a successful API response necessarily a completed business task. A coding agent that returns malformed code, a content model that produces an unusable draft, or a schema generator that fails validation has consumed tokens without delivering the outcome you intended to buy.

    In measured 2026 production usage, the categories commonly omitted from simple estimates represented 52.5% of billed tokens and added 70.4% above a list-price-only estimate. These percentages are not universal overhead rates. They are a practical checklist of what your own logging needs to capture.

    Cost commonly missedShare of billed tokensAdded cost versus list-price estimateWhat to inspect
    Invisible reasoning tokens22.4%38.6%Whether reasoning usage is returned separately from visible output
    Re-sent system prompts and tool schemas11.9%9.4%How much fixed context is transmitted on every model call
    Retried and discarded generations7.8%8.1%Every failed, rejected, or superseded attempt
    Long-context pricing above 200K tokens3.1%6.2%Requests crossing a provider’s long-context pricing boundary
    Failed tool calls and malformed structured output4.6%5.3%Calls that return successfully but fail downstream validation
    Unrecovered cache-write premium2.7%2.8%Cache entries written without enough subsequent reuse

    Do not solve this by applying one generic markup to every vendor quote. Instrument each category instead. A reasoning-heavy model, a tool-using agent, and a short classification call can have radically different overhead even when their visible prompts look similar.

    Falling rate-card prices do not remove this problem. Within a constant-capability mid-tier series from Q1 2023 through Q3 2026, the list-price index fell 91.4%, but real cost per completed task fell only 62.9%. Token consumption per completed task rose 4.3 times. The completed-task cost reached its low point in Q4 2024 and then increased 80% by Q3 2026 even as published rates generally continued downward. More capable reasoning behavior can consume part of the saving advertised on the price sheet.

    Compare models by accepted task, not by token rate

    Three abstract AI processing stations turn identical inputs into rejected fragments and one finished object that fits a quality-check fixture.

    A model comparison becomes useful only after the denominator represents something your business accepts. From May 4 through August 21, 2026, a standardized set of 14 production tasks was run across 11 commercial models. The resulting cost included billed reasoning, prompt repetition, cache activity, retries, and discarded output. The September 2026 prices and measured completed-task costs show why rate-card ranking and production ranking can diverge.

    ModelInput per 1M tokensOutput per 1M tokensMeasured cost per completed task
    GPT-5.4 nano$0.20$1.25$0.0219
    Gemini 3.1 Flash-Lite$0.25$1.50$0.0288
    Claude Haiku 4.5$1.00$5.00$0.0474
    GPT-5.6 Luna$1.00$6.00$0.0607
    GPT-5.4 mini$0.75$4.50$0.0627
    Claude Sonnet 5$2.00$10.00$0.0848
    Gemini 3.6 Flash$1.50$7.50$0.1040
    GPT-5.6 Terra$2.50$15.00$0.1662
    Gemini 3.1 Pro$2.00$12.00$0.1683
    Claude Opus 5$5.00$25.00$0.2131
    GPT-5.6 Sol$5.00$30.00$0.3447

    Several reversals matter when you shortlist a model. GPT-5.4 mini had lower published input and output prices than Claude Haiku 4.5, yet its measured task cost was $0.0627 versus $0.0474. Claude Sonnet 5 had higher published rates than Gemini 3.6 Flash but completed the task set for $0.0848 instead of $0.1040. At the frontier end, GPT-5.6 Sol and Claude Opus 5 shared the same $5.00 input price, but Sol cost 62% more per completed task, with the difference driven almost entirely by output volume.

    These results do not make one model universally cheaper. Your prompts, tools, input-to-output ratio, quality threshold, and retry policy may reverse the ranking again. Use published comparisons to choose candidates, then reproduce the comparison on your own workflow.

    1. Define completion before testing. For JSON-LD, completion might require parsable output that passes your validation checks. For a content brief, it might require every mandatory field and entity. An HTTP success code is not an acceptance criterion.
    2. Freeze a representative task set. Give every candidate the same source material, system instructions, tools, output requirements, and acceptance tests.
    3. Record every billable attempt. Keep rejected generations, malformed output, repair prompts, tool-call failures, and fallback calls in the numerator.
    4. Separate visible output from total usage. Store every usage field the provider exposes, including reasoning and cache categories where available.
    5. Compare only models that meet the quality gate. A low-cost result that cannot be used is a failed attempt, not a bargain.
    6. Divide total model spend by accepted completions. That figure is your effective task cost and the basis for a credible monthly forecast.

    Content costs multiply after the first draft

    Content teams often estimate AI spend from the tokens in one draft. That calculation stops before the expensive part: revisions, replacement drafts, citation repair, structural fixes, and output that never reaches publication.

    For 1,000 words of finished, publishable copy, the measured token cost included revision rounds and discarded generations. The difference between first-draft and finished cost was substantial across every tested model.

    ModelFirst-draft costAverage revision roundsDiscarded draftsFinished cost per 1,000 wordsFinished versus first draft
    GPT-5.6 Sol$0.0861.614%$0.2072.4x
    Claude Opus 5$0.0791.29%$0.1642.1x
    GPT-5.6 Terra$0.0431.817%$0.1142.7x
    Gemini 3.1 Pro$0.0361.919%$0.1012.8x
    Gemini 3.6 Flash$0.0242.426%$0.0843.5x
    Claude Sonnet 5$0.0321.513%$0.0742.3x
    GPT-5.6 Luna$0.0172.324%$0.0583.4x
    GPT-5.4 mini$0.0132.931%$0.0544.2x
    Claude Haiku 4.5$0.0162.122%$0.0513.2x
    Gemini 3.1 Flash-Lite$0.00414.145%$0.0245.9x
    GPT-5.4 nano$0.00344.448%$0.0216.2x

    The cheapest and most expensive first drafts were separated by roughly 25 to 1. After revisions and discards, finished costs were separated by about 10 to 1. Draft rejection narrowed the apparent advantage of the cheapest models.

    Discard rate was also more useful than list price for anticipating finished cost. Claude Sonnet 5 started at $0.032 per 1,000 words, above Gemini 3.6 Flash at $0.024. Sonnet finished lower, at $0.074 versus $0.084, because its discarded-draft rate was 13% rather than 26%.

    Build that distinction into your content operations. Give every generated asset a final status such as accepted, revised, or discarded, and associate all attempts with the same job identifier. Then calculate finished token cost from all spend attached to accepted copy, divided by accepted word count and multiplied by 1,000. Counting only the last successful generation erases the waste you are trying to manage.

    Keep the quality gate explicit. For an SEO or GEO workflow, your requirements may cover factual accuracy, source support, search intent, entity coverage, structure, brand constraints, and valid structured output. The exact rubric is yours, but it must be stable across models. Otherwise, a permissive review process can make a weak model look artificially inexpensive.

    The figures above cover model-token spend. They do not represent a fully loaded content cost. Your internal budget should add editorial review, fact-checking, workflow infrastructure, monitoring, and any human repair work rather than treating a low token figure as the total cost of publication.

    Budget by workload, then route each job to the right tier

    Different task objects move through a central routing hub toward small, medium, and large processing machines, with one path passing through a cache chamber.

    A single company-wide average hides the workflows most likely to break your budget. Agentic coding, customer support, retrieval-based research, document processing, sales personalization, and content production have different volumes, context sizes, output patterns, and failure modes.

    For a modeled 50-person company, the same mix of 157,400 monthly tasks cost $6,610 at the economy tier, $19,150 at the mid tier, and $48,670 at the frontier tier. That is a 7.4-times spread before changing the workload itself.

    WorkloadMonthly tasksFrontier tierMid tierEconomy tier
    Coding agent, 20-developer team14,800$18,350$7,140$2,510
    Customer support automation62,000$9,610$3,720$1,240
    Internal RAG research tool21,500$7,290$2,940$1,020
    Document and contract processing9,700$6,410$2,580$890
    Sales outreach personalization46,000$4,830$1,910$640
    Content marketing, 8-person team3,400$2,180$860$310
    All workloads157,400$48,670$19,150$6,610

    Volume alone does not reveal the expensive workflow. The coding agent ranked fourth by task count but was the largest monthly cost. At the frontier tier, it cost $1.24 per completed task, compared with $0.16 for customer support. Agentic workflows repeatedly call models, tools, and validation steps, so a task can contain much more billable activity than one support interaction.

    Build your forecast from accepted workload volume

    Your budget sheet should have one row per distinct workflow, not one row per provider. Separate content briefs from finished drafts, retrieval answers from document ingestion, and schema generation from schema repair. They may use the same API while having different cost behavior.

    • Workload identity: team, application, task type, model, and model version.
    • Demand: expected completed tasks, not merely API requests.
    • Usage: input, output, reasoning, cache-read, and cache-write tokens where exposed.
    • Workflow overhead: attempts, tool calls, validation failures, fallback calls, and discarded results.
    • Outcome: accepted, repaired, rejected, or abandoned.
    • Unit economics: total billed spend divided by accepted completions.

    Forecast monthly model spend by multiplying expected accepted-task volume by your measured cost per accepted task. Keep the rate-card calculation beside it as a reconciliation check, not as the primary forecast. A widening gap between the two tells you to investigate prompt growth, longer retrieved context, increased reasoning, lower cache reuse, tool failures, or a rising retry rate.

    Recalculate after changes to the model version, system prompt, tool schema, context strategy, output format, or acceptance threshold. Each can alter consumption or completion efficiency even when the published token rate stays fixed.

    Use routing instead of choosing one model for everything

    Model tier should be a workload decision. Economy models are strongest candidates when the task is constrained, output can be checked automatically, and failure is cheap to retry. Mid-tier models suit broader production work where reliability and cost both matter. Frontier models deserve the jobs whose ambiguity or quality requirement produces a measurable improvement worth their higher completed-task cost.

    That does not require moving every workflow downmarket. In the modeled company, moving only the two highest-volume workloads – customer support and sales personalization – to economy models while leaving the other four at the frontier tier reduced total monthly spend by 26%. Selective routing captured savings without imposing one capability tier on every task.

    Put a quality gate after the lower-cost route and send only failed or uncertain cases to a stronger model. Count both calls when escalation occurs. Otherwise, the first model appears cheaper in your dashboard while the fallback cost disappears into another service or team.

    Key takeaways

    • Published cost per million tokens is a unit rate. Your actionable metric is total billed spend per accepted task.
    • Log reasoning, repeated system context, cache activity, retries, discarded output, tool failures, and long-context pricing instead of hiding them in a generic contingency.
    • For content, calculate cost per 1,000 accepted words from every draft and revision associated with the finished asset.
    • Benchmark candidates on the same tasks and acceptance criteria. Compare costs only among models that clear the required quality threshold.
    • Route by workload. High-volume, tightly validated tasks may justify an economy model, while ambiguous or high-impact work may justify a more capable tier.
    • Refresh the forecast whenever the model, prompt, tools, context, output contract, or quality gate changes.

    Start with one workflow that already generates meaningful volume. Attach every billable attempt to an accepted or rejected outcome, calculate its effective cost, and use that result to challenge the rate-card estimate. Once the accounting works for one workflow, extend the same measurement to the rest of your AI stack and route each task on evidence rather than model reputation.

    References


  • Leading RevOps Firms: How to Choose a Fractional Agency

    Leading RevOps Firms: How to Choose a Fractional Agency

    You are not buying RevOps in the abstract. You are deciding whether an outside team can repair your revenue engine without slowing sales, damaging CRM data, or leaving you with an expensive system nobody internally knows how to run.

    The difficult part is that fractional leadership, managed operations, CRM implementation, enablement, and AI automation are often sold under the same label. The right choice depends less on which firm tops a general leaderboard and more on the work you need someone to own. This guide helps you identify that work, match it to leading RevOps firms, and test whether a candidate can deliver it.

    Key takeaways

    • Choose the engagement model before the agency. Embedded fractional ownership, managed RevOps, project implementation, and coaching solve different problems.
    • Match lifecycle breadth to the actual break. A problem spanning marketing, sales, onboarding, retention, and expansion needs broader coverage than a contained CRM or outbound project.
    • Do not mistake a long platform list for operational depth. Test the candidate against a real workflow, data model, integration, or handoff from your environment.
    • Make every AI claim concrete. Require a named workflow, defined data access, approval rules, evaluation criteria, logs, failure handling, and a human owner.
    • Replace generic ranking weights with your own priorities. Published 2026 methodologies give substantially different weight to leadership, platforms, AI implementation, and lifecycle scope.
    • Treat recognizable client logos as context, not proof of fit. Even the ranking methodologies used for this shortlist assigned notable clients only 5% of the total score.

    Choose the RevOps engagement model before the firm

    A leadership team compares three visual pathways representing fractional leadership, managed operations, and technical implementation services.

    Fractional describes how you access leadership or operating capacity. It does not guarantee that a senior operator will be embedded in your team, that the agency will configure systems, or that it will cover the complete customer lifecycle. Confirm the operating model in the contract rather than relying on the label.

    • Embedded fractional ownership: Choose this when no internal leader owns the revenue system across functions. The outside operator should make decisions, coordinate stakeholders, prioritize work, and remain accountable for implementation rather than merely recommend changes.
    • Managed RevOps or RevOps as a Service: Choose this when you have an ongoing queue of administration, reporting, automation, data, and process work but do not want to assemble an internal team. The central buying question is how strategic decisions and recurring execution are divided.
    • Project-based specialist: Choose this for a bounded migration, CRM rebuild, routing redesign, CPQ implementation, outbound system, or integration. A contained scope should have explicit deliverables, acceptance tests, change controls, and a handoff owner.
    • Coaching, methodology, or enablement: Choose this when your internal team can implement but needs a common sales process, operating language, management cadence, or training system. Do not buy advisory work if your real constraint is a lack of hands-on capacity.

    Map the failure before contacting vendors. Trace the customer path from acquisition through qualification, opportunity management, closed-won, onboarding, adoption, renewal, and expansion. Mark the point where ownership becomes unclear, data stops moving, or teams begin using conflicting definitions.

    If failures appear across Marketing Operations, Sales Operations, and Customer Success Operations, favor a full-lifecycle team. If the problem stays inside a known system or workflow, a specialist may be faster and easier to govern. If your team knows what to do but applies it inconsistently, coaching may be sufficient. If nobody has authority to decide what should happen, you need an accountable fractional leader before you need more tools.

    A useful buying brief fits in one sentence: We need an accountable owner to improve this lifecycle handoff in these systems, with success judged by these business and operational measures. If you cannot complete that sentence, use discovery to define the problem before committing to a large implementation.

    Leading RevOps firms, organized by the work they fit

    No firm is the universal best choice. The table below treats leading RevOps companies as a fit map: what each appears equipped to handle, followed by the issue you should validate before signing.

    FirmConsider it whenWhat to validate
    DomestiqueYou are a B2B SaaS company seeking embedded, full-lifecycle coverage across Marketing Operations, Sales Operations, Customer Success Operations, platform implementation, and agentic infrastructure. Its reported capabilities include more than 60 senior operators, work with more than 250 B2B organizations, and hands-on AI agents and MCP integrations.Confirm which senior operators will work on your account, their allocated capacity, and the leadership participation expected from your team. The fractional-agency assessment specifically notes that active client leadership involvement is important at the strategy layer.
    Go NimblyYou run a Salesforce- or HubSpot-centered growth-stage SaaS environment and need revenue architecture, technical execution, AI readiness work, or RevOps coaching. Its positioning combines AI-enabled GTM strategy with Salesforce, HubSpot, Outreach, and Salesloft experience.Define how much hands-on Customer Success Operations coverage is included. Also identify the exact team composition because reported delivery pace can depend on scope and staffing.
    SkaledYou need a modular intervention rather than complete outsourced ownership. Available services span fractional CRO or VP leadership, CRM and automation support, revenue enablement, outbound performance, and an AI GTM system. A NoFraud case study reports a 126% pipeline increase and 95% MQL growth over eight months, but that result is case-specific rather than a forecast for another company.Ask who coordinates work when your scope crosses leadership, administration, enablement, and AI practices. Confirm which result from the relevant case work is transferable to your market, team, and funnel.
    RevPartnersYou are committed to HubSpot and want an ongoing RevOps-as-a-Service model, lifecycle measurement, GTM engineering, or Clay-powered outbound automation. Its Revenue Performance Model connects acquisition, conversion, retention, and expansion.Test the required depth outside HubSpot and Clay. Salesforce-primary companies and teams requiring extensive hands-on Customer Success Operations should define those needs explicitly before assuming they are covered.
    FullFunnelYou need broad B2B GTM strategy plus Sales Operations, Marketing Operations, or managed RevOps. Its listed platform footprint includes HubSpot, Salesforce, Clay, Apollo, and n8n.Ask which lifecycle stages the proposed team will own, which it will support, and which remain with you. Platform breadth should be converted into named deliverables and accountable operators.
    OperatusYour requirements center on Salesforce CPQ, MuleSoft, systems integration, or managed RevOps in a stack that may also include HubSpot, Apollo, Salesloft, LeanData, Outreach, or Marketo. Those platform and consulting specialties distinguish its systems-oriented offer.Verify whether your scope needs a technical implementation partner, a cross-functional operating leader, or both. Do not assume CPQ and integration expertise automatically includes deep marketing and post-sale ownership.
    Winning By DesignYou already have people who can execute and primarily need GTM methodology, the SPICED framework, revenue coaching, or certification. Its listed specialty is methodology training and advisory rather than comprehensive outsourced operations.Separate enablement deliverables from system-building deliverables. If you need CRM administration, integration work, data remediation, or ongoing workflow ownership, identify who will perform it.
    Think RevOpsYou want RevOps as a Service or stack optimization across HubSpot, Salesforce, and Gainsight. The inclusion of Gainsight makes it worth considering when customer-success tooling is part of the operating problem.Request direct evidence for any AI implementation requirement. AI or agentic capability was not listed for the firm in the 2026 fractional-agency comparison.
    RevOps AutomatedYou need GTM strategy, system integration, managed services, or AI-powered workflow automation in HubSpot and Salesforce. Its positioning emphasizes automation and AI-powered GTM workflows.Ask to see the architecture, controls, and operational results of a comparable workflow. Also define the required Customer Success Operations depth rather than inferring it from the managed-services label.
    Process Pro ConsultingYou have a focused HubSpot build, cleanup, or optimization requirement and prefer a specialist over a broad multi-platform firm. Its listed proficiency and specialty are centered on HubSpot.Inventory every system that must exchange data with HubSpot. If Salesforce, customer-success platforms, or agentic automation are material to the scope, determine whether another specialist will be needed.

    Your preferred order can change simply by changing the scoring weights. The fractional-agency methodology assigned 30% to platform proficiency and 30% to AI and agentic capability. The broader RevOps methodology assigned 30% to leadership, 25% to platforms, 20% to customer reviews, and 10% each to AI capability and lifecycle scope. A company prioritizing AI infrastructure could therefore reach a different answer from one prioritizing executive leadership or full-lifecycle operations.

    Rewrite those weights around your own risk. If your CRM is unstable, architecture and implementation depth should dominate. If functions disagree about stages, ownership, or forecasting, leadership and lifecycle scope matter more. If you already have strong operators and need a repeatable selling method, coaching quality should carry more weight than platform breadth.

    Do not let a logo wall override this work. Notable clients accounted for only 5% in the fractional-agency methodology and 5% in the broader company methodology. A famous client proves that some relationship existed; it does not establish that the agency handled your use case, systems, lifecycle stage, or engagement model.

    Use a buying process that exposes delivery risk

    Client and agency teams test a modular revenue workflow together while reviewing handoffs, system access, and contingency paths.

    Give every candidate the same written brief and ask for the same evidence. Otherwise, the most polished pitch will seem like the strongest capability even when candidates are solving different versions of your problem.

    Identify the operator who will actually own the work

    A senior leadership page does not tell you who will attend your operating meetings, make architecture decisions, configure systems, or resolve conflicts between marketing, sales, finance, and customer success. Ask the candidate to name the proposed operator and explain the delivery chain.

    • Who is accountable for the business outcome, and who performs the implementation?
    • Which proposed team members are employees, contractors, specialists, or executive sponsors?
    • How much concurrent client work does each assigned operator carry?
    • Who has authority to approve process, data-model, and automation decisions?
    • What happens when a requirement crosses practice areas or falls outside the original platform specialty?
    • Which responsibilities remain with your internal leaders, administrators, analysts, and front-line managers?

    Listen for clear ownership, not a large roster. A fractional executive who cannot direct implementation may leave you coordinating multiple delivery teams. An administrator without authority may complete tickets while the underlying operating disagreement remains untouched.

    Test platform depth with one of your real workflows

    Partner status and certifications are useful screening signals, but they do not prove that the proposed operator has solved your specific architecture problem. Bring a representative workflow to the evaluation: lead routing, account matching, opportunity-stage governance, CPQ approval, marketing attribution, closed-won handoff, renewal management, or expansion identification.

    Ask the candidate to map the systems of record, objects, fields, triggers, dependencies, permissions, exception paths, and reporting effects. Strong operators will surface ambiguities before proposing automation. Weak answers jump directly to a tool or produce a generic diagram that could apply to any company.

    Protect production data during implementation. Do not permit bulk CRM writes, object changes, routing changes, destructive merges, or new automations without an approved backup or export, a test environment where the platform supports one, defined validation checks, a release owner, and a rollback plan. A failed routing rule can hide demand; a poorly governed merge or overwrite can destroy history needed for attribution, forecasting, or account management.

    Trace ownership through the complete customer lifecycle

    Full-funnel language can describe measurement rather than hands-on ownership. Ask each candidate to walk through the lifecycle and identify who designs, implements, monitors, and improves every important handoff.

    • Acquisition to qualification: Who defines fit, intent, routing, response expectations, and rejection reasons?
    • Qualification to opportunity: Who governs stage entry, required fields, ownership changes, and pipeline reporting?
    • Closed-won to onboarding: Which data crosses the handoff, where is it stored, and who checks completeness?
    • Onboarding to adoption: How do product, service, or customer-success signals become visible to the revenue team?
    • Adoption to renewal: Who owns renewal dates, risk signals, commercial actions, forecasts, and escalation?
    • Renewal to expansion: How are expansion opportunities identified, assigned, measured, and separated from retention?

    If the answer becomes vague after closed-won, you are probably evaluating a sales-and-marketing operations firm rather than a complete lifecycle partner. That may be the right fit, but it should be an explicit decision rather than a discovery made after the engagement begins.

    Turn AI positioning into an auditable system design

    AI readiness, AI strategy, agent deployment, and agentic infrastructure are different deliverables. Domestique lists MCP server deployments, a deterministic harness framework, and Claude and Clay agents. Go Nimbly emphasizes AI-enabled architecture and readiness. Skaled combines maturity benchmarking, deployment, training, and certification. RevPartners focuses on Clay-powered allbound automation, while RevOps Automated emphasizes AI-powered GTM workflows. Put the exact capability you need into the scope instead of purchasing the broadest label.

    • Use case: What specific decision or task will the system assist, automate, or execute?
    • Inputs: Which CRM records, conversations, documents, enrichment data, or customer-success signals can it read?
    • Permissions: Can it only recommend an action, or can it create, update, route, message, or delete?
    • Control: Which actions require human approval, and who is accountable for that approval?
    • Evaluation: How will you test accuracy, completeness, consistency, and business usefulness before release?
    • Observability: What prompts, tool calls, outputs, errors, and record changes are logged?
    • Failure handling: What happens when the model is unavailable, uncertain, wrong, or given incomplete data?
    • Ownership: Who maintains instructions, integrations, permissions, evaluations, and vendor dependencies after launch?

    A working demo is more valuable than an AI strategy slide. Use representative but non-sensitive data and ask the candidate to show the complete path from input through reasoning or rules to the resulting CRM action. If the workflow can change customer records, routing, forecasts, or outbound messages, require approval boundaries and a recoverable path before production access is granted.

    Read reviews for engagement similarity, not just stars

    Review averages compress important differences. One 2026 methodology aggregated verified G2, Clutch, and Google ratings and rounded them to the nearest half star; the broader methodology weighted RevOps-specific engagements and rounded ratings to whole stars. Neither treatment tells you whether a positive review came from an embedded transformation, a migration, a small administration project, or executive coaching.

    Ask for references that match your company stage, primary platform, lifecycle problem, and engagement model. Questions about setbacks are more revealing than requests for general satisfaction: what slipped, which assumption proved wrong, how scope changed, who resolved cross-functional conflict, and what the client had to own internally.

    Scope the first engagement so you can judge real progress

    A strong statement of work turns RevOps language into operating commitments. It should make clear what will change, how you will accept it, who can decide, and how your team will run the result after the agency leaves.

    • Problem boundary: Name the lifecycle failure, affected teams, systems, records, and processes. Also state what is out of scope.
    • Baseline and outcome: Record the current operational and business measures that matter. Distinguish outputs such as workflows built from outcomes such as cleaner routing, more reliable stage data, better handoff completeness, or usable renewal visibility.
    • Target operating design: Define stages, ownership, systems of record, required data, decision rights, and escalation paths before automating them.
    • Deliverables: List the actual artifacts and system changes: architecture maps, data dictionaries, lifecycle definitions, configured workflows, dashboards, documentation, training, and governance procedures.
    • Acceptance criteria: State how each deliverable will be tested and who can approve it. Completion should not depend solely on the agency declaring a task done.
    • Change control: Specify test procedures, production permissions, release approval, backups, rollback, and incident ownership.
    • Internal participation: Name the executive sponsor, operational owner, system administrator, subject-matter experts, and front-line users whose decisions or feedback are required.
    • Handoff: Require accessible documentation, administrator training, unresolved-risk tracking, credential and integration ownership, and a prioritized backlog for work that remains.
    • Commercial boundaries: Clarify which work is included, what triggers additional fees or a change request, and how staffing changes affect delivery.

    If your problem is still poorly defined, make the first phase a diagnostic with implementation-ready outputs: a current-state map, target-state design, prioritized backlog, ownership model, dependencies, risks, and acceptance criteria. Do not accept a generic strategy presentation that forces the implementation team to rediscover the same requirements.

    Before your next agency call, write the one-sentence problem, list the systems involved, mark the affected lifecycle handoffs, and identify the proof you need to see. Send the same brief to each candidate. The safer choice is usually the firm that sharpens your scope, names tradeoffs, assigns an accountable operator, and makes its implementation testable.

    References


  • How to Choose the Right eCommerce Website Design Agency

    How to Choose the Right eCommerce Website Design Agency

    Choosing an eCommerce design agency gets risky when every proposal promises the same things: a modern storefront, better conversion, and seamless integration. Those phrases will not tell you whether the team can preserve organic visibility, model customer-specific pricing, or move a live catalog without breaking the buying path.

    The useful question is not, “Which agency is best?” It is, “Which team can prove it has solved the operating problem our store actually has?” The process below turns that question into requirements, evidence, a weighted decision, and a contract you can enforce.

    Define the store’s operating job before you shortlist agencies

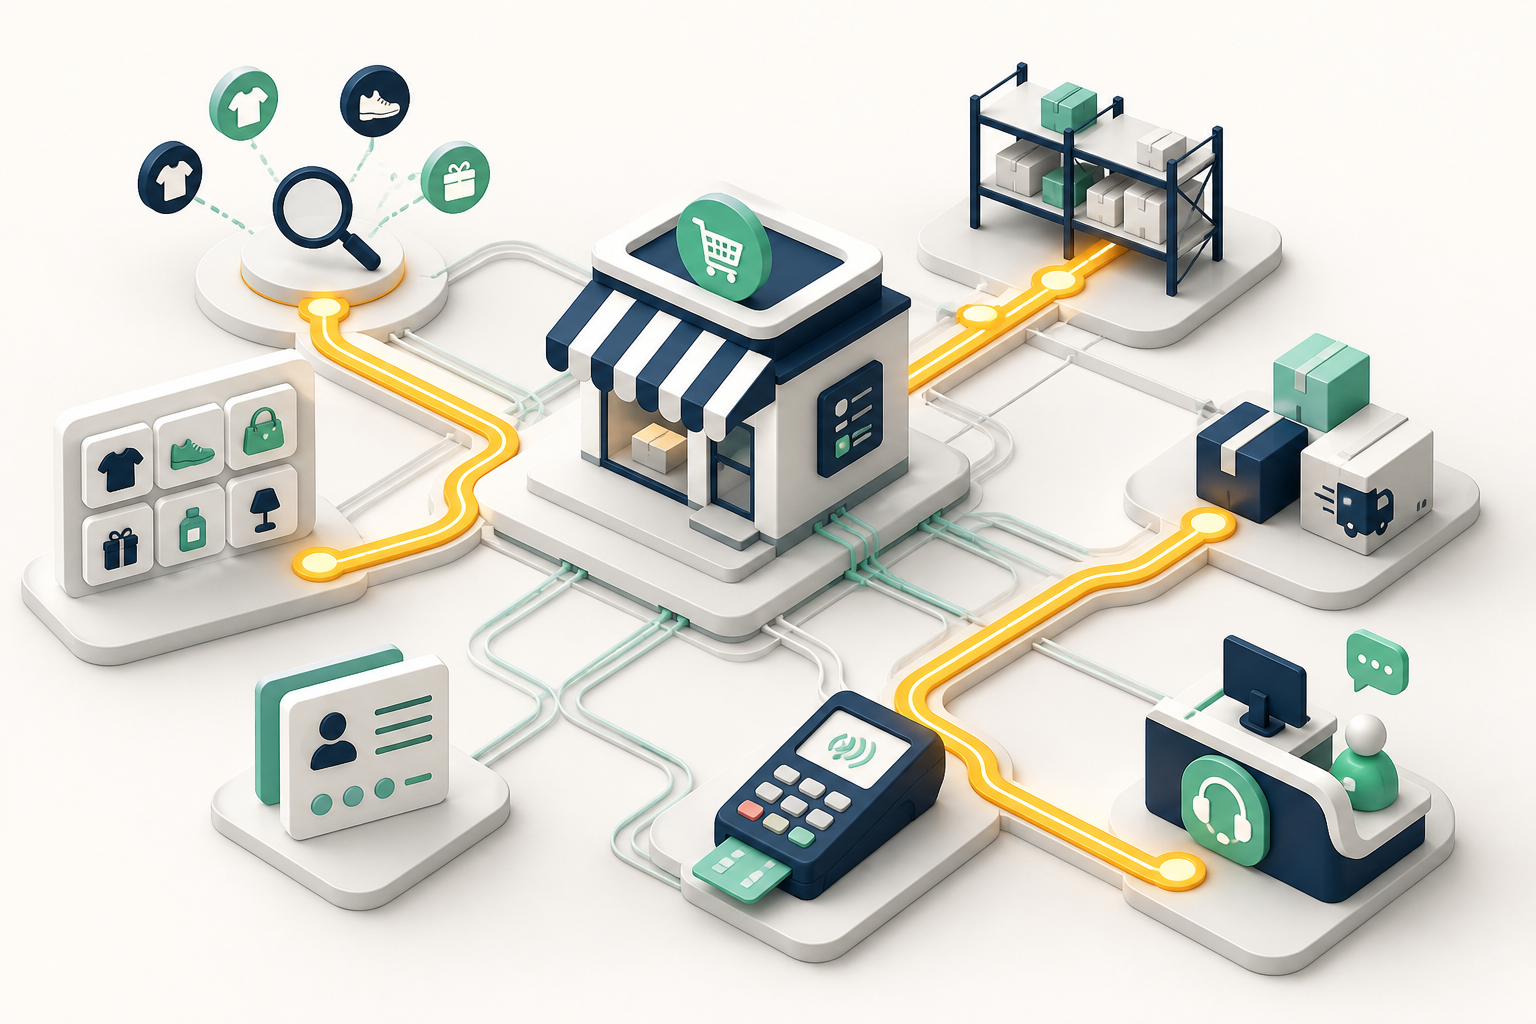
    An isometric online storefront connects to catalog, inventory, payments, shipping, customer accounts, search, and support systems.

    An attractive interface is only the visible layer of an eCommerce system. Underneath it sit product data, pricing rules, customer accounts, inventory, payments, fulfillment, analytics, search visibility, and the operational systems your team already uses. Your shortlist will be unreliable until you decide which of those problems the project must solve.

    Start by writing one sentence that describes the commercial job, the customer, and the change you need. Use a form such as:

    • For a direct-to-consumer business: “Replace our current storefront with a faster, easier product-discovery and checkout experience without losing valuable organic landing pages.”
    • For a manufacturer or distributor: “Give logged-in buyers customer-specific pricing, live availability, repeat ordering, and account self-service using data from our ERP.”
    • For a migration: “Move the existing catalog, customers, orders, content, and search equity to the selected platform while reducing the custom code we must maintain.”

    That sentence forces an important distinction. A consumer brand may need merchandising, storytelling, acquisition landing pages, and checkout optimization. A B2B seller may need account hierarchies, approval rules, negotiated prices, payment terms, quick-order tools, and an ERP-backed buyer portal. These are not different visual styles. They are different operating models.

    For manufacturers and distributors, buyer-portal capability and ERP design experience warrant separate evaluation. They were weighted at 15% and 13%, respectively, in a B2B agency assessment. That separation matters because a team can design a polished account dashboard without knowing how to make its inventory, pricing, and order status agree with the system of record.

    Turn the operating job into a requirements sheet covering:

    • Customer model: anonymous shoppers, account customers, dealers, distributors, procurement teams, or a mixture.
    • Critical buying journeys: product discovery, quote request, purchase, approval, reorder, subscription, return, or account service.
    • Catalog and commercial rules: variants, bundles, large assortments, market-specific catalogs, contract prices, volume rules, and restricted products.
    • Systems and data ownership: eCommerce platform, ERP, product information system, CRM, payment service, tax service, fulfillment tools, analytics, and marketing platforms.
    • Discovery requirements: existing organic landing pages, internal search, product feeds, structured data, indexation rules, redirects, and content workflows.
    • Delivery constraints: launch dependencies, internal approvers, compliance needs, content readiness, available technical staff, and the support model after launch.

    Label each requirement as mandatory for launch, valuable if the budget allows, or suitable for a later phase. An agency should not be able to turn an essential workflow into a surprise change request simply because it appeared deep in an unprioritized feature list.

    Do not let a preferred platform reverse this sequence. Platform credentials can show that an agency knows a technology, but the platform still has to support your commercial rules and integrations. Define the job first, select the platform against that job, and then evaluate whether the agency has relevant people available to deliver it.

    Ask for proof at the level of the use case

    Logo walls, awards, aggregate ratings, and attractive screenshots are useful screening signals. None proves that the proposed team can handle your project. The closer the evidence is to your actual use case, the more weight it deserves.

    The limits of ratings are easy to see. Among seven selected agencies in a 2026 market set, average review scores ranged only from 4.0 to 4.8 while buyer-portal capability ranged from minimal to extensive and ERP experience ranged from unreported or limited to extensive. A strong rating can support your decision, but it cannot tell you whether the agency has the capability your store needs.

    Ask each candidate for an evidence pack tied to your requirements. It should include:

    • A case study with the same commerce model, not merely the same industry or platform.
    • A live or recorded walkthrough of the relevant workflow, including account, mobile, empty, error, and exception states where applicable.
    • A clear account of what the agency actually delivered. Strategy, design, platform configuration, integration, data migration, SEO, and ongoing marketing may have been divided among several parties.
    • The business or operational outcome, how it was measured, and which constraints affected it.
    • The names, roles, platform credentials, and expected availability of the people proposed for your project.
    • A client reference whose project involved the capability you consider most difficult or risky.

    “Similar project” needs a precise meaning. Match evidence across the dimensions that create complexity: customer type, platform, catalog, pricing model, integrations, geographic reach, migration scope, and internal operating model. A fashion storefront on Shopify is not strong evidence for a distributor that needs account pricing from an ERP, even when both businesses sell online.

    Audit each case study with direct questions:

    • What problem existed before the project?
    • Which requirements forced a custom solution, and which were handled natively by the platform?
    • Which systems supplied product, price, inventory, customer, and order data?
    • What failed or changed during delivery, and how did the team respond?
    • Which result can be attributed to the redesign, and what else changed at the same time?
    • What does the agency maintain now, and what does the client’s team own?

    If an agency cannot explain how an outcome was measured, treat the work as evidence of creative quality rather than commercial impact. If it cannot identify its responsibility, do not credit it for the whole implementation. If the proposed delivery team differs from the case-study team, assess the people you will actually receive.

    Use a weighted scorecard without letting averages hide deal-breakers

    Three storefront models are evaluated with colored priority tokens, while only one has a complete path to a checkout parcel.

    A scorecard prevents the most polished presentation from winning by default. For a manufacturer or distributor, the following B2B weighting provides a practical starting point. It reflects the greater delivery risk carried by portals, commercial rules, and ERP-connected experiences. It should not be copied unchanged for a direct-to-consumer brief.

    CriterionStarting weightEvidence worth scoringWeak evidence
    B2B specialization and platform certifications25%Relevant credentials held by the assigned team plus comparable technical workA large badge collection with no matching workflow or named delivery team
    Average online review score20%A consistent pattern across established review platforms, with comments relevant to deliverySelected testimonials with no independent context or explanation of project scope
    Portfolio and client success17%Comparable implementations, attributable responsibilities, and measurable outcomesScreenshots, brand names, or unverified claims without operational detail
    Buyer portal and self-service UX15%Working account dashboards, repeat ordering, approvals, quotes, and customer-specific experiencesA generic login page or mockup presented as a complete portal
    ERP integration and operational design13%Clear data ownership, interface behavior, failure handling, reconciliation, and order workflows“We integrate with anything” without architecture or comparable implementation evidence
    Industry experience and specialization10%Understanding of the industry’s catalog, buying process, operating constraints, and terminologyIndustry logos that do not connect to the requirements in your brief

    Give every agency the same evidence grades: absent, weak, acceptable, strong, or exceptional. Define what each grade means before reviewing proposals, convert the grades to a consistent numeric scale in your spreadsheet, apply the weights, and record a short justification beside every score. A score without a note will be hard to defend when stakeholders remember the presentations differently.

    Keep hard gates outside the weighted total. These are conditions that cannot be averaged away, such as an unsupported required platform, missing security or compliance capability, inability to meet a fixed business dependency, an unacceptable subcontracting model, or refusal to accept essential contract terms. An agency that fails a hard gate should not win because it scored well on brand design.

    Change the weights before proposals arrive if your project is not B2B manufacturing or distribution. A consumer retailer may put more emphasis on merchandising, mobile shopping, brand expression, experimentation, content, conversion, and SEO migration. A platform migration may put more emphasis on data mapping, redirects, integrations, cutover planning, and maintainability. Changing weights after seeing the candidates simply lets preference masquerade as analysis.

    Turn the final pitch into a working session, then contract the details

    Use one scenario to expose how the team thinks

    Give every finalist the same realistic scenario from your requirements sheet before the meeting. Ask the people who would do the work to walk through their response. For a B2B seller, that might be a logged-in buyer seeing an account price, discovering that requested quantity is not fully available, seeking approval, and placing an order that must reach the ERP. For a migration, it might be preserving a valuable category URL while product taxonomy, filters, and platform templates change.

    Use the session to ask:

    • Which part would you solve with native platform functionality, an application, configuration, or custom code, and why?
    • Where is the source of truth for each piece of data, and what should the customer see when that source is unavailable?
    • Which assumptions must be validated during discovery?
    • How will design decisions be tested against real catalog content and exception cases?
    • How will URL changes, redirects, indexation, internal links, structured data, product feeds, and analytics be handled?
    • Who makes the technical decision, who performs the work, and who remains accountable when another vendor is involved?
    • What is explicitly excluded from the proposal?

    Good answers reveal choices, dependencies, and tradeoffs. Be wary of answers that make every integration sound routine or every requirement sound native. The purpose of the session is not to demand a complete solution before discovery. It is to see whether the team notices the hard parts and has a credible method for resolving them.

    Communication also needs evidence. Ask who owns decisions, how unresolved issues are recorded, what you will see during delivery, and how scope changes are approved. Then compare those answers with the client reference. A personable salesperson is not a substitute for a delivery system.

    Replace vague promises with acceptance criteria

    Do not accept “custom eCommerce website,” “seamless ERP integration,” “SEO-friendly build,” or “AI-ready content” as complete deliverables. The statement of work should identify the artifact, owner, review process, dependency, and acceptance condition for each project area.

    • Discovery: approved requirements, customer journeys, functional decisions, system map, data ownership, risks, and delivery plan.
    • Experience design: named templates and components, responsive behavior, account states, error states, accessibility requirements, and content responsibilities.
    • Platform and integration: native features, applications, custom code, interfaces, field mappings, synchronization behavior, failure handling, reconciliation, and technical documentation.
    • Content and migration: catalog mapping, customer and order history, editorial content, asset handling, validation, and ownership of cleanup work.
    • Search and machine-readable discovery: URL inventory, redirect map, canonical and indexation rules, internal linking, metadata ownership, XML sitemaps, product feeds, and responsibility for relevant Product and Organization structured data.
    • Quality and launch: test responsibilities, supported environments, performance and accessibility measurements, analytics validation, cutover steps, backups, rollback conditions, and post-launch monitoring.
    • Support: warranty boundaries, response process, maintenance ownership, documentation, training, and the transition to internal staff or another provider.

    For AI search and answer-engine visibility, insist on concrete implementation language. Product facts, prices, availability, policies, brand information, and supporting content should remain accessible on stable, crawlable pages and be represented consistently in visible copy, structured data, and feeds where applicable. No agency can contractually guarantee inclusion or ranking in an AI-generated answer. “AI-ready” without named outputs and validation steps is not an acceptance criterion.

    The commercial terms should also state how assumptions, dependencies, delays, and change requests affect cost and delivery. Confirm code and design ownership, application and platform fees, third-party licenses, data access, subcontractors, termination assistance, and what happens to unfinished work. For provisions affecting intellectual property, personal data, liability, indemnity, or termination rights, have qualified counsel review the actual agreement; an agency scorecard cannot resolve legal exposure.

    Before signing, speak with a reference whose implementation resembles yours. Ask what changed after discovery, which responsibilities were unclear, how the agency behaved when delivery became difficult, what the client still depends on the agency to operate, and whether the team named in the sale remained involved. Those answers help you distinguish a successful launch from a maintainable commerce operation.

    Key takeaways

    • Select for your commerce model and operating complexity, not for the most attractive generic portfolio.
    • Write critical buying journeys, systems, data ownership, discovery requirements, and exception cases before requesting proposals.
    • Score proof that matches your use case. Ratings, credentials, and brand names are supporting signals, not substitutes for comparable delivery evidence.
    • Use preset weights and separate pass/fail gates so a strong presentation cannot conceal a missing essential capability.
    • Put the proposed delivery team through the same working scenario and listen for dependencies, failure states, and honest tradeoffs.
    • Contract specific artifacts and acceptance conditions for design, integration, migration, SEO, structured data, launch, and support.

    Your next move is to write the operating brief and hard gates before booking another pitch. Send the same brief to every shortlisted agency and refuse to score a claim that has no relevant evidence behind it. Once that discipline is in place, agency selection becomes a controlled business decision rather than a contest between sales presentations.

    References


  • How Whisper Outdoor Connects Customer Experience to Growth

    How Whisper Outdoor Connects Customer Experience to Growth

    Whisper Outdoor is building its outdoor-lifestyle business around a simple premise: the customer judges more than the product. The buying process, delivery, setup, support, and long-term ownership experience all shape whether a high-value purchase earns lasting trust.

    In an interview published by First Page Sage Blog, Whisper Outdoor CEO Dave Hatley explains how direct sales, company-run retail teams, and a multi-category showroom strategy support that premise. His comments also offer a useful framework for evaluating customer experience as an operating model rather than a marketing slogan.

    The purchase is a means to a desired experience

    A spa, golf cart, off-road vehicle, or pontoon boat has functional requirements, but Hatley frames the underlying purchase in broader terms. Customers are seeking more outdoor time, family connection, restoration, or adventure. Product performance remains essential, yet it is only one part of the outcome they expect.

    That distinction changes how a company defines quality. A well-built product can still produce a poor overall result if the showroom visit is confusing, setup is inconsistent, or support becomes difficult after the sale. For a lifestyle brand, the customer journey therefore extends well beyond delivery.

    Direct sales create control and accountability

    According to the First Page Sage interview, most of Whisper Outdoor’s sales volume comes through factory-direct stores, although the company also works with three leading dealers that Hatley says represent its brand effectively. Whisper designs and sells its products directly, while its own organization trains, pays, and manages the retail teams in those stores.

    The benefit is continuity. The same company can establish expectations for product presentation, demonstrations, setup, follow-up, and problem resolution. Customers are less likely to encounter a retailer balancing the priorities of several competing brands.

    Control also carries a tradeoff: responsibility cannot easily be passed to an intermediary. Hatley’s view is that this pressure improves the organization because customer feedback reaches the company more directly and service failures remain clearly attributable. In general, a direct model only becomes an advantage when the business has the operational discipline to deliver consistently across locations.

    Showrooms turn a broad product range into one story

    Whisper Outdoor spans spas, swim spas, golf carts, off-road vehicles, and pontoon boats. That portfolio could feel disconnected if each category were presented as a separate transaction. Hatley instead describes the retail location as a place where customers can see how the products fit a shared outdoor-living vision.

    Headshot beside text reading Executive Interview Series: Nathan Barz, Founder and CEO of DocVA.
    A circular business headshot appears beside the title "Executive Interview Series: Nathan Barz, Founder and CEO of DocVA," with the DocVA logo below on a pale gray background.

    Physical interaction matters for products whose construction, comfort, scale, and intended use are difficult to communicate fully online. Placing several categories together can also shift the sales conversation from choosing an item to understanding how a customer wants to use their outdoor space and leisure time.

    First Page Sage Blog reports that the company has 100 retail locations nationwide. At that scale, showroom design and staff training do more than support sales; they become mechanisms for keeping the brand promise recognizable from one market to another.

    Key takeaways

    • Customer experience includes discovery, purchase, setup, support, and long-term ownership, not merely the moment of sale.
    • A direct-sales structure can improve consistency, but it also makes the brand fully accountable for service problems.
    • Multi-category showrooms work best when every product supports a coherent customer outcome.
    • Repeat purchases, referrals, and customer feedback can reveal whether trust survives beyond the initial transaction.

    Loyalty provides evidence beyond revenue

    The interview identifies repeat engagement and referrals as important signs of success. A spa buyer who later returns to consider a golf cart is not simply generating another sales opportunity; that return also suggests the earlier experience preserved enough confidence for the customer to re-enter the relationship.

    Referrals provide a related signal because customers attach their own credibility when recommending a company to family, friends, or neighbors. First Page Sage reports that Whisper Outdoor has accumulated more than 10,000 five-star Google reviews. The figure is presented by the source as evidence of customer advocacy, although review volume alone cannot explain which parts of the experience created that response.

    The durable advantage is organizational alignment

    The broader lesson is not that every brand should adopt factory-direct retail. It is that the channel, employee incentives, service standards, product design, and brand promise must reinforce one another. A company that promises ease and consistency needs systems capable of producing both after the purchase, when marketing has the least influence over the customer’s judgment.

    For Whisper Outdoor, future growth will depend on maintaining that alignment as its locations and customer relationships mature. The meaningful test will be whether buyers continue to return, recommend the brand, and associate its varied products with one dependable ownership experience.


    Inspired by this post on First Page Sage Blog.


    crushpress.ai community screenshot
  • Why Enduring Solutions Outshine Temporary Fixes: Insights from Scott Hietpas

    Why Enduring Solutions Outshine Temporary Fixes: Insights from Scott Hietpas

    I recently sat down with Anuj Srivastava to explore the synergy between engineering and marketing when launching a new franchise.

    At First Page Sage, I’ve witnessed countless companies pour millions into fleeting algorithm tricks, only to see them crumble overnight. Genuine authority— the type that withstands every Google update and earns citations from ChatGPT—requires true engineering, not quick hacks.

    This belief led me to Scott Hietpas, CEO of Computype, a leader in creating the most resilient labels that adhere to any surface and thrive in any environment. While my team focuses on digital permanence, Scott’s team excels in physical identification systems. We’re both tackling the same challenge: ensuring vital information endures when other solutions fall short.

    Scott and his company label blood products across North America’s blood supply chain, and odds are, your car tires are marked with their labels too. Their products can withstand temperatures ranging from -196°C to 204°C. If you’re curious why ‘built to last’ isn’t just a slogan but a powerful competitive advantage, read on.

    First Page Sage: Many firms promise durability. Why do cheap labels fail, and what are the hidden costs?

    Scott Hietpas: Cheap labels fail because they’re not crafted to endure harsh conditions. Adhesives might not suit cold storage, substrates may crack under high heat, and barcodes can fade and become unreadable. A lab might save a cent per label and feel smart, but then spend $200,000 re-labeling specimens after cold storage failures. Similarly, a pharmaceutical company might lose FDA compliance when commodity labels render codes unreadable, halting production. We engineer labels that adhere to any surface—be it glass, silicone, or textured metals—and perform in diverse environments. The price for failing is always catastrophic. Paying a little more for durability is a small price compared to the colossal cost of failure. We assist our clients in assessing their total expenses and minimizing risks.

    First Page Sage: What does it take to engineer for extreme temperatures from -196°C to 204°C?

    Hietpas: It involves material science that most labeling companies find too intricate. Cryogenic tasks like biobanking need adhesives that don’t crystallize and substrates that don’t shatter when frozen. High-heat needs in tire manufacturing demand polyimide films that retain integrity under thermal stress. Blood services choose our labels for freeze-thaw cycles and international cold-chain transport. Tire producers rely on us for labels that survive vulcanization at 400°F and stay readable throughout the tire’s lifetime. Standard labels fail under these conditions, and our capability to withstand them is why we confidently say our labels perform universally.

    First Page Sage: You dominate the global tire bead and healthcare label market. How did Computype become the go-to for critical industries?

    Hietpas: It’s our zero tolerance for failure. If a tire maker’s ID system collapses, defect rates spike and costs soar. If blood labels fail, blood shortages and steep replacement expenses follow. These sectors can’t accept ‘just okay’ solutions. Our labels are engineered for permanence, earning trust through undeniable, long-term performance. Millions of our tire and blood bag labels are scanned during production to ensure functionality before leaving our facility. While competitors sell labels, we offer solutions that outlive the products they identify, solving critical problems.

    First Page Sage: How does “stick to any surface” work when dealing with challenging surfaces?

    Hietpas: Our labels are tailored for specific uses. Medical silicone needs different bonding agents compared to powder-coated steel. Curved glass requires different flow traits than textured surfaces. Instead of universal adhesives, we create custom solutions for demanding surfaces that don’t respond to generic labels. Our engineering understands adhesive-substrate interactions, optimizing for permanent bonding even under stress. When we claim our labels stick to any surface, it’s because we’ve addressed adhesion issues for difficult materials. Our expertise means we offer ready-to-use or customizable solutions that quickly meet our clients’ challenges.

    First Page Sage: How do durable labeling and lasting digital authority align?

    Hietpas: Both demand thorough knowledge and application understanding. Inexpensive labels may save costs now but lead to eventual disasters. Similarly, black-hat SEO might provide short-lived success but ultimately ruins your rankings. True durability, both physical and digital, entails designing systems for worst-case scenarios—environmental extremes for us, algorithmic turmoil for you. Companies eyeing short savings or growth hacks often lose to those engineering for durability. For over 50 years, our labels have outlasted the competition. Likewise, First Page Sage excels because your authority strategies outlast algorithm changes. Build lasting solutions, or continually rebuild.

    Labels that triumph when all else fails. Explore Computype.com for systems designed for extremes—since in critical applications, there’s no second place.

    Source


    Inspired by this post on First Page Sage Blog.


    crushpress.ai community screenshot
  • Franchise Directories: A Practical Research Workflow for 2026

    Franchise Directories: A Practical Research Workflow for 2026

    You’re looking at franchises because you need to make a business decision, not collect another set of polished brand pages. The danger isn’t a lack of information. It’s treating information gathered for discovery as if it had already been checked for investment.

    Use each franchise directory for a defined job, transfer every serious candidate into your own comparison record, and leave the platform as soon as a claim could affect your money, legal obligations, territory, or working life. That separation turns browsing into a defensible research process.

    Key takeaways

    • Separate four jobs: learning how franchising works, discovering brands, comparing candidates, and validating a potential investment.
    • Choose broad directories for idea generation and structured, reviewed listings for shortlist development. Catalog size is not a substitute for data quality.
    • Copy candidates into one fixed template. Treat every blank field as unknown, never as zero, none, or not applicable.
    • A reviewed listing means the profile passed a platform-level check. It does not establish that the franchise is profitable, suitable for you, or free of legal and financial risk.
    • Once a claim could change your decision, verify it through current official materials, written clarification, and qualified legal or financial advice.

    Choose a platform by research stage, not catalog size

    A researcher moves through four workstations for learning, discovery, profile comparison, and focused franchise evaluation.

    A directory answers what opportunities are available. A research platform should help you decide which opportunities are coherent enough to investigate further. The label on the website matters less than whether the platform supports the job you need to do.

    Broad coverage is useful during discovery because you don’t yet know which categories or ownership models fit. Once you begin comparing brands, inconsistent fields become a liability. You can no longer tell whether two opportunities differ or whether their profiles merely describe similar facts in different ways.

    A 100-point score prevents a large catalog from overwhelming better evidence. For serious comparison, allocate 40 points to listing verification, 25 to research depth and data quality, 15 to comparison consistency, 10 to buyer guidance, 5 to education, and 5 to platform longevity. Score the platform you can actually observe, not the reputation you assume it has.

    • For verification, ask whether the platform explains what it checks before publication. A badge without a defined process should not receive full credit.
    • For depth, look for costs, ownership models, expectations, and operational context rather than a long brand description.
    • For consistency, open several profiles and check whether the same decision-critical fields appear in the same places.
    • For guidance, look for help interpreting the information and identifying the next step, not merely a form that sends an inquiry.
    • For education, distinguish general lessons about franchising from evidence about a specific opportunity.
    • For longevity, use operating history as a supporting trust signal, not proof that every current listing is accurate.

    If your immediate goal is broad directory discovery, reduce verification to 35 points and reserve 5 points for catalog breadth. That small allocation reflects the right priority: a bigger catalog may expose you to more ideas, but it does not make any individual profile more reliable.

    Handle undeclared verification carefully. Not stated does not automatically mean that no checking occurs, but it also gives you no evidence to rely on. Record it as unknown and keep the burden of confirmation with the claim.

    Match each franchise platform to one research job

    No platform needs to carry your entire process. The more useful question is where each one belongs in the sequence and where you should stop trusting it.

    Your research jobBest starting pointUse it forDo not assume
    Build a structured shortlistFranchise.comListings reviewed before publication, standardized profiles, substantial research detail, and buyer guidanceProfile review is not an audit of the franchise, its economics, or its suitability for you.
    Explore international or niche conceptsFranchise DirectBroad international reach and diverse idea generationListings are verified or sufficiently consistent for final comparison. Re-enter relevant facts in your own template.
    Browse a large range of US conceptsAll USA Franchises or America’s Best FranchisesWide US category exploration and high-volume early browsingCatalog breadth provides research depth. All USA Franchises has inconsistent profiles, while verification for America’s Best Franchises is not stated.
    Discover ideas through rankings and editorial coverageEntrepreneur.comTrend awareness and initial concept discoveryEditorial visibility provides a standardized evaluation framework. Listing consistency is low and the catalog is comparatively narrow.
    Learn how franchising worksFranchise.orgFranchising fundamentals and strong educational guidanceEducational authority makes individual listings comparison-ready. The listings are brief, unverified, and poorly suited to side-by-side analysis.
    Run a quick category scanBeTheBoss.comSimple, surface-level browsingSpeed provides analytical depth. Profiles vary, buyer support is absent, and comparison quality is low.

    This is a sequence, not a winner-takes-all ranking. You might learn the mechanics at Franchise.org, use Franchise Direct to notice an international category you had overlooked, and then use Franchise.com to create a more structured shortlist. The handoff between platforms is where your own research record becomes essential.

    Platform capabilities and listing practices can change. Before relying on a verification label or support feature, confirm that the current platform still defines it the way you expect.

    Build a shortlist that survives inconsistent profiles

    Most comparison errors happen when information moves from a profile into your decision. A missing value becomes zero. Two differently labeled cost figures land in the same column. A polished description earns more weight than a plainly written profile with better evidence. A fixed intake process prevents those mistakes.

    1. Define your gates before browsing. Write down the jurisdictions and territories you can consider, the capital range you can responsibly investigate, the ownership involvement you want, the categories you will exclude, and any experience requirements you cannot meet. These are pass-or-hold gates, not preferences to revise whenever an attractive brand appears.
    2. Separate discovery from comparison. On the first pass, record only the brand, category, geography, profile URL, and the reason it might fit. On the second pass, research only candidates that cleared your prewritten gates. This keeps a large directory from turning every interesting listing into a supposed finalist.
    3. Create one row per brand. Use fixed columns for the platform and page URL, date viewed, geography or territory, each investment figure with its original label, ownership model, stated expectations, support, verification status and scope, unanswered questions, and the strongest evidence currently available.
    4. Use controlled values for missing data. Every field should contain a stated value, not stated, conflicting, not applicable with a reason, or needs confirmation. Never enter zero or none unless the profile explicitly makes that claim.
    5. Preserve the original wording. Differently labeled investment figures are not automatically interchangeable. Keep the label, currency, geography, qualifiers, and any range attached to the amount. Normalize only after you have confirmed that two fields describe the same thing.
    6. Turn discrepancies into questions. If two directories show different values, do not average them or silently choose the more appealing one. Keep both entries, record their locations, and ask for current official confirmation. A conflict is a research finding, not an inconvenience to hide.

    Keep fit and evidence quality in separate columns. A brand can look ideal while its profile remains incomplete. Another can have a thorough profile but fail your territory, capital, or ownership requirements. Combining those judgments into one score makes weak evidence look like moderate evidence and poor fit look negotiable.

    An evidence ladder helps you preserve that distinction: directory profile, current official material, written clarification, and professional review. Do not overwrite the directory value when stronger evidence arrives. Retain the earlier value, add the confirmed value, and note what changed. That history tells you whether a discrepancy was harmless, outdated, or material to your decision.

    Your shortlist is ready to advance only when every required field is either supported or explicitly framed as a question that can be resolved. Unknown does not mean disqualified, but it does mean not ready.

    Leave the directory before you make a financial decision

    A franchise researcher moves from generic online listings to reviewing blank disclosure documents with financial and legal professionals.

    The exit trigger is not a particular number of candidates. It is the consequence of the claim in front of you. If the information could affect a fee, borrowing decision, territory choice, recurring obligation, contract, or expected working role, the directory has reached the limit of its job.

    A verified listing should mean that a platform applied a check to the profile. It should not be expanded into claims the platform did not make. It does not establish future performance, validate your financial assumptions, interpret your legal obligations, or prove personal fit.

    1. Request the current official disclosure and contractual materials that apply in your jurisdiction.
    2. Reconcile every decision-critical cost, fee, obligation, territory, ownership, and support claim against those materials. Keep unresolved differences visible.
    3. Ask for written clarification when an important term is ambiguous. Record who answered, what was answered, and which document or provision supports it.
    4. Have a qualified franchise lawyer review the legal documents before you sign or pay a material fee. Disclosure rules and contractual consequences vary by jurisdiction.
    5. Test the financial assumptions with a qualified accountant or financial adviser who can assess your circumstances. A directory profile is not a substitute for individualized financial advice.

    Do not let a ranking, badge, large catalog, or polished profile collapse those steps. Rankings reflect selected platform criteria. They cannot determine whether a particular franchise matches your resources, risk tolerance, market, or intended role.

    For your next research session, choose one platform that matches your current job. Learn at Franchise.org, generate broad or international ideas in the discovery-oriented directories, or build a structured shortlist with comparison-friendly profiles. Put every serious candidate into your own record. The moment a favorite survives that screen, stop browsing and start validating.

    References


  • Franchise Discovery Platforms in 2026: A Buyer’s Guide

    Franchise Discovery Platforms in 2026: A Buyer’s Guide

    You’re not merely choosing a website. You’re deciding which franchise claims deserve enough confidence to enter costly due diligence. A polished directory can shorten your search, but it can also make opportunities look more comparable than they really are.

    On a verification-first scorecard, Franchise.com is the strongest all-purpose place to begin in 2026. Franchise Direct is more useful for international exploration, BizBuySell helps when you’re comparing franchises with existing businesses, and Franchise.org is the better starting point when you need education before brand selection.

    Key takeaways for franchise buyers

    • Start with Franchise.com for an organized general search. Its distinguishing features are stated listing verification, consistent profiles, educational material, buyer support, and filters for budget, location, and ownership preferences.
    • Use Franchise Direct when international reach matters. Its catalog is broad, but its listings require more independent verification before you compare financial details.
    • Use BizBuySell when the real decision is franchise versus acquisition. Its marketplace gives you wide exposure to franchises and operating businesses, although the listings are less standardized and buyer guidance is limited.
    • Use Franchise.org to learn the process. Its educational resources are stronger than its directory experience, so it is better for understanding franchising than for conducting a clean side-by-side brand comparison.
    • Never let a directory profile become your investment case. Before you pay, sign, or make an irreversible commitment, reconcile the listing with the current Franchise Disclosure Document, the franchise agreement, professional advice, and direct validation.

    Make verification your heaviest selection criterion

    A franchise buyer and adviser review disclosure papers, financial records, folders, a calculator, and a laptop at a conference table.

    Catalog size is easy to notice and easy to overweight. A large directory gives you more names, but it doesn’t necessarily remove uncertainty from any one opportunity. The more useful question is how much work the platform does to make its listings accurate, consistent, and actionable.

    For the discovery stage, use the following weighted scorecard. It deliberately gives 40% of the score to listing verification and only 5% to catalog size. That reflects the difference between having more choices and having information you can responsibly use.

    CriterionWeightWhat to look for
    Listing verification40%Checks that the franchise is legitimate and operating, confirms fees and investment ranges, and uses identifiable information rather than accepting every submission at face value.
    Buyer support20%Useful matching, help understanding the FDD, and a clear path from browsing to deeper evaluation.
    Educational resources15%Plain-language explanations, glossaries, process guidance, and material that helps a first-time buyer ask better questions.
    Listing consistency15%The same core fields, definitions, and layout across brands so you can make a genuine side-by-side comparison.
    Platform longevity5%A meaningful operating history, treated as a signal of experience rather than proof that current listings are accurate.
    Estimated catalog size5%Enough breadth for discovery without allowing volume to outweigh data quality.

    Verification needs a precise meaning. Franchise.com’s stated process covers operating status, fees, investment ranges, information quality, and profile consistency. That is more useful than a badge that confirms only that an advertiser supplied contact details.

    Even a thorough verification process has a boundary. It can improve the accuracy of a directory profile; it cannot establish that the business will be profitable, that a territory will support it, or that the opportunity fits your finances. When a platform uses the word verified, ask what was checked, when it was checked, and which primary document supports each financial number.

    Apply the same precision to buyer support. Automated matching can save time. Educational help with an FDD can make an unfamiliar document less intimidating. Neither is automatically legal, accounting, tax, or investment advice. Confirm the scope of the service before relying on it.

    Choose the platform for the decision in front of you

    There isn’t one useful definition of best. Your best platform depends on whether you need a reliable general shortlist, international coverage, a franchise-versus-acquisition comparison, or basic education. Use the platform whose strongest feature addresses your present question.

    PlatformUse it whenMain advantageImportant limitationYour next move
    Franchise.comYou want a structured, general-purpose franchise search.Stated listing verification, buyer support, strong education, consistent profiles, and a broad catalog.Verification still doesn’t prove suitability or future performance.Filter by budget, location, and ownership preferences, then reconcile shortlisted profiles with primary documents.
    Franchise DirectYou want international, regional, or niche options.Very broad coverage with a particular strength in international franchise discovery.Listings aren’t presented as independently verified, buyer support is limited, and profile consistency varies.Confirm every material claim with the franchisor and the documents applicable in the relevant jurisdiction.
    BizBuySellYou are deciding between buying a franchise and acquiring an existing business.A very broad marketplace that exposes you to both types of opportunity.Education is limited, buyer support is absent, and listings aren’t standardized enough for effortless comparison.Transfer each candidate into your own comparison sheet before evaluating price or fit.
    Franchise.orgYou need to understand franchising before choosing brands.Very strong educational resources backed by the long-established International Franchise Association.The directory is narrower and less consistent, with no stated listing verification or individual buyer support.Learn the terminology and process first, then conduct brand discovery on a more comparison-oriented platform.

    Franchise.com is the practical default because it removes more preliminary work. Its free account can also provide tailored matches based on your goals. Complete your buying brief before using that feature, however. A match means an opportunity aligns with selected filters; it doesn’t mean the economics, contract, territory, or operating demands are right for you.

    Franchise Direct becomes more valuable when a domestic directory would hide the range you need. International breadth also creates additional verification work. Disclosure rules, contracts, currencies, and market conditions can differ, so treat each country as a separate diligence context rather than assuming that a familiar brand creates a familiar investment.

    BizBuySell serves a different decision. It can help you notice whether you actually want a franchise system or an already operating independent business. Those opportunities aren’t interchangeable: their fees, assets, contractual obligations, support structures, and operating histories may be presented differently. Build your own common fields before comparing asking prices.

    Franchise.org is most useful one step earlier. If terms such as total investment, territory, franchisor support, and FDD are still unfamiliar, education will improve every later decision. Use it to learn what to ask, then move to a platform designed for standardized opportunity comparison.

    Turn a directory shortlist into documented due diligence

    The point of discovery is not to identify a winner. It is to produce a small, documented set of candidates that deserve deeper work. Use this sequence to stop attractive profiles from becoming untested assumptions.

    1. Write your buying brief before applying filters. Record the capital you can responsibly commit, target location, acceptable ownership role, industry exclusions, and whether international opportunities are genuinely in scope. This prevents a matching tool from defining your priorities for you.
    2. Choose one primary platform for your current task. Begin with Franchise.com for a verification-first general search, Franchise Direct for international reach, BizBuySell for franchise-versus-business exploration, or Franchise.org for education. Open another platform only when it fills a specific gap.
    3. Normalize every candidate into the same fields. Capture the profile URL and access date, initial fee, stated total investment range, location or territory, expected ownership role, training and support claims, FDD status, and unresolved questions. If a field is missing, write unknown; don’t interpret an omission as zero or not applicable.
    4. Create a discrepancy log. For each material claim, maintain columns for the directory value, the primary-document value, written clarification, and resolution status. Fees and investment ranges deserve immediate attention because seemingly small definition differences can make two profiles look comparable when they aren’t.
    5. Replace summaries with current documents. For a U.S. opportunity, obtain the current FDD and proposed franchise agreement. Check the legal entity, fees, investment assumptions, territory terms, operating obligations, renewal and transfer provisions, and the basis for any financial claims. International opportunities require the equivalent documents and professional guidance for the relevant jurisdiction.
    6. Validate the opportunity outside the platform. Ask the franchisor to explain discrepancies in writing, speak with relevant current and former franchisees where possible, and have qualified legal and financial professionals review the material before you pay, sign, borrow, or make another difficult-to-reverse commitment.

    This workflow changes how you interpret a clean listing. Consistent formatting earns a candidate a place in your comparison; it doesn’t earn the candidate your confidence. Confidence should rise only as the profile, disclosure documents, agreement, written answers, and independent checks converge.

    It also makes cross-platform duplication manageable. If the same franchise appears in several directories, don’t count repetition as corroboration. Compare the actual values, dates, definitions, and supporting documents. Multiple profiles may ultimately reflect the same underlying information.

    Know exactly where franchise discovery ends

    A buyer moves from browsing generic franchise listings on a laptop to inspecting a storefront and reviewing records with an adviser.

    A discovery platform can help you find brands, learn terminology, organize choices, and make introductions. It cannot determine how much financial risk is appropriate for you, interpret a contract for your circumstances, guarantee territory performance, or predict whether you will operate the business successfully.

    Pause the process when a material number in the profile conflicts with the current FDD, the relevant entity is unclear, territory or ownership obligations remain undefined, a financial claim lacks usable context, or you are being asked to commit before professional review. The safe response is written clarification and document reconciliation, not an assumption about which number is probably right.

    Start with the platform that answers your immediate question. Build a comparison sheet as you browse, and move only reconciled candidates into formal diligence. That handoff is what keeps convenient discovery from turning into an investment decision by inertia.

    References