Category: Analytics & conversion

  • How the Shakeout Effect Changes Customer Lifetime Value

    How the Shakeout Effect Changes Customer Lifetime Value

    Your retention curve looks reassuring: churn is steep just after acquisition, then settles. The tempting conclusion is that customers become more loyal as they age. Some may, but the curve can improve even when nobody changes. The people most likely to leave are simply no longer in the cohort.

    That distinction matters whenever you use customer lifetime value to set acquisition bids, approve channel budgets, or judge onboarding. A single average churn rate can make a weak cohort look valuable, make a durable customer base look fragile, or hide the period in which customer acquisition cost is actually at risk.

    The curve improves because the cohort is changing

    The shakeout effect occurs when early churn removes less durable customers from a mixed cohort. The customers who remain tend to have lower churn propensity, stronger engagement, and more predictable purchasing behavior. As their share of the surviving cohort rises, the observed churn rate falls.

    Imagine acquiring two unlabelled customer types at the same time. One type has a high probability of leaving early. The other is more likely to keep buying. You initially observe a blend of both types. After the first wave of departures, the surviving group contains a larger proportion of the durable type. Cohort-level churn has improved, but that does not prove that an individual customer’s underlying propensity changed.

    This is why three measurements that sound similar must remain separate:

    • Period churn measures how many at-risk customers leave during a particular customer-age interval.
    • Cumulative retention measures how much of the original acquisition cohort remains at each age.
    • Conditional survivor value measures the expected future value of someone who has already remained active to a specified age.

    The distinction prevents two opposite errors. If you extend the high early churn rate across the entire customer lifetime, you can undervalue customers who survive the shakeout. If you apply the mature survivors’ low churn rate to every new acquisition, you can overvalue the incoming cohort by pretending its early departures will not happen.

    The second error is especially expensive. New customers can churn before their value covers acquisition cost, while profit may be concentrated among a comparatively small loyal group. If you price acquisition from that loyal group’s economics, you are valuing every prospect as though they have already survived.

    Build the cohort view that exposes the shakeout
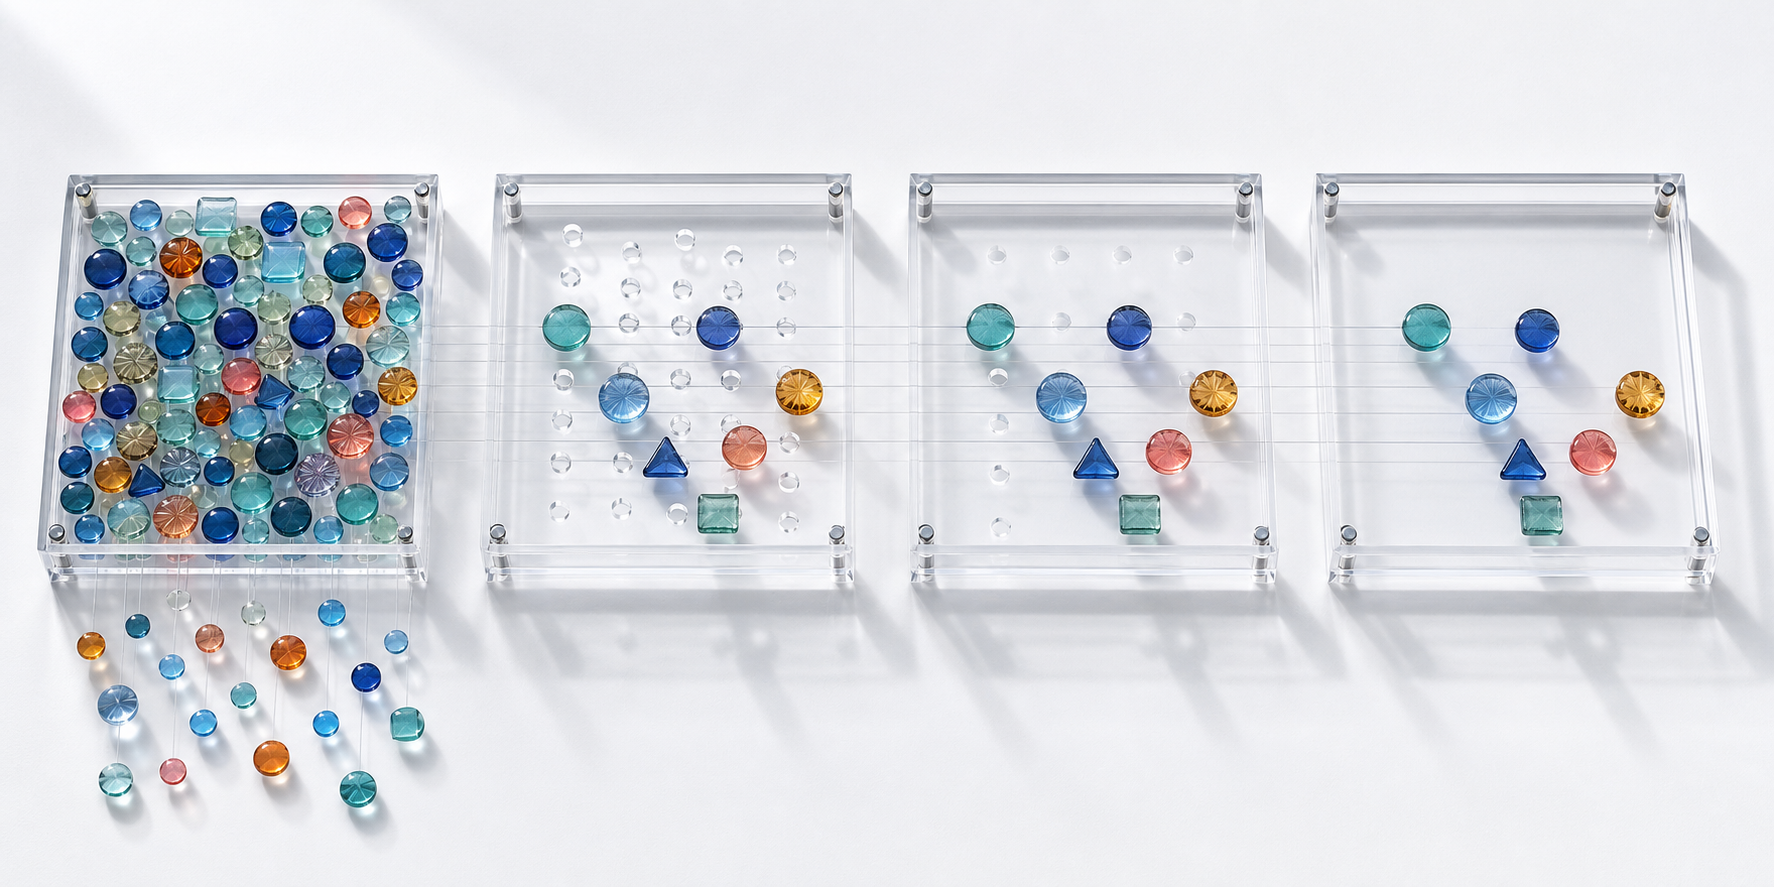
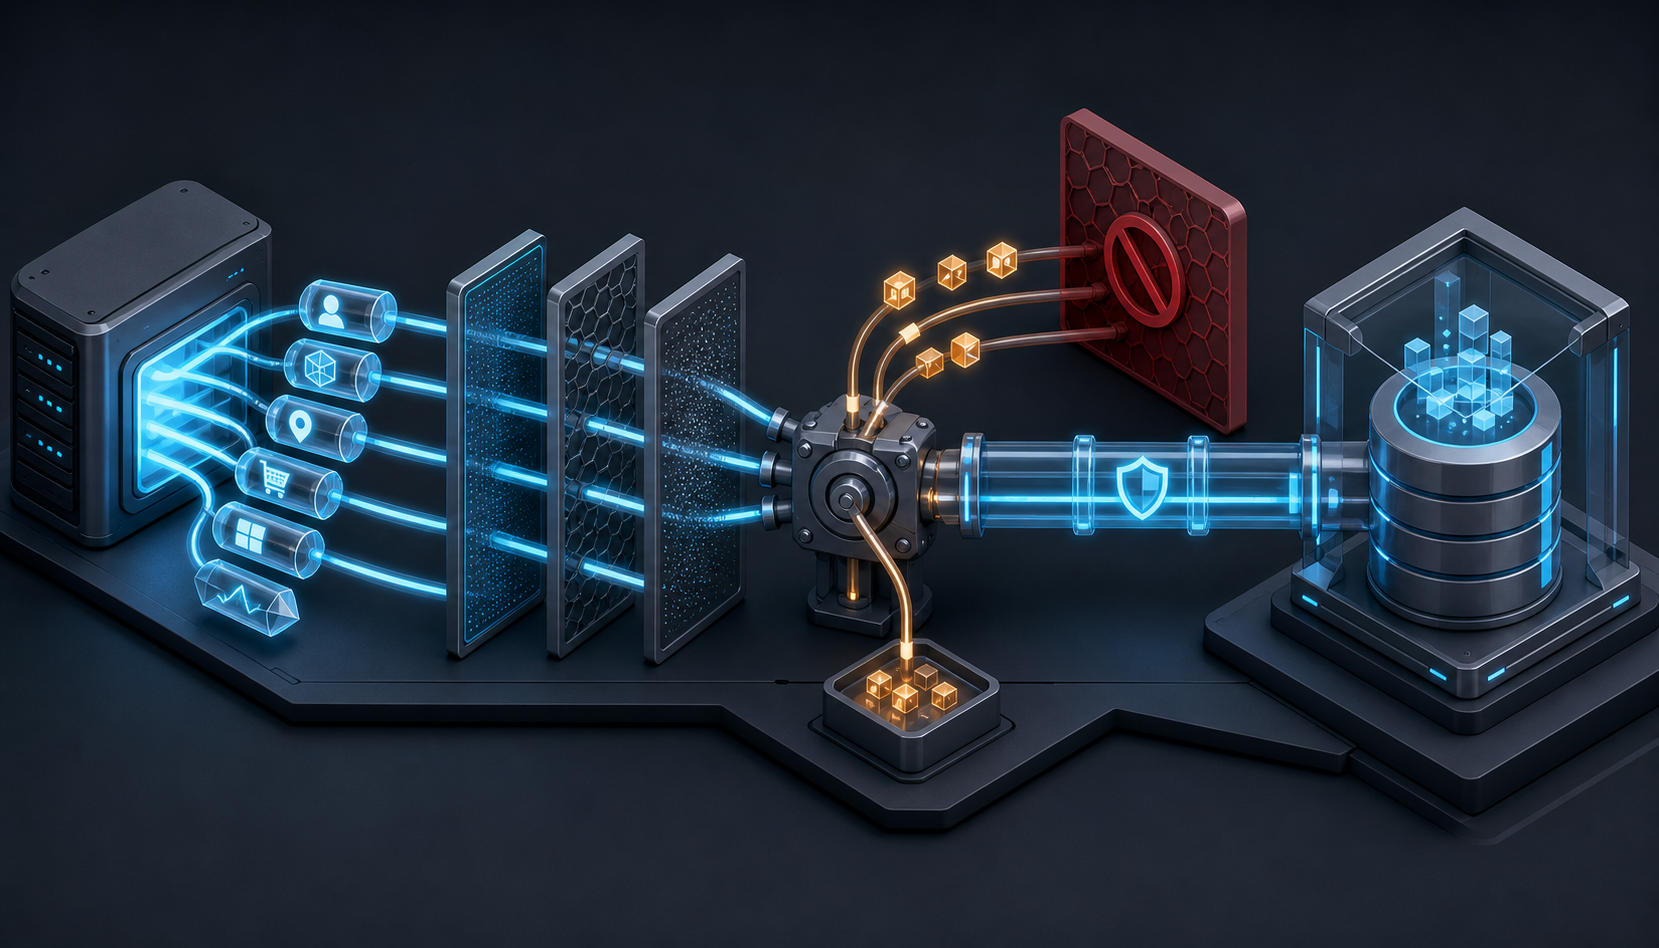
    Successive transparent trays show a varied group of colored tokens shrinking as many drop out early and a stable subset remains.

    You do not need an advanced predictive model to see the effect. Start with a customer-age cohort table that preserves the original acquisition population and follows it forward.

    1. Define entry consistently. Use a first paid order, activated subscription, signed contract, or another event that represents the start of the commercial relationship. Do not mix account creation with first purchase unless they mean the same thing in your business.
    2. Group customers into acquisition cohorts. A cohort should contain customers who entered during the same reporting period. Keep the cohort identifier fixed even if a customer’s channel, campaign, or status later changes.
    3. Replace calendar date with customer age. Label intervals as the first period after acquisition, the next period, and so on. This lets you compare customers at the same lifecycle stage instead of comparing a new cohort with an old one.
    4. Write an operational churn rule. For a monthly subscription whose status is inferred from transactions, the first 30 days can be a critical observation window, with no subsequent purchase treated as churn. If you use a 30-day inactivity rule, the newest 30 days are unresolved; do not count those customers as confirmed retained.
    5. Count the at-risk population at the start of every interval. Period churn must use that interval’s active population as its denominator. Dividing every interval’s departures by the original cohort produces cumulative attrition, not the churn propensity of current survivors.
    6. Attach value to the same intervals. Record revenue or contribution value per original acquired customer, and keep the definition consistent. If your decision concerns acquisition profitability, a value measure that ignores the costs required to serve orders can make payback look healthier than it is.
    7. Preserve acquisition-time dimensions. First-touch UTM medium, campaign, geography, initial product, job title, vertical, and account type can reveal whether the aggregate curve is hiding customer groups with different retention patterns.

    For each customer-age interval, calculate churn among customers active at its start. If A(t) is the at-risk population and D(t) is the number that churns during the interval, the interval churn propensity is D(t) divided by A(t). Retention for that interval is one minus that value when churn is the only exit. Multiplying the interval retention values gives the cumulative survival of the original cohort.

    Plot both interval churn and cumulative retention. A retention curve alone tells you how much of the cohort remains. The interval churn curve tells you whether the surviving population is becoming more stable. A sharp early decline followed by lower, steadier churn is the pattern that should prompt a shakeout investigation.

    Do not treat the shape as proof by itself. Split it by dimensions known at acquisition. An illustrative first-touch breakdown showed approximately 27% retention for email and 18% for Google after 500 days. Those figures are not portable benchmarks. Their value is methodological: an aggregate curve can conceal materially different acquisition populations.

    Model acquisition CLV and survivor CLV separately
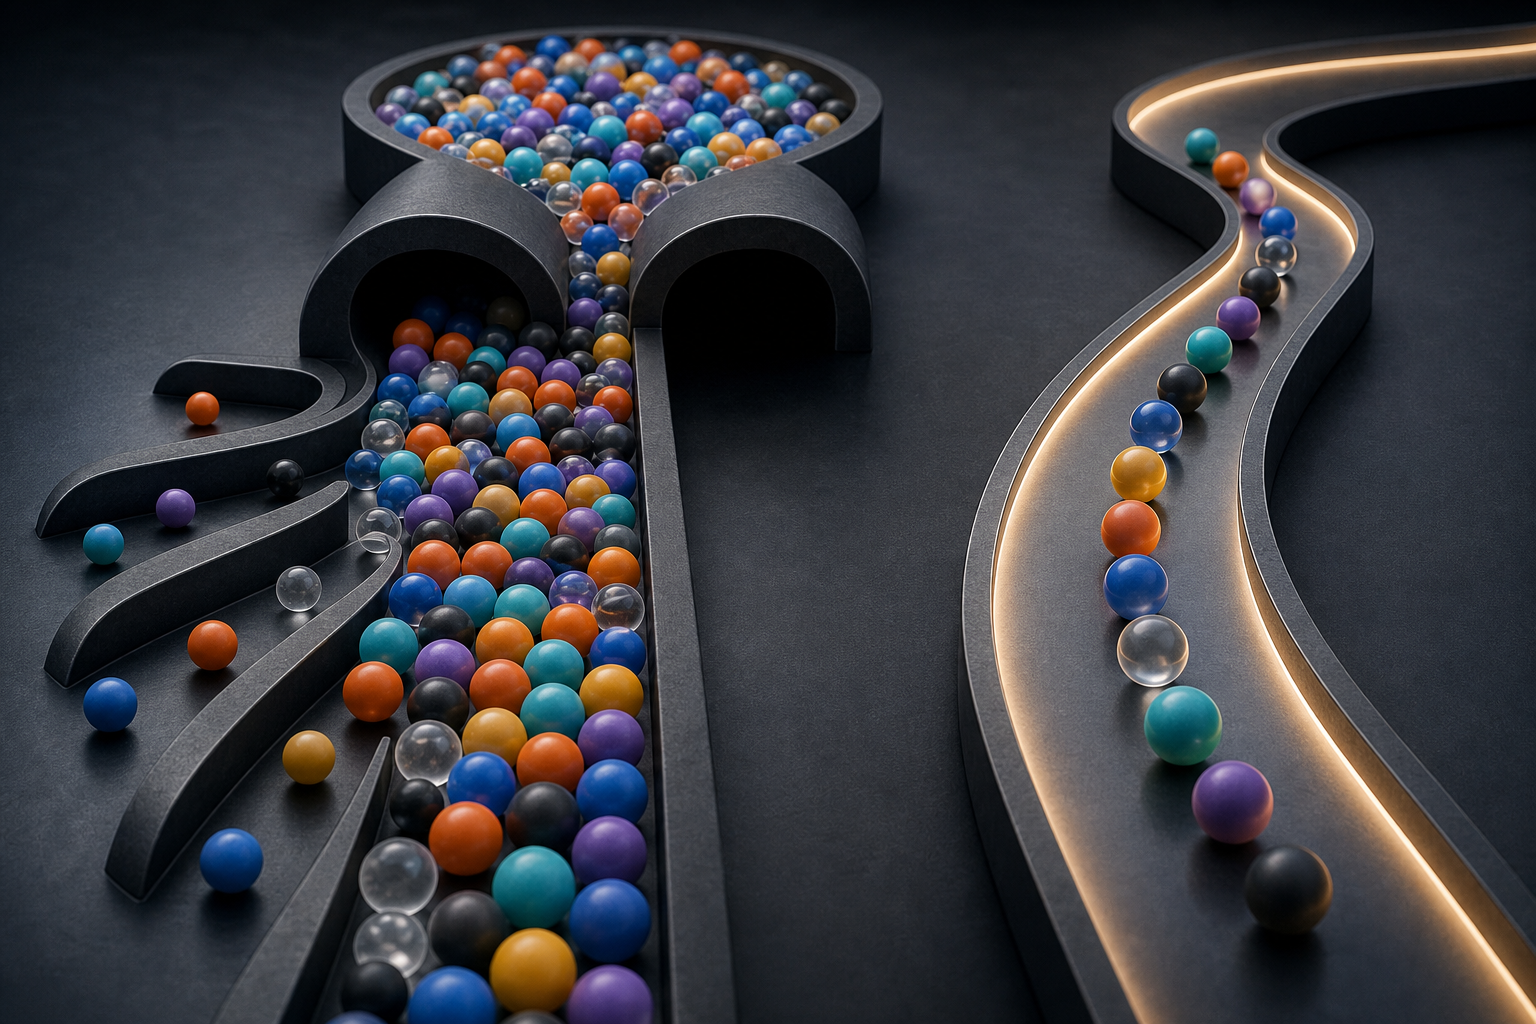
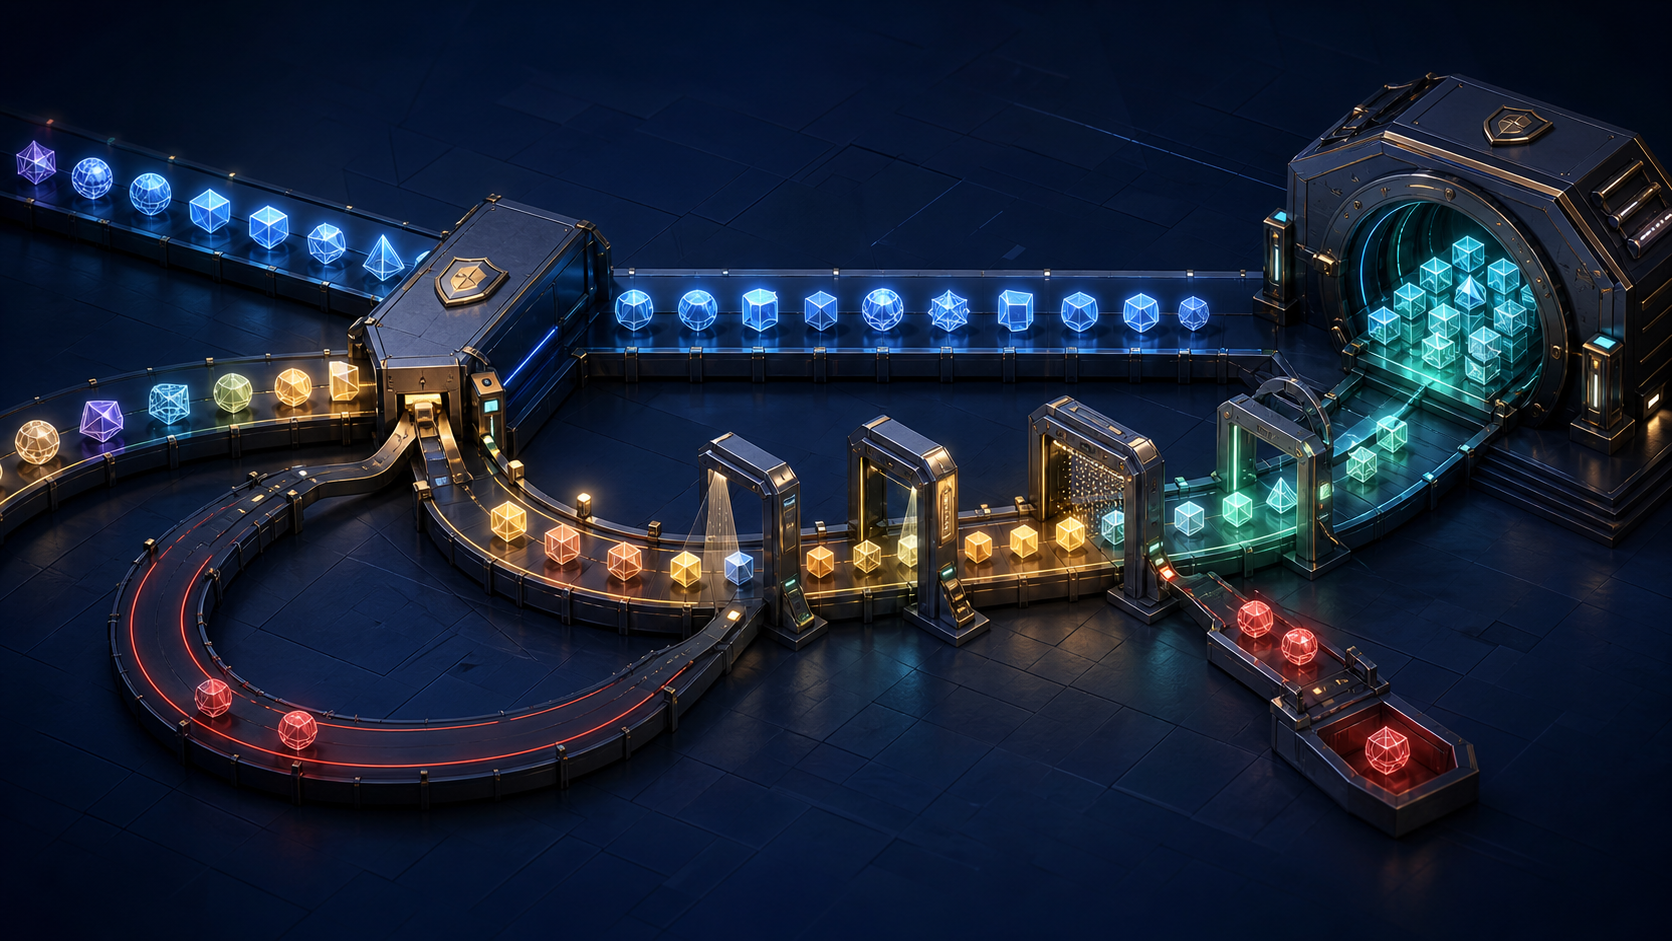
    A diverse stream of spheres loses some members near an acquisition gateway, while the surviving spheres continue along a separate longer track.

    The cleanest correction is to label the point from which every CLV estimate begins. There are two legitimate questions, but they require different answers:

    • Acquisition CLV asks what a newly acquired customer is worth before you know whether they will survive the early shakeout. It must include the value and probability of early exits.
    • Conditional survivor CLV asks what a customer is worth given that they are still active at a specified age. It starts from a selected, more durable population.

    Never use the second estimate to answer the first question. Conditional survivor CLV is useful for retention spending, account prioritization, and forecasting an existing customer base. Acquisition CLV is the relevant starting point for channel bidding and customer acquisition cost decisions.

    Replace one churn rate with lifecycle-specific probabilities

    A practical CLV forecast can be built period by period. For every future interval, estimate the probability that a customer reaches it, then multiply that probability by the expected value produced during that interval. Add the resulting period values across the forecast horizon.

    The important change is not mathematical complexity. It is allowing churn propensity and value to differ by customer age. Your early intervals represent the mixed acquisition population and its shakeout. Later intervals represent customers who have already survived. A segmented model can then allow those lifecycle patterns to differ by channel, product, geography, or account type.

    Choose the observation horizon deliberately. CLV analysis may use a one-year window or the available purchase history, depending on the business and the question. Whatever horizon you choose, keep observed value separate from forecast value. Recent customers have not yet had the same opportunity to churn or purchase as mature customers, so incomplete follow-up cannot be interpreted as long-term retention.

    Validate the path, not only the final total

    A model can land on a plausible total CLV for the wrong reasons. Check its predicted active-customer count, period churn, and period value at each customer age. If it underpredicts early departures and overpredicts later departures, those errors may partially cancel in the total while still producing bad acquisition and retention decisions.

    Backtest with mature cohorts whose later outcomes are already observable. Fit or calibrate the model using only the information that would have been available at an earlier cutoff, then compare its age-by-age predictions with what happened afterward. Repeat the check by acquisition segment. A model that works only for the blended population may fail as soon as the channel mix changes.

    Find heterogeneity you can actually use

    The shakeout effect tells you that customers differ. It does not tell you which fields explain those differences or whether a relationship is actionable. Explore the CRM in a sequence that separates targeting variables from behavior observed after acquisition.

    1. Start with acquisition-time fields. Channel, campaign, geography, initial product, B2B job title, vertical, and account type are available early enough to inform targeting, bidding, qualification, or positioning.
    2. Use early behavior as a lifecycle signal. Purchase frequency, newsletter subscription, recency, and product behavior can help identify which existing customers are moving toward the durable core.
    3. Keep outcome-derived fields out of acquisition predictions. A field that is only known after the customer has accumulated value cannot explain what you knew when the acquisition decision was made.
    4. Inspect distributions, not only averages. Plot CLV or contribution value across relevant dimensions so that a small group of very valuable customers does not make an entire segment appear uniformly strong.
    5. Confirm patterns on a later cohort. A field can correlate with CLV because of one campaign, product mix, or acquisition period. It is not useful for planning until the relationship survives an out-of-sample check.

    Ranked cross-correlation can serve as an exploratory screen for CRM features whose ordering varies with CLV. Above-average CLV has been associated with frequent purchases, newsletter subscription, purchase recency, and initial product behavior. For B2B analysis, job title, vertical, and account type provide additional dimensions worth screening.

    Treat those relationships as clues, not causes. Newsletter subscribers may be valuable because already-engaged customers choose to subscribe; subscribing itself may not create the value. Use acquisition-time fields to build prospect segments, use early behaviors to trigger retention work, and test any intervention before assigning it causal credit.

    A Lorenz curve can show how concentrated value is. Sort customers from lowest to highest lifetime value, calculate the cumulative share of customers, and compare it with their cumulative share of value. The familiar claim that roughly 80% of CLV may come from 20% of customers is a heuristic, not a ratio to impose on your data. Calculate your own concentration and identify the point at which the durable core actually begins.

    Turn the curve into acquisition and retention decisions

    Once the early shakeout and durable core are visible, each commercial decision should use the population that matches its starting point.

    • For acquisition budgets, use the full new-customer cohort. Include early churn and compare value with acquisition cost at the channel or segment level. Do not substitute the economics of mature survivors.
    • For onboarding, locate the customer-age intervals where departures are concentrated. Test changes before or during those intervals and judge them on incremental retention and value, not engagement alone.
    • For retention spending, estimate conditional future value among current survivors. A customer who has passed the shakeout can justify a different intervention budget from a newly acquired customer.
    • For channel evaluation, report both early survival and later conditional value. A channel can deliver many early exits yet still produce a valuable durable core, or show attractive mature-customer value while failing to produce enough survivors.
    • For forecasting, weight each lifecycle segment by the expected future acquisition mix. A historical blended churn rate becomes unreliable when the mix of channels, products, or account types changes.

    Your dashboard should therefore show at least four aligned views: cumulative retention by customer age, period churn among customers still at risk, value per original acquired customer, and conditional value per active survivor. Add the same views for the acquisition dimensions you can act on. This makes it much harder to confuse a changing cohort composition with a genuine improvement in customer behavior.

    Key takeaways

    • A falling cohort churn rate does not, by itself, prove that individual customers are becoming more loyal.
    • Acquisition CLV must include early exits; survivor CLV is conditional on having passed them.
    • Calculate churn from the active population at the start of each customer-age interval.
    • Segment by fields known at acquisition before using a retention pattern to change targeting or bids.
    • Validate age-specific survival and value, not only the model’s final CLV total.
    • Compare CLV with acquisition cost only when both measures refer to the same starting population.

    Start with one mature cohort. Put customer age on the horizontal axis, calculate period churn from the customers active at each interval’s start, and split the result by first-touch channel. If churn falls as the cohort ages, rebuild the CLV forecast with separate early and mature stages. That single correction keeps the loyal core from being mistaken for the average new customer.
    References

  • Google Ads Data Transmission Control: Setup and Decisions

    Google Ads Data Transmission Control: Setup and Decisions

    You have Consent Mode running, but the harder question starts when a visitor denies ad storage: should your Google tag send a limited signal with identifiers removed, or send nothing until consent is granted? Google Ads Data Transmission Control gives you that choice.

    This means consent denied is no longer a complete measurement policy. You need a decision for each data stream, a configuration that reflects it, and test evidence showing what actually leaves the browser in denied and granted states.

    Key takeaways

    • Data Transmission Control works only when Consent Mode is enabled, and it applies only to Google tags.
    • When ad_storage consent is denied, advertising data can be blocked completely or transmitted in a limited form with identifiers removed. The limited option still supports conversion modeling.
    • Behavioral analytics and diagnostic data can be controlled separately from advertising data. Restricting one stream does not force the same choice for the others.
    • Once consent is granted, normal data transmission resumes automatically.
    • The setting enforces a technical choice. It does not determine whether that choice satisfies your privacy notices, consent policy, contracts, or applicable law.

    What the control changes when consent is denied

    Consent Mode communicates a visitor’s consent state to Google tags. Data Transmission Control adds another layer: your organization decides how those tags should behave when advertising storage has not been permitted. It does not replace the consent signal or create the visitor-facing consent choice.

    For advertising data, you can allow limited transmission with identifiers removed or block transmission until consent is obtained. Limited transmission preserves signals that can support conversion modeling. Complete blocking prioritizes a no-transmission policy but removes those denied-state advertising signals.

    Data or consent stateAvailable decisionOperational result
    Advertising data while ad_storage is deniedAllow limited transmissionIdentifiers are removed, while the remaining signal can support conversion modeling.
    Advertising data while ad_storage is deniedBlock transmissionAdvertising data is not transmitted until consent is obtained.
    Behavioral analyticsSet independentlyAnalytics can remain allowed when advertising data is restricted, or it can be blocked separately.
    Diagnostic dataSet independentlyDiagnostic transmission can follow its own policy instead of automatically inheriting the advertising choice.
    Consent grantedAutomatic resumptionData transmission resumes without someone manually changing the control.

    The independence of these streams is the important part. A single denied consent state can produce several valid configurations. For example, you might block advertising data, allow behavioral analytics under a separately approved policy, and retain only the diagnostic data required to operate the tag. Another organization may block all three. The interface can support either approach; it cannot decide which approach is appropriate for you.

    What Data Transmission Control does not cover

    • It does not work without Consent Mode. If your tags do not receive the correct consent state, this control has no reliable state on which to act.
    • It governs Google tags only. Third-party pixels, custom scripts, server integrations, and other non-Google data flows need their own controls and tests.
    • It is configured at the tag level. Do not assume that changing one Google tag creates an account-wide rule for every tag in your implementation.
    • It does not change existing behavior merely by becoming available. If the feature is not enabled, the current transmission behavior remains in place.
    • It does not certify compliance. Identifier removal is a technical treatment, not a legal conclusion about whether data is anonymous, exempt from consent, or permitted in a particular jurisdiction.

    Choose a denied-state policy before opening the interface

    A hand hovers over a selector between a filtered data pathway and a pathway stopped by a solid barrier.

    The costly mistake is treating this as a measurement-team preference. The setting affects privacy posture, reporting coverage, and conversion modeling at the same time. Settle the policy first, then implement it in the interface.

    1. Define the advertising rule. If your approved policy requires zero advertising-data transmission until consent, choose complete blocking. If limited identifier-removed transmission is permitted, decide whether retaining modeling support is worth enabling that option.
    2. Assess behavioral analytics separately. Do not allow analytics merely because advertising data is blocked, and do not block it automatically merely because the advertising rule is strict. Record the purpose, data involved, consent treatment, and internal approval for the analytics decision.
    3. Define what counts as necessary diagnostic data. Separate information required to detect a broken implementation from information that is merely convenient to retain. Apply the transmission choice approved for that purpose.
    4. Resolve geographic or policy differences outside the toggle. If your rules vary by market, property, or user state, make sure the surrounding consent implementation supplies the correct state and scope. Data Transmission Control responds to the state it receives; it does not design your consent architecture.
    5. Decide who can approve a change. A measurement owner can document the reporting consequence, but privacy or legal owners should resolve unsettled questions about permitted transmission. Do not ask the interface to settle a policy dispute.

    Record the decision in a three-stream matrix

    A short decision record prevents the configuration from becoming an unexplained toggle that nobody wants to touch later. For each of advertising, behavioral analytics, and diagnostics, record:

    • The behavior required when consent is denied.
    • The business or operational purpose for any permitted transmission.
    • Whether the stream is limited, allowed, or blocked.
    • The Google tags and digital properties covered by the decision.
    • The policy, privacy, or legal owner who approved it.
    • The implementation owner and the date of the change.
    • The evidence that will prove the configuration works.

    Do not interpret identifiers removed as equivalent to no data or automatically compliant. If your organization has not classified the limited signal, keep transmission blocked while the privacy question is reviewed. Reduced measurement can be addressed later; data transmitted under the wrong policy cannot be recalled.

    Configure the control without losing track of scope

    In Google Ads, open Data Manager > Google tag > Manage > Manage data transmission. The setting is easy to miss because it sits inside the management view for the selected Google tag.

    1. Confirm that Consent Mode is enabled. Verify that the relevant Google tag receives a denied state when your consent system represents ad storage as denied.
    2. Select the Google tag in scope. Record its name, destination, and current transmission behavior before changing anything.
    3. Apply the approved advertising-data choice for denied ad_storage consent: limited transmission with identifiers removed, or complete blocking until consent is granted.
    4. Set behavioral analytics independently. Match the decision record instead of copying the advertising choice by habit.
    5. Set diagnostic data according to its approved purpose and scope.
    6. Save the configuration and add it to your implementation change log. Include the previous behavior, the new behavior, the affected tag, and the person who approved the policy.
    7. Repeat the review for every relevant Google tag. Then inventory non-Google tags separately, because this control does not govern them.

    The control can also be set through the user interface in Google Analytics or Campaign Manager 360. Whichever interface you use, the underlying prerequisites and scope remain important: Consent Mode must be enabled, and the control applies to Google tags.

    A saved setting is not proof of correct behavior. Your consent platform still has to pass the intended state, the intended Google tag has to receive it, and the resulting request has to match the selected transmission rule. Move directly from configuration to state-based testing.

    Test the denied, granted, and transition states

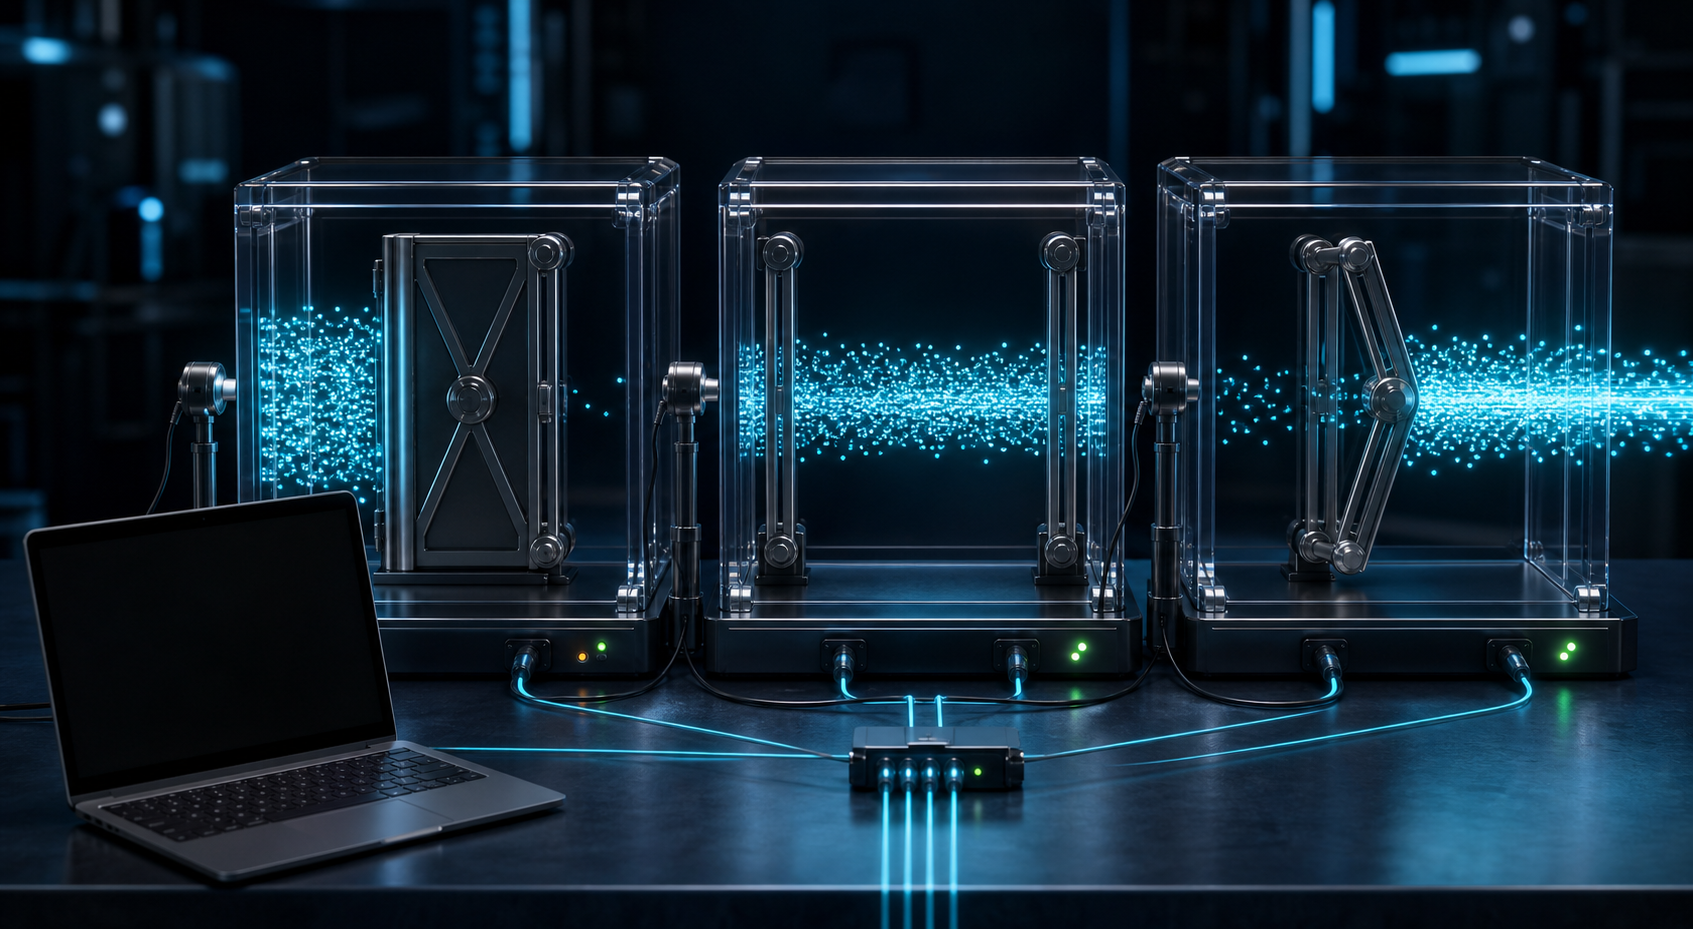
    Three connected test chambers show data particles blocked, transmitted, and changing as a privacy gate opens.

    Test what leaves the browser, not only what the consent banner displays. A banner can show denied while a tag receives the wrong state, and a correctly configured tag cannot compensate for that mismatch. Use your tag debugger and browser network inspection where applicable, and retain evidence from each test.

    1. Start with a clean browser session. Trigger the state your consent platform represents as denied, then confirm that the Google tag receives that state before evaluating its requests. Testing only a mid-session toggle cannot prove the initial page load behaved correctly.
    2. Check advertising transmission. Under complete blocking, confirm that the governed advertising data is not transmitted before consent. Under limited transmission, confirm that a request can occur only in the intended limited form and that the identifiers your policy prohibits are absent.
    3. Check behavioral analytics independently. Its observed behavior should match its own setting, even when advertising data follows a different rule.
    4. Check diagnostic transmission independently. Make sure operational data is neither blocked accidentally nor retained simply because another stream is allowed.
    5. Grant consent in the same session. Confirm that data transmission resumes automatically and that no manual configuration change is required.
    6. Repeat the test after navigation and in a new session. This checks whether the surrounding consent implementation preserves and communicates the state consistently; Data Transmission Control does not manage consent persistence for you.
    7. Repeat the matrix for each Google tag in scope. Audit non-Google requests separately so that a successful Google-tag test is not mistaken for proof that the whole site follows the same rule.

    Interpret reporting changes as implementation changes first

    Changing denied-state transmission can create a measurement discontinuity. Moving from limited transmission to blocking removes a class of signals that could support conversion modeling. Moving in the other direction introduces limited signals that were previously withheld. A before-and-after difference should not be attributed to campaign performance until you have separated the effect of the configuration change.

    Analytics and advertising totals may also diverge by design when behavioral analytics remains allowed while advertising data is blocked. Check the three-stream decision matrix before treating that difference as a broken tag or an attribution defect.

    Add an annotation to your measurement records with the change date, affected Google tags, previous choices, new choices, and test results. Anyone evaluating campaign or conversion trends later will then have the context needed to avoid a false performance conclusion.

    Your next step is concrete: write the three-stream policy, configure every Google tag in scope, and attach denied-state and consent-transition evidence to the change record. That turns a buried interface setting into an auditable control your privacy and measurement teams can manage together.

    References

  • Open-Source Marketing Mix Modeling Tools: How to Choose

    Open-Source Marketing Mix Modeling Tools: How to Choose

    You have a budget decision to make, channel data in hand, and four prominent open-source names on your shortlist: Robyn, Meridian, Orbit, and Prophet. The expensive mistake is not choosing the least sophisticated model. It is choosing a framework your team cannot validate, explain, refresh, or use when the next allocation decision arrives.

    The first question is not which tool is best. It is whether you need a working marketing mix modeling system or a forecasting component from which your team will build one. Once you make that distinction, the shortlist becomes much clearer.

    First, separate MMM systems from forecasting components

    A split illustration shows a connected end-to-end measurement machine beside a standalone forecasting engine surrounded by components that still need assembly.

    Marketing mix modeling uses aggregated business, marketing, and contextual data to estimate how different factors relate to an outcome such as revenue, orders, or qualified leads. A useful MMM workflow must do more than forecast that outcome. It also has to represent delayed advertising effects, account for diminishing returns, estimate channel contributions, communicate uncertainty, and turn the result into a budget scenario.

    That difference divides the four tools into two groups. Robyn and Meridian are designed to produce marketing insights and allocation guidance, while Orbit and Prophet are primarily forecasting tools. Orbit or Prophet can support an MMM system, but neither gives you a complete attribution and budget-optimization workflow on its own.

    ToolPrimary jobBest fitOperational cost to expect
    RobynAutomated MMM model exploration, channel response analysis, and budget optimizationA marketing analytics team that wants a relatively direct route from prepared data to actionable scenariosYou still have to choose among plausible models, validate the attribution, and monitor whether performance relationships have changed
    MeridianBayesian MMM with geo-level modeling and budget-reallocation scenariosA team with statistical expertise, geographic data, and market-specific allocation questionsThe methodology, diagnostics, assumptions, and uncertainty require informed statistical ownership
    OrbitBayesian time-series forecasting with time-varying coefficientsEngineers and data scientists building a custom measurement systemYour team must add MMM-specific transformations, attribution logic, validation, reporting, and optimization
    ProphetForecasting and separation of trend and seasonal patternsA team that needs a temporal modeling component inside a broader pipelineIt does not provide a complete channel-attribution or budget-allocation system

    This is more than a feature comparison. A model can predict next period’s sales accurately while assigning the wrong reason for those sales. Forecasting performance does not, by itself, establish credible marketing attribution. If your question is where to move budget, start with an MMM framework. If your goal is to build proprietary measurement infrastructure, a forecasting library may be the more flexible foundation.

    Open source removes a software-licensing barrier. It does not remove the cost of data preparation, statistical review, engineering, documentation, or ongoing model ownership. Include those jobs in your tool decision from the start.

    Match the tool to the way your team will operate it

    Choose Robyn when the priority is a usable MMM workflow

    Robyn is the practical starting point for many teams because it automates a large part of model exploration. It can evaluate thousands of configurations and return multiple strong candidate solutions, reducing the amount of manual tuning needed to reach a usable model set.

    Multiple solutions are a strength only if you have a rule for choosing among them. Do not automatically select the model with the most attractive return on ad spend or the most aggressive budget recommendation. Require acceptable overall fit, plausible channel behavior, stability across candidate models, and consistency with any experimental evidence you possess.

    Robyn also carries an important operating assumption: marketing performance is treated as reasonably consistent over the modeled period. A product launch, pricing change, tracking migration, major distribution shift, or campaign redesign can break that assumption. Mark known structural changes in the data and revalidate the relevant period before treating an old channel coefficient as current.

    Choose Meridian for geo-level questions and Bayesian depth

    Meridian is better suited to teams that want an advanced Bayesian model and can use geographic variation in their analysis. Its geo-level orientation is valuable when the real decision is not simply how much to spend by channel, but how channel performance and allocation may differ across markets.

    Do not choose Meridian merely because Bayesian sounds more rigorous. Bayesian modeling moves important judgment into model structure, prior assumptions, diagnostics, and interpretation of uncertainty. The right team should be able to explain those choices to the budget owner and rerun the analysis without depending on one person who understands the implementation.

    Meridian’s scenarios describe what may happen under the fitted model and its assumptions. They are not promises about the next planning period. That distinction should remain visible in every budget recommendation.

    Choose Orbit when you intend to build the MMM yourself

    Orbit is a forecasting foundation, not a shortcut to a finished MMM program. Its Bayesian time-varying coefficients are useful when relationships may evolve, but your team must still design the marketing-specific parts of the system. That includes carryover and saturation transformations, channel-contribution logic, scenario generation, validation, reporting, and an interface that planners can actually use.

    Orbit makes sense when custom behavior is the requirement and you have engineers and statisticians who will own the framework as a maintained product. If the custom build is only a way to avoid adapting to an existing MMM workflow, the maintenance burden will probably exceed the benefit.

    Use Prophet for temporal structure, not standalone attribution

    Prophet can help separate trend and seasonal patterns from a time series. That can make it useful in preprocessing, baseline forecasting, or another supporting role. It does not independently tell you how much incremental revenue a channel created or how the next budget should be allocated.

    If a proposed Prophet implementation ends with channel-level return figures, ask where the attribution assumptions, response curves, delayed effects, and optimization rules enter the pipeline. If those layers have not been designed and validated, you have a forecast labeled as an MMM.

    Build the minimum viable measurement plan before installing a tool

    Analysts arrange channel, outcome, calendar, external-factor, and experiment modules on a table before connecting them to several modeling devices.

    An MMM project should begin with a decision specification, not a package installation. The specification prevents a technically valid model from answering a question no one needs to ask.

    1. Write the allocation decision in one sentence. Name the business outcome, the budget that can move, the channels or markets in scope, and the planning decision the model must support. A request to understand marketing is too broad to determine the right model.
    2. Fix the unit, calendar, and boundaries. Choose one outcome definition and one consistent time interval. Align spend, exposure, business outcomes, promotions, and other controls to the same calendar and market coverage. Mismatched cutoffs can make an ordinary timing error look like an advertising lag.
    3. Create a channel dictionary. Record what each column includes, whether it represents spend or exposure, how platform names map to planning channels, and where definitions changed. Grouping should be detailed enough to support a decision but not so fragmented that several nearly identical series compete to explain the same movement.
    4. Identify demand drivers and structural breaks. Marketing is not the only reason an outcome changes. Record known effects such as promotions, price changes, distribution changes, launches, and tracking migrations. A model cannot infer a business event that is absent or incorrectly encoded in its inputs.
    5. Decide how delayed effects and saturation should behave. Advertising may continue to influence outcomes after the spend occurs, and additional spend may produce progressively smaller gains. Robyn and Meridian include mechanisms for these behaviors, but the resulting curves still need to make sense for the channel and the observed data.
    6. Define acceptance checks before seeing ROI estimates. Specify how you will assess fit, channel plausibility, stability across acceptable models, agreement with experiments, and sensitivity to changed assumptions. Setting the rules first reduces the temptation to accept whichever model supports the preferred budget narrative.
    7. Assign an operating owner. Name who refreshes the data, investigates failed checks, approves model changes, documents assumptions, and translates scenarios into planning constraints. If no one owns the second run, the first run is a demonstration rather than a measurement capability.

    Data variation matters throughout this process. A channel that barely changes cannot reveal much about how different spending levels affect the outcome. Two channels that always rise and fall together are difficult to separate cleanly. The tool may still return precise-looking contributions, but interface precision cannot create information the data does not contain.

    The budget optimizer belongs at the end of this workflow. If the outcome, calendar, channel definitions, or response assumptions are wrong, optimization simply reallocates the error with greater confidence.

    Treat allocation outputs as testable scenarios, not account ledgers

    MMM contributions are model-conditioned estimates. They are not transaction records showing exactly which channel caused each sale. This matters because the most visually convincing output is often the optimizer: it turns uncertain relationships into a clean allocation. The neatness of that recommendation can hide the uncertainty underneath it.

    Run four checks before moving material budget

    1. Check direction across acceptable models. If one credible model says to increase a channel and another says to decrease it, the decision is not robust. Report the disagreement instead of averaging it into false certainty.
    2. Separate interpolation from extrapolation. A response curve is more defensible within spending levels represented in the data. A recommendation far beyond that range depends heavily on the assumed curve shape. Label that dependence and use a staged change rather than treating the estimate as observed behavior.
    3. Use experimental outcomes where available. Robyn can incorporate real-world experiment results. Treat those results as calibration evidence and investigate meaningful conflicts between the experiment and the observational model rather than selecting the answer with the better financial story.
    4. Apply real planning constraints. Contracts, minimum brand presence, inventory, market capacity, and operational limits do not disappear because an unconstrained optimizer prefers a different allocation. Put those constraints into scenario design or apply them before presenting the recommendation.

    A full reallocation based on a first model can waste budget if the model has learned a temporary correlation or extrapolated beyond the available evidence. Stage consequential changes where possible, observe the outcome, and feed that evidence into the next model cycle. The objective is not to obey an optimizer. It is to make a better decision and create evidence for the decision after it.

    Your final output should show more than a single return estimate. Keep the modeled period, outcome definition, channel mapping, major assumptions, candidate-model uncertainty, scenario constraints, and known structural breaks beside the recommendation. A planner should be able to see why the number may change before acting on it.

    Key takeaways

    • Robyn is the practical default when you need an accessible, end-to-end MMM workflow and can actively validate its candidate models.
    • Meridian fits geo-level allocation questions when your team has the statistical depth to own a Bayesian model and explain its uncertainty.
    • Orbit is a foundation for a custom time-series and MMM system, not a ready-made attribution and optimization product.
    • Prophet can model trend and seasonality, but it does not become a complete MMM simply because marketing variables are added.
    • Choose the tool only after defining the budget decision, data boundaries, validation checks, planning constraints, and long-term owner.

    If you need a usable MMM workflow, start by testing Robyn against one clearly defined allocation decision. Evaluate Meridian instead when geographic variation is central and Bayesian expertise is available. Reserve Orbit for a deliberate custom build, and use Prophet only for the supporting forecasting job it is designed to do.

    Before installing anything, complete this sentence: We will use [outcome] at [time and geographic level] to decide [specific budget action], and we will trust the result only if it passes [named validation checks]. If your team cannot fill in those four blanks, tool selection is premature.

    References

  • How to Migrate Google Ads Conversion Tracking Safely

    How to Migrate Google Ads Conversion Tracking Safely

    Your Google Ads reports can look normal right up until an import starts being rejected. If your server-side or offline conversion pipeline includes session attributes or IP address data, the weak point is now the route those fields take, not necessarily the conversion event itself.

    The safest response is a controlled handoff. Identify every affected import, move the restricted data to the Data Manager API, verify the new route without counting the same event twice, and retire the old path only after reporting and error handling are stable.

    First, prove that your conversion import is affected

    This is not a blanket shutdown of every Google Ads API conversion workflow. The immediate trigger is narrower: new users of session attributes or IP address data cannot send those fields through Google Ads API conversion imports. Existing implementations may continue for now, but continued acceptance should not be treated as a permanent architecture guarantee.

    Start with the payload your system actually sends. A design document or old integration ticket may not reflect production behavior, especially if another team added enrichment fields later.

    • Find every sender. Inventory scheduled jobs, CRM connectors, server-side services, data warehouses, tag-management servers, and vendor integrations that import conversions through the Google Ads API.
    • Inspect the request definition. Check the serialized payload, mapping configuration, or schema for session attributes and IP address fields. Inspect field presence without copying raw IP addresses or user data into an audit spreadsheet.
    • Map the affected scope. Record which Google Ads customers and conversion actions receive data from each sender.
    • Identify the developer token. The restriction is tied to allowlisting, so two integrations serving the same advertiser may behave differently if they use different credentials.
    • Search error telemetry. Look specifically for CUSTOMER_NOT_ALLOWLISTED_FOR_THIS_FEATURE rather than relying on a generic failed-jobs total.
    • List downstream users. Note which reports, alerts, budget decisions, and automated bidding strategies depend on the imported conversions.

    You should finish this audit with one of three classifications. If neither field is present, this particular restriction is not an immediate migration trigger. If you are building a new implementation that needs either field, design it around the Data Manager API before launch. If an existing allowlisted implementation still works, use that continuity as a migration window rather than a reason to postpone the work.

    Treat the change as a data-route migration

    An isometric routing junction redirects conversion events from a blocked legacy channel into a secure data channel.

    Simply renaming or deleting fields misses the architectural change. Google is positioning the Google Ads API around campaign management and core conversion workflows while directing more complex conversion and user-data transfer toward the Data Manager API.

    That means your migration plan needs to separate three responsibilities:

    • Event creation: the system that decides a conversion occurred and constructs the business record.
    • Data delivery: the API route that carries the conversion and any associated session or user data.
    • Measurement control: the monitoring that confirms events were accepted once, reached the intended destination, and remained available to reporting and bidding.

    Write a field-level migration contract before changing production code. For each field in the current payload, record its originating system, its purpose, its destination in the new route, whether it may remain in the Google Ads API request, and what should happen if the destination rejects it. Explicitly mark session attributes and IP address data so they cannot leak back into the legacy request through a shared serializer or enrichment step.

    The contract also needs an event identity rule. During a staged migration, two working API clients can be more dangerous than one broken client because both may submit the same conversion. Do not assume the two routes will deduplicate an event for you. Use a non-overlapping test scope or a verified deduplication control, and make the event identifier visible in operational logs without exposing unnecessary user data.

    Use a staged cutover that protects conversion continuity

    Unique conversion tokens pass through parallel migration lanes and a deduplication checkpoint before reaching one counting destination.

    A migration should change one variable at a time. If you replace the API route, revise attribution logic, rename conversion actions, and alter campaign goals in the same release, a reporting difference will be almost impossible to diagnose.

    1. Capture a baseline. Record normal submitted, accepted, rejected, and retried event volumes for each affected conversion action. Include conversion values and delivery delays where those matter to your reporting.
    2. Instrument the current path. Make sure every submission has a traceable status and that policy errors are separated from transient delivery failures. A single generic success rate hides the failure you need to see.
    3. Build the Data Manager route. Implement the mapped destination for the complex conversion and user data, including the session attributes or IP-related data your existing workflow requires.
    4. Clean the Google Ads API payload. Remove session attributes and IP address fields from that route. This can prevent the allowlisting rejection while the new transfer path is established, but it does not prove that the resulting measurement is equivalent.
    5. Test a non-overlapping slice. Route a clearly defined subset through the new path. Keep the rest on the existing path so you can isolate differences without submitting the same events twice.
    6. Reconcile at the event and aggregate levels. Check individual event identity and status, then compare counts, values, rejection reasons, and availability timing for comparable conversion actions and time windows.
    7. Expand gradually. Increase the new route’s scope only after its error behavior is understood. Watch reporting and automated bidding inputs as closely as API health because missing conversions can distort both performance analysis and bidding decisions.
    8. Retire the legacy import. Phase out the affected Google Ads API conversion import only after the Data Manager route, monitoring, replay behavior, and operational ownership have all been validated.

    Define stop and rollback conditions before launch

    Set the conditions that pause the cutover before you begin it. Useful signals include an unexpected rise in rejected events, missing event identifiers, duplicate submissions, a material drop in accepted conversions, or delivery delays outside the range your campaigns normally receive.

    A rollback must not reintroduce restricted fields into a non-allowlisted Google Ads API request. The safer fallback is to pause expansion, keep unaffected conversion imports running, and repair the Data Manager route. Replay failed events only when your retention rules allow it and your event identity controls can prevent duplicates.

    Handle the allowlisting error as a routing failure

    The error CUSTOMER_NOT_ALLOWLISTED_FOR_THIS_FEATURE means the conversion import was rejected because session attributes or IP address data were included without the required allowlisting. Treat it as a deterministic policy failure, not as ordinary network instability.

    Automatic retries with an unchanged payload will repeat the same mistake. Your failure handler should instead follow a specific branch:

    1. Stop blind retries for the rejected payload.
    2. Record the affected customer, conversion action, event identifier, credential path, and prohibited field type without logging the raw IP address or unnecessary user data.
    3. Remove session attributes and IP address fields from the Google Ads API version of the request.
    4. Route the affected complex data through the Data Manager API.
    5. Retry the cleaned conversion only if the remaining request is valid and your event controls show it has not already been accepted.
    6. Alert the integration owner if the same policy error recurs after the payload has supposedly been cleaned. That usually points to a shared serializer, enrichment service, or secondary sender still adding the fields.

    This distinction matters operationally. A transient failure belongs in a delayed retry queue. A policy rejection belongs in a remediation queue because time alone will not change the result.

    Validate reporting and bidding, not just API delivery

    A healthy API dashboard is necessary, but it is not enough. The purpose of the pipeline is to produce trustworthy conversion signals. A request can leave your system without generating the measurement outcome your team expects.

    Use four layers of validation:

    • Transport health: attempted, accepted, rejected, retried, and permanently failed submissions by route.
    • Event integrity: missing identifiers, duplicated identifiers, unexpected field omissions, and events sent through both routes.
    • Measurement continuity: conversion counts and values by conversion action, source system, and comparable time window. Compare like with like; a changed scope can make a correct migration look wrong.
    • Decision continuity: sudden changes in the conversions used for campaign reporting or automated bidding. Avoid declaring a campaign performance change while a known tracking gap is still being repaired.

    Choose alert thresholds from your own baseline rather than copying a universal percentage. Conversion volume and delivery timing differ too much across businesses for one threshold to be meaningful. The important control is that a known policy rejection, duplicate, or unexplained loss cannot remain hidden inside an aggregate success metric.

    Keep the migration observable after cutover. The first clean deployment does not protect you from a later code change that adds the restricted fields back to the Google Ads API payload. Add a schema-level test or outbound request check that fails before such a request reaches production.

    Key takeaways

    • This migration is immediately relevant when Google Ads API conversion imports include session attributes or IP address data.
    • Existing access may continue, but it should be treated as time to migrate rather than proof that the current route is permanent.
    • Move complex conversion and user-data transfer to the Data Manager API, and remove the restricted fields from Google Ads API requests.
    • CUSTOMER_NOT_ALLOWLISTED_FOR_THIS_FEATURE is a policy and routing problem. Retrying an unchanged payload will not resolve it.
    • Test with a non-overlapping event scope, reconcile individual events and aggregate results, and prevent duplicate conversion submissions.
    • Judge the cutover by reporting and automated bidding continuity as well as API acceptance.

    Your next action is small and decisive: open the production request definition and determine whether either restricted field is present. If the answer is yes, name the migration owner, document the current baseline, and create the Data Manager route before changing the legacy importer. That sequence gives you a controlled cutover instead of an emergency caused by rejected conversions.

    References

  • Google Ads and Measurement Updates: A Practical Action Plan

    Google Ads and Measurement Updates: A Practical Action Plan

    Your Google Ads account can look healthy while the business behind it becomes harder to explain. A Vehicle Ad can generate a phone call before the shopper visits your site, tag traffic can move through your first-party domain, and a mid-month budget edit can change spending behavior immediately.

    If your reporting still assumes a neat click-to-pageview-to-form path and evenly distributed daily spend, those changes create blind spots. The practical response is to manage calls, tagging and budgets as parts of the same revenue system: capture the demand, preserve the measurement signal and control what you spend to acquire it.

    Treat the updates as one revenue system

    These changes sit in different Google interfaces, but they affect one connected workflow. Vehicle Ads determine how a prospect reaches you. Google Tag Gateway affects how reliably eligible tag requests travel from your site to Google. Campaign budgets determine how much demand you can pursue and when.

    A failure at any point can distort the others. More calls are not valuable if nobody answers them. More observable events are not useful if duplicate or poorly defined conversions inflate the count. A larger budget is not productive if finance cannot reconcile the projected spend or the sales team cannot handle the resulting demand.

    Key takeaways

    • Treat a call from an ad as the start of a measurable sales path, not proof of a sale.
    • Use first-party tag routing to strengthen signal transport, but keep consent, event definitions and data quality controls separate.
    • Model a budget change before editing the campaign because Google can alter the applicable spending limit and pacing from the change date forward.
    • Give marketing, analytics, sales operations and finance a shared definition of success before you scale any of these changes.

    The unifying document should be a measurement contract. For every important event, write down what happened, which system recorded it, who owns the next step and which business decision the event supports. That short exercise exposes gaps that a polished dashboard can hide.

    Make click-to-call accountable past the tap

    A shopper calls beside a vehicle as a glowing signal links the phone to attribution checkpoints and a sales handshake.

    Google’s click-to-call capability for Vehicle Ads reduces the distance between a high-intent vehicle search and a live conversation with a dealership. It also moves part of the conversion experience away from the landing page and into an operational channel that paid-media teams do not always control.

    That changes the question you need to answer. It is no longer enough to ask whether the ad produced a call. You need to know whether the call connected, whether the caller was a plausible buyer, whether an appointment or useful follow-up resulted, and whether the opportunity eventually generated revenue.

    Build the call conversion chain

    1. Capture the ad interaction. Retain the campaign, ad group, advertised vehicle and other available acquisition context. Do not promise fields that your advertising, phone and CRM systems cannot actually pass between them.
    2. Record the operational outcome. Distinguish an initiated call from an answered call, a missed call, a disconnected attempt and a completed callback.
    3. Classify the sales outcome. Use a small, enforced set of CRM statuses such as unqualified, qualified, appointment booked, follow-up required, closed lost and sold.
    4. Attach value at the appropriate stage. A raw call and a completed sale should not carry the same meaning. If value is unavailable, report the outcome honestly instead of inventing a revenue proxy.
    5. Reconcile the systems. Compare ad-generated call records with phone-platform and CRM outcomes. Unmatched records should enter an exception queue rather than silently disappearing from reporting.

    A simple metric ladder makes the handoff visible:

    MetricCalculationWhat it helps you notice
    Connection rateAnswered calls divided by initiated callsRouting, staffing or phone-system friction
    Qualification rateQualified calls divided by answered callsWhether the ads are attracting plausible buyers
    Appointment yieldAppointments divided by qualified callsHow effectively staff convert intent into a next step
    Sales yieldCompleted sales divided by qualified callsWhether call volume is producing business value

    Do not collapse that ladder into a single conversion count. If initiated calls rise while the connection rate falls, bidding is not the first problem to solve. Check opening hours, routing rules, queue coverage and missed-call ownership. If calls connect but few qualify, inspect campaign targeting, inventory alignment and the expectations set by the ad. If qualified calls stall after the conversation, the failure sits in sales follow-up rather than media delivery.

    Give every call an operational owner

    Before enabling call-led demand broadly, document who handles each state:

    • Which team answers during advertised business hours.
    • Where a call goes when the primary recipient is unavailable.
    • Who reviews missed and abandoned calls.
    • How callbacks are associated with the original lead instead of counted as unrelated opportunities.
    • Which CRM field records qualification, appointment and sale outcomes.
    • Who audits missing outcomes and how often that review occurs.

    This is not administrative detail. Once the ad itself becomes a direct contact point, call handling becomes part of campaign performance. Media optimization cannot compensate for unanswered demand, and a sales team should not be judged on lead quality when the acquisition data cannot be connected to actual conversations.

    Use Tag Gateway to strengthen transport, not excuse data design

    Google Tag Gateway now has a beta deployment path through Google Cloud Platform. The workflow is available from Google Tag Manager and Google tag settings and uses Google Cloud’s Global External Application Load Balancer to route eligible tag traffic through your first-party domain before forwarding it to Google.

    The architecture places Google’s tagging infrastructure behind a same-site, same-origin first-party host. It is intended to improve signal quality and make measurement more resilient to some ad-blocking behavior and browser restrictions, including Apple’s Intelligent Tracking Prevention. Treat those benefits as the purpose of the design, not a guarantee that every missing signal will return.

    The distinction matters. A gateway can improve the route a request takes. It cannot repair a badly named event, an accidental duplicate, a broken data-layer value or a conversion that has no relationship to a business outcome. It also does not turn data collection into permission. Your consent rules, disclosure obligations, retention controls and internal governance still apply when traffic uses a first-party host.

    Deploy it as a measured infrastructure change

    1. Map the current request path. Record which Google tags load, where they load, which events they send and which teams own the site, tag manager, cloud infrastructure and analytics configuration.
    2. Capture a baseline. Preserve representative event counts, conversion counts, duplicate rates and known gaps before changing the route. Without a baseline, a higher count after deployment can be mistaken for an improvement even when it comes from duplication.
    3. Choose a contained scope. Because the Google Cloud integration is in beta, begin where you can validate the route and reverse the change without disrupting every property or campaign.
    4. Use the supported setup path. Complete the workflow from Google Tag Manager or Google tag settings and review the External Application Load Balancer configuration created in Google Cloud.
    5. Validate the route. Confirm that intended requests use the first-party host and reach the expected destination. Also verify that unrelated application traffic is not being caught by the routing rules.
    6. Test event behavior. Compare event names, parameters and conversion totals before and after the change. Investigate missing events, unexpected increases and duplicate conversions before calling the deployment successful.
    7. Document ownership and rollback. Record the hostname, routing configuration, deployment owner, monitoring owner and the safe procedure for returning to the previous path.

    The new GCP workflow reduces deployment friction for teams already operating in Google Cloud. Cloudflare had been the only automated option identified for Google Tag Gateway, while other content delivery networks required manual setup. Lower setup friction is useful, but it should not remove technical review. A one-click provisioner can create infrastructure; it cannot decide whether your event model is correct.

    Use reconciliation, not event volume, as the success test

    Measure the gateway at three levels. First, confirm transport health: intended requests use the expected first-party route and complete successfully. Second, confirm analytics integrity: event names, parameters and deduplication behavior remain correct. Third, reconcile business outcomes: the conversions used for bidding and reporting still agree with downstream lead, appointment, order or revenue records.

    An increase in observed events is only useful when you can explain it. The increase might represent recovered signal, but it might also expose a pre-existing implementation difference or introduce duplicate collection. Keep the classification open until the analytics and business records agree.

    Model every budget edit before you make it

    An operations specialist compares stable and surging token flows in a tabletop simulation before adjusting a budget control.

    A Google Ads average daily budget is not a strict daily ceiling. Google may spend up to twice that amount on a high-traffic day while applying the relevant monthly charging limit. That makes smooth daily pacing a planning assumption, not a platform promise.

    A mid-month budget change recalculates the plan from the edit date forward. The applicable monthly limit reflects the old budget for the earlier period and the new budget for the later period. The potential daily overdelivery threshold adjusts immediately, and Google re-optimizes pacing for the remaining time.

    This is why simply multiplying the new daily amount by the days left can give you the wrong expectation. It ignores what has already been spent, the earlier budget period and the platform’s pacing behavior.

    Use three projections for three different questions

    ControlQuestion it answersHow to use it
    Budget reportWhat spend is Google currently projecting?Review the campaign’s budget history, change marker and projected billing outcome.
    Performance PlannerWhat performance trade-off might a different budget create?Compare budget scenarios against projected clicks, conversions and other relevant outcomes.
    Manual calculationDoes the platform projection fit the business constraint?Subtract cost to date from the revised period goal, then divide the remainder by the days left as a planning guide.

    The manual check is deliberately simple:

    Remaining allowable spend = revised period goal minus cost to date.

    Planning pace = remaining allowable spend divided by the days left in the period.

    That pace is a finance guardrail, not a guarantee that Google will spend the same amount each day. Compare it with the budget report. If the platform projection does not fit the business constraint, resolve the difference before saving the edit.

    Performance Planner answers a separate question. A budget reduction may meet the spending requirement while also reducing projected clicks or conversions. Put both effects in the approval request. Saying that a change saves money without showing the likely opportunity cost leaves the decision incomplete.

    Use a repeatable edit protocol

    • Before the edit: capture cost to date, the current budget report projection, the relevant Performance Planner scenario and the revised business target.
    • At the edit: record the old budget, new budget, campaign, timestamp, approver and reason. Google Ads reporting can display a gray triangle at the change date, but your internal record should explain why the change happened.
    • After the edit: reopen the budget report and verify that the revised projection matches the intended direction. Do not rely on the number entered in the budget field as proof.
    • During the remaining period: compare actual cost with the remaining allowable amount and watch conversion quality. A campaign can underspend because demand, targeting or return-on-ad-spend constraints limit delivery, even when budget is available.
    • At period close: reconcile billed spend, reported performance and the approval record so the next planning cycle begins with an explainable baseline.

    Manage campaign total budgets separately from average daily budgets. Campaign total budgets aim to spend a defined amount by an end date and do not use the same daily-cap model. They can suit bounded promotional or video activity, but their end-date orientation makes them a different planning instrument, not a shortcut around daily-budget controls.

    Run the rollout as a controlled operating change

    The cleanest implementation assigns an owner and evidence standard to every workstream:

    WorkstreamPrimary ownersEvidence required before expansion
    Vehicle call conversionPaid media and sales operationsCalls can be connected to answer, qualification, appointment and sales outcomes.
    First-party tag routingAnalytics, web engineering and cloud infrastructureRequests use the intended route without unexplained loss, duplication or parameter changes.
    Budget controlPaid media and financeThe budget report, performance scenario and manual constraint check tell a coherent story.
    Business reconciliationMarketing operations and the relevant revenue ownerAdvertising conversions can be compared with downstream CRM or commerce outcomes.

    Start by writing the measurement contract for a contained campaign or property. Preserve the current baseline. Make the scoped change, then reconcile platform events with operational and financial outcomes. Expand only after the team can explain both gains and discrepancies.

    Your shared dashboard does not need every available Google Ads field. It needs the fields that reveal a broken handoff: spend to date, projected spend, the latest budget change, calls initiated, calls answered, qualified opportunities, appointments, sales outcomes, expected tag events, received tag events and unresolved exceptions.

    At your next change window, trace a real prospect from the ad through the call or site event, into the downstream business record and back to the budget decision. Wherever that trace breaks is where you should work next.

    References

  • How to Measure Brand Growth Beyond Clicks and Traffic

    How to Measure Brand Growth Beyond Clicks and Traffic

    You open the dashboard and see fewer organic sessions, fewer referral visits, or a lower click-through rate. The immediate conclusion is tempting: the brand is losing ground. But traffic can fall even while more people are learning your name, considering your offer, and searching for you when they are ready to act.

    The answer is not to replace traffic with another all-purpose KPI. You need a measurement system that separates brand visibility, demand, demand capture, and business results. That gives you a way to judge brand growth even when AI answers, social discovery, video, marketplaces, and delayed decisions leave no clean click trail.

    Separate demand creation from demand capture

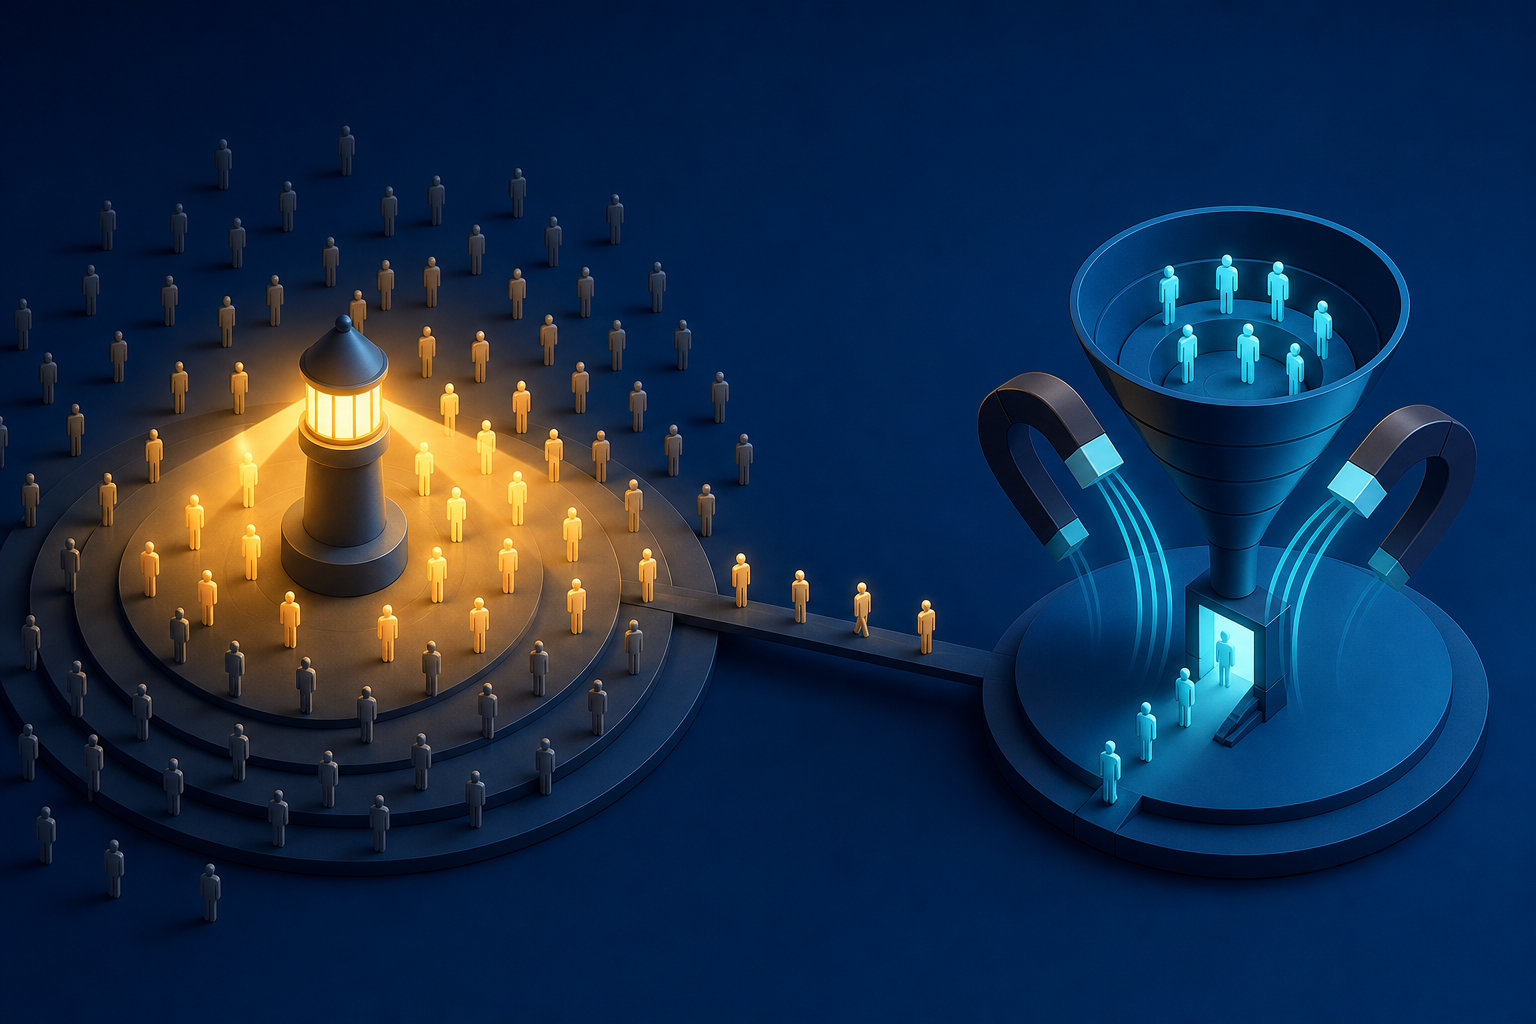
    Split illustration with a beacon creating awareness among a broad audience on the left and a funnel guiding interested people toward a purchase doorway on the right.

    A click is an observable interaction. It tells you that someone selected a tracked link on a particular device, browser, platform, and occasion. It does not tell you everything that made the person recognize, trust, or prefer the brand.

    That distinction matters because buyers rarely move through a single, fully tracked path. Someone might encounter your brand in a LinkedIn video, read independent reviews, study a case page, ask an AI assistant about the category, and return later through a branded Google search. A click-based model may credit only the final search even though several earlier interactions educated and persuaded the buyer.

    First-click, last-click, linear, and time-decay attribution models distribute credit differently, but they share the same boundary: they can allocate only the interactions the system captured. An untracked exposure cannot receive credit. Cross-device research, offline conversations, social viewing, AI answers, and delayed brand recall can therefore disappear from the reported journey.

    Traffic has a similar limitation. It measures delivery to your website, not total demand for your brand. A visit can be highly valuable, but a person can also learn enough from an answer surface to skip the visit and search for your company later. As AI and platform experiences answer more questions without an outbound click, the gap between influence and site traffic becomes harder to ignore.

    Measurement layerQuestion it answersUseful signalsDecision it should inform
    Business resultDid marketing contribute to an outcome the organization values?Revenue, qualified pipeline, sales, renewals, or another defined commercial outcomeWhether growth is reaching the business
    Brand demandAre more category buyers actively looking for us?Share of search, branded search volume, and direct brand-seeking behaviorWhether mental availability and preference may be strengthening
    Visibility and validationWhere can buyers encounter or verify the brand?Brand mentions, answer-engine presence, reviews, category visibility, video exposure, and case-content useWhere awareness or trust may be developing
    Demand captureHow efficiently do we turn existing interest into an owned interaction?Clicks, sessions, landing-page behavior, leads, and conversion rateWhether channels and experiences capture demand effectively

    No row makes the others unnecessary. Business outcomes can arrive too late to diagnose a current problem. Visibility can grow without producing qualified demand. Branded demand can rise while a weak website or sales process wastes it. Clicks can fall because distribution changed rather than because the brand weakened.

    Label every metric on your current dashboard by layer. If nearly everything sits in demand capture, you do not have a brand measurement dashboard. You have a website acquisition report.

    Use share of search as a demand signal

    Share of search compares demand for your brand with branded search demand across the category you have defined. Expressed as a percentage, the working formula is:

    Share of search = your branded search volume / total branded search volume for the selected competitive set

    This is not the same as your share of generic keyword rankings. It asks how often people look specifically for you relative to the brands against which you compete. That makes it a useful indicator of underlying consumer interest, and it has been associated with market share and future demand. Treat that relationship as a signal, not proof that search activity caused a sale.

    The calculation is simple. The definition work is where teams usually create misleading results. Build the metric with a written protocol:

    1. Define the category. List the brands a buyer would reasonably consider for the same job. Do not quietly add or remove competitors when the trend becomes inconvenient.
    2. Define each brand query set. Record the main brand name, accepted spellings, common misspellings, and any product names you intend to count. Apply the same inclusion logic to every competitor.
    3. Lock the dimensions. Use the same geography, language, search platform, device scope, and reporting period whenever you compare one period with another.
    4. Preserve the numerator and denominator. Report your own branded volume, total category-brand volume, and the resulting share. The ratio alone hides why it changed.
    5. Version the methodology. When a rebrand, acquisition, new entrant, or product change requires a revised query set, record the effective point. Do not present the revised series as if its definition had always been identical.

    Keeping the numerator and denominator visible prevents four common misreadings:

    • Your branded volume and share can both rise, meaning your brand is gaining searches while outpacing the defined category set.
    • Your branded volume can rise while share falls, meaning category-brand demand grew faster than demand for you.
    • Your branded volume can fall while share rises, meaning category-brand demand contracted faster than demand for you.
    • Your branded volume and share can both fall, which warrants checking whether visibility, consideration, availability, or category conditions changed.

    Do not merge unlike platform counts into a polished but opaque index. Discovery and search behavior can span Google, Amazon, TikTok, YouTube, LinkedIn, and AI interfaces, but each environment exposes different data. Keep platform-specific views separate unless you have a documented normalization method. A directional signal with clear limits is more useful than false precision.

    Share of search is valuable partly because an onsite optimization cannot directly manufacture the underlying act of looking for a brand. It is still not immune to interpretation problems. News coverage, controversy, promotions, product launches, seasonality, and curiosity can increase searches without creating durable preference. Low category volume can also make the ratio jump when the underlying movement is small. Always inspect the raw demand and the business outcome beside the share.

    Interpret divergent signals before changing the budget

    Three executives compare symbolic traffic, awareness, search, and purchase signals around a circular decision table before moving budget blocks.

    A brand search is evidence of active interest, but it is not a receipt showing which exposure created that interest. An AI response may introduce the name. A video may make it memorable. A review may remove doubt. A branded search may simply be the easiest route back. Crediting the final click with the whole outcome confuses demand capture with demand creation.

    Classify touchpoints by the role they can plausibly play:

    • Demand creators introduce an idea, problem, category, or brand before the buyer is actively navigating to you.
    • Validators help the buyer assess credibility and fit through reviews, demonstrations, comparisons, case material, expert discussion, or other evidence.
    • Demand capturers make it easy for someone with existing intent to find your site, contact the business, or complete the next step.

    A channel can play more than one role. The point is not to force every interaction into a permanent bucket. It is to stop treating the easiest interaction to track as the only one that mattered.

    Use divergence between metrics as a diagnostic prompt:

    • Traffic falls while share of search and business outcomes hold. Investigate changes in click behavior, answer surfaces, rankings, tracking, and channel mix before declaring a brand problem. Cutting demand creation solely because site visits fell could remove the activity sustaining later branded demand.
    • Share of search rises while business outcomes remain flat. Check whether the new interest is qualified and whether the offer, availability, landing experience, lead handling, or sales process can convert it. Also compare the observation window with the normal buying cycle before assuming the demand has failed to monetize.
    • Generic traffic rises while branded demand weakens. Your content may be capturing category questions without making the brand memorable. Review whether the brand has a clear point of view, recognizable expertise, useful proof, and a logical next step.
    • Conversions improve while share of search falls. Better capture efficiency may be supporting current results while the future demand pool softens. Do not extrapolate conversion gains without investigating the demand trend.
    • Visibility, branded demand, traffic, and outcomes all decline. Treat this as a broader performance issue. Segment the change by market, product, audience, and channel to find where the deterioration begins.

    These patterns generate hypotheses; they do not establish causes. A line that rose after a campaign is not enough to prove the campaign caused the rise. Add campaign annotations, product changes, public-relations events, distribution changes, pricing events, and measurement changes to the same timeline. Segment by exposed and less-exposed markets or audiences when the data permits. For consequential budget decisions, use controlled tests or another defensible causal design where feasible.

    Self-reported attribution can also fill part of the blind spot. A carefully phrased question about how a buyer first heard of the brand may surface video, word of mouth, communities, events, podcasts, or AI tools that click tracking missed. Keep those responses in their own evidence stream rather than forcing them to reconcile perfectly with analytics. Each method observes a different part of the journey.

    Build an executive dashboard that leads to decisions

    An executive dashboard should not reproduce every channel report. Its job is to show whether the brand is creating demand, capturing it, and turning it into a business result. The reader should be able to see where signals agree, where they diverge, and what needs investigation.

    Organize the view in this order:

    1. Start with the business outcome. Choose the result that matches the business model, such as revenue, qualified pipeline, sales, renewals, or another explicitly defined outcome. Avoid a blended success score that nobody can audit.
    2. Add the demand layer. Show share of search, your branded search volume, and the category-brand denominator together. If different markets behave differently, provide the relevant market view rather than relying only on a global average.
    3. Add visibility and validation signals. Include only the measures that reflect how your buyers actually discover and assess brands. These might cover answer-engine presence, brand mentions, reviews, category visibility, video exposure, or engagement with proof-oriented content. Label coverage gaps clearly.
    4. Add demand-capture efficiency. Retain clicks, sessions, branded and nonbranded arrivals, lead completion, and conversion rate where they help diagnose execution. Clicks belong here as context, not as a substitute for brand demand or commercial results.
    5. Add the context timeline. Mark campaigns, launches, tracking changes, category events, and material changes to the metric definitions. Without this layer, teams tend to invent explanations after seeing the chart.

    Every dashboard metric needs a small measurement contract. Record its business question, exact formula, data source, inclusions, exclusions, reporting scope, update cadence, owner, and known limitations. If two teams can calculate different values while claiming to report the same metric, the dashboard is not ready for a budget discussion.

    Give each executive metric a decision rule as well. A useful rule names the condition, the investigation it triggers, and the decision it may change. For example:

    • If share of search declines while category-brand demand is stable, inspect competitor gains, brand visibility, and market segments before changing capture-channel spend.
    • If share of search grows but qualified outcomes do not, inspect intent quality and conversion constraints before buying more awareness.
    • If traffic declines but branded demand and business results remain healthy, investigate the distribution change without treating session recovery as the automatic objective.
    • If a metric cannot change an executive decision, move it to the operating report where the channel team can still use it diagnostically.

    This structure also changes how SEO and AI-search work is evaluated. Nonbranded visibility can introduce the brand. Useful content can validate expertise. AI visibility may influence later discovery without producing a referral. Branded search can reveal active demand. The website and sales process then capture and convert that demand. Measurement becomes a connected operating model instead of a contest over which platform receives the final credit.

    Key takeaways

    • Clicks and traffic measure observable demand capture; neither one measures the full effect of brand exposure.
    • Use share of search to track branded demand relative to a stable, documented competitive set, and always show the raw numerator and denominator.
    • Keep business outcomes, brand demand, visibility, validation, and capture efficiency in separate layers so one metric cannot conceal weakness in another.
    • Treat divergent signals as hypotheses to investigate. A later branded search does not prove which earlier touchpoint created the preference.
    • Define every executive metric, disclose its coverage limits, and connect it to a decision rule before using it to move budget.

    At your next performance review, place share of search and one agreed business outcome beside the traffic chart. Keep the clicks, but require the three signals to be interpreted together. The first useful change is not a more elaborate attribution model. It is a dashboard that can tell the difference between lost traffic, weak demand, poor demand capture, and an actual decline in the brand.

    References

  • How TV Advertising Changes Search Behavior and Demand

    How TV Advertising Changes Search Behavior and Demand

    A TV campaign can do its job and still look inefficient in your dashboard. The spot creates curiosity, the viewer searches, and search receives the click and often the conversion. If the channels are reported separately, search gets credit for demand it did not create while TV loses credit for the action it caused.

    When a campaign is approaching, your practical problem is not whether TV affects search. It is whether the questions created by the commercial will meet the right result, whether your pages and paid campaigns can capture the resulting demand, and whether measurement can distinguish demand creation from demand capture. Treat those as one operating system.

    TV changes the query, not just the number of searches

    TV advertising does more than send extra people toward keywords that already exist. It can change what people search for, how specific their searches become, and which brand they include in the query.

    Someone who might otherwise search for a category such as car insurance may search for a particular insurer after seeing its commercial. Someone who was not shopping at all may search for the actor, song, claim, product, offer, or scene they remember. A later search may become more commercial: price, reviews, availability, eligibility, alternatives, or where to buy.

    That produces several distinct kinds of demand:

    • Navigational demand: The viewer remembers the company or product and wants the official destination.
    • Campaign-identification demand: The viewer remembers a celebrity, character, song, phrase, or plot but not necessarily the brand.
    • Informational demand: The commercial creates a question about what the product does, how an offer works, or whether a claim applies to the viewer.
    • Commercial-investigation demand: Interest turns into searches for pricing, reviews, comparisons, specifications, availability, or alternatives.
    • Transactional demand: The viewer looks for a store, application, booking page, product page, or other way to act.

    The sequence is not always linear. A viewer can search during the commercial on a second device, later that evening after another exposure, or days afterward when a related need appears. Comscore’s 2024 work connected coordinated TV and digital activity with stronger engagement and second-screen actions. In February 2025, YouTube also said television had overtaken mobile as the primary device for its U.S. viewing, based on Nielsen data. Your TV-to-search plan therefore needs to cover broadcast, connected TV, and streaming rather than treating them as separate consumer journeys.

    The timing can be fast. Google and Nielsen found in 2015 that TV ads could increase branded search queries by up to 20%, often within hours of an airing. DAIVID, a creative-analytics provider, has offered a higher vendor estimate of up to 60%, with the possibility of more in well-coordinated campaigns. Those figures demonstrate the possible scale, but they are upper bounds from different contexts, not universal planning assumptions. Reach, repetition, creative attention, prior brand awareness, category demand, market conditions, and the clarity of the call to action all affect the result.

    Do not place 20% or 60% into a forecast as if TV produces a fixed search multiplier. Build your planning range from your own previous airings, separated by market, creative, product, and schedule. If this is your first flight, treat branded search lift as a measurement question rather than a promised outcome.

    A useful working model is: exposure → attention → memory or curiosity → query → result → action. Search teams control the final handoffs. If the memorable clue from the commercial is absent from your pages, ads, video metadata, and entity information, viewers can be interested and still fail to find you.

    Build the search surface from the creative itself

    A television, phone, and laptop display matching unbranded visual elements connected by glowing lines.

    Keyword tools show existing demand. A new commercial can create language that did not have meaningful volume before the campaign. Start with the finished creative, not with last month’s keyword export.

    Watch the commercial without the creative brief in front of you. Record what an ordinary viewer could actually remember: the spoken brand name, product name, campaign line, spokesperson, character, visual device, offer, claim, date, location, and requested action. Then watch it again without sound. Connected-TV viewers may be distracted, and visual memory can produce a different query from the approved campaign wording.

    Turn those observations into a search-intent inventory:

    1. List exact entities. Include the brand, product, service, campaign, spokesperson, featured organization, and location named or shown in the spot.
    2. Write identification queries. Model the fragments a viewer might remember, such as [brand] commercial actor, ad with [scene], or what company made the ad about [theme].
    3. Write promise and explanation queries. Include the central benefit, claim, offer, qualification, or problem depicted in the commercial.
    4. Write action queries. Cover price, availability, release date, eligibility, locations, applications, bookings, trials, and where to buy when those intents apply.
    5. Add natural variants. Include abbreviations, common misspellings, shortened product names, and spoken versions of stylized brand names.
    6. Map every query family to a destination. Assign an existing page, create a new one, or document why paid coverage is the appropriate route.
    7. Inspect the live results. Search the phrases from the target market and device context. Check whether the correct page appears and whether the title and description make the relationship to the commercial obvious.

    The map should connect each memory or intention to an answer, not merely to your home page.

    Search signalLikely query patternBest destinationFailure to catch before airing
    Brand or product recall[brand], [product name]Official brand or product pageAn outdated page, reseller, or competitor is more prominent
    Memory of the creative[brand] commercial song, ad with [person or scene]Campaign page, video page, or concise commercial FAQThe creative clue appears nowhere in crawlable text or video metadata
    Offer or claim[offer] terms, how does [claim] workOffer page with conditions, dates, and next stepThe landing page repeats the slogan but does not explain it
    Evaluation[product] reviews, [product] vs [alternative]Product details, evidence, comparison, or review resourcesThe viewer must leave the site to understand basic differences
    Availability or locationwhere to buy [product], [service] near meStore locator, local page, product listing, or booking flowInventory, locations, or business information is inconsistent
    Eligibility or applicationwho qualifies for [offer], apply for [service]Eligibility explanation and application pageImportant restrictions appear only after the user starts converting

    The destination should visibly repeat the language and visual identity of the commercial. A viewer who searches after seeing an ad is looking for recognition as much as information. If the page uses a different product name, campaign line, image, or offer, the visitor has to decide whether they found the right company before they can consider the product.

    Put the answer to the commercial’s main unresolved question near the beginning of the page. Include dates, eligibility, price conditions, inventory limits, or geographic restrictions when the campaign depends on them. A memorable slogan is not an explanation. Sending every query to a generic home page wastes the context that made the search valuable.

    Prepare the machine-readable layer with the same discipline. Use Organization, Product, Offer, or VideoObject structured data only when the visible content supports it. Keep names, URLs, images, availability, dates, and offer details consistent across the page and markup. If you publish the commercial, include a useful title, description, transcript or summary, thumbnail, and campaign context. Structured data can clarify entities and relationships for search and answer systems, but it cannot repair an absent answer or an unsupported marketing claim.

    Write a few direct, self-contained answers for people who search conversationally or ask an AI assistant to identify the ad. State what the campaign promotes, which product or service appears, how the offer works, and where someone can act. Do not bury those facts in brand language that only makes sense after a visitor has watched the full commercial.

    Run paid and organic search as one response system

    Organic pages cannot be switched on at the moment an ad airs. They need to be published, crawlable, internally linked, indexed, and tested beforehand. Paid search can respond more quickly, but it still needs the right keywords, creative, budgets, locations, schedules, landing pages, and measurement conventions before volume arrives.

    Before the flight

    • Create one airing log with the creative ID, campaign name, product, market, channel or platform, planned timestamp, and time zone. Search and analytics teams should use the same identifiers.
    • Verify that every mapped landing page is indexable, uses the intended canonical URL, works on mobile, and completes its conversion path without errors.
    • Check page titles, descriptions, headings, visible copy, video metadata, structured data, and internal links against the language viewers will remember.
    • Build paid coverage for brand, product, campaign, offer, and high-value action queries. Review match types and negative keywords so a new campaign phrase is not accidentally blocked.
    • Confirm that budgets and targeting reflect the markets and times receiving media. A national paid-search increase is a poor response to a limited regional TV schedule.
    • Record a baseline for branded, product, campaign-related, and non-brand category queries before the campaign changes demand.
    • Test site capacity, inventory feeds, forms, phone routing, store data, and analytics events. A search spike has little value if the next step fails.

    Share creative changes immediately. A late edit to an offer, product name, spokesperson, or campaign line can invalidate keyword coverage and landing-page copy even when the media schedule stays the same.

    During the flight

    Monitor around actual airings where the volume supports that level of analysis. Look at branded and campaign-cue queries, paid impression share, spend, click-through rate, organic impressions, landing-page traffic, page errors, conversion events, on-site searches, and customer questions. Use the time zone recorded in the airing log; otherwise an apparent lag or lead may be a reporting error.

    Paid copy should repeat the recognizable product, benefit, and offer from the commercial, then add the practical detail the viewer needs. If the spot is emotional and the search ad sounds like unrelated direct-response copy, the handoff feels broken. Consistency does not require copying the script. It requires confirming that the searcher has reached the right answer.

    Do not automatically raise bids on every branded query. Blanket increases can make you pay for visits your organic result would have received anyway. Paid brand coverage is more defensible when competitors are present, the results are ambiguous, the campaign needs a precise destination, or the organic page is not yet strong enough. Where volume allows, compare markets or airing windows with and without paid brand coverage to estimate whether the ads add clicks and conversions rather than merely moving them from organic search.

    Watch the mix, not just total volume. If searches grow for the actor or song but not the brand or product, the entertainment may be more memorable than the advertiser. If viewers search for basic eligibility, pricing, or meaning, the spot has created interest but left a consequential question unresolved. Update paid copy and owned answers while the campaign is still running.

    After an airing or flight

    Do not remove campaign pages the moment paid media stops. Search can lag an exposure, and commercials can continue circulating through streaming, video sharing, press coverage, and memory. Use your own query and visit decay to decide how long active paid support should remain.

    When an offer expires, keep a useful destination if people are still searching. State clearly that the promotion ended, preserve relevant campaign context, and direct visitors to a current product, offer, or support page. Replacing a known campaign URL with a generic error page converts residual demand into confusion.

    Annotate changes to the creative, media weight, search campaigns, pages, offers, pricing, and tracking. Without that change log, a later analyst may attribute a search shift to the wrong channel or assume that two materially different commercials were the same treatment.

    Measure incremental demand without giving search all the credit

    Two miniature neighborhoods show different levels of glowing activity from televisions to phones and destinations.

    Last-click reporting answers which channel completed the recorded journey. It does not answer which channel created or accelerated the need to search. A branded search conversion after a commercial may be captured by PPC or SEO while being caused partly by TV. The reverse mistake is also possible: not every branded search during a TV flight was caused by the campaign.

    Separate three layers in your reporting:

    • Demand response: Incremental brand, product, campaign-cue, and relevant category searches associated with the airing.
    • Search capture: The portion of available demand reached through organic and paid results, followed by clicks and useful landing-page behavior.
    • Business outcome: Incremental leads, purchases, store actions, applications, bookings, or other outcomes after accounting for the demand that would have existed without TV.

    This distinction prevents a common misreading. A successful TV campaign can lower the conversion rate of search traffic because the commercial brings in a broader, earlier-stage audience. More curious visitors may arrive before they are ready to buy. Total incremental conversions can rise even while the percentage of visits that convert falls. Judge the campaign using volume and incrementality alongside conversion rate, not conversion rate in isolation.

    Use a repeatable measurement sequence:

    1. Define the expected baseline. Compare with similar non-airing periods, matched weekdays and dayparts, previous weeks, or comparable markets. Adjust the baseline when seasonality or an established trend makes a simple average misleading.
    2. Align the airing log. Use actual timestamps and markets when available, not merely the campaign’s overall start and end dates.
    3. Group queries by intent. Separate brand, product, campaign identifier, offer, high-intent non-brand, navigational, and unrelated searches. A total branded-search line can conceal what changed.
    4. Inspect multiple response windows. Look for an immediate second-screen response and a later memory response. Do not force one universal attribution window onto every product, creative, or buying cycle.
    5. Control overlapping activity. Promotions, product launches, email, public relations, influencer activity, news, seasonality, competitor campaigns, site changes, and search-platform changes can all move demand at the same time.
    6. Use a comparison design when feasible. Matched geographic markets, staggered schedules, non-airing periods, or carefully chosen holdouts produce a stronger estimate than a simple before-and-after chart.
    7. Reconcile the channels. Report how much demand appeared, how much search captured, and how much converted. Do not add TV-attributed and search-attributed conversions if both labels include the same people.

    A simple diagnostic calculation is: search lift (%) = (observed query volume – expected query volume) / expected query volume x 100. The difficult part is not the arithmetic. It is constructing a credible expected value. A baseline contaminated by a promotion or product launch will produce a precise-looking but unreliable lift figure.

    No single platform supplies the complete denominator. Google Trends shows relative interest rather than absolute query counts. Search Console shows impressions and clicks involving your properties, not every search in the market. Paid-search reporting describes the auctions and traffic your campaigns entered. Web analytics describes visits and recorded outcomes after a user reaches the site. Read those alongside airing data, direct traffic, on-site search, video search behavior, sales, calls, and customer-service questions.

    Search terms also function as creative feedback, but only when you interpret their meaning:

    • A rise in exact brand and product searches indicates that viewers connected the message to the advertiser.
    • A rise dominated by the celebrity, song, or scene can indicate strong entertainment recall but weak brand linkage.
    • Queries such as what company is that ad or repeated misspellings can expose a naming or pronunciation problem.
    • Growth in pricing, availability, location, or application queries signals movement toward action and tells you which destination must be strongest.
    • Growth in eligibility, explanation, or what does it mean queries reveals an information gap. The gap may be intentional curiosity, but the search result still has to resolve it.
    • Complaint, skepticism, or confusion queries should not be counted as favorable response merely because volume increased. Investigate the underlying issue and adjust the answer or campaign where warranted.

    Branded search volume is therefore a useful creative-response indicator, not a standalone verdict. It tells you that the commercial entered behavior. Query composition, result quality, incremental visits, and business outcomes tell you whether that behavior helped.

    Key takeaways

    • TV can create navigational, informational, commercial, and transactional searches; it can also shift an existing generic search toward a named brand.
    • Search response may begin within minutes or hours, so pages, paid campaigns, tracking, and operational systems must be ready before the commercial airs.
    • Build the keyword and content map from what viewers can remember in the creative, including the product, offer, person, phrase, scene, and unresolved question.
    • Give every important query family a recognizable destination instead of sending all TV-driven demand to a generic home page.
    • Coordinate paid-search schedules and budgets with actual markets and airings, while testing whether branded ads add incremental value over organic results.
    • Measure demand creation separately from search capture, then use matched baselines or holdouts to estimate the incremental effect.
    • Read the query mix as feedback: product searches, campaign-identification searches, action searches, and confusion searches tell you different things about the creative.

    Before the next creative lock, bring the media schedule, search team, analytics owner, web team, and campaign decision-maker into the same handoff. Leave with four concrete artifacts: a query inventory, a destination map, a scheduled paid-search plan, and a measurement sheet with baselines and comparison markets or periods.

    If one of those is missing, the campaign is not fully ready. The goal is not to make TV look like search or search look like TV. It is to ensure that the demand your commercial creates reaches a clear answer, and that each channel receives credit for the part of the journey it actually performed.

    References

  • When a Dark B2B Landing Page Can Outperform a Light One

    When a Dark B2B Landing Page Can Outperform a Light One

    You chose a light B2B landing page because it looks clean, credible and safe. Now a darker concept feels more natural for your audience, but changing the visual system without evidence could put paid traffic and lead flow at risk.

    Don’t settle the decision through taste or a generic benchmark. A dark design can outperform when it reflects the buyer’s working world, supports the right brand associations and makes the conversion path unmistakable. It can also lose when it weakens readability or merely follows a design trend. The useful question is not whether dark pages convert better. It is whether a dark page communicates your particular offer better to your particular buyer.

    A dark theme is a hypothesis, not a best practice

    One industrial fleet-repair SaaS experiment sent paid traffic evenly to dark and light landing pages with identical copy. During a three-to-four-week Google Ads search run, the campaigns spent $8,205.97 and produced 767 clicks and 30 conversions. The light variant recorded a 16.62% higher click-through rate, yet it generated 42% fewer conversions. Meta testing also favored the dark direction.

    That is meaningful evidence that audience context can overturn a common design default. It is not evidence that dark backgrounds are universally better for B2B. The result belongs to a specific market, offer, traffic mix and page treatment. A finance buyer working in spreadsheets, a healthcare administrator reviewing compliance software and a commercial shop operator surrounded by equipment do not necessarily interpret the same visual language in the same way.

    The industrial audience provides a plausible explanation for the result. Dark and metallic tones were familiar within the buyers’ operating environment. The visual treatment could communicate durability, seriousness and functional value, while white form fields against the dark background created an obvious destination for attention. Those explanations are useful mechanisms to test, but they are not independently proven causes.

    Consider a dark concept when it has a defensible connection to the buyer’s environment or expectations. Do not choose it because your design team prefers it, because a competitor uses it or because dark interfaces currently look modern. If you cannot complete the sentence, “This treatment should work for this audience because…”, you do not yet have a testable rationale.

    Translate audience context into a design hypothesis

    A professional works in a dim operations room while a laptop displays an abstract dark landing-page interface.

    A buyer persona containing a job title and company size will not tell you whether to use a black background. You need to examine the context in which the buyer works, the visual conventions of the category and the meaning your page must convey at the moment of decision.

    • Inspect the working environment. Look at the equipment, materials, interfaces, documents and spaces your buyer encounters every day. Record recurring colors, textures and levels of visual density.
    • Identify category signals. Decide which visual cues already mean dependable, technical, premium, efficient or familiar to this audience. Separate useful conventions from competitors’ arbitrary styling.
    • Define the decision state. A buyer urgently trying to restore an operation may need a forceful, obvious path to action. A committee comparing a complex platform may need more reading comfort and visible evidence.
    • Name the conversion target. Decide whether the design must direct attention to a form, demo request, pricing path or another action. Contrast should support that target rather than decorate the page evenly.
    • Document the risk. Write down what the treatment might accidentally communicate, such as low readability, consumer entertainment, excessive luxury or a lack of transparency.

    Turn those observations into one sentence before anyone opens a design tool: “For this audience in this context, this visual system will make the offer feel more familiar and the action easier to locate, increasing completed lead forms.” That statement gives you an audience, a proposed mechanism and a measurable outcome.

    For commercial shop operators, the hypothesis might connect an industrial palette with familiarity and seriousness, then connect high-contrast fields with easier form discovery. For another audience, the same palette could create distance or make a text-heavy evaluation harder. Design psychology should generate the hypothesis; observed behavior should decide whether you keep it.

    Dark is not the same as accessible

    White text on a dark background does not make a page accessible by itself. Check body copy, headings, links, field labels, entered text, borders, keyboard focus, validation errors and disabled states. A form can appear high-contrast at a glance while still hiding field boundaries or error messages from someone trying to complete it.

    Run the same checks on the light version. Accessibility is not a reason to assume one theme will win; it is a requirement both variants must satisfy before their conversion results are worth comparing. If one treatment is difficult to read or operate, you are testing usability failure against a functional page, not audience preference.

    Decide whether you are testing a theme or a design system

    The most important methodological distinction is easy to miss. A broad concept test tells you which complete experience performs better. An isolation test tells you whether one component caused a difference. Both are legitimate, but they answer different questions.

    In the industrial SaaS experiment, the copy stayed constant, but several visual elements changed together. The dark version used a black background, white text, prominent white form fields, a subtly outlined black call-to-action button and no header logo. The light version used white and gray surfaces, dark text, a blue button and a prominent header logo. The experiment therefore showed that one complete design treatment beat the other. It did not establish that the background color alone produced the conversion difference.

    Use a concept test to choose a direction

    A concept test is appropriate when you need to choose between substantially different visual systems. Make the alternatives different enough to express distinct hypotheses, but preserve the underlying commercial proposition.

    1. Keep the offer, copy, form fields, call-to-action wording and post-submit experience unchanged.
    2. Define each visual system in advance, including its background, typography, field treatment, button styling, imagery and brand presence.
    3. Send the same audience and advertising promise into a stable random assignment. An even split is useful when traffic permits it.
    4. Record the assigned variant, landing-page visit, form completion and any downstream lead-quality outcome.
    5. Name the primary success metric before launch. Do not promote whichever metric looks favorable after results arrive.
    6. Plan the required sample using your normal test method and expected conversion rate. Do not borrow the three-to-four-week duration from another campaign as a universal stopping rule.
    7. Review the overall result first. Treat source, device or audience-segment differences as follow-up hypotheses unless the original test was designed to evaluate them.

    This approach answers a practical production question: which page should receive traffic? It does not tell you which ingredient inside the winner mattered most.

    Use isolation tests to find the cause

    Once a concept wins, clone it and test its components deliberately. You might compare logo presence, form-field contrast or button treatment in separate experiments. If your claim is specifically about dark versus light, keep the logo, layout, field count, copy, button wording and promotional promise the same. Treat the foreground and background palette as the variable, while ensuring both versions remain readable and operable.

    This two-stage sequence prevents an attractive but unsupported conclusion. A dark concept may win because of its field contrast, its reduced header distraction, its overall tone or an interaction among those elements. Selecting the winning bundle is still valuable. Naming the cause requires another test.

    Do not let click-through rate choose the landing page

    Two abstract landing-page paths lead from clicks through forms and qualified prospects to a business handshake, with different numbers reaching the final outcome.

    Click-through rate measures behavior before the visitor experiences the landing page. Unless the page design is visible in the ad creative, a user cannot react to its theme before clicking. A variant-level CTR difference should therefore trigger a review of traffic assignment, campaign delivery and tracking. It should not automatically be credited to the landing-page palette.

    The industrial SaaS result makes the practical danger clear: the light treatment’s CTR was 16.62% higher while its conversion count was 42% lower. Choosing the page on CTR alone would have favored the upstream metric and ignored the action the landing page existed to produce.

    MetricWhat it answersHow to use it
    Ad click-through rateDid the ad and its targeting earn a click?Use it to diagnose traffic acquisition, not to declare a landing-page theme the winner.
    Landing-page conversion rateWhat proportion of landing-page visitors completed the intended action?Use it as the primary page metric when a form completion is the immediate objective.
    Qualified lead rateWhat proportion of visitors became leads your business considers usable?Use it to catch variants that generate more forms but poorer-fit prospects.
    Cost per qualified leadHow much media spend produced each usable lead?Use it when deciding which experience should receive budget.

    Also distinguish conversion volume from conversion rate. If variants receive different numbers of visitors, raw form totals cannot make a fair comparison on their own. Use the actual visitor count assigned to each experience. And do not describe one page’s leads as better qualified merely because it generated fewer clicks and more forms; lead quality requires downstream evidence such as acceptance, sales progression or another definition your team applies consistently.

    Key takeaways

    • Do not adopt dark mode as a general conversion rule. Use it when you can connect the treatment to a specific audience context and buying task.
    • Write the proposed mechanism before designing: identify what the theme should communicate, where it should direct attention and which outcome should change.
    • Choose between a broad concept test and an isolated variable test. A bundle can select a production winner, but it cannot prove which component caused the result.
    • Keep the offer, copy, form requirements and traffic assignment controlled. Make both variants accessible enough that usability failure does not decide the experiment.
    • Treat ad CTR as an acquisition diagnostic. Judge the landing page by visitor conversion and, where available, qualified lead or business outcomes.
    • Use a winning concept as the start of component testing, not as permission to declare that all B2B audiences prefer the same theme.

    Your next move is simple: create two annotated mockups and label the audience signal each important choice is meant to send. Decide whether you need a concept winner or an explanation of one component, then write down the primary metric before traffic begins. If dark wins, isolate the elements that may have produced the lift. If light wins, revise the audience hypothesis rather than forcing the aesthetic. Either outcome replaces an assumption with something you can use on the next campaign.

    References

  • How to Track Brand Visibility Across AI Search Platforms

    How to Track Brand Visibility Across AI Search Platforms

    You ask an AI assistant for the best options in your category. Your brand appears. You change a few words, try another platform, or add a location, and it disappears. That is a useful spot check, but it is not visibility tracking.

    A defensible tracking program uses a fixed set of prompts, consistent labels, and saved answer evidence. It tells you where your brand is mentioned, whether it is recommended, which sources support the answer, which competitors occupy the same space, and whether the description is accurate. More importantly, it tells you what to fix next.

    Stop treating AI visibility like a single keyword rank

    A traditional rank tracker asks where a URL appears for a keyword. AI search often returns a synthesized answer instead of a stable list of links, and those answers may mention, recommend, or cite only a small selection of brands and sources. A position-based metric cannot describe all of those outcomes.

    Use a prompt-level definition instead: AI search visibility is your brand’s observable presence and representation across a controlled set of prompts, platforms, markets, and collection runs. The basic unit is not a keyword position. It is a platform-prompt-market observation with a saved response behind it.

    Each observation should distinguish several states:

    • Mention: The answer names your brand, product, service, or another recognized brand entity.
    • Recommendation: The answer explicitly presents the brand as a suitable choice, shortlist candidate, or conditional fit.
    • Citation: The answer links to or identifies a source associated with the brand. Record this only when the interface exposes citations.
    • Representation: The answer describes the brand favorably, neutrally, unfavorably, or with a meaningful qualification.
    • Accuracy: The claims about the brand are correct, incorrect, ambiguous, or too incomplete to evaluate.

    These states are not interchangeable. A mention can be negative. A citation can support a category fact without recommending the company that published it. A recommendation can rely on a third-party source rather than the brand’s own site. If your dashboard collapses all of them into a single visibility score, you will not know whether you have a discovery problem, an evidence problem, a positioning problem, or a reputation problem.

    That is also why a successful ChatGPT result cannot stand in for the entire market. Visibility can differ across ChatGPT, Claude, Gemini, and Perplexity. Report each surface separately before producing any aggregate view.

    Build a prompt set around real customer decisions

    Your prompt set determines what your visibility score means. If every prompt includes your brand name, the tracker measures how the systems describe a known entity. It does not measure whether the brand gets discovered when a buyer has not named it.

    Build separate prompt groups for the decisions you need to observe:

    • Category discovery: Which [category] options fit [audience or use case]?
    • Problem-led discovery: What is a good way to solve [specific problem] under [constraint]?
    • Comparison: How do [brand or product] and its alternatives differ for [use case]?
    • Requirement matching: Which options support [required capability, integration, market, or workflow]?
    • Branded validation: Is [brand] appropriate for [audience], and what are its limitations?
    • Factual verification: Does [brand] provide [specific feature, service, policy, or availability]?
    • Post-purchase help: How do users complete [task] with [brand or product]?

    Unbranded prompts measure discovery and category association. Branded prompts measure understanding, accuracy, and reputation. Keep their results separate. Otherwise, strong performance on easy branded questions can conceal absence from the category questions that introduce new buyers to a company.

    Use neutral wording. A prompt such as Why is [brand] the best choice? presupposes the result and cannot tell you whether the brand would appear naturally. Ask which options fit a defined need, then let the answer reveal the competitive set.

    Store enough metadata to reproduce each observation:

    • A stable prompt ID and the exact prompt text.
    • The intent group and business question behind the prompt.
    • Whether the brand was named in the prompt.
    • The platform and any model or search-surface label displayed to the user.
    • The market, location, and language used for the run when they matter.
    • The audience, product line, or use case being tested.
    • The prompt version and the date that version became active.

    Location deserves its own field rather than a note buried in the prompt. Tracking by location can expose market-specific gaps that disappear inside a global average. This is especially relevant when availability, terminology, regulations, service areas, or competitors differ between markets.

    Freeze the wording once a prompt enters the benchmark set. If you discover a better version, create a new version and establish a new baseline. Quietly rewriting prompts between runs makes a reporting change look like a visibility change.

    Record answer evidence, not just a visibility score

    Abstract AI response cards are organized with colored evidence markers, source tiles, and saved snapshots on a dark tabletop.

    Define every metric before collecting results. In particular, define an eligible answer as a completed response to an in-scope prompt. Log platform errors, refusals, and unavailable responses separately. Treating a failed run as a brand omission would contaminate the denominator.

    MetricOperational calculationWhat it helps you diagnoseMain caution
    Mention rateEligible answers naming the brand divided by all eligible answers in the segmentBasic discovery and entity recognitionA mention is not necessarily positive or prominent
    Recommendation rateEligible answers explicitly recommending or shortlisting the brand divided by all eligible answers in the segmentWhether the brand is presented as a viable choiceSeparate unconditional recommendations from recommendations limited by a caveat
    Citation rateEligible answers citing a brand-associated source divided by answers for which citations are exposedWhether the brand’s evidence is being selected as supportNot all interfaces expose citations; mark those cases unavailable rather than uncited
    AI share of voiceBrand mentions divided by mentions of the defined competitor set within the same prompt segmentRelative presence in competitive answersThe result depends on the prompt mix and competitor definition
    RepresentationDistribution of favorable, neutral, unfavorable, and qualified descriptionsPositioning, reputation, and recurring objectionsSave the exact claim and reason for the label; sentiment alone is too blunt
    Factual accuracyDistribution of accurate, inaccurate, ambiguous, and unevaluable brand claimsEntity consistency and misinformation riskReviewers need an approved factual reference for comparison
    Platform coveragePlatforms with an observed mention divided by platforms tested for the same prompt segmentCross-platform resilienceDo not let an aggregate hide a weak individual platform

    Citation frequency, brand visibility, AI share of voice, sentiment, and cross-platform coverage belong in the same scorecard because each answers a different question. If your tool supplies a composite visibility score, document its formula and retain the component metrics. A rising aggregate can otherwise conceal worsening accuracy or a loss of recommendations on commercially important prompts.

    Save the evidence needed to audit a result

    A row with only a yes-or-no mention field is not enough. Save the exact response, collection time, prompt version, platform label, market, citation URLs, cited domains, competitor mentions, recommendation wording, representation label, factual issues, and reviewer notes. Where the platform permits it, retain a response link or screenshot as well.

    Classify cited domains as owned, independent third-party, competitor-owned, or another relevant type. That distinction matters. An answer citing your documentation points to a different opportunity than an answer recommending your brand while relying entirely on an external review or directory.

    Human review remains important for conditional language. Suitable for small teams that do not need [capability] is not equivalent to a general endorsement. A tracker that counts both as positive recommendations may produce a clean chart and a misleading decision.

    Use a collection cadence you can reproduce

    Begin with a baseline run across the full prompt-platform-market matrix. Repeat the same matrix at a regular interval, and capture additional before-and-after runs around material content, product, or entity changes. Keep prompt versions and segments consistent during the comparison.

    Do not interpret one generated answer as a trend. Look for a pattern that repeats across related prompts, collection runs, platforms, or markets. A manual spreadsheet can establish this discipline while the prompt set is small. When the workload grows, evaluate GEO tracking tools on prompt control, raw-response retention, citation capture, platform and location segmentation, competitor grouping, historical comparisons, exports, and transparent metric definitions.

    Turn recurring patterns into specific GEO work

    A strategist turns repeated patterns from abstract AI answer chambers into website, source, location, and fact-checking work.

    Start with the pattern in the evidence, not with a general instruction to publish more. Different gaps call for different work.

    Your brand is absent from unbranded discovery prompts

    First, check whether the absence repeats across related prompts and whether competitors appear consistently. Then inspect the claims and sources used in those answers. You are looking for a missing association: a category, use case, audience, capability, problem, or market that competitors explain more clearly.

    Create or strengthen a focused page that answers the missing intent directly. State who the offering is for, which problem it solves, what it supports, where it applies, and what its meaningful limits are. Link that page to the relevant product and organization entities. Use appropriate structured data to reinforce names and relationships already visible in the content, but do not treat markup as a substitute for a clear answer.

    This is the practical meaning of expanding your semantic footprint, fact density, and entity authority: cover the relationships buyers ask about, make important claims explicit and supportable, and keep the identity of the organization and its offerings consistent.

    Your brand is mentioned but rarely cited or recommended

    A mention without a citation can indicate that the entity is recognized while its owned evidence is not being selected. Review which domains the answers do cite. If they consistently provide concise definitions, comparison criteria, specifications, or market facts that your pages obscure, improve the relevant evidence on your site and remove contradictions between pages.

    A citation without a recommendation is a different gap. Your content may be useful as evidence while the offering’s fit remains unclear. Strengthen the pages that explain the intended audience, requirements, tradeoffs, integrations, constraints, and differentiators. Do not manufacture praise. Give the system enough accurate context to determine when the brand is and is not a sensible option.

    The answer gets your brand wrong

    Record the exact incorrect claim rather than assigning only a negative sentiment label. Then identify whether your own site contains conflicting names, outdated facts, unclear availability, or ambiguous product relationships. Establish a canonical location for each important fact, correct internal contradictions, and align visible copy with structured entity information.

    If the claim comes from external coverage, the work may involve reputation management, clearer public documentation, or credible third-party corroboration. Do not try to suppress a valid limitation. Explain the current position accurately and address the underlying issue where possible.

    One platform or market underperforms

    Do not rewrite the entire site because one surface produced a weak answer. Confirm that the same prompt, language, location, and evaluation rules were used. Compare the source types and competitor claims selected by the stronger and weaker platforms. A platform-specific gap may point to missing evidence in the sources that surface retrieves, while a market-specific gap may point to unclear local availability, terminology, or entity information.

    Prioritize changes using business impact, repeatability, evidence, and control. A recurring absence on important unbranded prompts is more actionable than an isolated wording difference. A verified factual error on a decision-stage prompt deserves attention before a minor shift in a blended score. A gap tied to a page you control can usually be addressed more directly than a change in an opaque platform behavior.

    After making a change, measure both layers. The first layer is the AI response: mentions, citations, recommendations, representation, and accuracy. The second is the business outcome available in your analytics, such as relevant referral activity, branded interest, or qualified conversions. An AI mention is evidence of visibility, not proof of revenue.

    Key takeaways

    • Track platform-prompt-market observations, not a supposed universal AI rank.
    • Separate unbranded discovery prompts from branded reputation and accuracy prompts.
    • Measure mentions, recommendations, citations, share of voice, representation, accuracy, and platform coverage independently.
    • Preserve exact prompts and raw responses so every chart can be audited.
    • Diagnose repeated patterns before choosing a content, entity, technical, or reputation fix.
    • Keep AI visibility metrics connected to business outcomes without treating a mention as a conversion.

    Your next move is simple: open a tracking sheet, choose a small but balanced set of branded and unbranded prompts, run the same set across the platforms and markets that matter, and label each answer with the definitions above. Select the clearest recurring gap, make the narrowest relevant improvement, and preserve the prompt set for the next run. Once you can explain why a metric moved and what evidence changed, you are tracking visibility rather than collecting screenshots.

    References

  • How to Measure SEO and Choose Tools That Earn Their Budget

    How to Measure SEO and Choose Tools That Earn Their Budget

    Your SEO stack can produce a dashboard full of green arrows and still leave you unable to defend the next renewal. If you are deciding whether to keep a platform, add AI-search monitoring, or build an internal agent, the first question is not which option has the longest feature list. It is what decision the investment must improve.

    Build the measurement system before the shortlist. You will expose missing data, avoid paying twice for the same capability, and give every candidate a real job to perform.

    Key takeaways

    • Define the business outcome, search signal, diagnostic evidence, decision, and owner before evaluating any tool.
    • Use the 24-hour view for investigation, weekly reporting for operating decisions, and monthly reporting for direction and resource allocation.
    • Buy a capability only when it closes a documented measurement or workflow gap. An AI label is not a use case.
    • Run trials with representative weekly work, the same inputs, and pass-or-fail criteria that matter after the demo.
    • Separate observed trial evidence from forecast business impact. A short trial can validate a workflow, but it cannot prove future revenue.

    Build a measurement brief before opening a vendor tab

    Five connected groups of objects represent a business target, search signals, evidence, a decision gate, and an action on a strategy table.

    SEO tool evaluations often begin with feature inventories because features are easy to count. That produces a weak business case: leadership generally needs a connection to business results, while many platforms stop at keyword volume, optimization speed, or activity.

    Replace the feature wish list with a short measurement brief. Complete these fields before you request a demo:

    • Business question: State the decision in plain language. Examples include which landing-page group deserves investment, whether a technical release repaired organic acquisition, or which market needs local content.
    • Outcome: Name the result the business already recognizes, such as qualified leads, completed orders, subscriptions, booked consultations, or another defined conversion.
    • Search-performance signal: Identify what you expect to move before the outcome does. Depending on the job, that could include impressions, clicks, landing-page traffic, organic conversions, or search visibility for a defined query set.
    • Diagnostic evidence: List the information needed to explain the movement, such as indexation status, page-template defects, query mix, SERP composition, country, language, or device.
    • Decision rule: Describe what you will do when the evidence changes. A metric without a resulting action is reporting inventory, not a requirement.
    • Owner and cadence: Name who reviews the result, who receives the work, and whether the decision belongs in incident response, a weekly queue, or monthly planning.
    • Boundary: Record what the measurement will not prove. This prevents a ranking change, an alert, or an AI-generated recommendation from being presented as revenue attribution.

    Keep outcomes, performance indicators, and diagnostics separate

    A useful SEO measurement model has distinct layers:

    • Outcome measures describe business results: revenue, qualified demand, completed transactions, subscriptions, or another accepted conversion.
    • Performance indicators describe how organic search contributed: query impressions, clicks, landing-page visits, conversions attributed to organic sessions, and visibility within a defined search set.
    • Diagnostic measures help explain why performance changed: crawling and indexation states, template issues, internal-linking gaps, SERP changes, or differences between markets and devices.

    Do not collapse these layers into a proprietary health score and assume the result has business meaning. A technical score can improve without demand changing. Visibility can rise on queries that never produce a useful visit. Organic conversions can move because of a pricing change, promotion, tracking repair, or landing-page redesign rather than the SEO work being evaluated.

    Write the evidence chain explicitly: the work performed, the observable search change, the on-site action, and the business outcome. Annotate releases and tracking changes. Compare the affected page or query group with a relevant unaffected group when one exists. If the chain is incomplete, call the result an association or an operational improvement rather than attribution.

    Measure at the level where the intervention happened. A template fix should be evaluated on the affected template group. A localized content program should be separated by country and language. A rewrite aimed at one query theme should not be judged only through a sitewide total. Aggregation can make a successful change disappear, or make an unrelated gain look like success.

    Match the reporting interval to the decision

    Google Search Console performance reporting now includes weekly and monthly views in addition to the familiar 24-hour perspective. The practical benefit is not another way to format a chart. It is the ability to choose a reporting grain that fits the question.

    Reporting viewQuestion it should answerWhat not to use it for
    24-hourDid an abrupt change coincide with a release, tracking failure, indexing problem, or other incident?Declaring a durable trend from a short movement.
    WeeklyIs the movement persistent enough to enter the operating queue, and did recent work affect the intended pages or queries?Proving long-term business return from a single reporting period.
    MonthlyIs the program moving in the intended direction, and should priorities or resources change?Finding the exact cause of a sudden failure.

    Use the shortest interval that can answer the decision without letting routine variation dominate it. Then preserve the finer view for diagnosis. A monthly decline can justify investigation; the weekly and 24-hour views help locate when it began and which segment moved.

    Reporting grain does not fix a poor comparison. Compare complete periods with complete periods. Keep seasonal demand and major campaigns in view. Do not compare a global total after launching a new locale without separating the new market from established ones.

    Segment before you explain. Useful cuts include query theme, landing-page group, template, device, country, language, and a documented branded-versus-non-branded rule. A flat sitewide result can conceal growth in one segment and decline in another.

    Maintain a change log next to the performance data. Include site releases, migrations, tracking changes, canonical-rule updates, internal-linking work, and major campaigns. When performance moves, check those known events before assigning the change to an algorithm, competitor, or tool recommendation.

    Turn capability gaps into must-pass jobs

    A shortlist should reflect the gaps in your measurement brief. Useful evaluation areas include advanced data analysis, SERP intelligence, meaningful automation, multilingual support, and transparent pricing. Those labels are still too broad to purchase. Convert each one into a task and a required form of evidence.

    CapabilityTrial jobEvidence required
    Advanced analysisConnect search performance, landing-page behavior, and the defined business outcome for the affected page group.Repeatable definitions, visible transformations, segment-level results, and an export that another analyst can inspect.
    SERP intelligenceExplain a visibility change for a defined query set and market.The underlying queries, capture context, date, location, device, competing results, and relevant search features rather than an unexplained score.
    AutomationComplete a recurring weekly task from detection to prioritized handoff.Rules, exceptions, deduplication, evidence attached to each recommendation, an owner, and a record of what happened after the alert.
    Multilingual supportAnalyze a real country-and-language workflow without merging markets that require different decisions.Locale-specific query and page context, correct filters, preserved terminology, and reporting that can be reviewed by the market owner.
    Pricing clarityPrice the expected operating state rather than the demo environment.A written breakdown of seats, tracked entities, usage limits, exports, integrations, AI consumption, implementation, support, and overage conditions.

    If AI-search visibility is the stated gap, define the observation before accepting a visibility score. Ask which model or search surface was checked, in which locale, against which prompt or query set, at what time, with what captured answer, and under what entity-matching rule. Treat the tracked set as a measurement panel with documented boundaries. An opaque score can summarize evidence, but it should not replace the evidence.

    The replacement standard should be especially high for established crawling and technical-audit workflows. Core technical SEO tooling is comparatively stable. If your current system reliably finds relevant issues, preserves history, and routes work to the right owner, adding an AI label is not enough reason to replace it.

    Decide whether to buy an AI tool or build an agent

    The choice between a ready-made platform and a custom AI agent belongs after the workflow is defined.

    • Buy a platform when the task is standardized and the main value comes from vendor-maintained datasets, integrations, interfaces, support, and ongoing product upkeep.
    • Build an agent when the useful context lives in internal data, business rules, approval paths, or proprietary workflows that a general platform cannot represent. Include evaluation, monitoring, security review, maintenance, and internal ownership in the cost.
    • Keep the existing stack when the real bottleneck is an undefined decision, weak implementation discipline, missing conversion data, or unclear ownership. A new interface will not repair those conditions.

    For a small team, automation must remove work rather than produce more material to review. Outputs without market and business context tend to create noise. Require the system to suppress duplicates, show supporting evidence, explain uncertainty, and hand the next action to a named owner.

    Run a trial that can survive the sales demo

    Three evaluators observe two identical workstations completing the same controlled trial with blank result cards and evidence boxes.

    Do not evaluate a tool through a polished example that the vendor selected. Start with understandable pricing, secure a trial, and test the work your team actually performs in a normal week.

    1. Lock the use case and finish line. Describe the input, expected output, decision, owner, and acceptable evidence before anyone sees the product.
    2. Capture the current baseline. Record active work time, waiting time, systems touched, manual handoffs, recurring errors, and the decision produced by the current workflow.
    3. Use representative inputs. Include ordinary data and a known difficult case. A candidate that works only on a tidy sample has not passed the operational test.
    4. Separate setup from recurring operation. Record configuration, integration, tagging, permissions, and training effort independently from the work expected after adoption.
    5. Run the same task across candidates. Keep the data, operator instructions, and required output consistent so the comparison reflects the tools rather than different demonstrations.
    6. Trace every important output. Follow recommendations back to queries, pages, captured results, or other underlying evidence. Label generated explanations separately from observed data.
    7. Count decisions changed, not alerts created. Record whether the output changed a priority, prevented an error, removed a manual step, or supplied evidence the current stack could not provide.
    8. Test the handoff. Export the result, route it to the intended owner, apply permissions, and verify that history remains understandable outside the person who configured the trial.
    9. Price the operating state. Obtain the expected cost at normal usage, including implementation, integrations, support, consumption limits, internal administration, quality assurance, and any tools the purchase would actually retire.

    Apply pass-or-fail gates before scoring convenience features:

    • Data fitness: It covers the required sites, markets, languages, queries, pages, and business data at a usable level of detail.
    • Evidence quality: Important outputs are reproducible, traceable, and explicit about assumptions or uncertainty.
    • Workflow value: It removes a documented step, improves a defined decision, or enables a necessary analysis that is currently impractical.
    • Operational fit: The intended users can configure, review, export, and act on the output without relying indefinitely on a vendor specialist.
    • Governance: Access controls, retention, deletion, input reuse, and approval requirements fit your organization’s rules.
    • Commercial clarity: The written price covers the expected usage, dependencies, overages, implementation, renewal conditions, and exit path.

    Do not upload confidential query, customer, conversion, or client data until the appropriate security, privacy, and legal owners have approved the environment. Use a sanitized export or synthetic test set while that review is incomplete. The convenience of a trial is not worth creating an uncontrolled copy of sensitive data.

    Ask vendor questions that expose operating cost

    Send the use case before the call, then ask questions that require specific answers:

    • Which assumptions about seats, sites, markets, tracked queries, prompts, exports, API use, and AI consumption are included in this quote?
    • Which capabilities shown in the demonstration require another package, service, integration, or implementation fee?
    • What work is required from our team during setup and during normal operation?
    • Which claims describe production functionality, and which depend on a roadmap?
    • Can we export raw observations, definitions, configurations, and history in a usable format?
    • How are AI inputs retained, reused, isolated, and deleted, and where can those terms be verified?
    • What happens to access, stored data, reports, and integrations if usage changes or the contract ends?

    Build a budget case without pretending the trial proved revenue

    A short trial can establish data coverage, repeatability, workflow fit, evidence quality, and whether the output changes a decision. It usually cannot establish that the tool caused a durable ranking, conversion, or revenue increase. The business case should keep observed evidence, forecasts, assumptions, and unknowns in separate fields.

    Calculate full cost as the subscription, expected usage and overages, implementation, integrations, training, quality assurance, administration, and any internal build or maintenance effort, minus only the cost of tools that will genuinely be retired.

    Treat saved labor carefully. It becomes direct financial savings only when it avoids actual spending. Otherwise, describe it as capacity and name where that capacity will be redeployed. Treat incremental business impact as a forecast with an explicit mechanism: better evidence leads to a different decision, that decision changes the work, and the work may affect the defined outcome.

    Present a range of choices: keep the current stack, make a narrow change that closes the priority gap, or fund a broader platform or internal build. Include dependencies, risks, and exit criteria for each. That is more credible than forcing every benefit into an optimistic return figure, especially while direct connections between search activity and tangible business outcomes remain uncommon in tool offerings.

    Set checkpoints before signing. Confirm usability and evidence quality at the end of the trial, review operational value after a complete reporting period, and revisit adoption, overlap, business impact, and full cost before renewal. If the tool does not improve the decision named in the original brief, downgrade it, replace it, or stop paying for it.

    Your next move should be a blank measurement brief, not another demo booking. Choose a real decision from the next closed weekly or monthly period and ask each candidate to produce evidence your current stack cannot. A tool that cannot change that decision has not earned a place in the budget.

    References