Month: September 2026

  • Low-CAC Marketing Channels: How to Choose the Right Mix

    Low-CAC Marketing Channels: How to Choose the Right Mix

    If you’re choosing a marketing channel because it has the lowest published customer acquisition cost, you’re one step away from an expensive mistake. A cheap customer who arrives after your runway runs out, requires an unaffordable test budget, or disappears when an auction gets crowded isn’t cheap for your business.

    You need more than a ranked list. You need to know which channels fit your economics, how long each one needs to produce a useful signal, and whether the apparent efficiency will survive additional spend. Here is a practical way to make that decision.

    A low CAC is useful only when it fits your constraints

    Among 214 companies analyzed in 2026 – 137 B2B and 77 B2C – the four lowest B2B acquisition costs came from paid, organic, and offline channels. Channel family alone was a weak predictor of efficiency. Email, public speaking, generative engine optimization, and an early advertising platform all appeared near the top for different reasons and carried different constraints.

    That is why a benchmark should open your shortlist, not settle it. Before you compare channels, calculate the most you can afford to pay for a customer. Use contribution margin rather than top-line revenue, and choose a payback period your cash position can actually support. A business with high lifetime value but a long recovery period can still run out of cash while reporting an attractive LTV-to-CAC ratio.

    Screen each candidate through four gates:

    • Economic ceiling: What is your allowable CAC after fulfillment, sales, onboarding, refunds, and other variable costs? A channel fails if its marginal CAC exceeds that ceiling, even when its average looks acceptable.
    • Time to evidence: How long can you fund the work before the first attributable customer is likely to appear? Do not evaluate a six-month channel with a six-week deadline.
    • Viable commitment: Can you spend enough to buy or generate a measurable test? A low unit cost does not help if the minimum workable commitment is beyond your budget.
    • Repeatability: Can the channel absorb more activity without exhausting the audience, the available speaking slots, or an unusually favorable early auction?

    Put these four columns beside every channel in your planning sheet. Reject any option that misses a hard constraint before debating creative concepts, vendors, or campaign tactics.

    Be equally careful with published LTV-to-CAC ratios. The 2026 B2B ratios were calculated using the same $32,414 lifetime value across channels, while the B2C calculations used $10,089. Those figures make channels comparable inside the benchmark, but they are not substitutes for your retention, margin, and customer-value data.

    Use the 2026 benchmarks to build a realistic shortlist

    The most useful comparison pairs CAC with the condition governing the channel. The figures below are directional averages, not quotes or forecasts. For offline channels, the spending figures are the lowest monthly commitments at which measurable acquisition was observed, not universal vendor minimums. N/A means there was not enough volume in that segment to report a benchmark.

    ChannelB2B CACB2C CACConstraint that affects the decision
    ChatGPT Ads$468$131Only seven weeks and 14 accounts; weekly B2B CAC rose from $312 to $549
    Email marketing$510$2871.4 months to the first attributable acquisition
    Public speaking$518$472$2,500 observed minimum viable monthly spend
    GEO$584$2615.8 months to the first attributable acquisition
    Webinars$603$2512.1 months to the first attributable acquisition
    Thought leadership SEO$647$2986.4 months to the first attributable acquisition
    Organic social media$658$2123.2 months to the first attributable acquisition
    Informal networking$711$472$1,200 observed minimum viable monthly spend
    PPC/SEM$802$290B2B CAC was 14.1% higher than in 2024
    Direct mail$864$347$18,000 observed minimum viable monthly spend
    LinkedIn Ads$982N/AB2B CAC was 31.2% higher than in 2024
    Basic SEO$1,786$1,2018.6 months to the first attributable acquisition
    Account-based marketing$4,664N/AHighest B2B CAC in the benchmark

    This table changes several common channel decisions.

    • Email is efficient when you already have legitimate access to an audience. If another campaign had to acquire those subscribers, include its appropriate share of list-growth cost. Otherwise email receives credit for closing customers while the channel that created the audience absorbs the expense.
    • Organic does not automatically mean inexpensive. For B2B, the gap between thought leadership SEO and basic SEO was $1,139 in CAC and 2.2 months to first acquisition. That does not guarantee an identical saving for you, but it is a strong reason to compete through expertise and positioning instead of publishing interchangeable pages for keyword volume.
    • GEO and thought leadership SEO are close enough to plan together. Their B2B benchmarks differed by $63 in CAC and 0.6 months to first acquisition. Question research, clear answers, expert evidence, consistent entity information, and genuinely distinctive content can support both search discovery and generative-engine visibility. Structured data should reinforce what a visitor can see, not make claims the page does not support.
    • Offline CAC can hide a large cash commitment. Direct mail carried an $864 B2B CAC, but measurable acquisition appeared only from a monthly commitment of $18,000. Public speaking combined a lower $518 CAC with a $2,500 observed threshold, although access to relevant events and the number of credible appearances limit its scale.
    • Paid-channel inflation belongs in your forecast. Every established paid channel in the benchmark became more expensive from 2024 to 2026. Use your current marginal CAC for budgeting, not the blended average from the campaign’s cheapest months.

    Build the mix around time horizons, not channel labels
    A strategist waters quick-growing sprouts, flowering plants, and a deeply rooted young fruit tree in three greenhouse beds.

    A sensible channel mix gives each component a distinct job. If every channel is expected to create awareness, capture demand, nurture prospects, and close sales, attribution becomes political and weak results are easy to excuse.

    Use paid channels for fast feedback and demand capture

    PPC/SEM and ChatGPT Ads can help you test offers and capture active demand without waiting for an organic audience to compound. They are most useful when the landing experience, sales follow-up, and conversion event are already measurable. If those pieces are broken, faster traffic only lets you lose money faster.

    ChatGPT Ads requires special treatment. OpenAI opened the self-serve platform on July 22, 2026, and the available benchmark covers just seven weeks across 14 advertiser accounts. Weekly B2B CAC climbed 76%, from $312 in week one to $549 in week seven, while the weekly spend index rose from 100 to 611. The spend-weighted average was $468, and week seven remained 32% below the $802 PPC/SEM benchmark.

    That low average is an invitation to test, not a safe annual-planning assumption. Before launching, write down your allowable CAC, maximum test spend, minimum customer count needed for a useful decision, and the date when a complete sales cohort can be evaluated. Review weekly and cohort CAC rather than relying on the cumulative average. An early cheap week should not conceal deteriorating marginal performance.

    Use email and webinars to convert an audience you can reach

    Email and webinars are attractive when you have subscribers, partners, customers, event registrants, or a reliable way to recruit the right people. Their observed organic ramps – 1.4 months for email and 2.1 months for webinars – make them more suitable for near-term acquisition than a program whose first result historically took half a year.

    Audit the audience before committing. Count reachable, permissioned contacts in the target segment; identify how many acquired customers can realistically be attributed; and include the cost of producing the content and building attendance. A webinar presented to an untargeted list is not a low-CAC strategy merely because the video call itself is inexpensive.

    Give GEO and thought leadership enough time to compound

    GEO and thought leadership SEO should build durable discovery around the questions your buyers ask before contacting a vendor. Their observed 5.8- and 6.4-month ramps mean they should not be assigned the job of rescuing the current quarter. That is a planning inference from the averages, not a promise that your first acquisition will arrive on either schedule.

    Choose commercially meaningful questions rather than the largest possible list of keywords. Publish a direct answer, make important claims easy to verify, show who is responsible for the content, and connect related pages so search engines and generative systems can understand the subject and the entity behind it. Then distribute the work through email, social media, webinars, and credible communities. Distribution is part of acquisition cost, so record it rather than treating publication as the end of the job.

    If your budget is constrained, start with one fast-feedback channel and one compounding channel. Fund both through their decision dates. Six underfunded experiments usually produce six ambiguous results, while a smaller mix gives you enough volume and time to distinguish channel failure from an incomplete test.

    Measure channel CAC without giving cheap channels free credit
    An analyst balances blank cost tokens among several connected marketing touchpoints that lead to a packaged purchase.

    Channel rankings become unreliable when each team uses a different numerator, denominator, or attribution window. Write one measurement policy before you compare performance.

    1. Define an acquired customer. Use the same completed event across channels, such as a paid first order or a signed contract. Do not compare qualified leads from one channel with customers from another.
    2. Use a fully loaded numerator. Include media, sponsorships, allocated labor, agency fees, creative production, content production, software, event costs, travel, and other expenses required to operate the channel. Record shared costs under a consistent allocation rule.
    3. Match spend to the customer cohort it created. A customer closing this month may belong to an earlier campaign. Keep immature cohorts open until the relevant sales cycle has elapsed instead of dividing current spend by whichever customers happened to close during the same calendar period.
    4. Separate acquisition from assistance. Record both a primary acquisition source and meaningful assisting touches. Email may close a prospect first introduced through GEO, a webinar, a search ad, or public speaking. Your reporting should show that path without charging the full customer to every participant.
    5. Track marginal CAC as you scale. Average CAC tells you how the program performed so far. Marginal CAC tells you what the next block of customers is costing. Use the second figure for budget increases, especially in auctions or finite audiences.
    6. Pair cost with customer quality and payback. Compare contribution margin, retention, sales effort, deal size, and time to recover acquisition spending. A lower CAC can still produce a worse business outcome if it brings low-margin customers who leave quickly or consume disproportionate support.

    The working formula is simple: channel CAC equals the channel’s fully loaded acquisition cost divided by new customers attributed under your written policy. The difficult part is consistency. Do not change the definition when a favored channel begins to look expensive.

    The same discipline prevents a dramatic benchmark ratio from distorting a budget decision. For example, the reported B2B ratios of 69.3x for ChatGPT Ads and 63.6x for email rely on the shared $32,414 lifetime-value assumption. Recalculate both with your own contribution economics and the payback window your finance team can support.

    Key takeaways

    • Treat an external CAC benchmark as a shortlist, not a forecast or spending target.
    • Reject a channel that fails your allowable CAC, time-to-evidence, viable-commitment, or repeatability test.
    • Email had the lowest organic B2B CAC and the shortest organic ramp, but list creation and audience access still belong in its true cost.
    • GEO and thought leadership SEO carried lower B2B CACs and shorter ramps than basic SEO, supporting an expertise-led approach over undifferentiated keyword production.
    • ChatGPT Ads produced the lowest observed B2B CAC, but the seven-week, 14-account sample and rapidly rising weekly CAC make it an experiment rather than a stable budget baseline.
    • Use fully loaded cohort CAC, assisting-touch reporting, marginal CAC, customer quality, and payback together before moving budget.

    Open your channel plan and add four columns today: allowable CAC, minimum viable commitment, earliest decision date, and marginal CAC. Keep one channel that can generate timely feedback and one that can compound discovery. If you cannot fund a candidate until its evidence date or measure the customers it creates, remove it from the plan before it becomes an expensive ambiguity.

    References


  • International SEO Keyword Localization: A Practical Workflow

    You have a translated landing page, a target-country keyword database, and a discouraging result: the obvious phrase has little volume or no data at all. Before you question the market, question the phrase you used to enter it.

    International keyword localization is the work of discovering how people in a specific market describe the category, their role, the outcome they need, and any local qualification or institution that shapes the search. Done properly, it tells you whether to translate an existing page, rewrite it around a different concept, or create a market-specific page from scratch.

    Start with the market’s vocabulary, not a translation

    Translation answers, “How do we express this phrase in another language?” Keyword localization answers, “What does someone in this market actually search when they need this product, service, qualification, or outcome?” Those questions overlap, but they aren’t interchangeable.

    A translated category can be accurate, fluent, and almost useless as a research seed. People may organize the same need around an occupational title, exam, license, professional card, regulatory code, agency acronym, or locally familiar shorthand. These terms are market artifacts: labels created by the institutions and practices of the market rather than by the generic category itself.

    The effect can be large enough to resemble an absence of demand. In one U.S. Semrush lookup, “commercial drone operator training” returned no related keywords, while “drone pilot training” opened a 26,520-keyword set. FAA Part 107 appeared at rank 17 within the first 1,000 deduplicated rows. In Spain, “curso de operador profesional de drones” returned no data, while “curso de piloto de drones” produced 338 raw terms and 292 after normalization; “AESA A1 A3” appeared at rank 14.

    Those snapshots don’t prove that occupational wording always beats descriptive wording, and the numbers shouldn’t be reused as forecasts for another market. They demonstrate a more important mechanism: a seed controls which keyword neighborhood a tool can enter. If the seed sits outside the market’s normal vocabulary, the tool may return nothing. If it enters the wrong neighborhood, it may return an impressive list that still excludes the terms that govern real demand.

    Build a market vocabulary map

    Before collecting volume, map the different ways the market can name the need. A useful map separates five layers:

    Vocabulary layerQuestion it answersTypical seed types
    CategoryWhat is being sold or learned?Training, software, insurance, certification course
    RoleWhat does the searcher call the person or occupation?Drone pilot, security guard, technician, adviser
    QualificationWhat proves eligibility or competence?License, card, certificate, exam, statutory title
    Institutional systemWhich authority, law, framework, or code organizes the activity?FAA Part 107, AESA A1/A3, TIP, EPA 608
    Task or outcomeWhat is the person trying to do next?Qualify, prepare, renew, apply, comply, become eligible

    One concept may need seeds from every layer. A generic training phrase can reveal broad informational demand, while a license or exam term reveals the route taken by people closer to enrollment. Neither should automatically replace the other. Their jobs are different.

    This is also why “ask a native speaker” is incomplete advice. A native speaker can produce natural wording without knowing the specialist vocabulary of private security, aviation, financial licensing, healthcare, or another regulated field. You need linguistic fluency and market knowledge.

    Give your local reviewer concrete questions instead of asking for a translation:

    • What do practitioners and customers call the occupation?
    • Which license, card, certificate, exam, or membership is associated with entry?
    • Which agency, regulator, law, or code appears in ordinary conversation?
    • What language appears in job listings, training catalogs, and provider navigation?
    • What would a beginner search, and what would an experienced practitioner search?
    • Which acronyms are used on their own, and which full names should accompany them?
    • Does the term describe a legal requirement, an industry convention, or merely a popular course name?

    That last distinction matters. Do not infer a legal obligation from keyword volume, competitor copy, or an AI answer. When a credential or regulation affects eligibility, verify its current name, scope, and issuing authority with the relevant regulator or a qualified local specialist before publishing. Search data can reveal the vocabulary; it isn’t a legal authority.

    Run native keyword research as a controlled workflow

    A reliable process preserves the path from the business concept to the localized page. It should be possible to see which seed produced a term, which tool and discovery route returned it, how a local reviewer interpreted it, and which page will satisfy it.

    1. Define one market, one audience, and one offer. A language isn’t a market. Record the country, language or locale, audience, product availability, conversion action, and any eligibility restrictions before opening a keyword tool.
    2. Write a neutral concept statement. Describe what the offer does and who it serves without treating the home-market keyword as universal. This statement keeps the meaning stable while local terminology changes.
    3. Collect market artifacts before expansion. Review local regulator terminology, professional bodies, training catalogs, job listings, competitor navigation, result-page titles, and recurring questions. Record full names, acronyms, spelling variants, and the relationship between each artifact and the offer.
    4. Create a seed portfolio. When the evidence supports them, use two or three candidates from the category, role, qualification, institutional, and task layers. A portfolio protects the project from the failure of any single translated phrase.
    5. Run lexical and discovery routes separately. A broad-match route may mainly return phrases containing variations of the seed. Related-keyword or keyword-idea routes attempt to construct a broader neighborhood. Label the route in your export so a term that appeared because you typed it directly isn’t mistaken for an independently discovered opportunity.
    6. Preserve raw data, then normalize a copy. Keep the original query, accents, punctuation, and tool metrics. In separate fields, create a canonical form for deduplication, group obvious singular-plural or word-order variants, and assign intent. Never destroy the form people actually use just to make the spreadsheet tidy.
    7. Complete native and commercial review before prioritizing volume. Confirm what the query means, whether its result pages match the assumed intent, whether the offer can serve that intent in the market, and whether the term belongs on an existing page or needs a new one.

    Your working sheet should include more than keyword and volume. At minimum, retain the market and locale, original query, normalized cluster, seed, vocabulary layer, provider, retrieval route, intent, market artifact, relevance status, proposed page, reviewer, and verification status. This provenance becomes essential when two tools disagree or a stakeholder asks why a local page doesn’t mirror the home-market one.

    Keep discovery separate from prioritization

    Discovery asks whether you have found the vocabulary of the market. Prioritization asks which validated clusters deserve content and investment. If you sort by volume before discovery is credible, generic phrases will dominate while lower-volume institutional terms may disappear from view.

    Start by classifying each query into intent and vocabulary layers. Then assess relevance, page fit, commercial value, and available metrics. Avoid summing every close variant as though each represents a separate audience. Keep both cluster-level demand and the underlying query forms so writers know which wording sounds natural.

    Diagnose empty and convincing result sets differently

    An empty result set is visible, so teams often notice it. A populated but incomplete result set is more dangerous because it looks like successful research.

    A controlled comparison run on August 21, 2026 illustrates both failure modes. It used eight predetermined U.S. and Spanish cases and 80 combinations across Semrush and DataForSEO, with seeds, aliases, normalization rules, analysis limits, and decision thresholds fixed before retrieval. In Semrush Related, neutral descriptive seeds recovered the predetermined market artifact in two of seven observable cases; the other five cases returned empty sets. DataForSEO Keyword Ideas recovered the artifact in two of eight cases, but every neutral seed returned a populated set. In six cases, the artifact was absent from the first 1,000 canonical rows.

    These are results from a small, constructed comparison, not universal recovery rates for either provider. Their value is diagnostic. Similar-looking success rates concealed different problems: failure to enter a keyword neighborhood in one route and failure to expose the institutional layer in another. The providers also disagreed about which cases they recovered, so adding another tool is useful as a coverage check, not as an automatic tie-breaker.

    What you seeWhat may be happeningWhat to do next
    No keywords returnedEntry failure: the seed didn’t connect to a usable neighborhoodTry role, qualification, institution, and task seeds. Confirm the country database. Do not record zero demand.
    Many keywords, but no known credential or codeDiscovery failure: a neighborhood exists, but its institutional layer is missingSearch verified artifacts directly, add their aliases, use another discovery route, and inspect local result pages.
    The artifact appears only when used as the seedLexical retrieval rather than independent discoveryKeep the term, but label its provenance correctly. Test whether related seeds can recover it.
    Providers return different artifactsDifferent databases or retrieval methods expose different neighborhoodsTake the union of relevant terms, preserve provider provenance, and let local validation resolve meaning.
    Generic high-volume terms dominateThe seed may be too broad or aligned with the wrong intentAdd occupation, eligibility, exam, application, or compliance language and recheck page-level intent.

    Use coverage gates before calling the map complete

    Create a verified artifact list for the market, then give every item one of four statuses: independently discovered, found only when seeded, absent, or irrelevant to the offer. A simple artifact-coverage measure is the number of relevant artifacts recovered through discovery divided by the number of relevant artifacts verified outside the tool. It isn’t a ranking metric. It tells you whether the research process can see the market vocabulary you already know matters.

    Apply four additional gates:

    • Semantic gate: a native reviewer confirms that the term means what the team thinks it means.
    • Intent gate: the target-market results represent an intent the proposed page can satisfy.
    • Institutional gate: names, acronyms, credentials, and legal claims have been checked against a current authoritative source.
    • Commercial gate: the business can actually provide the product, pathway, or outcome implied by the query in that jurisdiction.

    Only after those gates should search volume, competition, conversion proximity, and production cost determine priority. A term with attractive volume but the wrong qualification, jurisdiction, or user expectation isn’t an opportunity. It is a mismatch.

    Turn localized clusters into the right page architecture

    Keyword localization isn’t complete when the spreadsheet is approved. Its value appears in the decision you make about each page.

    • Localize the existing page when the dominant intent, offer, and user journey remain substantially the same and only the language changes.
    • Rewrite the page around a local frame when the offer is the same but people enter through a different role, credential, or institutional term.
    • Create a market-specific page when eligibility, required steps, proof, or conversion paths differ enough that translated copy would mislead the reader.
    • Exclude the cluster when the business cannot serve the implied jurisdiction, requirement, or outcome. Traffic isn’t useful if the page creates a false expectation.

    A localized content brief should identify the primary cluster, supporting variants, user stage, dominant local role, relevant market artifacts, jurisdiction, page purpose, required answers, internal-link targets, and claims that need authoritative verification. It should also flag home-market language that must not be carried over automatically.

    Use the local terminology in the visible content before considering structured data. Name the qualification, institution, product, and jurisdiction clearly; expand ambiguous acronyms on first use; and explain how the entities relate. JSON-LD should represent what the page actually says. Schema markup can’t repair a page built around the wrong market concept, and adding an entity name only in markup doesn’t make the visible answer useful.

    The same clarity supports answer-engine and generative-search optimization. Give important market questions direct, self-contained answers. If a credential controls the journey, state who issues it, which market it applies to, who needs it, and what action the reader is trying to complete. Keep those statements current and evidence-backed. This creates a clearer entity-and-intent structure for search systems without pretending that formatting or schema guarantees visibility.

    Technical international SEO comes after that editorial decision. Hreflang, canonicals, language targeting, and localized URLs help search engines understand page relationships, but they can’t make a literal translation satisfy a different local intent. Decide what each market needs first; then encode the relationship accurately.

    Measure each localized cluster by market rather than blending language-level performance. Track impressions, clicks, qualified conversions, and page-level intent. If you monitor AI answers, record the prompt, language, market setting, date, response, and cited URL so results can be compared consistently. Revisit the vocabulary map when the offer, qualification pathway, or regulatory terminology changes.

    Key takeaways

    • Translate the business concept, then research the query language natively.
    • Use a seed portfolio spanning category, role, qualification, institution, and task language.
    • Treat licenses, exams, cards, agency acronyms, and regulatory codes as first-class keyword candidates.
    • An empty keyword set indicates a failed entry route, not proof that the market has no demand.
    • A large keyword set can still be incomplete if it omits verified market artifacts.
    • Keep lexical and discovery routes separate, preserve provenance, and validate meaning before prioritizing volume.
    • Let localized intent determine whether you translate, rewrite, create, or exclude a page.

    Start with one high-value page and one target market. Build its artifact list, run seeds from each vocabulary layer, and mark what every route recovers or misses. You will quickly learn whether your existing plan reflects the way that market searches or merely the way your home market describes itself.

    References


  • How to Audit Google Business Profile Collected Info

    How to Audit Google Business Profile Collected Info

    When Google calls, texts, or messages your business to confirm a detail, the answer may not disappear when the conversation ends. Google can retain that information and use it to match your business with people looking for relevant services.

    You can now inspect some of this automated data in the Collected info area of your Google Business Profile. The important part is knowing what to verify, what to delete, and what must be corrected elsewhere. Deleting a collected item and editing your public profile are two separate actions.

    Key takeaways

    • Collected info can contain details gathered through automated calls, texts, WhatsApp messages, or chat conversations with your business.
    • Open your Business Profile and select Edit profile, then Collected info, to review available entries.
    • Check the content, collection date, source, and original language before deciding whether an item is accurate.
    • Delete information that is wrong, outdated, misleading, or no longer representative of the business.
    • Deleting an item removes it from Google’s collected records but does not change a detail already displayed on your Business Profile.
    • The feature is limited to certain regions, languages, and business categories, so an absent tab does not necessarily indicate an account problem.

    What Collected info contains and why it matters

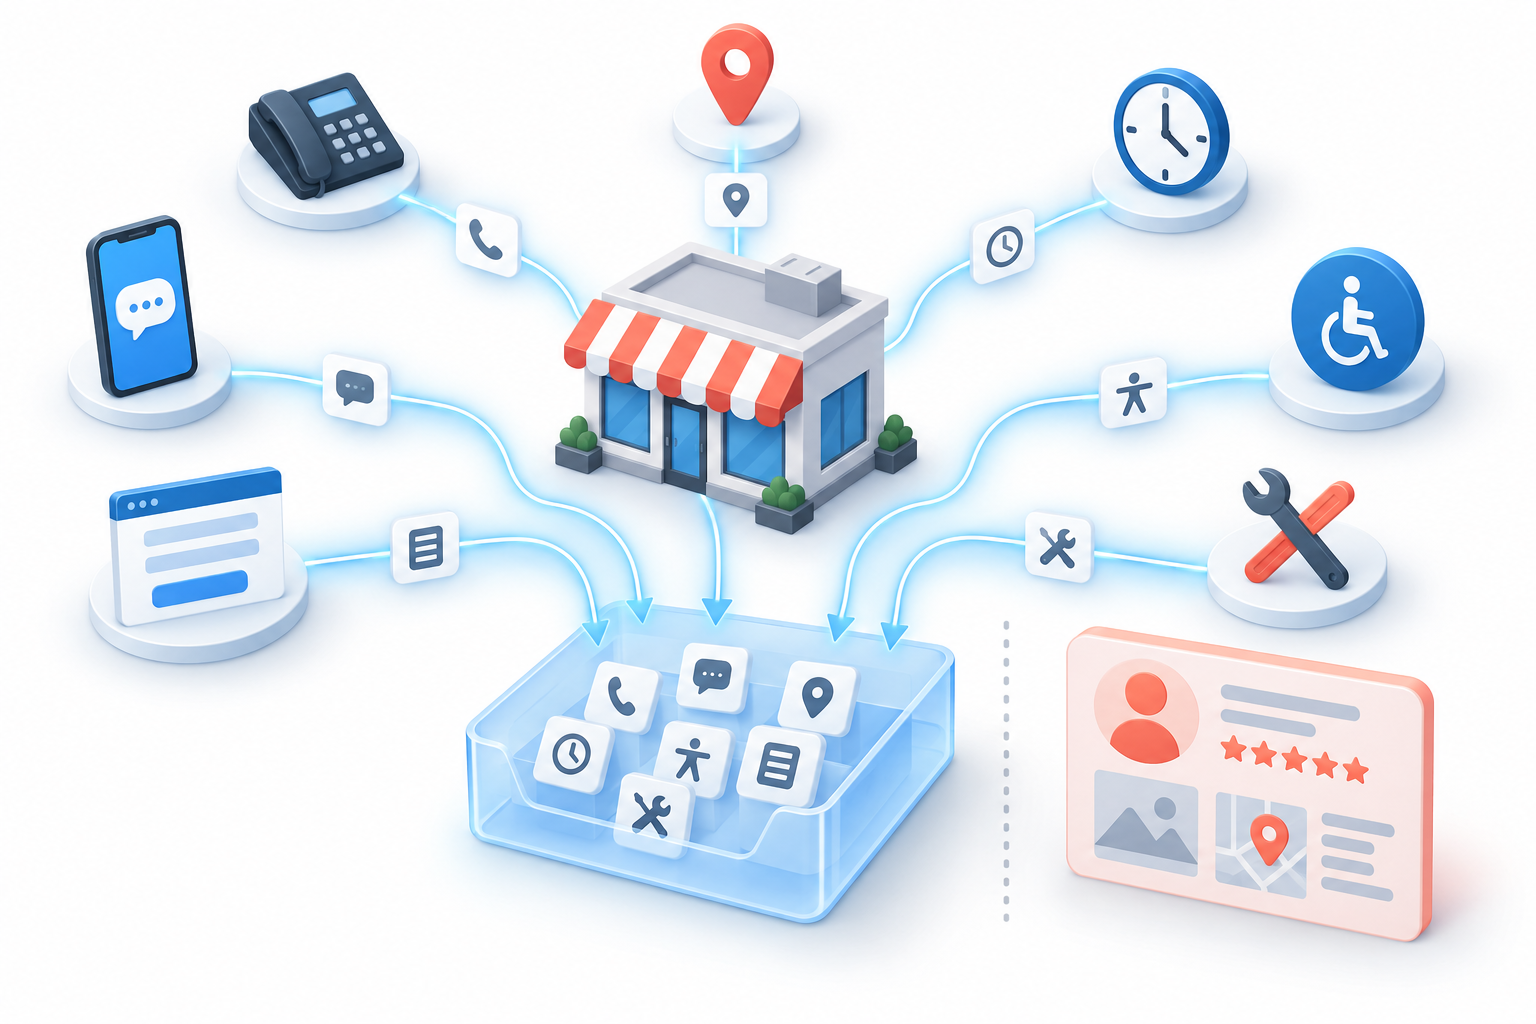
    Phone, message, location, hours and service symbols feed data into a collected-information tray beside a separate public profile panel.

    Collected info is a record of business details obtained through conversations involving Google’s automated assistant. Google may occasionally contact the verified phone number on a profile through a call, text, or WhatsApp message to confirm information. The dashboard can also identify information gathered through phone or chat conversations.

    The stated purpose is practical: the information may be used to update the profile and help match the business with customers looking for relevant services. Treat each entry as a claim about what a customer can expect from your business, not as harmless background data.

    For example, a staff member might give an accurate answer about an exceptional request, a temporary service, or an option available only at one location. The answer can still become misleading if it is interpreted as a general promise. Your audit therefore needs to check scope and conditions, not just whether the words are technically true.

    This is an accuracy control, not a new local ranking switch. Nothing about the feature establishes that retaining more collected entries will improve rankings. The useful goal is to keep Google from relying on a fact that is stale, incomplete, or broader than the service you actually provide.

    Collected info is also not a complete edit history for your listing. It covers information gathered through the relevant automated interactions. Changes made through other profile fields or systems still need their own checks.

    Audit each entry against the business customers can use

    Start from the Google account that manages the verified profile. Open the Business Profile, choose Edit profile, and then select Collected info. If the option is available, work through the entries in a fixed order:

    1. Read the entire entry before acting. Do not delete something merely because its wording differs from your website.
    2. Check where it came from. The interface can show the source of the information, which helps you identify the conversation or operating process behind it.
    3. Check when it was collected. A once-correct answer can become inaccurate after a service, policy, staffing, or location change.
    4. Account for the language. Collected information is displayed in the language in which it was originally provided. Ask a qualified colleague to review it if nobody responsible for the profile can confidently interpret that language.
    5. Compare it with current operations. Confirm that employees at the location would give the same answer now and that customers can actually receive what the entry implies.
    6. Compare it with your public facts. Check the relevant Business Profile field, location page, service page, and structured data where applicable. Note every conflict before deciding which system needs correction.

    Use four questions to test the meaning of an entry:

    • Is this true for this specific location?
    • Is it a normal offering, or was it an exception made for one customer?
    • Does the answer depend on an appointment, schedule, service area, qualification, or other condition?
    • Would a customer reading the statement without the original conversation understand it correctly?

    The fourth question catches the most subtle problem. A short answer can be true inside a conversation while becoming overbroad when separated from the question that prompted it. If essential context is missing, do not preserve the item merely because one interpretation is accurate.

    If you do not see Collected info, do not assume the profile is broken or that Google has gathered nothing. The feature is available only for select regions, languages, and business categories. Continue auditing the visible profile and keep your operational facts consistent while availability expands or changes.

    Delete the collected record, then correct the public layer

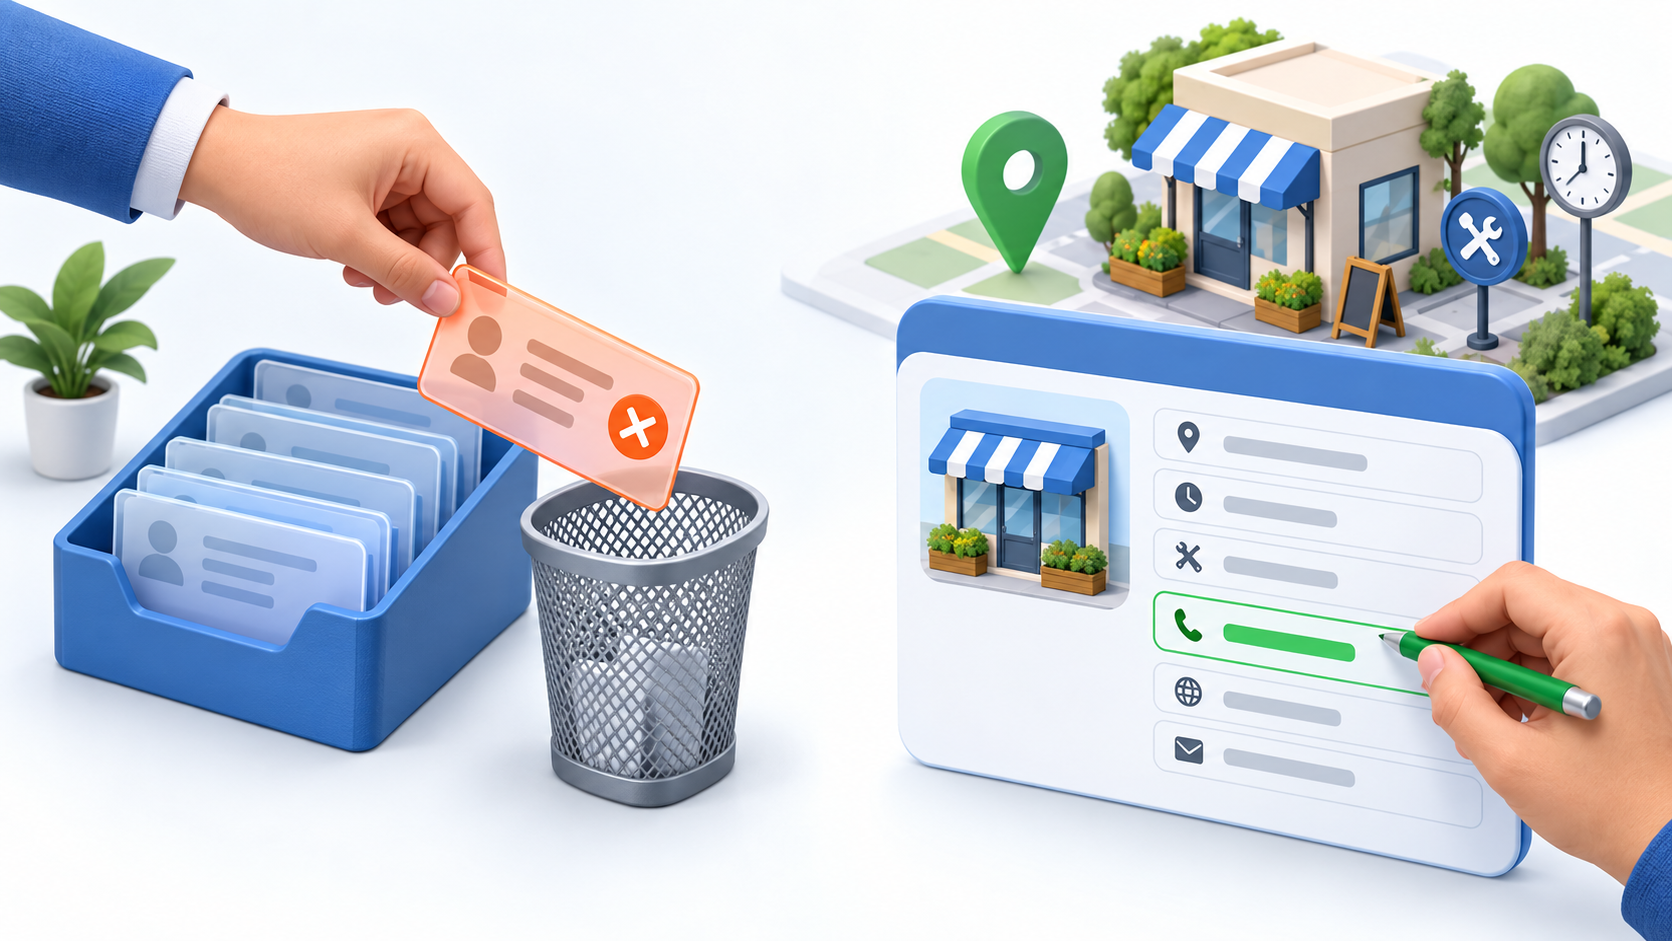
    One hand removes an incorrect collected data card while another updates the matching field in a separate public business profile.

    When an entry is inaccurate or outdated, select Delete and confirm Delete. Before doing so, record the value, collection date, and displayed source in your internal audit log if your team needs an explanation of what was removed.

    The deletion has a narrow effect. It removes the item from Google’s collected records but does not alter other details already present on the Business Profile. This distinction prevents a common cleanup mistake: deleting the collected evidence while leaving the customer-facing error untouched.

    After deleting an incorrect item, inspect the live profile separately. If the same claim appears in a public field, correct that field through the appropriate Business Profile editor. Then check your website and LocalBusiness structured data. A profile action does not rewrite page copy or JSON-LD, and a website correction does not automatically remove a collected record.

    Use this decision rule for every entry:

    • Accurate and properly scoped: leave the collected item in place and confirm that your other customer-facing information agrees.
    • Accurate but easy to misread: check whether the public profile or website needs clearer conditions. If the collected wording itself creates a false impression, delete it.
    • Outdated: delete the collected item and update every public location where the old fact still appears.
    • Incorrect: delete it, correct any affected profile fields, and find out why the business supplied the wrong answer.
    • Unverifiable: ask the person who owns that service or location to confirm it. Do not guess based on old marketing copy.

    Do not delete an entry simply because it was gathered automatically. Automation explains how the information arrived; it does not determine whether the information is useful. Accuracy, scope, and currency should decide the action.

    Prevent the next automated answer from creating a conflict

    A profile manager can clean up the dashboard, but the underlying problem often begins elsewhere. The person answering a call or message may be working from memory, accommodating an unusual request, or using terminology that differs from the website. If that operating gap remains, another interaction can produce another questionable answer.

    Create a compact fact sheet for employees and vendors who handle customer conversations. For each important business attribute, record:

    • the approved customer-facing statement;
    • the location or service area to which it applies;
    • any conditions that materially change the answer;
    • the employee or team authorized to verify it;
    • the primary system or document that owns the fact; and
    • the last time the fact was confirmed.

    This does not need to become a large governance project. A shared sheet or controlled internal page is enough if someone owns it and frontline staff can find it while responding to a call or message.

    Review Collected info when a material business fact changes, when a new entry appears, or when you discover a mismatch in a broader local listing audit. Useful triggers include changes to services, operating hours, appointment requirements, contact routes, location-specific availability, and the team or vendor answering customer inquiries. Event-based checks are more defensible than inventing a universal daily or weekly schedule.

    For AEO and generative engine optimization work, keep the scope clear. Collected info belongs to Google Business Profile; it is not JSON-LD, and its presence does not prove that unrelated AI systems know the same fact. Use the audit to identify your canonical answer, then align the Business Profile, website copy, structured data, and staff responses where each applies.

    Your next move is simple: open Edit profile, look for Collected info, and validate the first entry against current operations before deleting anything. If you find an error, fix both layers involved: the collected record and every public field that still repeats the claim.

    References


  • Meta-TikTok Child Safety Dispute: What Marketers Should Do

    Meta-TikTok Child Safety Dispute: What Marketers Should Do

    If you manage paid social, publish platform news, or forecast teen audience reach, the tempting conclusion is that TikTok rejected Meta’s child safety settlement. That is not what the documented event establishes. TikTok rejected Meta’s ads after classifying them as political content; it did not announce a formal rejection of the settlement terms.

    That distinction should shape your next move. The settlement, Meta’s pressure campaign, TikTok’s advertising decision, and the possible effects on teen media use are related, but they are not interchangeable. Separate them before you change a campaign, brief leadership, or publish an answer that search engines and AI systems may repeat.

    Four events are being compressed into one headline

    Four separate evidence stations on a newsroom desk depict an agreement, a pressure campaign, a blocked advertisement, and youth media use connected by colored threads.

    Meta agreed to pay up to $16.7 billion to settle allegations from U.S. states that Facebook and Instagram were designed in ways that harmed children. The word allegations matters: a settlement resolves claims, but the reported figure should not be rewritten as a judicial finding that every allegation was proved.

    The financial structure gives Meta a direct reason to seek participation from its competitors. About $5 billion of Meta’s settlement is conditional on TikTok and YouTube reaching agreements with similar restrictions and payments of roughly $5 billion from each company. Meta therefore has financial, operational, and competitive interests in turning its agreement into a broader platform standard.

    Meta then launched a public campaign urging TikTok and YouTube to accept comparable terms. It argues that restrictions limited to Facebook and Instagram would be less effective because teens could move to other apps. Meta also says operating alone would put it at a competitive disadvantage. Those are Meta’s positions. They are not established evidence that teen migration will occur at a particular scale or that identical rules across platforms would produce identical safety outcomes.

    TikTok’s action occurred at a different layer. Meta attempted to buy TikTok placements calling on TikTok and YouTube to join the settlement. TikTok blocked the campaign because it contained political content, a category the platform prohibits in advertising. A policy decision about whether an ad may run does not, by itself, reveal whether TikTok accepts or rejects the policy proposal promoted inside that ad.

    • Confirmed settlement fact: Meta agreed to the reported financial and product terms with U.S. states.
    • Confirmed advertising fact: TikTok rejected Meta’s campaign under its political advertising policy.
    • Attributed position: Meta says industry-wide restrictions are necessary for safety and competitive fairness.
    • Unresolved question: TikTok and YouTube had not publicly committed to comparable agreements when Meta applied pressure.

    Use those four labels in internal briefs and published coverage. They prevent the most consequential error in this story: changing TikTok rejected Meta’s ads into TikTok rejected child safety rules.

    The reported restrictions create planning scenarios, not forecasts

    Meta’s agreement includes limits on daily use and overnight access, notification restrictions during school hours, chronological-feed options, and limits on showing likes and other reactions to young users. These terms identify where audience behavior and campaign performance could change. They do not establish how large any change will be.

    Reported termWhat your team should examineDecision to make now
    Daily usage restrictionsReach, repeat exposure, frequency, and sequences that depend on several visitsBuild a sensitivity case with less repeat exposure, then replace assumptions with platform data when relevant terms take effect.
    Overnight access restrictionsDelivery and engagement concentrated in overnight periodsSeparate overnight performance from the rest of the day so dependence on that window is visible.
    Limits on notifications during school hoursCampaigns or publishing patterns that rely on prompts bringing young users backMeasure direct sessions and notification-assisted returns separately wherever your tools permit it.
    Chronological-feed optionsThe relationship among publishing time, recency, organic distribution, and paid amplificationTrack posting time and distribution source rather than treating all feed impressions as equivalent.
    Restrictions on displaying likes and reactionsCreative that relies on visible engagement as social proofTest whether the message remains persuasive when reaction counts are not part of the presentation.

    These are testing priorities, not promised outcomes. The reported material does not provide precise age boundaries, implementation dates, enforcement mechanics, or campaign-performance estimates. Do not invent those details to complete a forecast. Use the age definitions and effective dates that appear in final platform documentation when they become applicable to your account.

    Your planning model should distinguish three scenarios. If comparable restrictions remain limited to Facebook and Instagram, use platform-specific assumptions rather than reducing teen reach across every channel. If TikTok and YouTube sign similar agreements, reassess reach, frequency, dayparting, notification dependence, and social-proof creative across the affected platforms. If negotiations remain unsettled, preserve your operating plan but attach sensitivity ranges and explicit triggers for revising it.

    Do not assume similar settlements would produce identical interfaces or delivery systems. A common restriction can be implemented differently by each platform. Your measurement plan should therefore follow the actual product changes, not merely the legal label attached to them.

    TikTok’s rejection is an advertising-governance warning

    The immediate lesson for advertisers is broader than this corporate fight. A campaign can be about reputation, safety, regulation, or competitor conduct and still be classified as political advertising. A large advertiser and a socially framed message are not automatic exceptions to a platform’s eligibility rules.

    If your campaign asks a regulator, platform, trade group, or competitor to adopt a public-policy position, treat policy review as an early production dependency. Do not wait until the media booking is complete and the creative is final.

    • Write down the campaign’s real objective: selling a product, changing corporate reputation, influencing a policy debate, or pressuring another organization. The label your team prefers does not control how the platform will classify it.
    • Ask for an eligibility assessment before committing the full production and distribution budget. Preserve the platform’s response and the policy language supplied with it.
    • Prepare an owned-channel and earned-media route for the same message. A campaign directed at another platform should not depend entirely on that platform selling you access to its audience.
    • Create channel-specific plans instead of assuming an approval on one network transfers to another. Political-content definitions and enforcement decisions can differ.
    • Do not disguise the campaign’s purpose to evade review. That creates a separate policy and reputational risk without resolving the original classification issue.

    A rejection also needs precise external language. Say that the platform rejected the ad and state the reason provided. Do not escalate that into a claim that the platform opposes child safety, refuses negotiations, or rejected the underlying settlement unless you have separate evidence for that statement.

    A response plan for marketing, communications, and SEO teams

    Three professionals review an abstract social media advertisement at a layered governance checkpoint with a shield, balance scale, and branching paths.

    You do not need to predict which company will concede. You need a process that remains useful under each outcome.

    1. Create a claim ledger with three fields: confirmed event, attributed company position, and unresolved question. Put every sentence in a leadership brief, campaign memo, or news page into one of those fields.
    2. Audit your exposure to the reported restrictions. Identify campaigns that depend heavily on teen repeat visits, overnight delivery, school-hour re-engagement, algorithmic-feed distribution, or visible reaction counts.
    3. Define evidence that will trigger a plan change. Useful triggers include a signed rival agreement, published platform rules, an effective date, product documentation, or a measurable change in your account data. A corporate pressure ad is not an implementation notice.
    4. Maintain separate platform forecasts. Do not copy an assumed Facebook or Instagram effect into TikTok or YouTube merely because Meta wants equivalent terms.
    5. Prepare creative that can work with less visible social proof and fewer repeat exposures. This is a resilient test even if the broader settlement never materializes.
    6. Assign ownership for monitoring. Legal or policy teams should validate obligations, media teams should track delivery changes, analytics teams should preserve baselines, and editorial teams should update public claims when the status changes.

    If you publish about the dispute, answer the narrow question before adding analysis: TikTok rejected Meta’s ads as political content, while TikTok and YouTube had not publicly joined the settlement campaign. That sentence preserves the actors, action, reason, and unresolved status. Avoid the shorter but unsupported formulation that TikTok rejected the settlement.

    That precision also matters for AEO and GEO. Machine-generated answers can collapse adjacent events when a page uses settlement rejection, ad rejection, and policy disagreement as synonyms. Keep each claim in a self-contained sentence, place attribution next to contested positions, and connect every figure to the agreement it describes.

    Use Article or NewsArticle JSON-LD that matches the visible page. Include the real headline, author, publisher, publication date, and modification date. Treat Meta, TikTok, YouTube, and the U.S. states as distinct entities in the copy rather than referring vaguely to the platforms or the parties. Update both the visible wording and structured data when the status materially changes. Schema can clarify a well-written page, but it cannot repair an inaccurate claim.

    Do not use the reported settlement as your organization’s legal compliance checklist. If you serve minors or have separate legal duties, ask qualified counsel to evaluate the rules that apply to your organization. Relying on a competitor’s reported agreement could cause you to miss obligations, age definitions, jurisdictions, or effective dates that are specific to your situation.

    Key takeaways

    • TikTok rejected Meta’s advertisements under its political-content policy; the documented rejection was not a formal rejection of the settlement terms.
    • Meta agreed to pay up to $16.7 billion, with about $5 billion of its settlement contingent on comparable agreements involving TikTok and YouTube.
    • Meta’s claim that teens will migrate to less restricted rivals is a strategic argument, not a measured outcome supplied with the settlement.
    • The reported restrictions give you specific variables to audit: repeat exposure, overnight activity, school-hour notifications, feed order, and visible reactions.
    • Change forecasts when concrete platform terms, dates, product updates, or account data justify it, not merely because one company is publicly pressuring another.
    • For search and AI visibility, distinguish confirmed actions, attributed positions, and unresolved questions in both visible copy and structured data.

    Your best next step is to document the distinction now, while the outcome is still open. Audit where your strategy depends on the affected engagement mechanics, define the evidence that would trigger a change, and keep every public claim narrower than the proof behind it. That leaves you ready to adapt if the restrictions spread without making costly decisions based on a pressure campaign alone.

    References


  • How to Choose a Medtech GEO Agency: A Buyer’s Scorecard

    How to Choose a Medtech GEO Agency: A Buyer’s Scorecard

    You are probably not shopping for another content vendor. You are trying to fix a specific failure: an AI answer omits your device, describes it inaccurately, cites a competitor, or sends a clinician or buyer toward a source you do not control. In medtech, correcting that failure only counts as progress if the work also survives clinical and regulatory review.

    The right selection process tests more than AI-search fluency. It tests whether an agency can connect answer monitoring, clinical evidence, technically clear content, third-party authority, structured data, and your approval workflow. Use the process below to turn a vague GEO pitch into a decision your marketing, medical, technical, and regulatory teams can defend.

    Define the answer problem before requesting proposals

    You cannot evaluate a GEO retainer until you can name the answer behavior that needs to change. More visibility is too vague. An agency can increase brand mentions while leaving the important inaccuracies, weak citations, and dead-end buyer journeys untouched.

    Start by separating four common problems:

    • Omission: Your product or company is absent from a relevant category, procedure, technology, or vendor answer where inclusion would be appropriate.
    • Misrepresentation: The answer uses outdated language, confuses your device with another category, overstates a capability, or misses an important limitation.
    • Weak attribution: The answer mentions you but relies on low-quality, obsolete, or indirect citations instead of accurate evidence.
    • No useful next step: The answer is broadly correct, but the cited page does not help the user validate the claim, understand the product, or continue an appropriate commercial journey.

    Build a prompt ledger before contacting agencies. For every priority question, record the exact wording, intended audience, market, platform and model, run date, generated answer, cited URLs, factual errors, and desired outcome. Preserve enough context to repeat the check. Generated answers can vary between runs and environments, so an isolated screenshot is not a defensible baseline.

    Your prompt set should cover the decisions people actually make around the product. That can include discovering a device category, comparing approaches, checking evidence, understanding appropriate use, evaluating implementation, and identifying vendors. Do not turn unapproved product claims into test prompts and then ask an agency to make the model repeat them. Give finalists the approved language and evidence boundaries first.

    Define success at three levels. Representation asks whether the answer identifies and describes the product appropriately. Evidence asks whether the answer rests on accurate, citable material. Business usefulness asks whether an eligible user can reach a credible next step. A mention can pass the first test and fail the other two.

    Score expertise in the order medtech risk appears

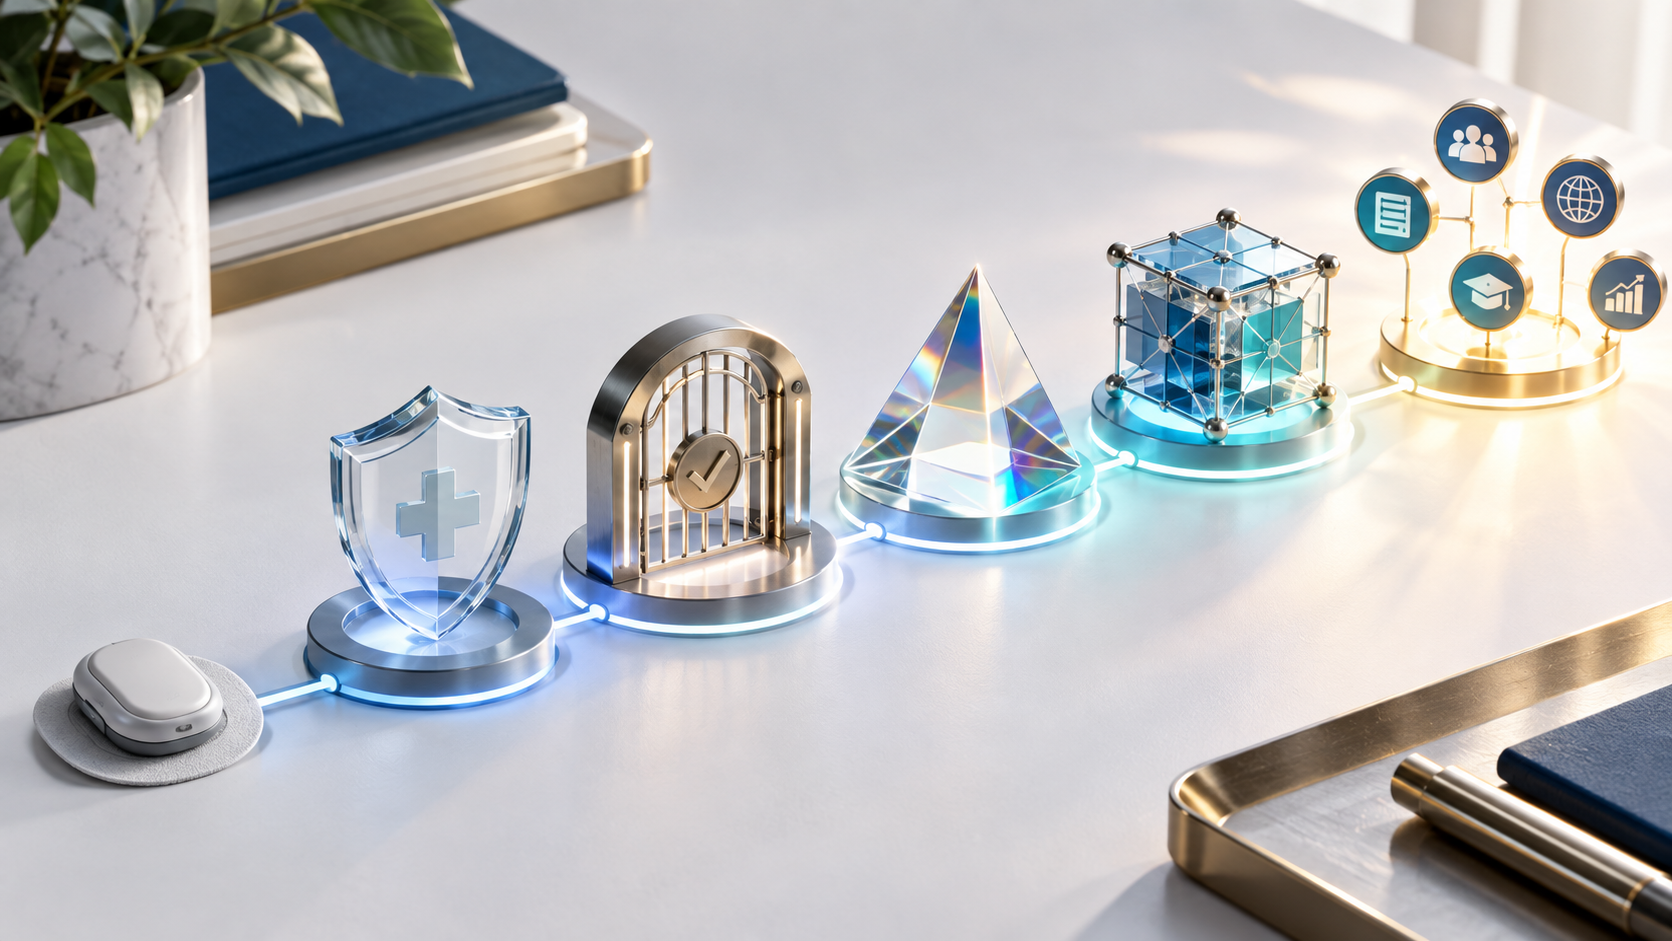
    An unbranded medical sensor follows a tabletop path through a transparent shield, approval gate, evidence prism, data cube, and independent source markers.

    A 2026 medtech agency framework gives GEO expertise 25% of the decision, clinical content expertise 20%, verified reviews 15%, leadership experience 15%, notable clients 15%, and medically trained writers 10%. Those weights are not an industry standard, but they provide a useful starting structure because they keep AI-search capability and clinical discipline at the top of the evaluation.

    CriterionStarting weightEvidence to requestWarning sign
    GEO expertise25%An anonymized prompt audit, a citation-tracking report, a documented correction workflow, and an explanation of how owned, earned, and technical work fit togetherGEO is presented as conventional rank tracking with AI terminology added
    Clinical content expertise20%A device-content sample with claims mapped to evidence, reviewer comments, and a revision historyCopy contains unsupported superiority language or treats a citation as permission to make any claim
    Verified reviews15%Reviews you can inspect, references with comparable scope, and permission to ask about delivery quality rather than results aloneTestimonials cannot be traced to a platform, client, engagement type, or accountable team
    Leadership experience15%Names, roles, availability, and escalation responsibilities for the people who will oversee the workSenior experts run the sales process but disappear from delivery
    Relevant clients15%Device or diagnostics work involving a comparable evidence burden, buyer, market, and approval processA logo wall substitutes for an explanation of what the agency actually delivered
    Medically trained writers10%Credentials, relevant subject experience, authorship responsibilities, and the process for resolving evidence questionsA credential is treated as a substitute for product expertise or formal regulatory approval

    Adjust the weighting to the problem in your brief. If the work involves sensitive clinical claims, raise the importance of content governance and evidence handling. If AI systems repeatedly reproduce outdated information, put more weight on answer auditing, correction strategy, and third-party authority. If your content is already accurate but difficult to interpret, technical architecture and structured data may deserve more attention.

    Do not let an agency collapse clinical writing and regulatory approval into one line item. A medically trained writer can improve evidence interpretation and reduce avoidable errors, but your authorized regulatory team or counsel should make final claims decisions. The proposal should show exactly where that decision occurs and what happens when approval is withheld.

    Match the shortlist to the operating model you need

    Agency names matter less than the mechanism you are buying. The current specialist set spans integrated content programs, device-focused marketing, belief correction, digital PR, full-cycle healthcare GEO, lead generation, and broader performance marketing. Shortlist by that operating model before comparing polished pitch decks.

    There is also an important evidence limitation: First Page Sage produced the available vendor ranking and placed itself first. Treat its numerical scores, client examples, and review summaries as vendor-supplied leads to verify, not independent proof of superiority.

    Operating modelNamed starting pointsPotential fitWhat to verify
    Integrated GEO, SEO, and regulatory-aware contentFirst Page SageYou want one team coordinating search strategy, clinical content, project management, and an internal review layerWho performs the review, how biomedical or life-sciences writers are assigned, and how the agency distinguishes internal quality control from your formal approval
    Medical-device-specialist marketingIcovy and Buzzbox MediaDirect experience with regulated device companies matters more than a broad healthcare portfolioThe depth of answer monitoring, technical optimization, structured-data implementation, and evidence management within the GEO scope
    Belief correction and third-party authorityGenevate and Avenue ZYour main problem is inaccurate or outdated AI representation, weak external corroboration, or insufficient digital authorityDirect device-industry experience, placement terms, editorial independence, paid costs, correction strategy, and what remains live after the engagement ends
    Full-cycle healthcare GEOFocus DigitalYou need content strategy, technical work, and ongoing AI-citation tracking under one teamWhether experience with providers and consumer-facing healthcare search transfers to your manufacturer, product, buyer, and regulatory context
    Lead-generation-oriented GEOSignal Hill StrategiesThe mandate must connect AI visibility to qualified commercial demandClinical content depth, device-specific experience, lead definitions, attribution rules, and the handoff from cited answer to conversion path
    Combined GEO, SEO, and paid acquisition95 ProjectsYou prefer a broader performance program covering AI search, organic search, and PPCMedtech references, because named clients were not publicly disclosed in the available profile, plus the credentials of the people handling clinical material

    These categories can overlap. Use them to design better diligence questions, not to force every agency into one box. A device specialist may also run digital PR, while a healthcare GEO team may have strong technical capability. The issue is whether the people assigned to your account can demonstrate the full chain from answer diagnosis to approved intervention and measurement.

    Make finalists prove the operating system before you sign

    A medtech client and agency team test a review workflow with a wearable device, approval cards, and an abstract source-to-answer display.

    Give every finalist the same test packet

    A fair evaluation uses one controlled brief. Provide a product overview, priority market, approved indication and claims, permitted evidence, existing web properties, priority audiences, representative prompts, prohibited claims, and your review path. Remove confidential material that is not necessary for the exercise, and use approved secure channels rather than pasting sensitive product information into a public consumer AI interface.

    Ask each agency to return the same working artifacts:

    1. A baseline answer map. It should pair exact prompts with the platform, model or interface, run date, observed answer, citations, error type, and eligibility for intervention.
    2. An intervention map. Every gap should connect to a proposed owned-content, third-party-authority, technical, or correction action, with an owner and approval requirement.
    3. An evidence-led content brief. It should identify the audience question, intended answer, permitted claims, supporting evidence, reviewer, page purpose, and the boundaries the writer must not cross.
    4. A technical plan. It should explain how information architecture, crawlability, entity clarity, internal linking, and structured data will support the content. Any schema must match visible, approved information; markup cannot create clinical evidence or authorize a claim.
    5. A reporting specimen. It should expose the prompt set, denominator, platforms, run dates, scoring method, citations, factual review status, and any observable business actions.
    6. A governance map. It should name the strategist, medical writer, technical specialist, editor, account lead, and client-side approvers, including escalation paths for evidence disputes and material errors.

    A proposal that jumps directly to a content calendar has skipped the diagnostic work. Publishing more pages can increase the amount of material available to an AI system without correcting the entity confusion, evidence gap, or third-party consensus that caused the problem.

    Use metrics that can survive an internal review

    Require every percentage to come with its prompt set, denominator, platform, dates, and scoring rule. Without those elements, an AI-visibility score cannot be reproduced or interpreted.

    • Eligible mention coverage: The share of priority prompts in which the company or product appears when inclusion is appropriate.
    • Accuracy pass rate: The share of checked answers that pass your internal factual and claims review.
    • Citation quality: Whether answers rely on current, relevant, authoritative material rather than merely producing more links.
    • Corrective asset progress: Whether inaccurate claims have an approved response plan, published corrective material, and follow-up monitoring.
    • Owned-source reach: Whether accurate pages from your controlled properties are being surfaced and cited for the questions they were built to answer.
    • Qualified business actions: Observable visits, inquiries, or other agreed actions that follow AI discovery. Keep directly observed data separate from modeled attribution.

    Do not set an improvement target until the baseline is complete. The eligible prompt universe matters: a device should not be rewarded for appearing in an answer where it is irrelevant, unsupported, or outside its approved use.

    Put governance and uncertainty into the contract

    The statement of work should name the platforms and markets in scope, deliverables, reporting cadence, prompt-versioning process, client review stages, revision responsibilities, third-party placement costs, content ownership, data handling, automation disclosure, conflicts, and offboarding materials. It should also say who can publish and who can approve claims.

    Reject guaranteed recommendations, permanent citations, or control over a frontier model’s output. An agency can improve the clarity, authority, availability, and consistency of information that AI systems may use. It cannot compel an external model to produce a particular answer. A credible contract defines controllable work and a transparent measurement protocol instead of converting uncertainty into a sales promise.

    Medtech GEO agency FAQ

    What does a medtech GEO agency actually do?

    A medtech GEO agency audits how AI systems represent a company, product, or device category; identifies factual, citation, entity, content, and authority gaps; improves owned content and technical clarity; develops appropriate third-party authority; and monitors whether generated answers become more accurate and useful. In regulated work, it must also fit those activities into clinical evidence and approval workflows.

    How is GEO different from healthcare SEO?

    SEO primarily improves discovery through ranked search results and the pages users visit. GEO focuses on how a brand, product, or fact is represented and cited inside generated answers. The disciplines overlap because clear, crawlable, authoritative pages can support both. A capable agency should explain that overlap without pretending conventional keyword rankings fully measure AI visibility.

    Do you need an agency with direct medical-device experience?

    Direct device experience becomes more valuable as the evidence burden, claims sensitivity, buyer complexity, and approval workflow increase. An adjacent healthcare or life-sciences agency may still be a fit if it can demonstrate the right people, comparable work, and a precise governance model. Judge the assigned team and operating process, not the sector label on the homepage.

    Can an agency guarantee that ChatGPT will recommend your device?

    No. The agency does not control ChatGPT or another external model. It can make accurate information easier to understand, substantiate, discover, and cite, then measure how answers change. A recommendation guarantee is a reason to investigate the methodology and contract language more closely.

    Your next move is simple: send the same problem brief to each finalist and score the artifacts, assigned people, and approval workflow rather than the pitch. If a team cannot show a reproducible baseline, an evidence chain, a safe review path, and transparent measurement, pause before buying the retainer.

    The strongest choice will make your device easier to identify, describe, substantiate, and cite without leaving regulatory reviewers to repair the work after publication.

    References


  • How to Build a Google Analytics Dashboard for Decisions

    How to Build a Google Analytics Dashboard for Decisions

    You open Google Analytics to answer one question and end up moving through several reports, copying figures into a document, and trying to remember whether everyone used the same comparison period. The data may be available, but the route to a decision is unnecessarily long.

    Google Analytics Dashboards can shorten that route by putting selected KPIs and visualizations on a customizable, grid-based canvas. The useful part isn’t the canvas itself. It is the discipline of deciding which questions deserve permanent space, which chart can answer each question, and what someone should do after seeing the result.

    Decide what the dashboard must make obvious

    A dashboard should reduce decision time. It shouldn’t reproduce every report your team might occasionally need. Before you add a card, write a short dashboard brief that answers:

    • Who will use it? An SEO lead investigating landing pages needs different detail from an executive checking overall acquisition and conversion performance.
    • What recurring decision will it support? Examples include deciding where to investigate a traffic decline, which content group needs attention, or where users leave a conversion journey.
    • How often will someone review it? The review rhythm determines whether short-term movement or longer trends deserve more space.
    • What is the primary outcome? Name the result the dashboard is supposed to monitor before choosing supporting metrics.
    • Who owns the response? A metric without an owner becomes decoration. Decide who investigates, who explains, and who acts.

    Turn each proposed card into a complete question. “Organic traffic” is only a label. “Is traffic from organic discovery moving in the expected direction, and which landing content explains the change?” is a question. It tells you that you need a headline value, a trend, and enough detail to locate the affected content.

    Give every KPI an explicit scope as well. The team should know which property, audience, outcome, time period, and comparison the number represents. Two people can read the same number differently when one assumes all traffic and the other assumes a particular channel. The dashboard won’t fix an unsettled definition; it will simply make the ambiguity more visible.

    This distinction matters for SEO, AEO, and GEO reporting. Google Analytics can show activity captured in the property, including measurable visits and subsequent behavior. It cannot turn external rank tracking, AI citation visibility, crawl findings, CRM revenue, or platform delivery data into Analytics measurements merely by arranging cards on a page. Keep those claims in their appropriate systems, then use the dashboard for the questions its data can actually answer.

    Build from outcomes to diagnosis

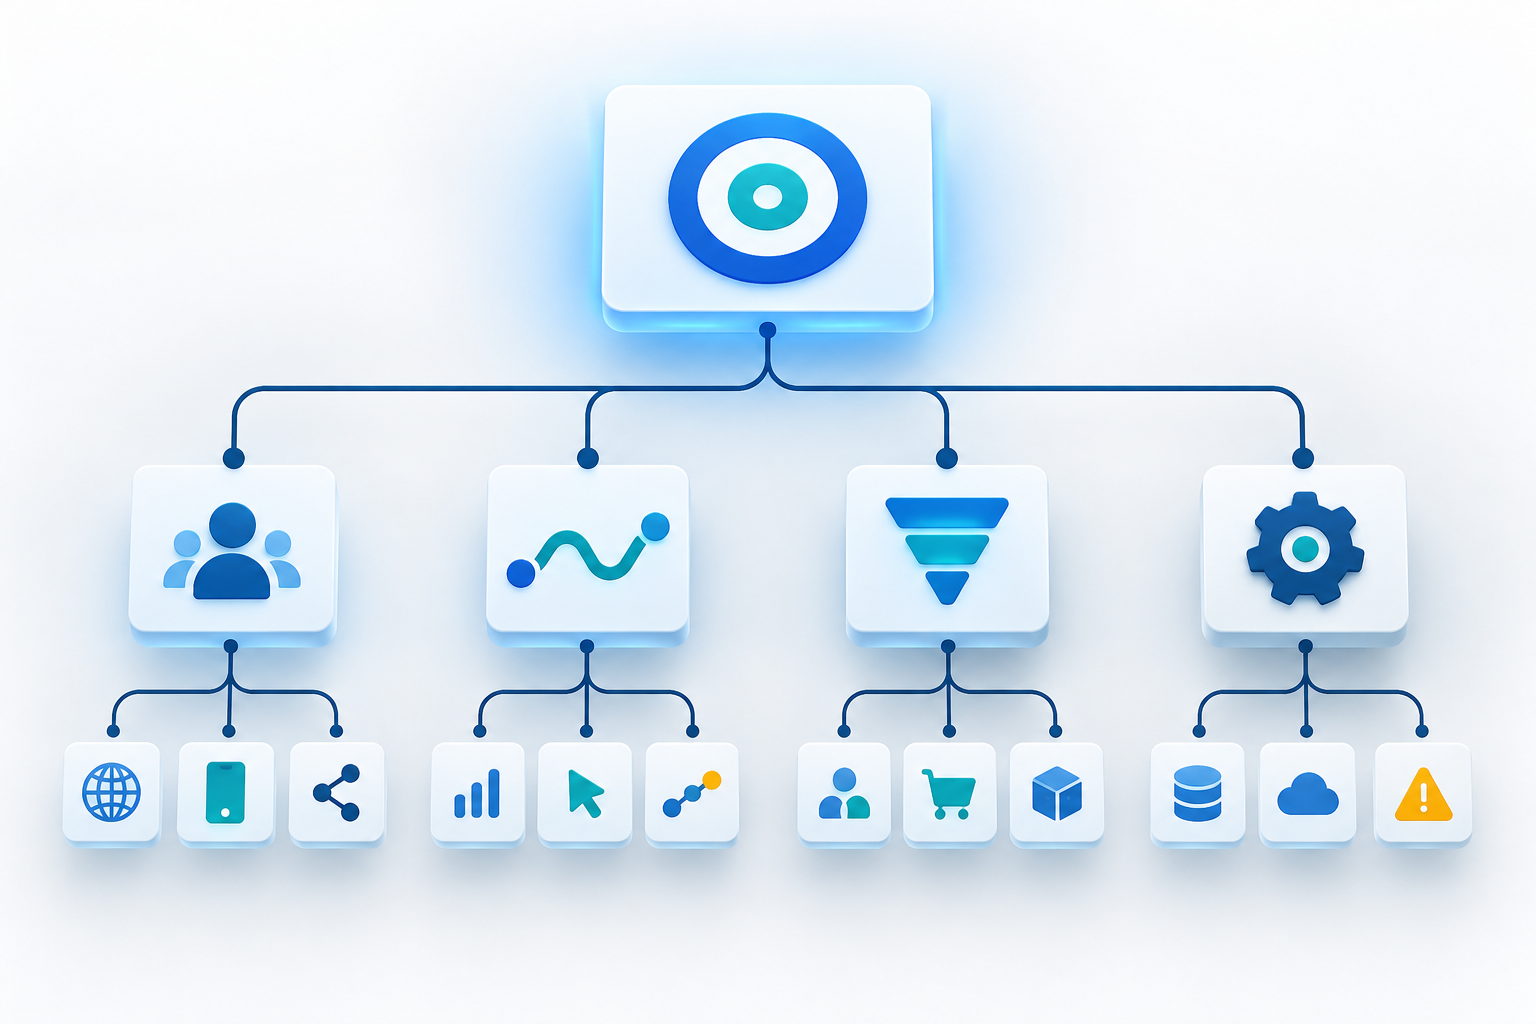
    A large outcome tile branches into several smaller diagnostic dashboard modules in a layered hierarchy.

    The builder lets you drag dimensions and metrics onto the canvas, then position, resize, and align the resulting visualizations. That makes experimentation easy, but it also makes it easy to fill the page before establishing a hierarchy.

    Build in the order a reader will think:

    1. Start with the outcome. Place the KPI that best represents the dashboard’s primary business result where the eye lands first.
    2. Add its context. Show the input or volume metric needed to interpret that result. An outcome without scale can make a small fluctuation look more important than it is.
    3. Show direction. Add a time-series view so the reader can distinguish a sustained movement from an isolated value.
    4. Expose the main comparison. Break performance down by the category most likely to explain a change, such as an acquisition grouping or content grouping that your measurement plan defines consistently.
    5. Provide a diagnostic route. Use a detailed table for the pages, campaigns, or other entities someone will inspect next.
    6. Add the journey where it matters. If the decision concerns an ordered conversion process, use a funnel to reveal the step where progress changes.
    7. Remove repetition. If two cards lead to the same observation and action, keep the clearer one.

    This sequence creates a practical reading path: outcome, context, trend, explanation, detail, action. It also leaves room beneath the documented cap of 15 cards for standard properties. Premium properties can contain up to 30, but a larger allowance isn’t a reason to use every available position.

    Review the completed canvas at the size your intended audience will normally use. Visual priority comes from position and size as well as chart type. If the primary outcome is smaller than a supporting breakdown, the layout is telling the reader that the breakdown matters more.

    Match each business question to the right visualization

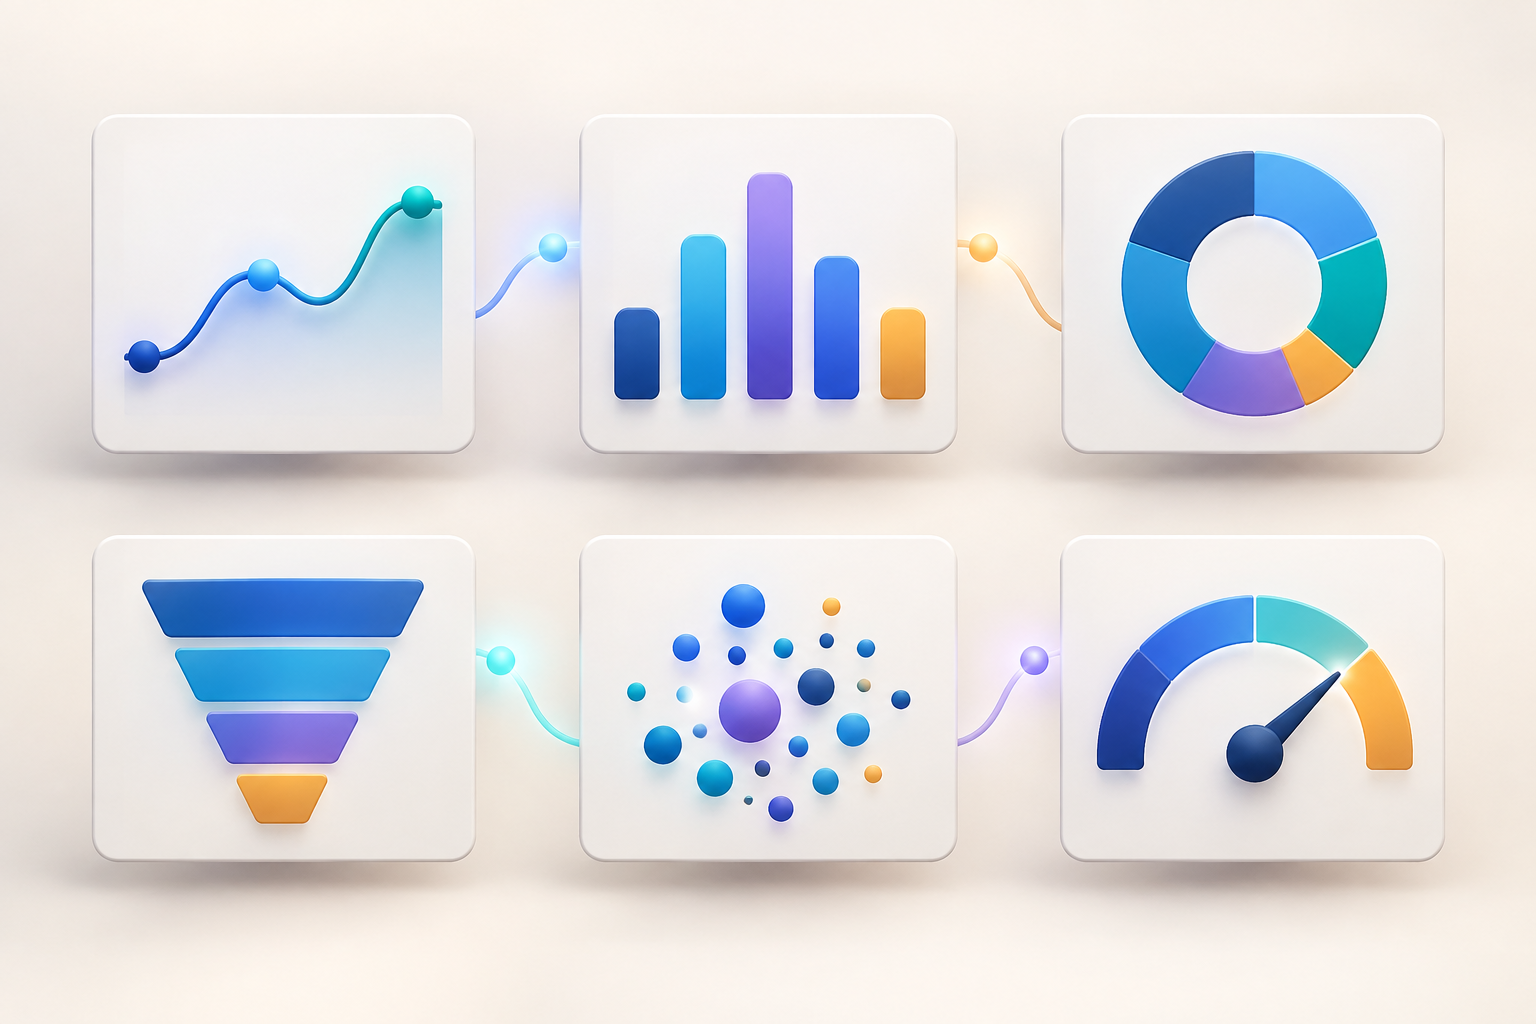
    Six dashboard cards display abstract line, bar, ring, funnel, dot, and gauge visualization forms.

    Six visualization types are available: scorecards, tables, line charts, bar charts, donut charts, and funnel charts. Choose among them by the question being asked, not by the visual variety they add to the page.

    VisualizationQuestion it should answerBest useCommon mistake
    ScorecardWhat is the current headline value?A primary KPI or an essential context metricDisplaying several isolated values without showing why any change matters
    Line chartWhen did the movement begin, and did it persist?Performance over timeUsing a trend line when the real question is a comparison between categories
    Bar chartWhich categories are larger, smaller, ahead, or behind?Direct category comparisonsAdding so many categories that meaningful differences become hard to see
    Donut chartHow is a whole divided among a limited set of parts?A simple composition or share breakdownUsing similar-sized or numerous slices that are difficult to compare
    TableWhich exact item requires investigation?Detailed rows that support diagnosisTurning the dashboard into an exhaustive data export
    Funnel chartAt which ordered step does progression change?Conversion steps and drop-offsTreating unrelated actions as if they formed a single sequential journey

    Use date context deliberately. Scorecards can display percentage change when a date comparison is applied, while line charts support daily, weekly, and monthly views. Pick the line-chart interval that matches the decision rhythm. A view that is too granular can distract the reader with ordinary variation; one that is too broad can conceal when a meaningful shift began.

    A percentage movement also needs its underlying value. A large percentage attached to a small base may deserve less attention than a modest movement in the metric most closely tied to the business outcome. Keep the scorecard for quick detection, then place a trend or detailed breakdown nearby so the reader can test whether the movement is broad, persistent, and actionable.

    Publish with property-wide governance in mind

    Creating a useful layout is only half the job. A user needs an Editor or Administrator role to create and publish a dashboard. Once published, the dashboard can be viewed by anyone who has access to the property, and it can be placed directly in the Reports navigation without routing it through the Analytics library.

    That convenience changes the governance standard. Published dashboards are shared across the property rather than privately with selected individuals, so don’t treat the published area as a personal scratchpad. Settle experimental metric definitions and layouts before exposing them to every property user.

    • Name the audience and purpose clearly. A title such as “Content performance” is weaker than one that identifies the intended decision or review context.
    • Assign an owner outside the dashboard. Someone should be responsible for definitions, layout changes, and questions from viewers.
    • Record the KPI definitions. Preserve the scope, outcome meaning, and expected response in team documentation so the dashboard doesn’t become its own undocumented vocabulary.
    • Check the published view with ordinary access. Confirm that the navigation placement and reading order work for viewers, not only for the person who built it.
    • Review cards when strategy changes. Remove KPIs that no longer inform a live decision instead of leaving them in place for historical familiarity.

    Plan around the launch limitations before promising the dashboard as a complete reporting system. API support, segments, and card-level comparisons were not supported at launch. That means you shouldn’t design a workflow that depends on programmatic dashboard management, segment-based dashboard cards, or a different comparison basis for each card unless those capabilities are verified in your property.

    The absence of card-level comparisons is especially important. Agree on a coherent comparison before presenting the page, and explain any analysis that requires a different baseline somewhere else. Otherwise, adjacent cards can appear comparable while answering different questions.

    Key takeaways

    • Start with a recurring decision and its owner, then choose the metrics needed to make that decision.
    • Arrange cards as a reading path from outcome to context, trend, explanation, and diagnostic detail.
    • Use scorecards for headline values, line charts for timing, bar charts for comparison, donut charts for simple composition, tables for diagnosis, and funnels for ordered journeys.
    • Keep metric definitions and scope explicit; a clean layout cannot repair an ambiguous KPI.
    • Design within the 15-card standard or 30-card premium limit, but treat those figures as ceilings rather than targets.
    • Publish only after accounting for property-wide visibility, role requirements, and the feature limitations that applied at launch.

    Your first dashboard should feel focused rather than comprehensive. Open the builder with your decision brief beside you, place the primary outcome first, and add a card only when it helps the reader detect a change, explain it, or choose the next action. If a card does none of those jobs, leave the space empty.

    References


  • Professional Ghosting: How to Close the Loop in Business

    Professional Ghosting: How to Close the Loop in Business

    The promised update has passed. You delivered the proposal, joined the interview, signed the paperwork, or took the call. Now the other person has disappeared, and you are deciding whether to follow up again, wait quietly, or write off the relationship.

    You do not need to keep guessing. A clear follow-up boundary can protect your time without turning a delayed reply into a confrontation. The same standard can help your team stop creating this problem for candidates, vendors, partners, clients, and professional contacts.

    Professional ghosting begins where commitment ends

    A slow reply is not automatically ghosting. People get pulled into urgent work, approvals stall, budgets change, and decisions take longer than expected. The defining problem is not the delay. It is the abandoned commitment.

    Professional ghosting happens when someone initiates or actively advances a business process, creates a reasonable expectation of another step, and then stops communicating without closing that process. The pattern is especially clear when a person requests a proposal, paperwork, an introduction, or participation in an interview process and does not acknowledge the work after it arrives.

    This distinction matters because it tells you what to respond to. You are not demanding instant access to another person. You are asking them to account for a commitment they chose to make.

    A useful test is to identify the last explicit agreement. Did someone promise an update by a named date? Ask you to prepare something? Say they would arrange another conversation? Accept responsibility for getting an answer? If no commitment was made, you may simply have an undeveloped lead. If a commitment was made and abandoned, you have an open loop that needs a boundary.

    The business cost extends beyond an unanswered inbox:

    • Calendar uncertainty: You may hold time, delay another decision, or reserve delivery capacity for work that is no longer moving.
    • Unpaid effort: A customized proposal, interview, review, introduction, or contract document consumes real attention even when no transaction follows.
    • Distorted pipeline data: An opportunity that is functionally dead can remain marked as active because nobody recorded the decision.
    • Reputational spillover: Candidates, consultants, vendors, and former colleagues may remember how the process ended and share that experience when your name comes up.
    • Weaker future communication: Once missed commitments become normal, people stop trusting dates and next steps from the organization.

    The answer does not have to be yes. Nobody is entitled to a contract, job, partnership, or detailed explanation. But silence transfers the follow-up work and planning cost to the person who did not create the uncertainty. A direct no is usually easier to manage because it lets everyone release time and make the next decision.

    Follow up from the commitment, not from your anxiety

    A calm professional reviews a blank planner at an organized desk with one sealed envelope, a face-down phone, and a closed laptop.

    Repeatedly checking in without a decision rule makes you feel active while leaving the underlying uncertainty untouched. A better follow-up points to the agreed next step, asks for a small status decision, and explains what you will do if no answer arrives.

    Match the message to the state of the conversation

    • A promised update is overdue: Follow up after the promised date has passed. Name that date without accusation and ask whether the matter is active, paused, or closed.
    • You sent a requested deliverable: Confirm that it arrived, then ask what decision or review step follows. Do not keep producing additional work to provoke a reply.
    • No next step was agreed: Treat the conversation as interest, not an active opportunity. Ask for a concrete next action only if you still want one.
    • You are holding time or capacity: State when you need to release it. This is operational information, not a threat.
    • The other person already missed several self-imposed commitments: Stop asking for another vague update. Close the opportunity on your side and require a fresh plan if they return.

    Use one message to request a decision

    Subject: Status of [project or opportunity]

    Hi [Name], you mentioned that I would receive an update by [promised date], so I wanted to close the loop. Is this moving forward, paused, or no longer under consideration? Any of those answers is fine; I need the current status so I can plan [capacity, scheduling, or the next deliverable]. If the timing is still uncertain, a simple paused is enough.

    This works because it lowers the effort required to answer. The recipient does not have to compose a defense or manufacture certainty. They only have to identify the present state.

    Avoid messages such as just checking in or circling back. They do not tell the recipient what you need, and they do not establish what happens next. Also avoid writing a long account of the work you completed. If the person already knows what they requested, repeating every detail can make a straightforward status request sound like a dispute.

    Close the opportunity when waiting has a cost

    If your decision request remains unanswered and you need to plan around the uncertainty, send a final operational note:

    Hi [Name], since I have not received an update, I am marking this opportunity inactive and releasing the time associated with it. If the project becomes active again, feel free to reconnect. We can review the scope, timing, and availability based on the situation then.

    This is not a tactic for forcing a response. It is a record of the decision you are entitled to make: you will no longer reserve attention or capacity for an unconfirmed opportunity. Once you send it, act accordingly. Update the pipeline, release the calendar hold, and stop chasing.

    Handle warm introductions without recruiting the introducer

    A warm introduction carries an extra relationship. The person who connected you has attached some of their reputation to the exchange, so the introduction should create more accountability, not less.

    Do not immediately ask the introducer to pressure the silent party. Follow up directly first. If the process stays unresolved, give the introducer a neutral closure update:

    Thanks again for connecting us. We spoke, but we did not establish a next step, and I have now closed the conversation on my side. No action is needed from you; I just did not want to leave your introduction unresolved.

    That message protects the introducer from wondering what happened without turning them into a collections agent for attention. Keep it factual. Do not speculate about motives or invite them to take sides.

    Decide whether to reopen the relationship

    People sometimes return after a long silence. You do not have to punish them, but you also do not have to restore the old assumptions. Evaluate the return using three questions:

    • Did they acknowledge the gap? Ownership is more useful than an elaborate excuse. Someone who pretends nothing happened may repeat the pattern.
    • Is there a real decision now? Ask what changed, who owns approval, and what the next committed action is.
    • Can you reduce the cost of another disappearance? Restart with a smaller defined step, written responsibilities, and no speculative work beyond what the opportunity justifies.

    A returned email does not restore expired availability. Reconfirm scope and timing instead of silently absorbing the disruption into your schedule.

    Say no clearly without damaging the relationship

    Most closure messages do not require a long explanation. They need a decision, the current status, and any legitimate next step. Clarity is kinder than a soft phrase that keeps the recipient waiting.

    SituationWhat to sayWhat to avoid
    The fit is wrongWe will not be moving forward because this does not match our current requirements.Excessive praise followed by an ambiguous maybe.
    Priorities changedThe project is paused, and we do not have an approved restart point.We will circle back soon when no follow-up is planned.
    Another option was selectedWe chose a different direction and have closed this evaluation.A defensive comparison of every candidate or vendor.
    The decision is delayedWe have not made the decision. I missed the update I promised, and the next checkpoint is [date].Letting the original deadline pass without acknowledgment.
    You dropped the ballI failed to close this loop. I am sorry. The current status is [status].Restarting the thread as though the silence never happened.

    Decline a proposal or partnership

    Hi [Name], thank you for the time and work you put into this. We have decided not to move forward with [proposal or partnership]. The reason at a high level is [brief, accurate reason, if useful]. This closes the evaluation on our side. I appreciate your participation and wanted to give you a definite answer.

    Do not offer future work merely to soften the no. If you genuinely want to revisit the relationship under identifiable conditions, name them. Otherwise, a clean ending is more respectful than a fictional possibility.

    Report a delay before it becomes ghosting

    Hi [Name], I promised an update by [date], but the decision is not ready. [Approval, budget, or priority] remains unresolved. The next real checkpoint is [new date or event]. You do not need to do anything in the meantime. If that timing no longer works for you, I understand.

    A delay notice is valuable even when it contains no new decision. It proves that someone still owns the process and prevents the recipient from having to chase information you already know is missing.

    Own a missed commitment

    Hi [Name], I said I would update you and did not. That was my mistake. The current status is [active, paused, or closed]. [State the next action, if one exists.] I am sorry I left you without an answer.

    Do not bury the acknowledgment under an account of how busy the team became. The recipient needs the truth and the status. An explanation is optional; ownership is not.

    Build closure into the workflow, not into good intentions

    Two professionals exchange an unmarked folder over a project table where blank wooden tiles form a complete circle.

    Ghosting often persists because the organization records acquisition activity but not closure responsibility. A system may track calls booked, interviews completed, proposals requested, and documents sent while leaving nobody accountable for the final message.

    Every active external conversation should have four visible fields:

    • Current state: Exploratory, active evaluation, waiting on us, waiting on them, paused, accepted, or declined.
    • Named owner: One person responsible for the next communication. A department cannot send an email.
    • Next commitment: The specific decision, document, meeting, or update that has been promised.
    • Trigger: The date or event that tells the owner to act, even if the decision is still pending.

    At the end of a meeting, say the handoff aloud: who will do what, what the recipient should expect, and what will happen if the answer is not ready. A transcript or meeting summary can preserve that agreement, but recording a promise is not the same as fulfilling it.

    Make the initiator responsible for closure

    A practical ownership rule is that the person or team requesting effort owns the next acknowledgment until another person explicitly accepts the handoff. If your company asks for an interview, custom proposal, security review, NDA, sample, introduction, or planning session, assign the response owner before the request goes out.

    Before asking someone to do substantial work, confirm internally:

    • What decision will this work inform?
    • Who can actually make or approve that decision?
    • Who will acknowledge receipt?
    • Who will communicate a delay or rejection?
    • What event closes the process if the project loses priority?

    If nobody can answer those questions, the process is not ready to consume another person’s time.

    Use automation to surface promises

    Automation can create a reminder when an update is promised, flag a waiting-on-us record, prepare a draft, or show an owner all overdue commitments. It should reduce the chance that a relationship disappears inside a crowded inbox.

    It should not invent a decision, send an insincere rejection, or remove human judgment from a sensitive relationship. Efficiency should leave more room for judgment and professional courtesy. It should not enable a team to open more conversations than it can responsibly finish.

    Audit closure debt at your normal planning cadence

    When you review work in progress, filter for external conversations marked waiting on us, records whose trigger has passed, and opportunities with no defined next step. For each one, choose an actual state: advance it, pause it with an update, decline it, or assign a new owner.

    Do not measure professionalism by inbox volume. Track the conditions that reveal whether your process can finish what it starts: overdue external commitments, open records without an owner, requested deliverables without an acknowledgment, and inactive opportunities still counted as live. Your own trend is the useful benchmark. The purpose is to reduce unresolved commitments, not create a decorative score.

    Key takeaways

    • Professional ghosting is an abandoned commitment, not merely a slow response.
    • Follow up by naming the agreed next step and asking whether the matter is active, paused, or closed.
    • If waiting affects your schedule or capacity, send a final closure note and release the time.
    • A warm introduction deserves extra care because the introducer’s reputation is part of the exchange.
    • You can decline without a detailed defense. State the decision, give a concise reason when useful, and remove false ambiguity.
    • Assign an owner, next commitment, and trigger whenever your team asks an external person to invest effort.
    • Use automation to reveal overdue promises, while keeping consequential relationship decisions under human ownership.

    Choose one unresolved conversation you own and close it now. Send the decision if you have it. If you do not, send the current status and the next honest checkpoint. That small habit is how professional trust survives changing priorities, crowded calendars, and uncomfortable answers.

    References


  • How to Tell Whether an SEO Audit Is Worth the Money

    How to Tell Whether an SEO Audit Is Worth the Money

    You have an SEO audit proposal in front of you, but the deliverables sound suspiciously like a list of errors from a crawling tool. The price may buy expert investigation, or it may buy an export you could generate yourself.

    The difference is judgment. A valuable audit identifies which findings are real, explains why they matter to your business, accounts for intentional choices and technical constraints, and gives your team a safe order of operations. Use the framework below before signing a proposal or implementing recommendations from an audit you have already received.

    Start with the decision the audit must unlock

    An audit cannot be valuable in the abstract. It has to help you make a decision: what to repair, what to improve, what to leave alone, and where to invest next.

    Write the audit’s job as one sentence before discussing tools or deliverables. For example:

    • Find out why commercially important pages are not being crawled, indexed, or discovered.
    • Determine whether a site migration introduced technical problems that are suppressing organic visibility.
    • Identify which content gaps prevent the site from satisfying the audience’s most important questions.
    • Separate genuine technical defects from warnings that do not affect search performance.
    • Assess whether search and AI visibility lead visitors toward a meaningful conversion.

    That sentence becomes your first acceptance criterion. If a recommendation does not help answer the stated question, it should not outrank work that does.

    The auditor also needs context that a crawler cannot collect on its own. At minimum, provide your business goals, priority audiences, important products or services, conversion paths, recent site changes, platform constraints, known technical debt, and any SEO decisions your team made intentionally. Without that context, an automated warning can easily be mistaken for a defect. Implementing the resulting recommendation may waste development time or reduce visibility instead of improving it.

    AI search does not make this discovery work optional. Many large language model experiences use retrieval and existing search results to find information with which to construct or check an answer. Your pages still need to be accessible, indexable, relevant, credible enough to surface, and useful once someone arrives. That makes an effective SEO audit part technical review, part content evaluation, and part business analysis. Calling the same crawler export a GEO audit does not add value.

    A valuable audit adds judgment to crawler data

    A specialist inspects a layered website structure with a magnifying lens while automated devices flag both harmless details and one broken connection.

    Crawlers are useful. They can expose URLs, response behavior, directives, internal linking patterns, metadata, and other machine-readable signals at a scale that manual browsing cannot match. The mistake is treating those observations as conclusions.

    This distinction matters because professional audits can cost from $2,500 to more than $20,000, depending in part on the size of the site and the engagement. Screaming Frog and Sitebulb cost a fraction of that amount, and trial access may be available. Run one of them against your site before buying an audit. You do not need to become a technical SEO; you only need enough familiarity to recognize when the final deliverable reproduces automated output without adding analysis.

    Part of the workLow-value outputUseful audit work
    DiscoveryRepeats crawler warnings and severity labelsCombines automated findings with manual investigation
    ContextAssumes every unusual configuration is wrongChecks business intent, technical debt, templates, and platform constraints
    EvidenceNames an issue without showing its scopeProvides affected URLs, patterns, or examples when they are needed
    ExplanationUses generic wording that could describe any siteExplains what is happening on your site, why it matters, and what may have caused it
    RecommendationIssues a universal command such as fix all or remove allTailors the action to your goals and identifies exceptions, dependencies, and risks
    PriorityCopies a tool’s high, medium, or low labelOrders work by likely business impact, effort, confidence, and potential downside
    HandoffEnds with a list of tasksClarifies ownership, implementation needs, and how the result will be checked

    Ask the auditor to walk you through one finding using that table. A convincing answer should distinguish what the tool detected from what manual review established. It should connect the issue to your audit objective, explain the proposed change, identify what could be affected, and state how your team will know whether the change worked.

    Generic explanations are another warning sign. Crawler documentation often explains why a category of warning may matter. Paying an expert makes sense when the expert can determine whether it matters here. A useful explanation names the relevant part of your site and shows the path from observation to consequence. If the same paragraph could be pasted into an audit for an unrelated company, it is probably documentation rather than analysis.

    Test every recommendation before it enters the backlog

    A technical team tests a website component in a transparent staging chamber before moving it toward a balanced production structure.

    A long audit can feel substantial while still being difficult to use. Do not judge it by page count, warning count, or the number of charts. Judge each recommendation by whether your team can verify, understand, execute, and measure it.

    Is the finding valid?

    Start with the evidence. Which URLs, page types, templates, queries, or journeys are affected? Is the pattern consistent? Did manual review confirm the crawler’s interpretation? Could the behavior be intentional?

    A tool can tell you that two pages look similar or that a directive blocks crawling. It cannot reliably decide whether the pages serve different audiences or whether the directive protects low-value areas from unnecessary crawling. The audit should resolve that ambiguity, not hide it beneath a severity label.

    Is the finding material?

    Connect the issue to a meaningful outcome. Does it prevent discovery or indexing? Does it weaken the page’s relevance for an important audience? Does it make a valuable page harder to navigate? Does it obstruct the conversion path?

    Not every technically imperfect detail deserves engineering time. An audit should make that trade-off visible. The useful question is not whether a warning exists; it is whether resolving that warning is a better use of resources than the competing work in your backlog.

    Is the recommendation executable and safe?

    Your implementation team should be able to identify the target, desired behavior, dependencies, owner, and exceptions. The auditor should provide examples where that falls within their expertise. Where it does not, they should still explain what needs to change and why, then identify the type of specialist required.

    Be especially careful with recommendations that affect server configuration, templates, directives, canonicals, redirects, or large groups of URLs. A blanket change can alter access to far more pages than the audit intended. Do not send ambiguous instructions straight into production. Have a qualified developer define the implementation, use your normal review and testing process, and preserve a rollback path.

    Can you verify the result?

    Define completion before implementation. A technical change may be complete when the intended URLs return the expected behavior and the crawler confirms no unintended pattern. A content change may require checking discovery, relevant search visibility, qualified visits, and the next step in the conversion journey.

    Separate implementation validation from performance evaluation. The first asks whether the change was deployed correctly. The second asks whether it improved the outcome that justified the work. Without both, your team can close tickets without learning whether the audit created value.

    For a fast review, label every recommendation Keep, Clarify, or Reject. Keep it when the evidence, consequence, action, risk, and validation plan are clear. Mark it Clarify when one of those elements is missing. Reject it when manual review disproves the finding, the action conflicts with an intentional decision, or the likely value does not justify the risk and effort. This turns an intimidating report into a governed backlog.

    Protect the engagement in the scope and contract

    You should know what will be delivered before the crawl begins. A strong scope does not merely promise an SEO audit. It describes the investigative work, the form of the evidence, the method of prioritization, and the handoff.

    • Manual review: Require investigation beyond crawler, analytics, or LLM output.
    • Site-specific reasoning: Require each material finding to explain its relevance to your site, audience, and business objective.
    • Evidence: Specify that affected URLs, templates, examples, or patterns will be included where needed.
    • Prioritization: Ask for impact, confidence, effort, dependencies, and implementation risk rather than tool-generated severity alone.
    • Handoff: Define whether the fee includes a walkthrough, questions from developers, implementation examples, or post-change validation.
    • Exclusions: Record what the auditor will diagnose but cannot implement, and who is expected to own that work.
    • Early notification: Require the auditor to tell you if manual investigation finds nothing material beyond automated output.

    A refund or scope-change provision can make the final point enforceable. One practical starting point is: The deliverable must include material findings from manual review and site-specific reasoning beyond automated crawler or LLM output. If the auditor determines that no such findings exist, the parties will agree to a revised scope or an appropriate partial refund before final delivery. A deliverable consisting solely of automated output triggers a full refund.

    That language carries commercial and legal consequences, so have your procurement team or counsel adapt it to the engagement and local requirements. The purpose is not to prohibit crawlers or AI assistance. Those tools can support the work. The provision makes clear that your fee purchases human discovery, interpretation, and prioritization rather than undisclosed automation.

    If the investigation finds that a full audit is unnecessary, do not force production of a padded report. Agree on the useful alternative before the work continues. Depending on the professional’s actual skills and your original goal, the remaining effort might be redirected toward content, development planning, conversion analysis, analytics, or another defined need. Document the revised deliverable and price so goodwill does not replace accountability.

    You can also evaluate the auditor’s fit before signing. The relevant expertise depends on the question you need answered. A crawl and indexation problem calls for strong technical and development literacy. A visibility problem may require content and audience analysis. An engagement expected to connect traffic with revenue needs analytics and conversion competence. No individual has to implement every discipline, but the proposal should state where the auditor’s expertise ends and how gaps will be handled.

    Key takeaways

    • An audit fee should buy judgment, prioritization, and a safer decision path, not merely crawler data.
    • Define the business question first; recommendations that do not help answer it should not dominate the backlog.
    • Run a crawler yourself before hiring so you can distinguish automated output from expert investigation.
    • Require manual review that accounts for your audience, goals, intentional decisions, technical debt, and conversion path.
    • Accept a recommendation only when its evidence, consequence, action, risk, ownership, and validation method are clear.
    • Put site-specific deliverables, early notification, scope revision, and refund terms in the agreement before work begins.
    • Evaluate AI-search readiness through the same fundamentals: accessible and indexable pages, relevant content, sufficient visibility, and a useful destination for the visitor.

    Open the proposal or completed audit now and highlight where it promises manual discovery, site-specific reasoning, prioritized action, implementation safeguards, and validation. Ask for a revision wherever one of those elements is absent. If recommendations have already reached your backlog, place the ambiguous ones on hold until someone can supply the missing evidence or context.

    The right audit leaves you with fewer uncertainties, not simply more tasks. Buy it when you need informed decisions that your tools and internal context cannot produce separately.

    References