Month: September 2026

  • Crawl Budget and Pagination: A Technical SEO Playbook

    Crawl Budget and Pagination: A Technical SEO Playbook

    If your products or archive posts disappear after page 1, reducing the number of crawlable URLs can feel like the obvious fix. It often is not. Pagination may be the only internal route that exposes deeper items, so removing it can turn crawl waste into orphaned content.

    The better objective is controlled discovery: give crawlers a finite, stable sequence through valuable content while preventing filters, sort orders, tracking parameters, and duplicate URL formats from multiplying that sequence. You protect crawl capacity by removing useless paths, not by hiding useful ones.

    First decide whether you have a crawl-budget problem

    Crawl budget is the time and computing resources a crawler is prepared to spend on your site. For Googlebot, it reflects both crawl capacity and crawl demand. Capacity concerns what your server can handle without becoming unstable. Demand concerns which URLs appear valuable or in need of another visit.

    Those two forces create different problems. Slow responses and server errors can cause a crawler to reduce its pace. Duplicate, low-value, or spam-like URL patterns can reduce the apparent value of fetching more URLs. A pagination fix cannot compensate for an unreliable server, and faster hosting cannot make an unlimited set of filter combinations worth crawling.

    Google’s criteria for active crawl-budget management are narrower than many teams assume. The clearest candidates are sites with more than 1 million unique pages, medium or large sites whose content changes frequently, and sites with many URLs marked “Discovered – currently not indexed” in Google Search Console.

    That does not mean a smaller site can skip the audit. Your catalog, article count, or CMS dashboard does not reveal the number of URLs a crawler can encounter. Facets, pagination, alternate parameter orders, languages, locations, search pages, and session values can turn one content set into many crawlable representations.

    • Inventory the exposed URLs. Crawl from the same public entry points available to search engines. Do not begin with a spreadsheet of products or posts.
    • Group URLs by pattern. Separate canonical content, pagination, filters, sort orders, internal search, tracking parameters, and malformed combinations.
    • Distinguish discovery from indexing. A URL that has never been fetched points to a different constraint than a fetched page that was judged unworthy of indexing.
    • Check server behavior. Look for timeouts, error responses, and URL patterns that require disproportionately expensive rendering or database work.

    There is no universal healthy number of crawls per day. A useful baseline is whether important new or changed URLs are discovered and revisited while requests to low-value patterns remain controlled. Measure that outcome on your own site instead of copying another domain’s crawl rate.

    Build pagination as discovery infrastructure
    A finite chain of page modules connects a category platform to multiple groups of content cards.

    Pagination divides one ordered content set into addressable pages. It adds URLs, but those URLs provide paths to products, posts, discussions, and other deeply nested content. That is productive crawl activity when each page exposes items that would otherwise be difficult to reach.

    A crawler should be able to begin at the first category or archive page, follow ordinary HTML links through the sequence, and reach every intended item. It should not need to click a JavaScript-only button, submit a form, maintain a session, or scroll until client-side code decides to load another batch.

    1. Choose one stable URL format. Formats such as ?page=2 or /page/2/ can work. Do not expose multiple formats for the same sequence.
    2. Use links with href destinations. Previous and next controls should be crawlable links. A short set of numbered links can provide additional routes into a long sequence.
    3. Link every listed item directly. Products and posts should have canonical destination URLs in the rendered listing, not destinations assembled only after an interaction.
    4. Give each page a distinct slice. Page 2 should not reproduce page 1 under a different URL. Stable ordering also reduces unnecessary repetition when crawlers revisit the sequence.
    5. Use a self-referencing canonical by default. If page 2 contains a distinct set of items, pointing its canonical to page 1 misrepresents that relationship. Consolidate only URLs that are genuinely equivalent.
    6. Keep page 1 canonicalized consistently. Link to one preferred first-page URL instead of alternating between the clean category URL and a duplicate such as ?page=1.
    7. Give infinite scroll a paginated fallback. Each batch should be available at a stable URL through crawlable links, even if human visitors receive a continuous visual experience.
    8. Stop at the real end of the sequence. Do not generate an endless run of empty page numbers. Remove internal links to pages beyond the last valid result and return an appropriate not-found response when an invalid page is requested.

    Do not automatically canonicalize every paginated URL to the first page or apply a blanket noindex directive. Overly aggressive canonicalization can prevent useful paginated URLs from appearing in search results, while removing their crawl value can make deeper items harder to find. A canonical signal expresses a preferred equivalent; it is not a general crawl-control switch.

    An XML sitemap helps crawlers discover canonical products, posts, and other destination pages, but it does not replace internal linking. Pagination remains an additional discovery route even when sitemaps are present. That route also shows how the content belongs within your site architecture.

    Do not spend engineering time adding rel=prev/next solely for Google. Google disclosed in March 2019 that it had stopped using that markup. There is little evidence that the tags now improve Google crawling. Stable URLs and ordinary internal links do the essential work.

    Control the URL multipliers surrounding pagination
    A central route carries unique page tiles forward while barriers stop surrounding branches from producing duplicates.

    Pagination is often blamed for an explosion created elsewhere. A page parameter moves through an ordered set. A facet creates a subset. A sort parameter rearranges a set. A tracking parameter records attribution. Treating all four as interchangeable leads to the wrong controls.

    Consider a category with filters for material, color, size, availability, and price. If every combination can be reordered, paginated, and expressed in several parameter orders, each useful category sequence gains a large number of low-value variants. Faceted navigation and uncontrolled URL creation can make a site far larger than its owners expect.

    URL classIts roleRecommended default
    Primary category or archiveMain landing page for a content setIndexable, internally prominent, and self-canonical
    Page 2 and deeperContinuation and item discoveryCrawlable, linked in sequence, and normally self-canonical
    Curated facet with standalone valueStable subset that serves a distinct needExpose deliberately, give it a consistent URL, and support it with useful content and links
    Sort or filter variant with no standalone valueAlternate presentation of an existing setKeep it out of routine crawl paths; consolidate only when it is truly equivalent
    Tracking or session URLMeasurement or temporary stateRemove it from internal links and point users and bots toward the clean destination
    Empty or out-of-range pageNo useful contentRemove links to it, omit it from sitemaps, and return an accurate response

    Turn that classification into generation rules in the CMS or commerce platform. Cleanup at the crawler level is less effective if templates continue manufacturing new variations.

    • Whitelist intentional facets. Link only to combinations that have a defined user and search purpose. A usable filter does not automatically need an indexable landing page.
    • Normalize parameter order and naming. The same state should not be reachable as several URLs merely because parameters were added in a different sequence or aliases were used.
    • Keep tracking values out of internal links. Campaign parameters belong at acquisition boundaries, not in persistent navigation, breadcrumbs, related-item modules, or pagination controls.
    • Prevent impossible combinations. Do not render links to empty intersections or filters that cannot change the result.
    • Limit pagination to valid result pages. Calculate the actual last page and avoid links to arbitrary higher values.
    • Consolidate exact duplicates. Redirect duplicate URL formats when the equivalence is permanent. Use canonical signals when an alternate representation must remain available, but do not label materially different subsets as duplicates.

    Be careful with robots.txt. Blocking a pattern may reduce requests, but it also prevents the crawler from seeing page-level canonical or noindex signals on those URLs. More importantly, a broad rule can remove the only route to products buried in a filtered or paginated set. First confirm that every valuable destination has another crawlable path. Then remove unwanted internal links and duplicate generation at the source. Use crawling restrictions only after you know what they will cut off.

    The same caution applies to noindex. Indexing eligibility and crawl access solve different problems. A noindex directive can keep a low-value result page out of the index, but the page still has to be crawled for that directive to be read. If the real problem is an unlimited URL generator, noindex alone leaves the generator running.

    Audit the path from category page to destination URL

    A useful audit must show both what your site exposes and what crawlers actually request. A crawler simulation, server logs, and Google Search Console answer different parts of that question. None is sufficient alone.

    1. Crawl from public entry points. Use Googlebot or Bingbot settings and begin at the homepage, major category pages, and XML sitemaps. Crawling as the search bot sees the site reveals a more realistic exposed URL count.
    2. Export every discovered URL with its pattern. Record status code, canonical target, indexability, referring page, crawl depth, and whether the URL appeared in a sitemap.
    3. Map representative page sequences. For each important template, follow page 1 to page 2, a middle page, the last page, and several item destinations. Verify that links exist in the rendered HTML and that each page returns the expected slice.
    4. Find canonical destinations with no internal links. A product listed in a sitemap but absent from navigation is still weakly connected. Determine which category or archive should provide its durable route.
    5. Analyze server logs by crawler and URL pattern. Separate requests for canonical destinations, pagination, facets, sorting, tracking parameters, errors, and redirects. This shows whether crawl activity supports discovery or loops through variants.
    6. Inspect “Discovered – currently not indexed” samples. Identify whether affected URLs are valuable destinations, duplicate parameters, or deep items whose only route is fragile pagination. The remedy depends on that classification.
    7. Check capacity signals. Compare bot requests with slow responses, timeouts, and server errors. Because poor server response can cause a crawler to reduce fetching speed and connections, reliability fixes may precede URL-policy changes.
    8. Repeat the crawl after deployment. Confirm that intended destinations remain reachable and that removed patterns are no longer linked. Do not judge success only by a smaller URL total.

    Prioritize by consequence. Server failures and unbounded URL generation can affect the entire site. Broken page-to-page links can isolate whole sections. Duplicate first-page formats are usually narrower. Metadata refinements on page 27 matter less than restoring the link that allows a crawler to reach page 27 at all.

    Track a compact set of outcome measures rather than one headline crawl count:

    • The share of intended canonical products or posts reached during a full crawl.
    • The number of valuable destination URLs with no crawlable internal link.
    • The share of verified bot requests spent on noncanonical parameter patterns, redirects, errors, and empty pages.
    • The recurrence of server errors or slow responses during crawler activity.
    • The time between a meaningful content change and the next verified bot request, using CMS timestamps and logs.
    • The trend and URL composition of “Discovered – currently not indexed” in Google Search Console.

    Segment AI crawler traffic separately from Googlebot and Bingbot. AI agents and bots add their own access and resource considerations, so their requests should not be folded into one generic bot total. The broadly compatible foundation is still the same: stable URLs, accessible HTML links, accurate responses, deliberate crawler rules, and a server that remains healthy under load.

    Key takeaways

    • Optimize crawl paths, not the smallest possible URL count. Useful pagination can increase URL volume while improving discovery.
    • Keep each valid paginated page stable and crawlable. Use direct HTML links, distinct result slices, one URL format, and self-referencing canonicals by default.
    • Treat facets as the main multiplier. Whitelist intentional combinations and stop templates from linking arbitrary filter, sort, tracking, and pagination permutations.
    • Do not use canonical, noindex, and robots.txt interchangeably. They address consolidation, indexing, and crawling respectively, and a careless rule can hide the only path to valuable content.
    • Prove the result with three views. A site crawl shows what can be reached, logs show what bots request, and Search Console shows how Google processes discovered URLs.

    Start with one high-value category rather than changing the whole site at once. Export its complete page chain, list every parameter variation the templates expose, and trace several deep items back to crawlable category links. If you cannot reach every intended item without entering arbitrary parameter states, fix that path first. Once the model works, apply the same URL rules to the remaining templates.

    References


  • How to Measure AI Answer Visibility and Google Rankings

    How to Measure AI Answer Visibility and Google Rankings

    Your rankings have held steady, but search traffic has fallen. Or your brand appears in an AI answer while the cited page barely registers in your rank tracker. Do not assume either pattern is a reporting error.

    You are looking at two different visibility systems. Organic rankings measure where a URL appears in the traditional results. AI visibility measures whether an answer appears, whether your brand or page is included, and where the citation sits inside that answer. You need to preserve that distinction until both systems reach the outcome layer: clicks, sessions, leads, sales, or another business action.

    Rankings and AI citations are separate search surfaces

    A single position column can no longer explain search performance. In one 2026 U.S. vendor dataset, an AI-generated answer appeared on 81.6% of queries and more than 94% of informational and commercial-research queries. The estimates come from the vendor’s client Search Console panel, referral-attribution data, and weekly SERP crawl, so treat them as directional benchmarks rather than universal click guarantees.

    The important distinction is structural, not numerical. A page can rank, be cited, do both, or do neither. Fewer than four in ten cited URLs in the same dataset also appeared in the organic top ten for the matching query. Citation visibility therefore cannot be inferred from organic rank, and organic rank cannot be inferred from a citation.

    Measure these questions independently:

    • Answer presence: Did the search surface generate an AI answer for this query or prompt?
    • Brand inclusion: Did the answer name your brand, product, author, research, or other tracked entity?
    • Linked citation: Did the answer link to your domain, and which URL received the link?
    • Citation placement: Was your page the first cited source, a later inline source, or hidden in an expanded source panel?
    • Organic position: Where did your URL rank, and was an AI answer present on that same result page?
    • Outcome: Did the exposure produce a click or a measurable action after the visit?

    Do not collapse a brand mention and a linked citation into one status. A mention can matter for brand representation, but it is not a referral opportunity. Likewise, a linked citation buried in an expanded panel is not equivalent to the first source attached to the opening claim.

    The click data makes that placement distinction consequential. The first citation in a Google AI answer received an estimated 5.2% CTR, compared with 3.1% for the second and 1.9% for the third. The first three citations captured 77.9% of AI-answer citation clicks. Counting citations without recording their position can make weak visibility look stronger than it is.

    Build one stable query set before choosing metrics

    You cannot compare AI visibility with Google rankings if the underlying questions keep changing. Start with a canonical measurement set: a controlled list of queries and prompts that represents the demand you actually care about.

    Give every tracked question a permanent query ID. Store the exact wording, but do not use wording as the identifier; you may later add a natural-language variant without wanting it to overwrite the original observation. Each query record should also contain:

    • Search intent, such as informational, commercial research, transactional, local, or navigational.
    • Journey stage and the business outcome the query can plausibly influence.
    • Brand or non-brand classification.
    • Topic cluster, product line, audience, and market.
    • Language, region, device, and interface where those variables affect the result.
    • The preferred page, entity, or domain you expect to be represented.
    • Available demand data, such as Search Console impressions or another consistently defined demand measure.

    Keep two collections. Your benchmark set stays stable so you can detect movement over time. Your discovery set can grow as customer questions, products, and search behavior change. Promote a discovery query into the benchmark set deliberately; otherwise, a rising citation rate may simply mean that you added easier prompts.

    Collect AI and organic observations under matching conditions wherever possible. For every run, log the timestamp, engine or surface, exact prompt, market, language, device or interface, and any account state that could affect personalization. Generative answers can vary between runs, so retain the observation count and raw result instead of overwriting yesterday’s answer with today’s.

    Do not combine every answer engine into a generic AI column. Google AI Overviews, Google AI Mode, and answers generated by other systems are different surfaces. A citation rate is meaningful only when its denominator identifies the surface, query set, location, and measurement period.

    Put five layers in the visibility dashboard

    Five translucent dashboard layers show abstract query tiles, ranking blocks, answer signals, citation nodes, and outcome paths connected vertically.

    A useful dashboard moves from opportunity to exposure to outcome. It should let you inspect each layer before showing an executive roll-up.

    LayerPrimary metricCalculationDecision it supports
    Answer opportunityAI answer appearance rateObservations with an AI answer / eligible observationsShows how often the surface creates a citation opportunity
    AI inclusionDomain citation rateObservations citing your domain / all tracked observationsMeasures total citation coverage across the query set
    Conditional AI visibilityCitation rate when an answer existsObservations citing your domain / observations with an AI answerSeparates your performance from changes in answer availability
    PlacementLead citation shareFirst-position citation appearances / all your citation appearancesReveals whether citation growth is occurring in prominent positions
    Organic visibilityRank distribution by SERP statePositions segmented by AI-answer present or absentExplains why the same rank can produce different click opportunity
    Business outcomeTraffic and conversion measuresClicks, sessions, qualified actions, and value under your existing definitionsShows whether visibility reaches a result the business values

    Report both versions of citation rate. The all-query rate answers, “How visible are we across this market?” The conditional rate answers, “When an AI answer offers a citation opportunity, how often do we earn one?” If the first falls while the second holds, the engine may be generating fewer answers for your query mix. If the second falls, your competitive visibility has weakened even if overall answer coverage is unchanged.

    Organic rank needs the same conditional treatment. In the 2026 benchmark, the first organic result earned an estimated 22.6% CTR without an AI answer but 3.6% when an AI answer was present. Its blended CTR was 7.1%. The blended value can help with portfolio forecasting, but it conceals the mechanism you need for page-level decisions.

    This is also why a first citation and a first organic position should remain separate rows. On a result page containing an AI answer, the estimated 5.2% CTR for the lead citation exceeded the 3.6% estimate for organic position one. Citation placement can therefore carry more click opportunity than the conventional rank your SEO dashboard treats as the main event.

    If you need a forecasting model, calculate expected click opportunity separately for each surface using the appropriate conditional CTR, then show the components beside the total. Do not present the result as measured traffic. It is a scenario based on an external benchmark, and it should be replaced or calibrated when your own impression and click data can support a better estimate.

    Avoid one opaque AI visibility score. A composite can hide whether you improved answer coverage, citation frequency, placement, or brand mentions. If leadership needs a single trend line, retain the component metrics directly beneath it and publish the formula, weights, denominator, and query-set version.

    Read the mismatch before changing the page

    A central web page follows two diverging paths, one through search result cards with few visitor signals and another into a bright answer panel with citation nodes, while an inspection lens highlights the mismatch.

    The most useful analysis starts where AI and organic performance disagree. Build a query-level view with four cohorts: cited and ranking, cited but not ranking, ranking but not cited, and neither cited nor ranking. Each cohort points to a different next action.

    Rank is stable, but clicks are falling

    First, compare result pages with and without an AI answer. Do not attribute the decline to a ranking problem until you have checked whether the page acquired a new answer surface, whether your organic result moved below that surface, and whether a competing domain owns the prominent citations.

    The wider click pool may also be shrinking. In the same 2026 U.S. dataset, 74.2% of searches ended without a click. Among discovery clicks, with navigational searches excluded, AI-answer citations accounted for 46.2% and traditional organic results for 33.8%. These figures should not be treated as universal, but they show why unchanged rankings can coexist with lower traffic.

    Your action is to add the SERP state to traffic analysis. Compare like with like: the same query cohort, intent, market, device class, and AI-answer condition. A before-and-after comparison that ignores a changed result-page layout will diagnose the wrong problem.

    Your page is cited but does not rank

    Treat this as genuine visibility, not a tracking anomaly. Record the cited URL, citation position, query intent, referral traffic where it is identifiable, and downstream actions. Then inspect whether the cited page is the page you would choose for that question. AI systems may surface a supporting resource while your commercial page remains the intended destination.

    Do not force the cited page to imitate a conventional results-page winner if it is already satisfying the answer need. Preserve the passage or evidence that appears to support the citation. Improve the path from that resource to the next relevant action, and monitor whether the citation survives the change.

    Your page ranks but is not cited

    Ranking proves that Google can retrieve the page for the query. It does not prove that an answer system will select the page as support for a specific claim. Review the actual answer and identify what it is trying to establish. Then compare that need with the passage on your page, not merely with the title tag or target keyword.

    A practical content test is to place the definitive, quotable answer within the first 150 words. State the answer directly, keep its qualification and support nearby, use descriptive headings, and name important entities consistently. This is a testable editing pattern, not a guarantee of selection.

    Review technical eligibility separately. Confirm that the preferred URL is indexable, canonicalized as intended, internally discoverable, and not blocked from the system you are measuring. Use structured data to clarify applicable entities and relationships, but do not count schema implementation as AI visibility. The citation itself remains the observed outcome.

    Citations are rising, but conversions are flat

    Check intent before editing the page. Informational prompts can generate substantial visibility without producing the same immediate action rate as high-intent commercial queries. Segment citations by journey stage and report their outcomes separately.

    Then inspect citation placement and landing-page fit. A later citation may add to your count while receiving little click opportunity. A highly visible citation may also send readers to a page with no clear path to the next useful step. Keep exposure, traffic, and conversion in separate columns so a weakness at one stage is not mislabeled as failure at another.

    Run a measurement cycle that leads to a decision

    Your reporting process should end with a page, query cohort, or technical condition to investigate. A practical cycle looks like this:

    1. Freeze the benchmark set. Version the query list and document every addition, removal, or classification change.
    2. Capture both surfaces. For each query observation, record AI-answer presence, brand mention, cited domain, cited URL, citation placement, organic URL, organic position, and relevant result-page features.
    3. Join on stable dimensions. Match observations through query ID, surface, market, device or interface, and collection period rather than through query text alone.
    4. Segment before averaging. Break results out by intent, brand status, topic, journey stage, AI-answer state, and citation position.
    5. Prioritize the mismatch. Start with valuable queries where the diagnosis is clear: ranking without citation, citation without the preferred page, or visibility without a usable next step.
    6. Make a scoped change. Change one interpretable content pattern, technical condition, or internal path within the selected page group. Annotate the deployment so later movement has context.
    7. Compare like with like. Evaluate the same query cohort and search conditions. Keep raw observations so you can distinguish a durable shift from answer-to-answer variation.
    8. Assign the next action. Every dashboard review should name the affected query cohort, the suspected mechanism, the owner, and the metric that would confirm or reject the diagnosis.

    Your tooling should conform to these definitions, not define them accidentally. If Profound is already in your stack, its refreshed Answer Engine Insights includes streamlined views and customizable tables that can support this kind of analysis. Keep your canonical query IDs, metric formulas, raw exports, and change log under your control so a dashboard redesign does not break continuity.

    Key takeaways

    • Measure AI-answer presence, brand mentions, linked citations, citation placement, organic rank, and business outcomes as distinct fields.
    • Calculate citation visibility across all tracked queries and conditionally across queries that generated an AI answer.
    • Always segment organic rank by whether an AI answer was present; the same position can carry radically different click opportunity.
    • Track citation position, not citation count alone. The first sources receive most of the available citation clicks in the 2026 benchmark.
    • Use a stable benchmark query set for trends and a separate discovery set for new opportunities.
    • Let mismatches determine the action: rank without citation, citation without rank, visibility without clicks, or clicks without conversion each requires a different response.

    Start with one stable query set and one row per observation. Add the AI-answer state and citation fields beside your existing ranking data before buying a new score or redesigning content. Once you can see which surface changed, you can make a targeted decision instead of asking an organic position to explain an entire search journey.

    References


  • People-First Content for AI Search: A Practical Framework

    People-First Content for AI Search: A Practical Framework

    You need content that can appear in AI-generated answers without turning your site into a warehouse of robotic definitions. The difficult part is not choosing between people and machines. It is making the useful answer obvious to a machine while preserving the context, judgment, and next step that make a person trust it.

    The right standard is simple: a reader should be able to make a better decision after visiting the page, even if no search engine existed. AI optimization then becomes a matter of structure, clarity, and accurate representation – not a separate style of writing.

    Start with the reader’s decision, not a target phrase

    A keyword can tell you what someone typed. It does not tell you what they need to decide, what they already understand, or what would make the answer usable. If your brief stops at a phrase such as people-first content, AI SEO, or conversational search optimization, the draft will usually become a broad explanation with no practical destination.

    Write a reader-task sentence before you outline the page:

    After reading this page, a specific reader should be able to make a specific decision or complete a specific task without making a predictable mistake.

    For this topic, that sentence might be: After reading, a content lead should be able to revise an AI-assisted draft so it answers the searcher’s question clearly, retains expert judgment, and can be quoted without losing an important qualification.

    That sentence gives you an editorial boundary. A paragraph belongs only if it helps the reader reach the stated outcome. Background that does not change a decision can be shortened, linked elsewhere, or removed.

    Build the brief around the reader’s unresolved questions

    A useful brief should answer these points before drafting begins:

    • Reader: Who is acting on this information? Name a role or situation, not a demographic label.
    • Immediate question: What do they need answered before they can continue?
    • Decision: What choice will the answer help them make?
    • Constraint: What condition could change the recommendation?
    • Failure mode: What plausible but wrong interpretation should the page prevent?
    • Next action: What should the reader inspect, change, compare, or document after reading?

    This framing also prevents keyword coverage from becoming topic sprawl. You do not need a paragraph for every variation of a query. Group variations by the decision behind them, answer that decision once, and use the language a reader would naturally recognize.

    The enduring core of search copywriting is still clear content written for people. AI can assist with analysis, brainstorming, and feedback, but the writer still supplies the voice, brand knowledge, and connection to the reader. Treating those contributions as optional is how efficient production turns into interchangeable content.

    Build answer units that remain useful outside the page

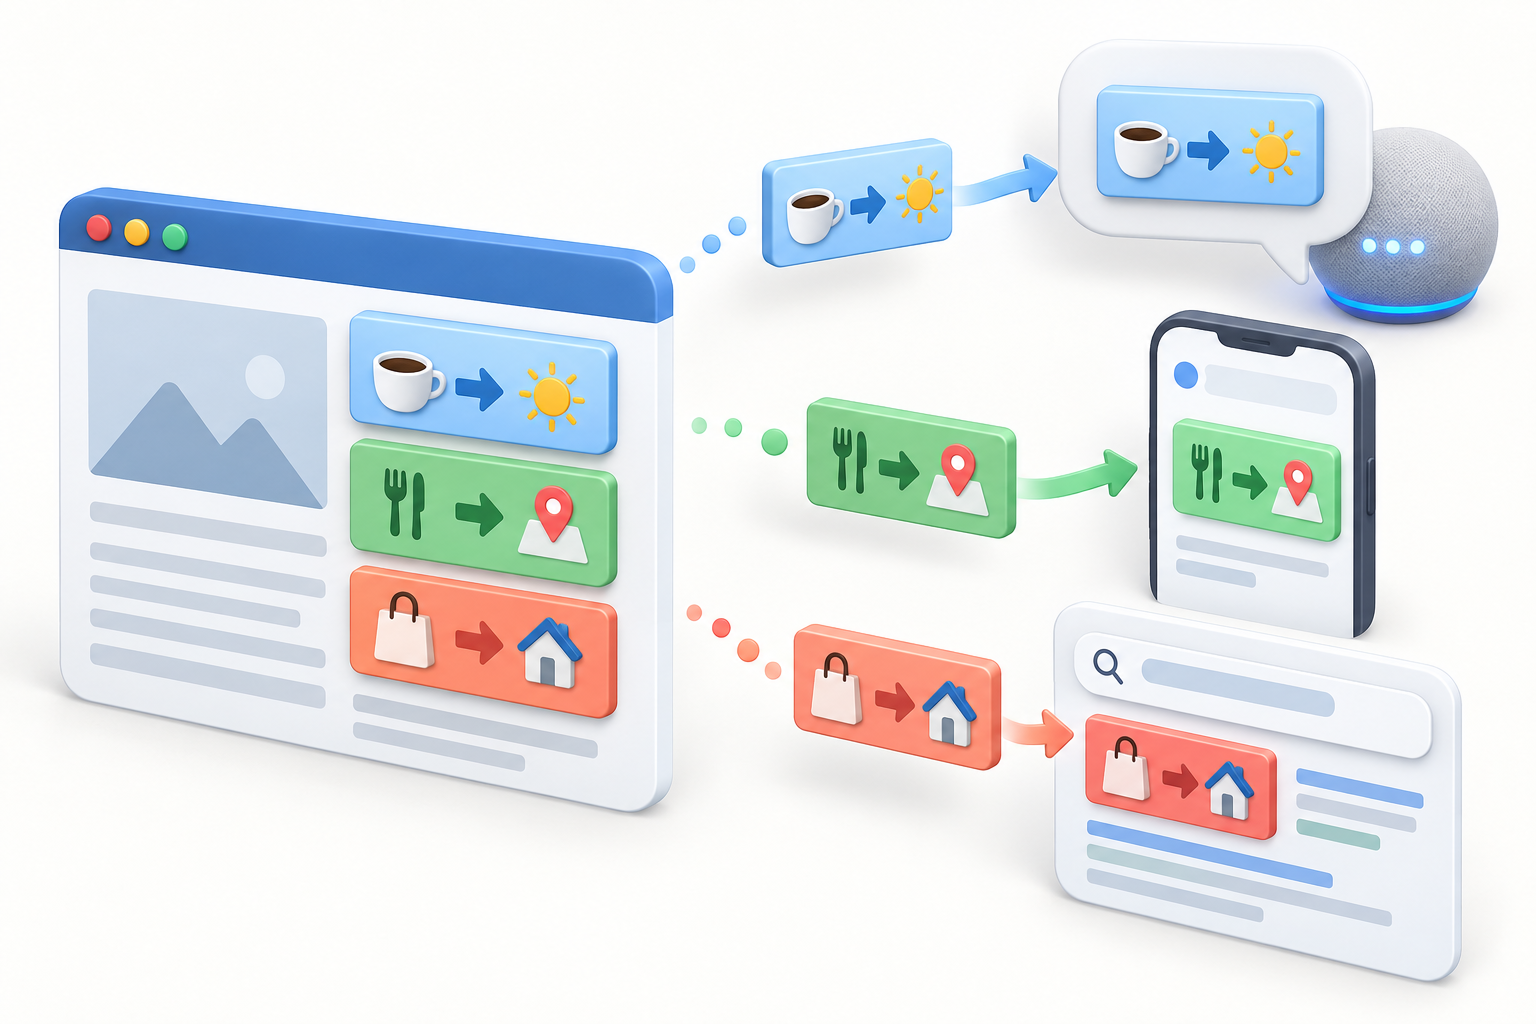
    Modular information tiles move from a central page into several different digital interface frames while retaining their complete visual structure.

    People normally read with context: they see the title, scan nearby headings, and understand how one paragraph relates to the next. An AI search product may retrieve or quote a smaller passage. If the definition is in one section, the qualification is much later, and the recommended action appears somewhere else, the extracted answer can be incomplete even when the full page is accurate.

    The practical response is to write in self-contained, citable chunks. This does not mean reducing the page to disconnected snippets. It means giving each section a complete local purpose while arranging those sections into a coherent journey.

    Use a repeatable anatomy for important sections

    For every question the page must resolve, use this sequence:

    1. Name the question in the heading. A heading such as When human review is required carries more meaning than Considerations or Best practices.
    2. Give the direct answer immediately. Do not make the reader cross an origin story, trend summary, or sales preamble to find your position.
    3. State the boundary. Explain when the answer applies, when it does not, and which missing fact could change it.
    4. Support the answer. Add an example, process detail, definition, documented fact, or clearly attributed observation.
    5. Close with an action. Tell the reader what to inspect or do with the answer.

    Consider a section answering whether an AI-generated draft can be published without review. A vague version says that the choice depends on business needs and that quality is important. A useful version says that an AI draft should be treated as unverified input; a qualified reviewer must check factual claims, scope, examples, links, and promises before publication. It then distinguishes a wording edit from a claim that requires subject-matter validation and gives the editor a review checklist.

    The second version works better for both audiences. A person can act on it. An answer system can quote it without having to infer what quality means.

    Keep the qualification beside the claim

    A claim and its limiting condition belong in the same passage. Do not write AI-generated content is safe to publish in one paragraph and place only after expert review several screens later. The first sentence is not merely incomplete; it can become false when separated from the later condition.

    Use nouns when a pronoun could become ambiguous outside the section. Replace This improves it with Descriptive headings make the answer easier to scan and retrieve. Define specialist terms where they first affect the decision. Repeat an essential qualifier when necessary; elegant variation matters less than accurate extraction.

    Lists should also carry meaning in isolation. Each item needs a parallel structure and enough context to remain understandable when quoted. A list containing Accuracy, Voice, and Check it is not a usable framework. Factual verification, brand-voice review, and final human approval are distinct, actionable checks.

    Do not mistake an FAQ farm for answer engineering

    Breaking every keyword variation into a separate question creates repetition and weakens the reading experience. Put foundational questions in the main narrative where the answer changes what comes next. Reserve an FAQ for genuine follow-up questions that can be answered independently and do not deserve full sections.

    No heading pattern guarantees that ChatGPT, Perplexity, an AI Overview, or another answer system will cite a page. The controllable goal is narrower: make the passage accurate, self-contained, easy to interpret, and worth selecting. That is useful even when the reader arrives through a conventional result, a shared link, or an internal knowledge base.

    Put human judgment where it changes the answer

    People-first does not mean conversational filler, personal anecdotes added for texture, or repeatedly saying you understand the reader. It means using knowledge of the reader to improve the substance of the answer.

    The human contribution is most valuable at decision points. That is where a competent writer or subject-matter expert can distinguish similar options, notice a dangerous assumption, explain a tradeoff, or say that the available evidence does not support a confident conclusion.

    Look for these forms of human value during editing:

    • Judgment: State which option you recommend and identify the criteria behind that recommendation.
    • Boundaries: Name the situation in which the usual answer stops applying.
    • Operational detail: Show what the work involves, who needs to review it, and what must be true before the next step.
    • Original evidence: Use relevant analytics, customer questions, interviews, product documentation, or internal observations only when you genuinely have them and are authorized to publish them.
    • Reader context: Explain how the answer changes for the role or situation addressed by the page.
    • Accountability: Separate verified facts from editorial recommendations and make ownership of the final claim clear.

    A useful test is to remove your company name from the draft and ask whether any competent competitor could publish it unchanged. If the answer is yes, the page probably contains category knowledge but little distinct judgment. Add what your qualified team can responsibly contribute: a decision rule, a better explanation of the tradeoff, a real workflow, or an evidence-backed correction to a common misunderstanding.

    Do not manufacture distinctiveness. Invented customer stories, fabricated tests, unnamed experts, and synthetic quotations make a page look specific while making it less trustworthy. If you lack original evidence, say what is known, label your recommendation as a recommendation, and narrow the claim to what you can support.

    Separate fact, interpretation, and recommendation

    Many weak pages blur these categories. A descriptive fact becomes a rule, an internal preference becomes an industry standard, or a plausible explanation becomes a proven cause. Mark the difference in the language itself:

    • Fact: State what can be checked and link the words that carry the claim to supporting material.
    • Interpretation: Explain what the fact may mean and preserve any uncertainty.
    • Recommendation: Say what you advise the reader to do and identify the criterion behind that advice.

    This separation improves more than credibility. It gives an answer system fewer opportunities to present your opinion as a settled fact or strip a recommendation from the condition that justifies it.

    Use AI for leverage, then run a human-led audit

    An editor reviews content cards at a desk using a magnifying glass, balance scale, compass, and human figure as visual quality checks.

    AI is well suited to expanding the editor’s field of view. It can organize questions, compare wording, identify repetition, test whether a passage depends on missing context, and point to claims that need verification. It should not be asked to supply experience, evidence, or authority that your organization does not possess.

    A disciplined workflow keeps that boundary visible:

    1. Write the human brief. Define the reader, decision, constraint, failure mode, and intended next action before generating prose.
    2. Assemble approved material. Gather the facts, product details, internal expertise, links, and examples the page is allowed to use.
    3. Use AI to map the problem. Ask it to group reader questions by underlying intent, expose overlaps, and identify missing objections. Treat the output as suggestions, not demand data.
    4. Create the answer structure. Give each major decision a descriptive heading and plan the direct answer, condition, support, and action beneath it.
    5. Draft with ownership. A writer may use AI to explore phrasing or alternatives, but a responsible human chooses the claim, preserves the brand’s meaning, and rejects unsupported additions.
    6. Audit every claim. Mark each substantive statement as verified fact, established background, interpretation, or recommendation. Investigate anything that does not fit.
    7. Approve the final page. The person signing off should be qualified to judge both factual accuracy and whether the advice is appropriate for the intended reader.

    Useful AI review requests are narrow. Ask it to list factual statements that lack visible support, identify pronouns with unclear antecedents, find conclusions that appear before their necessary conditions, or show where two sections answer the same question. Tell it not to rewrite while it diagnoses. You want an inspection report before you accept new prose.

    Be especially cautious when the model makes the copy smoother by removing qualifications. Words such as may, generally, only when, and for this audience can carry the factual boundary of the claim. Concision is not an improvement if it changes what the sentence promises.

    Run a people pass

    Read the page as someone trying to act, not as the person who commissioned it. Check whether:

    • The opening identifies the reader’s real problem and offers a useful direction without a long preamble.
    • Each major question receives a direct answer before supporting detail.
    • The recommendation names the condition under which it applies.
    • Examples clarify the decision instead of merely decorating the prose.
    • Technical terms are explained when understanding them affects the action.
    • The reader can tell which statements are facts and which are your editorial judgment.
    • The close gives the reader a realistic next move.

    Run an extraction pass

    Then inspect each important section as if it had been removed from the rest of the page. Check whether:

    • The heading names the question or decision accurately.
    • The opening sentence answers that heading rather than introducing the general topic again.
    • Essential subjects are named instead of hidden behind vague pronouns.
    • Definitions, limitations, and version or audience constraints sit beside the claims they govern.
    • List items remain meaningful when read without the preceding paragraph.
    • Link text describes the supported claim instead of saying click here or learn more.
    • A quoted passage would represent your actual position without requiring a distant correction.

    Check the publishing layer without expecting it to rescue the copy

    The title, visible headings, metadata, internal links, and structured data should describe the same subject and purpose. If you use schema, its claims must match content a visitor can actually see. Markup can clarify the meaning of a sound page; it cannot supply missing expertise, fix an evasive answer, or make an unsupported claim reliable.

    After publication, keep a small query log for the decisions that matter to your business. Record the question tested, the search or answer surface, the page surfaced or cited, the wording represented, and the action you want a qualified visitor to take. Use that record to find content gaps and misrepresentation. Do not treat a citation by itself as proof that the page served the reader or the business.

    Key takeaways

    • Define the reader’s decision before selecting headings or generating copy.
    • Give each important section a direct answer, its limiting condition, meaningful support, and a next action.
    • Keep qualifications beside the claims they govern so an extracted passage remains accurate.
    • Add human value through judgment, boundaries, operational detail, and genuine evidence – never invented experience.
    • Use AI to organize, question, and inspect the work while a qualified human owns every published claim.
    • Audit the page twice: once for the person completing a task and once for the system that may retrieve a passage.

    Start with one page that influences a real decision. Rewrite its opening around the reader’s task, turn its major sections into complete answer units, and challenge every unsupported sentence. When the page becomes easier for a person to trust and use, you have also created a stronger candidate for accurate representation in AI search.

    References


  • AI Search Visibility and Attribution: A Practical Framework

    AI Search Visibility and Attribution: A Practical Framework

    You have screenshots showing that AI systems mention your brand, a small line of AI referrals in GA4, and no defensible answer when someone asks whether either one affected pipeline. The problem isn’t necessarily weak performance. It’s that AI exposure, website behavior, and revenue happen in different systems, often without a trackable click connecting them.

    You need a measurement chain, not one magic metric: what an AI says, which information appears to influence the answer, what the buyer does next, and which outcomes reach your CRM. Once those stages are separated, you can report what you observed without inflating what you proved.

    Key takeaways

    • AI visibility and AI attribution answer different questions. Measure them separately before connecting them.
    • Referral traffic from AI assistants is an observable minimum, not a complete count of AI-influenced visits or buyers.
    • Start with one customer segment and a fixed panel of about 20 prompts across awareness, consideration, and action.
    • Organize attribution into three layers: directly recorded outcomes, influenced outcomes, and the future visibility moat you are building.
    • Report changes as observed, attributed, associated, or still unknown. That vocabulary prevents correlation from turning into an unsupported revenue claim.

    Why conventional attribution misses the AI search journey

    Traditional search reporting assumes a recognizable sequence: a person searches, clicks a result, lands on a tagged page, and converts in the same measurable journey. AI search can break that sequence at every step.

    A person may get a complete answer without leaving the interface. They may see your brand recommended, remember its name, and search for it later. They may copy your domain rather than use the citation link. Mobile and desktop applications can also remove referral information, while switching devices can sever the connection entirely. As a result, AI-generated visits recorded in analytics represent an observable floor, not the full population of people exposed to your brand.

    This creates two measurement problems that must not be collapsed:

    • Visibility: Does the AI include your brand, describe it correctly, and cite information that supports the answer?
    • Attribution: Is there credible evidence that this exposure contributed to a visit, lead, opportunity, sale, or another business outcome?

    A visibility score cannot prove revenue. A referral report cannot reveal all visibility. Treating either one as a complete measure produces false precision.

    Direct traffic doesn’t solve the problem. In analytics, “direct” is a bucket for visits without usable referral information; it isn’t a synonym for people who typed your domain, and it certainly isn’t an AI channel. A rise in direct visits may be consistent with AI influence, but it needs supporting evidence before you describe it that way.

    The practical fix is to preserve several kinds of evidence with different confidence levels. A ChatGPT referral that becomes a closed-won opportunity is strong but incomplete evidence. A simultaneous rise in AI mentions, branded searches, and direct demo requests is useful contextual evidence, but it doesn’t establish that AI caused every increase. Your framework should make that distinction visible.

    Establish a repeatable AI visibility baseline first

    An analyst reviews a symmetrical wall of abstract AI response cards generated from repeated query tokens and marked with recurring source indicators.

    You can’t attribute a change until you know what changed. Begin with a controlled visibility baseline for one customer segment, not a broad list of every question anybody might ask.

    Build a fixed prompt panel around one buyer

    Choose a segment with a distinct problem, evaluation process, and purchase decision. “Mid-market security teams replacing a legacy platform” is measurable. “Anyone interested in cybersecurity” isn’t.

    Create approximately 20 prompts covering three stages of the journey:

    • Awareness: Questions about the problem, available approaches, common mistakes, and signs that help may be needed.
    • Consideration: Questions about leading providers, alternatives, pricing expectations, selection criteria, locations, and suitability for a specific type of customer.
    • Action: Questions about your brand, its specialization, reviews, fit, and comparisons with named competitors.

    Run every prompt in a fresh conversation. Use a private window or logged-out session where possible, because accumulated chat context and account personalization can change the answer. Test the same wording in AI Mode, Gemini, and ChatGPT, then add another platform only when your audience actually uses it. The goal is a stable panel, not the largest possible prompt inventory.

    For every run, record the date, platform, exact prompt, whether your brand appeared, which competitors appeared, which pages or domains were cited, and whether the description of your brand was materially correct. This fresh-session testing method and three-stage prompt structure gives you a reproducible diagnostic rather than a collection of favorable screenshots.

    Turn the prompt log into diagnostic metrics

    Calculate metrics that reveal different failure modes:

    • Mention rate: Prompts that mention your brand divided by eligible prompts tested. Break this out by journey stage; an overall average can hide strong awareness visibility and weak consideration visibility.
    • Competitive inclusion rate: Consideration prompts in which your brand appears alongside the companies buyers are likely to evaluate.
    • Owned citation rate: Eligible prompts whose answers cite one of your pages. If a platform doesn’t expose citations for a run, record “not available” rather than converting missing data into a zero.
    • Perception accuracy: Brand mentions with a materially accurate description divided by all brand mentions. Keep an error log for incorrect claims about your offering, audience, pricing, location, or integrations.
    • Citation-domain coverage: The domains repeatedly supporting answers in your category, marked by whether your brand is represented on them.

    Keep the denominator beside every percentage. “Mention rate increased to 40%” means little unless the reader knows whether that represents eight mentions among 20 fixed prompts or an opaque score assembled from a changing prompt set.

    A share-of-voice number is useful for detecting movement, but it functions as a temperature reading rather than a diagnosis. If visibility is weak, the remedy could be inaccurate brand information, absent third-party coverage, poor indexing, a mismatch between your offering and the prompt, or a competitor that has stronger evidence in the cited ecosystem. Publishing more pages before identifying the gap may simply create more content that AI systems continue to ignore.

    Map where the answers are being shaped

    Add an influence map beside the prompt panel. Put journey stages in the rows and four discovery behaviors in the columns: streaming, scrolling, searching, and shopping. In each cell, record two things: the channels or cited domains that influence the buyer at that moment, and whether your brand is present there.

    This map tells you whether you have an on-site content problem or a broader representation problem. If the same review site, directory, video channel, discussion community, or competitor comparison keeps shaping answers and you are absent from it, another blog post on your own domain may not close the gap. If AI repeatedly misstates a product fact that your site never explains clearly, the correction belongs in your canonical product or service information first.

    Connect visibility to outcomes with three attribution layers

    Three transparent layers show abstract AI responses above website activity and customer pipeline stages, connected by solid, dotted, and faint glowing threads.

    A three-layer model of direct attribution, influenced attribution, and future moat lets you preserve weak signals without pretending they all carry the same evidentiary weight.

    LayerEvidence to trackWhat it can supportWhat it cannot prove alone
    Direct attributionKnown AI referrals, self-reported discovery, CRM source details, opportunities, closed revenueA recorded AI interaction was part of the measurable journeyThe complete amount of AI-influenced demand
    Influenced attributionBranded search, direct-source visits and demos, sales-cycle length, conversion rate, competitive win rateBusiness behavior changed in a way consistent with increased AI exposureThat AI caused every observed change
    Future moatMention coverage, perception accuracy, citation presence, influence-map coverage, proprietary and task-completing assetsYour brand is becoming easier for search and AI systems to understand and recommendGuaranteed traffic, pipeline, or future revenue

    Layer 1: Capture directly attributable outcomes

    Start with the records you can defend individually. Create an AI search channel or source-detail field in your CRM for leads carrying a recognizable AI referrer. Preserve the original source data rather than overwriting it, because you may need to audit the classification later.

    Add “AI assistant or AI search” to the “How did you hear about us?” field on high-intent forms. Follow it with optional free text asking which tool the buyer used and what they were researching. If changing the form would hurt completion, have sales representatives ask the same question during qualification and save the response in a structured field.

    At minimum, retain these fields:

    • Detected referral source and landing page.
    • Self-reported discovery source and the buyer’s free-text explanation.
    • Lead, opportunity, and close dates.
    • Opportunity stage, value, and closed-won revenue.
    • Product, segment, geography, and campaign context.

    Revenue-linked records are your most defensible outcome evidence even when the count is small. Report them as recorded AI-attributed outcomes, while stating that lost referrals, no-click interactions, and cross-device journeys make the count incomplete.

    Layer 2: Test for influenced demand

    Next, examine behavior that could occur after an untracked AI interaction. The useful signals include branded organic search, direct-source visits and demo requests, lead-to-opportunity conversion, sales-cycle length, and win rate against competitors appearing in your prompt panel.

    The mechanism matters. A buyer can ask an assistant for a shortlist, remember your name, and search Google several days later. They can also resolve pricing, integration, or fit objections before reaching your sales team. In those cases, the visible outcome may be a branded query or a better-prepared buyer rather than an AI referral. Branded search lift, direct demand, sales-cycle changes, and competitive win rates are therefore relevant influenced-attribution measures.

    They are not automatically AI outcomes. Compare the same segment, product, geography, and time window. Annotate major brand campaigns, paid-media changes, launches, pricing changes, seasonality, public relations activity, and website migrations that could move the same metrics. Use the median sales-cycle duration as well as the average so a few unusually large or slow opportunities don’t dominate the result.

    Your claim should match the evidence: “Branded demand and direct demo submissions rose during the same period as consideration-stage visibility” is defensible. “AI generated the entire increase” isn’t, unless individual records establish that connection.

    Layer 3: Measure the future moat without monetizing it

    The third layer is a strategic scorecard, not delayed revenue attribution. It tracks whether your brand is becoming easier to retrieve, understand, verify, and distinguish.

    Monitor accurate category inclusion, coverage across high-value prompt clusters, representation in frequently cited domains, and correction of recurring perception errors. Track whether your site supplies assets that a generic answer cannot reproduce: proprietary data, useful tools, original workflows, product capabilities, and pages that help a visitor complete a task. Strong topical focus and a clear description of the business also make your entity easier to interpret.

    Keep the SEO foundation visible here. Google’s generative answers depend on information in Google’s index, so crawlability, indexing, internal linking, and clear canonical pages remain prerequisites. Where Search Console provides a generative AI view, use it to identify which existing pages are being surfaced. Treat that information as visibility evidence, not as a complete cross-platform attribution report.

    Build one dashboard that preserves confidence and context

    Your dashboard should show a chain of evidence rather than compress everything into a proprietary score. Keep four panels on one page.

    • Visibility panel: Mention rate, competitive inclusion, owned citation rate, perception accuracy, and results by journey stage.
    • Influence panel: Frequently cited domains, competitor co-mentions, missing cells in the streaming-scrolling-searching-shopping map, and recurring factual errors.
    • Behavior panel: Branded organic demand, direct-source visits, direct demo submissions, high-intent page visits, and conversion rates for the same segment.
    • Business panel: AI-referred and self-reported leads, opportunities, pipeline value, closed revenue, sales-cycle duration, and competitive win rate.

    Display the current value, baseline value, absolute change, denominator, reporting window, and data owner for every metric. Add an annotation lane for interventions and confounders. Without dates for page updates, technical changes, campaigns, and product announcements, a trend line cannot tell you what to investigate.

    Do not add visibility, visits, and revenue into a single composite “AI performance” score. They use different units, denominators, and levels of confidence. A composite can improve even while the business outcome deteriorates, and nobody can diagnose the reason without unpacking it.

    Use the pattern to choose the next action

    • Low mentions and irrelevant citations: Check whether your offering actually fits the prompt, then investigate the domains and competitors shaping the answer before producing more content.
    • Brand mentioned but described incorrectly: Strengthen the canonical pages that define the disputed facts, remove contradictory messaging, and address influential third-party profiles where possible.
    • Accurate mentions but weak consideration visibility: Examine comparison, pricing, use-case, audience-fit, and selection-criteria gaps. Buyers need evidence that helps them choose, not another broad category definition.
    • Visibility rises but behavior does not: Verify that the prompt panel represents commercially relevant demand. Visibility for informational questions outside your market may never become pipeline.
    • Behavior rises without movement in your visibility panel: Your prompt set may be incomplete, another campaign may be responsible, or AI may be influencing questions you aren’t testing. Investigate before assigning credit.
    • Direct AI revenue appears while reported traffic remains small: Preserve the revenue records and describe analytics traffic as incomplete. Do not scale the small tracked count into an invented total.

    Run a 30-day operating cycle

    1. Days 1-3: Select one customer segment, define the buying problem, and inventory the analytics and CRM fields you already have.
    2. Days 4-7: Run the fixed prompt panel in fresh sessions, record citations and competitors, and score perception accuracy.
    3. Week 2: Build the influence map and identify one commercially relevant gap. Choose a gap that can be changed and measured, such as a missing comparison, unclear product fact, absent use-case page, or influential profile that misrepresents the brand.
    4. Week 3: Make one coherent intervention. Record the affected prompts, pages, channels, launch date, and expected leading signal.
    5. Week 4: Rerun the fixed panel under the same protocol. Review early visibility movement, but keep behavioral and revenue windows open long enough for your normal buying cycle.

    One month is enough to install the measurement discipline and inspect leading signals. It may not be enough to judge pipeline or revenue, especially in a long B2B sales cycle. Match the evaluation window to the outcome: model visibility can move before branded demand, and branded demand can move before opportunities close.

    Report the evidence without turning correlation into causation

    A credible AI search report should separate four types of statements:

    • Observed: The brand appeared, a page was cited, a competitor was included, or a tracked metric changed.
    • Attributed: A preserved referral or self-reported response connects an AI interaction to a known lead, opportunity, or customer.
    • Associated: Visibility and a business indicator moved in a consistent sequence for the same segment, but the individual journeys cannot be connected.
    • Unknown: The journey may have involved AI, but available data cannot establish whether or how.

    Use a consistent reporting sentence: “Among [N] fixed prompts for [segment], brand mentions changed from [A] to [B] after [intervention]. During [business window], [branded demand or pipeline metric] changed from [C] to [D]. [Known confounders] were also present, so we classify the relationship as [observed, attributed, or associated]. The next test is [action].”

    This format answers the questions decision-makers actually have: What moved? How reliable is the connection? What else could explain it? What will you do next?

    Start with one segment and 20 prompts rather than an enterprise-wide score. Within 30 days, you can have a repeatable visibility baseline, CRM fields that retain direct evidence, an influence map that exposes the real gaps, and one controlled improvement under measurement. That won’t make the dark funnel fully visible. It will give you a framework strong enough to guide the next investment without pretending uncertainty has disappeared.

    References


  • How to Fill Google Ads Conversion Gaps With Offline Data

    How to Fill Google Ads Conversion Gaps With Offline Data

    Your website tag records the purchase at checkout, but your backend may hold the version of the transaction you actually want Google Ads to learn from: more complete customer information and the amount after an upsell, refund, or final order adjustment.

    If both records carry the same transaction ID, Google Ads can use the backend record to improve the tagged conversion instead of forcing you to accept whatever was available in the browser. The implementation is less about uploading more data than establishing a reliable join between two versions of the same business event.

    What offline gap filling changes – and what it does not

    Google Ads’ multi-source conversions beta can match an offline record to a website conversion through its transaction ID. Once Google finds that match, the offline record can supply user-provided data that the tag did not capture, including an email address, phone number, or address.

    The same mechanism can correct the conversion value. If the tag sent an initial amount and your backend later has the finalized order total, upsell, or refund adjustment, the uploaded amount replaces the value attached to the matching tagged transaction.

    Think of this as a database join, not a second copy of the sale. One conversion action can receive information from the website tag and the offline system. That distinction helps you avoid three common implementation mistakes:

    • Do not assume every offline row enriches a tagged event. The gap-filling path depends on Google finding the corresponding transaction ID. An unmatched record cannot fill fields on a tagged conversion it has not been connected to.
    • Do not expect the offline row to overwrite every tag field. The supplemental data is primarily used for missing user-provided information and conversion-value updates.
    • Do not use an uploaded GCLID as a repair mechanism for a matched transaction. Google ignores GCLIDs from the supplemental record in this scenario, so they do not replace the information associated with the tag event.

    Multi-source reporting may also contain additional conversions from the offline source. Treat those separately in your validation plan. “Conversions added” and “tagged conversions supplemented” are different outcomes, even if they appear under the same conversion action.

    The capability is documented as a beta. Confirm that it is available in your account before making it a dependency of your measurement design.

    Make the transaction ID your dependable join key

    Two digital transaction records with identical geometric identifiers lock together through a central connector.

    The transaction ID is the bridge between the browser event and the backend record. If the two systems generate unrelated identifiers, drop the value, or transform it differently, the rest of the upload can be accurate and still fail to improve the original conversion.

    A clean data path should work in this order:

    1. Your site completes the conversion and assigns its transaction ID.
    2. The Google tag sends the conversion with that ID and the data available at that moment.
    3. Your order system, CRM, or other backend retains the identical ID while customer details and the final value are confirmed.
    4. Google Ads Data Manager or the Data Manager API sends the supplemental record.
    5. Google uses the shared ID to associate the offline information with the tagged transaction.

    Rules for a durable transaction ID

    • Generate the ID once and persist it across the browser, order database, CRM, and upload pipeline.
    • Use an ID that represents the actual conversion rather than creating a separate Google Ads-only identifier later.
    • Keep it unique to the business event. Reusing an ID across orders makes reconciliation ambiguous.
    • Do not embed an email address, phone number, or other personal data in the ID.
    • Retain the ID in your integration logs so you can trace a reported mismatch back to the tag payload and backend record.
    • Avoid trimming, reformatting, or replacing the ID in only one part of the pipeline.

    Before connecting an offline source, take a sample of real conversions and trace each transaction ID from the site event to the backend export. If you cannot follow the same value across that entire path, fix the ID lineage first. Adding more customer fields will not repair an uncertain join.

    User-provided data also deserves a separate governance check. Confirm that the information is accurate, that your organization is permitted to send it, and that access to the upload pipeline is appropriately controlled. Matching performance does not justify sending data your business should not use.

    Build the offline feed around information that arrives later

    Your offline feed should have a narrow job: supplement the browser event with authoritative information that became available elsewhere. It should not become an undifferentiated export of every field in your CRM.

    The following controls belong in the internal feed design. Some are upload fields; others are operational metadata that helps you decide whether a record is ready to send.

    Data itemPreferred internal originControl to apply
    Transaction IDThe system that created or persisted the conversionConfirm that it is identical to the ID sent by the website tag.
    Email, phone number, or addressThe approved backend customer or order recordSend only accurate, permitted information intended to fill a field the tag missed.
    Conversion valueThe authoritative order, billing, or CRM recordPublish the amount your business treats as final for that update, including applicable upsell or refund changes.
    Record statusYour order or revenue workflowUse it internally to prevent provisional records from being presented as finalized value corrections.
    Ready and upload timestampsYour integration logMeasure the delay between backend availability and delivery to Google Ads.

    Conversion value requires the tightest control because the uploaded value replaces the tag’s value for the matching transaction. It is not merely attached as an alternative value. A stale amount in the offline feed can therefore replace a better amount captured on the site.

    Define which backend system is authoritative and what “final” means in your business process. Then make that rule part of the integration. Do not label a provisional amount as final simply to make the upload run sooner.

    At the same time, delivery speed matters. Google recommends sending the supplemental data within 24 hours for the best Enhanced Conversions matching and bidding performance. Track two intervals separately: how long the backend takes to make the record ready and how long your integration takes to upload it. That separation tells you whether the delay belongs to the business process or the data pipeline.

    The 24-hour window is an optimization recommendation, not a promise that every record will match. If your integration routinely misses it, shorten unnecessary batch, approval, and transfer delays. Preserve data accuracy while doing so; faster uploads of unreliable values are not an improvement.

    Use the 14-day trial to validate the pipeline, not bidding

    An analyst monitors purchase records moving through matching and validation checkpoints in a controlled data pipeline.

    You can connect the additional source through Google Ads Data Manager or the Data Manager API. A newly connected source then enters a 14-day trial period.

    The trial creates an important split between what you can see and what Google uses. Additional conversions may appear in reporting and diagnostics during those 14 days, but they are not used for bidding. Conversion-value updates are also disabled during the trial.

    That means a reporting change during the trial is not evidence that Smart Bidding has learned from the new source. It is also not a valid test of whether finalized offline values are replacing the original tag values. Changing campaign targets or budgets solely because trial-period reporting moved could make you react to information the bidding system is not yet using.

    Structure the rollout in three phases:

    1. Before connection: preserve a baseline of tag counts, values, transaction-ID coverage, upload latency, and relevant campaign reporting. Save enough internal detail to explain differences later.
    2. During the 14-day trial: confirm that records arrive, inspect diagnostics, investigate unmatched or duplicated internal IDs, and verify that the correct conversion action and backend source are involved. Do not score bidding or value correction while those functions are inactive.
    3. After the trial: verify that the source has left trial status, check value behavior against the authoritative backend output, and annotate the activation date in your performance analysis.

    A practical validation checklist

    • Identity coverage: for sampled transaction IDs, confirm that a field missing from the tag is present in the approved backend record.
    • ID overlap: compare the set of IDs sent by the tag with the set prepared for upload. Investigate unexpected gaps before looking for a Google Ads explanation.
    • Uniqueness: ensure your internal export does not present unrelated transactions under the same ID.
    • Value authority: compare the outbound value with the finalized amount in the designated system of record before it reaches Google.
    • Delivery latency: count the records sent inside and outside the recommended 24-hour window. Monitor the trend instead of relying on an average that can hide delayed batches.
    • Trial separation: label trial-period reporting so nobody mistakes visible additional conversions for bidding inputs or completed value corrections.
    • Post-trial monitoring: watch diagnostics and reporting after activation rather than assuming that a successful upload guarantees a successful match.

    When numbers differ, debug in the order the data travels: tag execution, transaction-ID persistence, backend record readiness, export construction, upload delivery, matching, and finally reporting. Starting with campaign performance makes a pipeline problem much harder to isolate.

    Key takeaways

    • Google Ads offline gap filling uses the transaction ID to connect backend information with the corresponding website-tag conversion.
    • A matched upload can add missing user-provided data such as an email address, phone number, or address.
    • An uploaded conversion value replaces the original value on the matching tagged transaction, so only an authoritative system should publish value corrections.
    • An uploaded GCLID is ignored for matched transactions and should not be treated as a way to overwrite the tag’s attribution information.
    • Send supplemental data within 24 hours when possible to support Enhanced Conversions matching and bidding performance.
    • During a new source’s 14-day trial, additional conversions may be visible but are not used for bidding, while value updates remain disabled.

    Start with one conversion action whose transaction IDs are already stable. Trace a sample from the tag to the backend, name the system that owns the final value, and define your trial acceptance checks before connecting the source. If that lineage is clean, the offline feed can close specific measurement gaps without turning your conversion setup into two competing versions of the truth.

    References


  • Patient Acquisition Cost Benchmarks for Medical Practices

    Patient Acquisition Cost Benchmarks for Medical Practices

    Your patient acquisition cost can be mathematically correct and still give you the wrong answer. A single number cannot tell you whether marketing is efficient until you know which costs it includes, what qualifies as an acquired patient, and whether you are comparing the same specialty and channel.

    Use the benchmarks below as diagnostic reference points, not spending targets. The practical goal is to find out whether your result reflects normal acquisition economics, a measurement problem, a weak channel, or a breakdown between the first inquiry and the completed appointment.

    Key takeaways

    2026 PAC benchmarks by specialty and marketing channel

    Three miniature healthcare settings are reached by different patient pathways with varying amounts of unmarked spending tokens.

    The 2021-2026 benchmark dataset uses anonymized results from medical practices. Specialty sample sizes range from three reporting practices for rheumatology to 27 for cosmetic and plastic surgery, so the apparent precision of the dollar figures should not be confused with equal statistical strength.

    Practice typeAverage patient acquisition costPractices reporting
    Allergy / Immunology$4214
    Cardiology$5899
    Cosmetic / Plastic Surgery$61727
    Dentistry$37911
    Dermatology$44818
    Endocrinology$4024
    Family Practice$27217
    General Practice$20119
    Geriatrics$41111
    Med Spa$2938
    Naturopathic$3876
    Neurology$59213
    Obstetrics & Gynecology$3385
    Orthodontics$5338
    Pediatrics$16011
    Podiatry$2216
    Psychiatry$2935
    Rheumatology$3543
    Urgent Care$29121

    The channel view answers a different question. It shows averages blended across all practice types, not specialty-by-channel benchmarks.

    Marketing channelAverage patient acquisition cost
    Organic Search (SEO)$218
    Paid Search (PPC)$346
    Organic Social$297
    Paid Social$299
    Direct Mail$245
    Radio Advertising$391
    TV Advertising$469
    Video / YouTube Marketing$358
    Outdoor Advertising$420

    No channel-level sample sizes accompany those averages. The figures also do not isolate geography, service mix, payer mix, patient value, attribution model, or the costs included in PAC. That does not make them useless. It means they are best used to flag a result for investigation rather than to certify that a campaign is efficient.

    Choose the right comparison before judging your result

    Start with the specialty benchmark when you are evaluating the practice’s overall acquisition cost. Start with the channel benchmark when you are investigating how a particular marketing method performs. Do not combine the two tables to manufacture a number that is not present.

    For example, dermatology averages $448 by specialty while paid search averages $346 across practice types. Averaging those figures would not produce a dermatology PPC benchmark. One describes a specialty across acquisition activity; the other describes a channel across specialties.

    If your practice has materially different service lines, calculate PAC for each one. A blended practice number can hide an expensive elective service behind a lower-cost primary-care line, or make a valuable specialty program look inefficient because its patients cost more to acquire. If your specialty is absent from the benchmark set, label any substitute as a proxy and rely more heavily on your own historical cohorts.

    What you seeWhat to test before actingUseful next action
    Your PAC is below the relevant averageCosts may be missing, returning patients may be counted as new, or one patient may be credited to multiple channels.Reconcile marketing expenses with finance and patient records before increasing the budget.
    Your PAC is near the relevant averageThe comparison may be reasonable, but average performance can still be unprofitable for your patient economics.Compare PAC with contribution margin and available clinical capacity.
    Your PAC is above the relevant averageThe cause may be expensive traffic, poor inquiry quality, booking friction, no-shows, limited capacity, or an attribution error.Segment the funnel before cutting the channel. Fix the component that is raising the cost.

    A benchmark becomes more useful when it changes the question from “Are we above average?” to “Which assumption would have to be true for this comparison to be fair?” That question exposes measurement gaps before they turn into budget decisions.

    Calculate a like-for-like patient acquisition cost

    Patient acquisition cost = eligible acquisition cost divided by newly acquired patients.

    The formula is simple. The definitions are where most comparisons break. Write those definitions beside the metric in your dashboard so that a future analyst, agency, or practice manager cannot silently change them.

    PAC layerCosts in the numeratorPatient denominatorBest use
    Media-only PACDirect advertising spendNew patients attributed to that advertisingOptimizing bids, audiences, and campaigns inside a paid channel
    Fully loaded channel PACMedia, agency or vendor fees, labor, creative, content, technology, and channel-specific trackingNew patients attributed to the channel under one consistent ruleComparing the economic performance of channels
    Fully loaded practice PACAll eligible patient-acquisition costsAll newly acquired patientsFinancial planning and evaluating the complete acquisition program

    Do not compare a media-only internal number with an external figure that may include labor and vendors. If the benchmark’s cost scope is not defined well enough to match yours, preserve your more useful internal definition and treat the external number as directional.

    Fix the patient milestone

    A lead, appointment request, booked appointment, attended consultation, and completed first encounter are not interchangeable. Choose the event that means the practice has genuinely acquired a patient and apply it everywhere. A completed first encounter is generally more stable than a booking because cancellations and no-shows have already been resolved, but your operational model may require another milestone.

    • Count each new patient once at the chosen milestone.
    • Exclude returning patients unless you intentionally maintain a separate reactivation metric.
    • Resolve duplicate records across locations, phone systems, forms, and scheduling tools.
    • Document how free consultations, canceled appointments, no-shows, and later conversions are handled.
    • Keep the definition unchanged when comparing periods or channels.

    Use one attribution rule without erasing the patient journey

    A patient may first encounter the practice in an organic result or AI-generated answer, later click a branded ad, and finally call. Giving every touchpoint full credit inflates the denominator for each channel. Giving only the last click credit can hide the activity that created demand.

    Keep both discovery and trackable conversion information when your systems allow it. Record how the patient says they first found the practice, preserve any available campaign or referral data, and assign one primary channel under a documented rule for PAC reporting. An intake field with fixed options and free text can capture search engines, AI assistants, social platforms, referrals, and offline media when click-based attribution is incomplete.

    Align costs and acquired patients to a consistent measurement basis as well. This matters especially for organic search, content, structured data, and other programs whose work and patient response may not occur in the same reporting period. A mismatched numerator and denominator can create a dramatic PAC change even when underlying performance has not changed.

    Turn the benchmark into a budget and operations decision

    Patients move from outreach through reception and scheduling to an examination room, with one person paused at a scheduling bottleneck.

    Set a ceiling from patient economics

    The market average is not your allowable PAC. Your ceiling comes from the value a new patient contributes to the practice and the cash-flow period the practice can support.

    Expected contribution before acquisition = expected collected revenue over the chosen value horizon minus the variable costs of delivering care.

    Expected contribution after acquisition = expected contribution before acquisition minus PAC.

    Use collected revenue rather than sticker price, and keep the value horizon consistent. Comparing one channel with first-visit revenue and another with the value of an entire treatment episode will favor the second channel by design. If your estimates affect a material spending commitment, have the practice’s financial lead validate the revenue, cost, capacity, and cash-flow assumptions before the budget changes.

    A below-benchmark PAC can still destroy value when contribution margin is lower. An above-benchmark PAC can still be workable when the patient relationship contributes enough margin and the practice has capacity. The external average tells you what deserves scrutiny; your economics decide what is affordable.

    Separate traffic cost from conversion failure

    When qualified inquiries are measured consistently, the funnel can be expressed as PAC = cost per qualified inquiry divided by the inquiry-to-acquired-patient conversion rate. This decomposition tells you whether the acquisition problem begins before or after the inquiry.

    • If inquiry costs rise while conversion is stable, inspect targeting, competition, creative, search intent, and channel mix.
    • If inquiry costs are stable while PAC rises, inspect call handling, response delays, service fit, scheduling friction, appointment availability, cancellations, and no-shows.
    • If both appear stable while PAC changes, audit missing expenses, duplicate patient records, channel reassignment, and changes to the acquired-patient definition.
    • If demand exceeds usable appointment capacity, increasing marketing can raise cost without creating additional completed care. Resolve the capacity constraint before adding spend.

    This distinction protects you from cutting an effective campaign because the practice could not answer, qualify, or schedule the demand it generated. It also prevents an operational problem from being disguised as an advertising problem.

    Budget against marginal PAC, not only the historical average

    Your average PAC describes the patients already acquired. A budget decision concerns the additional patients expected from additional spending. Track the incremental cost and incremental acquired patients when you expand a channel; the next segment of demand may not perform like the existing average.

    Planning budget = desired new-patient volume multiplied by planning PAC. Use your own normalized PAC as the base, the relevant external benchmark as a reasonableness check, and your contribution-based ceiling as the financial constraint. Then test whether the required patient volume fits actual appointment capacity.

    Organic search carries the lowest reported channel average at $218, but that does not make it an automatic budget winner. Include content production, technical SEO, structured data, analytics, optimization labor, and outside support in the organic numerator when those costs are part of patient acquisition. Apply the same discipline to every channel. A television average of $469 is not automatically unacceptable if the channel produces patients whose contribution and incrementality support that cost.

    Before approving the next budget change, write the PAC definition at the top of the forecast, rebuild the latest complete measurement period with that scope, choose the appropriate specialty and channel references, and add your contribution-margin ceiling and capacity limit. You will then have more than a benchmark: you will have a decision rule your marketing, operations, and finance teams can use consistently.

    References


  • Search Marketing Performance Intelligence: A Decision System

    Search Marketing Performance Intelligence: A Decision System

    Your CPA jumps, organic clicks soften, and visibility across AI search looks uneven. Your dashboard confirms that something moved. It does not tell you whether demand changed, a competitor became more aggressive, your ads lost relevance, or the conversion path broke.

    You need more than a cleaner report. You need a repeatable way to connect business outcomes, funnel metrics, account changes, market behavior, and search-surface coverage – then turn that evidence into one defensible action. That is the practical job of search marketing performance intelligence.

    Replace the reporting question with a decision question

    Reporting asks what happened. Performance intelligence asks what you should change, why that change is justified, and what evidence would prove it worked.

    That difference sounds small, but it changes how you build the entire analysis. If you start with all available data, you tend to produce a dashboard full of metrics. If you start with a pending decision, you can select only the evidence needed to make that decision safely.

    Write a one-sentence decision question before opening your reporting tools. It should name the affected scope, the observed change, and the choice in front of you. For example: Should we restore non-brand bids, revise the ads, or repair the landing-page experience after conversion volume fell in these campaigns?

    A useful decision question has five parts:

    • Scope: The channel, market, campaign, topic, device, audience, or landing page affected.
    • Outcome: The business metric that moved, such as conversions, revenue, CPA, return on ad spend, or average order value.
    • Timing: When the movement began and which comparison period is genuinely comparable.
    • Competing explanations: At least one internal cause and one external cause worth testing.
    • Decision: The bid, budget, targeting, creative, content, landing-page, or measurement change you might make.

    This prevents a familiar failure: treating a falling line as a diagnosis. A traffic decline only becomes actionable after you identify where it began, what drove it, and what decision follows. Until then, it is an alert.

    Separate outcome metrics from diagnostic metrics as well. Revenue and qualified conversions are outcomes. Impressions, click-through rate, CPC, Quality Score, ranking coverage, and AI Overview presence can help explain those outcomes, but none is a business result by itself. A Quality Score decline, for example, may surface before a later increase in click costs becomes obvious. Treat it as an early clue to investigate, not a target to optimize in isolation.

    Trace every performance shift through five evidence layers

    Five translucent evidence layers show business outcomes, a conversion funnel, campaign controls, market activity, and search surfaces connected by one glowing signal.

    A strong diagnosis moves from the business result toward its possible causes. Do not begin with the most interesting chart or the most accessible data set. Work through the same evidence layers in the same order so that a plausible story does not outrun the facts.

    1. Confirm the business outcome. Compare equivalent conversion definitions and comparable periods. Determine whether the change sits in conversions, revenue, CPA, return on ad spend, or average order value. Check whether it is account-wide or concentrated in a particular campaign, topic, product, market, device, or landing page.
    2. Decompose the funnel. Inspect impressions, click-through rate, clicks, average CPC, conversion rate, and average order value. The arithmetic keeps the analysis honest: clicks are driven by impressions and click-through rate; conversions are driven by clicks and conversion rate; for commerce, revenue is driven by orders and average order value. Find the first meaningful component that changed.
    3. Inspect internal account state. Review budgets, bids, targeting, search terms, negatives, ads, Quality Scores, landing pages, tracking, and account change history. Match each change to the affected segment and date. A coincidental account edit is not automatically the cause, but it is a testable lead.
    4. Add market context. Look at competitor participation, competitor messaging, auction conditions, generic demand, and relevant market events. Joining account behavior with market behavior helps distinguish an internal failure from a broader shift. Timing can narrow the explanation, although it does not prove causation on its own.
    5. Check visibility across surfaces. For the same high-value topics, inspect paid coverage, organic rankings, and AI Overview presence. A paid keyword gap has a different priority when you already hold strong organic or AI visibility than when competitors occupy every visible surface.

    Keep the comparison grain consistent. If the outcome is measured weekly by market and campaign, do not explain it with a monthly global competitor trend. Align time zones, currencies, conversion definitions, attribution settings, and segment boundaries before drawing a conclusion. Otherwise, the data join can manufacture a shift that did not occur.

    The table below is a diagnostic starting point, not a set of automatic conclusions. Each pattern should produce a hypothesis and a verification step.

    Observed patternLeading hypothesesNext check or action
    Impressions fall while downstream rates remain steadyDemand, eligibility, budget coverage, or competitive participation changedSplit brand from non-brand, inspect budget and targeting status, then compare market demand and competitor presence
    Impressions hold but click-through rate fallsThe message no longer fits the query, a competitor has a stronger proposition, or the results page changedCompare creative by placement and query theme; inspect competitor messaging and AI Overview presence
    CPC rises while Quality Scores weakenAd or landing-page relevance may be deteriorating; competitive pressure may also have increasedLocate the affected campaigns, ads, queries, and pages before changing bids; add auction and competitor context
    Clicks remain steady but conversion rate fallsTraffic mix, landing-page behavior, offer fit, site function, or conversion measurement changedSegment by search term and landing page, verify tracking, and test the on-site path before buying more traffic
    Conversion rate holds but average order value fallsProduct, offer, customer, or order mix changedFind the affected commercial segment before altering acquisition settings
    Search terms spend without recorded conversionsThe traffic may be irrelevant, but conversion lag, low volume, or measurement gaps may be hiding valueValidate the window, tracking, query intent, and assisted value; add negatives only where exclusion is justified
    Generic market demand exists but non-brand coverage is thinBudget may be concentrated on branded demand while competitors capture discovery trafficRank the gaps by commercial relevance and plausible return, then account for existing organic and AI visibility

    This sequence also prevents channel teams from optimizing against each other. A PPC team can see a missing keyword and increase bids while the SEO team already owns the result. An SEO team can celebrate stable rankings while an AI Overview changes the visible path to the site. Performance intelligence treats those as parts of one demand landscape rather than separate scorecards.

    Make every visualization perform a diagnostic job

    A visual earns its place when it answers a defined question, eliminates an explanation, or supports a decision. A graph that merely makes a metric easier to look at is still reporting.

    Build your diagnostic sequence as a short evidence story:

    1. Establish the baseline. Use a trend view to show when the outcome changed. Split the line by the segment that matters, such as brand versus non-brand, market, campaign, topic, or landing page.
    2. Expose the mechanism. Decompose the movement into impressions, click-through rate, CPC, conversion rate, and average order value. Show which component moved first and where the change is concentrated.
    3. Test the cause. Add account changes, competitor participation, auction information, campaign launches, promotions, and relevant external events. Use them to compare explanations, not to decorate the timeline.
    4. Mark the intervention. Annotate the date and scope of the bid, budget, creative, targeting, content, landing-page, or measurement change.
    5. Show the resolution. Extend the same view beyond the intervention. State whether the expected signal appeared and whether the business outcome followed.

    This setup-conflict-intervention-resolution structure is useful because one chart rarely provides enough context to explain both a performance change and its cause. The sequence lets each view carry one part of the reasoning.

    Choose the format according to the question:

    • Line chart: Locate when a change began and whether an intervention coincided with recovery. Segment the line rather than relying on an account-wide average.
    • Metric heatmap: Find combinations that behave unexpectedly, such as strong placement paired with weak click-through rate. This is useful for creative triage because the contrast becomes visible immediately.
    • Calendar heatmap: Expose day- or week-level patterns around seasonality, launches, promotions, and operational events. Use it to generate a timing hypothesis, then verify the mechanism in the underlying metrics.
    • Word cloud: Scan dominant query or content themes, overlap, gaps, and possible cannibalization. Frequency is not commercial value, so validate promising themes against conversions, revenue, or another business outcome.
    • Exception table: Hand the team a finite work queue. Include only the affected entity, evidence, recommended action, expected effect, risk, and owner.

    Write chart titles as questions or findings. Traffic Trend forces the reader to interpret the graph. Non-brand traffic fell after eligible impressions declined tells them what to inspect. If the evidence cannot support that stronger title, use the question you are testing: Did competitor participation coincide with the CPC increase?

    Every visual should end with a short decision caption: what changed, the leading explanation, which alternatives were checked, what action is proposed, and what evidence is still missing. If no action is justified, name the next investigation and its owner. Uncertainty is acceptable; an ownerless ambiguity is not.

    Turn the diagnosis into a controlled action queue

    Tangled performance signals pass through a diagnostic prism and become an orderly queue of controlled actions, with one action highlighted.

    The deliverable is not the dashboard. It is a prioritized queue of changes that someone can review, execute, and measure.

    Each queue item should contain:

    • Problem: The business outcome and affected scope.
    • Evidence: The internal metric, account state, market context, and cross-surface coverage supporting the diagnosis.
    • Proposed action: The exact campaign, query set, creative, budget, landing page, or content area to change.
    • Expected signal: The first diagnostic metric that should respond and the business outcome expected to follow.
    • Confidence and gap: How strong the explanation is and what remains unknown.
    • Risk and rollback: What valuable traffic, data, or revenue the change could disrupt and how to reverse it.
    • Ownership: Who approves, who implements, and when the result will be reviewed.

    Prioritize with judgment rather than a single opaque score. Start with financial exposure, confidence in the diagnosis, urgency, reversibility, and learning value. A broken landing page or measurement failure deserves attention before a speculative keyword expansion. A reversible creative test can move ahead with less evidence than a large budget reallocation. A negative-keyword upload needs careful review because an incorrect exclusion can remove useful reach across Search, Shopping, or Performance Max.

    A practical order of work is to stop compounding loss, repair leading indicators, reallocate proven resources, and then test growth gaps. That usually means checking broken or outdated pages, tracking failures, and clearly irrelevant spend first; then addressing weak relevance or creative; then moving budget toward supported opportunities; and only then expanding into uncovered demand.

    Automation should follow the same progression. Begin with observation, move to evidence-linked recommendations, then generate an editable implementation file, and require approval before changes are applied. Limited automatic execution should come only after you have reliable inputs, explicit guardrails, monitoring, and a tested rollback path.

    Adthena describes a commercial version of this approach that joins advertiser account data with its market view and returns actions such as negative terms, copy changes, and budget moves. Its vendor-provided examples currently produce editable reports or upload-ready files, and the product is identified as Alpha. Treat that as a useful model for workflow design, not independent proof that every generated recommendation is correct.

    Before approving any machine-generated action, confirm that it exposes the evidence it used, the campaigns affected, the expected result, and the reversal method. Also verify account scope, time zone, currency, attribution settings, conversion definitions, and data freshness. A recommendation that cannot show its inputs is not performance intelligence. It is an instruction without an audit trail.

    Keep market context in the same evidentiary role. A competitor change that aligns with your decline is a serious lead, but timing alone does not prove the competitor caused it. Compare affected and unaffected segments, inspect the internal funnel, and use a reversible intervention where possible. The goal is not a confident story. It is a decision that can survive review.

    Key takeaways

    • Start with a pending decision, not a collection of metrics.
    • Trace the shift from business outcome to funnel mechanism, internal account state, market context, and cross-surface visibility.
    • Treat charts as diagnostic steps: establish the baseline, expose the mechanism, test causes, mark the intervention, and verify the result.
    • Turn every supported finding into an owned action with an expected signal, risk, rollback method, and review point.
    • Use paid, organic, and AI visibility together when evaluating gaps so one channel does not buy coverage another already provides.
    • Keep automated recommendations editable and auditable until their inputs, guardrails, and rollback process have earned greater authority.

    At your next performance review, choose one material shift and run it through the five evidence layers. Publish only the top supported action, its risk, and the signal you will remeasure. If the meeting ends with an observation but no decision or owned evidence gap, you still have a report – not performance intelligence.

    References


  • Title Tag SEO: A Practical Guide to Relevance and Clicks

    Title Tag SEO: A Practical Guide to Relevance and Clicks

    Your page can hold its position in search and still become easier to ignore. The usual problem is not a missing keyword. It is a title tag that names the topic without showing why this result is the right one for the searcher.

    A strong title tag makes relevance obvious, sets an accurate expectation, and gives the listing a reason to be chosen. Here is how to write one, evaluate it in context, and diagnose it when rankings and clicks tell different stories.

    Make relevance unmistakable before you try to be clever

    The title tag is the HTML <title> element that summarizes a page. Google may use it as the clickable title link in search results, but that wording is not guaranteed to appear unchanged. It is also different from the H1: the title tag describes the page in search and other external contexts, while the H1 introduces the content on the page itself.

    Before writing the title, answer three questions:

    • What phrase or entity would the intended searcher recognize immediately?
    • What specific task, answer, product, or outcome does the page provide?
    • What truthful detail distinguishes this page from neighboring results?

    A dependable working structure is: recognizable topic + specific value + useful qualifier. That might produce Title Tag SEO: A Practical Writing Guide, Invoice Approval Software for Small Teams, or Family Red T-Shirts: XS-XXL Under $25. The structure is not a template you must fill mechanically. It is a check that each word has a job.

    Include the keyword phrase or entity you want the page associated with, using the language your audience actually uses. Exact wording can be especially helpful when someone is new to a subject and does not know its synonyms, product nicknames, or category jargon. Search systems may understand related entities, but that does not remove the need for clear user-facing terminology.

    Consider meal replacement shakes and mass gainers. The products may overlap, but the phrases imply different needs. A page can be technically relevant to both while its title speaks convincingly to neither. Choose the primary audience for that page, use that audience’s term in the title, and handle secondary language naturally in the body.

    Do not treat the keyword as a guarantee of ranking. Its more immediate value is recognition: the searcher should not have to infer whether the page addresses the query. We would usually place the subject near the beginning when it reads naturally, not because the first position is a magic signal, but because the page should identify itself before secondary wording consumes the visible space.

    This clarity also matters beyond the conventional results page. AI systems can use search results to ground answers and select material to recommend. A title tag is not a command that makes an AI system cite you, but weakening organic discoverability can also reduce your opportunity to be found through AI-assisted search.

    Keep the important meaning inside the visible title

    Essential page and search symbols remain visible inside a title-shaped frame while decorative shapes are cropped at the right edge.

    A practical character-based recommendation is to keep a title tag at roughly 55 characters or fewer, including spaces. Treat that as a planning constraint, not a universal law. Search results are rendered by width, so different words consume different amounts of visible space. A content management system may also append a brand name or separator that was not present in your draft.

    Long titles create two presentation risks: the visible title may end with an ellipsis, or Google may choose different wording. Neither outcome automatically means the page cannot rank. It means you have surrendered some control over the message a searcher sees.

    Use this editing sequence:

    1. Write a natural draft that states the page’s subject and benefit.
    2. Move the essential topic and qualifier into the opening portion.
    3. Delete repeated category words, empty adjectives, and phrases already implied by the topic.
    4. Count the complete title, including spaces, separators, dates, and any brand text added by the site.
    5. Read the shortened version as a promise. If it becomes vague or misleading, restore the words needed for accuracy.
    6. Compare it with the live results for the target query before publishing.

    For example, Complete Guide to Title Tag SEO: Everything You Need to Know spends much of its space announcing comprehensiveness. Title Tag SEO: A Practical Writing Guide identifies the subject and the utility with less ceremony. The second title is not better merely because it is shorter. It is better if the page genuinely provides a practical writing process.

    Do not add filler to reach the available limit. When surrounding listings use nearly all of their space, a shorter, specific title can become visually distinct. Length is therefore an upper constraint and a competitive choice, not a target you need to hit.

    Stand out with evidence, not decoration

    You cannot judge differentiation inside a spreadsheet. Search the primary query and inspect the titles around yours. You are looking for repeated structures: the same adjective, the same year, the same question, the same long chain of benefits, or the same punctuation-heavy formula.

    Then work through this SERP review:

    1. List the dominant title patterns on the results page.
    2. Mark the words every result uses because the query requires them.
    3. Separate those necessary terms from language that merely copies the category.
    4. Choose one concrete distinction the page can prove.
    5. Rewrite the title so the shared topic remains recognizable and the distinction is visible.

    Useful distinctions often come from the decision the visitor is already making. For a product page, that could be price, discount, size, or length. For software, it could be the intended team or task. For an instructional page, it could be the precise deliverable. Numbers and symbols can attract attention when they communicate one of those real details rather than decorating a generic claim.

    • Family Red T-Shirts: XS-XXL identifies the available size range.
    • Red T-Shirts Under $25 identifies a spending threshold.
    • Invoice Approval Software for Small Teams identifies the intended user.
    • Title Tag Audit: A Six-Step Workflow identifies a concrete format.

    Every modifier creates an obligation. If the title says Under $25, the landing page must honor that threshold. If it promises six steps, the page must contain six usable steps. If a price or promotion changes frequently, connect the title-update process to the same operational change or choose a more durable distinction. A stale claim may win the wrong click and lose trust on arrival.

    Avoid relying on Best, Ultimate, Complete, or Essential unless the page demonstrates what the word means. These terms are not automatically forbidden, but they rarely distinguish a listing when every competitor uses them. Formulaic question titles, stacked separators, parenthetical asides, and repeated keyword variants can also make a title look machine-assembled. One clear proposition usually communicates more than a chain of loosely related promises.

    Diagnose title problems from the symptom you can observe

    A magnifying glass connects two abstract search-result symptoms to separate diagnostic paths on a dark digital workbench.

    Do not rewrite a title simply because traffic fell. Ranking movement, result-page changes, terminology, and the title itself are different variables. Check them separately so the edit addresses the actual problem.

    Observed symptomPossible readingFirst action
    Rankings and the results layout are stable, but traffic has fallenThe title may use a product or service name that searchers no longer preferCompare the wording in the title with the current language used in relevant queries and competing results
    The visible title is cut off before the differentiatorThe essential value appears too lateMove the topic and deciding detail forward, then remove repetition
    Google displays substantially different wordingThe HTML title may be long, vague, repetitive, or less useful than another page labelCompare the displayed wording with the title tag, H1, and actual page purpose before revising
    Visibility is healthy, but clicks lagThe title may be relevant without being distinctive or may answer the wrong intentInspect adjacent results and add one truthful qualifier tied to the searcher’s decision
    Clicks rise, but qualified actions weakenThe title may attract an audience the page is not designed to serveMake the audience, scope, price condition, or use case more explicit

    The first pattern deserves particular attention. When ranking and the SERP layout have not materially changed, a traffic decline can point to a mismatch between the title’s terminology and the audience’s current wording. A competitor using the more familiar name can earn the click without displacing your ranking.

    Keep a simple change record for every meaningful revision: the previous HTML title, the replacement, the target query, the displayed search title, the date, and the reason for the change. Hold other page changes steady where practical. That makes the result interpretable instead of leaving you to guess whether the title, content, or layout change moved the metric.

    Evaluate the outcome against the hypothesis. If you changed terminology, look for stronger response from the intended queries. If you shortened the title, verify that the deciding words now appear. If you added a price or size, check whether the arriving audience behaves like the audience that qualifier was meant to attract. A ranking check alone cannot tell you whether the title is doing its user-facing job.

    Key takeaways

    • Lead with the phrase or entity your intended searcher will recognize, then state a concrete value or qualifier.
    • Use roughly 55 characters, including spaces, as a practical editing constraint rather than a quota.
    • Inspect the live results page before writing; differentiation depends on what appears beside your listing.
    • Use prices, percentages, sizes, lengths, and other modifiers only when the page can prove and maintain them.
    • When rankings stay steady but traffic falls, check audience terminology before assuming the page has lost relevance.
    • Treat AI visibility as an extension of sound search visibility, not as a reason to stuff conversational phrases into the title.

    Start with one page that has stable visibility but an underperforming search listing. Write down its audience, primary phrase, promise, and strongest truthful distinction. Reduce those four inputs to one clear title, log the change, and judge it by whether it attracts more of the right clicks.

    References


  • AI Agent Adoption in 2026: A Practical Market Guide

    AI Agent Adoption in 2026: A Practical Market Guide

    If you are deciding whether to deploy an AI agent, do not start with the market leader. Start with the job you need completed, the systems the agent may touch, and the consequences when it stops halfway through.

    The market is growing while its center of gravity weakens. Tracked AI agent usage rose from 142 million aggregate monthly active users in Q3 2025 to 293 million in Q3 2026, but the four largest platforms’ combined share fell from 58.6% to 49.3%. That is the environment you are buying into: rapid adoption, many credible specialists, and no safe assumption that one platform will own every workflow.

    The market is expanding faster than any one leader

    An AI agent is more than a chatbot with a new label. It accepts a goal, breaks that goal into subtasks, chooses actions as conditions change, and works across tools or systems until it reaches an end state. A single-turn assistant does not meet that definition. Neither does an orchestration framework such as LangGraph or Bedrock AgentCore, which helps developers build agents, nor a classification model that chooses a route without pursuing a goal of its own.

    This distinction protects you from buying the wrong layer. A chat license may improve drafting without automating a process. A framework may give your engineering team control without supplying a ready-to-use worker. A fast decision model may make an agent cheaper and safer without replacing the agent itself.

    The following snapshot covers selected leaders from a 40-platform market tracked between May 15 and September 10, 2026. The estimates combine company disclosures, app-store telemetry, procurement records, and account-level observations. They measure platform reach rather than unique people, so someone using several agents can appear in several platforms’ totals.

    AgentPrimary useEstimated MAUsQ3 2026 shareQuarter-over-quarter growth
    ChatGPT AgentMulti-step research, booking, and file work58.9M20.1%+16%
    Microsoft 365 CopilotDocument and Office workflow agents33.4M11.4%+13%
    GitHub Copilot AgentTurning bug reports into code fixes26.7M9.1%+11%
    Gemini Agent ModeBrowser automation and form completion25.5M8.7%+19%
    Claude CodeRepository-wide refactoring and test generation19.3M6.6%+24%
    CursorMulti-file changes inside the editor13.5M4.6%+8%
    OpenAI AtlasSite navigation and transactional tasks11.7M4.0%+27%
    Perplexity CometAgentic browsing, comparison, and checkout10.8M3.7%+22%
    Salesforce AgentforceSupport deflection and CRM pipeline hygiene9.1M3.1%+15%
    Grok BotPersistent work on a cloud computer7.9M2.7%New
    All other agentsVertical, open-source, and smaller platforms45.1M15.4%+14%

    Market-share loss does not necessarily mean user loss. ChatGPT Agent’s share declined from 24.9% in Q3 2025 to 20.1% in Q3 2026 while its estimated users increased from 35.4 million to 58.9 million. Microsoft 365 Copilot and GitHub Copilot Agent also added users while losing relative share. New entrants and expanding specialists diluted the incumbents because the total market grew faster than they did.

    Use market share to assess reach, integration momentum, talent availability, and the likelihood that a product will remain supported. Do not use it as a proxy for successful task completion. The practical response to fragmentation is portability: retain task definitions, approval rules, logs, evaluation cases, and critical business data in systems you control wherever possible. Switching agents should not require rebuilding your operating knowledge from scratch.

    Choose a workflow category before you choose a vendor

    There is no single AI agent market in operational terms. Coding, browser automation, enterprise productivity, CRM work, personal assistance, and long-running general-purpose work have different tools, permissions, failure modes, and definitions of success.

    Coding is currently the largest category, representing 24.8% of tracked agent usage. Even there, the products are not interchangeable. GitHub Copilot Agent is positioned around taking a bug report through to a finished fix. Claude Code emphasizes repository-wide changes and tests. Cursor centers work in the editor, Replit Agent spans prototype-to-deployment creation, and Amazon Q Developer focuses on cloud and coding operations.

    The same specialization appears outside software development. Microsoft 365 Copilot sits inside Office workflows. Salesforce Agentforce works inside CRM processes. Gemini Agent Mode, OpenAI Atlas, and Perplexity Comet concentrate on browser actions, but their stated strengths range from form completion to transactional navigation and comparison-led checkout. A generic request for the “best agent” hides these material differences.

    Write an outcome brief before requesting demonstrations

    A useful evaluation begins with a workflow that has an observable finish. Document these elements before you shortlist products:

    • Goal: State the result the agent must produce or the action it must complete.
    • Starting state: Identify the request, file, ticket, record, or event that begins the run.
    • Permitted systems: List the applications, data, credentials, and tools the agent may use.
    • Definition of done: Describe the final artifact or system state precisely enough that a reviewer can mark it complete or incomplete.
    • Approval gates: Specify where a person must approve publishing, payment, deletion, external communication, code deployment, or another consequential action.
    • Stop conditions: Tell the agent what uncertainty, missing permission, policy conflict, or unexpected state requires escalation.
    • Recovery requirement: Define what the agent must log, preserve, or reverse when it cannot finish.

    For an SEO team, “help with a content audit” is too loose to evaluate. A testable workflow identifies the properties to crawl, the fields to collect, the rule for classifying each page, the destination for the findings, and whether the agent may change a live page. The clearer the end state, the easier it becomes to compare products without being distracted by fluent demonstrations.

    Adopt at the workflow level rather than declaring an organization-wide agent strategy first. A company may reasonably use one agent for repository work, another for CRM operations, and another for browser research. Fragmentation becomes manageable when every deployment has a named job and a shared governance model.

    Completion rate is the buying metric that corrects popularity

    An automated workflow passes through connected stations to a completed package while several alternate routes stop at incomplete handoffs.

    Monthly active users tell you that people invoked a platform. They do not tell you whether it finished the job. For an autonomous workflow, the more relevant question is simple: what percentage of eligible runs reaches the defined end state without a person correcting the agent?

    One standardized comparison required each platform to attempt 48 multi-step tasks across five trials, producing 240 runs per platform. A run counted as complete only when it finished end to end without human correction. Claude Code led at 72.1% unassisted completion, followed by ChatGPT Agent at 65.3% and Grok Bot at 63.7%. Gemini Agent Mode reached 59.6%, GitHub Copilot Agent 57.2%, and Cursor 55.8%.

    Those figures are useful for shortlisting, not for forecasting your deployment. The task mix may not resemble your workflow, and an agent’s performance changes with tool access, permissions, data quality, integration depth, and the exact definition of completion. Claude Code’s result is especially relevant to repository work; it does not establish that a coding agent is the best choice for CRM cleanup or browser checkout.

    Speed also needs context. In that benchmark, OpenAI Atlas had a median completion time of 4 minutes 51 seconds and Perplexity Comet 4 minutes 39 seconds, while ChatGPT Agent took 8 minutes 52 seconds and Grok Bot 19 minutes 14 seconds. A fast incomplete run is not efficient. A slower run may still be preferable if it completes more often, requires fewer interventions, or handles a more complex job.

    Measure the run, not the demo

    Your pilot dashboard should separate these outcomes instead of compressing them into a vague satisfaction score:

    • Unassisted completion rate: Eligible runs that reach the defined end state with no corrective intervention.
    • Partial completion rate: Runs that create useful progress but fail to reach the required state.
    • Intervention rate: Runs in which a person must clarify, repair, approve unexpectedly, or take over.
    • Time to successful completion: Measure completed runs separately so quick failures do not make the agent appear faster.
    • Cost per successful completion: Divide total run costs, including retries and supporting model calls, by completed outcomes rather than by invocations.
    • Recovery quality: Check whether failed runs leave clear logs, preserve work, avoid duplicate actions, and return systems to a known state.
    • Policy adherence: Record attempts to cross approval boundaries, use disallowed data, or invoke an unauthorized tool.

    Keep every started run in the denominator. If your goal is autonomous completion, a person quietly fixing the result before it reaches the dashboard is a failed autonomous run, even when the final output looks good.

    Separate the agent from the decision engines beneath it

    An exploded modular AI system shows an agent above separate reasoning, memory, control, data, and tool components as a hand replaces one module.

    An agent does not need a large generative model for every step. Planning, writing, summarizing, classifying, routing, policy checking, and executing an API call are different computational jobs. Treating them as one undifferentiated prompt raises latency and cost while making failures harder to diagnose.

    The term System One model is being used for a model that returns a typed, calibrated decision from a predefined answer set rather than free-form prose. It can choose a ticket category, route a request to a model, select a tool, or decide whether a proposed action meets a policy. It does not independently accept a goal and pursue it, so it belongs inside an agent architecture rather than in the agent column of a market-share table.

    This layer matters because structured decisions are numerous but relatively inexpensive. Across 3.1 billion production API calls observed in 1,400 applications beginning June 1, 2026, structured decision tasks represented 63.7% of calls but only 15.5% of token spend. Long-form generation showed the opposite pattern: 9.1% of calls consumed 38.4% of token spend. A specialized decision model can therefore remove a large amount of traffic from a general-purpose model without displacing a comparable share of model spending.

    The best candidates have an answer space you can enumerate before the call. Binary classification led a September 2026 survey of 421 AI engineering teams, with 60.5% already piloting or planning adoption within six months. Schema extraction ranked last at 28.7% because field values are often open-ended. That gap gives you a practical rule: use a decision model when you can list all legitimate outcomes; retain a generative model when the output itself must be created.

    Type safety is necessary, but it is not factual accuracy

    A model can return a perfectly valid category and still choose the wrong category. Constrained decoding on a small language model achieved a 0.0% type error rate in the same benchmark as Jev, so valid output syntax is not, by itself, a differentiator. You still need labeled evaluation cases that test whether the decision is correct.

    The alternatives also remain competitive. A fine-tuned encoder classifier recorded 0.09-second median latency and a $0.018 cost per million input tokens, compared with Jev at 0.14 seconds and $0.042. The tradeoff is breadth: a new classification question can require another encoder to be trained, while a broader decision endpoint can answer different predefined questions. A small language model using constrained decoding was slower at 2.1 seconds, with input priced at $0.35 per million tokens and output at $1.40.

    Early demand does not prove steady-state adoption. Jev was only seven days old when launch-week estimates put it at 31,416 developers making at least one API call, while 6.2% of new accounts reached production. Treat that as evidence of interest and low integration friction, not as evidence that the architecture has already become standard.

    A clean production design assigns each layer a narrow responsibility:

    • The agent owns the goal, task state, planning, and recovery path.
    • Decision models handle enumerable classifications, routing, ranking, policy checks, and tool selection.
    • Generative models create prose, summaries, code, and other open-ended outputs.
    • Deterministic tools read or change external systems under explicit permissions.
    • Human approval remains in front of irreversible, externally visible, or high-consequence actions.

    Log the input, output, confidence or score, selected route, tool result, and final task outcome at the relevant layer. Otherwise, a failed workflow leaves you guessing whether the planner, classifier, generator, integration, or external system caused the problem.

    Build an adoption plan that survives vendor churn

    A durable rollout does not depend on predicting which logo will lead the next market table. It depends on preserving your workflow knowledge and measuring interchangeable components against the same definition of success.

    1. Select one bounded workflow. Favor a repeatable job with an observable end state and enough current friction to justify integration work.
    2. Map the action boundary. Separate read-only work, reversible internal changes, external communications, financial actions, deployments, and destructive operations. Require human approval where an error would be difficult to reverse.
    3. Shortlist by category fit. Compare agents designed for the systems and work involved instead of beginning with overall reach.
    4. Run identical evaluation cases. Include normal requests, missing information, ambiguous instructions, permission failures, tool errors, and requests that should trigger a refusal or escalation.
    5. Score completed outcomes. Track unassisted completion, interventions, time, cost, policy adherence, and recovery behavior using the same denominator for every candidate.
    6. Decompose expensive runs. Identify classification, routing, ranking, safety, and tool-selection calls that can move to a specialized decision model or deterministic rule.
    7. Retain a migration path. Keep prompts, outcome briefs, schemas, evaluation cases, logs, and business rules outside proprietary interfaces when the platform permits it.

    If customers encounter your business through agents

    Agent adoption changes acquisition as well as operations. ChatGPT Agent is used for multi-step research and booking; Gemini Agent Mode handles browser automation and forms; OpenAI Atlas performs site navigation and transactions; Perplexity Comet supports comparison and checkout. If any of those journeys matter to your business, visibility alone is an incomplete success metric. The agent must be able to identify the right page, understand the offer, verify important facts, and complete or correctly hand off the next step.

    Apply the same outcome-based discipline to AI SEO, AEO, and GEO work:

    • Put essential product, service, eligibility, policy, and contact information in visible page text rather than only in images or interactive widgets.
    • Give each important entity, offer, and resource a stable canonical URL with a clear page purpose.
    • Keep structured data consistent with the claims a visitor can see. Schema is a machine-readable consistency layer, not permission to publish contradictory or unsupported markup.
    • Use specific labels for links, buttons, form fields, and required inputs so an agent does not have to infer what an interface element does.
    • Publish dates, units, methodology, limitations, and originating evidence beside factual claims that an agent may need to evaluate or cite.
    • Test complete journeys from discovery to the required outcome. Record where the agent selects the wrong page, loses context, cannot operate a control, encounters conflicting facts, or reaches an unexpected approval step.

    This is where agent analytics should meet search analytics. A mention in an AI answer, an agent visit, a successful product comparison, and a completed transaction are separate events. Tracking only referral traffic hides the failures between discovery and completion.

    Key takeaways

    • AI agent usage is expanding rapidly, but market share is fragmenting rather than settling around one permanent winner.
    • Choose an agent for a defined workflow category and observable end state, not for overall popularity.
    • Use unassisted completion, intervention, recovery, time, and cost per successful outcome as the core buying metrics.
    • Keep goal pursuit in the agent layer while routing enumerable decisions to specialized models or deterministic rules where appropriate.
    • Make customer journeys explicit, structured, and testable if browser and general-purpose agents are part of your discovery or conversion path.

    Your next move is deliberately small: choose one workflow whose finish you can describe in a sentence, preserve a human gate before consequential actions, and run the same cases through category-appropriate candidates. The market will keep changing. A clear outcome definition and a portable evaluation set let you benefit from that competition instead of being trapped by it.

    References


  • Google Discover’s “Dive Deeper” Test: A Publisher Playbook

    Google Discover’s “Dive Deeper” Test: A Publisher Playbook

    If Google Discover sends you meaningful traffic, the new “Dive deeper” experiment deserves a measurement plan, not a panic rewrite. The AI-powered card can occupy a feed position that might otherwise show publisher content, then answer part of the user’s need before offering links to the web.

    Your immediate job is to separate a plausible traffic risk from an observed traffic loss. Establish a Discover baseline, isolate the content most exposed to the test, and make the value of clicking unmistakable. You can do all of that without guessing at an undisclosed ranking factor or inventing a new schema strategy.

    What the test changes in the Discover journey

    A normal publisher card offers a relatively direct choice: open the content or continue scrolling. “Dive deeper” introduces another route. A person can enter an AI-generated topic overview and then decide whether one of its linked stories, community reactions, or pieces of original reporting deserves another click.

    Google describes those destination links as prominent, but prominence doesn’t remove the added decision point. The overview itself may satisfy a casual reader. A publisher also has to win selection among several related resources rather than win the initial feed interaction alone.

    That creates three distinct risks for publishers:

    • Displacement: the topic card may use feed space that could have carried a publisher’s individual item.
    • Intermediation: the user reaches an overview before reaching a publisher, adding another choice between discovery and the site visit.
    • Substitution: the generated overview may provide enough context that some people no longer need the underlying coverage.

    Those are mechanisms, not measured outcomes. Google is starting the experiment with videos and trying multiple designs. That makes it premature to treat the interface as a completed rollout, assume every Discover user can see it, or attribute every traffic decline to it.

    Measure the test without mistaking correlation for cause

    Two streams of content tiles pass through separate test pathways while a magnifying lens and measuring vessels represent controlled analysis.

    A total traffic chart won’t tell you whether “Dive deeper” affected your site. Publishing volume, subject mix, headline quality, seasonality, and changing audience interest can all alter the same line. You need a Discover-specific view and enough page-level detail to identify the shape of the change.

    1. Preserve your baseline. Export Discover clicks, impressions, click-through rate, and landing-page performance from Google Search Console. Use a period long enough to show your site’s normal range rather than selecting only a convenient high point.
    2. Record editorial context. Annotate major changes in publishing frequency, topic selection, video output, headlines, and distribution. Otherwise, a newsroom decision can look like a platform effect.
    3. Separate video-led content. Because the experiment begins with videos, compare pages built around video with the rest of your Discover inventory. Keep the classification consistent; don’t move a page between groups merely because its performance changed.
    4. Inspect pages before aggregates. Identify which landing pages lost impressions, which retained exposure but lost clicks, and which continued to convert after the visit. A sitewide average can conceal all three patterns.
    5. Connect visits to outcomes. Pair Discover traffic with the action that matters on your site, such as engaged reading, registration, subscription, or revenue. Fewer visits would still be harmful at scale, but a publisher should know whether the remaining visits became more or less valuable.

    Use the pattern below as a diagnostic guide, not as proof of exposure to the experiment.

    Pattern in your dataWhat it may indicateWhat to check next
    Impressions fall while CTR stays near its normal rangeReduced feed exposure or weaker topic relevanceCompare publishing volume, subject mix, and video-led versus non-video pages
    Impressions hold while CTR fallsA more competitive or more satisfying interface, or weaker packagingReview the affected headlines, media, and the distinctive value promised by each page
    Clicks fall while value per visit holdsA volume problem rather than a visitor-quality problemModel the total subscription or revenue impact and reduce channel concentration
    Only a small group of pages declinesA page, format, or topic issue rather than a sitewide platform effectCompare those pages with stable content before changing the whole editorial plan

    If you cannot identify which users encountered “Dive deeper,” describe any relationship as an association. A decline that begins during a platform experiment is worth investigating, but timing alone doesn’t establish causation.

    Give readers a reason to continue beyond the overview

    A reader moves from a small translucent summary card into a series of deeper chambers filled with visual research and practical resources.

    The wrong response is to make content longer or more mysterious. An overview competes most easily with generic coverage that repeats known facts. Your stronger position is content whose useful part cannot be reproduced by a short topic summary.

    Google says the expanded experience can link to related stories, community reactions, and original reporting. Treat those labels as clues about the types of destination that can complete a reader’s journey, not as confirmed ranking factors.

    • Make the unique asset visible in the headline. Name the interview, analysis, data, demonstration, timeline, local detail, or expert interpretation the reader will receive. A broad topic label gives the overview little reason to send the user onward.
    • Put original evidence near the top. If the page contains reporting, show what was learned and how. Don’t bury the differentiating material beneath a generic explanation that an overview can already provide.
    • Define the unanswered question. A useful headline and opening should reveal what the short overview cannot settle: why an event happened, what changed, who is affected, how competing claims differ, or what the viewer can verify in the full video.
    • Match the promise to the page. A headline that implies original reporting must lead to original reporting. Artificial curiosity may win an occasional click, but it creates a poor destination and weakens the value of being selected.
    • Build a useful next step on your own site. Connect the landing page to genuinely related analysis, primary material, or an update path. If Discover supplies a more fragmented entry point, your internal journey has to restore context quickly.

    For video-led pages, audit the complete package: title, thumbnail, opening text, video, transcript or summary, and supporting evidence. The page should make clear what the video contributes beyond the surrounding topic overview. Don’t assume that embedding a video makes otherwise generic coverage distinctive.

    Do not invent a schema fix for a user-interface test

    This is where technical teams can lose time. Google’s disclosed description of “Dive deeper” does not specify a new structured-data type, an opt-in setting, or a publisher control for the feature. There is therefore no responsible basis for promising that a markup change will secure placement or prevent summarization.

    Keep existing Article or VideoObject markup accurate when those types properly describe the page. Make sure visible titles, dates, authorship, media, and structured properties agree. That is sound technical hygiene, but it shouldn’t be presented internally as a “Dive deeper optimization.”

    Use this decision rule before approving Discover-related technical work:

    • If the change repairs inaccurate or inconsistent markup, make it.
    • If the change improves how people understand and navigate the page, evaluate it on that merit.
    • If the change depends on an undocumented “Dive deeper” signal, hold it until Google provides supporting guidance or your own controlled evidence justifies the work.

    Also keep the product distinction clear in reports. “Dive deeper” is an experiment inside Discover; it is not evidence that every Discover card is being replaced, and it should not be casually relabeled as the search results feature commonly called AI Overviews. Blurring those surfaces makes your measurements and recommendations less reliable.

    Reduce the business risk before the interface settles

    You don’t need to predict the final design to manage the exposure. Start with channel concentration. Calculate how much traffic, engagement, subscription activity, and revenue comes from Discover, then identify the pages and formats responsible for most of that contribution.

    Build scenarios from your own historical range rather than borrowing an arbitrary industry percentage. Your baseline scenario can reflect normal variation. A lower-range scenario can show what happens when Discover underperforms without disappearing. A stress scenario can show which editorial products become uneconomic if referral volume contracts materially.

    Assign an action to each scenario before traffic moves. That action might be protecting distinctive reporting, changing the volume of generic video coverage, improving conversion on the visits you retain, or accelerating channels you control more directly. Email subscriptions, direct visits, feeds, memberships, and durable search demand won’t reproduce Discover’s feed distribution exactly, but they can reduce the damage caused by dependence on any single interface.

    Avoid across-the-board cuts based on one weak reporting period. A narrow decline in commodity coverage calls for a different response from a broad loss of impressions across original work. The first may be a content-positioning problem; the second may justify a larger distribution and revenue review.

    Key takeaways

    • “Dive deeper” inserts an AI-generated topic overview between parts of the Discover experience and publisher destinations, creating a credible risk of click compression.
    • The experiment begins with videos and may use multiple designs, so its current form should not be treated as a settled, universal rollout.
    • Track Discover impressions, clicks, CTR, landing pages, content format, and downstream value separately; aggregate traffic alone cannot diagnose the cause.
    • Make original evidence and the reason to continue beyond a summary explicit in the headline, opening, and page experience.
    • Do not promise a structured-data solution when Google has not identified special markup or a publisher control for the test.
    • Model Discover dependency now so your response is based on business impact rather than fear generated by an unfamiliar interface.

    Start with a clean export of your current Discover performance. Classify the leading pages as video-led or non-video, note the distinctive value each one offers, and record the editorial conditions behind the baseline. If the interface begins affecting your audience, you will have evidence for a targeted decision instead of a reason to overhaul everything at once.

    References