Tag: Content Operations

  • Google Opal for Scalable AI Content Without Scaled Spam

    Google Opal for Scalable AI Content Without Scaled Spam

    Your bottleneck is not generating another draft. It is knowing whether the next draft deserves to exist. Google Opal can widen production quickly, but the same speed that helps a campaign can also multiply weak claims, overlapping pages, and editorial work.

    If you are deciding whether to use Opal at scale, build the controls before the volume. The safest operating model has three parts: one governed fact base, one clear job for every asset, and a human release decision for every publishable URL.

    Scale the production system, not the number of URLs

    Opal can turn a single product concept into blog posts, social captions, and video advertising scripts. That one-to-many pattern can be useful because each channel asks the content to do a different job.

    A blog post might answer a buyer’s question in detail. A social caption might introduce the idea to someone who was not looking for it. A video script might demonstrate the product or frame the problem visually. The underlying facts can remain consistent while the format, depth, and immediate purpose change.

    The trouble starts when a team treats every generated variation as a new search page. Changing a keyword, location, audience label, or product name does not automatically create a new reason to publish. If the reader receives substantially the same answer, the outputs are variants of one asset rather than independent URLs.

    Google’s scaled content abuse policy is concerned with producing many pages mainly to influence rankings, especially when those pages are unoriginal and add little value. Generative AI used to manufacture large amounts of low-value content is one example of that risk. The presence of AI is not the decisive issue. The purpose and usefulness of the resulting pages are.

    Scale itself is not a verdict either. Google’s apparent acceptance of Reddit using AI to translate pages at scale illustrates the distinction: a transformation can expand access to existing information instead of manufacturing search inventory. That does not create blanket permission for automated publishing, but it shows why volume alone is the wrong test.

    Before opening Opal, make an output map. Give every proposed asset the following fields:

    • Audience: Who specifically needs this asset?
    • User task: What are they trying to understand, compare, decide, or complete?
    • Distinct value: What will they get here that is not already available on your existing page?
    • Format: Why is a blog post, landing page, caption, or video script the right container?
    • Destination: Will it become an indexable URL, update an existing URL, or live only in a distribution channel?
    • Owner: Who can approve, merge, revise, or reject it?

    If two rows have the same audience, task, evidence, answer, and destination, consolidate them before generation. That single check prevents a campaign plan from quietly becoming a doorway-page plan.

    Ground Opal in a reusable source packet
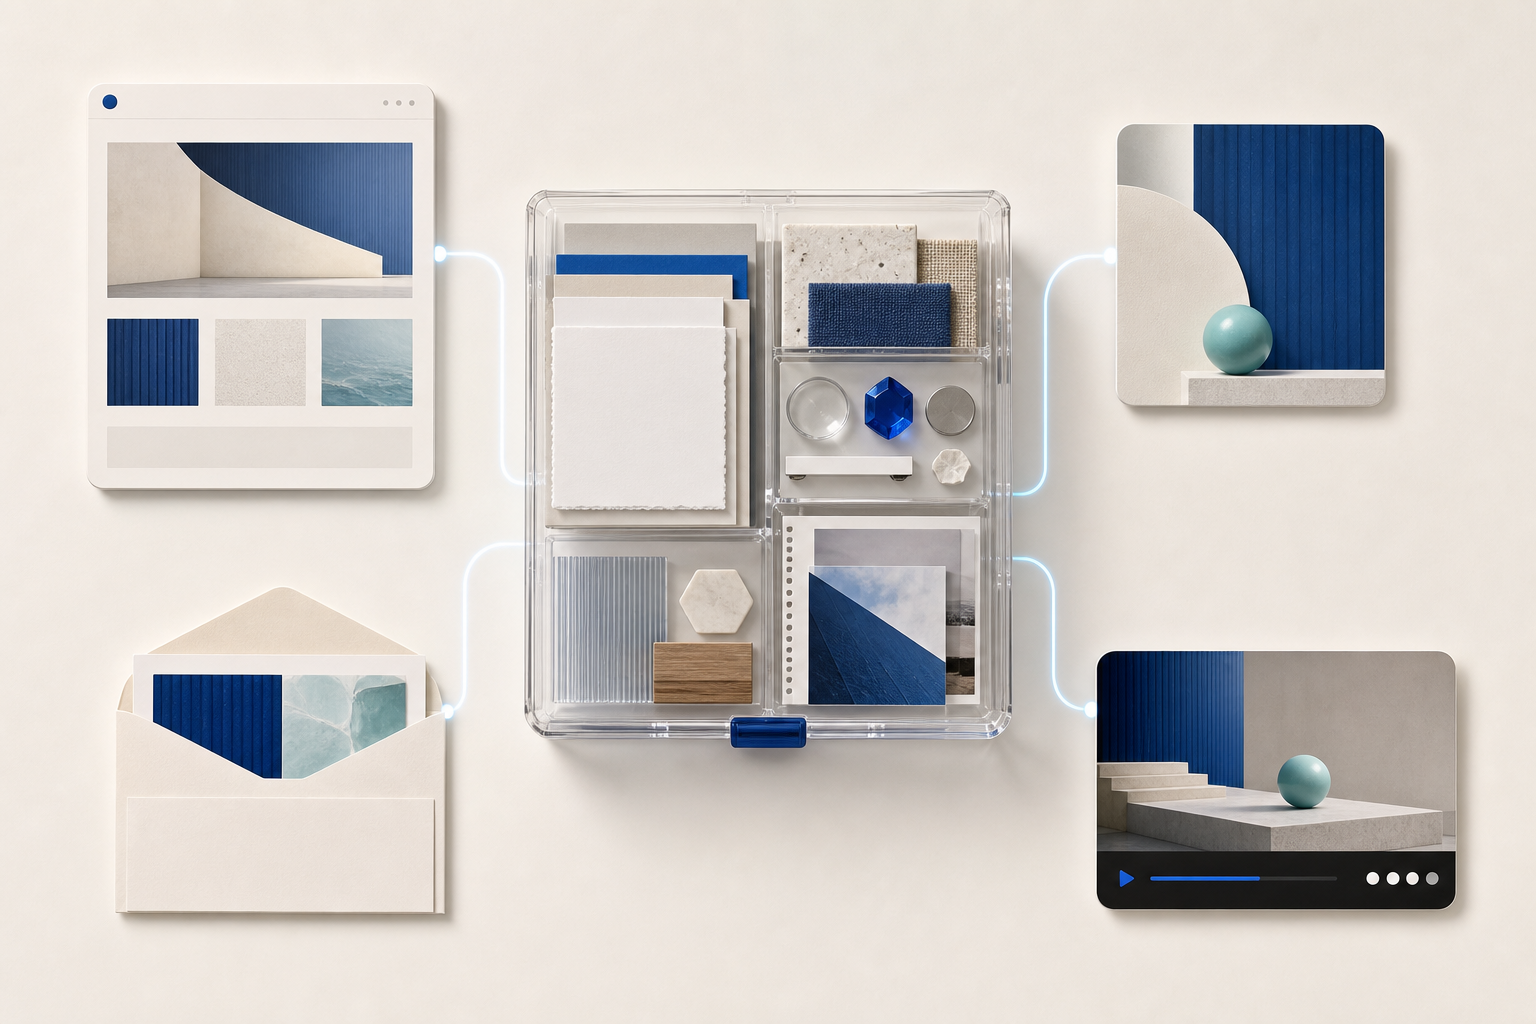
    An organized central source packet connects to several distinct content formats on a clean creative workspace.

    A product concept is enough to inspire copy, but it is not enough to govern factual content. When the input is vague, a fluent output can hide assumptions, omit necessary qualifiers, or turn a positioning idea into an unsupported claim.

    Build a source packet before you generate anything. This becomes the controlled factual layer shared by the article, social copy, scripts, and future updates. Include:

    • Approved facts: Product capabilities, limitations, compatibility details, terminology, and other statements the content may treat as true.
    • Claim provenance: The internal record, public evidence, subject-matter owner, or approved page supporting each important claim.
    • Entity names: The exact names of the company, product, feature, category, people, places, standards, and versions involved.
    • Prohibited claims: Comparisons, guarantees, performance statements, or implications the available evidence does not support.
    • Audience context: What the intended reader already knows, what decision they face, and what would make the answer useful.
    • Unique contribution: The explanation, example, method, data, opinion, or decision support that gives the asset a reason to exist.
    • Canonical relationship: Which page owns the main answer and how each derivative should refer back to it.
    • Next action: What the reader should be able to do after consuming the asset.

    The packet should also define how Opal handles missing information. A practical generation contract is: use supplied facts for specific claims, preserve every qualification, flag unsupported gaps, and never convert a creative suggestion into a factual assertion. Asking for a visible marker such as [NEEDS EVIDENCE] is more useful than letting a plausible sentence pass unnoticed.

    Have the workflow return a claim ledger with the draft. The ledger does not need to be elaborate. It should identify each verifiable assertion, the packet item supporting it, and any statement that still requires review. This turns fact-checking from a hunt through polished prose into a finite approval task.

    The source packet also gives you an update path. When a product fact changes, revise the controlled record first, identify the affected assets, and update them from the same approved information. Without that shared layer, every derivative becomes an independent copy that can drift away from the truth.

    Put human decisions at the points automation cannot judge
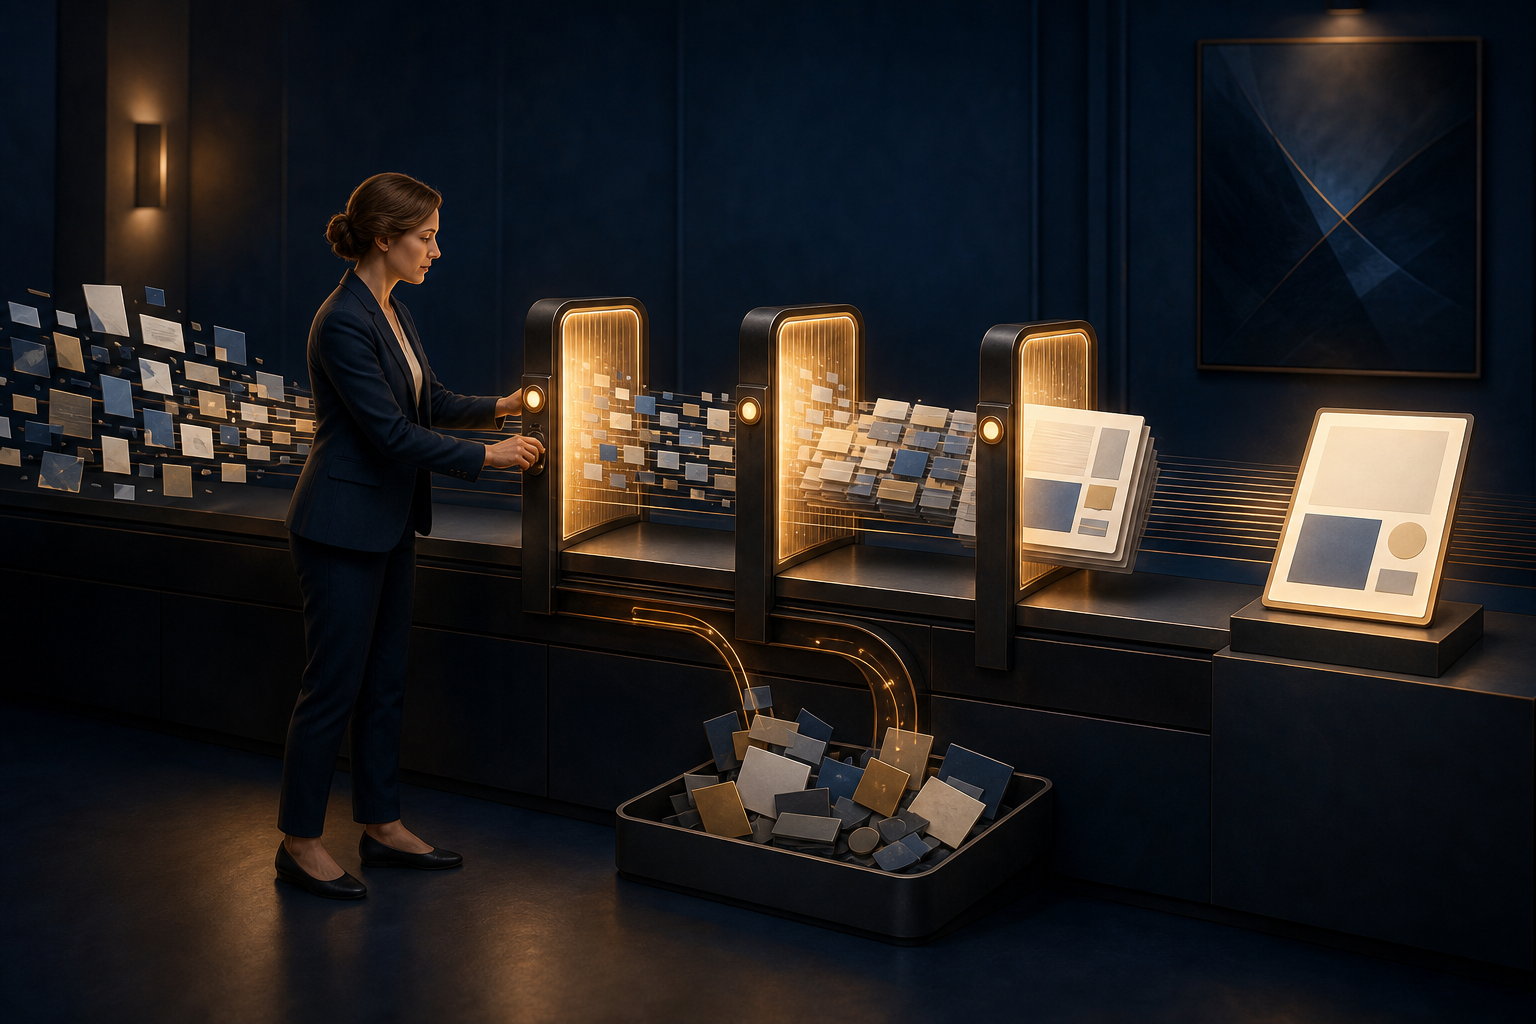
    A human editor operates decision gates along an automated content pipeline, approving one page and diverting uncertain items for review.

    Human review should not mean correcting punctuation after generation. A polished unsupported claim is still unsupported, and an elegant duplicate page is still a duplicate page. Reviewers need authority to decide whether an asset should exist at all.

    1. Intent gate: Before generation, confirm the asset serves a named user task. Reject briefs whose only purpose is covering another keyword variation.
    2. Claim gate: Compare the draft and claim ledger with the source packet. Remove or qualify anything that cannot be traced to approved information.
    3. Value gate: Identify the passage that makes this asset more useful than the canonical page or an existing competitor-independent answer. If that passage does not exist, merge or rework the draft.
    4. Editorial gate: Remove generic setup, repeated conclusions, false certainty, and transitions that merely restate headings. Make the answer direct enough that a reader does not have to excavate it.
    5. Release gate: Decide whether the output becomes an indexable page, an update to an existing page, a non-indexed campaign asset, or discarded material.

    Apply the full set of gates to every indexable URL. A social caption or advertising script may need a lighter structural review, but it still needs factual and brand approval because it draws from the same claims. A publishing template cannot absorb that responsibility; generated outputs can fail in different ways even when they share a prompt.

    Where possible, separate generation from final approval. The person accountable for throughput will naturally see usable material in an almost-finished draft. An approver accountable for accuracy, usefulness, and site quality has a different incentive and can stop unnecessary pages before they enter the index.

    Measure the workflow by accepted assets and resolved user tasks, not raw drafts. Draft count rewards regeneration. Published URL count rewards fragmentation. A useful operating record instead tracks why an asset was accepted, merged, revised, or rejected. Those decisions reveal whether Opal is removing production friction or simply moving the bottleneck into review.

    Make useful content legible to search and AI systems

    SEO, AEO, and GEO work cannot manufacture value after generation. They can make existing value easier for search engines and language models to identify, extract, and connect to the right entity or question. Treat optimization as a clarity layer.

    • Answer the primary question near the start instead of delaying it behind a generic introduction.
    • Use headings that describe real decisions, distinctions, risks, or steps rather than repeating broad keywords.
    • Name products, organizations, features, standards, and versions consistently so the subject does not shift across assets.
    • Keep qualifications next to the claims they limit. Do not hide them in a note at the bottom.
    • Link derivative assets to the page that owns the complete explanation, and update that canonical page when the core answer changes.
    • Use examples only when they illuminate the reader’s task. A generated example that adds no information is decoration, not evidence.
    • Add structured data only for information that is present and visible on the page. JSON-LD describes content; it cannot compensate for a thin or unsupported answer.
    • Use FAQ content only when distinct questions require distinct answers. Do not turn heading variations into artificial question-and-answer padding.

    Then run a release audit from the reader’s side. Ask:

    • Can we state the user’s task in one clear sentence?
    • Does the page deliver information, reasoning, or utility that its closest existing page does not?
    • Can every consequential claim be traced to the source packet?
    • Would the page still help someone who received the link if search rankings disappeared?
    • Does the title promise exactly what the body delivers?
    • Are product names, qualifiers, and conclusions consistent with the related captions and scripts?
    • Does any structured data match the visible page rather than an intended or generated version of it?
    • Are we publishing this URL because a person needs it, or because the workflow happened to produce it?

    The answers should lead to an explicit disposition. Publish an asset with a distinct job, grounded claims, and a complete answer. Merge an asset whose useful material belongs on an existing page. Rework one with a valid user task but inadequate evidence or differentiation. Keep a campaign variation out of the index when it serves distribution rather than search. Discard an output whose only remaining purpose is expanding keyword coverage.

    This is how one product concept can support a coherent content system: the canonical page owns the durable answer, channel assets adapt it for their environments, and the source packet keeps every expression aligned. Opal can accelerate the transformations without being allowed to decide that every transformation deserves a URL.

    Key takeaways

    • Use Google Opal to scale governed transformations across channels, not near-duplicate indexable pages.
    • Require a unique audience task and a distinct contribution before generating a new search asset.
    • Ground every output in a reusable source packet containing approved facts, prohibited claims, entity names, and provenance.
    • Make human review a publish, merge, rework, or reject decision rather than a copy-editing step.
    • Use SEO, AEO, GEO, internal links, and structured data to clarify genuine value, never to substitute for it.
    • Judge the system by accepted, useful assets and consistent claims rather than drafts produced or URLs published.

    Before your next Opal run, choose one product concept, build its source packet, and map each proposed output to a real user task. Generate the channel set only after that map survives review. Scale further when the workflow repeatedly produces assets your editors would choose to publish even without the pressure to produce more.
    References

  • How to Build a Forum That Earns Visibility in AI Search

    How to Build a Forum That Earns Visibility in AI Search

    Your content team can answer the obvious questions. The harder problem is everything too specific, contextual, or fast-changing to justify its own editorial brief. Those questions still get asked. If your site does not host the conversation, users and AI assistants will look elsewhere for it.

    A well-run forum gives those questions a durable home while letting customers, practitioners, and subject-matter experts add the details a conventional content calendar misses. But the software is the easy part. To earn visibility, the community must produce public, well-structured, trustworthy answers rather than empty categories, unresolved threads, and searchable spam.

    Forums capture the demand your editorial calendar misses

    Traditional SEO programs tend to prioritize head terms: topics with recognizable search volume, clear commercial value, and enough demand to support a standalone page. That leaves a wide gap around questions involving unusual configurations, narrow use cases, product combinations, exceptions, and real-world tradeoffs.

    Users do not experience that gap as a keyword problem. They experience it as a question nobody has answered. When an AI assistant lacks enough internal knowledge to respond, it may search the web through engines such as Google or Bing. A detailed discussion can then become more useful than another broad page repeating the standard explanation.

    The scale of that appetite is already visible: Reddit appeared in more than 40% of LLM responses in a June 2025 analysis of 150,000 AI citations. That percentage is not a promise that launching a forum will produce citations. It shows how often AI answer systems rely on conversational material when they need specific, experience-shaped information.

    A useful thread can contain several forms of evidence at once: the language of the original problem, the constraints that made it difficult, several proposed solutions, objections from other practitioners, and a final resolution. That creates semantic depth naturally. It also exposes where an answer works, where it fails, and which conditions change the outcome.

    User-generated content is not automatically accurate, current, or trustworthy. Those qualities come from expert participation and active curation. An unanswered question is merely a thin page. A confident but incorrect reply is worse because it can mislead a customer and give search or AI systems a poor representation of your brand’s knowledge.

    Start by building a question inventory from places where long-tail demand is already visible:

    • Support conversations that require more context than the help center provides.
    • Pre-sale questions that repeatedly need a specialist to answer.
    • Internal site searches that return no useful result.
    • Comments and replies that reveal exceptions to your published guidance.
    • Implementation questions that have several valid answers rather than one universal procedure.
    • Product feedback that begins as a how-to question but exposes a missing feature, unclear workflow, or documentation gap.

    For each candidate, record the audience, product or process involved, constraint, desired outcome, and evidence needed for a credible answer. This becomes both your launch backlog and your first taxonomy. It is far more useful than creating empty categories based on the structure of your company.

    Choose the community format before choosing the software

    A forum should not absorb every type of content. The right format depends on the job the user is trying to complete and how much disagreement belongs in the answer.

    User needBest primary formatWhy it fits
    Compare approaches, share examples, or discuss tradeoffsDiscussion forumSeveral perspectives may remain useful even after the original problem is resolved.
    Solve one defined problem and identify the clearest resolutionQ&A communityAnswers can be evaluated, corrected, and marked as accepted or resolved.
    Confirm an official rule, specification, policy, or supported procedureDocumentationThe brand needs to maintain one canonical answer without ambiguity.
    Explain a broad strategy or synthesize several related issuesEditorial contentA controlled narrative is better than asking readers to reconstruct the answer from replies.

    Many brands need a combination. The community surfaces the question and gathers experience. Documentation records the official procedure. Editorial content explains the larger pattern. Links between those formats help a user move from conversation to an authoritative answer without forcing one page to do every job.

    For discussion-led communities, Flarum and Discourse are open-source options. For a more resolution-oriented Q&A model, Apache Answer and Question2Answer fit that structure. Open-source software can provide customization and control over community data, but it does not remove the operating work. Hosting, security updates, spam controls, moderation, backups, and contributor support still need owners.

    Evaluate each platform against the workflow you intend to run, not the length of its feature list:

    • Public access: Can valuable threads be read without signing in, and can their text be crawled at stable URLs?
    • Data control: Can you export users, threads, replies, moderation history, and attachments in a usable form?
    • Answer states: Can moderators mark a question as resolved, identify an accepted answer, and reopen it when circumstances change?
    • Identity and authority: Can you distinguish employees, verified experts, moderators, experienced members, and ordinary participants without implying that every badge guarantees accuracy?
    • Curation: Can you merge duplicates, redirect obsolete URLs, feature a useful summary, and connect related discussions?
    • Moderation controls: Can permissions expand gradually as a member earns trust, with a clear escalation path for sensitive cases?
    • Search hygiene: Can you prevent thin tag, filter, profile, and empty category pages from overwhelming the useful discussions?

    Do not launch merely because the installation works. Your minimum launch gate should include a named community owner, published participation rules, a prepared backlog of real questions, committed experts who will answer them, and a process for escalating incorrect or sensitive replies. Without those pieces, early visitors learn that asking is not worth the effort.

    Turn each thread into a page an answer engine can understand

    A branching group of discussion tiles is organized into a structured page with separate areas for a question, a primary answer, supporting replies, and related topics.

    A forum thread is both a conversation and a content page. If you optimize only for conversation, the useful answer may be buried under vague titles, missing context, jokes, and outdated replies. If you optimize only for search, the community begins to feel like an unpaid content factory. The page template has to serve both.

    1. Require a descriptive question title. A title such as Need help with discounts carries almost no meaning. How can I limit a discount to subscriptions without changing one-time purchases names the action, object, and constraint.
    2. Prompt for decision-changing context. Ask for the product or process, relevant version, intended outcome, constraints, steps already tried, and any visible error. Do not ask users to publish account credentials, personal information, confidential data, or anything else that should remain private.
    3. Put the usable answer near the top. Once a thread is resolved, add or feature a short summary that states the solution before the longer discussion. Keep the reasoning and alternatives below it for readers whose situation differs.
    4. Label the role behind each reply. An official policy, a verified specialist’s recommendation, and a customer’s workaround are different kinds of evidence. Make that distinction visible instead of flattening every reply into the same level of authority.
    5. Show the resolution and freshness state. Mark threads as open, resolved, or superseded. Display when the accepted information was last reviewed, and reopen the question when a product or policy change makes the old resolution uncertain.
    6. Curate duplicates into a stronger destination. Merge substantially identical questions or point them to the canonical discussion. Preserve distinct threads when a different constraint genuinely changes the answer.

    The technical baseline matters as much as the editorial template. Give every valuable thread one durable URL. Expose the question and replies as crawlable HTML. Use a descriptive page title, keep internal links reachable, redirect merged discussions, and keep empty or low-value system pages out of the index. Include only eligible public pages in discovery feeds such as XML sitemaps.

    Structured data may help machines interpret the page, but it must describe what visitors can actually see. Do not mark an unresolved reply as accepted, manufacture an answer that is absent from the thread, or treat decorative voting as evidence of expertise. Markup can clarify a sound page; it cannot turn a weak discussion into an authoritative answer.

    Being crawlable is not the same as being citable. A passage becomes easier to reuse when it answers the question in self-contained language. Replace replies such as That worked for me with language that names what worked, under which conditions, and what the reader should check before applying it. The simple editorial test is whether two sentences could be quoted outside the thread without losing the subject, constraint, or conclusion.

    Preserve useful disagreement. A minority answer may cover a version, market, or implementation the accepted answer does not. Moderators should remove abuse, spam, impersonation, and dangerous misinformation, but they should not erase a good-faith alternative merely to make the thread look unanimous. Expert consensus is valuable only when the community can see how it was reached.

    Operate the forum as a knowledge system, then measure it

    Community stewards review, connect, and maintain glowing discussion nodes inside a digital archive-like workspace.

    Build moderation into the publishing workflow

    Moderation is not a cleanup queue that begins after growth. It is the process that turns raw participation into reliable knowledge. Define the boundaries before inviting users: what belongs in the community, what evidence is expected, what promotion is allowed, how conflicts are handled, and which questions must move to private support.

    1. Triage new questions. Correct unclear titles, request missing context, merge true duplicates, and move private account issues out of public view.
    2. Route the question. Assign unanswered topics to the employee, partner, or community expert most able to resolve them. Publish an internal response target that reflects actual staffing so questions do not disappear between teams.
    3. Separate contribution from endorsement. Let members share workarounds, but mark which answers represent official guidance. Correct false claims without presenting all disagreement as misconduct.
    4. Close the knowledge loop. When the question is resolved, feature the clearest answer, add a concise summary, connect relevant documentation, and record whether the resolution depends on a particular version or condition.
    5. Distribute responsibility carefully. Give consistent contributors limited moderation privileges, then expand those permissions as judgment and reliability become clear. Keep policy decisions and serious escalations under accountable brand ownership.

    Community-led moderation can scale better than routing every task through one central team because knowledgeable members can improve titles, flag duplicates, welcome newcomers, and surface strong answers. It still needs oversight. Passion for the topic is not the same as authority to set company policy or adjudicate every dispute.

    Measure answer quality before celebrating traffic

    Pageviews can rise while the community deteriorates. Define what counts as a useful reply and a resolved question before building the dashboard, then keep those definitions consistent. Track a small set of measures tied to decisions:

    OutcomeWhat to trackWhat you can do with it
    Question coverageIn-scope questions, unanswered share by topic, time to first useful reply, and resolved shareFind topics with real demand but insufficient expert capacity.
    Contributor healthRepeat contributors, active subject-matter experts, answer corrections, and reliance on a single responderSee whether knowledge is becoming distributed or remains a bottleneck.
    DiscoveryIndexed resolved threads, non-branded search landings, verified AI citations, and identifiable AI referral sessionsDetermine which answer formats and topic clusters earn external visibility.
    Customer valueRepeated support questions, forum-assisted journeys, documentation gaps, and product issues surfaced by discussionsConnect the community to support, content, sales, and product decisions.

    Do not collapse these signals into one vanity score. Response health is an operating signal; search and AI visibility are downstream outcomes. A bot crawl is not a citation, and a citation is not automatically a conversion. Verify important AI mentions against the actual answer, inspect the landing behavior where analytics allows it, and check whether the cited thread represents your position accurately.

    The best measurement loop changes the community. If one topic attracts questions but few answers, recruit or assign an expert. If several threads resolve the same issue, promote the resolution into documentation. If a discussion exposes several legitimate strategies, turn it into a deeper editorial resource and link back to the original examples. If obsolete threads keep earning visits, update or supersede them before they continue spreading stale advice.

    Key takeaways

    • A forum is most valuable when it captures narrow, contextual questions that conventional keyword and editorial planning leave unanswered.
    • Choose discussion software for multiple valid perspectives and a Q&A model when users need a clearly resolved outcome.
    • Require descriptive titles, decision-changing context, visible authority labels, concise answer summaries, and clear resolution states.
    • Public crawlability, stable URLs, duplicate control, and accurate page markup are prerequisites, not substitutes for trustworthy answers.
    • Measure response quality, expert participation, discovery, and customer value separately so you know which part of the system needs attention.

    Your first move is not to install a platform. Collect the questions already escaping into support queues, sales calls, comments, and third-party communities. Choose one coherent topic area, assign the people who can answer it, and design the resolution workflow before opening the doors. A focused forum that reliably solves difficult questions is a stronger AI-search asset than a large community full of unanswered ones.

    References

  • How to Evaluate Conductor’s Unified SEO Intelligence Platform

    How to Evaluate Conductor’s Unified SEO Intelligence Platform

    If your rankings, content work, and website changes live in separate tools, the expensive part is not collecting another chart. It is deciding which page to change, why the change deserves priority, who owns it, and whether it worked.

    That is the right lens for evaluating Conductor’s unified SEO intelligence platform. Do not start with how much data it can display. Start with whether your team can move from evidence to a governed action without rebuilding the context at every handoff.

    Define what “unified” must mean for your team

    Conductor is positioning unified data and SERP visuals as connected parts of SEO decision-making. Its partnership with Acquia also points toward bringing AI-powered SEO insights closer to website optimization. Those are useful signals about the platform’s direction, but they are not proof that its workflow will fit your organization.

    A unified screen is not necessarily a unified operating model. If a marketer still has to export a chart, explain it in a meeting, rewrite the recommendation in a project tool, and ask a publisher to reconstruct the reasoning, the interface has consolidated information without unifying the work.

    Use this chain to define what you actually need:

    • Evidence: The team can see where an observation came from, what it measures, and when it was captured.
    • Context: The evidence retains the relevant page, query, market, device, search surface, and business objective.
    • Interpretation: A recommendation explains the observed problem and the assumption connecting that problem to the proposed change.
    • Action: The recommendation reaches a named owner with an approval state, publishing route, and preserved rationale.
    • Learning: The team can return to the same decision after publication and compare the outcome with the original expectation.

    Data aggregation only completes the evidence layer. SEO intelligence begins when the rest of the chain remains intact. Write these requirements down before a demonstration or pilot. Otherwise, polished dashboards will pull the conversation toward what is easy to show rather than what your team needs to decide.

    Test Conductor with a real decision from your backlog

    An analyst reviews visual search evidence around one highlighted webpage while a queue of other task cards remains in the background.

    A generic product tour is a weak test because the vendor controls the query, pages, narrative, and desired conclusion. Bring a live page group with a known owner and an unresolved decision. Choose work that matters but does not require exposing sensitive customer or commercial data.

    Frame the decision before anyone opens the platform. A useful prompt might be: “Should we refresh these pages, consolidate them, change their format, or leave them alone?” That forces the platform to support a choice rather than merely surface movement in a metric.

    1. State the business purpose. Identify what the page group is meant to produce, such as qualified demand, transactions, product discovery, or support resolution.
    2. Establish the observation. Ask the operator to show the performance change and the definitions, filters, and date context behind it.
    3. Inspect the search environment. Use the SERP view to determine whether the results page, competing page types, or visible search features changed alongside your metric.
    4. Create a recommendation. Require a clear proposed action, affected page scope, expected result, alternative explanation, and accountable owner.
    5. Route the work. Send the recommendation through the workflow your content, SEO, development, and compliance teams would actually use.
    6. Preserve the decision. Make sure someone returning later can see the original evidence, what was approved, what was published, and what outcome followed.

    The platform passes this test when a teammate who did not perform the analysis can understand the decision without asking for a separate slide deck. It fails when the rationale disappears between analysis and execution, even if every individual feature looks capable.

    Pay particular attention to definitions. “Visibility,” “rank,” “traffic,” and “conversion” are not interchangeable. Ask which metric is canonical for each decision, which filters are applied, and whether an export preserves the same definitions. A unified platform can still produce conflicting answers when teams use different segments or quietly change the denominator.

    Use SERP visuals as evidence, not decoration

    A rank value tells you where a result appeared under a defined observation. It does not, by itself, show what surrounded that result or whether the search page changed shape. SERP visuals can add that missing context, but only if your team treats them as evidence with a timestamp, market, device, and query attached.

    For a query connected to a meaningful page group, ask:

    • Which page types are prominent: product pages, category pages, editorial explanations, videos, local results, or another format?
    • Which search features occupy attention before or around the organic listings?
    • Does your page satisfy the same apparent intent as the visible results, or is it competing with a different kind of answer?
    • Did your ranking move while the surrounding result composition stayed stable, or did both change?
    • Can the team retrieve the visual evidence that supported an earlier recommendation, rather than seeing only the latest state?

    Record each interpretation as an observation, implication, and next test. For example: the visible results favor category pages over long-form explanations; that may indicate a page-type mismatch; compare the affected template and intent before rewriting copy. This wording matters. It keeps a visual pattern from turning into an unsupported claim about causation.

    Do not collapse conventional SERP visibility and AI visibility into one label. AI answers, citations, brand mentions, and standard search listings are different observations. Ask exactly which surfaces Conductor captures, how each metric is defined, which markets or response modes are included, and whether historical evidence is retained. If a surface is not measured, a conventional ranking or SERP image cannot stand in for it.

    This distinction is especially important for AEO and GEO programs. A page can be technically discoverable, rank conventionally, and still fail to provide the concise claims, explicit entities, supporting detail, and clear provenance that answer systems need to interpret it. Conversely, an AI mention does not prove that the underlying page attracts qualified visits or supports a business outcome. Keep those findings connected, but do not pretend they are the same metric.

    Put governance between AI insight and publication

    Three reviewers inspect an AI-generated insight at an approval checkpoint before a webpage is allowed to move toward publication.

    An AI-generated recommendation should enter your workflow as a hypothesis, not an approval. The useful question is not whether the system can produce suggestions quickly. It is whether a reviewer can inspect the evidence, understand the proposed change, limit its scope, and reject it without losing the surrounding analysis.

    The connection between AI SEO insights and the Acquia environment could reduce the distance between analysis and website work. A shorter handoff can be valuable, but it can also move a weak recommendation toward production faster. Evaluate the control layer with the same care as the insight layer.

    Separate automation permissions by action:

    • Observe: Read data and identify patterns without creating work or changing content.
    • Recommend: Create a documented suggestion or task for a human owner.
    • Draft: Prepare a proposed edit in a reviewable environment without publishing it.
    • Publish: Change the live website only after the required approval and validation.

    Require visible permissions, preview, version history, and approval states before granting write access. Redirects, canonical tags, robots directives, structured data, and shared templates deserve production-release controls because one mistake can affect many URLs. Keep those changes staged and reviewable; do not allow a plausible-sounding recommendation to trigger a broad live edit automatically.

    Apply the same discipline to JSON-LD and other schema work. A generated schema recommendation must match the page’s visible content and actual meaning. Being generated inside an SEO platform does not make the markup accurate, eligible, or appropriate. The reviewer should be able to see the proposed properties, the content supporting them, the affected templates, and the validation result before publication.

    Finally, decide where the permanent record lives. Conductor may hold the evidence and recommendation while your CMS, project system, or governance tool holds approval and deployment state. That division is acceptable if identifiers and links survive the handoff. It becomes a problem when each system contains a different version of why the change was made.

    Key takeaways for your platform decision

    • A unified platform should preserve the chain from evidence through interpretation, ownership, publication, and outcome; a shared dashboard alone is not enough.
    • Evaluate Conductor with a live SEO decision and your real handoff process, not only a vendor-controlled demonstration.
    • Use SERP visuals to examine search-result context, while keeping observation separate from causal explanation.
    • Ask for distinct definitions and coverage for conventional search, AI answers, citations, brand mentions, traffic, and business outcomes.
    • Treat AI recommendations as reviewable hypotheses and assign automation permissions according to the risk of the proposed action.
    • Choose the platform only if another teammate can reconstruct why a change was made without relying on an analyst’s memory or a separate presentation.

    For your next evaluation session, take a real page group and an unresolved decision into Conductor. Ask the team to carry that decision from raw evidence through SERP context, recommendation, approval, publishing, and measurement. If the context survives every handoff, the platform is doing intelligence work. If your team still exports screenshots and rewrites the rationale elsewhere, you are buying consolidation rather than a unified decision system.

    References

  • How to Protect Brand Authenticity in AI-Assisted Content

    How to Protect Brand Authenticity in AI-Assisted Content

    You need to publish more useful content without turning your brand into a production line of polished, interchangeable pages. AI can remove hours of mechanical work, but it can also remove the judgment, specificity, and recognizable point of view that make your content worth choosing.

    The answer is not to keep AI out of the workflow. It is to decide where efficiency belongs, where a human must remain accountable, and what every page has to prove before you publish it.

    Content quality must serve the reader and the retrieval system

    AI is valuable because it can increase speed and automate repeatable work. The problem begins when a team treats faster production as evidence of better content.

    A page can be grammatically clean, keyword-aware, and structurally complete while still failing the reader. It may repeat familiar advice, hide the answer beneath an introduction, make claims it cannot support, or sound as though no identifiable organization chose the words.

    In the AI era, useful content has to pass several different tests:

    • Accuracy: Can you trace every meaningful factual claim to reliable evidence, and have you preserved any necessary limits or uncertainty?
    • Usefulness: Can the reader make a decision, complete a task, or notice a problem they would otherwise miss?
    • Specificity: Does the page explain the mechanism, constraint, sequence, example, or trade-off behind its advice?
    • Distinctiveness: Does it contain a judgment, method, explanation, or framing that reflects what your brand actually knows and believes?
    • Retrieval clarity: Can a relevant passage stand on its own when a search engine or answer system extracts it from the surrounding page?
    • Brand coherence: Do the vocabulary, promises, evidence standards, and level of certainty match the rest of your site?

    These tests catch different failures. Accurate but generic content is forgettable. Distinctive but unsupported content is risky. Search-ready content that reads like a machine-generated template may earn an impression without earning trust. A page is ready only when it is useful, supportable, recognizable, and easy to interpret.

    Keep human judgment where trust is created

    The safest division of labor is based on accountability, not on whether a task appears easy. Let AI transform approved material. Keep people responsible for deciding what is true, what matters, what the brand believes, and what the reader should do.

    AI is well suited to bounded transformations such as reorganizing notes, proposing outlines, generating headline alternatives, turning a long explanation into a checklist, identifying repeated language, and adapting an approved passage to another format. Those tasks have visible inputs and reviewable outputs.

    Human ownership matters most at the points where an error would change meaning or weaken trust:

    • Selecting the audience, search intent, and decision the page must support.
    • Choosing evidence and deciding which claims the evidence can genuinely carry.
    • Contributing subject expertise, exceptions, operational details, and a defensible point of view.
    • Setting the boundary between established fact, editorial judgment, inference, and uncertainty.
    • Approving promises about products, outcomes, customers, compliance, or performance.
    • Accepting final responsibility for the published page and its structured data.

    For claims that need proof, do not treat model memory as evidence. A fluent sentence can still be unsupported, overgeneralized, or detached from the conditions that made the original claim true.

    Give the model a content contract, not a loose prompt

    A prompt that asks for an authoritative SEO page leaves the important decisions unresolved. Before drafting, create a short content contract with fields an editor can inspect:

    • Reader situation: What has brought this person to the page, and what do they already understand?
    • Reader job: What should they be able to decide or do after reading?
    • Primary claim: What is the clearest answer you are prepared to defend?
    • Evidence packet: Which approved facts, documents, examples, and internal expertise may the draft use?
    • Brand position: What does your organization believe that a generic overview would not say?
    • Claim boundaries: What must not be asserted, implied, invented, or generalized?
    • Voice constraints: Which language patterns should appear, and which should be removed?
    • Retrieval target: Which question deserves a concise, self-contained answer within the page?
    • Next action: What useful step should the reader take, even if they never become a customer?

    Then run the work in an explicit sequence:

    1. A subject owner approves the reader job, primary claim, evidence, and brand position.
    2. AI proposes an outline in which every section resolves a distinct reader question.
    3. An editor removes sections that exist only to make the page look comprehensive.
    4. AI drafts from the approved contract and evidence packet.
    5. A factual pass checks claims, qualifiers, entity names, citations, and unsupported implications.
    6. A separate brand pass checks judgment, vocabulary, tone, repetition, and generic phrasing.
    7. An optimization pass improves headings, answer units, internal links, metadata, and relevant structured data without changing the approved meaning.
    8. A named human owner approves the visible content and machine-readable representation together.

    Separating the passes matters. If one reviewer tries to verify facts, improve voice, shorten sentences, and inspect schema at the same time, the visible polish can distract from a weak claim or an unhelpful answer.

    Turn brand voice into an editing system

    An editor adjusts an unlabeled instrument that turns plain gray tiles into varied designs with a consistent color palette and material style.

    Authenticity does not depend on a human typing every sentence. It comes from a consistent relationship between what your brand knows, what it believes, what it promises, and what it publishes. AI can help express that relationship, but it cannot invent it responsibly.

    Labels such as friendly, expert, bold, or conversational are too subjective to guide a draft. Replace them with observable editorial rules:

    • Beliefs: Record the principles that shape your recommendations. For example, visible content should answer the question before structured data describes the answer.
    • Audience contract: State what you owe the reader. This might include explaining constraints, separating evidence from opinion, and never hiding the practical answer behind a sales pitch.
    • Proof habits: Define when claims need links, examples, named entities, qualifications, or review by a subject expert.
    • Language choices: List preferred terminology, prohibited hype, acceptable contractions, sentence-length tendencies, and the technical terms that must remain precise.
    • Boundaries: Document claims the brand will not make, including guarantees, fabricated experience, invented customer stories, and unsupported comparisons.
    • Approved examples: Save real passages that demonstrate the voice and annotate why they work. A model needs patterns, not just adjectives.

    Consider the difference between a generic claim and an owned editorial position.

    Generic: AI is transforming content marketing and helping businesses improve efficiency.

    Owned: Use AI to compress mechanical work. Keep evidence selection, claim boundaries, and final judgment with an accountable editor.

    The second version is not stronger because it sounds more colorful. It makes a decision, draws a boundary, and tells the reader what to do differently. That is the material from which a recognizable brand voice is built.

    Use a swap test during editing: if a competitor could publish the paragraph unchanged, it probably lacks an owned insight. Do not add a slogan merely to make it sound branded. Add the missing judgment, mechanism, example, limitation, or operating rule.

    Also remove simulated experience. If your organization did not run a test, interview a customer, inspect an account, or observe a result, the draft must not imply that it did. Explain what you know and how you know it. Honest limits are part of brand voice.

    Make content easy for people and answer systems to use

    Optimization for AI search does not require stripping personality from the page. It requires making the important meaning easy to locate, interpret, and reuse without distortion.

    Build important sections as self-contained answer units:

    1. Use a heading that names the actual question or decision.
    2. Answer it in the opening sentence without forcing the reader through background first.
    3. Explain why the answer holds or how the mechanism works.
    4. Name the condition, exception, version, audience, or limitation that changes the advice.
    5. Give the reader a concrete next action.
    6. Link the words carrying an evidence-dependent claim, rather than attaching an unexplained list of links.

    The opening answer provides clarity. The mechanism and limitation provide trust. The recommended action is where brand judgment becomes visible. You can therefore write a passage that is both extractable and distinctly yours.

    Run a context test on each candidate answer unit. Copy the passage into a blank document and ask:

    • Is the subject named, or does the passage depend on a vague pronoun?
    • Can a reader tell whether the statement is a fact, recommendation, definition, or opinion?
    • Are material conditions and exceptions still present?
    • Does the passage identify the product, organization, feature, standard, or audience precisely?
    • Would the passage remain accurate if displayed without the preceding paragraph?

    If the answer unit fails outside its original context, revise the language rather than stuffing more keywords into it.

    Consistency also matters across the site. Use one canonical name for your organization, products, services, features, and authors. Explain genuine synonyms, but do not rotate terminology simply to create lexical variety. Unnecessary variation makes it harder for a person or system to determine whether two passages refer to the same entity.

    Apply the same discipline to JSON-LD and other structured data. Markup should represent the visible page accurately. It should not introduce credentials, ratings, offers, authorship, answers, or relationships that the reader cannot verify in the content. Schema can clarify a strong page; it cannot supply the substance the page is missing.

    Finally, use internal links to connect a concise answer with the deeper proof behind it. A summary page can resolve the immediate question, while a supporting page explains the method, terminology, evidence, or implementation. This creates a useful path for readers without forcing every page to become an exhaustive encyclopedia.

    Replace output metrics with a publish gate and feedback loop

    A circular track carries blank page-shaped objects through a human review station, with one sent back for revision and another released to waiting readers.

    Traditional quality metrics are not enough for AI-first content. Word count, production volume, grammar checks, and a passing optimization score can describe the artifact or workflow, but they cannot establish that the page is accurate, useful, distinctive, or trusted.

    A useful measurement system separates four kinds of signals:

    • Production signals: Track drafting time, approval loops, substantial rewrites, and where work repeatedly returns to an earlier stage. These reveal workflow efficiency, not content quality by themselves.
    • Integrity signals: Track unsupported-claim flags, citation gaps, correction requests, entity inconsistencies, and mismatches between visible content and structured data.
    • Brand signals: Track prohibited language, failed swap tests, unapproved promises, simulated experience, and sections that lack an identifiable editorial position.
    • Discovery signals: Where your tools can observe them, track the queries that surface the page, branded and non-branded visibility, citations or mentions in answer experiences, and referrals from AI interfaces.
    • Outcome signals: Match the page to its intended job, such as a completed setup, qualified inquiry, subscription, product comparison, or movement to a deeper supporting page.

    Read these signals together. Faster production accompanied by more factual corrections means the workflow moved effort downstream rather than removing it. Strong visibility with weak outcomes may indicate that the page answers the query but does not help with the decision behind it. Good engagement with repeated swap-test failures means the page may be useful while doing little to build brand recognition.

    A composite quality score can help you prioritize review, but it should not own the publishing decision. Use a simple editorial gate:

    • Block: A material claim lacks evidence, the page invents experience, a required limitation is missing, an entity is misrepresented, or structured data asserts something the visible page does not support.
    • Revise: The answer is buried, advice remains generic, sections repeat one another, the next action is unclear, or the language fails the brand’s documented rules.
    • Publish: The page answers a real reader need, important claims are supportable, brand judgment is visible, answer units survive the context test, and a named owner accepts responsibility.

    After publication, feed what you learn back into the system. Log corrections with their causes. Add strong and weak passages to the annotated voice examples. Update the content contract when reviewers keep fixing the same omission. Revisit important pages when the offer, evidence, entity information, or reader decision changes.

    Key takeaways

    • Use AI for bounded, reviewable transformations; keep people accountable for evidence, judgment, promises, and approval.
    • Define brand voice through beliefs, proof habits, language rules, boundaries, and annotated examples rather than vague tone adjectives.
    • Write self-contained answer units that give a direct answer, explain the mechanism, preserve limitations, and recommend a useful action.
    • Keep entity language, visible content, internal links, and structured data consistent.
    • Measure production efficiency separately from integrity, brand distinctiveness, discovery, and reader outcomes.
    • Block publication when a material claim, implied experience, or machine-readable assertion cannot be supported.

    Start with one commercially important page. Write its content contract, mark every evidence-dependent claim, run the swap and context tests, and compare its structured data with what a reader can actually see. The weaknesses you find will tell you exactly which rules your wider AI content workflow needs next.

    References

  • CrushPress AI Actions: Reliable Workflow Automation

    CrushPress AI Actions: Reliable Workflow Automation

    If your AI visibility process ends with a crowded inbox, an unassigned alert, or a spreadsheet nobody revisits, automating it will only produce clutter faster. A useful Action must turn a meaningful signal into an owned decision, preserve the evidence behind it, and define how you will know the work is finished.

    The practical promise behind Actions is to reduce repetitive handling and make AI visibility work more efficient. Real reliability, however, comes from the workflow around the automation: the trigger, decision rule, evidence, owner, review gate, and verification step.

    Define the decision before you automate the task

    Start with a recurring decision that currently requires someone to collect the same information, apply the same rule, and route the result. Do not start with a vague goal such as “improve AI visibility.” An Action cannot execute that goal because it does not identify what changed, what should happen next, or who can approve the response.

    A better starting question is: “What decision keeps waiting because the evidence is scattered?” In an AI visibility workflow, that might be whether a new brand claim needs correction, whether a missing citation points to a content gap, whether a tracked answer changed enough to investigate, or whether an observation is merely noise that should be logged without creating work.

    Write a workflow contract before configuring the Action. It should contain:

    • Outcome: The operational result you want, such as an approved correction task or a content brief ready for review.
    • Trigger: The observable event that starts the workflow. Describe the event, not the desired conclusion.
    • Required evidence: The fields that must exist before the workflow is allowed to continue.
    • Decision rule: The condition that separates “act,” “review,” “observe again,” and “ignore.”
    • Output: One bounded deliverable with a predictable structure.
    • Owner: The role responsible for accepting, rejecting, or completing the output.
    • Stop condition: The point at which the Action must end rather than starting another loop.
    • Verification rule: The evidence required to mark the result as checked, not merely completed.

    For example, “alert the SEO team when visibility drops” is not yet a workflow. “When a tracked query produces a materially different answer, capture the old and new observations, classify the change, and create an investigation brief for the named owner” is much closer. It specifies a trigger, evidence, classification, output, and destination without pretending the automation already knows the cause.

    Use a simple readiness test: can the owner make the intended decision from the Action’s output without reopening every tool used upstream? If not, the automation has moved the repetitive work rather than removed it.

    Build a closed loop for AI visibility changes

    Glowing signals converge into a beacon that moves through a circular observation, action, and verification system.

    AI-generated answers can vary across runs, models, interfaces, languages, and locations. A single observation is therefore evidence of what appeared in that context, not automatic proof of a durable visibility trend. Your workflow should preserve that context before it attempts to classify the result.

    A practical visibility loop

    1. Observe: Start from a defined query or query set on a chosen AI surface. Avoid mixing unrelated prompts into one trigger.
    2. Capture: Save the exact prompt, answer, model or interface, observed time, relevant language or market, cited pages, and any brand or competitor mentions needed for review.
    3. Compare: Evaluate the observation against a declared expectation or earlier observation. Keep the raw evidence alongside the comparison.
    4. Classify: Route the result into a limited set of operational states, such as no meaningful change, uncertain result, incorrect claim, missing mention, citation gap, content gap, or competitor displacement.
    5. Act: Produce one appropriate output. That might be a correction task, investigation brief, content brief, structured-data review, escalation, or no-action record.
    6. Verify: Recheck the same success criterion in a planned observation window, while retaining the model and interface context.

    The separation between observation and classification matters. If an Action turns every changed answer into an optimization task, ordinary output variation becomes a queue of false emergencies. A classification stage lets you require more evidence when the result is ambiguous and reserve immediate action for clear, consequential problems.

    Example: route a potentially incorrect brand claim

    Suppose a tracked answer contains a claim that conflicts with your approved brand facts. The Action should not jump directly to rewriting a page or publishing corrective content. Design the loop like this:

    • Trigger: A captured answer contains a claim that appears inconsistent with the approved fact set.
    • Evidence packet: Include the exact prompt, complete surrounding answer text, AI surface, cited URLs, observation context, conflicting approved fact, and link to the canonical internal record.
    • Decision gate: A reviewer confirms whether the statements actually conflict and whether the issue is consequential.
    • Action: Create a correction plan that identifies the canonical page, structured data, documentation, or third-party information requiring investigation.
    • Approval: Require an authorized owner to approve any public edit, deletion, or external response.
    • Verification: Confirm that the approved source of truth was corrected, then record later AI observations separately from the operational completion.

    This distinction prevents an important reporting error. Completing a content or data correction proves that your team performed the approved work. It does not prove that the correction caused a particular model to change its answer. Track “work completed” and “visibility outcome observed” as separate states.

    Verification should test the original condition

    A generic “done” status tells you that a task moved through the system. It does not tell you whether the initiating problem was resolved. Write the verification rule when you create the workflow, using the same language as the trigger.

    If the trigger is an incorrect brand claim, verification asks whether the approved source of truth is now accurate and whether later observations still contain the claim. If the trigger is a citation gap, verification asks whether the target page became a stronger, accessible source and whether subsequent answers cite it. If the trigger is a visibility change, verification repeats the planned observation method rather than substituting a different prompt or surface.

    Make every handoff carry its own evidence

    A brittle automation often fails at the handoff. The Action detects something real, but the destination receives a title such as “Check AI visibility” with no prompt, answer, comparison, or reason for the priority. The assignee must reconstruct the investigation before making a decision.

    Prevent that failure by treating the evidence packet as part of the deliverable. Every routed item should answer these questions:

    • What was observed? Preserve the exact text or structured result, not only a generated summary.
    • Where did it occur? Identify the AI surface, model or interface when available, query, language, market, and relevant source URLs.
    • What changed? Show the comparison or rule that activated the workflow.
    • Why was it classified this way? Expose the decision rule instead of presenting the label as unquestionable.
    • What remains uncertain? Label suspected causes as hypotheses. Do not let generated explanations masquerade as established facts.
    • What should the owner decide? Ask for a specific approval, rejection, prioritization, correction, or investigation decision.
    • What would close the item? State both the operational completion condition and the later visibility check.

    Route by issue type before routing by team. “Content,” “technical,” or “communications” may describe a destination, but they do not explain the problem. A useful classification identifies the issue first: unsupported claim, stale canonical fact, inaccessible source, weak answer coverage, structured-data inconsistency, or uncertain observation. The destination can then follow from that diagnosis.

    Measure decision quality, not automation volume

    Task count is a poor success metric. A noisy workflow can create many tasks while making the team slower. Use operational measures that reveal whether the Action improves the decision process:

    • Useful-signal rate: How often reviewers agree that a routed item deserved attention.
    • Time to ownership: How long a valid signal remains unassigned or undecided.
    • Rework: How often the owner must retrieve missing evidence, change the classification, or rebuild the requested output.
    • Closure quality: How often completed items include the required approval and verification record.
    • Repeated failure: Which triggers, fields, or destinations create the same rejection or exception pattern.
    • Observed outcome: Whether later checks satisfy the declared visibility criterion, recorded without claiming unsupported causation.

    Review rejected and corrected outputs as design feedback. If reviewers repeatedly change the same classification, the rule is probably ambiguous. If they repeatedly ask for the same missing field, add it to the evidence contract. If valid items stall after assignment, the problem is ownership rather than detection.

    Add review gates and failure controls before scaling

    Two professionals pass a transparent evidence case through a guarded review checkpoint with inspection and recovery controls.

    The right automation boundary depends on the consequence of being wrong. Capturing evidence is reversible. Publishing a factual claim, deleting content, changing structured data, contacting an external party, or altering permissions can create reputational, technical, or legal exposure. Put explicit approval in front of those actions and provide the reviewer with a preview or difference view wherever possible.

    Automate preparation before irreversible choices

    A sensible responsibility split looks like this:

    • Safe to automate: Evidence capture, formatting, deterministic field validation, duplicate detection, status updates, routing, and creation of a reviewable draft.
    • Automate with review: Intent grouping, issue classification, priority suggestions, root-cause hypotheses, content recommendations, and proposed schema changes.
    • Require explicit approval: Publishing, deletion, public corrections, external outreach, access changes, and any claim whose accuracy or wording carries material consequences.

    Generated drafts should remain drafts until an accountable person approves them. This is especially important when the input is an AI-generated answer: the workflow is processing an output that may itself be incomplete, variable, or wrong.

    Give failures a visible destination

    An Action is not ready merely because its successful path works. It is ready when a failed run is legible, contained, and recoverable. Build or document these controls around it:

    • Required-field validation: Stop the workflow when the evidence needed for a decision is missing.
    • Duplicate protection: Use a stable combination of query, observation, issue, and destination so repeated detection does not create competing tasks.
    • Scoped permissions: Give the workflow access only to the systems and operations it needs.
    • Bounded retries: Prevent a failing destination from producing an uncontrolled loop of repeated attempts.
    • Visible exceptions: Send failed and uncertain runs to a named owner with the input, error state, and last successful step intact.
    • Versioned rules: Record which prompt, classification logic, template, and approval policy produced each output.
    • Recovery path: Preserve the prior state or require a reversible draft when an automated step could change content or data.

    If a particular control is not available inside the Action itself, put it in the surrounding operating process. Do not assume that a successful status means the destination accepted the right data, that a retry is harmless, or that a generated classification is safe to publish.

    Roll out with known cases before live expansion

    1. Replay resolved cases: Feed the workflow examples whose correct routing and outcome are already known. Include ambiguous, duplicate, incomplete, and no-action cases.
    2. Run in shadow mode: Let the Action produce a log or draft without changing production content or contacting anyone externally.
    3. Limit the live scope: Start with one trigger family, one output type, and a named owner who can inspect exceptions.
    4. Correct the contract: Update missing fields, ambiguous rules, permissions, and failure handling based on actual review patterns.
    5. Expand by pattern: Reuse the proven structure for adjacent workflows while keeping each Action’s trigger, owner, and success condition explicit.

    Name each workflow so its behavior is obvious: “trigger → decision → outcome.” A name such as “tracked claim conflict → reviewer confirmation → correction plan” is easier to operate than “AI monitoring automation.” It also makes overlapping or redundant Actions easier to spot.

    Key takeaways

    • Automate a recurring decision with a defined outcome, not a broad ambition such as improving visibility.
    • Preserve the prompt, answer, AI surface, comparison, and source context before classifying a visibility change.
    • Keep operational completion separate from later AI visibility observations; the latter does not automatically prove causation.
    • Make the evidence packet complete enough for the owner to decide without reconstructing the investigation.
    • Require human approval for publishing, deletion, external communication, permissions, and consequential factual or structured-data changes.
    • Scale only after duplicate handling, visible exceptions, ownership, verification, and recovery work on known cases.

    Your best first CrushPress AI Action is the recurring visibility decision that consumes attention without requiring novel judgment every time. Define its evidence packet, make its output reviewable, and test its failure path. Once that loop closes reliably, use the same contract to automate the next decision.

    References