Tag: Clarity

  • How to Optimize Content for Humans and AI Discovery

    How to Optimize Content for Humans and AI Discovery

    Your page has two jobs before it can earn a business result. A person must understand why it matters, and a search or AI system must be able to identify what it says without guessing. Treat those as separate writing assignments and you usually get a stiff “AI version” alongside a more expressive page whose meaning remains implicit.

    Use one clarity-first page instead. Make its meaning explicit, its value hard to substitute and its next action easy to complete. That approach matters because generic informational content now competes with direct AI answers while visibility becomes scarcer. Publishing more is not enough. Each page must be understandable, retrievable, memorable and useful.

    Optimize the shared information, not two separate audiences

    People and AI systems process a page differently, but they tend to struggle at the same points: an unclear subject, an unsupported claim, an unexplained term, a buried qualification or an ambiguous next step. That is why clear messaging, usable experiences and technical precision form a shared foundation for people and automated systems.

    A person can sometimes infer meaning from visual position, tone or previous experience. An automated system may depend more heavily on labels, surrounding text and explicit relationships. The answer is not to flatten your writing into robotic prose. Keep the voice, examples and visual hierarchy that help people, but state the essential facts in text that can stand on its own.

    Page elementWhat a person needsWhat an AI system needs to identifyShared treatment
    OpeningWhether the page is relevantThe primary subject, audience and outcomeGive a direct answer or promise before background
    HeadingsA fast route to the right detailClear boundaries between subtopicsUse descriptive headings that name the question or decision
    EvidenceA reason to believe the claimThe relationship between a claim, its support and its limitsPlace support and qualifications beside the claim
    Call to actionConfidence about what happens nextThe action available and its destinationUse a specific label and a working, direct path

    Key takeaways

    • Optimize one canonical page for shared clarity instead of creating separate human and AI versions.
    • Put the main answer, offer or decision near the beginning, then add the context needed to evaluate it.
    • Use descriptive headings and self-contained sections so readers and systems can locate the right passage.
    • Keep evidence, definitions and limitations close to the claims they support.
    • Make the primary next action explicit in both its wording and its destination.
    • Plan how the page will reach its audience before committing resources to its production.

    Build every page as a question-to-action path
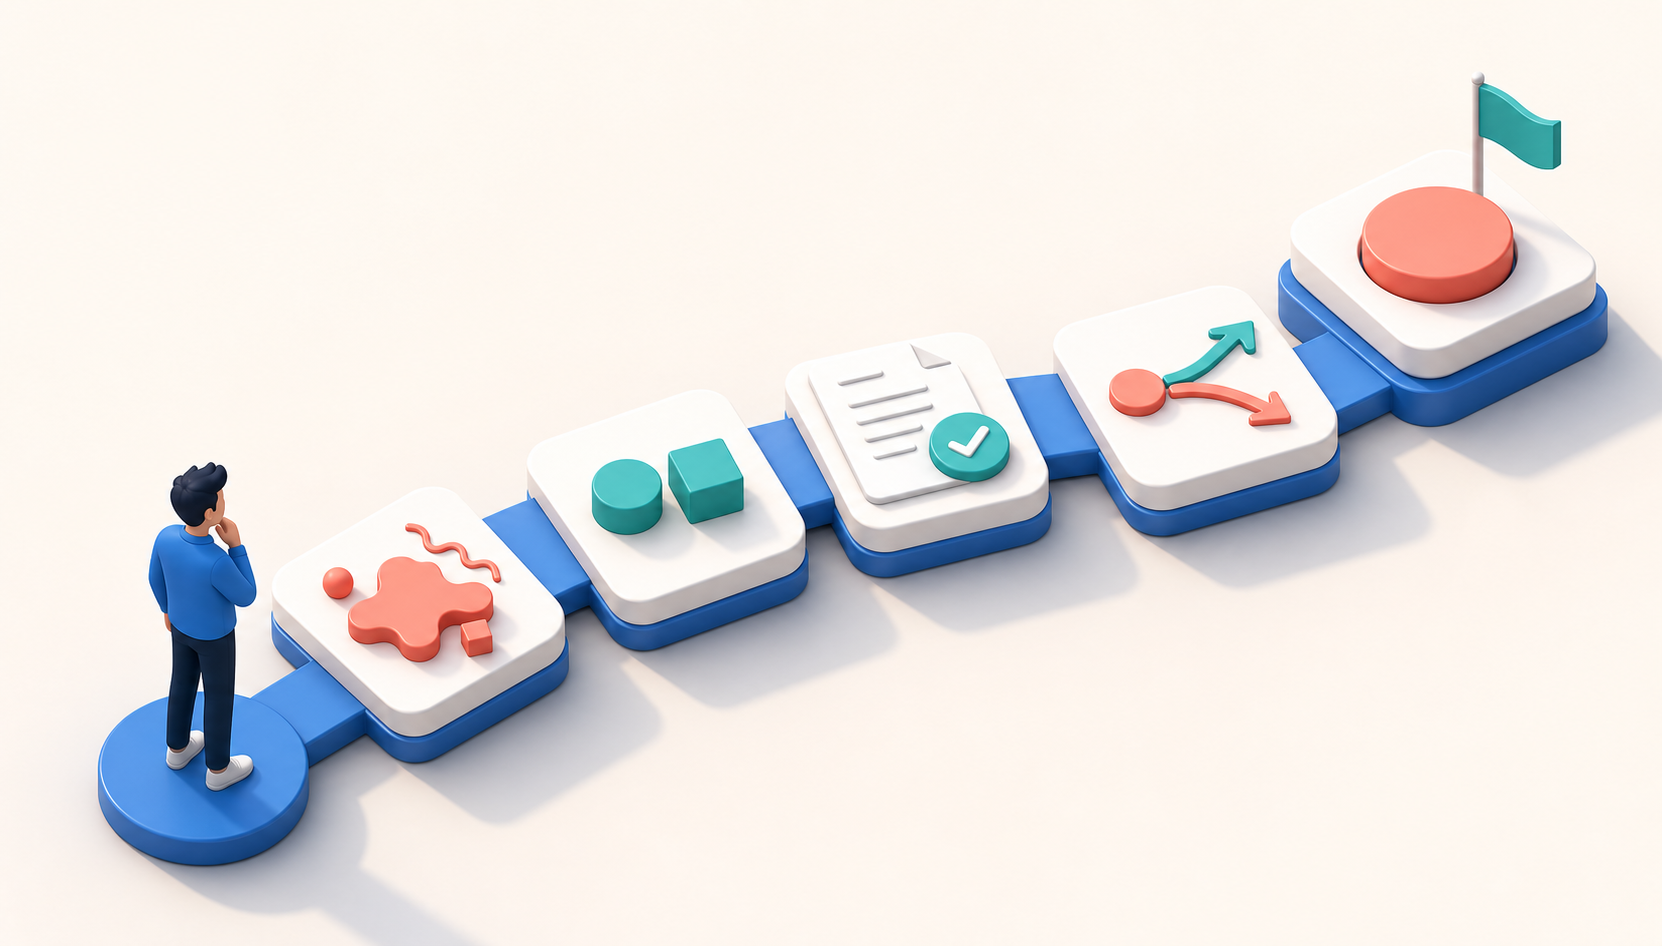
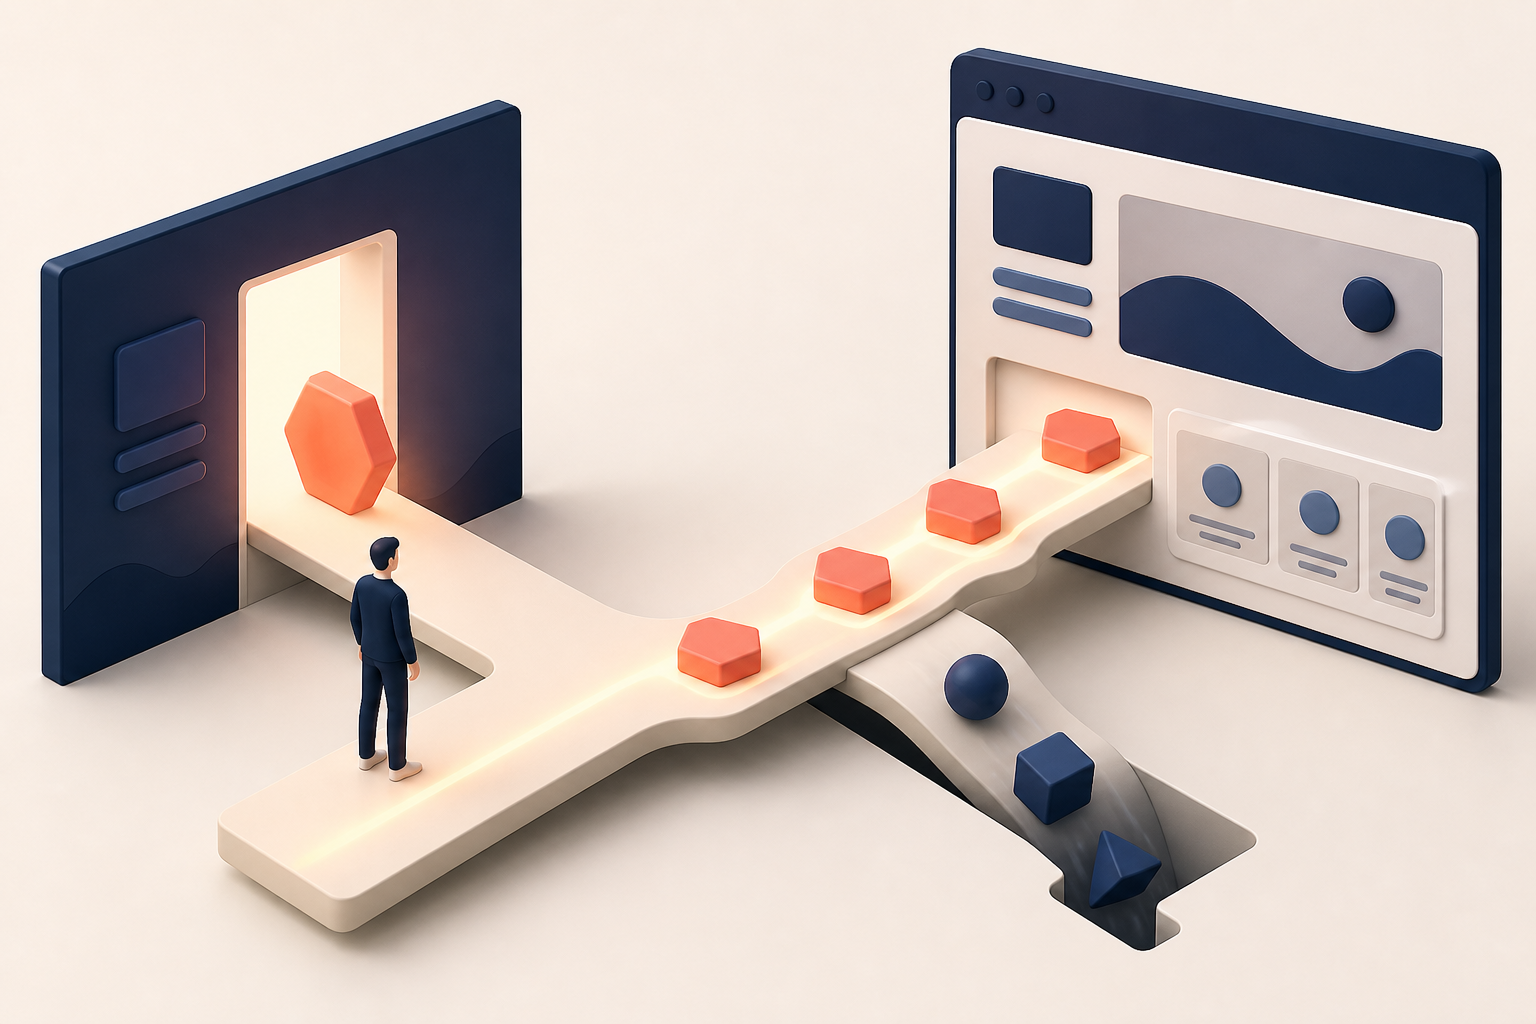
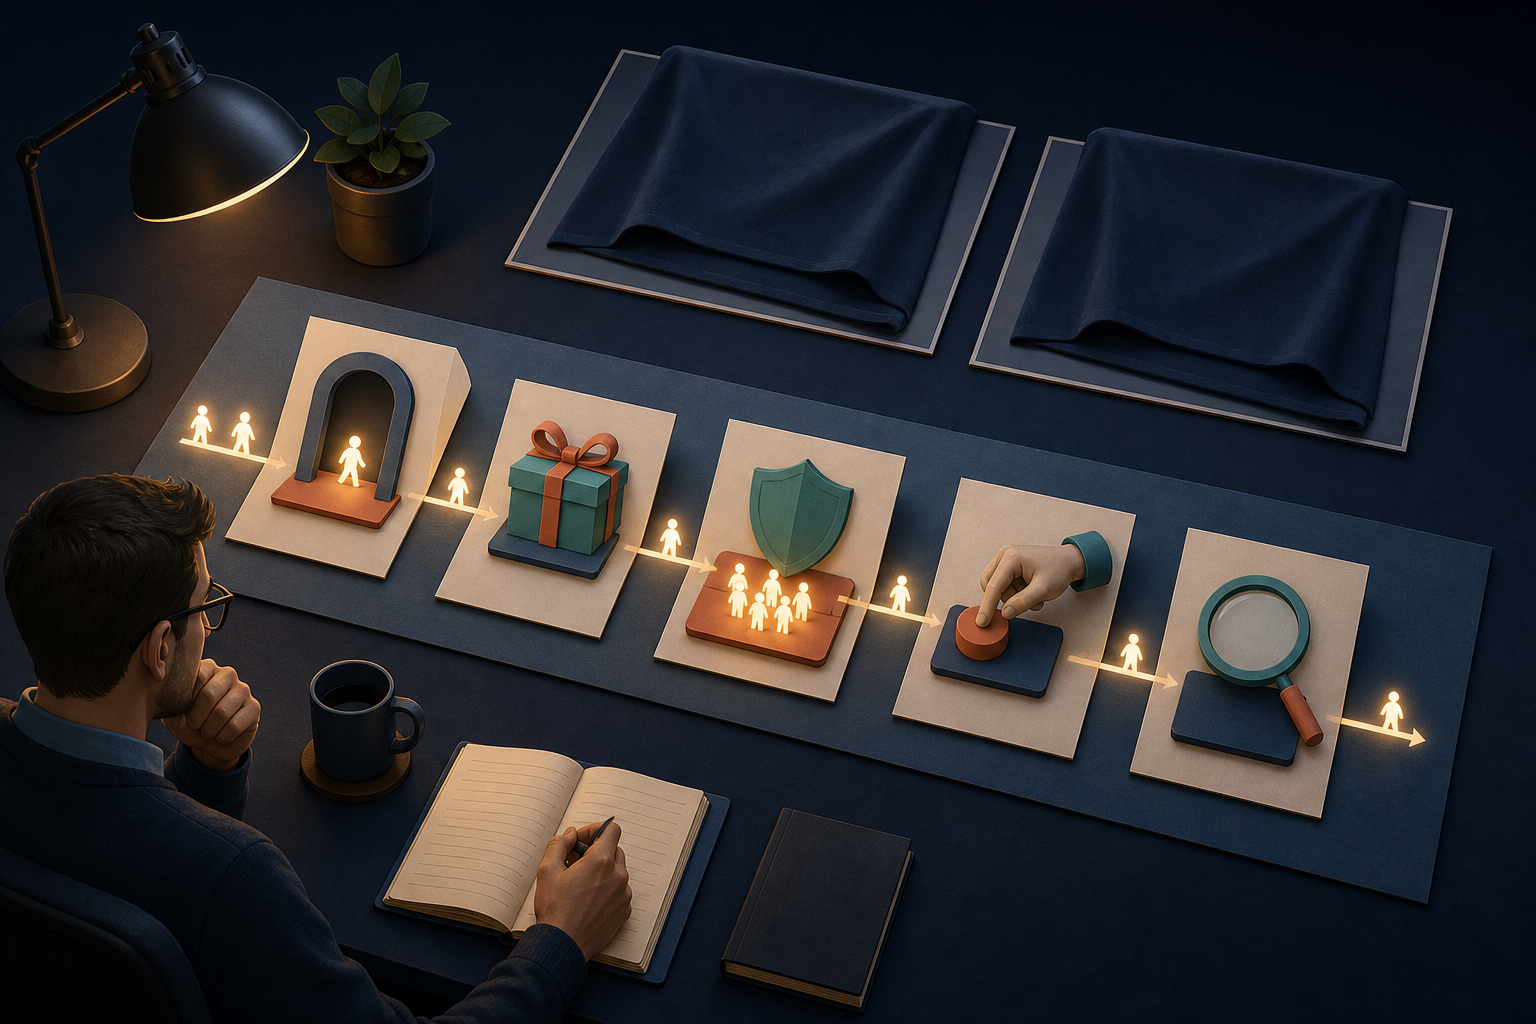
    A person follows a connected path of blank content cards from an initial question to a final action control.

    Optimization starts before the draft. Write a three-line page contract that prevents the page from drifting into a broad topic summary:

    • Audience: Who is making a decision or trying to complete a task?
    • Promise: What will this page help that person understand, choose or do?
    • Action: What should become possible after the promise has been fulfilled?

    Be specific enough that an editor could reject material that does not belong. “People interested in AI SEO” is too broad. “A content lead deciding how to revise service pages for human visitors and AI discovery” establishes a reader, a page type and a decision.

    1. Choose one dominant job. Decide whether the page primarily helps someone learn, compare, evaluate, buy or complete an action. A page may support secondary needs, but it should not give all of them equal weight.
    2. Answer before explaining. State the conclusion, offer or recommended direction early. Background belongs after the reader knows why it matters.
    3. Develop a visible reasoning chain. Move from the answer to the mechanism, supporting evidence or criteria, important limitations and the appropriate next step.
    4. Name important entities consistently. If you alternate among a product name, category name and vague phrases such as “the solution,” neither the reader nor a downstream system should have to infer whether they refer to the same thing.
    5. Close the loop. The call to action should follow from the page’s promise. A comparison page might lead to a specification, consultation or purchase path. An instructional page should let the reader perform or verify the task it explained.

    Then perform a sentence-level clarity audit. Replace pronouns whose antecedents are uncertain. Define an acronym at first use. Remove adjectives such as “advanced,” “leading” or “seamless” unless the page supplies a basis for them. Put exceptions beside the rule instead of hiding them in a closing note. Replace generic links such as “click here” and “learn more” with labels that identify the destination or action.

    A useful stress test is whether a 10-year-old could roughly explain what you offer, why it matters and how someone engages with it. That clarity test is meant to expose unnecessary complexity, not to make a technical subject childish. Keep the precise terms your audience needs, but define them in the same section where they become relevant.

    Write modules that survive scanning, extraction and reuse
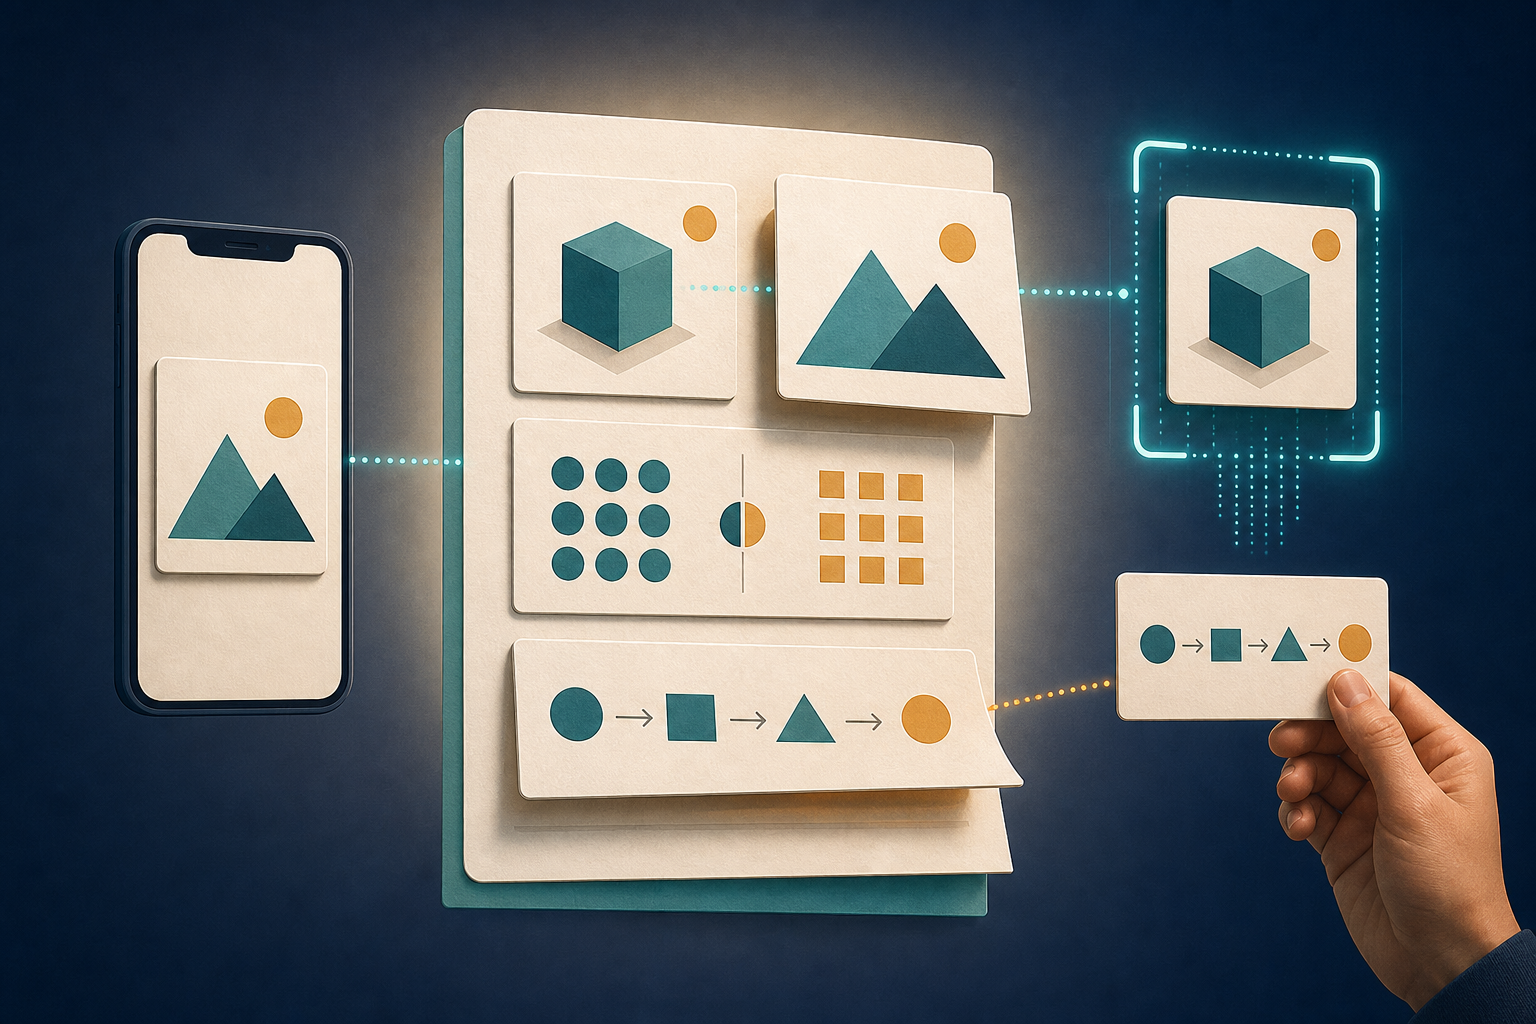
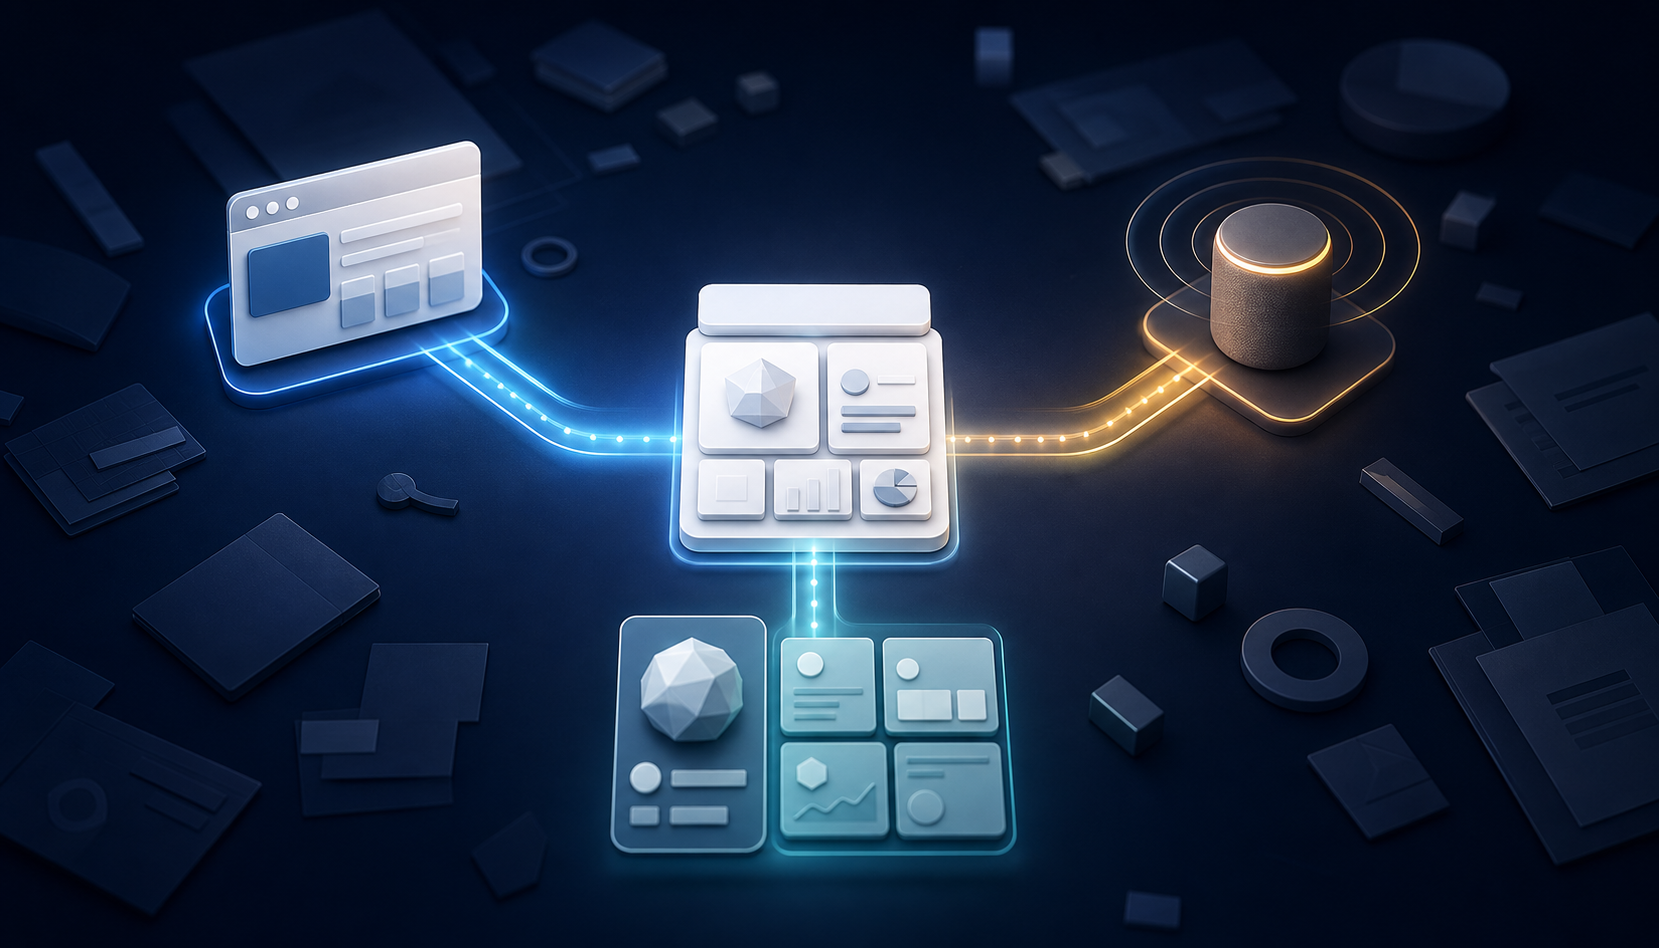
    Blank visual content modules move from a central page into a mobile screen, an AI extraction frame, and a reader's reference card.

    There is no universally correct amount of text for a page. The right length is the amount required to explain the offer or answer, establish why it is credible, distinguish it from alternatives and support the intended action. A long page can be easy to use when it is modular. A short page can still fail when it omits the facts needed to decide.

    Give each section a repeatable internal shape:

    1. Descriptive heading: Name the subquestion, criterion or decision addressed by the section.
    2. Direct opening: Answer that subquestion in the first sentence or paragraph.
    3. Support: Add the mechanism, evidence, definition, example or comparison needed to evaluate the answer.
    4. Boundary: State any condition under which the answer changes or does not apply.
    5. Implication: Tell the reader what to notice, decide or do with the information.

    This structure makes a section useful when someone scans directly to it. It also reduces the risk that a sentence will be extracted without the qualifier that changes its meaning. Do not repeat the same conclusion in every module. Each section should advance the decision.

    Match formatting to the relationship in the information. Use bullets for criteria of the same kind, numbered lists when sequence matters and tables only when readers need to compare the same attributes across multiple options. Use images when they explain something the text cannot show as efficiently. Relevant alt text should communicate the image’s purpose or information, while decorative imagery should not be forced to carry a claim. Readable typography, adequate contrast and meaningful image descriptions support accessibility as well as comprehension.

    Once the visible copy is stable, align the structured layer. Treat JSON-LD as a machine-readable restatement of facts on the page, not as a second marketing message. Entity names, descriptions, relationships and available actions should agree with what a visitor can see. Do not add a claim to structured data that the page does not substantiate, and do not expect schema to rescue copy whose subject or purpose is unclear.

    • Use the same preferred name for the organization, product, service or person in the copy and structured data.
    • Make each marked-up type match the thing the page actually describes.
    • Keep dates, status information and other changeable facts synchronized wherever they appear.
    • Ensure an action described in structured data resolves to a real, functioning destination.
    • Remove obsolete markup when the corresponding visible content or capability is removed.

    When an AI agent must interact with tools or shared information rather than merely read a page, connection standards such as Model Context Protocol can help systems reach those resources. But clean, well-structured and actionable information is still required downstream. Connectivity does not correct an ambiguous offer, an unsupported statement or a broken workflow.

    Add value that cannot be replaced by a generic summary

    A generic explanation can be accurate and still be strategically weak. If a capable system can reproduce the page’s entire value from common knowledge, the reader has little reason to remember your brand or visit for the next step. As content production becomes easier, originality, distinctiveness and deliberate distribution carry more of the visibility burden.

    Do not confuse originality with novelty for its own sake. A useful page becomes harder to substitute when it contributes at least one defensible unit of value:

    • A decision rule: A clear way to choose between options, including the condition that changes the choice.
    • A bounded position: A recommendation that states where it applies, where it does not and why.
    • Owned evidence: Substantiated data, examples, observations or methods that your organization is entitled to publish.
    • An operational method: A checklist, sequence, template or diagnostic that lets the reader perform the work.
    • A revealing limitation: A tradeoff or failure mode that generic descriptions tend to omit.
    • A distinctive asset: A useful visual, framework or recurring editorial device that people can recognize and share.

    Use only material you can support. Invented data, anonymous anecdotes and manufactured certainty may make a page look specific, but they weaken trust and make its claims unsafe to reuse. Precision includes saying when evidence is limited or a recommendation depends on context.

    Apply a substitution test before publication. Could a competitor replace the logo and publish the page unchanged? Does the page contain a rule someone can use, or only a summary of the topic? Is there a sentence that expresses a recognizable point of view? Would a partner have a concrete reason to share it? If every answer points to interchangeability, revise the value proposition before polishing metadata.

    Distinctive content still needs a route to attention. Reverse the volume-era workflow that publishes first and asks about promotion later. Media, partnerships and events can push useful work toward an audience instead of leaving discovery entirely to search. Complete a distribution brief before approving the draft:

    • Audience: Name the specific group that will use the page and the decision it helps them make.
    • Carrier: Identify the newsletter, partner, community, media relationship, event, paid placement or owned channel capable of reaching that group.
    • Reason to share: State the practical value the carrier can offer its audience by distributing the work.
    • Portable asset: Choose the checklist, chart, decision rule, example or excerpt that can travel without stripping away the meaning.
    • Destination: Decide where interested people should land and what they should be able to do there.

    If you cannot identify a credible carrier or reason to share, that is useful information. Narrow the audience, strengthen the original contribution or reconsider whether the page deserves production. Distribution should shape the content brief, not become a rescue operation after publication.

    Use a publish gate for clarity, action and delivery

    Technical optimization belongs after the message and user path are coherent. It can expose and remove friction, but it cannot manufacture relevance. A fast, marked-up page with a vague offer remains vague. The final review should test meaning, task completion, rendering, discovery and distribution as one system.

    Run the same comprehension test with a person and an AI assistant

    Give the page to a colleague who was not involved in writing it. Ask that person to identify the intended audience, main answer or offer, supporting evidence, important limitation and primary next action. Do not explain the page before the test.

    Then give an AI assistant only the visible page copy and use this prompt: “Identify the intended audience, main claim or offer, supporting evidence, limitations and primary next action. Quote the text that supports each answer. If an answer is unsupported, write ‘not stated.’” Compare both responses with the page contract.

    A correct AI response does not prove that the page will rank, appear in an answer or receive a citation. Treat the exercise as an ambiguity detector, not a visibility score. When the assistant invents a benefit, misses a limitation or chooses the wrong action, find the wording or structure that allowed the misreading. The same ambiguity may also be costing human comprehension.

    Complete the action yourself

    • Follow the primary call to action and confirm that its destination matches its label.
    • Test phone numbers, email links, forms, validation messages and confirmation states where they are part of the path.
    • Remove form fields and separate steps that are not required to complete or qualify the action.
    • Check that a user can recover from an error without re-entering unrelated information.
    • Confirm that transactional or lead-generation intent is stated in visible language instead of being implied only by a button or form.

    Clear calls to action and simple task paths matter because unclear checkout and lead-generation flows obstruct people and automated agents alike. A button labeled “Submit” identifies an interface event. A label such as “Request the estimate” identifies the user’s action and expected outcome.

    Inspect the experience that carries the content

    • Load the page at common desktop and mobile widths and check whether text, controls or media move after they first appear.
    • Remove intrusive overlays, excessive advertising and visual elements that compete with the page’s primary purpose.
    • Check contrast, text readability, keyboard access, control labels and meaningful alternative text.
    • Verify that the complete page renders, internal resources load and security warnings are absent.
    • Review the visible copy and structured data after deployment rather than assuming the content management system published both correctly.

    Large layout shifts, incomplete rendering, weak contrast, malware warnings and disruptive pop-ups undermine usability and trust. Fix those problems because they interfere with the experience, not because a technical score can replace a clear answer.

    Measure the page by the job it was built to do

    Traffic remains useful context, but it is not a complete outcome. Informational visits have always been a proxy for business progress, and direct answers make that proxy less dependable on its own. Keep a small scorecard tied to the page contract:

    • Comprehension: Record which parts people or AI extraction tests misinterpret, omit or overstate.
    • Action: Track starts, completions, abandonment and errors for the page’s intended task.
    • Discovery: Monitor the relevant queries, impressions, brand mentions and AI-answer appearances that matter to the defined audience.
    • Demand and memory: Watch branded search, direct or returning visits and voluntary brand engagement without treating any one measure as conclusive.
    • Distribution: Record placements, partner participation, qualified referral activity and reuse of the portable asset.

    Tools can make individual checks easier. IndexNow can notify participating search engines about a changed URL more quickly, though notification is not a promise of indexing or visibility. Microsoft Clarity can reveal behavioral friction, including problems in chatbot experiences. Both are diagnostic aids for updates and user behavior, not substitutes for editorial judgment.

    Start with the page closest to a meaningful customer decision. Make its promise and action unmistakable, align its structured data, run the paired comprehension test and give it a real distribution path. Once that page passes, turn the same publish gate into the default for every high-value page you create or revise.
    References

  • Rubric-Based AI Prompting: A Practical Reliability Framework

    Rubric-Based AI Prompting: A Practical Reliability Framework

    The draft looks finished. The structure is clean, the tone is right, and the citations look plausible. Then you check one claim and discover that the evidence is not there. Editing that sentence treats the symptom; the prompt still rewards a complete answer more than a defensible one.

    Rubric-based prompting changes that incentive. You tell the model not only what to produce, but how to decide whether it has enough support, when it may infer, when it must qualify, and when it should stop. That is the difference between requesting a polished deliverable and defining a controlled production process.

    Why polished prompts still fail when information is missing

    A conventional prompt usually describes the destination: write an article, analyze a competitor, summarize a document, or recommend a strategy. It may specify the audience, tone, length, headings, and output format. Those instructions can improve presentation without resolving the most important question: what should the model do when it cannot support part of the requested answer?

    If you request a complete deliverable but provide incomplete evidence, the model faces competing objectives. It can acknowledge the gap and leave part of the task unfinished, or it can produce something fluent enough to resemble completion. Unless you define which objective has priority, fluency can win.

    This matters in content, SEO, AEO, and GEO workflows because unsupported material rarely stays in one draft. A fabricated statistic can migrate into a headline, executive summary, FAQ, metadata, structured data, presentation, or client recommendation. The first error may be a sentence. The operational problem is the chain of assets built from it.

    The downside is not theoretical. In 2025, Deloitte had to refund substantial costs associated with a government report containing AI errors, including fabricated citations. That is an extreme outcome, but it illustrates the basic risk: an authoritative-looking answer can travel farther than its evidence warrants.

    A vague prompt is not the only reason an AI system can be wrong, and no rubric can guarantee truth. Models can misunderstand material, mishandle conflicting evidence, or generate an incorrect answer despite clear instructions. A rubric addresses the preventable part of the problem: ambiguity about evidence, uncertainty, inference, and failure behavior.

    The distinction is simple. A prompt describes what a successful output should contain. A rubric defines the decisions the model must make when success is not fully possible. It replaces requests such as be accurate or do not hallucinate with conditions that can actually govern the response.

    Build the rubric around decisions, not aspirations

    Hands sort abstract document cards through green, amber, and red decision paths for supported, uncertain, and unsupported material.

    An instruction such as use reliable information sounds responsible, but it leaves every operational term undefined. Which information is authorized? What counts as support? May the model draw an inference? Should it omit an unsupported section, qualify it, or ask you a question?

    A useful rubric resolves those choices before generation starts. Build yours around the following decisions.

    1. Define the evidence boundary. Name the material the model may use: supplied documents, approved URLs, a product fact sheet, a transcript, a dataset, or general background knowledge. If freshness matters, state whether information outside the supplied material is prohibited or must be separately verified. Do not use an open-ended phrase such as credible sources when you need a closed evidence set.
    2. Classify claims by support. Tell the model to distinguish facts directly supported by the authorized material from reasonable inferences, unresolved conflicts, and unavailable information. Give each state a visible treatment. A supported fact may be stated normally. An inference should be labeled. A conflict should remain visible. An unavailable claim should be omitted or marked as needing evidence.
    3. Identify material uncertainty. Not every missing detail should stop the task. Define a gap as material when it could change the central claim, recommendation, audience, scope, or risk. The model may proceed with a harmless formatting choice, but it should not quietly invent a product capability, legal requirement, price, quotation, date, or performance result.
    4. Specify the fallback behavior. Decide what should happen when a criterion fails. Your choices include asking a blocking question, returning a partial answer, labeling a provisional assumption, inserting a clear evidence placeholder, or declining the unsupported portion. Without a fallback, even a good accuracy rule leaves the model to improvise.
    5. Set an acceptance test. Describe what must be true before the response is considered complete. For example, every factual claim must map to authorized evidence; every inference must be labeled; every citation must support the adjacent claim; and summaries, FAQs, metadata, and structured fields must not introduce facts absent from the approved material.

    Put these rules in priority order. If accuracy and completeness conflict, say which one wins. If the requested format requires a statistics section but no statistics are available, the rubric should instruct the model to flag the missing evidence instead of manufacturing a plausible number to preserve the format.

    The same principle applies to conflicts among inputs. Do not tell the model merely to resolve discrepancies. Tell it whether to prefer a designated primary record, use the most applicable version, present both positions, or stop and ask. Otherwise, the final answer may hide the disagreement behind confident prose.

    Keep the rubric concise enough to enforce. Repeated rules written in slightly different ways can create new conflicts. Each criterion should contain a trigger, a required action, and a visible outcome. If you cannot tell whether the output passed a criterion, rewrite the criterion.

    A copy-ready rubric for content and SEO workflows

    You do not need to rebuild the framework for every task. Keep a stable core and add task-specific rules only where the risk changes.

    Reusable prompt block

    Place this block after the task, audience, context, and required output format. Replace the bracketed fields with boundaries that match your workflow.

    • Priority: Factual support and transparent uncertainty take precedence over completeness, fluency, tone, and length.
    • Authorized evidence: Use only [approved inputs] for factual claims about [subject]. Do not treat a requested claim as evidence that the claim is true.
    • Supported claims: State a factual claim only when the authorized evidence supports that specific wording and scope. Do not broaden a narrow claim.
    • Inferences: You may infer only when the conclusion follows reasonably from the evidence and does not introduce a new factual detail. Label the conclusion as an inference and identify the evidence behind it.
    • Missing or conflicting information: Do not invent names, numbers, dates, quotations, citations, URLs, capabilities, examples presented as real, or research findings. Mark unsupported items as [preferred label]. Preserve material conflicts instead of silently choosing a side.
    • Clarification rule: Ask a blocking question before drafting when the missing information could change the central claim, recommendation, audience, scope, or risk. Otherwise, continue and record the limitation.
    • Final check: Before returning the answer, remove or label every unsupported claim, confirm that each citation supports the claim beside it, and confirm that derivative sections introduce no new facts.
    • Response: Return the requested deliverable followed by a short exception log containing material omissions, labeled inferences, unresolved conflicts, and blocking questions. Do not return hidden reasoning or a generic assurance that the answer is accurate.

    The exception log is important because it makes failure visible without requiring you to inspect the model’s internal reasoning. If the log is empty but the draft contains unsourced specifics, the output has failed the rubric.

    Worked example: an evidence-controlled content brief

    Suppose you ask AI to create an AEO-focused brief from an approved product fact sheet, a set of customer questions, and selected reference pages. A normal prompt may request key claims, search intent, supporting statistics, FAQs, and suggested structured content. The format is clear, but the evidence rules are not.

    Add task-specific criteria such as these:

    • Use the approved packet for every product claim, date, number, quotation, comparison, and attributed statement.
    • Do not invent search volume, ranking difficulty, trend data, customer stories, survey findings, product limitations, or competitor capabilities.
    • Separate evidence-backed audience questions from editorial questions proposed for further research. Do not present a suggested question as observed search behavior.
    • Separate factual claims from recommendations about page structure. A heading recommendation does not need to masquerade as a fact about the market.
    • Create a claim register that pairs each publishable factual claim with the item that supports it. If no item supports the claim, label it Needs evidence.
    • Apply the same evidence boundary to the summary, FAQ, metadata, and any structured fields. Changing the format does not authorize a new claim.
    • Return blocking questions before the brief when missing information would change the page’s audience, core promise, or factual position.

    This version still lets the model help with organization and editorial planning. It removes permission to imitate missing research. That distinction prevents a common failure: treating the model’s familiarity with the shape of an SEO brief as evidence for the facts inside it.

    Test the rubric with deliberately incomplete input. Remove the support for a requested statistic, product claim, or quotation while leaving the request in place. A passing response should flag the gap, ask a material question, or omit the unsupported item according to your rule. If it produces a plausible replacement, tighten the evidence boundary and failure action before using the prompt in an automated workflow.

    Review the output with a separate acceptance rubric

    A separate reviewer checks an AI-produced manuscript against evidence tokens and sets one questionable fragment aside.

    The generation rubric controls how the draft should be produced. An acceptance rubric controls whether that draft can move forward. Separating the two prevents a polished response from being treated as approved merely because it followed the requested structure.

    Use clear statuses such as pass, revise, and block. A numeric score can hide a serious defect inside an acceptable average. One fabricated citation should block publication even if the tone, organization, and formatting are excellent.

    CriterionPass conditionFailure action
    Evidence coverageEvery externally verifiable factual claim is traceable to an authorized input or visibly labeled as an inference.Remove the claim, add appropriate evidence, or change its status.
    Citation fitEach citation exists and supports the exact claim, scope, and qualification beside it.Replace the citation, narrow the wording, or block the claim.
    Uncertainty handlingMaterial gaps and conflicts remain visible; low-impact assumptions are identified where relevant.Add a qualification, request clarification, or return the item for research.
    Instruction priorityThe output meets the task without violating higher-priority evidence and uncertainty rules.Revise the deliverable instead of waiving the higher-priority rule.
    Claim propagationSummaries, FAQs, metadata, and structured fields contain no unsupported facts copied from or added to the main draft.Remove the derivative claim or supply support before publishing.
    Exception logMaterial omissions, inferences, conflicts, and questions are specific enough for a reviewer to resolve.Replace generic caveats with the affected claim, missing input, and required next action.

    You can ask the model to apply this acceptance rubric to its own output, but treat that as a consistency check, not independent verification. The same system that generated an unsupported claim can overlook it during self-evaluation. A person should still open important citations, compare claims with the underlying material, and review conclusions that affect money, legal exposure, health, reputation, or publication under someone else’s name.

    When a rubric performs badly, the pattern usually points to the missing rule:

    • The answer is fluent but contains invented specifics. The evidence boundary is open-ended, or unsupported claims have no mandatory failure action.
    • The model refuses to complete useful work. The rubric treats every uncertainty as blocking. Define which inferences and low-impact assumptions are allowed.
    • The answer is buried in caveats. The rubric does not distinguish material uncertainty from details that do not affect the outcome. Add a materiality test.
    • The citations look correct but do not support the claims. The rubric checks citation presence rather than citation fit. Require support for the exact adjacent statement.
    • Different sections contradict one another. The rubric evaluates local sentences but not the deliverable as a whole. Add a cross-section consistency check.
    • The model follows some rules and ignores others. The rubric is probably too long, repetitive, or internally conflicted. Remove overlap and state the priority order.
    • The self-review always passes. The acceptance criteria are subjective, or the same model is being treated as an independent reviewer. Replace impressions such as high quality with observable pass conditions and retain human verification where the consequence warrants it.

    A rubric does not replace retrieval, source selection, subject-matter expertise, or fact-checking. It governs what the model should do with the information and uncertainty it has. That narrower role is still valuable because it makes incomplete evidence visible before fluent prose conceals it.

    Key takeaways

    • A standard prompt defines the deliverable; a rubric defines how the model must behave when evidence is missing, conflicting, or insufficient.
    • Prioritize factual support over completeness explicitly. Otherwise, a request for a finished answer can compete with the instruction to avoid unsupported claims.
    • Every criterion needs a trigger, required action, and visible outcome. Be accurate is a goal, not an enforceable rule.
    • Define allowed evidence, labeled inference, material uncertainty, clarification conditions, and failure behavior before generating the draft.
    • Use a separate acceptance rubric for publication. Self-review can improve consistency, but it is not independent factual verification.

    Start with one prompt you already use. Add an evidence boundary, an uncertainty classification, a stop condition, and an acceptance check. Then test it against incomplete or conflicting input. If the model fills a gap you expected it to expose, revise the decision rule before you scale the workflow. The useful rubric is not the one that sounds strict; it is the one that produces the correct behavior when the easy answer is unavailable.

    References

  • AI-Era Copywriting: Turn Positioning Into Recommendations

    AI-Era Copywriting: Turn Positioning Into Recommendations

    Your team can produce more words than ever, yet your homepage may still leave a buyer asking three basic questions: Is this meant for me? Does it solve my problem? Why should I believe you?

    That gap is where copywriting matters in AI-era marketing. You do not need another layer of generic content. You need language that makes your offer easy for a person to choose and easy for a generative system to match to the right buying situation.

    Key takeaways

    • AI has reduced the value of generic explanation, not the value of persuasion. Information can be compressed; a credible reason to choose you still has to be established.
    • Write from the buyer’s situation rather than from a broad description of your company. State who the offer is for, what problem it solves, how it works, and what supports the claim.
    • Generative engine optimization is partly a positioning problem. Your brand must be available as a relevant solution when a person describes a need, not merely visible for a category keyword.
    • Create separate pages only for meaningfully different decisions. If the audience, offer, proof, and next step are unchanged, changing a few nouns does not justify another page.
    • Use AI to organize evidence, expose gaps, and produce controlled variations. Keep positioning, promises, exclusions, and factual approval under human control.
    • Judge copy by commercial movement: qualified visits, revenue-page actions, lead quality, conversions, and branded demand. Raw traffic is not the final objective.

    Start with the decision, not the draft

    Hands arrange audience, problem, and proof symbols around a product prototype while a blank sheet and capped pen sit nearby.

    A page can be accurate, readable, and optimized without helping anyone decide. That usually happens when the writing explains a category but never establishes a position inside it.

    AI is particularly capable of summarizing, synthesizing, matching patterns, and compressing familiar information. That makes undifferentiated publishing easier to reproduce and easier to replace. It does not remove the need to influence a real choice. In practice, AI exposed the difference between informational production and persuasive copywriting.

    Before writing a headline, complete a positioning brief. If your team cannot agree on the brief, polishing sentences will only conceal the disagreement.

    <!– wp:list {
  • How to Build Trust in AI-Driven Financial Research

    How to Build Trust in AI-Driven Financial Research

    You can make financial research easy for an AI system to find, summarize, and cite. The harder question is whether the answer remains trustworthy after the system compresses it. A careful analysis can become a dangerously confident sentence when its evidence, assumptions, or limits disappear.

    Your job is therefore larger than increasing AI visibility. You need to publish answers whose meaning survives extraction: the claim stays connected to its evidence, the reasoning can be inspected, and the boundary between general research and personal financial advice remains unmistakable.

    Key takeaways

    • Optimize financial research for verification before visibility. Search exposure cannot make an unsupported conclusion reliable.
    • Place the evidence, reasoning, relevant date, and limiting condition close to every consequential claim.
    • Connect technical signals, fundamentals, alternative data, and portfolio context without forcing them into artificial agreement.
    • Write important qualifiers into the sentence an AI system is most likely to extract, not into a distant disclaimer.
    • Use structured data and on-page optimization to describe trustworthy content, never to manufacture the appearance of authority.

    Trust begins where the answer can be checked

    Financial information has a short trust fuse because weak or inaccurate research can produce fast, measurable consequences. A vague answer about an ordinary purchase might waste time. A vague answer that influences a trade, allocation, credit decision, or risk assessment can lose money.

    That changes the minimum standard for a useful page. A reader should be able to identify what you know, how you know it, what you inferred, and what could invalidate the inference. An AI-generated summary should preserve those distinctions instead of presenting every sentence as an equally established fact.

    Use a six-field answer card

    Before drafting a financial answer, complete these six fields. They can live in your editorial brief, content management system, or review checklist:

    1. User question: Record the exact decision or uncertainty the page will address. A broad topic such as market risk is not yet a usable question.
    2. Bounded answer: Write the shortest conclusion the available evidence can support. Include the market, asset, period, or scenario that limits the claim.
    3. Evidence: Identify the underlying observations and where they came from. Preserve relevant dates, units, definitions, and methodology.
    4. Reasoning: Show how the evidence leads to the conclusion. Name any assumption that the argument needs in order to hold.
    5. Limit: State what the evidence does not establish, which alternative explanation remains possible, and what would change the conclusion.
    6. Ownership: Assign responsibility for reviewing, updating, correcting, or withdrawing the answer when its basis changes.

    If you cannot complete the evidence or limit field, do not ask a language model to fill the gap. Its fluent transition may disguise the absence of support. Publish a narrower answer, label the uncertainty, or withhold the conclusion until it can be checked.

    Separate observation, calculation, and interpretation

    A trustworthy answer distinguishes three layers that are often blended together:

    • Observation: What was measured, reported, or recorded?
    • Calculation: What transformation or comparison did you apply to those observations?
    • Interpretation: Why might the result matter, and which assumptions connect it to that meaning?

    Labeling these layers prevents an interpretation from inheriting the apparent certainty of the underlying data. It also gives an AI system clearer units of meaning to retrieve. Instead of receiving a paragraph that mixes facts and forecasts, the system encounters an explicit evidence chain.

    Keep the safety boundary close to the consequential statement. If a conclusion could influence an individual’s financial decision, present it as general research and direct the reader to a qualified financial professional for advice based on their circumstances. A footer disclaimer does not repair personalized or overly certain language in the main answer.

    Connect the evidence without hiding disagreement

    Blue and amber evidence trails remain visibly separate while connecting to a shared transparent model on a research table.

    Trust weakens when readers have to assemble an answer from unrelated dashboards, definitions, charts, and commentary. Each extra handoff introduces another opportunity to misread the period, use a different definition, or miss an important qualification. Fragmentation also makes it harder to demonstrate that you understand how the pieces relate.

    A stronger research experience connects technical signals, fundamentals, alternative data, and portfolio analysis in context. This does not mean squeezing every available metric onto one screen. It means giving the user a coherent route from question to conclusion.

    For a consequential research question, organize that route in this order:

    1. Answer: Give the bounded conclusion and its main limitation.
    2. Change: Show what happened and the comparison that makes the change meaningful.
    3. Drivers: Explain the mechanisms that could account for it.
    4. Cross-checks: Show which other evidence supports, weakens, or contradicts the interpretation.
    5. Relevance: Explain how the finding may affect a general research or portfolio question without turning it into personal advice.
    6. Method: Make definitions, provenance, calculations, and update information available where the reader needs them.

    The cross-check stage matters. Connected research is not research in which every indicator agrees. If a technical signal points one way while fundamentals or alternative data point another, preserve the disagreement. Explain whether the measures cover different time horizons, definitions, or mechanisms. If you cannot reconcile them, say that plainly.

    Clarity does not mean removing complexity. It means helping the reader distinguish relevant complexity from clutter. Even an experienced investor benefits when you explain why a development is significant rather than merely reporting that it occurred.

    A useful explanation answers five questions: What happened? Compared with what? Through which mechanism could it matter? What else could explain it? What evidence would make us revise the conclusion? Those questions turn a data display into reasoning the reader can inspect.

    Centralization can be achieved without creating an enormous page. Use shared definitions, consistent labels, visible dates, stable identifiers, and direct links between related modules. The goal is continuity of meaning. A reader moving from a chart to a methodology note should not have to guess whether the same term, period, or calculation still applies.

    Optimize for AI retrieval without manufacturing authority

    Keyword coverage can help a page become discoverable, but it cannot establish financial expertise. In AI-driven discovery, visibility increasingly depends on being consistently useful and demonstrating depth, consistency, and reasoning. That requires three separate layers of work.

    LayerQuestion to askWhat to doWhat it cannot fix
    Technical accessCan a search or AI system reach and read the main answer?Keep the substantive answer in accessible page content, maintain clear internal links, and make machine-readable descriptions consistent with what users can see.Missing evidence or an unsupported conclusion.
    Semantic extractionCan a passage retain its meaning when removed from the page?Use descriptive headings, stable terminology, explicit relationships, and short passages that keep claims beside their qualifiers.Ambiguous reasoning or conflicting definitions.
    Epistemic credibilityCan a reader inspect why the claim should be believed?Expose provenance, calculations, assumptions, counterevidence, limitations, and review ownership.Stale, inaccurate, or fabricated inputs.
    Decision safetyCould the answer be mistaken for individualized advice?Define the intended use, avoid prescriptive language about personal circumstances, and place warnings beside the relevant conclusion.A risky claim hidden behind a general disclaimer.

    Apply these layers in order. Making weak analysis easier to crawl only distributes the weakness. Adding structured data to vague content only describes the vagueness more efficiently. Technical optimization should expose a sound evidence structure that already exists on the page.

    At the page level, use these rules:

    • Lead with the bounded answer. State the conclusion, scope, and main qualification before expanding the analysis.
    • Use headings that describe the reasoning. A heading such as “Why the indicators disagree” carries more information than “Analysis.”
    • Keep one main claim per paragraph. This makes extraction cleaner and reduces the chance that a qualifier will attach to the wrong conclusion.
    • Put evidence links beside the supported claim. A generic bibliography forces readers and machines to reconstruct the relationship.
    • Keep critical qualifiers in the same sentence. Write “under these assumptions” or “for this period” where the conclusion appears.
    • Define terms once and use them consistently. If two metrics sound similar but differ, explain the distinction before comparing them.
    • Make visible content and machine-readable markup agree. Structured data should reflect the answer, authorial responsibility, and other information actually available to the reader.

    Avoid producing thin pages for every wording of the same query. Financial authority emerges from linking concepts and showing their relationships in a comprehensive answer. One well-maintained explanation with clear subtopics is usually a stronger foundation than a collection of near-duplicates that omit context.

    Run a trust audit before the page becomes an AI answer

    Three analysts inspect linked evidence nodes, blank source documents, and output layers during a research trust review.

    Your final review should test more than grammar, keyword use, and formatting. It should simulate what happens when a search engine, assistant, analyst, or hurried reader extracts only the most quotable part of the page.

    1. Build a claim ledger. Copy each consequential claim into a review sheet. Label it as an observation, calculation, interpretation, scenario, or recommendation. If the label is unclear, the sentence probably blends categories.
    2. Trace the evidence. Confirm that every observation has identifiable provenance and that the relevant date, definition, unit, and scope remain available. Do not accept a citation that merely discusses the same topic.
    3. Reperform the reasoning. Follow the path from evidence to conclusion without relying on the prose’s confidence. Check whether a missing assumption or alternative explanation breaks the chain.
    4. Test the qualifier. Copy the key conclusion into a blank document. If it becomes misleading without a nearby paragraph, rewrite the sentence so its essential boundary travels with it.
    5. Look for forced agreement. Identify evidence that conflicts with the conclusion. Explain the disagreement, narrow the claim, or state that the result is unresolved.
    6. Check the decision boundary. Ask whether a reasonable reader could mistake general research for an instruction tailored to their finances. If so, revise the language and position professional-help guidance next to the risk.
    7. Assign the next review. Record what type of change would trigger reassessment and who can correct or withdraw the conclusion. Trust depends on how you handle changed information, not only how carefully you launch a page.

    Use a simple release gate. Publish when the evidence, reasoning, scope, and limits are all inspectable. Revise when the evidence is sound but the extracted answer could mislead. Hold the page when a consequential conclusion cannot be verified. Do not let polished AI-generated prose turn that third condition into the second.

    Start with one financial page that already attracts an important question. Rebuild it around the six-field answer card, connect the evidence that a reader would otherwise have to assemble, and run every key sentence through the extraction test. Once it passes, use that page as the editorial pattern for your wider AI search strategy.

    References

  • Microsoft Copilot Conversational Commerce: Merchant Guide

    Microsoft Copilot Conversational Commerce: Merchant Guide

    If your products already rank in search, that does not mean they are ready to sell inside Microsoft Copilot. Conversational commerce adds two points of failure: the assistant must answer a buyer’s exact question from reliable product data, and the purchase path must preserve the right product, variant, terms and price through checkout.

    Microsoft’s rollout gives merchants two related but distinct surfaces to prepare for: Copilot Checkout inside Copilot.com and Brand Agents on Shopify stores. You need a different operating plan for each one, followed by a shared catalog audit, conversation test and measurement framework.

    Treat Copilot Checkout and Brand Agents as separate surfaces

    It is easy to collapse both products into a single AI shopping feature. That creates muddled ownership and incomplete testing. Copilot Checkout handles a transaction within a Copilot conversation; a Brand Agent answers and guides shoppers on a merchant’s own Shopify site. One changes an off-site buying path. The other changes an on-site decision path.

    Copilot Checkout shortens the path from answer to purchase

    Copilot Checkout began its U.S. rollout on Copilot.com, allowing a buyer to complete a purchase without leaving the current conversation. PayPal, Shopify, Stripe and Etsy were named as integration partners.

    That changes what it means to be visible. A product mention is no longer the final objective; the product also has to remain purchasable when the buyer acts. Ask your commerce owner to verify which catalog, inventory, price, variant and policy records feed the transaction. The presence of a payment partner does not tell you which system supplies each product fact.

    Shopify merchants are automatically enrolled and can opt out. Treat that as a reason to check your status, not as proof that your store is ready or that a particular product is already appearing. Non-Shopify merchants have an application route, so eligibility work and content optimization should be managed as separate tasks.

    Brand Agents influence the decision on your own site

    Brand Agents are available to Shopify merchants. They use the merchant’s product catalog to answer product-specific questions, adopt the brand’s voice and guide shoppers from browsing toward purchase. Microsoft says they can be set up in a few hours.

    Fast setup is not the same as production readiness. A quick installation cannot resolve contradictory variant names, incomplete compatibility details, buried exclusions or a returns rule that differs between the catalog and the storefront. Put catalog and policy owners in the launch workflow before asking the marketing team to tune the agent’s tone.

    The practical ownership split is simple: your ecommerce team should own transaction integrity, your product-data team should own factual answers, and your brand team should own voice. Give one person authority to stop the rollout when those layers disagree.

    Build an answer-ready catalog, not just an indexable page

    Structured product records connect colors, sizes, inventory, delivery, returns, and pricing to an AI-assisted recommendation.

    Traditional product-page optimization often concentrates on discoverable titles, category copy and commercial keywords. A conversational agent also needs enough explicit information to resolve follow-up questions. The difference matters because shoppers rarely ask for a keyword in isolation. They add a use case, compare options, introduce a constraint and then ask whether a particular variant will work.

    For every product family you expect an agent to recommend, review these elements:

    • Identity: Use one canonical product name and a plain description of what the product is. Keep abbreviations, model names and bundles distinguishable.
    • Variants: Make size, color, capacity, configuration and other selectable attributes unambiguous. A buyer should not have to infer whether two labels describe the same option.
    • Fit and compatibility: State who or what the product works with, along with material exclusions. Do not hide a decisive limitation in an image or an unrelated help page.
    • Included items: Say what arrives in the package and what must be purchased separately. This prevents a recommendation from creating the wrong expectation.
    • Commercial facts: Keep price, availability, shipping conditions, returns and warranty language aligned with the systems that govern the transaction.
    • Comparison logic: Explain the decision-relevant difference between adjacent products. A list of specifications is less useful than a clear statement of when a buyer should choose one option over another.
    • Claim boundaries: Mark subjective language as positioning and reserve factual claims for statements you can support. Brand voice must not turn a qualified benefit into a guarantee.

    Your structured data should reflect the same facts. Keep Product and Offer markup synchronized with visible copy and store data, but do not present schema as a magic switch for Copilot eligibility. The announced merchant routes are Shopify enrollment or a non-Shopify application; adding markup alone does not complete either route.

    When the page, JSON-LD, catalog and checkout disagree, choose a system of record for each field and repair the downstream copies. Do not solve the conflict by giving the agent a more persuasive answer. The correct response to uncertain availability or compatibility is a qualified answer, a request for clarification or a refusal to claim more than the data supports.

    Turn the catalog audit into an answer audit. Write representative questions in the language a shopper would use, then attach each approved answer to the exact field, policy or page statement that supports it:

    • What is this product, and what problem is it meant to solve?
    • Will it work with the model, space, use case or constraint I described?
    • What is the meaningful difference between these two options?
    • Which variant should I choose, and why?
    • What is included, and what would I still need?
    • What happens if the item is unavailable or the stated condition is not met?
    • Which shipping, return or warranty qualification applies to this purchase?

    If an approved answer has no supporting location, you have found a data gap. Repair that gap before expanding the agent’s vocabulary. This is also the most useful place for SEO, AEO and ecommerce teams to collaborate: the question set reveals what buyers need, while the evidence map shows whether your content and structured data can answer them consistently.

    Test the complete buying conversation before launch

    A merchant team checks each stage of an AI-guided purchase, from a shopper's question through product selection, variant validation, checkout, and delivery.

    A polished demonstration usually follows a clean prompt and a known product. Real buyers are less orderly. They misspell model names, change constraints, compare products that are not equivalent and revise a variant near the end. Your test should reproduce that behavior instead of asking only whether the agent can recite a product description.

    1. Begin without a product name. Describe a need and see whether the agent asks a useful clarifying question or jumps to an unsupported recommendation.
    2. Add a material constraint. Introduce compatibility, size, intended use or another condition that should narrow the answer. Check whether the recommendation changes appropriately.
    3. Request a comparison. Ask why one product or variant is a better fit than another. Confirm that every claimed difference exists in the catalog or visible product information.
    4. Probe an exception. Ask about an unavailable option, an ambiguous model, an excluded use or a policy edge case. A safe agent should expose uncertainty instead of smoothing it over.
    5. Continue toward purchase. Verify that the selected product, variant, quantity, price and applicable terms survive the handoff to checkout. Use the approved test method for your commerce stack rather than real customer payment details.
    6. Change your mind late. Switch a variant, revise a constraint or return to the comparison. Confirm that the final checkout state reflects the latest instruction rather than an earlier choice.

    Record the expected answer, observed answer, supporting evidence, severity and owner for every test. Use a severity model that reflects actual commercial risk:

    • Blocker: wrong product, price or variant; an unsupported policy statement; a payment problem; or a claim that could materially mislead the buyer.
    • Major: the agent cannot answer a common high-intent question, loses an important constraint or recommends an option without evidence.
    • Minor: awkward wording, unnecessary repetition or a tone mismatch that does not change the factual meaning.

    Do not approve a production launch with unresolved blockers. Correctness belongs ahead of personality because a charming wrong answer still creates the wrong order. Tune brand voice after the agent can identify uncertainty, retain constraints and carry the correct selection into the transaction.

    Measure assisted commerce without mistaking correlation for lift

    Microsoft Clarity provides Brand Agent conversation insights and lets merchants compare agent-assisted sessions with organic traffic. That gives you a useful diagnostic view, but the two groups are not automatically equivalent. People who open a shopping conversation may already have different intent from visitors who do not.

    Microsoft says Brand Agent-assisted sessions show higher engagement and conversion. Treat that vendor claim as a hypothesis for your store, not a forecast. No percentage is supplied, and more interaction can be a mechanical result of adding a chat experience. Engagement is useful only when it helps explain a commercial outcome or reveals a problem.

    Build your measurement plan around questions that lead to a decision:

    • Did the agent attract use? Measure eligible sessions, agent starts and meaningful exchanges. Define a meaningful exchange before reviewing results so a greeting is not counted as successful assistance.
    • Did it improve buying progress? Compare product views, checkout starts and completed orders for relevant segments. Use your store or analytics platform for commerce outcomes that Clarity does not provide.
    • Did it improve order quality? Watch cancellations, returns, support contacts and variant corrections associated with agent-assisted purchases. A higher conversion rate can conceal a recommendation problem if downstream friction rises.
    • Which questions failed? Group unsuccessful conversations by missing product fact, ambiguous variant, policy gap, unsupported comparison, technical handoff or tone. Send each category to the team that can repair the underlying system.
    • What changed during the period? Annotate catalog updates, promotions, traffic shifts and agent revisions. Without that change log, a conversion movement is easy to credit to the wrong cause.

    Use the Clarity comparison directionally unless you have a controlled test with comparable audiences. When a controlled test is not practical, compare matched time periods and similar acquisition segments, then look for the same pattern across commerce outcomes and conversation quality. Do not call a result incremental lift merely because assisted sessions converted differently.

    Keep Copilot Checkout and Brand Agent reporting separate. The first can influence a purchase completed inside an off-site conversation; the second assists a shopper on your Shopify site. Before reporting AI-commerce revenue, document how each path appears in analytics, payment records and order data. Otherwise, a change in attribution can look like a change in demand.

    Key takeaways

    • Copilot Checkout and Brand Agents solve different parts of the journey, so assign separate owners and tests.
    • Shopify merchants should verify their Copilot Checkout enrollment status and readiness rather than assuming automatic enrollment means every product is transaction-ready.
    • A conversational agent needs explicit product identity, variants, compatibility, comparisons, commercial terms and claim boundaries.
    • Keep storefront copy, catalog data, JSON-LD and checkout records consistent; schema cannot compensate for contradictory commerce data.
    • Test discovery, clarification, comparison, exceptions, late changes and checkout state before tuning the agent’s personality.
    • Use Clarity insights to find behavior and answer gaps, but verify commercial outcomes in store analytics and avoid treating an observational comparison as causal lift.

    Your next move is a catalog-and-conversation audit on the product family where a wrong recommendation would create the most customer friction. Run discovery, fit, comparison, exception and checkout prompts against it. Repair every unsupported answer at the data or policy layer, then decide whether the experience is ready to scale.

    The first win is not making the agent sound clever. It is making sure the buyer receives the same accurate answer from the catalog, product page, agent and checkout.

    References

  • Google Search Snippets: A Technical SEO Readiness Guide

    Google Search Snippets: A Technical SEO Readiness Guide

    When Google adds an extra route from a search result into the middle of your page, the visitor may never see your title, introduction, or opening explanation. Your technical SEO job is no longer limited to improving the description beneath a blue link. You also need useful section-level entry points and a stable preferred URL.

    You cannot force Google to show a particular snippet enhancement. You can make the page ready for one, prevent JavaScript from sending conflicting canonical signals, and verify what Google can recognize. That is the practical standard this guide will help you apply.

    Build sections that work when the introduction is skipped

    Google’s read-more links can take a searcher directly to a section that is relevant to the query. That changes the page from a single top-down destination into a collection of possible entry points.

    Read an important section as if everything above it were hidden. If its opening depends on context from the introduction, a search visitor can land in the right place and still feel lost. The fix is not to repeat the entire page. It is to put the minimum orientation at the point of arrival.

    • Use a heading that names the question, decision, or task the section resolves. Replace labels such as “More details” or “Other considerations” with headings such as “When JavaScript should set the canonical URL.”
    • Answer the heading immediately. Put the direct answer in the opening sentence, then add qualifications and implementation detail.
    • Remove unexplained backward references. Phrases such as “as described above” fail when the visitor has bypassed the earlier material.
    • Define any term or acronym the reader needs to use the section. Do not make the visitor search upward for a definition that could fit in a short clause.
    • Keep the relevant example, warning, or next action with the explanation it belongs to. A section-level visitor should not have to reconstruct the procedure from disconnected parts of the page.
    • Use stable section IDs when they help your internal navigation or make sections easier to share. Treat those IDs as useful site architecture, not as a guarantee that Google will display a read-more link.

    Run the mid-page landing test

    Open the page at each important heading instead of starting at the top. Read only the heading, its opening paragraph, and the nearby action. You should be able to identify the subject, understand the answer, and know what to do next without consulting the introduction.

    This test also exposes content problems that a meta description cannot repair. Search-result copy may persuade someone to click, but only the destination can fulfill the promise. If the section is vague, fixing metadata leaves the actual landing experience unchanged.

    Treat snippet enhancements as outputs, not settings

    Read-more links have appeared in many results, but they are not included in every search snippet. Their absence is therefore not proof of a technical defect, and their presence is not proof that every section of the page is well optimized.

    The additional link creates another clickable route from a result and may give the page another opportunity to satisfy the searcher. It does not guarantee more traffic. The query, the wording Google presents, the selected destination, and the usefulness of that destination still shape what happens after the result is shown.

    Keep the control boundary clear. You control the page’s headings, section order, explanations, initial HTML, rendered HTML, canonical declaration, and indexability instructions. Google decides whether a result receives an additional link and which relevant section it exposes.

    That distinction prevents two common overreactions. Do not rewrite a canonical URL merely because an extra link did not appear. A canonical identifies the preferred page-level URL; it is not a switch for selecting a section. Likewise, do not assume that a visible enhancement makes the underlying technical setup correct. The result can look useful while JavaScript is still changing a critical signal behind the scenes.

    Use the symptom to choose the audit. If no read-more link appears, review section clarity and basic indexability without treating the absence as an error. If the link reaches a confusing passage, rewrite that section as an independent entry point. If Google surfaces an unexpected page URL, move your attention to canonical consistency.

    Make the canonical URL identical before and after JavaScript

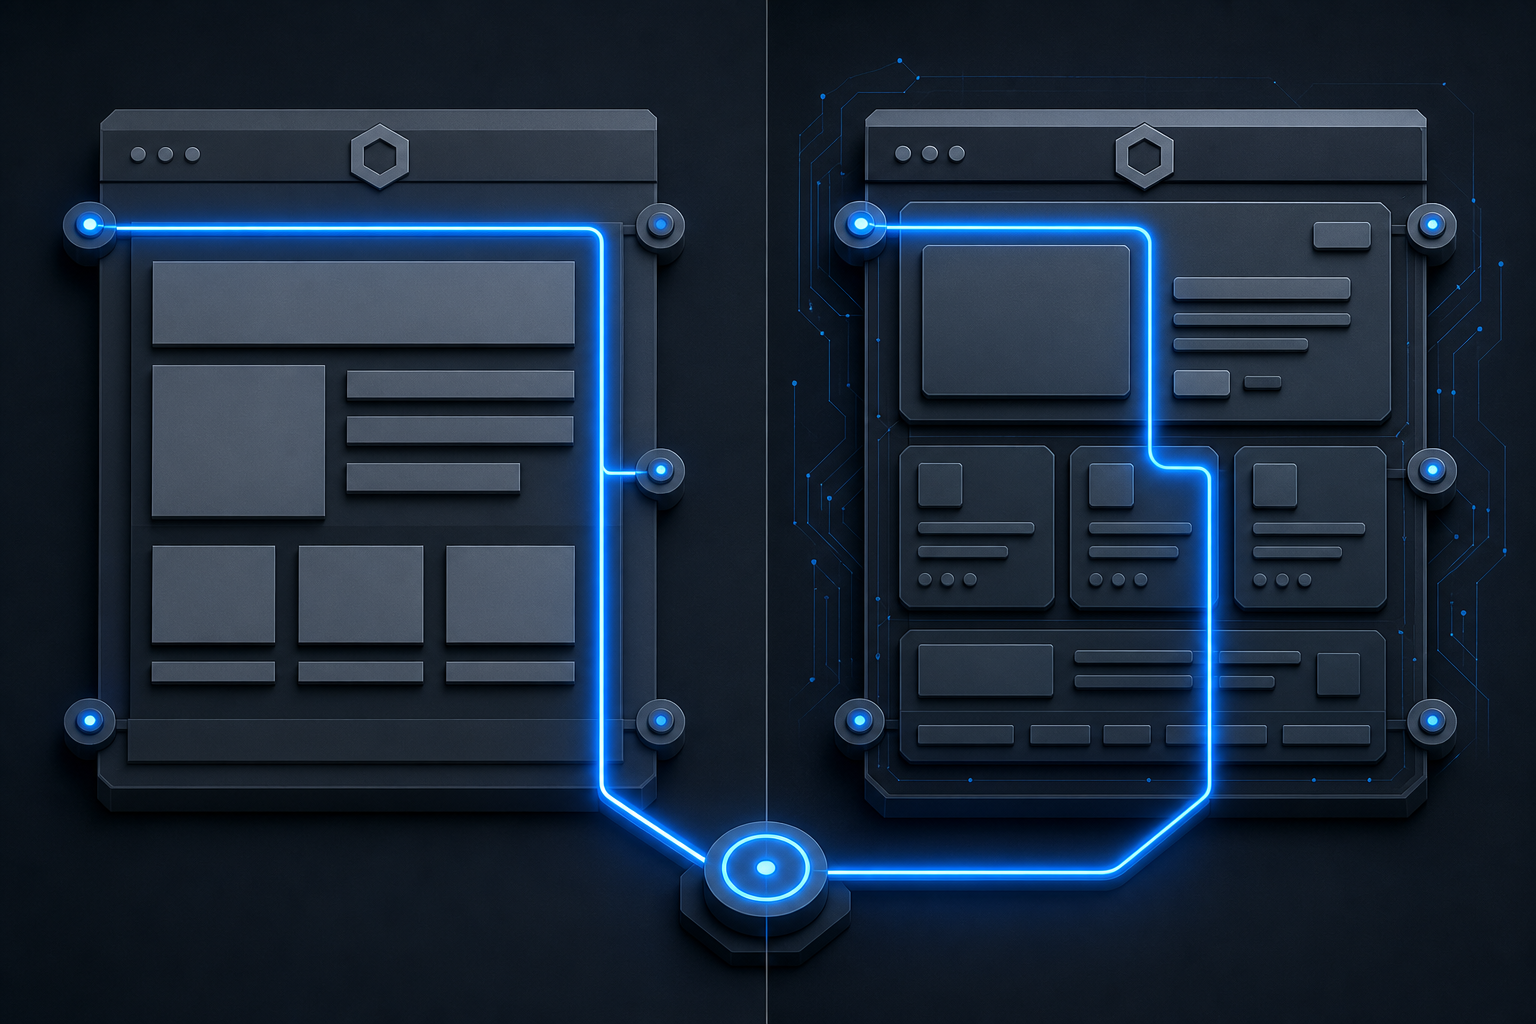
    Side-by-side abstract versions of an original and rendered web page following matching blue routes to the same destination node.

    The canonical link tells Google which page-level URL you want treated as the preferred version. The cleanest implementation places that URL in the original HTML. If JavaScript also manages the document head, it should preserve the same canonical rather than changing it.

    A straightforward HTML declaration looks like <link rel="canonical" href="https://example.com/technical-seo/">. If that exact URL is present in the original response, the rendered document should retain it. Do not publish one value as a placeholder and depend on client-side JavaScript to replace it with another.

    Original HTMLAfter JavaScript runsWhat to do
    Canonical ACanonical AKeep this consistent pattern.
    Canonical ACanonical BResolve the conflict so both layers use the intended preferred URL.
    No canonicalJavaScript sets canonical AUse this only when the canonical cannot be emitted in the original HTML, then verify that Google recognizes it.

    In the table, “canonical A” means the exact preferred URL you intended to declare. During an audit, record the complete string from both layers. Compare the protocol, hostname, path, trailing slash, and query string. Even when two variants eventually reach the same content, a difference tells you that separate parts of the rendering system disagree about the page’s identity.

    If your framework genuinely cannot place the canonical in the original HTML, leave it out there and let JavaScript set the intended value. That is safer than publishing a provisional canonical and changing it after rendering. The JavaScript-only pattern is a fallback to verify, not a reason to move a working HTML canonical into client-side code.

    Trace any mismatch to the component that owns the document head. Common architectural pressure points include a server-rendered template supplying one URL while a client-side router or SEO component calculates another. You do not need two canonical systems competing for control. Establish one preferred URL and make every rendering layer produce the same answer.

    Keep section navigation separate from canonicalization. A search result may send someone into a particular passage, but the canonical still describes the page as a whole. Do not change the canonical to represent whichever section Google happened to expose for a query.

    Audit the original HTML, rendered page, and Google view

    Three abstract panels show a web page as original document structure, fully rendered layout, and a crawler-inspected view under magnifying lenses.

    A browser can show you a functioning page while concealing a disagreement between the response Google first receives and the document JavaScript eventually creates. A useful audit therefore checks both states and then confirms Google’s interpretation.

    1. Choose a page that uses the same template and rendering path as the pages you care about. If multiple templates manage metadata differently, audit each template rather than assuming the homepage represents the whole site.
    2. Open the original page source. Record the canonical URL exactly as delivered and check whether an index-blocking instruction is present.
    3. Inspect the document after JavaScript has completed its normal rendering. Record the rendered canonical and check for duplicate canonical elements.
    4. Compare the initial and rendered values character by character. If JavaScript changes the value, fix the component producing the disagreement instead of accepting the rendered value as “close enough.”
    5. Use Google Search Console’s URL Inspection tool to verify Google’s recognition of a JavaScript-generated canonical. This is especially important when the initial HTML contains no canonical.
    6. If a live search result contains a read-more link, follow that actual link. Check whether the selected heading and opening explanation make sense without the top of the page.
    7. Repeat the check after changes to routing, templates, head-management components, or deployment logic. Those are the layers most capable of altering the original-versus-rendered relationship.

    Do not rely on JavaScript to undo an initial noindex

    If you want a page indexed, do not put a noindex instruction in the original code and expect JavaScript to remove it later. The safer implementation is to omit the initial noindex from a page intended for indexing.

    This matters when staging controls leak into production or when a rendering system starts with restrictive metadata and relaxes it on the client. Resolve the deployment state before the page is served. An indexable production page should not begin by telling a crawler not to index it.

    Canonical and noindex also answer different questions. The canonical identifies the preferred URL among versions; noindex asks that a page not appear in the index. Do not use one as a substitute for the other, and do not expect an attractive snippet treatment to compensate for contradictory indexability instructions.

    Key takeaways

    • A Google read-more link may bypass the top of your page, so every important section should make sense as an entry point.
    • The enhancement is not universal and cannot be treated as a setting, technical entitlement, or guaranteed traffic increase.
    • Put the canonical URL in the original HTML when possible. If JavaScript also touches it, the value should remain identical.
    • If the original HTML cannot contain a canonical, omit it there, set the intended value with JavaScript, and verify Google’s recognition in URL Inspection.
    • Do not ship an initial noindex on a page you want indexed and depend on client-side code to remove it.
    • Audit search presentation and page identity separately: section quality affects the landing experience, while canonical consistency protects the preferred page-level URL.

    Start with one JavaScript-rendered template. Place its original source beside the rendered document, compare the canonical values, and then open its major sections without reading the introduction. That small audit will tell you whether the next fix belongs in your content structure, rendering system, or indexability controls.

    References

  • Landing Page Conversion Mistakes and How to Fix Them

    Landing Page Conversion Mistakes and How to Fix Them

    When a landing page attracts visits but not leads or sales, do not start by changing the button color. First locate the point where the visitor’s decision breaks: the traffic promise, the offer, the evidence, the action, or the measurement.

    Traffic and conversion are separate outcomes. More visits can expose a weak page without making it more persuasive, which is why high traffic does not guarantee conversions. The audit below helps you diagnose the actual failure, make the smallest useful correction, and verify whether it improved the business result.

    Fix the gap between the traffic promise and the page

    A visitor follows a matching coral symbol from an entry doorway to an unlabeled landing page while mismatched shapes fall into a gap.

    Your landing page begins before the visitor reaches it. An ad, search result, email, social post, referring page, or AI-generated answer creates an expectation. The landing page must continue that expectation without forcing the visitor to reinterpret what you meant.

    Message match is not a requirement to repeat the referring copy word for word. It means preserving the audience, problem, offer, and intended outcome. If an ad promises payroll software for small construction companies but the landing page opens with a generic statement about business efficiency, the visitor has to work out whether the page is still relevant. That interpretive work is avoidable friction.

    Write a message-match brief

    Audit each major traffic source against the page using a short brief:

    1. Name the exact audience the source addresses.
    2. Copy the promise or question that earns the click.
    3. State what the visitor is likely to expect next.
    4. Identify the words or ideas on the landing page that confirm the visitor is in the right place.
    5. Write the action the page asks that visitor to take.

    You have a message-match problem if the source and page disagree about the audience, outcome, offer, or next step. You also have one if the connection is technically present but buried below company history, a product overview, or several unrelated features.

    Do not send meaningfully different promises to one generic page merely because maintaining one URL is convenient. If separate campaigns address separate use cases, either create purpose-built variants or build a page that lets each audience recognize its route immediately. The deciding question is not whether the products are related. It is whether the same opening argument honestly serves every visitor.

    Answer the entry question before advancing the sale

    A person arriving from an informational search may still be defining the problem. Someone clicking a retargeting ad may already understand the product and need pricing, proof, or implementation details. Giving both visitors the same argument can make the page feel either premature or repetitive.

    For search and AI-discovery traffic, answer the query that earned the visit near the beginning of the page. Then connect that answer to the offer. For high-intent campaign traffic, confirm the advertised offer immediately and make its conditions visible. Do not hide the promised detail behind a form unless receiving that detail is explicitly what the visitor agreed to request.

    If one source converts poorly while other sources perform acceptably on the same page, inspect its promise, targeting, and visitor intent before redesigning the entire landing page. A source-specific failure is evidence about the handoff, not automatically evidence that every part of the page is broken.

    Make the offer understandable before making it persuasive

    Clarity is not the same as minimal copy. A short page can still be vague, and a detailed page can still be easy to follow. The real test is whether a qualified visitor can understand the offer without assembling its meaning from scattered headings, screenshots, and buttons.

    The opening portion of the page should answer these questions:

    • What is being offered?
    • Who is it for?
    • What useful outcome does it support?
    • What will the visitor receive or gain access to?
    • What commitment does the next step require?
    • What happens after the visitor acts?

    If your team cannot answer those questions in plain language, polishing the layout will not solve the underlying problem. Rewrite the offer as a single sentence before touching the page. A workable internal template is: this is a specific offer for a defined audience that helps with a named problem, and the next step is a clear action. The published copy can be more natural, but its meaning should remain that precise.

    Build a visible hierarchy instead of a wall of benefits

    A practical opening sequence is a headline that identifies the relevant outcome, supporting copy that qualifies the audience or method, evidence that makes the claim credible, and a call to action that names the next step. This sequence gives each element one job.

    Avoid opening with an unsupported superlative, a slogan that could describe any competitor, or a broad category label. Replace it with the most specific claim you can support. If you cannot substantiate a dramatic promise, narrow it. Accurate specificity is more useful than inflated certainty.

    Organize the rest of the page around the decision, not your internal company structure. A visitor usually does not need a tour of every capability before learning whether the offer addresses the current problem. Present the core outcome, explain how it works, show relevant evidence, address the main objections, and make the next step clear. Place secondary detail where an interested visitor can reach it without making everyone process it first.

    Make the call to action describe the real next step

    Labels such as Submit, Continue, or Learn More hide the consequence of clicking. Use language that describes the action or deliverable, such as View plans, Request a demo, Start the assessment, or Get the checklist. The best wording depends on what the button actually does.

    The destination must honor the label. A button that says View pricing should not unexpectedly open a sales-contact form. A button that says Start free should not conceal a required sales conversation. When the wording and destination disagree, the page creates mistrust at the exact moment the visitor is considering action.

    A single primary action does not require a single button. You can repeat the same call to action as the argument develops. It means that the most prominent controls support the same decision. Keep a secondary action only when it serves a clear alternate state, such as letting a visitor inspect documentation before requesting a technical demo. Several equally prominent actions force the visitor to decide how to use the page before deciding whether to accept the offer.

    Remove friction without removing the confidence to act

    Reducing friction does not mean making every page short or every form tiny. It means removing effort that does not help the visitor make a sound decision or help your team complete the promised next step.

    Require only information that has an immediate purpose

    Review every form field with the same questions:

    • Why is this information needed before the next step?
    • Will the answer change eligibility, routing, preparation, or the immediate response?
    • Could the information be inferred from existing data or collected later?
    • Is the label clear about the expected format?
    • Does the error message explain how to correct the entry?

    A demo request may legitimately need information that helps assign the right specialist. A simple resource delivery may not need the visitor’s phone number, company size, job level, budget, and purchasing timeline. Form length should follow the transaction, not a blanket preference for short or long forms.

    Do not remove required privacy controls, consent choices, or disclosures merely to shorten the interaction. Those elements may carry legal or operational consequences. Simplify their language and presentation with qualified review, but preserve requirements that apply to the data and jurisdiction involved.

    Treat uncertainty as friction

    A page can be visually simple and still feel risky. Before acting, a visitor may need to know whether the offer fits the relevant use case, what happens after submission, how personal or business information will be used, what commitment is involved, and whether the claims can be verified.

    Place each answer near the moment the doubt arises. Put important conditions near the offer. Put a concise data-use explanation near the form. Put implementation evidence near implementation claims. Put relevant customer proof beside the outcome it supports. Do not make the visitor hunt through a footer, separate FAQ, or generic testimonials to resolve a predictable objection.

    Evidence should be inspectable. A screenshot can clarify what the product looks like. A testimonial is more useful when its context makes clear who benefited and from what use case. A process description can reduce uncertainty about the next step. Logos, badges, counters, and quotations should never imply validation you cannot substantiate.

    Test the complete path, not just the page appearance

    Run a manual conversion check on the devices and input methods your visitors use. Complete the path as a new visitor rather than as someone who already knows how the interface works.

    1. Open the actual campaign or search destination, including its query parameters.
    2. Check that the page loads and remains usable on a phone-sized screen.
    3. Navigate interactive elements with a keyboard and confirm that labels remain understandable without placeholder text.
    4. Submit the form empty, with invalid entries, and with valid entries.
    5. Confirm that errors identify the affected fields and preserve information already entered.
    6. Try repeated clicks and verify that they do not create duplicate submissions or charges.
    7. Confirm that the success state appears only after a real completion.
    8. Check the promised follow-up, such as an email, download, booking, account state, or sales notification.

    A page-level change cannot fix a broken confirmation email, an unavailable booking calendar, a validation loop, or a form that silently fails. If primary CTA clicks rise while completed actions remain flat, investigate what happens after the click before revising the headline again.

    Measure the decision path before running an A/B test

    An analyst examines visitor markers moving through five symbolic decision checkpoints while two alternative page panels remain covered.

    Conversion optimization becomes guesswork when the success event is ambiguous. Define the completed business action first, then instrument the steps that help you locate failure.

    For a lead page, a useful event path may include the landing-page view, primary CTA click, form start, validation error, successful submission, and confirmed thank-you state. For a purchase or account flow, the events will differ, but the distinction remains: intermediate interactions diagnose behavior; the completed action measures conversion.

    Do not call a button click a lead when a valid submission is the actual objective. Do not call a form submission a purchase when payment confirmation is the objective. Naming an early event as the conversion can make a broken downstream path appear successful.

    Before comparing versions, verify that the conversion event fires once, fires only after genuine success, carries the correct campaign context, and excludes or identifies internal quality-assurance activity. Keep the denominator consistent. A rate based on landing-page sessions cannot be compared directly with one based on users, ad clicks, or all site visits without explaining the difference.

    Segment enough to find the problem, but not enough to invent one

    Start with segments that can change your diagnosis: traffic source or campaign, device class, offer, landing-page variant, and new versus returning visitors when that distinction matters. Add geography, query group, or audience segment only when the page or offer meaningfully differs for those visitors.

    Look for a coherent break in the path. Low CTA engagement can indicate weak relevance, poor offer clarity, or insufficient evidence. Strong CTA engagement followed by low form completion points toward the form, its expectations, or a technical failure. High form completion followed by low-quality leads points toward targeting, qualification, or an offer that attracts the wrong action.

    Pair the landing-page conversion with a downstream measure when the business cares about lead or customer quality. Qualified leads, attended meetings, completed purchases, successful activations, or another relevant outcome can reveal whether an apparently improved page merely created more low-fit submissions. The correct downstream measure depends on the actual job of the page.

    Turn observations into testable hypotheses

    An A/B test should answer a decision, not provide movement for a dashboard. Write the hypothesis before building the variant:

    1. Describe the observed break in the conversion path.
    2. Name the most plausible mechanism behind it.
    3. Choose the smallest meaningful change that addresses that mechanism.
    4. Select the primary outcome and any guardrail, such as lead quality or completed purchases.
    5. Decide in advance how you will judge the result, and do not stop merely because one version takes an early lead.
    6. Record the traffic sources and audience segments included so the result is not applied beyond the visitors actually tested.

    For example, a large drop between form start and completion supports a form-friction hypothesis more directly than a headline hypothesis. You might clarify why a sensitive field is required, repair confusing validation, or remove a field that does not affect the next step. A random button-color test would not address the observed break.

    Keep variants interpretable. If you change the headline, offer, proof, layout, form, and CTA together, a different result will not tell you which mechanism mattered. A broader rebuild can still be appropriate when the baseline is fundamentally incoherent, but treat it as a page-level replacement rather than evidence that every individual change was beneficial.

    When traffic volume cannot support a credible comparison, do not pretend that a handful of conversions settles the question. Use message reviews, session-level diagnostics, form-error data, support or sales questions, and manual path testing to identify obvious defects. Make corrections with a clear rationale, then keep monitoring the business outcome.

    Key takeaways

    • Audit the promise that earns the visit before changing the design that receives it.
    • Make the audience, offer, outcome, commitment, and next step understandable near the beginning of the page.
    • Use calls to action that describe what will really happen after the click.
    • Remove form fields and page elements that do not support the decision or immediate follow-up, while preserving required controls.
    • Place proof and risk-reducing information beside the claims or actions they support.
    • Track the completed business action separately from diagnostic events such as clicks and form starts.
    • Prioritize the point where the conversion path visibly breaks, then test a change tied to a plausible mechanism.
    • Check lead or customer quality so a higher page conversion rate does not conceal a worse business result.

    Choose one commercially important landing page and write down its traffic promise, intended visitor, offer, primary action, and confirmed success event. Walk the full path once, then inspect the data for the first meaningful break. That break is your next change. Put it in a test or change log with the reason, expected effect, and business measure before you ship it.

    References


  • AEO Foundations: How to Build Content for Search Features

    AEO Foundations: How to Build Content for Search Features

    Your page can explain a subject accurately and still be passed over for a featured snippet, spoken answer or entity result. The usual problem is not a missing trick. It is that the page makes the answer engine infer too much: which question it answers, where the complete response begins, which entity the facts describe and how the information should be classified.

    Good answer engine optimization removes that ambiguity. You choose the search feature you are preparing for, build a self-contained answer unit, make entities and relationships explicit, add only the structured data the visible content supports, and measure whether the result improves. That sequence is the foundation of AEO.

    Pick the answer surface before you edit the page

    Do not begin with a broad keyword and a blank document. Begin with the job the searcher is trying to complete. A person asking for a definition needs a compact explanation. A person trying to complete a task needs ordered steps. A person searching for an organization, product, place or public figure may need an entity summary rather than another general paragraph.

    This distinction matters because search features present information differently. A featured snippet can extract a paragraph or list. People Also Ask can expose a self-contained response to a follow-up question. A voice assistant needs an answer that makes sense when spoken without the rest of the page. A Knowledge Panel is built around an entity and its relationships, not simply a matching phrase.

    Searcher jobSurface to prepare forUseful answer shape
    Get one fact or definitionFeatured snippet or spoken answerA direct paragraph that names the subject and answers immediately
    Complete a taskStep-based answerAn ordered list with one action per step
    Understand a person, organization, place or productKnowledge Panel or entity resultExplicit facts, attributes and relationships tied to the named entity
    Investigate the next questionPeople Also AskA question heading followed by a response that stands on its own
    Find an option in a specific areaVoice or local answerConversational wording with an accurate place qualifier

    These are editorial targets, not promises that a particular feature will appear. Their value is that they force you to decide what a successful answer looks like before you add more copy.

    Entity-oriented features require a different mental model from keyword matching. Google introduced the Knowledge Graph in 2012. It represents real-world things as connected entities, with attributes and relationships that help distinguish one meaning from another. Its basic workflow includes entity extraction, relationship mapping and knowledge integration. If a query could refer to several things, repeating the query phrase will not resolve the ambiguity. Clear names, types and relationships will.

    Write a one-page intent brief before revising the content. It only needs five fields:

    • Primary question: the complete question, written as the reader would ask it.
    • Required qualifier: the audience, location, product, condition or context without which the answer would be misleading.
    • Target surface: paragraph snippet, list, table, follow-up answer, spoken response or entity result.
    • Answer shape: the shortest format that can still give a complete and accurate response.
    • Next question: the useful follow-up that justifies the reader continuing beyond the extracted answer.

    If you cannot complete those fields, you do not yet have an AEO writing problem. You have an intent problem. Resolve that before changing headings or adding schema.

    Build a self-contained answer before adding depth

    A compact group of interlocking blocks forms a complete unit in front of a longer pathway of supporting layers.

    An answer engine should not have to assemble the response from five paragraphs. Put a descriptive question or task heading on the page, then answer it immediately below. The first sentence should state the conclusion. The next sentences can add the minimum qualification, condition or definition needed to prevent a misleading extraction.

    A 50- to 100-word answer is a useful editorial starting range for many straightforward questions. It is not a platform rule, and some answers need fewer or more words. Use the range as a forcing function: if the response cannot become clear within that space, the question may be too broad or the essential answer may still be buried.

    Example answer unit: Answer engine optimization, or AEO, is the practice of shaping web content so search and assistant systems can identify a question, understand the entities involved and extract a complete response. It combines intent-focused writing, an appropriate answer format, consistent facts and relevant structured data. AEO complements the technical and authority work that makes a page discoverable.

    That paragraph can sit at the top of a much deeper page. AEO favors brevity at the answer level, not shallowness at the page level. Once the direct response is complete, you can explain exceptions, evidence, implementation and related decisions. The short answer earns attention; the supporting material earns trust and helps the reader act.

    Use this sequence for each important question:

    1. Name the question. Use a natural heading that reflects the actual intent, not a fragment built only around a keyword.
    2. Lead with the answer. Do not open with background, history or a promise that the answer is coming.
    3. Repeat the subject where necessary. A sentence such as “It improves visibility” may lose its meaning when extracted. Name what “it” refers to.
    4. Add the decisive qualifier. Include the condition that changes the answer, especially when location, audience or content type matters.
    5. Choose the native format. Use prose for definitions and explanations, ordered lists for procedures, bullets for criteria and tables only for genuine comparisons.
    6. Expand below the answer. Add the reasoning, examples and next action without rewriting the same response several ways.

    Conversational language is particularly important for spoken and question-based searches. That does not mean filling every heading with awkward phrases such as “what is the best way to.” It means using the words a person would understand when hearing the answer once. Replace internal abbreviations, unexplained acronyms and vague category labels with plain terms.

    Do not manufacture an FAQ section merely to repeat facts already covered on the page. Split material into separate questions only when each heading represents a distinct intent and each response remains useful outside the surrounding section. Ten near-identical questions create ambiguity rather than coverage.

    Make entities and relationships explicit to people and machines

    Answer extraction works at the passage level, but entity understanding works across facts and relationships. A system needs to know whether a name refers to a company, person, product, place, concept or event. It also needs to connect attributes to the correct subject.

    Review the page as if the reader arrived without your site navigation, brand knowledge or previous paragraph. Then make these relationships explicit:

    • Use the entity’s full, consistent name near the beginning of the page.
    • State what kind of thing it is. A name alone does not establish whether it is an organization, service, method or product.
    • Attach each important fact to a named subject. Avoid a chain of pronouns when several entities appear in the same section.
    • Explain the relationship between entities in plain language, such as who created something, which organization operates it or which place an event belongs to.
    • Distinguish similarly named entities with an accurate qualifier instead of relying on capitalization or context clues.
    • Keep foundational facts consistent across the page and other important pages on the same site. Contradictory names, descriptions or relationships make the entity harder to interpret.

    This is not an invitation to repeat a brand name in every sentence. The goal is referential clarity. A reader should always know which entity owns the attribute or performs the action. If that is clear to the reader, you have also made the page easier for a machine to parse.

    Use structured data as a label, not a substitute for content

    Structured data describes visible information in a machine-readable form. JSON-LD can identify a content type, its properties and the entities it concerns without forcing those labels into the prose. Useful Schema.org types depend on the material: Article, FAQPage, HowTo, Recipe, Product and Event serve different purposes.

    Choose the closest accurate type. A tutorial is not automatically a HowTo merely because it contains advice. A page is not an FAQPage merely because question marks appear in its headings. The markup must describe what the reader can actually see, and every value should agree with the visible name, description, steps, dates or other facts.

    A reliable implementation sequence is:

    1. Identify the page’s primary content type and main entity.
    2. Select the most specific schema type that truthfully describes that content.
    3. Add only properties for information that is present and accurate on the page.
    4. Place the JSON-LD in the page head or body without changing the visible answer.
    5. Check that names, URLs, dates and relationships match the rendered page.
    6. Test the markup with Google’s Rich Results Test and resolve errors before publication.
    7. Recheck the markup whenever the visible facts or page purpose change.

    Passing a validator confirms that the markup can be parsed. It does not confirm that the content is correct, that the schema type is appropriate or that a search feature will select the page. Adding more unrelated schema will not repair a vague answer. Fix the content and entity relationships first, then use markup to describe them.

    Voice-oriented pages need the same discipline. Use a complete, natural response; include a location only when the question has local intent; and make the page usable on a phone. Conversational phrasing and mobile usability support question-based and voice-search behavior, but neither justifies adding a false local qualifier or rewriting every sentence as a question.

    Diagnose the missing feature instead of adding more copy

    A magnifying lens reveals an empty connector slot in a modular search-result mechanism beside unused stacks of blank cards.

    AEO improvement should be a controlled editing process. Record the page, target question, intended feature, current answer block and current search performance before you revise anything. Change the smallest element that addresses the observed failure. If you rewrite the answer, change the heading, replace the page structure and add several schema types at once, you will not know which decision helped or hurt.

    What you observeLikely communication problemNext edit to test
    The page receives relevant impressions but no direct-answer visibilityThe response is buried, incomplete or split across sectionsPut one complete answer immediately below a specific question heading
    The page appears for a broader or different questionThe heading or opening answer lacks a decisive qualifierAdd the audience, location, entity or condition that changes the meaning
    The answer is understandable on the page but confusing when isolatedIt relies on pronouns, prior definitions or surrounding contextRepeat the subject and include the minimum context needed to stand alone
    The structured data validates but no enhancement appearsValid syntax has been mistaken for guaranteed selectionVerify that the type matches the visible content; do not add unrelated markup
    Important brand or product facts are interpreted inconsistentlyNames, entity types or relationships vary between sections or pagesChoose canonical wording and correct the conflicting high-value pages
    A local or spoken query underperformsThe response sounds written rather than spoken, lacks an accurate place qualifier or is difficult to use on mobileRewrite the answer for one-pass comprehension and fix the specific local or mobile gap

    Use Google Search Console to monitor impressions and clicks for the relevant pages and queries. Record observed appearances in featured snippets or other answer surfaces separately, then compare them with the content change you made. Monitoring impressions, clicks and answer-feature visibility matters because validation alone cannot tell you whether the page is communicating the answer more effectively.

    Do not treat every impression increase as proof of AEO success. Check whether the page is appearing for the intended question and whether the extracted wording remains accurate. A larger audience for the wrong intent is not an improvement. If visibility rises while clicks do not, inspect the result itself and make the next step on the page genuinely useful; do not weaken the answer simply to withhold information.

    Key takeaways

    The foundations of answer engine optimization are a matched intent, an extractable response, clear entities, truthful structured data and disciplined measurement.

    • Choose the intended search feature before choosing the content format.
    • Place a direct, self-contained answer immediately below a specific heading.
    • Use paragraphs for definitions, ordered lists for procedures and tables for real comparisons.
    • Name entities, attributes and relationships clearly enough to survive extraction from the page.
    • Add the most specific accurate schema type, and keep its values aligned with visible content.
    • Measure one controlled change at a time using the target query and page, not sitewide traffic alone.

    For your next revision, choose one page built around a recurring question. Write the question in full, replace the opening response with a complete 50- to 100-word answer, check every important entity name, add only matching schema and record the baseline before publishing. Once that page has a clear question-to-answer path, you have a repeatable AEO process rather than a collection of search-feature guesses.

    References

  • AI-Era SEO: An Operating Model for Search and AI Visibility

    AI-Era SEO: An Operating Model for Search and AI Visibility

    Your team may have an SEO roadmap, an AI visibility dashboard, and several departments publishing different versions of the same product story. That is not mainly a tooling problem. It is an ownership problem.

    AI-era SEO still depends on discoverable pages, clear answers, credible evidence, and a usable website. The job has widened, though. You now need to keep your brand understandable across search results, generative answers, third-party mentions, sales conversations, and the journey that follows discovery. Here is a practical operating model for doing that without building a separate strategy around every new acronym.

    The channel changed; the job got wider

    People can investigate the same decision through a search results page, an AI-generated response, a publisher, a social discussion, or a vendor website. Those routes overlap, but they do not retrieve, summarize, or present information in exactly the same way.

    The behavioral shift is substantial enough to plan for. Of 2,000 consumers surveyed in June, 82% described AI-powered search as significantly more useful than traditional methods. That result reflects one survey, not a universal migration away from search engines, but it is a strong reason to examine whether your brand can be represented accurately outside a conventional results page.

    The terminology remains unsettled. GEO currently has enough recognition to work as a strategy label: 84% of surveyed practitioners recognized GEO, while 42% selected it when asked for one term to describe generative-platform visibility. Yet no acronym resolves the operational question: who is responsible when a system cannot understand, support, or accurately explain what your company does?

    Use the following as working definitions, not universal standards:

    LabelUseful operating meaningWhat it does not mean
    SEOThe umbrella discipline for making content discoverable, understandable, relevant, and useful throughout an organic search journey.Rankings alone, or work that ends when a visitor reaches the website.
    GEOA strategy for helping generative systems represent a brand, entity, product, or idea accurately and with support.A guaranteed method for earning a mention or citation from an AI system.
    AEOThe practice of making important questions and answers explicit, concise, and well supported.A reason to turn every page into a shallow collection of question-and-answer blocks.
    AISEO or AISOUmbrella language for SEO roles or programs that explicitly include AI-mediated discovery.A settled technical standard or a replacement for content, technical, authority, and user-experience work.

    A simple nomenclature policy prevents weeks of internal debate. Keep SEO as the established business function, use GEO for the generative-discovery workstream, and use AEO for answer design when that distinction helps. If your organization prefers another label, document it once and move on. The operating model matters more than the name.

    Treat visibility as an answer supply chain

    An isometric workflow moves source materials through verification and publishing stations before branching to web, search, AI, media, and sales channels.

    A search or AI answer is the visible end of a longer supply chain. Customer language enters the business, teams turn it into positioning and evidence, publishers distribute it, systems interpret it, and a person decides whether to take the next step. Weakness at any handoff can make an otherwise strong page irrelevant.

    1. Capture the decision. Start with what a person is trying to choose, verify, compare, or accomplish. Search queries are one input. Add recurring sales objections, customer-success questions, support language, account discussions, and the reasons prospects choose you or reject you.
    2. Define the facts. Establish the approved names, descriptions, relationships, capabilities, limitations, audiences, and differentiators that every team should communicate consistently.
    3. Attach evidence. Connect each material claim to a page, case study, demonstration, policy, customer example, or other evidence that actually supports it. If nobody can point to support, rewrite or remove the claim.
    4. Publish and reinforce. Express the same core meaning across product pages, educational content, communications, public relations materials, customer resources, and relevant third-party profiles. Adapt the format to each audience without changing the underlying fact.
    5. Complete the journey. After discovery, make the logical next action obvious. A correct answer that leads to an unclear page, an unexplained form, or an irrelevant call to action has not created much business value.

    This model changes how you diagnose poor visibility. Do not begin with, “How do we get mentioned by an AI tool?” Begin with, “Which decision are we failing to support, and where does the answer supply chain break?” The problem might be missing evidence, contradictory descriptions, weak distribution, inaccessible content, or a landing page that does not continue the conversation.

    Empathy becomes operational here. You need to understand the person’s uncertainty, the constraints of the platform presenting the answer, and the internal team responsible for the missing input. Machines do not need empathy. The people asking questions, building platforms, approving claims, and acting on answers do.

    Build a canonical brand knowledge layer

    Six workplace teams connect to one illuminated central archive containing organized product facts, evidence, policies, insights, and visual assets.

    Most large organizations do not lack content. They lack agreement. A product page uses one category name, sales uses another, public relations emphasizes a third, and customer success explains the offer in language that never reaches the website. Each version may be defensible in isolation while the combined brand becomes difficult to interpret.

    Create a claim ledger before creating more pages

    A claim ledger is a controlled record of what the organization is prepared to say and prove. Build it around one priority offer first. Give every entry the fields needed for review, reuse, and correction:

    • The entity, product, service, or capability being described.
    • The approved name and concise description.
    • The audience and customer problem to which the claim applies.
    • The exact claim, including any limitation or qualification needed to keep it accurate.
    • The evidence and canonical URL supporting the claim.
    • The business owner responsible for accuracy.
    • Permitted wording variants for different channels or audiences.
    • The review trigger, such as a product change, policy change, expired proof point, or revised positioning.

    Separate facts from promotional language. “The product includes capability X” is a factual claim that product should verify. “The easiest way to solve Y” is a comparative or persuasive claim that requires a different standard of support. Mixing the two is how unsupported superlatives spread across pages and later become difficult to correct.

    Turn the ledger into an enterprise ontology

    An ontology is the organized map behind the ledger: what the important entities are, which names refer to them, how they relate, and which attributes belong to each one. You do not need to model the entire company at once. Start with the entities needed to explain one buyer decision without ambiguity.

    • Define the company, brand, offer, category, audience, problem, capability, and evidence entities involved in the decision.
    • Record preferred names, accepted variants, and terms that should not be treated as synonyms.
    • Map relationships explicitly: which company offers which product, which capability addresses which problem, and which evidence supports which claim.
    • Identify exclusions and limits. Knowing what an offer does not do can prevent a damaging overstatement.
    • Assign an owner to each business-critical entity so changes have a clear path into content and data.

    Consistency does not require identical copy everywhere. A technical page, a press briefing, and a sales deck serve different readers. Their depth and tone should differ. The entity name, category, capability, limitation, and proof should not contradict one another.

    Align visible content and JSON-LD

    Treat JSON-LD as the machine-readable expression of the same knowledge layer, not as an independent growth hack. The visible page and its structured data should describe the same entity, relationships, and facts. Markup should never introduce an aspirational claim that the page itself does not support.

    Use this order of operations: approve the fact, publish a clear human-readable explanation, encode the matching structured data, and then distribute or reinforce the fact elsewhere. Starting with markup merely gives a contradictory organization another place to contradict itself.

    • Check that names, descriptions, and relationships match the approved knowledge layer.
    • Confirm that important claims have visible evidence a reader can inspect.
    • Remove stale markup when the corresponding offer, fact, or page changes.
    • Find older pages, profiles, and downloadable assets that still use obsolete positioning.
    • Record corrections in the ledger so the same discrepancy does not return during the next campaign.

    Structured data can reduce ambiguity, but it cannot force a search engine or generative system to use, cite, or endorse your content. Its strategic value comes from expressing a truthful and consistent model of information you have already made clear.

    Make every function responsible for one part of the answer

    AI-era visibility becomes fragmented when each department optimizes its own output. Product focuses on features, public relations focuses on reputation, analytics focuses on exposure, and SEO tries to reconcile the results after publication. Give each function a defined responsibility inside the answer supply chain instead.

    • Product marketing owns the approved positioning, audience, differentiators, and visual explanation of the offer.
    • Product confirms feature names, current behavior, limitations, and changes that make existing content inaccurate.
    • Communications and public relations carry consistent facts into announcements, briefings, profiles, and outreach while respecting the editorial independence of third parties.
    • Customer success contributes recurring questions, implementation language, adoption barriers, and evidence that reflects real customer needs.
    • Sales and account executives contribute decision-makers, objections, comparison criteria, buying language, and reasons a prospect chooses or rejects the offer.
    • Analytics connects discovery activity with useful actions and distinguishes exposure from qualified progression.
    • Compliance reviews claims whose wording creates regulatory, contractual, or reputational exposure and states the boundaries teams must preserve.

    Do not ask every department to “do GEO.” That request is too abstract to own. Bring each team a named discrepancy: an outdated product description, a missing proof point, an objection nobody answers, a case study disconnected from the relevant offer, or a discovery path that ends on the wrong page.

    Run a narrow pilot around one decision

    A useful pilot is organized around a customer decision, not an AI platform. Choose one important offer, one audience, and one decision where inaccurate or incomplete representation has a plausible business consequence.

    1. Write the questions a person asks while discovering, comparing, validating, and acting on that decision.
    2. Capture the current environment: search results, relevant AI answers, owned pages, third-party profiles, sales materials, and the destination pages offered to the user.
    3. Classify each problem as absent, inaccurate, unsupported, inconsistent, inaccessible, or a journey dead end. This makes the remediation assignable.
    4. Trace every problem back to its owner. Product corrects a capability. Customer success supplies an implementation answer. Communications resolves a stale profile. Content publishes missing evidence. Web teams repair the next step.
    5. Update the canonical facts before updating individual channels. Otherwise, each team may solve the same discrepancy differently.
    6. Revise the relevant pages, structured data, supporting assets, and approved external materials.
    7. Repeat the documented questions, inspect the resulting pages, and test the user’s path to the intended action. Record what changed and what remains unresolved.

    This framing can change internal participation. A cross-functional GEO pilot can turn a resisted outreach task into a shared brand-clarity problem because every participant can see the inaccurate representation and the part they control.

    Do not confuse consistency with syndicating identical copy. Preserve the same factual meaning while allowing each channel to serve its audience. You can govern your claims and approved assets; you cannot require an independent publisher to use your preferred wording or reach your preferred conclusion.

    Measure accuracy and decisions, not just exposure

    Traffic, rankings, and visibility remain useful diagnostics. They are not a complete account of AI-era performance. A report that ends with those metrics cannot show whether teams corrected a false claim, supported a buyer decision, or removed friction after discovery.

    Use a scorecard tied to the answer supply chain

    • Decision-question coverage: the share of monitored priority questions for which the brand is represented in a relevant and accurate context.
    • Claim accuracy: the share of sampled statements about the brand that are correct and supportable under your agreed review rubric.
    • Evidence coverage: the share of material claims connected to current, accessible proof.
    • Cross-surface consistency: the share of checked priority surfaces that agree on core names, categories, capabilities, and limitations.
    • Correction cycle time: the elapsed time between identifying a material discrepancy and correcting the surfaces under your control.
    • Journey completion: the share of tested discovery paths on which a person can find the promised information and complete the intended next action without an avoidable block.
    • Business contribution: qualified inquiries, assisted opportunities, retained accounts, or other business outcomes in which a monitored discovery path played a documented role.

    Define the rubric before scoring results. Decide what counts as a relevant appearance, a material error, acceptable supporting evidence, and a completed journey. Establish your own baseline rather than borrowing a universal benchmark that ignores your category, buying cycle, risk, and current visibility.

    Sample AI answers as observations, not fixed rankings

    Log enough context to make each observation interpretable: the exact question, platform, model or mode when displayed, language, location, observation date, logged-in state, response, cited URLs, and evaluator. Repeat the same controlled question set over time and retain the outputs.

    A single response is evidence of what happened in one run, not a stable market-share percentage. Look for repeated patterns: the same factual error, the same missing proof, the same competitor framing, or the same destination-page problem. Those patterns tell you where to intervene even when individual wording changes.

    Connect visibility to the nearest defensible outcome. If revenue attribution is not available, use qualified progression, completed tasks, evidence coverage, resolved objections, or correction speed. Label proxies as proxies. Do not convert an appearance count into an invented revenue claim.

    Key takeaways

    • Keep SEO as the operating foundation; use GEO and AEO to describe distinct work when the labels improve ownership.
    • Organize the program around customer decisions and answer supply chains, not around whichever AI platform is receiving attention.
    • Build a controlled knowledge layer linking approved claims, entities, evidence, owners, pages, and structured data.
    • Require consistency of meaning across teams and channels, not word-for-word duplication.
    • Start with one offer, one audience, and one decision so every discrepancy has an accountable owner.
    • Measure accuracy, evidence, journey completion, correction speed, and business contribution alongside traffic and visibility.

    Your next move is small but consequential. Select one high-value question a buyer asks before choosing your offer. Trace the answer from customer language to approved claim, supporting evidence, search or AI representation, destination page, and next action. Mark every contradiction and dead end, then bring the responsible teams together to resolve those specific failures.

    That completed loop is more valuable than another visibility dashboard. It gives you the repeatable unit from which an AI-era SEO operating model can grow.

    References

  • Microsoft Publisher Ad Safety: A Clarity Compliance Plan

    Microsoft Publisher Ad Safety: A Clarity Compliance Plan

    If your site earns revenue from Microsoft Advertising inventory, a missing analytics implementation can now become a billing problem. Impressions and clicks from pages without activated Microsoft Clarity can be filtered out as nonbillable, even when the rest of your publisher setup appears healthy.

    Your goal is not merely to add a tag to the homepage. You need to know that every monetized page type loads Clarity, has Consent Mode activated, and remains covered when templates, consent tooling, or tag rules change.

    Treat Clarity as a page-level revenue requirement

    Microsoft requires third-party publishers to install Clarity and activate Consent Mode to continue receiving paid impressions and clicks through Microsoft Advertising. The important operational detail is where enforcement happens: billing eligibility is tied to traffic from pages where Clarity is active.

    That creates several possible partial-compliance states. Your Clarity account may exist while a newly launched template omits its code. The homepage may pass while an archive, community, or commerce template does not. A consent banner may display while Consent Mode has not actually been activated for Clarity. Each case looks superficially complete but leaves affected inventory exposed.

    The failure may not appear as a broken page or a rejected ad request. It can surface later as an unexplained difference between the activity you expected to monetize and the impressions or clicks treated as billable. That is why an account-level check is too coarse. Compliance needs to be tested at the same level at which your site serves inventory: the live page.

    Build the implementation around monetized templates

    A central website template branching into several page layouts, each with an ad placeholder, analytics module, and shared consent layer.

    Start with a map of your ad-bearing surfaces, not a count of all published URLs. A large site may generate many URLs from a relatively small set of templates. If you verify the actual rendering paths, you can cover the inventory systematically and repeat the audit after a release.

    1. Inventory every monetized surface. List the templates, applications, subdomains, and partner-managed experiences that actually carry Microsoft Advertising inventory. Include alternate mobile, regional, logged-in, and cached variants where they use different rendering paths.
    2. Identify the injection point for each surface. Record whether Clarity is delivered through a shared site template, a tag manager, an application component, or another controlled mechanism. Do not assume one global configuration reaches every publishing system.
    3. Choose the measurement scope deliberately. A sitewide installation reduces the chance that a new monetized route will be missed. A narrower deployment limits measurement to the surfaces that need it. Either approach must cover every page whose Microsoft Advertising impressions and clicks you expect to be billable.
    4. Install Clarity on every in-scope rendering path. The correct technical location varies by CMS and application architecture. The acceptance criterion does not: a representative live page must execute Clarity and send behavioral activity to the intended Clarity property.
    5. Activate Consent Mode. Installing Clarity alone does not satisfy the stated requirement. Confirm that Consent Mode is enabled and that Clarity’s behavior corresponds to the consent choices presented by your site.
    6. Assign owners and retain evidence. Record the tested URL, template, result, date, and responsible owner. Give ad operations responsibility for inventory scope, engineering or analytics responsibility for execution, and your privacy owner responsibility for consent configuration.

    That ownership split matters because the requirement crosses three systems that are often managed separately. Ad operations knows where inventory exists. Engineering or analytics knows how the tag is deployed. Privacy specialists know how the site’s consent experience is intended to behave. A launch can fail when any one of those teams assumes another team verified the complete path.

    Validate live behavior, not just the presence of code

    Desktop, tablet, and phone displaying abstract publisher pages while a magnifying lens highlights an active consent and analytics connection.

    A code snippet in a template is implementation evidence, but it is not proof that the finished page works. Production consent rules, tag conditions, application errors, content security controls, and alternate templates can change what actually executes. Test representative live URLs and confirm the result at each layer.

    ControlPass conditionTypical coverage gap
    Clarity executionAn interaction on a representative live URL produces the expected behavioral data in the intended Clarity property.A Clarity property exists, but the tested route does not load or execute its implementation.
    Consent ModeConsent Mode is activated and Clarity’s observed behavior matches the consent choices exercised during the test.The consent interface appears on the page, but Clarity is not connected to the site’s consent handling.
    Template coverageAt least one live URL from every monetized template and material variant passes the execution and consent checks.The main article template passes while another ad-bearing route remains unmeasured.
    Billing investigationA change in billable impressions or clicks is checked against page-level deployment evidence before the team draws a conclusion.A missing template implementation is hidden inside aggregate traffic or revenue reporting.
    Release resilienceThe checks are repeated after changes to the CMS, theme, tag manager, consent platform, application shell, or ad layout.A compliant implementation quietly drifts out of coverage after a later release.

    Do not infer full compliance because you can see activity in Clarity. That proves that some pages are reporting, not that every monetized page is reporting. The reverse is also important: a billing change does not by itself prove a Clarity failure. Compare the affected page types and deployment evidence before you diagnose the cause.

    Add this matrix to the release criteria for any system that can create or modify ad-bearing pages. A one-time audit fixes the current implementation. A release check prevents the next template, redesign, or consent change from recreating the same exposure.

    Keep eligibility, ad safety, and optimization distinct

    Clarity now has more than one role in a Microsoft publisher operation. Separating those roles will help you avoid making claims that the data cannot support.

    • Revenue eligibility: Clarity and Consent Mode are required controls, and uncovered page traffic can be excluded from billable impressions and clicks.
    • Ad-safety visibility: Microsoft is using the added transparency to support its editorial and safety standards and give advertisers more confidence in where their ads appear.
    • Publisher optimization: click, scroll, and engagement patterns can help you identify friction in the user experience and improve conversion paths.

    Do not treat the presence of Clarity as automatic editorial approval. Instrumentation gives Microsoft visibility into the page and makes the required control enforceable; it does not remove your responsibility to maintain acceptable content, placements, and user experience.

    Likewise, do not treat behavioral analytics as a reason to maximize ad interactions at any cost. Use the data to notice broken journeys, unclear navigation, unread content, or conversion friction. An increase in clicks is not inherently an improvement if the placement confuses the user or undermines the quality of the page.

    Consent Mode also needs to be treated as an operational privacy control, not a checkbox. Its required activation does not replace accurate notices, appropriate consent choices, or review of the rules that apply to your audience and configuration. If your team is uncertain about those obligations, have the deployment reviewed by the person responsible for privacy or by qualified legal counsel before broadening data collection.

    Key takeaways for publisher teams

    • Microsoft requires third-party publishers to install Clarity and activate Consent Mode for paid impressions and clicks through Microsoft Advertising.
    • The financial consequence is page-specific: activity from pages without active Clarity can be filtered as nonbillable.
    • An account, homepage, or global tag-manager check is insufficient when monetized templates have different rendering paths.
    • Validate Clarity execution, incoming behavioral data, Consent Mode, and template coverage on representative live URLs.
    • Repeat the audit after CMS, theme, application, tag-manager, consent, or ad-layout changes.
    • Use Clarity’s behavioral insights for user-experience and conversion decisions without confusing analytics data with editorial approval.

    Before your next publisher release, select a live URL from every monetized template and run it through the validation matrix. Fix any uncovered rendering path before you spend time investigating downstream revenue discrepancies. That small release discipline turns Clarity compliance from a fragile installation into a maintained revenue control.

    References