Tag: Campaign Strategy

  • B2B Video Sales Strategy: Win the Shortlist Before the Demo

    B2B Video Sales Strategy: Win the Shortlist Before the Demo

    Your sales team gets the meeting, sends a polished demo, and still hears that the buyer is leaning toward a familiar competitor. That is often not a demo problem. The vendor list may have hardened before the buyer ever filled out your form.

    LinkedIn and Bain & Company found that 86% of buyers had preferred vendors in mind on Day 1, while 81% eventually chose from their initial list. Without a disclosed sample and method, those percentages should guide prioritization rather than forecast your pipeline. The practical point is still hard to ignore: your B2B video strategy has to create recognition before demand appears, reduce risk while the buying group evaluates you, and make the next step easy when intent arrives.

    Build recognition across the buying group before intent appears

    Day 1 is not necessarily the day an inquiry reaches sales. It is the point at which people inside an account begin forming a mental shortlist. By the time they search for a category, download a comparison, or request a proposal, familiar vendors already have an advantage.

    That advantage belongs to the buying group, not just your internal champion. A functional leader may like your product and still fail to move the deal when finance, procurement, security, or an executive approver encounters an unfamiliar company. In the reported buying data, a vendor known across the group was more than 20 times likelier to be selected on Day 1. Treat that figure as directional platform evidence, not a guaranteed multiplier. It is a strong reason to stop defining reach as contact with one lead.

    Start your strategy with a buying-group map. Do not begin with a list of video formats.

    1. Name one buying situation. Describe the moment that makes the account reconsider its current approach, not merely the category you sell.
    2. Write one memory sentence. It should connect that situation to the change your company enables without trying to explain every feature.
    3. List the roles that can advance, fund, review, use, or block the purchase. Remove roles that do not participate in this specific buying situation.
    4. Give each role one question to answer. A user may ask whether the workflow will improve. A functional leader may ask whether the change can be implemented. A budget owner may ask whether the choice is defensible. A reviewer may ask what new exposure it creates.
    5. Create role-specific cuts from the same narrative. Keep the central promise consistent, but change the proof, language, and next step for the viewer.
    6. Distribute those cuts through paid media, executive and employee channels, relevant website pages, and sales follow-up. The story should travel across channels even when the individual video files differ.

    This approach prevents a common failure: one broad brand video reaches many people but gives none of them a reason to remember you. Recognition requires both reach and a usable memory. The viewer should be able to repeat what problem you understand and why your approach belongs on the shortlist.

    Measure this stage at the account and role level. Total impressions can hide the fact that you repeatedly reached users while missing economic buyers and approvers. Track which target accounts saw the campaign, which relevant roles were represented, whether those accounts returned, and whether later opportunities contained prior video exposure. You are looking for buying-group coverage, not a large anonymous view count.

    Give every video one job in a three-play portfolio
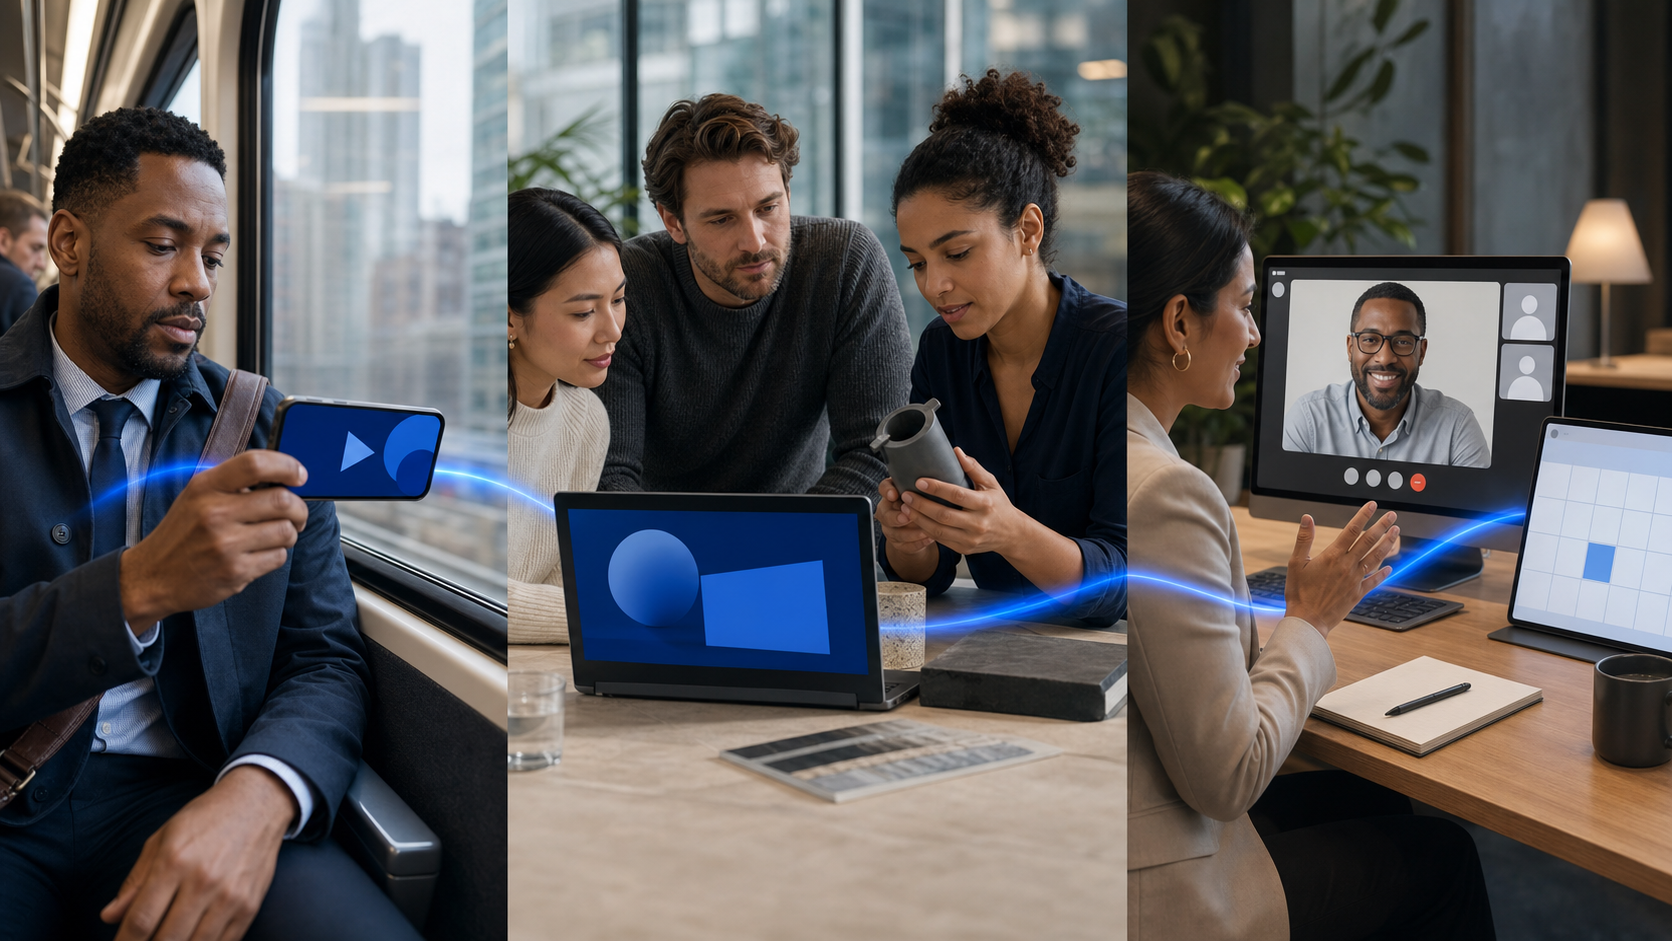
    Three connected scenes show an executive noticing a phone video, a buying group reviewing product proof, and a buyer joining a sales meeting.

    A demo is not an awareness asset, and a memorable brand clip is not a substitute for implementation proof. Trying to make one video perform every sales job usually produces a slow introduction, a rushed product section, weak evidence, and an abrupt request to book a meeting.

    Build a connected portfolio instead. Each play should answer a different buyer question and earn a different next action.

    PlayBuyer momentQuestion to answerVideo jobAppropriate next step
    Reach and primeBefore active evaluationHave I heard of this company, and what is it known for?Create a memorable association between a buying situation, a point of view, and your brandWatch, visit a focused page, or remember the brand
    Educate and nudgeWhile options are being exploredCan I trust and defend this approach?Explain the change, show expertise, and reduce perceived professional riskReview proof, understand the process, or share the asset internally
    Convert and captureWhen the group is ready to actWill this work here, and how difficult will the next step be?Resolve a specific objection and remove friction from the handoffSubmit a form, request an assessment, or begin a sales conversation

    Play 1: Reach and prime

    Your first-play video is a memory device. It does not need to present the interface, introduce every service line, or prove the full business case. It needs to make one relevant idea easy to notice and easy to retrieve later.

    A useful script sequence is: recognizable buying situation, sharp point of view, credible promise, brand cue. For example, the situation should be concrete enough that the right viewer recognizes their work. The point of view should reveal how you think. The promise should name the direction of improvement without making an unsupported result claim. The brand cue should arrive while attention is still present, not after a long cinematic reveal.

    The call to action should match that modest job. Asking a cold viewer to schedule a complex consultation can create unnecessary friction. A focused page, a related explanation, or simply a clear branded ending may be enough. The purpose is to improve the odds that your company feels familiar when the account begins evaluating vendors.

    Play 2: Educate and nudge

    Once viewers recognize you, the task changes from getting noticed to becoming buyable. Capability matters, but a technically strong product can still lose if the person recommending it expects to be blamed for a poor outcome. Only two of five leading buyer considerations centered on product capability, while 34% prioritized confidence that they could defend the decision if it went wrong.

    Your evaluation videos should therefore answer the questions a buyer will hear in an internal review:

    • Why should we change the current approach?
    • What makes this method credible rather than merely different?
    • What has to be true for it to work?
    • What will our team need to contribute?
    • What are the likely objections from finance, procurement, operations, or leadership?
    • What evidence can the champion forward without having to reinterpret it?

    Strong assets at this stage include an executive explaining a category change, a practitioner walking through the operating process, a customer describing a comparable decision, and a direct response to a recurring objection. The goal is not to overwhelm the viewer with information. It is to give the buying group language and evidence it can reuse when you are not in the room.

    Play 3: Convert and capture

    A conversion video should stop broad persuasion and help the viewer complete one next step. State what will happen after the click, who will be involved, what information is needed, and what the buyer will receive. If the form opens onto an unexplained sales process, the video has not removed the important friction.

    On LinkedIn, combining video ads with immediate lead-generation forms was reported to triple form open rates. That platform benchmark is a testable hypothesis, not a promise. Compare the full path in your own campaign: form opens, completed submissions, accepted meetings, qualified opportunities, and progression after the first call.

    Match the handoff to sales-cycle length. For a cycle under 30 days, the suggested starting pattern is a direct video-and-form combination that captures intent immediately. For a longer cycle, retarget engaged viewers with expert-led material and invite a useful conversation rather than forcing an early transaction. In either case, define what the next step gives the buyer. Learn more is not a value proposition.

    Make the first frame work with the sound off

    B2B video is often reviewed in a quiet office, between meetings, or inside a fast-moving feed. If meaning begins only when a speaker finishes an introduction, much of the audience never reaches the point.

    On LinkedIn, 79% of users were reported to browse without sound. The same platform data associated bold colors with 15% higher engagement and clear, process-oriented steps with 13% better retention. Those figures do not mean every brand should use the same palette or turn every message into a numbered list. They show why visual contrast and immediate structure deserve a place in the brief.

    Use this silent-first production check before approving a cut:

    • The first frame identifies a relevant situation, tension, or outcome. A logo by itself does not do that job.
    • Captions begin with the first meaningful spoken line. Do not make the viewer wait for context.
    • On-screen text carries the essential nouns and verbs. Keep supporting detail in the narration, caption track, or destination page.
    • Each visual beat advances one idea. Decorative motion should not compete with the claim.
    • The brand appears while the central idea is being communicated, not only on an end card that many viewers will never see.
    • The last frame names a specific next action and the value of taking it.

    For awareness on LinkedIn, videos in the 7-to-15-second range produced stronger brand lift than shorter or longer alternatives. Keep the qualifier attached: that is an awareness finding from one platform, not a universal length for demos, customer stories, webinars, or sales follow-up. An evaluation video should be as long as necessary to answer its assigned question and no longer. Cutting a complex proof point to fit an awareness benchmark can make the asset less useful.

    Use repeatable storyboards instead of one universal template

    • For recognition: show the buying situation, introduce a counterintuitive point of view, connect it to a credible promise, and close on a brand cue.
    • For evaluation: state the buyer’s question, make the claim, show the mechanism or process, supply proof, address the strongest objection, and offer a deeper resource.
    • For conversion: identify the peer or use case, show the relevant outcome, clarify what the buyer must do, explain what happens next, and present the form or conversation as a useful exchange.

    Use cultural references and memes carefully. They were associated with 41% and 111% higher engagement, respectively, in the reported platform data. Engagement is not the same as trust, buying-group coverage, or revenue. A reference earns its place only when your audience understands it, your brand can carry it naturally, and it sharpens the commercial point. If the joke is more memorable than the problem you solve, it has taken over the asset.

    Resolve execution, decision, and effort risk with proof
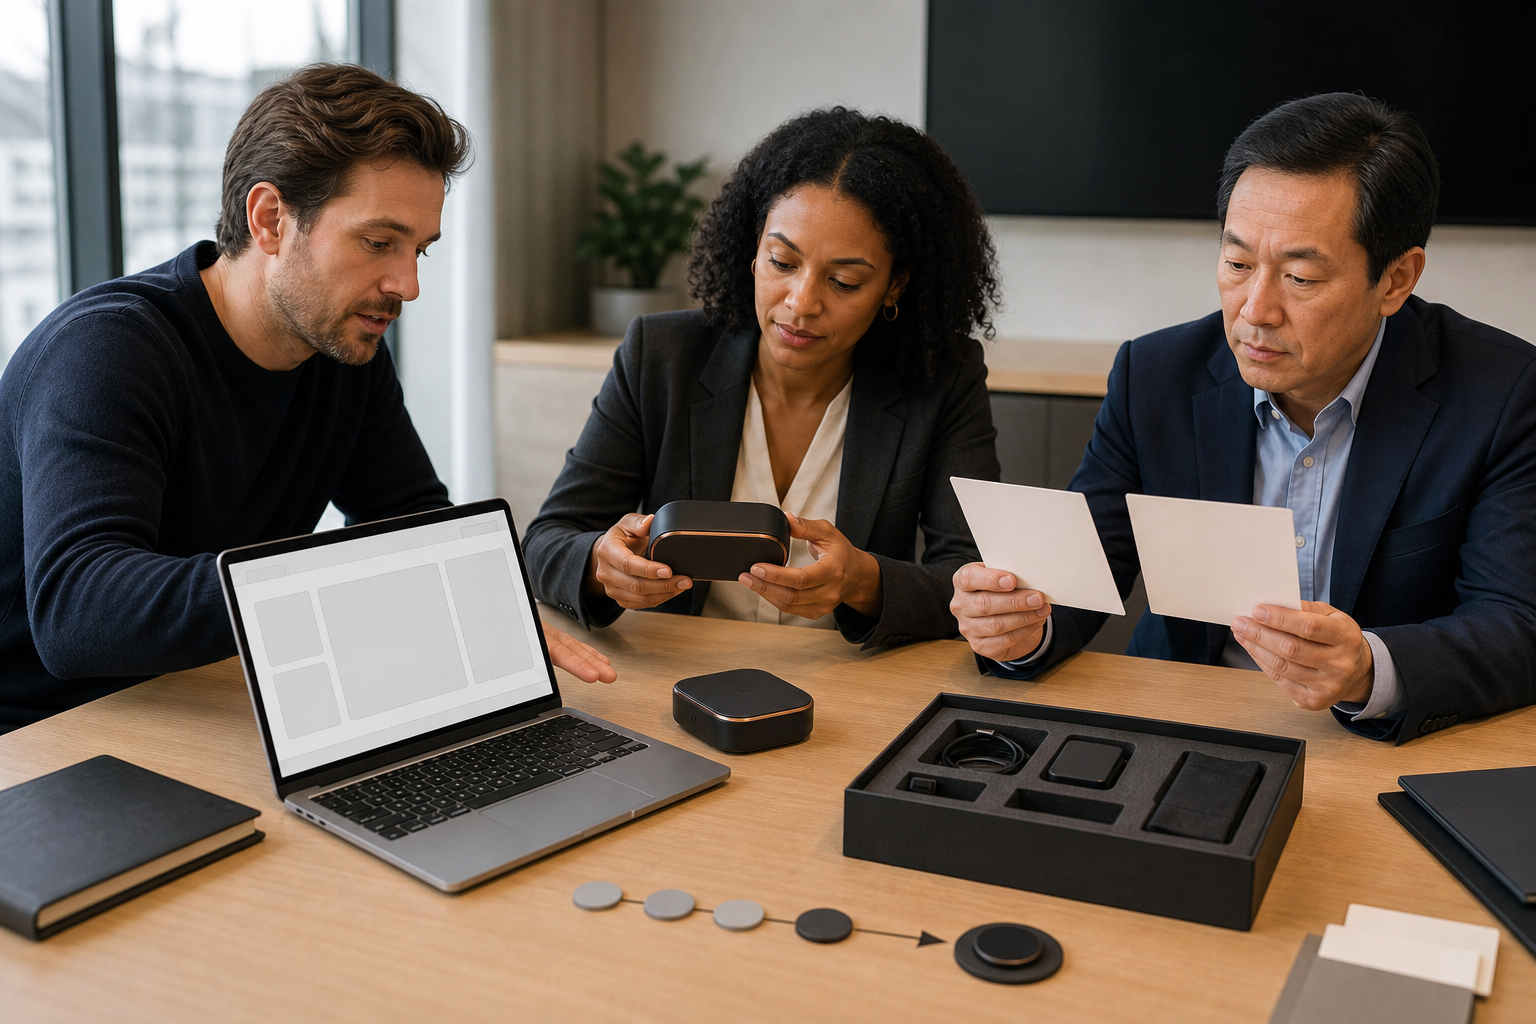
    Three business decision-makers review a product workflow, a finished deliverable, and an implementation kit with a technical specialist.

    Late-stage buyers do not need another general claim that your solution is powerful, seamless, or innovative. They need evidence that addresses the downside they are trying to avoid. Separate that anxiety into three practical categories before choosing the speaker or format.

    • Execution risk: Will the solution produce the expected result in an organization like ours? Use a credible peer, comparable context, and a clear explanation of what changed.
    • Decision risk: Is this a choice I can recommend and defend? Use expert reasoning, transparent decision criteria, and visible people who can support the account.
    • Effort risk: How difficult will adoption be? Show the implementation process, responsibilities, dependencies, first milestone, and the support available after purchase.

    Social proof is especially important here. A reported 90% of buyers rely on social proof, but a wall of customer logos gives the buying group little material to evaluate. A recognizable logo may signal familiarity. It does not explain whether the customer faced the same constraint, made the same tradeoff, or completed a comparable implementation.

    Build a customer proof video around information the viewer can actually use:

    1. Identify the customer’s role and relevant operating context.
    2. Describe the prior condition without inflating the problem.
    3. Explain the criteria used to choose an approach.
    4. Show what implementation required from both sides.
    5. Present only outcomes the customer has verified and approved for publication.
    6. Name an important condition, limitation, or lesson so the story does not sound frictionless.
    7. Point to a page or conversation where the buyer can examine the proof in more depth.

    Real people also make the vendor easier to evaluate. On LinkedIn, ads featuring executive experts were associated with 53% higher engagement, rising to 70% for executives shown speaking on conference stages. The useful lesson is not to manufacture stage footage. Put credible subject-matter experts in situations where their expertise is visible: explaining a tradeoff, challenging a weak assumption, or walking through a decision.

    Employee distribution can extend that trust beyond a corporate account. Regular posting by only 3% of employees was associated with a 20% lift in lead generation. Do not turn 3% into a staffing target or pressure employees to repeat approved slogans. Start with people who already have useful expertise and a credible relationship with the audience. Give them a clear topic, factual guardrails, captions, and room to speak in their own voice.

    For effort risk, show enough of the process to make the work legible. Explain the first meeting, the information the buyer must supply, the teams typically involved, and the ownership on each side. Do not claim implementation is effortless if it is not. Visible complexity can be managed; hidden complexity damages confidence after the contract is signed.

    Run one always-on system and measure movement, not views

    A three-play strategy fails when brand, demand generation, sales, and customer marketing operate separate video libraries. Brand buys broad reach. Demand generation asks for form fills. Sales records one-off explainers. Customer marketing owns the usable proof. The buyer then encounters different claims, visual identities, and promises at each stage.

    Create one shared brief for every asset. It should contain the buying situation, target roles, assigned play, risk being addressed, claim, approved proof, channel, next action, and success metric. Give every video an identifier that follows it into campaign reporting, landing-page analytics, and the CRM. That makes it possible to see which asset introduced an account, which one deepened evaluation, and which one preceded a qualified handoff.

    Consistency matters more than occasional bursts. Always-on campaigns were associated with 10% higher conversions than campaigns that repeatedly stopped and restarted. Always-on does not mean running one creative indefinitely. It means preserving continuous buying-group coverage while rotating messages, speakers, proof, and formats as performance or buyer questions change.

    Measure each play against the movement it is supposed to create:

    • Reach and prime: target-account reach, role coverage, frequency, qualified visits, and later opportunity exposure.
    • Educate and nudge: repeat engagement from target accounts, completion of substantive proof assets, visits to customer or implementation pages, internal sharing where observable, and influence on open opportunities.
    • Convert and capture: form open-to-submit rate, accepted meetings, qualified-opportunity rate, progression after the meeting, and time to the agreed next step.

    Views, watch time, and engagement remain useful creative diagnostics. They are not interchangeable with commercial progress. If an asset earns attention but reaches the wrong roles, produces no deeper evaluation, and never appears in opportunity journeys, decide whether it needs a different audience, message, or place in the portfolio.

    Companies that connected video across the buying journey were reported to generate up to 1.4 times as many leads. That relationship does not prove that integration alone caused the lift. Use it as a reason to test a connected system against your current fragmented approach, with the same commercial definitions on both sides.

    Key takeaways

    • Enter the buying process before active demand by building recognition across the full buying group, not only the likely user or champion.
    • Assign every video one job: create memory, make the choice defensible, or remove friction from the next step.
    • Design awareness video for silent viewing, immediate context, and fast brand association; do not force its length rules onto proof-heavy assets.
    • Sell buyability as well as capability by answering execution, decision, and effort risk with verifiable proof.
    • Use experts, customers, and employees because of the specific questions they can answer, not merely because a human face tends to attract engagement.
    • Connect brand and demand measurement at the account level so views can be related to buying-group coverage, evaluation, and pipeline movement.

    Start with one buying situation and one account segment. Build three connected assets: a silent recognition cut, a risk-answering expert or customer explanation, and a conversion video that makes the next step explicit. Give each asset its own audience, action, and metric, then distribute them as a sequence rather than three unrelated campaigns.

    Your next sales video should not begin with a camera choice. It should begin with a buying-group role, a risk, and a next action. If the brief cannot name all three, do not shoot yet.
    References

  • How to Build an Intent-Driven Google Ads Strategy

    How to Build an Intent-Driven Google Ads Strategy

    Your Google Ads account can be neatly organized by match type and still be built around the wrong thing. A searcher does not arrive as an exact-match phrase or a broad-match variant. They arrive with a problem, a level of awareness, and a decision they are trying to make.

    An intent-driven strategy connects that decision to your campaign structure, ad promise, landing page, and measurement. You still use keywords, but you stop asking them to carry the entire strategy.

    Stop treating the keyword as the whole decision

    The practical change is not that keywords have disappeared. It is that Google can increasingly interpret the goal behind a search instead of relying only on a literal query-to-keyword correspondence. Complex questions can be decomposed into related subtopics through query fan-out and intent inference, allowing an apparently informational search to reveal a plausible commercial next step.

    Consider the query Why is my pool green? The wording does not name a product. The underlying job is troubleshooting, however, and products may be part of the solution. A campaign limited to explicit product language can miss that relationship. A campaign that chases every pool-related question without understanding the product’s role can waste money just as easily.

    Intent is the bridge between those two extremes. It explains why the person is searching and where your offer fits. The keyword remains useful as a targeting input, an observation point, and a control. It should not automatically determine the account architecture.

    The reverse problem matters too. Identical words do not guarantee identical intent. Someone searching for best CRM may be learning which features matter, creating a shortlist, replacing an existing system, or preparing to contact a vendor. Google can make contextual distinctions between searches that look alike. Your messaging and destinations need to account for them as well.

    Before assigning a query to a campaign, answer four questions:

    • What problem is the person trying to resolve? Name the situation in the customer’s language, not your internal product category.
    • What decision are they making now? Diagnosing, exploring, comparing, selecting, and returning to buy are different jobs.
    • What role can the offer legitimately play? It might explain the problem, provide a tool, supply a remedy, replace an existing solution, or complete a purchase.
    • What is the smallest appropriate next step? Reading an explanation, comparing options, checking fit, viewing an offer, requesting contact, and purchasing are not interchangeable.

    That four-part description is your intent hypothesis. It is a hypothesis because a query rarely proves intent by itself. You validate it through the search terms that appear, the pages people use, and the business outcomes that follow.

    Build an intent map before changing campaign structure

    A strategist arranges icon clusters for learning, comparison, local action, and purchase around a central searcher symbol on a tabletop.

    Do the first pass outside the Google Ads interface. A worksheet forces you to describe the customer decision before the existing campaign names and match types pull you back into the old structure.

    1. Inventory the language already reaching the account. Collect meaningful search-term themes, current keywords, ads, landing pages, and conversion actions. You are looking for recurring situations, not merely recurring word roots.
    2. Group expressions by the problem they represent. Phrases with different vocabulary can belong together when the user needs the same answer. Similar-looking phrases may need to be separated when they lead to different decisions.
    3. Assign a decision stage. Use a small working vocabulary such as diagnosing, exploring, comparing, selecting, or purchasing. These are planning labels, not official Google categories.
    4. Define the product’s role. State exactly how the offer helps at that stage. If you cannot write this in one sentence, the group is probably too broad or the relationship is too weak.
    5. Choose the promise and destination. Decide what the ad can truthfully promise and which page can fulfill that promise without making the visitor translate it.
    6. Mark ambiguity explicitly. Do not force every query into one supposedly correct intent. Record the plausible alternatives and decide whether they require different messages, pages, or success criteria.

    A useful intent map looks like this:

    Search signal and contextUser’s immediate jobDecision stageOffer’s roleMessage directionBest destination type
    Why is my pool green?Identify the cause and a path to fix itDiagnosingProvide a relevant remedy after the problem is understoodExplain the likely path from diagnosis to treatmentTroubleshooting page with clear routes to relevant products
    Best CRM, with broad research behaviorLearn how to evaluate possible systemsComparingBecome a credible candidate in the shortlistHelp the user compare fit, workflows, and constraintsEvaluation or comparison page
    Best CRM, with clear vendor-selection behaviorChoose a provider and determine the next stepSelectingPresent the solution directlyShow product fit and the available next actionProduct, offer, pricing, or contact page, depending on what actually exists

    The two CRM rows are deliberately similar at the query level. The distinction comes from the decision being made. If both people receive the same generic ad and the same generic page, the account asks one experience to do incompatible jobs.

    For each row in your own map, write a one-sentence intent brief:

    • The user is trying to complete this immediate job.
    • They are currently at this decision stage.
    • Our offer helps by playing this specific role.
    • The appropriate next step is this action.

    If two keyword clusters produce the same brief, they may not need separate structures. If one cluster produces two materially different briefs, a single ad group may be hiding an important distinction.

    Turn the map into campaigns, ads, and landing pages

    An intent map becomes useful only when it changes what the searcher sees. Structure, creative, and destination should tell the same story. If one layer points to a different intent, performance data becomes difficult to interpret because you no longer know which promise the system is learning from.

    Split structures when the customer experience must change

    Do not create a campaign for every subtle variation. Split an intent when the distinction requires a different business decision or customer experience. A separate structure is more defensible when one or more of these elements changes:

    • The problem being solved.
    • The person’s decision stage.
    • The role of the product or service.
    • The promise the ad needs to make.
    • The landing page needed to fulfill that promise.
    • The conversion action or business value used to judge success.
    • The amount of budget exposure you are willing to accept while testing the hypothesis.

    Keep variations together when they are merely different ways of expressing the same job and can honestly use the same ad, page, and success definition. This prevents intent strategy from turning into a new form of over-segmentation.

    Match types can still help you manage boundaries. Use them in service of the intent plan: to protect a proven pattern, explore adjacent language, or limit an uncertain theme. Do not let a match-type label become a substitute for explaining why the traffic deserves the same treatment.

    Write the ad around the goal, not an echoed phrase

    Keyword repetition can make an ad look relevant while leaving the user’s actual question unanswered. Build the message from three layers:

    • Goal: Acknowledge what the person is trying to accomplish.
    • Role: Explain how the offer fits that job, using only claims the destination can support.
    • Next step: Offer an action appropriate to the decision stage.

    For a troubleshooting search, the ad might lead with understanding the cause and finding the relevant treatment path. For an early CRM comparison, it might help the user evaluate fit. For a selection-stage CRM search, it can move directly to product details and the available contact or purchase step.

    The distinction is small in wording but large in function. One message helps the searcher frame a decision. Another helps them complete it. Do not promise a comparison, diagnosis, price, demonstration, or outcome that the landing page does not actually provide.

    Make the landing page finish the same job

    A good ad-to-page transition should not require the visitor to reinterpret your offer. The first meaningful portion of the page should make four things clear:

    • They have reached a page for the problem or decision they had in mind.
    • The page provides the type of help promised in the ad.
    • The connection between that help and the offer is understandable.
    • The next action matches their current level of readiness.

    This is why every informational query should not be sent straight to a product page. When the user is still diagnosing the problem, a focused explanation with a clear route to the relevant solution may create a more coherent journey. Conversely, a person ready to evaluate a specific offer should not be forced through a broad educational page before they can find product details.

    Intent-based organization can affect eligibility, landing-page effectiveness, and system learning. Treat the landing page as part of targeting, not as a destination chosen after the campaign has already been designed.

    Measure whether you captured the right intent

    Colored pathways connect searcher intent symbols to campaign containers, ad cards, landing pages, and evaluation instruments, while one mismatched pathway is diverted.

    A search term that resembles your keyword is not proof that the campaign worked. The real test is whether the account reached a useful customer situation, made an appropriate promise, and produced an outcome worth paying for.

    Create an intent-level scorecard alongside your normal campaign reporting. For each intent, review:

    • Coverage: Which expressions and customer situations are being reached, and which intended situations remain absent?
    • Traffic response: Do the ad and offer earn attention from the people in that intent group?
    • Destination behavior: Do visitors take the next step that the page was designed to support?
    • Business outcome: Do leads, sales, qualified opportunities, or conversion value justify the spend?
    • Query drift: Are new search terms still versions of the intended job, or has the group expanded into unrelated needs?
    • Stage fit: Are you judging a diagnosing visitor by a purchasing action that the experience never prepared them to take?

    Do not turn every early-stage action into an equally valuable optimization goal. A page view, content interaction, qualified lead, and sale may each tell you something, but they do not represent the same business result. Keep the distinction visible so cheap activity does not masquerade as successful intent matching.

    Common performance patterns point to different fixes:

    • Relevant-looking traffic but weak business outcomes: Recheck the intent definition, conversion action, and search-term drift before changing bids. The campaign may be attracting a real audience for the wrong job.
    • Strong ad response but weak landing-page action: Compare the ad promise with the page’s first answer and next step. A stage mismatch often appears at this handoff.
    • Conversions from many different phrasings: Preserve the shared intent before fragmenting the group by vocabulary. The language varies, but the customer job may be stable.
    • Mixed quality from the same apparent query theme: Stop treating the words as a complete label. Revisit the possible decision states and test distinct messages or destinations where the difference is meaningful.
    • Traffic concentrated around only explicit product terms: Look for adjacent problem and comparison intents where the offer has a clear, defensible role. Expansion without that role is merely broader targeting.

    Because Google Ads spend has direct financial consequences, do not dismantle a profitable structure solely to make the account taxonomy look more modern. That can remove your baseline and expose more budget before the new intent hypothesis is proven.

    Use a bounded migration instead:

    1. Select one campaign or problem cluster with a clear customer job and interpretable conversion data.
    2. Record its current structure, search-term themes, spend, outcomes, and landing pages as your baseline.
    3. Write the new intent brief and identify exactly what is changing: grouping, message, destination, or some combination of them.
    4. Keep the underlying definition of business success stable while testing the new structure. If you change both the campaign logic and the conversion definition, you will not know which change produced the result.
    5. Protect proven coverage while the new approach is evaluated. Do not assume broader eligibility is automatically better.
    6. Judge the test on business quality and intent fit, not only on added traffic.
    7. Expand the model to adjacent clusters only after the original intent remains coherent from query through outcome.

    This approach gives you a way to learn without turning an account-wide rebuild into a single irreversible bet.

    Key takeaways

    • Treat keywords as evidence and controls, not as complete descriptions of the customer.
    • Define each important intent through the user’s problem, decision stage, product role, and appropriate next step.
    • Group different phrasings when they require the same message, page, and success measure.
    • Separate similar-looking searches when they represent materially different decisions.
    • Write ads around the goal behind the query, then send the visitor to a page that completes the same job.
    • Evaluate intent groups by downstream business quality, not by query resemblance or traffic volume alone.
    • Migrate a bounded part of the account first, preserve your baseline, and expand only when the new structure proves useful.

    For your next account review, choose one campaign and try to describe its audience without mentioning a keyword or match type. If you cannot state the problem, decision stage, product role, and next step clearly, that is where the intent-driven rebuild should begin.

    References

  • How to Target Google Ads and See Where PMax Performs

    How to Target Google Ads and See Where PMax Performs

    Your Search campaigns can be well built and still leave growth on the table. Keywords meet people after they express intent; they do not automatically reach every suitable buyer who has not started searching. If you answer that gap by handing more work to Performance Max, you inherit a second problem: knowing which Google channel produced the result.

    You can solve both problems without pretending automation is transparent. Define targeting as a two-part decision – where relevant intent appears and who qualifies – then use Google Ads API v23 channel reporting to inspect how Performance Max distributed and converted traffic. That gives you a practical operating loop: targeting hypothesis, channel evidence, focused correction, and cost-per-acquisition review.

    Separate where an ad can appear from who should see it

    A targeting plan becomes much easier to audit when you stop treating every setting as interchangeable. Google Ads targeting falls into two functional groups: content targeting and audience targeting.

    DecisionContent targetingAudience targeting
    Question it answersIn what query or content environment can the ad appear?What kind of person should be eligible to see the ad?
    Main optionsKeywords, topics and placementsGoogle data, your data, custom segments and automated targeting
    Best useCapturing a relevant moment or contextImproving the fit between the person, message and offer
    Common mistakeAssuming a relevant query always identifies the right buyerAssuming a plausible audience is ready for the same offer at the same time

    Keyword targeting reaches people through searches and also extends into dynamic ad groups and Performance Max. Topic targeting places ads alongside content about a selected subject in display and video campaigns. Placement targeting lets you choose particular websites, apps, YouTube channels or videos.

    Audience targeting works on a different axis. Google’s prebuilt options include detailed demographics, affinity segments, in-market segments and life events. Your own data can include website visitors, app users, people who engaged with your Google content and eligible Customer Match data. Custom segments can be based on relevant searches, interests, websites or apps. Automated options can expand from the signals and data you provide, although their names and exact behavior vary by campaign type.

    The distinction matters because a keyword can reveal intent without identifying the buyer. Someone searching for vacation packages could be planning a family trip, honeymoon or retirement holiday. The query is the same, but the useful message, proof and offer can be completely different. Treat the keyword as evidence of a moment, not as a complete persona.

    Build the targeting stack before automation expands it

    An isometric targeting system shows layers for intent, context, audience qualification, and controlled automated expansion.

    Before changing campaign settings, write down the answers to two separate questions: How can Google Ads promote this offer, and how can Google Ads reach this particular audience? If you can answer only the first, you have a distribution plan without an audience strategy. If you can answer only the second, you have a persona without a reliable way to reach it.

    1. Define the action that creates business value. Name the conversion you actually want, the offer attached to it and the page where it happens. This prevents cheap but irrelevant traffic from becoming the campaign’s de facto objective.
    2. Describe audience fit independently of search behavior. State who has the problem, what makes the offer relevant and what language that person would immediately recognize. Do this before selecting a Google segment.
    3. Choose the content signals that reveal a useful moment. Use keywords for expressed search intent, topics for subject context and placements when you know the specific sites, apps, channels or videos where the audience spends attention.
    4. Add the audience data you can legitimately use. Consider Google’s segments, eligible first-party data and custom segments. Treat automated expansion as another layer of reach, not as a substitute for defining the audience yourself.
    5. Make the creative perform a targeting job. Use the buyer’s vocabulary, problem, context and expected outcome. A broad audience paired with precise creative can filter attention more effectively than generic creative placed in a narrowly named segment.
    6. Set the success hierarchy before launch. Put conversions and cost per acquisition ahead of click volume and cost per click. Otherwise, an apparent traffic improvement can move the campaign away from qualified demand.

    For example, lead-generation software intended for Google Ads professionals could use custom segments informed by searches for terms such as Performance Max, visits to relevant industry sites or use of the Google Ads app. Content targeting could add placements on industry education channels and topics around search marketing. The creative should then speak in the terminology of campaign management rather than generic business-software language.

    This is a coordinated stack, not necessarily an instruction to combine every setting as a restrictive intersection. Campaign types interpret signals differently. Your planning document should show what each input contributes: context, identity, prior relationship, expansion or creative qualification.

    When remarketing or custom segments are restricted

    Some sensitive-interest campaigns, including certain legal or healthcare advertising, may not be eligible for custom segments or remarketing. When those options are unavailable, do not treat the restriction as a technical obstacle to work around. Start with an eligible Google data audience that has plausible overlap, then let the creative filter for relevance.

    Industry terminology, recognizable acronyms and specialist visuals can make the intended audience pay attention while other people move on. That approach is especially useful when you can target a broad eligible group but cannot encode the sensitive trait directly. Confirm which options are available in the account and campaign you are actually running before finalizing the plan.

    Use API v23 to turn PMax delivery into channel evidence

    An analyst observes one automated advertising stream separated into visible paths for search, video, shopping, web, and map channels.

    Older Google Ads API versions returned MIXED for the Performance Max ad_network_type segment. API v23 can instead break results out across Search, YouTube, Display, Discover, Gmail, Maps and Search Partners. That changes Performance Max reporting from a single blended row into a view of where delivery occurred.

    The visibility is available at three useful levels:

    • Campaign level: See the overall channel mix and identify which channels deserve a closer look.
    • Asset group level: Determine whether a channel pattern belongs to the whole campaign or is concentrated in one audience-and-creative grouping. This channel breakdown is available through the API, not the Google Ads interface.
    • Individual asset level: Connect channel delivery to particular creative assets instead of judging every asset against one blended campaign result.

    There are three implementation constraints you should record in the reporting specification. Channel-specific data is available only for dates beginning June 1, 2025. A blank result before that date means the breakdown is unavailable, not that the channel delivered nothing. Asset-group channel reporting must come from the API, so a UI-only review will not reproduce the same analysis. Any pipeline that expects the old MIXED value must also be updated to accept and store the distinct channel enums.

    Your export should retain the campaign, asset group and asset identifiers alongside the date, channel, cost, clicks, conversions and whichever business-value metric governs the account. Keep the v22 segments ad_using_video and ad_using_product_data in the analysis where relevant. They let you distinguish video-supported delivery from product-data-supported delivery rather than assuming that every result inside a channel used the same ad format.

    This is reporting visibility, not proof that each channel should receive a manual budget or that the channel caused the conversion by itself. Use the channel enum to locate a pattern. Then use the asset group, asset type, audience hypothesis and conversion outcome to explain what may be producing it.

    Turn channel visibility into a focused optimization decision

    A channel report is useful only when it changes the next decision. Start at campaign level, narrow the pattern to an asset group or asset, and then change the smallest controllable input that could explain it.

    1. Validate the conversion basis. Make sure the report is evaluating the action the campaign is meant to produce. A channel comparison built on the wrong conversion cannot guide useful optimization.
    2. Read conversion rate and cost per acquisition before CPC. High click costs can be acceptable when those clicks convert efficiently. Low click costs are not a win when they buy unqualified visits.
    3. Compare channels at campaign level. Look for meaningful differences in delivery, conversion rate and acquisition cost. Do not label the largest channel good or bad solely because it received the most traffic.
    4. Drill into asset groups. If the pattern appears across every asset group, investigate campaign-wide assumptions such as the offer, audience definition or landing experience. If it appears in one asset group, keep the correction confined to that group.
    5. Inspect the relevant assets and format flags. For YouTube delivery, use the video segment and asset results to inspect whether the video communicates the offer clearly. For Search delivery involving product data, separate that traffic from other Search behavior before deciding what needs to change.
    6. Correct the closest mismatch. If clicks arrive but conversions do not, examine the continuity between targeting, creative promise, offer and landing page. If one asset performs poorly only within one channel, revise that asset before rebuilding the entire campaign.
    7. Recheck a comparable reporting window. Keep the conversion definition and analysis scope consistent so the next result answers whether the focused change improved acquisition quality.

    The metric order has a large financial consequence. In an illustrative comparison, a $10 click with a 10% conversion rate implies a $100 cost per acquisition. A $1 click with a 0.02% conversion rate implies a $5,000 cost per acquisition. The cheaper click is fifty times more expensive at the outcome that matters. This is why low-quality traffic is a more serious problem than a high CPC.

    Channel visibility also limits the blast radius of your changes. If weak YouTube results are concentrated in one asset group and one video, you have a creative diagnosis, not yet a reason to rewrite the entire campaign. If inefficient traffic appears across channels and asset groups, the shared offer, conversion setup or audience premise deserves attention first.

    Key takeaways

    • Ask two targeting questions: where relevant intent appears and which people fit the offer.
    • Use keywords, topics and placements for context; use Google data, your data, custom segments and automation for audience reach.
    • Make creative specific enough to qualify attention, especially when sensitive-interest restrictions limit audience options.
    • Google Ads API v23 reports Performance Max delivery across Search, YouTube, Display, Discover, Gmail, Maps and Search Partners for dates beginning June 1, 2025.
    • Use the API for asset-group channel reporting; that breakdown is not available in the Google Ads interface.
    • Treat channel data as a diagnostic dimension and judge outcomes by conversion quality and cost per acquisition, not cheap clicks alone.

    Start with the Performance Max campaign carrying the most financial consequence. Write its targeting hypothesis in one sentence, then export v23 channel data at campaign, asset-group and asset level. If your reporting cannot preserve those levels, fix the reporting path before changing the campaign. Once the pattern is visible, correct the narrowest mismatch you can support with conversion evidence.

    References

  • Meta Andromeda and GEM: A Practical Ads Strategy for 2026

    Meta Andromeda and GEM: A Practical Ads Strategy for 2026

    If your old Meta Ads playbook depended on narrow interest stacks, duplicated ad sets, and frequent bid or budget adjustments, Andromeda and GEM create an uncomfortable question: which controls still help, and which ones now obstruct the system?

    The practical answer is not to hand everything to automation. It is to move your effort upstream. Use targeting to define genuine eligibility, give Meta a stronger range of creative choices, consolidate avoidable fragmentation, and judge performance at planned checkpoints instead of reacting to every short-term movement.

    What Andromeda and GEM actually change

    A useful operating model begins by separating retrieval from recommendation. Andromeda, introduced in 2024, retrieves ads that may be relevant to a person by using past interactions and creative-level signals. GEM then applies broader predictive intelligence to ad selection and sequencing. In simple terms, Andromeda helps assemble the viable candidates; GEM helps determine which candidate should be delivered and what interaction may make sense next.

    That distinction matters because neither system can rescue weak inputs. Retrieval cannot surface a useful creative concept that does not exist in your account. Recommendation cannot optimize toward a business outcome that is poorly measured or represented by the wrong campaign objective.

    LayerOperational roleYour strongest leverCommon mistake
    AndromedaRetrieves potentially relevant ads for an individual opportunityDistinct creative concepts and enough eligible reachDividing the audience so narrowly that each campaign sees only a thin slice of demand
    GEMPredicts which ad and sequence may produce the desired responseClear objectives, dependable measurement, stable delivery, and coherent offersChanging campaigns so often that the system has to optimize around a moving setup
    Combined systemMatches available ads to people and outcomes across Meta’s ecosystemHigh-quality inputs, useful creative variety, and disciplined evaluationTreating automation as a substitute for positioning, economics, or conversion experience

    This is why broad targeting and creative-first planning often belong together. A broader eligible audience gives the system more opportunities to find response patterns. Distinct creative concepts give it meaningful choices within that audience. Broad groups have been able to outperform elaborate interest-based setups as Meta’s retrieval became more creative-centric, but that is a strategic direction, not a promise that every broad campaign will win.

    Creative-first also does not mean targeting has become irrelevant. Targeting should still enforce real constraints: where you can sell, who is legally eligible, which existing customers should be included or excluded, and which regions can receive the offer. What has weakened is the case for using speculative audience slices as the main way to express relevance. When the difference is a motivation, pain point, use case, or level of awareness, express it in the ad before creating another audience partition.

    Consolidate campaigns without erasing business controls

    Many tangled campaign pathways merge into a few organized channels while several distinct control gates remain separate.

    The goal of simplification is signal concentration, not the smallest possible account. Before merging anything, ask whether the campaigns can genuinely share an objective, conversion event, offer, geographic eligibility, and economic target. If they cannot, separation may still be necessary. If they can, duplicated structures may only be dividing delivery data and forcing Meta to relearn similar patterns in several places.

    Use this consolidation test on every campaign and ad-set boundary:

    • Keep the boundary when the business outcome differs. A lead campaign and a purchase campaign are not interchangeable merely because they advertise the same brand.
    • Keep it when eligibility differs. Regional availability, language-dependent destinations, legal restrictions, and customer exclusions can justify separate delivery rules.
    • Keep it when economics require independent control. Offers with materially different margins, sales capacity, or acceptable acquisition costs may need their own budgets.
    • Question it when the only difference is a guessed persona or interest. If both groups can buy the same offer under the same economics, let persona-specific creative carry more of the distinction.
    • Question it when the split exists only for reporting convenience. Naming conventions, asset labels, and downstream reporting can often provide visibility without creating another delivery silo.

    After consolidation, do not judge success by whether every creative or audience receives equal spend. The system is designed to allocate delivery unevenly when it predicts unequal opportunity. Your decision metric should remain the campaign’s business outcome. Asset-level delivery is diagnostic evidence, not a fairness requirement.

    Budget belongs in the same discussion. Larger, consistent budgets can accelerate learning by producing a steadier flow of data. That does not make a budget increase an automatic cure. More spend can simply purchase more weak traffic when the offer, measurement, or creative is wrong. Scale only when the resulting acquisition cost and conversion quality remain acceptable to the business.

    A more useful budget question is: can this campaign run long enough to reach a planned decision point without a rescue edit? If the answer is no, reduce structural fragmentation, narrow the number of simultaneous tests, or revise the expected volume. A budget that forces constant intervention is not giving either system a stable problem to solve.

    Build creative coverage, not a pile of cosmetic variants

    Six distinct advertising concepts surround a central product pedestal, including demonstration, lifestyle, close-up, creator-style, problem-focused, and promotional scenes.

    Andromeda can retrieve only from the ads you supply. If every asset makes the same promise to the same implied buyer in nearly the same format, a large creative count can still represent very little strategic variety. Changing a background color, trimming a caption, or moving the logo produces a variant. Changing the buyer problem, promise, proof, objection, or presentation creates a new concept.

    Plan the creative library as a coverage map. For each concept, record:

    • Buyer context: the situation that makes the offer relevant, such as an urgent problem, a recurring task, or a planned upgrade.
    • Primary promise: the outcome the ad asks the buyer to value.
    • Reason to believe: the demonstration, mechanism, evidence, or explanation supporting that promise.
    • Objection addressed: the concern that could prevent action, such as effort, fit, complexity, or switching cost.
    • Format: the way the idea is experienced, including a demonstration, direct explanation, customer perspective, static visual, or short-form video.
    • Destination: the page or conversion path that continues the same message after the click.

    This map exposes false diversity quickly. If several ads have different thumbnails but identical entries in every other field, you have executional variation rather than broad conceptual coverage. That can still be useful for refining a proven idea, but it should not be mistaken for a portfolio capable of matching several motivations.

    A hypothetical analytics product illustrates the difference. One concept could focus on the reporting backlog and demonstrate an automated workflow. Another could focus on uncertainty in decision-making and show how an executive sees the underlying evidence. A third could address implementation anxiety with a clear explanation of the setup. The product is unchanged, but the reason to care, the proof, and the implied buyer situation are genuinely different.

    Meta’s AI-driven setup benefits from creative tailored to different personas and delivered through varied media formats. Treat that as a portfolio requirement, not permission to publish ungoverned volume. Every concept still needs an accurate claim, recognizable brand voice, and a landing experience that fulfills the promise.

    GEM’s role in sequencing also changes how you should think about a winner. The account does not necessarily need one universal ad that performs every communication job. It needs useful material for different interaction contexts: introducing the problem, explaining the solution, supplying proof, handling an objection, and stating the offer. You cannot dictate the exact sequence for every person, but you can make sure the available library contains coherent next steps.

    Use labels that preserve this strategic information. A useful asset name identifies the concept, promise, proof type, format, and version. That lets you see whether Meta is finding repeatable demand for a message or merely concentrating delivery on one execution. Without concept-level labels, creative analysis collapses into filenames and superficial format comparisons.

    Test with stable inputs and diagnose the right layer

    Stability does not mean leaving a campaign untouched indefinitely. It means deciding in advance what evidence will justify a change. Short-lived performance peaks and daily fluctuations are weak foundations for structural decisions. Longer engagement patterns, continuous creative renewal, and fewer hasty modifications fit the way Andromeda and GEM learn.

    Run a deliberate operating loop:

    1. Define the question. State whether you are testing a new buyer problem, promise, proof type, format, offer, or destination. Do not call an undefined batch of new ads a test.
    2. Set the decision rule before launch. Name the primary business outcome, any quality or profitability guardrail, and a review point that accounts for your normal conversion delay and data volume.
    3. Hold avoidable inputs stable. Keep the objective, measurement, offer, and destination consistent when the purpose is to compare creative concepts.
    4. Intervene only for a clear exception. A broken destination, rejected asset, invalid tracking setup, material pacing risk, or incorrect offer deserves immediate action. Ordinary movement does not.
    5. Review campaign outcomes and creative patterns separately. Decide whether the campaign is economically viable first. Then use asset patterns to brief the next round of concepts.
    6. Document the decision. Record what changed and why, so a later performance shift is not misattributed to the newest creative when budget, tracking, or structure changed at the same time.

    If you need causal certainty, use a controlled experiment that isolates the variable. Normal AI-optimized delivery is not an even creative rotation, so comparing two ads that received different audiences, spend, and timing does not produce a clean causal answer. Routine campaign reporting can identify promising patterns; it cannot automatically explain why they occurred.

    When results disappoint, diagnose the layer before rebuilding the account:

    • The campaign cannot spend: check eligibility, approvals, budget, bid or cost controls, audience restrictions, and delivery settings before blaming creative matching.
    • Ads receive delivery but little meaningful response: examine the hook, buyer problem, format, and clarity of the promise. More audience slicing will not repair an irrelevant message.
    • People engage but do not complete the next step: check whether the destination continues the ad’s promise, whether the offer is clear, and whether the conversion path adds avoidable friction.
    • Reported conversions change after measurement edits: separate the tracking change from the media conclusion. A reporting shift is not automatically a change in buyer behavior.
    • One concept absorbs most delivery: do not force equal allocation solely to make the report look balanced. Examine what buyer problem or proof it represents, then develop materially distinct ways to serve the same underlying demand.
    • Performance weakens after a previously productive run: refresh the concept portfolio and inspect the offer and destination. Recreating old audience complexity is unlikely to solve creative exhaustion.

    This diagnostic order protects you from a common failure mode: using targeting changes to solve a message problem, using new creative to solve a broken conversion path, or using more budget to solve weak economics. Andromeda and GEM can optimize delivery choices. They cannot decide which business problem you actually have.

    Key takeaways

    • Andromeda retrieves potentially relevant ads; GEM adds predictive selection and sequencing across broader interaction data.
    • Use targeting for genuine eligibility and control. Express motivations, use cases, and objections through creative before building another speculative audience slice.
    • Consolidate campaigns that share the same outcome, measurement, eligibility, offer, and economics, but retain boundaries that protect real business constraints.
    • Build distinct creative concepts around different problems, promises, proof, objections, and formats. Cosmetic variations are not strategic diversity.
    • Keep budgets and campaign inputs stable until a planned review point unless an operational problem requires immediate intervention.
    • Judge automation by profitable business outcomes, then use delivery patterns as evidence for the next creative brief.

    Start with one account audit. Mark every campaign boundary that exists only because of an assumed audience distinction, label each live ad by its actual concept, and choose the next review point based on your conversion delay. Those three actions will show whether you are giving Andromeda and GEM a clear optimization problem or a maze of competing instructions.

    References

  • Paid Search Readiness: Fix the Account or Build Demand?

    Paid Search Readiness: Fix the Account or Build Demand?

    Your paid search campaigns can look efficient and still refuse to grow. That does not automatically mean bids are too low or automation is too timid. You may have a readiness problem inside the account, or you may have reached the amount of demand currently available to capture.

    Those constraints need different fixes. Better tracking, bidding and landing-page controls can repair an account that is not ready to scale. Demand generation is the answer when a healthy account has already captured most of its worthwhile opportunity. Diagnose that distinction before you increase budgets or enable Google AI Max.

    Diagnose the constraint before you pay to expand it

    A strategist inspects a transparent campaign pipeline where one misaligned module restricts the flow of audience signals.

    Paid search converts expressed intent. It can reach someone who searches for a problem, product, category or brand, but additional budget cannot manufacture an unlimited supply of eligible searches. At the same time, an underspending campaign is not automatically demand-constrained. Weak measurement, low rank, restrictive targeting, poor relevance or an unsuitable offer can produce the same symptom.

    Read the account in a fixed order: measurement first, existing auction opportunity second, relevance and rank third, and market demand last. If you reverse that order, you can mistake a repairable campaign problem for a small market.

    What you seeLikely constraintWhat to do next
    Primary conversions are duplicated, inflated or disconnected from qualified outcomesMeasurement readinessRepair the conversion signal before changing bids, budgets or targeting
    Profitable, high-intent campaigns lose impression share because of budgetCapture budgetProtect and fund proven demand before paying for expansion
    Campaigns have room in their budgets, but rank, relevance or landing-page performance is weakCampaign executionImprove the ads, structure, offer and landing path before broadening reach
    Broadening queries adds traffic but degrades lead quality or unit economicsRelevance or market fitFind where intent breaks instead of treating more reach as progress
    Tracking is trusted, proven demand is funded, relevance is healthy and eligible traffic remains limitedDemand ceilingCreate demand outside paid search and build a deliberate route back into capture campaigns

    Budget loss deserves particular attention. If your best keywords are already missing impressions because their campaigns are capped, an expansion layer can compete with the demand you already know how to convert. The safer sequence is to fund proven keywords before giving AI Max room to experiment.

    Do not use account-wide averages for this diagnosis. Brand, non-brand, competitor, Shopping and remarketing activity can have different constraints. A strong branded campaign can hide weak generic acquisition, while a broad campaign can consume budget without proving that it created incremental demand. Classify campaigns separately, then decide where money should move.

    Pass the AI Max readiness gate

    AI Max is an expansion mechanism, not an account repair tool. It uses signals beyond conventional keyword targeting to decide when an ad may be relevant. That gives the system more freedom, which means weaknesses in your conversion data, bidding or page controls can spread farther and consume budget faster.

    Make the conversion signal worth optimizing

    Accurate conversion tracking is the first gate because automated bidding treats your selected outcomes as its definition of success. If a low-quality form submission, duplicated purchase or easy micro-conversion is marked as primary, the system can optimize efficiently toward the wrong result.

    • List every primary conversion action and identify the business outcome it represents.
    • Check whether one customer action can trigger more than one primary conversion.
    • Separate diagnostic events, such as page views or button clicks, from outcomes you are willing to buy.
    • For lead generation, compare platform conversions with qualified leads or later pipeline stages rather than form volume alone.
    • For value-based bidding, confirm that the values distinguish more valuable outcomes instead of assigning arbitrary numbers to every action.
    • Resolve unexplained jumps, missing imports and tracking changes before using the affected period as a baseline.

    This is also where demand-generation measurement and search optimization must stay separate. Reach, video engagement and content consumption can help you understand whether a message is landing, but they should not become primary paid-search conversions unless they are genuinely the outcomes you want bidding to purchase.

    Align automated bidding with the economic goal

    A sensible AI Max test needs a conversion-focused automated bid strategy. Target CPA can fit a campaign where conversions have broadly similar value and you know an acceptable acquisition cost. Maximize Conversion Value fits only when the submitted values are trustworthy enough to guide trade-offs. The strategy name matters less than whether its objective matches the result your business actually values.

    Where you already know viable unit economics, a target can give the system a clearer boundary than an unconstrained maximize strategy. Do not change the bid strategy, conversion definition and targeting expansion at the same moment. If performance moves, you will not know which change caused it.

    Check data volume, broad match history and budget pressure

    A practical screening heuristic is to start with a campaign producing at least 30 conversions per month, with greater confidence around 100 or more. These are test-selection heuristics, not guaranteed performance thresholds or formal Google minimums. If your campaign sits below the lower figure, consolidation or a conventional campaign improvement is usually a more informative next move than giving automation a larger search space.

    Past broad match performance is another readiness signal because AI Max effectively broadens the system beyond exact keyword control. A campaign that has already converted relevant broad-match traffic at acceptable economics gives you evidence that the account can tolerate looser matching. If broad match has failed, determine whether query relevance, ad-group structure, creative, landing pages or conversion quality caused the failure before adding another expansion layer.

    Your first test candidate should therefore meet five conditions: trusted primary conversions, conversion-focused bidding, enough recent conversion volume to evaluate, positive broad match history, and no meaningful budget loss on the proven demand you need to protect.

    Control landing pages and generated assets before launch

    URL expansion lets Google select a page it considers relevant when AI Max triggers an ad. That can improve message-to-page matching on a well-organized commercial site. It can also send paid traffic to policy pages, thin informational content, outdated offers or the wrong geographic page.

    Build exclusions before you enable the feature. Remove pages that cannot complete the intended conversion, locations the campaign does not serve, obsolete products, internal search results and any page whose claims or offer conflict with the ad. If you rely on dedicated local landing pages, confirm that expansion cannot replace them with a page for another market.

    Apply the same discipline to automatically created assets. Generated messaging can broaden coverage, but irrelevant sitelinks or incompatible callouts can weaken an otherwise suitable ad. Review the source pages the system can draw from, remove obsolete copy, and define brand or compliance boundaries before the test begins.

    One distinction prevents a common strategic error: AI Max is not required for ads to appear in AI Overviews. Broad match keywords can already make an ad eligible there. Enable AI Max because you have a controlled case for incremental conversions, not because you assume it is an admission ticket to AI-generated search experiences.

    Build demand and capture as one connected system

    Audience figures, media touchpoints, a search mechanism, and conversion tokens are connected by a continuous loop of glowing signals.

    Once measurement is reliable, valuable auction opportunity is funded and campaign execution is healthy, the remaining ceiling may sit above paid search. Search and Shopping eventually stop scaling when they are expected only to capture demand and too little activity is creating new interest for them to capture.

    Demand generation is not simply buying broad reach. Its job is to make more suitable buyers recognize a problem, understand a category or remember a brand, then give that changed intent somewhere useful to go. If the demand message and the search experience are planned by different teams, the handoff often breaks between those two moments.

    1. Define the demand message in one sentence: the problem the buyer should notice, the outcome worth pursuing and the category or solution that makes the outcome possible.
    2. Map the searches that message could reasonably produce. Separate brand terms, category terms, problem-led terms and product terms rather than assuming every exposed person will search for your brand.
    3. Create a capture route for each valuable intent. The route should include an eligible campaign, relevant ad or product presentation, and a landing page that continues the same promise.
    4. Keep the language continuous. If demand creative teaches one category concept but paid search and the landing page use unrelated terminology, the buyer has to translate your message for you.
    5. Feed search-term language back into demand creative. Queries reveal how people describe the problem after interest forms, which can expose gaps between your internal vocabulary and the buyer’s words.
    6. Report brand and non-brand search separately. A blended total can make demand creation look efficient simply because existing branded demand converts cheaply.

    Measure the handoff without giving one channel all the credit

    Measure delivery, demand signals and commercial outcomes as different layers. Delivery tells you whether the intended audience had a chance to receive the message. Directional demand signals can include changes in branded searches, direct visits, returning visitors or relevant category searches. Commercial outcomes include qualified leads, purchases, revenue or another verified business result.

    A rise in branded search after a demand campaign is useful evidence, but timing alone does not prove causation. Seasonality, publicity, competitor activity and other media can move the same signal. Use a credible control or holdout where your scale permits it, and keep the claim directional where it does not.

    Attribution settings can also obscure the handoff. A search click near the end of a journey may receive credit for a conversion even when another channel created the interest. That does not make search unimportant; it means capture efficiency and demand creation answer different questions. Judge paid search on whether it captured intent economically, and judge demand activity on whether it increased the supply or quality of that intent.

    Test AI Max as an expansion layer, not a rescue plan

    Start with a non-brand campaign. Brand traffic can make expansion look more efficient than it is, and AI Max performance around brand queries has been inconsistent. Choose one proven, conversion-rich ad group instead of switching on account-wide automation. Ad-group-level activation through Google Ads Editor makes that controlled starting scope practical.

    1. Write the hypothesis. State what incremental opportunity you expect AI Max to find and which conversion outcome must improve.
    2. Record the baseline. Capture conversion volume, conversion value, CPA or return, query mix, landing-page mix and downstream lead quality for the selected ad group.
    3. Choose the candidate. Use a non-brand ad group with successful broad match behavior, sufficient conversion volume and no unresolved tracking issue.
    4. Set the boundaries. Finalize URL exclusions, geographic controls, brand restrictions, negative concepts and asset-review rules before launch.
    5. Hold unrelated changes. Avoid simultaneous restructuring, conversion-action changes or major landing-page rewrites unless a safety, compliance or budget issue requires intervention.
    6. Monitor what expanded. Look beyond the topline result to the queries, pages, locations and assets receiving the additional spend.
    7. Judge incrementality and quality. More platform-reported conversions are not enough if they replace branded conversions, lower lead quality or move spend away from better existing demand.

    Define stop conditions before the test starts. Pause or narrow the rollout if it sends traffic to incompatible pages, shifts substantial budget away from proven demand, produces irrelevant query themes, or increases nominal conversions while qualified outcomes deteriorate. Predefined conditions stop the team from rationalizing weak traffic after money has already been spent.

    A successful result is not simply that AI Max spent more. It is that the selected ad group found additional, relevant conversions or conversion value within the economics you set, without hiding losses in brand mix, lead quality or landing-page selection. If it passes, expand one controlled unit at a time. If it fails, the query and page data should tell you whether to repair relevance, tighten controls or return budget to demand creation.

    Key takeaways

    • Paid search readiness starts with trusted conversion tracking, aligned automated bidding, sufficient data and funded high-intent demand.
    • An underspending campaign does not prove that demand is exhausted; measurement, rank, relevance and targeting must be ruled out first.
    • For an initial AI Max test, 30 monthly conversions is a practical screening heuristic, while 100 or more provides a stronger data base; neither is a guaranteed Google threshold.
    • Positive broad match history is an important readiness signal because AI Max expands beyond tight keyword control.
    • AI Max is not required for ad eligibility in AI Overviews; test it for incremental conversion opportunity, not access.
    • When a healthy search account reaches its capture ceiling, connect demand messages to likely queries, eligible campaigns and matching landing pages.

    Open your last stable reporting window and classify each campaign as measurement-constrained, budget-constrained, execution-constrained or demand-constrained. Fix the first three before expanding automation. If the remaining limit is demand, build the message-to-query-to-landing-page handoff and let paid search capture the intent it creates. Only then give AI Max a small, controlled opportunity to prove that it can add something genuinely incremental.

    References

  • The Medtech Marketing Agency Landscape: A 2026 Guide

    The Medtech Marketing Agency Landscape: A 2026 Guide

    You can waste a substantial budget on a capable medtech marketing agency if it solves the wrong problem. A trade show specialist, brand studio, account-based marketing team, enterprise media firm, and organic authority partner can all make persuasive pitches, but they are built for different jobs.

    Your first decision is therefore not which agency is best. It is which commercial constraint must change next. Once you name that constraint, the medtech agency landscape becomes much easier to navigate.

    Choose the bottleneck before you choose the agency

    Write a one-sentence diagnosis before you schedule discovery calls: “Our immediate constraint is [problem], among [audience], at [stage of the buying journey], and progress means [business outcome].” If your team cannot complete that sentence, an agency will fill the gap with the services it already sells.

    Route your search according to the job that needs to be done:

    • You need sustained discovery and qualified inbound demand. Look for thought leadership, technical content, SEO, and generative engine optimization. The agency should be able to connect visibility with a defined conversion path, not merely publish content.
    • You need paid reach at enterprise scale. Look for media buying, audience data, analytics, creative production, landing-page support, and a clear handoff into your CRM and sales process.
    • Your product is difficult to explain or your company is preparing to raise capital. Start with positioning, message architecture, visual identity, and materials that can be used consistently in customer and investor conversations.
    • A conference or trade show is the immediate commercial event. A booth specialist can solve the physical experience, but your scope also needs lead capture, meeting preparation, and post-event follow-up.
    • Your market consists of a finite group of valuable organizations. Account-based marketing is the natural lane. The agency must show how marketing and sales will coordinate around named accounts and multiple stakeholders.
    • You need a coordinated device launch or brand program across several channels. An integrated medtech agency may reduce handoff friction, provided it has genuine depth in the channels that matter to you.

    Do not treat “full service” as automatically better. Breadth helps when your problem crosses channels. It creates unnecessary cost and management overhead when you only need a specialist intervention.

    Seven agencies occupy distinct positions in the 2026 landscape

    Seven different agency work areas surround a central diagnostic device, with each area represented by tools for a distinct marketing specialty.

    The profiles below reflect a market snapshot updated January 26, 2026. Use them as routing information for a shortlist, not as a substitute for current due diligence. Company size, staffing, client relationships, and service emphasis can change.

    AgencyPrimary laneReported organizational contextWhat you should verify
    First Page SageThought leadership combined with SEO and GEO for lead generationFounder-led; founded in 2009; reported size of 100-250; named work includes Biovia and AltoidaAsk how search visibility, visibility in generative answers, and content engagement connect to qualified lead definitions. Expect a detailed onboarding process and confirm what your subject-matter experts must contribute.
    EpsilonEnterprise, full-service marketing with a concentration in paid advertising and data analyticsNot founder-led; founded in 1969; reported size of 1,000+; named work includes Visionworks and WalgreensClarify the dedicated delivery team, minimum viable scope, data requirements, and total operating cost. Enterprise capacity has little value if your account receives a generic team or more infrastructure than it needs.
    Parker WhiteBrand development and creative marketing for medical and lifestyle brands, including B2C and B2B workFounder-led; founded in 1997; reported size of 11-50; named work includes Orthofix and FUJIFILM SonositeIf pipeline is the goal, ask who owns distribution, conversion, and measurement after the brand work is finished. A strong identity is not automatically a demand-generation system.
    Distill HealthBrand strategy and visual identity for medtech companies preparing for fundingFounder-led; founded in 2018; reported size of 1-10; named work includes Theragen and NuvaraConfirm capacity, access to senior staff, the customer or investor validation process, and who executes the brand after fundraising preparation. No marketing agency can promise that branding will secure funding.
    ExponentsTrade show booth design, manufacturing, and installationNot founder-led; founded in 1985; reported size of 11-50; named work includes HealthGridDefine the boundary between booth delivery and campaign delivery. Assign responsibility for pre-event outreach, appointments, lead qualification, data capture, and follow-up to Exponents, another partner, or your internal team.
    The ABM AgencyOmnichannel account-based marketing for high-value organizational buyersFounder-led; founded in 2007; reported size of 11-50; named work includes MedPost and Care SpotAsk how accounts are selected, how buying-committee roles are mapped, what sales must do, and how engaged accounts become opportunities. Also clarify cost before assuming ABM is efficient for your market.
    IcovyIntegrated branding, multimedia, and traditional marketing for medical device companiesFounder-led; founded in 2019; reported size of 11-50; named work includes Poba Medical and Kaneka MedicalIdentify the named specialist for every channel in your scope. Determine what is delivered in-house, what is subcontracted, and who owns integration, reporting, and corrective decisions.

    These firms are not interchangeable entries in a league table. Epsilon’s enterprise scale does not make it the natural choice for a startup that needs investor-ready positioning. Distill Health’s funding-oriented brand work does not make it the default choice for a mature manufacturer seeking paid media at scale. Exponents may be highly relevant to a conference deadline while remaining intentionally narrow outside the trade show itself.

    Founder involvement, company age, and headcount are context rather than outcomes. A founder-led specialist may offer direct senior attention, but you still need to know who will perform the weekly work. A large firm may provide broader capabilities and resilience, but you still need a dedicated team with relevant experience.

    Turn agency credentials into evidence of fit

    Two people evaluate unbranded project samples, process materials, and a medical device prototype on a conference table.

    For initial market screening, notable clients carry 35% of the evaluation, founder status and leadership experience 20%, company age and employee tenure 15%, marketing approach 15%, reviews 10%, and media references 5%. Those inputs are useful, but your buying decision should test what each signal actually means for your assignment.

    • Client names establish adjacency, not success. Ask what the agency delivered, which audience it addressed, how long the work ran, and what changed. A recognizable logo can represent a small project that bears little resemblance to your scope.
    • Relevant similarity is multidimensional. Product category alone is not enough. Compare the buyer, sales motion, company stage, geographic scope, channel, and internal review process. A consumer campaign and a hospital-enterprise sale can require very different work even when both sit under the medtech label.
    • Leadership experience matters only if it reaches delivery. Ask who joins the pitch, who designs the strategy, who manages the account, and who creates the work. Get those roles into the scope. Do not assume the founder or senior strategist in discovery will remain involved.
    • Tenure is a continuity clue. Within this group, reported median employee tenure ranges from 1.7 years at The ABM Agency to 4.6 years at Epsilon. That does not prove quality, but it gives you a reason to ask about turnover, backup coverage, and knowledge transfer.
    • Reviews require context. Look for comments about the type of work you are buying, responsiveness when a campaign underperforms, and the quality of project oversight. A high average without detail cannot tell you whether the agency can solve your problem.
    • Media references indicate visibility, not operational competence. They can support an authority assessment, but they do not replace current work samples, named team members, a delivery plan, or access to reporting.

    Ask every shortlisted agency to walk through a documented engagement that resembles your situation. Have it explain the starting constraint, its exact scope, the client responsibilities, the approval path, the deliverables, and the business result. If the answer skips from a client logo directly to an outcome, the missing middle is where delivery risk usually sits.

    Medtech work also needs an explicit claims-review workflow. Your internal medical, legal, regulatory, or quality reviewers may own approval, but the agency must know when review occurs, how revisions are tracked, and which version is cleared for each channel. If this process remains vague, timelines and budgets can deteriorate after production begins.

    Write a scope that matches the agency lane

    A useful brief does more than list services. Use this structure: “Help [audience] move from [current state] to [conversion or commercial outcome] by producing [deliverables], distributing them through [channels], and reporting [business and diagnostic measures].” Add your approval roles, required systems, ownership terms, dependencies, and exclusions.

    For SEO, thought leadership, and GEO

    Name the technical themes, buyer questions, priority audiences, conversion events, subject-matter experts, and owned properties in scope. Require the agency to distinguish traditional search performance from observed brand inclusion or citation in generative answers. Both can contribute to discovery, but they are not the same measurement.

    Qualified organic inquiries, target-account visits, completed demo or consultation requests, coverage of problem-led searches, and observed AI-answer visibility are more useful together than traffic alone. Traffic remains a diagnostic measure. It is not proof that the right buyer understood the product or entered a sales conversation.

    For paid media and integrated campaigns

    Specify the audience data, media channels, creative formats, landing pages, tracking, CRM handoff, and approval workflow. Decide who owns media accounts, analytics access, campaign data, source files, and website changes. Your organization should retain administrative access to the systems and assets it is paying to build; losing access can make a future agency transition expensive and slow.

    Make qualified opportunities and pipeline the commercial measures when your sales cycle supports them. Use accepted leads, qualified conversations, landing-page conversion, and acquisition cost as operating indicators. Click-through rate and impressions can diagnose a campaign, but they should not become substitutes for business progress.

    For account-based marketing

    Define how target accounts enter the program, which stakeholder roles matter, what sales will do, which messages vary by role, and how engagement is recorded. ABM fails quietly when marketing runs account-targeted ads while sales follows an unrelated list and neither side owns the handoff.

    Track meaningful engagement across the buying group, meetings with relevant roles, account progression, opportunities, and pipeline. Raw account impressions are not enough. Your agency should also explain what evidence causes it to intensify, change, or stop work on an account.

    For branding, fundraising preparation, and trade shows

    A brand scope should name the positioning decision, message architecture, visual system, required customer or investor materials, validation method, and internal approvers. Define how the system will reach the website, sales materials, presentations, and campaigns. Otherwise, you can finish with an attractive identity that the commercial team cannot apply consistently.

    A trade show scope should connect the physical booth with pre-event outreach, meeting booking, on-site data capture, lead qualification, CRM entry, and follow-up. If the booth provider does not offer those services, assign them elsewhere before the event. Booth traffic is an incomplete result; qualified conversations and subsequent opportunities are the commercial test.

    In every lane, separate agency deliverables from client dependencies. Technical interviews, product access, approved claims, customer references, CRM configuration, and executive sign-off can all sit with your team. Put each dependency beside an owner and approval path so neither side can hide a preventable delay inside a status report.

    Key takeaways: use the pitch to expose delivery risk

    • State the bottleneck first: What precise commercial constraint will this engagement change, and which business outcome will show that it changed?
    • Interrogate the closest example: Which past engagement most closely matches your buyer, product stage, sales motion, and channel? What did the agency itself deliver?
    • Name the working team: Who owns strategy, account management, content or creative production, media, analytics, and claims coordination after the pitch?
    • Expose outside dependencies: Which services are subcontracted, which require another partner, and which depend on your internal experts or systems?
    • Map the approval process: When do technical and claims reviews happen, who resolves conflicting feedback, and how are approved versions controlled?
    • Protect ownership: Who owns the ad accounts, analytics properties, audience data, CRM records, domains, website access, source files, and finished assets?
    • Demand decision-grade reporting: Which measures represent commercial outcomes, which are leading indicators, and which merely diagnose activity?
    • Set correction rules: What evidence will cause the agency to change the message, channel, audience, budget allocation, or scope?

    Send the same written brief to every agency on your shortlist and insist that each response addresses the same outcome, responsibilities, evidence, and ownership terms. That makes proposals comparable and prevents a polished pitch from redefining your problem around an agency’s preferred services.

    Choose the partner whose lane matches your immediate constraint, whose relevant work survives detailed questioning, and whose named team can explain how delivery becomes a measurable business result. That is a stronger basis for a decision than rank, reputation, or breadth alone.

    References

  • Google Demand Gen Commerce Updates: A Practical Playbook

    Google Demand Gen Commerce Updates: A Practical Playbook

    You may be looking at Demand Gen because paid social is getting harder to scale, or because YouTube creates attention that your conversion reports struggle to explain. Google’s commerce updates give you three new levers, but each solves a different problem.

    The practical question isn’t whether to adopt every new feature. It is whether shoppable connected TV, dynamic travel offers, or branded-search attribution closes a specific gap in your customer journey. Start there, and you can test the updates without turning a product announcement into an open-ended budget request.

    What changed, and what each update actually does

    The three additions sit under the same Demand Gen umbrella, but they are not interchangeable:

    The first two features change what a prospective customer can see or do. The third adds an attribution signal. That distinction matters: a new measurement report does not improve the buying experience, and a shoppable ad does not by itself prove that the resulting sales were incremental.

    Match the feature to the constraint in your funnel

    Three connected scenes show television shopping, adaptive travel offers, and a search-to-purchase path overcoming different journey obstacles.

    Use shoppable CTV when the missing link is product action

    Shoppable CTV is most relevant when viewers understand your product from video but have no natural next step from the television screen. The testable idea is simple: can adding a product interaction to that viewing experience produce more conversions without weakening return on investment?

    Do not begin by moving a large video budget. Begin with a product set that makes the test interpretable. Favor products that are easy to recognize visually, have a clear use case, and are supported by dependable price and availability data. The item presented in the ad should also be easy to find at the destination. A viewer who meets a different product, price, or offer after acting on the ad has not experienced a media failure; they have experienced a broken handoff.

    • Make the product and its main benefit understandable at television viewing distance. Do not rely on dense copy or small interface details to explain the offer.
    • Check the full path from the video impression to the product action and final destination. Look for changes in item identity, price, availability, or promotional language.
    • Judge the test primarily on conversions, conversion value, CPA, or ROI, according to your business model. Video engagement can diagnose creative response, but it should not replace the commercial outcome.
    • Document what adding CTV is expected to change. If the hypothesis is merely that the campaign will reach more people, the test is too vague to justify a performance conclusion.

    Use Travel Feeds when changing offers make creative stale

    Travel Feeds address a different source of friction. Hotel pricing and availability can change faster than a team can rebuild conventional video assets. Connecting Hotel Center allows those offer details, along with property ratings, to populate dynamic video ads.

    The feed becomes part of the advertising experience, so feed quality is campaign quality. Before increasing spend, sample the properties and offers being promoted. Compare the price, rating, and availability presented in the ad journey with what a traveler encounters when moving toward a booking. Decide how your team will identify unavailable properties, inconsistent prices, and destinations that no longer match the promoted offer.

    • Audit Hotel Center data before evaluating the creative. Incorrect or incomplete offer data can make capable media look ineffective.
    • Review a representative mix of properties rather than checking only the most visible or highest-volume listing.
    • Assign ownership for feed corrections. A media buyer who can identify a mismatch but cannot route it to the person responsible for hotel data will repeatedly diagnose the same problem.
    • Keep the booking outcome as the primary metric. Dynamic assembly reduces creative and offer friction; it does not remove the need to evaluate booking quality and campaign economics.

    Use Attributed Branded Searches when last-click reports hide influence

    Demand Gen can affect what people search for after seeing an ad, even when the eventual search or conversion does not look like a direct response to the original impression. Attributed Branded Searches are designed to expose that brand-search activity across Google and YouTube.

    That makes the metric useful, but not equivalent to revenue. A rise in attributed brand searches can indicate that the campaign created interest. It cannot, on its own, tell you whether those searches produced profitable, incremental customers. Read it beside conversions, conversion value, CPA, ROI, and any customer-quality measure your business already trusts.

    Because a Google representative must activate the feature, treat access as a pre-launch dependency rather than an item to chase after the campaign ends. Ask the representative to confirm eligibility, the activation date, the metric definition, the reporting location, the applicable attribution window, and any limitations that could affect interpretation. Record those answers with the campaign brief so nobody later compares two reports built on different rules.

    Build the measurement plan before you move budget

    A desk with connected devices, interaction tokens, measurement checkpoints, and budget tokens waiting behind a transparent gate.

    The updates make Demand Gen more measurable, but more metrics do not automatically create a clean test. You still need a decision framework that separates commercial outcomes from diagnostic signals.

    1. Write one falsifiable hypothesis. For example: adding TV screens will increase conversions while maintaining ROI, or feed-driven hotel video will increase bookings without exceeding the campaign’s CPA constraint. Avoid a bundle such as improving awareness, engagement, sales, and efficiency at once.
    2. Select one primary outcome and one guardrail. The outcome might be purchases, bookings, conversion value, or another completed business action. The guardrail might be CPA or ROI. Branded search and video engagement should remain supporting signals unless they are genuinely the business objective.
    3. Lock the comparison rules. Use consistent conversion actions, value rules, attribution settings, and reporting periods when comparing Demand Gen with an existing campaign or channel. If those controls cannot be aligned, label the comparison as directional rather than causal.
    4. Record operational diagnostics. For commerce, inspect product continuity and availability. For travel, inspect Hotel Center data and the offer-to-booking path. For brand measurement, confirm that Attributed Branded Searches were active during the period being evaluated.
    5. Define the next decision before results arrive. State what would justify a limited scale-up, what would trigger a feed or landing-path repair, and what would cause the test to stop. You do not need to invent universal thresholds; use the economics your account must already meet.

    Once the campaign is running, interpret combinations of signals instead of celebrating one favorable number:

    Signal patternWhat it may meanWhat to do next
    Conversions rise while ROI holds or improvesThe commerce path may be creating useful additional demand at acceptable efficiency.Verify order or booking quality, repeat the result, and scale gradually.
    Attributed brand searches rise but conversions remain flatThe campaign may be generating interest that the offer, destination, or conversion path is not capturing.Do not declare a revenue win. Inspect search destinations, landing experiences, offer consistency, and conversion tracking.
    Video engagement improves but commercial outcomes weakenThe creative may attract attention without qualifying the right buyer or making the next action clear.Rework the product promise and handoff before adding budget.
    Travel ads show inconsistent offers or weak deliveryHotel Center data or campaign configuration may be obscuring the media result.Resolve feed accuracy and eligibility questions before concluding that the channel failed.

    Use Google’s performance figures as test inputs, not forecasts

    Google reports that Demand Gen campaigns featuring TV screens generated 7% more conversions at the same ROI. LG Electronics also reported a 24% higher conversion rate than paid social while reaching high-value customers at a 91% lower CPA. Those figures make a reasonable case for testing the channel, but they are vendor-reported results rather than a guaranteed outcome for your account.

    The LG comparison is especially easy to misuse. Without matching details for audience, geography, campaign period, conversion action, creative, and attribution model, a 91% CPA difference cannot become your forecast. Even the phrase “paid social” can conceal campaigns with different objectives and levels of maturity.

    • Use the 7% figure to support the question, “Is a controlled CTV test worth running?” Do not insert it automatically into a revenue plan.
    • Use the LG result as evidence that Demand Gen can compete with paid social under some conditions, not that it will always outperform it.
    • Put the comparator beside every benchmark in your internal presentation. A percentage without its baseline, campaign objective, and measurement rules is not an operating target.
    • Let your account’s conversion quality and unit economics decide whether to scale. A lower reported CPA is not valuable if it produces lower-value customers or bookings that do not hold.

    Key takeaways

    • Shoppable CTV is a commerce-path update: use it when YouTube viewing creates product interest but the television experience lacks a clear response mechanism.
    • Travel Feeds are an offer-assembly update: audit Hotel Center data because price, rating, and availability accuracy directly affect what the traveler sees.
    • Attributed Branded Searches are a measurement update: activate the feature through a Google representative before launch and interpret it beside commercial outcomes.
    • Google’s 7% conversion figure and LG Electronics’ paid-social comparison can justify a test, but neither should be treated as an account forecast.
    • The strongest rollout ties one feature to one constraint, one primary outcome, one efficiency guardrail, and a written scale-or-stop decision.

    Before your next campaign-planning meeting, write a one-sentence hypothesis and the two numbers that will decide whether you scale or stop. Then introduce only the Demand Gen feature capable of moving that hypothesis. That keeps the update focused on a business decision instead of letting it become a reason to spend first and explain the result later.

    References

  • Google Campaign Mix Experiments: A Practical Testing Guide

    Google Campaign Mix Experiments: A Practical Testing Guide

    You need to decide whether the next dollar belongs in Search, Performance Max, Shopping, Demand Gen, Video, or App. Looking at campaign-level ROAS alone will not answer that question. Changing one part of the account can alter what the other campaigns capture, so the decision has to be evaluated at the portfolio level.

    Google Campaign Mix Experiments gives you a way to compare complete campaign combinations rather than treating every campaign as an isolated unit. Used carefully, the beta can tell you whether a different mix produces a better business result. Used casually, it can produce a confident-looking answer to a badly framed question.

    Start with the spending decision, not the campaign list

    A useful mix experiment begins with a decision you could make after seeing the result. “Test Performance Max” is not a decision. “Determine whether moving budget from the current Search and Shopping mix into a Search and Performance Max mix improves conversion value at the same total budget” is.

    Write your hypothesis in this form:

    If we change [one portfolio variable] while holding [the important controls] constant, we expect [primary metric] to improve enough to justify [the account change].

    Campaign mix experiment hypothesis template

    The phrase “enough to justify” matters. A measurable difference is not automatically a commercially important difference. Before launch, define the smallest improvement that would cover the operational cost, additional complexity, or risk created by the proposed mix. That threshold is your materiality rule.

    Choose one primary metric that matches the decision:

    • ROAS fits a revenue-efficiency decision when your conversion values are dependable.
    • CPA fits a cost-efficiency decision when the counted conversions have reasonably comparable business value.
    • Conversions fits a volume decision when generating more qualified actions is the main objective.
    • Conversion value fits a growth decision when total value matters more than efficiency alone.

    Google supports reporting around ROAS, CPA, conversions, and conversion value. You can inspect all of them, but naming one primary metric in advance prevents a common analytical mistake: searching the results for whichever metric makes the preferred arm look best.

    Key takeaways

    • Frame the experiment as a portfolio-level business decision, not a request to identify the best individual campaign.
    • Change one meaningful variable between arms and keep the other important conditions aligned.
    • Keep total budgets comparable unless total spend is explicitly the variable under test.
    • Avoid shared budgets and material account changes while the experiment is running.
    • Preselect the primary metric, confidence interval, materiality rule, and minimum duration before looking at outcomes.
    • Plan for at least six to eight weeks, but do not assume that duration alone guarantees a decisive result.

    Build arms that isolate one portfolio variable

    Two balanced experiment trays contain matching campaign modules with one controlled difference between them.

    An experiment arm is one complete version of the campaign portfolio. The beta supports up to five arms, and the same campaign can appear in more than one arm. That flexibility is valuable because you can preserve the common parts of the account while changing only the element you need to evaluate.

    More arms are not inherently better. Every additional arm creates another comparison and divides the available traffic. Use the fewest arms that can answer the decision. For many questions, a current-state control and one alternative are enough.

    The framework covers Search, Performance Max, Shopping, Demand Gen, Video, and App campaigns. Hotels campaigns are excluded. That breadth lets you test a cross-channel plan, but it does not remove the need for a clean experimental contrast.

    DecisionWhat changes between armsWhat should stay aligned
    Channel budget allocationThe distribution of budget among campaign typesTotal portfolio budget, measurement, and other material settings
    Consolidation versus fragmentationThe number or structure of campaignsTotal budget, business objective, and the intended audience or inventory scope
    Bidding strategyThe bidding approach being evaluatedCampaign mix, budget treatment, targeting, and measurement
    Targeting optionThe selected targeting treatmentBudgets, bidding, creative treatment, and the rest of the portfolio
    Feature adoptionThe feature is used in one arm and not the otherEverything not required to enable that feature

    Suppose you change campaign structure, bidding, targeting, and budget distribution in the same arm. A winning result tells you that the package performed differently, but not which change caused it. You also cannot tell whether one helpful change compensated for another harmful one. That may be acceptable when the package itself is the business decision, but it is a poor design when you need reusable knowledge.

    Budget handling deserves particular care. If you want to test the mix, keep the total planned budget equal and change its internal allocation. If you want to test a higher total spend level, make total spend the sole intended difference. Do not quietly give the preferred arm both a different campaign combination and more money; the result will not distinguish the effect of mix from the effect of spend.

    Traffic can be allocated among arms with splits starting at 1%, and reporting is adjusted to the smallest split so the comparison remains fair. Treat 1% as a configuration boundary, not a recommendation. A very small arm may receive too little information to resolve a commercially modest difference, especially when conversions are sparse. The better question is whether every arm can accumulate enough relevant outcomes during the planned window.

    Protect the comparison for the full test window

    A strong setup can still fail after launch. New promotions, tracking changes, creative replacements, altered conversion values, revised targets, and unplanned budget moves can all change the conditions under which the arms are being compared. If those interventions affect the arms differently, you no longer have the experiment you designed.

    Plan to run a campaign mix experiment for at least six to eight weeks. This is a minimum operating window, not a promise of statistical certainty. An account with limited conversion volume or a small true difference may still produce a wide range of plausible outcomes after that period.

    Before launch, complete a short preflight:

    1. Validate measurement. Confirm that the conversions and values feeding the primary metric represent the business outcome you intend to optimize. Fix tracking before the experiment, not during it.
    2. Check arm symmetry. Verify that the total budgets and non-tested settings are aligned wherever the hypothesis requires them to be.
    3. Remove shared-budget dependencies. Google advises avoiding shared budgets during these experiments. A shared budget can redistribute spend across campaigns and obscure the portfolio treatment you meant to test.
    4. List prohibited changes. Record which budgets, bidding settings, targets, campaign structures, features, and measurement rules must remain untouched.
    5. Record unavoidable events. If a promotion, inventory interruption, landing-page failure, or other business event occurs, document when it began, which campaigns it affected, and whether it compromised comparability.
    6. Set review dates. Monitor for broken delivery or measurement, but do not repeatedly judge the winner from early fluctuations.
    7. Define stop conditions. Separate genuine operational failures, such as broken tracking, from ordinary underperformance. A disappointing early result is not by itself evidence that the experiment is invalid.

    The instruction to avoid significant changes does not mean ignoring a serious problem. If tracking fails or an arm cannot deliver as designed, protect the business and correct the problem. Then decide whether the comparison remains interpretable or needs to be restarted. The mistake is pretending that a materially altered test still answers the original hypothesis.

    Keep a change log even when no restart is needed. Record the date, affected arms, reason, and expected impact of every intervention. When the result arrives several weeks later, that log will help you distinguish a real portfolio effect from a mid-test account event.

    Read the portfolio result before diagnosing campaigns

    A large magnifying lens frames an interconnected campaign system while smaller lenses point toward its individual components.

    The Experiment summary should answer the question you wrote before launch: did one complete mix improve the primary business metric enough to change your decision? Campaign-level reporting then helps you understand where the portfolio difference appeared. Reversing that order invites cherry-picking.

    One campaign can improve while the portfolio remains flat or declines. Another campaign can look weaker while the total arm improves because the mix is capturing demand more efficiently as a whole. Campaign-level movement is diagnostic evidence; it is not a substitute for the arm-level result.

    Google lets you view experiment reporting with 95%, 80%, or 70% confidence intervals. Choose the interval before reading the outcome. A more conservative interval demands stronger evidence and will generally produce a wider range. A lower interval accepts more uncertainty. Switching among them until a preferred arm appears convincing turns an analytical setting into a result-shopping tool.

    Read the result through three separate lenses:

    • Direction: Which arm currently appears better on the primary metric?
    • Uncertainty: Does the interval leave room for a materially different conclusion, including a meaningful loss?
    • Materiality: Is the likely difference large enough to justify the budget move, structural complexity, or operational burden?

    Do not collapse those questions into a single winner label. A positive point estimate with a broad interval can still be inconclusive. A statistically clear but commercially tiny improvement may not justify rebuilding the account. An interval that includes little or no difference does not prove that the arms are identical; it means this run did not resolve the difference precisely enough under the selected standard.

    Use the metric in the context of its inputs. ROAS and conversion value depend on the quality of the values assigned to conversions. CPA can look healthier when the mix generates cheaper but less valuable actions. Conversion volume can increase while efficiency deteriorates. These are not reasons to abandon a primary metric. They are reasons to make sure it represents the decision before the test begins and to use the other metrics as context rather than alternate finish lines.

    Turn the finding into a controlled account decision

    The result should lead to one of three actions: adopt the alternative, retain the current mix, or collect more evidence. Write the rule before launch so the post-test discussion is about evidence and tradeoffs rather than stakeholder preference.

    • Adopt: The alternative improves the preselected primary metric, the uncertainty is acceptable under the chosen interval, and the effect exceeds your materiality threshold.
    • Retain: The alternative is worse, creates an unacceptable downside, or fails to produce enough benefit to cover its complexity and cost.
    • Collect more evidence: The plausible range includes outcomes that would lead to different business decisions. Treat this as unresolved, not as a tie and not as permission to select the preferred narrative.

    If you adopt a winning mix, implement the treatment you actually tested. Adding new targeting, changing bids, moving the total budget, and restructuring campaigns during rollout creates a new package whose performance was never evaluated. Make the validated change first, observe it under normal account conditions, and treat later improvements as separate decisions.

    If the result is inconclusive, do not automatically rerun the same design. First identify why the answer remained unclear. The true difference may be too small to matter, an arm may have received too little useful traffic, the primary outcome may be too sparse, or account changes may have weakened the comparison. Rerun only when you can improve the design or when resolving the decision is worth another full testing window.

    A compact decision record makes the learning reusable. Save these fields with the result:

    • The business decision and one-sentence hypothesis
    • The campaigns and settings included in every arm
    • The single intended difference between arms
    • Total budget treatment and traffic allocation
    • The primary metric and materiality threshold
    • The preselected confidence interval
    • The planned and actual run dates
    • All material account or business events during the test
    • The arm-level result and relevant campaign-level diagnosis
    • The final decision, owner, and implementation boundary

    Your best first use of Campaign Mix Experiments is the largest unresolved allocation decision that can still be isolated cleanly. Write the hypothesis, name the metric, and sketch the control and alternative on one page. If you cannot explain exactly what changes and what stays fixed, the experiment is not ready to launch.

    References

  • How to Choose an Industrial Marketing Agency That Fits

    How to Choose an Industrial Marketing Agency That Fits

    If you are choosing an industrial marketing agency, a polished proposal is the easy part. The harder question is whether the team can learn a technical offer, earn access to your subject-matter experts, reach the people involved in the purchase, and show what became qualified pipeline.

    A candidate pool gives you names. A disciplined selection process tells you which agency can actually do the work. Use the framework below to prepare your brief, test technical fluency, compare proposals, and protect the engagement before you sign.

    Write the buying brief before you build the shortlist

    Do not begin with a list of services you think you need. Begin with the commercial problem the agency must help solve. Otherwise, every proposal will describe a different interpretation of success, and you will be comparing presentation quality rather than strategic fit.

    Prepare a compact decision brief with the following information:

    • Commercial outcome: State whether the priority is qualified pipeline, entry into a market, distributor support, aftermarket growth, account expansion, product adoption, or another defined business result.
    • Offer boundary: Name the products, services, applications, territories, and customer segments that are in scope. Identify what is explicitly out of scope.
    • Buying group: List the people who use, specify, approve, purchase, install, maintain, or resell the offer. Do not flatten them into a generic buyer persona.
    • Available evidence: Inventory approved specifications, certifications, performance data, technical drawings, case material, expert commentary, customer proof, and product imagery. Mark anything that requires legal, engineering, or customer approval.
    • Valuable conversion: Define the actions that matter, such as a qualified request for quote, sample request, site visit, consultation, drawing download, specification download, phone call, or distributor inquiry.
    • Measurement path: Identify the CRM stages, lead-status definitions, sales owner, and reporting systems that will determine whether marketing activity produced useful demand.
    • Operating constraints: Document restricted claims, regulatory reviews, channel conflicts, brand requirements, development limitations, subject-matter expert availability, and internal approval steps.

    Replace goals such as “increase awareness” or “generate leads” with language your sales team can recognize. For example, define what information an inquiry must contain before sales can quote it, which customer types are commercially attractive, and which inquiries should be excluded. If marketing and sales cannot agree on a qualified inquiry, an agency cannot optimize toward one.

    Set your disqualifiers at the same time. These might include weak analytics capability, no technical review process, outsourced execution with no named owner, unclear account ownership, or an unwillingness to work inside your claims-approval rules. A disqualifier should remain a disqualifier even when the pitch is impressive.

    Test industrial fluency with a real working session

    A plant engineer explains an opened industrial pump assembly to two marketing specialists during a hands-on workshop.

    An agency does not need to arrive knowing every detail of your process. It does need a credible method for learning technical material without turning it into vague benefit copy. You can see that method more clearly in a working session than in a capabilities deck.

    Give each finalist the same public product or service page and the same application context. Ask the proposed team to work through these questions with you:

    • What does the offer do, where does it fit, and where does it not fit?
    • Which facts are clear, which are unsupported, and which require an expert to verify?
    • Who uses the offer, who specifies it, who approves it, and who controls the purchase?
    • What operational problem brings a buyer to the page, and what information would help that buyer continue evaluating?
    • What proof would make the central claim credible?
    • Which search questions, comparison questions, and implementation questions should the content answer?
    • What should the visitor do next, and what would make that action useful to sales?
    • What would the team need from engineering, product, sales, service, compliance, or distribution before publishing?

    Pay attention to the questions the agency asks. Strong discovery separates facts from assumptions, notices exclusions and tradeoffs, and identifies the internal expert who can resolve each uncertainty. Weak discovery paraphrases the existing page, adds generic adjectives, and starts recommending channels before the buying problem is understood.

    Ask for evidence of the working process, not just customer logos. Useful evidence can include a redacted content brief, an interview guide for a technical expert, a claims-review workflow, a campaign measurement specification, a reporting example, or a before-and-after explanation of how a technical page was improved. The closest match is not always an identical industry. Comparable product complexity, buying risk, sales motion, and review constraints can be more revealing than a familiar vertical label.

    Confirm who produced each example and whether those people will work on your account. Agency credentials matter less when the proposed delivery team did not create the work being shown.

    Judge the channel plan as a connected demand system

    Unbranded communication tools connect through illuminated cables to a transparent pipeline leading toward a sales meeting area.

    Industrial demand rarely fits neatly inside a single campaign report. A buyer may discover a problem through search, compare technical approaches, return through a branded query, download a drawing, speak with a distributor, and enter the CRM under a different source. Your agency should design the content, channels, conversion paths, and measurement rules as parts of the same system.

    Make technical content useful before making it plentiful

    Ask the agency to propose a page architecture based on buyer tasks, not a publishing quota. Depending on your offer, that architecture may include:

    • Product or service pages that explain fit, exclusions, specifications, constraints, evidence, and the appropriate next action.
    • Application pages that connect an operating condition or use case to a suitable solution without pretending every product fits every environment.
    • Technical answer pages that address selection, compatibility, troubleshooting, maintenance, installation, or implementation questions your experts can answer accurately.
    • Comparison and alternative pages that explain meaningful tradeoffs rather than declaring your offer universally superior.
    • Proof pages that organize approved performance evidence, certifications, case material, processes, and expert qualifications.
    • Commercial access pages that help a visitor request a quote, locate a distributor, submit project details, download the correct resource, or reach the appropriate team.

    For search, answer engines, and generative systems, the fundamentals still have to be present on the page. The agency should make products, services, applications, organizations, and expert claims unambiguous; answer important questions directly; connect related pages with purposeful internal links; and use applicable structured data that agrees with the visible content.

    Ask who selects the structured-data types, who validates the markup, how conflicts with existing plugins or templates are handled, and what triggers an update when the page changes. JSON-LD can clarify machine-readable facts. It cannot repair an unsupported claim, a confused page, or missing evidence. Treat guaranteed rankings, guaranteed AI citations, and guaranteed inclusion in generated answers as disqualifiers.

    The same discipline applies to paid search, paid social, email, industry media, distributor programs, and event support. For every proposed channel, require the agency to state:

    • Which audience condition or buying task the channel addresses.
    • Which offer and asset the audience will encounter.
    • Which next action is appropriate at that stage.
    • Which signal will indicate useful progress.
    • Which evidence would cause the team to change or stop the tactic.

    Make measurement survive the sales handoff

    A useful measurement design follows the path from campaign or source to landing page, conversion, CRM record, sales disposition, and opportunity. A dashboard that stops at impressions, clicks, rankings, or sessions cannot tell you whether the agency is attracting commercially relevant demand.

    Require a measurement specification before launch. It should identify each tracked action, the data captured with it, the CRM destination, the person responsible for follow-up, the treatment of duplicates and spam, and the check used to catch broken forms or tags. Campaign identifiers, call tracking, form fields, consent handling, and offline sales updates should fit the systems you actually use.

    Marketing should not invent revenue attribution after the fact, and sales should not leave every lead status blank. Agree on shared definitions before judging performance. The most useful report shows not only what happened, but which audience, message, page, offer, or channel should receive more investment, correction, or removal.

    Compare proposals by evidence, dependencies, and ownership

    Standardize your evaluation before proposals arrive. Mark each requirement as mandatory or preferred, then record the evidence as confirmed, assumed, or missing. This prevents a polished presentation from quietly compensating for a fatal weakness elsewhere.

    Evaluation areaEvidence to requestWarning sign
    Technical discoveryProduct and buyer hypotheses, open questions, expert-interview plan, and claims-review processGeneric personas and recommendations formed before technical discovery
    StrategyClear connection between the commercial objective, buyer task, channel role, offer, and conversionA menu of tactics with no decision logic
    Content qualityRepresentative brief, source requirements, technical review steps, and approval ownershipA production-volume promise with no accuracy workflow
    SEO, AEO, and GEOPage architecture, query and intent mapping, entity clarity, internal linking, structured-data governance, and update planGuaranteed rankings, citations, or generated-answer placement
    MeasurementEvent definitions, CRM mapping, lead-status rules, dashboard example, and data-quality checksReporting limited to visibility and traffic
    Delivery teamNamed roles, allocation assumptions, escalation path, and examples produced by the proposed teamSenior specialists sell the engagement but disappear from delivery
    Commercial modelIncluded deliverables, client dependencies, media treatment, change-control process, and acceptance criteriaA vague retainer that leaves scope and accountability open to interpretation
    Ownership and accessWritten terms for accounts, data, source files, creative assets, tracking, code, and transition supportCritical systems remain under an agency-controlled identity

    Ask every finalist to solve the same working problem and use the same evaluation areas. Do not score a claim such as “we can handle analytics” as evidence. Score the measurement design, sample output, named owner, and proposed quality checks.

    Reference conversations are more useful when you ask about operating behavior. Find out who actually performed the work, what the client had to supply, how the agency handled technical corrections, whether reporting changed decisions, and what happened when priorities shifted. Speak with the people who will manage and execute your engagement as well as the people selling it.

    Contract for learning, ownership, and a clean handoff

    The contract should turn proposal language into operating rules. Have the appropriate commercial and legal owners review the terms before signature. Unclear ownership or access provisions can make an agency change expensive, interrupt measurement, or leave you without editable assets.

    Resolve these points in writing:

    • Scope and acceptance: Define included and excluded work, review rounds, approval criteria, and the process for changing priorities.
    • Client dependencies: Name the access, technical experts, product data, approvals, development support, and sales feedback your team must provide.
    • Claims governance: Identify who can approve performance claims, comparisons, certifications, customer references, and regulated language.
    • Account control: Use company-controlled identities for analytics, advertising, search tools, tag management, domains, repositories, and other critical systems. Give the agency the access it needs without making it the only administrator.
    • Asset ownership: Address final assets, editable source files, research, keyword maps, content briefs, templates, tracking specifications, structured data, custom code, and historical reporting.
    • Data handling: Define permitted access, storage, retention, deletion, confidentiality, and incident responsibilities for lead, customer, employee, and account data.
    • Fees and spend: Separate agency fees, media spend, software costs, production expenses, and pass-through charges so the budget can be reconciled.
    • Transition: Specify how credentials, documentation, files, active campaigns, reporting history, and open work will be transferred when the engagement ends.

    If important uncertainty remains, structure the initial phase around a decision checkpoint. Useful outputs include approved positioning, a claims and evidence inventory, a prioritized page architecture, a measurement specification, a representative deliverable, and an execution plan with dependencies. You can then continue, revise the scope, or stop based on visible work rather than optimism.

    Key takeaways

    • Brief the agency in commercial and sales language before discussing channels.
    • Test the proposed team on a real product, application, and buying problem.
    • Look for a disciplined learning and technical-review process, not superficial familiarity with industry terminology.
    • Evaluate content, SEO, AEO, GEO, paid media, conversion, CRM handling, and reporting as a connected demand system.
    • Require evidence for every capability claim and reject guarantees the agency cannot control.
    • Keep critical accounts, data, editable assets, and documentation accessible through company-controlled systems.

    Your next move is practical: finish the decision brief, choose a representative working problem, and send both to every serious finalist. The strongest choice will be the team whose reasoning stays coherent from product truth and buyer need through conversion, sales acceptance, and measurable pipeline.

    References

  • How to Choose a Healthcare or Medtech Marketing Agency

    How to Choose a Healthcare or Medtech Marketing Agency

    You may be staring at several polished agency proposals that all promise strategy, content, search visibility, and growth. The difficult part isn’t finding a capable-looking firm. It is determining which firm understands your revenue path, can work safely inside your approval process, and will let you verify what it actually contributes.

    The market is crowded enough that 2026 screens of medtech SEO agencies began with more than 60 firms, while a separate assessment of healthcare marketing agencies also began with more than 60. You will narrow that field much faster with a precise buying brief, an evidence-weighted scorecard, and a realistic working test.

    Write the brief around the revenue path, not marketing services

    An illustrated medtech revenue path connects a device demonstration, compliance review, hospital procurement, clinical use, and revenue tokens.

    Healthcare and medtech sit near each other on an industry map, but they do not automatically create the same agency brief. A provider organization may need to turn local demand into qualified appointment requests. A medtech company may need to educate clinicians, administrators, procurement stakeholders, distribution partners, or other participants before a commercial conversation can advance.

    If you ask for SEO, content, paid media, or AI optimization before defining that path, agencies will sell the services they already deliver. Start with the change your organization needs and work backward to the marketing capability.

    If you market a practice or care-delivery organization

    • Name the service line and location you need to support. Local visibility for a specific service is a different assignment from national brand building.
    • Define a qualified conversion. It might be an appointment request, a call that meets your intake criteria, or a professional referral inquiry. A raw form submission is not automatically a useful lead.
    • Describe the path after conversion. Tell the agency who receives the inquiry, how eligibility or fit is assessed, and where the result is recorded.
    • State operational constraints. If a location, clinician, or intake team cannot absorb additional demand, more traffic can create a worse patient experience without improving the business.
    • List the people who approve medical statements, patient-facing language, advertising claims, and reputation responses. The agency needs to design around that workflow.

    If you market a medical technology

    • Map the audience chain. Separate the people who use the technology, evaluate it, approve it, purchase it, distribute it, and search for information about it.
    • Name the decision friction. You may need category education, technical explanation, economic justification, evidence discovery, or help distinguishing the product from an established alternative.
    • Choose a meaningful commercial action. A demo request, distributor inquiry, sales-accepted conversation, or engagement from a target organization can be more informative than undifferentiated lead volume.
    • Document the evidence boundary. Give the agency the approved language, supporting material, prohibited claims, required review steps, and owner of each decision.
    • Identify geographic and organizational complexity. A single-market campaign should not be scoped like a multi-region program that must balance central messaging with local relevance.

    Turn those decisions into a short brief before you take another sales call. Include the business outcome, audience, current obstacle, desired conversion, geographic scope, approval owners, evidence constraints, available assets, required systems, and definition of a qualified result. Add explicit non-goals as well. If brand awareness is not the assignment, say so. If the agency will not control paid media, website development, or sales operations, say that too.

    This brief makes proposals comparable. It also reveals whether an agency can reason from your problem or merely translate its standard package into healthcare language.

    Match the agency model to the bottleneck you actually have

    Specialist healthcare agencies do not all solve the same problem. Available models span authority building, local search, international programs, full-service marketing, long-term content, technical web work, reputation management, and combined search and social strategies. None of those models is universally superior. The right one removes the constraint that is currently preventing progress.

    • Choose a local-search specialist when patients must discover a particular location or service in geographically relevant results. Ask for evidence of location architecture, business-profile management, local content judgment, review workflows, and conversion tracking through intake.
    • Choose an authority-and-content specialist when your audience cannot make progress without credible education. Ask to see how topics are selected, how subject-matter experts participate, how claims are checked, and how content connects to an intended commercial action.
    • Choose a technical website and SEO firm when crawlability, site structure, publishing friction, accessibility, performance, or an impending rebuild is the main constraint. Require a clear division between diagnosis, implementation, design, content migration, validation, and ongoing optimization.
    • Choose a reputation-led agency when trust signals, inconsistent profiles, or the handling of public feedback is obstructing demand. Ask who is authorized to respond, which issues are escalated, and how the work connects to brand and search visibility without exposing sensitive information.
    • Choose a multi-location or international specialist when central control and local relevance keep colliding. Ask the agency to show how it governs shared templates, local pages, market-specific review, brand consistency, and reporting across regions.
    • Choose an integrated firm when channel coordination is the bottleneck. A broad agency can be useful when the same strategy must govern web, search, content, advertising, and social execution. Make it identify the owner of the integrated plan; a bundle of separate channel teams is not automatically integration.
    • Choose a social-and-search model when audience discovery genuinely crosses those surfaces. Require a clear role for each channel and a method for recognizing when social attention creates branded search, site engagement, or a qualified inquiry.
    • Choose an AI-search specialist only when it can turn generative engine optimization into inspectable work. Some firms now market GEO alongside conventional Google SEO, with visibility in recommendations from platforms such as ChatGPT as an objective. Ask for the target questions, baseline observations, content changes, authority work, measurement method, and limitations behind that objective.

    Do not buy a larger service bundle just because it appears more complete. If the real problem is medical-content production, adding paid media and social posting may increase coordination before it increases performance. Conversely, a narrow SEO firm may be the wrong choice when your website, analytics, intake process, and brand message all need coordinated repair.

    Ask each agency to identify the bottleneck in its own words. Then ask what it would defer. A credible prioritization includes work that should not happen yet.

    Score evidence before you score the presentation

    A scorecard prevents the most confident presenter from quietly becoming the default choice. One cardiology-focused evaluation considered 73 specialist firms and weighted average review score at 30%, healthcare experience at 25%, leadership experience at 15%, active client portfolio at 10%, compliance expertise at 10%, median employee tenure at 5%, and media references and case studies at 5%.

    That weighting is a useful starting structure, not a universal procurement rule. Adjust the emphasis before opening proposals. A sensitive content program may deserve more emphasis on compliance and subject-matter workflow. A rebuild may require more scrutiny of technical delivery. A highly specialized device may make relevant audience and category experience more important than the size of the agency’s general healthcare portfolio.

    CriterionBenchmark weightEvidence to request
    Average review score30%Recurring themes from clients with comparable scopes, including what happened when delivery was difficult. Treat a rating as a lead for verification, not proof by itself.
    Healthcare industry experience25%Work involving a similar audience, business model, review burden, and conversion path. General healthcare logos do not establish experience with your particular problem.
    Leadership experience15%The named person accountable for strategy, their relevant background, and their actual involvement after the sale.
    Client portfolio size10%Relevant active work, team capacity, possible conflicts, and an explanation of how resources will be assigned to your account.
    Compliance expertise10%An actual workflow for evidence, medical review, advertising review, privacy-sensitive access, escalation, approval, and revision history.
    Median employee tenure5%The expected delivery team, continuity of key roles, and the handoff plan if a strategist, writer, or account lead changes.
    Media references and case studies5%Cases that define the starting problem, agency contribution, measurement method, relevant constraints, and result. Ask which parts can be independently verified.

    Rate the evidence behind each answer as verified, plausible but unverified, or absent. Keep that confidence judgment separate from the agency’s claimed capability. A beautiful case study with an undefined baseline should not outscore a less dramatic example with a clear method and comparable scope.

    Set disqualifiers before scoring. Reasonable examples include refusal to follow your medical or legal review process, uncertainty about who owns core accounts and content, an unexplained need for sensitive data, a material client conflict, or guarantees of rankings and AI recommendations that the agency cannot control. A disqualifier should represent unacceptable exposure, not merely a preference.

    Put finalists through one real working session

    Healthcare and agency professionals collaborate around a table with a medical device, blank evidence cards, approval tokens, and workflow blocks.

    References and proposals tell you what an agency wants you to believe. A controlled working session shows you how its team thinks. Give every finalist the same redacted scenario and the same information. Do not share real patient information or sensitive commercial material merely to make the exercise realistic.

    1. Present the business problem without prescribing the channel. Ask the team to identify the audience, conversion, unknowns, constraints, and likely bottleneck before proposing tactics.
    2. Request a prioritized first phase. The team should distinguish prerequisites from experiments and explain what it would postpone. Listen for dependencies on your website, analytics, subject-matter experts, intake operation, or sales process.
    3. Test the content workflow. Provide a fictional or already approved example claim and ask how it would become a page, campaign, or answer-ready content asset. Require the team to identify where evidence, medical review, compliance review, and final approval enter the process.
    4. Trace measurement from discovery to business outcome. Ask the agency to draw the path from a search result, AI answer, advertisement, or social interaction through the website and into the system where your organization accepts or rejects the inquiry.
    5. Examine the AI-search plan separately. Ask which user questions it will monitor, how it will assess brand mentions and citations, which on-site changes it expects to make, how structured data fits the work, and how it will distinguish visibility from a qualified outcome.
    6. Review the operating model. Confirm the day-to-day team, decision rights, meeting purpose, reporting inputs, revision process, account ownership, content ownership, data access, and offboarding handoff.

    Make compliance visible in the workflow

    Compliance expertise should produce more than a badge in a capabilities deck. Ask the agency to draw the route from topic selection to evidence collection, drafting, subject-matter review, compliance or legal review, publication, monitoring, and later revision. Every handoff needs an owner. The agency should also be able to explain what happens when a reviewer rejects a claim or when approved language changes.

    If the work could involve information your organization treats as protected or sensitive, let your privacy, security, compliance, and legal owners determine the access and contractual requirements before access is granted. An agency’s familiarity with HIPAA or healthcare advertising standards does not replace your organization’s review or professional legal advice.

    Watch how the agency reacts to limits. Strong teams ask for the evidence they need, mark unresolved claims, and adapt the message. Weak teams treat review as a final proofreading step or assume that careful wording can rescue an unsupported promise.

    Treat GEO as auditable work, not a separate pile of AI copy

    A defensible healthcare GEO program still needs content that is understandable, medically accurate, and connected to authority. A documented cardiology approach combines accessible medical content and authority building with GEO and conventional Google search. Use that combination as a diligence framework, not as proof that any agency can guarantee inclusion in a particular answer.

    Ask the finalist to show the chain of reasoning: which audience question matters, what information an adequate answer requires, what your site currently lacks, which approved evidence supports the response, what content or structured information will change, and how visibility will be observed over time. It should also separate work on your own site from third-party authority or mentions that it cannot directly control.

    Do not accept isolated screenshots as a complete measurement system. Require a repeatable query set, a record of the conditions under which observations were made, visibility and citation tracking, site-engagement measures, and a connection to qualified commercial or patient-access outcomes. The agency should acknowledge uncertainty and variation instead of converting every appearance into a success claim.

    Make reporting follow the lead beyond the form

    Marketing reports often stop at the easiest event to count. Your decision should not. Ask who will connect an inquiry to intake acceptance, a scheduled interaction, a sales disposition, or whichever downstream status your organization uses. If that connection cannot be made yet, the proposal should identify the data gap and assign responsibility for closing it.

    The agency should distinguish three things: activity it completed, visibility or engagement that followed, and business outcomes that may have multiple causes. That separation protects you from both exaggerated credit and premature blame. It also makes optimization possible because you can see whether the problem is discovery, conversion, qualification, or follow-up.

    Key takeaways for a defensible agency decision

    • Define the audience, business outcome, qualified conversion, approval path, and non-goals before requesting channels or deliverables.
    • Choose the agency model that removes your present bottleneck. Local search, content authority, technical web work, reputation, integrated marketing, and GEO are different capabilities.
    • Use weighted criteria to control the decision, but adjust the emphasis before you see agency proposals.
    • Score the quality of evidence separately from the claimed capability. Comparable work and a transparent method matter more than a familiar logo.
    • Test finalists with the same redacted working scenario. Observe how they diagnose, prioritize, handle claims, design measurement, and respond to constraints.
    • Keep medical, privacy, compliance, and legal decisions with the qualified owners inside your organization. Agency expertise should support that governance, not replace it.
    • Require AI-search work to identify target questions, content and authority gaps, observable changes, measurement limits, and the connection to a meaningful outcome.

    Before your next agency call, reduce your assignment to one sentence: for this audience, we need this measurable action to improve, within these evidence and operating constraints. Send the same brief to every finalist and require each one to show its reasoning against it. The best choice is the team that gives you the clearest, safest, and most verifiable path from audience need to business result.

    References