Tag: Buyer Personas

  • Paid Social Audience Strategy That Proves Search Demand

    Paid Social Audience Strategy That Proves Search Demand

    Your paid social campaigns may be creating customers that your reporting assigns to search. Someone sees a Meta ad, remembers the brand, searches later, and converts through a paid search ad. Last-touch reporting makes search look efficient and social look expendable.

    Fixing that measurement problem starts before you open an attribution report. You need creative that reaches genuinely different parts of the market, followed by a test that measures the search demand those messages produce. Otherwise, you can mistake repetitive creative for broad audience coverage and mistake missing attribution credit for missing business impact.

    Creative determines which demand you can create

    An ad set is no longer your complete audience plan. On Meta, the delivery system interprets what each ad communicates and uses that signal to find likely responders. The hook, problem, proof, offer, and framing all influence which part of a broad audience is most likely to receive the ad.

    This is why producing more assets does not necessarily expand your reach. Ten ads that make the same argument are ten production variations, but they may amount to only one targeting signal. They can compete for the same people, increase frequency inside that segment, and leave other prospective buyers untouched.

    Build your audience plan around distinct buyer states rather than a count of images and videos. Three useful starting states are:

    Buyer stateQuestion in the buyer’s mindCreative job
    Problem-awareIs this problem important enough to solve?Name the problem, show its consequence, and introduce a credible path forward.
    SkepticalWhy should I believe this will work?Lead with relevant proof and address the reason the buyer hesitates.
    Price-drivenIs the value worth the cost?Clarify the offer, value, or economic tradeoff without disguising the price question.

    These are messaging states, not permanent demographic boxes. Define each one by the objection or decision it represents. That keeps the creative brief focused on why someone would respond, rather than forcing every audience distinction into an interest-targeting setting.

    Use this process for each state:

    1. Write the buyer’s immediate question in one sentence.
    2. Choose one argument that answers that question.
    3. Select the proof and offer that support that argument.
    4. Write a hook that makes the intended state unmistakable.
    5. Only then adapt the message into different formats, lengths, and executions.

    Label every ad internally with its buyer state and messaging angle. A useful naming pattern is state – angle – format – version. For example, a proof-led video for a skeptical buyer and a proof-led static image for the same buyer are format variations within one angle. They should not be counted as two separate audience strategies.

    There is also a quick editorial test: exchange the opening lines of two ads. If both ads still make sense, their angles probably are not different enough. Change the argument, proof, or offer before spending more money on additional executions.

    Find creative fragmentation before it distorts the results

    An overhead illustration shows repetitive ad tiles reaching one audience cluster while varied creative tiles reach several different clusters.

    Creative fragmentation does not arrive as a clear platform warning. It appears as a pattern across delivery and cost metrics. One metric alone is not conclusive, because auction conditions, budgets, and offers can also move performance. Several signals moving together deserve attention.

    • Frequency rises while reach stalls: your ads may be returning to the same people instead of finding another buyer state.
    • A new ad spikes and immediately settles near the old ads: it may be taking impressions from an existing execution rather than opening new demand.
    • Each creative version fatigues faster: repeated exposure may be exhausting one segment while the rest of the market receives little relevant messaging.
    • Cost per click creeps upward without an obvious external cause: similar ads may be competing for the same impressions.

    Those patterns are practical indicators of creative-led audience overlap. Treat them as diagnostic prompts, not automatic proof. Check whether the changes began after you added near-duplicate creative and whether the effect is concentrated inside one messaging group.

    Run a monthly overlap audit while the account is active:

    1. List every live ad, including its hook, primary claim, proof, offer, and intended buyer state.
    2. Ignore format while grouping the ads. A video and carousel making the same argument belong in the same message group.
    3. Flag groups where more than two or three live ads carry essentially the same message.
    4. Consolidate redundant executions so the account has fewer versions competing for the same response.
    5. Identify buyer states that have no live message and brief creative specifically for those gaps.
    6. Track reach, frequency, cost, and outcomes by message group rather than judging each asset in isolation.

    Refresh schedules should also follow the buyer state. A large segment may continue responding after a narrower one has fatigued. Do not replace the entire creative portfolio because one angle has worn out. Write a new hook for that state, preserve differentiated messages that still work, and keep every important audience represented.

    Cleaner first-party conversion data matters here. Pixel and CRM signals help the system match differentiated messages with likely responders. If the conversion signal is incomplete or inconsistent, a well-designed set of angles still has less useful feedback to optimize against.

    Measure demand creation at the right level of confidence

    Attribution and incrementality answer different questions. Attribution decides which recorded interaction receives credit. Incrementality asks whether an outcome happened because the campaign ran. Paid social is easy to undervalue when you use last-touch attribution, restrict the conversion window to 24 hours, or report social separately from search and other channels. Each choice removes part of the journey in which social exposure can lead to a later search and conversion.

    You do not need to jump immediately to the most complex experiment. Choose the method that matches the decision you must defend.

    Use branded search lift as the first demand signal

    A rise in exact brand and product-name searches is one of the clearest observable signs that more people are actively looking for you. It is stronger evidence than social engagement alone because the user has moved from receiving a message to expressing search intent. It is still correlational, so use disciplined controls.

    1. Record 30 to 60 days of baseline impressions and clicks for exact brand and specific product-name queries.
    2. Define the paid social launch or scaling period before looking at the result.
    3. Keep paid search budgets, bids, and nonbrand campaigns flat during the observation period.
    4. Record social spend and impressions alongside the branded query data.
    5. Compare branded search changes with the timing of social impression increases.
    6. Log other events that could create brand demand, such as a promotion or publicity, so you do not quietly credit social for an external spike.

    The basic lift calculation is:

    Branded search lift = (campaign-period volume – baseline volume) / baseline volume x 100

    Calculate impressions and clicks separately. Impressions indicate how often the tracked brand queries appeared, while clicks show how much of that expressed demand reached your site. If the baseline is zero, a percentage change is not meaningful; report the absolute increase instead.

    A corresponding increase during or shortly after heavier social exposure is evidence that social may be generating demand for search to capture. It is not proof that every additional query came from social. That stronger conclusion requires better isolation.

    Align revenue with the real conversion delay

    Same-day comparisons fail when buyers commonly wait between their first interaction and purchase. Determine the average time from first touch to conversion in your multichannel funnel data, then shift the search outcome window by that observed latency.

    If your own data shows a 14-day conversion lag, compare social exposure with search conversions roughly 14 days later rather than forcing a same-day relationship. The 14-day figure is an example, not a default. Use the delay found in your business, and declare it before judging the campaign so the lag is not selected merely because it produces a favorable chart.

    Examine both conversion volume and revenue. A search conversion increase can look impressive while producing little business value, and revenue without conversion context can be distorted by a small number of large orders. Reading both gives you a more stable view of delayed demand.

    Use matched geographic markets when causality matters

    When a budget decision requires stronger evidence, use a geographic holdout. Select two markets that are demographically similar and have comparable historical sales. Maintain the normal paid search program in both. Turn on or double social investment in the treatment market while blacking out or capping it in the control market for four to six weeks.

    Then compare how search conversion volume and efficiency changed in each market. Do not compare raw totals if the markets began at different sizes. Compare each market with its own baseline, then subtract the control-market change from the treatment-market change. That difference helps remove movement that affected both places.

    This design provides stronger incrementality evidence than a broken cross-device tracking path because it evaluates market-level business outcomes. Its credibility still depends on execution: the markets must be genuinely comparable, paid search must remain stable, and other major interventions must not be introduced in only one region during the test.

    Connect audience coverage, search demand, and revenue

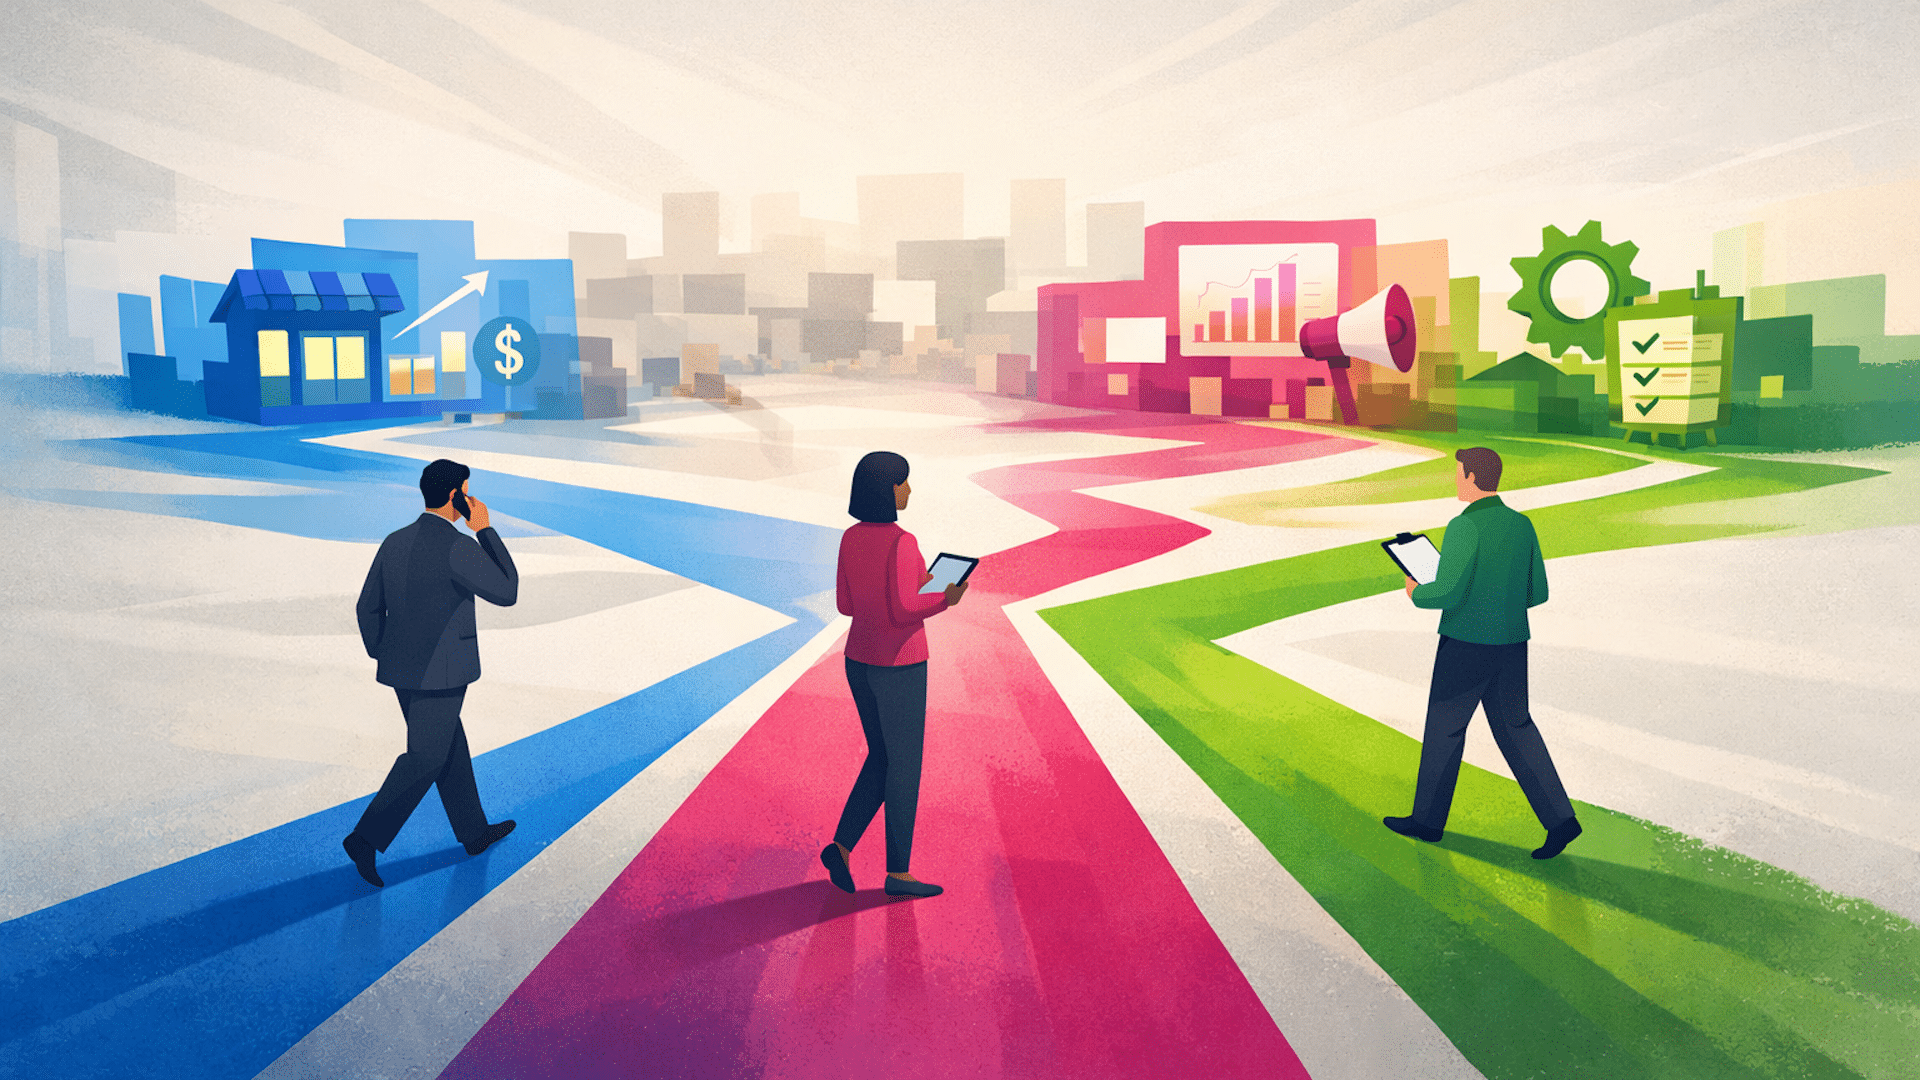
    Three connected scenes show diverse audiences receiving ads, moving toward a search symbol, and reaching shopping baskets and parcels at checkout.

    Your operating report should show how demand moves through the system, not place social and search on unrelated scorecards. Organize it into four connected layers:

    • Social inputs: spend and impressions by buyer state, message angle, campaign, and test market.
    • Audience distribution: reach and frequency by message group, with creative launch and refresh dates.
    • Search demand: impressions and clicks for exact brand and product-name queries.
    • Business capture: paid search conversions, revenue, and efficiency aligned to the observed sales-cycle delay.

    Read the report as a sequence. First ask whether the creative expanded reach without rapidly concentrating frequency. Then ask whether branded search moved. Finally, inspect whether search captured that intent after the expected delay. This keeps you from using a strong last-click result to excuse weak demand creation or using a social reach number to claim revenue that never appeared.

    The pattern determines the next action:

    • Frequency rises, reach stalls, and branded search stays flat: audit message duplication. Consolidate near-identical ads and introduce an angle for an uncovered buyer state.
    • Reach expands and branded search rises near the expected time: social is showing a demand-creation signal. Preserve the controls and continue to the revenue window before making a budget claim.
    • Branded search rises but search conversions do not: inspect demand capture. Check whether campaigns cover the relevant brand and product queries and whether the landing journey matches what the social creative promised.
    • Search conversions rise without a corresponding demand signal: do not automatically credit social. Look for changes in existing search demand, conversion rate, promotions, or another channel.
    • A matched-market test shows incremental search outcomes despite weak direct social return: evaluate social and search as one demand system rather than cutting social on last-touch performance alone.
    • The treatment market produces no meaningful incremental movement: the test has not supported the campaign’s demand-creation case. Verify the test conditions, then change the message, offer, audience-state coverage, or investment decision.

    Be equally careful with angle-level claims. If you launch several buyer-state messages at the same time in the same market, an account-level increase in branded search cannot tell you which angle caused it. Isolate an angle in a clean test when that distinction will change a material creative or budget decision. Otherwise, treat the lift as evidence for the portfolio.

    Write the measurement plan before launch. It should name the hypothesis, social exposure, primary demand metric, business outcome, expected delay, controls, test period, and decision rule. A prewritten rule prevents a common failure: moving between direct conversions, engagement, branded searches, and attributed revenue until one number makes the campaign look successful.

    Key takeaways for your next campaign cycle

    • More ads do not guarantee more audience coverage. Distinct messages aimed at distinct buyer states are what give Meta meaningfully different delivery signals.
    • Group creative by its argument, not its format. If more than two or three live ads make essentially the same pitch, consolidate them and fill an uncovered messaging gap.
    • Rising frequency plus stalled reach is a fragmentation warning, especially when new ads plateau quickly and fatigue accelerates.
    • Measure exact brand and product-name search impressions and clicks against a stable 30- to 60-day baseline.
    • Align search conversions and revenue with the conversion delay observed in your own funnel, not an arbitrary 24-hour window.
    • Use a four- to six-week matched-market test when the budget decision requires causal evidence rather than correlation.
    • Judge paid social and paid search as connected parts of demand creation and demand capture, while keeping their operational responsibilities visible.

    Before the next budget change, inventory every live creative by buyer state and core message. Then lock the branded-search baseline and write down the expected conversion delay. Those two actions will show whether you have an attribution problem, a creative coverage problem, or both.

    Your next review can then answer a more useful question than which platform claimed the sale: which messages expanded active demand, and how effectively did search capture it?

    References


  • How to Build Vibe-Coded SEO Tools That Earn Search Demand

    How to Build Vibe-Coded SEO Tools That Earn Search Demand

    You have found a search query that deserves more than another long page. The user needs to calculate, compare, filter, check, choose or generate something, and an interactive tool could finish that job faster than prose.

    An AI coding assistant can shorten the path from idea to working interface. It cannot decide whether the idea deserves a page, make unreliable logic trustworthy or turn a frustrating widget into a useful search result. Your advantage comes from choosing the right task, specifying it clearly and building the surrounding page as carefully as the tool.

    Key takeaways

    • Start with a repeatable user decision, not a keyword that merely contains the word calculator or generator.
    • Choose the smallest interface that removes a meaningful step from the user’s work.
    • Write the rules, inputs, outputs, edge cases and failure states before asking AI to generate code.
    • Keep the methodology, assumptions and useful supporting information visible in ordinary page content.
    • Verify the logic independently, then test accessibility, mobile use, performance, privacy and analytics.
    • Scale a tool format only after real search and usage data show that people can find and complete it.

    Choose a task that deserves an interactive result

    Vibe coding is the use of natural-language instructions to generate and refine software with an AI coding assistant. For an SEO team, its immediate value is a shorter prototyping loop. A marketer can describe a calculator, selector or comparison interface, inspect a working version and refine the behavior without waiting for every experiment to enter a development roadmap.

    That lower barrier creates a new problem: it becomes easy to publish tools nobody needs. A useful tool compresses a task. It accepts information the user already has, applies a defensible rule and returns an answer that changes what the user does next.

    Before you build, test the idea with these questions:

    1. What decision is the user trying to make? Write it as a sentence that ends with an action, such as choosing an option, checking likely eligibility or finding a date.
    2. Which inputs change the answer? If every visitor receives the same result, you probably need a concise answer page rather than a tool.
    3. Can you explain the transformation? You should be able to state how each input affects the result without hiding behind the AI that wrote the code.
    4. Is the result useful immediately? A tool should return the answer, show the important assumptions and make the next step obvious.
    5. Can you maintain the rules? If rates, deadlines, program criteria or product data change, someone must own those updates.

    The interface should follow the task. A calculator fits deterministic arithmetic. An eligibility checker fits a set of explicit conditions. A checklist fits a process with completion states. A calendar or countdown fits a date-based question. A dynamic table fits comparison across variables. A persona selector fits a situation in which different users care about different parts of the same offer. A generator fits a request for a novel output, provided you can keep the output relevant and safe.

    Calculators, checklists, calendars, countdown timers and generators have all worked as the central experience on search-focused tool pages. Their simplicity is part of the lesson. You do not need a miniature software platform when a focused control and a clear result eliminate the user’s immediate friction.

    Persona controls deserve special attention. A traveler arranging an airport transfer with children has different concerns from someone traveling alone. Tabs can let each visitor identify their situation and reveal the safety, convenience or flexibility information that matters to them. The control is useful because it resolves a real information-selection problem, not because tabs look more sophisticated than headings.

    Use your own search data to find comparable opportunities. Group Search Console queries by the task behind them. Look for repeated questions involving cost, quantity, dates, eligibility, compatibility, comparison or selection. Read the landing page for each group and identify the manual work it still leaves to the visitor. Then inspect the search results. A results page filled with explanations can expose an interface gap, but only when the query actually requires interaction.

    Reject an idea when the answer is static, the underlying data cannot be maintained, the result would imply certainty you cannot support or the tool would collect sensitive information without a necessary reason. Faster code generation does not improve a weak premise.

    Turn the idea into a behavior contract before prompting

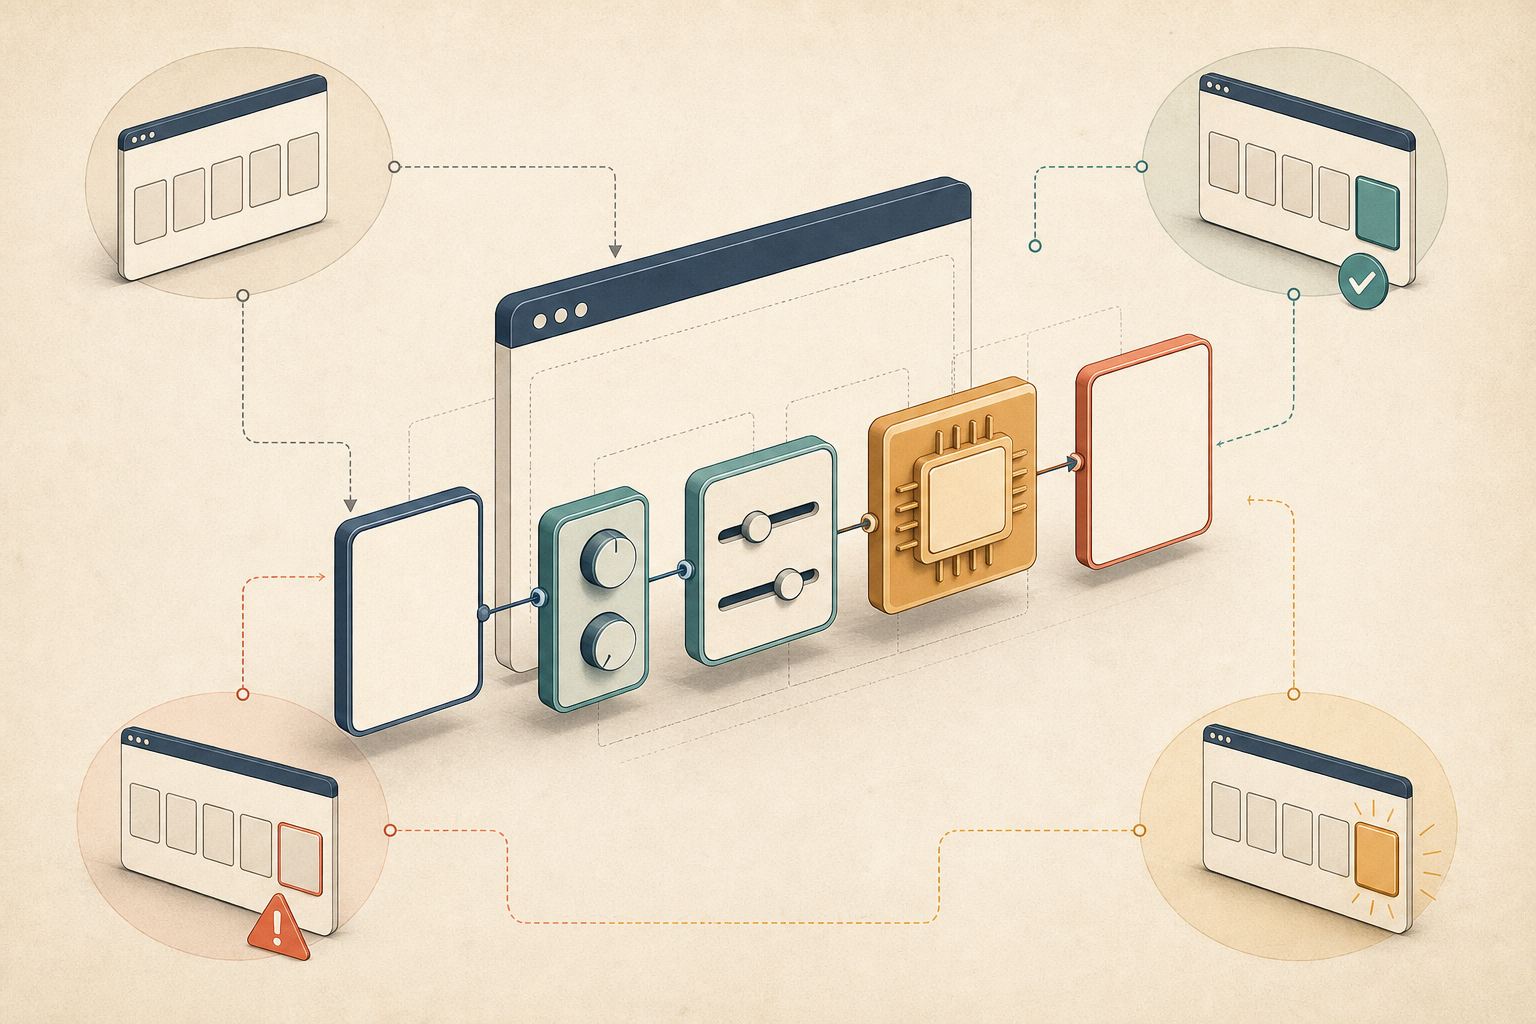
    An exploded blank web interface connects input, control, processing and result modules, surrounded by empty, valid, warning and completed states.

    A loose prompt such as “build an SEO calculator” delegates the product decision to a model that does not know your audience, business rules or tolerance for error. The first deliverable should be a behavior contract: a plain-language specification detailed enough that another person could predict what the tool will do.

    Include the following in that contract:

    • User and job: who is using the tool, the question they bring and the decision the result should support.
    • Inputs: every field, its format, unit, valid range, default state and whether it is required.
    • Rules: the calculation, decision tree, data mapping or content-selection logic in plain language.
    • Output: the primary answer, supporting explanation, assumptions, rounding behavior and next action.
    • Edge cases: empty fields, invalid values, unavailable combinations, boundary conditions and conflicting selections.
    • States: the initial view, active input, validation error, completed result, loading state and external-service failure where relevant.
    • Data ownership: where changeable rules come from, who approves them and how an expired rule will be detected.
    • Privacy boundary: which inputs stay in the browser, which are transmitted and what does not need to be collected at all.
    • Measurement: the user actions that indicate a start, successful completion, error or valuable next step.
    • Accessibility: labels, keyboard behavior, focus movement, error announcements and a result that does not depend on color alone.

    Now split generation into reviewable stages. Ask for the input model and core logic before visual polish. Review those rules. Ask for the smallest working interface. Review it on narrow and wide screens. Add validation and error states. Review them with a keyboard. Add tracking only after the event names and permitted data are clear. Small changes make it easier to see when a later prompt breaks behavior that already worked.

    Keep reference outcomes outside the generated implementation. Work through representative cases manually or with an independently reviewed calculation, record the expected result and compare the tool against it. If the model writes both the logic and the only test that declares that logic correct, the same misunderstanding can appear on both sides.

    Do not expose credentials in browser code or paste private production data into a coding prompt. Bring a developer into the loop when the tool requires authentication, sensitive data, payments, complex integrations or infrastructure that must handle material scale. Vibe coding changes prototype speed; it does not remove engineering, security or operational ownership.

    Build a page that remains useful without operating the tool

    The tool should be the main event, but it should not be the page’s only intelligible content. A person, crawler or answer system should be able to understand the purpose, method and limitations without guessing what happens after every possible interaction.

    A strong tool page usually follows this order:

    1. State the job. Use a short opening that identifies what the tool returns and the information the visitor will need.
    2. Present the interface. Keep labels explicit, put units beside their fields and avoid making users read a long preamble before they can begin.
    3. Explain the result. Show the answer in selectable text, name the assumptions and say what the user can do with it.
    4. Show the method. Describe the formula, rules or decision path in language a qualified reader can audit.
    5. Prevent predictable mistakes. Cover confusing inputs, common interpretation errors and cases the tool does not handle.
    6. Support the next step. Add the relevant walkthrough, comparison, application path or related resource.
    7. Expose maintenance context. When the tool depends on changeable criteria, identify what the criteria cover and make updates visible on the page.

    This combination can be more competitive than either a bare widget or a text-only page. An eligibility page that paired its interactive check with a transparent algorithm, application-error guidance, historical updates and a walkthrough reached the first page within three days in one documented launch. Treat that outcome as an example of what strong intent satisfaction can enable, not as a ranking timetable you can promise.

    Make the experience legible to search and answer systems

    • Give the page a stable canonical URL. Do not create indexable URLs for every input combination unless each state represents a durable search intent and has unique, maintainable value.
    • Keep the task definition, input meanings, method, assumptions and limitations in ordinary HTML content. Do not place all useful context inside a canvas, image or interaction-only state.
    • Write labels and explanations with explicit entities and units. “Monthly cost in Canadian dollars” is clearer than “Amount,” both for a visitor and for a system extracting meaning.
    • Return a result that can be selected, copied and understood out of context. A number without its unit, period or qualifying condition is not a complete answer.
    • Use accessible control semantics. Tabs should behave like tabs, form controls need associated labels, and keyboard focus should move predictably when an error or result appears.
    • Apply JSON-LD only when the selected type accurately describes the visible page. Keep names, descriptions and other marked-up claims consistent with what the visitor can verify. Structured data can clarify a page; it cannot repair misleading logic or missing content.
    • Link the tool from pages that already serve the same intent. A relevant guide can explain the problem and hand the calculation to the tool, while the tool can return users to the deeper explanation.

    Performance is part of the product decision. A simple formula does not need a heavy application shell. Load only what the interaction uses, reserve space for results so the layout does not jump and make external-service failures understandable. If a remote API is optional, decide whether a local fallback can still answer part of the user’s question.

    Verify logic and consequence, not just appearance

    A polished result can still be wrong. Build a test matrix before publication and repeat it whenever a rule, dependency or generated component changes.

    Test caseWhat to verify
    Empty stateThe tool explains what is required without showing a misleading default result.
    Invalid inputThe message identifies the field, explains the correction and preserves valid work.
    Boundary conditionThe rule changes at the intended point and the explanation matches the output.
    Representative inputThe result agrees with an independently established reference outcome.
    Conflicting selectionsThe interface prevents or clearly resolves combinations the rules do not support.
    Refresh, back and shared stateThe page retains, resets or reconstructs inputs according to the behavior contract.
    Keyboard and assistive useEvery control, error and result can be reached and understood without a pointer.
    Dependency failureThe page avoids false answers and gives the user a safe next step.

    If the output could influence a medical, legal or financial decision, do not let an AI-generated implementation become the final authority. Have the rules and wording reviewed by an appropriately qualified person, distinguish an estimate from a determination and state the limits beside the result. The specific downside is false confidence: an interface can make uncertain or incomplete logic look definitive.

    Measure task completion before you scale the format

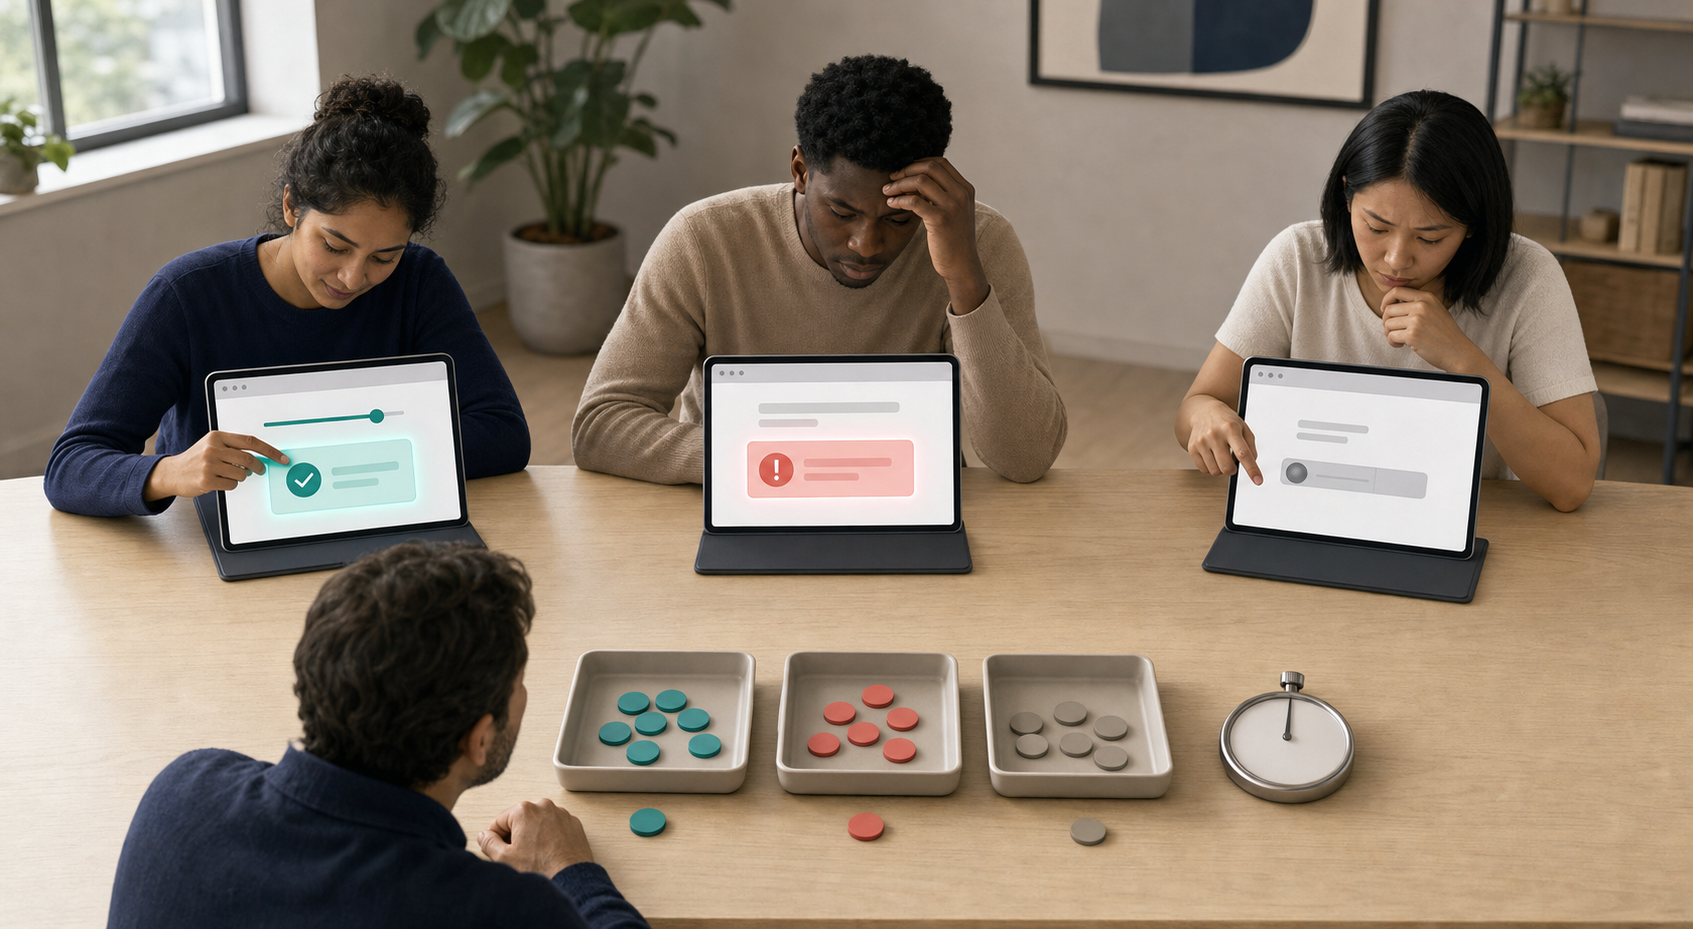
    A researcher observes three people testing a blank web tool, with one reaching a result, one seeing a warning and one hesitating at a control.

    Organic visits tell you that a page was discovered. They do not tell you whether the tool worked. Instrument the interaction as a short funnel: tool view, meaningful start, validation error, successful completion and result action. A result action might be copying the answer, opening a relevant application page, viewing a recommended option or continuing to a related guide.

    Do not send raw personal inputs into analytics simply because the interface makes them available. Record the minimum event information needed to diagnose the experience. For many tools, the event name, tool version, broad error type and completion state are more useful than the user’s exact values.

    Read search and product signals together:

    • Impressions increase but clicks do not: check whether the title and description make the utility clear and whether the page is appearing for the intended task.
    • Clicks arrive but starts are scarce: check query-to-page fit, the placement of the interface and whether the required inputs feel disproportionate to the promised answer.
    • Starts are healthy but completions are weak: inspect validation events, confusing labels, mobile controls, load failures and unnecessary fields.
    • Completions occur but the next step is ignored: confirm that the action logically follows the result. Do not force a commercial call to action onto an informational task.
    • Usage is strong but search discovery is weak: improve internal links, visible explanations and query alignment before rebuilding a tool users already understand.
    • Search traffic grows but rule maintenance slips: pause expansion and fix ownership. An outdated answer becomes more harmful as its audience grows.

    A dedicated category can become worthwhile once several tools serve related demand and each has a clear purpose. One documented category containing ten simple tool pages generated more than 5,000 clicks in two months, even with seasonal variation. That is a useful proof of possibility, not a portfolio benchmark. Your decision to scale should depend on your own query demand, completion data, maintenance cost and downstream value.

    When a format works, standardize the repeatable parts: the input shell, validation patterns, result component, methodology section, analytics events, accessibility behavior and update record. Keep the rules and explanatory content specific to each task. A shared component system speeds later launches; duplicated thin pages merely multiply maintenance.

    Start with one Search Console query family in which users must perform work after reading the current answer. Write the behavior contract, calculate the reference outcomes and build the smallest interface that completes that work. If people can find it, finish it and trust the explanation, you have a format worth extending.

    References

  • Unlock AI Success: Use Customer Personas to Gain Early Wins

    Unlock AI Success: Use Customer Personas to Gain Early Wins

    Most content out there tends to be too generic, making it less effective in AI search. I’ve discovered that using customer personas allows me to pinpoint real problems and step into the search space much earlier.

    Whenever buyers pose a question, my goal is to deliver a clear answer. That’s essentially the “They Ask, You Answer” (TAYA) framework, which thrives even in AI-driven discovery.

    Though it sounds straightforward, I’ve seen many teams struggle to anchor their approach. This typically results in generic questions that lead to generic content.

    This is problematic since AI is transforming search behavior, shifting from simple queries to in-depth, context-rich questions. The difference lies in the questions we choose to answer, and that’s where customer personas shine.

    The Problem with Generic Questions

    Chances are, both I and my competitors have tackled these generic questions already or could do so quite easily.

    The trap of generic questions occurs when marketing teams, including mine at times, begin brainstorming content ideas with broad topics like:

    • What is CRM software?
    • What is marketing automation?
    • What is warehouse management?

    While reasonable, these questions are not what real buyers ask. Real buyers ask questions based on their specific situations, such as:

    • “What CRM should a 10-person sales team use?”
    • “Why are leads slipping through the cracks in our marketing?”
    • “Why is our warehouse picking speed so slow?”

    This distinction is subtle but crucial. The second set of questions integrates a person and a problem, transforming the quality of the content I produce.

    Why This Matters More in AI-Driven Discovery

    With AI, buyers are asking detailed, context-rich questions, such as:

    • “I run a 15-person marketing team, and we’re struggling to track leads properly. What should we do?”

    The AI provides explanations, outlines solutions, and suggests vendors, essentially giving the buyer a consultation. My content’s job is to explain why a specific persona faces a specific issue, framing how it should be perceived.

    This positions me into the conversation earlier, increasing the likelihood of staying top of mind as the user’s understanding evolves.

    Imagine this scenario, using myself as the subject:

    • Marcus.
    • 50 years old.
    • Meeting old friends in Birmingham, UK.
    • Looking for things to do for the day.

    I might start with a broad question:

    • “I’m looking for some things to do with friends in Birmingham on the weekend. I’m 50, and I have some old friends visiting for a day. We’ll enjoy some beers, but need activities too.”

    The answers might include bars, food, and activity bars. An F1 gaming arcade could be suggested, sparking my interest since I enjoy games but not cars, which prompts my follow-up question:

    • “Ah, we all like games. What gaming arcades could you recommend?”

    The responses might highlight a pinball arcade in Digbeth.

    • “Pinball Factory in Digbeth sounds fun. What else is there to do around there, food- and drinks-wise?”

    This kind of dialogue allows me to refine my day’s plan perfectly for my friends.

    Being part of the conversation from the start helps shape the dialogue and boosts the chance of being included in the final decision.

    Personas Make TAYA Far More Precise

    With personas, I think like my customers, identifying the questions they might ask long before they reach my offerings.

    When I define a customer segment, I delve into that persona, understanding their problems and goals to think like them, which helps in crafting content that answers their early-stage questions.

    Instead of creating content for a vague audience, I focus on real people, addressing specific needs like, “The best day out in Birmingham for a group of 50-year-old gamers.”

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    This small shift often leads to valuable content, positioning me within meaningful conversations rather than competing on crowded commercial queries.

    A Simple Way to Uncover Better Questions

    No need for a complex persona framework. Often, a simple three-question exercise reveals the problems buyers seek to solve.

    For each persona, I ask:

    • What are they responsible for? Examples include sales targets, marketing leads, or warehouse operations.
    • What problems complicate that responsibility? Issues like missed targets or inefficient operations might arise.
    • What might they search for when facing these problems?

    Now, the questions I generate differ greatly from generic ones:

    Instead of saying: “What is CRM software?”

    I see questions like:

    • “Why are leads slipping through the cracks in our CRM?”
    • “What CRM should a small sales team use?”
    • “Why is our warehouse picking speed so slow?”

    These questions reflect real situations, providing the most substantial content opportunities.

    ‘They Ask, You Answer’ Works Better with Personas

    TAYA covers five key areas: cost, problems, comparisons, reviews, and best-of. These topics offer structure, but approached generically, they mirror what everyone else is doing.

    Generic questions like:

    • “How much does CRM software cost?”
    • “What problems do warehouse systems have?”
    • “HubSpot vs. Salesforce”
    • “Best CRM systems”
    • “Salesforce review”

    Can be transformed into more targeted questions:

    • “What does CRM cost for a 10-person sales team?”
    • “Why do my warehouse managers struggle with picking accuracy?”
    • “HubSpot vs. Salesforce for a small B2B marketing team”
    • “Best CRM for growing sales teams”
    • “Is Salesforce suitable for a mid-size sales organization?”

    Although the topic remains the same, the approach is tailored to the buyer’s reality. This makes the content more useful and aligns with AI interactions.

    Targeted questions might include:

    • “We’re a small marketing team struggling to track leads properly. What CRM should we use?”

    If my content already answers these persona-centered questions, it increases the chance of my explanations becoming part of their conversation.

    In short, personas enhance TAYA by transitioning from broad topics to specific questions associated with real problems, improving the content and aligning better with buyers’ needs.

    Start with the Problem, Not the Product

    A common misstep in content marketing is leading with the product. Buyers, however, start with a problem.

    By using personas, I anchor content in the buyer’s perspective rather than my own, ensuring the focus is on the customer.

    This change can mean the difference between influence and mere existence of my content.

    Where You Enter the Conversation Matters

    “They Ask, You Answer” is an effective framework when the questions I address are of high quality.

    Personas help in turning vague topics into precise problems, resulting in content that resonates with buyers and AI systems while earning their trust.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot