Tag: Budget Management

  • Google Ads Optimization Starts With Conversion Measurement

    Google Ads Optimization Starts With Conversion Measurement

    If campaign performance looks unstable, resist the next bid or budget change. Google Ads cannot optimize around the outcome you intended; it can only react to the conversion signal it receives. A missing purchase, duplicated form submission, or low-intent contact counted as a lead turns CPA and ROAS into confident-looking answers to the wrong question.

    Your first job is to make the signal trustworthy. Then you can use cross-channel reporting, search-term evidence, and negative keywords to improve performance without confusing a tracking change for a marketing win.

    Define the signal before you optimize the spend

    A conversion name such as “form submit” is not a measurement specification. It does not tell you whether the form was accepted, whether a duplicate was removed, whether the person was qualified, or whether the event represents a business outcome at all.

    For every action currently treated as a conversion, write down:

    • Business outcome: What changed for the business: a completed order, an accepted lead, a booked appointment, or another explicit result?
    • Completion condition: What observable event proves that outcome occurred? A button click alone rarely proves that the receiving system accepted the transaction.
    • Funnel stage: Is this a final outcome, a qualified intermediate action, or a diagnostic engagement signal?
    • Identity and deduplication: Which order, lead, or internal event ID prevents one outcome from being recorded twice?
    • Value: Does the action carry revenue, an approved proxy value, or no monetary value? Document the reason rather than silently assigning one.
    • System of record: Which backend, CRM, booking system, or commerce platform can confirm that the outcome was real?
    • Owner: Who investigates when the platform count and the operational record diverge?

    The correct measurement boundary depends on the surface. Where your account uses calls, lead forms, or message assets, the ad interaction may move contact intent closer to Google Ads. That does not make every tap, open, or connection a qualified lead. Decide what must happen after the interaction before it earns that label.

    Conversion pathUseful completion boundaryReconciliation evidence
    Website purchaseThe order is accepted, not merely startedOrder ID, status, value, and currency in the commerce system
    Website or lead-form submissionThe receiving system accepts a valid submissionLead ID and the later qualification or rejection status
    Call or messageThe contact meets your documented business rulePlatform reference or timestamp matched to a disposition in the operating system
    Micro-conversionThe engagement action actually occursAnalytics event used for diagnosis, not automatically treated as revenue

    Build a conversion hierarchy, not a bag of events

    Put final business outcomes at the top, qualified intermediate outcomes below them, and diagnostic events at the bottom. Use the highest-quality signal that can support the decision you are making. More event volume is not automatically better input. Promoting a page view or unverified click to “conversion” status may make an automated system look busier while moving it farther from revenue.

    If a campaign does not yet produce enough final outcomes for stable decisions, preserve the distinction. Report the lower-funnel result and the supporting signal separately. A volume constraint is useful information; relabeling weak intent hides it.

    Audit the conversion chain before interpreting CPA
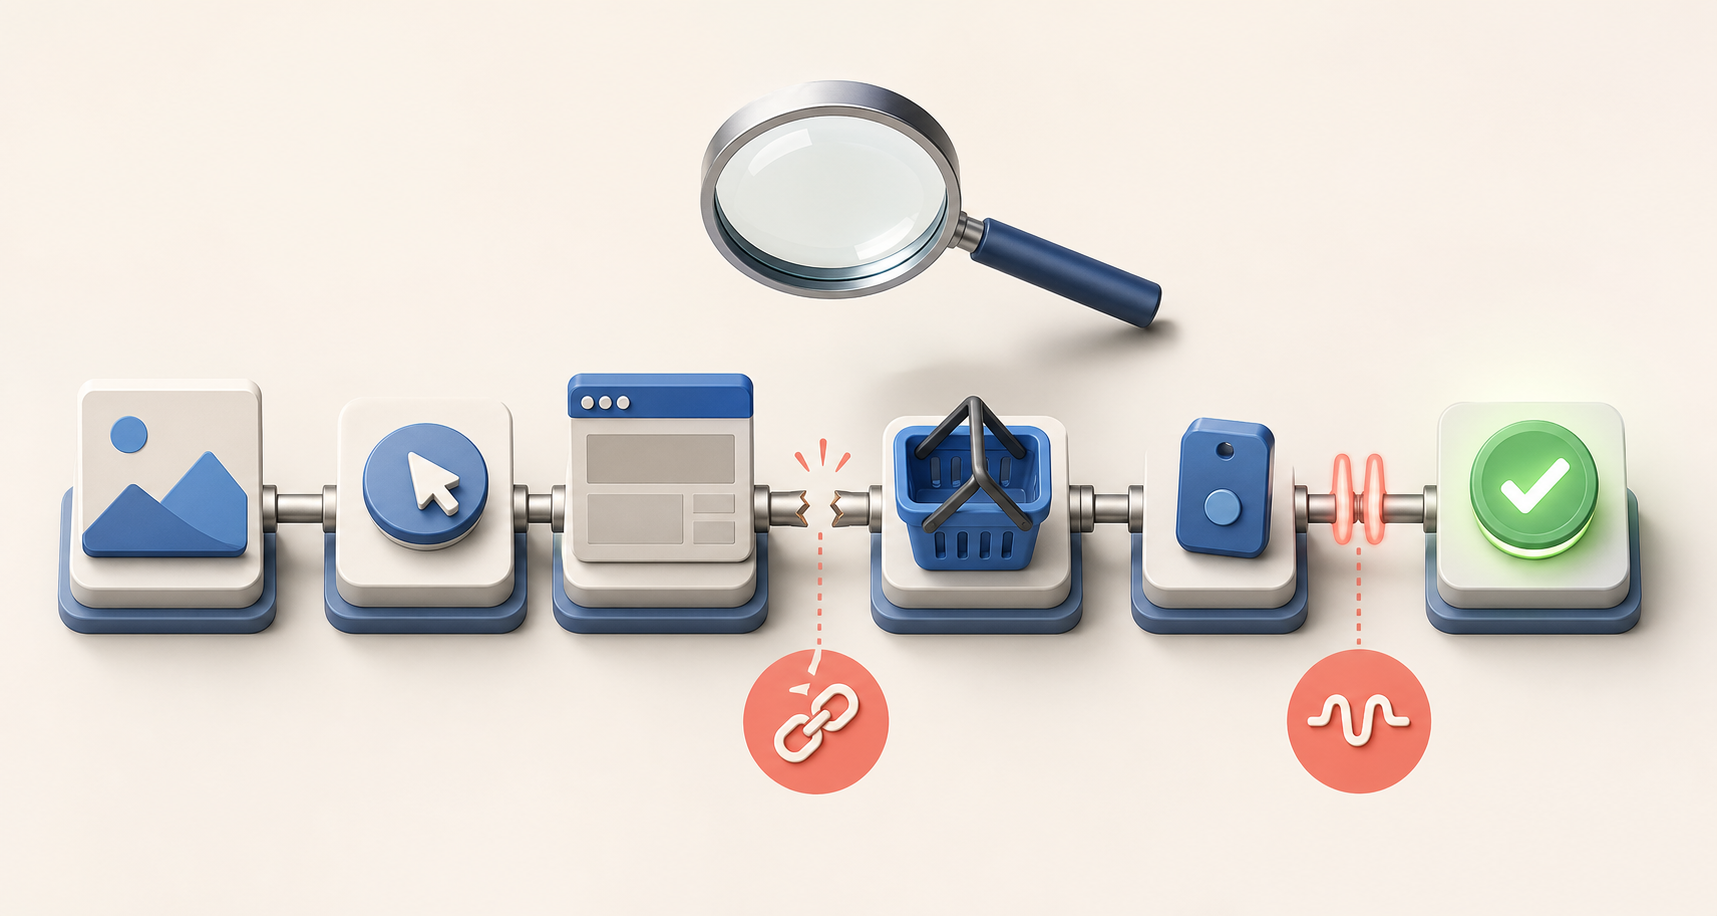
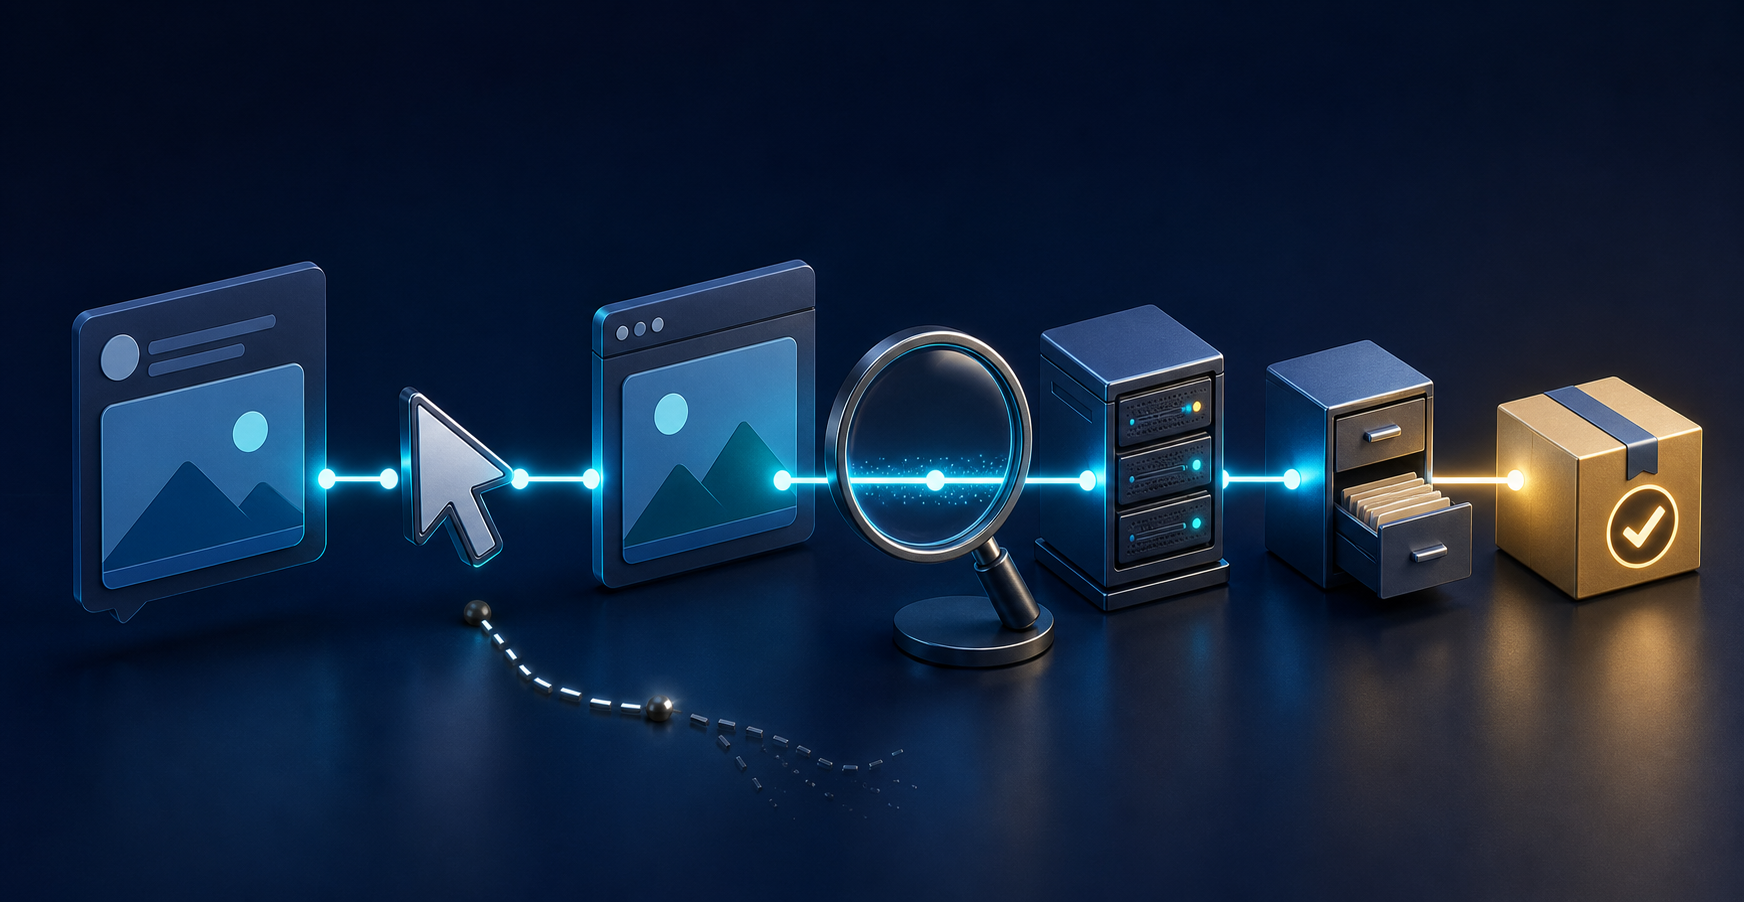
    An isometric chain connects an ad, click, landing page, customer action, tracking sensor, and verified conversion while a magnifying glass reveals a broken link and duplicate signal.

    A conversion can fail at several points between the customer’s action and the report. Checking only whether a tag fired leaves most of that chain untested. Audit the complete path in this order:

    1. Outcome: Complete the intended action and confirm that the business system accepted it.
    2. Trigger: Verify that the conversion condition occurred once, at the right moment, with the expected identifier and value.
    3. Transport: Check that the event moved through the applicable browser, tag, server, API, consent, and integration layers.
    4. Platform record: Confirm that the event appeared under the intended conversion action rather than a similarly named action.
    5. Reconciliation: Match the platform record to the order, lead, appointment, call, or message disposition in the system of record.

    Use a controlled test record and document its expected result before running it. For purchases or other actions that can create a charge, use an approved test or staging method. Do not place an unrecoverable live transaction merely to validate reporting.

    Your test matrix should cover the paths where implementation defects tend to hide:

    • Desktop and mobile completion paths.
    • Direct landing-page visits and the redirects used by campaign traffic.
    • Cross-domain steps, if the journey moves between domains.
    • Form success, validation failure, and repeated clicking.
    • Confirmation-page reloads and browser back-button behavior.
    • Each enabled call, form, or messaging route.
    • Accepted, rejected, cancelled, refunded, duplicate, and spam outcomes where those states affect business value.

    Record the test ID, timestamp and time zone, device or browser, conversion action, expected value, observed platform result, and backend ID. Use internal identifiers rather than personal data. This creates evidence that another person can inspect without repeating the transaction.

    Classify mismatches before fixing them. A missing conversion points toward an absent trigger, failed transport, incorrect mapping, consent behavior, or unavailable integration. A duplicate points toward repeated triggers or weak deduplication. A conversion recorded under the wrong action points toward naming or configuration drift. These defects require different fixes; a general “tracking issue” label is too vague to be actionable.

    Do not demand identical totals from systems that use different dates, time zones, attribution rules, inclusion rules, or value conventions. Align those definitions first. Then investigate the unexplained remainder. When you repair a material defect, preserve the old data, annotate the repair time, and define the first clean reporting window. Rewriting history without a documented method can make the next optimization decision less reliable than the last one.

    Use cross-channel reporting as a control view, not absolute truth

    Once your conversion definitions are stable, a unified reporting layer can reduce the time spent assembling channel exports. Google’s Analytics Data API can provide paid and organic conversion data in one programmatic view that mirrors the Conversion performance report in the Analytics interface.

    The capability is in alpha, and access is not universal. Verify eligibility for the exact Analytics property before making it a production dependency. If the property does not expose the feature, keep the same internal reporting contract and populate it from the available interface reports until API access arrives. That lets you improve the operating model without pretending an unavailable feature exists.

    Your reporting contract should make every row interpretable. At minimum, document the property or account, conversion-name mapping, channel classification, date and time-zone logic, attribution convention, value and currency treatment, extraction time, and the period in which late revisions are accepted. These are not decorative metadata. They explain why two legitimate reports can disagree.

    A unified view centralizes attributed conversion reporting; it does not prove that a channel caused the outcome. Attribution can move credit between touchpoints without changing the number of real orders or qualified leads. Read the data in layers:

    1. Confirm total business outcomes and value in the operational system.
    2. Confirm that Analytics received the intended conversion actions.
    3. Inspect how paid platforms recorded and attributed those actions.
    4. Use the cross-channel view to understand where credit was assigned.

    If channel credit changes while backend outcomes stay flat, investigate attribution, classification, or tracking before declaring growth. If backend outcomes increase while reported conversions do not, investigate measurement loss. If both move in the same direction and the definitions remain stable, you have a stronger basis for changing spend.

    Automation is most useful for surfacing exceptions: a conversion action disappears, a value field becomes empty, one channel changes abruptly, or the cross-channel total stops reconciling within your normal operating pattern. Let the pipeline find the anomaly. Keep the decision about bids, budgets, and exclusions attached to business context.

    Turn trusted conversion data into negative-keyword decisions
    An analyst adjusts filter gates that block irrelevant abstract search-query tokens while relevant tokens continue toward a conversion beacon and budget coins.

    Negative keywords become safer after measurement is credible. Before that point, a relevant query can appear unproductive simply because its outcome was missed or classified under the wrong action. Excluding it would reduce waste in the report while potentially blocking valuable demand in the market.

    Review each candidate search term by cause:

    • Clearly misaligned: The words indicate the wrong product, service, audience, location, or intent.
    • Relevant but early: The term belongs to the buyer journey but is being judged against an outcome it is unlikely to produce immediately.
    • Relevant and expensive: The term has consumed enough budget without producing the defined outcome.
    • Uncertain: The sample is sparse, the buying cycle is incomplete, or measurement quality is in doubt.

    Choose the negative match type according to the scope of the exclusion. Use negative exact match for a specific long-tail query, negative phrase match for a related query family, and negative broad match for words that identify a misaligned audience. Start with the narrowest scope that solves the problem. A broad exclusion can block adjacent demand, so export the current negatives and record the intended scope before making bulk changes.

    Your threshold should reflect the account’s job. A growth-focused campaign needs room to discover demand and can tolerate more exploration. One practical trigger is to review a query after it has spent more than three times the target CPA over 90 days without a conversion. Treat that as a decision trigger, not an automatic deletion rule: confirm tracking health, intent, and buying-cycle timing first.

    An efficiency-focused account can use a stricter, budget-based trigger tied to the amount you are willing to spend on one query without an outcome. A 30-day window can be too aggressive outside a short promotion. A 90-day window is a balanced starting point, while a 365-day view can be more appropriate for a long buying cycle. Keep the threshold and window together in the decision log; either one without the other is ambiguous.

    Competitor queries also need an explicit policy. Do not exclude them merely because they are competitor terms, and do not preserve them merely because automation might find a conversion. Decide whether that intent fits the offer, economics, and brand strategy. Then judge the terms under the same documented evidence rules as other traffic.

    Use this approval sequence for every material negative:

    1. Confirm that the relevant conversion actions were healthy during the evidence window.
    2. Classify the query’s intent and its alignment with the ad and landing page.
    3. Check spend, outcomes, target CPA, and buying-cycle maturity.
    4. Select exact, phrase, or broad scope deliberately.
    5. Record the query, scope, date, evidence window, reason, owner, and rollback condition.
    6. Review affected traffic after the change for both reduced waste and unintended demand loss.

    The search-terms report is not a weekly deletion queue. Review it regularly, but add negatives when the evidence and account objective support the decision. Calendar-driven exclusions can teach the campaign a narrower version of your market than you intended.

    Run an optimization cadence that protects the signal

    Separate measurement maintenance from performance optimization. If you change the conversion definition, negative-keyword scope, bid strategy, and budget in one cycle, the next report cannot tell you which change mattered.

    Decision layerQuestion to answerAction
    Measurement healthDid a defined action stop, duplicate, move, or change value?Repair and annotate the signal before interpreting performance.
    Business qualityDo orders, lead dispositions, and other backend outcomes support the platform signal?Correct qualification, deduplication, or value mapping.
    Demand qualityAre search terms aligned with the offer, ad, and landing page?Approve narrow, evidence-based exclusions or improve the message and destination.
    EconomicsDoes clean data support the target CPA, value, and budget decision?Change bids or budgets only after the earlier layers pass.

    Rerun a conversion smoke test after a site release, tag change, CRM integration change, form replacement, checkout update, or contact-route change. On each reporting refresh, check for missing actions, unexpected duplicates, empty values, naming drift, and abrupt channel changes. Review search terms and lead quality at a regular operating interval, but make exclusions only when the chosen evidence window has matured.

    Keep one change log for both measurement and media decisions. Each entry should contain the timestamp, owner, hypothesis, affected campaigns or actions, evidence window, expected metric movement, and rollback condition. The log gives you a clean way to distinguish a genuine performance shift from a new definition, delayed data, or implementation failure.

    Key takeaways

    • Define conversions as business outcomes with explicit completion, deduplication, value, and reconciliation rules.
    • Test the full path from customer action to backend record; a fired tag is only one link in the chain.
    • Use unified paid and organic conversion reporting as a control view, while preserving attribution and availability caveats.
    • Choose negative-keyword scope, aggression, and evidence windows according to the campaign’s growth or efficiency objective.
    • Repair measurement and validate business quality before changing exclusions, bids, or budgets.

    Before your next budget change, select one important conversion action and run it through the complete audit. Reconcile it to the business record, document the clean-data start time, and only then review the search terms consuming the most budget. That sequence gives the next optimization decision a signal worth trusting.
    References

  • ChatGPT Self-Serve Ads: A Practical Launch Framework

    ChatGPT Self-Serve Ads: A Practical Launch Framework

    If you have been waiting for a practical way to test ChatGPT advertising without entering a large, managed pilot, self-serve buying changes the conversation. The important question is no longer whether the channel sounds interesting. It is whether you can run a controlled test without mistaking novelty, clicks, or platform-reported conversions for profitable growth.

    You need a defined conversion, a defensible cost ceiling, a landing page that matches the ad, and tracking that reaches your order system or CRM. Put those pieces in place before you request access or allocate budget, and ChatGPT ads can be evaluated like a performance channel rather than treated as an open-ended experiment.

    What self-serve buying changes, and what it does not

    The announced rollout moves ChatGPT advertising beyond a tightly controlled pilot. Advertisers can pursue inventory through agency and technology partners or use a beta Ads Manager rolling out in the United States. The direct interface provides control over budgets, bids, creative uploads, and performance tracking.

    That lowers the operational barrier for smaller businesses and teams that could not justify a high-touch engagement. It does not mean access is universal. The product remains in beta, so confirm that your account and market are eligible before you build a launch plan around it.

    The addition of cost-per-click bidding is the most consequential change for performance marketers. The initiative began with CPM-based buying, where cost is tied to impressions. CPC lets you bid around visits instead. That is useful because ChatGPT interactions can occur while people are exploring a problem, comparing approaches, or moving toward a decision.

    A click is still an intermediate event. CPC is not CPA: paying for a click does not mean you are paying only when a sale, signup, or qualified lead occurs. You still own everything between the click and the business outcome, including page relevance, offer strength, conversion friction, follow-up, and measurement.

    Use exploratory, comparative, and decision-ready intent as a creative planning lens:

    • Exploratory intent: Explain the problem and the practical outcome your offer supports. Avoid demanding a large commitment before the visitor understands the value.
    • Comparative intent: State the relevant difference, qualification, or tradeoff plainly. Give the visitor enough evidence to judge fit.
    • Decision-ready intent: Make the offer, next step, price condition, or eligibility requirement easy to find.

    This is a messaging framework, not a claim that Ads Manager exposes individual prompts, conversation targeting, or query-level reports. OpenAI’s measurement model is aggregated, and advertisers do not receive access to individual conversations. Do not design targeting, attribution, or sales workflows that depend on identifying what a particular person told ChatGPT.

    Direct access is not the only route. Agency and technology relationships include WPP, Publicis Groupe, Criteo, and Adobe. If you buy through a partner, ask who owns the account, which bidding controls you receive, how conversion data is implemented, what reporting can be exported, how frequently it is delivered, and which fees sit outside media spend. A familiar partner workflow is useful only if you can still audit the campaign’s economics.

    Keep paid ChatGPT campaigns separate from organic AI visibility work. Ads buy exposure and traffic; AEO and GEO aim to improve how machines understand, retrieve, cite, and represent your content. Do not use paid click-through or conversion data as proof that organic ChatGPT visibility improved. Label the channels separately in analytics so paid traffic does not distort your AI-search reporting.

    Decide whether your business is ready to test

    Self-serve access makes launching easier, but it cannot supply the business logic that determines whether a campaign should run. Use the following readiness gate before committing spend:

    • You can name the primary conversion. Choose the event that represents value: a purchase, signup, or lead. If you optimize for a shallow action, such as a form start, keep the true business outcome visible in your reporting.
    • You know what that conversion is worth. Establish an acceptable acquisition cost from contribution margin, lead quality, close rate, retention assumptions, and fulfillment cost. Do not copy a target from another advertising channel without checking whether the traffic and sales process are comparable.
    • The destination can fulfill the ad’s promise. The landing page should repeat the core offer, explain who it is for, show relevant evidence, and provide the next step without forcing the visitor to reconstruct the argument.
    • You can connect ad activity to business records. Ads Manager reporting should be reconciled with web analytics and the system that records revenue or lead quality. Platform conversions alone cannot tell you whether a lead was qualified, duplicated, refunded, or closed.
    • You can afford an inconclusive test. A beta channel may not produce enough evidence to support a scaling decision. Treat the approved test budget as money at risk, not as revenue you expect the campaign to return on a fixed schedule.

    For a performance campaign, calculate a planning ceiling before choosing a bid:

    Maximum break-even CPC = acceptable cost per conversion multiplied by the expected landing-page conversion rate.

    Use the conversion rate from genuinely comparable traffic when you have it. If you do not, model a conservative range rather than borrowing the best rate from branded search, email, or returning visitors. The result is a break-even boundary, not an automatic bid recommendation. Your actual bid still has to reflect available controls, delivery, competition, and the evidence generated by the campaign.

    Lead-generation teams need an additional check. A campaign can appear efficient when it produces inexpensive forms but fail when sales rejects the leads. Define what makes a lead qualified, ensure the CRM records that status, and decide whether the beta’s Conversions API can receive the deeper outcome you want to optimize toward. If it cannot, use the deeper event for business evaluation even if campaign optimization must rely on an earlier event.

    Wait to launch if nobody owns the landing page, conversion implementation, or lead follow-up. Buying traffic before those responsibilities are assigned creates a predictable dispute: the ad platform shows activity, analytics shows something different, and the sales team sees outcomes that neither report explains.

    Build the first campaign around a falsifiable hypothesis

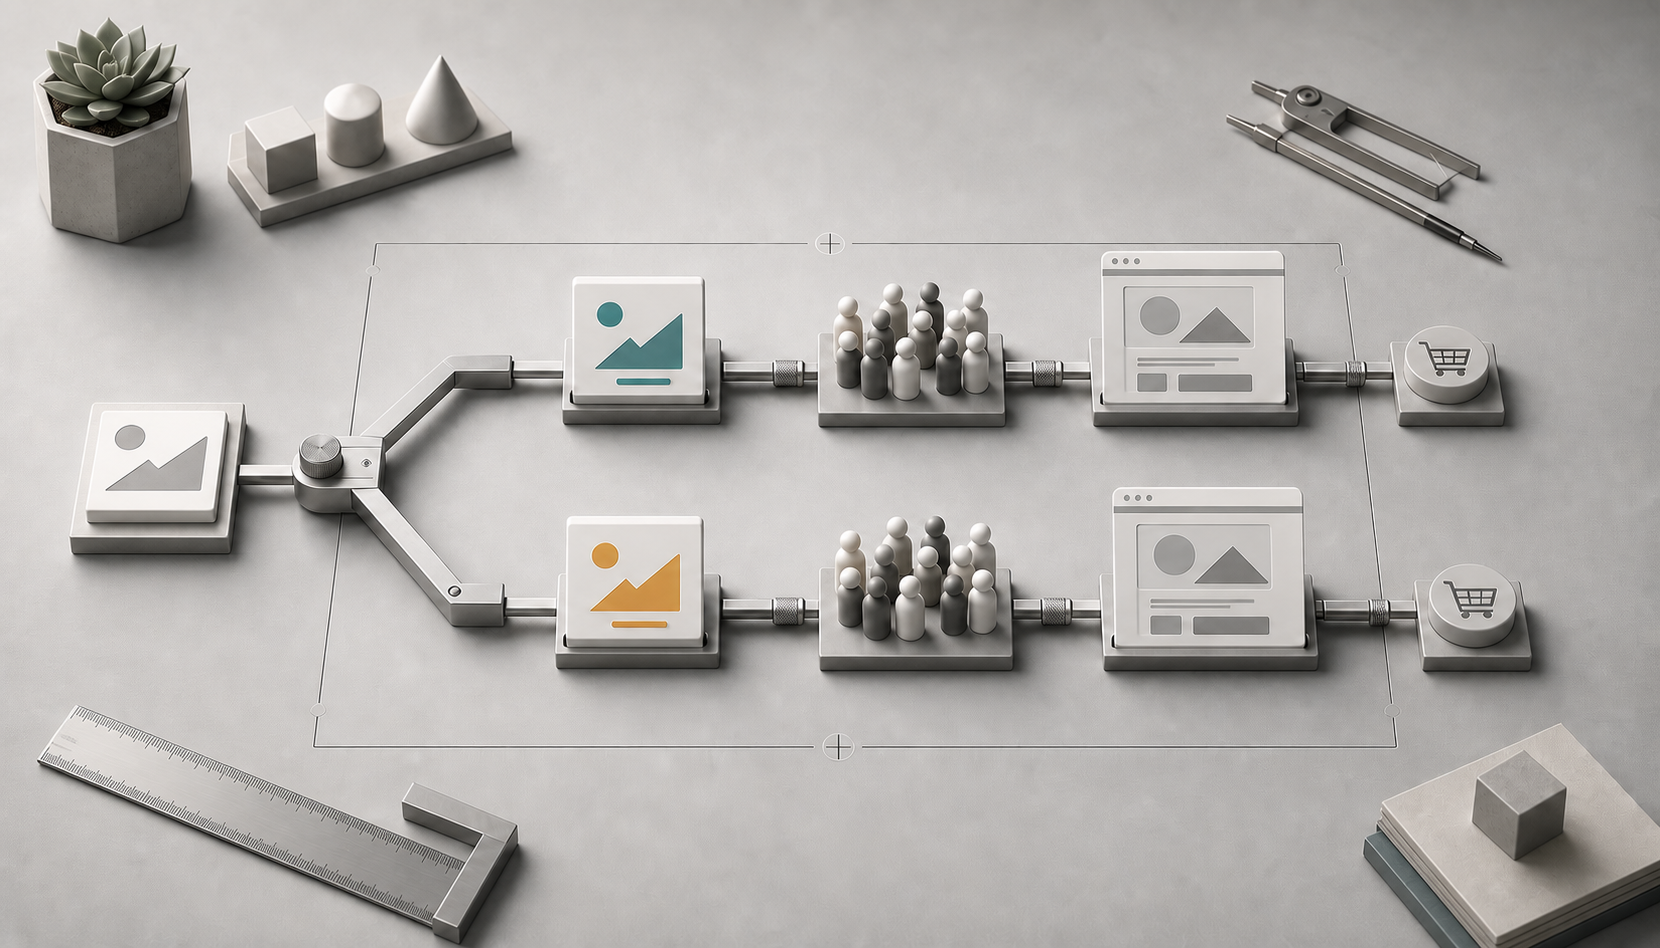
    A tabletop testing setup splits one ad concept into two parallel audience and landing-page paths with a single visual variable changed.

    Your first campaign should answer a narrow business question. Write the hypothesis before opening Ads Manager:

    For people in a defined decision state, this offer and message will produce this conversion at or below this acquisition-cost ceiling.

    That sentence prevents several common mistakes. It keeps brand awareness from being judged by last-click sales, stops a lead campaign from optimizing toward unqualified form fills, and gives you a reason to pause when the economics do not work.

    1. Choose a single primary outcome. Purchases, signups, and leads require different pages, event definitions, and follow-up. Pick the event that matches the offer instead of mixing several goals into one test.
    2. Define the decision state. Decide whether the message is helping someone understand a problem, compare alternatives, or act. Use that decision in your creative brief and landing-page structure. Apply only targeting options that are actually available in your beta account.
    3. Write a specific promise. State the result, the relevant qualifier, and the next step. Avoid copy that merely announces your brand or repeats broad AI terminology. The visitor should know why the click is worth making.
    4. Prepare controlled creative variants. Vary the claim, proof, or call to action separately so you can interpret the result. If every element changes at once, a winning variation does not tell you what to retain.
    5. Build message continuity after the click. The landing page headline should resolve the promise made in the ad. Put the decision-critical facts, constraints, evidence, and action on the page rather than hiding them behind generic navigation.
    6. Set stop and scale rules. Pause immediately if conversion tracking fails. Stop and diagnose when the approved test budget is exhausted without evidence that supports the hypothesis. Scale only when verified outcomes remain within the acquisition-cost ceiling.

    Do not invent a universal testing threshold. The amount of evidence you need depends on conversion frequency, normal sales-cycle length, the cost of a false positive, and how much variation exists in lead or order value. Record the threshold you will use before seeing the result so a promising-looking dashboard does not move the goalposts.

    Use a stable campaign naming and URL-tagging convention from the start. A workable UTM pattern is utm_source=chatgpt, utm_medium=paid_ai, a campaign value tied to the offer, and a content value tied to the creative variant. Record the exact values in the campaign brief. Consistency matters more than the label itself because it lets analytics, CRM, and finance records join the same test.

    Your SEO and GEO work should support clarity on the destination page without being confused with ad configuration. Use visible, accurate facts and structured data that matches the page. JSON-LD can help machines interpret supported entities and attributes, but it is not a ChatGPT ad-targeting control, conversion tag, or substitute for persuasive page content.

    Make measurement trustworthy before optimizing bids

    An illuminated tracking path connects an ad interaction to a landing page, server, customer record, and verified order package.

    ChatGPT advertising is adding pixel-based tracking and a Conversions API for actions such as purchases, signups, and leads. The pixel can capture supported browser-side events. A Conversions API can pass supported events from a server, commerce system, or CRM. Check the beta documentation available in your account before implementation because event fields and diagnostics may evolve.

    If you use both methods, verify how duplicate events are handled before sending the same conversion through each path. Two tracking methods should improve resilience, not turn one order into multiple conversions. Test event names, identifiers, values, currency fields, timestamps, and final status against the platform’s current specification.

    Build the measurement chain from the business outcome backward:

    • Business system: The order platform or CRM records revenue, qualification, cancellation, refund, or closed status.
    • Analytics: The session retains the expected campaign parameters and records the relevant onsite actions.
    • Conversion integration: The pixel or Conversions API sends the supported event with the correct value and status.
    • Ads Manager: The campaign reports clicks, spend, and attributed conversions using the attribution settings shown in the account.

    Run a validation pass before meaningful spend begins. Confirm that the landing URL works through every redirect, UTM parameters survive navigation, consent behavior is understood, the intended event fires only when its real condition is met, and the backend stores the campaign identifiers you need. Save evidence of the test so later discrepancies can be compared with a known-good implementation.

    Expect the systems to disagree at times. Attribution windows, consent choices, browser restrictions, server timing, duplicate handling, and later changes to an order or lead can all create differences. Reconcile the direction and magnitude of the data rather than forcing a false impression of perfect identity. The privacy model also means you should not expect a conversation-level customer trail: reporting is aggregated, and individual ChatGPT conversations are not exposed to advertisers.

    Read early results in a fixed order: tracking integrity, visitor behavior, conversion quality, and only then media efficiency. The pattern in the data tells you where to look first:

    Observed patternFirst interpretation to testAction
    Ads Manager records clicks, but analytics sees few matching sessionsThe click path, redirects, campaign parameters, consent handling, or analytics filters may be breaking attributionValidate the final URL and session tracking before changing bids or creative
    Analytics and the backend record completions, but Ads Manager records few conversionsThe pixel or Conversions API event may be missing, malformed, delayed, or duplicated incorrectlyRepair and retest the conversion integration before judging campaign performance
    Clicks arrive, but visitors do not reach meaningful onsite actionsThe creative may be attracting curiosity, or the page may not continue the ad’s promiseTighten the qualification in the message and remove landing-page mismatch
    Platform conversions look efficient, but sales rejects the leadsThe optimized event is too shallow to represent business valueReport qualified outcomes from the CRM and use a deeper supported event when possible
    Verified conversions remain within the cost ceilingThe campaign is a candidate for controlled expansionIncrease exposure gradually and keep the offer, page, and measurement stable while evaluating the change
    Delivery remains limitedCampaign settings, bid or budget constraints, access, or available inventory may be limiting the testCheck account diagnostics and settings before concluding that demand is absent

    Do not respond to weak conversion economics by raising the bid first. Confirm that measurement works, inspect the promise-to-page transition, and check whether the recorded conversion represents real value. Increase bids or budgets only when account data indicates delivery is constrained and the verified acquisition economics can absorb more traffic.

    Document every material change with its effective time, including bid, budget, creative, destination, event definition, and attribution setting. If several variables change together, the next reporting period may look different without telling you why.

    Key takeaways

    • ChatGPT’s self-serve Ads Manager is a U.S. beta, so verify access and current account controls before planning a launch.
    • CPC bidding makes traffic easier to buy and evaluate, but a paid click is not a sale, qualified lead, or profitable customer.
    • Write the campaign hypothesis, conversion definition, cost ceiling, test budget, and stop rule before spend begins.
    • Use a matching landing page and consistent campaign parameters so Ads Manager, analytics, and backend outcomes can be reconciled.
    • Pixel and Conversions API tracking improve measurement, but data is aggregated and does not expose individual conversations.
    • Keep paid ChatGPT performance separate from organic AEO and GEO visibility. Neither should be used as proof that the other improved.

    Your next move is to write the hypothesis and acquisition-cost ceiling, then trace the conversion from the landing page to the final business record. If either remains undefined, keep the budget closed. If both survive that check, you have the basis for a controlled beta test and a clear decision when the results arrive.

    References

  • A Practical Paid Media and Cross-Channel Measurement Plan

    A Practical Paid Media and Cross-Channel Measurement Plan

    Your paid social dashboard says the campaign worked. Paid search gets credit for the eventual conversion. Direct traffic also rises. If you evaluate each channel in isolation, you can end up paying three platforms for the same story or cutting the channel that started it.

    You need an execution plan that separates platform-reported performance from incremental business impact. That means assigning each channel a job, preserving a measurable journey, testing a specific causal claim, and deciding in advance what evidence will change the budget. AI-driven changes have made paid media platforms more complex, but they haven’t removed the need for this discipline.

    Measure the customer journey, not a stack of channel totals

    A platform conversion total answers a narrow question: which conversions can this platform claim under its attribution rules? It does not tell you how many conversions would have disappeared without the campaign. That second question is incrementality, and it is the one that should guide a material budget decision.

    Cross-channel journeys make the distinction important. A paid social impression may introduce the brand. The person may later search for it, click a paid search ad, and convert on the site. In that journey, social created or accelerated demand, search captured it, and the website closed it. Giving the entire outcome to the last interaction understates social. Adding every platform’s claimed conversions overstates the total.

    Paid social can build familiarity that later appears in branded search volume, paid search click-through rates, and conversion rates. Those effects are plausible hypotheses, not universal laws. Some businesses will see a meaningful relationship; others will see little or none. Your measurement design has to distinguish the two.

    Start by assigning a role to every campaign. Use roles such as demand creation, demand capture, remarketing, registration, or conversion. Do not let every channel claim to be a direct-response closer merely because its interface reports conversions. The role determines which signals deserve attention and which signals are only diagnostic.

    Key takeaways

    • Platform attribution shows claimed credit; an incrementality test estimates what the advertising caused.
    • Do not add channel-reported conversions together unless you have deduplicated the underlying business events.
    • Give each campaign a defined job in the journey before selecting its success metrics.
    • Judge an awareness campaign partly by downstream demand signals, not only by its last-click conversions.
    • Use a control whenever the budget decision depends on causality rather than reporting convenience.

    Define the decision and hypothesis before changing spend

    A useful paid media test begins with a budget decision, not a dashboard. Write down what you might do differently after the result: increase social investment, reduce it, move money between audiences, protect branded search coverage, or change the registration journey. If no possible result would alter an action, you are monitoring rather than testing.

    Next, turn the decision into a falsifiable hypothesis. A practical format is: changing a named campaign variable for a defined audience or geography will change a specified business or downstream channel outcome relative to a control.

    For example: increasing paid social exposure in selected markets will increase branded paid search demand relative to comparable markets where social spend remains unchanged. The mechanism is greater brand familiarity. The primary signals are branded search impression and click volume. Search click-through rate and conversion rate are supporting signals because familiarity may affect both, but they should not quietly replace the primary outcome after the test begins.

    Your campaign brief should record the following before launch:

    • Business decision: the budget or execution choice the result will inform.
    • Intervention: the exact variable you will change, such as social spend, audience exposure, creative, or destination.
    • Expected mechanism: why that change should affect customer behavior.
    • Primary outcome: the business or downstream channel signal that directly tests the hypothesis.
    • Supporting metrics: signals that help explain the result without redefining success.
    • Guardrails: delivery, cost, lead quality, or customer-experience indicators that could make an apparent win unacceptable.
    • Control: the audience, geography, or other comparable group that will not receive the change.
    • Decision rule: what pattern of evidence would justify scaling, stopping, or running a narrower follow-up test.

    This record prevents a common failure: finding an attractive metric after launch and treating it as the goal. Engagement can explain delivery. It cannot substitute for registrations when registrations were the reason for the campaign.

    Build one observable journey across channels and destinations

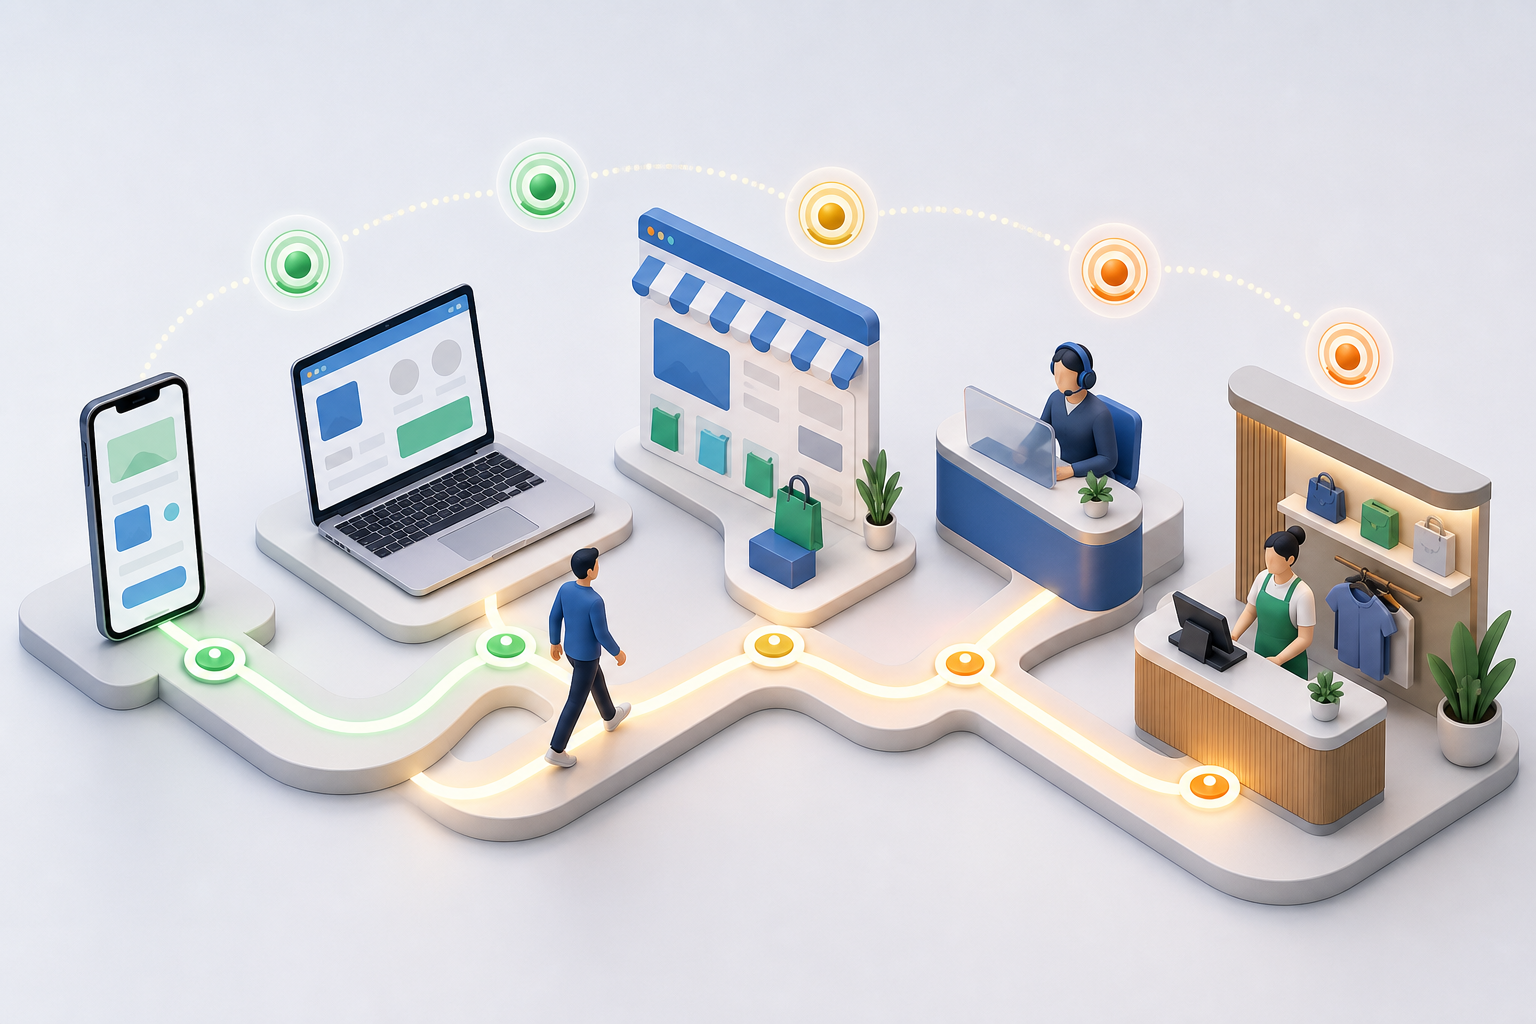
    An isometric customer journey connects a phone, laptop, online store, call center, and retail counter with one illuminated path.

    Cross-channel measurement breaks when execution creates different definitions of the same customer action. If paid social counts a form submission, paid search counts a confirmation page, and the CRM counts an accepted lead, the totals are not comparable. Establish the business event first, then map each platform signal to it.

    Use a shared campaign taxonomy across ad platforms, analytics, landing pages, and downstream reporting. The taxonomy should let you identify the channel, campaign, audience, geography, creative, offer, and test group without decoding inconsistent names. Preserve those values through the conversion path where your systems allow it. The aim is not a longer campaign name; it is a reliable join between spend, exposure, site behavior, and the final business event.

    Off-platform destinations give you more control over that join. LinkedIn’s off-platform Event Ads can direct clicks to an external webinar platform, landing page, or livestream site while Campaign Manager retains platform performance reporting. The format can support awareness, engagement, traffic, or lead-generation objectives and includes event details such as its date and format.

    That flexibility does not make measurement automatic. Before sending event traffic to your site, verify the complete path:

    1. Open the live ad destination and confirm that campaign and test identifiers survive the redirect.
    2. Complete a test registration and verify that analytics records the same completion event used in business reporting.
    3. Confirm that duplicate page loads or repeated form submissions do not create multiple business conversions.
    4. Check that the registration reaches the system where lead quality or attendance will eventually be evaluated.
    5. Separate campaign clicks, landing-page sessions, completed registrations, qualified registrations, and attendance. Each represents a different stage and should not be relabeled as another.
    6. Document any platform-reported conversion window or modeled result that differs from your analytics definition so stakeholders do not compare unlike totals.

    If you compare a native platform experience with an external destination, treat the destination as part of the intervention. A difference in registration rate may reflect page speed, form length, trust, tracking loss, or the handoff itself rather than the ad format alone. Keep the audience, offer, and conversion definition as stable as the platform permits, then examine the full path from click to qualified outcome.

    Use a geographic split when channels influence one another

    Two similar miniature city regions sit on opposite sides of a river, with media signals illuminating only one region.

    A simple before-and-after comparison is weak evidence for a cross-channel effect. Seasonality, promotions, news, competitor activity, and changes in search demand can move at the same time as your spend. A geographic split improves the comparison by exposing selected markets to the change while comparable markets act as controls during the same period.

    A defensible geographic paid social test requires more than dividing a map. Match treatment and control markets on factors that could affect the outcome, including income characteristics and region type. Check for local television campaigns, televised sports activity, regional promotions, distribution differences, or other events that reach one group but not the other. Either redesign around a major imbalance or document it before interpreting the result.

    Then protect the test from delivery constraints:

    • Confirm that the treatment budget can create a real difference in social exposure. A nominal budget increase that does not change delivery is not a meaningful intervention.
    • Keep the non-tested parts of the media plan as stable as practical across treatment and control markets.
    • Inspect paid search impression share before and during the test. If search is capped by budget or rank, added demand may not produce more paid search clicks.
    • Use the same conversion definition and reporting window in both groups.
    • Record campaign edits, outages, landing-page changes, promotions, and regional anomalies while the test runs.
    • Compare the change in treatment markets with the change in control markets. Do not infer lift merely because treatment improved from its own earlier level.

    Testing a reduction in spend can be valid when social investment is already substantial, but the financial consequence is real: you may suppress demand in the treatment markets. Define the exposure change, affected markets, stopping conditions, and recovery plan before launch. If you cannot tolerate the downside, test an increase in selected markets instead.

    If you lack comparable geographies, sufficient delivery, or trustworthy outcome data, say that the test is inconclusive. An attribution model can help describe journeys, but changing the model does not create a control group and should not be presented as proof of incrementality.

    Read the result as a system, then make one budget move

    Begin evaluation with the primary outcome written into the brief. Then use supporting metrics to explain why it moved or why it did not. This order matters. It stops an improvement in an easy platform metric from masking a flat business result.

    QuestionUseful signalMisreading to avoid
    Did social create more brand demand?Change in branded paid search impressions and clicks in treatment versus control marketsJudging the effect only by social last-click conversions
    Did familiarity change search response?Brand and non-brand paid search click-through and conversion ratesCalling every rate change causal without a control
    Could paid search capture added demand?Impression share and budget statusReading flat search clicks as proof that demand did not change when delivery was constrained
    Did the path between channels change?Visitor overlap, conversion touchpoints, and attribution-model comparisonsTreating descriptive journey data as an incrementality test
    Did an external event journey work?Campaign clicks, site sessions, registrations, qualified registrations, and attendanceOptimizing to engagement while losing registration quality after the click

    Expect the supporting metrics to disagree occasionally. Reducing social spend can produce mixed conversion-rate changes across regions even when overall conversions decline. A decline in branded search volume may strengthen the case that social supported demand, while a rising conversion rate may simply show that the remaining visitors had stronger intent. The conversion rate alone would tell the wrong story.

    When the result looks unusually large, investigate before scaling. Check tracking releases, site changes, inventory, promotions, search budgets, regional events, and changes to platform delivery. An anomaly is a reason to inspect the mechanism, not an invitation to replace the original hypothesis.

    Finish with one of four decisions: scale the tested change, reverse it, keep the current allocation, or run a narrower follow-up test. State which evidence drove the choice and which uncertainty remains. Avoid changing audiences, creative, bids, destination, and budget simultaneously after a test; you will lose the ability to learn which adjustment mattered.

    For your next planning cycle, choose one disputed budget question and write its hypothesis before opening an ad platform. Lock the conversion definition, identify a credible control, verify the end-to-end path, and agree on the decision rule. That turns cross-channel measurement from a reporting exercise into a repeatable way to allocate spend.

    References

  • How to Audit Campaign Controls Before You Optimize Spend

    How to Audit Campaign Controls Before You Optimize Spend

    Your campaign can look more efficient while becoming harder to control. Spend may be compressed into fewer active days, conversion signals may be incomplete, and a polished dashboard may show activity without giving you the controls needed to explain or stop it.

    If performance changes without a clear bid, audience, or creative change, audit the control layer first. You need to know what the platform is allowed to do, what data its optimizer can see, and whether your reports describe the same system you configured.

    Key takeaways

    • Budget, schedule, consent, optimization, and reporting are separate controls. Changing or validating one does not validate the others.
    • A restricted ad schedule may concentrate spending rather than reduce the campaign’s monthly spending limit.
    • Consent diagnostics should help you locate missing or inconsistent signals. A consent rate is not a target to maximize at the expense of genuine user choice.
    • A dashboard is not a mature control system unless you can inspect state, enforce changes, verify their effects, and reconstruct who changed what.
    • Paid placement in an AI interface and earned visibility in a generated answer require separate attribution and reporting.

    Audit the whole control chain before touching bids

    Campaign optimization is usually treated as a bidding problem. In practice, bidding is only one link in a chain. The platform first determines whether an ad is eligible, then how much it may spend, which signals it can use, what decision automation should make, and what evidence you get afterward.

    A weakness anywhere in that chain can produce a misleading result. A schedule can alter the concentration of spend. A consent implementation can reduce observable conversions. A reporting delay can make a stable campaign appear volatile. Raising or lowering a bid before resolving those conditions adds another variable without answering the original question.

    Control layerQuestion to answerEvidence to record
    Business constraintWhat outcome, total cost, or operational load can you accept?Approved spending ceiling, capacity limit, and stop condition
    EligibilityWhen is the campaign allowed to enter auctions?Active days and hours, plus the business reason for each restriction
    DeliveryHow may the platform allocate spend while the campaign is eligible?Budget values, bidding mode, spending caps, and documented pacing behavior
    SignalWhich conversions and consent states can the optimizer observe?Conversion definitions, consent diagnostics, and coverage by relevant dimension
    ObservationCan you explain what happened after delivery?Reporting latency, available breakdowns, exports, attribution settings, and change history

    Run the audit in that order. Starting with reports is tempting, but a report cannot tell you whether the configured business constraint was correct. Starting with bidding is worse because the optimizer may be responding rationally to a budget, schedule, or signal state you did not intend.

    1. Write down the campaign’s intended result and its hard constraint. Separate a performance target from a limit the platform must not cross.
    2. Capture the current schedule, budget, bidding mode, conversion actions, consent state, targeting, and exclusions. Use actual settings, not what the launch plan says should be configured.
    3. Translate settings into effective exposure. For example, calculate the monthly spending ceiling and inspect how much delivery could be compressed into eligible periods.
    4. Check whether the optimizer receives the signals you expect across apps, platforms, regions, and traffic sources. Treat gaps as unresolved until you have distinguished user choice from an implementation problem.
    5. Verify that important controls are enforceable. A pause button, budget edit, or exclusion is useful only if you can confirm its scope, timing, and effect.
    6. Record each change with the old value, new value, timestamp, reason, expected effect, evaluation window, and stop condition. Where practical, avoid changing another layer before the first change can be evaluated.

    This gives you a baseline that optimization can build on. Without it, every performance movement invites a new theory, and several contradictory theories may fit the same aggregate chart.

    Scheduled campaigns need a spend-concentration audit

    A hand adjusts a scheduling gate above a blank calendar grid where glowing budget tokens are concentrated into only a few active tiles.

    A budget limits spending; a schedule limits eligibility. Those settings may feel interchangeable when a campaign runs only on selected days or hours, but they answer different questions.

    Under Google’s scheduled-campaign pacing model, a campaign can pace toward its full monthly spending limit even when its ads are not eligible every day. Disabled days remain disabled, but the system has more reason to capture available demand during the periods that remain open.

    The stated limits make the exposure calculable: the monthly spending cap remains 30.4 times the average daily budget, while spending on an individual day can reach up to twice that daily budget. These are ceilings, not promises about what the campaign will spend.

    The practical correction is simple: do not assume that fewer eligible days will produce a proportionally smaller monthly bill. If you intend to reduce total exposure, set the budget to reflect that intention. Keep the schedule focused on when the business can serve demand or when traffic is valuable.

    • Find every non-continuous schedule. Include campaigns limited to particular weekdays as well as those restricted to certain hours.
    • Write down why the restriction exists. A schedule tied to staffing, inventory, response time, or lead quality is an operational guardrail. Do not remove it merely to smooth a spending chart.
    • Calculate the monthly ceiling. Multiply the average daily budget by 30.4, then compare that amount with the total monthly exposure you actually approved.
    • Check the active-day boundary. Ask whether spending up to twice the average daily budget on an eligible day would create a cash-flow, inventory, or service-capacity problem.
    • Review eligible periods directly. Monthly averages can hide concentrated delivery. Inspect spend, conversions, and downstream quality during the windows when ads were allowed to run.
    • Change the correct control. Lower the budget when the total amount is too high. Narrow or widen the schedule only when eligibility itself is wrong.

    This distinction also improves diagnosis. Faster spending during active periods does not automatically mean bidding has become more aggressive or demand has improved. It may be the predictable result of the pacing system trying to use the same monthly allowance within fewer opportunities.

    Consent diagnostics tell you whether the optimizer can learn

    An analyst examines anonymous data signals passing through transparent consent gates toward an unbranded optimization engine, with some signals blocked or fading.

    An optimizer cannot act on a conversion it cannot observe. That makes consent signal quality part of campaign operations, not a separate technical housekeeping task.

    Google Ads’ App Consent Insights exposes consent diagnostics across apps, platforms, regions, and traffic sources. The view includes an overall rating of Excellent, Good, or Poor, a live count of apps sending consented data, and conversion consent rates with EEA and non-EEA differences.

    Use those dimensions to localize a gap. Do not interpret the account-level rating as a complete diagnosis. A lower rate could reflect genuine user choices, traffic composition, a deployment inconsistency, or missing signal transmission. Those possibilities need different responses.

    1. List the apps and platforms that should be sending consent information. Compare that inventory with the live count shown in the diagnostic.
    2. Locate the narrowest break. Determine whether the difference belongs to one app, one platform, one region, one traffic source, or a wider implementation.
    3. Compare EEA and non-EEA results without assuming geography is the cause. Review the regional consent implementation and the underlying traffic mix separately.
    4. Validate the technical path from the consent choice to the advertising platform. Confirm that the relevant state is collected, transmitted, and associated with the intended conversion setup.
    5. Annotate the release or configuration change that corrected a gap. Keep unrelated budget and bidding edits out of the same evaluation window where possible.
    6. Reassess campaign performance only after the corrected signal flow has had an appropriate observation period for your normal conversion lag.

    The overall rating is a diagnostic indicator, not an optimization objective. Do not make a consent experience more coercive just to lift a platform metric. Changes to consent language or interaction design should remain under the appropriate privacy and legal review. The campaign team’s job is to make sure a valid choice is transmitted accurately and that missing instrumentation is not mistaken for user behavior.

    This protects decision quality in both directions. You avoid blaming creative when measurement is incomplete, and you avoid treating every consent-rate difference as a tagging failure. Once signal coverage is understood, bidding and conversion reports become easier to interpret.

    Prove an AI ads manager can control delivery before scaling it

    New advertising interfaces can improve access long before their control systems become mature. OpenAI is testing a ChatGPT Ads Manager that moves beyond weekly CSV reporting toward real-time campaign management, monitoring, and optimization. That is meaningful progress, but testing an interface is not evidence that every targeting, reporting, governance, or automation capability is complete or broadly available.

    Evaluate an emerging ad manager by what you can verify, not by how familiar its dashboard looks. For every requirement, distinguish between a control that is promised, a control visible in the interface, and a control whose effect you have confirmed.

    • Authority: Can the authorized operator pause delivery, edit budgets, and reverse a change at the required account or campaign scope?
    • Budget semantics: Is the budget daily, monthly, lifetime, or another form? How is pacing described, and what prevents an unexpected concentration of spend?
    • Eligibility and exclusions: Which scheduling, targeting, placement, brand-safety, and exclusion controls actually exist? Do not assume parity with Google Ads or Meta because the navigation feels familiar.
    • Measurement: Which event counts as a conversion, what attribution rules apply, how quickly do results appear, and can reported totals be reconciled with your analytics?
    • Diagnostic depth: Can you break performance down far enough to separate delivery, audience, creative, placement, and signal problems?
    • Auditability: Is there a change history showing who changed a setting, when it changed, and what the previous value was?
    • Portability: Can you export campaign, delivery, and conversion data in a form your reporting system can retain and compare?
    • Governance: Can access be limited by role, and can a second operator review high-impact changes before they affect delivery?

    If a required control is missing or unverified, limit the test to exposure your organization can tolerate and define a manual stop path before launch. A report that arrives quickly is helpful, but speed does not replace enforcement, audit history, or the ability to reconcile results.

    Keep paid AI advertising separate from GEO and earned AI visibility as well. An ad impression purchased inside an AI experience is not proof that the brand was selected, cited, or recommended organically by a model. Give paid campaigns their own attribution labels, landing-page tracking, and reporting view so an increase in paid traffic cannot be presented as improved generative visibility.

    Before your next optimization cycle, open one consequential campaign and record its monthly spending ceiling, the reason for its schedule, its maximum active-day exposure, its consent-signal coverage, the controls that can stop delivery, and the delay in its reporting. Resolve any unknown that could change the meaning of the results. Once those controls are observable and enforceable, bid and creative changes can produce evidence you can actually use.

    References


  • Google Ads Automation: A Practical Optimization Framework

    Google Ads Automation: A Practical Optimization Framework

    You want Google Ads automation to remove repetitive work, not remove your control over spend. The problem is that an automated campaign can look efficient inside the platform while attracting weak leads, claiming conversions that would have happened anyway, or scaling a creative idea that has never proved incremental value.

    The answer is not to choose between manual management and full autonomy. Build a control system in which machines execute within explicit boundaries, experiments establish causality, and a person remains accountable for the objective, economics and exceptions.

    Key takeaways

    • Automate repeatable execution, but keep conversion definitions, economic thresholds, exclusions and stop conditions under human control.
    • Fix the conversion signal before optimizing against it. Faster optimization only magnifies a bad definition.
    • Treat attributed conversions and incremental conversions as different measures. Attribution assigns credit; incrementality tests whether advertising caused an additional result.
    • For a Demand Gen asset uplift experiment, isolate one creative variable, use a 50/50 cookie-based split, protect the budget for at least four weeks and aim for at least 50 conversions across the test groups.
    • Scale only when a change passes two gates: it produces acceptable business economics and it operates without violating your controls.

    Choose exactly what automation is allowed to control

    A modular control console shows separate guarded mechanisms for budget, audiences, bidding, creative selection, and conversion quality.

    Automation is not one switch. Bidding, budgets, keyword or query expansion, audiences, creative, campaign construction and landing-page testing are separate control layers. Give each layer its own permission, boundary and owner.

    Some commercial platforms are marketed as handling campaign builds, bids, ad copy, keyword expansion, landing-page experiments and reporting. That feature scope is a vendor claim, not independent evidence that full autonomy will improve profit or generate incremental demand in your account. Evaluate the decision rights behind the feature list.

    Control layerWhat automation may doWhat you must defineWhen to pause it
    Conversion measurementReceive events and values used for optimizationWhich event represents a real business outcome and how its value is calculatedTracking breaks, duplicates appear or the mix of conversion events changes unexpectedly
    Bidding and budgetAdjust bids and allocate spend within approved campaignsMaximum acceptable acquisition cost, minimum acceptable return and hard spending limitsSpend or unit economics moves outside the approved boundary
    Queries and audiencesExplore demand patterns and expand reachMarkets, exclusions, customer fit and intent boundariesTraffic drifts toward irrelevant intent, excluded regions or low-value prospects
    CreativeAssemble, rotate or test approved assetsClaims, tone, brand rules and the hypothesis being testedA policy or brand risk appears, or simultaneous changes make the test uninterpretable
    Landing pagesRoute traffic or test approved variationsPermitted page elements, data handling and the required user journeyForms, tracking, consent mechanisms or essential page functions fail

    Write these boundaries before connecting a tool that can make changes. At minimum, your operating brief should contain:

    <!– wp:list {
  • AI-Era Advertising: How to Prove and Scale Real Growth

    AI-Era Advertising: How to Prove and Scale Real Growth

    Your dashboard says advertising is working. ROAS is up, automated campaigns are claiming conversions, and conversational AI is opening new inventory. But the decision in front of you is harder: which spending actually created revenue that would not have happened otherwise?

    You can answer that question without waiting for perfect attribution. Separate platform-reported performance from incremental lift, measure the return on the next dollar rather than the average dollar, and treat new AI placements as controlled learning investments. That gives you a practical basis for scaling, holding, or cutting spend.

    A high ROAS can still describe demand capture

    Platform ROAS answers a narrow question: how much revenue did the platform attribute to ads relative to their cost? It does not tell you how many of those purchases required the ads.

    That distinction becomes important when automated systems can concentrate spending around branded searches, repeat visitors, existing customers, and people already close to buying. The platform may be accurately recording its involvement while claiming revenue that would have arrived through direct, organic, or another channel. The number is useful for optimizing activity inside the platform, but it is not causal proof of growth.

    Before you increase a campaign budget, ask three separate questions:

    • Did the platform influence conversions? Platform attribution, CPA, and ROAS can help answer this.
    • Did advertising cause additional conversions? A controlled incrementality test is needed to estimate this.
    • Will the next block of spending remain profitable? Marginal return and contribution economics answer this better than average ROAS.

    Use the right calculation for each decision

    • Attributed ROAS equals platform-attributed revenue divided by ad spend. Use it to compare campaigns under the same attribution rules and improve execution within a platform.
    • Incremental revenue is the difference between the outcome for an exposed group and the estimated outcome for a comparable unexposed group, after accounting for relevant baseline differences.
    • Incremental ROAS equals incremental revenue divided by the advertising cost required to produce that lift. Use it to decide whether the campaign adds enough business value to keep funding.
    • Marginal ROAS equals the change in incremental revenue divided by the change in spend. Use it to decide whether an additional budget block is worth buying.

    The average and marginal numbers can point in opposite directions. A campaign that produces $50,000 from its first $10,000 has a 500% average ROAS. If another $5,000 produces only $5,000 more revenue, the combined average still looks respectable at roughly 366%, but the marginal ROAS on the added spend is only 100%.

    Do not call that final dollar break-even merely because one dollar of spend returned one dollar of revenue. Product costs, fulfillment, payment fees, returns, sales commissions, and other variable costs can make a 100% revenue ROAS unprofitable. Convert incremental revenue into incremental contribution before approving more budget. If margins differ by product or customer segment, calculate contribution at that level instead of applying one blended percentage to everything.

    Build a measurement ladder instead of one master metric

    Two analysts inspect a five-level staircase containing signal lights, matched customer groups, test vessels, and a prism illuminating a new group.

    No single metric can optimize campaigns, prove causality, and allocate the next dollar. A measurement ladder gives each metric a specific job and prevents a familiar dashboard number from being stretched beyond what it can establish.

    DecisionPrimary evidenceWhat that evidence cannot prove alone
    Which bid, audience, or creative should run?Platform conversions, CPA, and attributed ROASWhether the advertising caused the conversion
    Should the campaign keep receiving money?Incremental lift, incremental ROAS, and contributionWhether a larger budget will perform at the same rate
    Where should the next budget block go?Marginal incremental revenue or contributionHow performance will change after a major market or product shift
    Is the brand gaining visibility in AI answers?Paid exposure and unpaid AI mentions measured separatelyThat either form of visibility caused profitable demand

    Run an incrementality test that matches the business question

    You do not need a perfect measurement laboratory. You do need a credible counterfactual: an estimate of what would have happened without the advertising.

    1. Choose one business outcome before launch. Use completed revenue, gross contribution, qualified pipeline, new customers, or another outcome tied to the decision. Do not replace it mid-test with whichever platform metric looks strongest.
    2. Choose a control design. Comparable geographic markets, randomized audience holdouts, platform lift tests, audience exclusions, and controlled spend reductions can all create evidence beyond ordinary attribution. Geo splits and audience holdouts are especially useful when user-level journeys cannot be observed cleanly.
    3. Protect the contrast. Record which campaigns, markets, audiences, promotions, and prices differ between treatment and control. A large promotion in only one group can look like advertising lift even when the ad had little effect.
    4. Record the exposure rules. Preserve campaign settings, eligibility, placement types, creative versions, market coverage, and any platform product changes. This matters more in AI inventory, where formats and reporting can change while the channel is still maturing.
    5. Let the test cover the decision cycle. A test that ends before delayed purchases or qualified leads can mature will favor channels with short feedback loops. Set the observation window from the actual buying process, not from a convenient reporting date.
    6. Report uncertainty with the result. A positive point estimate from a small or volatile control group is not automatically a scalable win. If the result is too noisy to distinguish lift from normal variation, enlarge the test unit, repeat it, or classify the conclusion as unresolved.

    Maintain a test ledger with the hypothesis, primary outcome, treatment and control definitions, launch and end conditions, known confounders, result range, and budget decision. That record stops teams from remembering only successful tests and makes later retesting much faster.

    Treat conversational AI ads as a learning budget

    A researcher directs a measured stream of budget tokens into three transparent chambers testing abstract conversational ad experiences with anonymous audiences.

    Conversational advertising should not inherit the assumptions of search, social, or display. OpenAI began rolling out ads to Free and Go users in Australia, New Zealand, and Canada while keeping Pro, Business, Enterprise, and Education plans ad-free. Results from that inventory therefore should not be generalized to every ChatGPT user, market, or subscription tier.

    The early buying environment also carries unusually high measurement risk. Initial advertiser accounts described impression-led campaigns, limited reporting, high CPMs, and starting commitments in the six-figure range. Those accounts are preliminary, not a dependable benchmark for what every advertiser will pay or achieve. They are still enough reason to demand a sharper test plan before committing a material budget.

    Write the pilot brief before negotiating inventory

    • State the user moment. Name the conversational situation you expect to influence, such as category comparison, product research, retailer selection, or troubleshooting. A generic awareness objective is too broad to diagnose.
    • Define an exposure. Establish whether the platform reports a served impression, visible placement, interaction, click, conversation, or another unit. Do not compare CPMs until you know what the impression represents.
    • Name one primary outcome. Choose incremental qualified visits, incremental orders, incremental contribution, or qualified pipeline. Treat impressions and clicks as diagnostic signals rather than proof of growth.
    • Set the economic boundary in advance. Calculate the maximum acceptable acquisition cost or minimum contribution return from your own unit economics. If the required commitment would displace a proven campaign or consume the budget needed for a valid control, wait.
    • Specify the control. Use an unexposed geography, audience, eligible period, or other comparable unit where the placement will not run. If the seller cannot support or tolerate a credible comparison, classify the investment as exploratory rather than performance-proven.
    • Preserve evidence. Export the available delivery, market, tier, placement, creative, billing, and outcome data. Note reporting-definition changes so a product update is not mistaken for a performance change.
    • Set a stop rule. Decide what level of economic loss, reporting failure, brand-safety concern, or control contamination ends the test. The novelty of the format is not a reason to ignore an invalid experiment.

    Keep paid presence separate from earned AI visibility

    A sponsored brand appearing near a recommendation is not the same as a model selecting, citing, or mentioning that brand without payment. Early placements may influence the journey indirectly by making a sponsored retailer more prominent among recommendations, even when the underlying answer is presented as independent from the ad.

    Measure three lanes separately:

    • Paid AI delivery: eligible exposure, served placements, interactions, clicks, cost, and available conversion signals.
    • Earned AI visibility: unaided brand mentions, citations, recommendation presence, and factual accuracy across a fixed set of representative prompts.
    • Business effect: incremental visits, qualified leads, new customers, revenue, and contribution against a control or credible baseline.

    This separation protects your AEO and GEO work from a false success signal. Paid exposure can increase while unpaid recommendation visibility falls, or an AI system can mention the brand more often without creating profitable demand. Neither outcome should be credited to the other without a test.

    Move budget according to marginal contribution

    The AI shift does not make established channels irrelevant. IAB/PwC figures put U.S. search advertising revenue at $114.2 billion in 2025 within a $294.6 billion digital advertising market. Digital video reached $78 billion after 25.4% growth, while social reached $117.7 billion after 32.6% growth. The ten largest companies controlled 84.1% of the market.

    Those market totals describe where money went, not where your next dollar belongs. A rapidly growing channel can be unprofitable for your offer, while a slower-growing channel can still produce strong incremental contribution. Concentration also means the same large platforms often control inventory, optimization, and attribution. Use their reporting to manage campaigns, but require independent business outcomes or controlled lift before treating claimed conversions as proof.

    Use a repeatable capital-allocation cycle

    1. Rank current channels by marginal contribution. Use the most recent credible spend change or controlled test, not lifetime average ROAS.
    2. Choose the next observable budget block. It should be large enough to create a measurable change but small enough that a weak result does not materially damage the plan.
    3. Estimate the expected range. Record a low, central, and high outcome using evidence from your tests and unit economics. Do not convert an uncertain pilot into a single precise forecast.
    4. Move one block from the weakest expected marginal use to the strongest. Keep major promotions, pricing changes, and other confounders visible so they do not receive advertising credit.
    5. Remeasure after the change. Marginal returns usually change with spend. A channel that deserved the previous increase does not automatically deserve the next one.

    It also helps to classify spending by purpose. Core campaigns have repeatable causal and economic evidence. Experimental campaigns buy information about new inventory, audiences, or creative. Verification spending retests old assumptions after platform, product, or market changes. A brand-defense campaign may remain strategically valuable despite low measured incrementality, but label it as protection rather than presenting it as growth. That makes the trade-off explicit.

    Key takeaways

    • Platform ROAS measures attributed performance; it does not establish how much revenue advertising caused.
    • Incrementality tells you whether a campaign created an outcome that would not otherwise have occurred.
    • Marginal contribution, not blended ROAS, should determine whether the next budget increase is economically sound.
    • Conversational AI ads need a defined exposure unit, control, business outcome, economic limit, and stop rule before a substantial commitment.
    • Paid AI placements, earned AI visibility, and business impact belong in separate measurement lanes.
    • Market growth identifies where advertisers are moving, but your own causal evidence and unit economics should determine where you move.

    For your next budget review, replace the single ROAS column with six fields: attributed return, incremental lift, incremental contribution, marginal return, confidence level, and next test. Mark an untested channel as unproven rather than successful or failed. Then fund the next measurable budget block where the expected marginal contribution is strongest. AI formats will keep changing; that decision discipline will remain useful even when the placements do not.

    References


  • Google’s Ad Business Is Under Pressure: What Marketers Do Now

    Google’s Ad Business Is Under Pressure: What Marketers Do Now

    If Google Ads carries a large share of your pipeline, the useful question isn’t whether Google is finished. It isn’t. The question is whether your current level of dependence still makes sense when competitive momentum, platform reliability problems and legal challenges are converging on the same advertising business.

    You don’t need to abandon profitable campaigns. You do need to know what would happen if Google became less efficient, an automated review stopped your ads, or another platform produced a better marginal return. That calls for a controlled resilience plan, not a panicked budget shift.

    Three different forces are squeezing Google’s ad business

    Pressure on Google is often treated as one sweeping story about the decline of search advertising. That framing isn’t useful. Competitive, operational and legal pressure work through different mechanisms, so each requires a different response from you.

    Competitive pressure is following performance and automation

    A 2026 forecast puts Meta at $243.46 billion in global ad revenue and Google at $239.54 billion. The corresponding shares of worldwide ad spending are projected at 26.8% and 26.4%. If the forecast holds, Google would lose the global digital ad revenue lead for the first time.

    The gap is narrow, and a forecast is not a completed result. Google also remains enormous, continues to grow and operates one of the world’s most profitable search advertising engines. The strategic signal is subtler: incremental budgets are increasingly attracted to systems that automate creative production, targeting and campaign optimization while making return on investment easy to communicate.

    That does not prove Meta will outperform Google in your account. It does show that Google can no longer be treated as the automatic home for every additional advertising dollar. Its performance must earn the budget against a credible alternative.

    Operational pressure turns automation into a continuity risk

    Automated ad review gives Google scale, but it can also interrupt otherwise sound campaigns. Advertisers have encountered sudden destination disapprovals attributed to DNS failures or HTTP 500 errors even when their landing pages appeared to work normally. In one account, more than 1,500 ads were reportedly disapproved at 1:30 p.m. UTC.

    A page can load for your team while failing for an automated crawler because of a temporary DNS problem, timeout, redirect, geographic rule, firewall setting or origin-server error. It is also possible for the crawler or review system to be the source of the failure. Either way, the commercial effect is the same: eligible ads stop serving, and traffic, leads or sales can disappear while your team investigates.

    This is more than a support inconvenience. When a platform can suspend a revenue-producing route through an automated decision, platform reliability belongs in your acquisition risk model.

    Legal pressure has moved closer to advertiser economics

    Federal courts found in 2024 that Google had unlawfully monopolized online search and parts of the ad technology infrastructure connecting advertisers with publishers. Google is appealing both decisions. Advertisers are also exploring mass arbitration claims tied to alleged overpayments for search and display advertising.

    An economic analysis commissioned by claimant counsel estimated that potential claims could exceed $218 billion, while mass arbitration proceedings commonly take an estimated 12 to 24 months. Neither figure is an award, a settlement or a reliable receivable for an individual advertiser. Google says it has strong arguments and intends to defend itself.

    The practical meaning is not that your ad costs are about to fall or that compensation is assured. It is that Google’s legal exposure is no longer confined to regulatory headlines. Advertiser claims could create direct financial and contractual pressure, but the outcome, timing and effect on the advertising market remain uncertain.

    Key takeaways for the person holding the budget

    • Google remains a formidable and growing advertising platform. Pressure on the business is a reason to manage concentration, not evidence that every account should leave.
    • Meta’s projected revenue lead is an aggregate market signal. Your allocation still needs to follow qualified leads, profitable sales and incremental return in your own business.
    • Unexpected ad disapprovals can turn a technical review into an immediate revenue interruption. You need an incident procedure before the next alert arrives.
    • Antitrust rulings and proposed mass arbitration claims are consequential but contested. Do not budget for a payout or make legal decisions without qualified counsel.
    • The strongest response is to preserve profitable Google activity while building independent measurement, tested channel alternatives and owned search or AI visibility.

    Reallocate budget from account evidence, not market headlines

    Hands distribute metallic budget tokens between one large central channel tray and several smaller test channels on a strategy table.

    Moving money from Google to Meta simply because Meta may become the larger ad company substitutes one form of platform dependence for another. Start by separating the jobs your campaigns perform. Search often captures explicit demand. Paid social can create or reactivate demand through audience and creative systems. You cannot evaluate those jobs honestly with one undifferentiated return figure.

    1. Classify each campaign by its actual job. Use categories such as branded demand capture, non-branded demand capture, remarketing, prospecting and brand reach. Do not allow a campaign to claim credit for every stage of the buyer journey.
    2. Connect platform activity to business outcomes. Evaluate qualified leads, accepted opportunities, completed sales, gross margin and acquisition cost where those measures are available. A cheap lead that sales rejects is not evidence of channel efficiency.
    3. Separate platform-reported results from your own records. Keep first-party lead and sales data, campaign identifiers and attribution assumptions accessible outside Google and Meta. The platforms can inform the decision, but they should not be the only systems capable of grading themselves.
    4. Compare the marginal dollar, not the historical average. A mature campaign may have an excellent blended return while its next increment of spend produces much less. That next increment is the money an alternative channel must beat.
    5. Run controlled transfer tests. Keep the offer, business outcome and measurement logic as consistent as the channels permit. Judge results over a complete conversion cycle, especially when revenue closes well after the ad click.
    6. Write the scale, hold and stop conditions before seeing the result. This prevents a team from explaining away weak performance because it prefers a platform, campaign type or creative idea.

    Do not compare click-through rate or cost per click across fundamentally different campaign jobs and call the cheaper platform the winner. A high-intent search click may cost more because the user is closer to a decision. A social impression may influence demand without receiving the final conversion credit. Compare the business outcome each campaign was assigned to produce.

    Also inspect concentration below the platform level. A Google account can appear diversified while most revenue depends on one campaign, match type, audience, product category or landing page. Record the percentage of paid-media revenue associated with each critical component. The point is to identify where one suspension, policy change or performance decline would be difficult to replace.

    If Google still produces the best qualified acquisition economics after that review, keep funding it. Resilience is not the same as forced diversification. It means alternatives are measured and available before the core channel gives you a reason to need them.

    Make ad disapprovals a rehearsed incident, not a surprise

    A marketing operations team calmly activates a prepared backup route after one campaign module turns red and disconnects.

    An unexplained destination disapproval creates two bad instincts: assume Google must be wrong, or rebuild a working site before establishing what failed. Both waste time. Use a fixed diagnostic sequence so the team can distinguish a site defect from a transient or platform-side review problem.

    1. Record the event before changing anything. Capture the account, campaign, affected ads, destination URLs, policy reason, first observed time and number of affected ads. Save the disapproval notice and relevant account views.
    2. Read the exact reason in Google Ads Policy Manager. Do not troubleshoot a generic destination problem when the platform has supplied a more specific policy category.
    3. Test the final URL as a new visitor. Check multiple devices and networks where practical, follow the complete redirect path and confirm that the intended landing page returns rather than an error, login wall or region block.
    4. Inspect DNS, CDN, firewall and origin-server evidence. Look for lookup failures, timeouts, blocked automated requests, redirect loops and temporary 500 responses around the recorded incident time. A successful manual visit later does not prove the crawler could reach the page earlier.
    5. Determine the scope. If unrelated accounts, domains or landing pages fail at roughly the same time, preserve that pattern. If one URL or infrastructure component is isolated, prioritize the local fault.
    6. Correct a verified site problem, then request review. If the destination works and your logs do not support the stated error, submit an appeal with concise evidence instead of blindly reconfiguring production infrastructure.
    7. Track the commercial effect. Record lost serving time, affected campaigns and the downstream lead or revenue impact you can substantiate. This supports internal incident analysis and any later escalation.

    Assign ownership before an incident. The paid-media owner should know who can inspect DNS and server logs, who can approve a landing-page change, who submits an appeal and who informs sales or leadership when lead flow is interrupted. An escalation path buried in an agency inbox is not a continuity plan.

    Set monitoring around business symptoms as well as website uptime. A generic uptime check may remain green while ads lose eligibility. Watch for abrupt changes in approved-ad counts, impressions and conversions, then investigate those signals together. The goal is not to assume every drop is a platform error; it is to discover the interruption before a full reporting cycle has passed.

    Maintain compliant fallback assets for important offers where your operation supports them. That can include a separately verified landing destination, current creative files, approved messaging and a tested alternative acquisition channel. A fallback should present the same truthful offer and comply with platform policies. It should never be used to disguise a destination or evade review.

    Build leverage before Google changes the terms

    Your leverage does not come from predicting which pressure will matter most. It comes from reducing the number of decisions Google can make on your behalf without an effective response from you.

    Keep the legal question separate from the media plan

    Mass arbitration may become relevant to some advertisers because advertising contracts can require disputes to proceed through arbitration rather than ordinary litigation. A coordinated filing can change the economics of pursuing smaller individual claims, but participation, eligibility, deadlines, evidence and possible costs are legal questions specific to the advertiser and contract.

    Preserve ordinary business records that already support your accounting and campaign decisions: applicable contracts, invoices, billing exports, campaign histories and the internal records used to connect spend with outcomes. Do not alter retention practices, assert damages or join a claim solely from a revenue estimate in public coverage. Ask qualified counsel to assess your actual position. A possible recovery should not appear in your forecast or justify continued inefficient spending.

    Own the measurement layer

    A platform has more leverage when it owns the auction, delivery, optimization and final performance narrative. Define conversions in business terms outside the ad interface. Reconcile ad-reported conversions with lead quality, sales acceptance, cancellations, returns and margin where those factors apply to you.

    Document attribution rules as well. When Google and Meta both claim the same conversion, your team needs a consistent method for deciding how the result affects allocation. The method does not have to be perfect. It has to be stable enough that a platform’s reporting change cannot rewrite your entire performance history.

    Diversify discovery, not just ad vendors

    Moving spend between advertising platforms protects only part of the journey. Pressure from AI search also makes owned visibility more important. Organic search, answer-engine optimization and generative-engine optimization will not replace a high-performing paid campaign on command, but they can reduce the amount of demand you must rent one click at a time.

    Start with the queries and sales questions that already signal commercial intent. Build pages that answer the central question early, distinguish your offer clearly, name relevant entities consistently and support important claims. Add structured data only when it accurately represents visible content. Maintain citations, authorship and update information so a search engine or AI system can understand what the page says and why it is trustworthy.

    Measure this work against its assigned role. Some pages should create qualified organic leads. Others may improve brand discovery, support a later conversion or give prospects the evidence needed to return through a branded search. Treating every owned page as a last-click sales page will cause you to underinvest in the assets that create negotiating room with paid platforms.

    Your next move can be concrete and limited: map where paid-media revenue is concentrated, write the destination-disapproval procedure, select one credible budget-transfer test and choose one high-intent question your business should answer without buying the visit. Google may remain your strongest advertising channel after all four steps. The difference is that it will be a measured choice rather than an unmanaged dependency.

    References


  • Claude-Powered PPC Automation: From Prompts to Systems

    Claude-Powered PPC Automation: From Prompts to Systems

    If Claude gives you a strong search-term analysis only after you paste the same instructions and CSV into a new chat, you have improved the task, not automated it. You still have to assemble the context, request the analysis, normalize the output, and move each approved change into Google Ads.

    Claude-powered PPC automation becomes useful when you design those handoffs once. The practical system has three separate parts: decision logic, access to current campaign data, and controls over what the AI may change. Get those parts right and Claude can take recurring work off your desk without taking campaign authority away from you.

    The three parts of a reliable Claude PPC system

    Three connected modules represent campaign data access, AI decision logic, and human-controlled execution safeguards.

    The model is only one layer of the system. A dependable workflow also needs a stable playbook and an explicit operating boundary.

    System partWhat it doesThe question you must answer
    Claude SkillEncodes the task, decision rules, required inputs, exceptions, and output structure.What should happen every time this PPC job runs?
    Data and toolsSupply campaign context and, when authorized, provide a way to execute an approved action.Which data may Claude read, and which operations may it call?
    Workflow controlsDefine scope, approval requirements, stop conditions, and records of proposed or completed changes.What is Claude allowed to decide, recommend, and change?

    A Claude Skill is a task-specific playbook, not a general preference about tone or behavior. It can tell Claude how to audit an account, evaluate search terms, generate ad assets, or compare budget opportunities. The instructions can be stored in a Markdown file, kept locally, or shared through a repository so the team uses the same method.

    The main benefit is procedural consistency. Without a fixed contract, one run might return letter grades while another uses percentages or an unrelated numerical scale. That is more than a presentation problem. A person, spreadsheet, script, or approval workflow cannot reliably consume an output whose structure changes between runs.

    A Skill should make the process predictable, but it should not pretend every PPC judgment is deterministic. Campaign evidence changes, and some cases will remain ambiguous. Your playbook therefore needs both decision rules and an explicit way to return insufficient evidence, conflicting signals, or required human review.

    The data layer solves a different problem. A Skill can know how to evaluate a search query report while knowing nothing about the queries currently appearing in your account. A Model Context Protocol connection can bridge that gap: MCP can connect Skill logic to live data sources and account tools. That turns a static playbook into an operating workflow, but it also makes permissions and approval gates essential.

    Build the first workflow around one recurring decision

    Start with a bounded job rather than asking Claude to optimize an account. Search-term mining is a practical first candidate because you can define the input, inspect every recommendation, and test the logic without granting write access.

    1. Define the job in one sentence. For example: review search terms from the requested 14-day window, identify waste and opportunity using the account’s approved criteria, and return proposed actions for review. The 14-day period is an input to this workflow, not a universal recommendation for every account.
    2. Write down the judgment currently living in the operator’s head. Include the evidence Claude must consider, the conditions that support each recommendation, the exceptions that require escalation, and anything it must never infer from missing data.
    3. Lock the output contract. Name every required field, its allowed values, and what a stopped run looks like. Do not let Claude invent a new scoring system or column set each time.
    4. Convert the SOP into a Skill. A useful instruction is: Convert this SOP into a task-specific Claude Skill. Preserve the decision rules, define required inputs, return a fixed schema, stop when required fields are missing, and do not take write actions without approval.
    5. Run the Skill against a known CSV before connecting an account. Confirm that it covers the intended records, follows the rubric, flags exceptions, and returns the exact structure your reviewer or downstream tool expects.
    6. Connect live data in read-only mode. Compare the live run with the CSV-based process. Add write capabilities only after the connected workflow passes the same acceptance checks.

    A useful output contract for this workflow can require:

    • The account, campaign, and reporting window included in the run.
    • A completion status that distinguishes a finished analysis from a stopped or incomplete run.
    • The item reviewed, the evidence used, and the applicable decision rule.
    • The proposed action and a concise reason for it.
    • An exception field for missing inputs, conflicting signals, or cases outside the Skill’s authority.
    • An authorization state such as proposal, approved, executed, or rejected.

    The output contract is what turns a clever response into a component another person or system can trust. Claude should never quietly substitute a plausible answer when a required campaign field is unavailable. A stopped run with a precise error is safer and more useful than a polished recommendation built on incomplete context.

    Put money-changing actions behind explicit gates

    A human operator approves one proposed campaign change at a guarded barrier before it reaches an advertising budget.

    Access and authority are not the same thing. An MCP-enabled tool may make an account change technically possible, but your workflow still decides whether Claude may propose it, prepare it, or execute it. That distinction matters whenever an action can change spend, targeting, messaging, or delivery.

    Operating modeClaude’s roleHuman role
    Manual-context assistantAnalyzes an uploaded report and returns structured recommendations.Exports data, checks the result, and implements every change.
    Connected analystPulls permitted live data and prepares account-specific proposals.Reviews and approves each proposed action before execution.
    Controlled operatorExecutes only approved action types within the defined scope and constraints.Sets policy, handles exceptions, reviews logs, and can stop the workflow.

    Most teams should move through these modes in order. Live read access removes manual report handling without immediately exposing the account to automated edits. Proposal-only operation then shows whether the logic behaves well under current conditions. Controlled execution comes last, after the team knows which exceptions appear in real runs.

    Before enabling any write action, add these controls to the workflow:

    • Default-deny permissions. Claude may read or modify only the accounts, campaigns, objects, and action types explicitly included in scope.
    • Action-specific approval. Treat applying an existing extension, creating an ad experiment, changing a search-term response, and reallocating budget as separate permissions.
    • User-defined financial boundaries. A budget workflow must operate inside limits set by the account owner rather than deciding its own acceptable spend change.
    • Fail-closed behavior. Missing data, an invalid schema, an unavailable tool, or an out-of-scope request should stop the run instead of triggering a best guess.
    • A preview of the exact modification. The reviewer should see what object will change, its current state, the proposed state, and the reason before approving it.
    • An audit trail. Preserve the input scope, Skill version, findings, approval state, tool response, and execution result so a later reviewer can reconstruct what happened.
    • A conflict rule. Give each task one canonical Skill, because overlapping audit or optimization Skills can reintroduce the inconsistency the system was built to remove.
    • A recovery plan. Document how an executed change will be reversed when reversal is available. Keep irreversible or poorly understood actions manual.

    Budget reallocation deserves the tightest gate because it moves money between campaigns. A recommendation can still be automated: Claude can compare the permitted data, explain the proposed shift, and prepare the action. Execution should remain subject to the account owner’s constraints and approval until the workflow has demonstrated reliable behavior in proposal-only mode.

    Use acceptance checks rather than impressions when deciding whether a workflow is ready. The run should always return the required fields, stop on missing inputs, stay inside its declared scope, expose the evidence behind each proposal, and show the planned modification before execution. If any of those checks fail, improve the Skill or connection before expanding its authority.

    Choose PPC tasks by controllability, not novelty

    The best first automation is not necessarily the task consuming the largest budget or producing the most visible output. It is the task whose rules can be written clearly, whose evidence can be inspected, and whose mistakes can be contained.

    PPC workflowWhat the Skill should standardizeFirst safe deploymentExpanded deployment
    Search-term miningThe evaluation rubric, required evidence, exception handling, and recommendation format.Analyze an uploaded report and return proposals for review.Pull live search-term data and implement only separately approved actions.
    Ad copy generationHow landing-page information, keywords, user intent, and value propositions become proposed ad assets.Generate structured drafts for human review.Identify underperforming ads, prepare alternatives, and create an approved experiment.
    Account auditingThe checklist, severity logic, supporting evidence, and distinction between findings and remedies.Return a consistent audit with no account changes.Use live account data and apply permitted remedies, such as attaching an existing extension where appropriate.
    Budget reallocationThe comparison method, constraints, explanation, and escalation conditions.Produce proposed reallocations with no write access.Execute approved shifts inside account-owner limits and record every result.

    These four workflows can all progress from manual data handling to connected execution, but they should not receive the same authority by default. Search-term analysis, ad generation, account auditing, and budget reallocation involve different consequences and therefore need different approval paths.

    Score a candidate workflow against five practical questions before building it:

    • Does the task recur often enough that removing handoffs will matter?
    • Can an experienced operator state the decision rules without relying on unexplained instinct?
    • Are the required inputs available in a stable, inspectable form?
    • Can a reviewer verify the recommendation before the account changes?
    • Can the impact of an error be contained to a narrow scope?

    If the answers are weak, connecting more tools will not improve the workflow. Clarify the SOP first. Automation magnifies whatever is encoded: good judgment becomes repeatable, while an ambiguous process becomes ambiguous at greater speed.

    For a first deployment, we would favor a proposal-only search-term or account-audit workflow. Both make it easy to compare Claude’s output with an existing human process. Ad experiments can follow once asset review is defined. Budget execution belongs later because its consequences reach spend directly.

    Frequently asked questions

    What is Claude-powered PPC automation?

    It is a workflow in which a Claude Skill applies a repeatable PPC playbook, data connections supply the required campaign context, and explicit permissions determine whether Claude analyzes, proposes, or executes an action. A chat response alone is assistance; automation also handles the recurring context and handoffs.

    Do you need MCP to use a Claude Skill for PPC?

    No. You can run a Skill against a manually uploaded CSV and implement its recommendations yourself. MCP becomes relevant when you want Claude to retrieve live data or use connected account tools. Start with manual or read-only data if the Skill’s decision logic has not yet been validated.

    Which PPC workflow should you automate first?

    Choose a recurring workflow with written rules, inspectable inputs, a fixed output, and limited consequences when something goes wrong. Search-term mining or a checklist-based audit is usually easier to validate than autonomous budget reallocation. Keep the first version proposal-only so you can judge the logic before granting execution authority.

    How do you prevent inconsistent Claude outputs?

    Use one canonical Skill for the task, define required fields and allowed values, state how exceptions must be returned, and stop the run when required data is missing. Remove or narrow competing Skills that could handle the same request. Test structural consistency before connecting the output to another tool.

    Take the next recurring search-term review or account audit and write down its rubric, output contract, and stop conditions. Test that process on a CSV, connect live data in read-only mode, and grant write access only after the workflow passes explicit acceptance checks. That sequence turns Claude from another prompt window into a PPC system you can supervise.

    References