Tag: Budget Management

  • Political Campaign AI Spending: Where the 2026 Money Goes

    Political Campaign AI Spending: Where the 2026 Money Goes

    If you are building, buying, or measuring AI for a 2026 political campaign, the biggest budgeting mistake is treating AI as a single technology line. The headline total combines tools, AI-assisted work, automated outreach, and the media used to distribute AI-influenced advertising. A campaign can therefore spend little on software while creating a large AI-related footprint.

    You need to separate cost, operational use, and public exposure before deciding whether your campaign is underinvesting, overspending, or simply counting differently. That distinction turns an eye-catching market estimate into a budget you can actually manage.

    The $899 million headline is not a software market size

    Political campaigns, party committees, and outside groups are projected to spend $899 million on AI during the 2026 cycle. That would be 2.8 times the 2024 total and about 22 times the 2022 total. It is also equivalent to roughly 8.5% of the projected $10.6 billion in overall political advertising for the cycle.

    But $899 million does not mean campaigns are buying $899 million of AI software. The estimate includes three materially different forms of spending:

    • Direct payments for AI vendors, platforms, and general-purpose subscriptions.
    • The portion of production, targeting, fundraising, and outreach costs attributed to AI.
    • Media dollars placed behind advertisements generated or enhanced with AI.

    Those categories answer different questions. Direct vendor spending helps you assess the technology market. AI-attributable workflow spending tells you how deeply campaigns are using the technology. Media placement measures how much paid distribution sits behind AI-influenced assets. Combining them is useful for estimating AI’s overall campaign footprint, but it cannot tell you what AI products earned or how much a campaign saved.

    The total is also a projection, not a final audited tally. Its methodology covers more than 41,000 federal and state disbursement records, platform advertising libraries, and 57 consultant and vendor interviews, with activity tracked through September 24 and modeled through Election Day on November 3. Treat it as a structured market estimate. Do not use it as proof that every campaign classifies AI spending the same way.

    Before comparing your own budget with the market, decide which question you are asking. If you want to know what your technology stack costs, exclude media. If you want to understand operational adoption, include the AI-assisted share of labor and services. If you are assessing voter exposure, include distribution but keep it separate from production. One blended figure cannot answer all three questions.

    Distribution and outreach absorb more money than AI tools
    A small AI workstation connects through branching light trails to many phones, screens, mail pieces, and canvassing devices.

    The projected category mix shows where AI is entering campaign operations. Media placement behind AI-generated or AI-enhanced advertising is the largest category. General-purpose subscriptions are the smallest. That gap matters: the visible scale of political AI is being driven more by amplification and workflow adoption than by the price of access to a model.

    Spending categoryProjected 2026 spendingShare of totalGrowth versus 2024Question your budget should answer
    Media placement behind AI-generated or AI-enhanced ads$237 million26.4%3.3xCan you connect each placement to a specific asset, audience, and outcome?
    AI voter outreach$173 million19.2%3.0xWhen does an automated interaction move to a trained person?
    AI fundraising optimization$147 million16.4%2.4xAre you measuring net fundraising performance rather than message volume?
    AI audience modeling and targeting$131 million14.6%1.8xDoes the model improve decisions against a defined non-AI baseline?
    AI creative production$98 million10.9%4.7xWho verifies facts, voices, likenesses, and required disclosures before release?
    AI-assisted media buying fees$65 million7.2%2.8xCan you separate the service or algorithmic fee from the underlying media spend?
    General-purpose AI tools and subscriptions$48 million5.3%4.0xWho controls accounts, data access, retention, and offboarding?

    Creative production is growing fastest at 4.7 times its 2024 level, but it still accounts for only 10.9% of projected 2026 AI spending. Audience modeling is growing slowest at 1.8 times because it already had a meaningful base before the recent expansion of generative tools. Fast growth, large spending, and operational maturity are therefore three different signals.

    Do not judge an AI program by the number of assets it produces. A campaign can generate hundreds of variants without improving persuasion, fundraising, or contact quality. Measure the result associated with each workflow: approved production time for creative, net revenue for fundraising, successful contacts and escalations for outreach, incremental performance for targeting, and cost per desired action for media. Keep output volume as a diagnostic metric, not the primary success metric.

    Adoption also cuts across party lines. Republican candidates, parties, and aligned outside groups account for a projected $415 million, compared with $374 million on the Democratic side. Outside groups allocate a larger portion of their budgets to AI than candidates and parties, with Republican-aligned groups reaching 10.2%. Party affiliation is a poor proxy for AI maturity; spender type and workflow are more useful.

    Race size, geography, and timing change the right strategy

    Absolute spending concentrates in federal contests. House races account for a projected $305 million and Senate races for $286 million, together representing 65.7% of campaign AI spending. Yet smaller races use AI more intensively relative to their available media.

    Local and judicial races have AI-generated or AI-enhanced elements in 16.2% of ads, and AI represents 13.8% of their media budgets. State legislative races follow at 14.7% of ads and 12.4% of media budgets. House races are lower on both measures, at 9.2% and 8.9%, despite carrying the largest dollar total. Ballot measures sit at the other end, with AI elements in 6.3% of ads and 5.2% of media budgets.

    This is a denominator problem that can distort competitive analysis. A small campaign may look more AI-intensive because automation replaces work it could not otherwise afford. A large federal campaign can spend far more dollars while AI remains a smaller percentage of a much larger operation. Compare campaigns on both absolute spending and share of budget. Using only one will misclassify the smaller operation or obscure the larger one’s reach.

    Geography produces another concentration effect. The ten highest-spending states account for $460.1 million, or 51.2% of the projected total. Maine reaches $25.09 per registered voter, almost three times the next-highest figure in that group, as a competitive Senate race concentrates spending across a relatively small electorate. A national average will not tell you what competitive pressure looks like in an individual state.

    Disclosure practices vary just as sharply. Among the ten highest-spending states, the recorded share of AI ads carrying a disclosure ranges from 29% in Georgia to 78% in California. Across states with AI disclosure laws, 64% of AI ads carried a disclosure, versus 27% in states without one. That relationship indicates that legal requirements affect behavior, but it is not a substitute for a state-by-state compliance review.

    Build a jurisdiction field into the asset record before production begins. Record where the asset will run, what was generated or materially altered, which disclosure decision was made, who approved it, and which final version entered distribution. When the applicable rule is unclear, hold the asset and ask qualified election counsel. Retrofitting a disclosure after placement creates avoidable legal, financial, and reputational exposure.

    Timing is equally important. At the aligned one-month point, cumulative 2026 AI spending reaches $612 million, with a projected $899 million by Election Day. Spending within each cycle has roughly doubled every three months as Election Day approaches. The final month is projected to contain 32% of 2026 spending, below the 37% final-month share in 2024 because outreach and fundraising automation moved earlier to reach early voters.

    Do not postpone governance until the spending ramp. The final weeks are when review time contracts, asset volume rises, and media decisions become harder to reverse. Approve vendors, data permissions, escalation paths, disclosure rules, and evidence requirements before the high-volume period. The late-cycle budget should scale a controlled workflow, not finance the first real test of one.

    Build an AI budget that can survive scrutiny
    Transparent budget containers, coins, a magnifying glass, a locked data box, and a balance scale are arranged on an orderly campaign planning desk.

    A defensible AI budget starts with a ledger, not a list of tools. The cost of an AI program can include software, implementation, data work, human review, compliance, vendor services, and media. If you record only subscription invoices, you will understate the program. If you label every placement behind an AI-assisted asset as technology spend, you will lose sight of what the technology itself costs.

    1. Choose the unit of analysis. State whether you are tracking direct vendor cost, AI-enabled workflow cost, or media exposure. Maintain all three if leadership needs a complete view, but never merge them without labels.
    2. Classify spending at the invoice or line-item level. Assign every item to creative production, outreach, fundraising, targeting, media-buying services, general tools, or media placement. Prevent one invoice from disappearing into a broad digital-services account.
    3. Attach each cost to an accountable workflow. Record the race, jurisdiction, vendor, campaign owner, data used, synthetic or altered elements, human reviewer, approval status, and distribution channel.
    4. Set the baseline before the pilot. Compare the AI-enabled workflow with the existing process on the outcome that matters. Time saved is meaningful for production; it is not evidence of better persuasion. Message volume is meaningful for operations; it is not evidence of better fundraising.
    5. Create a release gate. Require factual verification, permission checks for voice and likeness, disclosure review, accessibility review where relevant, security review, and named human approval before an asset or automated interaction goes live.
    6. Scale only the validated component. If a creative workflow saves time but targeting does not improve performance, scale production rather than buying a larger bundled program. A vendor relationship does not have to expand as one indivisible unit.

    Your ledger should let a reviewer move in both directions: from an invoice to the assets and outcomes it funded, and from a public asset back to its production record, approval, disclosure decision, and media spend. That traceability is more useful than a generic AI policy because it shows how the policy operated in a specific case.

    If you publish or optimize political content

    More campaign investment means more creative variants, automated contacts, and paid distribution. It does not create independent corroboration. Treat campaign-generated material as a claim that requires verification, even when the asset looks polished or appears repeatedly across channels.

    • Put the publication or revision date, jurisdiction, race, candidate or issue, and sponsor context where a reader can see them.
    • Separate campaign assertions from independently verified facts, and link to the strongest available primary evidence for factual claims.
    • Keep the original approved asset and a correction history so changes do not erase provenance.
    • Use structured data only for information visible on the page. Markup can clarify entities and dates, but it cannot turn an unsupported claim into reliable evidence.
    • Do not present repeated synthetic content as multiple independent confirmations. Distribution volume and source diversity are not the same thing.

    These practices help human readers, search systems, and AI answer engines distinguish what happened, who is making a claim, when it applies, and which evidence supports it. They do not guarantee visibility or favorable treatment, but they reduce ambiguity at the point where political information is most likely to be compressed into a short answer.

    Key takeaways

    • The projected $899 million total measures a broad AI-related campaign footprint, not just software purchases or vendor revenue.
    • Media placement is the largest category at $237 million, while general-purpose tools and subscriptions account for $48 million.
    • Creative production is growing fastest, but output volume alone does not establish campaign impact.
    • Federal races lead in total dollars, while local, judicial, and state legislative races use AI more intensively relative to their media.
    • Disclosure practices differ substantially by state, so every asset needs a jurisdiction-specific review and an auditable approval record.
    • Budgeting should separate direct technology cost, AI-enabled workflow cost, and paid exposure, then connect each to a defined outcome.

    Start by exporting every AI-related expense and reclassifying it into technology, workflow, or distribution. Then choose one high-exposure workflow, give it a measurable baseline and a named approval owner, and resolve its disclosure path before shifting more money into it. That is how you turn a market trend into a campaign decision you can explain, test, and defend.

    References


  • Google Ads Automation and Localization Without Losing Control

    Google Ads Automation and Localization Without Losing Control

    If you manage Google Ads, your website is becoming part of the campaign-building system. An offer published on a page may become a promotion asset, while an existing Search campaign may become the template for a new language and market.

    That can remove hours of repetitive setup. It can also scale an expired discount, awkward translation or unsuitable budget before anyone notices. The right response is not to reject automation. It is to put a clear approval boundary between what Google can generate and what your business is prepared to promise and spend.

    Separate the two automations before setting policy

    Automated promotions and campaign localization solve different problems. They also fail differently. Treating them as one generic AI feature makes it harder to assign the right reviewer and control.

    WorkflowWhat Google createsInitial scopePrimary control
    Automated promotionsA promotion asset based on an eligible offer found on your websiteSearch and Performance Max campaigns with linked location assets and no promotion asset already attachedThe account-level Automated Promotions setting, followed by a review of assets that serve
    AI campaign localizationA new, independent campaign with localized ads, assets and keywordsEligible U.S. English Search campaigns translated into supported languages and markets during the betaLanguage, landing-page and commercial review before the localized campaign goes live

    The promotion workflow extracts a commercial claim that already exists. The localization workflow transforms an existing campaign for a different audience. The first can misstate an offer; the second can reproduce a sound campaign in a market where its language, intent or economics no longer fit.

    A useful account policy is simple: automation may identify, translate and assemble; a named owner must still authorize the promise, the audience and the spend.

    Audit your website before automated promotions serve

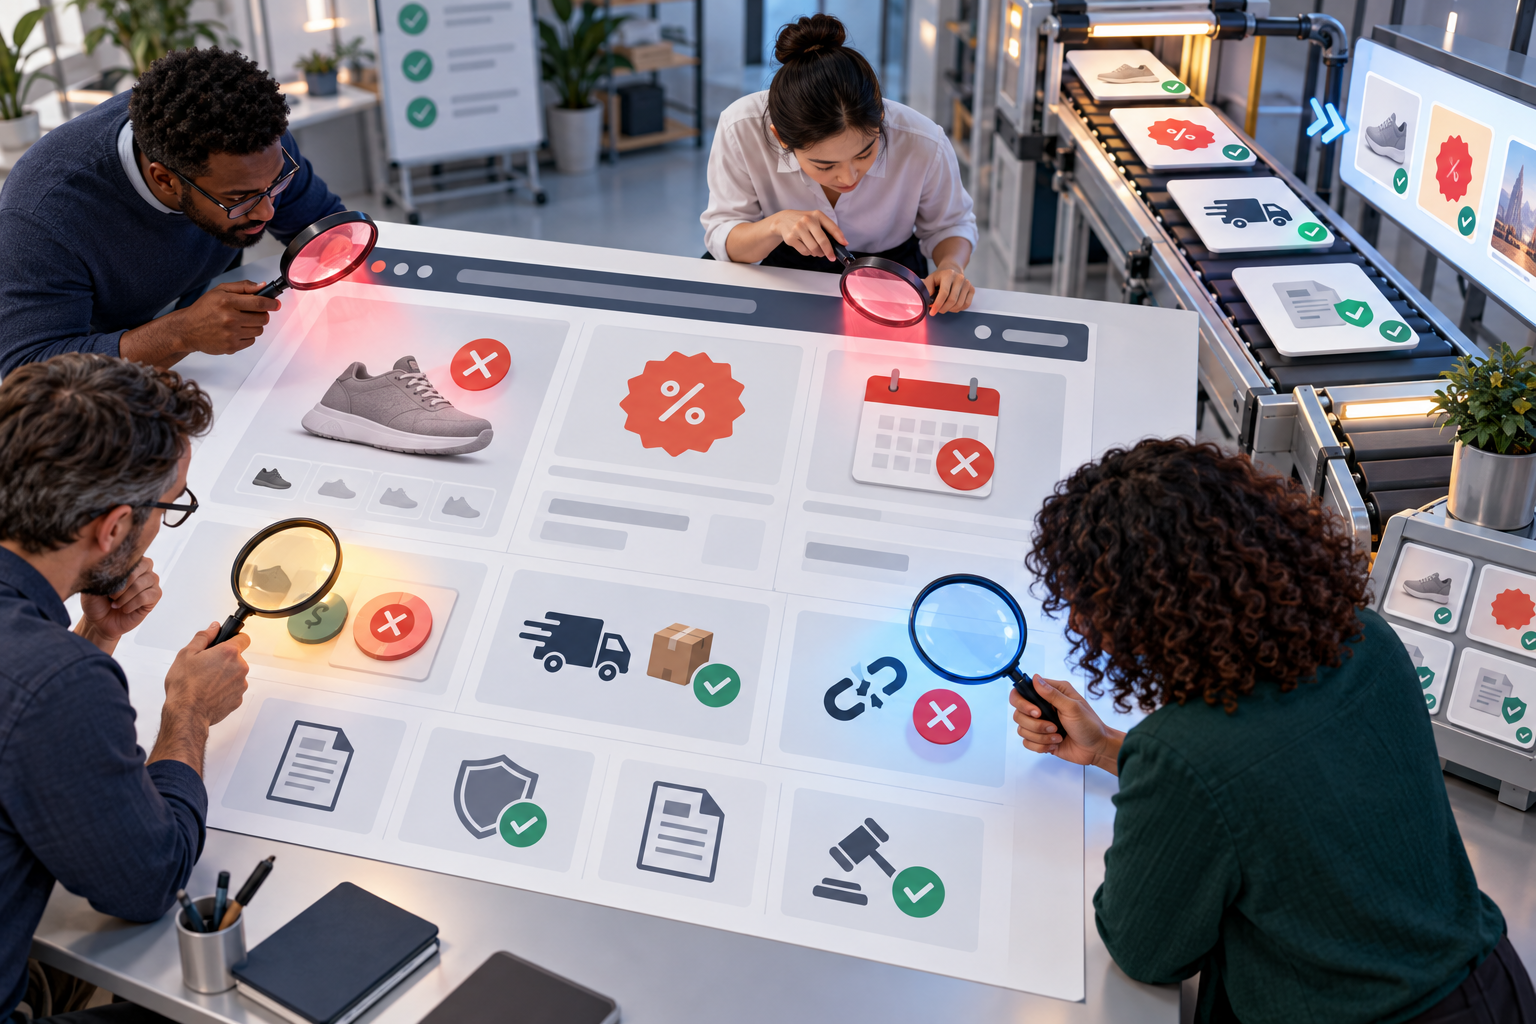
    A review team inspects a website page for expired dates, mismatched prices, unavailable products, and broken links before automation.

    Starting Oct. 12, eligible advertisers may be enrolled automatically. That changes the default risk. Doing nothing is no longer necessarily the same as declining the feature.

    Your first decision is whether the account should participate at all. Keep it enabled when public offers are current, clearly qualified and consistently honored online and in stores. Disable it when promotions require case-by-case approval, depend on complex eligibility rules or frequently remain visible after they expire.

    1. Open the account’s automated asset settings and find Automated Promotions. Record whether it is on or off and who approved that choice.
    2. Inventory public pages that mention discounts, coupon codes, bundles, free items or limited offers. Include store pages when location assets connect campaigns to physical locations.
    3. Make each offer understandable without surrounding marketing copy. State what qualifies, what the customer receives and, where applicable, when and where the offer is valid.
    4. Reconcile the page with the real transaction. Pricing, eligibility and brand wording should agree with the checkout flow, sales process and in-store terms.
    5. After an automated promotion begins serving, inspect it in the Assets section. An asset that has not received impressions will not appear there, so an empty view does not prove that the account is opted out.

    That last distinction matters. The setting tells you whether Google has permission to create automated promotions. The Assets view tells you what has actually accumulated impressions. Check both rather than using one as a proxy for the other.

    If you opt out, use the explicit account-level control. Do not rely on incomplete pages, ambiguous offer wording or the presence of a manually managed asset as an informal safeguard. Automated Promotions can be turned off in automated asset settings, which gives the account team an auditable decision instead of an accidental outcome.

    Launch localization as a new market, not a translation task

    The localization beta can turn one eligible Search campaign into a separate campaign for another language and location. The original campaign remains unchanged. That independence is useful, but it does not make the new campaign commercially ready.

    1. Choose a parent campaign worth reproducing. Fix known targeting, messaging or landing-page problems before translation, or the new campaign will begin with the same structural weaknesses.
    2. Select the exact target language and location. A language label is not a market strategy: Spanish for Spain and Spanish for Latin America and the Caribbean are available as distinct variants in the beta.
    3. Give the AI explicit language rules. Tell it which brand names, product names and technical terms must remain unchanged, and specify whether the voice should be formal or conversational.
    4. Review every campaign component, not just the headlines. The workflow can localize headlines, descriptions, sitelinks, callouts and keywords.
    5. Choose the landing-page method deliberately. You can install a Google-provided JavaScript snippet that dynamically translates page text for visitors from localized ads, or update the campaign URLs to point to pages you already maintain in the target language.
    6. Require a human language and market review. Use the original, localized version and English back-translation shown side by side to check meaning, then ask a fluent reviewer to assess naturalness, search intent, cultural fit and brand terminology.
    7. Reset the economics. Budgets and bids are copied from the original campaign without automatic currency conversion or exchange-rate adjustment. Do not approve launch merely because those fields are populated.

    The landing-page choice deserves particular care. Dynamic translation is a practical route when the underlying offer and customer journey are genuinely the same. A maintained local page is the stronger option when prices, availability, delivery terms, legal wording or conversion steps differ by market. In either case, review the page as the visitor will see it after clicking the localized ad.

    Images also need a separate check. When an image contains text, the workflow can remove the original wording and use the translation as supplemental text assets. Do not assume the output will simply be the same image with perfectly replaced lettering. Preview the complete creative combination and confirm that the visual still makes sense without its original embedded message.

    The beta supports U.S. English Search campaigns localized into Dutch, French, Canadian French, German, Italian, Polish, Brazilian Portuguese, European Portuguese, Spanish for Spain and Spanish for Latin America and the Caribbean. Google plans to add languages by the end of 2026 and later extend localization to Performance Max. Treat that as a roadmap, not as a capability your current launch can depend on.

    Use one release gate for assets, language and money

    Three reviewers check advertising assets, localized language elements, and budget tokens at a single campaign release gate.

    The most reliable control is a short release record shared by the website owner, campaign manager and market reviewer. It should force a yes-or-no decision on the places where automation cannot judge your business obligations.

    • Commercial truth: Is the promoted price or benefit currently available, and will every customer who meets the stated conditions receive it?
    • Qualification: Are exclusions, dates and location restrictions consistent across the ad asset, landing page, checkout or sales process, and physical store where relevant?
    • Language: Has a fluent reviewer approved the customer-facing wording rather than relying only on the English back-translation?
    • Search intent: Do the localized keywords represent how people in that market look for the offer, not merely a literal rendering of the parent keywords?
    • Landing experience: Does the visitor remain in the intended language through the meaningful conversion steps?
    • Economics: Have the copied budget and bids been reviewed for the target market instead of accepted as inherited defaults?
    • Ownership: Is one person responsible for pausing the asset or campaign when an offer, page or market condition changes?

    Use event-based reviews rather than a vague instruction to monitor regularly. Reopen the record when an offer starts or ends, a price or landing page changes, an automated asset first receives impressions, a new localized campaign is generated, or its budget and bids are changed.

    After launch, judge the localized campaign on its own market economics. It is an independent campaign, so the parent campaign’s historical success is context, not proof. For automated promotions, compare the served asset with the live offer page and the transaction customers actually receive. The purpose of monitoring is not just to catch strange wording; it is to catch a broken commercial promise.

    Key takeaways

    • Check the account-level Automated Promotions setting before Oct. 12; eligible advertisers may be enrolled without making an affirmative choice.
    • Treat every public offer page as potential campaign input, especially when Search or Performance Max campaigns use linked location assets.
    • Do not use an empty Assets view as proof that automation is disabled; unserved assets do not appear there.
    • Review localized campaigns as independent market launches, including keywords, creative, landing pages, language quality and cultural fit.
    • Replace copied budgets and bids with a deliberate market decision because the localization workflow does not perform currency or exchange-rate adjustments.

    Your next step is small and concrete: open one eligible account, document its automation setting, then choose one live offer and one possible target market to run through the release gate. That will expose missing ownership and inconsistent inputs before automation exposes them to customers.

    References

  • Ecommerce Advertising Readiness: When and Where to Scale

    Ecommerce Advertising Readiness: When and Where to Scale

    Your campaigns can be approved and spending while your store is still unprepared to scale. The weakness usually appears after demand rises: a feed rejects sale prices, a bestseller runs out, attribution has not caught up, or a promotion turns an apparently healthy return on ad spend into a loss.

    Advertising readiness means knowing what you can profitably sell, trusting the data used to optimize it, and choosing a channel that matches the customer’s current level of intent. Work through those decisions in that order and you can expand without asking automation to repair a broken funnel.

    Key takeaways

    • Do not scale traffic until purchase tracking, product availability, pricing, and contribution margin are reliable.
    • Use Search and Shopping to capture existing demand. Use YouTube to create demand when the lower funnel already converts.
    • Performance Max can distribute ads onto YouTube, but distribution is not a YouTube strategy. You still need deliberate creative, audience logic, measurement, and testing.
    • Segment products by margin, promotion, and stock position so one blended ROAS target does not treat fundamentally different products as equals.
    • Make campaign, feed, approval, and payment changes before a peak period. During the event, monitor exceptions and respect conversion lag instead of repeatedly resetting the system.

    Pass the readiness gate before choosing another channel

    A new channel adds traffic. It does not fix weak economics, inaccurate measurement, or a checkout that already loses qualified shoppers. In fact, sending cold YouTube traffic into a funnel where Search and Shopping traffic does not convert can simply accelerate the existing loss.

    Before increasing spend, give the store a clear pass or fail on four gates:

    1. Lower-funnel performance: Search and Shopping can turn relevant, high-intent visits into completed purchases without unexplained breaks in the journey.
    2. Measurement: transactions, order values, currency, and customer signals reach the advertising platforms accurately enough to guide bidding.
    3. Economics: you know the contribution available after discounts and variable order costs, not just revenue and platform-reported ROAS.
    4. Operations: the feed, stock data, payment methods, landing pages, creative approvals, and alerting process can withstand a sudden increase in demand.

    A failure on any gate determines your next investment. A tracking failure calls for measurement work. A stock or price failure calls for feed operations. A negative contribution margin calls for a commercial decision. None of those problems should be handed to a bidding algorithm as if they were targeting problems.

    Verify the data that bidding will learn from

    Run a test order from the storefront through the complete measurement path. Confirm that the purchase appears once, carries the correct value and currency, and can be reconciled with the order record. Then inspect the supporting stack: server-side measurement where appropriate, Consent Mode, Enhanced Conversions, and offline conversion measurement if meaningful outcomes happen after the online event. These are among the data checks that should be completed before a high-demand period, not during it.

    First-party audiences also need structure. An undifferentiated customer upload tells the platform that every buyer has equal value. Segment usable lists by factors such as average order value and customer lifetime value, then keep acquisition and retention decisions distinct. Apply the same discipline to the audience data used across Google Ads and Meta.

    Finally, document conversion lag. If purchases commonly arrive several days after an ad interaction, the newest dates will always look artificially weak. A reporting delay is not a campaign collapse, and reacting to it every morning can turn normal lag into genuine instability.

    Set a profit boundary before approving a discount

    Revenue-based ROAS can hide whether an order creates value. Start with a product or product-group calculation:

    Net selling price – product cost – variable fulfillment, payment, and expected return costs = contribution before advertising.

    That contribution is the amount available to pay for acquisition and leave profit behind. If you lower the selling price, recalculate it before setting the promotion live. A 15% discount removes part of the margin at the same time acquisition costs may rise. Matching a competitor’s discount without doing this calculation can produce more orders and less profit.

    To judge the promotion, divide the baseline contribution you want to preserve by the new contribution per order. The result is the number of discounted orders required before advertising costs are considered. Then add the expected acquisition cost. If the required volume is implausible, change the offer, limit it to suitable products, or accept that the promotion has a strategic cost rather than pretending it is profitable.

    Give each channel one clear job

    Channel choice becomes easier when you start with the customer’s state. Search and Shopping are pull channels: the shopper expresses intent and the advertiser competes to answer it. YouTube is a push channel: the advertiser interrupts someone who was doing something else and must create enough interest to earn a later action. Those conditions require different creative, timelines, skills, and measurement.

    Channel or campaign typeCustomer statePrimary jobWhat you must control
    Search and ShoppingAlready looking for a product, category, or solutionCapture existing demandQuery or product relevance, offer quality, feed accuracy, bids, margin, and landing-page conversion
    YouTubeNot actively shopping at that momentCreate interest, demonstrate a product, and generate future demandHook, argument, demonstration, proof, audience, creative refresh, and a longer evaluation window
    Performance MaxVaries because inventory spans multiple Google surfacesAllocate spend across eligible inventory toward the configured conversion goalFeed quality, conversion inputs, asset quality, product segmentation, budget, targets, and interpretation of blended reporting

    This distinction matters because Performance Max may already be buying YouTube impressions for your store. It can reuse uploaded assets or, when no video is supplied, assemble video from product images, transitions, and text. That gives the campaign something to serve, but it does not supply positioning, persuasion, creative sequencing, or a channel-specific learning plan.

    Treat Performance Max as a distribution system, not proof that you have a YouTube strategy. A blended conversion total cannot tell you whether upper-funnel impressions created new demand, harvested demand that already existed, or received credit for a purchase that would have happened anyway. Do not accept that number uncritically, but do not make the opposite mistake of testing YouTube once, grading it like Search, and declaring the channel ineffective.

    Use a simple channel decision sequence

    1. If relevant Search and Shopping traffic does not convert, repair the offer, product pages, checkout, feed, or measurement before adding cold reach.
    2. If profitable search demand is still available, capture it before paying to manufacture more awareness.
    3. If existing demand is constrained, or the product is new and lacks search volume, assess whether YouTube can create demand.
    4. If the goal is product discovery, brand awareness that can drive later searches, a time-limited seasonal promotion, or a new-product launch, give YouTube a defined budget and its own measurement plan.
    5. If you cannot produce and refresh persuasive video, postpone the channel rather than allowing generic automated assets to stand in for strategy.

    Build YouTube creative as a persuasion sequence

    A YouTube viewer did not ask to see your product. The creative therefore has to do more than show it. Build each concept around a complete sequence:

    1. Hook: earn attention in the first five seconds.
    2. Problem: make the relevant frustration, desire, or missed opportunity recognizable.
    3. Mechanism: explain how the product addresses that problem.
    4. Demonstration: show the product doing the work instead of relying on a claim alone.
    5. Proof: give the viewer a reason to believe the result.
    6. Call to action: make the next step explicit and consistent with the landing page.

    Creative is the operating cost of this channel. Fatigue arrives faster than it does in intent-led campaigns, so two or three occasional videos are not a substantial testing program. For a serious effort, plan the people, production process, and approval capacity needed to test 20 or 30 videos per month. If that volume is beyond reach, narrow the test deliberately rather than spreading a small set of assets across too many audiences and offers.

    Define success before launch. Direct sales still matter, but the feedback loop is longer and attribution is less clean than it is for Search. Separate YouTube’s budget and evaluation from the assumptions used for demand capture, account for the store’s observed conversion lag, and watch whether the channel is creating the future demand it was assigned to create. Changing the success definition after seeing the result makes the test impossible to interpret.

    Make feed and margin structure govern spend

    An overhead arrangement of unbranded products, packaging, coins, a calculator, and a tablet with abstract product tiles.

    For an ecommerce advertiser, Google Merchant Center is not an administrative afterthought. Its product feed is a core input to Shopping and Performance Max. When availability, price, or identifiers are wrong, automation makes decisions from a distorted catalog.

    Configure the feed around the decisions your team will need to make under pressure:

    • Automate promotional prices. Populate sale_price and sale_price_effective_date with exact start and end timestamps. This allows scheduled price changes and reduces the risk of a mismatch between the website and feed when a sale begins.
    • Protect price-annotation eligibility. If strikethrough pricing is part of the plan, the base price must have been active for at least 30 days within the previous 200 nonconsecutive days.
    • Increase freshness during peak windows. Raise feed synchronization to three or four times per day when prices and inventory are changing quickly.
    • Stop advertising unavailable inventory. Use automated rules or feed scripts to flag and pause out-of-stock SKUs instead of buying visits to products that cannot be ordered.
    • Add commercial labels. Use Custom Label 0 through Custom Label 4 to represent attributes such as actual margin, promotional status, and stock position.

    Do not wait for the promotion to discover whether the feed and checkout disagree. Schedule a sale-price test, verify the timestamps, inspect the landing page and cart, and confirm that a product returns to its normal price after the test window. A valid feed submission is useful, but the shopper experiences the complete path.

    Translate labels into campaign decisions

    Labels become valuable when they change how you allocate spend. A high-margin, well-stocked bestseller can support a different target and budget from a low-margin item with limited inventory. Blending the two under one target ROAS encourages the platform to optimize revenue while concealing the difference in profit.

    • High margin and strong stock: make these products eligible for more assertive acquisition, subject to the contribution boundary.
    • Low margin: use a more defensive target or restrict promotion unless the product has a deliberate strategic role.
    • Promotional: isolate the discounted economics so ordinary-price performance does not subsidize an unprofitable event in the reporting.
    • Low stock: reduce exposure before availability becomes a customer and feed problem.
    • Out of stock: pause promptly and restore eligibility only after the feed and storefront agree.

    Keep a working record for each important SKU or product group: normal price, promotional price, product cost, variable order cost, contribution before advertising, stock position, and active promotion. That record gives the media team a commercial map. Without it, campaign structure is merely technical organization.

    Prepare the peak-period operation before demand arrives

    Workers pack unbranded orders at organized stations in a well-stocked ecommerce fulfillment area.

    Peak-period readiness is mostly timing. A change that is sensible in an ordinary month can be reckless immediately before Black Friday if it triggers a learning period, waits for approval, or alters the data used by bidding. Depending on account size and market, Q4 preparation may need to begin in August or September.

    Sequence the work around risk

    1. Months before demand peaks: validate measurement, segment first-party audiences, repair the lower funnel, calculate promotion economics, and begin warming audiences where demand creation is part of the plan.
    2. Well before the event: launch new campaign structures and bidding strategies early enough to move beyond their initial learning behavior. Upload creative with time for review instead of risking a pending approval on the day before the sale.
    3. Before prices change: test sale attributes and effective dates, confirm stock rules, set feed schedules, fund the advertising account, and add a backup payment method.
    4. During Cyber Week: inspect Merchant Center Diagnostics early each morning, prioritize disapproved bestsellers, and maintain the higher feed-sync frequency.
    5. After each major sales window: wait for the known conversion lag before treating recent ROAS as complete, then compare product-level contribution with the target established before launch.

    Decide in advance how much control you want over rising CPCs and CPMs, including whether a portfolio bid cap belongs in the plan or whether the bidding system will operate without one. The important point is to make that choice from economics and risk tolerance before the auction becomes unusually competitive.

    Monitor exceptions instead of micromanaging campaigns

    Create alerts for payment failures, material CPC changes, rapid budget consumption, feed disapprovals, and inventory problems. Then write the response beside each alert. An alert without a response rule merely creates anxiety; an alert tied to a check and an owner shortens the time to a useful decision.

    • If a bestseller is disapproved, inspect price, availability, and landing-page consistency before changing a bid.
    • If a campaign consumes its daily budget unusually early, check traffic quality, CPC movement, and the promotion schedule before reallocating money.
    • If reported ROAS falls on the newest dates, compare that window with the account’s normal conversion lag before changing targets.
    • If stock becomes scarce, use the stock label or automated rule to reduce exposure rather than continuing to sell demand you cannot fulfill.
    • If a payment method fails, switch to the verified backup before delivery stops during the most valuable traffic window.

    Frequent intervention can be as damaging as neglect. When conversion lag is several days, daily changes based on incomplete purchases make each decision depend on a partial result. Reserve emergency changes for genuine operational failures or clearly breached financial boundaries. Let ordinary performance accumulate enough evidence to judge.

    Your next move is not automatically another campaign. Choose one upcoming promotion or product launch and score it against the four readiness gates. Fix the first failed gate. When all four pass, assign Search, Shopping, Performance Max, or YouTube a precise job, budget, success measure, and stopping condition. That is the point at which scaling becomes a controlled decision rather than a bet.

    References


  • Why More Paid Search Budget Stops Producing More Leads

    Why More Paid Search Budget Stops Producing More Leads

    Your paid-search account can look healthy right up to the moment you try to scale it. You increase the budget, spend rises, and clicks follow – but qualified leads barely move. The instinct is to blame bids, keywords, ad copy, or the agency. Often, however, the account has reached the limit of the demand available to capture.

    Your real decision is not whether paid search works. It is whether you are missing profitable, high-intent searches or asking a demand-capture channel to manufacture demand. That distinction tells you whether the next dollar belongs in search, conversion work, sales follow-up, or the channels that create recognition and trust before a search happens.

    Key takeaways

    • Paid search scales efficiently only while valuable, existing demand remains uncaptured.
    • Judge a budget increase by its marginal cost per qualified lead, not the account’s blended cost per lead.
    • Separate brand, high-intent non-brand, broader non-brand, and Local Services Ads before diagnosing a growth ceiling.
    • Search ads can capture or confirm preference, but they cannot carry the entire burden of building recognition, evidence, and trust.
    • When incremental search spend stops producing qualified opportunities, protect the profitable core and invest in creating future demand.

    The ceiling appears when demand capture is mistaken for demand creation

    Paid search is strongest when a prospective customer has already expressed a need. The person searches for a service, product, problem, or brand; the platform runs an auction; and an eligible advertiser competes for that attention. Increasing the budget can capture more leads when valuable searches exist and your ads are missing them because the account is constrained.

    But the supply of relevant searches is not unlimited. Once you are consistently present for the queries, locations, and times that produce good customers, additional spending has to find volume somewhere else. It may enter more expensive auctions, reach broader queries, accept weaker intent, or buy additional clicks from people who are less likely to become customers. Spend can keep scaling after qualified demand stops scaling.

    A budget increase is therefore most promising when all four of these conditions are true:

    • Your ads are being withheld from proven, high-intent searches because the budget is exhausted.
    • The missed searches occur in locations and operating periods your business can serve.
    • The additional queries resemble those that already produce qualified opportunities or sales.
    • Your landing pages, call handling, qualification process, and sales team can absorb more demand without lowering conversion quality.

    If those conditions are not present, more budget is not a growth strategy. It is permission for the platform to pursue increasingly marginal inventory.

    Brand campaigns make the distinction especially easy to miss. Someone who searches for your company by name has usually encountered it elsewhere. Bidding on that name may help you capture the visit, but it did not necessarily create the recognition that caused the search. Prospects now encounter businesses through ChatGPT, Reddit, Facebook, LinkedIn, YouTube, videos, customer stories, events, and other online and offline touchpoints before they type a final query.

    That prior exposure changes what the ad is being asked to do. For a familiar business, a search ad can reassure the buyer that they have found the right company. For an unfamiliar business, a few lines of ad copy must compete against every doubt the prospect has about its credibility. Raising the bid does not resolve that trust gap.

    The search results page itself can also redistribute attention without creating more underlying demand. AI Overviews can compress what people see near the top of a results page. A reported Google test gave Local Services Ads larger images and a more prominent information area, potentially making participating businesses more noticeable and pushing other results farther down. That format remains a test with no confirmed broad rollout. Even if it expands, a more visible ad unit can change who wins an existing local inquiry; it does not guarantee that more people will need a plumber, roofer, HVAC contractor, or other local provider.

    Diagnose the constraint before approving another increase

    An analyst inspects the narrow junction in a transparent marketing pipeline as tokens accumulate upstream.

    Do not start the diagnosis with the account-wide cost per lead. A blended average can remain attractive while the newest portion of spending performs poorly. Cheap branded conversions, repeat visitors, and strong Local Services Ads can conceal an expensive expansion into weaker non-brand traffic.

    Use this constraint audit instead:

    1. Separate the demand pools. Report brand search, high-intent non-brand search, broader or adjacent queries, and Local Services Ads independently. If materially different intentions are mixed together, you cannot see which pool is actually scaling.
    2. Find where proven demand is being missed. Look for valuable searches your campaigns could serve but do not because the available budget runs out. Check whether that loss occurs in profitable locations and periods, rather than treating every missed impression as equally valuable.
    3. Measure the incremental layer. Compare the extra spend with the extra qualified leads it produced. Do not give the increase credit for leads the previous budget was already generating.
    4. Follow leads past the form or phone call. Count how many new leads meet your service area, need, customer profile, and sales criteria. Then examine appointments, opportunities, or sales. A rising form count with flat sales volume is not successful scaling.
    5. Inspect the handoff. If qualified inquiries are being missed, answered slowly, routed incorrectly, or left without sales follow-up, buying more clicks adds pressure to a broken step. Repair the handoff before enlarging the campaign.
    6. Check the pre-search environment. If branded demand is flat and unfamiliar prospects rarely convert, the limiting factor may be awareness or trust rather than search coverage.

    The most useful calculation is simple: marginal cost per qualified lead equals additional spend divided by additional qualified leads. If an account moves from one budget level to another, isolate only the spending increase and only the qualified-lead increase. When the denominator is zero, the added budget produced no measurable qualified-lead lift, regardless of how healthy the blended dashboard still looks.

    Interpret the result in context:

    What you observeLikely constraintWhat to do next
    Proven, high-intent searches are missed because the budget runs outCapture capacityRun a controlled budget increase and measure incremental qualified leads
    Clicks and spend rise, but qualified leads remain flatDemand or traffic-quality ceilingStop expanding broadly and examine query intent, market awareness, and trust
    Raw lead volume rises, but opportunities or sales do notQualification, offer, landing-page, or sales-handoff problemRepair the failing stage before buying more traffic
    Brand and local campaigns perform well, but branded demand is not growingAwareness constraintFund consistent discovery and trust-building activity outside search
    Qualified leads rise, but the marginal cost exceeds their economic valueEconomic ceilingKeep the profitable base and reject the uneconomic increment

    This audit prevents a common reporting error: interpreting the ability to spend as evidence of the ability to scale. Advertising platforms are usually capable of spending more. Your market may not be capable of returning more qualified demand at the same cost.

    Build a growth system around search, not entirely inside it

    A central search hub connects to surrounding modules for content, awareness, landing pages, referrals, sales follow-up, and measurement.

    A durable lead-generation system gives different channels different jobs. Trying to make every channel produce an immediately attributable form submission leads to underinvestment in the work that makes later conversion possible.

    Create recognition before the buyer searches

    Use the places your prospects already pay attention to: industry events, professional networks, relevant communities, YouTube, paid social, connected TV, trade media, or local offline media. The correct mix depends on where your buyers actually discover and evaluate providers. There is no universal percentage that should move from search into each channel.

    AI-assisted discovery now belongs in that map. A buyer may ask ChatGPT for possible approaches or encounter a business in a community discussion before opening Google. Search-only planning ignores those earlier encounters. For your content program, that means answering the commercial questions buyers investigate before contacting anyone: who the offer is for, what problem it solves, where it is available, how the process works, what evidence supports it, and what the sensible next step is.

    Give buyers evidence they can use to reduce risk

    Recognition gets you considered; evidence makes the consideration credible. Useful evidence may include clear demonstrations, customer success stories, detailed service pages, educational material, credible third-party coverage, and answers to the objections sales teams hear repeatedly.

    This work matters most when the purchase is expensive, unfamiliar, or slow. Prospects may evaluate a company for weeks, months, or even a year. A text ad can provide the route back when they are ready, but it cannot substitute for the body of evidence they encountered during that period.

    Let paid search capture and confirm intent

    Keep paid search focused on the job it performs well: meeting people who express a relevant need, protecting high-value brand and local visibility, and making the next action obvious. Search does not become less important in a multichannel system. It becomes more accountable because you stop expecting it to perform every stage of the buyer journey.

    Measurement should reflect that division of labor. Search may record the final conversion even when earlier exposure created the preference. Review branded-search movement, direct and returning visits, engagement with demonstrations or customer evidence, sales feedback about prior touchpoints, and qualified pipeline alongside campaign conversions. None of these signals alone proves causation, but together they help you distinguish growing demand from merely reallocating credit for it.

    Test a higher budget without funding the ceiling

    You do not need to choose between endlessly increasing search and cutting it. Treat the next increase as a controlled business test with an explicit constraint, economic threshold, and decision rule.

    1. Write the hypothesis. State exactly why additional budget should produce additional qualified demand. For example: proven high-intent searches are being missed because the daily allocation is exhausted in serviceable markets.
    2. Protect the profitable base. Identify the campaigns, locations, queries, and lead types that already meet your economics. Do not destabilize them merely to create a larger experiment.
    3. Isolate the increment. Track the added budget separately from the established level. Keep the conversion definition, targeting logic, geography, and other major variables stable enough to make the result interpretable.
    4. Define quality before launch. Decide what qualifies as a useful lead and which downstream outcome matters. If the team changes the definition after seeing the result, the test cannot answer the original question.
    5. Set the economic boundary. Estimate what a qualified lead can be worth from the gross profit of a new customer and the proportion of qualified leads that become customers. Do not scale an incremental lead source whose cost exceeds the value it can reasonably return.
    6. Preserve demand-building activity. Do not cut awareness, video, social, content distribution, or other discovery work while testing whether search can capture more demand. Changing both sides at once makes the result ambiguous and can shrink the future searches the campaign depends on.
    7. Allow for the normal sales cycle. Judge the test after enough time has passed for the added leads to reach the downstream outcome you selected. Fast form volume should not be mistaken for pipeline when qualification and sales take longer.
    8. Apply the decision rule. Continue cautiously if incremental qualified leads remain inside the economic boundary. Stop the expansion if spend rises without qualified-lead lift. If qualified leads rise but sales do not, investigate the offer, qualification process, or handoff rather than purchasing still more traffic.

    Consistency also matters when you test demand creation. One documented medical-device launch spent $40,000 over four months and was later advised to use a steady $4,000 to $5,000 monthly awareness investment after disappointing lead performance. Those amounts belong to that account and are not a benchmark for yours. The transferable lesson is that a short spending burst may be a poor test of an activity intended to build familiarity and trust over a long buying journey.

    A practical budget structure has three parts: a protected core for proven demand capture, a controlled reserve for testing incremental search inventory, and a sustained allocation for creating recognition and trust. Set the amounts from your own marginal economics and buying cycle, not from a generic channel split.

    At your next budget review, do not ask only whether paid search can spend more. Ask which constraint the next dollar will remove. If it buys missed, profitable intent, scale it deliberately. If it only reaches weaker versions of demand you already capture, keep the profitable search engine intact and put the next dollar to work creating the buyers it will serve later.

    References


  • Marketing Investment and Incrementality: A Practical Guide

    Marketing Investment and Incrementality: A Practical Guide

    You have a campaign with a healthy return on ad spend, a partner claiming attributed sales, and a finance team asking whether the next dollar should stay. Those facts can all coexist even when the campaign created little new demand. If the budget decision rests on attribution alone, you can reward the channel that was best at standing near an existing sale.

    Incrementality gives you a better basis for that decision. It estimates what changed because of the investment, counts what the investment really cost, and separates a profitable growth engine from activity that merely collected credit. The same discipline works for paid media, commerce networks, SEO and GEO programs, content operations, and AI automation.

    Start with the decision, not the dashboard

    Attribution and incrementality answer different questions. Attribution assigns credit among observed touchpoints. Incrementality asks whether the outcome would have occurred without the marketing activity. That distinction matters because a person exposed to an ad may have purchased anyway.

    Measurement approachQuestion answeredUseful forMain failure mode
    AttributionWhich touchpoint received credit for an observed conversion?Reporting journeys, managing campaigns, and diagnosing channel interactionsCrediting marketing for demand that already existed
    IncrementalityHow much did the outcome change because the investment was present?Budget allocation, forecasting, renewal decisions, and growth planningUsing a weak or contaminated comparison as the counterfactual

    You can never observe the same customer at the same moment both with and without an intervention. A credible test therefore constructs a counterfactual: a comparable estimate of what would have happened without the investment. The quality of that estimate determines whether your lift number is useful.

    Write the decision before choosing a metric. A practical decision statement is: For this eligible population, will this investment produce enough additional business value over this comparison to clear our economic hurdle? Every term needs an operational definition.

    • Eligible population: The customers, accounts, regions, queries, pages, or workflows that could realistically receive the intervention.
    • Investment: The exact spend, campaign, content program, partner, tool, or process change being evaluated.
    • Primary outcome: One business result that can change the decision, such as completed purchases, qualified opportunities, retained customers, or accepted production output.
    • Comparison: A randomized holdout, matched market, staged rollout group, or another defensible estimate of the no-investment outcome.
    • Economic hurdle: The minimum contribution, payback, capacity gain, or other finance-approved result required to justify the investment.

    Use an outcome hierarchy

    A campaign can improve a platform metric without improving the business. Prevent that confusion by assigning each metric a role before launch:

    • Primary outcome: The result that decides whether to invest, such as incremental contribution or qualified pipeline.
    • Guardrails: Results that must not deteriorate, such as margin, return rates, lead quality, publishing accuracy, or customer retention.
    • Diagnostic metrics: Impressions, clicks, rankings, citations, AI visibility, engagement, and other signals that help explain why the primary outcome moved.

    Transaction proximity can make measurement cleaner because the path from exposure to purchase is shorter. It does not, by itself, prove causation. Closed-loop purchase data can show that an exposed customer bought; only a credible comparison can estimate whether the exposure changed that customer’s behavior.

    Count the full investment, including hidden AI labor

    A transparent worktable reveals human review, computing infrastructure, data preparation, and quality control beneath a small set of visible campaign costs.

    Incremental revenue is not enough to justify an investment. You need to compare incremental economic value with the complete cost of producing it. Media spend and software subscriptions are visible. Learning time, quality control, data preparation, creative production, agency support, and operational rework often are not.

    The visibility gap is especially pronounced with AI initiatives. An NBER working paper surveying about 6,000 senior executives across four countries found that 69% used AI for less than one hour a week and 28% did not use it at all. Decision-makers who are distant from production can see a subscription price and a fast output without seeing the workflow construction, failed runs, checking, correction, and governance underneath it.

    Build an investment ledger with separate lines for:

    • Media, platform, network, and technology fees.
    • Creative, content, landing-page, feed, and schema production.
    • Agency, contractor, analytics, engineering, and legal or compliance support.
    • Data acquisition, identity resolution, tagging, storage, and measurement.
    • Internal planning, campaign operations, stakeholder review, and reporting time.
    • Training, workflow design, prompt or automation development, and rollout support.
    • Quality assurance, fact-checking, editing, exception handling, and rework.
    • Incremental fulfillment, support, discounts, returns, and other variable costs created by the additional business.

    For an AI-enabled marketing investment, run a 30-day labor audit before defending its efficiency. Have the people doing the work record time in four distinct categories: learning tools, operating workflows, checking and repairing outputs, and editing or fact-checking long-form work. Explain that the audit measures the process rather than individual performance. Anonymous aggregation can reduce the pressure to underreport.

    Separate setup costs from recurring costs. A pilot may look expensive because it includes workflow design and training that will not recur at the same level. The reverse also happens: an impressive demonstration can omit the continuing cost of review, maintenance, data cleanup, and failures in daily use. Show both the learning-period economics and the expected steady-state economics instead of averaging them into one reassuring number.

    Keep the financial calculation legible

    Do not hide the business case inside one blended percentage. Show these lines separately:

    • Incremental outcome: The observed result minus the estimated no-investment result.
    • Incremental net revenue: Revenue attributable to the incremental outcome, after cancellations, discounts, or returns where applicable.
    • Incremental contribution before marketing: Incremental net revenue minus the variable costs required to deliver it.
    • All-in marketing investment: The cash and labor costs required to run and measure the intervention.
    • Net incremental value: Incremental contribution before marketing minus the all-in marketing investment.

    If finance uses a different contribution or payback definition, use that definition consistently. Do not silently substitute platform revenue for finance-approved value. Show opportunity cost alongside the calculation: what work, campaign, or capacity did this investment displace? That cost may not belong in the formal ratio, but it belongs in the decision.

    Run a test that can change the budget

    Two matched miniature commercial districts are compared, with an abstract marketing intervention applied to one district while the other remains untreated.

    A useful incrementality test is designed backward from a decision. It does not begin with whatever report a platform happens to provide. Before money moves, document the following:

    1. Choose one primary decision metric. Secondary metrics can explain the result, but they must not replace the primary outcome after the data arrives.
    2. Define the unit of assignment. Depending on the investment, this may be a customer, household, account, region, page group, topic cluster, or production workflow.
    3. Select the strongest practical comparison. Randomized holdouts are usually the cleanest option when assignment and exposure can be controlled. Matched geographies, staggered rollouts, or time-based switchbacks can be useful when individual randomization is not feasible.
    4. Set the observation window and detectable effect in advance. Base test size and duration on the normal outcome rate, expected variability, and the smallest lift worth acting on. A monthly meeting date is not a measurement rationale.
    5. Record contamination and operational changes. Cross-channel exposure, audience overlap, internal linking, promotions, pricing changes, stock constraints, sales activity, and mid-test optimizations can all make the comparison less credible.
    6. Pre-commit to actions. State what result will lead you to scale, repair, retest, or stop. This prevents a favored program from receiving a new success definition after it misses the original one.

    Choose the comparison design that fits the investment

    • Randomized audience holdout: Use when you can assign eligible people or accounts to treatment and control and can observe the business outcome for both groups. Watch for people receiving the campaign through another platform or device.
    • Geographic holdout: Use when media exposure or commercial activity can be separated by market. Match markets on relevant baseline behavior and account for local promotions, distribution, competitors, and seasonality.
    • Staggered rollout: Introduce the program to comparable units at different times. This can suit SEO, GEO, content, platform, or workflow changes when a permanent control is impractical. Keep rollout order from simply mirroring business priority or existing performance.
    • Switchback design: Alternate treatment and comparison periods when simultaneous holdouts are unavailable. This is vulnerable to day-of-week effects, seasonality, carryover, and changes in demand, so the time blocks must reflect how quickly the intervention’s effect starts and fades.
    • Pre/post comparison: Use only when stronger designs are unavailable. Demand, competition, algorithms, distribution, and pricing can change between periods, making a simple before-and-after result easy to misread.

    Match the outcome to the type of investment

    InvestmentPossible assignment unitDecision-grade outcomeCommon contamination risk
    Commerce or retail mediaCustomer, household, or geographyCompleted purchases, incremental contribution, or new-customer valueExposure through overlapping networks or promotions
    Paid search or paid socialAudience cell, customer, or geographyQualified conversions, contribution, or pipelineRetargeting and cross-device exposure
    SEO, AEO, or GEO programEligible page group, topic cluster, market, or rollout waveQualified organic demand, leads, or attributable business valueInternal-link, brand, and domain-level spillover
    AI marketing automationTask type, workflow, team, or rollout waveAccepted outputs, time per accepted output, throughput, or defect-adjusted capacityUnrecorded manual work and people switching between old and new processes

    For SEO, AEO, and GEO work, rankings, mentions, citations, and visibility are valuable diagnostics. They are not automatically incremental business outcomes. If visibility is the strategic objective, define it that way before the program begins. If revenue, leads, or qualified demand is the objective, do not substitute visibility after launch because it improved first.

    Report uncertainty with the point estimate. A positive estimate surrounded by a wide range of plausible outcomes is not the same as dependable positive lift. If the plausible range includes both no effect and an economically valuable effect, the result is inconclusive. That does not prove the investment failed, but it also does not justify describing success as established.

    Statistical significance and economic significance are also different. A precisely measured lift can still be too small to cover the investment. A larger but uncertain estimate may deserve another test rather than an immediate scale-up. Let the economic hurdle and the cost of making the wrong decision determine the next step.

    Turn lift into allocation rules and partner requirements

    An incrementality result becomes valuable when it changes allocation. Put each tested investment into one of four decision states:

    • Scale: Lift is credible, net incremental value clears the agreed hurdle, and guardrails remain acceptable. Increase investment in controlled steps and remeasure because response can weaken as reach expands.
    • Repair: The activity creates additional outcomes, but fees, labor, margin, lead quality, or operational burden make the economics unattractive. Fix the cost structure or targeting before buying more volume.
    • Learn: The result is inconclusive, but resolving the uncertainty is worth more than the cost of another test. Improve assignment, sample size, tracking, or exposure separation rather than repeating the same design.
    • Stop or reallocate: Credible evidence shows little lift, negative value, unacceptable guardrail damage, or no realistic path to trustworthy measurement. Continuing because a platform reports attributed conversions compounds the original error.

    Partner selection should support this process. For commerce media, compare options across scale and purchase intent, measurement, activation, working relationship, and proximity to the transaction. A large reachable audience is less valuable when it is passive or difficult to measure. A smaller, high-intent audience can be more useful when exposure, purchase, and comparison data are clear.

    Any evaluation framework supplied by a media network should organize your diligence, not serve as independent proof of lift. Before committing budget, ask each prospective partner:

    • How are treatment and comparison groups created?
    • Can the comparison group still receive ads through another placement, network, campaign, or device?
    • Which outcome is primary, and when is that outcome considered complete?
    • Are reported sales new to the business, shifted from another channel, accelerated from a later date, or merely attributed to the exposure?
    • How are repeat purchasers, new customers, cancellations, returns, and duplicated conversions handled?
    • Will the partner report uncertainty, group sizes, exclusions, and failed assignments as well as the lift estimate?
    • Can your analysts inspect sufficiently detailed data and methodology to reproduce or challenge the conclusion?
    • Will campaign optimization remain stable during the test, or will the platform change delivery in ways that undermine the comparison?
    • If customer lifetime value is used, which portion is observed and which portion is forecast?
    • Can the test be repeated after spend, audience, creative, or season changes?

    No partner needs to solve every marketing problem. One may offer strong purchase signals and limited reach; another may provide scale but a weaker counterfactual. Build a portfolio around the jobs each partner can actually perform, then compare the incremental value of those jobs against their all-in costs.

    Use a one-page investment memo

    Give leadership a decision document rather than a dashboard tour. Keep it to six lines of argument:

    1. Decision: The budget, renewal, rollout, or allocation choice that must be made.
    2. All-in investment: Cash, labor, setup, recurring operations, measurement, and material opportunity cost.
    3. Test: Eligible population, assignment unit, counterfactual, primary outcome, window, and known contamination.
    4. Result: Incremental outcome and its uncertainty, with attributed performance shown separately.
    5. Economics: Incremental net revenue, contribution before marketing, all-in investment, and net incremental value.
    6. Action: Scale, repair, learn, or stop, including the next budget level and the condition that would reverse the decision.

    This format also improves conversations about AI investment. Instead of arguing whether AI is broadly fast, useful, or inevitable, you can show the workflow affected, the human effort consumed, the accepted output produced, the quality guardrails, and the capacity or financial value that changed.

    Key takeaways

    • Attributed revenue tells you where credit landed; incrementality estimates how much business the marketing activity actually created.
    • Define the budget decision, eligible population, counterfactual, primary outcome, and economic hurdle before the campaign or rollout begins.
    • Count the full investment. For AI workflows, include learning, operation, output repair, editing, and fact-checking time rather than measuring only subscriptions or generation speed.
    • Use the strongest feasible comparison design, document contamination, and distinguish an inconclusive result from evidence of no lift.
    • Judge partners by the quality and transparency of their incrementality method, not just their attributed sales, audience scale, or dashboard polish.
    • Translate every result into a pre-agreed action: scale, repair, learn, or stop.

    Before your next budget review, choose one disputed investment and write its decision statement. Build the all-in cost ledger, name the counterfactual, and agree on the action thresholds before asking for another report. That small change turns incrementality from a measurement project into an allocation discipline.

    References


  • Google Ads Smart Bidding: The 50-Conversion Benchmark

    Google Ads Smart Bidding: The 50-Conversion Benchmark

    You changed a Smart Bidding strategy, performance moved, and Google Ads now shows a Learning status. The difficult decision is whether to wait, reverse the change, or treat the movement as evidence that something is wrong.

    The short answer is that 50 conversions is not a minimum requirement or a guaranteed turning point. Google says calibration can take up to roughly 50 conversion events or three conversion cycles, with faster learning possible when useful historical data already exists. Treat those figures as planning boundaries for diagnosis, not as a finish line the campaign must cross before it can work.

    The 50-conversion figure is a benchmark, not an entry fee

    A Smart Bidding strategy does not sit idle until conversion number 50. It bids while it is learning. The approximate 50-event figure describes how much feedback calibration may require after a qualifying change; it does not mean every campaign needs 50 conversions before automation becomes usable.

    It is also not a 50-conversions-per-month rule. Calendar months are arbitrary boundaries to a bidding system. What matters is the stream of conversion feedback available after the change and how quickly that feedback arrives.

    The second part of the benchmark matters just as much: three conversion cycles. A conversion cycle is the time between the traffic being generated and the resulting conversion feedback arriving. If customers tend to convert after a delay, the bidder cannot immediately observe the eventual outcome of recent auctions. A week of elapsed time can therefore contain plenty of traffic but little mature conversion evidence.

    That distinction corrects four common misreadings:

    • You do not have to accumulate 50 conversions before enabling Smart Bidding.
    • The 50th event does not guarantee that performance will suddenly stabilize or meet your business target.
    • Fifty clicks, leads in a separate system, or other uncounted actions are not substitutes for the conversion events available to the bidding strategy.
    • A campaign with strong relevant history may calibrate before it reaches the approximate upper benchmark.

    Use the benchmark to answer a narrow question: has the bidder had a reasonable opportunity to observe outcomes since the material change? Keep that separate from the larger question of whether the campaign is profitable.

    Estimate learning time with two clocks

    Two numeral-free clocks connected to a learning system, one surrounded by event signals and the other by three broad cycle rings.

    Asking how many days Smart Bidding needs is usually too imprecise. Two campaigns can be the same age while giving the bidder very different amounts of usable information. Track a volume clock and a feedback-latency clock instead.

    Planning signalQuestion to answerHow to use it
    Conversion-event volumeHow many relevant conversion events have arrived since the change?Compare the observed count with the approximate 50-event calibration benchmark. Do not treat 50 as a required quota.
    Conversion-cycle lengthHow long does it normally take conversion feedback to arrive after traffic occurs?Use up to three cycles as the alternative time frame. Recent traffic may still be too immature to judge.
    Historical conversion dataDoes the strategy already have useful evidence from before the change?Expect that relevant history may shorten calibration, but do not assume that unrelated or obsolete history will settle the current decision.
    Change historyDid another material edit happen during the observation period?Separate the periods in your change log. Otherwise, you may attribute one change’s effect to another.

    For rough capacity planning, you can calculate a volume-only estimate as follows: subtract the conversion events already observed from 50, then divide the remainder by the campaign’s recent average conversion events per day. This is not an official completion forecast. Conversion rates fluctuate, historical data can accelerate calibration, and delayed outcomes can make the most recent days look artificially weak.

    The practical lesson for a low-volume campaign is simple: the same amount of algorithmic feedback can require much more calendar time. If conversion events arrive slowly, checking the campaign every few days does not create new evidence. It only creates more opportunities to interrupt learning with another edit.

    Do not manufacture apparent volume by redefining a shallow action as a primary conversion merely to approach 50. That changes what the bidder is being asked to optimize. More signals are not better when they represent the wrong business outcome.

    Performance Max needs an additional expectation check. It can take longer to reach performance goals when most traffic comes from channels outside Search or Shopping. If that describes your campaign, avoid transferring a Search campaign’s calendar expectations directly onto Performance Max.

    Protect the learning period from overlapping changes

    A glowing network develops inside a protective dome while hands pause above several surrounding control levers and dials.

    A campaign can enter Learning when you create or reactivate a bidding strategy, change its settings, or make certain changes to campaign composition. Changes to conversion goals are also relevant for Search, Shopping, and Performance Max campaigns.

    This creates a change-control problem. If you edit the bidding strategy, alter the goal, adjust the campaign again, and then judge the combined result, there is no clean observation window. You will know that performance changed, but not which intervention deserves credit or blame.

    Before making a material change, create a short learning record with:

    • The exact time and date of the change.
    • The campaign and bidding strategy affected.
    • The setting, campaign composition, status, or conversion goal that changed.
    • The conversion events the strategy is intended to optimize.
    • The typical conversion-cycle length used for planning.
    • The accumulated conversion-event count you will review after the change.
    • The business guardrails that would justify intervening before calibration is complete.

    Then give the change a clean observation period when business risk allows it. This is particularly important during the initial Performance Max learning period, when frequent budget, bidding-strategy, and campaign-status changes can be counterproductive.

    A clean observation period does not mean ignoring the account. Monitor measurement, spend, and lead or transaction quality throughout. The restraint applies to unnecessary optimization edits, not to detecting broken tracking or containing unacceptable cost.

    Know when to wait and when to intervene

    The Learning label is not a command to leave a campaign untouched at any cost. Advertising spend is real exposure. Your decision should combine calibration evidence with measurement integrity and business limits.

    1. Check measurement first. Confirm that the intended conversion events are still being recorded and that the bidder is optimizing toward the outcome you actually value. If tracking is broken or the wrong goal is active, waiting for more data only gives the system more bad information.
    2. Identify the most recent material change. Use that point as the start of the current observation period. If several changes overlap, document each one before drawing a causal conclusion.
    3. Read both learning clocks. Count relevant conversion events and assess how many conversion cycles have had time to mature. Do not substitute impressions, clicks, or elapsed days for conversion feedback.
    4. Apply business guardrails. Continue observing when measurement is sound, the campaign remains within tolerable cost boundaries, and it is still inside the approximate calibration window. If spend is creating unacceptable exposure, protect the budget even though another change may lengthen learning.
    5. Escalate the diagnosis after a fair opportunity. Once the strategy has seen roughly the benchmark amount of evidence or enough conversion cycles, continuing volatility does not automatically prove that Smart Bidding failed. It does mean that learning alone is no longer a sufficient explanation.

    When that last condition applies, inspect the inputs and constraints rather than repeatedly toggling the strategy. Check whether the selected conversion goal represents the desired outcome, whether recent changes altered campaign composition, whether traffic quality shifted, and whether the business target is compatible with the campaign’s available opportunities. These are different problems, and none is solved merely by waiting for a Learning status to disappear.

    The most useful decision rule is therefore conditional:

    • Wait when measurement is valid, the change is understood, the campaign is still accumulating meaningful evidence, and spend remains within your limits.
    • Investigate now when conversion tracking appears broken, the wrong goal is active, or another change has contaminated the observation period.
    • Intervene when the financial exposure is unacceptable. Learning is not a reason to ignore a budget or cost boundary.
    • Broaden the diagnosis when sufficient event volume or conversion-cycle time has passed but the campaign still misses the outcome that matters.

    This framework prevents opposite mistakes: aborting a sound strategy before delayed outcomes arrive, and excusing persistent underperformance indefinitely because automation is supposedly still learning.

    Key takeaways

    • Roughly 50 conversion events is an approximate upper calibration benchmark, not a universal eligibility requirement.
    • Three conversion cycles account for delayed feedback that a simple day count misses.
    • Conversion volume, conversion-cycle length, bidding strategy, and available history can all affect calibration time.
    • Low-volume campaigns may need more calendar time because they accumulate conversion evidence slowly.
    • Frequent changes make the learning period harder to interpret and can prolong the path to a useful decision.
    • Broken measurement, an incorrect conversion goal, or unacceptable spend warrants action before any numerical benchmark is reached.

    For your next Smart Bidding change, record the event count, conversion-cycle expectation, and acceptable spend boundary before you edit the campaign. When performance moves, you will have a defined basis for waiting, investigating, or acting instead of treating day 50 or conversion 50 as a magic answer.

    References


  • Holiday Display Ad Costs: A Practical 2026 Budget Plan

    Holiday Display Ad Costs: A Practical 2026 Budget Plan

    You are deciding whether to spend before Black Friday or preserve your display budget for the peak shopping period. The 2026 cost signal supports an early move, but for a specific purpose: buy less expensive prospecting reach, learn which value proposition works, and build audiences you can approach again when purchase intent strengthens.

    That is not a reason to spend simply because impressions are cheaper. CPM is only the price of access to an audience. If cautious shoppers ignore the offer, inexpensive exposure can still produce expensive customers. Your budget plan therefore needs two controls: one for media cost and another for commercial results.

    Read the 2026 cost drop as an opportunity, not a forecast

    AdRoll activity from July 1 through September 8 showed a pronounced decline in display pricing. Prospecting CPMs were 45% lower year over year and 25.5% below the comparable Q2 period. Retargeting CPMs were 29.1% lower year over year and 40.2% below the comparable Q2 period.

    Display activityYear-over-year CPM changeChange from comparable Q2 periodWhat it means for your plan
    Prospecting45% lower25.5% lowerTest new audiences and messages before peak competition intensifies.
    Retargeting29.1% lower40.2% lowerReconnect with known visitors, but let the size and quality of your audience limit spending.
    Account-based marketing4.4% higher15.1% lowerBudget against the value of named accounts rather than broad-market CPM trends.

    These figures describe relative changes, not a universal dollar price for holiday inventory. They do not tell you the CPM your account, audience, placement, geography, or buying platform will receive. Treat them as a directional benchmark for the AdRoll activity captured during that period, then compare the signal with your own live auction prices.

    The timing matters too. A decline measured before the holiday rush does not guarantee that inventory will remain inexpensive around Black Friday or Cyber Monday. Competition can intensify as more advertisers enter the auction. The useful conclusion is that an early testing window may exist, not that peak-period media has become permanently cheaper.

    Demand conditions also point in two directions. U.S. inflation held at 3.4% in August, while the University of Michigan consumer sentiment index fell to 47.8 in September, 13.2% below its year-earlier level. At the same time, Bank of America card activity showed August spending per household increasing 4.5% year over year, with shoppers favoring value-oriented and big-box retailers.

    That combination does not prove that every category will enjoy strong holiday demand. It does tell you why cheap reach and difficult conversion can coexist. People may continue spending while becoming more selective about the merchant, product, price, and promotion that earns the purchase.

    Key takeaways

    • The clearest 2026 cost opportunity is pre-peak prospecting: use it to learn and build qualified audiences, not merely to accumulate impressions.
    • Lower CPM does not automatically lower customer acquisition cost. Conversion rate and contribution per order still determine whether the campaign is economically sound.
    • Keep prospecting, retargeting, and account-based marketing separate in both reporting and budget decisions because they reach different audiences and perform different jobs.
    • Make value visible in the ad and on the landing page. A vague brand message asks a cautious shopper to do too much interpretive work.
    • Do not treat pre-holiday CPM declines as a Black Friday price guarantee. Preserve budget for peak demand and release it only when current results meet your commercial rule.

    Protect conversion economics before buying more reach

    An analyst adjusts a funnel as many tokens enter near generic ad tiles and only a few emerge beside shopping parcels.

    CPM answers one narrow question: how much did you pay for 1,000 impressions? The basic relationship is straightforward: impressions purchased equal media spend divided by CPM, multiplied by 1,000. When CPM falls, a fixed budget can buy more impressions.

    That calculation says nothing about how many viewers were suitable prospects, visited the site, understood the offer, or purchased. Customer acquisition cost answers a different question: how much media spend was required for each attributable new customer? If your CPM declines while the purchase rate declines by more, acquisition cost can rise. Scaling on CPM alone can therefore turn cheaper inventory into a larger unprofitable campaign.

    Set the commercial limit before you increase the budget. For an ecommerce campaign, that normally means defining the maximum acquisition cost the order can support after the discount and variable costs are considered. For a longer B2B sale, define the lead or opportunity outcome you are willing to fund. Do not substitute impressions, clicks, or an unqualified form submission for that outcome merely because those numbers arrive faster.

    Your holiday display scorecard should separate four layers:

    • Delivery: spend, CPM, impressions, unique reach, and frequency.
    • Response: landing-page visits and the qualified action that indicates genuine interest.
    • Commercial outcome: purchases or qualified leads, conversion rate, acquisition cost, revenue, and contribution after the promotion.
    • Audience status: new prospects, previous visitors, existing customers, and purchasers who should be excluded from acquisition messaging.

    Use the same attribution window and outcome definition whenever you compare tests. Also compare like with like. A warm retargeting audience should usually behave differently from people encountering the brand for the first time, so a blended account average can hide weak prospecting behind strong retargeting results.

    Build the holiday budget in stages

    A staged budget lets you use the inexpensive window without assuming that the same economics will survive at greater scale or during peak competition.

    1. Establish your own baseline. Pull the most comparable recent campaigns and separate prospecting, retargeting, and ABM. Record their CPM, frequency, conversion rate, acquisition cost, offer, creative, landing page, and attribution settings. This is the benchmark that matters when a broad market trend does not match your account.
    2. Fund an early prospecting test. Use the lower observed prospecting cost to compare audiences and value messages before the holiday auction becomes more crowded. Change one major promise at a time so you can identify why one version performed differently.
    3. Build a usable retargeting audience. Send qualified prospects to a page that continues the ad’s promise. Segment visitors by meaningful behavior where your platform and consent setup permit it, and exclude purchasers from acquisition ads. Cheap retargeting CPM is not useful if the underlying audience is tiny, poorly matched, or already converted.
    4. Release more budget only after a commercial signal. Scale an audience-message pair when it remains within your acceptable acquisition cost or lead economics. If CPM is attractive but the downstream outcome misses the rule, revise the audience, offer, creative, or landing page before increasing spend.
    5. Keep a peak-period reserve. Do not commit the entire seasonal budget at pre-peak prices. Hold enough flexibility to support proven combinations when shopper intent strengthens, while recognizing that the auction price may also rise.

    This approach avoids two common errors. Waiting until peak week forces you to pay for learning when competition may be stronger. Spending the full budget early assumes that cheap awareness is as valuable as high-intent demand. The staged plan buys learning first and scale second.

    Match each buying method to the job it can do

    A media planner directs budget tokens toward three different ad-buying stations connected to blank display placements.

    Use prospecting to discover demand

    Prospecting is the clearest place to use the early cost decline. Its job is to reach people who have not yet demonstrated interest, identify promising audience-message combinations, and supply qualified visitors for later campaigns. Evaluate it on both audience quality and the downstream customers it creates. Do not demand the same immediate conversion rate as retargeting, but do not excuse it from commercial accountability either.

    Let retargeting audience quality control the budget

    Retargeting reaches people who have already visited or interacted, which is why it should be reported separately. The 40.2% decline from the comparable Q2 period creates an appealing cost environment, but the available spend is constrained by the number of qualified people in the audience. Raising the budget against a small pool can increase repetition instead of finding more buyers. Watch reach and frequency together, and stop serving acquisition messages to people who have already purchased.

    Judge ABM by account value, not the broad display trend

    Account-based marketing moved differently, with CPMs rising 4.4% year over year even though they were 15.1% below the comparable Q2 period. ABM targets narrower groups of named accounts, so its pricing is not a reliable proxy for the wider display market. Use it when the potential account value and sales process justify concentrated exposure. A cheap broad-reach CPM is not a reason to replace that account strategy, and a higher ABM CPM is not evidence that it has failed.

    Whatever buying method you choose, make the value proposition easy to verify. State what is being offered, who it is for, what the price or promotion requires, and why the product deserves consideration. Carry the same terms onto the landing page. If a discount requires a code, minimum purchase, or limited eligibility, reveal that condition before the visitor reaches checkout. Hidden conditions may improve the apparent click response while weakening trust and conversion.

    Test meaningful differences rather than cosmetic variations alone. Compare a price-led message with a benefit-led message, or a general promise with a category-specific one, while keeping the audience and measurement settings stable. The goal is to learn which reason to buy survives beyond the impression and produces the outcome your budget needs.

    Before adding another dollar, separate your recent results by buying method and write the acceptable acquisition cost or lead outcome beside each one. Then fund the smallest pre-peak test that can produce a clear decision. Increase the combinations that satisfy that rule; change or stop the ones that merely deliver inexpensive impressions.

    References


  • Practical SEO Measurement: How to Prioritize What Works

    Practical SEO Measurement: How to Prioritize What Works

    You can have rankings, clicks, conversions, and a polished dashboard yet still be unable to answer the question that matters: should you put another sprint, another content batch, or another dollar into this SEO initiative?

    The practical goal isn’t to prove that SEO caused every conversion. It is to build enough reliable evidence to decide what to continue, what to expand, what to repair, and what to stop. That requires a measurement contract for every meaningful initiative, explicit thresholds, and an honest separation between what you observed and what you inferred.

    Measure for the decision, not the dashboard

    An architectural model shows a central evidence platform leading to four distinct routes, with a pointer aimed toward one path.

    Start by naming the decision your measurement must support. Are you deciding whether to launch, wait, expand, revise, or stop? A metric can be useful without answering all five questions.

    Separate the evidence into four levels:

    • Delivery evidence: Did the planned pages, templates, links, or technical changes actually ship? Until they do, you are measuring execution failure or delay, not SEO impact.
    • Leading indicators: Did search engines discover and index the affected pages? Are nonbrand impressions, rankings, or other early visibility signals moving in the expected direction?
    • Observed business outcomes: Did the affected traffic produce qualified leads, revenue, subscriptions, lower acquisition costs, affiliate earnings, or another unit of value that the business recognizes?
    • Attributed influence: How much of that outcome can reasonably be connected to the initiative? This is usually the least certain layer because SEO changes overlap with seasonality, algorithm changes, product releases, competitor activity, and work elsewhere on the site.

    Do not promote evidence from one level into another. Indexation shows that pages entered the search system; it does not show that the pages created profitable demand. More impressions indicate visibility; they do not prove incremental revenue. An organic conversion is observable, but its recorded channel does not reveal every earlier interaction that influenced the buyer.

    This distinction also keeps disagreements about tools from derailing the decision. Search Console and web analytics observe different events, while Search Console totals may not reconcile when segmented. Assign one system of record to each metric, document the definition, and judge movement within that system. Do not force unlike datasets to produce an artificial match.

    For every metric on your scorecard, complete this sentence: “If this crosses the agreed threshold by the review date, we will make this decision.” If you cannot finish the sentence, the metric may be informative, but it is not yet operational.

    Write a measurement contract before the work starts

    A project board is arranged with a target, balance scale, hourglass, boundary blocks, and separate trays of evidence stones.

    A forecast describes what you hope will happen. A measurement contract states how the team will decide what to do after reality arrives. Write it while everyone is still neutral, before delayed results and sunk costs make the thresholds negotiable.

    The contract should contain:

    <!– wp:list {
  • Patient Acquisition Cost Benchmarks for Medical Practices

    Patient Acquisition Cost Benchmarks for Medical Practices

    Your patient acquisition cost can be mathematically correct and still give you the wrong answer. A single number cannot tell you whether marketing is efficient until you know which costs it includes, what qualifies as an acquired patient, and whether you are comparing the same specialty and channel.

    Use the benchmarks below as diagnostic reference points, not spending targets. The practical goal is to find out whether your result reflects normal acquisition economics, a measurement problem, a weak channel, or a breakdown between the first inquiry and the completed appointment.

    Key takeaways

    2026 PAC benchmarks by specialty and marketing channel

    Three miniature healthcare settings are reached by different patient pathways with varying amounts of unmarked spending tokens.

    The 2021-2026 benchmark dataset uses anonymized results from medical practices. Specialty sample sizes range from three reporting practices for rheumatology to 27 for cosmetic and plastic surgery, so the apparent precision of the dollar figures should not be confused with equal statistical strength.

    Practice typeAverage patient acquisition costPractices reporting
    Allergy / Immunology$4214
    Cardiology$5899
    Cosmetic / Plastic Surgery$61727
    Dentistry$37911
    Dermatology$44818
    Endocrinology$4024
    Family Practice$27217
    General Practice$20119
    Geriatrics$41111
    Med Spa$2938
    Naturopathic$3876
    Neurology$59213
    Obstetrics & Gynecology$3385
    Orthodontics$5338
    Pediatrics$16011
    Podiatry$2216
    Psychiatry$2935
    Rheumatology$3543
    Urgent Care$29121

    The channel view answers a different question. It shows averages blended across all practice types, not specialty-by-channel benchmarks.

    Marketing channelAverage patient acquisition cost
    Organic Search (SEO)$218
    Paid Search (PPC)$346
    Organic Social$297
    Paid Social$299
    Direct Mail$245
    Radio Advertising$391
    TV Advertising$469
    Video / YouTube Marketing$358
    Outdoor Advertising$420

    No channel-level sample sizes accompany those averages. The figures also do not isolate geography, service mix, payer mix, patient value, attribution model, or the costs included in PAC. That does not make them useless. It means they are best used to flag a result for investigation rather than to certify that a campaign is efficient.

    Choose the right comparison before judging your result

    Start with the specialty benchmark when you are evaluating the practice’s overall acquisition cost. Start with the channel benchmark when you are investigating how a particular marketing method performs. Do not combine the two tables to manufacture a number that is not present.

    For example, dermatology averages $448 by specialty while paid search averages $346 across practice types. Averaging those figures would not produce a dermatology PPC benchmark. One describes a specialty across acquisition activity; the other describes a channel across specialties.

    If your practice has materially different service lines, calculate PAC for each one. A blended practice number can hide an expensive elective service behind a lower-cost primary-care line, or make a valuable specialty program look inefficient because its patients cost more to acquire. If your specialty is absent from the benchmark set, label any substitute as a proxy and rely more heavily on your own historical cohorts.

    What you seeWhat to test before actingUseful next action
    Your PAC is below the relevant averageCosts may be missing, returning patients may be counted as new, or one patient may be credited to multiple channels.Reconcile marketing expenses with finance and patient records before increasing the budget.
    Your PAC is near the relevant averageThe comparison may be reasonable, but average performance can still be unprofitable for your patient economics.Compare PAC with contribution margin and available clinical capacity.
    Your PAC is above the relevant averageThe cause may be expensive traffic, poor inquiry quality, booking friction, no-shows, limited capacity, or an attribution error.Segment the funnel before cutting the channel. Fix the component that is raising the cost.

    A benchmark becomes more useful when it changes the question from “Are we above average?” to “Which assumption would have to be true for this comparison to be fair?” That question exposes measurement gaps before they turn into budget decisions.

    Calculate a like-for-like patient acquisition cost

    Patient acquisition cost = eligible acquisition cost divided by newly acquired patients.

    The formula is simple. The definitions are where most comparisons break. Write those definitions beside the metric in your dashboard so that a future analyst, agency, or practice manager cannot silently change them.

    PAC layerCosts in the numeratorPatient denominatorBest use
    Media-only PACDirect advertising spendNew patients attributed to that advertisingOptimizing bids, audiences, and campaigns inside a paid channel
    Fully loaded channel PACMedia, agency or vendor fees, labor, creative, content, technology, and channel-specific trackingNew patients attributed to the channel under one consistent ruleComparing the economic performance of channels
    Fully loaded practice PACAll eligible patient-acquisition costsAll newly acquired patientsFinancial planning and evaluating the complete acquisition program

    Do not compare a media-only internal number with an external figure that may include labor and vendors. If the benchmark’s cost scope is not defined well enough to match yours, preserve your more useful internal definition and treat the external number as directional.

    Fix the patient milestone

    A lead, appointment request, booked appointment, attended consultation, and completed first encounter are not interchangeable. Choose the event that means the practice has genuinely acquired a patient and apply it everywhere. A completed first encounter is generally more stable than a booking because cancellations and no-shows have already been resolved, but your operational model may require another milestone.

    • Count each new patient once at the chosen milestone.
    • Exclude returning patients unless you intentionally maintain a separate reactivation metric.
    • Resolve duplicate records across locations, phone systems, forms, and scheduling tools.
    • Document how free consultations, canceled appointments, no-shows, and later conversions are handled.
    • Keep the definition unchanged when comparing periods or channels.

    Use one attribution rule without erasing the patient journey

    A patient may first encounter the practice in an organic result or AI-generated answer, later click a branded ad, and finally call. Giving every touchpoint full credit inflates the denominator for each channel. Giving only the last click credit can hide the activity that created demand.

    Keep both discovery and trackable conversion information when your systems allow it. Record how the patient says they first found the practice, preserve any available campaign or referral data, and assign one primary channel under a documented rule for PAC reporting. An intake field with fixed options and free text can capture search engines, AI assistants, social platforms, referrals, and offline media when click-based attribution is incomplete.

    Align costs and acquired patients to a consistent measurement basis as well. This matters especially for organic search, content, structured data, and other programs whose work and patient response may not occur in the same reporting period. A mismatched numerator and denominator can create a dramatic PAC change even when underlying performance has not changed.

    Turn the benchmark into a budget and operations decision

    Patients move from outreach through reception and scheduling to an examination room, with one person paused at a scheduling bottleneck.

    Set a ceiling from patient economics

    The market average is not your allowable PAC. Your ceiling comes from the value a new patient contributes to the practice and the cash-flow period the practice can support.

    Expected contribution before acquisition = expected collected revenue over the chosen value horizon minus the variable costs of delivering care.

    Expected contribution after acquisition = expected contribution before acquisition minus PAC.

    Use collected revenue rather than sticker price, and keep the value horizon consistent. Comparing one channel with first-visit revenue and another with the value of an entire treatment episode will favor the second channel by design. If your estimates affect a material spending commitment, have the practice’s financial lead validate the revenue, cost, capacity, and cash-flow assumptions before the budget changes.

    A below-benchmark PAC can still destroy value when contribution margin is lower. An above-benchmark PAC can still be workable when the patient relationship contributes enough margin and the practice has capacity. The external average tells you what deserves scrutiny; your economics decide what is affordable.

    Separate traffic cost from conversion failure

    When qualified inquiries are measured consistently, the funnel can be expressed as PAC = cost per qualified inquiry divided by the inquiry-to-acquired-patient conversion rate. This decomposition tells you whether the acquisition problem begins before or after the inquiry.

    • If inquiry costs rise while conversion is stable, inspect targeting, competition, creative, search intent, and channel mix.
    • If inquiry costs are stable while PAC rises, inspect call handling, response delays, service fit, scheduling friction, appointment availability, cancellations, and no-shows.
    • If both appear stable while PAC changes, audit missing expenses, duplicate patient records, channel reassignment, and changes to the acquired-patient definition.
    • If demand exceeds usable appointment capacity, increasing marketing can raise cost without creating additional completed care. Resolve the capacity constraint before adding spend.

    This distinction protects you from cutting an effective campaign because the practice could not answer, qualify, or schedule the demand it generated. It also prevents an operational problem from being disguised as an advertising problem.

    Budget against marginal PAC, not only the historical average

    Your average PAC describes the patients already acquired. A budget decision concerns the additional patients expected from additional spending. Track the incremental cost and incremental acquired patients when you expand a channel; the next segment of demand may not perform like the existing average.

    Planning budget = desired new-patient volume multiplied by planning PAC. Use your own normalized PAC as the base, the relevant external benchmark as a reasonableness check, and your contribution-based ceiling as the financial constraint. Then test whether the required patient volume fits actual appointment capacity.

    Organic search carries the lowest reported channel average at $218, but that does not make it an automatic budget winner. Include content production, technical SEO, structured data, analytics, optimization labor, and outside support in the organic numerator when those costs are part of patient acquisition. Apply the same discipline to every channel. A television average of $469 is not automatically unacceptable if the channel produces patients whose contribution and incrementality support that cost.

    Before approving the next budget change, write the PAC definition at the top of the forecast, rebuild the latest complete measurement period with that scope, choose the appropriate specialty and channel references, and add your contribution-margin ceiling and capacity limit. You will then have more than a benchmark: you will have a decision rule your marketing, operations, and finance teams can use consistently.

    References