Tag: Brand Visibility

  • How to Choose an Industry-Focused SEO Agency in 2026

    How to Choose an Industry-Focused SEO Agency in 2026

    An industry-focused SEO agency should offer more than a portfolio containing familiar company names. Its real value lies in understanding how a sector’s customers search, which evidence earns their trust, and what technical or geographic constraints shape the path to conversion.

    Three 2026 agency reports covering solar, agriculture, and local SEO reveal a useful selection framework. They also show why a ranking should begin due diligence rather than settle the decision.

    Key takeaways

    • Relevant client experience, review quality, and leadership expertise recur across all three agency evaluations.
    • Specialization should be tested at the level of search behavior, content, technical requirements, geography, and commercial outcomes.
    • Local SEO is a distinct operating capability, not a substitute for knowledge of a client’s industry.
    • Scorecard weights reveal what a ranking values, but buyers still need to examine the evidence behind each score.
    • The best agency is the one whose delivery model fits the organization’s actual bottleneck, whether that is authority, local visibility, branding, or technical execution.

    What specialization should change in practice

    The three reports share a basic premise: experience close to the client’s market matters. The solar evaluation gave notable clients 28% of its score and also considered home-services experience when an agency had less direct solar work. The agriculture evaluation assigned 25% to notable clients and emphasized leadership experience in agriculture-specific strategy. The local SEO report made demonstrated local experience its largest factor, at 25%.

    Those criteria point to different kinds of relevance. Vertical expertise concerns the market itself: its audiences, terminology, buying process, content opportunities, and standards of credibility. Local expertise concerns how a business competes across places, including location pages, structured information, and visibility in map-oriented results. An agency may possess one capability without the other.

    The solar report illustrates how varied agencies within one vertical can be. It described First Page Sage as using thought-leadership content, geographically targeted landing pages, and white papers for mid-market and enterprise providers. Siana Marketing was presented as combining SEO and generative engine optimization, or GEO, with knowledge of solar sales cycles. Anchour was positioned around branding for smaller companies, while XEN Solar was associated with technical SEO and HubSpot optimization. These profiles are source-reported positioning, not independently verified performance, but they demonstrate that an industry label can encompass substantially different delivery models.

    What the agency scorecards measure – and omit

    ReportAgency pool reviewedMost heavily weighted evidenceDistinctive considerations
    Solar SEO31 agenciesNotable clients, 28%; leadership experience, 22%; average reviews, 22%Year founded, 16%; company size, 12%
    Agriculture SEO81 companiesAverage reviews, 25%; notable clients, 25%; leadership experience, 20%Services, founder involvement, and media references, each 10%
    Local SEO48 firmsLocal SEO experience, 25%; average reviews, 20%Technical expertise and local-pack effectiveness, each 15%; leadership, employee tenure, and media references

    The overlap is meaningful. All three reports considered client reviews and leadership experience, while the two vertical studies placed substantial weight on recognizable or relevant clients. Taken together, the reports treat market evidence, reputation, and senior expertise as complementary signals rather than interchangeable ones.

    The differences are just as instructive. The solar methodology rewarded longevity and company size. The agriculture methodology considered whether the founder remained active and how often the company appeared in media. The local evaluation gave explicit weight to technical SEO, local-pack results, and median employee tenure. A buyer that values stable account teams may find tenure more informative than media visibility; a multi-location operator may care more about local-pack evidence than an agency’s founding date.

    Methodological transparency also needs scrutiny. The agriculture article says it used seven factors, but the supplied methodology names six: reviews, clients, leadership, services, founder involvement, and media references. Their stated weights total 100%, yet the mismatch between the announced and enumerated factor count is a reminder to inspect the underlying rubric rather than rely only on the final order.

    How to test an agency’s claimed industry expertise
    A client team tests SEO consultants around a table containing technical components, map contours, product samples, and unlabeled evidence folders.

    Interrogate the case evidence

    A logo establishes that some relationship existed; it does not explain the scope, duration, baseline, or result. Buyers can ask what the agency was responsible for, which search problems it addressed, and how outcomes were measured. Reviews deserve similar examination. The agriculture report said it consulted G2, Clutch, and Google Reviews, while the local report described a composite drawn from Google, Clutch, and other verified platforms. The solar report referred more generally to publicly available reviews and gave additional weight to solar-client feedback.

    That makes review composition more important than a headline average. Relevant questions include whether comments describe SEO work, whether they come from comparable organizations, and whether they discuss communication and execution as well as satisfaction.

    Distinguish leadership credentials from delivery capacity

    Leadership experience appeared in every methodology, receiving 22% in solar, 20% in agriculture, and 10% in local SEO. Senior expertise can shape strategy and quality standards, but buyers also need to learn who will actually conduct research, create content, implement technical changes, and report results. The local report’s inclusion of employee tenure offers one possible signal of delivery continuity; the solar report instead used company size as an indicator of capacity and client support.

    Request a diagnosis specific to the business

    A credible proposal should connect tactics to an identified constraint. An authority problem may call for expert-led content. A location-discovery problem may require technically sound location architecture and local visibility work. A weak market position may require branding before publishing at scale, while an implementation backlog may favor a technically oriented partner. This diagnosis is more revealing than whether an agency repeats the vocabulary of the sector.

    Match the engagement model to the actual search problem

    The sources suggest that industry specialization is not a single service category. In the agriculture report, First Page Sage was described as offering SEO, GEO, advertising, and web development, with thought leadership at the center of its positioning. The report said the company was founded in 2009 and began adapting to generative AI in 2023, while also crediting it with early GEO research. Those are claims made by the source and should be assessed alongside work samples and client evidence.

    The appearance of GEO in both the agriculture and solar coverage indicates that some sector-focused firms are extending their positioning beyond conventional search results. That does not remove the need for foundational SEO. A buyer can ask the agency to separate established deliverables – such as site architecture, content, and location optimization – from newer visibility initiatives, then explain how each will be measured.

    Organizational fit matters as well. The solar report associated one agency with enterprise thought leadership, another with small-company branding, and another with agile technical support. A specialist can therefore be relevant to the industry but wrong for the client’s scale, internal resources, technology stack, or immediate commercial objective.

    Turn selection criteria into an accountable engagement
    A client and agency team build a modular tabletop pathway with illuminated checkpoints connecting search activity to a conversion symbol.

    Before contracting, the organization should translate its selection rationale into a clear operating agreement. The scope can identify the audiences and markets being pursued, the technical and content responsibilities of each party, the approval process, and the business actions that count as meaningful conversions. Reporting should distinguish completed work and search visibility from qualified commercial outcomes.

    The same evidence used to select the agency can become a review standard. If leadership involvement influenced the decision, its expected role should be explicit. If local-pack effectiveness was decisive, the relevant locations and queries should be agreed upon. If industry content expertise won the work, editorial quality and access to subject-matter experts should be built into the process.

    As search interfaces and agency offerings continue to evolve, the strongest partnerships will be those that define specialization through observable decisions and accountable work, rather than through category labels alone.
    References

  • AI Brand Visibility: A Practical Content and Measurement Plan

    AI Brand Visibility: A Practical Content and Measurement Plan

    If your AI visibility report is a list of prompts and brand mentions, you have a monitoring snapshot, not a strategy. It can tell you that your name appeared. It cannot tell you why the model chose you, whether you stayed visible as the buyer refined the question, or whether the appearance produced a useful business outcome.

    You need a system that connects four things: the buyer’s decision path, the evidence your content supplies, the way different AI modes retrieve that evidence, and the actions people take afterward. Build those connections and AI visibility becomes something you can improve, even though you cannot measure every personalized conversation.

    Key takeaways

    • Measure AI visibility by buyer-journey stage and reasoning mode, not as one sitewide score.
    • Start with the conversion you care about, then map the Problem, Exploration, Comparison, Validation, and Selection questions that lead to it.
    • Publish focused pages and page sections for the sub-questions an AI system may research, including pricing, limitations, integrations, compliance, implementation, and support.
    • Keep mentions, citations, links, referral visits, and conversions as separate metrics. They describe different outcomes.
    • Use automation to collect and organize data, but keep positioning, prioritization, evidence quality, and business interpretation under expert control.

    Treat AI visibility as a pathway, not a rank

    Several people follow branching illuminated paths while the same amber beacon appears at multiple stages of their journey.

    A search ranking belongs to a relatively defined query, result page, location, device, and time. An AI answer can depend on the model, version, mode, conversation history, wording, available web access, and the system’s decision to conduct additional searches. Two superficially similar prompts can therefore expose your brand to different competitive sets.

    This makes a universal visibility percentage misleading. A prompt tracker observes a controlled sample of outputs. It does not observe every question customers ask, every conversational path, or every personalized answer. The useful unit of analysis is narrower: a buyer pathway, a stage within that pathway, and a defined AI environment.

    Reasoning mode deserves its own dimension. In a limited analysis covering 200 GPT-5.2 responses across 20 buyer journeys and four sectors, high reasoning increased the share of responses with citations from 50% to 68%. Average citations per cited response rose from 2.6 to 4.5, and fan-out searches increased by 4.6 times. Only 25.6% of cited domains overlapped between the two modes.

    That is one bounded dataset, not a universal benchmark. Its strategic implication is still important: minimal reasoning and high reasoning may behave like different discovery environments. If you average them together, a gain in one mode can conceal a loss in the other. You may also misdiagnose a content problem when the actual change is routing, retrieval depth, or source selection.

    Segment by query type rather than assuming that reasoning belongs to a particular customer tier. Complex comparisons, compliance questions, evaluation frameworks, and open-ended shopping tasks can prompt deeper research. Bounded tasks with a predefined answer structure may need little or no external retrieval. In the same limited dataset, some bounded Selection prompts generated no fan-out searches, while open-ended Selection prompts generated 28 to 40.

    Your baseline should therefore record the platform, model or visible version, reasoning mode, date, complete prompt, pathway, and stage. If any of those fields change, treat the result as a different observation rather than silently adding it to the old average.

    Map content backward from the conversion you need

    Do not begin with a collection of SEO keywords and rewrite each one as a chatbot prompt. Begin with a real conversion: a purchase, qualified enquiry, product trial, booked consultation, application, subscription, or another action your organization already values. Then work backward through the decisions a person must make before that action becomes reasonable.

    A Funnel Query Pathway gives that work a usable structure. It replaces the fantasy of monitoring the entire AI ecosystem with a defined cohort of intentions you can inspect and improve.

    Pathway stageWhat the person is trying to decideContent jobEvidence to make accessible
    ProblemWhether the condition is real, important, and worth addressingExplain symptoms, causes, consequences, and thresholds for actionClear definitions, diagnostic questions, examples, and credible context
    ExplorationWhich categories of solution could fitDescribe available approaches and the tradeoffs between themCategory maps, use cases, constraints, terminology, and suitability criteria
    ComparisonWhich option fits a specific set of requirementsSupport a defensible side-by-side evaluationFeatures, pricing structure, limitations, integrations, compliance, service, and support details
    ValidationWhether a preferred option will deliver without creating unacceptable riskResolve objections and verify claimsMethodology, implementation requirements, proof, exclusions, policies, and independent corroboration
    SelectionHow to choose, buy, deploy, or beginRemove the final information and process gapsCurrent plans, setup instructions, availability, onboarding steps, documentation, and a clear next action

    Build the prompts from customer language rather than marketing language. Sales objections, support questions, internal site searches, product reviews, community discussions, and questions submitted to your team can reveal how people describe the problem before they know your category vocabulary. Remove identifying customer information before placing any of that material in an external AI tool.

    Include both broad and constrained prompts. A broad prompt reveals which categories and brands the system introduces without help. A constrained prompt tests whether your evidence survives real requirements such as team size, budget structure, integration needs, jurisdiction, implementation capacity, or an existing technology stack. Do not insert your brand into every prompt. That measures the model’s ability to discuss a brand it was handed, not its ability to discover or recommend you.

    Finally, connect each prompt to a page or content gap. If a prompt matters but you cannot identify where a person or retrieval system would find a reliable answer on your site, you have found a strategy problem. If the answer exists but is buried in a PDF, vague sales copy, an outdated help page, or an unlabelled table, you have found an accessibility problem.

    Publish for the questions hidden inside the question

    A buyer may ask one comparison question, but a reasoning system can decompose it into many retrieval tasks. It may investigate API limits, security controls, pricing tiers, contract terms, integrations, implementation effort, support options, and suitability for the stated use case before composing an answer.

    The retrieval load is especially visible around evaluation. In the GPT-5.2 analysis, Comparison prompts generated an average of 24 fan-out searches under high reasoning and 5.5 under minimal reasoning. Average citations at that stage reached 9.8 and 5.8 respectively. Your page does not need to imitate those internal searches, but your content system does need authoritative answers for the branches that matter to the purchase.

    Build answer surfaces, not one oversized buying guide

    A long guide can introduce a topic, but it is rarely the best home for every operational detail. Pricing changes on a different schedule from API documentation. Compliance claims require different ownership from product comparisons. Implementation instructions need maintenance after the campaign that launched them has ended.

    Give each important question a stable, maintained answer surface. That may be a dedicated page or a clearly headed section on a broader page. For each surface:

    • State the direct answer near the relevant heading, then explain conditions and exceptions.
    • Use the same product, company, plan, and feature names across marketing pages, documentation, structured data, and profiles.
    • Show which version, market, plan, or customer type a claim applies to when the distinction matters.
    • Separate facts from positioning. A feature description should not force the reader to decode a slogan.
    • Link comparison and category pages to the underlying pricing, policy, technical, compliance, and support pages.
    • Identify who is responsible for reviewing details that can become stale.
    • Apply relevant structured data only where the visible page supports it. Schema can clarify entities and relationships, but it cannot rescue missing or untrustworthy evidence.

    Lists have a legitimate role when the question is inherently enumerable. A citation analysis framed around 25,000 URLs found a notable relationship between list-style content and AI citations. The useful lesson is not to turn every page into a numbered roundup. Use a list for alternatives, criteria, steps, requirements, or failure modes when those items can be evaluated consistently. A shallow list of brands with interchangeable descriptions supplies little evidence for a serious recommendation.

    Win the Problem stage before the shortlist exists

    Comparison pages attract attention because their commercial intent is obvious. Problem-stage content can be more strategically important in a conversation, however, because it helps define the solution landscape before the user has formed a shortlist.

    In the high-reasoning dataset, a brand persisted from Problem through Selection in four of the 20 journeys. All four occurred in Finance, where authoritative pages and official information can carry unusual weight. That is too small and sector-specific to support a universal persistence rate. It does show why early visibility should not be dismissed as awareness with no decision value: an AI conversation can carry an early frame into later evaluation.

    For your highest-value pathways, inspect the Problem and Exploration stages for missing content. Explain when the problem deserves action, which alternatives exist, when your category is a poor fit, and what information a buyer needs before comparing vendors. Candid exclusions improve usefulness because they give the model and the reader boundaries, not just claims.

    Make the brand behind the evidence unambiguous

    A citation and a brand mention are not the same event. An AI answer can use your page without naming your company, mention your company without linking it, or link a third-party page that describes you inaccurately. Your content architecture should reduce that ambiguity.

    Keep organization, author, product, and publisher identities explicit. Put substantive information on crawlable pages. Maintain documentation at stable URLs. Use descriptive titles and headings. Connect factual claims to the page that owns and maintains them. Where independent verification matters, work on the underlying reputation and public evidence rather than publishing another self-authored claim.

    This is where professional judgment remains valuable. AI can accelerate metadata, data preparation, report generation, and design prototyping, but understanding customer behavior and connecting technical work to business outcomes still determines which questions deserve coverage and which evidence is credible. Faster production does not fix weak positioning or unsupported claims.

    Measure mentions, citations, clicks, and outcomes separately

    Four separate visual streams represent mentions, source citations, clicks, and business outcomes before converging at an analyst's lens.

    AI visibility is not one metric because an appearance can create several different kinds of value. A brand may become part of the answer, provide evidence for the answer, receive a clickable link, earn a site visit, influence a later branded search, or contribute to a conversion. Collapsing those events into one score hides the mechanism you need to improve.

    A reported ChatGPT change on May 7, 2026 illustrates the distinction. When brand mentions began receiving direct homepage links, observed OpenAI referrals to brand sites nearly doubled. Treat that as a documented observation, not a transferable traffic forecast. The broader lesson is durable: an interface change can increase clicks even if the underlying frequency of brand mentions does not change.

    Use a layered scorecard

    Keep the raw observation available, then calculate rates only within a clearly labelled sample. A useful record contains:

    • Environment: platform, visible model or version, reasoning mode, run date, and any known location or account context.
    • Intent: pathway, funnel stage, prompt type, constraints, and the exact prompt text.
    • Brand exposure: whether the brand appears, how it is described, whether it is recommended, and whether important qualifications are accurate.
    • Evidence: whether the response cites external material, whether it cites your brand’s pages, which URL and domain it uses, and whether the same domain supports multiple claims.
    • Link opportunity: whether the brand mention or citation is clickable and which landing page receives the link.
    • Pathway persistence: whether the brand remains present as the conversation moves from one stage to the next.
    • Site behavior: identifiable AI referral visits, landing-page engagement, assisted actions, and conversions, with the limits of your attribution made explicit.
    • Search support: impressions, clicks, queries, and pages from Google Search Console for the topics that underpin the pathway.
    • Business result: the qualified action, revenue event, pipeline movement, or other conversion the pathway was built to support.

    From those records, you can calculate a mention rate, brand-citation rate, linked-mention rate, and pathway-persistence rate for the prompts you actually observed. Label the denominator. A 40% citation rate across a fixed Comparison cohort is not 40% visibility across the market. It is 40% within that cohort, in the recorded environments, during that observation period.

    Do not record an unobservable event as zero. Referral traffic can be identifiable while influence inside an answer remains hidden. A person can also encounter your brand in an AI response and return later through direct or branded search. Keep confirmed traffic, assisted influence, and unknown attribution in different buckets.

    Turn the report into a decision queue

    Your dashboard should end in editorial and technical decisions, not decorative trend lines. Organize the working report around:

    • A pathway-by-stage view that exposes where the brand enters, disappears, or is represented inaccurately.
    • A separate view for minimal and high reasoning so their source sets and citation behavior are not averaged together.
    • A citation inventory showing which owned and third-party pages support each important claim.
    • A content-gap queue tied to high-value prompts, missing evidence, and the page responsible for resolving the gap.
    • A traffic and conversion view that keeps AI referrals beside, but distinct from, traditional organic search.
    • A change log for content updates, technical releases, model changes, and interface changes that could explain movement.

    Automation is useful here because the repetitive work is substantial. A local coding assistant such as Claude Code can analyze Search Console CSV files or work with Search Console API data to generate focused tables and visual reports. The tool is optional; the workflow is what matters. Standardize the data, preserve the raw export, document transformations, and make every chart traceable to its inputs.

    Test changes as hypotheses. Name the pathway node you expect to improve, the missing evidence you intend to add, the controlled prompt cohort you will revisit, and the downstream action you will watch. Recheck both reasoning modes without changing the baseline prompts. A movement that repeats across comparable observations is more useful than a favorable answer captured once, but it still does not prove that one page edit caused the change.

    Your next move is concrete: choose the conversion that matters most, map its five decision stages, capture a mode-separated baseline, and fix the first evidence gap that blocks a real buyer question. Then follow the result from answer to citation, from citation to visit, and from visit to outcome. That is how AI visibility becomes an operating strategy instead of a mention count.

    References

  • Build Google Commerce Infrastructure From Visibility to Revenue

    Build Google Commerce Infrastructure From Visibility to Revenue

    You can have thousands of products appearing on Google and still have two expensive blind spots. Shoppers may never see listings hidden behind a carousel scroll, while purchases or qualified leads completed elsewhere may never return to Google Ads.

    If you own ecommerce growth, you need two connected but distinct systems: one that measures whether products earn usable visibility, and one that returns offline outcomes to the advertising platform. Here is how to build both without confusing presence with exposure, activity with revenue, or shared reporting with attribution.

    Count the product placements shoppers can actually see

    Shopper viewing a product carousel where several items are visible and many more remain hidden beyond the screen edge.

    A product-pack appearance is not automatically an impression worth celebrating. Google can place products in horizontally scrollable carousels, so the first visible positions receive a very different opportunity from listings that require interaction before they appear.

    The scale makes this distinction material. A monitoring dataset covering more than 63,000 merchants from January 2025 through January 2026 found searches with as many as 60 individual organic product listings on one results page. A report that counts every one of those listings equally will overstate the practical reach of products buried deep in a carousel.

    Keyword coverage can be just as misleading. eBay appeared in product results for 874,621 keywords and generated about 3.2 million estimated visits, while Home Depot appeared for a slightly smaller 831,699 keywords but generated nearly 28.8 million estimated visits. The difference was associated with Home Depot securing more prominent, immediately visible positions. More appearances did not mean more useful exposure.

    Build your product-pack scorecard in layers. Keep each layer separate so an impressive top-line number cannot hide weak placement:

    • Eligible catalog: Products you expect Google to understand and consider for the category.
    • Total appearances: Every detected placement, including positions that require scrolling.
    • Visible appearances: Placements shown before a shopper scrolls the carousel.
    • Visible rate: Visible appearances divided by total appearances. Preserve the counts beside the percentage so a small sample does not look more important than it is.
    • Query quality: Segment high-demand category searches from low-volume long-tail queries. Raw keyword coverage otherwise rewards breadth whether or not that breadth produces meaningful traffic.
    • Observed visits and outcomes: Use analytics for measured sessions, transactions, leads, and revenue. Label third-party traffic estimates as estimates rather than blending them with observed data.

    Review the scorecard by category, not only by domain. A healthy total can conceal one category that wins visible positions and another that appears frequently but remains out of sight. That second category is where feed and merchandising work may create the largest gain.

    Fix commerce inputs before reaching for a blanket discount

    Discounting is easy to change and easy to report, which makes it an attractive explanation for product-pack performance. It is not a reliable standalone lever.

    Among large merchants in the monitored data, Amazon discounted 49% of its catalog and achieved a 72% visibility rate. eBay discounted only 8% and reached 81%. Walmart Seller reached the same 81% visibility rate with 24% of products discounted, while Walmart discounted 27% and recorded a lower 62% visibility rate. That irregular pattern does not establish a universal ranking formula, but it does show why discount depth should not be treated as the primary explanation for placement.

    Start with the inputs Google and shoppers need to evaluate the product: complete product data, clear category relevance, strong images, current pricing and availability, and credible reviews. Promotions can still support a commercial offer, but they cannot compensate for an unclear product identity or poor category fit.

    Turn low visibility into a product-level work queue

    1. Choose one commercially important category rather than auditing the whole catalog at once.
    2. Export products that appear for relevant queries but have a low visible rate.
    3. Compare those products with visible winners in the same category. Check data completeness, category alignment, image quality, review strength, price, and availability.
    4. Group repeated defects. Ten products with the same missing or weak input should become one system fix, not ten unrelated tickets.
    5. Correct one defect class, record the date, and remeasure the same category. Product-pack placement fluctuates, so a before-and-after comparison needs consistent queries and a sufficiently stable observation window.
    6. Escalate products that remain hidden despite clean inputs. They may face a relevance, competitiveness, or demand problem rather than a feed defect.

    This process will not prove that one field caused a ranking change. It will give you a disciplined way to improve controllable inputs without assuming that every movement came from price.

    Specialist retailers should be especially careful not to confuse smaller scale with weaker potential. Camp Chef appeared for 155,299 keywords yet generated about 2.6 million estimated visits through advantageous placements. Its footprint was much smaller than the largest marketplaces, but category focus and placement quality produced substantial estimated traffic. Depth in a category can be more commercially useful than millions of marginal appearances.

    Protect offline conversion measurement as the API route changes

    Offline checkout and sales outcomes flowing through a secure gateway into a newer cloud-based measurement connection.

    Product-pack optimization addresses organic commerce visibility. Offline conversion imports address Google Ads measurement and bidding. They belong in the same commerce operating model, but they are not the same channel and should never be presented as if one directly measures the other.

    Google is moving offline conversion imports, including enhanced conversions for leads, from the Google Ads API toward the Data Manager API. Under the communicated change, UploadClickConversions becomes nonfunctional after June 15 for affected accounts that have not used the feature during the preceding 180 days. The change applies to offline conversion imports for some developers, while other Google Ads API operations continue.

    Do not infer that your integration is safe merely because it still runs or because another Google Ads API operation succeeds. An application can keep managing campaigns while its offline conversion path quietly becomes obsolete. Missing imports can weaken reporting, attribution, and the conversion signals used by automated bidding.

    Use this migration checklist

    1. Find every dependency. Search application code, scheduled jobs, middleware, vendor integrations, and internal runbooks for UploadClickConversions. Include enhanced conversions for leads and any sales or lead events completed outside the immediate ad interaction.
    2. Map the affected accounts. Record which accounts use each workflow, when each last imported conversions, who owns the source system, and how frequently the job runs. The 180-day activity condition makes account-level evidence more useful than a platform-wide assumption.
    3. Define the event contract. Document what qualifies as a conversion, where it originates, how it is identified, which value is sent, and which system is authoritative. Migration is a poor time to preserve an event definition nobody can explain.
    4. Build the Data Manager API route. Keep unrelated Google Ads API operations in place unless they have a separate reason to move. The scope here is the conversion-ingestion workflow.
    5. Test a controlled slice. Confirm that source events are accepted, rejected events are visible to operators, and imported counts and values reconcile with the originating system.
    6. Prevent double counting. A temporary overlap can help validate a migration, but sending the same business event through two active routes without a deduplication plan can corrupt reporting. Document exactly when the old writer stops and the new writer becomes authoritative.
    7. Add failure monitoring. Alert on missing runs, unexpected volume changes, rejected events, and reconciliation gaps. A job that reports technical success but delivers no usable conversions is not healthy.

    Because the communicated cutoff applies selectively, treat the date as a prompt to verify your current environment rather than assuming every account failed at once. The decisive evidence is your dependency inventory, recent account activity, accepted-event reporting, and reconciliation with the source system.

    Join the systems without inventing cross-channel attribution

    A shared commerce data spine makes the two workstreams easier to operate. It does not make Google Ads conversion imports a measurement system for organic product packs. Preserve channel and attribution boundaries while standardizing the business entities used in both.

    At minimum, use consistent product and category identifiers across the commerce feed, landing pages, analytics, CRM or order system, and internal reporting. If you publish product structured data, align its product identity, price, and availability with the same source of truth. The immediate benefit is diagnostic: your team can trace a category from search visibility through site behavior and recorded outcomes without manually translating competing names.

    Product-pack visibilityOffline conversion pipelineWhat you can concludeNext action
    Strong and visibly placedHealthy and reconciledBoth discovery and advertising measurement are operational, but their results still require separate attribution.Compare category economics and prioritize the products with the strongest observed business outcomes.
    Strong and visibly placedBroken or uncertainOrganic discovery may be healthy, but Google Ads reporting and bidding signals are unreliable.Restore and reconcile the conversion pipeline before making bid or campaign conclusions.
    Weak or mostly hiddenHealthy and reconciledAdvertising measurement is usable; the organic product-pack problem sits upstream.Work the category-level product data, relevance, image, review, price, and availability queue.
    Weak or mostly hiddenBroken or uncertainYou have two separate failures, not one vague Google problem.Assign independent owners. Protect conversion ingestion because bidding can be affected, while product visibility remediation proceeds in parallel.

    Give each layer an operating cadence

    • Daily: Check whether offline conversion jobs ran, whether expected events arrived, and whether rejection or reconciliation thresholds were breached.
    • Weekly: Review visible versus non-visible product-pack appearances by category. Create a prioritized issue queue for products with meaningful query exposure but poor placement.
    • Monthly: Compare category-level visibility, measured site outcomes, advertising results, catalog changes, promotions, and resolved data defects. Keep estimated traffic in a separate column from observed sessions and revenue.
    • After a sudden change: Check availability, price, images, reviews, feed completeness, and category mix before concluding that discounting or a single platform update caused the movement.

    Expect movement. Nearly every merchant in the year-long monitoring dataset experienced product-pack visibility shifts, with some gaining during one period and receding later. Google can change how it weighs feed quality, availability, reviews, pricing, and images, so a previously strong visible rate is not a permanent asset.

    Key takeaways

    • Report visible product-pack appearances separately from placements hidden behind a carousel scroll.
    • Segment performance by category and query value; raw keyword coverage can conceal poor positioning and weak traffic.
    • Treat discounts as one commercial input, not a substitute for complete product data, category relevance, good images, reviews, current price, and availability.
    • Audit UploadClickConversions dependencies now and move affected offline conversion workflows to the Data Manager API with reconciliation and failure alerts.
    • Keep organic visibility and Google Ads attribution distinct, even when they share product identifiers and business reporting.

    Start with one important category and one conversion workflow. Establish the visible-placement baseline, clear the highest-frequency product-data defect, and verify that the corresponding offline conversion job reaches its destination. That gives you a working control loop you can extend across the catalog without scaling hidden measurement errors along with it.

    References

  • How to Choose an Addiction Treatment SEO Agency in 2026

    How to Choose an Addiction Treatment SEO Agency in 2026

    Your facility is not buying traffic. You are choosing who will translate real services, locations, qualifications, and intake pathways into pages that people can find and trust. A weak choice can waste budget, but it can also create false expectations for people making consequential care decisions.

    The right agency is not necessarily the one with the longest service list. It is the one whose operating model fits your actual constraint, whose claims survive due diligence, and whose work remains under your clinical, privacy, and business control. Use this process to build a defensible shortlist and run a much more revealing sales conversation.

    Define the problem before you compare agencies

    The first mistake is asking which addiction treatment SEO agency is best before deciding what the agency must own. Two facilities can want more qualified inquiries while needing completely different work.

    • Strategy and architecture: You have capable internal writers, but no clear map connecting services, locations, search intent, and priority pages.
    • Content production: Your experts know the subject, but drafts stall because nobody can turn approved clinical facts into useful search content.
    • Technical recovery: Important pages are difficult to crawl, duplicate templates compete with one another, internal links are weak, or a redesign left redirects and metadata in disarray.
    • Local visibility: Your location information, service-area pages, business profiles, and on-site location details do not tell a consistent story.
    • Integrated acquisition: SEO cannot be planned in isolation because branding, advertising, social media, automation, or offline outreach also shape how prospective patients reach intake.

    Choose a primary constraint. Secondary needs can remain in the brief, but they should not obscure the result you are hiring the agency to produce. A technical specialist should not win merely because its proposal contains more content deliverables. A full-service agency should not win merely because it can bundle channels you do not need.

    Before contacting vendors, prepare a short decision brief containing:

    • The services and levels of care you actually provide.
    • The physical locations that deliver each service.
    • The inquiries you want and the inquiries you should not attract.
    • The people who may approve clinical, brand, privacy, and legal claims.
    • Your website platform, analytics access, content resources, and known technical constraints.
    • The business event that matters after a visit, such as an appropriate inquiry or an intake milestone defined by your operations team.
    • The work your internal team will continue to own.

    This brief prevents a common procurement failure: buying a generic SEO package and discovering later that nobody owns implementation, clinical review, or the connection between marketing data and intake outcomes.

    Match the agency model to your operating constraint

    Category experience deserves a place in the first screen, but it should not decide the contract. One market screen spanning 40 enterprises and ranking 10 weighted notable clients at 45%, leadership experience at 25%, years in business at 25%, and company size at 5%. Those factors can help identify established candidates. They do not establish clinical accuracy, lead quality, implementation skill, privacy governance, geographic fit, or the quality of the team assigned to your account.

    The providers below have meaningfully different service mixes. Treat each one as an interview starting point, not as an automatic endorsement.

    AgencyDocumented emphasisWhen the model may fitWhat to verify
    First Page SageSEO content and strategic planning for in-house marketing teamsYou can implement or publish internally but need a search strategy and content engineWho develops the strategy, how briefs become approved pages, and where implementation responsibility ends
    Armada MedicalSEO combined with traditional marketing, including direct mailYour acquisition plan spans digital and offline channelsHow attribution, messaging, and budget decisions stay consistent across channels
    Dreamscape Marketing, LLCWeb design and marketing automation for addiction centersYour search problems are tied to the website experience or follow-up systemsPlatform ownership, migration safeguards, automation governance, and which work is performed by the assigned team
    SensisBranding and public-service content marketingPublic education and brand communication are central to the engagementHow educational content connects to service discovery without turning awareness material into unsupported treatment claims
    REQBranding, advertising, and SEOYou want coordinated brand and acquisition work from one partnerWhether SEO has dedicated leadership, deliverables, measurement, and implementation capacity inside the broader account
    Digital DotSocial media combined with SEO, with an emphasis on reaching younger audiencesSocial discovery is a deliberate part of your audience strategyHow audience assumptions are validated and how social activity supports, rather than substitutes for, durable search assets
    OffciteWebsite design and technical SEO, with newer addiction-treatment experienceYour main constraint is technical or design-relatedRecent category-specific examples, clinical review procedures, migration controls, and the experience of the people doing the work

    Service breadth is not the same as depth. If you already employ designers and developers, a bundled redesign can add cost and coordination risk. If your site is structurally unsound, a content-only engagement may produce drafts that cannot perform as intended. Shortlist agencies by the bottleneck they are equipped to remove.

    Make every agency prove its judgment before you hire it

    Clinical, compliance, admissions, and operations leaders question two agency strategists during a website planning review.

    A polished proposal tells you how the agency sells. A controlled working exercise tells you how it thinks. Give every finalist the same decision brief and ask the same questions so that differences cannot hide behind presentation style.

    1. Ask for relevant proof, not a client logo. Request a de-identified example involving an addiction treatment or comparable healthcare organization. Have the agency explain the starting condition, actions, implementation owner, business measure, and factors it could not control. Confidentiality may limit names and raw data; it should not prevent a coherent explanation of the work.
    2. Run a live problem-solving exercise. Choose a real service or location page from your site. Ask what the agency would investigate, what it would change first, who would make the change, and how it would verify the result. You are testing prioritization, not requesting a free comprehensive audit.
    3. Meet the people who will do the work. Clarify which leaders remain involved after the sale, who writes, who handles technical implementation, who reports results, and which tasks may move to contractors. Category experience at the company level matters less if the assigned team cannot demonstrate it.
    4. Inspect the clinical review workflow. Ask how writers separate search intent from medical fact, how claims are sourced, where your clinical reviewer enters the process, and what happens when an expert rejects or qualifies a draft. An SEO writer should organize approved knowledge, not invent eligibility rules, outcomes, or treatment advice.
    5. Define the measurement chain. Have the agency connect search visibility to visits, calls or forms, appropriate inquiries, and the intake outcomes your team is authorized to share. Traffic alone does not show whether the work is reaching people who can use the service.
    6. Clarify implementation. Determine whether the agency only recommends changes or can safely make them. Ask how it handles backups, approvals, staging, redirects, structured data, quality assurance, and rollback when a technical change fails.
    7. Test the handoff. Ask what you retain when the engagement ends: content, design files, code, accounts, dashboards, keyword or topic maps, structured-data documentation, change logs, and administrative access. The answer should also appear in the contract.

    Watch for signals that the sales process is outrunning the agency’s judgment:

    • Guaranteed rankings, inquiry volume, or admissions. Search outcomes are not fully under an agency’s control, and treatment suitability belongs to qualified care and intake professionals.
    • A proposal built around publishing volume before the agency verifies your services, locations, capacity, and approval process.
    • Case studies that show traffic growth but never explain query intent, geography, implementation, or business relevance.
    • Reports that merge brand searches, informational searches, and service-seeking searches into one favorable number.
    • Refusal to provide administrative access to accounts created for your organization.
    • Structured data used as a hidden place for claims that are absent from, or unsupported by, the visible page.
    • A request to copy patient histories, diagnoses, substance-use details, or call transcripts into general marketing tools without a formally approved privacy and data-governance process.

    An agency can understand addiction treatment marketing without becoming a clinical authority. Keep that boundary explicit. Your qualified clinical, privacy, and legal owners must control the decisions that fall within their roles.

    Scope the work so SEO, AI visibility, and safety agree

    Hands arrange unlabeled planning tiles beside a laptop and a secured records folder with a key on a conference table.

    The strongest engagement turns organizational truth into a controlled publishing system. It does not begin with a large keyword list. It begins with facts the facility is prepared to verify and maintain.

    Build a service-fact matrix before producing pages

    For every service and location, record the approved version of the facts that marketing may use:

    • The service name and a plain-language explanation.
    • The setting and level of care actually provided.
    • The physical location responsible for delivering the service.
    • The audience, eligibility conditions, and exclusions, using language approved by qualified staff.
    • Credentials, affiliations, or accreditations that can be substantiated.
    • Insurance and payment language approved for publication.
    • The correct contact and intake path.
    • Any emergency or crisis direction that your clinical and legal owners require.

    The agency can then map approved facts to service pages, location pages, educational resources, metadata, internal links, local profiles, and structured data. When a search opportunity requires a claim that is not in the matrix, the agency should request review instead of stretching the available language.

    Make answer-engine and generative-engine work auditable

    AI visibility can become a vague upsell unless the agency connects it to concrete site work. Ask which questions it wants your pages to answer, which facts need clarification, which entities and locations need consistent naming, and how it will check whether your organization is represented accurately in the search and answer environments included in the scope.

    JSON-LD should represent content and claims that a person can verify on the page. It should not manufacture authority, imply a service at a location that does not provide it, or turn a marketing description into a clinical fact. Require documentation showing which visible page elements support each important structured-data field and who owns updates when services change.

    Do not buy an AI optimization package that cannot identify the pages, facts, templates, or publishing processes it will change. A visibility report may be useful, but it is not a substitute for accurate content, accessible pages, technical maintenance, or appropriate inquiries.

    Measure the path to intake without exposing patient detail

    Build reporting as a chain rather than a single dashboard total:

    • Visibility for the intended service, informational, and location queries.
    • Visits and meaningful actions on the relevant landing pages.
    • Calls or forms attributed within the limits of your approved systems.
    • Inquiries meeting a definition agreed with your intake team.
    • Downstream operational outcomes that can lawfully and safely be reported in aggregate.

    The agency should report the layers it influences, while your organization owns the definitions and permissions. Do not send detailed health histories, diagnoses, substance-use disclosures, or unredacted conversations into analytics, advertising, call-tracking, or AI systems merely to improve attribution. Your privacy and legal owners should determine what may be collected, where it may go, who may access it, and how long it may be retained.

    Put ownership and change control in the contract

    The statement of work should make performance visible and a future handoff possible. Include:

    • Deliverables: Name the audits, pages, technical changes, local work, structured data, reports, and implementation support included. Avoid a scope defined only as ongoing optimization.
    • Responsibility: Assign each deliverable to the agency, your team, or a shared workflow. State who publishes and who validates changes.
    • Approvals: Identify the content that needs clinical, brand, privacy, or legal review and what happens when approval is delayed or denied.
    • Access and ownership: Confirm that your organization controls its domain, content-management system, analytics, search tools, local listings, call-tracking assets, creative files, and data exports.
    • Change records: Require a log of material publishing and technical changes so that a decline, error, or compliance concern can be investigated.
    • Measurement: Define the reportable events, data limits, attribution assumptions, and treatment of branded versus non-branded demand.
    • Conflicts: Clarify whether the agency serves competing facilities in the same market and what account separation or exclusivity, if any, the agreement provides.
    • Exit and handoff: Specify the access, documentation, exports, unpublished work, and transition support delivered when the relationship ends.

    Have qualified counsel review material contract, privacy, and regulatory terms. Marketing procurement should not quietly make legal or clinical decisions simply because they appear inside an SEO statement of work.

    Key takeaways

    • Choose an agency for the constraint it can remove, not for the number of services it can place in a proposal.
    • Use client history, leadership experience, longevity, and size to create a preliminary screen, then test the assigned team’s actual judgment.
    • Require finalists to solve the same real page problem and explain implementation, clinical review, measurement, and handoff.
    • Keep treatment claims, eligibility language, crisis direction, and privacy decisions under qualified internal review.
    • Make AI visibility and JSON-LD auditable by tying them to visible, approved, maintainable facts.
    • Define account ownership, data limits, approvals, change control, reporting, and exit terms before work begins.

    Before booking agency demonstrations, finish your decision brief and turn the evidence questions above into a shared scorecard. Give every finalist the same facility facts and the same page scenario. The differences in their answers will tell you far more than another customized pitch.

    References

  • How to Measure Brand Visibility in AI-Mediated Journeys

    How to Measure Brand Visibility in AI-Mediated Journeys

    You may already be appearing inside AI answers while your organic dashboard says little has changed. Or AI bots may be crawling your site without your brand ever making the shortlist. If you count only clicks, both situations become an attribution mystery.

    You need to separate machine access, brand selection, human handoff, and business outcome. That gives you a measurement system that can locate the weak point in an AI-mediated journey and tell you what to test next.

    Decide what brand visibility means before scoring it

    A visit is no longer the only useful sign that a brand won. Depending on how much of the journey a person delegates, a win can be a click, an AI recommendation, or an action completed by an agent. A single traffic metric cannot represent all three.

    Start by classifying the journey into search, assistive, and agentic modes. These modes can coexist within the same purchase. Someone might discover a category through search, ask an assistant to compare the options, and then let an agent find a qualifying seller. Your measurement should follow that movement instead of assigning the whole journey to its last observable click.

    Journey modeWhat visibility looks likePrimary evidenceCommon misreading
    SearchYour page or brand is presented as an option the user can inspect.Search impressions, result position, clicks, landing sessions, and subsequent actions.Treating a high position as proof that the result influenced a decision.
    AssistiveAn AI answer names, explains, compares, cites, or recommends your brand.Observed mentions, recommendation role, cited URLs, claim accuracy, and answer-engine referrals.Counting an incidental mention as a recommendation.
    AgenticAn agent recruits your brand as an eligible option, selects it, or completes an action through it.Selection records where available, agent referrals, API or commerce events, and confirmed business outcomes.Assuming a bot request means the agent selected your brand.

    Define a qualifying visibility event before collecting data. At minimum, the brand must be correctly identified and relevant to the prompt. Record whether it was merely named, used as supporting evidence, included in a shortlist, explicitly recommended, or selected for action. Those roles have different commercial meaning.

    Set an eligibility rule for the denominator as well. A prompt belongs in your visibility rate only if your brand could reasonably satisfy the stated need, market, audience, and constraints. Including irrelevant prompts depresses the score. Excluding difficult but commercially important prompts inflates it.

    Measure each layer from machine access to business outcome

    Four connected transparent chambers depict machine access, AI selection, human handoff, and a business outcome, with observation points between them.

    AI visibility is a sequence, not an isolated mention. A useful diagnostic model follows ten gates: discovered, selected, crawled, rendered, indexed, annotated, recruited, grounded, displayed, and won. The early gates make your information available to machines. The later gates determine whether the system can understand, use, present, and act on it.

    You will not observe every gate directly. Server logs can show that a crawler requested a URL, but they cannot prove that the page was indexed, understood correctly, or used in a response. A citation can show that a URL supported an answer, but it does not reveal every internal retrieval or ranking decision. Label each measurement as observed or inferred so your dashboard does not manufacture certainty.

    Measurement layerQuestion it answersUseful measuresWhat it does not prove
    Machine accessCan qualifying bots reach and process the pages that matter?Priority URLs requested, response status, rendered content availability, repeat access, and crawler identity confidence.That the information was indexed, trusted, or selected.
    Entity understandingDoes the answer associate your brand with the correct category, products, locations, capabilities, and constraints?Entity accuracy, attribute accuracy, category association, and contradiction frequency.That the brand will be recruited for a particular decision.
    Recruitment and groundingDoes the system use your brand or content when constructing an answer?Qualifying mention rate, citation rate, cited-page coverage, claim usage, and competitor co-mentions.That the user saw a meaningful recommendation.
    PresentationHow is the brand shown to the user?Recommendation rate, shortlist inclusion, order when a genuine ranking exists, description, caveats, and next action offered.That the user followed the recommendation.
    Handoff and outcomeDid the journey reach your property or produce a business event?Answer-engine referrals, engaged sessions, leads, account creation, purchases, bookings, and other confirmed outcomes.That one observed AI answer caused the outcome.

    Keep these layers separate before creating any composite score. A blended score can rise because crawler activity increased even while recommendation visibility fell. That looks like progress until you inspect the components.

    Use a small metric dictionary so everyone calculates the same thing:

    • Qualifying mention rate: eligible prompt runs containing a valid brand mention divided by all eligible prompt runs.
    • Recommendation rate: eligible prompt runs in which the brand is positively recruited as an option divided by all eligible prompt runs.
    • Citation rate: eligible prompt runs citing an owned or controlled page divided by all eligible prompt runs. Report third-party citations separately.
    • Claim accuracy rate: checked brand claims that are materially correct divided by all checked brand claims.
    • Priority-page bot coverage: priority URLs receiving a qualifying bot request divided by all URLs in the defined priority set.
    • AI referral engagement rate: qualifying answer-engine sessions that complete your chosen engagement event divided by all qualifying answer-engine sessions.
    • AI-attributed outcome rate: confirmed outcomes with an observable AI referral or another declared attribution signal divided by the applicable set of outcomes.

    Always display the numerator and denominator next to each rate. A clean percentage built from a tiny or changing prompt set is less informative than a modest rate calculated from a stable, representative panel.

    Build a prompt panel around real decisions

    A prompt tracker is useful only when its prompts resemble the decisions your audience delegates. A list of branded questions will tell you whether an engine can repeat known facts about you. It will not tell you whether the brand is discoverable when the user has not chosen it yet.

    Build the panel from intent and constraints:

    1. Map the decisions. Include discovery, comparison, validation, troubleshooting, and action-oriented needs. Connect each need to a product line, audience, market, or journey stage.
    2. Add realistic constraints. Use the factors that can change eligibility, such as use case, compatibility, location, availability, delivery requirement, organizational size, or risk tolerance. Do not add a constraint merely to make the prompt longer.
    3. Balance non-branded and branded prompts. Non-branded prompts measure discovery and recruitment. Branded prompts measure entity understanding, accuracy, and competitive positioning.
    4. Define matching rules. List the canonical brand name, legitimate variants, product names, and exclusions that could create false positives. Decide how acquisitions, resellers, and similarly named entities will be handled before scoring begins.
    5. Fix the test conditions. Preserve the prompt wording, engine, model label, account state, location, language, and personalization state when those variables are available. Record any condition you cannot control.
    6. Review the full answer. A string match cannot tell whether the brand was recommended, dismissed, confused with another entity, or mentioned only inside a citation title.

    Useful prompt templates include:

    • What are suitable ways to solve [problem] for [audience or situation]?
    • Which providers meet [requirement] and [constraint]?
    • Compare options for [use case], especially [decision factor].
    • Is [brand or product] suitable for [specific scenario]?
    • Find an option for [need] that can satisfy [action constraint].

    Do not average every prompt into one headline number. Segment results by intent, journey mode, market, product, and engine. A brand can be highly visible in informational answers yet absent when the prompt moves to comparison or action. That boundary is where the commercial problem usually becomes diagnosable.

    For every run, capture the prompt ID, intent cluster, test conditions, brand presence, mention role, recommendation strength, cited domains, cited URLs, claims made, claim accuracy, competitors named, caveats, and proposed next action. Preserve the answer itself when your governance rules permit it. Otherwise, retain a structured review and enough metadata to reproduce the test.

    Model outputs can vary with wording, context, model changes, and personalization. Treat an individual answer as an observation, not a stable market fact. Repeated runs and a fixed protocol help you distinguish a persistent visibility pattern from an isolated output. When an engine or model changes, mark the break in the time series instead of presenting the new results as a clean continuation.

    Join prompt observations, bot visits, referrals, and outcomes

    Four colored streams of prompt observations, bot activity, referral paths, and outcome signals converge in a transparent measurement hub.

    No single analytics system sees the entire AI-mediated journey. Prompt monitoring observes the answer. Server logs observe requests to your site. Web analytics observes some human handoffs. Product, commerce, and customer systems observe downstream outcomes. Your job is to connect those views without pretending they form a deterministic user-level trail.

    Some agent analytics workflows now make bot visits and human referrals available as separate inputs. Keep that separation in your own model. Bot activity is evidence of machine access. Human referral activity is evidence of a visible handoff. Neither is a substitute for the other.

    Evidence streamMinimum fields to retainBest useImportant limitation
    Prompt observationsTimestamp, engine and model label, prompt ID, intent, market, mention role, citation, recommendation, claims, and competitors.Measuring whether and how the brand appears in AI responses.The observed answer cannot reveal every internal retrieval step or every answer shown to other users.
    Server and edge logsTimestamp, requested URL, response status, user agent, verified bot classification where possible, and rendering outcome.Diagnosing whether relevant machines can access priority content.User-agent labels can be spoofed, and a request does not establish indexing or use.
    Referral analyticsReferral class, referring domain when exposed, landing URL, session ID, campaign parameters, and engagement events.Measuring observable human handoffs from answer engines.Not every app or handoff exposes a usable referrer, so measured referrals are not the whole audience.
    On-site behaviorLanding page, content path, engagement event, lead event, account event, and transaction event.Finding friction after an AI-mediated arrival.On-site behavior alone does not establish which answer or prompt influenced the visit.
    Business outcomesOutcome type, timestamp, product or service, market, value where appropriate, and declared acquisition signal.Connecting visibility work to decisions the organization values.Self-reported and last-touch signals are useful but incomplete attribution evidence.

    Join these streams at an aggregate level using the safest shared dimensions: time period, landing URL, product, market, intent cluster, and engine class. For example, you can compare a change in citation coverage for a product cluster with bot access to its priority pages, referrals landing on those pages, and relevant conversions. That creates a defensible sequence of evidence without claiming that an anonymous conversion came from a particular monitored prompt.

    Use explicit evidence labels in every analysis:

    • Observed: a monitored answer named the brand, a known bot requested a page, a referrer identified an answer engine, or a tracked session completed an event.
    • Inferred: a page probably contributed to an answer, a referral may have followed a particular prompt, or an AI mention may have influenced a later direct visit.
    • Unknown: the platform did not expose enough information to connect the events responsibly.

    This distinction matters most when direct traffic or branded search rises after AI visibility improves. That movement may support an influence hypothesis, but it does not identify the original answer or prove causation. A post-conversion question about how the person found you can add directional evidence, provided you keep self-reported responses separate from observed referrals.

    Use the dashboard to choose the next intervention

    Your dashboard should help someone decide what to change. Organize it by the measurement layers rather than by whichever tool supplied the data:

    • Access: priority-page bot coverage, response failures, blocked resources, and rendering problems.
    • Understanding: entity confusion, missing attributes, inaccurate claims, and contradictory descriptions.
    • Selection: qualifying mention rate, recommendation rate, citation rate, cited-page distribution, and competitor overlap.
    • Handoff: answer-engine referrals, landing-page distribution, engaged sessions, and return behavior.
    • Outcome: leads, registrations, purchases, bookings, and other confirmed business events by relevant cohort.

    Read combinations of signals rather than reacting to one chart:

    Observed patternLikely failure areaNext test
    Priority pages receive qualifying bot visits, but the brand is rarely mentioned.Entity understanding, recruitment, or grounding rather than basic access.Clarify who the brand serves, what it offers, where it operates, and the constraints it satisfies. Align structured data with visible page claims, then rerun the same prompt cluster.
    The brand is mentioned, but descriptions are inaccurate or inconsistent.Entity reconciliation and claim clarity.Consolidate canonical facts, remove contradictory copy, make relationships between the organization and its products explicit, and track the disputed claims individually.
    The brand is mentioned but seldom recommended for high-intent prompts.Weak evidence for the decision criteria used in comparison.Add verifiable information about fit, limitations, availability, compatibility, or policies on the most relevant pages. Do not present unsupported superiority claims.
    Owned pages are cited, but referrals remain low.The answer may satisfy the need without a click, or the brand may be functioning as evidence rather than the chosen option.Inspect the mention role and next action before treating this as failure. Strengthen the path to a useful next step where the user genuinely needs one.
    Answer-engine referrals rise, but conversions do not.Landing-page intent mismatch or on-site friction.Compare the answer’s promise and constraints with the landing page. Preserve context, answer the next likely question, and test the relevant conversion path.
    Conversions rise without identifiable AI referrals.An attribution gap rather than confirmed absence of AI influence.Improve referral classification, retain landing context, add a carefully worded self-report field, and analyze direct and branded-search cohorts without relabeling them as AI traffic.

    Run improvement work as a controlled diagnostic. Choose one intent cluster and one suspected failure layer. Preserve the prompt panel and test conditions. Record a baseline, make the narrowest relevant change, and then observe the nearest layer as well as downstream effects. If you changed entity and product facts, claim accuracy and recruitment should move before you expect a clean conversion effect.

    Possible interventions include correcting crawl barriers, consolidating entity information, adding decision-critical details, improving citation-worthy evidence, aligning JSON-LD with visible content, or repairing an AI referral landing path. Structured data can make explicit facts easier to interpret, but it does not guarantee retrieval, citation, recommendation, or display. Measure the relevant output after implementation.

    Record platform and model changes beside your experiments. If the engine changes during the test, you have a confound, not a clean before-and-after result. Keep the observation, mark the limitation, and repeat under the new condition rather than forcing the numbers into an unsupported success claim.

    Key takeaways

    • AI visibility has distinct access, understanding, selection, presentation, handoff, and outcome layers.
    • A brand mention, an owned citation, a recommendation, a referral, and a completed action are separate events.
    • A stable, decision-based prompt panel is the foundation of comparable visibility measurement.
    • Bot visits show machine access, not brand preference or human demand.
    • Aggregate evidence can support a journey hypothesis, but anonymous events should not be turned into deterministic user-level attribution.
    • The best next optimization is the one aimed at the first layer where the evidence weakens.

    Start with one commercially important journey and map its evidence from prompt to outcome. You do not need perfect attribution before acting. You need a clear boundary between what you observed, what you inferred, and which failure point your next change is designed to address.

    References

  • Unlock Reddit: Boost Your SaaS Brand Visibility & Trust

    Unlock Reddit: Boost Your SaaS Brand Visibility & Trust

    I’ve recently discovered how impactful Reddit can be in shaping brand discovery and perception. This is increasingly significant as AI search engines prioritize Reddit threads and comments, adding weight to these discussions.

    During my deep dive into 117 SaaS brands on Reddit, I uncovered how people truly feel about brands—feelings often lost in polished marketing campaigns.

    As communities wield more power over brand perception, presence on Reddit is no longer optional; it’s essential.

    Let me share my analysis and how you can leverage Reddit for your brand.

    How I Analyzed 117 SaaS Brands: The Methodology

    My journey began by identifying key industry verticals, including:

    • Project management and productivity (15 brands)
    • Customer relationship management (CRM) (10 brands)
    • Marketing automation (14 brands)
    • SEO and marketing intelligence (8 brands)
    • Design and creative (8 brands)
    • Development and software development and IT operations (DevOps) (12 brands)
    • AI (12 brands)
    • Customer support and engagement (10 brands)
    • Analytics and data (10 brands)
    • Sales and revenue (8 brands)
    • Collaboration and communication (10 brands)

    I organized this data in a Google sheet and tracked each brand’s Reddit presence, subreddit activity, and common discussion topics.

    ```json
{
  "alt": "Social media post inviting DMs for purchasing a community.",
  "caption": "Curious about buying a community? This post invites you to DM for details!",
  "description": "A screenshot of a social media platform post dated 9 months ago, extending an invitation via direct message to purchase a community. The interface design includes icons typical of a social platform, showcasing interaction engagement. Keywords: social media, community purchase, direct message."
}
```

    Analyzing over 300 threads across these brands, I assessed brand mentions, sentiment, community engagement, and participation.

    Now, let me share the key findings.

    1. Reddit Rewards Authentic Brands

    What’s clear is that authenticity resonates with people. Brands represented by genuine, helpful, and non-promotional moderators see better engagement than those with a corporate tone.

    Redditors seek real opinions and experiences, not marketing pitches. Hence, peer recommendations are more credible than brand messages.

    When brands communicate directly and acknowledge both strengths and limitations, they gain positive reception. Some even earn upvotes and gratitude from the community.

    ```json
{
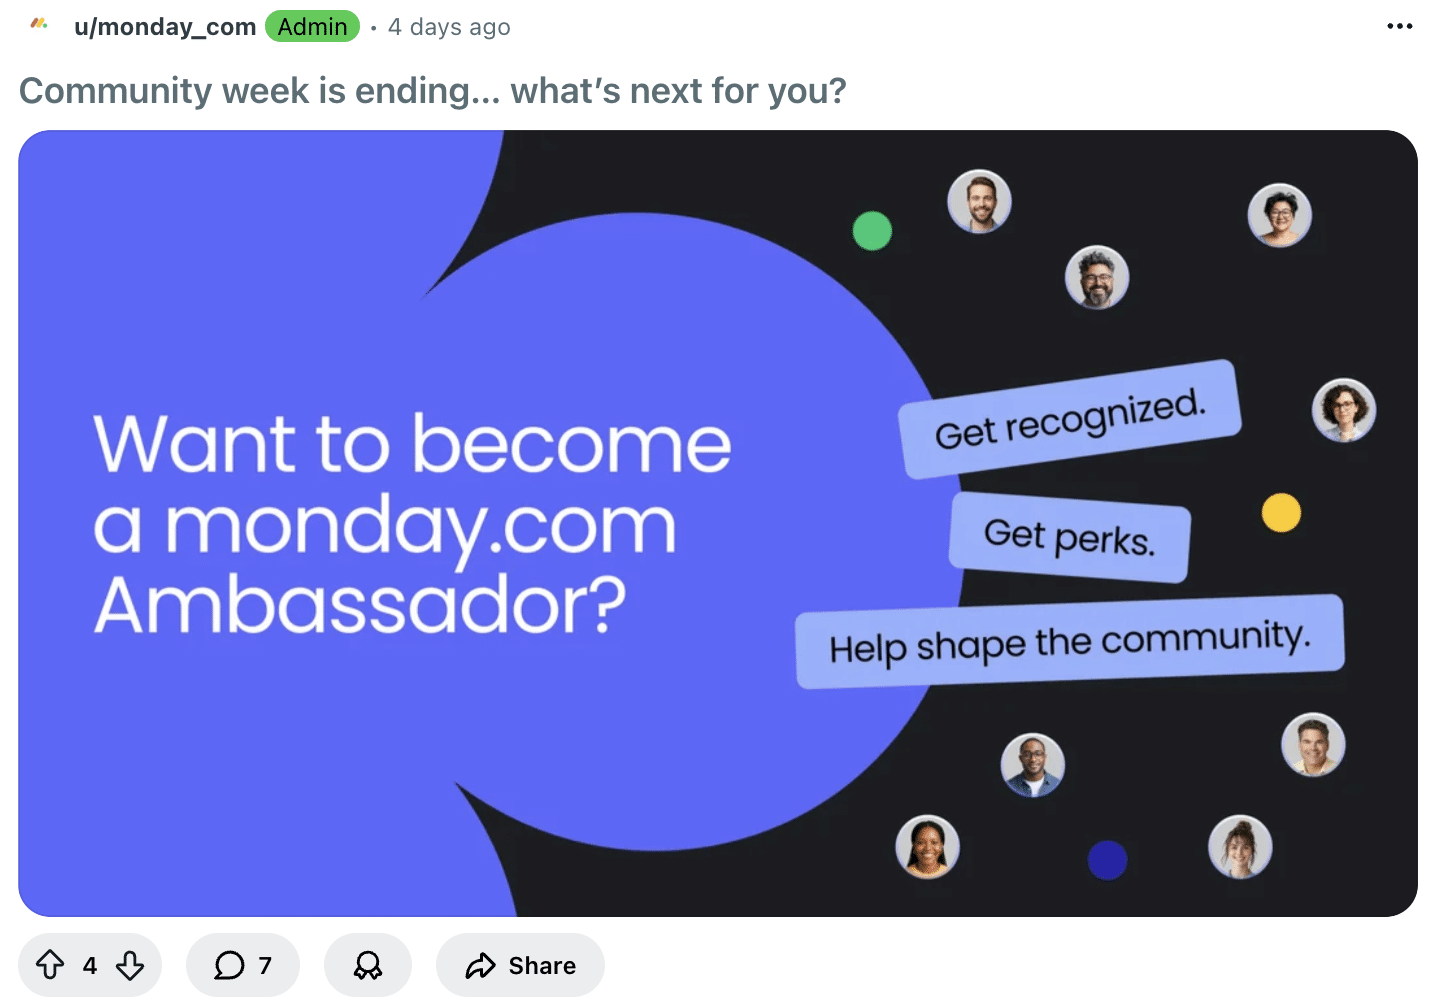
  "alt": "monday.com Ambassador program invitation with avatars and benefits like recognition and perks.",
  "caption": "Dream big with monday.com! Become an ambassador to earn recognition, enjoy perks, and shape an inspiring community. Join today and make a difference!",
  "description": "This image promotes the monday.com Ambassador program, featuring the question, 'Want to become a monday.com Ambassador?' on a blue background. Surrounding the text are circular avatars of community members and text bubbles highlighting benefits like getting recognized, getting perks, and helping shape the community. The vibrant design with contrasting colors and personal elements invites viewers to engage with the program. Keywords: monday.com, Ambassador, community, engagement, recognition, perks, join."
}
```

    2. Brands Not on Reddit Are Missing Out

    Conversations about brands happen on Reddit with or without their presence. Astonishingly, 30 of the brands I researched don’t engage on Reddit, and 23 have inactive subreddits.

    Users pose direct questions about brands and receive insights from fellow redditors. Without a brand presence, these discussions and reputations evolve independently.

    Sometimes, other entities may misuse popular brand names, creating potential misrepresentations. Ensure you’re part of the conversation to maintain control over your brand’s narrative.

    3. Reddit is a Customer Research Goldmine

    Reddit offers unfiltered user insights that traditional feedback methods might miss. Customers openly discuss onboarding issues, integration challenges, and more.

    Reddit Captures Feedback That Traditional Methods Miss

    On Reddit, users frequently talk about issues like:

    ```json
{
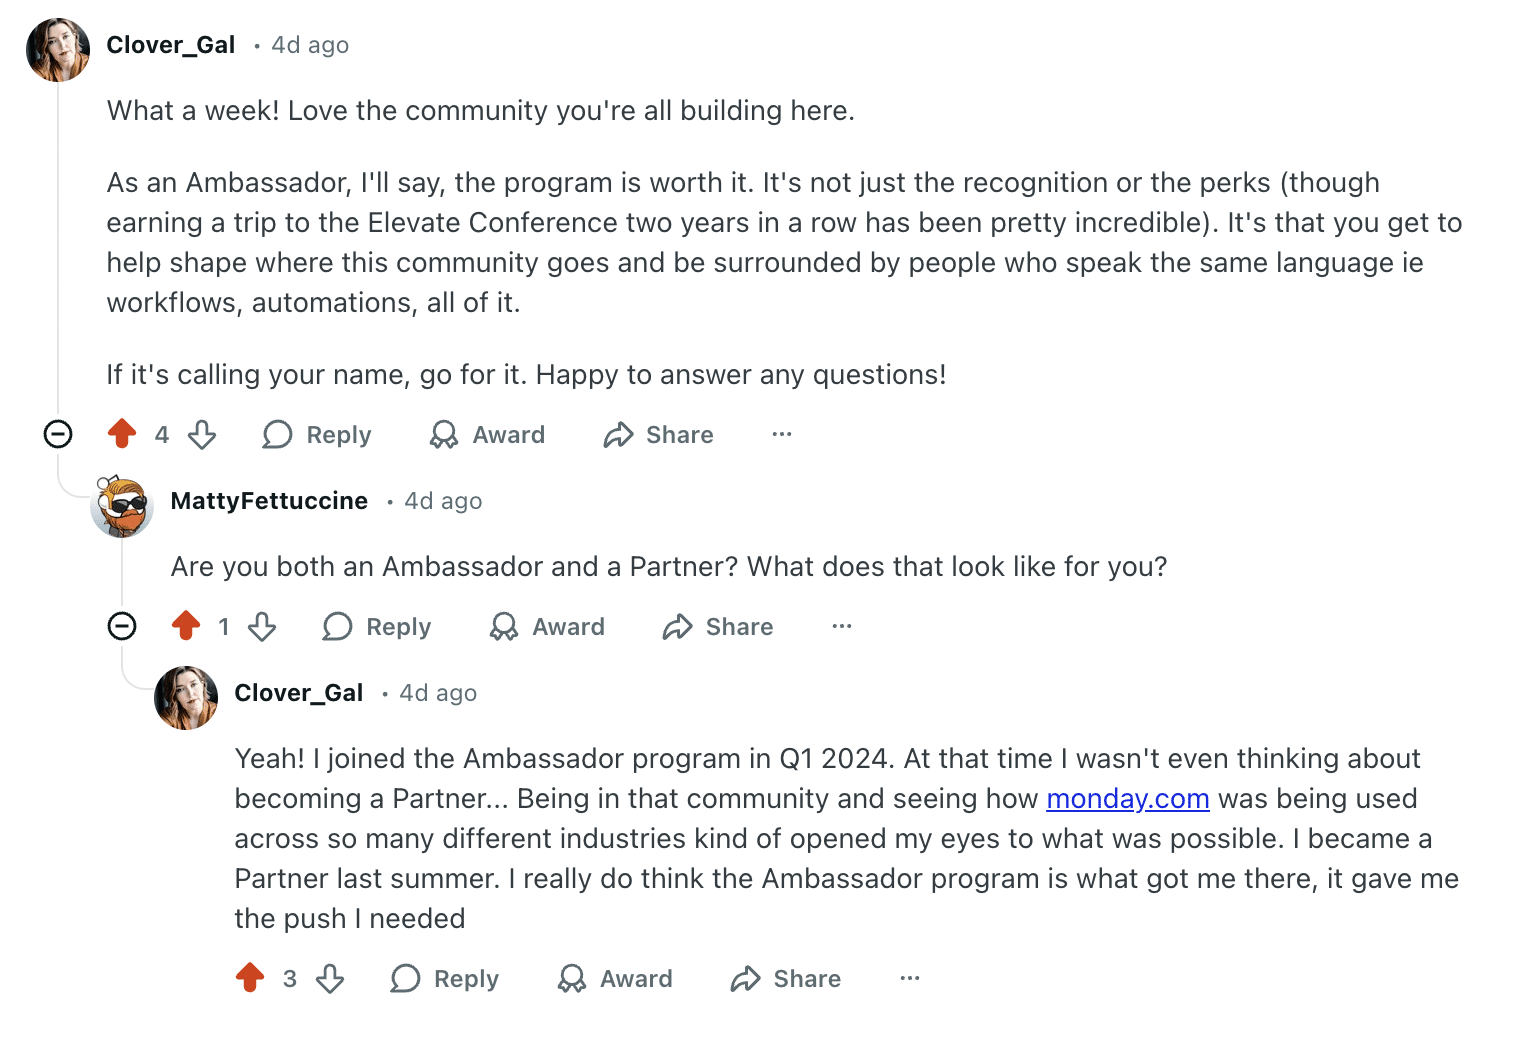
  "alt": "Reddit thread discussing the ambassador program's value, with users Clover_Gal and MattyFettuccine exchanging insights.",
  "caption": "Community spirit shines in a Reddit thread as Clover_Gal shares the perks of joining the ambassador program, engaging with fellow user MattyFettuccine.",
  "description": "This image captures a Reddit conversation where Clover_Gal praises the ambassador program, mentioning benefits like attending the Elevate Conference. MattyFettuccine asks about the dual role of Ambassador and Partner, to which Clover_Gal responds with enthusiasm about joining in Q1 2024. The comment highlights experiences with different industries, particularly with monday.com, emphasizing the program’s value for professional growth. Upvotes and reply options are visible, indicating community engagement."
}
```
    • Onboarding struggles
    • Integration challenges
    • Mobile usability issues
    • AI feature frustrations
    • Updates confusion
    • Alternatives being built

    This invaluable honesty helps refine SaaS products beyond what traditional surveys can capture.

    Reddit Supports Brand Advocates

    Happy customers often become brand advocates on Reddit, promoting brand ambassador programs and sharing their positive experiences, enhancing brand image.

    Some Brands Have Self-Sustaining Reddit Communities

    Some Reddit communities thrive with little brand intervention, offering peer-to-peer support, problem-solving, and resource sharing, ensuring community sustainability.

    Redditors Highlight Preferred Competitor Features and Pricing Frustrations

    Pricing is a hot topic, with users often expressing discontent and citing alternative options, highlighting gaps and opportunities for improvement.

    Redditors Share Their Actual Use Cases

    Reddit is a platform where users detail their real-world tool applications, which provides valuable insight for product optimization.

    Reddit is Essential for Brand Visibility and Perception

    With real-time brand discussions, Reddit plays a crucial role in shaping visibility and perception, impacting AI-driven search results and influencing consumer decisions.

    It’s crucial for brands to monitor these discussions, engage meaningfully, and utilize Reddit as a platform for reputation management and product insights.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • AI Search Visibility: An SEO Plan for Zero-Click Results

    AI Search Visibility: An SEO Plan for Zero-Click Results

    Your ranking report looks healthy, but organic visits are slipping. That gap does not automatically mean your SEO has failed. It can mean that more of the search journey is happening inside an AI answer, featured result, or search-results page before a visitor reaches your site.

    Zero-click behavior also predates generative search. Rand Fishkin traces its emergence to around 2011, estimates that nearly half of searches ended without a click by 2016-2017, and puts the current share above two-thirds. Those estimates should not become a universal benchmark for your reporting, but the direction is clear: you need to measure whether your brand influenced the answer, not only whether your page received the visit.

    Replace the traffic funnel with a visibility ladder

    Traditional SEO reporting often jumps from ranking to session to conversion. AI search introduces several observable outcomes between ranking and session. If you skip them, every answer that satisfies a user without a click looks like failure, while every low-quality visit looks more valuable than it really is.

    Use a visibility ladder instead:

    • Retrievability: The page can be found, crawled, understood, and associated with the relevant question.
    • Answer inclusion: Your information, page, or brand appears in an AI answer, AI Overview, featured result, or other search feature.
    • Attribution: The answer names your brand, cites your page, or provides a link. These are different outcomes and should be recorded separately.
    • Recognition: Searchers repeatedly encounter your brand in connection with the subject, even when they do not leave the results page.
    • Engagement: Some searchers click, return directly, subscribe, or continue into another measurable interaction.
    • Business impact: The interaction contributes to a qualified lead, sale, subscription, renewal, or another outcome your organization actually values.

    A mention is not a conversion, and a citation is not revenue. They are upstream signals. Keeping the stages separate prevents you from assigning invented financial value to an AI appearance while still acknowledging that search visibility can exist without a session.

    Visibility layerWhat to recordWhat it helps you decide
    Answer exposurePresence in AI answers, AI Overviews, featured snippets, and other answer surfacesWhether your content is entering the visible answer set
    AttributionBrand mentions, citations, links, cited URLs, and the context surrounding the mentionWhether the platform connects the information to you
    Site engagementSearch impressions, click-through rate, AI referral visits, deep-link landings, and useful on-site actionsWhether the visible answer creates a reason to continue
    Brand demandBranded searches, direct visits, returning visitors, subscriptions, and preferred-source selection where availableWhether repeated exposure is becoming intentional demand
    Business outcomeQualified leads, purchases, subscriptions, renewals, or another agreed conversionWhether the search program contributes to the organization

    Do not collapse these measures into a single visibility score unless every weight has a defensible business meaning. A composite score can rise because mentions increased while qualified visits disappeared. A stage-by-stage dashboard makes that tradeoff visible.

    Publish an answer that earns visibility and a page worth visiting

    A concise content module moves from a larger web page into an abstract AI answer panel beside a richer page with supporting material and exploration paths.

    The wrong response to zero-click search is to conceal the answer and force the user to hunt for it. That weakens the page for the person who does visit and makes its central purpose harder to identify. The stronger model has two layers: an answer layer that can stand on its own and a continuation layer that helps the reader make a decision or complete a task.

    Layer one: make the direct answer unambiguous

    Start the relevant section with the conclusion, definition, instruction, or status the query requires. Name the subject explicitly. State important scope conditions beside the claim instead of hiding them in a distant caveat. A reader and an answer system should not need to combine several vague paragraphs to work out what you mean.

    This is the practical value of utility content: service-oriented explanations, checklists, FAQs, and comprehensive guides answer immediate audience questions in a simple form. Simple does not mean thin. A short answer can be clear while the rest of the page handles exceptions, evidence, consequences, and application.

    • Use a heading that matches the real question rather than a clever label that needs interpretation.
    • Put the answer immediately beneath that heading.
    • Identify the product, platform, location, audience, or version whenever the answer depends on it.
    • Keep names and terminology consistent across the title, headings, copy, internal links, metadata, and structured data.
    • Separate facts from recommendations. Readers should be able to tell what is documented, what is conditional, and what you advise them to do.
    • Correct or update the visible passage when the underlying fact changes; changing only a date or schema field does not repair stale content.

    Layer two: give the reader a reason to continue

    An answer surface can usually absorb a definition, a short explanation, or a basic checklist. It is less able to replace the work that comes after the answer. That is where your page should become more useful.

    • Decision support: Explain the criteria, tradeoffs, exceptions, and consequences that change the choice.
    • Application: Show how the answer changes for distinct situations instead of repeating the same generic advice.
    • Original value: Add evidence, examples, tools, templates, calculations, or analysis that cannot be reproduced accurately from a short summary alone.
    • Execution: Turn the answer into a sequence the reader can follow, including what to inspect and what a failed check means.
    • Maintenance: State what can change, then update the page when that trigger occurs.

    Do not add length merely to manufacture a click. A long generic page gives an AI system more interchangeable language without giving the reader more value. The continuation layer should resolve uncertainty that remains after the top-line answer.

    This also changes how you manage evergreen content. Keep a working inventory of the questions each page owns. Watch the events that could invalidate an answer. Refresh the relevant explainer when the facts change, create content only where a genuine question remains uncovered, and consolidate overlapping pages into a maintained topic library. Recirculate the useful resource when demand returns. Evergreen should describe the question, not an assumption that the answer never needs attention.

    Make important passages reachable as well as readable

    Passage-level visibility matters when a search result sends the reader to a specific section rather than the top of the page. Google’s read-more snippet links make that path possible, but the destination has to survive the load process. The first test is not whether the section exists in your content management system. It is whether a visitor following the deep link can see the intended passage immediately.

    Google’s published implementation advice is concrete: keep the destination content visible, avoid JavaScript that takes control of the user’s scroll position during page load, and preserve the hash fragment when using the History API or changing window.location.hash.

    • Do not hide the answer exclusively inside a closed tab, accordion, carousel, or other expandable control.
    • Give major sections descriptive headings and stable fragment identifiers.
    • Paste the complete deep URL, including its fragment, into a fresh browser tab and confirm that it lands on the intended section.
    • Watch the page after scripts, banners, fonts, and late-loading components finish. The destination should not be pushed away or replaced by a scripted scroll.
    • Test the same URL from a mobile-sized viewport because overlays and responsive components can change the landing behavior.
    • If a script rewrites the URL during load, verify that it does not remove the fragment or redirect the visitor to a generic location.

    Treat structured data the same way. JSON-LD should clarify the entities and relationships already supported by the visible page. It should not introduce answers, authorship, reviews, dates, or other claims that a visitor cannot verify in the content. Valid markup can improve machine readability, but validation alone does not guarantee an AI citation, a rich result, or a ranking.

    Your final quality check should follow the user’s route: search result, deep link, visible passage, supporting detail, and next action. A technically valid page can still fail if that route breaks after the click.

    Measure repeated visibility, not a lucky screenshot

    An analyst reviews a matrix of abstract answer panels in which the same amber source marker appears repeatedly across multiple results.

    Generative answers are not fixed search listings. The same or similar request can produce different wording, citations, and omissions across attempts. That variability makes a single screenshot useful as evidence of an occurrence, but weak as evidence of reliable visibility. A more defensible process repeats prompts and looks for consistent patterns across the outputs.

    1. Define a stable query set. Include the actual questions behind your important pages, not just head terms. Preserve the wording so changes in the test do not masquerade as changes in visibility.
    2. Record the observation context. Log the platform, search surface, model or mode when shown, prompt, date, location, device context, and sign-in or personalization state when relevant.
    3. Repeat the observation. Check whether the brand, citation, linked page, and answer framing persist across attempts. Do not report a single appearance as durable coverage.
    4. Separate mention from citation and link. A brand can be named without receiving a citation, and a page can be cited without the brand being prominent. Each outcome creates a different opportunity and risk.
    5. Capture the cited destination. A citation to an obsolete page, weak supporting page, or unintended URL can produce visibility while sending the user into the wrong experience.
    6. Compare exposure with behavior. Review answer presence beside impressions, click-through rate, AI referrals, branded demand, useful on-site actions, and business outcomes. Look for aligned movement without pretending that correlation proves causation.
    7. Turn the finding into an editorial action. Repair incorrect framing, strengthen a missing answer passage, consolidate competing URLs, add continuation value, or refresh a fact that has fallen out of date.

    The pattern matters more than any isolated metric. If search impressions remain strong, clicks decline, and attributed AI appearances become more consistent, zero-click consumption is a plausible explanation. Protect the accurate answer while improving the reason to continue. If rankings hold but your brand rarely appears in answer surfaces, inspect the directness, scope, freshness, entity consistency, and passage accessibility of the page before producing more content on the same question.

    If citations increase but qualified actions do not, inspect the query and landing experience. The content may be visible for an informational question that has little relationship to the business, or the cited passage may answer the question without leading naturally to a useful next step. That is not an argument for making the answer worse. It is a reason to stop treating every impression as equally valuable.

    Brand framing deserves its own review. An unlinked but accurate mention can still support recognition. A prominent but inaccurate mention can damage it. Record the surrounding claim, not merely the presence of your name. Where a platform lets users choose preferred sources, inviting an existing audience to select your publication can support future visibility and loyalty, but it should remain a separate measure from organic inclusion.

    Key takeaways

    • Falling clicks do not prove falling visibility. Measure answer inclusion, brand mentions, citations, links, engagement, and business results as separate stages.
    • Give the immediate question a direct, visible answer, then earn the visit with decision support, application, original value, and a workable next step.
    • Maintain evergreen pages around durable audience questions while refreshing the answers whenever facts, products, or conditions change.
    • Keep important passages visible and deep-linkable. Preserve URL fragments and prevent scripts from overriding the visitor’s landing position.
    • Repeat AI-search observations because an isolated output cannot establish dependable visibility.
    • Use structured data to describe supported, visible content. Do not treat valid JSON-LD as a guarantee of rankings or citations.

    For your next publishing cycle, choose a commercially meaningful topic cluster and map its visibility ladder before adding more pages. Rewrite the primary answer for clarity, strengthen the continuation value, test every deep link, and add repeated AI observations to the same dashboard as traffic and conversions. You will then be able to distinguish lost demand from changed behavior and make the right fix.

    References


  • Healthcare Review Compliance: A Local SEO Playbook

    Healthcare Review Compliance: A Local SEO Playbook

    You need enough recent reviews to compete in local search, but one careless request or reply can expose a patient relationship, violate a professional ethics rule, or turn a routine reputation task into a compliance problem.

    The answer is not to abandon reviews. It is to govern them as carefully as any other healthcare communication: decide who may be approached, separate the request from clinical care, remove pressure from the interaction, and prevent public replies or appeals from revealing private information.

    Set the compliance boundary before anyone asks for a review

    Reviews matter because they influence both discovery and trust. Review quantity, quality, recency, and consistency account for four of the top 15 factors in a Whitespark survey of Google Maps ranking factors. More than 80% of consumers also use Google reviews when judging local businesses. That creates real pressure to collect more feedback, but the marketing goal never overrides your privacy and professional obligations.

    The first deliverable should be a one-page eligibility map, not a review-request message. Have the appropriate privacy, compliance, or legal professional approve it before launch. Healthcare rules and professional codes vary by provider type, jurisdiction, organization, and relationship, so a process that works for one facility is not automatically safe for another.

    • Governing rules: Record the privacy requirements, licensing-board rules, professional ethics codes, and internal policies that apply to the people involved.
    • Excluded relationships: Identify the patients, clients, family members, or other people who must not be solicited.
    • Permitted stage: Define the point in the relationship, if any, at which an approved request may be made.
    • Authorized requester: Name the role responsible for the request and state whether clinical personnel may participate.
    • Approved channels: Specify whether the request may be delivered verbally, by text, through an alumni group, or with a QR code.
    • Escalation rule: Tell staff to stop and ask for compliance review whenever eligibility is unclear.

    Mental-health practices require particular care. Therapists governed by the American Psychological Association’s ethics code can face restrictions on soliciting testimonials from clients because the clinical relationship creates a risk of undue influence. That is not a minor wording issue that a softer request can fix. If the relationship is excluded, the practice should not ask.

    Former patients, alumni, and people no longer receiving active treatment may present a different situation, but “former” is not a universal safe harbor. Confirm that the applicable code and your organization’s policy permit the request. Using non-clinical staff is a useful separation of duties, not permission to bypass an ethical restriction.

    Build a steady review process without creating pressure

    A clinic visitor independently considers a blank review invitation after leaving a private appointment area.

    A compliant review engine is a repeatable operational workflow. It should not depend on a clinician remembering to ask at the end of an appointment, and it should not reward employees for producing a particular number of reviews. Both practices can create pressure at the point where the care relationship is most sensitive.

    1. Assign a non-clinical owner. Give one coordinator responsibility for approved outreach, links, staff questions, monitoring, and escalation. Make compliance with the process part of the role; do not make compensation depend on review volume.
    2. Choose an eligible interaction trigger. A permitted alumni check-in or other approved post-care interaction is more controllable than an improvised request during treatment. Document exactly what event makes the person eligible.
    3. Ask person to person. An approved staff member can make a neutral request during the eligible interaction. The person must be free to decline without affecting services, access, or the relationship.
    4. Shorten the path after consent. If someone says they are willing to leave feedback, send the direct review link by the approved channel. A QR code can also reduce friction in an alumni communication or other approved setting.
    5. Track cadence and process health. Monitor whether approved requests are happening consistently, whether staff are following the eligibility rules, and whether questions are being escalated. Do not treat a sudden burst of reviews as a substitute for a sustainable process.

    One addiction-treatment center used a non-clinical alumni coordinator, an online alumni group, QR codes, and direct links sent after verbal commitments. Its operating goal was 50 to 100 new reviews while maintaining at least one new review per week. The center added more than 100 reviews in a year, moved from a 4.6 to a 4.8 rating, and reached 500 total reviews by February 2026.

    That is one program’s result, not a universal benchmark. The transferable lesson is the operating design: outreach happened through a defined alumni program, a non-clinical employee owned the workflow, and willing participants received a direct route to the review page. The improvement came from consistency and lower friction, not from asking active patients at vulnerable moments.

    Reply without confirming that the reviewer was a patient

    A healthcare staff member prepares a generic public reply as a translucent filter separates private medical details from the response.

    A reviewer may voluntarily discuss treatment, a diagnosis, medication, staff, or dates. That disclosure does not give your organization permission to confirm or expand on it. Even a well-intended sentence such as “We are sorry your appointment went badly” may validate that the person received care.

    Use a response structure that addresses the public audience without discussing the individual’s circumstances:

    1. Acknowledge the feedback, not the relationship. Thank the person for taking the time to comment without calling them a patient or client.
    2. State the privacy boundary when needed. Explain that privacy obligations prevent discussion of individual circumstances in a public forum.
    3. Refer only to general policy. You may describe how the organization ordinarily handles concerns, but do not say how a particular case was handled.
    4. Offer an approved offline route. Direct the reviewer to a privacy-reviewed phone number, email address, or responsible role.
    5. Stop there. Do not defend the organization by quoting records, naming clinicians, identifying services, or debating the reviewer’s account.

    A restrained positive reply can be as simple as: “Thank you for taking the time to share feedback. We appreciate it.”

    For a critical review, use a privacy boundary and an offline route: “We take feedback seriously. Privacy obligations prevent us from discussing individual circumstances here. Please contact our [role] through [approved channel] so the concern can be reviewed.”

    Templates reduce improvisation, but they still need internal approval. Give responders a short prohibition list as well. They should never write “we checked your chart,” “you were not our patient,” “when you came to us,” or anything that confirms a diagnosis, medication, appointment, treatment, family relationship, or service history.

    This rule also applies when staff believe a review is fabricated. Publicly stating that the organization has no record of the person can still disclose how patient status was checked. Respond generically, preserve the evidence internally, and move the dispute into the platform’s reporting process.

    Report policy violations without submitting patient information

    A removal request should explain why the content violates the platform’s policy. It should not attempt to prove that the reviewer was, or was not, a patient. That distinction matters because a reputation problem does not justify disclosing protected information to Google.

    1. Preserve the public evidence. Record the review text, date, URL, and the specific language you believe violates policy.
    2. Select the narrowest applicable category. Focus on issues such as personally identifiable information, offensive material, unrelated content, repetitive content, or another explicit platform violation.
    3. Explain the violation using public facts. Point to the words in the review and the policy they conflict with. If the problem is a demonstrably false public claim, address that claim without referring to a patient file or care relationship.
    4. Exclude clinical and relationship evidence. Do not attach records, disclose treatment details, identify staff-patient interactions, or tell the platform whether the reviewer received services.
    5. Log the submission internally. Keep the policy category, evidence, submission date, decision, and any approved next step together so later appeals remain consistent.

    Not every false or unfair review will qualify for removal. A policy-based submission gives the platform a specific issue to evaluate; a long rebuttal about the reviewer’s history creates privacy risk without necessarily strengthening the case. If the available evidence depends on confidential information, stop and have privacy or legal counsel decide what, if anything, may be submitted.

    Key takeaways

    • Map the applicable privacy and professional-ethics restrictions before writing a review request.
    • Do not assume every former patient or alumnus may be solicited; approve eligibility for the specific provider and relationship.
    • Give a non-clinical owner responsibility for a steady, documented workflow, without volume-based incentives.
    • Make approved participation easy with direct links or QR codes after a person has voluntarily agreed to leave feedback.
    • Reply to the feedback without confirming that the reviewer received care or discussing individual circumstances.
    • Report reviews through the relevant platform-policy category and keep patient records out of the submission.

    Start with the eligibility map and response templates. Once those are approved, add one permissible request trigger and one accountable owner. That gives you a review process you can run consistently without asking frontline staff to make privacy and ethics decisions in the moment.

    References


  • Google Maps Contributor Features: A Practical Workflow

    Google Maps Contributor Features: A Practical Workflow

    You have useful photos on your phone and first-hand details about a place, but turning them into a clear Google Maps contribution still takes judgment. The latest contributor features reduce the mechanical work: they surface media sooner, draft captions and make contributor history more visible.

    Use that convenience to publish more useful evidence, not simply more content. A faster upload, an AI-written caption or a prominent badge can attract attention, but none of them can make a vague or inaccurate contribution trustworthy.

    Key takeaways

    • Local Guides profiles now place greater emphasis on total points, levels and badges. Gold profile indicators can make top contributors more noticeable, but prominence is not proof that every contribution is accurate.
    • Gemini can analyze selected photos and propose a caption. You can edit or discard the draft, so treat it as a starting point rather than an observation you must accept.
    • The Contribute tab surfaces recent uploads, while camera-roll suggestions can shorten the path from taking a photo to sharing it. Media access is required for those suggestions.
    • These features may affect which reviews and businesses receive attention. They do not, by themselves, establish a direct improvement in local rankings, AI-search visibility or business performance.

    Match each contributor feature to the job it actually does

    The contributor changes solve three different kinds of friction. Keeping those jobs separate prevents you from treating every feature as a ranking tool.

    • Contributor profiles provide context. The redesigned Local Guides profile displays total points and levels more prominently, gives badges a refreshed presentation and adds gold profile indicators for top contributors. These are reputation and attention signals around a contribution. They do not verify the claim inside it.
    • Gemini caption drafts reduce writing friction. The feature analyzes the photos you select and proposes text that you can edit or reject. Its useful job is getting you past the blank field, not supplying knowledge that the image cannot contain.
    • Media suggestions reduce retrieval friction. Recent uploads appear in the Contribute tab, and Google Maps can suggest camera-roll images after you allow media access. This helps when the obstacle is finding the right photo later.

    If you contribute regularly, test every photo or review without its profile decoration: would the content still help someone choose an entrance, recognize a storefront, understand the layout or set an accurate expectation? If not, more points and a brighter badge will not repair it.

    If you manage local visibility for a business, reverse the test. A gold indicator may cause a user to notice a review, but you should still inspect the review’s specificity, recency and visible evidence. Contributor status is context for evaluating a claim, not a substitute for evaluating it.

    Edit Gemini captions until they say what the photo proves

    A contributor compares a phone photo with a cafe's accessible entrance while editing a draft description.

    At its introduction, the Gemini caption feature was available in English on iOS in the United States. Broader Android and international availability was planned. Availability can therefore differ by device, language and location; keep a manual caption workflow even if another contributor already has the control.

    The most important limitation is conceptual. Gemini can analyze the selected image, but a photo does not necessarily prove how the service felt, how food tasted, whether a route is fully accessible or whether a temporary display will remain in place. The draft can turn a visual impression into a stronger claim than the evidence supports.

    Use a four-pass caption edit

    1. Name the visible subject. Identify the entrance, seating area, menu board, counter, parking area or other feature the photo is meant to show.
    2. Remove inferred praise. Delete generic judgments such as “excellent,” “welcoming” or “perfect” unless the caption is deliberately expressing your own experience and the wording makes that clear.
    3. Add decision-relevant context. Explain where the photographed feature is located or why someone might need to recognize it. Add only details you observed or verified.
    4. Check whether the claim will age badly. Prices, hours, displays and layouts can change. Do not present a time-sensitive detail as a permanent feature.

    For example, a draft such as “A cozy cafe with plenty of seating” is broad and evaluative. A more useful edit would be “Indoor tables are beside the front window, with the order counter at the back.” The second version tells a visitor what the image is intended to establish without pretending that the photo proves comfort, availability or service quality.

    There is also a quick test for generic AI text: ask whether the same caption could be pasted onto a different venue’s photo without anyone noticing. If it could, the caption is not finished. Name the concrete feature that makes this image useful at this place.

    Turn camera-roll suggestions into a controlled publishing queue

    A smartphone displays selected and dimmed place-photo thumbnails arranged as a controlled publishing queue.

    The media-sharing update has a broader footprint than the initial caption rollout. Recent media and camera-roll suggestions were made available on iOS and Android globally. Suggestions depend on granting media access.

    A suggestion is an invitation to review an image, not confirmation that the image belongs on Maps. Camera rolls also contain duplicates, screenshots, private details and photos whose location is ambiguous. Put a short verification step between the prompt and the publish button.

    1. Open the Contribute tab after a visit. Review the recent media while you can still distinguish the venue and remember what each image shows.
    2. Confirm the exact place. Check the name and location, especially when a business has several branches or neighboring listings look similar.
    3. Choose the highest-information image. Prefer a photo that answers a practical question over several nearly identical angles.
    4. Inspect the full frame. Exclude unrelated or sensitive details and any image too blurry, dark or obstructed to support its caption.
    5. Write or generate the caption. Apply the evidence test even when Gemini supplies the first draft.
    6. Read the listing and caption together. Make sure the text describes this image at this place, then publish only when both are unambiguous.

    If you are not comfortable enabling camera-roll access, do not enable it merely to save a few taps. A slower, deliberate selection process is better than a convenient workflow you will not review carefully. You can also revisit the relevant operating-system permissions if your comfort level or contribution habits change.

    Do not mistake contributor visibility for a ranking result

    More prominent contributor profiles, faster media sharing and clearer captions can change what people notice. That can influence which reviews they consider credible and which businesses receive attention. It is still a leap from increased attention to a claim that a feature directly raises a business in Google Maps, local search results or an AI-generated answer.

    Three outcomes need separate measurement:

    • Publishing efficiency: Did the recent-media flow help you turn relevant photos into completed contributions instead of leaving them in a backlog?
    • Contribution quality: Did the final captions become more specific, accurate and useful after editing, or did AI merely increase the volume of generic text?
    • Search or business visibility: Did the business’s observed visibility change after the contribution? If it did, record the timing as a correlation. Do not assign causation without isolating other listing, review, competition and search changes.

    The same restraint applies to AEO and GEO claims. A Google Maps caption may add useful public context around a place, but these contributor changes do not demonstrate that a frontier model will retrieve, cite or rank that caption. Treat any such effect as a hypothesis to measure, not a benefit to promise.

    Start with one recent photo that answers a real visitor question. Verify the place, edit the caption until every claim is supportable and record when you published it. If the workflow consistently produces clearer contributions, keep it. If it only produces more contributions, tighten the review step before you scale it.

    References


  • How to Make Your Brand Clear Enough for AI Discovery

    How to Make Your Brand Clear Enough for AI Discovery

    You can publish more content, refine your metadata and add structured data, yet still leave AI systems with a vague picture of your brand. The problem is often upstream of SEO: your site never makes one coherent case for who you help, when you matter and what specific outcome you enable.

    Fix that before you scale production. A clear solution definition gives your pages, schema, brand mentions and conversion paths the same job. It also makes it easier for an AI-generated answer to place your brand in the right decision, rather than describing you as one more member of a broad category.

    The real failure is ambiguity, not a lack of content

    People no longer have to search with a short category phrase, open a row of tabs and assemble their own shortlist. They can describe a situation, constraint and desired result in one prompt. Generative systems can then break that request into related questions and synthesize an answer.

    That changes the competitive unit. Your product category may get you considered, but the problem you solve determines whether you belong in the final answer. An AI system needs enough consistent information to connect your brand to a particular customer situation.

    Four ideas are commonly blurred together:

    • Category: what kind of company or product you are.
    • Offering: what the customer can buy or use.
    • Problem: the undesirable situation that creates a reason to act.
    • Outcome: the progress the customer expects after choosing you.

    A project-management platform is a category. Automated client approvals may be an offering. Work stalling because feedback is scattered across email and chat is a problem. Getting approved work into production without repeated follow-up is an outcome. Those statements are related, but they are not interchangeable.

    Category-only language is especially weak in AI discovery. Phrases such as complete platform, innovative solution and tools for growing businesses give a system almost nothing with which to match your brand to a specific request. They omit the trigger, the affected customer, the consequence and the reason your approach fits.

    Look for ambiguity wherever your company could give several plausible answers to the same question. If the homepage emphasizes efficiency, the sales deck leads with cost control, the About page claims innovation and product pages focus on collaboration, you have activity without a stable position. Each claim may be defensible alone. Together, they make the brand harder to classify.

    Define the decision in which your brand should appear

    A glowing route links a faceted object to a person at an open doorway while other paths disappear into fog.

    Start with a solution statement written for internal use. It should be precise enough to guide a homepage, a content brief and a structured-data review:

    For [specific customer] facing [trigger or situation], [brand] helps [desired progress] through [relevant mechanism], especially when [important constraint or decision criterion].

    This is not a tagline. It is a decision rule. Each field forces a useful choice:

    • Specific customer: name the role, operating context or level of need that changes the decision. A useful audience is narrower than businesses or consumers.
    • Trigger or situation: identify what has happened to make the problem urgent. The trigger might be a failed handoff, an expanding workload, a new requirement or an existing process that no longer works.
    • Desired progress: describe what becomes easier, safer, faster or more reliable for the customer. Do not substitute a feature for the result it supports.
    • Relevant mechanism: explain how your approach produces the result. This may be a workflow, service model, specialization or product capability.
    • Constraint or criterion: state the condition under which your difference matters. This is often where real positioning appears.

    Do not force every capability into the statement. Choose the situation in which you have the clearest combination of relevance, differentiation and evidence. Secondary use cases can branch from that center. If every use case has equal priority, no use case guides the rest of the brand.

    Stress-test the statement before publishing it

    Put the draft through these tests:

    • Substitution test: remove your name and insert a typical competitor. If the statement remains equally true, the mechanism or criterion is too generic.
    • Prompt test: turn the situation into a natural-language request beginning with Which option is right for someone who… Your brand should be a logical candidate without adding facts that are absent from your site.
    • Exclusion test: state who would not be well served by the promise. A position that excludes nothing usually distinguishes nothing.
    • Evidence test: underline every implied claim. Each one should connect to visible support such as a demonstrated capability, documented process, relevant credential, customer result or clearly explained limitation.
    • Internal consistency test: ask people responsible for leadership, sales, product and support to complete the statement independently. Materially different answers reveal a positioning decision that has not actually been made.

    If the evidence test fails, narrow the promise. Do not compensate with stronger adjectives. Clear, supportable language is more useful than a sweeping claim that your public footprint cannot substantiate.

    Make every public signal support the same solution

    Once the solution statement is stable, translate it across the places where people and machines encounter the brand. Consistency does not mean repeating one sentence word for word. It means preserving the same audience, problem, outcome and explanation while adapting the detail to each page.

    Use a simple signal hierarchy:

    • Identity signals: the brand name, category, primary offering and audience should not change casually between the homepage, About page, profiles and structured data.
    • Positioning signals: core pages should connect the brand to the same primary problem and desired outcome.
    • Explanatory signals: service, product and educational pages should show how the approach works, when it fits and where it does not.
    • Evidence signals: claims should lead to the appropriate proof rather than relying on unsupported superlatives.
    • Action signals: the next step should match the visitor’s decision stage, whether that means inspecting technical detail, comparing options, reviewing evidence or starting a conversation.

    Create a small messaging record that lists the approved category, primary audience, problem, outcome, mechanism and evidence. Add preferred names for products and services. Use that record when editing webpages, writing press materials, creating partner profiles or implementing schema.

    Use structured data to confirm facts, not manufacture positioning

    JSON-LD can help label an Organization, Product or Service and connect related facts. It cannot rescue a proposition that remains contradictory in visible copy. The structured version should describe the same entity, offering and relationship that a reader sees on the page.

    Check for mismatches such as these:

    • The homepage calls the company an enterprise platform while pricing and customer examples point primarily to individual operators.
    • A service page promises strategic consulting while structured data describes only a software application.
    • The About page defines the mission around one problem while the main navigation organizes every offering around a different one.
    • Product names, company names or category labels vary enough across profiles that they appear to describe separate entities.

    Resolve the underlying business language first, then update both visible copy and markup. Adding more schema properties to conflicting statements only makes the conflict more elaborate.

    Build content around situations, not isolated funnel stages

    The old assumption that awareness, research and conversion will occur in a tidy sequence is less dependable when streaming, scrolling, searching and shopping blend within a compressed decision process. A person can encounter a problem, request options, compare tradeoffs and decide what to do next inside one interaction.

    Your content plan therefore needs to create, capture and help convert demand at the same time. That does not mean turning every page into a sales pitch. It means giving each page enough context to connect a problem with an informed next step.

    Replace the generic keyword brief with a decision-situation brief containing:

    • Trigger: what caused the person to seek help now?
    • Stakes: what happens if the problem remains unresolved?
    • Constraints: what limits the acceptable options?
    • Alternatives: what other approaches could reasonably solve the problem?
    • Decision criteria: what would make one approach a better fit than another?
    • Evidence: what would a careful buyer need before trusting the answer?
    • Next action: what is the smallest useful step after reading?

    A useful page answers the immediate question near the top, explains the important distinction, identifies fit and non-fit conditions, supports its claims and offers a relevant next action. That structure helps a reader make a decision and gives an AI system explicit passages it can associate with the underlying situation.

    Organize the plan in a working matrix with one row for each decision situation. Track the natural-language question, the best page, the claim being made, the available evidence and the next action. Empty cells reveal what to create. Repeated rows reveal where several pages compete to say the same thing.

    This also prevents volume from becoming the strategy. A large library of loosely related content can expand your topical footprint while weakening the connection between the brand and its best problem. Publish when a page fills a real decision gap, clarifies an important tradeoff or supplies missing evidence.

    Audit brand clarity before scaling AI visibility work

    Abstract digital touchpoints on an inspection table project mostly aligned beams toward one central model as a calibration tool adjusts two outliers.

    A brand-clarity audit is a claim audit, not a design critique. Its purpose is to discover what an outside system could reasonably conclude from the signals you already publish.

    1. Collect the major surfaces. Include the homepage, About page, primary offering pages, high-visibility educational content, public profiles and relevant structured data.
    2. Extract the claims. Copy the exact language each surface uses for the audience, problem, outcome, mechanism, category and evidence.
    3. Group equivalent language. Different wording is acceptable when it preserves the same meaning. Separate genuine synonyms from statements that point to different positions.
    4. Mark contradictions and omissions. Flag surfaces that target a different buyer, imply a different outcome, rename the offering or make claims without visible support.
    5. Repair the central surfaces first. Align the homepage, primary offering pages, About page and structured data before updating peripheral content. Those central definitions should guide the rest.
    6. Test realistic decision prompts. Use prompts that include a customer situation, constraint and desired result. Record whether the resulting description places your brand in the intended category and whether it connects the brand to the intended problem.

    Do not treat one generated answer as a verdict. Outputs can vary by model, prompt and available context. Look for a pattern across relevant prompts: Is the brand described consistently? Does it appear for the right situations? Are the cited pages the ones that contain your clearest explanation and evidence?

    Pair visibility observations with business signals. Relevant discovery should lead the right people toward the right pages and actions. A higher mention count is not automatically useful if the brand appears for a problem it does not solve well.

    Repeat the audit when you introduce a major offering, change the target customer, reposition the company or restructure the site. Those changes can create conflicting definitions even when every individual update appears reasonable.

    Key takeaways

    • AI discovery depends on whether your public signals connect the brand to a specific customer situation, not merely a broad product category.
    • Define one primary audience, trigger, outcome, mechanism and decision criterion before producing more content.
    • Keep visible copy, product naming, public profiles and JSON-LD aligned around the same facts.
    • Plan pages around complete decision situations so they can educate, establish fit and support a sensible next action.
    • Measure whether your brand appears in the right context, not just whether it receives more mentions.

    Before approving the next content brief, write your solution statement and compare it with the homepage, primary offering pages, About page and structured data. If those surfaces tell different stories, pause expansion and repair the central promise. Once the brand is clear at its core, every SEO, AEO and GEO effort has a more coherent signal to amplify.

    References