Tag: Audience Data

  • Ecommerce Advertising Readiness: When and Where to Scale

    Ecommerce Advertising Readiness: When and Where to Scale

    Your campaigns can be approved and spending while your store is still unprepared to scale. The weakness usually appears after demand rises: a feed rejects sale prices, a bestseller runs out, attribution has not caught up, or a promotion turns an apparently healthy return on ad spend into a loss.

    Advertising readiness means knowing what you can profitably sell, trusting the data used to optimize it, and choosing a channel that matches the customer’s current level of intent. Work through those decisions in that order and you can expand without asking automation to repair a broken funnel.

    Key takeaways

    • Do not scale traffic until purchase tracking, product availability, pricing, and contribution margin are reliable.
    • Use Search and Shopping to capture existing demand. Use YouTube to create demand when the lower funnel already converts.
    • Performance Max can distribute ads onto YouTube, but distribution is not a YouTube strategy. You still need deliberate creative, audience logic, measurement, and testing.
    • Segment products by margin, promotion, and stock position so one blended ROAS target does not treat fundamentally different products as equals.
    • Make campaign, feed, approval, and payment changes before a peak period. During the event, monitor exceptions and respect conversion lag instead of repeatedly resetting the system.

    Pass the readiness gate before choosing another channel

    A new channel adds traffic. It does not fix weak economics, inaccurate measurement, or a checkout that already loses qualified shoppers. In fact, sending cold YouTube traffic into a funnel where Search and Shopping traffic does not convert can simply accelerate the existing loss.

    Before increasing spend, give the store a clear pass or fail on four gates:

    1. Lower-funnel performance: Search and Shopping can turn relevant, high-intent visits into completed purchases without unexplained breaks in the journey.
    2. Measurement: transactions, order values, currency, and customer signals reach the advertising platforms accurately enough to guide bidding.
    3. Economics: you know the contribution available after discounts and variable order costs, not just revenue and platform-reported ROAS.
    4. Operations: the feed, stock data, payment methods, landing pages, creative approvals, and alerting process can withstand a sudden increase in demand.

    A failure on any gate determines your next investment. A tracking failure calls for measurement work. A stock or price failure calls for feed operations. A negative contribution margin calls for a commercial decision. None of those problems should be handed to a bidding algorithm as if they were targeting problems.

    Verify the data that bidding will learn from

    Run a test order from the storefront through the complete measurement path. Confirm that the purchase appears once, carries the correct value and currency, and can be reconciled with the order record. Then inspect the supporting stack: server-side measurement where appropriate, Consent Mode, Enhanced Conversions, and offline conversion measurement if meaningful outcomes happen after the online event. These are among the data checks that should be completed before a high-demand period, not during it.

    First-party audiences also need structure. An undifferentiated customer upload tells the platform that every buyer has equal value. Segment usable lists by factors such as average order value and customer lifetime value, then keep acquisition and retention decisions distinct. Apply the same discipline to the audience data used across Google Ads and Meta.

    Finally, document conversion lag. If purchases commonly arrive several days after an ad interaction, the newest dates will always look artificially weak. A reporting delay is not a campaign collapse, and reacting to it every morning can turn normal lag into genuine instability.

    Set a profit boundary before approving a discount

    Revenue-based ROAS can hide whether an order creates value. Start with a product or product-group calculation:

    Net selling price – product cost – variable fulfillment, payment, and expected return costs = contribution before advertising.

    That contribution is the amount available to pay for acquisition and leave profit behind. If you lower the selling price, recalculate it before setting the promotion live. A 15% discount removes part of the margin at the same time acquisition costs may rise. Matching a competitor’s discount without doing this calculation can produce more orders and less profit.

    To judge the promotion, divide the baseline contribution you want to preserve by the new contribution per order. The result is the number of discounted orders required before advertising costs are considered. Then add the expected acquisition cost. If the required volume is implausible, change the offer, limit it to suitable products, or accept that the promotion has a strategic cost rather than pretending it is profitable.

    Give each channel one clear job

    Channel choice becomes easier when you start with the customer’s state. Search and Shopping are pull channels: the shopper expresses intent and the advertiser competes to answer it. YouTube is a push channel: the advertiser interrupts someone who was doing something else and must create enough interest to earn a later action. Those conditions require different creative, timelines, skills, and measurement.

    Channel or campaign typeCustomer statePrimary jobWhat you must control
    Search and ShoppingAlready looking for a product, category, or solutionCapture existing demandQuery or product relevance, offer quality, feed accuracy, bids, margin, and landing-page conversion
    YouTubeNot actively shopping at that momentCreate interest, demonstrate a product, and generate future demandHook, argument, demonstration, proof, audience, creative refresh, and a longer evaluation window
    Performance MaxVaries because inventory spans multiple Google surfacesAllocate spend across eligible inventory toward the configured conversion goalFeed quality, conversion inputs, asset quality, product segmentation, budget, targets, and interpretation of blended reporting

    This distinction matters because Performance Max may already be buying YouTube impressions for your store. It can reuse uploaded assets or, when no video is supplied, assemble video from product images, transitions, and text. That gives the campaign something to serve, but it does not supply positioning, persuasion, creative sequencing, or a channel-specific learning plan.

    Treat Performance Max as a distribution system, not proof that you have a YouTube strategy. A blended conversion total cannot tell you whether upper-funnel impressions created new demand, harvested demand that already existed, or received credit for a purchase that would have happened anyway. Do not accept that number uncritically, but do not make the opposite mistake of testing YouTube once, grading it like Search, and declaring the channel ineffective.

    Use a simple channel decision sequence

    1. If relevant Search and Shopping traffic does not convert, repair the offer, product pages, checkout, feed, or measurement before adding cold reach.
    2. If profitable search demand is still available, capture it before paying to manufacture more awareness.
    3. If existing demand is constrained, or the product is new and lacks search volume, assess whether YouTube can create demand.
    4. If the goal is product discovery, brand awareness that can drive later searches, a time-limited seasonal promotion, or a new-product launch, give YouTube a defined budget and its own measurement plan.
    5. If you cannot produce and refresh persuasive video, postpone the channel rather than allowing generic automated assets to stand in for strategy.

    Build YouTube creative as a persuasion sequence

    A YouTube viewer did not ask to see your product. The creative therefore has to do more than show it. Build each concept around a complete sequence:

    1. Hook: earn attention in the first five seconds.
    2. Problem: make the relevant frustration, desire, or missed opportunity recognizable.
    3. Mechanism: explain how the product addresses that problem.
    4. Demonstration: show the product doing the work instead of relying on a claim alone.
    5. Proof: give the viewer a reason to believe the result.
    6. Call to action: make the next step explicit and consistent with the landing page.

    Creative is the operating cost of this channel. Fatigue arrives faster than it does in intent-led campaigns, so two or three occasional videos are not a substantial testing program. For a serious effort, plan the people, production process, and approval capacity needed to test 20 or 30 videos per month. If that volume is beyond reach, narrow the test deliberately rather than spreading a small set of assets across too many audiences and offers.

    Define success before launch. Direct sales still matter, but the feedback loop is longer and attribution is less clean than it is for Search. Separate YouTube’s budget and evaluation from the assumptions used for demand capture, account for the store’s observed conversion lag, and watch whether the channel is creating the future demand it was assigned to create. Changing the success definition after seeing the result makes the test impossible to interpret.

    Make feed and margin structure govern spend
    An overhead arrangement of unbranded products, packaging, coins, a calculator, and a tablet with abstract product tiles.

    For an ecommerce advertiser, Google Merchant Center is not an administrative afterthought. Its product feed is a core input to Shopping and Performance Max. When availability, price, or identifiers are wrong, automation makes decisions from a distorted catalog.

    Configure the feed around the decisions your team will need to make under pressure:

    • Automate promotional prices. Populate sale_price and sale_price_effective_date with exact start and end timestamps. This allows scheduled price changes and reduces the risk of a mismatch between the website and feed when a sale begins.
    • Protect price-annotation eligibility. If strikethrough pricing is part of the plan, the base price must have been active for at least 30 days within the previous 200 nonconsecutive days.
    • Increase freshness during peak windows. Raise feed synchronization to three or four times per day when prices and inventory are changing quickly.
    • Stop advertising unavailable inventory. Use automated rules or feed scripts to flag and pause out-of-stock SKUs instead of buying visits to products that cannot be ordered.
    • Add commercial labels. Use Custom Label 0 through Custom Label 4 to represent attributes such as actual margin, promotional status, and stock position.

    Do not wait for the promotion to discover whether the feed and checkout disagree. Schedule a sale-price test, verify the timestamps, inspect the landing page and cart, and confirm that a product returns to its normal price after the test window. A valid feed submission is useful, but the shopper experiences the complete path.

    Translate labels into campaign decisions

    Labels become valuable when they change how you allocate spend. A high-margin, well-stocked bestseller can support a different target and budget from a low-margin item with limited inventory. Blending the two under one target ROAS encourages the platform to optimize revenue while concealing the difference in profit.

    • High margin and strong stock: make these products eligible for more assertive acquisition, subject to the contribution boundary.
    • Low margin: use a more defensive target or restrict promotion unless the product has a deliberate strategic role.
    • Promotional: isolate the discounted economics so ordinary-price performance does not subsidize an unprofitable event in the reporting.
    • Low stock: reduce exposure before availability becomes a customer and feed problem.
    • Out of stock: pause promptly and restore eligibility only after the feed and storefront agree.

    Keep a working record for each important SKU or product group: normal price, promotional price, product cost, variable order cost, contribution before advertising, stock position, and active promotion. That record gives the media team a commercial map. Without it, campaign structure is merely technical organization.

    Prepare the peak-period operation before demand arrives
    Workers pack unbranded orders at organized stations in a well-stocked ecommerce fulfillment area.

    Peak-period readiness is mostly timing. A change that is sensible in an ordinary month can be reckless immediately before Black Friday if it triggers a learning period, waits for approval, or alters the data used by bidding. Depending on account size and market, Q4 preparation may need to begin in August or September.

    Sequence the work around risk

    1. Months before demand peaks: validate measurement, segment first-party audiences, repair the lower funnel, calculate promotion economics, and begin warming audiences where demand creation is part of the plan.
    2. Well before the event: launch new campaign structures and bidding strategies early enough to move beyond their initial learning behavior. Upload creative with time for review instead of risking a pending approval on the day before the sale.
    3. Before prices change: test sale attributes and effective dates, confirm stock rules, set feed schedules, fund the advertising account, and add a backup payment method.
    4. During Cyber Week: inspect Merchant Center Diagnostics early each morning, prioritize disapproved bestsellers, and maintain the higher feed-sync frequency.
    5. After each major sales window: wait for the known conversion lag before treating recent ROAS as complete, then compare product-level contribution with the target established before launch.

    Decide in advance how much control you want over rising CPCs and CPMs, including whether a portfolio bid cap belongs in the plan or whether the bidding system will operate without one. The important point is to make that choice from economics and risk tolerance before the auction becomes unusually competitive.

    Monitor exceptions instead of micromanaging campaigns

    Create alerts for payment failures, material CPC changes, rapid budget consumption, feed disapprovals, and inventory problems. Then write the response beside each alert. An alert without a response rule merely creates anxiety; an alert tied to a check and an owner shortens the time to a useful decision.

    • If a bestseller is disapproved, inspect price, availability, and landing-page consistency before changing a bid.
    • If a campaign consumes its daily budget unusually early, check traffic quality, CPC movement, and the promotion schedule before reallocating money.
    • If reported ROAS falls on the newest dates, compare that window with the account’s normal conversion lag before changing targets.
    • If stock becomes scarce, use the stock label or automated rule to reduce exposure rather than continuing to sell demand you cannot fulfill.
    • If a payment method fails, switch to the verified backup before delivery stops during the most valuable traffic window.

    Frequent intervention can be as damaging as neglect. When conversion lag is several days, daily changes based on incomplete purchases make each decision depend on a partial result. Reserve emergency changes for genuine operational failures or clearly breached financial boundaries. Let ordinary performance accumulate enough evidence to judge.

    Your next move is not automatically another campaign. Choose one upcoming promotion or product launch and score it against the four readiness gates. Fix the first failed gate. When all four pass, assign Search, Shopping, Performance Max, or YouTube a precise job, budget, success measure, and stopping condition. That is the point at which scaling becomes a controlled decision rather than a bet.

    References


  • How to Build Connected Customer Profiles From Marketing Data

    How to Build Connected Customer Profiles From Marketing Data

    Your analytics platform records a purchase. Your ad platform records a conversion. Your loyalty system recognizes a member. Your point-of-sale system knows what was sold. Yet when you try to decide whether that person is a new prospect, a regular buyer or someone drifting away, the systems give you different answers.

    You don’t solve that problem by collecting more events. You solve it by giving each event a clear meaning, connecting it to the right identity, carrying consent through the connection and turning the resulting history into signals that can change a marketing decision.

    Key takeaways

    • Event capture and profile connection are separate quality layers. A perfectly recorded purchase can still land on the wrong profile.
    • Measure identity coverage as the share of relevant transactions attached to a known customer, not the number of people enrolled in a loyalty program.
    • Start with a marketing decision, then specify the event, identity, profile attribute, freshness and consent required to make it.
    • No-code tagging can simplify deployment, but it doesn’t define what an event means or prove that the event is accurate.
    • Different customer attributes need different refresh schedules. A missed purchase may matter immediately, while category affinity normally changes across repeated purchases.
    • Keep unknown customers separate from confirmed first-time customers. Treating unresolved identity as proof of newness corrupts acquisition decisions.

    Design the marketing decision before you design the data capture

    A conversion feed can contain product choices, basket value, discounts, channel, location and other transaction details. That still doesn’t reveal the customer’s relationship with the business. A $100 order from a first-time buyer and a $100 order from a frequent buyer look the same when history is missing, even though you should not necessarily advertise to those people in the same way.

    This is why a connected customer profile should begin with a decision contract, not a request to collect everything. The contract states what marketing is trying to change and the minimum data needed to make that change responsibly.

    1. Name the action. Be precise: suppress an existing customer from acquisition, include a lapsed customer in reactivation, select an eligible loyalty offer or adjust conversion-value optimization.
    2. Define the eligible population. State who may enter the decision and who must be excluded because of consent, geography, account state or insufficient identity.
    3. Identify the event that supplies evidence. A confirmed purchase, authenticated session or loyalty identification is evidence. A page view near the checkout is not proof of an order.
    4. Choose the identity requirement. Specify which authenticated account, loyalty or transaction identifier can connect the event to a profile. Also define what happens when that identifier is missing.
    5. Define the profile attribute. Write down how the system distinguishes first-time, repeat, active or lapsed customers and which events are allowed to change that status.
    6. Set the freshness requirement. Ask how old the event or derived attribute can be before the marketing action becomes misleading.
    7. Record the permitted use. State which destinations may receive the event, profile attribute or audience and which consent or governance condition must be satisfied.
    8. Choose the success measure. Evaluate the marketing decision that changes, not merely whether another field was added to a profile.

    For an acquisition-suppression use case, the action might be to exclude established buyers from campaigns intended only for new customers. The required evidence is confirmed purchase history connected to a reliable identity. If the transaction cannot be resolved, the safe data classification is unknown, not first-time. The profile can enter the suppression audience only when the status is current, the audience rule is valid and the intended advertising use is permitted.

    That distinction prevents a common measurement failure. When unknown and new are collapsed into one value, improvements in identity coverage appear to change customer composition even if actual buying behavior has not changed. Give unknown its own state in reports, audiences and quality checks.

    Capture events once, then validate their meaning everywhere

    Give every decision-critical event a contract

    A tag firing is a transport result. It doesn’t prove that the event represents the business outcome you intended. Before anyone configures a visual selector, tag or software development kit, create an event contract containing:

    • A canonical event name with one business meaning across web, app and physical channels.
    • The condition that confirms success. For a purchase, that should reflect a completed transaction rather than an early checkout interaction.
    • The occurrence time and the originating channel or system.
    • The stable event or transaction identifier used to detect repeat delivery.
    • The authenticated, loyalty, customer or anonymous identifiers available at that moment.
    • Only the properties required by an approved use case, such as product, basket, discount or location context.
    • The consent, purpose or permission context that controls collection and downstream activation.
    • The destinations authorized to receive the event.
    • An owner who approves changes to the event’s definition.

    Use the same canonical event when the same business outcome occurs in different interfaces. Channel belongs in a property; it should not force every team to invent a different definition of purchase. If the web team calls an order purchase, the app team calls it checkout_complete and the point-of-sale team calls it sale_closed, identity resolution may work while profile calculations still disagree.

    Also decide how duplicate delivery is handled. Browser retries, destination forwarding and overlapping implementations can produce more than one record for the same outcome. The profile layer needs a stable transaction or event key so a retry doesn’t become another purchase in cadence, value or repeat-buyer calculations.

    Treat no-code tagging as an implementation aid

    Google’s unified tagging direction makes implementation more accessible. Existing Google tags are being upgraded into capable Google Tag Manager containers, bringing interface-driven configuration, debugging and version control into a more unified setup. Google has also introduced visual event creation that lets an operator navigate a site and select elements while the system handles selectors and triggers.

    That can reduce the coding needed to deploy an event. It doesn’t answer whether clicking the selected element proves a conversion, whether the same interaction exists in an app or store, whether the event will fire twice, or whether the attached identifier and consent state are valid. Set the event contract first, then use visual tagging to implement the approved condition.

    The updated setup can also provide a visual map of the Google destinations receiving measurement data. Optimized containers may send data directly to those destinations instead of loading additional gtag.js code, which Google says can reduce measurement latency and potentially improve site performance. Treat the destination map as part of release review: every expected destination should be present, and every unexpected destination should be investigated before publication.

    If you already run a sophisticated Tag Manager container, don’t publish an optimization proposal on the assumption that a simpler configuration is identical. Optimization is optional, and authorized users can preview proposed changes before publishing. Existing event tags are intended to remain unchanged, but initialization and account-linking behavior still deserve review.

    Pay particular attention to deployment code. Google’s announced direction moves new snippets toward a shared format without the gtag config command and recommends the gtm init trigger for initialization behavior. A legacy setup that still depends on the config command can be configured to wait for it. Document that dependency before migration so a cleanup doesn’t silently change consent initialization, configuration order or event availability.

    Before publishing any capture change, run the actual customer path and verify the business result, not just the debug console. Confirm that the event fires once, carries the expected transaction and identity keys, excludes unapproved properties, reaches only approved destinations and remains consistent after navigation or refresh. Save the reviewed container version so the release can be traced and reversed if validation fails.

    Connect interactions to a governed customer identity

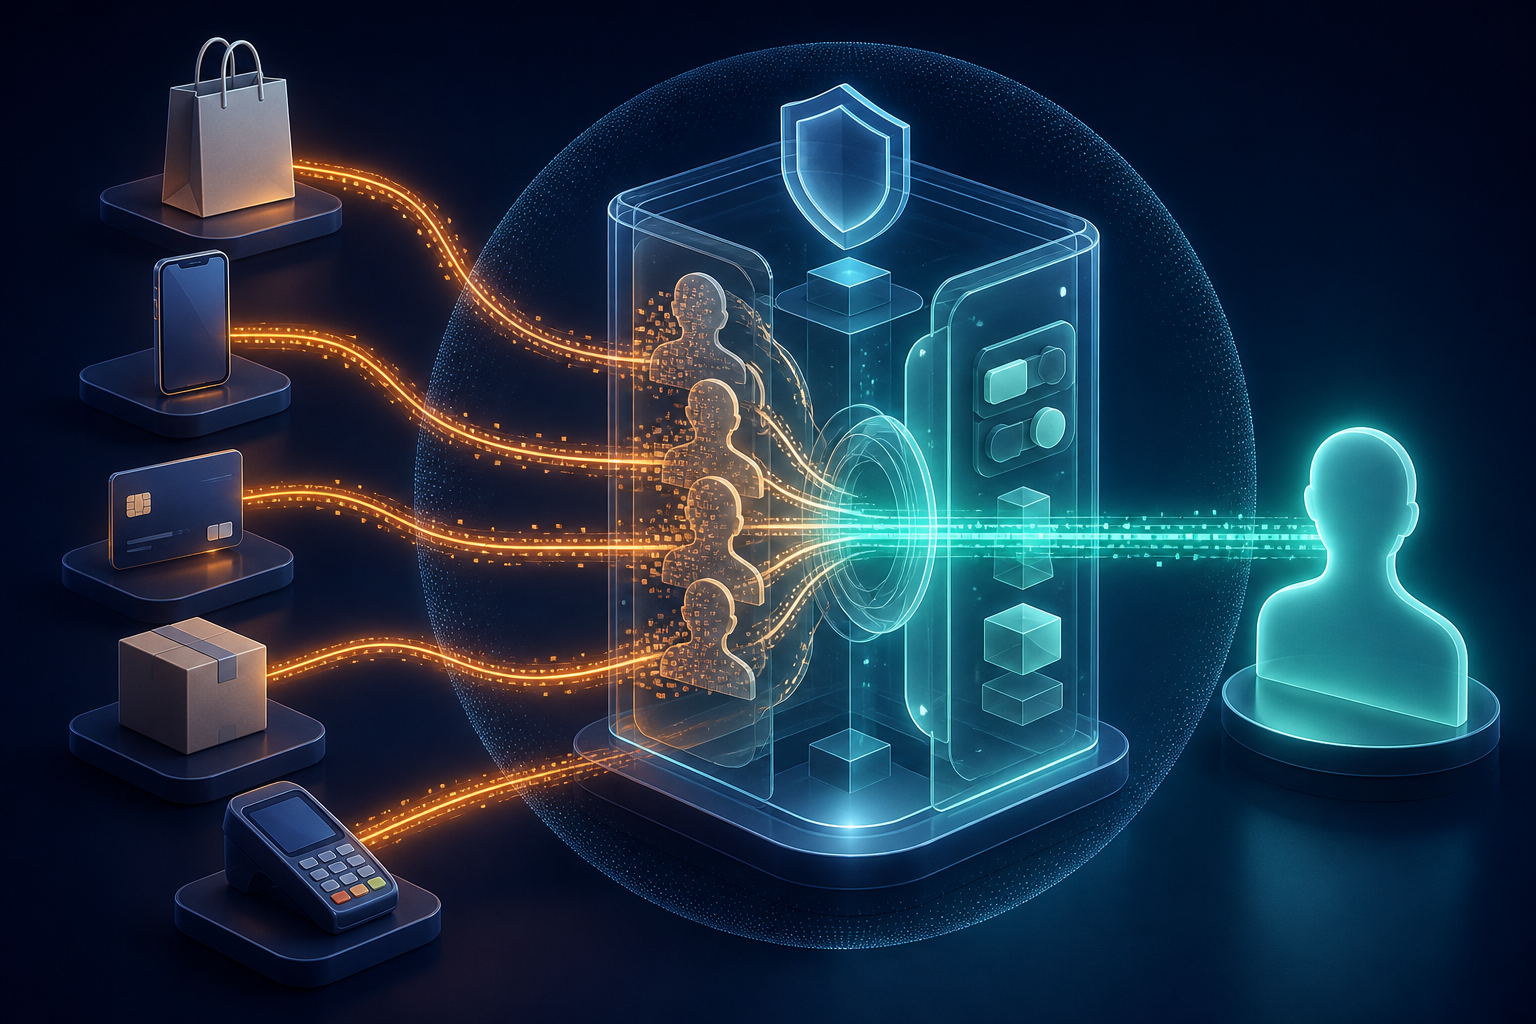
    Retail and digital interaction objects pass through a protected matching hub and connect to one customer silhouette.

    Measure identity coverage, not enrollment

    Ecommerce accounts and subscription relationships often provide authentication by design. Physical retail, grocery and quick-service transactions are harder because a purchase can happen without identification. Loyalty can bridge that gap when a member identifies at the register, in an app or during a drive-through transaction.

    A large loyalty membership total doesn’t show whether purchase history is connected. The operational metric is the share of transactions that arrive with a customer attached.

    Identity coverage = identified eligible transactions divided by all eligible transactions.

    Define eligible for your business before using the ratio. It should represent transactions in which your measurement design provided a legitimate opportunity to identify the customer. Then segment coverage by channel, device, store, checkout path or other operational handoff. The aggregate rate can look stable while one important path fails to collect or transmit an identifier.

    Coverage alone isn’t enough. A transaction can contain an identifier and still connect to the wrong profile. Track at least three separate outcomes: identified and resolved, identified but unresolved, and anonymous. That separation tells you whether the problem sits in collection, transport or identity matching.

    Make identity joins explainable and correctable

    Keep raw identifiers and the connected profile identifier as separate fields. The raw values show what each system observed; the profile identifier shows the result of resolution. If you overwrite the former with the latter, it becomes difficult to explain a bad merge or repair customer history later.

    • Prefer authenticated or directly captured relationships when linking activity to a known profile.
    • Record which identifier and originating system caused each link.
    • Define what evidence permits two records to merge and what evidence requires them to split.
    • Preserve the time of the link so historical calculations can be reproduced.
    • Do not label an unresolved identifier as a new customer merely because no history was returned.
    • Provide a correction path for shared accounts, recycled identifiers, entry errors and other bad joins.

    Consent must travel with this process. A profile join can turn previously disconnected activity into a more revealing customer history, so it can expand the consequences of a permission error. Store the relevant permission and permitted-use context with identifiers and events, enforce it before audience activation and have the appropriate privacy or legal owner validate retention and use rules for your business. A separate consent database that isn’t consulted during the join or audience sync does not protect the downstream decision.

    The final test is continuity. A register transaction, app session and loyalty account create connected history only if they resolve to the intended profile, appear soon enough for the marketing decision and retain the same governance rules wherever they are used.

    Turn connected history into fresh, usable marketing signals

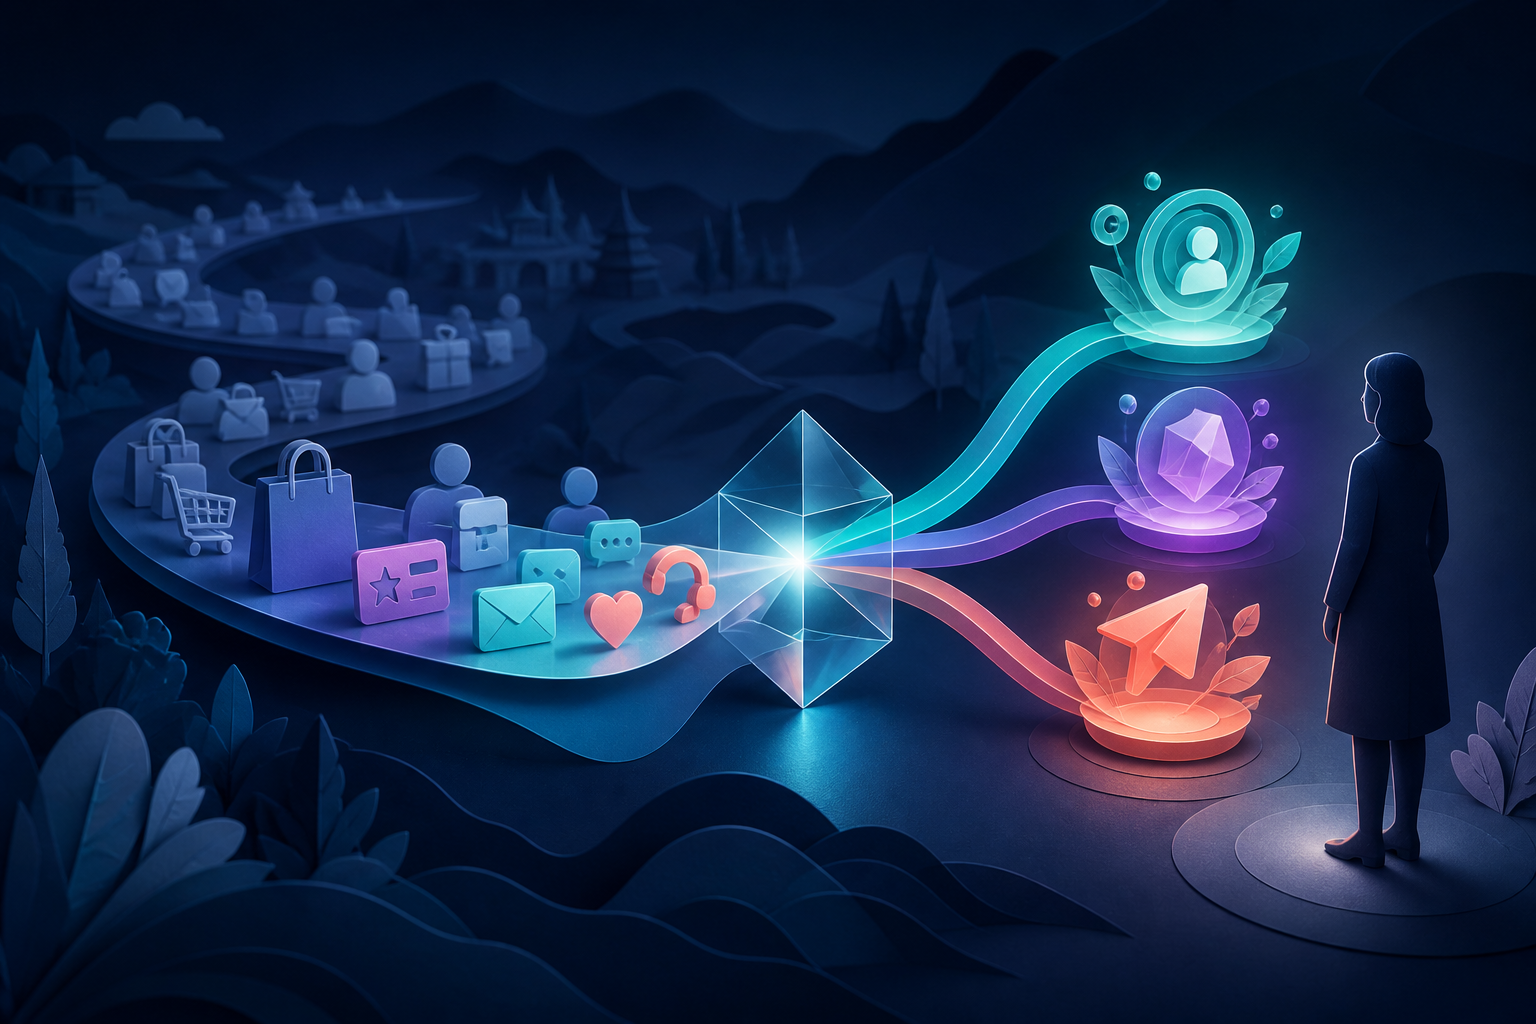
    A sequence of customer interactions passes through a glowing prism and emerges as three illuminated marketing signals beside a customer silhouette.

    Once events are connected, keep three data layers distinct. They have different owners, update patterns and failure modes.

    Data layerWhat belongs in itQuestion it must answer
    Identity and governanceIdentifiers, consent, permitted uses and relationships among profilesMay this activity be joined and used for this purpose?
    Loyalty program stateTier, points balance, reward eligibility, redemption history and tenureWhat program status or benefit currently applies?
    Derived attributesPurchase cadence, time between orders, category affinity, time and location patterns, channel mix and offer responseWhat does connected behavior imply for the next marketing decision?

    The third layer makes history actionable, but only when freshness matches the behavior. Purchase cadence can produce a signal when nothing happens. If a customer usually buys on a recurring pattern and then misses expected purchases, no new transaction arrives to trigger an update. A scheduled calculation must detect the absence. Category affinity changes differently: repeated purchases can establish or shift a preference, while an isolated purchase should not automatically redefine the profile.

    Don’t assign one universal refresh schedule to every attribute. Work backward from the decision. An exclusion used by an active acquisition campaign may need recent purchase status. A category preference built across a longer history can change more gradually. The right interval depends on your observed buying cycle and how quickly a stale value can cause the wrong action.

    Give every derived attribute its own contract:

    • A plain-language definition that marketing, analytics and engineering interpret the same way.
    • The qualifying events and event properties used in the calculation.
    • The identity coverage required before the result is considered usable.
    • The update mode: event-driven, scheduled or both.
    • The condition that makes the value stale or unknown.
    • The allowed marketing destinations and permitted purposes.
    • The fallback when history is incomplete, delayed or contradictory.
    • The owner responsible for validating changes to the logic.

    Activation should preserve those definitions. If repeat-buyer status means one thing in analytics and another in the ad audience, the profile is not truly connected at the decision layer. Use a shared, versioned rule or prove that each destination implements an equivalent rule.

    • Acquisition suppression: use confirmed, sufficiently current customer history; never assume unresolved means new.
    • Reactivation: use a cadence or inactivity signal that is recalculated even when no new event arrives.
    • Category messaging: require enough connected history to distinguish a repeated preference from an isolated purchase.
    • Loyalty treatment: use current program state rather than recreating tier or reward rules inside each advertising destination.
    • Conversion-value optimization: document which profile signal changes the value and how stale, missing or disallowed data is handled.

    Audit one customer journey from capture to activation

    A dashboard can show healthy event volumes while a profile, audience or consent handoff is broken. Use a governed test profile and trace one complete journey through the system:

    1. Complete the intended interaction through the real web, app, loyalty or point-of-sale path.
    2. Confirm that the canonical event appears once with the expected occurrence time, transaction key, properties and consent context.
    3. Verify that the captured identifier resolves to the intended profile and that the resolution method is recorded.
    4. Inspect the connected history to make sure the event appears once and in the correct order.
    5. Run or wait for the relevant derived calculation, including any scheduled logic required to detect inactivity.
    6. Evaluate the audience or decision rule and confirm that unknown, stale and disallowed states follow their documented fallback.
    7. Verify that only approved destinations receive the event, attribute or audience membership.
    8. Change or withdraw the test permission where your system supports it, then confirm that downstream activation respects the new state.

    Run that trace after changes to tags, identity rules, profile calculations, consent handling or audience logic. Volume monitoring should remain in place, but an end-to-end trace reveals whether all the individually healthy components still produce the intended customer decision.

    Your next move is deliberately narrow. Choose one campaign in which a first-time customer and an established customer should be treated differently. Write the decision contract, instrument the minimum required event and trace one test profile from capture to destination. Expand to another signal only after you can explain every identity join, freshness rule, permission check and fallback on that path.

    References


  • Google Ads Audience Targeting for Higher-Quality B2B Leads

    Google Ads Audience Targeting for Higher-Quality B2B Leads

    Your Google Ads dashboard can say a B2B campaign is working while your CRM says otherwise. If bidding rewards every form submission equally, Google learns to find people who complete forms – not companies that qualify, reach an opportunity stage, or buy.

    The fix is not simply tighter audience targeting. You need a chain of signals that connects consented first-party data, meaningful funnel events, realistic bidding targets, and controlled audience expansion. Build that chain before asking Google Ads to find more people.

    Key takeaways

    • Make qualified leads, opportunities, and sales visible to Google Ads before expanding your audience. A form fill alone teaches the system to maximize form fills.
    • Give each first-party audience one job: exclusion, reacquisition, re-engagement, retention, or a high-quality signal. Do not merge customers, qualified prospects, and raw leads into one list.
    • Audit campaigns that use tCPA or tROAS and carry a Limited by budget status. An old target can direct new spend toward traffic that satisfies the platform target without improving pipeline economics.
    • Treat Enhanced matching for Customer Match as an opt-in experiment if it appears in your account. Its incremental reach, participating publishers, and precise matching behavior have not been publicly detailed.
    • Judge AI-driven expansion by qualified pipeline and revenue signals. Lower CPC, more clicks, and more form submissions can coexist with a worse cost per lead or weaker sales outcomes.

    Start with the conversion Google Ads is actually learning from

    A circular optimization loop connects a visitor, form submission, reviewed contact, business opportunity, and completed agreement, with signals flowing back toward a central targeting engine.

    Audience strategy cannot repair a weak conversion signal. If your primary conversion is Lead form submitted, every audience feature and bidding system starts with the same incomplete definition of success.

    That is particularly damaging in B2B. A form may come from a strong account, a student, an existing customer, a job seeker, a vendor, a competitor, or someone outside your service area. Google Ads cannot infer which one matters if you send all of them back under the same label and value.

    Map the funnel as separate conversion events

    Start with the stages your sales team already uses. The names will differ by business, but the distinctions should remain explicit:

    1. Lead created: the person completed the initial conversion action.
    2. Qualified lead: the record passed your documented fit and intent criteria.
    3. Opportunity created: sales accepted the record into an active buying process.
    4. Closed outcome: the opportunity became revenue or reached another definitive result.

    Keep the initial lead event for measurement, but do not automatically make it the event that controls every campaign. Import later-stage events and values so bidding can distinguish an inexpensive form from a commercially useful lead.

    Offline conversion imports are the foundation for journey-aware bidding, value-based bidding, and expansion-heavy campaign types such as Performance Max, Demand Gen, and AI Max to optimize beyond cheap volume. Google has added direct Data Manager integrations for Mailchimp, ActiveCampaign, Klaviyo, and Google Drive, plus partner API connections including Zapier, Stape, Adswerve, Bloomtech, and Treasure Data. If an engineering backlog has delayed CRM feedback, check whether one of those paths removes the dependency.

    Verify the meaning of the data, not just the connection

    A successful connector does not guarantee a useful bidding signal. Before changing campaign optimization, verify four things:

    • The CRM and Google Ads use the same definition for each lifecycle stage.
    • Rejected, duplicate, spam, test, and otherwise invalid records cannot be imported as qualified outcomes.
    • Conversion values preserve the difference between stages or business outcomes instead of assigning every event an arbitrary equal value.
    • The import runs consistently enough that missing batches do not make campaign performance appear better or worse than it is.

    Use Data Manager’s map view to audit where account data is deployed. Then reconcile imported records against the CRM. You are checking whether the advertising platform received the right event for the right record, not merely whether a green status indicator appeared.

    Journey-aware bidding is intended to let a tCPA Search campaign learn from multiple stages between lead and sale instead of relying only on the first form or a sparse final-sale event. It remains a developing capability, so availability and maturity may vary. If it appears in your account, clean lifecycle data is still the prerequisite; the feature cannot repair inconsistent qualification rules.

    Give every audience a specific job in the funnel

    A B2B audience is useful only when you know what the campaign should do differently because a person belongs to it. Build lists around actions, not around the vague idea that more first-party data must be better.

    Separate exclusion, signaling, and re-engagement

    • Existing customers: exclude them from net-new acquisition where appropriate, or move them into a separate retention, renewal, or expansion campaign.
    • Qualified leads and closed-won contacts: use these consented records as a quality signal. Keep them separate from unqualified form submissions so the signal retains its meaning.
    • Open opportunities: avoid paying to reacquire them through a generic prospecting experience when sales is already managing the conversation. If advertising still has a role, use messaging that reflects the active evaluation stage.
    • Stalled or closed-lost opportunities: re-engage them only when your offer, timing, or message addresses why the earlier process stopped.
    • Raw leads: retain them for analysis and carefully scoped remarketing, but do not present them to the bidding system as evidence of customer quality.

    This structure also makes performance easier to diagnose. If a campaign grows by reaching more known customers rather than new qualified accounts, a blended conversion total can hide the problem. Separate audiences let you see which business job produced the apparent growth.

    Choose observation or restriction deliberately

    In Search campaigns, adding an audience does not always need to narrow eligibility. Observation lets you examine how a segment behaves while preserving the campaign’s broader reach. Targeting restricts delivery to the selected audience or audience criteria.

    Use observation when you are still learning whether an audience predicts quality. Use targeting when the campaign is explicitly designed for that known group, such as re-engaging consented contacts with stage-specific messaging. This distinction prevents a common error: restricting a high-intent keyword campaign to a list that is too small, stale, or incomplete before you know whether membership improves downstream results.

    Customer Match remains the central tool for reconnecting with known, consented first-party audiences across Google properties. Upload only records your organization is permitted to use, keep list purposes explicit, and avoid treating a matched identity as proof of a person’s current role, authority, or purchase intent.

    Test Enhanced matching without assuming what it can do

    An Enhanced matching option for Customer Match is appearing in some Google Ads accounts. When enabled, Google says it can use connected customer lists to extend reach by matching consented advertiser users with consented users from participating publishers, where available.

    The control has appeared unchecked, which makes it an opt-in decision rather than something you should assume is already active. Availability also appears limited. Google has not publicly specified the incremental reach, named participating publishers, or explained exactly how the process differs from existing Customer Match matching.

    If the setting appears in your account, we would test it as a new source of reach, not relabel it as proven precision. Record the activation date, isolate the campaigns affected where practical, and compare qualified-lead, opportunity, and revenue outcomes with the prior baseline. If you cannot separate its impact from other targeting and bidding changes, you will not know whether the extra reach helped.

    Align bidding targets with B2B economics before adding reach

    A stale bidding target is easy to miss because it can appear conservative. In a limited-budget campaign, however, that target influences which additional traffic Google can buy as it tries to spend consistently.

    Following Google’s Aug. 17 change, campaigns marked Limited by budget and using tCPA or tROAS are designed to deliver more consistently to the stated target instead of quietly outperforming it. This deserves immediate attention in B2B accounts, where campaigns often remain budget-limited and launch-era targets may survive long after lead quality or sales economics have changed.

    Audit those campaigns in this order:

    1. Filter for campaigns with a Limited by budget status and a target-based bid strategy.
    2. Identify which conversion actions and values the strategy is using. Do not assume account reporting columns match the campaign’s actual optimization goal.
    3. Compare the target with current qualified-lead, opportunity, and revenue economics rather than the original form-fill CPA.
    4. Inspect where incremental spend is going, including available query, network, audience, and landing-page information.
    5. Change one major control at a time where practical. A simultaneous budget increase, target change, audience expansion, and new conversion goal destroys your ability to attribute the outcome.

    A tROAS target only becomes meaningful for lead generation when imported values reflect genuine differences in business value. If every lead is assigned the same placeholder value, tROAS is effectively optimizing lead count through a value-shaped interface.

    Do not let cheaper traffic settle the argument. In one PPC Live account study, AI Max reduced average CPC by 59% and nearly tripled click volume while cost per lead increased from $493 to $850. One account study is not a universal benchmark, but it demonstrates the failure mode clearly: a favorable auction metric can accompany a worse acquisition result.

    The same caution applies to reported reach gains. Google says Search campaigns using Smart Bidding Exploration see 27% more unique converting users on average. That is a vendor-reported average, not a promise of 27% more qualified B2B buyers. A unique converter is useful only if your conversion definition makes that person commercially relevant.

    Put guardrails around AI-driven audience expansion

    A glowing intelligent network expands toward groups of professional figures while transparent boundaries and control gates restrict which paths can pass through.

    AI Max, Performance Max, optimized targeting, and other expansion mechanisms can find demand outside your manually defined audience. That is useful after Google can distinguish valuable outcomes. Before then, expansion gives the system more ways to pursue the shallow event you supplied.

    Several mechanisms can make the top-line numbers look healthy while weakening B2B performance. Query expansion can add less-specific searches. Landing-page expansion can route people to pages that educate but were not designed to convert. Generated ad copy can remove distinctions that matter to a narrow buyer. None of those outcomes is automatically bad, but each changes more than audience size.

    Use these guardrails before enabling or enlarging AI-driven reach:

    • Set the learning objective first. Confirm that qualified and downstream events are flowing before you expand traffic.
    • Define the business test. Decide whether success means more qualified leads, more opportunities, greater pipeline value, or revenue at an acceptable acquisition cost. Do not substitute CTR or CPC after launch.
    • Preserve a comparison. Avoid rolling audience, creative, landing-page, budget, and bidding changes into one release. You need a usable baseline.
    • Review the destination experience. Check whether eligible pages state the offer, ideal customer, pricing approach, features, security position, and integrations accurately. Expansion cannot compensate for ambiguous product facts.
    • Read CRM cohorts separately. Compare expanded traffic with the campaign’s earlier traffic at the same lifecycle stages. A larger lead cohort is not progress if qualification or opportunity creation deteriorates.
    • Keep exclusions purposeful. Prevent existing customers, active opportunities, internal users, or other irrelevant groups from inflating acquisition results when those exclusions fit your campaign objective and data permissions.

    Opacity matters even more in AI search placements. Ads in AI Mode currently depend on AI Max or Performance Max, while available reporting offers little visibility into what the AI said about the brand, when an ad appeared, or what triggered it. Do not invent certainty the reporting cannot provide. Ring-fence the test, label its timing, and evaluate the CRM outcomes you can observe.

    Business agents for leads are also being tested in selected verticals. The concept places a Gemini chat agent inside a Search ad, grounds its answers in the advertiser’s website, and can present a pre-filled form after the user demonstrates intent. That makes the clarity of your website part of ad readiness: pricing, features, security, and integration pages need explicit, consistent information that both people and language models can interpret. The capability is not broadly available enough to build a lead-generation plan around, but cleaning those pages helps conventional evaluation as well.

    Open one important campaign and trace its full signal path: search or audience, landing page, lead record, qualification, opportunity, and final outcome. If the path stops at the form, do not widen the audience yet. Repair the CRM feedback, separate the audience jobs, and update the bidding target first. Then test the smallest expansion you can evaluate against downstream results.

    References


  • Google Data Manager Audience Updates: A Practical Playbook

    Google Data Manager Audience Updates: A Practical Playbook

    If you own a Customer Match sync, the dangerous outcome is no longer only a failed request. The Data Manager API can now process valid records while warning about invalid optional fields, and one audience operation can clear an entire list. Those capabilities reduce manual cleanup, but they also expose integrations that reduce every run to a simple green or red status.

    For you, this is an operating-model change as much as an API change. Build observability first, put destructive audience actions behind explicit controls, and only then widen the user-provided data you send. That order gives you evidence and a recovery path before the higher-risk capabilities go live.

    Key takeaways

    • Audience refreshes are simpler but more consequential: RemoveAllAudienceMembers can clear a list in one operation or remove members added before a supplied timestamp. Treat full clearing and cutoff-based clearing as separate modes with separate safeguards.
    • A successful request may still contain data-quality problems: invalid optional fields can produce field-level warnings while valid records continue through ingestion. Your monitoring needs a completed-with-warnings state.
    • Address support has widened for Google Analytics destinations: street address, city, and state or province can accompany previously supported information such as name, postal code, and region. This is not a reason to collect or transmit fields without a defined purpose.
    • User-provided data has a conditional identifier role: it can satisfy identifier requirements for certain multi-source events when other identifiers are unavailable. Do not generalize that fallback to every event type.
    • AI-assisted implementation has official scaffolding: Google has added Data Manager API agent skills to its Google Skills GitHub repository, but generated code still needs human review around audience selection, timestamps, privacy, and warning handling.

    Make audience replacement a controlled operation

    A technician monitors two audience-data containers connected by a guarded transfer system with a separate rollback reservoir.

    The RemoveAllAudienceMembers method supports both complete clearing and timestamp-based removal. Do not expose those behaviors through one vaguely named refresh command. Give each mode an explicit name in your own integration so an operator, scheduler, or AI coding agent cannot confuse them.

    Internal operationUse it whenRequired safeguard
    Full clearYou intend to rebuild every current membership from an authoritative dataset.Validate the exact audience target and retain the input, query, or export required to rebuild it.
    Remove before timestampYou intend to retire memberships added before a defined boundary.Record the serialized cutoff and its timezone, then calculate the expected cohort in your own system before making the call.

    A full clear should begin only after the replacement dataset is ready. If extraction fails and returns no rows, an automatic clear-first workflow can turn an upstream outage into an empty audience. Your job must distinguish between a valid business result of no qualifying members and a technical failure that merely produced an empty file.

    1. Build the replacement input first. Finish the source query or export before touching existing membership.
    2. Check whether the result is plausible. Compare its volume and partition coverage with your own recent successful runs. Use a business-specific baseline rather than an arbitrary universal threshold.
    3. Resolve the target from controlled configuration. Record the account, destination, and audience identifier. Avoid accepting an unverified free-text audience name at execution time.
    4. Declare the removal mode. Require either full clear or before timestamp. If a timestamp is supplied, store the exact value used by the request.
    5. Preserve the rebuild path. Retain the source query version, input reference, and run identifier under your normal data-retention controls.
    6. Remove, rebuild, and verify as one runbook. Do not declare the refresh complete merely because the removal call succeeded; the replacement ingestion and its warnings are part of the same operational outcome.

    The cutoff has a narrow meaning: it targets members added before the timestamp. It is not automatically a proxy for last purchase, last site visit, consent expiry, or customer inactivity. If your business rule depends on one of those events, calculate eligibility upstream instead of assuming membership age represents it.

    Boundary behavior deserves a fixture test before production. Place known test members before, at, and after a chosen cutoff, run the operation against a disposable test audience where your environment supports one, and inspect the result. Also verify how your integration treats members that were updated or re-added; do not build a retention policy on an untested timestamp assumption.

    Treat ingestion warnings as a real pipeline outcome

    A validation machine sends most record packets into storage while diverting malformed fragments into an amber inspection channel.

    Field-level warnings change the meaning of success. When an optional field is invalid, the API can continue processing valid records and return details about the field and validation problem. A 2-state dashboard that shows only succeeded or failed will hide exactly the defects this behavior was designed to reveal.

    Represent at least three states in your own monitoring, even if your internal labels differ:

    • Failed: the requested ingestion did not complete successfully.
    • Completed with warnings: processing continued, but one or more fields failed validation.
    • Completed without detected warnings: the run completed and no warning was returned to your handler.

    Persist enough context to diagnose a warning without copying raw customer data into general application logs. A useful warning record contains the internal run identifier, destination, field name, validation reason, occurrence count, deployment version, and first-seen time. If record-level correlation is available in your integration, use a restricted internal reference rather than a name, street address, or complete payload.

    Your alerting should focus on changes in the data contract, not merely the existence of any warning:

    • Escalate a warning reason that appears for the first time after a mapping or formatter release.
    • Investigate a material increase in a known warning relative to that feed’s normal baseline.
    • Route recurring warnings to the team that owns the source field, not only the team that operates the API client.
    • Keep the run visibly degraded until the warning has been classified, even when usable records reached the destination.

    Do not blindly retry the identical batch. An invalid optional value will remain invalid, and valid data may already have been processed. Correct the mapping, normalization, or source value first, then send the corrected data through your normal controlled ingestion path. This makes the next warning result evidence of whether the repair worked.

    Expand address data only where the destination and purpose match

    For Google Analytics destinations, the API now accepts street address, city, and state or province alongside fields such as name, postal code, and region. Keep that destination qualifier in your schema. Support in a Google Analytics path does not establish that every Data Manager destination should receive the same payload.

    • Newly supported for the stated Google Analytics use: street address, city, and state or province.
    • Already supported in the described address data: name, postal code, and region.

    Do not collapse state or province and region into one source column merely because the labels appear related. Define what each field means in your data model, preserve country-specific semantics, and document the transformation applied before transmission. Missing values should remain missing; fabricated placeholders create a payload that may be syntactically complete but semantically false.

    Before adding any address field, require a small data-contract record that answers five questions:

    1. Where did the value come from? Name the source system and field, not just the downstream JSON property.
    2. Which destination may receive it? Use a destination allowlist so the Analytics mapping cannot leak into an unintended advertising or analytics path.
    3. What transformation is applied? Document trimming, formatting, or country mapping in code and tests.
    4. What authorizes its use? Confirm that your collection notice, consent or other applicable control, and internal data policy cover sending the finer-grained address data to the configured destination. If they do not, leave the fields disabled until your privacy or legal owner approves the change.
    5. How will you observe quality without exposing values? Track populated-field counts and validation-warning categories rather than logging raw addresses.

    User-provided data can also satisfy identifier requirements for certain multi-source events when other identifiers are unavailable. The word certain matters. Encode the fallback as an eligibility decision: use the usual identifier path when it is available, use user-provided data only for event and destination combinations that support it, and hold records that satisfy neither condition. Never synthesize an identifier merely to make an event pass validation.

    API acceptance is not a performance guarantee. A field passing validation does not prove that it improved audience size, attribution, or campaign results. Measure those outcomes separately, and keep the expanded payload only when it has a defined operational purpose and remains within your data-governance rules.

    Roll out the changes in a sequence you can reverse

    Do not combine destructive audience controls, new warning behavior, and additional user-provided address fields in one production release. Separate deployments make it possible to identify which change caused a data-quality or audience-maintenance problem.

    1. Inventory each integration path. Mark whether it maintains a Customer Match list, sends data to Google Analytics, or performs both jobs. Record the actual Google Ads, Display & Video 360, or Google Analytics destination rather than assuming all Data Manager paths have identical needs.
    2. Capture warnings on the existing payload. Deploy warning persistence and the completed-with-warnings status before altering deletion or field mappings. This gives you a baseline for current data defects.
    3. Add a guarded removal wrapper. Expose full clear and before timestamp as distinct internal operations. Require a target, mode, recovery input, and explicit cutoff where applicable.
    4. Exercise a fixed test matrix. Test a full clear followed by rebuilding, members before and around a cutoff boundary, a mixed payload containing an invalid optional field, and a warning response that must reach monitoring.
    5. Add address fields by destination. Enable only approved Google Analytics mappings, preferably one mapped field at a time, so warnings can be traced to a specific change.
    6. Test identifier fallback separately. Cover an eligible multi-source event with another identifier, an eligible event without one, and a configuration that is not eligible for the user-provided-data fallback.

    Use Google’s agent skills as scaffolding, not authority

    Google has also released Data Manager API skills in the Google Skills GitHub repository for AI-assisted coding environments. They can help an agent start an integration, but the agent should not decide which audience to clear, choose a business cutoff, approve new address use, or determine whether warnings are acceptable.

    Give the coding agent a narrow implementation brief. For example: create an internal wrapper around RemoveAllAudienceMembers; require an explicit audience identifier and either a full-clear or before-timestamp mode; reject a missing cutoff in the second mode; emit structured warning data without raw user-provided fields; and add fixture tests for clearing, rebuilding, cutoff boundaries, and partial-warning ingestion. Then review the generated client types, request construction, authentication handling, and tests against the API materials and dependency versions actually installed in your environment.

    Set production acceptance criteria

    • A scheduled full clear cannot run unless its replacement dataset and rebuild job are ready.
    • Every cutoff-based operation records the exact timestamp and timezone used by your integration.
    • Completed-with-warnings runs are visible in dashboards and alert routing.
    • Ordinary logs exclude raw names, addresses, and complete user-provided-data payloads.
    • Destination controls prevent expanded address fields from entering an unapproved path.
    • The recovery runbook has been exercised against a controlled audience fixture, not merely written down.

    Start by capturing warnings from the payload you already send. Once that signal is reliable, introduce timestamp-based cleanup behind an explicit approval path, then prove the full-clear rebuild process with controlled data. Expand Analytics address mappings last. You will gain the automation benefits without making a destructive audience action or a sensitive-data change your first live test.

    References


  • Audience Identity Match Rates: Find the Reach You Are Losing

    Audience Identity Match Rates: Find the Reach You Are Losing

    Your customer-list campaign can show a healthy click-through rate, conversion rate, and return on ad spend while missing a large share of the people you intended to reach. The reporting is not necessarily wrong. It is reporting on the customers the platform recognized, not everyone in the file you uploaded.

    Before you change bids, audiences, or creative again, measure that recognition gap. Audience identity match rate tells you whether the platform can use the audience you already paid to acquire.

    What audience identity match rate actually measures

    When you upload a first-party audience to Google Ads, Meta, or another paid platform, the destination attempts to connect identifiers such as hashed email addresses and phone numbers with its logged-in accounts. Records it cannot resolve fall out of the targetable audience.

    For an internal audit, use this operational formula:

    Audience identity match rate = matched audience / eligible records submitted x 100

    Keep the denominator consistent. Record the original export count, the number of eligible records you submitted, and any accepted-record count the platform provides. If one team calculates against raw CRM rows while another uses a cleaned and deduplicated upload, their percentages will not be comparable.

    Suppose you submit 100,000 eligible customers and the destination matches 55%. The platform recognizes 55,000 of them. The remaining 45,000 are not targetable through that uploaded list, regardless of your bid or creative quality. That does not mean all 55,000 matched customers will receive an impression; it means they have crossed the identity-resolution step and can become eligible for delivery.

    This distinction gives you three separate quantities:

    • Built audience: the customers who meet your CRM or customer-data-platform rules.
    • Matched audience: the portion the advertising destination can recognize.
    • Delivered reach: the matched people who actually receive an impression.

    Do not use reach or impressions as the numerator in your match-rate calculation. Those are delivery outcomes downstream of identity matching.

    Key takeaways

    • Match rate measures identity coverage, not campaign performance.
    • Calculate it separately for every destination, audience, and use case.
    • Inspect suppression lists as carefully as retargeting lists because an unmatched customer cannot be excluded.
    • Treat 70% as a useful triage heuristic, not a universal standard; identifier mix and platform behavior affect the result.

    Where a weak match rate quietly spends your budget

    Low match rates are often treated as a retargeting limitation. In practice, the same identity gap affects four different paid-media jobs:

    • Acquisition: Partially matched seed and exclusion lists give the platform less of the first-party signal you intended to provide. Rising customer acquisition cost can have many causes, but identity coverage belongs on the diagnostic list before you assume the bid strategy or creative is at fault.
    • Retargeting: At a 45% match rate, more than half of the intended list cannot enter that list-based retargeting audience. Campaign reporting can still look efficient because it describes the matched 45%, not the full customer group you selected.
    • Suppression: An exclusion only works for customers the platform recognizes. Unmatched existing customers can remain eligible for acquisition advertising, causing you to pay to reacquire people you already have. They may also see a new-customer offer that erodes margin or creates an avoidable customer-service problem.
    • Lookalike modeling: The platform expands from the matched part of your seed, not the complete file. If matched and unmatched customers differ systematically, the model learns from a narrower or skewed sample of the customers you considered valuable.

    Suppression and lookalike seeds inherit the same recognition problem as retargeting. That is why one account-wide match-rate average is not enough. A 70% retargeting rate does not compensate for a 42% suppression rate on a much larger customer list.

    Match rate also changes how you should read downstream metrics. A strong return on ad spend tells you the matched audience performed well. It does not tell you whether the destination recognized a representative share of the audience, whether exclusions worked, or whether your seed supplied the model with the customers you meant to supply.

    Run a 30-minute match-rate audit

    An analyst sorts anonymous audience records into matched and unresolved groups beside a laptop and timer.

    You do not need a new attribution model to establish a baseline. Start with the destinations already receiving the most money and make the calculation visible alongside the performance metrics your team reviews.

    1. Select your top three paid destinations by spend. Do not begin with every channel. The purpose of the first pass is to find whether the gap is material where it can cost the most.
    2. Choose two audiences per destination. Use one large targeting or retargeting audience and the largest suppression list. The suppression result often exposes waste that campaign-level efficiency reports cannot show.
    3. Capture the submitted count. Save the audience definition, extraction date, eligible row count, identifier fields included, and accepted-record count if the destination supplies one.
    4. Capture the recognized count. Google Ads provides a bucketed match-rate indication for Customer Match uploads. For Meta, compare the resulting audience size with the list sent. The two reporting methods are not equally precise, so label estimates and ranges rather than presenting them as exact counts.
    5. Calculate and classify the gap. If the platform provides a range, preserve the low and high estimate. Do not convert an imprecise platform value into a falsely precise percentage.
    6. Repeat after any pipeline change. Use the same audience definition and denominator so the new rate can be compared with the baseline.

    A small audit sheet is enough. Record these fields for every audience:

    Audit fieldWhat to recordWhy it matters
    DestinationGoogle Ads, Meta, or another paid platformMatch behavior differs by destination.
    Audience and purposeName plus acquisition, retargeting, suppression, or lookalikePrevents a blended rate from hiding a weak high-value list.
    Eligible inputRecords actually submitted for matchingProvides the denominator.
    Matched count or rangePlatform-reported rate or resulting audience estimateProvides the numerator or the closest available proxy.
    Identifier setEmail, phone, or bothShows whether limited identity inputs correlate with the gap.
    Extraction dateDate the file or sync snapshot was producedKeeps comparisons tied to a known audience version.

    Email-only lists commonly fall in a 40% to 60% range. A result above 70% is a reasonable signal to return your attention to creative, bids, and delivery, but it is not a guarantee that every relevant customer is covered. Use the threshold to prioritize work, not as a cross-platform leaderboard.

    Fix identity gaps in the right order

    A low rate does not automatically justify buying an enrichment product. First determine whether your own export, formatting, and identifier coverage are creating an avoidable loss.

    1. Verify the audience definition and counts. Confirm that the destination received the intended list, not an older export or a filtered subset. Reconcile the CRM count with the number actually submitted before diagnosing identity resolution.
    2. Check destination-specific preparation. Validate every field against that platform’s current formatting and hashing requirements. A phone number represented differently on each side may not resolve. Hashing protects the submitted representation; it does not turn inconsistent values into the same identifier.
    3. Use approved first-party identifiers together. If you legitimately collect both email and phone data, test a permitted multi-identifier upload against an email-only baseline. A customer may use a work address with you and a personal address on a social account, so one field can leave the platform without a usable bridge.
    4. Test record age. Compare recent customers with older cohorts using the same identifier set. If the recent cohort matches materially better, stale contact information is a more plausible problem than campaign configuration. Refresh data through legitimate customer interactions instead of guessing or silently appending questionable records.
    5. Evaluate connection-level enrichment only after the baseline. Require a clear description of what data is used, where it is processed, whether it is stored or written back, and how existing exclusions are preserved. A well-governed setup should not reintroduce identifiers deliberately withheld for privacy or compliance.

    Do not improve match rate by bypassing consent, purpose limitations, or fields your organization has excluded. The specific downside is larger than a weak campaign: you can create privacy, contractual, and compliance exposure while breaking the governance rules your customer-data system is supposed to enforce. The safe path is to improve recognition only with data your organization is entitled to use for that destination and purpose.

    Prioritize the fixes by economic consequence. Start with the largest suppression list on the highest-spend destination, then high-value retargeting audiences, acquisition exclusions, and lookalike seeds. This ordering addresses the place where a missed identity can make you pay for a customer twice before moving to less direct modeling effects.

    Prove the lift before you scale the change

    Two parallel audience test streams produce different numbers of identity connections before a closed gate to a larger audience.

    A higher match rate proves that the destination recognized more of the submitted audience. It does not, by itself, prove incremental revenue or better return on ad spend. The newly matched group may behave differently from the original matched group, so separate the identity result from the media result.

    1. Freeze the audience definition. Keep eligibility rules and the extraction window constant between baseline and treatment.
    2. Change one identity layer. Test corrected formatting, an additional approved identifier, a fresher data path, or enrichment separately when possible.
    3. Compare counts first. Verify that the input population stayed stable, then compare matched count and match rate. A larger upload is not a match-rate improvement.
    4. Hold media variables as steady as practical. Stable budgets, campaign structure, and creative make it easier to determine whether expanded recognition changed reach, conversions, customer acquisition cost, or return on ad spend.
    5. Measure suppression leakage separately. Flag acquisition conversions from people who already existed in your customer system before the campaign interaction. A falling leakage rate shows that exclusions are becoming more complete.

    Rokt mParticle reports that an identity-enrichment implementation for CKE Restaurants produced match-rate improvements of up to 117% on Google Ads and 29% on Meta, alongside improved return on the same spend. Those are vendor-reported, company-specific results, not a benchmark you should forecast into your own plan. They demonstrate what to test: whether better recognition expands usable audience coverage while the rest of the campaign remains substantially unchanged.

    Put one new line into your next paid-media review: the match rate of your largest suppression audience on your highest-spend platform. Establish the baseline, fix one failure point, and rerun the same calculation. Until that number is visible, you cannot tell whether you are optimizing the audience you built or only the fraction the platform happened to find.

    References

  • AI Marketing Data Activation: From Signals to Outcomes

    AI Marketing Data Activation: From Signals to Outcomes

    AI-powered marketing data activation is not simply the use of a model to analyze a database. It is the operating discipline of turning available signals into decisions, actions, and measurable feedback while the information is still useful.

    The two source articles examine that challenge at different levels. One presents a focused SEO workflow that joins competitive, search, and engagement data to prioritize content. The other argues for an enterprise performance model in which a unified data foundation and activation layer help marketers pursue business outcomes without continually expanding the technology stack. Together, they show what separates an isolated AI task from a repeatable activation system.

    Data activation is a decision system, not another data store

    Marketing teams can possess substantial amounts of data and still struggle to act on it. The performance-marketing article identifies fragmented customer profiles, disconnected activation systems, and stale audience definitions as barriers that AI cannot overcome by itself. Its central argument is that many apparent model failures are actually failures in the underlying data and operating architecture.

    The content-gap workflow demonstrates the same issue in a narrower setting. Competitive rankings can expose thousands of missing keywords, but the list alone does not establish what the business should publish. The workflow adds Google Search Console signals and Google Analytics engagement data so that AI can interpret competitive opportunity alongside existing authority and business value.

    This distinction is fundamental: data collection produces records, analysis identifies patterns, and activation connects those patterns to an approved action. AI can accelerate interpretation and propose a course of action, but it does not eliminate the need for relevant inputs, decision criteria, or an execution path.

    Key takeaways

    • AI activation begins with connected, usable data rather than a model or agent selected in isolation.
    • First-party performance signals help distinguish attractive-looking opportunities from opportunities that support business goals.
    • A useful system converts a stated outcome into proposed logic, a reviewable action, and measurable feedback.
    • Human oversight remains important for competitor selection, exclusions, strategic context, and final approval.

    The right foundation combines relevance, quality, and access

    Three interlocking data layers support a glowing activation hub while incoming signals pass through quality filters and access gateways.

    A strong activation foundation does not require every available data point. It requires the information needed to make a particular decision, joined at a level that preserves its meaning. More inputs can create more noise when they represent irrelevant markets, incompatible intent, outdated definitions, or entities that should not be compared.

    The SEO source illustrates relevance through competitor selection. Its workflow narrows the comparison to three to five sites serving a similar business and audience, while generally filtering out marketplaces, community sites, reference properties, directories, and unrelated publishers that could distort the opportunity set. It also recommends a stakeholder check because product or sales teams may know about strategic competitors that are not yet obvious in organic-search data.

    Quality then depends on cleaning the inputs. The workflow removes duplicates and excludes such noise as competitor-branded terms, careers, login and support queries, out-of-scope locations, mismatched intent, and overly broad commercial terms. This is not clerical work around the edges of AI. It defines the boundaries within which the model can form useful clusters and recommendations.

    Access is the third requirement. The SEO article describes both manual exports and direct retrieval through Model Context Protocol connections. Either route can support the analysis; the important point is that competitive rankings, first-party search signals, and landing-page outcomes become available within one reasoning workflow. Direct connectivity may reduce transfer work, but it does not replace validation, exclusions, or governance.

    At enterprise scale, the performance-marketing source extends this principle to customer profiles and activation destinations. It argues that the data foundation and activation layer should operate as a connected performance engine. That is a broader architectural claim than the SEO example, but both approaches depend on the same underlying capability: AI must be able to interpret trusted context and pass an approved decision toward execution.

    A practical loop turns signals into marketing action

    The sources suggest an operating loop that can be applied beyond SEO or audience management. The specific datasets and delivery channels will vary, but the decision sequence remains useful:

    1. Define the outcome. Begin with the result the team wants to influence, such as improving a content opportunity, increasing customer value, or reducing churn. A clear outcome gives the model a basis for prioritization.
    2. Select decision-relevant signals. Combine external opportunity data with first-party evidence and business performance. In the content-gap example, those roles are filled by Semrush, Google Search Console, and Google Analytics respectively.
    3. Normalize and filter the inputs. Remove duplicate, stale, irrelevant, or mismatched records before asking AI to detect patterns. Retain the exclusions and assumptions so that another reviewer can understand the analytical boundary.
    4. Ask AI for structured proposals. The output should be reviewable logic rather than an opaque verdict: topic clusters, priority tiers, audience conditions, supporting evidence, and uncertainties are more useful than a bare recommendation.
    5. Apply business review. Marketers and relevant stakeholders should confirm that the proposed logic reflects strategy, customer meaning, brand constraints, and operational reality.
    6. Activate through a defined destination. An approved decision must connect to a content roadmap, audience system, campaign platform, or another execution process. Without this step, the workflow remains analysis rather than activation.
    7. Measure and feed back the result. Performance data should return to the decision process so the team can refine its definitions and priorities instead of repeatedly starting from a static segment or report.

    The SEO workflow makes the prioritization stage concrete. It looks for missing competitor topics, areas where competitors rank higher, and subjects where the site already leads. Search Console impressions and positions between 8 and 20 can indicate existing topical association, while Analytics engagement and conversion signals add evidence of business relevance. The resulting roadmap is therefore based on the relationship among opportunity, attainability, and value rather than search volume alone.

    The enterprise source applies outcome-led reasoning to audience creation. It describes an mParticle capability that lets a marketer express an objective in plain language, after which an agent proposes audience logic for review and approval. It also presents Audience Expansion and Household Reach as examples of using first-party data to seek additional prospects or address a wider decision-making unit. These are vendor-reported product examples, not independent proof of performance, but they illustrate how an AI proposal can be connected to an activation path.

    Governance and measurement keep automation useful

    A circular workflow connects signal collection, AI decision-making, channel actions, measurement, and a guarded oversight checkpoint.

    The sources do not support a hands-off model of marketing. The performance article explicitly frames the marketer as the leader and the agent as a collaborator. The SEO workflow likewise preserves human judgment when selecting competitors, defining exclusions, checking stakeholder knowledge, and deciding which opportunities belong on the roadmap.

    That division of labor offers a practical governance model. AI can reduce the effort required to reconcile large datasets, group related signals, draft audience logic, and surface patterns. People remain accountable for the objective, data scope, acceptable trade-offs, approval, and interpretation of results. A proposed segment or content cluster should therefore be traceable to its inputs and understandable before it reaches production.

    Measurement should also match the original outcome. The content-gap source uses organic sessions, engagement rate, average engagement time, key events or conversions, and landing-page performance to add business context. The performance source emphasizes outcomes such as customer lifetime value and churn rather than the operational completion of an audience-building task. In both cases, task completion is not the same as marketing success.

    A sensible maturity path is to begin with one bounded decision where data sources, reviewers, activation destinations, and success signals are identifiable. Once that loop is reliable, the organization can reuse its controls and feedback process for additional use cases. The durable advantage will come from shortening the distance between evidence and action while preserving the context and accountability that make the action worth taking.

    References

  • How AI Advertising Signals Are Reshaping Audience Targeting

    How AI Advertising Signals Are Reshaping Audience Targeting

    AI-powered advertising is moving beyond simple demographic segments or keyword lists. The emerging model combines advertiser-supplied audiences, platform-native attributes, exposure data, creative inputs and conversion outcomes to help automated systems decide whom to reach and how to optimize.

    Reports about ChatGPT Ads and Microsoft Advertising illuminate different parts of that model. The former points to more direct audience control through customer-list uploads, while the latter shows how many supporting signals must work together before automated targeting can produce useful results.

    Key takeaways

    • CrushPress.AI reported an apparent ChatGPT Ads feature that accepts email- or phone-based audience lists, but the report was preliminary and did not establish match rates or performance.
    • Microsoft Advertising offers a broader signal mix that reportedly includes LinkedIn profile attributes, impression-based remarketing, landing-page imagery and conversion data.
    • An audience identifier tells an ad system who may be relevant; measurement signals tell it which outcomes should guide optimization.
    • More data does not automatically improve targeting. Clean tracking, concentrated campaign structure and relevant creative help automation interpret signals correctly.
    • Advertisers need governance for consent, list handling, exclusions and platform-specific policies alongside performance controls.

    Three signal layers now shape audience decisions

    Three layers of abstract customer, contextual, and outcome signals converge through a targeting lens toward a diverse audience.

    Advertiser-supplied identity signals

    CrushPress.AI reported that an Audiences area was appearing under Tools in ChatGPT Ads Manager. According to the report, advertisers could upload raw or hashed email addresses and phone numbers in CSV or TXT files, then use the resulting audiences as campaign filters. The account was based partly on screenshots attributed to Craig Graham and Joss Froggatt on LinkedIn, so it should be treated as an apparent rollout rather than a complete product specification.

    This type of first-party identity signal can connect an advertiser’s known customers or prospects with accounts recognized by an advertising platform. Its practical value depends on factors the report did not resolve, including audience matching, minimum usable size, availability across accounts, exclusions and measured lift. The important development is therefore not a guaranteed performance gain, but the appearance of a more direct way for advertisers to define relevant audiences inside a conversational advertising environment.

    Platform-native profile and exposure signals

    The Microsoft Advertising account describes a different source of audience intelligence: information already available within the platform’s ecosystem. It reports that LinkedIn Profile Targeting can support observation and bid adjustments, while Company, Industry, Job Function and Seniority data can serve as Performance Max audience signals. For B2B campaigns, those attributes can express professional relevance without requiring the advertiser to possess every prospect’s contact details.

    The same source highlights impression-based remarketing, which can reportedly include, exclude or adjust bids for people who have seen an ad. It says this method does not require an existing email list or site pixel and that a person may remain eligible for up to 30 days after one impression. Unlike an uploaded list, this signal reflects prior advertising exposure rather than a known customer relationship.

    Creative and outcome signals

    Audience targeting is only one part of an automated decision system. The Microsoft Advertising source also treats creative assets as signals: the platform can reportedly retrieve images from landing pages when that capability is enabled, using the advertiser’s own site as material for ad experiences. Strong, relevant imagery may help the system represent the offer, while unsuitable page images can introduce a different kind of noise.

    Conversion and attribution data complete the loop. The source identifies Microsoft Click ID, view-through conversions and simplified conversion setup as mechanisms that help connect advertising activity with outcomes. In general terms, identity and profile data indicate possible relevance, creative communicates the proposition, and conversion data tells automation which decisions appear to be working.

    Signal quality matters more than signal volume

    The two reports together suggest that AI targeting should be understood as signal engineering, not merely audience selection. Uploading a customer file may define a valuable group, but it does not establish the campaign objective, repair incomplete conversion tracking or ensure that the creative matches that group. Conversely, sophisticated bidding cannot recover reliable meaning from duplicated attribution, irrelevant conversions or poorly maintained landing-page assets.

    Campaign structure affects this interpretation. The Microsoft Advertising source argues that ad-group-level scheduling and location settings can reduce unnecessary campaign duplication and concentrate conversion activity. It also warns that automatic synchronization from an imported campaign can overwrite platform-specific changes. Importing from another advertising system may accelerate setup, but preserving the original account’s assumptions can prevent the destination platform from learning from its own audiences and auction conditions.

    Controls should be applied at the level where the underlying decision belongs. The source says Microsoft Advertising supports account-level phrase- and exact-match negatives, while noting that neither handles close variants. A broad account exclusion can remove unwanted traffic everywhere, but a nuanced restriction may belong at campaign or ad-group level. The broader lesson applies across AI advertising: guardrails help when they remove genuinely invalid choices, but overly broad rules can suppress useful learning.

    Measurement and governance determine whether targeting is useful

    A protected AI decision core filters audience signals through privacy, balance, and verification symbols before they reach groups of people.

    A useful evaluation begins by separating audience availability from audience effectiveness. The reported ChatGPT Ads capability answers a setup question: can an advertiser provide identifiers and use the matched audience as a filter? It does not, on the evidence supplied, answer whether that audience improves incremental conversions, lowers acquisition costs or simply reaches people who would have converted anyway.

    The Microsoft Advertising account emphasizes measurement before bid changes. That ordering matters because incomplete attribution can make an audience, keyword or bidding strategy appear responsible for a problem created elsewhere. Click-based and view-through measurements can also assign value differently, so teams need consistent definitions of the outcomes used to train automation.

    Before expanding an AI-targeted campaign, advertisers should establish:

    1. The targeting purpose: whether a signal is intended for inclusion, exclusion, observation, bid adjustment or automated prospecting.
    2. The source and freshness: where the data originated, how recently it was collected and whether it still represents the intended audience.
    3. The optimization event: which conversion actions represent business value and whether they are recorded consistently.
    4. The comparison: what control group, holdout or other baseline can distinguish incremental impact from ordinary demand.
    5. The creative fit: whether supplied or automatically retrieved assets accurately represent the offer for the selected audience.
    6. The governance boundary: whether collection, uploading, hashing, retention and activation follow applicable consent requirements and platform rules. Hashing changes how an identifier is represented; it does not by itself establish permission to use it.

    These checks also make cross-platform comparisons more meaningful. An uploaded customer audience, a professional-profile signal and an impression-based remarketing pool represent different relationships with a person. Treating them as interchangeable because all three appear under an audience label would conceal their different intent, reach and measurement requirements.

    The next advantage will come from coherent signals

    As conversational and established advertising platforms add more automation, audience access alone is unlikely to be a durable advantage. The stronger capability will be coordinating permissioned audience data, platform-specific context, suitable creative and trustworthy outcomes into one understandable learning loop. Marketers that can explain what each signal means, where it belongs and how its contribution will be tested will be better positioned to use new targeting controls without surrendering accountability.

    References

  • Google Ads Updates Split Bidding Labels From Data Automation

    Google Ads Updates Split Bidding Labels From Data Automation

    Two Google Ads updates illustrate why the word automation needs careful interpretation. One reorganizes how established bidding strategies are named, while the other automatically begins processing eligible advertisers’ conversion data into customer lists.

    The practical distinction is consequential: the bidding update is reported as cosmetic, but the audience update changes an account default. Advertisers therefore need different responses to each development rather than treating both as changes to campaign optimization.

    Two updates, two different forms of automation

    The bidding report says Google is restoring the standalone Target CPA and Target ROAS names. It also says the underlying bidding behavior and expected campaign performance remain unchanged, with no advertiser action required.

    By contrast, the customer-list report describes an operational default: eligible accounts will have conversion-based customer lists enabled automatically, with data processing reported to begin on August 18. The sources therefore cover complementary but materially different issues. One changes the language used to describe automated decisions; the other changes how an audience-data feature is activated.

    Restored bidding names make campaign intent easier to read

    A campaign manager examines unchanged bidding mechanisms beneath rearranged blank color-coded tabs.

    According to the bidding report, “Maximize conversions with a Target CPA” will again be called Target CPA, while “Maximize conversion value with a Target ROAS” will return to Target ROAS. Maximize Conversions and Maximize Conversion Value remain available as separate strategies for advertisers prioritizing conversion volume or conversion value.

    This creates a clearer conceptual boundary between an unconstrained maximization objective and an objective governed by a stated efficiency target. It should not, however, be interpreted as a new bidding model, a performance intervention or a reason to reset campaigns. The source explicitly characterizes the change as naming-only.

    The report also connects the revised interface labels with Google Ads API terminology. Teams maintaining integrations or reporting systems are advised to watch for adjustments involving the BiddingStrategyType enum, standalone TargetCpa and TargetRoas messages, and optional targets within MaximizeConversions and MaximizeConversionValue. That makes taxonomy mapping a more relevant concern than bid-performance troubleshooting.

    Automatic customer lists require a governance decision

    A compliance team reviews anonymous data tokens passing through a privacy checkpoint into an automated audience container.

    The customer-list report says automatic enablement applies to qualifying advertisers already using both Enhanced Conversions and Customer Match but not conversion-based customer lists. Google will process existing conversion data to make the lists available without additional implementation work, according to the source.

    Availability is not the same as campaign use. The report says advertisers can subsequently decide whether to add the resulting audiences to campaigns or ad groups. The immediate decision is therefore whether the account should permit list generation at all; targeting decisions remain a separate step.

    Advertisers that do not want the feature enabled can disable conversion-based customer lists in account settings before the reported August 18 processing date. This opt-out makes the update relevant to account ownership, consent practices and internal audience-data policies even when no campaign is scheduled to use the lists.

    Key takeaways for Google Ads teams

    • Treat the Target CPA and Target ROAS update as a terminology change, not evidence that bidding logic or campaign performance has changed.
    • Keep Maximize Conversions and Maximize Conversion Value distinct from target-based strategies when documenting objectives and reporting results.
    • Review eligible accounts before the reported August 18 date and make an explicit decision about conversion-based customer-list processing.
    • Separate list creation from list activation: automatic availability does not require an advertiser to use an audience in a campaign or ad group.
    • Check API integrations and internal naming maps as Google aligns interface labels with standalone bidding-strategy types.

    What advertisers should monitor next

    Together, the updates point toward a Google Ads environment in which interfaces may become clearer while data features become more automatic. Strong account management will depend on identifying which changes merely improve labels and which alter defaults, permissions or data flows. Teams that document both bidding intent and audience-data choices will be better prepared for subsequent interface and API adjustments without mistaking automation for loss of control.

    References

  • How AI Platforms Are Reshaping Commerce Advertising

    How AI Platforms Are Reshaping Commerce Advertising

    AI-powered commerce is not emerging as a single ad format. Across the supplied reports, four related shifts are taking shape: structured product data is becoming ad creative, retailer audiences are moving into broader media channels, conversational assistants are becoming shopping environments, and transaction data is being used to connect advertising with business outcomes.

    For advertisers, the useful distinction is not simply between search, retail media and conversational AI. It is between platforms that help people discover an offering, platforms that support a buying decision, and platforms that can also complete or measure the resulting action.

    The ad is moving into the transaction interface

    Amazon’s reported Alexa for Shopping experience represents the most complete version of this transition. According to the supplied report, Amazon combined Rufus with Alexa+ to support product research, comparisons, price tracking, cart building and automated purchases. Sponsored products, Sponsored Brands and conversational ad formats can appear within that journey, placing advertising in the same environment where a customer expresses preferences and moves toward a purchase.

    OpenAI’s reported approach begins at a different layer. Its Ads Manager beta reportedly lets retail advertisers upload product feeds and generate ads from individual catalog items. Rather than building every product campaign manually, participating retailers can use structured catalog data to match products with purchase-oriented conversations in ChatGPT. The supplied report characterizes early beta performance as strong, but it does not provide a methodology or numerical results.

    Google’s richer Local Services Ads for Home Listings show that the same reduction in friction is not limited to conversational assistants. The supplied real estate report says these ads can display property photos, prices and home features using data provided through a collaboration with HouseCanary. Prospective buyers can then call, message or book an appointment with an agent from the ad experience. This is a lead-generation model rather than an automated purchase flow, but it similarly brings evaluation and action closer to the initial discovery surface.

    The Walmart Connect and Display & Video 360 integration addresses another part of the system: extending retailer audiences and sales measurement into media that the retailer does not own. The supplied report says advertisers can activate Walmart Connect audiences for YouTube campaigns through DV360 and relate ad exposure to purchases at Walmart, including online and in-store transactions. Taken together, the reports describe commerce advertising expanding both inward, deeper into shopping interfaces, and outward, across off-site media.

    Four models create different kinds of advertiser value

    Four connected miniature scenes depict product data, retailer audiences, conversational shopping, and purchase measurement around a central network.
    Reported platform moveWhere intent or action appearsPrimary advertiser valueImportant scope detail
    Walmart Connect audiences in Google DV360YouTube media followed by Walmart purchasesRetailer audience activation and sales attributionThe supplied report describes YouTube as the initial focus
    Google Home Listings in Local Services AdsProperty evaluation and agent contact within SearchRicher information for high-intent lead generationThe enhanced experience is reported as available nationwide in the U.S., with existing LSA advertisers automatically included
    OpenAI product-feed adsPurchase-focused conversations in ChatGPTCatalog-scale ad generation and product relevanceThe capability is described as an Ads Manager beta
    Amazon Alexa for ShoppingConversational research, comparison, cart building and purchaseAdvertising across a more complete shopping journeyThe report says existing sponsored ad campaigns are automatically eligible for the experience

    These are complementary models, not interchangeable products. Google Home Listings is oriented toward connecting a buyer with a service provider. OpenAI’s beta emphasizes scalable product-ad creation. Walmart and Google combine off-site reach with retailer transaction data. Amazon is placing discovery, advertising and commerce functions inside a single assistant. Comparing them by their position in the customer journey is more informative than grouping all four under a broad AI advertising label.

    The competitive stack is data, automation and proof

    Intent data is becoming more explicit

    Traditional targeting commonly relies on observable proxies such as searches, page visits or prior transactions. The Amazon report argues that conversational shopping can add direct expressions of needs, preferences and purchase goals. Walmart’s reported advantage is different but related: its shopper audiences are based on retail behavior and can be activated in YouTube campaigns. One source supplies language-rich intent, while the other supplies transaction-informed audience data.

    Those signals serve different purposes. A conversation can clarify what a shopper wants at a particular moment, while retailer data can help identify or evaluate audiences using past shopping behavior. Platforms capable of combining contextual intent with dependable commerce data may offer more precise decision inputs, although the supplied reports do not establish how the platforms compare on accuracy, privacy safeguards or incremental performance.

    Automation is changing the unit of campaign work

    OpenAI’s feed-based model shifts campaign preparation from constructing an ad for every item toward maintaining a catalog that can supply product-level ads. Amazon reportedly makes existing sponsored campaigns available in Alexa for Shopping and offers AI-driven campaign optimization tools. Google’s real estate update automatically brings existing LSA advertisers into the enriched listing experience.

    These examples automate different tasks. Product-feed ingestion automates ad assembly at catalog scale; campaign eligibility extends existing advertising into another surface; and optimization systems help determine how campaigns operate. Advertisers should therefore evaluate what a platform actually automates rather than treating every automated feature as equivalent. Less manual assembly does not remove the need for accurate data, suitable creative, inventory governance or campaign oversight.

    Measurement separates exposure from commercial evidence

    The Walmart-DV360 and Amazon reports place closed-loop measurement at the center of their advertiser propositions. Walmart’s integration reportedly links YouTube exposure with Walmart transactions. Amazon’s reported offering combines advertising, first-party signals and measurement inside an environment that can extend through purchase.

    The other two models require different interpretations. Google’s enriched real estate ads produce direct contacts with agents, but the supplied report does not describe transaction-level attribution for completed home sales. The OpenAI report says feed-based ads have performed well during the beta without disclosing the measurement framework. Consequently, a lead, a reported ad-performance result and an attributed retail sale should not be treated as the same outcome.

    Key takeaways

    • Commerce ads are moving closer to evaluation and action, whether that action is contacting an agent, adding a product to a cart or completing a purchase.
    • Structured feeds are becoming operating infrastructure for advertising, not merely back-office catalog records.
    • Conversational platforms can capture explicitly stated preferences, while retail platforms contribute audiences and transaction signals derived from shopping behavior.
    • Closed-loop attribution is a meaningful differentiator, but it is not described consistently across all four reports.
    • Platform maturity varies: the supplied material describes a beta at OpenAI, an initial YouTube focus for Walmart’s DV360 integration, a nationwide Google LSA experience and a broader shopping-assistant model at Amazon.

    Advertisers need a surface-by-surface operating plan

    Two marketing professionals view connected mobile, retail, media, search, and checkout environments coordinated by shared data flows.

    Treat structured data as a media asset

    When ads are assembled from feeds or enriched with listing information, data quality directly affects what a prospective customer sees. Retailers need reliable product names, availability and other relevant catalog fields; real estate advertisers depend on accurate property information and visuals. This is a general operating implication of feed-driven advertising, not a performance claim about any one platform.

    Define the outcome before comparing platforms

    A useful measurement plan should distinguish among media engagement, a conversation, an agent inquiry, a cart action and an attributed sale. The reports show why a single efficiency metric cannot explain every model. Each platform should be evaluated against the business action it can observe and the evidence it provides for connecting advertising to that action.

    Separate convenience from control

    Automatic enrollment and feed-generated ads can reduce setup work, but advertisers still need to understand where campaigns may appear, how products are selected and which reporting is available. Existing campaign portability, audience portability and measurement access are separate capabilities. A platform that offers one does not necessarily offer all three.

    Evaluate the customer experience alongside performance

    Advertising inside product research or a conversational exchange can shorten the path to action, but it also places greater weight on relevance and clear commercial context. As assistants take on more shopping tasks, advertisers and platforms will need to balance monetization with an experience that remains useful enough for customers to continue relying on it.

    The next stage of commerce advertising will likely be shaped less by the novelty of an AI interface than by how well each system connects dependable data, useful recommendations, controlled activation and credible measurement. Advertisers prepared to assess those components separately will be better positioned as these reported integrations expand and mature.

    References

  • Google AI Search Ads: Access, Control and Measurement

    Google AI Search Ads: Access, Control and Measurement

    Google’s AI-enhanced search experiences are changing more than ad placement. They are separating campaign management into three distinct questions: how advertisers gain access to AI Search inventory, how they guide automated decisions, and how they measure results when reporting remains incomplete.

    The supplied CrushPress.AI report, based on a discussion involving Google Ads Liaison Ginny Marvin and the PPC Chat community, offers useful answers across those questions. Viewed together, its details point to a system in which participation remains relatively open, but effective optimization increasingly depends on strong data and carefully defined instructions.

    Key takeaways

    • AI Max is not reported to be a prerequisite for ads to appear in AI Overviews or AI Mode.
    • Broad match can provide a route into AI Search inventory, while AI Max can extend matching beyond the advertiser’s explicit keyword set.
    • AI Search ads do not yet have a distinct reporting breakdown, limiting advertisers’ ability to isolate their contribution.
    • Google’s direction combines automated matching with advertiser guidance, first-party data and measurement designed for longer conversion cycles.

    AI Search eligibility is broader than AI Max

    One of the most consequential distinctions in the report is between eligibility and expansion. According to CrushPress.AI’s account of Marvin’s comments, advertisers do not need to enable AI Max merely to participate in Google’s AI-driven search experiences. Search campaigns using broad match keywords can still be eligible for AI Overviews and AI Mode.

    AI Max instead appears to widen the matching opportunity. The report says it can apply broad-match behavior to phrase and exact match keywords while also enabling keywordless matching. That makes AI Max less of an admission ticket and more of an additional discovery mechanism.

    This distinction should shape campaign decisions. An advertiser can evaluate AI Search exposure separately from the decision to grant Google more latitude in matching queries. The relevant question is therefore not simply whether to adopt AI Max, but whether its broader reach fits the campaign’s economics, message constraints and tolerance for automation.

    Reporting has not caught up with the new inventory

    An analyst examines fragmented advertising signals as some data paths vanish behind translucent blank reporting panels.

    Access to AI Search inventory does not currently come with equivalent visibility. The source reports that ads appearing in AI Overviews and AI Mode are recorded like other top-of-page ads, without a separate reporting breakdown. It also says Google was still determining what dedicated reporting should eventually look like.

    That creates an important analytical limitation. Advertisers may participate in AI Search without being able to isolate its traffic, conversion performance or incremental value from standard search placements. A campaign-level improvement cannot automatically be attributed to AI inventory, while a weak result does not reveal whether the problem arose from an AI placement, another top-of-page impression or a broader campaign setting.

    Until reporting becomes more granular, AI Search should be treated as part of the campaign’s combined delivery environment. Conclusions about its standalone effectiveness would go beyond the evidence available in the reported interface.

    AI Brief and first-party data serve different roles

    The report describes AI Brief as a forthcoming control layer for AI Max. Advertisers are expected to be able to supply guidance covering matters such as target audiences, preferred message themes, priority search intents and prohibitions including instructions not to mention prices. CrushPress.AI says the rollout was planned to begin with English-language Search campaigns before extending to Performance Max and Shopping campaigns.

    Those instructions and an advertiser’s data are complementary rather than interchangeable. AI Brief can communicate strategic boundaries: whom a campaign should address, which ideas it should emphasize and what it should avoid. First-party data provides signals about actual customer and conversion outcomes.

    CrushPress.AI reports that Google emphasized data quality through a concept called Data Strength and pointed to Enhanced Conversions and Google Tag Gateway as important tools. The broader implication is that automation does not eliminate foundational measurement work. If the underlying signals are incomplete or unreliable, more sophisticated matching and creative guidance cannot supply the missing business evidence.

    Measurement is moving toward longer customer journeys

    A shopper follows a winding path across several digital touchpoints while interaction signals converge into a measurement lens and a secure data vault supports the journey.

    Qualified Future Conversions, or QFC, represents another part of Google’s reported direction. The source describes it as a metric that estimates potential conversions occurring within 180 days after an ad interaction. It was reportedly being tested with selected advertisers and was presented as especially relevant to B2B and lead-generation businesses with lengthy sales cycles.

    QFC addresses a different measurement problem from the missing AI Search breakdown. Dedicated placement reporting would help advertisers understand where an interaction occurred; a future-conversion estimate is intended to help evaluate what that interaction may eventually produce. Neither capability substitutes for the other.

    The report also identifies new AI Search ad formats, QFC and YouTube Creator Partnerships as three areas Marvin highlighted after Google Marketing Live. Together, those priorities suggest attention to discovery, delayed outcomes and creator-led reach. For search advertisers, the immediate challenge is to prepare reliable inputs and explicit campaign guidance while avoiding stronger claims about AI-specific performance than the available reporting can support.

    What advertisers should prepare next

    The most durable preparation is not adoption of every automation feature. It is a campaign structure that can accommodate wider matching without losing strategic intent, supported by dependable conversion signals and documented messaging boundaries. As AI-specific controls and reporting develop, advertisers with those foundations will be better positioned to test new inventory and interpret the results responsibly.

    References