Tag: Analysis

  • How to Prioritize SEO Technical Debt Without Wasting Sprints

    How to Prioritize SEO Technical Debt Without Wasting Sprints

    Your crawler has finished, and now you have 10,001 flags competing for attention. The highest counts look urgent, the tool has assigned severity labels, and someone wants to know how quickly the team can make the report green.

    Do not turn that export into your roadmap. Your job is to find the small set of problems that obstruct valuable pages, repeat through important templates, or become more expensive if they survive the next release. Everything else should be scheduled, monitored, or deliberately left alone.

    Start with page value, not issue volume

    Technical SEO debt is the gap between the site you have and the technical foundation needed to support organic discovery, indexation, performance, and growth. It can sit in crawling, indexation, architecture, templates, performance, migrations, structured data, or reporting. That breadth is why a raw list of errors is such a poor prioritization system.

    A warning matters only in context. A canonical conflict on a revenue-generating template is a different problem from the same conflict on an old tag page with no impressions. A missing meta description on an important category page may deserve attention; the same omission across zero-impression utility URLs may have no useful upside. Issue type alone cannot tell you what to do.

    Segment the site before scoring the debt. At minimum, separate these groups:

    • Revenue and conversion pages: Product, service, category, lead-generation, signup, or other pages tied to a valuable action.
    • Organic discovery pages: Editorial, educational, comparison, glossary, location, and other pages intended to attract demand.
    • Supporting pages: Content that strengthens navigation, topical relationships, trust, or the user journey without being the final conversion destination.
    • Utility pages: Account, filter, sort, search, print, login, and operational URLs that may not belong in search results.
    • Legacy and generated URLs: Redirected paths, parameters, faceted combinations, outdated structures, and other URLs created by historical or automated behavior.

    For each segment, record its intended indexation state, business purpose, organic role, template, and owner. This prevents a common audit failure: treating every crawlable URL as though it should rank. An excluded utility URL may be working exactly as intended, while one excluded product template could represent a serious access problem.

    Then validate whether each finding is isolated or systemic. Sample representative URLs and inspect the underlying template or rule. A thousand warnings caused by one template defect are one scalable problem, not a thousand separate tasks. Conversely, one incorrect robots.txt rule can be more urgent than thousands of harmless metadata warnings.

    Put every finding into one of four action buckets
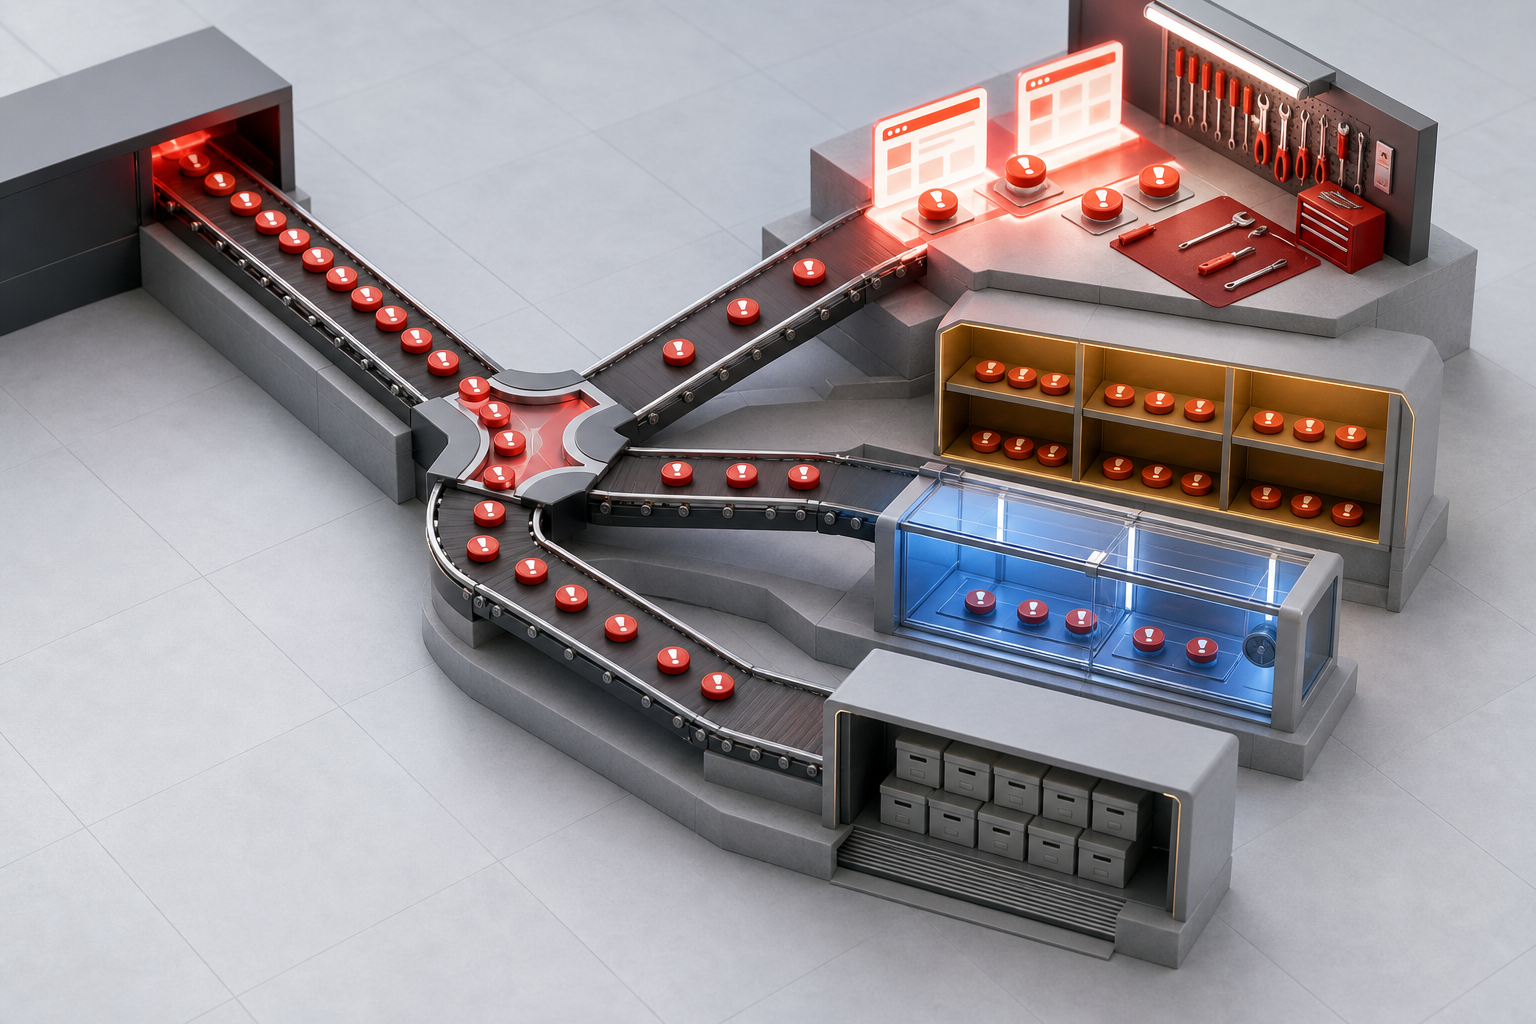
    A miniature audit station sorts small issue tokens into a repair bench, a future-work shelf, an observation chamber, and an archive compartment.

    Every finding should end with a decision, not merely a severity label. Use four buckets: fix now, fix soon, monitor, and ignore for now. The boundaries depend on affected pages and outcomes, not on how alarming the crawler makes the warning look.

    ActionUse it whenTypical examples
    Fix nowThe issue blocks or materially weakens access, discovery, ranking, conversion, or a business-critical path.Noindex directives on priority pages; robots.txt blocks on important sections; key pages canonicalized elsewhere; broken migration redirects; broken internal links to revenue pages; slow core templates; competing duplicate page sets.
    Fix soonThe issue creates meaningful drag, affects a valuable segment, or will constrain growth and maintenance if allowed to spread.Buried priority pages; outdated XML sitemap entries; faceted crawl waste; missing schema on important templates; thin indexable pages at scale; inconsistent heading templates.
    MonitorThe possible impact is limited or unclear, and current performance does not justify immediate work.Minor performance misses on low-traffic pages; a few redirect chains; duplicate titles on low-value URLs; non-critical crawl anomalies; JavaScript concerns involving non-indexable elements.
    Ignore for nowThe imperfection does not affect search access, valuable journeys, current performance, or future scalability.Missing descriptions on zero-impression pages; old 404s with no traffic or links; duplicate headings on utility pages; low-value HTML validation warnings; flags on intentionally blocked or noindexed URLs.

    The phrase for now matters. Ignoring an issue is a documented decision based on current scope and impact, not a claim that the issue can never matter. A warning on a dormant template may move into the roadmap if that template becomes part of a launch, migration, or expansion.

    Use this decision sequence when a finding is disputed:

    1. Confirm intent. Is the directive, status code, canonical, internal-link pattern, or generated URL behavior deliberate?
    2. Identify the affected segment. Does the issue touch pages that should be discovered, indexed, ranked, or used to complete a valuable action?
    3. Describe the mechanism. State how the issue could affect crawling, indexation, internal authority flow, page understanding, user experience, or conversion. If you cannot describe a credible mechanism, do not assign an urgent priority.
    4. Check observable impact. Review indexation, impressions, organic traffic, conversions, crawl behavior, and affected search journeys where those measurements are available.
    5. Find the root cause. Determine whether the defect lives in one URL, a template, navigation, platform configuration, rendering, or a migration rule.
    6. Assess delay risk. Ask whether waiting leaves performance stable or allows the problem to spread, compound, or become embedded in another release.

    This sequence also exposes false emergencies. A crawler may flag blocked pages because it cannot inspect them fully, but those warnings are irrelevant if the pages are intentionally excluded and have no organic role. The target is not a perfect crawl score or zero excluded URLs. It is a site where important pages can be accessed, understood, prioritized, and used.

    Score impact, scale, risk, and effort without fake precision

    Once the action bucket is clear, score each finding across five factors: SEO impact, business impact, scale, risk, and effort. A simple high, medium, or low assessment is often more defensible than a complicated formula. The score should make the reasoning visible, not disguise judgment as mathematics.

    FactorQuestions that raise priorityQuestions that lower priority
    SEO impactCan this prevent crawling or indexation, send contradictory canonical signals, weaken internal discovery, or impair pages already earning visibility?Is the warning limited to intentionally excluded pages, cosmetic metadata, or behavior with no plausible search mechanism?
    Business impactDoes it affect pages tied to sales, leads, demos, signups, qualified visits, or another defined business outcome?Are the affected URLs unused, obsolete, or disconnected from valuable journeys?
    ScaleDoes one rule or template affect an important page set? Will the number of affected URLs grow automatically?Is it an isolated edge case with no sign of repetition?
    RiskCould waiting cause traffic loss, migration failure, index growth, cannibalization, or a harder future repair?Is the behavior stable, contained, reversible, and unlikely to spread?
    EffortCan a contained template or configuration change solve the root cause with manageable QA?Does the repair require broad platform work, content rewrites, multiple teams, or risky URL changes for little expected benefit?

    Effort should shape sequencing, but it should not erase impact. A difficult crawl or indexation blocker does not become unimportant because it needs engineering time. Likewise, an easy metadata cleanup does not become strategic merely because the team can finish it quickly. Keep quick wins on the roadmap only when their expected benefit exceeds the opportunity cost.

    Translate the result into priority language that product and engineering teams already understand:

    • P0: Business-critical pages cannot be crawled or indexed as intended.
    • P1: A high-impact template, architecture, performance, migration, or duplication issue is limiting visibility, growth, or conversion.
    • P2: The work is useful and justified but not urgent; schedule it behind access blockers and high-value systemic fixes.
    • P3: Monitor the condition, document why it is not being fixed, or batch it with related maintenance.

    Write a one-sentence priority case for every P0 and P1 item: This issue affects [page segment and scope], interferes with [search or user mechanism], puts [business outcome] at risk, and can be corrected through [root-cause change and dependencies]. If you cannot fill in those fields, the task probably needs more investigation or a lower priority.

    Structured data needs the same discipline. Missing or invalid schema on an important template can create machine-readable clarity debt and may justify a fix. But schema cleanup should not outrank a robots block, incorrect noindex, or canonical error that prevents the underlying page from being considered at all. Search and AI visibility begin with accessible, indexable, coherent pages; markup cannot compensate for a broken foundation.

    Turn the audit into root-cause tickets and a sequenced roadmap
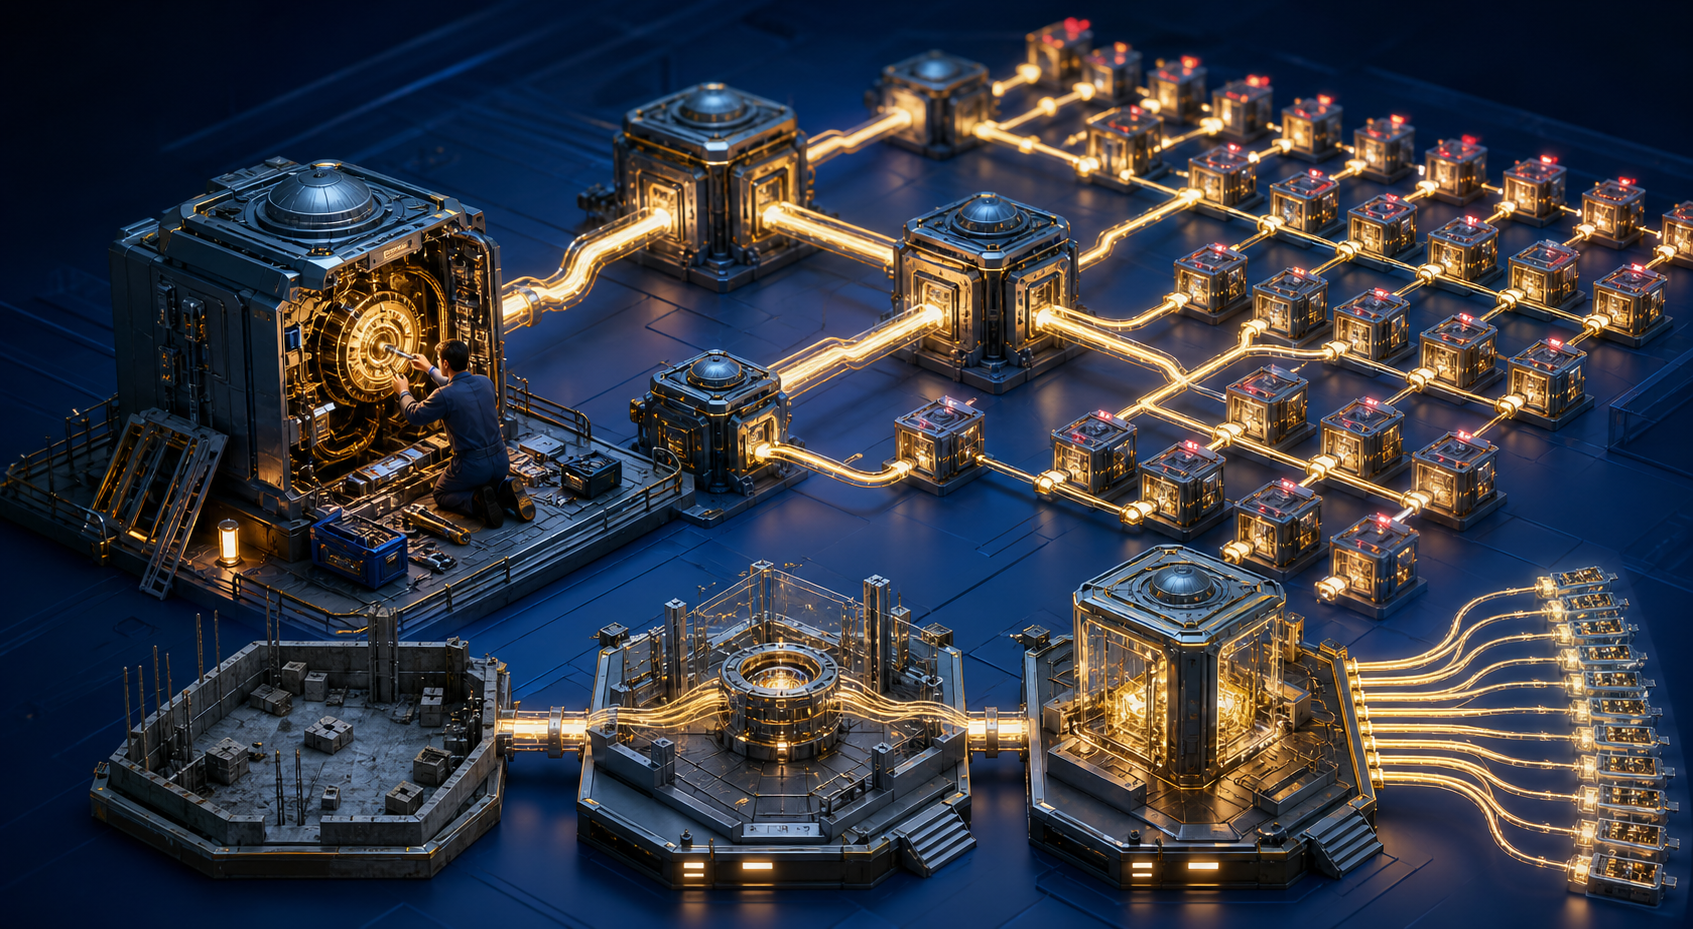
    A technician repairs one shared website template hub that feeds many connected page modules, with maintenance stations arranged in sequence beside the network.

    An audit finding is not ready for a sprint merely because it has a URL list. Development teams need a bounded change, an intended outcome, and a way to prove the fix worked. Create one ticket for the root cause and keep the affected URLs as evidence.

    Each implementation-ready ticket should contain:

    • Outcome: What should search engines and users be able to do after the change?
    • Affected segment: Which page group, template, directory, or navigation path is involved?
    • Observed and intended behavior: What happens now, and what should happen instead?
    • Scope evidence: Representative URLs, the known pattern, and whether the count is exact or crawl-dependent.
    • Impact case: The search mechanism, business consequence, scale, and delay risk supporting the priority.
    • Root cause: The template, rule, component, content process, or platform behavior that should change.
    • Acceptance criteria: Testable conditions covering directives, status codes, rendered output, links, canonicals, sitemap inclusion, or structured data as relevant.
    • QA and rollback: Representative test cases, expected side effects, monitoring signals, and a safe way to reverse the change.
    • Ownership and dependencies: The engineering, SEO, content, analytics, or product work required to finish the task.

    Bulk changes to canonicals, robots directives, redirects, internal links, and URL generation can remove valuable pages from search or create new crawl paths. Test template changes on representative URLs, preserve the previous configuration, and define rollback conditions before deployment. A large affected count increases the need for QA; it does not prove the expected benefit.

    Sequence the roadmap by dependency. Restore access to important pages first. Then repair high-value templates and architecture. Address scalable crawl, indexation, performance, and structured data debt after the underlying pages are stable. Batch low-impact cleanup with related platform or content work rather than demanding a separate sprint.

    Do not overlook reporting debt. If Google Search Console and analytics data cannot be mapped to useful page groups, the team cannot reliably distinguish a broad commercial problem from noise on low-value URLs. In that case, segment-level measurement may be the enabling task that makes the rest of the prioritization defensible.

    Every monitor or ignore decision needs a review trigger. Reassess when the affected template changes, the issue spreads into a priority segment, indexation or traffic shifts, a migration is planned, or the site begins generating the URLs at greater scale. This turns the backlog into a controlled risk register instead of a graveyard of unresolved warnings.

    Key takeaways

    • Prioritize technical SEO debt by page segment and business purpose, not by warning count.
    • Fix access blockers and defects on valuable, scalable templates before cosmetic cleanup on low-value URLs.
    • Assign every finding to fix now, fix soon, monitor, or ignore for now; do not leave the decision implicit.
    • Score SEO impact, business impact, scale, future risk, and implementation effort, then write the reason for the assigned priority in plain language.
    • Create root-cause tickets with acceptance criteria, QA, rollback conditions, ownership, and monitoring triggers.
    • Measure success through restored access, visibility, useful journeys, conversions, or reduced scalable risk, not a perfect crawl score.

    Take the highest-volume issue in your current audit and re-evaluate it against one valuable page segment. If you cannot connect it to a search mechanism, business outcome, scalable risk, or enabling dependency, move it down. Then give the recovered capacity to the smallest root-cause change that protects the pages your organic strategy actually depends on.
    References

  • How to Use Profound Aim Brainstorm Mode Productively

    How to Use Profound Aim Brainstorm Mode Productively

    You can have useful AI Search data and still face a blank next step. The data may expose several promising directions, but it cannot choose which uncertainty your team should resolve first.

    Brainstorm Mode within Profound Aim is designed for that handoff: it guides a broad goal toward scoped, ready-to-run Agents. The practical value is not producing more ideas. It is reducing the distance between an ambition and a task that can inform a real decision. To get that value, you need to give Brainstorm Mode strategic direction without prematurely prescribing the analysis.

    Use Brainstorm Mode to close a decision gap

    Brainstorm Mode is most useful when you know the outcome you want but do not yet know what an Agent should investigate. That is a decision gap: your team has a business objective and relevant data, but the next analytical question remains unclear.

    Good reasons to start in Brainstorm Mode include:

    • You can describe the business outcome, but several parts of the AI Search data could be relevant.
    • You have noticed a visibility pattern and need to decide which part deserves deeper investigation.
    • Different teams are proposing different explanations for the same result.
    • You need to turn a broad AI visibility priority into work that has a clear boundary.
    • You know someone can act on the answer, but you have not yet defined the question that would produce it.

    Brainstorming adds less value when the task is already precise. If you know the exact question, scope, evidence and required output, you may already have an Agent brief. Starting another ideation cycle can introduce ambiguity that was not there before.

    There is a simple readiness test: complete the sentence, “When this Agent finishes, we will decide whether to ______.” If you cannot fill the blank with a decision your team is prepared to make, the problem is not Agent scope yet. You still need alignment on the purpose of the work.

    Give Aim a broad goal without giving it an empty one

    A glowing sphere and several streams of abstract evidence pass through an open funnel and become three distinct research capsules.

    Broad and vague are not the same. A broad goal leaves room to discover the right investigation. A vague goal hides the decision, audience and boundary that make an investigation useful.

    “Improve our AI visibility” is vague. It does not say which part of the business matters, what kind of visibility problem is in scope or what anyone will do with the result. Brainstorm Mode may still be able to propose work, but you will have no strong basis for judging whether that work matters.

    A useful goal normally contains these ingredients:

    • Outcome: the change you want to support, such as choosing a content priority or understanding a visibility weakness.
    • Business scope: the brand, offering, product area or customer problem that matters.
    • Audience scope: the market, language, geography or buyer context that should govern relevance.
    • Decision: what the team expects to choose after seeing the evidence.
    • Evidence boundary: what the available AI Search data can reasonably help examine.
    • Constraint: what should remain outside the first investigation so the Agent does not become an entire strategy project.

    You can assemble those ingredients with this reusable structure:

    Help us decide [decision] for [brand, offering or audience] by using our AI Search data to investigate [uncertainty]. Keep the first Agent focused on [scope], and produce evidence we can use to [next action].

    Goal-framing template

    For example, replace “Improve our AI visibility” with: “Help us decide which content area should receive the next optimization effort. Use our AI Search data to investigate where visibility is weakest within the product area we plan to grow, and keep the first Agent focused on identifying and characterizing the gap rather than recommending a complete content strategy.”

    The improved version is still broad enough for Brainstorm Mode to shape the work. It also supplies a decision, a business boundary and a stopping point. That stopping point matters. Without it, one Agent can easily become responsible for finding a problem, explaining it, designing a strategy, writing content and evaluating results. Those are different jobs with different evidence requirements.

    Review every proposed Agent as a research brief

    “Ready to run” describes an operational state, not automatic strategic importance. Before running a proposed Agent, make sure its result could actually change what you do. A technically valid investigation can still be too broad, unanswerable from the available data or disconnected from the decision owner.

    Use this pre-run check:

    • One primary question: Can you express the Agent’s job as one question without joining several assignments with “and”?
    • Defined boundary: Does the brief identify the relevant brand, topic, audience or market while excluding unrelated areas?
    • Available evidence: Can the AI Search data support the requested analysis, or is the Agent being asked to infer facts the data does not contain?
    • Usable output: Will the result help someone choose, prioritize, approve, reject or investigate something specific?
    • Inference discipline: Does the brief distinguish observed patterns from possible explanations?
    • Named owner: Is there a person or team prepared to use the result?

    Break apart bundled Agents

    A bundled Agent might be asked to find every visibility gap, explain every cause, compare all relevant competitors, build a content strategy and produce implementation briefs. It sounds comprehensive, but each stage depends on choices made in the previous one. If the first interpretation is weak, every later deliverable inherits the problem.

    Start with the smallest question that can change the next action. An initial Agent might identify and characterize an in-scope visibility gap. A later Agent can investigate evidence-linked explanations for the selected gap. Content planning should begin only after you decide that the gap is important enough to address.

    This sequence also makes poor outputs easier to diagnose. You can tell whether the difficulty came from the goal, the data boundary, the interpretation or the proposed action instead of debugging one oversized deliverable.

    Separate observations from explanations

    AI Search data can reveal a pattern. A pattern does not, by itself, prove why that pattern exists. “The brand appears less often for this topic” is an observation. “The brand appears less often because of a particular content weakness” is an explanation that still needs support.

    If a proposed Agent asks why something is happening, require it to distinguish direct evidence from inference. The useful output is not an unsupported diagnosis stated confidently. It is a set of plausible explanations connected to the available evidence, with the remaining uncertainty made visible. That gives your team something it can test instead of a conclusion it can only accept or reject.

    Turn the first Agent into a controlled decision loop

    A research capsule moves around a circular track with four abstract review stations while a person oversees the final branching gate.

    The fastest way to create a pile of unused analysis is to run every plausible Agent at once. The outputs arrive without an order of operations, overlap in scope and often answer questions that no longer matter after the first decision.

    Use Brainstorm Mode as the beginning of a controlled sequence:

    1. Write the decision sentence: “When this Agent finishes, we will decide whether to ______.”
    2. Frame the broad goal around that decision and the relevant AI Search data.
    3. Use Brainstorm Mode to translate the goal into a proposed Agent or set of Agents.
    4. Apply the pre-run check and select the smallest Agent whose result could change the decision.
    5. Run that Agent before commissioning downstream analysis.
    6. Record the finding, the interpretation and the decision as separate items.
    7. Create another Agent only when the decision exposes a new uncertainty that must be resolved.

    A working note for each completed Agent can remain short:

    • Finding: What is directly supported by the output and underlying data?
    • Interpretation: What might the finding mean, and which part remains an inference?
    • Decision: What will the team do, defer or reject because of the finding?
    • Owner: Who is responsible for the next action?
    • Validation: What later AI Search signal would help determine whether the action had the intended effect?

    Consider a team deciding which product area deserves its next content investment. The first Agent could identify which in-scope topic area shows the most decision-relevant visibility weakness in the available data. The team then selects a topic based on business importance, not merely the size of the gap. A second Agent, if needed, can examine answer patterns for that topic and organize evidence-linked hypotheses. Only then does the team choose a content intervention and define how it will evaluate the result.

    That order preserves human judgment at the points where data cannot make the business choice. Brainstorm Mode helps structure the investigation; it does not remove the need to decide which market, audience, risk and opportunity matter.

    Key takeaways

    • Use Brainstorm Mode when you have a meaningful AI Search goal but have not yet converted it into an answerable investigation.
    • Frame the goal around a decision, business boundary, audience and evidence source instead of asking generally for better visibility.
    • Reject proposed Agents that combine discovery, diagnosis, strategy, production and measurement in one assignment.
    • Make every Agent distinguish data-backed observations from explanations that remain hypotheses.
    • Run the smallest useful Agent first, make a decision and generate follow-up work only when a new uncertainty appears.

    Before you open Brainstorm Mode, write one sentence: “When the first Agent finishes, we will decide whether to ______.” Use that decision to frame the goal you bring into Aim. If the blank is still empty, pause the Agent design and settle the business question first.

    References

  • Evidence-Led SEO: From Search Data to Defensible Action

    Evidence-Led SEO: From Search Data to Defensible Action

    Evidence-led SEO connects three questions that are too often handled separately: What is happening in search performance, what might explain it, and why should the business act? Google Search Console data can reveal demand and performance patterns, while official documentation can clarify the search requirements behind a recommendation.

    AI can shorten the journey from raw data to a plausible opportunity, but it does not turn a hypothesis into proof. A reliable strategy keeps observed data, machine-assisted interpretation, documented guidance, and business judgment distinct until they are assembled into a decision.

    Build an evidence chain instead of citing a best practice

    A glowing thread links search signals, hypothesis nodes, documentation pages, and a decision token on a table.

    The two source articles address different weaknesses in SEO decision-making. The Search Console analysis article describes using AI to detect patterns across large query exports. The documentation article explains how official Google references can make technical recommendations easier to defend with developers, clients, and other stakeholders.

    Together, they suggest an evidence chain with four layers. Each layer answers a different question, and none should be asked to do the work of all the others.

    Evidence layerQuestion it answersProper role
    Search Console dataWhat happened in organic search?Establish observed queries, pages, impressions, clicks, rankings, and click-through patterns.
    AI-assisted analysisWhat patterns or hypotheses deserve attention?Classify, cluster, compare, and organize large datasets for human review.
    Official documentationWhat behavior or implementation does Google describe?Support the technical rationale and create a shared external reference point.
    Business contextWhy should this action be prioritized?Connect the recommendation to likely value, risk, effort, and competing priorities.

    This separation matters. Search Console can show that a page receives comparison-oriented impressions, but it cannot by itself establish why the page underperforms. AI can propose explanations, but its output remains analysis rather than observed fact. Documentation may support a technical requirement, but it does not establish the commercial value of fixing a particular page. The final recommendation becomes credible only when the layers are connected without being conflated.

    Turn query data into a prioritized opportunity

    The Search Console source reports a workflow that begins by narrowing query data with regular expressions and then exporting the result for AI-assisted classification. Its examples include question-led searches, comparison terms, emerging terminology, and signals related to pricing, alternatives, implementation, migration, or vendor evaluation.

    The strategic value is not the regular expression itself. Filtering reduces a large dataset to a decision-shaped subset. AI can then group related queries by intent or theme, revealing patterns that would be difficult to recognize one row at a time.

    1. Start with a decision. Define the question before exporting data, such as whether an existing educational page is attracting evaluation-stage searches.
    2. Isolate the relevant observations. Filter for patterns connected to that question, then retain the associated performance fields and landing pages.
    3. Ask AI for structured analysis. Request categories, themes, confidence assessments, and ambiguous cases rather than an unqualified verdict.
    4. Inspect the underlying rows. Check whether the proposed cluster is coherent and whether a few high-volume queries are distorting the interpretation.
    5. Map the pattern to a page-level action. Decide whether the evidence supports updating an existing page, creating a focused asset, improving internal links, or changing the path to the next step.
    6. Define a measurement plan. Record the affected query set, page, intended outcome, and comparison method before implementation.

    This approach also changes how content opportunities are framed. The source notes that clusters of audience questions can inform FAQs, support material, sales resources, and content intended to provide direct answers. It also reports that apparently informational traffic can contain evaluation signals. In those cases, improving the page that already earns visibility may be more appropriate than automatically publishing another article.

    Use AI to accelerate analysis, not manufacture certainty

    An analyst reviews selected data clusters while an abstract AI system sorts a larger field of anonymous signals.

    AI is most useful when the assignment is bounded and auditable. Suitable tasks include generating a proposed Search Console regex, classifying query intent, clustering questions, identifying changes in terminology, and suggesting content formats. The Search Console source describes prompts that request CSV classifications with confidence scores or group queries into definitions, tutorials, comparisons, and expert recommendations.

    Those outputs should be treated as provisional labels. Intent can be mixed, a query can fit several themes, and an apparent trend can reflect the selected date range, page set, or filter. A defensible workflow therefore preserves the original export and maintains a visible connection between each conclusion and the rows supporting it.

    A practical review should test:

    • Whether the filter matches the intended language without excluding obvious variants.
    • Whether classifications are supported by the wording of the queries and their landing pages.
    • Whether the opportunity is broad-based or driven by a small number of observations.
    • Whether the recommended content format fits the likely task behind the query.
    • Whether the proposed action follows from the evidence or merely sounds plausible.

    This distinction is especially important for queries that may produce AI-generated search features. The source describes using informational and comparison patterns as an approximation for searches likely to trigger AI Overviews because Search Console does not provide the filter needed for that analysis. That is a useful hypothesis-building method, but the approximation should not be reported as confirmed feature exposure.

    Translate the opportunity into a defensible recommendation

    Finding an opportunity does not guarantee that it will reach a development sprint or content roadmap. The documentation source emphasizes that SEO work competes with product schedules, CMS constraints, legal concerns, brand requirements, technical debt, security, and other business priorities. Its central argument is that an official reference can move a discussion beyond personal preference, even though it cannot determine priority on its own.

    The same source cautions that Google documentation is incomplete and simplified for a broad audience. It should therefore serve as a starting reference, not an infallible account of every ranking mechanism or edge case. The article identifies canonicalization, robots.txt behavior, JavaScript rendering, discoverable internal links, structured-data eligibility, and HTTP status codes as areas where documented guidance can clarify implementation discussions.

    A strong recommendation package can combine both sources’ methods:

    1. Observation: State the Search Console pattern without interpretation.
    2. Hypothesis: Explain the likely missed intent, content gap, or technical obstacle, and identify AI’s role if it helped generate the hypothesis.
    3. Documentation: Link to the relevant official guidance and explain precisely how it applies to the current implementation.
    4. Recommendation: Describe the requested change in terms that content, engineering, or product teams can evaluate.
    5. Expected value and risk: Connect the change to the observed opportunity while avoiding unsupported forecasts.
    6. Validation: Specify what will be monitored after release and what result would challenge the original hypothesis.

    This format also improves collaboration. Developers can evaluate how to satisfy a documented search requirement within the site’s technical constraints. Content teams can see which audience behavior supports an update. Decision-makers can compare the opportunity with other work instead of being asked to accept an unexplained SEO rule.

    Key takeaways

    • Search Console establishes observed performance; AI helps organize it into hypotheses and possible actions.
    • Query filtering should begin with a decision question, not an open-ended search for anything interesting.
    • AI classifications, clusters, and trend signals require review against the original query and landing-page data.
    • Official Google documentation can support the technical rationale, but it does not replace experience, testing, or business prioritization.
    • The most defensible SEO proposal connects observation, hypothesis, documentation, action, value, and validation.

    As search interfaces and audience language continue to change, the durable advantage will come from shortening the path between evidence and action while keeping every inference inspectable. Teams that preserve that discipline can use AI for speed without surrendering accountability.

    References

  • Three Google Updates Reshape Search Measurement for Publishers

    Three Google Updates Reshape Search Measurement for Publishers

    Three Google updates reported by CrushPress.AI affect different points in a publisher’s measurement workflow: assessing search demand, checking whether pages can appear in search, and tracking visits after a click.

    Together, the changes make some analysis easier, but they also underline an important distinction: demand, indexability, and on-site traffic are separate signals. Publishers need to read them in sequence rather than treating any one report as a complete account of search performance.

    Key takeaways

    • Google Trends now offers preceding-period comparisons that can put changes in search interest into context.
    • Search Console’s page indexing report resumed updating after a reported three-week delay, restoring fresher diagnostic information.
    • Google Search now sends AMP visitors to publisher-hosted pages instead of presenting cached pages within Google’s AMP viewer.
    • Google reportedly characterized the AMP change as a delivery and measurement update, not a ranking change.

    Google Trends adds context before content decisions

    A content strategist compares two abstract periods of search-interest patterns at a desk.

    Google Trends sits near the beginning of the measurement process. It indicates relative search interest, helping publishers evaluate whether attention around a term or topic is gaining momentum, declining, or following a recurring pattern.

    CrushPress.AI reported that new controls above the Trends timeline can surface changes for periods such as week over week, month over month, and selected year-over-year comparisons. A preceding period can also be overlaid on the chart with a comparison line. This reduces the work required to establish a historical baseline before interpreting a movement.

    The practical benefit is better timing context. A rise in current interest is more meaningful when compared with the immediately preceding interval, while a year-over-year view can help reveal whether apparent momentum may instead reflect seasonality. Trends still addresses audience interest rather than the performance of a publisher’s individual pages, so its findings should guide investigation rather than serve as traffic or ranking evidence.

    Fresh indexing data restores a missing diagnostic layer

    Search Console answers a different question: whether Google can find and index pages on a particular site. Its page indexing report separates indexed and non-indexed pages, provides reasons pages may not be indexed, and can display impressions alongside the indexing chart, according to the source report.

    CrushPress.AI reported that this report had remained stuck on June 11, 2026, for roughly three weeks. As of Friday, July 3, it was displaying information through June 29. The refresh matters because an outdated diagnostic view can make a recent publishing, crawling, or indexing problem difficult to distinguish from reporting latency.

    The episode also offers a measurement caution. When a reporting interface is delayed, the age of its latest data should be checked before teams infer that a recent technical change caused an indexing movement. With fresher data available, publishers can return to examining affected pages and the reasons Search Console assigns, while still separating reporting status from the underlying indexing status.

    Direct AMP visits simplify the post-click measurement path

    A mobile visit follows a single direct path from a search result card to a publisher page and measurement hub.

    The AMP update concerns what happens after a searcher selects a result. CrushPress.AI reported that Google Search now directs AMP users to the publisher-hosted AMP page rather than a cached version displayed through Google’s AMP viewer. Google told the publication that the change should simplify analytics and tracking while reducing some maintenance associated with supporting AMP content.

    This shift can make the measurement path easier to understand because the destination is again the publisher’s own host. It does not, however, establish that AMP pages will gain more visibility. The report explicitly said Google described the change as unrelated to ranking and said the serving and ranking treatment of AMP in Search and Discover would remain the same.

    The distinction is especially important because AMP’s broader search role has already diminished. The source noted that AMP no longer receives preferential treatment in Top Stories and that such pages are encountered less often than before. The update therefore looks less like a revival of AMP as an SEO advantage and more like a cleanup of delivery, ownership, and analytics for publishers that continue to use the format.

    A more coherent search measurement workflow

    Read together, the updates describe three successive layers of analysis. Trends helps establish whether an audience is searching for a subject. Search Console helps determine whether relevant pages are eligible to be discovered through indexing. Publisher analytics then records what visitors do after reaching the site, with the new AMP routing potentially making that last step less complicated.

    This sequence helps prevent common category errors. Increasing search interest does not prove that a site is indexed for the topic. Successful indexing does not guarantee impressions or visits. Cleaner AMP analytics does not indicate a ranking improvement. When the signals diverge, teams can investigate the layer where the break occurs instead of forcing all three into a single performance narrative.

    Publishers should watch whether the refreshed reports remain timely and whether direct AMP delivery produces cleaner on-site data in practice. The durable opportunity is a measurement process that connects market demand, technical visibility, and owned-site behavior while preserving the limits of each signal.

    References

  • What Google Content Visibility Signals Really Tell Publishers

    What Google Content Visibility Signals Really Tell Publishers

    Google visibility is often discussed as if it could be improved through a single tactical change: choose a more successful headline pattern, add a machine-readable file, or imitate whatever appears to perform best across a large dataset. The source reporting points to a more demanding conclusion.

    A study of Google Discover headlines shows how an apparent format advantage can be driven by publisher and audience differences, while Google’s reported guidance on llms.txt says the file has no effect on Search rankings. Together, these accounts offer a practical way to distinguish an observable characteristic from a credible visibility lever.

    Visibility is not one outcome or one mechanism

    The two source articles address different Google environments. The Discover analysis concerns how often editorial articles appeared across the 1492.vision fleet. Its metric was hits per article, which the source described as a proxy for visibility rather than a count of Discover clicks. The llms.txt article, by contrast, concerns whether a site-level file affects visibility in Google Search.

    That distinction matters because a feature associated with frequent appearances on one surface is not automatically a ranking factor, a cause of traffic, or a general rule for Google visibility. A Discover headline can be correlated with exposure without causing it. A file can help another service understand a site while remaining irrelevant to Google Search. The surface, measured outcome, and proposed mechanism must therefore be identified before a result becomes actionable.

    Headline format looks powerful until publisher context is added

    Two contrasting publisher environments show different content-card styles, audience sizes, and distribution conditions around a central magnifying lens.

    The Discover report described an analysis of 1,674,518 English articles and 1,690,295 French articles from the 1492.vision corpus. When publishers were pooled, quote-led headlines produced 37% more hits per article than statements in English and 48% more in French. Questions also exceeded statements in the aggregate, by 7% in English and 16% in French.

    Those figures appear to support a simple editorial prescription. Yet the report argued that the aggregate comparison mixed together publishers with different audiences, subject matter, editorial styles, and patterns of Discover exposure. Celebrity publications, regional news organizations, and outlets focused on trending topics were among the types said to use quotations more often. Their underlying visibility could therefore make the quotation format look more effective than it was.

    The source identified this as an example of Simpson’s paradox: a relationship visible in pooled data can weaken, disappear, or reverse after the data is separated into meaningful groups. In this case, the relevant test is not simply whether all quote headlines outperform all statements. It is whether the formats perform differently within comparable publishers and contexts, with each publisher serving as its own baseline.

    This does not make headline construction irrelevant. It changes the claim that the evidence can support. The reported aggregate results describe where visibility occurred across a mixed population; on their own, they do not establish that converting a statement into a quotation will create the same lift for an individual publisher.

    Google’s llms.txt position removes a different false lever

    The second source reported that Google updated its AI Search optimization guidance to say that llms.txt files do not affect Search rankings. According to that account, Google Search does not use the files, and publishers do not need to create new AI-oriented text or Markdown files to qualify for inclusion in Search experiences involving generative AI.

    The reported guidance includes an important qualification: Google may still discover, crawl, and index various file types. That general ability does not mean llms.txt receives special ranking treatment. The source also noted that a site may maintain the file for other services without improving or damaging its Google Search visibility.

    This is a more direct finding than the Discover correlation. The headline analysis asks whether an apparent advantage survives contextual controls. The llms.txt guidance says the proposed mechanism is not used for the claimed Google Search benefit. One tactic requires better causal analysis; the other has been explicitly ruled out as a Google ranking aid in the source’s account.

    A stronger test for proposed visibility signals

    Glowing signal tokens move through a sequence of evidence checkpoints, with weaker signals diverted and stronger signals reaching an illuminated content card.

    The synthesis suggests that publishers should evaluate any claimed signal along three dimensions. First, the claimed outcome should be precise: ranking position, impressions, Discover appearances, clicks, or another measure. Second, comparisons should account for publisher, audience, topic, language, and surface whenever those factors could influence both the tactic and the outcome. Third, the proposed mechanism should be checked against Google’s stated use of the feature when relevant guidance exists.

    For headline decisions, the most informative evidence would come from comparisons within the same publication and from controlled editorial tests that keep topic and distribution conditions as comparable as possible. Hits per article can reveal exposure patterns, but it should not be presented as click performance or as proof that punctuation and syntax independently caused the result.

    For machine-readable files, the decision can be separated by beneficiary. An llms.txt file may be maintained for a non-Google service that uses it, but the reported Google guidance provides no basis for treating its creation as a Search ranking project. This prevents an implementation task from being justified with an unsupported visibility promise.

    Key takeaways

    • Google visibility claims must name the surface and metric; Discover hits, clicks, and Search rankings are not interchangeable outcomes.
    • The reported quote-headline advantage appeared in pooled English and French data, but publisher and audience differences made a simple format-based explanation unreliable.
    • Within-publisher comparisons are more useful than global averages when editorial conventions and baseline visibility vary across outlets.
    • According to the llms.txt source, Google Search does not use the file as a ranking aid, although sites may keep it for other services.
    • An observable pattern becomes actionable only after plausible confounders and the proposed mechanism have been examined.

    As new visibility tactics emerge, the durable editorial advantage will come from asking what was measured, what else could explain it, and whether the platform recognizes the proposed mechanism. That discipline leaves room for experimentation while keeping correlation, platform guidance, and causal claims in their proper roles.

    References

  • Server Log Analysis for Technical SEO: A Practical Guide

    Server Log Analysis for Technical SEO: A Practical Guide

    Server log analysis shows what search crawlers actually requested and how the server responded. That direct evidence can reveal crawl inefficiencies, response problems, and neglected page groups that simulated crawls or reporting interfaces may not expose.

    The goal is not to replace Google Search Console, Bing Webmaster Tools, or site crawlers. It is to add an infrastructure-level record that can confirm whether important URLs receive crawler attention, identify where requests are being diverted, and provide a baseline for migrations and platform changes.

    What server logs add to the SEO evidence stack

    SEO crawlers test a site from the outside, while webmaster platforms present search-engine reporting. Server logs answer a different question: which requests reached the infrastructure, and what happened when they arrived?

    The supplied CrushPress.AI article reports that logs capture individual requests, including visits from Googlebot and Bingbot, whereas other SEO tools may depend on samples, delayed reporting, or simulated crawls. It argues that this distinction is especially useful for sites with large URL inventories, where aggregate reports can conceal meaningful differences among directories, templates, and parameter combinations.

    Logs still have boundaries. A request does not prove that a URL was indexed, ranked, or considered valuable by a search engine. Log analysis is therefore strongest when combined with crawl data, indexation evidence, internal-link analysis, and business priorities.

    Key takeaways

    • Server logs record crawler requests received by the infrastructure rather than simulating crawler behavior.
    • Analysis should compare crawler attention with the site’s intended URL and page-section priorities.
    • Repeated requests to parameters, obsolete URLs, errors, or redirect paths can indicate crawl inefficiency.
    • Response status and timing help distinguish URL-management problems from infrastructure problems.
    • Retained historical logs support before-and-after analysis for migrations, redesigns, and platform changes.
    • Logs complement rather than replace Search Console, webmaster platforms, and technical crawlers.

    The technical SEO questions logs can answer

    QuestionEvidence to examinePossible decision
    Are priority pages being crawled?Requests grouped by page type, directory, or templateReview discovery paths, internal linking, or URL accessibility
    Where is crawler attention going instead?Requests for parameters, outdated structures, and low-priority URL groupsReduce unnecessary URL generation or tighten crawl controls where appropriate
    Are crawlers receiving unexpected responses?Status patterns, redirect paths, and repeated requests to failing URLsCorrect response handling, redirect logic, or broken destinations
    Is performance trouble isolated or persistent?Response timing segmented by URL group and observed over timeInvestigate affected templates, services, or infrastructure components
    Did a deployment change crawler behavior?Comparable periods before and after a migration, redesign, or infrastructure changeAddress new errors, lingering legacy requests, or reduced access to priority sections

    The source highlights a common large-site pattern: crawlers may spend requests on parameterized URLs while important product or category pages receive less attention. It also reports that obsolete URL structures can continue consuming crawl activity after a site has moved on operationally.

    These observations should be interpreted as patterns, not automatic diagnoses. Heavy crawling of a URL group may be intentional, temporary, or caused by references outside the system being reviewed. Likewise, low request frequency becomes actionable only after confirming that the affected pages are important and meant to be discoverable.

    A repeatable workflow for log analysis

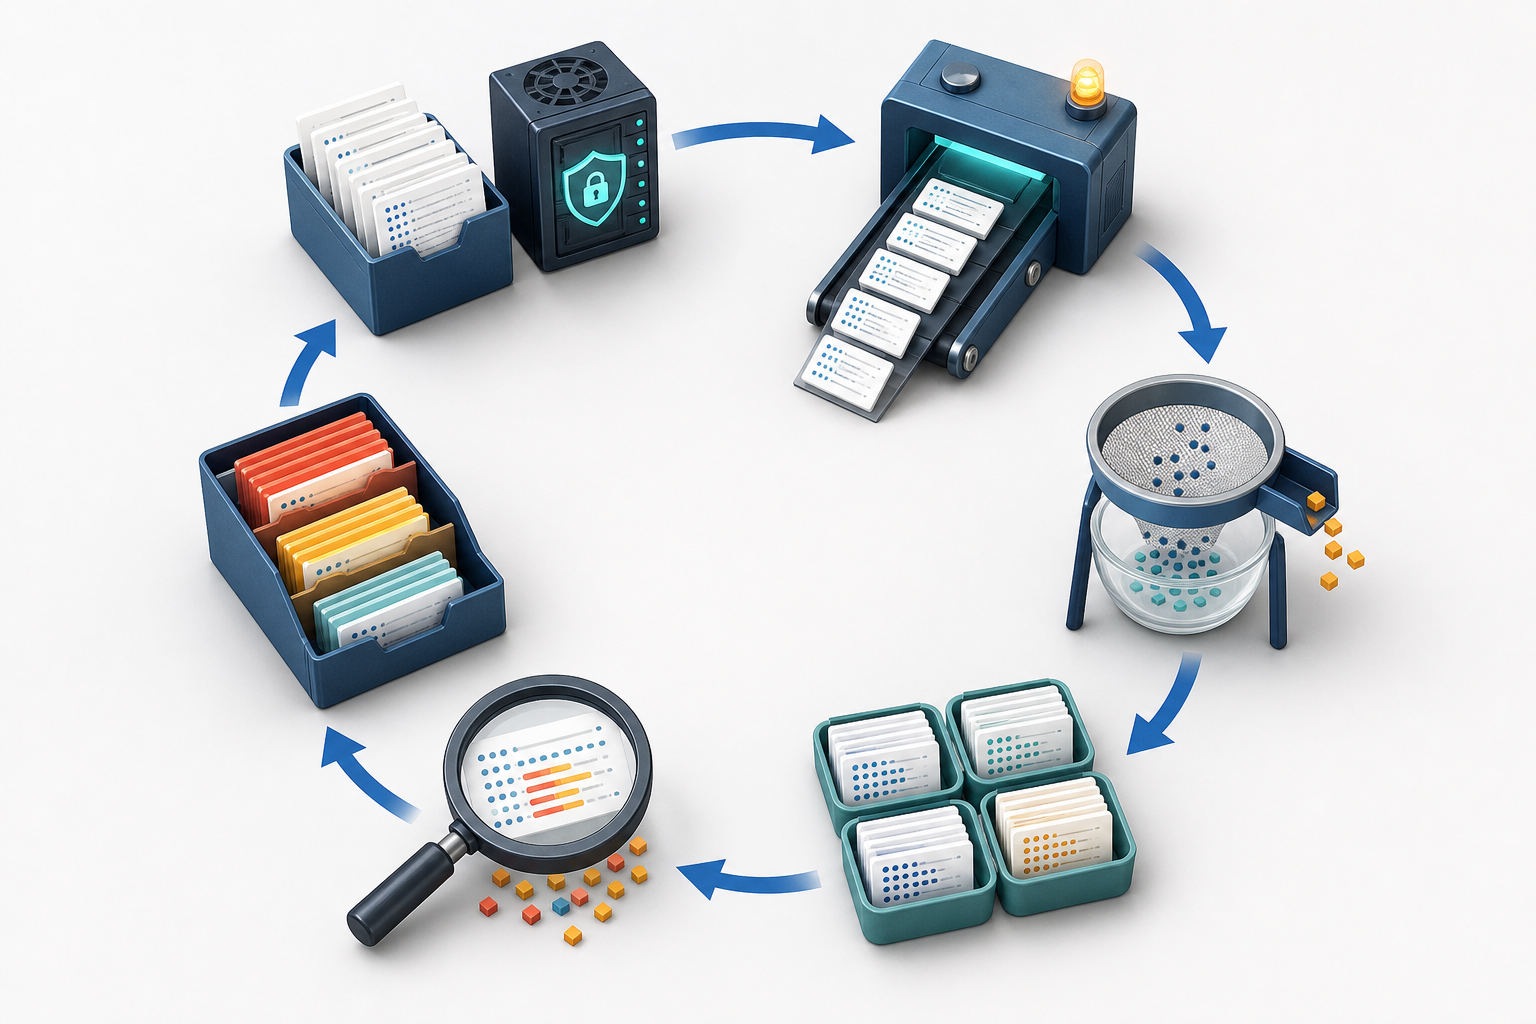
    Server files move through filtering, grouping, inspection, and prioritization stages arranged in a circular workflow.
    1. Define the decision first. Specify whether the analysis concerns crawl allocation, errors, redirects, server performance, a migration, or another technical question.
    2. Choose a representative time window. Preserve enough history to separate an isolated event from a recurring pattern and mark deployments or infrastructure changes that could affect interpretation.
    3. Prepare the required request fields. A useful dataset generally needs the requested path, request time, response status, user agent, and response timing when the logging configuration provides it.
    4. Identify legitimate crawler traffic. Do not assume that every request carrying a search-bot user agent is genuine; apply the organization’s bot-validation process before drawing conclusions.
    5. Normalize and group URLs. Separate meaningful page types from parameters, duplicate forms, obsolete paths, static resources, and other request classes so that high-volume noise does not dominate the analysis.
    6. Compare crawler behavior with site priorities. Examine whether commercially or editorially important sections receive attention while low-value or retired URL spaces consume requests.
    7. Segment response outcomes. Review successful responses, errors, redirects, and response timing by section or template rather than relying only on sitewide averages.
    8. Validate findings elsewhere. Reproduce suspected issues with a crawler or direct request, then compare them with Search Console, Bing Webmaster Tools, internal-link data, and infrastructure monitoring.
    9. Create a baseline. Retain comparable summaries so future releases, migrations, and redesigns can be evaluated against known crawler behavior.

    Turning log patterns into defensible priorities

    An analyst prioritizes website crawl issues while request paths show an overlooked page cluster, repeated loops, and broken routes.

    The most useful findings connect crawler behavior to a specific technical mechanism. Requests concentrated on unnecessary parameter combinations point toward URL generation or crawl-control decisions. Repeated visits to obsolete addresses suggest that old discovery paths or redirects still matter. Persistent errors or slow responses concentrated in one template point toward a narrower application or infrastructure investigation.

    Frequency and persistence help with prioritization. The supplied article notes that historical logs can distinguish temporary incidents from continuing infrastructure problems and can show crawler behavior before and after migrations. A recurring issue affecting an important section deserves different treatment from a short-lived anomaly with no continuing impact.

    Teams should also avoid treating crawl volume as a ranking metric. The defensible conclusion is that logs reveal access and response behavior; broader SEO evidence is still needed to explain indexation or search performance. Used this way, retained logs become an ongoing observability layer that can make the next deployment or migration easier to evaluate.

    References

  • Google Search Console Impression Correction: What to Do Next

    Google Search Console Impression Correction: What to Do Next

    If your Search Console impression line falls while clicks stay steady, don’t treat the chart as proof that your search visibility collapsed. Google confirmed that a logging error over-reported impressions from May 13, 2025 onward, so corrected reporting can produce a visible drop without removing any clicks you actually received.

    The right response is to audit the measurement before changing your SEO. You need to separate the reporting correction from any genuine performance movement, rebuild affected comparisons, and explain why impression-based ratios may change even when user behavior does not.

    What the correction changes and what it doesn’t

    The confirmed problem was impression logging inside Google Search Console. It was not a change to how many people clicked your results, and Google said clicks were unaffected by the error. As fixes were implemented, the Performance report could therefore show fewer impressions without showing a corresponding loss of clicks.

    That distinction matters because the metrics answer different questions. Impressions describe how often your result appeared in search results. Clicks describe visits initiated from those results. Conversions describe what visitors did afterward. A correction to the first metric does not retroactively remove the activity measured by the other two.

    Click-through rate needs special handling because it is calculated from both affected and unaffected values:

    • CTR equals clicks divided by impressions.
    • An inflated impression denominator makes CTR appear lower.
    • If corrected impressions decrease while clicks stay unchanged, CTR can rise automatically.
    • That mathematical increase does not prove that titles, descriptions, rankings, or search intent improved.

    The correction also isn’t a blanket explanation for every decline after May 13. A real SEO loss can occur during the same period as a reporting repair. Treat the bug as a measurement issue to test, not as a reason to dismiss contradictory evidence.

    Use three signals before diagnosing an SEO decline

    Three analytical instruments converge on a glass sphere, symbolizing the use of multiple signals before diagnosing a decline.

    Don’t respond to the impression chart in isolation. Run the following check with the same Search Console property, search type, date range, country, device, page, and query filters throughout. Changing a filter halfway through creates another explanation for the difference.

    1. Compare impressions and clicks on the same timeline. A sharp impression change accompanied by stable clicks is consistent with a reporting correction. If clicks also decline, the impression bug does not explain the entire movement.
    2. Check an independent outcome. Review organic landing-page sessions, leads, sales, or another meaningful conversion in your analytics system. These numbers do not have to match Search Console clicks exactly because the systems measure differently; you are looking for corroborating direction, not identical totals.
    3. Inspect where the change appears. A broad impression step across many pages and queries, with clicks remaining steady, fits a logging correction better than a decline concentrated in one directory, page type, country, device, or query group. A concentrated loss deserves a separate technical, content, or ranking investigation.

    Google described the correction as a rollout taking several weeks rather than a single instantaneous rewrite. That means you should not expect every affected chart or saved report to change at exactly the same moment. Multiple movements during the correction window may still be reporting-related, but stable clicks remain the most useful first check supplied by this incident.

    Hold off on reactive title rewrites, content deletions, internal-link changes, or technical deployments until this check identifies an independent problem. Those changes can introduce real performance movement and make an already messy reporting period harder to diagnose.

    Rebuild comparisons around the May 13 boundary

    An analyst reorganizes abstract data tiles into separate groups on either side of a glowing reporting boundary.

    May 13, 2025 is the important boundary. Impression data before that date was outside the confirmed error period. Impression data from that date onward was subject to over-reporting and subsequent correction.

    May 2025 is therefore not a clean monthly baseline: it contains days before the confirmed start and days after it. Any longer reporting period that crosses May 13 also blends data from two measurement conditions. A smooth monthly or quarterly chart can hide that break unless you annotate it.

    1. Add a visible annotation at May 13, 2025 in every dashboard that uses Search Console impressions or CTR.
    2. Preserve exports created before the correction. Label them as pre-correction snapshots rather than silently replacing them; the old files will not update themselves.
    3. Re-export affected date ranges from the current Performance report when you need a corrected analysis. Record the export date so another analyst can distinguish it from the earlier snapshot.
    4. Recalculate every derived metric that uses impressions, including CTR, impression growth, impression forecasts, and custom visibility indices.
    5. Prefer clicks and downstream conversions when an immediate business comparison is required, while still investigating any independent decline in those metrics.

    Do not invent a flat correction factor. No reliable percentage was supplied for subtracting the overcount, and there is no basis here for assuming that every property, page, query, or day was inflated by the same proportion. Re-exporting corrected records is safer than multiplying old exports by an estimated adjustment.

    Year-over-year reporting needs the same care. If one side of the comparison came from an inflated export and the other did not, the calculated growth rate is partly a measurement difference. Rebuild both sides from a consistent dataset before presenting the percentage as an SEO result.

    Fix dashboards, forecasts, and the stakeholder narrative

    The correction has different consequences for different reports. Update each one according to the metric it actually uses:

    • Impression dashboards: refresh affected ranges and retain a data-quality annotation.
    • CTR reports: recalculate the ratio after impression values are corrected, then avoid crediting the mechanical change to optimization work.
    • Click reports: keep using click totals, but investigate any genuine click movement on its own evidence.
    • Conversion reports: use them as an independent business check, while remembering that attribution rules can make them differ from Search Console clicks.
    • Forecasts: retrain or rebuild models that learned from inflated impressions. Otherwise, the model may set an unreachable impression baseline even if future search performance is healthy.

    Your explanation to clients or leadership should distinguish a reporting change from an outcome change. It should also avoid promising that every unfavorable number is caused by the bug. The following status note keeps those boundaries clear.

    Google confirmed that Search Console over-reported impressions from May 13, 2025 onward because of a logging error. Corrected reporting may reduce the displayed impression total, while clicks were not affected by this error. We are rebuilding impression and CTR comparisons and separately checking clicks and conversions for evidence of any real performance change.

    Suggested stakeholder status note

    That wording is more defensible than saying rankings definitely did not change. The correction proves that impression reporting was wrong; it does not prove that every site’s underlying search performance remained unchanged throughout the same period.

    Google Search Console impression correction FAQ

    Did my rankings drop when reported impressions fell?

    The impression decrease alone cannot answer that question. If the drop appears as corrected reporting while clicks and independent organic outcomes remain stable, there is no evidence in that chart alone of a ranking loss. If clicks, conversions, or a specific group of pages and queries also decline, investigate that movement separately.

    Can I compare CTR from before and after May 13?

    Only after confirming that both sides use consistently corrected impression data. Clicks may be accurate on both sides while the impression denominator is not, producing an apparent CTR change that reflects data repair rather than different searcher behavior. Re-export the affected period and recalculate the ratio before drawing a conclusion.

    Can I keep using an old Search Console export?

    Keep it for the audit trail, but label it clearly if it includes impressions from May 13, 2025 onward and was captured before the correction. Do not combine its impression values with corrected exports or use it as an unqualified forecasting baseline. Create a new export for current analysis and retain the export date with the file.

    When was the correction complete?

    Google’s notice did not provide a precise completion date. It said the fixes would be implemented over several weeks. Avoid selecting an unsupported end date for the anomaly; document when each report was exported and verify affected historical ranges again before finalizing a high-stakes comparison.

    Start with one report that crosses May 13. Annotate the boundary, place clicks beside impressions under identical filters, and relabel any earlier exports. Once the measurement history is clean, you can see whether anything remains that genuinely requires SEO work.

    References

  • How to Use AI Response Patterns to Build Better Content

    How to Use AI Response Patterns to Build Better Content

    You ask an AI assistant which product, service, or method it recommends. Your brand appears. You run the same prompt again, and it disappears. If you build a content brief around either answer, you may be optimizing for an accident.

    The better unit of analysis is the pattern across many answers. Repeated structures, concepts, comparisons, and entity associations can show you what a model consistently treats as relevant. Once you separate those durable signals from one-off wording, AI responses become useful inputs for content planning rather than volatile rankings to chase.

    Key takeaways

    • Do not treat one AI answer, citation, or brand mention as a ranking result.
    • Test several phrasings of the same intent across at least two model families and repeated runs.
    • Keep web-search settings, model labels, context, and prompts documented so you know what changed.
    • Classify recurring signals as structural, conceptual, or entity patterns before editing content.
    • Use a working threshold to filter noise, then apply audience knowledge and factual review before acting.

    A single AI answer is not a position you can rank for

    Traditional rank tracking works because a search result has an ordered position that can be checked again. An AI response is generated probabilistically. Its wording, selections, order, and level of detail can change with the prompt, conversation context, model, retrieval method, and search setting.

    The variation can be substantial. Across one large prompt test, ChatGPT or Google AI had a less than 1% chance of returning the same brand list in two responses. That does not mean every topic will be equally unstable. It does mean that a single inclusion or omission is too fragile to support a content decision.

    Separate two questions that teams often mix together:

    • Visibility question: Did the model mention or cite your brand in this sample?
    • Pattern question: Which ideas, criteria, entities, and answer structures kept returning across the sample?

    The first question produces a volatile observation. The second can reveal a usable content opportunity. If renewal pricing appears in most answers about choosing a domain registrar, for example, you have evidence that the concept belongs in the decision journey. You still do not know that adding a renewal-pricing section will cause a citation. You do know that omitting the issue may leave the page incomplete for that cluster of questions.

    This distinction also changes how you report results. A sentence such as “we rank in ChatGPT” claims a stable position that may not exist. A defensible statement is narrower: your brand appeared in a stated share of a documented response sample, under specified test conditions. For content planning, the recurring concepts and associations in that sample are usually more actionable than the mention count alone.

    Build a response sample that can separate signal from noise

    Many abstract response tiles pass through a mesh filter, leaving repeated shapes grouped together while irregular fragments fade away.

    You do not need an expensive monitoring platform to begin. You do need a repeatable collection method. A spreadsheet is enough if every row records the conditions that could explain a different answer.

    1. Choose a small set of decision topics. Start with three commercially or editorially important topics. A topic should represent a decision or task your audience actually brings to an AI assistant, not just a keyword you want to rank for.
    2. Create three to five prompt variations per topic. Keep the underlying intent stable while changing the wording. A domain-registration cluster might include “How do I register a domain name?”, “How can I get a domain name?”, and “Where can I buy a domain?” Do not mix an introductory how-to prompt with a migration or troubleshooting prompt and call them one cluster.
    3. Define the test conditions. Select at least two model families. Decide whether web search will be enabled, disabled, or left to the model. If you test more than one search condition, analyze each as a separate segment. Use fresh or private sessions where possible so an earlier conversation does not silently alter the next response.
    4. Capture every response consistently. Record the prompt, displayed model or version, web-search status, date, full response, cited URLs, brand mentions, and any initial pattern labels. Preserve the complete answer; excerpts can hide section order and qualification.
    5. Repeat on a fixed cadence. Weekly collection is practical for many teams. Consistency matters more than running a large burst once and then changing the prompt set. Build toward 20 to 30 responses per prompt before drawing strong conclusions.

    Your tracking sheet can start with these columns:

    • Topic cluster
    • Exact prompt
    • Model and displayed version
    • Web search: enabled, disabled, or model-decided
    • Date
    • Full response
    • Citations or referenced URLs
    • Your brand mentioned: yes or no
    • Structural labels
    • Concept labels
    • Entity and association labels

    Do not pool unlike conditions without labeling them. A response produced with live web retrieval is not equivalent to one generated without it. A model update can also change the output even when your site and prompt remain untouched. Recording those conditions protects you from crediting your content for a change caused elsewhere.

    A useful working definition of a strong pattern is one that appears in at least 75% of the sampled outputs, across two models and multiple prompt variations. The threshold is a filter, not a law of AI behavior. It forces you to demand recurrence in more than one environment before calling an observation meaningful.

    Always retain the numerator and denominator. “Pricing transparency appeared in 9 of 12 responses” is auditable. “AI cares about transparent pricing” turns a bounded observation into an unsupported universal claim. If you work alone and cannot collect a full sample, you can flag patterns beginning around 60% as provisional, but keep them separate from patterns that clear the stronger threshold. A smaller workload should reduce your confidence, not disappear from the methodology.

    Read each response pattern at three different layers

    Three concentric transparent layers organize surface shapes, connected concepts, and generic objects around a central subject.

    Frequency alone does not tell you what to change. First classify what is recurring. Structural, conceptual, and entity patterns answer different editorial questions and lead to different actions.

    Pattern layerWhat you recordWhat it can changeCommon misreading
    StructuralSection order, lists, steps, comparisons, pros and cons, tables, and depthAnswer architecture and information sequenceCopying the model’s format as if it were a required template
    ConceptualRecurring criteria, risks, questions, features, and tradeoffsTopic coverage and explanation depthTreating every repeated phrase as a keyword to insert
    EntityBrands, products, tools, sources, categories, and feature associationsPositioning, evidence, comparisons, and partnership researchAssuming an omission proves a technical or reputation problem

    Structural patterns reveal the expected path through an answer

    Mark how each response is assembled. Does it begin with a definition, move into selection criteria, name tools, and end with implementation? Does it repeatedly use a comparison table? Does it frame the decision through advantages and disadvantages, or as a numbered procedure?

    If the sequence “definition > criteria > tools > implementation” persists across prompts and models, it is a clue that the topic is commonly synthesized as both an explanation and a decision process. Your page may need to support both. That does not require copying the sequence mechanically. A reader who already understands the category may need the criteria first, while a beginner may need a short definition before making sense of those criteria.

    Record the level of detail as well as the headings. A recurring step that receives several qualifications is more informative than a heading that appears but gets one sentence. The useful editorial question is not merely “Was this topic mentioned?” It is “What role did this topic play in helping the response reach a recommendation or action?”

    Conceptual patterns identify the criteria a page must handle

    Concepts are the recurring considerations inside the answer. For a domain-registrar decision, those may include initial and renewal pricing, customer support, privacy, email add-ons, security, bundles, and transfer procedures. A concept that returns across differently phrased prompts is more useful than an exact phrase repeated by one model.

    Turn each recurring concept into a question for the content, not an instruction to add a keyword. If renewal pricing is a strong pattern, ask:

    • Does the page distinguish the introductory price from the renewal price?
    • Can the reader locate that information without interpreting vague pricing language?
    • Does the comparison use equivalent billing periods and inclusions?
    • Are exceptions or conditions stated where they affect the decision?

    This approach improves usefulness even if the wording in future AI responses changes. It also prevents superficial optimization. Repeating “pricing transparency” does not make pricing transparent; showing the relevant terms clearly does.

    Entity patterns show how the category is being framed

    Entity analysis tracks more than which brands appear. Record which features, audiences, or use cases are attached to each entity, where the entity appears in the answer, and which pages are cited in support.

    Suppose a competitor repeatedly appears beside “simple transfers” while your brand appears beside “bundled services.” That pattern does not establish either claim as true. It does reveal the associations you should verify. Check whether your product documentation, comparison pages, and third-party coverage make the relevant capabilities explicit. If the association is inaccurate, the answer is not to imitate it. Clarify your actual positioning with evidence.

    An absent brand can have several explanations: model variability, an unfamiliar prompt, retrieval choices, weak category association, insufficient supporting content, or no factual fit for the recommendation. The response sample cannot diagnose the cause on its own. Use it to form a question, then inspect your content and real market position before choosing a remedy.

    Convert the pattern map into a content brief

    Once the sample is labeled, do not hand the raw answers to a writer and ask for an average version. That tends to reproduce generic phrasing and whatever biases already dominate the outputs. Convert the recurring signals into editorial requirements that leave room for expertise, original evidence, and a clear point of view.

    1. Name the reader’s decision. Write one sentence describing what the page must help the reader decide or complete. If your prompt variations contain different decisions, split the cluster before drafting.
    2. Write the direct answer first. State the useful answer in plain language before designing headings. This keeps a recurring AI structure from displacing the reader’s actual need.
    3. Select the structural pattern that supports that decision. Use a procedure for a task, a criteria-led structure for a purchase decision, or a comparison only when the underlying options are genuinely comparable.
    4. Translate strong concepts into coverage requirements. Record the observed frequency and the question each concept must answer. Specify required depth, such as a definition, caveat, example, or decision rule.
    5. Audit entity claims. List the brands, tools, features, and category relationships that require verification. Decide which claims need first-party documentation and which need credible independent support.
    6. Define what the page will not cover. Exclude concepts that belong to another intent or page. A recurring term is not permission to turn one focused answer into an unfocused topic warehouse.

    A practical response-pattern brief should contain these fields:

    • Reader and decision: who the page serves and what they must be able to do afterward.
    • Prompt cluster: the exact variations used to collect the sample.
    • Test conditions: models, versions, search settings, dates, and number of responses.
    • Direct answer: the page’s concise answer to the shared intent.
    • Strong structural patterns: recurring answer sequences and formats, with counts.
    • Strong conceptual patterns: required considerations, with counts and planned treatment.
    • Provisional patterns: useful leads that need more sampling or independent audience evidence.
    • Entity associations: repeated brand-feature or tool-use-case pairings that require verification.
    • Evidence plan: where facts, prices, limitations, and comparisons will be substantiated.
    • Exclusions: adjacent intents that belong on another page.

    Then run a simple editorial test on every proposed section. Can you trace it to a strong response pattern, direct audience evidence, necessary factual context, or the page’s stated decision? If not, remove it. For every strong concept, confirm that the draft answers the underlying question rather than merely using the model’s preferred vocabulary.

    The finished page should also add value that pattern analysis cannot supply. That may be a clearer decision rule, documented limitations, precise product information, a transparent comparison method, or an explanation of when the common recommendation does not apply. AI responses can expose the recurring frame. They should not set the ceiling for the content.

    Measure batches, not anecdotes, after you publish

    Preserve a baseline response batch before making a substantial update. After the revised page is available, repeat the same prompt set under comparable conditions. Keep the old and new batches separate, and document any model or search-mode change between them.

    Track a small group of interpretable measures:

    • Pattern persistence: which structural, conceptual, and entity patterns remain strong across later batches.
    • Concept coverage: whether the target page now answers each relevant strong concept accurately and at the required depth.
    • Brand mention rate: the number of sampled responses mentioning the brand divided by the total responses in that segment.
    • Association quality: whether the context around the brand is accurate, relevant, and aligned with its actual offer.
    • Citation behavior: whether the page is cited, what claim it supports, and whether the cited source is appropriate.
    • Page performance: whether conventional search visibility, qualified visits, engagement, and conversions move in a useful direction for the page’s purpose.

    Do not treat movement in a small AI sample as proof that your edit caused it. Models may draw from training data, live search, or a combination that is not obvious to the tester. Their behavior can also change after a new model release. A before-and-after batch gives you a better observation, not automatic causality.

    Use three decision rules to keep the program disciplined:

    • Act: A pattern clears your strong threshold across models and prompts, matches the reader’s decision, and can be addressed truthfully.
    • Investigate: A provisional pattern is strategically important but needs a larger sample, audience validation, or factual checking.
    • Ignore for now: A detail appears in isolated responses, depends on one model or wording, conflicts with reliable facts, or does not help the target reader.

    Watch for the feedback loop that makes every page look like an existing AI answer. Training-data bias, retrieval uncertainty, factual errors, and dominant category conventions can all recur. Repetition proves that a pattern exists in your sample; it does not prove that the pattern is correct, fair, current, or useful. Human review is the step that turns recurrence into an editorial decision.

    Choose one important prompt cluster for your next brief. Freeze the variations and test conditions, collect the first documented batch, and label the three pattern layers before changing the page. The question to carry into the edit is not “What did the AI say?” It is “What persisted, under which conditions, and what does our reader genuinely need from us?”

    References


  • Multifamily Investing in Volatile Markets: A Risk Framework

    Multifamily Investing in Volatile Markets: A Risk Framework

    You are not really deciding whether multifamily is a good investment during volatility. You are deciding whether one property’s current cash flow, debt structure, reserves, and operator can withstand conditions that are less favorable than the sales presentation assumes.

    That distinction matters. A lower purchase price can arrive with more expensive financing, uncertain valuations, or a business plan that leaves no room for delay. Use the framework below to identify what must go right, what can go wrong, and which evidence you need before putting capital at risk.

    Start with the four risks hidden inside one deal

    Market volatility is often discussed as though it were a single risk. It is not. A multifamily investment combines at least four separate bets:

    • Market risk: Will enough households want and be able to rent in this location?
    • Property risk: Can the building maintain occupancy, collect rent, control expenses, and avoid unexpected capital needs?
    • Financing risk: Can the property service its debt through the intended holding period without depending on a favorable refinancing market?
    • Execution risk: Can the operator deliver renovations, leasing, collections, maintenance, and reporting on schedule?

    A deal can look inexpensive on one dimension and remain fragile on another. A discounted property is not necessarily a bargain if its loan matures before the operating plan can produce stable income. Strong population growth does not repair a renovation budget built on incomplete bids. An experienced sponsor does not make an aggressive exit assumption conservative.

    Evaluate those four risks separately before you consider the projected return. Write one sentence for each: what must be true, what evidence supports it, and what happens if it is wrong. If you cannot complete those sentences without repeating language from the pitch deck, you do not yet understand the investment.

    This is especially important for passive investors. A private multifamily interest can be illiquid, distributions can be reduced or suspended, and governing documents may permit capital calls or other actions with financial consequences. Have a qualified securities or real estate attorney review the legal documents, and use a tax professional for consequences specific to your situation. Neither a preferred return nor a target holding period is a guarantee.

    Choose markets for durable demand, not a convincing growth story

    Your first market question should not be, “Where will rents rise fastest?” Ask, “What keeps renters here when conditions weaken?” The answer needs to rest on observable demand rather than hoped-for appreciation.

    Ivan Barratt’s market-selection thesis favors secondary and tertiary Midwest markets because economic diversity, steadier growth, and lower institutional competition may reduce dependence on speculative appreciation. That is a hypothesis to test at the local level, not a rule that makes every Midwest property defensive. A market label cannot tell you whether one submarket is gaining households, adding too much supply, or relying heavily on one employer.

    Build a market screen with evidence for each of these questions:

    • Demand: Are population and household trends supporting the number and type of units in the business plan? Household formation matters more than a broad claim that the region is growing.
    • Employment diversity: Which industries and employers support local renters? Flag a market where one employer, facility, or cyclical industry accounts for too much of the demand story.
    • New supply: How many competing units are operating, under construction, or planned near the property? Separate signed leases and completed units from speculative announcements, but do not ignore projects merely because they have not opened.
    • Rent affordability: Does the proposed rent leave room in the target household’s budget, or does the business plan require residents to absorb increases faster than their incomes?
    • Competitive position: Which properties are genuine alternatives for the same renter? Compare unit size, condition, concessions, parking, utilities, amenities, and location rather than relying on a blended market average.
    • Recurring ownership costs: How could taxes, insurance, utilities, payroll, repairs, and regulatory requirements change the property’s expense base?
    • Exit liquidity: Who is likely to buy this property later, and what financing would that buyer need? A market with less acquisition competition may offer a better entry opportunity, but it may also have a smaller buyer pool at exit.

    Local brokers can help you understand seller expectations, buyer activity, and neighborhood-level conditions. Longstanding broker relationships may also improve deal flow in markets with fewer institutional participants. But a broker’s local knowledge and confidence in a buyer’s ability to close are not substitutes for operating records, independent property inspections, or documented market data.

    Mark every market factor green, yellow, or red. Green means the claim is supported by current, property-relevant evidence. Yellow means it is plausible but incomplete. Red means the available evidence contradicts the business plan. Do not average the colors into a comforting score. A red flag tied to renter demand, new supply, or refinancing can be fatal even when several secondary factors look attractive.

    Rebuild the underwriting around failure points

    An apartment building model sits on a table beside blank tokens, an unmarked balance scale, empty unit pieces, and an unfinished construction section.

    A projected internal rate of return is an output, not evidence. It can change materially when the timing of distributions, refinancing, sale proceeds, or capital spending changes. Begin with the operating inputs that create the return and test whether each one is supported.

    Underwriting lineEvidence to requestDownside question
    Starting revenueCurrent rent roll, recent collections, concessions, delinquency, bad debt, and other incomeDoes the model use billed rent where collected rent would be more realistic?
    Rent growthRecent new leases, renewals, comparable properties, and planned competing supplyCan the deal operate if rent growth pauses?
    OccupancyPhysical occupancy, economic occupancy, unit status, notices, and turnover historyWhat happens if vacant units take longer to lease or require concessions?
    Operating expensesTrailing property statements, current contracts, tax information, insurance terms, payroll, utilities, and repair historyWhich costs are assumed to decline, and who has proved that reduction is achievable?
    RenovationsUnit-by-unit scope, vendor bids, completed-unit results, downtime, and contingency reservesWhat happens if costs rise, work slows, or renovated units fail to earn the projected premium?
    DebtRate type, maturity, amortization, extension conditions, covenants, reserves, and any rate protectionCan the property hold through maturity without a favorable refinance?
    Exit valueProjected net operating income, sale costs, timing, and exit capitalization-rate assumptionDoes the return still work without valuation improvement?

    Reconcile the model to actual operations. Net operating income is property revenue minus operating expenses before debt service and major capital expenditures. Debt-service coverage is net operating income divided by debt service. These calculations are simple, but inconsistent definitions can make comparisons misleading. Confirm which income and expenses the model includes before accepting the resulting ratio.

    You can also estimate break-even occupancy from the property’s own assumptions: add operating expenses and debt service, subtract non-rent income, and divide the result by gross potential rent. The output is only as reliable as the inputs. Use collected revenue, realistic concessions, and complete expenses rather than the cleanest figures available.

    Run at least three logically distinct cases:

    • Sponsor case: Reproduce the operator’s assumptions exactly so you know what the marketed return requires.
    • Current-operations case: Hold rent, occupancy, concessions, collections, and expenses close to documented recent performance. This shows whether the existing property can support the capital structure before improvements arrive.
    • Downside case: Delay renovations and lease-up, weaken collections or occupancy, increase relevant costs, and remove any assumption that a favorable refinancing or stronger valuation will rescue the deal.

    The point is not to select a dramatic worst-case scenario. It is to find the first operational or financial threshold that causes trouble. Does cash flow stop covering debt? Does an extension condition become difficult to satisfy? Are reserves exhausted before renovations finish? Would the operator need to suspend distributions, sell early, or request more capital?

    Ask for the sensitivity model in an editable form when possible. Change one assumption at a time before combining stresses. That lets you see whether the deal is mainly exposed to rent growth, vacancy, expenses, renovation timing, financing, or exit value. If a modest change in one assumption destroys the economics, the investment has less margin for error than its headline return implies.

    Test the operator’s execution system, not just its track record

    A property operations team inspects utility equipment and organized maintenance supplies inside an apartment building service area.

    A multifamily business plan becomes a sequence of ordinary operating tasks after closing: answer leads, lease units, collect rent, turn apartments, complete repairs, manage vendors, retain residents, and control spending. Returns depend on whether those tasks happen consistently.

    Vertical integration can give an owner more direct control over management, renovations, leasing, and expenses. Some vertically integrated operators therefore argue that execution can influence results more than acquisition pricing. The structure can improve alignment and speed, but the label proves nothing by itself. It can also concentrate responsibility inside affiliated companies that investors must evaluate.

    Whether management is internal or third-party, ask the same operational questions:

    • Who is accountable for property-level results, and how many properties or units are under that person’s supervision?
    • How quickly does management produce monthly financial statements and variance reports?
    • Which operating indicators are reviewed weekly? Useful indicators include leads, tours, applications, approvals, signed leases, renewals, notices, delinquency, collections, vacant-unit status, work orders, and renovation progress.
    • Who can change rents, concessions, staffing, vendor contracts, or renovation scope when results miss the plan?
    • How are related-party management, construction, acquisition, financing, or disposition fees disclosed and approved?
    • Can the operator show original underwriting beside actual results for completed and active properties?
    • What decision did the team make when a prior property missed its plan, and how quickly did it act?

    Track-record numbers need context. Separate realized results from projections, and request the full population of relevant deals rather than a few selected successes. For each property, compare the original rent, expense, renovation, financing, hold-period, and exit assumptions with what occurred. A good outcome produced by unexpectedly favorable valuation is different from a good outcome produced by better operations.

    Then inspect alignment. Determine how much capital the sponsor contributes, when fees are paid, how cash is distributed, who controls a sale or refinancing, and whether affiliates earn revenue even when investors do not receive distributions. A preferred return establishes an order or hurdle within the distribution structure; it does not guarantee that the property will generate enough cash to pay it.

    Lender and broker relationships can make an operator more credible as a buyer and improve its ability to close. Those relationships have real transaction value. They still do not answer the investor’s central question: can this asset perform under its actual debt terms after the closing?

    Make a pass, wait, or walk-away decision

    Do not force every reviewed opportunity into a yes-or-no investment decision. Use three statuses that reflect the quality of the evidence:

    • Pass to full diligence: Current operations can support the financing, the market thesis is documented, the downside case preserves workable options, and the operator has demonstrated the required execution capabilities. This means continue investigating, not commit automatically.
    • Wait for evidence: The thesis may be sound, but material documents or explanations are missing. List each missing item, assign it to a risk, and pause until you receive an adequate answer.
    • Walk away: The return depends on speculative appreciation, an unsupported refinance, unusually smooth execution, or assumptions that conflict with property records. Also leave when the operator restricts reasonable access to the documents needed to verify the deal.

    Missing information is not neutral. If you cannot verify collections, debt conditions, insurance, taxes, renovation costs, or related-party fees, do not silently substitute the sponsor’s most favorable assumption. Mark the risk unresolved. The safe alternative is to delay the decision or decline the opportunity.

    Key takeaways

    • Evaluate market, property, financing, and execution risk separately before looking at the projected return.
    • Treat geographic strategies as hypotheses. Test demand, employment diversity, new supply, affordability, recurring costs, and exit liquidity at the submarket level.
    • Reconcile underwriting to collected revenue and complete expenses, then locate the first threshold that creates a covenant, liquidity, or capital problem.
    • Judge vertical integration by reporting quality, decision rights, staffing, controls, and actual-versus-underwritten results.
    • Advance only when the deal can survive without depending on favorable appreciation, refinancing, or perfect execution.

    Before your next sponsor call, create a one-page decision memo. Write the investment thesis in one sentence, list the three facts that must remain true, identify the three most likely ways the plan could fail, and attach the evidence supporting each conclusion. Any blank space becomes your diligence agenda. If the answers do not close those gaps, you have your decision.

    References