Tag: Amazon Alexa

  • Amazon Alexa Listing Optimization: A Practical Framework

    Amazon Alexa Listing Optimization: A Practical Framework

    Your Amazon listing can be easy for a person to read and still be difficult for a shopping assistant to use. A shopper may describe a device, material constraint, room, task, recipient, or problem without using your primary keyword. If the deciding fact is missing, buried, or contradicted elsewhere, your listing gives Alexa weak evidence for a confident match.

    Alexa optimization starts with answerability. Your job is to turn verified product facts into clear, structured, consistent answers, then test whether those answers improve discovery without attracting shoppers the product cannot satisfy.

    Optimize the buying decision, not an imagined Alexa formula

    The platform context has changed: Alexa for Shopping has replaced Rufus as Amazon’s default AI assistant. That makes conversational product discovery an important optimization surface. It does not make an unverified ranking-factor checklist reliable.

    The Amazon catalog record is the asset you control. Improve it around the sequence a shopper follows when narrowing a purchase:

    • Relevance: Is this the right type of product for the need expressed in the request?
    • Qualification: Does it meet the shopper’s compatibility, size, material, care, capacity, or use-case constraints?
    • Choice: What verified difference gives the shopper a reason to choose it over another eligible option?

    This distinction matters because broad visibility is not automatically useful visibility. Vague claims may make a product sound suitable for more situations, but they also increase the risk of a poor match. Optimize to become the right answer to a defined need, not merely an answer that can be mentioned.

    Keywords still help label the product. They are not the whole task. A phrase such as portable fan identifies a category, while a request such as a fan that fits on a narrow desk and runs from a particular power source introduces conditions. Your listing needs accurate facts that resolve those conditions. Repeating the category phrase cannot do that work.

    Build a query-to-attribute map for one ASIN
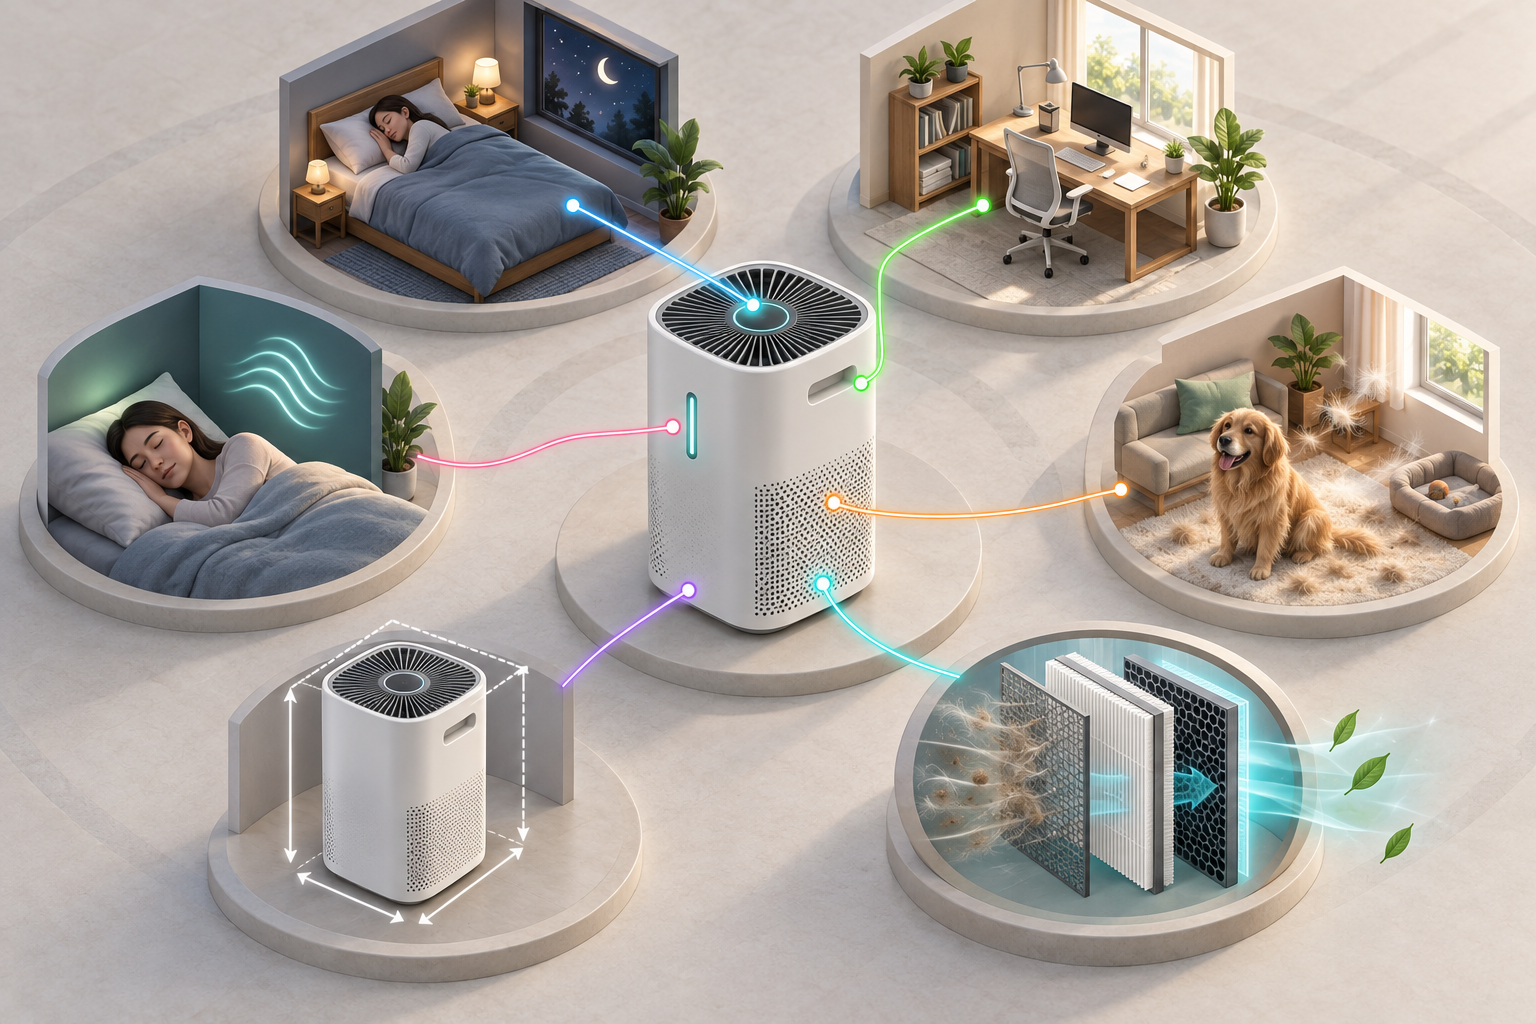
    A central air purifier is connected by colored paths to visual scenes representing room, pet, filtration, size, office, and quiet-use needs.

    Start with one Amazon Standard Identification Number rather than rewriting an entire catalog. Gather recurring language from customer questions, service tickets, reviews, return reasons, and search-term records you already use. Do not copy customer claims into the listing. Use the language to identify decisions that the current listing may leave unresolved.

    Turn each important question into a row in a query-to-attribute map. The map connects what a shopper asks to the exact product fact that should answer it.

    IntentTypical shopper questionEvidence the listing needsCommon failure
    CompatibilityDoes it work with a particular model or system?Exact supported identifiers, required conditions, and known exclusionsBroad compatible wording with no model boundary
    Use caseCan I use it for a particular task or environment?An explicit supported use and any relevant limitationA feature is named, but its practical use is left for the shopper to infer
    Dimensions or capacityWill it fit or hold what I need?Exact measurement, unit, and variant-specific valueThe value appears only in an image or differs between fields
    Material or careWhat is it made from, and how is it maintained?Precise materials and care instructions for the affected componentsAn umbrella term hides component-level differences
    Included itemsWhat arrives in the package?A clear distinction between included, optional, and merely compatible itemsAccessories shown or mentioned appear to be included
    Audience or constraintIs it suitable for a particular user or requirement?Verified suitability criteria and an honest boundarySuitability is inferred from marketing language rather than supported by a product fact

    Prioritize questions whose answers can change the purchase or prevent the wrong purchase. A color preference may matter, but an incompatible connector, incorrect dimension, missing accessory, or unsupported environment can make the product unusable. Those decisive facts deserve the clearest fields and the most visible copy.

    For each row, write one canonical answer before editing Amazon. A compatibility answer might follow this pattern: [product and variant] is compatible with [verified models] when [required condition]. It does not support or include [important boundary]. The placeholders force you to separate an actual product fact from a phrase that merely sounds persuasive.

    You do not need to insert every possible spoken variation into the visible listing. Establish the fact in plain language, then add natural synonyms only where they remove a genuine vocabulary gap. Repetition without new meaning makes the copy harder to scan and does nothing to resolve an unanswered constraint.

    Put each product fact in the field best suited to it

    A strong Alexa-oriented listing is not one long block of optimized prose. It is a coordinated catalog record. Structured attributes hold precise values. The title establishes identity. Bullets resolve major decisions. Longer content supplies context. Search-term fields cover relevant language that would be awkward in visible copy.

    Complete structured attributes before polishing prose

    Fill every applicable product-detail field with the verified value for that exact variant. Depending on the product, this may include product type, material, dimensions, capacity, color, model, power requirements, care instructions, compatibility, or included components.

    Do not force a value into an attribute that does not apply, and do not guess when product documentation is unclear. An incomplete record can be corrected after the fact is verified. An invented value can mislead the shopper, increase returns, and create a conflict that spreads across the listing.

    Keep the title focused on product identity

    The title should let a shopper identify the item and its defining variant without decoding a chain of claims. Include the product type and the details required to distinguish the purchasable item. Do not turn the title into a compressed FAQ or repeat near-identical phrases in the hope of covering more requests.

    If a term changes what the product is, it may belong in the title. If it explains when, why, or how the product is useful, it usually belongs in a bullet, attribute, or longer description. That division keeps identity separate from persuasion.

    Give every bullet a decision to resolve

    Assign each bullet to a high-priority row from the query-to-attribute map. A useful construction is: verified property, practical consequence, then boundary. For example: [component] measures [verified dimension], which allows [supported use]; it does not fit [known exclusion].

    The boundary is often the most useful part. Words such as premium, versatile, convenient, and advanced leave the assistant and the shopper to infer meaning. A measurement, named material, supported model, care requirement, or package-content statement answers a question.

    Use longer content for context and distinctions

    Use the description and any available enhanced content to explain scenarios that need more than a compact bullet. Show how related features work together, distinguish similar variants, and clarify setup or care where that affects suitability. Keep purchase-blocking facts in attributes or bullets as well; do not hide an exclusion deep in promotional copy.

    Where Seller Central provides non-visible search-term fields, use them for accurate synonyms and alternative language omitted from the visible copy. These fields can broaden vocabulary coverage, but they cannot repair a missing specification or make an unsupported claim true.

    Make every variant tell the same product truth
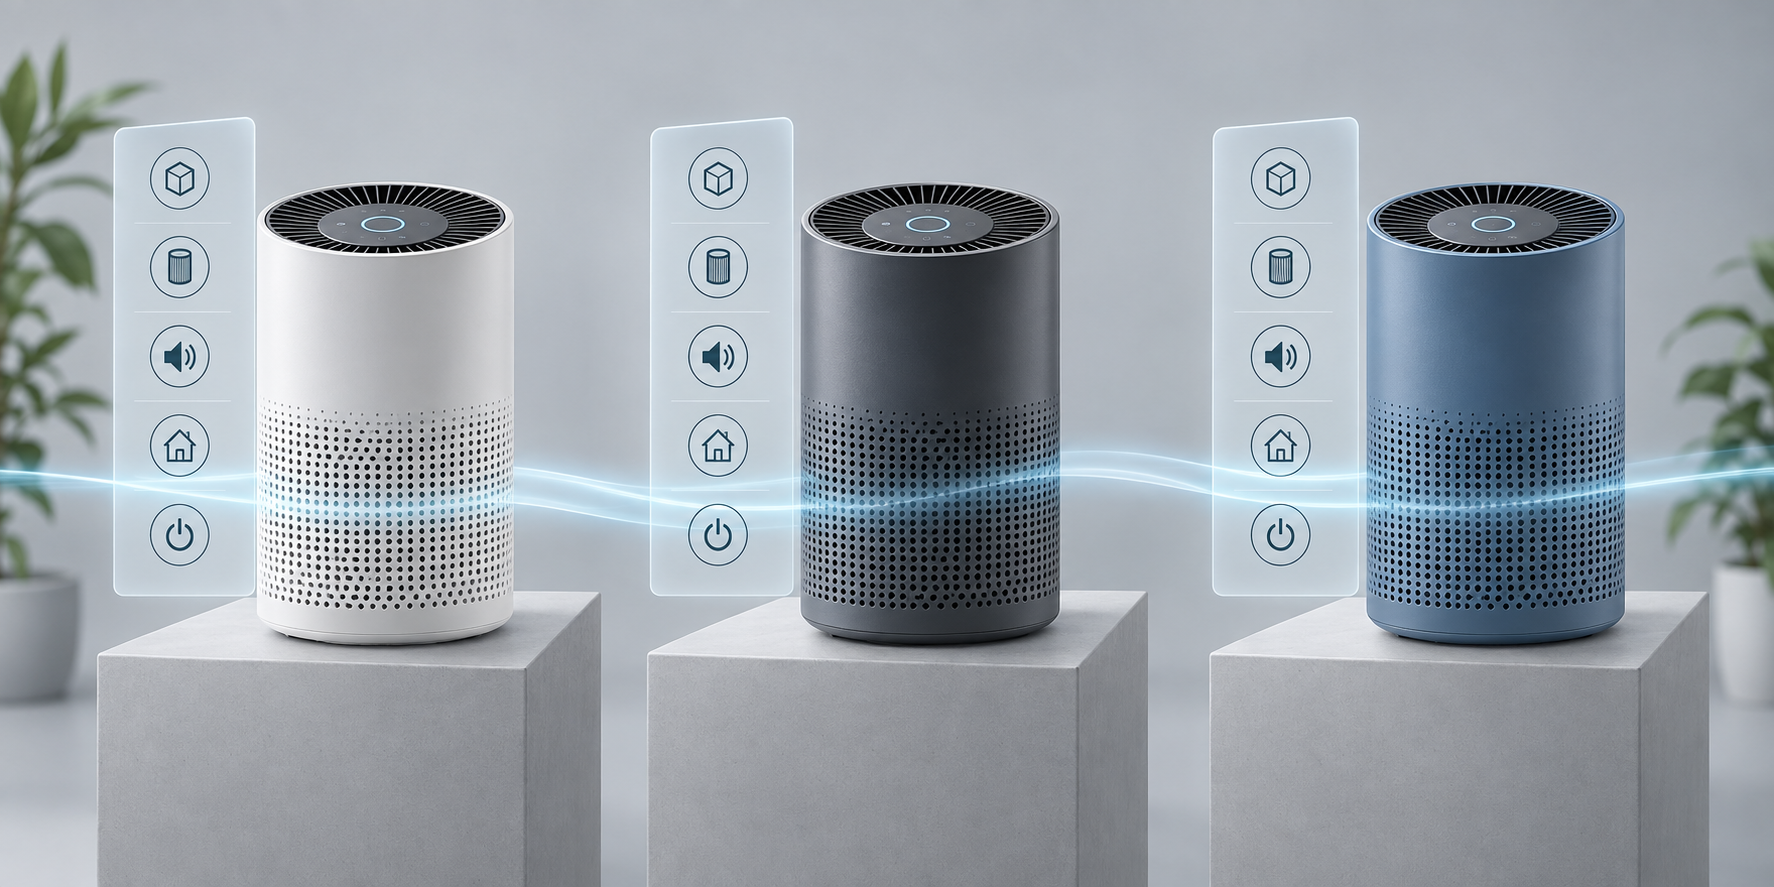
    Three color variants of the same air purifier display identical features and matching icon-based product information.

    An assistant-ready listing needs internal agreement. When the title, attributes, bullets, images, and variant labels disagree, no amount of elegant wording tells a dependable story. Resolve the underlying value before deciding which phrase sounds best.

    Run a field-by-field consistency audit:

    • Confirm that measurements, units, materials, model names, and package quantities agree wherever they appear.
    • Check each purchasable variant independently. A size, capacity, color, accessory, or capability belonging to one child item must not appear to apply to every child item.
    • Separate included items from products that are merely compatible, optional, or shown for context.
    • Qualify compatibility and suitability claims with the conditions that make them true.
    • Make sure synonyms preserve the same meaning. Related terms are not interchangeable when they describe different materials, product types, or technical standards.
    • Compare text embedded in images with the current catalog values. Old creative can preserve a contradiction after the written listing has been corrected.

    The parent-child relationship deserves special attention. Shared copy is efficient, but it can quietly transfer a fact from one variant to another. Treat each purchasable option as its own truth set, then share only claims that are genuinely common to the family.

    Keep a simple claim ledger outside Amazon. For each important claim, record the canonical value, the variants it covers, the evidence that supports it, and every field where it appears. When product specifications or packaging change, the ledger shows what must be updated. It also prevents one team from correcting a bullet while another republishes an outdated image or description.

    Do not use Alexa optimization as a reason to stretch a claim beyond your product documentation. The likely downside is not limited to an inaccurate answer. It can include unqualified traffic, avoidable returns, support costs, and disappointed customers. The safe alternative is to state the verified boundary clearly and optimize for shoppers whose requirements the product actually meets.

    Test assistant visibility without confusing observation with proof

    You cannot safely infer a secret ranking weight from one response. Assistant output can vary, and competing listings can change independently of your edits. Use a controlled observation process to determine whether a clearer catalog record produces a repeatable, useful direction.

    1. Create a fixed prompt set. Cover category discovery, a supported use case, a decisive constraint, compatibility, and an exclusion. Include unbranded requests so you are testing discovery rather than simple brand recall.
    2. Record a baseline. Save the exact prompt wording, marketplace, relevant account or device context, listing version, and what happened. Note whether the product appeared and whether important facts were described accurately.
    3. Change one fact cluster. Correct a related group such as compatibility, dimensions, materials, or package contents. Avoid rewriting every field at once, because a broad rewrite makes the cause of any change impossible to interpret.
    4. Wait until the listing edit is live, then repeat the same prompts. Keep the wording and testing context stable. Repeat observations rather than treating one appearance or disappearance as a verdict.
    5. Check commercial quality as well as visibility. Use the business metrics you already trust to see whether the change attracts qualified shoppers. More exposure accompanied by weaker conversion, more confusion, or more returns can indicate that the listing became broader without becoming more accurate.

    Label failures by type. A product may not be surfaced, may be surfaced for the wrong need, may appear with a deciding attribute omitted, or may be described with an incorrect value. Those failures require different responses. Missing visibility may justify broader relevant language. An omitted fact may point to poor placement. A wrong fact should trigger a consistency check before you add more copy.

    If your listing is consistent but Alexa still states a fact incorrectly, log the observation and keep the catalog truth intact. Distorting the listing to imitate an erroneous answer creates a second problem instead of solving the first.

    Judge the edit across the whole prompt group. A useful change improves matching for supported needs, preserves important exclusions, and does not degrade shopper quality. That is stronger evidence than an isolated change in apparent placement.

    Key takeaways for Amazon Alexa listing optimization

    • Optimize the relationship between a shopper’s question and a verified product fact, not keyword repetition alone.
    • Prioritize compatibility, dimensions, included items, and other constraints that can determine whether a purchase succeeds.
    • Correct structured attributes and variant data before polishing persuasive copy.
    • Use titles for identity, bullets for major decisions, longer content for context, and search-term fields for accurate vocabulary coverage.
    • Resolve contradictions across fields and creative assets before adding more language.
    • Test with fixed prompts and downstream business signals, treating repeated observations as directional evidence rather than proof of a ranking formula.

    Your next move is narrow and practical: choose one representative ASIN, map its most decisive shopper questions to verified attributes, and fix the highest-risk ambiguity. Save the baseline, rerun the same prompt set after the changes are live, and scale only the patterns that improve both answer quality and shopper fit.

    References


  • Platform-Specific AEO: Optimize for Voice and AI Answers

    Platform-Specific AEO: Optimize for Voice and AI Answers

    You have a page that ranks, valid schema, and a concise answer, yet Bing surfaces it while Grok ignores it and a voice assistant names another business. The problem is not necessarily weak content. You may be asking one page to satisfy several different retrieval and delivery paths.

    The practical fix is to maintain one canonical answer, then adapt its discovery, evidence, structure, and testing for each platform. Platform-specific AEO should change how an answer is found and delivered, not create conflicting versions of the facts.

    Key takeaways

    • Keep one authoritative version of each answer. Adapt the surrounding format and distribution for each platform.
    • For Bing and Copilot, prioritize extractable answer blocks, structured data, indexability, and external authority.
    • For Gemini, connect direct answers to a coherent topic cluster, clear authorship, supporting evidence, and natural-language questions.
    • For Grok, cover context thoroughly, keep changing facts current, and use X to distribute accurate summaries that point back to the canonical page.
    • For Alexa and other voice experiences, optimize the spoken result as well as the page: natural wording, self-contained answers, accurate local data, and device-level testing.
    • Measure observed answers, citations, referrals, and recognition failures. A single AEO ranking cannot describe performance across these surfaces.

    Map the answer path before changing the content

    A branching pathway connects one source to search, evidence, content, and voice symbols before reaching several generic devices.

    A spoken search has more failure points than a typed search. Speech recognition converts audio into text, natural-language processing interprets the request, retrieval finds candidate information, and text-to-speech delivers a response. A poor result can therefore begin before your page is considered: the device may mishear the request, resolve the wrong intent, miss the user’s location, or retrieve inconsistent business information.

    This is why voice search and AEO are related but not interchangeable. Voice is an interface. The answer engine is the system that interprets, retrieves, selects, and sometimes synthesizes the response. A typed Gemini prompt and a spoken request can express the same intent while taking different routes to an answer.

    Separate the route into five layers so you can fix the layer that actually failed:

    • Recognition: Does the device convert the user’s words into the intended query? Write around phrases people naturally say, not only compressed keyword forms.
    • Intent: Does the page resolve the real task, location, audience, or constraint behind the question? State those conditions explicitly.
    • Retrieval: Can the relevant platform discover and understand the page, entity, listing, or X post that contains the answer?
    • Selection: Is there a self-contained answer that can be separated from the rest of the page without becoming misleading?
    • Delivery: Will the selected passage still make sense when spoken aloud without its heading, table, image, or surrounding context?

    If the assistant misunderstood the speech, rewriting your schema will not solve the problem. If it understood the query but selected a competitor, recognition is not the issue. This diagnostic distinction prevents a great deal of unfocused content editing.

    Change the selection strategy for each platform

    The shared foundation is straightforward: an indexable page, a direct answer, factual support, clear authorship, and markup that agrees with the visible content. The emphasis around that foundation changes by platform.

    SurfaceMain selection pressureWhat to changeHow to check it
    Bing and CopilotSearch extraction, rich-result understanding, relevance, and authorityPut a concise answer directly below a question heading, keep the opening response under 100 words when the subject permits, use lists or tables for genuinely structured information, add appropriate schema, and support the page with credible citations and links.Inspect the actual Bing result and Copilot response. Use Bing Webmaster Tools to review queries and click-through rates, then compare the wording selected with the answer block you intended to expose.
    GeminiConversational intent, topical coverage, understandable structure, and trust signalsOrganize related questions into a topic cluster, connect them with meaningful internal links, write in natural language, expose author credentials, cite reliable evidence, and keep time-sensitive information current. Use JSON-LD to clarify what the page contains.Ask the core question in several natural phrasings and note whether the page or brand appears. Check whether pages built around specific questions earn better engagement than broad pages that make readers hunt for an answer.
    GrokContextual relevance, factual accuracy, current discussion, and discoverability through the web and XCover the conditions and user scenarios surrounding the answer, cite factual claims, monitor the questions being discussed on X, and publish accurate summaries on X that link to the fuller canonical explanation. Do not let a short social post introduce claims the page cannot support.Query Grok directly with the main question and its contextual variations. Record mentions or citations, and separately monitor referrals from grok.com and X rather than treating them as ordinary search traffic.
    Voice assistants, including AlexaA single speakable response, conversational intent, and accurate local or task-specific informationUse full-sentence questions, front-load a concise answer, and make important qualifiers audible. For local requests, maintain accurate names, addresses, opening hours, and other listing details. Treat Alexa as a surface that must be tested directly rather than assuming every voice assistant uses the same route.Speak the query on the target device. Record what the assistant heard, which answer it delivered, whether the location was correct, and whether the response remained useful without a screen.

    These are optimization priorities, not guarantees or permanent ranking formulas. Answer systems evolve, and their complete selection logic is not exposed. The defensible approach is to make a clear hypothesis about the relevant layer, change one meaningful element, and test the resulting answer on the actual surface.

    Do not turn the table into four copies of every page. Keep facts, definitions, policies, prices, and instructions in one canonical location whenever possible. Adapt the question heading, supporting depth, internal links, structured data, social distribution, local records, and testing around that location.

    Build a canonical answer unit that survives extraction

    A modular capsule containing linked information is extracted from surrounding content into several different device frames.

    Write for a decision or task, not a keyword fragment

    An answer unit is the smallest passage that resolves a specific question accurately. It is not merely the first paragraph, and it should not try to summarize an entire subject. Build it in this order:

    1. Choose one real task. Include the user, situation, or constraint when it changes the answer. A broad best-product query usually hides several different decisions.
    2. Use the complete question as a heading. Match natural speech where it remains clear. Do not force awkward keyword repetition into the heading.
    3. Give the direct answer immediately. A 40- to 60-word opening is a useful authoring target for a compact snippet or spoken response, while an answer under 100 words can remain easy for Bing to extract. These are editing constraints, not eligibility rules. Use fewer or more words when accuracy requires it.
    4. Place the decisive condition next. If the answer changes by location, product version, audience, or scenario, say so before the reader acts.
    5. Expand in a predictable order. Explain the mechanism, steps, exceptions, evidence, and next action. Use a numbered list for a sequence and a table only when the reader genuinely needs to compare fields.
    6. Connect the answer to its topic cluster. Link to prerequisite explanations and closely related decisions. This gives an answer engine more context without bloating the direct response.

    The direct answer does not have to be identical everywhere it appears, but its claims must remain consistent. An X summary may be shorter and a spoken response may omit secondary detail. Neither should contradict the canonical page or remove a condition that changes the meaning.

    Use schema to label meaning, not manufacture it

    Structured data helps a machine classify information that already exists on the page. It does not supply a missing answer, establish expertise by itself, or guarantee that a platform will quote the marked passage.

    • Use Article markup for an article and expose accurate author and publication information.
    • Use FAQPage when the visible page genuinely contains questions with their answers.
    • Use HowTo for a real ordered process, not for a page that merely discusses a task.
    • Use a more specific type such as Recipe, Product, or Event when the visible content supports it. Specific schema can help Bing understand the fields available for rich results and direct answers.
    • Keep every marked fact aligned with the visible page. If the opening hours, steps, author, or answer change, update the markup in the same release.

    Validate the implementation with Bing’s Markup Validator when Bing is in scope. Then inspect the rendered page as a reader would. Error-free JSON-LD attached to vague, stale, or contradictory copy is still a weak answer.

    Make the opening answer work without a screen

    A passage can scan well on a page and fail when read aloud. Before publishing, read only the proposed answer block without its heading or surrounding paragraphs. Revise it if the listener would have to see the layout to understand it.

    • Name the subject instead of opening with an ambiguous pronoun such as it or they.
    • State the important condition before the recommendation, not several paragraphs later.
    • Put the conclusion into a sentence before a supporting table or chart.
    • Avoid directions such as see below, choose the option on the left, or compare the highlighted column.
    • Keep citations and evidence on the page, but do not let a long attribution interrupt the spoken core of the answer.
    • Use words a customer would say. Preserve the precise technical term where it changes the meaning, then explain it plainly.

    Local voice queries add an entity-resolution problem. Addresses, opening hours, reviews, mobile usability, and page speed can affect whether a nearby business is a credible and useful response. Reconcile the website and business listings before polishing an FAQ; a beautifully written answer cannot repair the wrong location or closed hours.

    Test observed answers instead of looking for one AEO rank

    Traditional rank tracking is not enough here. A generated answer may mention you without sending a click, a voice assistant may deliver a correct response without showing a URL, and two phrasings of the same intent may produce different selections. Build a repeatable observation log.

    1. Create a stable query set. Include the direct question, a natural paraphrase, a relevant follow-up, and a local or comparison modifier when the intent calls for one.
    2. Record the environment. Note the platform, typed or spoken input, device or interface, recognized query, location context when relevant, and the date of the check.
    3. Capture the output. Save the answer, named sources or citations, linked page, factual errors, missing qualifiers, and whether the assistant asked a follow-up question.
    4. Classify the failure layer. Decide whether the problem was recognition, intent, retrieval, selection, factual consistency, or spoken delivery.
    5. Change the smallest relevant layer. Edit the answer block for extraction problems, the topic cluster for missing context, structured data for classification problems, X distribution for Grok discovery, or local records for nearby voice requests.
    6. Run the same query set again. Recheck after a material content, schema, listing, or platform change so that the new result is comparable with the earlier observation.

    Match each failure to a specific correction

    • The page never appears: inspect crawlability, indexing, internal links, entity consistency, and platform-relevant distribution before rewriting every paragraph.
    • The correct page appears but the extracted answer is poor: tighten the question heading, opening answer, list structure, and nearby qualifiers.
    • The answer is stale or contradictory: reconcile the visible copy, structured data, citations, dates, listings, and distributed summaries.
    • A competitor is repeatedly selected: look for a real gap in evidence, topical coverage, author credibility, external authority, or scenario-specific usefulness.
    • The spoken query is misheard: test alternative natural wording and inspect the device, language, pronunciation, and location context. Content selection has not yet become the primary problem.
    • The answer is correct but no referral arrives: record the mention or citation separately. Referral traffic alone cannot show every voice or generated-answer appearance.

    Keep platform evidence separate

    Do not roll these observations into a single visibility score until you can still see the underlying platform results. A rising aggregate can conceal a broken local voice answer, while a falling click count can coexist with more unlinked mentions in generated responses.

    Start with one high-value question already connected to a customer action. Build its canonical answer unit, add truthful schema, reconcile any local records, and run the same intent across the platforms that matter to your audience. Once that answer survives extraction, contextual prompts, and spoken delivery, use the structure as a template for the next question. The scalable system is one reliable knowledge base with controlled platform adaptations, not a separate content calendar for every assistant.

    References

  • Voice Search Optimization: A Practical AEO Workflow

    Voice Search Optimization: A Practical AEO Workflow

    When someone asks a voice assistant a question, there may be room for only one spoken response. Your page can be relevant and still lose that response because the useful sentence is buried, the business details conflict, or the answer needs too much context to make sense aloud.

    Treat voice search optimization as an answer-delivery problem. Your job is to make the right response easy to find, extract, verify, and speak while preserving the depth a person needs when they visit the page.

    Key takeaways

    • Start with a complete spoken question and its intent, not an isolated keyword.
    • Place a direct, self-contained answer immediately below the heading that asks the question.
    • Use FAQ or HowTo schema to describe visible content accurately; markup cannot compensate for a weak answer.
    • Treat local voice optimization as an entity-data task before treating it as a copywriting task.
    • Measure whether assistants select your answer. Rankings and engagement metrics are supporting evidence, not direct proof.

    Start with the spoken question, not a short keyword

    A typed query might be a compressed phrase such as clean coffee maker. A spoken query is more likely to express the whole need: How do I clean a coffee maker? Voice searches are often longer, conversational, and framed as questions. That difference affects the answer format as much as the keyword choice.

    Build your initial query set from language people already use. Customer-support messages, sales questions, site-search terms, product reviews, and conversations recorded by customer-facing teams are useful starting points. AnswerThePublic and Semrush can expand that set with question-based variations, but a tool-generated phrase still needs an identifiable intent before it deserves a page.

    For every candidate query, record five things:

    • The spoken question: Write the complete sentence a person might say, including relevant qualifiers such as product type, problem, or location.
    • The immediate intent: Decide whether the person wants a fact, instructions, a comparison, a nearby business, or an action.
    • The answer format: Choose a short explanation, ordered procedure, criteria list, local result, or another format that matches the need.
    • The best destination: Assign the query to an existing page when that page already satisfies the intent. Do not create separate pages for minor wording variations.
    • The basis for the answer: Identify the facts, process knowledge, business data, or other evidence that lets you answer credibly.

    Prioritize questions you can answer clearly and substantiate. A broad query such as What is the best marketing platform? hides the criteria needed to make the answer useful. A narrower question that identifies the user, task, or constraint gives you a better chance of producing a defensible response.

    Do not force every conversational variation into the copy. Select a natural primary question, answer it, and cover meaningful follow-up needs in the surrounding section. Repeating near-identical questions makes a page harder to read without making its central answer clearer.

    Build an answer unit that can stand on its own

    A complete illuminated content module sends a sound pulse to a speaker while fragmented page elements recede into the background.

    A voice assistant may extract only a small part of your page. That part must remain accurate when separated from the paragraphs around it. We call this an answer unit: a descriptive heading, an immediate response, and just enough structure to preserve the meaning.

    Use an answer-first order

    1. Ask the real question in the heading. Use the wording a reader would recognize, but keep it natural rather than mechanically copying every keyword variation.
    2. Answer in the opening sentence. Name the subject directly. Avoid an opening such as It depends or This is the best approach when the extracted sentence would leave the listener wondering what it or this means.
    3. Match the structure to the task. Use ordered steps for a procedure, bullets for criteria, and prose when the explanation depends on cause and effect.
    4. Add constraints immediately after the answer. State the conditions that could change the recommendation before moving into background material.
    5. Provide depth below the extractable response. Examples, evidence, alternatives, troubleshooting, and related questions belong here.

    Short sentences, bullets, and explicit steps make an answer easier for an assistant to interpret. They also help a human reader verify quickly that the page addresses the question.

    Different intents need different answer units:

    • Definition: Begin with [Term] is…, then explain what distinguishes it from nearby concepts.
    • How-to: State the outcome and any essential prerequisite, then present the actions in the order they must happen.
    • Comparison: Name the deciding criterion first, explain which option fits each situation, and support the distinction below.
    • Local service: Identify the business, service, and location plainly before giving directions, contact details, or the next booking action.

    Read the opening answer aloud without the heading. If its subject becomes unclear, rewrite it. Then read the heading and answer together. If they sound repetitive or robotic, keep the meaning but loosen the phrasing. Voice-friendly content should sound natural when spoken; it should not look like a transcript padded with keywords.

    Use schema to clarify content, not manufacture it

    Structured data gives machines explicit labels for content that already exists on the page. FAQ schema fits a genuine set of visible questions and answers. HowTo schema fits a real process with an ordered sequence. Neither type turns vague copy into a reliable response, and neither guarantees that an assistant will select it.

    Before publishing JSON-LD, check that:

    • The marked-up question and answer match what visitors can read on the page.
    • The schema type describes the content accurately rather than the result you hope to obtain.
    • A HowTo sequence follows the same order in the markup and the visible instructions.
    • Required qualifications and warnings appear in both the answer and its structured representation.
    • Content and markup are updated together when a fact, step, product, or business detail changes.
    • The markup still validates after a theme, template, CMS, or plugin change.

    Schema is only one part of the retrieval path. Alexa can draw responses from Amazon’s knowledge graph, third-party skills, and indexed web content. A correctly marked-up web page therefore remains dependent on crawlability, relevance, authority, and the platform’s own answer-selection process.

    Keep the technical objective narrow: help the system identify the question, the answer, and any ordered steps without creating a conflict between the markup and the visible page. If the two versions disagree, fix the publishing workflow rather than deciding which version a machine should trust.

    Make local facts and authority easy to verify

    An unbranded storefront connects to location, phone, hours, and verification symbols with matching check marks.

    A request such as Find a coffee shop near me is not solved by adding the phrase near me throughout a page. The assistant has to connect a service or business category with a location and a trustworthy entity. Conflicting records can undermine an otherwise well-written local page.

    Audit the business data that supports that connection:

    • Keep the Google Business Profile complete and current.
    • Check the business’s presence in Amazon’s relevant local services where applicable.
    • Use a consistent name, address, and phone number across the website and important listings.
    • Verify opening hours, service areas, contact routes, and location details whenever operations change.
    • Include city and service-area language where it helps a visitor understand coverage.
    • Make each location page useful on its own instead of swapping place names into otherwise identical copy.

    Write for local intent, not for the literal phrase. A clear statement such as We provide emergency plumbing services across [city and service area] communicates the entity, service, and geography. An awkward claim such as best emergency plumber near me does not tell the assistant where the business operates or why the claim should be believed.

    Authority also develops across related pages. Create a central resource for the broad subject, publish supporting answers for the recurring subtopics, and link them according to the reader’s next question. High-quality backlinks, accurate citations, and positive reviews provide additional trust signals. The aim is not sheer publishing volume. It is a connected body of content that answers the main question and the follow-up questions consistently.

    Measure answer selection before building an Alexa skill

    Keep a repeatable voice-search log

    Ordinary analytics cannot tell you reliably that a person heard your content from a smart speaker. A spoken answer can satisfy the request without producing a visit. Measure the selection event separately, then use rankings and on-site behavior to interpret what happens around it.

    1. Freeze a manageable set of important spoken questions.
    2. Test Alexa, Siri, and Google Assistant separately. Do not assume that selection on one platform transfers to another.
    3. Record the exact wording, platform, date, response, and any cited or named destination. Include location or account context when it materially affects the result.
    4. Classify each outcome: your answer was selected, another answer was selected, the assistant requested clarification, or no useful answer was returned.
    5. Compare the selected wording with your answer unit and identify the missing fact, structural difference, or authority signal.
    6. Change a single meaningful element, such as the opening answer or procedural structure, and repeat the check under comparable conditions.

    Featured-snippet visibility can be a useful supporting measure because featured snippets often correlate with voice answers. Ahrefs and similar SEO platforms can help track those positions. Time on page, bounce rate, and related engagement metrics can show whether visitors find the expanded page useful, but they do not prove that an assistant selected its answer. Keep those measurements in separate columns so a traffic gain is not mistaken for voice attribution.

    A/B testing can help you compare answer formats when the page receives enough comparable traffic or when your testing process can hold other factors steady. Test a meaningful difference, such as prose versus ordered steps, rather than changing the heading, answer, markup, and page layout simultaneously.

    Use an Alexa skill for a repeatable task, not as a ranking shortcut

    An Alexa skill gives a brand a controlled environment for responses. A fitness business, for example, could provide a requested morning workout through a dedicated skill. This can reduce dependence on web crawling within that skill experience, but it does not cause ordinary web pages to rank for generic voice searches.

    A skill is worth evaluating when users have a repeatable task, the interaction is useful without a screen, the response depends on a maintained workflow or data set, and the business can support the experience after launch. If the only goal is to make an informational page more visible, improve the page, structured data, authority, and entity consistency first.

    For a live skill, Amazon’s Alexa Developer Console can provide usage information that web analytics cannot. Review which requests succeed, where people stop, and which utterances fail to reach the intended response. That evidence should guide the skill’s language model and interaction flow separately from your web AEO work.

    Start with the questions already reaching your support, sales, and site-search channels. Choose a manageable group, assign each one to the right page, rewrite the answer units, align the schema, and verify every relevant business field. Then establish the measurement log before making further changes. A repeatable record of what assistants actually select will give you a more useful roadmap than another round of speculative keyword expansion.

    References