I remember the days when a Google search was akin to embarking on a quest for information. It was an adventure of navigating various links and forming my own opinions.
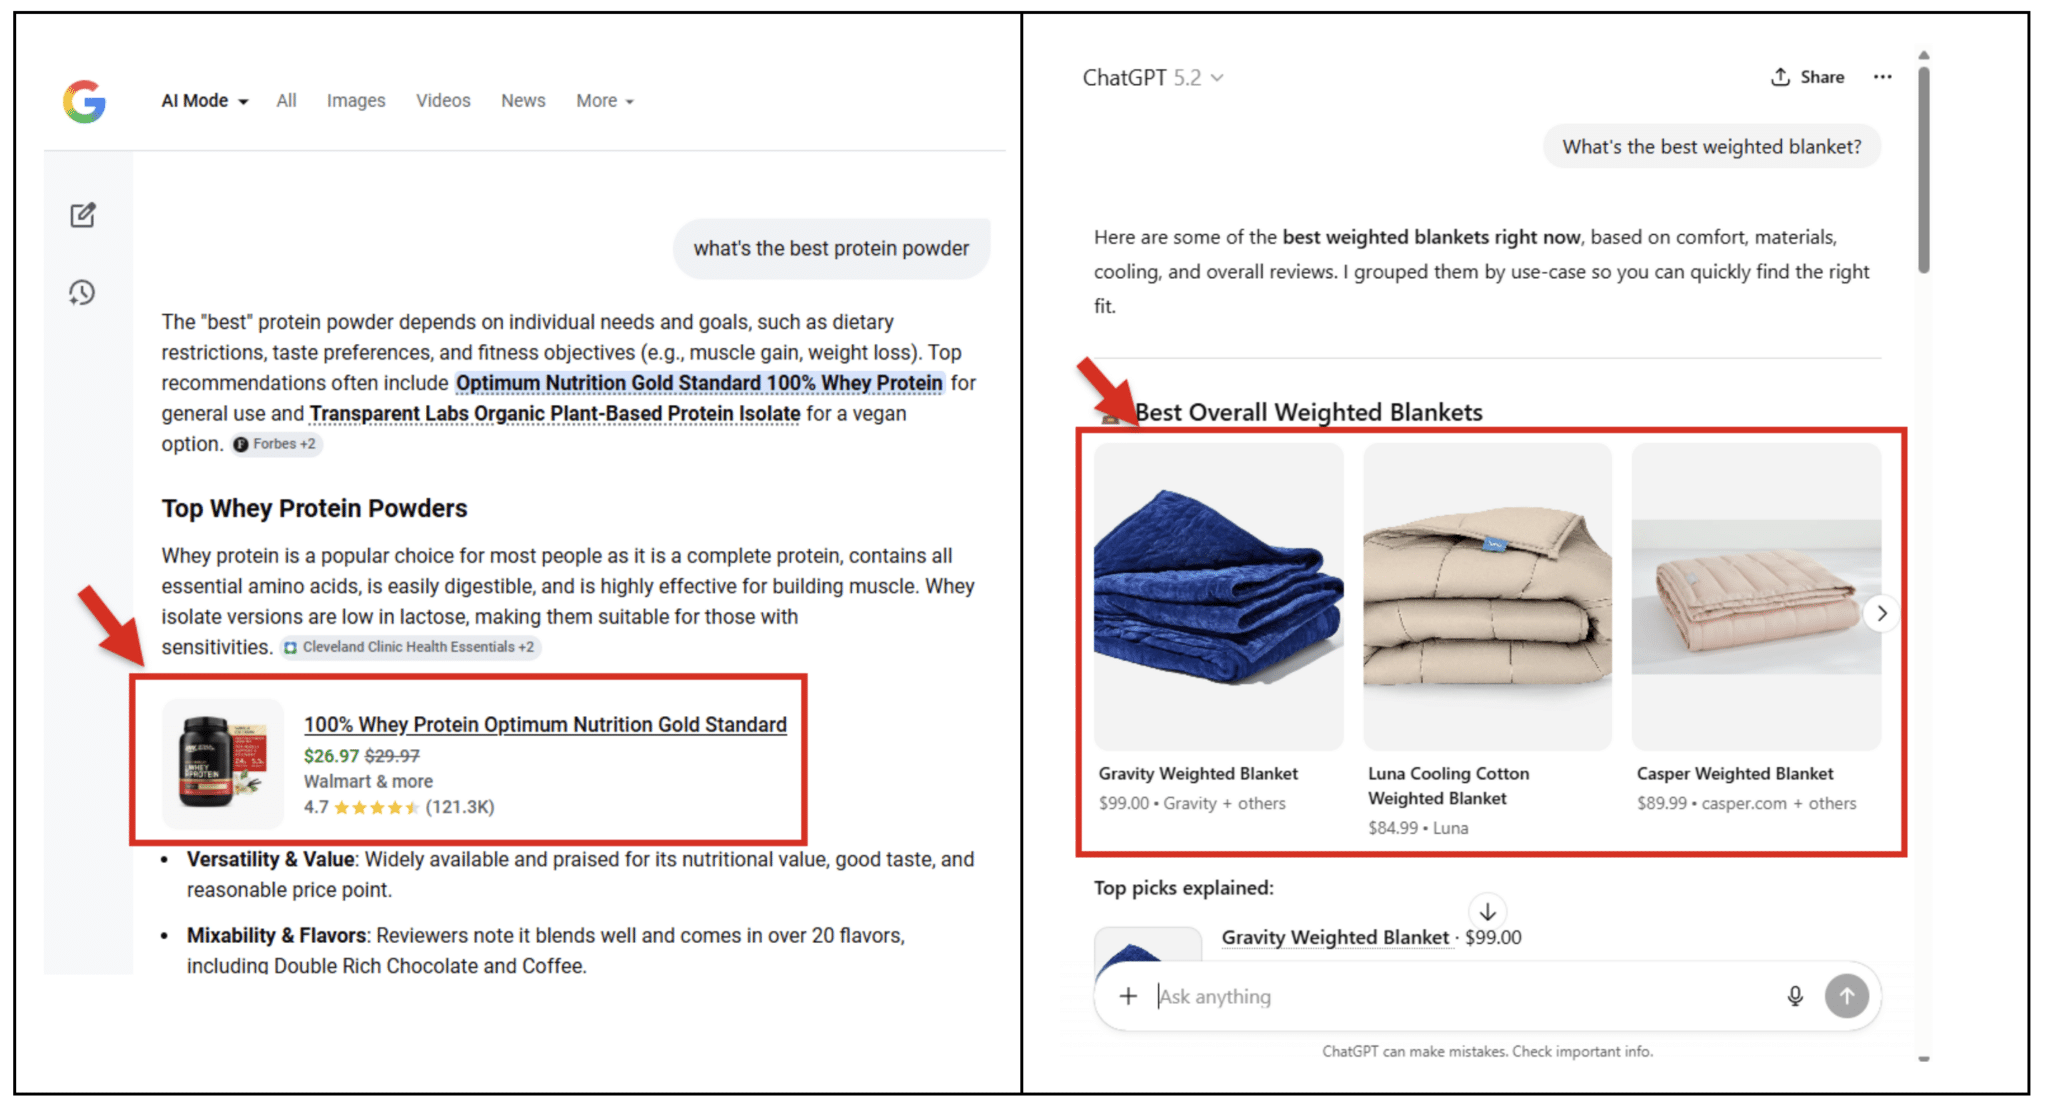
Nowadays, tools like AI Overviews, ChatGPT, and Perplexity condense all that information into a single, simplified answer. This transformation often strips away the finer details while amplifying certain perspectives.
This shift has redefined online reputation management. Now, search engines not only present information but shape the underlying narratives. This raises the stakes for brands, as even a top-ranking status doesn’t guarantee influence if AI stories tell a different tale.
For brands, the game has changed. Being number one doesn’t ensure visibility and influence anymore. The underlying narrative holds far greater power.
AI Narrative Formation: Crafting User Answers
AI platforms now utilize what I like to call ‘AI narrative formation.’ This process crafts the responses we receive from various search engines. Let me walk you through how this system works.
Source Pooling
These systems pull content from numerous sources. Contrary to expected reliance on peer-reviewed articles, they gather data from Reddit, YouTube, and social platforms like Instagram and TikTok.
Signal Weighting
Not all sources are equal. Often, a popular yet low-quality source can outweigh a singular, credible entry. A bustling Reddit thread with negative feedback might overshadow a well-researched Wikipedia page.
Narrative Compression
The summarization process compresses diverse inputs, often losing nuance along the way. Complex reputations are simplified into general statements like, ‘Users find this company untrustworthy.’
Continued Reinforcement
These summaries transcend their original context, getting shared and re-shared across social media. As these echoes return as new data, they further entrench the narratives in AI responses.
Unraveling a Finance Company’s Reputation in AI Search
To illustrate AI narrative formation, consider a recent case I worked on involving a financial company, which we’ll call Company X.
Company X’s reputation remained strong on traditional SERPs. High Trustpilot ratings and reputable endorsements were the norm until Google AI Overview threads surfaced a forgotten Reddit forum rife with grievances against them.
The AI Overview skewed the narrative, suggesting Company X had unresolved customer service issues, even though these concerns had been addressed years prior. This created a skewed perception that was hard to counteract.
The Amplified Risk from AI Searches
AI dramatically increases reputational risk through several mechanisms:
The Spread of Negative Narratives: Negative content surfaces faster and more prominently than before.
AI Hallucinations: Despite growing awareness, AI inaccuracies continue to deceive.
The Snowball Effect: Repeated narratives gain momentum, complicating reputation management efforts.
It has become evident that in ORM, repetition often overrides accuracy.
Auditing AI-Generated Narratives: A Step-by-Step Approach
Let’s consider a situation involving an AI-generated narrative challenge faced by CEO X of a well-known SaaS company.
After an out-of-context quote from CEO X’s podcast appearance went viral, AI summarized him unfavorably. Quickly, his reputation transformed negatively across major platforms.
Step 1: Mapping Queries
I initiated a process to understand what queries AI outputs were generating about CEO X. This helped identify the underlying issues.
Step 2: Capturing Outputs
Identifying repeated claims revealed how CEO X was perceived. Narratives from Google AI and ChatGPT were consistently portraying him negatively.
Step 3: Delving Through Sources
The next step involved examining the quality of sources contributing to these narratives, often outdated or lacking accuracy.
Step 4: Analyzing the Narrative Gap
This involved assessing discrepancies between AI narratives and his actual reputation, contextualizing the initial quote, and examining the long-standing perception of CEO X.
Step 5: Correcting and Replacing Sources
Finally, I focused on directly addressing, correcting, and replacing those negative narratives. This involved engaging directly with platforms that contributed to the misinformation and reinforcing positive content elsewhere.
A New Perspective: From SEO to Narrative Management
The focus has shifted from merely achieving top SEO rankings to understanding and adapting to narrative shifts. We must rethink our strategy from content engagement to managing the narratives AI disseminates.
To succeed, it’s important to reinforce AI systems with quality inputs, including crafting high-quality content, pursuing credible mentions, disseminating structured data, and managing misinformation directly.
Your page ranks, the answer is on the page, and your technical SEO looks sound. Yet Google AI Overviews does not cite it, and chatbot answers either omit your brand or mention it inconsistently. That is not a contradiction. It means organic rank and AI visibility are measuring different selection systems.
You need a baseline that separates AI-answer eligibility, brand mentions, citations, accuracy, and business outcomes. Once those signals are split apart, a visibility problem stops being mysterious: you can tell whether to change the query set, the page, the answer structure, the evidence, or nothing at all.
Rankings and AI visibility answer different questions
An organic ranking tells you where a page appears in a conventional result set. An AI citation tells you whether an answer system retrieved that page for a particular response. A brand mention tells you whether the system represented the entity in its answer. These outcomes can overlap, but none is a substitute for the others.
Record rank and citation status together. The four possible states point to different work:
Ranked and cited: preserve the passage that is being retrieved, then look for ways to improve the accuracy and prominence of the brand representation.
Ranked but not cited: investigate a retrieval gap. The page is competitive in organic search, but its answer may be buried, mismatched to the prompt, weakly structured, or insufficiently supported.
Not highly ranked but cited: inspect the selected passage closely. It may reveal an answer format, level of specificity, or intent match worth extending elsewhere without assuming that the page’s organic SEO is complete.
Neither ranked nor cited: check query-to-page relevance, crawlability, indexation, topical coverage, authority, and content quality before making narrow AI-focused edits.
AI-answer eligibility is another separate variable. One late-2025 estimate put AI Overviews at 16% of searches, with uneven coverage across query types. Transactional, navigational, and local searches were less likely to trigger them than many informational searches. If a query produces no AI Overview, do not record the page as a failed citation. Record no trigger, then continue measuring organic visibility and any other AI surfaces relevant to that query.
This distinction prevents a common reporting error. A falling citation rate can mean your content lost retrieval visibility, but it can also mean fewer tracked searches produced an AI answer. Trigger rate gives you the denominator needed to tell those situations apart.
Build a tracker that makes every observation reproducible
An API model response should also remain distinct from the corresponding consumer product. The model, system instructions, browsing or grounding capability, account state, and product interface can change what appears. Labeling everything ChatGPT or Gemini without those qualifiers creates a trend line that cannot be interpreted.
Define the surface and environment. Store the platform, product or API, model identifier when available, browsing or grounding state, locale, language, device class, and signed-in state where those conditions apply.
Create a query inventory around decisions and problems. Include unbranded discovery questions, comparison prompts, implementation questions, troubleshooting prompts, and branded fact checks. Assign each prompt to a topic, intent, funnel stage, market, and target page.
Freeze the wording. Give every prompt a stable ID and preserve its exact text. If you want to test conversational variants, create separate prompt IDs rather than silently changing the original.
Save the complete output. Store the raw answer, cited URLs, cited domains, response timestamp, and any visible ordering. A screenshot is useful for visual evidence, but searchable response text is better for rescoring and analysis.
Choose a repeatable cadence. Weekly checks can suit an active launch or optimization cycle; monthly checks can suit a stable portfolio. Consistency matters more than an aggressive schedule you cannot maintain.
Your query inventory should reflect the questions that matter to the business, not merely prompts that are likely to mention the brand. Include current search demand, sales objections, support questions, category-selection decisions, and prompts where competitors are already visible. Keep branded and unbranded prompts in separate cohorts so improved branded recognition does not disguise weak category discovery.
At minimum, each observation should contain a run ID, prompt ID, exact prompt, topic cluster, surface, model or product, environment, timestamp, completion status, AI-answer trigger status, raw response, brand mentions, owned citations, other cited domains, accuracy assessment, prominence assessment, and organic position where applicable. Add the target landing page and business outcome fields if you can connect the observation to analytics.
Protect the evidence before automating the score
Use persistent storage from the first working version. Keep the original response even after you add parsing, classification, or scoring. Raw API responses make parsing failures visible, while saved outputs let you apply a revised rubric to historical observations without rerunning every prompt.
If you build the tracker yourself, connect one surface and validate it before adding the next. Test authentication, response persistence, citation extraction, long-answer handling, and error states separately. Save a working version before changing a connector or parser. Otherwise, a software regression can look like a visibility loss.
Measure trigger, mention, citation, accuracy, and outcome separately
A single visibility percentage conceals the mechanism behind the result. Keep the component metrics visible, even if leadership also wants a roll-up score.
Metric
Calculation
What it tells you
AI-answer trigger rate
Completed searches with an AI answer divided by all completed searches
How often the tracked surface created an AI visibility opportunity
Conditional brand mention rate
Generated answers naming the brand divided by all generated answers
How often the brand appears when an answer exists
Owned citation rate
Generated answers citing an owned domain divided by all generated answers
How often your content is retrieved as supporting material
Accurate mention rate
Materially accurate brand mentions divided by all reviewed brand mentions
Whether visibility represents the brand correctly
Portfolio reach
Completed searches producing a brand mention or owned citation divided by all completed searches
Exposure across the whole tracked query set, including searches with no AI answer
Business outcome
Observed visits, assisted actions, leads, or conversions connected to the cited page or AI referral
Whether exposure contributes to a useful result
The denominators matter. Conditional brand mention rate answers what happens when an AI answer appears. Portfolio reach answers what happens across every tracked opportunity. Reporting only the first can make performance look strong when AI answers rarely trigger. Reporting only the second can make good content look weak when the surface itself has limited coverage.
Treat failed requests as null observations, not zero visibility. Retry timeouts, authentication failures, truncated outputs, and parsing errors. Treat a completed AI answer with no brand or owned citation as a genuine zero. For Google AI Overviews, treat a completed search with no Overview as no trigger: it belongs in the trigger-rate denominator but not in an answer-quality score.
Use a transparent five-signal response score
If stakeholders need one roll-up number, use a five-point rubric whose components remain auditable. A generated answer can earn one point for each of these signals:
The brand is named.
The brand is described materially accurately.
The brand appears in the main answer or an explicit shortlist rather than in incidental text.
An owned page is linked or cited.
The cited owned page directly supports the claim or recommendation beside it.
Define borderline cases before the first run. Decide, for example, whether a source carousel without an in-text citation counts, what qualifies as prominent placement, and which factual errors fail the accuracy signal. Keep those rules unchanged during an optimization cycle.
Average the response score by surface, query cluster, intent, and market. Always display mention rate, citation rate, and accuracy beside it. Two portfolios can have the same average score while needing opposite fixes: one may receive frequent uncited mentions, while the other earns citations that never surface the brand.
Do not add organic rank to the five-point score. Rank is a diagnostic dimension, not another form of AI visibility. Keeping it separate preserves the ranking-citation gap you need to investigate.
Turn each miss into a specific content change
Optimization should begin with the failure state, not with a sitewide rewrite. The smallest change that addresses the observed mechanism is easier to evaluate and less likely to disrupt content that already performs.
No AI answer appears for the query. Move the query out of the AI Overview citation cohort, but retain it for organic search and other AI surfaces. Recheck it at the next scheduled run. A missing Overview is not evidence that the page needs rewriting.
The page answers the topic but not the prompt’s version of the question. Write down the exact decision, constraint, or task expressed by the prompt. Add a section that resolves that need directly, or map the prompt to a more suitable page. Repeating the target keyword will not repair an intent mismatch.
The page is difficult to parse. Replace vague headings with headings that name the actual question or subproblem. Keep each section focused, use concise paragraphs, and make essential qualifiers part of the answer rather than scattering them through unrelated sections.
The answer lacks visible reasons to trust it. Add an accurate byline, relevant author credentials, dates, named evidence, methodology for original analysis, and links supporting consequential claims. Credibility needs to be visible on the individual page, especially for health, financial, legal, educational, and other high-consequence subjects.
The page is cited but the brand is absent or misrepresented. State the relevant entity facts plainly near the answer. Keep product names, organization details, authorship, and descriptions consistent across visible copy and structured data. Do not force promotional language into an informational answer; that can make the passage less usable.
One page carries the entire topic. Fill genuine coverage gaps with supporting pages that answer adjacent questions, comparisons, implementation needs, and limitations. Broader topical coverage gives an answer system more precise passages to retrieve than one oversized page trying to satisfy every intent.
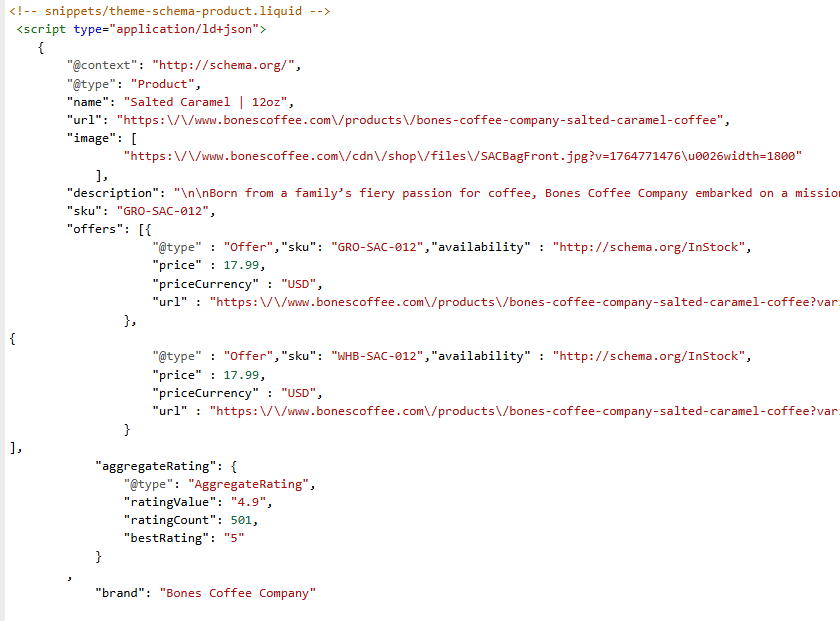
JSON-LD can clarify entities and page attributes, but it is not an AI citation switch. Use applicable types such as Article, Person, Organization, Product, or FAQPage only when the markup accurately describes visible content and meets the relevant eligibility rules. Structured data cannot compensate for an answer that is vague, unsupported, or aimed at the wrong question.
Keep a query-to-page diagnosis sheet with six columns: prompt ID, intent, required answer, current target page, observed failure state, and proposed change. That sheet forces every edit to answer a measurable problem. It also exposes prompts competing for the same page and pages expected to satisfy incompatible intents.
When another domain is cited, compare the exact passage, not the entire competing page. Note how quickly it answers, which qualifiers it includes, what evidence is visible, and whether its heading makes the passage understandable out of context. The goal is not to imitate wording. It is to identify the retrieval need your page leaves unresolved.
Run controlled cycles and judge results by query cluster
AI outputs can vary between runs, so one favorable answer is not a durable win. Collect repeated baseline observations, preserve the raw outputs, and compare cohorts under the same conditions. You may not have enough observations for formal statistical claims, but you can still avoid declaring success from a screenshot.
Freeze the test cohort. Keep prompt wording, surface, model or product, locale, and other recorded conditions stable.
Choose one hypothesis. Examples include a buried answer, an intent mismatch, weak page-level evidence, or inconsistent entity information.
Change the smallest relevant unit. Edit the introduction, one answer section, one evidence block, or the applicable structured data rather than rewriting unrelated material.
Record the deployment. Save the prior page version and note the publication time, changed section, hypothesis, and expected metric movement.
Rerun the same observations. Compare trigger rate, mention rate, citation rate, accuracy, prominence, and the five-signal score by query cluster and surface.
Check guardrails. Review organic rankings, search clicks, engagement, conversions, factual accuracy, and content readability. A citation gain is not worthwhile if the page becomes less useful or loses the outcome it was built to produce.
Use different success criteria for different goals. An informational publisher may prioritize owned citations and qualified visits. A recognized brand may care more about accurate representation in category answers. A newer brand may focus first on unbranded mention reach. The metric should follow the decision the business needs to make.
Keep AI visibility and business impact connected but distinct. A citation is evidence of retrieval, not proof of traffic or revenue. A brand mention can shape awareness without producing a trackable click. Report the visibility event honestly, then attach referral traffic, assisted behavior, leads, or conversions only where your analytics can support the connection.
Key takeaways
Track AI-answer triggers, brand mentions, owned citations, accuracy, prominence, and outcomes as separate signals.
Record the exact prompt, surface, model or product, environment, timestamp, raw answer, and cited URLs for every observation.
Keep organic rank beside AI visibility as a diagnostic; do not blend it into the same score.
Classify the failure before editing: no trigger, wrong intent, buried answer, opaque structure, weak evidence, inconsistent entity information, or insufficient topical coverage.
Test one hypothesis on a stable query cohort, preserve the prior version, and judge movement across repeated observations rather than one response.
Start with one commercially important topic cluster and build a clean baseline before changing its pages. Your first useful result is not a bigger visibility score. It is knowing whether the next action belongs in measurement, retrieval optimization, brand representation, or content strategy. Once that distinction is visible, the next edit becomes much easier to defend.
You publish a technically sound page. One AI engine cites it, another repeats an older version of the information, and a third never mentions your brand. That doesn’t automatically mean the page is weak. Each engine may be working from a different pool of accessible data.
Your job is no longer just to rank one URL. You need to make important facts discoverable, retrievable, understandable, and attributable across systems you don’t control. The way to do that is to diagnose the access path, strengthen the parts you own, and measure each platform separately.
AI search doesn’t operate from one universal index
That fragmentation makes a single visibility score misleading. AI search products can differ at several layers:
Discovery: The system has to find the URL through a crawl, feed, index, link, API, licensed collection, or another permitted route.
Access: The relevant crawler or retrieval service has to receive the content rather than a block, login screen, consent wall, empty shell, or error response.
Parsing: The system has to extract the main facts, entities, relationships, dates, and supporting evidence from the returned content.
Retrieval: The page has to be considered relevant when a user asks a particular question. Being stored somewhere does not guarantee selection for that query.
Synthesis: The answer generator has to use the retrieved information accurately and preserve material qualifications.
Attribution: The interface has to decide whether and how to display a citation. An accurate mention and a visible link are separate outcomes.
This distinction matters because each failure calls for a different fix. Adding more schema won’t correct a crawler block. Rewriting a page won’t repair an outdated third-party profile. Securing a brand mention won’t necessarily produce a clickable citation.
Use the following as a fault-isolation chart, not as proof of a cause. One observation is a lead; repeated tests and access evidence are what establish the diagnosis.
What you observe
Earliest likely failure
What to inspect next
The URL is absent everywhere you test
Discovery or access
Sitemaps, internal links, server responses, robots.txt, page-level directives, and authentication requirements
One engine uses the current fact while another gives an older answer
Retrieval freshness or a stale copy
The URLs each engine cites, cached or syndicated versions, and the last verified canonical update
The answer is accurate but has no link
Attribution or interface behavior
Track the mention as answer inclusion, then record citation presence separately
A third-party profile is cited instead of your site
Source selection or owned-page access
Whether the profile is more complete, more current, easier to parse, or the only version available to that engine
Your page is cited for branded questions but absent for category questions
Retrieval or evidence strength
Whether the page directly answers the non-branded need and supports its claims with specific, verifiable information
Audit the entire route from page to AI answer
Start with a query-level audit. A domain-wide score can hide the difference between a commercially important failure and an irrelevant miss. Choose questions tied to an actual decision: selecting a provider, verifying a product capability, comparing an approach, confirming eligibility, or checking whether information is current.
Define the fact that should survive the journey. Write down the exact claim an accurate answer needs to contain, the canonical URL that supports it, and any condition that must remain attached. If a limitation changes the meaning, include it in the expected answer.
Separate branded, non-branded, and verification queries. A branded prompt tests whether the engine recognizes your entity. A non-branded prompt tests whether you are retrieved for the problem you solve. A verification prompt tests whether the engine can confirm a precise fact. Do not blend these intents into one score.
Keep test conditions stable. Use the same query wording while comparing engines. Record the product, model or mode when displayed, date and time, account state, region when relevant, and whether web retrieval was enabled. Change one variable at a time.
Capture the answer before judging it. Save the wording, named entities, qualifications, citations, linked URLs, and any visible freshness indicators. Mark factual accuracy and citation presence in separate fields.
Trace every cited URL. Determine whether the engine selected your canonical page, a syndicated copy, a marketplace listing, a social profile, an aggregator, or another publisher. That choice reveals which data route is currently carrying your visibility.
Inspect the owned page as a machine receives it. Check the response status, redirect chain, canonical target, robots.txt rules, meta robots directives, X-Robots-Tag headers, rendered content, and the text available without a user completing an interaction. Confirm that the critical claim is present in the accessible page body.
Classify the earliest failure. Label it discovery, access, parsing, retrieval, synthesis, attribution, or external-copy drift. Fix that layer first. Later-stage optimization cannot compensate for an earlier-stage block.
Your audit sheet should preserve evidence, not just a final grade. Useful columns include query ID, intent, expected fact, canonical URL, engine, mode, test conditions, answer text, accuracy, qualification preserved, citation present, cited domain, cited URL, access result, failure class, owner, and next action.
Retest after a meaningful change to content, access controls, structured data, distribution, or a cited external record. Avoid repeatedly changing the prompt until you receive the answer you want. That measures prompt manipulation, not dependable visibility.
Build visibility that can survive platform boundaries
You cannot force every AI platform to ingest, retrieve, or cite your content. You can make your facts easier to obtain through permitted routes and reduce the damage when a platform changes its access policy.
Maintain a canonical fact layer on property you control
Give every decision-critical fact a stable home. The page should state the fact plainly, identify the entity it belongs to, carry necessary conditions beside the claim, and show the information needed to judge freshness. Essential information should not exist only in an image, video, downloadable file, tab, or client-side widget.
Create a fact register for content that commonly drifts. For each item, record:
The approved wording and any mandatory qualification
The canonical URL and responsible owner
The visible page element where the fact appears
The structured-data field, if one legitimately applies
The event that should trigger an update
The approved external channels carrying a copy
This turns freshness into an operating process. When a product detail, policy, service area, leadership record, or other material fact changes, you know which owned page and external records need attention.
Use external platforms as distribution, not the master record
Third-party platforms can be valuable discovery routes, especially when an AI engine has stronger access to them than to your site. They also create dependency. A profile can become stale, change format, restrict access, or disappear from an engine’s retrieval set.
Publish a compact, consistent version of important facts on approved channels, then maintain a map from each external record back to its canonical owner. Avoid copying every page everywhere. Full duplication multiplies the places where old wording can survive. Distribute the facts a channel genuinely needs, preserve qualifications, and link to the canonical page where the channel permits it.
If a platform restricts automated access or reuse, do not bypass its controls to create an unofficial data pipeline. Use its approved API, feed, export, publishing workflow, or licensing route. Circumventing access rules can create contractual or legal exposure, and the resulting pipeline is likely to break without notice.
Treat structured data as translation, not permission
JSON-LD helps a parser connect a page to an entity and interpret supported properties. It does not grant crawler access, compel retrieval, prove a claim, or guarantee a citation.
Use the schema type that matches the visible entity and content. Keep names, identifiers, URLs, dates, and relationships consistent with the page. Do not place promotional or unsupported claims in markup that a reader cannot verify in the visible content. After publishing, validate both the syntax and the rendered values; syntactically valid markup can still describe the wrong entity or carry an outdated field.
Support the same canonical layer with ordinary discovery mechanisms such as coherent internal links, XML sitemaps, useful page titles, stable URLs, and feeds where appropriate. For partners that accept structured submissions, maintain those feeds from the same fact register instead of editing each destination independently.
Measure access, inclusion, and citation separately
A blended AI visibility score can rise while the wrong fact is being repeated, or fall because an interface stopped displaying citations even though your information still shapes answers. Keep the signals separate so each metric leads to a clear decision.
Signal
Evidence to record
Decision it supports
Technical availability
Response, redirect, crawler rule, authentication, and returned HTML
Whether discovery and access need repair
Content extractability
Whether the expected fact and qualification appear in the fetched or rendered text
Whether essential content must be moved, clarified, or exposed more reliably
Answer inclusion
Whether the answer accurately contains the expected fact or entity
Whether retrieval and content relevance are working
Citation attribution
Whether a citation appears and which exact domain and URL receive it
Whether owned visibility or an external dependency carries the answer
Factual alignment
Correct, incomplete, contradicted, or unsupported, with the answer text preserved
Which misinformation or missing qualification needs priority
Freshness
Whether the answer matches the current canonical record and which version appears to be used
Whether an old owned page, stale external copy, or retrieval lag needs investigation
Cross-platform coverage
The result for each engine and query rather than one combined rank
Which platforms matter enough to justify targeted work
Dependency concentration
Which external domains repeatedly carry mentions or citations
Where loss of access could remove a large part of your visibility
Use clear labels such as pass, partial, fail, and not observable, then retain the underlying evidence. Not observable is important: you usually cannot inspect an engine’s private corpus or prove why it selected a particular passage. State what the test demonstrates and keep inference separate.
Prioritize wrong and outdated facts before missing citations. Next, fix owned-page access and parsing problems that affect several queries. Then address stale external copies and weak non-branded retrieval. An accurate uncited answer may still matter, but it should not be reported as equivalent to an owned citation.
Do not treat every engine discrepancy as a data-access failure. Query wording, retrieval timing, answer mode, personalization, and normal generation variation can also change the result. A stable query set, captured citations, server evidence, and repeated observations help you distinguish a platform pattern from a one-off response.
Key takeaways for an AI search access strategy
AI visibility is platform-specific because engines do not necessarily discover, access, retrieve, or cite the same data.
A public URL is not automatically discoverable, fetchable, parseable, retrievable, or eligible for visible attribution.
Audit the answer path in order and fix the earliest failing layer before changing later-stage content or schema.
Track accurate inclusion and visible citation as separate outcomes.
Keep critical facts on an owned canonical page, then distribute controlled versions through approved external routes.
Use JSON-LD to clarify visible information, not to replace access, evidence, maintenance, or content quality.
Measure each engine and query independently, preserve the evidence, and mark private platform behavior as inference rather than fact.
Start with one page tied to a real customer decision. Write down the fact it must communicate, test the corresponding query across the AI products your audience uses, and trace the route from discovery through citation. Fix the first broken layer, update every approved copy from the same fact register, and repeat the test after the change. That gives you a visibility system you can operate even when the surrounding platforms keep moving.
You are probably not short of AI SEO tools to evaluate. The harder problem is deciding which ones deserve a place in your stack when several products generate briefs, audit pages, track prompts, suggest schema, and summarize reports in slightly different ways.
The answer is not to buy the platform with the longest AI feature list. Build a system in which every tool produces evidence, that evidence leads to a named decision, and a person verifies the result before it changes a page. That gives you a stack that can support conventional search, answer engines, and generative search without paying for three versions of the same dashboard.
Choose tools by the decision they improve
Tool consolidation and AI adoption are happening at the same time. In the 2025 MarTech Replacement Survey’s cohort of 154 marketers who had replaced an application in the preceding year, 43.8% cited cost reduction, while 37.1% considered AI capabilities crucial and 33.9% wanted AI features in a new tool. Those figures describe one survey cohort, not the entire market, but they expose the decision most SEO teams now face: add AI capability without adding another layer of overlapping cost.
Start by inventorying decisions rather than products. Your working stack needs to cover these jobs:
Technical discovery: identify crawling, indexing, rendering, internal-linking, response-code, and metadata problems that block or weaken discovery.
Demand and intent: connect queries and audience questions to the page that should answer them.
Entity and structured-data management: make the people, organizations, products, topics, and relationships on a page explicit and internally consistent.
Search and AI visibility monitoring: record rankings, impressions, mentions, linked citations, cited URLs, and the accuracy of generated descriptions.
Workflow and reporting: turn findings into tickets, briefs, annotations, summaries, and accountable next actions.
One platform may cover several jobs. That is useful only when the outputs remain specific enough to act on. A single interface filled with generic scores is not an integrated stack; it is a consolidated reporting problem.
Use a keep, replace, remove, or build audit
Assign every current tool to one of four buckets:
Keep it when it produces evidence you use, fits the workflow, and has a clear owner.
Replace it when an important requirement is missing, the data cannot be exported, or another product can remove genuine duplication.
Remove it when nobody can name a recent decision that changed because of its output.
Build a narrow utility when your process, data model, or reporting logic is genuinely specific to your business.
For each product, complete this sentence: “When the tool shows ______, the owner does ______, and success is checked with ______.” A blank in any position reveals the real gap. You may have a data problem, an ownership problem, or a validation problem rather than a software problem.
Do not accept “AI-powered” as a requirement. Translate it into an observable capability. For example: classify a crawl export by likely impact; preserve citations when summarizing evidence; identify the URL cited in an answer; generate JSON-LD from approved fields; or turn approved metrics into a report narrative without changing the underlying numbers.
Custom software has become more plausible for these narrow jobs. Homegrown applications accounted for 8.1% of replacements in the 2025 survey, up from 3.4% in 2024. That is evidence of renewed interest, not proof that building is automatically cheaper. Buy common infrastructure such as crawling when a mature product already solves the problem. Consider building the small connector, classification rule, or reporting layer that reflects how your organization actually works.
Make vendors demonstrate the evidence trail
A useful evaluation should begin with your data and end with your decision. Give each shortlisted tool the same representative input, then inspect the complete path from evidence to recommendation.
Can you see the page, query, answer, citation, crawl row, or measurement behind a recommendation?
Can you export the raw evidence and the processed result in a usable format?
Can you distinguish observed facts from the tool’s interpretation?
Can you segment results by page type, intent, market, language, or another dimension that matters to your decisions?
Can a reviewer correct the output without rebuilding the workflow outside the product?
Can you connect the finding to an owner, ticket, brief, or content update?
Does the tool replace an existing cost, or does it merely add a new dashboard?
If a vendor can show a polished recommendation but not the evidence behind it, treat the output as a hypothesis. That distinction matters more in AI search because an answer can change across prompts and contexts. A tool that preserves the prompt, response, cited URL, date, and evaluation conditions gives you something you can audit. A visibility score without those components is much harder to interpret.
Put AI on high-friction work, not final judgment
AI earns its place in an SEO workflow when it reduces the effort between raw input and a reviewable result. It should not quietly become the authority that decides whether a claim is true, a page satisfies intent, or code is safe to deploy.
Use a repeatable prompt specification rather than an improvised request. Give the model the page’s purpose, audience, target query or task, approved evidence, constraints, required output format, and review criteria. Tell it how to mark uncertainty and what it must not invent. The last instruction is especially important when the input does not contain enough evidence to complete every field.
Accelerate content work without outsourcing expertise
Several practical AI-assisted SEO workflows share the same pattern: the model creates options or performs a first pass, while a person supplies expertise and approves what gets published.
First drafts: provide a real brief, audience, intended angle, target query, source material, and exclusions. Ask for a structure before a full draft. The editor must then add original reasoning, examples supported by evidence, and the publication’s voice.
Content refreshes: give the model the existing page, its target intent, performance context, and current approved facts. Ask it to separate missing coverage, stale material, unsupported claims, structural problems, and optional expansion ideas. Verify each proposed change rather than accepting a rewritten page wholesale.
Titles and descriptions: generate variations within your supplied constraints, then choose or combine them manually. Check that each option accurately describes the page; an enticing promise that the page does not fulfill is not optimization.
FAQ development: use AI to organize questions found in query research and audience conversations. Remove duplicates, verify that each question belongs on the page, and write answers from approved evidence. Do not manufacture an FAQ merely to create schema.
Alt text: supply the image and its function in the surrounding page, not just a filename. Review the result for accessibility and accuracy. A target keyword belongs only when it naturally helps describe the image.
The quality check is simple: can the reviewer identify what was supplied by the evidence, what was inferred by the model, and what was added by an expert? If those layers are blended together, the workflow is too opaque for reliable publishing.
Use AI as a technical interpreter and code assistant
Technical SEO often contains small, high-friction tasks that suit supervised generation:
Translate an error message or log excerpt into plain language, possible causes, evidence needed, and reversible diagnostic steps.
Generate a regular expression for a clearly described Google Search Console filter, then test it against examples that should and should not match.
Classify a crawl export into issue types and propose an order of investigation, while preserving the original rows used for each recommendation.
Generate JSON-LD from approved page facts and a named schema type, then compare every value with the visible page before validation.
AI-generated code can be syntactically tidy and still be wrong. Test regular expressions on a limited dataset. Validate structured data before deployment. Treat suggested fixes to templates, redirects, canonical tags, robots directives, or rendering behavior as code changes that require review and a rollback path.
Separate reporting observations from explanations
AI can help scan performance exports for anomalies, compress a long report into an executive summary, or draft the narrative connecting several approved metrics. The model should never be allowed to turn correlation into a confident cause.
Require reporting output in four labeled parts:
Observation: what changed in the supplied data.
Possible explanations: hypotheses that could account for the change.
Evidence still needed: data required to distinguish those explanations.
Next action: the check, experiment, or decision an owner should make.
This structure makes AI useful without hiding uncertainty. It also creates prompts worth saving. A maintained prompt library for recurring briefs, crawl analysis, metadata, reporting, and schema tasks is more valuable than repeatedly improvising requests, because the inputs, constraints, and review standard become part of the operating process.
Optimize pages for retrieval, comprehension, and citation
An AI visibility tool cannot compensate for a page that is inaccessible, unfocused, internally inconsistent, or difficult to support with a citation. Conventional SEO remains the retrieval layer. Answer engine optimization and generative engine optimization add a comprehension and representation layer on top of it.
Build each important page around a clear evidence path:
Assign one dominant intent. Decide which real question, comparison, task, or decision the page should resolve.
State the direct answer early. Do not make a reader or retrieval system work through several paragraphs before discovering the page’s position.
Break complex material into answerable units. Use descriptive headings, a direct explanation, applicable conditions, necessary caveats, and the supporting detail needed to act.
Keep entity names and attributes consistent. A product, organization, person, date, or feature should not acquire different names or conflicting descriptions across the title, body, metadata, structured data, and linked pages.
Support important claims where they appear. Link the words carrying the fact, and distinguish evidence from your interpretation.
Connect related pages deliberately. Internal links should tell a reader what the destination adds, not rely on vague anchor text.
Confirm technical availability. The intended canonical page must be crawlable, indexable where appropriate, renderable, and free from contradictory directives.
This approach also makes editorial review easier. A reviewer can inspect one answer unit at a time and ask whether it is clear, supported, current, and useful. That is a better quality control mechanism than chasing an aggregate optimization score.
Treat schema as a translation layer, not a ranking switch
Structured data gives machines explicit labels for information that may otherwise be expressed only in prose. It can clarify what a page and its entities represent, but it does not repair weak content, establish that an unsupported claim is true, or guarantee a citation in an AI answer.
Use this schema workflow:
Extract the facts that are visibly present on the page.
Select a schema type that accurately represents that page, such as Article for an editorial page or FAQ when genuine questions and answers appear in the visible content.
Generate or author the JSON-LD from those approved facts.
Compare every populated property with the visible page, including names, descriptions, dates, relationships, and URLs.
Validate the markup. AI can generate Article or FAQ JSON-LD quickly, but the resulting code should still be checked with Google’s Rich Results Test where applicable.
Publish through a controlled template or field mapping so later page edits do not leave stale values in the markup.
Recheck the rendered page and structured data after deployment.
Validation proves that a parser can understand the code and may surface eligibility issues. It does not prove that the data is accurate, that a search feature will appear, or that a language model will cite the page. Those remain separate checks.
Schema also should not become an isolated technical project. AI-search strategy increasingly connects technical foundations, content, social activity, public relations, mentions, and citations. The practical lesson is not that every channel needs another tool. It is that your content and reporting systems need a shared view of the entities, claims, questions, and pages the organization wants to be known for.
Measure AI visibility without disguising it as rank tracking
Rank tracking records an ordered search result under defined conditions. AI answer monitoring records a generated response that may vary with wording, context, system behavior, market, and time. Putting both into one visibility score may be convenient, but it can hide what actually changed.
License cost, active use, duplicated output, integration burden, maintenance owner
Whether to keep, replace, remove, or build
Clicks remain useful, but they cannot describe every zero-click or AI-generated experience. That is one reason teams now seek tools that can measure visibility beyond traditional rankings and clicks. Do not solve that limitation by treating every brand mention as equivalent. An unlinked mention, a citation to your page, a citation to someone else’s page, and an inaccurate description are four different outcomes.
Create a repeatable AI-answer benchmark
Build the benchmark from questions that matter to the business, not prompts chosen because the brand already performs well. Include the informational questions, comparisons, objections, and decision-stage tasks that your priority pages are meant to resolve.
Freeze the wording of each benchmark prompt and document its intended user intent.
Record the engine, market or language conditions, date, complete response, citations, and cited URLs.
Capture a baseline before changing content, templates, structured data, internal links, or external promotion.
Change a single meaningful variable where the workflow allows it, and annotate every other known change.
Run the same benchmark on a planned cadence rather than testing only when you expect a favorable answer.
Look for repeated patterns across relevant prompts before claiming that an optimization caused the outcome.
A mention is not automatically a success. Review whether the answer gives the correct name, category, attributes, limitations, and relationship to the user’s question. Also record which URL earned the citation. If an outdated page or a third-party page is repeatedly cited, that finding should lead to a different action than a simple absence from the answer.
Measurement should also expose automation failures. Record which AI suggestions were rejected and why. Repeated factual corrections point to an evidence or prompting problem. Repeated voice corrections point to an editorial specification problem. Repeated technical corrections point to a workflow that needs stronger tests, not a model that needs more freedom.
Key takeaways and your first move
Choose an AI SEO tool only when you can name the decision it improves, the evidence it preserves, the owner who acts, and the way the result will be checked.
Keep conventional crawling, indexing, intent, and content quality at the base of the stack. AI visibility monitoring adds a measurement layer; it does not replace the retrieval layer.
Use AI for first passes, classification, variants, interpretation, and formatting. Keep factual approval, strategic judgment, and deployment control with a qualified reviewer.
Make pages easier to retrieve and cite by answering a defined question, using consistent entities, supporting claims in place, and connecting related pages clearly.
Use schema only when it matches visible content. Validate the code and verify the facts separately.
Track generated answers with their exact prompts, citations, cited URLs, conditions, and accuracy. Do not compress unlike outcomes into one unexplained visibility score.
Your first move does not require a new subscription. Open the current stack inventory and complete the evidence-action-validation sentence for every tool. Remove the entries nobody can complete. Then choose one recurring workflow with visible friction, such as turning a crawl export into reviewed tickets or turning an approved brief into a review-ready draft. Define its inputs, output, owner, and checks before testing automation.
Once that workflow is reliable, extend the same operating model to structured data and AI-answer monitoring. You will know what to buy because the missing capability will be explicit, and you will know whether it worked because the evidence trail already exists.
You can have a fast, attractive website that still leaves an AI system guessing. A person may work around a price that appears late, two conflicting policy pages, an unlabeled button, or a confirmation shown only through a visual change. A machine may stop, cite the wrong fact, or repeat an action because it cannot tell whether the first attempt worked.
The goal is not to rebuild your site for bots at the expense of people. It is to make public information retrievable, meaning explicit, and actions safely bounded. That is the practical response to the shift toward machine-led website visits. This audit shows you where to look and what a passing result should look like.
Audit the journey, not the bot name
Agent readiness is broader than allowing a particular crawler through robots.txt. An AI search system may retrieve a page to answer a question, compare facts across pages, send a person to a landing page, or help a signed-in user complete a task. Each journey fails differently.
Start with the intent that matters, then follow it from request to outcome. Choose priority journeys from three groups: finding an answer, making a decision, and taking an action. Write the expected result before you test so that a plausible but incorrect response does not pass by accident.
Journey
What the machine needs
What failure looks like
Answer or cite
A public, stable page with a direct answer and enough context to interpret it
The answer is absent from the retrieved HTML, buried in an image, or contradicted elsewhere
Compare and decide
Consistent names, identifiers, attributes, prices, conditions, and limitations
The same offer has different facts across the page, structured data, and linked policies
Act and confirm
Clearly labeled controls, explicit prerequisites, bounded permissions, and a machine-readable result
The agent cannot identify the correct control, understand an error, or confirm whether the action succeeded
For each journey, name the authoritative page, the facts that must be preserved, the actions that are permitted, and the state that proves completion. This turns an abstract AI-readiness project into a set of testable requirements.
Make important pages retrievable without guesswork
A page is not agent-ready merely because it looks correct in your browser. Your browser may have cookies, cached scripts, a logged-in session, and enough processing time to assemble the page after the initial response. A fresh machine client may have none of those advantages.
Test every priority URL from a clean, logged-out session. Inspect the returned HTML as well as the rendered screen. The page title, primary heading, main answer, relevant entity name, and essential links should be available without requiring a person to reveal them through hover effects, tabs, or visual-only controls. When a fact is central to the page, do not assume every client will execute and wait for the same JavaScript path as a full browser.
Confirm that the preferred URL returns a successful response and does not enter a redirect loop, soft-error state, consent loop, or challenge page.
Review robots.txt, meta robots directives, and the X-Robots-Tag together. An accidental conflict can make an otherwise public page unavailable. Robots directives are discovery instructions, not security controls, so private information still belongs behind real authentication.
Use one canonical URL for each primary resource. Internal links, canonical tags, redirects, and the XML sitemap should agree on that URL.
Keep the sitemap focused on live, canonical pages that you actually want discovered. Remove obsolete, redirected, private, and erroring URLs rather than asking machines to sort through them.
Link important pages through ordinary crawlable navigation. Descriptive link text such as “Enterprise pricing” carries more meaning than repeated links labeled “Learn more.”
Provide an HTML version of essential facts that otherwise live only in an image, video, downloadable document, or interactive widget.
Test firewall, bot-management, content-delivery, and rate-limit rules with a fresh client. Record whether a failure comes from the application or from an infrastructure layer in front of it.
Never weaken authentication to make an agent test pass. Keep protected data protected and expose only the public information or authorized interface the task genuinely requires.
A useful retrieval record includes the requested URL, response status, final URL after redirects, declared canonical, applicable robots directives, and whether the required facts appeared in the response. A screenshot can confirm appearance, but it cannot replace those checks.
Make the page’s meaning explicit in content and JSON-LD
Once a machine can retrieve a page, it still has to identify what the page describes and which claims belong together. Ambiguity usually enters through inconsistent naming, missing qualifiers, stale duplicates, and structured data that says something different from the visible page.
Give each priority page a clear job. Put the direct answer near the point where the page establishes the question or offer, then supply the evidence, conditions, and alternatives a reader needs. Do not force the machine to combine fragments from a feature grid, tooltip, footer, and separate policy page just to understand the basic proposition.
Name the entity in full before relying on abbreviations or pronouns. If two products, locations, plans, or organizations have similar names, state the distinction on the page.
Attach qualifiers to the claim they modify. Geography, currency, billing period, eligibility, availability, effective date, tax treatment, shipping limits, and plan restrictions should not be left to implication.
Use stable identifiers where your operation already has them, such as a product code, plan name, location identifier, or internal service name. Keep the same identifier across templates, feeds, and structured data.
Choose an authoritative home for reusable facts such as the legal organization name, support contact, returns policy, or service-area definition. Other pages should link to or consistently reproduce that truth.
Update, redirect, remove, or clearly label stale pages. Two accessible pages that make incompatible claims create an interpretation problem even when only one appears in navigation.
Show ownership and maintenance information where it helps a reader judge the claim, such as an author, responsible team, publication date, or last reviewed date. Do not add decorative dates that are unrelated to a substantive review.
Use JSON-LD to restate and connect meaning that is already visible. Select the most specific appropriate schema type for the resource, such as Organization, Product, Service, Article, or BreadcrumbList. Treat the type as a description of the actual page, not as a keyword target.
Make names, URLs, prices, availability, dates, and identifiers agree with the visible content.
Give important entities stable @id values and reuse those identifiers when another object refers to the same entity.
Connect related objects deliberately. An article’s publisher, a product’s brand, and a service’s provider should resolve to the organization you actually mean.
Include only properties you can support and maintain. An empty or guessed field adds ambiguity rather than clarity.
Validate syntax after template changes, then inspect the generated object for meaning. Syntactically valid markup can still describe the wrong entity or carry stale values.
Do not use structured data to make claims that a person cannot verify on the page. Markup cannot repair inaccessible, contradictory, or inaccurate content, and it does not guarantee inclusion in an AI answer.
The final check is simple: read the visible page and the JSON-LD side by side. If they would lead a careful reader to different conclusions, the page is not ready.
Treat agent actions as controlled transactions
Retrieving a shipping policy is a read. Changing an address, booking an appointment, placing an order, publishing content, or deleting data is a write. Your design should preserve that boundary even when the same assistant handles both parts of the journey.
Public facts should not require authentication without a business reason. Actions that expose personal data or change state should require an authenticated, authorized user. Do not create a machine-only shortcut around the permission model used by your human interface.
Use real links, buttons, and form controls with persistent programmatic names. An icon, color change, or visual position alone is not a dependable instruction.
Give every field a label and every validation failure an actionable message. State what is missing or invalid and preserve valid input so the task can continue.
Show prerequisites and consequences before submission. Required documents, inventory constraints, cancellation terms, units, time zones, and final charges belong before the committing action.
Require review or explicit user confirmation before consequential actions involving payment, publication, deletion, cancellation, or a binding reservation. Automation is not a reason to remove a safety boundary.
Make retries safe. If a client repeats a request after a timeout, the system should not silently create duplicate orders, bookings, messages, or records.
Return an unambiguous result after submission. The response should state whether the action succeeded, failed, remains pending, or requires another step, along with the relevant record or transaction identifier.
Keep errors distinct from success states. A generic page refresh, disappearing modal, or disabled button does not prove what happened.
Apply the least privilege needed for the requested task. Scope credentials, sessions, and connected tools so that a narrow action does not grant unrelated access.
Log enough context to investigate a failure or duplicate action, while avoiding unnecessary capture of personal data, credentials, or sensitive form contents.
Test consequential paths in a staging environment or with a non-destructive mode whenever possible. If a production check could charge money, delete data, publish material, or create a real reservation, use an authorized test path rather than discovering the guardrails through a live transaction.
Measure readiness from fetch to business outcome
Referral traffic is useful, but it is not a complete AI-search scorecard. A system may use your information without sending a click, while a detected visit may still land on an inaccurate or unusable page. Keep the stages separate so you know which problem you are fixing.
Availability: Can a clean client retrieve the preferred page, and are canonical and robots signals aligned?
Comprehension: Can the required answer and its qualifiers be extracted from the visible content? Do the structured data and page agree?
Representation: Does a fixed set of relevant prompts produce an accurate description, mention, or citation on the AI surfaces you monitor? Record the prompt, surface, location or account context, date, output, and cited URL so later checks are comparable.
Referral: Which detectable AI referrals reach the site, where do they land, and do they engage with the intended next step? Treat missing referral data as unknown, not as proof that your content was never used.
Outcome: Do those visits or assisted journeys produce the qualified lead, completed task, sale, subscription, support resolution, or other result the page exists to support?
Create a worksheet with a row for each priority intent. Include the authoritative URL, approved answer, required fields, expected entity, permitted action, passing condition, owner, last test date, observed output, and remediation status. A useful AEO system of record should show where performance is strong and why, not merely accumulate screenshots and isolated visibility scores.
Establish a baseline before changing templates or access rules. Rerun affected journeys after changes to navigation, rendering, structured data, robots directives, authentication, forms, firewall policy, or core content. Keep the prompt and acceptance criteria fixed when you want a meaningful comparison; create a new test when the underlying intent changes.
Key takeaways
AI-agent readiness has four practical layers: retrieval, interpretation, safe action, and measurement.
A passing visual check is not enough. Inspect the response, redirects, canonical, robots directives, rendered content, and required facts.
Visible content and JSON-LD must describe the same entity with the same claims, identifiers, and qualifiers.
Read access and write access need different controls. Consequential actions require authorization, confirmation, retry protection, and an explicit final state.
Measure fixed intents across availability, comprehension, representation, referral, and outcome instead of treating traffic as the whole result.
Technical readiness improves eligibility and reduces ambiguity, but it cannot guarantee ranking, citation, recommendation, or agent selection.
Start with a revenue page, a policy page, and a consequential conversion path. Fetch them logged out, compare their visible facts with their JSON-LD, complete the permitted action in a safe environment, and record every point where the result becomes ambiguous. Fix those failures before expanding the audit across the rest of the site.
During a recent study, I discovered that Reddit stands out as the most-cited domain in AI-generated answers. In fact, it’s ahead of heavyweights like YouTube and LinkedIn, thanks to an analysis of 30 million sources conducted by Peec AI, a tool specializing in AI search analytics.
The findings: I’ve learned that Reddit claims the top spot across various AI platforms including ChatGPT, Google AI Mode, Gemini, Perplexity, and AI Overviews. Top contenders YouTube, LinkedIn, Wikipedia, and Forbes are right behind. Platforms like Yelp and G2 frequently appear when searching for recommendations.
As I delved deeper into the research, it became clear which domains the AI models tend to lean on:
ChatGPT values Wikipedia, Reddit, and editorial sites like Forbes.
Google shows preference for platforms such as Facebook and Yelp.
Perplexity favors Reddit, LinkedIn, and G2 for queries within the B2B realm.
Why we care: The insight that resonated with me was the importance of having authority beyond just our own websites. Brands that consistently feature on reputable third-party platforms have a better chance of being cited by AI.
Why these sources? It’s fascinating to see how AI systems are wired to prioritize both authority and authentic user input:
I’ve found that Reddit excels because it mirrors genuine user discussions.
YouTube shines in video citations, owing to their comprehensive transcripts and descriptions.
Wikipedia not only serves real-time data but also acts as a foundation for training datasets.
About the data: The analysis spanned 30 million sources, providing a comprehensive look at how often domains are directly cited in AI answers, effectively revealing what shapes these responses.
According to a recent, though unverified, report, Google Gemini’s AI is designed to tailor its responses based on the user’s tone, intent, and emotional context. This fascinating development suggests that the AI aligns its answers with the emotional backdrop of each query.
Why This Matters. If this information holds true, it means that the responses generated by AI might vary significantly, depending on how we phrase our queries, rather than just on the data available. This could change the way we engage with search engines.
New Findings. At the heart of this revelation is a system called upcast_info. As reported by Elie Berreby, head of SEO and AI search at Adorama, this system seems to provide the blueprint for how Gemini processes user queries, aiming to:
Reflect the user’s tone, energy, and purpose.
Acknowledge emotions before formulating a response.
Deliver answers from the user’s perspective.
Implications. Instead of maintaining a neutral stance, the AI’s responses could:
Emphasize negative perspectives (“Why is X bad?”).
Highlight positive aspects (“Why is X great?”).
Should the public sentiment toward a topic be negative, the AI might intensify that sentiment. As the report indicates:
AI mirrors prevalent emotional signals.
It doesn’t offer the balancing act usually provided by traditional search result links.
The Role of Query Framing. The emotional tone of a query can impact:
The choice of sources cited.
The style of summaries presented.
The overall tone and substance of the answers.
Google’s AI Overviews already demonstrate shifts in tone that align with the intent of queries, providing potential insight into the mechanics behind these changes.
Unsubstantiated Information. Google has yet to confirm this leak. As Berreby mentions: “I’ve decided to share just a portion of the leaked internal system data publicly. It’s not a security exploit or major breach, just a minor leak.”
A customer who searches Google for a nearby provider and another who asks ChatGPT for a local recommendation may want the same outcome, but they reach it through different discovery systems. If you optimize only for the map pack or only for conversational answers, your business can be easy to find in one place and absent in the other.
Your job is to establish one dependable record of each location, then present and measure that record appropriately on each surface. That means treating your Google Business Profile, location page, visible business facts and structured data as one system without pretending Google and ChatGPT have the same ranking model.
Google and ChatGPT answer different versions of a local question
Google local discovery is strongly tied to explicit profile fields and geography. Your business name, primary category, secondary categories, services, reviews, linked landing page and physical proximity can all shape where the business appears. A geo-grid can show that visibility changing from one neighborhood or city boundary to the next.
ChatGPT handles the discovery moment as a conversation. The user can describe a service, constraint and area in ordinary language, and shared location can make the local response more precise. Location is therefore a meaningful input, but that does not establish a permanent ChatGPT rank comparable to a map-pack position.
This distinction changes how you work. Measure Google across physical points on a grid. Evaluate ChatGPT with repeatable prompts and controlled location context. A strong result on either surface is useful, but it cannot serve as a proxy for the other.
Key takeaways
Build a single, accurate location record before optimizing individual discovery surfaces.
Audit Google Business Profile signals against the businesses that actually rank in your local grid, not against generic benchmarks.
Use a dedicated page for each real location and align it with the profile that links to it.
Keep LocalBusiness structured data consistent with facts a visitor can see on the page.
Test ChatGPT with fixed prompts and compare responses with and without shared location when that option is available.
Treat proximity limits and conversational omissions as different problems requiring different fixes.
Start with a five-part Google Business Profile audit
A profile audit becomes useful when it explains a visibility gap. Begin with the competitors appearing for the same commercial query in the areas you want to reach. Their lifetime review totals may look impressive, but totals alone do not tell you which signals separate the current winners.
Compare review recency and velocity. Look at how frequently leading competitors have earned reviews recently, not just how many they have accumulated. Fresh and consistent review activity can matter more than a large historical total. There is no universal target in this evidence, so derive your benchmark from the listings winning your own searches. Places Scout or Whitespark geo-grid data can help you connect review patterns with visibility. If you manage many markets, Places Scout API data can turn that comparison into a recurring monitor.
Verify the business name. A relevant keyword in a legitimate business name can have an outsized effect on local visibility. Do not add a service or city merely as a profile tactic when it is not part of the documented name. A DBA may make a name change legitimate, but it also creates legal, administrative and brand consequences. Treat it as a business decision, not a metadata shortcut.
Inspect the primary category first. The primary category can substantially influence local ranking. Compare the primary categories used by top businesses for the query you care about, then choose the closest truthful description of your core offering. Add relevant secondary categories and review the available service selections, but do not dilute the profile with categories the location cannot support.
Evaluate the linked landing page. A generic homepage forces both customers and machines to work out which location, service and contact details apply. A dedicated, keyword-focused location page can create better alignment between the profile and its destination. Check that the page identifies the same business, location and services as the profile.
Map the proximity ceiling. Visibility often contracts as the search point moves away from the location or crosses a city boundary. A ranking-radius view helps you distinguish an optimization problem from a geographic limitation. Local Falcon’s Share of Local Voice can help show the realistic reach of a location. If the business is strong nearby and consistently weak farther away, more profile edits may not solve the actual constraint.
Complete the audit before changing fields. Otherwise, a category edit, review campaign and page rewrite can overlap, leaving you unable to tell which change helped or hurt. Record the starting grid, profile configuration, linked page and recent review pattern, then make the change supported by the clearest gap.
Turn each location page into a reliable entity record
The page linked from your profile should resolve local uncertainty quickly. A visitor should not have to infer whether the location offers the requested service, whether it serves the relevant area or how to contact it. The same clarity also gives parsers less ambiguity to reconcile.
Make the visible page complete before adding schema
Identify the business and location in the opening copy using the same legitimate name shown on the profile.
Describe the primary services in plain language and keep them aligned with the profile’s categories and service selections.
Show the applicable address, service area, telephone number, opening hours and contact path.
Explain meaningful local constraints such as appointment coverage, access, service boundaries or location-specific availability.
Address the questions that determine whether a nearby customer is a fit instead of filling the page with interchangeable city-name paragraphs.
Link the corresponding Google Business Profile directly to this location page rather than sending every profile to the homepage.
If you operate multiple locations, give each real location its own URL and its own accurate details. Do not manufacture local relevance with addresses, service areas or location pages that do not represent an operating business. Besides misleading the reader, false location claims make your first-party record harder to keep consistent.
Use LocalBusiness JSON-LD to describe, not embellish
Choose the most specific LocalBusiness subtype that truthfully describes the location. Give the entity a stable @id and include relevant properties such as name, URL, telephone, address and openingHoursSpecification when those facts apply. Each physical location should have its own URL, identifier and location-specific values.
The markup should agree with the page and profile. Do not put a different name in JSON-LD, mark up an address the visitor cannot find, or use areaServed to claim places the business does not genuinely serve. Validate the syntax before deployment, then verify the rendered page still exposes the underlying facts to a human reader.
Structured data is useful for explicit entity description, but it is not a substitute for the profile, reviews, landing-page content or physical relevance. It also should not be treated as a guaranteed switch for ChatGPT inclusion. Its immediate job is simpler: prevent your own publishing stack from telling conflicting stories about the business.
Measure Google visibility and ChatGPT answers in separate loops
Use a geo-grid to diagnose Google
Run the same commercially meaningful query from fixed points around the location. Record where the business appears, where visibility fades and which competitors replace it. Mark city borders and meaningful neighborhood changes on the grid so that a geographic pattern does not get misread as a page problem.
Then compare the profile variables that can explain the pattern: recent review activity, primary and secondary categories, selected services, business name and landing-page alignment. If visibility is weak even close to the location, begin with those controllable signals. If it is strong nearby and falls away predictably, revise the target area or query expectations before considering another location. A new location should exist because demand and operations justify it, not merely to color more grid points.
Use a prompt set to diagnose ChatGPT
Build prompts from real customer decisions rather than from your brand name. Include requests for a provider offering a specific service near a named place, requests with a meaningful constraint and broader nearby requests that depend on the user’s location.
Keep the wording fixed when comparing results.
When location sharing is available, run the same local request with location shared and not shared.
Record whether the business appears, what reason is given, which business facts are used and which links or citations are shown, if any.
Flag incorrect names, services, locations and hours separately from a complete omission.
Retest under the same conditions after a meaningful profile, page or data correction.
A single conversational response is an observation, not a stable ranking report. Look for repeated patterns across the intents that matter. If the system describes the business incorrectly, inspect your visible location page, profile and structured data for conflicts. If the facts are correct but the business is not mentioned, improve the page’s explanation of who the location serves and which needs it can meet; do not randomly rewrite the profile in response to one answer.
What you observe
Likely constraint to investigate
Best next move
Google visibility is weak across the grid, including near the location
Profile relevance, review activity or landing-page alignment
Run the complete profile audit and correct the clearest competitor gap
Google is strong nearby but fades near borders or outer neighborhoods
Proximity and city geography
Target areas where the location can compete and reconsider unrealistic radius expectations
Google is strong but ChatGPT rarely mentions the business
Conversational fit or unclear first-party information
Test actual customer prompts and make services, location and constraints explicit on the page
ChatGPT mentions the business with incorrect facts
Ambiguous, incomplete or conflicting location data
Correct the visible page, profile and JSON-LD, then retest the same prompt
ChatGPT mentions the business but Google is weak
Google-specific profile or proximity signals
Use the geo-grid to separate an optimization gap from a geographic ceiling
Begin with a baseline, then choose the mismatch supported by the clearest evidence. If the Google grid collapses at a city boundary, stop expecting a title edit to erase geography. If ChatGPT gets a service wrong, correct the underlying fact before chasing mentions. If the profile is weak close to the location, audit categories, reviews and the linked page first. Fix the smallest defensible problem, rerun the same test and keep the two measurement loops separate.
I’ve recently delved into the world of AI search engines like ChatGPT, Google AI Mode, and Perplexity, and how they’re transforming the way consumers find and buy products online. It’s clear to me that if my product pages aren’t optimized for these AI assistants, I’m likely missing out on significant traffic and revenue.
What I’ve discovered is that AI assistants evaluate product pages differently than traditional search engines. They require a deep understanding of products to recommend them confidently to users with varied needs.
To ensure my product pages are AI-ready, I’ve crafted a simple scorecard focusing on six key factors:
1. Product specifications
Does the product page clearly display the product’s attributes and specifications?
AI assistants need explicit specifications to understand my products and match them with customer needs. For example, if someone asks for “an airline-friendly crate for a 115-pound dog,” the AI must see the weight limit clearly to recommend it.
Amazon excels at this, as their product pages display detailed specifications that likely boost their AI search performance.
Action item: I ensure all specifications are clearly presented on my product pages, ideally in a structured table or a list, rather than burying them in the description or marketing copy.
2. Unique selling points
Are the product’s unique benefits clearly described?
Highlighting what makes my products special gives AI a reason to recommend them over competitors. It’s crucial for AI to grasp these unique features to decide on recommendations.
Action item: I emphasize key features that set my products apart, avoiding vague claims like “high-quality craftsmanship” and instead focusing on specific differentiators.
3. Use cases and target audience
Discover everything you need to know about Mulch Glue, from safety and longevity to watering tips and delivery times.
Are the product’s intended use cases and audience clear?
AI matches products with people and their needs, not just keywords. Explicitly stating who the product is for and how it’s used makes it more likely to be recommended by AI.
Action item: I list the top use cases and audience segments for each product, considering situations, pain points, and goals.
4. FAQ section
Does the product page include an FAQ section answering common questions about the product?
FAQs can bolster AI’s confidence in recommending my products by showing they’re a good fit for specific queries. The more detailed the FAQ section, the more it helps in AI search contexts.
Action item: I gather and answer the most common questions from customer inquiries, reviews, and even competitor analysis to include on product pages.
5. Product reviews
Does the product page display customer ratings and review counts?
AI recommends products with proven reputations. Displaying a high rating and substantial number of reviews increases the chances of my products being recommended by AI.
Action item: I ensure high visibility for product ratings and review counts on every product page, possibly using third-party platforms to solicit reviews.
6. Product structured data
Does the product page include structured data for price, availability, reviews, and other key attributes?
Structured data helps AI understand my product information effortlessly and even feeds into knowledge graphs that power AI recommendations.
I understand that as AI agents engage more deeply in commerce, detailed product data becomes crucial for comparisons and purchasing.
Putting the scorecard to work
Here’s my concise strategy to audit and enhance my product pages for AI optimization, focusing on closing gaps where AI might overlook my products.
Prioritizing these optimizations means I’m not only engaging effectively but also increasing my competitiveness in the AI-driven market landscape.
If your brand ranks in conventional search but disappears when a buyer asks an AI assistant for options, you do not have a simple traffic problem. You have a representation problem. The system may not understand what your company does, may not find enough evidence to mention it, or may describe it in a way that does not help the buyer choose.
Generative Engine Optimization gives you a practical way to find and fix those gaps. The goal is not to make an AI repeat your marketing copy. It is to make your public evidence clear, consistent, extractable, and credible enough that your brand can be identified and represented accurately when it belongs in an answer.
Measure the answer, not just the search position
Generative Engine Optimization, or GEO, improves the likelihood that a brand, product, service, or expert will be correctly understood and surfaced in AI-generated answers. It matters across ChatGPT, Gemini, Perplexity, and Claude, but it should not be treated as a replacement for SEO.
SEO and GEO share much of the same foundation: accessible pages, clear information architecture, relevant content, reputable mentions, and technically sound publishing. The difference is the unit you inspect. Traditional rank tracking asks where a page appears for a query. GEO asks whether the generated answer includes your brand, understands it, places it in the right context, and supports the representation with an appropriate citation when citations are available.
An AI answer is not a permanent rank. Its wording can change with the platform, prompt, session context, and time. That makes a single screenshot weak evidence. You need a repeatable observation process that reveals patterns across the questions your buyers actually ask.
Build a prompt portfolio around decisions. Include category discovery, problem diagnosis, use cases, comparisons, constraints, alternatives, implementation questions, and branded fact checks. Use natural language and realistic context. A brand-name prompt only shows whether the system can retrieve a name it has already been given; it does not test discovery.
Capture a baseline on each relevant platform. Save the exact prompt, complete answer, platform, date, visible citations, and any important session conditions. Do not reduce the result to a yes-or-no mention.
Classify what happened. Record whether the brand was omitted, merely listed, described accurately, recommended for a suitable use case, confused with another entity, or attached to an unsupported claim.
Inspect the cited evidence. Note which pages or third-party references support the answer. A citation to your homepage tells you something different from a citation to a detailed product page, comparison, case study, or independent profile.
Repeat under comparable conditions. GEO measurement becomes useful when you can distinguish a recurring visibility gap from ordinary answer variation.
Do not collapse these observations into one vague visibility score. A mention can be prominent but wrong. A citation can be present but point to an outdated page. A brand can appear in an answer without being connected to the need that matters commercially. Keep the underlying observations visible so your team knows what to repair.
Turn each meaningful prompt into a query-to-evidence map. Put the buyer’s question on one side and the best page or external evidence capable of answering it on the other. If no suitable evidence exists, you have found a content gap. If the evidence exists but contradicts another page, you have found an entity or governance gap. If strong evidence exists but a competitor is consistently cited instead, you have found a discovery or authority gap.
Make your brand unambiguous before producing more content
Many visibility problems start below the content layer. The company name varies between profiles. A product page uses a new category label while an older page uses another. The homepage promises one audience, the About page names a second, and third-party listings preserve a description that no longer applies. Publishing more pages on top of those contradictions gives a generative system more material, but not more certainty.
Create an internal brand fact sheet before you change markup or commission new copy. This is not a page written for ranking. It is the approved record your writers, developers, public-relations team, profile owners, and partners use to keep public information aligned.
The canonical brand and product names, including capitalization and legitimate abbreviations.
A plain-language description of what the company offers and the category in which it operates.
The audiences and use cases the offering genuinely serves.
Locations, availability, pricing model, compatibility, and other constraints only when they are stable and publicly verifiable.
The official website, contact routes, owned profiles, and public organizational relationships.
Claims that are approved for public use, along with the page or evidence that substantiates each claim.
Claims, labels, or product descriptions that are obsolete and need to be removed.
Then assign every important fact a canonical public home. Your About page should establish organizational identity. Product and service pages should explain what is offered, who it is for, what it does, and where its limits are. Author or expert pages should show who is responsible for specialized content. Policy, support, and contact pages should answer the operational questions that help a reader verify the business.
Use the same core facts across those pages without cloning whole paragraphs. Consistency means the facts agree; it does not mean every page must use identical prose. Each page still needs to answer the intent that brought the visitor there.
Use JSON-LD as a consistency layer, not a secret channel
Structured data can make explicit relationships easier for machines to parse, but it cannot rescue unclear or unsupported visible content. Treat JSON-LD as a machine-readable restatement of facts a visitor can verify on the page.
Choose the most specific type that truthfully matches the page, such as Organization for the business identity, Product or Service for the relevant offering, Article for editorial content, and BreadcrumbList for page hierarchy.
Keep names, canonical URLs, identifiers, images, authorship, publisher details, and dates consistent with the visible page.
Use sameAs to connect an entity to legitimate identity profiles, not to create a loose list of every URL that mentions the brand.
Mark up offers, reviews, ratings, availability, and other commercial properties only when the information is real, current, and visible to users.
Validate the markup after publishing and again when templates, plugins, product data, or site architecture change.
Do not place stronger claims in schema than you are willing to show on the page. Hidden assertions produce a brittle identity layer and make maintenance harder. The safest rule is simple: visible content establishes the fact; structured data clarifies what the fact refers to.
Internal links complete the picture. Link the brand, product, service, category, expert, and supporting evidence with descriptive anchors. This helps a visitor move from a broad claim to its proof and makes the relationship among those pages explicit. An isolated case study or technical explanation cannot do much representational work if nothing connects it to the relevant offering.
Create evidence that can be extracted, checked, and cited
Generative systems assemble answers from passages, entities, and relationships. A page can be comprehensive yet difficult to use if the answer is buried beneath a long preamble, key nouns are replaced by ambiguous pronouns, or every claim is wrapped in promotional language.
For an important buyer question, give the answer a self-contained passage. Use a descriptive heading that states the question or decision. Follow it with a short direct answer, the conditions under which that answer holds, the evidence behind it, and the next detail a reader needs. This structure helps humans scan the page and reduces the amount of surrounding text needed to understand an extracted passage.
For example, a heading such as “Does the platform support multi-location teams?” is more useful than “More flexibility.” The answer should name the platform and define what support means. If support depends on a plan, integration, location, configuration, or workflow, say so beside the claim. A broad promise separated from its qualification is easy to misrepresent.
Build the pages your query-to-evidence map is missing
Category explanations define the problem, relevant terminology, suitable use cases, and important limitations without turning every sentence into a sales claim.
Product and service pages connect capabilities to concrete tasks, audiences, prerequisites, and constraints.
Comparison and alternatives pages explain meaningful differences, selection criteria, and cases where another approach may be a better fit. A fair boundary is more credible than declaring one option best for everyone.
Implementation content shows the sequence, dependencies, inputs, outputs, and failure points involved in getting a result.
Case studies and first-party evidence document what changed, in what context, how the result was measured, and what cannot be generalized. Do not turn an isolated outcome into a universal benchmark.
Research, documentation, and original tools give other publishers a reason to cite your domain rather than repeat a generic definition.
The strongest GEO content is not content that sounds as if an AI wrote it. It is content that contributes something identifiable: a precise definition, a transparent method, an original dataset, a documented workflow, a useful decision rule, a clear limitation, or accountable expertise. Generic text may cover a topic, but it gives a system little reason to associate that topic with your brand.
Apply a citability check before publication
Can a passage stand on its own without “it,” “this,” or “they” becoming ambiguous?
Does each material claim name the product, audience, condition, and limitation to which it applies?
Can the reader distinguish a fact, an interpretation, a recommendation, and a promotional claim?
Is evidence located close to the claim it supports?
Are the author, publisher, relevant dates, and update responsibility clear?
Does one canonical page own the fact, or do several pages compete with different versions?
Can crawlers access the useful content without relying on an interaction that hides it?
Do the title, headings, internal links, and structured data describe the same subject?
When a competitor is cited and you are not, resist copying its wording. Identify the job its cited page performs. It may define the category more clearly, answer the constraint directly, publish evidence you do not have, or receive corroboration from relevant third parties. Build the missing evidence for your audience instead of producing a disguised duplicate.
Run GEO as an operating cycle, not a publishing campaign
Brand visibility in AI answers crosses SEO, content, product marketing, public relations, analytics, and technical implementation. The work stalls when each team owns a fragment but no one owns the query-to-evidence map. Give one person responsibility for maintaining the prompt portfolio, routing gaps, and verifying whether completed changes improved representation.
Audit. Capture the current answers for commercially relevant and reputationally important prompts. Separate omission, inaccuracy, weak context, poor citation, and entity confusion.
Repair. Correct contradictory facts, obsolete descriptions, broken canonical relationships, inaccessible evidence, weak internal links, and structured data that disagrees with visible content.
Expand. Create the missing decision content and supporting evidence revealed by the prompt audit. Prioritize pages that answer real buyer questions rather than producing broad topic coverage for its own sake.
Corroborate. Keep legitimate business profiles consistent and earn relevant third-party coverage, references, partnerships, or citations. External mentions should confirm a real claim; placement alone is not useful evidence.
Verify. Run the same prompts again under comparable conditions. Record what changed in the answer, brand context, accuracy, and citations. Preserve misses as evidence rather than reporting only favorable outputs.
Your working dashboard should retain the prompt, intent, platform, observation date, brand status, description accuracy, cited URLs, competing entities, evidence gap, assigned action, and verification status. That record lets an editor see which page is missing, a developer see which identity signal conflicts, and a public-relations team see which claims lack independent corroboration.
Prioritize correctness before prominence. A confident but inaccurate description can create more risk than an omission. Correct the canonical public facts, remove contradictions, and make the authoritative explanation easy to find. You cannot directly edit a model’s answer, and no optimization can guarantee inclusion, but you can improve the evidence available to systems and people evaluating your brand.
Next, prioritize prompts closest to a meaningful decision and gaps you can substantively resolve. A page should not claim an unsupported advantage merely because a prompt asks for the best provider. If you lack the evidence required to make the claim, the right action is to develop the evidence or narrow the claim, not optimize the wording.
Key takeaways
Measure whether AI answers include, understand, contextualize, and accurately support your brand; a mention count alone hides the most important failures.
Resolve inconsistent brand facts before adding more content. More pages amplify contradictions as readily as they amplify clarity.
Make important answers self-contained, qualified, and close to their evidence so they can be extracted without losing meaning.
Use JSON-LD to restate visible facts and relationships, never to introduce claims the page does not support.
Map each valuable buyer prompt to the best available evidence, then use omissions and weak citations to set the content roadmap.
Treat GEO as a recurring audit, repair, expansion, corroboration, and verification cycle rather than a one-time launch.
Start with the decisions that matter most to your buyer. Capture how the major AI platforms answer those questions, choose the clearest representation failure, and repair the public evidence behind it. That first closed loop is more valuable than a large batch of speculative content because it gives your next GEO decision a visible reason and a result you can check.