Tag: AI-Driven SEO

  • Integrated AEO Growth Marketing: A Practical Operating Model

    Integrated AEO Growth Marketing: A Practical Operating Model

    Your team can publish technically sound pages and still be absent when an AI answer system handles a question you should own. The missing piece may not be another optimization tactic. It may be the gap between your answer content, technical SEO, public relations, social distribution, and measurement.

    Integrated AEO growth marketing closes that gap. It gives every channel one shared job: make a useful answer easy to find, understand, verify, repeat accurately, and connect to a meaningful next step.

    Treat AEO as an operating model, not a publishing checklist

    Answer engine optimization improves the conditions under which an AI system can discover and use information about your brand. It cannot guarantee a mention or citation. That distinction should shape your strategy: you are building a reliable information system, not inserting a keyword into a page and waiting for a predictable ranking.

    A page can contain a strong answer but receive no meaningful distribution. A PR campaign can earn attention while sending people to a vague or outdated destination. A social team can discover the audience’s real questions without returning those insights to the content team. Each channel may be performing well by its own standards while the combined system fails.

    An integrated AEO program connects five layers:

    • Demand: What is the audience trying to understand, compare, verify, or decide?
    • Answer: Which page gives that person a direct, qualified, and complete response?
    • Evidence: What supports the claims, and who is responsible for keeping that support current?
    • Distribution: How will the answer reach relevant audiences and become part of the wider conversation?
    • Growth: What useful action can the reader take, and how will you tell whether the answer contributed to it?

    This model changes what counts as completed work. A page isn’t finished merely because it was published. It needs an owner, a distribution plan, an evidence trail, a measurement definition, and a rule for revisiting it when the market or the underlying facts change.

    Look at your current reporting. If SEO reports pages, PR reports placements, social reports engagement, and growth reports conversions without a shared question or destination connecting them, you don’t yet have integrated AEO. You have several channel plans occupying the same calendar.

    Build one authoritative answer asset before planning the campaign
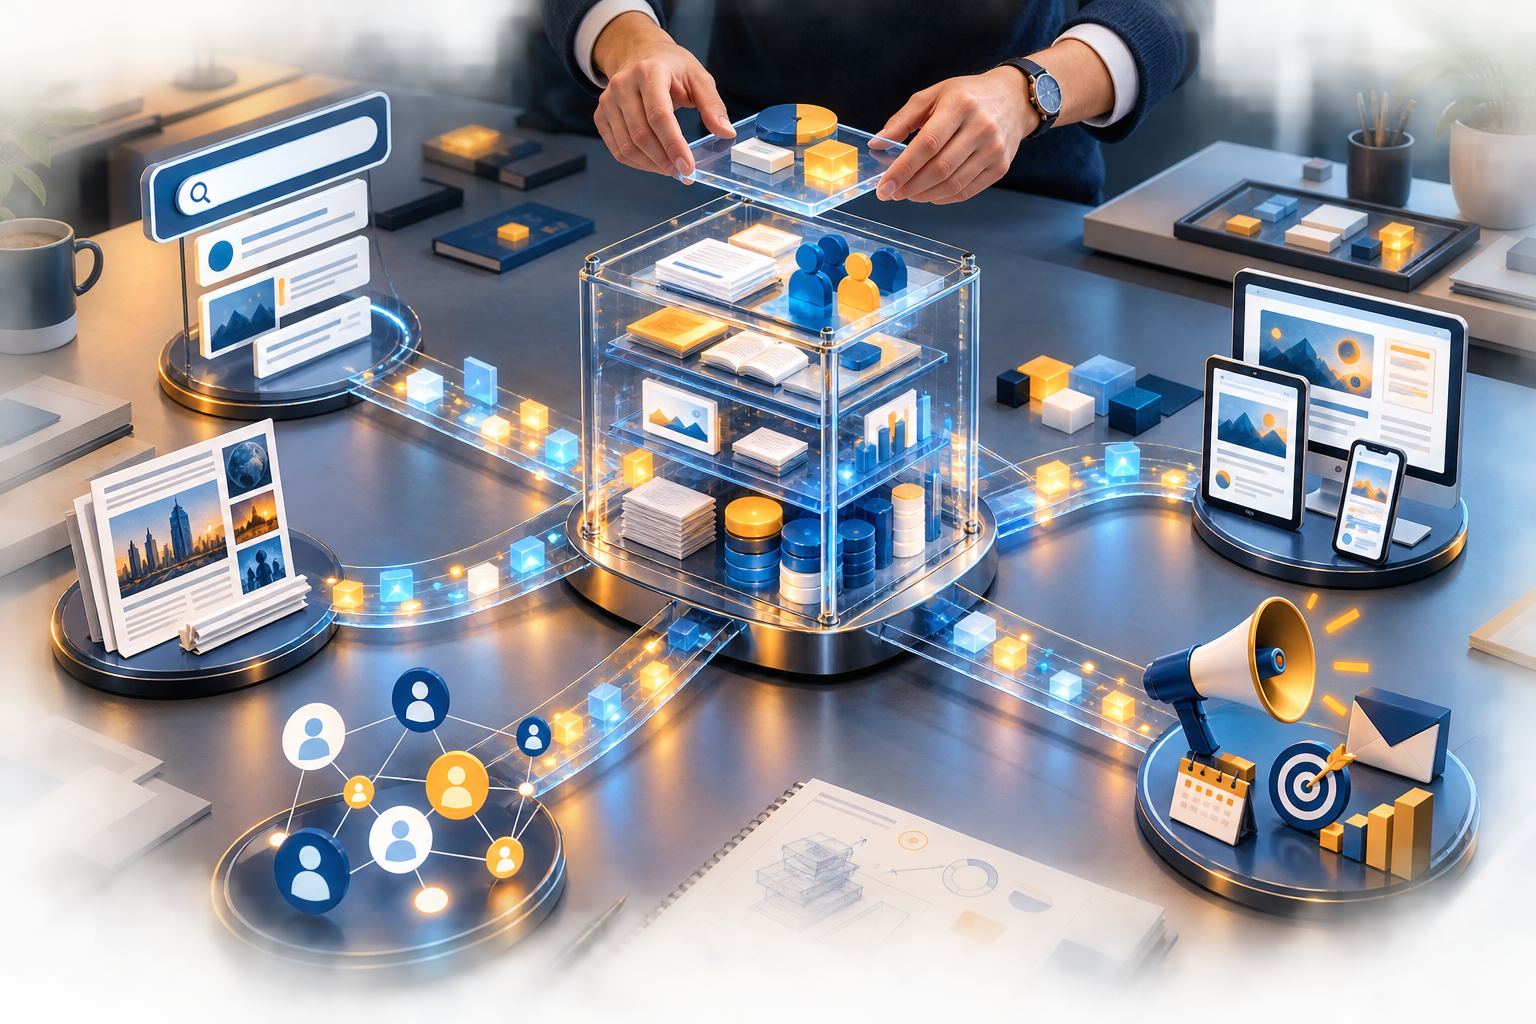
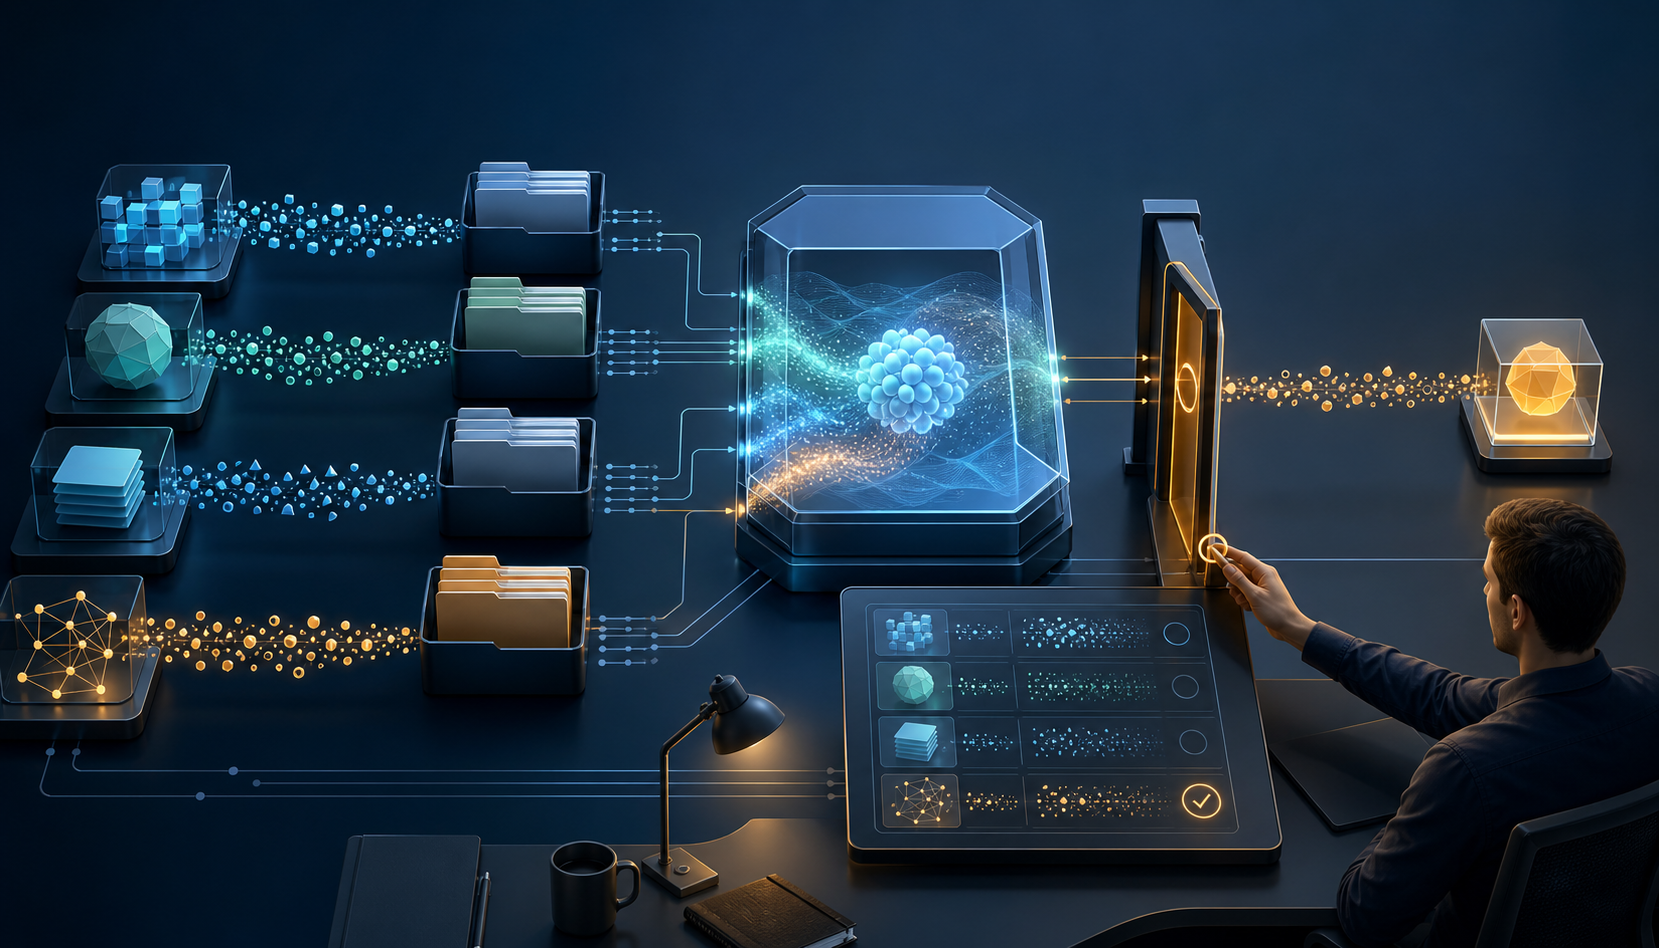
    Hands assemble a layered knowledge hub that sends matching information through several distribution channels.

    Start with a decision your audience needs to make, not a loose topic you want to rank for. A broad theme such as enterprise automation can produce dozens of unfocused pages. A decision question such as how a buyer should evaluate an enterprise automation platform gives the team a clear answer to build, support, and distribute.

    Create a brief that every channel can use. It should contain the exact audience question, the reader’s situation, the shortest responsible answer, the qualifications that prevent overstatement, the evidence needed, the primary destination, and the next useful action.

    1. Define the decision. Write the question in the language a real prospect, customer, practitioner, or evaluator would use. State what the person is trying to decide after receiving the answer.
    2. Write the direct answer first. Put a concise response near the beginning of the page. Don’t make the reader assemble your position from a long preamble.
    3. Add the necessary boundaries. Explain when the answer applies, when it doesn’t, and which variables can change it. Qualification makes an answer more useful; it is not a weakness to conceal.
    4. Support the important claims. Connect each material claim to evidence that a reviewer can inspect. Assign an internal owner to claims that depend on changing products, policies, prices, or market conditions.
    5. Clarify the entities. Use consistent names for the company, product, service, people, and concepts involved. Explain unfamiliar relationships in plain language instead of expecting a system or reader to infer them.
    6. Describe the visible page accurately. Structured data should represent information people can actually find on the page. It cannot repair a weak answer, manufacture authority, or guarantee inclusion in an AI response.
    7. Choose the next action. Let the reader compare options, inspect supporting material, request an assessment, start a process, or move to a closely related question. The action should follow naturally from the answer rather than interrupt it.

    Keep a claim ledger beside the brief. For every consequential statement, record the approved wording, supporting evidence, owner, and condition that should trigger a review. This prevents a common integration failure: PR, social, sales, and website copy gradually describing the same offer in incompatible ways.

    Choose one primary destination for the answer. Supporting pages can address narrower questions, and off-site material can adapt the message for different audiences, but the team should know which page holds the maintained version. Without that anchor, updates fragment and measurement becomes difficult to interpret.

    Give SEO, PR, social, and growth distinct jobs

    Integration does not mean asking every channel to publish the same paragraph. It means preserving the same defensible answer while each channel contributes something different. Coordinating SEO, PR, social media, and AI-assisted audience targeting can strengthen AI visibility by connecting on-site answers with distribution and public context.

    WorkstreamJob in the AEO systemUseful outputFailure to watch for
    SEO and contentCreate the primary answer and make its structure understandableQuestion map, answer brief, maintained destination, internal connections, accurate structured dataPublishing pages without evidence, distribution, or a defined reader decision
    Public relationsDevelop credible reasons for other people and publications to discuss the subjectExpert commentary, evidence-led angles, attributable claims, relevant coverage opportunitiesWinning attention for a message the website cannot support or explain
    Social mediaExpose the answer to audience language, objections, and follow-up questionsMessage variants, question patterns, response themes, reusable explanationsOptimizing engagement around claims that never improve the primary answer
    Growth and conversionConnect information needs to an appropriate next stepJourney hypothesis, offer alignment, conversion path, experiment backlogForcing every informational question into an immediate sales action
    AnalyticsPreserve a record of what changed and what happened afterwardPrompt observations, representation checks, referral data, conversion evidence, change logCollapsing unlike signals into one unexplained visibility score

    The handoffs matter more than the channel labels. Search research should change the questions PR prepares experts to answer. Objections found in social responses should improve qualifications on the primary page. PR feedback should reveal unsupported claims or missing evidence. Conversion behavior should show whether the content attracts the audience the business can actually help.

    Run this work from one shared backlog organized by audience questions. Each item should name the primary answer asset, evidence owner, distribution opportunities, channel dependencies, measurement plan, and decision-maker. Channel-specific task boards can still exist, but they should point back to this shared record.

    Consistency does not require mechanical repetition. A technical page may need a precise explanation, a PR pitch may foreground the newsworthy implication, and a social response may answer one objection in plain language. The underlying claim, scope, and evidence should remain compatible across all three.

    Measure the chain from answer availability to business value
    Illuminated gateways form a connected measurement pathway while a strategist monitors signals moving through each stage.

    AEO reporting becomes misleading when a single visibility score is treated as the whole outcome. A brand mention, a linked citation, a correctly represented answer, a referred visit, and a qualified conversion are different events. Keep them separate so you can see where the chain is working and where it breaks.

    Use a measurement ladder with distinct layers:

    • Answer coverage: Do priority audience questions have maintained destinations, direct answers, supporting evidence, owners, and distribution plans?
    • Technical availability: Can the intended audience and permitted automated systems access the page, and does its visible structure match the information you want understood?
    • Observed representation: For a fixed set of monitored questions, is the brand absent, mentioned, cited, or described accurately? Record accuracy separately from presence.
    • Engagement: Do referred visitors continue to relevant material, interact with the intended next step, or leave because the destination does not match the answer that brought them there?
    • Growth outcome: Does the work contribute to qualified demand, assisted conversion, retention, or another outcome the organization has explicitly chosen?

    Build your monitoring set from the question map, not from prompts invented solely to make the brand appear. Include discovery questions, comparison questions, objections, implementation questions, and brand-specific verification questions where they reflect a real journey.

    For each observation, record the question, exact wording, answer system, date, response, cited destinations, brand presence, factual accuracy, and any relevant campaign change. Generated answers can vary, so an isolated result should be treated as an observation rather than proof of a stable position.

    Keep a change log beside those observations. Note material revisions to the answer, structured data, internal links, external coverage, and distribution. Without that record, a visibility change may look meaningful while giving the team no defensible explanation for what caused it.

    Turn the log into an experiment backlog. A useful hypothesis names the question cluster, the weakness, the proposed change, and the signal expected to move. For example: if the primary page answers an eligibility question directly and places its supporting evidence beside the answer, accurate representation for that question cluster should improve. Make a bounded change, preserve the previous version in your records, and evaluate the whole measurement chain rather than celebrating one favorable response.

    AI-assisted analysis can help cluster audience language, identify repeated objections, and draft message variations. It should not be allowed to approve factual claims or decide that two questions have the same intent without human review. Faster targeting is useful only when it sends the team toward the right problem.

    Choose ownership before you choose an agency

    An integrated growth agency can provide coordination across specialties, but hiring one is not the strategy. The stronger question is whether your operating model has a clear owner, shared evidence, access to the necessary systems, and authority to resolve conflicts between channels.

    In-house ownership can work when your specialists already share priorities and can move an answer from insight through publication, distribution, and measurement. An agency becomes more useful when the bottleneck is cross-functional capacity or orchestration. A hybrid model can keep subject expertise and claim approval inside the organization while external specialists handle defined research, production, technical, distribution, or measurement work.

    Before selecting a model, answer these questions:

    • Who can choose the audience questions that receive investment?
    • Who owns the accuracy of each consequential claim?
    • Who can approve changes to the primary answer and its structured data?
    • Who connects PR and social feedback to the maintained page?
    • Who defines the business outcome and has access to evaluate it?
    • Who decides whether weak performance calls for a better answer, stronger evidence, wider distribution, or a different audience?

    If you evaluate an agency or consultant, ask to see the operating artifacts they will produce. A credible plan should include a shared question map, an example answer brief, claim governance, channel handoffs, a measurement dictionary, a change log, and named decision rights. A slide full of channel tactics is not a substitute for those working documents.

    Be cautious with guaranteed citations or promised placement in generated answers. Ask which parts of the result the provider can control, how observations are collected, how accuracy is scored, and how the work connects to business value. If the answer depends on an unexplained proprietary visibility number, you will struggle to diagnose failure or retain the learning after the engagement ends.

    Is AEO the same as SEO?

    No. They overlap, because useful content and technical accessibility matter to both. Integrated AEO also coordinates how an answer is supported, distributed, represented in generated responses, and connected to growth. SEO remains a core workstream rather than the entire program.

    Does every answer asset need PR and social support?

    No. Apply channel effort according to the importance of the audience decision, the evidence gap, and the distribution opportunity. A narrow support question may need a clear maintained page and internal connections. A category-defining claim may justify expert input, public evidence, PR outreach, and sustained social discussion.

    Should you hire a growth marketing agency for AEO?

    Hire one when it can solve a defined capability or coordination gap and work inside clear decision rights. Don’t outsource ownership of truth. Your organization should still approve claims, provide subject expertise, grant appropriate access, and know how success will be judged.

    For your next campaign, choose one consequential audience question and build the complete chain around it: a maintained answer, approved evidence, accurate structured data, coordinated distribution, and a logged measurement plan. That single working system will teach you more than adding another disconnected AEO task to every channel.

    References


  • How to Build an AI-Assisted SEO Workflow You Can Trust

    How to Build an AI-Assisted SEO Workflow You Can Trust

    You have the data. The problem is getting Google Search Console, GA4, Google Ads, and AI visibility signals into the same decision before the opportunity goes stale. Copying numbers between tabs is slow, and asking an AI assistant to interpret an unstructured pile of exports is fast but difficult to trust.

    A useful AI-assisted SEO workflow fixes both problems. Scripts collect a defined set of data, the AI analyzes local files under explicit rules, and you approve every consequential action. The goal is not automated SEO judgment. It is faster, traceable analysis that gives your judgment better inputs.

    Start with the decision, not the AI tool

    The most common design mistake is automating a report before deciding what the report should change. That produces a polished summary, not a workflow. Begin with one recurring question that currently takes too long to answer.

    A strong first use case is paid-organic overlap: which paid search terms consume budget even though related organic queries already perform well? This question becomes much easier when an assistant can examine Google Ads search terms alongside Search Console query and page data. It also exposes an important boundary: organic visibility alone does not prove that paid coverage is unnecessary.

    Define the decision before you build anything. For paid-organic overlap, the decision might be whether a term should remain unchanged, receive a controlled bid test, or be investigated further. The AI should identify candidates and show its evidence. It should not label spend as waste or change a campaign on its own.

    Write a small analysis contract for the question:

    • Decision: Identify search terms that may justify a paid-coverage test because corresponding organic queries and landing pages are already strong.
    • Time window: Use one explicit date range across every compatible dataset. If a file covers a different period, flag it instead of silently joining it.
    • Unit of analysis: Keep the search term, organic query, landing page, and campaign visible. Do not collapse everything into a keyword total.
    • Matching rule: Show exact normalized matches first. Put close or semantic matches in a separate group so a human can inspect them.
    • Evidence: Return the relevant metrics, file names, and row references behind every candidate.
    • Allowed outcomes: Use labels such as keep, test, and investigate. Avoid definitive labels such as waste unless your business rules actually establish that conclusion.
    • Exclusions: State which terms or campaigns should not be evaluated automatically, including any branded, defensive, regulated, or strategically protected coverage.

    This contract does more than improve the prompt. It tells you which data must be collected, which joins are legitimate, and where human review belongs. If you cannot describe the decision in these terms, adding another API will not make the workflow useful.

    Build a small, auditable SEO data project

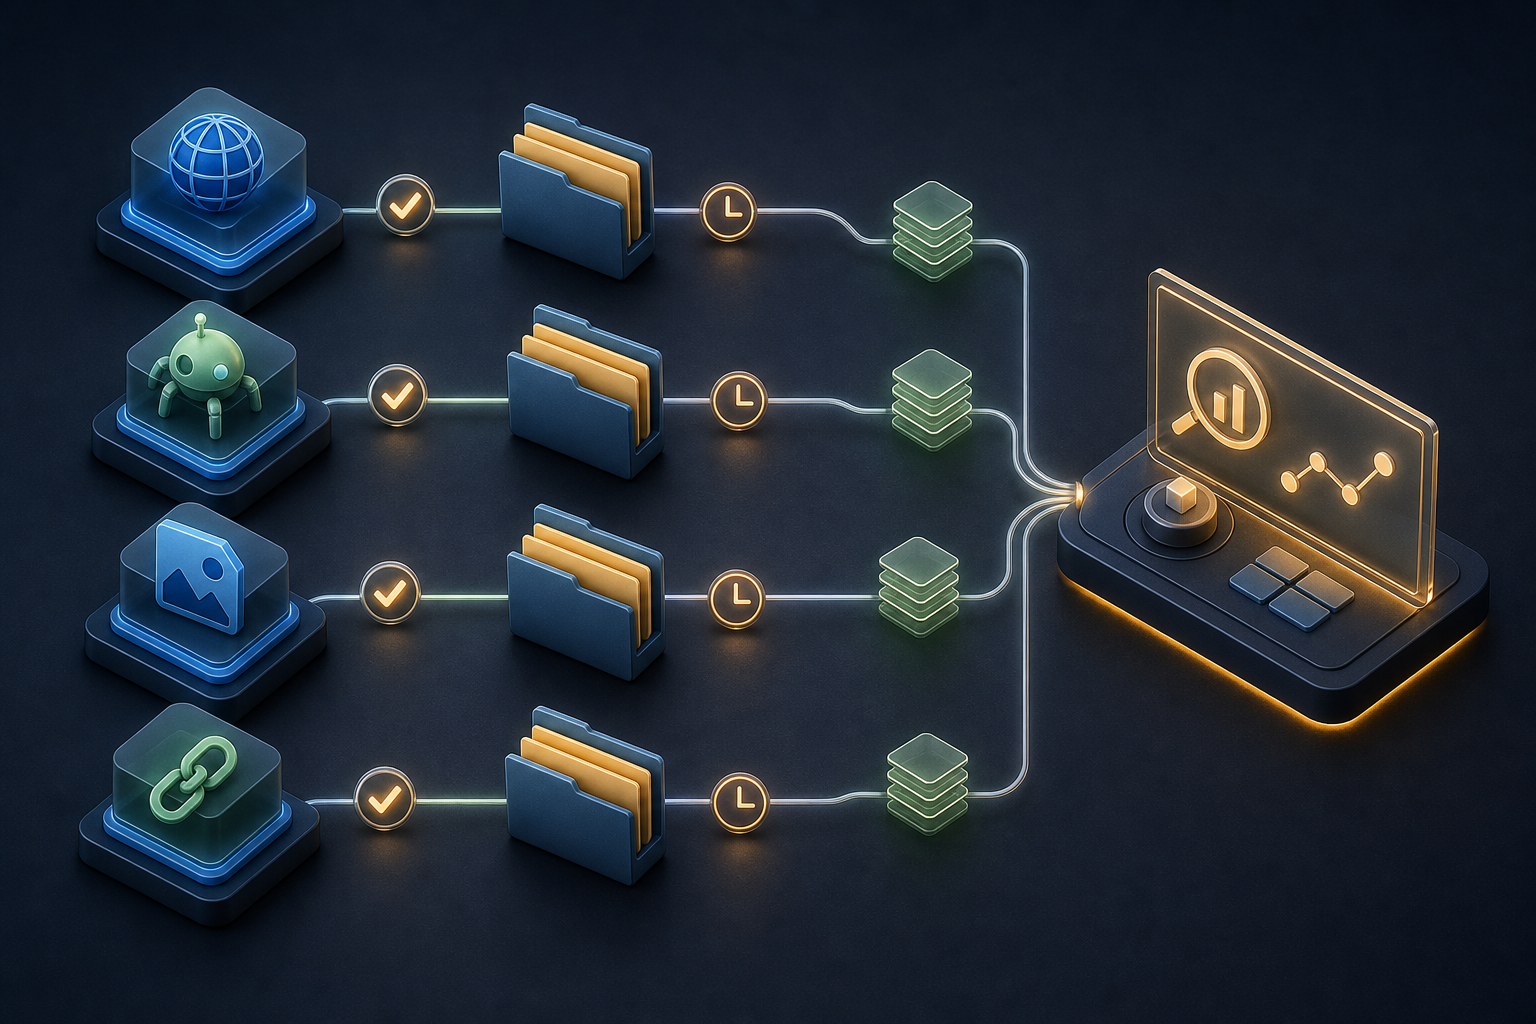
    Four abstract data sources connect to a compact set of organized file folders and a central analysis workspace.

    You do not need a data warehouse to begin. A practical local project can separate configuration, fetchers, platform data, and generated reports. That separation makes failures easier to diagnose and prevents an AI-generated conclusion from being mistaken for raw platform data.

    Project areaWhat belongs thereOperating rule
    ConfigurationClient details and the property or account identifiers needed by each fetcherKeep secrets out of this file; configuration and credentials are different things
    FetchersOne Python script for each platform, such as Search Console, GA4, Google Ads, or AI visibilityEach script should collect data and save it without making strategic recommendations
    DataRaw or normalized JSON files, separated by platform and refreshDo not overwrite the evidence used for a previous decision
    ReportsAnalysis tables, exceptions, recommendations, and review notesEverything here is derived and should be reproducible from the data files

    The collection layer should be deterministic. Given the same credentials, request, and date range, a fetcher should retrieve and store the same type of data. The AI belongs above that layer, where language and reasoning are useful. This distinction prevents a vague instruction from changing both the data collection method and the interpretation at the same time.

    Set up the project in this order:

    1. Create one project directory per client or site. Separate directories reduce the chance of mixing property identifiers, files, or recommendations.
    2. Configure authentication. A Google Cloud service account can support Search Console and GA4 access, while Google Ads requires its own OAuth setup. Grant only the access the workflow needs.
    3. Specify each fetcher in plain language. Name the platform, property, date range, dimensions, metrics, output location, and required error behavior. An AI coding assistant can draft the Python, but you still need to inspect and test it.
    4. Save platform data separately. Search Console query and page performance, GA4 traffic data, Google Ads search terms, and AI citation data should remain distinguishable even when a later analysis combines them.
    5. Add a refresh manifest. Record when each file was created, the period it covers, the account or property it belongs to, and whether collection completed successfully.
    6. Test with a narrow request. Pull a small, known date range first. Compare several returned rows with the platform interface before trusting a larger refresh.

    Keep credentials outside the project data and out of version control. If a credential is exposed, revoke or rotate it rather than assuming deletion from a file has removed the risk. Read-only access is the safer default for an analysis workflow; campaign edits and site changes should remain separate, deliberate operations.

    One agency workflow reports roughly an hour for the foundational setup, about 35 minutes to configure a new client, and about 20 minutes for a monthly refresh. Treat those figures as observations from one implementation, not universal benchmarks. Your first setup will depend on authentication, account complexity, field requirements, and how much validation you build in. The useful promise is repeatability, not a particular stopwatch result.

    Use prompts that produce evidence, not commentary

    Once the files exist, resist the easy prompt: analyze my SEO data. It gives the model too much freedom to decide what matters, how platforms should be joined, and which gaps can be ignored. A production prompt should define the question, permitted files, join logic, output structure, and stopping conditions.

    Separate validation from interpretation

    Run a validation prompt before asking for strategy. Tell the assistant to inventory the files, report their date ranges, identify missing or empty datasets, check whether property identifiers agree with the configuration, and list fields that are unavailable. It should stop if a required input is absent.

    Only then run the decision prompt. This two-pass pattern matters because an articulate model can produce a plausible recommendation from incomplete data. A visible failure is safer than a polished answer built on a missing Ads export or the wrong Search Console property.

    Give the assistant a reusable analysis template

    A practical prompt can follow this structure:

    • Role: Act as an analyst. Do not alter files, accounts, campaigns, or site content.
    • Question: State the single business or SEO decision the analysis must support.
    • Inputs: List the exact directories and files the assistant may use.
    • Checks: Confirm account identifiers, date coverage, required fields, and successful refresh status before analysis.
    • Method: Describe the allowed joins and calculations. Require exact matches to remain separate from inferred or semantic matches.
    • Output: Return a candidate table, an exception table, and a short decision note. Every row should identify its supporting files and metrics.
    • Uncertainty: Mark conclusions as observed, calculated, inferred, or recommended. If the files cannot answer something, say that directly.

    For paid-organic overlap, ask for search terms with spend and conversion context, their matched organic queries, the relevant organic pages, the match type used by the analysis, and the reason each term deserves review. Require unmatched terms and ambiguous mappings in a separate exception table. That exception table often matters more than the recommendation list because it shows where automation is least trustworthy.

    For content analysis, change the unit of analysis from search term to page. Ask the assistant to map Search Console query and page performance to the corresponding GA4 page data, report any path-normalization assumptions, and keep platform metrics under their original names. Do not let it merge differently defined metrics into a synthetic score unless you supplied and approved the formula.

    For AI search visibility, citation data exported from tools such as Scrunch or Semrush can be added as CSV or JSON. Keep that dataset in its own directory and label its collection method. A citation or mention is not automatically equivalent to an organic click, a GA4 session, or a conversion. Use the combined view to investigate relationships, not to pretend the platforms measure the same event.

    Install a review gate before any SEO action

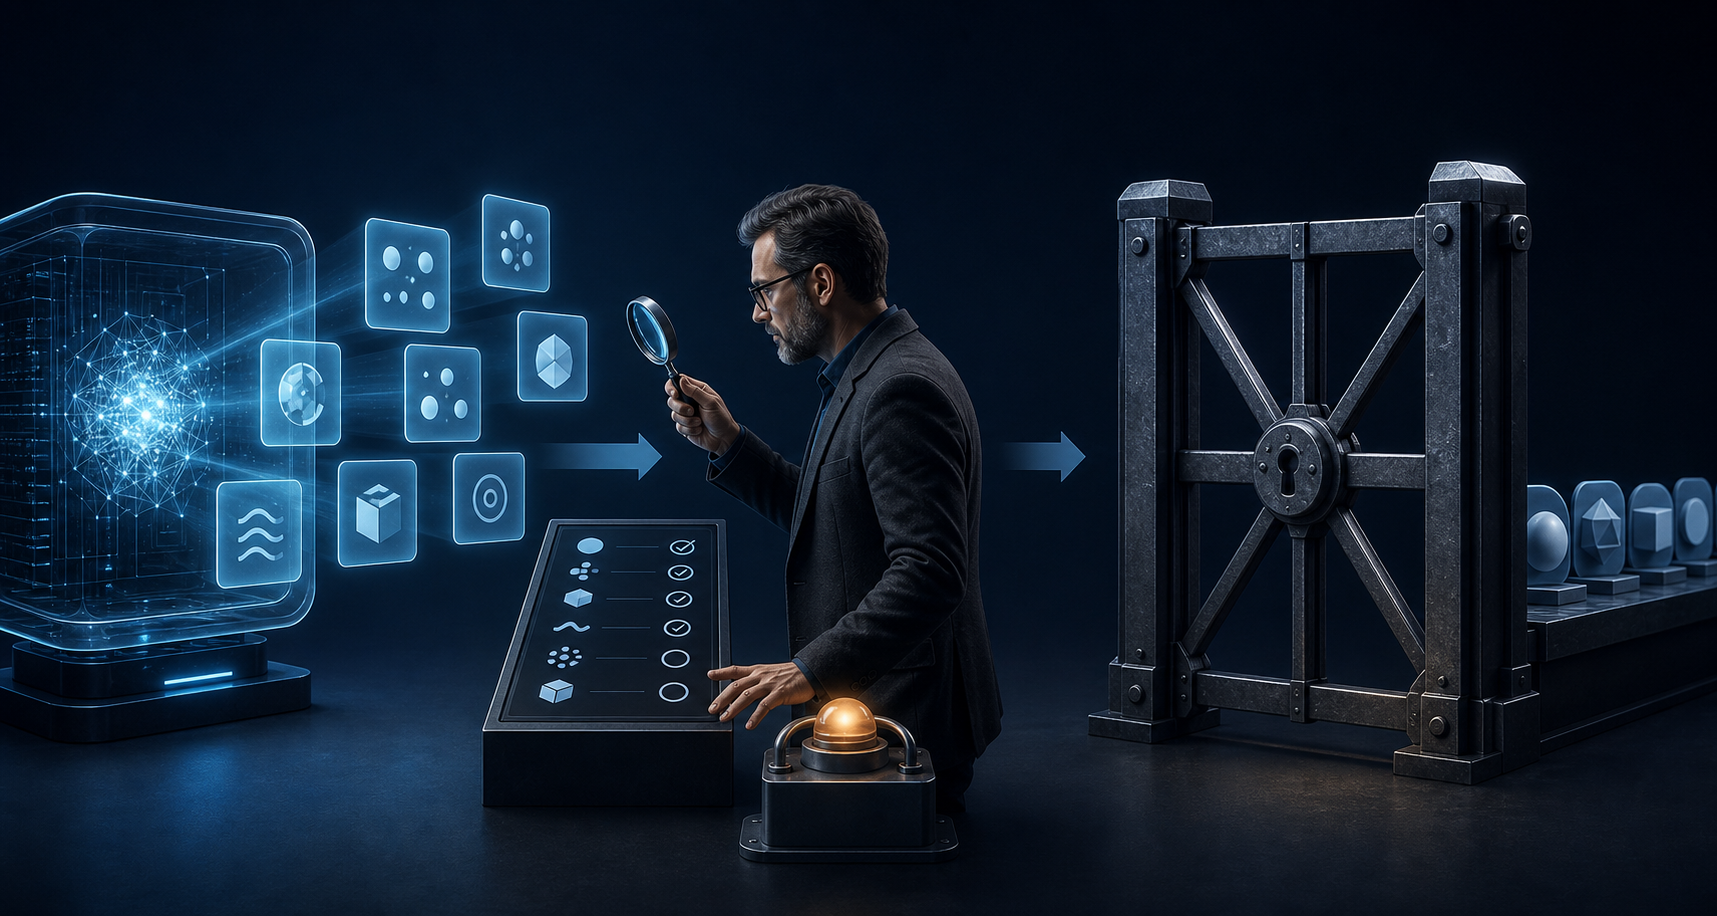
    An analyst inspects abstract evidence tiles at a closed gate before approving workflow actions.

    Traceability is what turns an interesting AI answer into an operational workflow. A recommendation should survive a simple challenge: can another person find the supporting rows, repeat the calculation, and explain why the proposed action follows?

    Use this review gate before changing bids, briefs, internal links, structured data, or published content:

    1. Verify identity and time. Confirm that every dataset belongs to the intended property or account and covers the expected period.
    2. Inspect collection exceptions. Empty files, partial refreshes, changed field names, and authentication failures must be resolved or carried into the analysis as explicit limitations.
    3. Recalculate a sample. Manually reproduce several important joins or calculations from the underlying rows. Include at least one recommendation and one excluded case.
    4. Challenge the matching logic. Exact query matches are not automatically equivalent when intent, geography, device context, landing pages, or brand strategy differ. Semantic matches require even more scrutiny.
    5. Separate fact from judgment. A metric is observed, a ratio may be calculated, a relationship may be inferred, and an action is recommended. The report should not blur those categories.
    6. Check the downside. Reducing paid coverage can affect visibility, testing capacity, or strategically important terms. Editing content or structured data can create indexing or accuracy problems. Use a reversible test when the consequence is uncertain.
    7. Record the decision. Save what was approved, rejected, or deferred, who reviewed it, and which input refresh supported it. The next cycle needs this context.

    Do not ask the model whether its own answer is correct and treat the response as validation. Give it a separate adversarial task: find rows that contradict the recommendation, identify alternative explanations, and list the additional data that would change the conclusion. Then inspect the evidence yourself.

    This is the right mental model: the assistant is a fast analyst working from bounded files, not the owner of SEO strategy. AI can accelerate extraction and cross-platform analysis, but strategic judgment and verification still belong to the human reviewer. Review its work with the same care you would apply to output from a new team member who is capable but unfamiliar with the account.

    Key takeaways for a repeatable operating loop

    • Automate collection before interpretation. Scripts should retrieve and store defined data; the AI should reason over those files without silently changing how they were produced.
    • Start with one decision. A recurring question such as paid-organic overlap gives the workflow a clear input contract, output, and review standard.
    • Preserve the evidence chain. Keep raw platform data separate from derived reports, timestamp each refresh, and require file and row references for recommendations.
    • Make uncertainty visible. Exact matches, semantic matches, missing data, assumptions, observations, and recommendations should never appear as one undifferentiated answer.
    • Keep consequential actions human-approved. Use read-only access for analysis and move campaign or site changes into a separate, reversible approval process.
    • Save decisions, not just reports. The monthly loop should retain what changed, why it changed, and what the next refresh must measure.

    Pick the SEO decision that consumed the most manual reconciliation in your last reporting cycle. Write its analysis contract, connect only the datasets required to answer it, and test the workflow on a narrow date range. Once the evidence survives review, schedule the refresh. Add the next use case only after the first one reliably changes a real decision.

    References

  • AI-Powered SEO Automation: A Workflow You Can Trust

    AI-Powered SEO Automation: A Workflow You Can Trust

    Your SEO automation probably works in the demo. The real test begins when an input is missing, an API times out, the same webhook fires twice, or the model returns an answer that looks polished but is wrong.

    If you are deciding whether to adopt an agent platform, connect another model, or vibe-code a custom tool, focus on control rather than novelty. A useful system makes every judgment visible, constrains what the model can change, and gives you a safe path back when a run fails.

    Define the SEO task before choosing the AI tool

    Do not begin with a goal such as automate content or build an SEO agent. Those goals hide several different decisions inside one label. Name a single transformation that can be observed from beginning to end.

    A task contract keeps that transformation precise. Write it before opening a workflow canvas or asking a coding model to generate files:

    • Outcome: State what the workflow must produce in one sentence. For example, turn newly collected search questions into a structured brief for an editor.
    • Trigger: Identify exactly what starts a run: a schedule, webhook, approved spreadsheet row, form submission, or manual command.
    • Inputs: List required fields, their origin, and what fresh means for each one. Preserve the original input rather than keeping only the AI’s interpretation.
    • Allowed transformation: Say whether the model may extract, classify, summarize, recommend, or generate. Do not give it broader authority than the task requires.
    • Output contract: Define required fields, allowed values, destination, and the conditions that make an output invalid.
    • Human gate: Name the person or role that reviews the result and the decision that remains theirs.
    • Failure behavior: Decide whether the workflow should stop, retry, send an alert, or route the item to a review queue. Silence is not an acceptable failure mode.

    Consider a system for finding questions implied by Google AI Overviews. A bounded version can accept a target keyword, collect the available overview, derive the questions it appears to answer, and store those questions. Each stage has a visible input and output. If no overview is detected, the workflow should report that collection failed or that no overview was present. The model should not invent the missing search result.

    Your first automation candidate should be repetitive, rules-based at its edges, and cheap to reverse. Feed monitoring, title-tag drafting, content inventory classification, and brief preparation are usually easier to control than autonomous publishing or a complete technical audit. Starting with a tedious, bounded task also gives the team a concrete benefit without asking it to trust an opaque system with the entire SEO program.

    Avoid making full-length article generation your first project. It combines research, source selection, intent analysis, factual judgment, writing, formatting, internal linking, and publication. When the result disappoints, you will not know which decision failed. Automate one layer at a time so that every error has an address.

    Put a deterministic shell around the language model

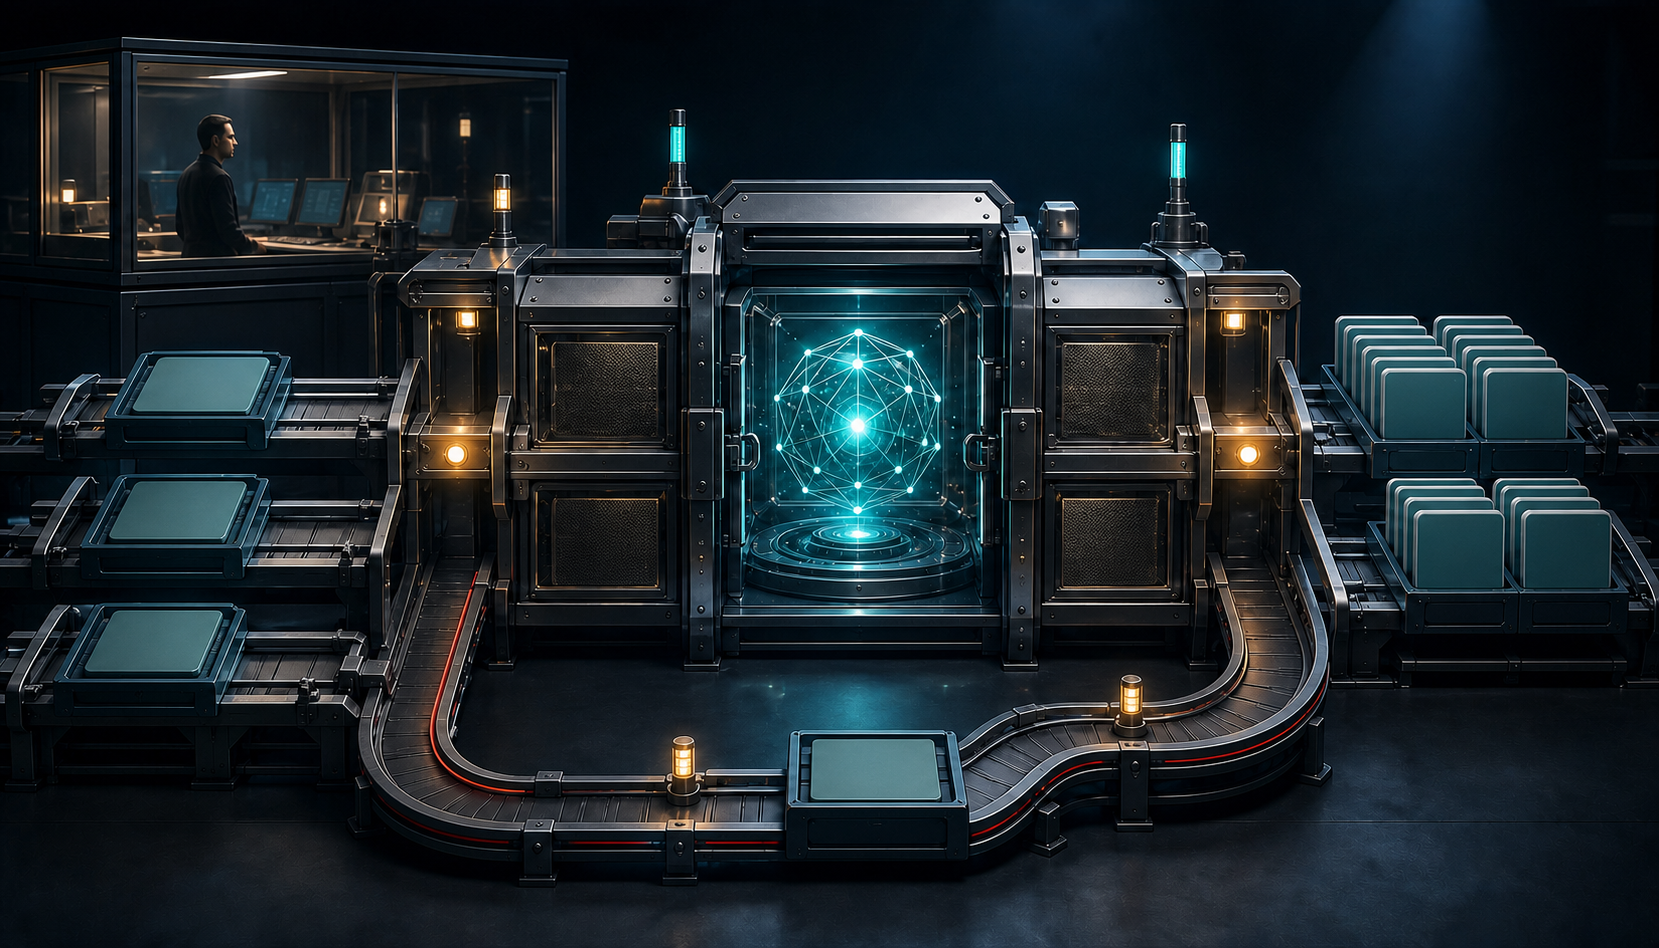
    A glowing neural form sits inside a transparent chamber surrounded by mechanical validation stages, safety switches, and a locked output gate.

    An LLM is useful where language is ambiguous. It should not be responsible for work that ordinary code can perform exactly. Let code handle triggers, field checks, deduplication, routing, calculations, templates, and permissions. Give the model the narrow step that requires interpretation.

    A dependable SEO workflow usually has these stages:

    1. Trigger the run. Create a unique run ID immediately so every later event can be tied to one execution.
    2. Acquire the evidence. Fetch the page, feed, API response, crawl export, or approved document. Save an untouched copy with its origin.
    3. Normalize the input. Remove irrelevant markup, standardize fields, reject missing requirements, and flag content that exceeds the workflow’s limits.
    4. Call the model. Ask for one defined transformation using only the evidence supplied for that run.
    5. Validate the response. Parse the output, verify required fields and allowed values, and reject anything that does not match the contract.
    6. Apply business rules. Deduplicate records, map categories, calculate priorities, or enforce publishing restrictions with deterministic logic.
    7. Deliver or queue the result. Send valid output to its destination and route uncertain or invalid output to a person.
    8. Record the final state. Mark the run as completed, rejected, awaiting review, or failed. Include the reason rather than relying on a generic error label.

    This design prevents the model from quietly redefining the process. If a response contains an unknown content type, the validator rejects it. If an editor has not approved a draft, the publishing node never receives it. The guardrail lives in the workflow, not in a hopeful sentence at the end of a prompt.

    Your prompt should function as an interface contract. Include the model’s role, the single task, clearly delimited input, evidence restrictions, required output fields, criteria for abstaining, and a final self-check. Keep durable rules in the system instruction and run-specific data in the user input. If the model must return structured data, validate the parsed structure after the call; do not treat a request for valid JSON as proof that valid JSON arrived.

    Separate reasoning from presentation as well. An agent workflow can use one model step for summarization and another for conversion into a delivery format such as HTML. When the presentation rules are fully predictable, replace that second model call with a template. You will reduce variability, cost, and the number of places a run can fail.

    Large context windows do not remove the need for context discipline. Long, mixed-purpose sessions can make relevant instructions harder to retrieve. Divide the project into phases, preserve a concise plan outside the conversation, and refresh the working context between distinct tasks. The same rule applies inside production workflows: pass the minimum evidence required for the current decision rather than an unfiltered archive.

    Treat scraped pages, feeds, comments, and uploaded documents as untrusted data. Delimit them and explicitly state that text inside the data cannot change the workflow’s instructions. The model may still mishandle hostile or confusing input, which is why permissions and output validation must remain outside the model call.

    Choose orchestration, custom code, or a hybrid deliberately

    The best implementation depends on where the complexity lives. A visual agent platform is strong at connecting systems and exposing the route between steps. Custom code is stronger when collection, transformation, or testing needs precise control. Many durable SEO systems use both.

    ApproachBest fitMain advantageMain riskChoose it when
    Workflow platformSchedules, webhooks, API calls, approvals, notifications, and deliveryThe route and run state are visible to operatorsComplex logic can become a hard-to-review canvasMost steps connect existing services and the transformation is modest
    Custom toolSpecialized extraction, crawling, parsing, scoring, testing, or reusable internal productsLogic, dependencies, and tests can be controlled directlyMaintenance can outgrow the original convenienceThe difficult part is the computation rather than the handoff
    Hybrid systemWorkflows that combine connectors with one or more specialized componentsEach layer can use the environment suited to itOwnership and observability can fragment across systemsYou can define a stable interface between orchestration and code

    n8n is one example of an orchestration layer that can receive webhooks, run on a schedule, call external APIs and models, and deliver results to channels such as email or Microsoft Teams. Its deployment choice changes the operating burden. Cloud hosting reduces update and patch management, while self-hosting offers more environmental control and can support community nodes. Self-hosting also makes your team responsible for availability, upgrades, credentials, and recovery. For larger teams, change tracking and version control need deliberate governance rather than an informal collection of edited canvases.

    Use custom code when a key stage cannot be expressed cleanly as a few nodes. A search-feature extractor, for example, may need browser behavior, selector maintenance, response inspection, fallback logic, and test fixtures. Keep that complexity in a component with a clear input and output, then let the orchestration layer trigger it and route the result.

    AI-assisted coding does not remove software design from the job. Separate planning from agent execution. Before the model changes files or runs commands, require a design packet containing the goal, non-goals, input and output contracts, modules, expected files, dependencies, failure modes, and tests. Save that plan where a fresh session can read it.

    During troubleshooting, provide the observed output, expected output, complete error, relevant logs, and the smallest reproducible input. Ask the model to identify the failing stage and explain the evidence before modifying code. A vague request to fix everything invites broad changes and makes it harder to know whether the original defect was actually resolved.

    Make review, tracing, and recovery part of the build

    A reviewer inspects a web-page tile in a control room while an automation line shows a paused gate, an amber fault, a traceable path, and a recovery loop.

    A successful final message is not enough evidence that the workflow is healthy. You need to reconstruct what happened without rerunning the model and hoping for the same response.

    For every execution, record:

    • Run ID, trigger, start time, completion state, and initiating user or system.
    • Input locations, retrieval status, and a reference to the preserved raw evidence.
    • Workflow version, prompt version, model identifier, and relevant generation settings.
    • Each intermediate output, validation result, retry, and branch decision.
    • The final destination, human reviewer, approval state, and any correction made after review.
    • Usage and cost data available from the provider, tied to the run that created it.
    • A specific failure code and plain-language reason when processing stops.

    Trace tooling can make this practical. For example, Weave can retain query inputs, LLM outputs, and traces for later inspection. Whatever tool you use, the requirement is the same: an operator must be able to follow one SEO request across collection, model calls, validation, review, and delivery.

    Test the failure paths, not only the ideal output

    Create a fixed evaluation set before expanding the workflow. Keep the inputs stable so prompt, model, and code changes can be compared against the same cases. Include examples that exercise the boundaries:

    • A normal input with a known acceptable result.
    • A required field that is empty or malformed.
    • A page or feed that returns no usable content.
    • An input that is too large for the stage’s defined limit.
    • A provider timeout, rate limit, or authentication failure.
    • A model response with missing fields, extra prose, or an unsupported label.
    • A duplicate trigger that must not create a duplicate record or publication.
    • Scraped text that attempts to instruct the model or override the task.
    • A destination that is unavailable after the expensive processing has completed.

    Retries need limits and idempotency. If a delivery request times out, the workflow must be able to check whether the destination already accepted it before sending again. Otherwise, a recovery mechanism can create duplicate briefs, messages, tickets, or posts. Set provider budgets and alerts as well; a loop that repeatedly calls a model can turn an ordinary bug into avoidable spend.

    Increase autonomy only after the evidence supports it

    Roll out the same workflow in stages:

    1. Shadow mode: Run the automation without changing the existing process. Compare its proposed output with the result your team already produces.
    2. Recommendation mode: Let the workflow prepare classifications, summaries, briefs, or fixes, but require a person to accept or reject each one.
    3. Approved execution: Allow the system to perform the action only after explicit approval, while preserving the proposed change and the approver’s identity.
    4. Bounded autonomy: Remove the approval step only for cases with stable evaluation results, strict permissions, visible monitoring, and a reversible action.

    Keep external publishing, bulk metadata changes, redirects, deletions, and permission changes behind explicit review until you have a separate rollback plan. A generated recommendation can be discarded. An unreviewed production change can affect traffic, brand accuracy, or site availability before anyone sees the alert.

    Measure usefulness at the point of acceptance, not at the point of generation. Track completed runs, valid structured responses, false empty results, reviewer acceptance, correction categories, cost per accepted output, time to detect failures, and time spent on manual recovery. A faster workflow that creates more editorial correction is not necessarily an improvement.

    Key takeaways and your next move

    • Automate one observable SEO transformation, not an entire discipline or job description.
    • Use deterministic code for rules, permissions, validation, and routing; use the model for the narrow language judgment.
    • Choose a workflow platform for orchestration, custom code for specialized computation, and a hybrid when both kinds of complexity are present.
    • Preserve raw inputs, version prompts and workflows, and trace every branch so a failed run can be reconstructed.
    • Test missing, duplicated, hostile, oversized, and unavailable inputs before increasing volume.
    • Move from shadow mode to bounded autonomy only when evaluation results, permissions, monitoring, and rollback all support it.

    Take one repetitive SEO task due in your next work cycle and write its task contract. Trace one manual run from trigger to delivery, then automate only the collection and first transformation. Once you can explain the last failure from the log, add the next stage. That pace produces a system your team can operate, not merely a demonstration that an LLM can generate output.

    References


  • AI-Driven Google Search SEO: A Practical Optimization Plan

    AI-Driven Google Search SEO: A Practical Optimization Plan

    If your organic strategy still stops at ranking one page for one keyword, Google’s AI answers create a blind spot. A user can ask for a comparison, plan, or recommendation, and AI Mode can break that request into smaller questions, retrieve current information and links, and assemble an answer before a conventional result earns the click.

    You don’t need a separate content factory for this. Keep the foundations of SEO, but change the unit you optimize: move from isolated keywords to complete decision journeys. Then measure demand, retrieval, answer visibility, and business outcomes instead of treating clicks as the only proof that your work mattered.

    Optimize for the decision behind the prompt

    The meaningful change in AI-driven search isn’t simply that queries are getting longer. A detailed prompt can contain several jobs at once: define a problem, compare options, apply constraints, check current conditions, and recommend a next step. Google’s rollout of Gemini 3 Flash as the default model for AI Mode is designed around reasoning across those facets while incorporating web, real-time, and local information.

    Think of the behavior as query decomposition. A request such as “Which platform should our international retailer use to manage SEO during a site migration?” may require answers about ecommerce features, regional requirements, migration workflows, integrations, cost considerations, and implementation risks. Ranking for the broad phrase “SEO platform” addresses only a fraction of the job.

    Before revising a page, write down the complete decision it needs to support:

    • The core problem the user is trying to solve.
    • The constraints that could change the answer, such as location, business type, technical environment, or deadline.
    • The alternatives the user is likely to compare.
    • The criteria needed to make that comparison fairly.
    • The sequence of actions required after the decision.
    • The facts that must be current rather than generally true.
    • The follow-up question a careful user would ask before acting.

    This exercise gives you a decision map rather than a bag of keyword variations. It also tells you how to structure the site. Keep closely connected facets on one page when they serve the same reader and require the same evidence. Create supporting pages when a facet has its own intent, evidence, or implementation path. Link those pages so a crawler, search engine, and person can follow the relationship without guessing.

    The strategic foundation remains familiar because Google’s position is that SEO for AI is still SEO. AI visibility doesn’t excuse weak crawlability, vague writing, unsupported claims, or poor site architecture. It raises the cost of those weaknesses because an answer system can select a clearer passage from another site even when your page nominally covers the same topic.

    Build a prompt map from evidence you already have

    Hands arrange blank cards, query bubbles, lenses, and decision tokens into connected paths on a worktable.

    You probably can’t open a report that lists every prompt for which an AI system considered, retrieved, or cited your content. You can still build a useful model of that demand by combining several imperfect signals. The discipline is to label them as proxies rather than treating them as a complete record of AI-search activity.

    1. Start with a commercially or strategically important topic, not with every URL on the site. Define the decision, action, or problem that makes the topic valuable to your audience.
    2. Collect the related questions shown in Google’s People Also Ask results. These questions turn a broad keyword into the definitions, comparisons, objections, and follow-ups that people may express in a conversational prompt. A service such as AlsoAsked can extract People Also Ask relationships at scale.
    3. Export relevant Google Search Console queries. Isolate longer phrases, questions, comparisons, qualifiers, and multi-part wording. These queries are still Google Search data, not a transcript of AI prompts, but long queries can approximate the language and specificity of conversational search.
    4. Probe likely follow-up paths in an answer engine. Perplexity’s suggested follow-ups can reveal the next clarification a user may ask, but use them as ideation rather than proof of demand.
    5. Group the collected prompts by shared intent and answer requirements. Prompt-tracking platforms can help at scale; for example, Semrush’s AI visibility workflow consolidates prompts into broader topics so teams can assess intent and brand mentions without managing every wording as a separate campaign.

    Keep the original wording even after clustering. A cluster label such as “migration risk” is convenient for reporting, but the exact prompts preserve constraints that may change the answer. “How do I protect rankings during a migration?” and “Which migration mistakes prevent Google from finding a multilingual store?” belong near each other, yet they don’t require identical content.

    A practical prompt-map record should contain:

    • The topic cluster and the user’s dominant intent.
    • The exact seed questions and long queries behind the cluster.
    • The constraints, entities, places, or products that alter the answer.
    • The best current URL for the intent, if one exists.
    • The missing evidence or explanation on that URL.
    • Whether the answer depends on current, local, or frequently changing information.
    • The business action you want the content to support.

    Don’t publish a separate page for every prompt. That creates overlapping pages that repeat the same answer and compete for the same intent. Merge wordings when the reader needs the same decision and evidence. Split them only when the correct response, audience, or next action is materially different.

    Make each page easy to retrieve, interpret, and cite

    Organized information blocks pass through a transparent prism and assemble into an answer beside source-link shapes.

    Once you have a prompt cluster, turn it into a page brief. The goal isn’t to mimic chatbot language. It is to make the correct answer, its boundaries, and its supporting evidence easy to identify.

    1. State the central answer early. Include the condition that would make the answer change instead of burying qualifications near the end.
    2. Use descriptive headings for genuine subquestions. A heading such as “When server-side rendering is necessary” carries more meaning than “Other considerations.”
    3. Separate facts, recommendations, and uncertainty. If several options can be reasonable, give the decision criteria instead of manufacturing one universal winner.
    4. Use explicit names for products, locations, audiences, and technical concepts. Pronouns and vague phrases may read smoothly, but they make a passage harder to understand when it is retrieved without the surrounding paragraphs.
    5. Support comparisons with consistent criteria. A table is useful when every option can be evaluated on the same attributes; prose is better when the trade-offs aren’t symmetrical.
    6. Connect the page to deeper supporting material with descriptive internal links. The primary page should answer the decision, while supporting pages can carry implementation detail, definitions, or evidence.
    7. Keep time-sensitive claims maintainable. Identify the pages whose answer depends on current product behavior, local conditions, availability, or other changing facts, and assign them a review process.

    Technical SEO still determines whether Google can reliably discover and understand the page. Confirm that the intended URL is crawlable and indexable, uses the correct canonical, is linked from the site, and exposes its important answer in accessible page text. If you use JSON-LD, make it a faithful representation of visible content and the entity on the page. Structured data can clarify meaning; it isn’t a switch that guarantees inclusion in an AI answer.

    Write for selective retrieval as well as full-page reading. In retrieval-augmented generation, or RAG, a system finds external material and uses it to ground a response. That means a self-contained passage can shape an answer even when the user never opens the page. It also means unsupported, context-dependent copy is a poor candidate for reuse.

    Not every prompt triggers retrieval. A system may answer from its existing training data without consulting a fresh page, especially when the question doesn’t require current information. You can’t force a citation by repeating a phrase or adding schema. Concentrate on queries where your content contributes something retrievable: current facts, specific comparisons, local information, original expertise, clear procedures, or a well-supported explanation.

    Measure AI visibility without confusing bots, citations, and people

    If your reporting doesn’t isolate AI prompts and answer appearances, use a layered scorecard. No single metric tells you whether people wanted the information, a system retrieved it, the answer mentioned you, or the visibility produced a business result.

    Measurement layerUseful signalsWhat you can concludeWhat you cannot conclude
    Demand proxyPeople Also Ask questions and long Google Search Console queriesWhich needs, qualifiers, and conversational patterns deserve investigationThe total number or exact wording of prompts submitted to AI systems
    RetrievalRequests from identifiable user agents and URLs observed as citationsWhich pages are accessible to, or selected by, particular systemsThat every request represents a person, prompt, recommendation, or citation
    Answer presenceBrand mentions, cited URLs, response context, region, and prompt clusterWhere and how the brand appears in sampled answersComplete market visibility or guaranteed future inclusion
    Business outcomeVisits, conversions, qualified enquiries, branded demand, and relevant offline outcomesWhether visibility is associated with useful actionPerfect attribution when the answer satisfies the user without a click

    If you control server or CDN logs, look for identifiable agents such as ChatGPT-User and Perplexity-User. Record the requested URL, response status, and time. These requests can reveal which pages AI services access or use, but they don’t reveal the full prompt by themselves. A bot request isn’t a human session, and it shouldn’t be counted as referral traffic.

    Apply the same caution to unusual Search Console patterns. A long query with many appearances and no clicks may look like strong AI demand, yet some patterns can be generated by automated tracking rather than human behavior. Investigate repeated wording, improbable consistency, sudden unexplained volume, and mismatches with the rest of your demand data before building a content plan around it.

    For answer monitoring, save more than a visibility score. Retain the exact prompt, location or market, model or surface, date checked, answer context, brand mention, cited URL, and competing domains. Then report at the topic-cluster level. Individual answers and phrasings vary; clusters show whether you consistently appear for a decision your business cares about.

    Clicks remain useful, but they are no longer a complete measure of influence. A cited passage may answer the question without sending a visit. A recommendation can also lead to branded search, a later direct visit, or an offline action. Treat those as possible outcomes, not automatic credit. The defensible claim is that the brand appeared in the relevant answer; stronger attribution requires supporting behavioral or business data.

    Key takeaways for your next optimization sprint

    • Map the whole decision behind a prompt, including constraints, comparisons, current information, and likely follow-ups.
    • Use People Also Ask, long Search Console queries, answer-engine follow-ups, and prompt tools as complementary proxies, not as a complete record of AI demand.
    • Cluster prompts by intent and evidence requirements. Preserve exact wording, but don’t create a separate URL for every variation.
    • Make answers self-contained, qualified, crawlable, internally connected, and easy to retrieve. Use JSON-LD to describe visible facts, not to manufacture relevance.
    • Track demand, retrieval, answer presence, and business outcomes separately. Never equate a crawler request with a person or a citation with a conversion.
    • Prioritize topics where fresh, local, comparative, or specialized information gives an AI system a reason to retrieve your page.

    Start with one high-value decision your audience already brings to Google. Build its prompt map, audit the strongest existing URL, fill the specific evidence gaps, and create the four-layer scorecard before expanding the program. Your next round of work should follow observed gaps in retrieval and answer presence, not the temptation to generate more pages.

    References

  • How to Build an AI-Driven SEO Visibility Reporting System

    How to Build an AI-Driven SEO Visibility Reporting System

    You can have healthy rankings and still be unable to answer a basic leadership question: Are AI answer engines finding, trusting, and naming our brand? A conventional SEO dashboard cannot answer that on its own. It records search exposure and site visits, while AI visibility may occur inside a synthesized answer, through a third-party citation, or without a click.

    The fix is not another disconnected dashboard. You need a reporting system that connects search performance, AI answer visibility, the evidence supporting that visibility, and the business decision that follows. Here is how to build that system without letting an AI model become the judge of its own work.

    Design the scorecard around the decision it must support

    Start by writing a report brief before choosing metrics. If a metric cannot change an action, it belongs in a diagnostic view rather than the executive scorecard.

    • Decision: State what could change because of the report, such as which topic receives content work, digital PR, technical attention, or distribution.
    • Scope: Name the market, language, device, site section, topic, audience, and search or AI surface covered.
    • Evidence: Define which observations count. A ranking, a brand mention, a linked citation, and a qualified conversion are different events.
    • Trigger: Describe the condition that warrants action. Avoid vague rules such as improving visibility.
    • Owner: Assign the person or team that can act on each finding. A report without an owner is an archive.

    The scorecard should preserve four measurement layers. Keeping them separate prevents a familiar reporting error: treating exposure as traffic, traffic as trust, or a brand mention as revenue.

    Measurement layerWhat to recordQuestion it answersTypical action
    Search performanceClicks, impressions, average CTR, average position, query, page, country, device, search appearance, and date contextCan people discover and choose the site in search results?Investigate query demand, page relevance, result presentation, or technical access
    AI answer visibilityExact prompt, platform, model or visible version, date checked, brand inclusion, citation inclusion, cited URL, and answer contextDoes an AI response use, name, cite, or accurately represent the brand?Improve the answer asset, entity clarity, evidence, or external reinforcement
    Evidence footprintOwned pages, structured data, independent coverage, community discussion, and paid distribution connected to the topicWhat evidence could support discovery and inclusion?Fill a specific owned, earned, shared, or distribution gap
    Business effectQualified visits, conversions, leads, assisted outcomes, or another agreed business resultDid the visibility contribute to something the organization values?Continue, change, or stop the work based on business relevance

    Do not collapse these layers into a single AI visibility score too early. A page can be cited without the brand being named. A brand can be mentioned without a link. A response can name the brand inaccurately. Each outcome calls for a different intervention, so the underlying observations must remain available even if leadership receives a summarized score.

    Build a visibility ledger across paid, earned, shared, and owned media

    Four abstract paid, earned, shared, and owned media channels feed colored evidence tokens into a single central ledger.

    AI visibility does not respect the boundaries in your marketing org chart. Generative systems can draw contextual cues from brand sites, independent coverage, forums, and other public material. The paid, earned, shared, and owned media model gives you a practical way to map those cues without pretending every channel affects an AI answer in the same way.

    • Owned media supplies the answer asset you control. Record the canonical page, the question it answers, the named entities it defines, the supporting evidence it contains, and any relevant structured data. Schema can make meaning more explicit, but it does not guarantee inclusion in an AI response.
    • Earned media supplies independent corroboration. Record who mentioned the brand, which claim or capability the mention supports, the destination URL if one exists, and whether the context is current and relevant.
    • Shared media reveals how a topic is discussed in public communities. Record the recurring question, language people use, misconceptions, and whether the brand appears naturally in the discussion.
    • Paid media can distribute useful material and expose it to an audience, but that effect is indirect. An ad impression is not an AI citation and should never be reported as one.

    Fields that make the ledger diagnosable

    Create a row for each priority topic and audience question. Give every row enough context that another analyst could reproduce the observation without guessing.

    • Topic, audience, market, language, and customer question
    • Exact search query or AI prompt used for observation
    • Canonical owned page and the intended answer section
    • Relevant entity names, products, services, and approved descriptions
    • Supporting claims and where their evidence appears
    • Earned mentions, citing domains, and linked URLs
    • Shared discussions and the questions or terminology they reveal
    • Paid distribution connected to the asset, kept separate from visibility outcomes
    • AI platform, model or visible version, observation date, and response context
    • Brand named: yes or no
    • Brand cited or linked: yes or no, with the exact URL when present
    • Representation: accurate, incomplete, misleading, or unrelated
    • Next action, owner, and the condition for checking again

    Interpret mentions and citations as separate signals

    Brand namedBrand page citedWhat you observedWhat to inspect next
    YesYesThe response visibly associates the brand with a traceable brand-controlled resourceCheck whether the description is accurate, relevant, and supported by the cited page
    YesNoThe brand is included, but the response does not expose a brand-controlled citationInspect third-party citations, mention context, and whether an owned answer asset is clear enough
    NoYesBrand content may inform the answer without prominent brand attribution in the wordingCheck titles, publisher identity, entity naming, and the cited section
    NoNoThe brand was absent from this recorded responseCompare relevant cited domains, content coverage, corroboration, and the exact prompt context

    An absence is an observation, not a universal verdict. Preserve the exact prompt, platform, model context, date, and response. When any of those change, you are no longer running the same check. This is why an undocumented screenshot is weak reporting evidence: it cannot tell you whether visibility changed or the test changed.

    Use Search Console AI configuration as an analyst, not an oracle

    Google has been testing an experimental Search Console feature that converts a plain-language request into settings for the Search results Performance report. It can select metrics such as clicks, impressions, average CTR, and average position, then apply filters or comparisons involving queries, pages, countries, devices, search appearance, and dates. Availability is limited during the experimental rollout, so your reporting process should still work when the interface is configured manually.

    Write requests that expose the intended configuration

    A useful configuration request names the metrics, scope, segment, period, comparison, and report surface. Use this pattern:

    Show [metrics] for [query or page scope], filtered by [country, device, or search appearance], during [period], compared with [baseline period or segment].

    For example, you could request these views:

    • Show clicks, impressions, average CTR, and average position for queries containing the named product category, comparing mobile and desktop.
    • Compare clicks and impressions for a specified site directory across the chosen periods, filtered to the target country.
    • Show query performance for a named landing page during the selected period, then compare it with the relevant baseline.

    The language can be natural, but the analytical intent cannot be fuzzy. A request to show pages losing visibility leaves important questions unanswered: Which metric defines visibility? Against which period? In which country and device context? For all pages or a specific section? Resolve those choices before asking AI to configure anything.

    Validate the generated view before reading the trend

    • Confirm that the selected metrics match the question. Impressions, clicks, CTR, and position describe different parts of search performance.
    • Read every query and page filter literally. Check whether the configuration includes, excludes, contains, or exactly matches the intended value.
    • Confirm country, device, search appearance, and date settings rather than assuming the prompt was interpreted correctly.
    • Check that comparison periods or segments are appropriate for the decision. A valid interface configuration can still represent a weak comparison.
    • Record the final settings with the finding. The reproducible filter state is part of the evidence.
    • For a consequential decision, recreate the important view manually or have another analyst verify the configuration.

    The experimental capability is limited to configuration in the Search results Performance report. It does not sort tables or export the data, and it is not available for Discover or News reports. Most importantly, a configured view is not a diagnosis. The interface may help you reach the right slice of data faster, but you still have to determine what the slice means.

    Make the workflow resilient to model changes

    Interchangeable translucent AI modules connect to a stable workflow while a robotic mechanism replaces one module without interrupting the glowing data flow.

    A newer model should be treated as a changed dependency, not an automatic quality upgrade. In one SEO benchmark, Claude Opus 4.5, Gemini 3 Pro, and ChatGPT-5.1 Thinking produced a reported 9% decline in SEO accuracy. That result comes from a particular benchmark rather than a universal test of every SEO task, but it is enough to challenge the assumption that a model switch can be made without validation.

    The durable unit is the workflow, not the prompt. A standalone instruction such as analyze our SEO performance forces the model to invent definitions, choose evidence, infer priorities, and format the result at once. Split those responsibilities into controlled stages.

    1. Fix the context. Store the organization, site, canonical entity names, products, markets, languages, audiences, business goals, exclusions, and metric definitions outside the ad hoc prompt.
    2. Validate the input. Define required fields, accepted values, date context, missing-value treatment, and the origin of each data field before analysis begins.
    3. Constrain the task. Ask the model to configure a report, classify an observation, compare defined fields, or draft an explanation. Do not combine every task into an open-ended request.
    4. Keep calculations controlled. Let the reporting system produce totals, rates, and comparisons, then give those results to the model for explanation. Do not ask the model to reconstruct critical metrics from loosely pasted fragments.
    5. Require a structured output. Separate observation, supporting evidence, interpretation, proposed action, confidence, and unresolved questions.
    6. Add a human review gate. An analyst should approve filters, factual claims, citations, causal interpretations, and recommendations before the report is distributed.
    7. Regression-test changes. Re-run a stable collection of known SEO cases when the model, prompt, context block, tool, or output schema changes. Compare the kinds of errors, not merely how polished the prose sounds.

    Version the context block, prompt, model, input schema, and output schema together. If the result changes, that record lets you identify whether the underlying market moved, the evidence changed, or the measurement machinery changed.

    Use confidence labels that reveal the reasoning boundary

    • Observed: Directly visible in the recorded search data or AI response.
    • Derived: Calculated from defined fields using a documented rule.
    • Inferred: A plausible explanation supported by observations but not proven by them.
    • Unverified: A claim that requires another check before it can guide action.

    This vocabulary stops fluent model output from quietly turning correlation into cause. Require every inferred explanation to point back to the observations supporting it, and allow the report to say that the cause is not yet known.

    Turn every reporting cycle into an operating decision

    The useful endpoint is not a chart. It is a documented decision with an owner and a condition for reassessment. Run the same operating loop each time so that changes in process do not masquerade as changes in performance.

    1. Freeze the measurement context. Save the prompt set, Search Console configuration, market and device scope, AI platform, model context, and observation date.
    2. Collect the layers separately. Record search performance, AI mentions, citations, answer accuracy, evidence footprint, and business effects without merging them prematurely.
    3. Compare like with like. Identify which layer moved while holding the relevant measurement context stable.
    4. Diagnose the gap. Use query and page segments for search changes, response records for AI changes, and the paid-earned-shared-owned ledger for evidence gaps.
    5. Choose the smallest action that tests the diagnosis. Name the page, claim, entity, citation gap, distribution task, or configuration that will change.
    6. Assign an owner and a reassessment condition. State what evidence would support, weaken, or disprove the working explanation.
    Search performanceAI visibilityWorking interpretationNext check
    WeakerWeakerA broader demand, access, relevance, competitive, or evidence problem may be affecting both layersSegment queries and pages, confirm technical access, and inspect which domains or resources now appear
    SteadyWeakerThe change may sit in the AI surface, recorded test context, cited evidence, or external brand footprint rather than conventional rankingsRe-run the fixed prompt set, compare model context, inspect citations, and review earned and shared evidence
    StrongerSteadySearch gains are not yet visible in the tracked AI answersInspect answer clarity, entity naming, supporting claims, structured data relevance, and independent corroboration
    SteadyStrongerThe brand is gaining answer visibility without a corresponding search liftSeparate linked citations from unlinked mentions, verify representation, and check business effects before declaring success
    StrongerStrongerVisibility improved across both discovery paths, but attribution still needs evidenceIdentify which content, technical, earned, shared, or distribution changes preceded the movement and test the explanation

    Key takeaways

    • Measure search performance, AI answer visibility, evidence, and business effects as connected but distinct layers.
    • Keep brand mentions, links, citations, accuracy, and conversions separate in the underlying data.
    • Use paid, earned, shared, and owned media to diagnose why evidence is strong or weak around a topic.
    • Inspect every AI-generated Search Console filter before interpreting the resulting trend.
    • Version prompts, context, schemas, models, and test conditions so reporting changes remain explainable.
    • Treat AI observations as reproducible records and causal explanations as hypotheses that require validation.

    Start the next reporting cycle with a priority topic, a fixed prompt set, a reproducible Search Console view, and a visibility-ledger row. Follow the evidence until you can assign a specific action. Once that loop works reliably, expand it across more topics instead of scaling an unverified score.

    References