Tag: AEO

  • Profound’s $35M Funding and Its Developer Ecosystem

    Profound’s $35M Funding and Its Developer Ecosystem

    If you’re deciding whether Profound belongs in your AI-search stack, the funding number is the least useful place to stop. A financing round can give a vendor room to build. It cannot tell you whether its data is trustworthy, its package fits your application, or its integration is safe to run in production.

    Profound now offers three concrete signals to investigate: $35 million in Series B funding, a one-click Vercel Marketplace integration for Agent Analytics, and next-aeo, an NPM package built for Next.js applications. That combination shows where an ecosystem may be forming. It does not remove the need for technical due diligence.

    Read the $35 million as capacity, not product proof

    Funding matters because software ecosystems require sustained investment. The core product is only one expense. A useful developer platform also needs documentation, integrations, package maintenance, support, security work, infrastructure, and compatibility testing.

    Profound’s $35 million raise creates capacity for that work. It does not prove that every part has already been delivered, nor does it guarantee product quality, vendor longevity, or a particular roadmap. A financing event is not a service-level agreement.

    Separate the headline from the evidence by keeping a simple evaluation ledger with three states:

    • Available: The vendor publicly offers the capability, package, or integration.
    • Verified: Your team has confirmed how it behaves in your own environment.
    • Unknown: The answer depends on documentation, testing, a contractual commitment, or a response from the vendor.

    The funding belongs in the available column as evidence of new financial capacity. The Vercel integration and next-aeo package also belong there until you test them. Do not quietly promote an available feature to verified merely because installation looks simple.

    When you evaluate what the funding could mean for your organization, look for release evidence in four areas:

    • Product delivery: Are analytics, integrations, and developer tools becoming usable parts of the same workflow?
    • Maintenance: Can you find version requirements, release notes, upgrade guidance, and a clear support path?
    • Operational depth: Are permissions, exports, retention, failure modes, and rollback procedures explained?
    • Developer adoption: Can an engineer install, inspect, test, and remove the tooling without relying on a sales demonstration?

    This keeps the decision grounded. Capital can accelerate an ecosystem, but only maintained interfaces make that ecosystem useful to your team.

    The ecosystem has three layers with different jobs
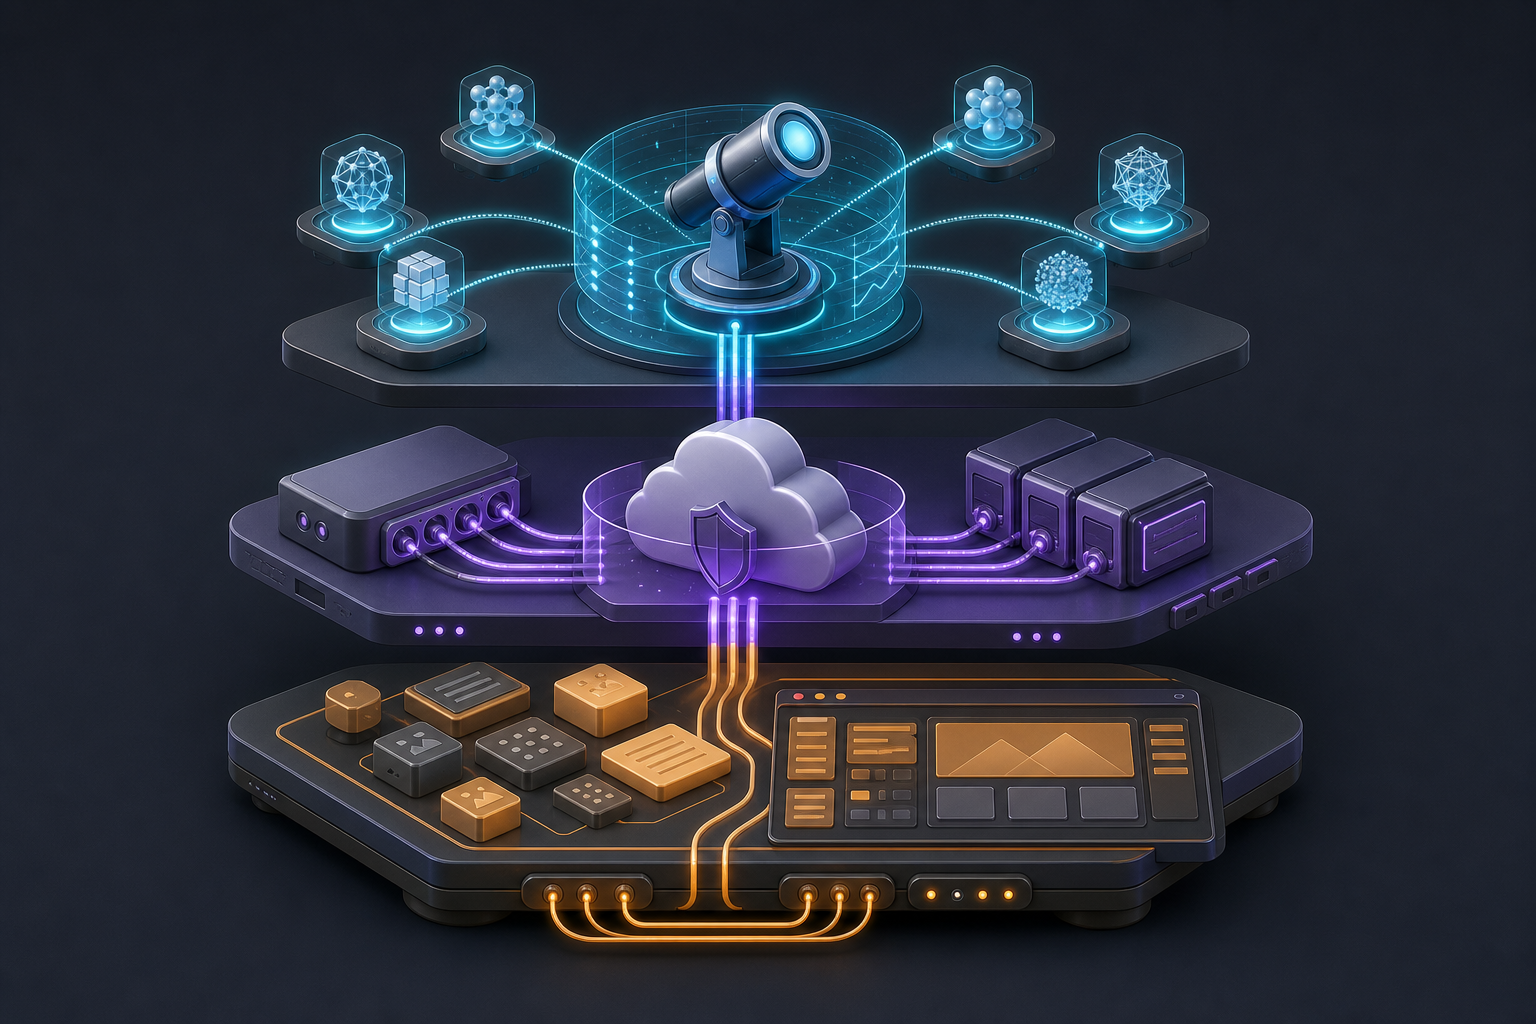
    An isometric three-level system connects AI-search analytics, a cloud integration gateway, and modular web application components.

    Profound’s current footprint spans company capacity, deployment distribution, and application-level tooling. Those layers answer different questions, so they should not be treated as interchangeable proof.

    LayerVerified public signalWhat it helps you assessWhat it does not establish
    Company capacity$35 million Series B fundingAccess to new capital for expansionProduct accuracy, profitability, long-term availability, or service quality
    Deployment distributionAgent Analytics on the Vercel Marketplace with a one-click connectionWhether a supported installation path exists for a Vercel workflowProduction permissions, data handling, metric definitions, or setup after authorization
    Application toolingnext-aeo as an NPM package for Next.jsWhether developers have a framework-specific AEO entry pointExact output, version compatibility, ranking effects, or maintenance quality

    The important question is whether these layers form a closed operating loop. Your application produces content and machine-readable signals. Analytics helps you observe how AI systems interact with the site. Those observations should lead to a specific content, code, or distribution decision. If your team cannot identify that final decision, the stack may create another dashboard without improving the workflow.

    One-click installation is not one-click operation

    The Vercel Marketplace integration is meaningful because it brings Agent Analytics into a deployment channel developers may already use. For a Vercel-based team, a marketplace connection can reduce custom setup work.

    But one-click describes the start of the connection, not the quality of the outcome. Before calling the integration production-ready, determine:

    • Which Vercel projects, environments, accounts, and resources it can access.
    • Which credentials or tokens it creates, where they are stored, and how they are revoked.
    • What data leaves your environment and whether prompts, URLs, responses, or user-related fields can be included.
    • How an AI interaction is identified, filtered, deduplicated, and attributed.
    • What happens when the integration fails, is disconnected, or encounters a deployment change.
    • Whether data can be exported before you remove the integration.

    Treat the marketplace listing as evidence of distribution maturity. Treat data quality, security, and operational fit as separate tests.

    next-aeo moves AEO into the application layer

    The next-aeo package targets Next.js developers and frames answer engine optimization as an implementation concern, not only an editorial checklist. That is useful because developers can potentially review AEO-related behavior alongside application code, dependencies, builds, and deployments.

    Do not infer its exact behavior from the package name. Before adoption, inspect whether it changes rendered HTML, metadata, structured data, routes, configuration, server behavior, or the build pipeline. Establish which Next.js versions and routing models it supports. Check whether the package behaves differently with static generation, server rendering, incremental regeneration, or client-rendered content where those patterns exist in your application.

    If next-aeo emits or transforms JSON-LD, inspect the final rendered markup rather than the source configuration alone. Look for invalid syntax, duplicate entities, conflicting identifiers, missing required properties, and differences between development and production builds. If it modifies metadata, compare canonical URLs, robots directives, titles, descriptions, and social metadata before and after installation.

    AEO does not create a guaranteed position in an AI-generated answer. Use the package to improve implementation discipline only after you can explain what it produces and why that output should help answer-oriented systems understand the page.

    Use a production-readiness checklist before connecting data
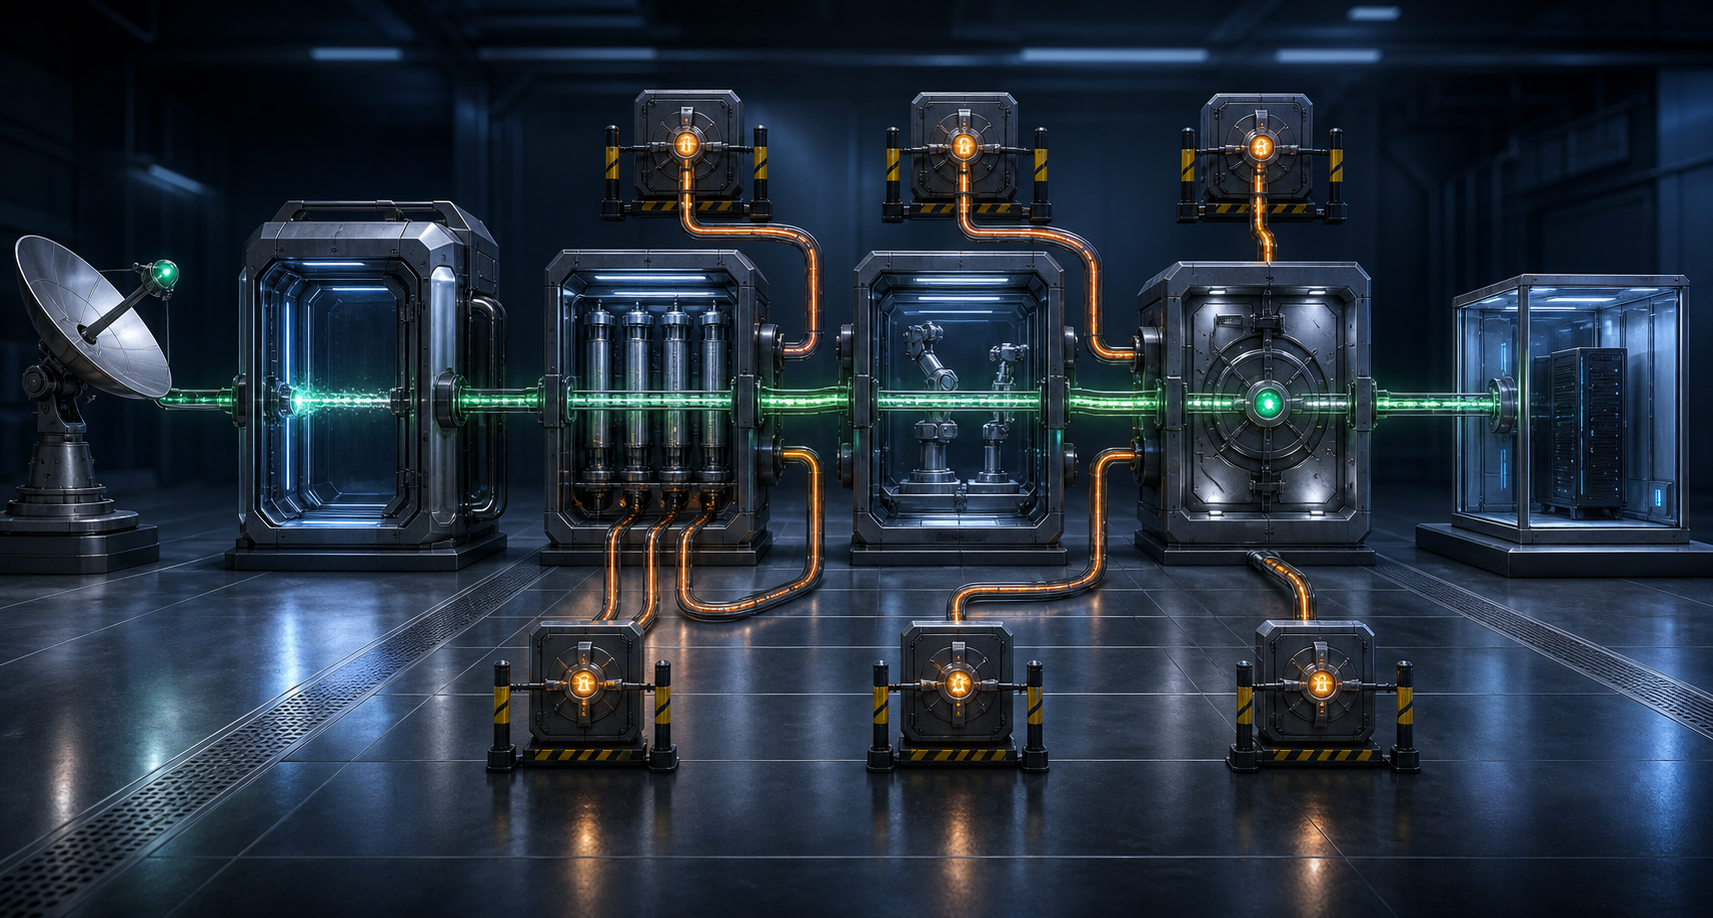
    A data pipeline passes through privacy, validation, testing, monitoring, and final approval gates before reaching a production application.

    The fastest way to make a weak platform decision is to install first and define success later. Write the test contract before the package or integration changes your environment.

    Define the measurement contract

    Agent Analytics is intended to provide insight into AI interactions with a site. That description is a starting point, not a metric definition. Your team should be able to answer these questions before using the data for strategy:

    • What event qualifies as an AI interaction?
    • How are agents distinguished from ordinary browsers, crawlers, proxies, automation, and spoofed user agents?
    • Which fields are observed directly, and which are inferred?
    • How are repeated requests, retries, cached responses, and internal traffic handled?
    • Which dimensions are available for filtering and comparison?
    • How far back does the data go, and can a methodology change alter historical comparisons?
    • Can the underlying records be exported for independent validation?

    Write the accepted definition beside every metric you plan to report. If a stakeholder asks what changed, you should be able to explain both the number and the collection mechanism. A polished dashboard label is not a substitute for a documented definition.

    Test application compatibility at the rendered-output level

    Record the exact Next.js version, router, rendering modes, deployment configuration, package manager, and existing SEO or schema tooling in the test environment. Then compare the application before and after installation at several points:

    • Dependency resolution and installation output.
    • Local and production-mode build logs.
    • Generated artifacts and server output.
    • Rendered HTML, metadata, response headers, and structured data.
    • Representative static, dynamic, localized, canonicalized, and authenticated routes used by your application.
    • Deployment logs, runtime errors, and page behavior after release.

    Pin the version you test and preserve a rollback path. An automatic package upgrade can change sitewide output, so do not leave a production AEO dependency floating across unreviewed releases.

    Review permissions and data handling before production

    Do not connect a production project until you understand the integration’s access scopes, network destinations, credential lifecycle, retention behavior, deletion process, and administrative controls. If prompts, URLs, responses, or user-related fields can be collected, involve the people responsible for security, privacy, and consent before enabling that collection.

    A mis-scoped credential can expose more infrastructure than the tool needs. Unexpected collection can create privacy or contractual exposure. Use a staging environment or a non-sensitive project while those questions remain unresolved, and grant the narrowest access that still supports the test.

    Assign operational ownership

    An ecosystem becomes expensive when every component exists but nobody owns the handoffs. Name the person or team responsible for each recurring task:

    • Reviewing package releases and compatibility changes.
    • Approving integration permissions and credential rotation.
    • Investigating analytics anomalies and methodology changes.
    • Turning observations into content or engineering work.
    • Maintaining documentation for installation, rollback, export, and removal.
    • Deciding whether the tooling still earns its place in the stack.

    If these responsibilities fall between SEO, engineering, analytics, and security, the integration will eventually become unowned infrastructure. Resolve that before rollout.

    Run a staged pilot that ends with a decision

    Your first pilot should establish operational fit. Do not promise an AI-visibility lift before the implementation and measurement definitions are stable. A narrow, reversible test will tell you more than a broad installation with no baseline.

    1. Name the decision. State whether you are evaluating Profound for measurement, application-level AEO implementation, or the combined workflow. Define what would lead to adoption, a hold, or rejection.
    2. Capture the baseline. Record the application version, deployment settings, representative routes, current HTML and metadata, existing JSON-LD, current analytics, and known errors before making a change.
    3. Review the artifacts. Check package requirements, permissions, data handling, release information, support paths, and removal steps. Put unresolved questions in the unknown column of your evidence ledger.
    4. Use a non-production environment. Connect the Vercel integration only after reviewing its requested access. Scope the next-aeo change as narrowly as the package and application architecture permit.
    5. Inspect every layer. Verify that the application installs and builds, that rendered output changes only as expected, and that analytics records can be explained using a documented definition.
    6. Roll back and repeat. Remove the package or integration, confirm that the environment returns to its baseline state, and repeat the installation from written instructions. This exposes hidden manual steps and configuration drift.
    7. Write the decision record. List what was verified, what remains unknown, who owns the workflow, and what would trigger reevaluation. Keep funding and roadmap expectations separate from tested behavior.

    Use explicit gates for approval. A credible pilot should produce a repeatable installation, understandable data, no unexplained output changes, acceptable permissions, a named operational owner, and a tested exit path. If one of those is missing, document the gap instead of averaging it away with strengths elsewhere.

    The combined stack earns a broader rollout only when the loop works: application changes are inspectable, analytics is explainable, and the resulting evidence leads to a concrete optimization decision. That is the difference between owning an ecosystem and merely accumulating tools.

    Key takeaways

    • Profound’s $35 million Series B provides capacity to invest, but it does not validate product performance, security, or long-term fit.
    • The Vercel Marketplace integration reduces initial connection friction; one-click installation does not settle permissions, data quality, retention, or operational ownership.
    • The next-aeo NPM package gives Next.js teams a framework-specific AEO entry point, but you still need to verify compatibility and inspect its rendered output.
    • Evaluate funding, analytics, deployment integration, and application tooling as separate layers before testing whether they form a useful workflow.
    • Use a narrow staging pilot, written measurement definitions, pinned dependencies, and a tested rollback path before committing production data or sitewide output.

    If Profound is on your shortlist, pair an engineer with the person who owns AI-search performance and complete the evidence ledger before procurement or production access. Let reproducible installation, explainable data, and safe removal make the decision.
    References

  • How to Optimize Existing Content for AI Visibility

    How to Optimize Existing Content for AI Visibility

    You probably don’t need another batch of articles. If your site already answers valuable customer questions, the faster route to more AI visibility may be to make those answers easier to identify, interpret, verify, and cite.

    That requires more than adding keywords or mentioning AI. You need to choose the right pages, map them to real questions, strengthen the passages that carry the answer, remove contradictions, and measure whether answer engines represent your brand more accurately afterward.

    Choose pages with a credible path to visibility

    Blank content tiles in a digital workspace, with three well-connected pages highlighted for selection.

    Don’t begin by refreshing every old URL. A large content library contains pages with very different jobs: some attract qualified demand, some support customers, some establish expertise, and some no longer deserve attention. Optimizing all of them equally spreads effort across content that has little chance of influencing an AI-generated answer.

    Start with the questions you want your brand to be associated with. Then identify which existing page should provide the best answer to each question. This question-to-page mapping matters because AI visibility is contextual. A brand mention for an irrelevant query is not a useful result, and several pages competing to answer the same question can make your intended answer less clear.

    Build your optimization queue around these signals:

    • Audience relevance: The page addresses a problem your buyers, users, or stakeholders genuinely need to solve.
    • Business relevance: You would be comfortable having this page represent your brand in an AI-generated answer.
    • A recoverable answer: The page contains useful knowledge, but the direct answer is buried, fragmented, vague, or outdated.
    • Evidence readiness: Important claims can be supported, qualified, or removed. A page full of assertions you cannot verify is a poor optimization candidate.
    • A clear page owner: Someone can review the content when products, processes, terminology, or evidence change.
    • Limited internal conflict: The same site does not give several incompatible answers to the question. If it does, consolidation or reconciliation comes before stylistic editing.

    Assign each candidate a practical disposition: update, expand, consolidate, replace, or leave alone. “Leave alone” is a legitimate decision when a page is accurate, clear, and serving its intended purpose. Optimization should solve a diagnosed problem, not create change for its own sake.

    For an established site, improving content already in the library can be more useful than treating publication volume as the default growth lever. The key is selection. Refresh the pages that already contain defensible knowledge and have a defined question to answer.

    Turn each target question into an evidence-led brief

    A content brief for AI visibility should specify the answer before it specifies the word count, format, or keyword set. Otherwise, the writer can produce a polished page without resolving the question an answer engine needs to handle.

    Use first-party evidence to find the language behind the question: search queries, on-site searches, support requests, sales objections, customer interviews, and the prompts your visibility monitoring already tracks. Group different phrasings by the underlying decision. “Should we update this page?” and “Does this page need a rewrite?” may belong to the same question family, while “Why did traffic fall?” requires a different answer.

    Your brief should contain:

    • Primary question: The exact problem the page must resolve.
    • Reader context: Who is asking, what they already know, and what decision follows the answer.
    • Direct answer: The conclusion the page can support without exaggeration.
    • Scope: The products, markets, use cases, versions, or conditions to which the answer applies.
    • Supporting questions: The follow-ups a reader needs before acting, not every loosely related keyword.
    • Evidence: The internal data, official documentation, primary material, or other support available for each consequential claim.
    • Required entities: The full names of products, organizations, standards, methods, and concepts that must be unambiguous.
    • Exclusions: Claims the evidence cannot support and tangents that would dilute the page’s purpose.
    • Desired citation: The specific fact, explanation, or recommendation for which this page should be the appropriate reference.
    • Maintenance owner: The person or team responsible for future review.

    This is where data-driven briefs earn their keep. They force the team to connect demand, evidence, and page structure before drafting. Vendor-reported results from teams using data-driven briefs include noticeable AI-visibility improvements within a few weeks. Treat that timing as an encouraging observation, not a guarantee or a universal benchmark; visibility depends on the question, competitive field, source discovery, and the answer system being monitored.

    Templates can also make quality more repeatable across writers and subject-matter experts. In vendor-reported use, teams have published template-led content that received AI citations. The template itself is not the reason to trust the page. Its value is that it makes missing answers, unsupported claims, and unclear ownership harder to overlook.

    Make the answer easy to extract without flattening the page

    Cutaway illustration of a structured web page with an answer block supported by connected evidence and context.

    An answer engine may encounter a passage without carrying all the context from the paragraphs around it. Your most important sections therefore need to make sense on their own. That does not mean reducing the whole page to disconnected snippets. It means placing the necessary context next to the claim it qualifies.

    Use descriptive headings that reveal the section’s job. “When to refresh an existing page” is more informative than “Content strategy.” Under the heading, answer the question immediately, then explain the reasoning, evidence, limits, and next action.

    Compare these two openings:

    Weak: It depends on several factors, and every situation is different.

    Stronger: Refresh an existing page when it still addresses the correct audience and intent, but its answer is incomplete, difficult to locate, internally inconsistent, or no longer current.

    The stronger version gives the reader a decision rule. The following paragraphs can still cover exceptions. This order serves both human readers and systems trying to determine what the passage claims.

    As you revise each answer-bearing section, check for these extraction problems:

    • Delayed answers: The section spends several paragraphs setting up a conclusion it could state at the beginning.
    • Unclear references: Pronouns such as “it,” “they,” or “this” could refer to more than one entity. Repeat the necessary name where ambiguity would change the meaning.
    • Missing conditions: A recommendation appears universal even though it applies only to a particular audience, product state, market, or scenario.
    • Orphaned numbers: A figure appears without the population, period, definition, or supporting evidence needed to interpret it.
    • Decorative lists: Prose has been broken into bullets even though the items are not parallel choices, steps, requirements, or criteria.
    • Heading drift: The heading promises one answer while the paragraph discusses a neighboring topic.
    • Conflicting claims: The summary, body, FAQ, metadata, and structured data describe the same fact differently.
    • Unsupported certainty: Words such as “always,” “best,” and “guaranteed” overstate what the available evidence can establish.

    Lists are useful when the reader needs to evaluate criteria or follow a sequence. Tables are useful when the same dimensions must be compared across several options. Plain paragraphs are better when the reasoning depends on context. Choose the format that preserves meaning instead of forcing every passage into a supposedly AI-friendly pattern.

    Keep evidence close to consequential claims. Name the organization, product, method, or standard involved. Link to the material that actually supports the sentence. If evidence is limited, state the limitation in the same section rather than hiding it in a general disclaimer.

    Structured data belongs in this consistency check, but it cannot rescue an unclear or unsupported page. Use a schema type that matches the visible content, and keep names, dates, authorship, descriptions, and other shared facts aligned with what a visitor can read. Do not place a claim only in JSON-LD and assume that markup turns it into evidence.

    Use separate workflows for live pages, drafts, and measurement

    A live page and an unpublished draft can use the same brief, but they do not carry the same risks. A draft has no established search role to preserve. A live URL may already earn traffic, links, conversions, citations, or internal prominence. Capture what the live page is doing before you change it.

    Refreshing a published page

    1. Record the baseline. Save the current title, headings, central claims, structured data, internal links, organic performance, conversions, brand mentions, and observed AI citations. Without a baseline, a later comparison becomes guesswork.
    2. Protect the page’s valid purpose. Write down the audience, target question, and useful material that must survive the refresh. Do not turn a functioning specialist page into a broad overview merely to cover more terms.
    3. Resolve factual conflicts. Compare important claims across the page and relevant pages on your site. Decide which statement is authoritative, update the others, and document the owner.
    4. Rewrite answer-bearing sections first. Improve the direct answer, scope, evidence, entity naming, headings, and supporting questions before polishing transitional copy.
    5. Check the whole published object. Review visible copy, links, metadata, canonical settings, indexability, structured data, media, and mobile presentation. A clean draft can still become an inconsistent page in the CMS.
    6. Log the change. Record what was changed, why it was changed, when it went live, which questions it targets, and what result would count as an improvement.

    Optimizing drafts and internal documents

    You do not need to wait for a public URL to test whether a draft answers the intended question. Some optimization workflows can evaluate pasted text and uploaded files as well as live URLs. That is useful for briefs, subject-matter-expert drafts, reports, and other material that should be corrected before it reaches the CMS.

    For unpublished material, mark the direct answer, evidence gaps, undefined entities, unsupported claims, and required follow-up questions in the source document. Then run a separate page-level review after publishing. A document file does not show the final navigation, metadata, structured data, internal links, templates, or rendering that can affect how the page is understood.

    Measuring a visibility change

    Measure against a stable set of questions. If you change the prompt, answer engine, page, and success criterion at the same time, you will not know what moved. For every observation, log the exact question, engine or model, date, brand representation, cited URLs, factual accuracy, and landing page.

    Track more than whether the brand appeared:

    • Question coverage: Does the answer address the intended problem or merely mention a related topic?
    • Brand representation: Is the brand associated with the correct product, category, position, or expertise?
    • Citation presence: Does the response link to a source, and is your page among the cited URLs?
    • Citation fit: Is the correct page cited for the claim, or has a weaker or unrelated page been selected?
    • Answer accuracy: Does the generated statement preserve your conditions, limitations, and current facts?
    • Durability: Does the result recur across repeated observations, or was it an isolated output?
    • Downstream value: When measurable, does visibility lead to qualified visits, branded demand, assisted conversions, or another outcome your organization values?

    Use misses as diagnostic clues, not instant proof of a cause. If the brand never appears, test whether the page truly matches the question and contributes information that deserves selection. If the brand appears without a citation, inspect whether the claim is self-contained and supported. If the wrong page is cited, look for overlapping intent or inconsistent internal signals. If the answer distorts your position, rewrite the ambiguous passage and remove conflicting language elsewhere.

    Answers can vary between runs, models, and interfaces. A single screenshot is therefore weak evidence of a durable gain or loss. Repeated observations using the same question set give you a more defensible basis for deciding whether to keep, revise, or reverse a change.

    Key takeaways

    • Optimize around questions you want your brand to answer, then assign a clear page to each question.
    • Prioritize existing pages with useful knowledge, business relevance, supportable claims, and a maintainable owner.
    • Put the direct answer near the start of each section, with its scope, evidence, and limitations close by.
    • Use descriptive headings, explicit entity names, genuine lists, and consistent facts across copy, metadata, links, and structured data.
    • Review drafts before publication, but repeat the audit on the rendered page because the CMS adds context the document does not contain.
    • Measure question coverage, citation fit, accuracy, durability, and business value against a recorded baseline.

    Choose a small set of commercially relevant questions and map each one to its strongest existing page. Complete the brief, revise the answer-bearing sections, validate every important claim, and record the baseline before publishing. That gives you an optimization cycle you can inspect and improve, rather than a collection of edits you can only hope will work.

    References

  • Profound’s AEO Expansion: A Practical Agency Playbook

    Profound’s AEO Expansion: A Practical Agency Playbook

    When a client asks why ChatGPT names a competitor instead of them, a screenshot is not an AEO service. You need to reproduce the result, distinguish a real visibility problem from prompt-level noise, identify an intervention, and show what changed afterward.

    Profound is expanding across the parts of that workflow: Starter and Growth plans intended to make AEO accessible to more businesses, Agency Mode for creating and managing brand environments from pitch audit through full setup, and a G2 partnership framed around making AI search a performance channel. For an agency, the opportunity is not simply to resell access. It is to build a disciplined service around those capabilities.

    Profound’s expansion raises the bar for agency value

    Starter and Growth plans change the commercial baseline. A business can approach AEO as a direct software purchase rather than assuming it must begin with a large consulting engagement. That does not remove the need for agencies. It removes the weakest version of the agency offer: charging mainly for access, exports, and screenshots.

    Your defensible value now sits in the work around the platform:

    • Translating the client’s buying journey into questions that real prospects might ask.
    • Separating category, comparison, validation, risk, and brand-specific questions instead of blending them into one visibility score.
    • Explaining whether an unfavorable answer reflects missing content, weak third-party evidence, ambiguous brand information, a reputation issue, or merely one unstable response.
    • Turning the diagnosis into owned work across content, technical optimization, brand, product marketing, and public relations.
    • Maintaining an evidence trail that shows what was observed, what changed, and what can reasonably be inferred.

    This distinction matters because ChatGPT, Perplexity, and Google AI Overviews are separate answer surfaces. They can interpret the same question differently, draw on different evidence, and present brands in different ways. Do not collapse their outputs into a single percentage unless you can explain the weighting and why that weighting matches the client’s market.

    Keep the underlying observations separate. Record the engine, exact question, answer, citations, competitors mentioned, brand description, and collection date. You can create an executive summary later, but the summary should remain traceable to those observations.

    Also keep three signals distinct. A citation means an answer used or exposed a source. A mention means the brand appeared. A recommendation means the answer positioned the brand as a suitable choice. Treating those events as interchangeable makes a report look cleaner while making it less useful.

    Design separate pitch and delivery workflows

    Two parallel studio lanes depict a short pitch audit and a longer client delivery workflow connected by a gated bridge.

    Agency Mode can reduce the setup friction around multiple brands, but an on-demand environment is only a container. Your methodology still determines whether that container becomes a repeatable service or a collection of unrelated prompts.

    Use the pitch environment to establish whether a problem exists

    A pitch audit should be narrow enough to complete without pretending it is a full strategy. Its job is to establish whether the prospect has a material, actionable AI-discovery gap.

    1. Define the decision before collecting answers. Write one sentence describing what the audit must help the prospect decide, such as whether to commission a full diagnostic or which product category deserves deeper analysis.
    2. Choose questions by intent. Include category discovery, direct comparison, evidence-seeking, objection, and branded questions. Do not select only prompts that are likely to produce a dramatic competitor comparison.
    3. Freeze the wording used for the audit. Small wording changes can alter an answer. Store the exact prompt rather than a shortened label such as “best tools.”
    4. Create an evidence ledger. For every observation, capture the answer surface, prompt, output, citations, brand status, competitor status, and collection date. Preserve the evidence behind every slide.
    5. End with decisions, not a visibility score. State which gaps appear actionable, what remains uncertain, and what a full engagement would need to investigate.

    A pitch finding should sound like this: the brand was absent from a group of comparison questions while named competitors appeared with third-party support, so the next step is to examine the evidence those answers relied on. It should not sound like this: the brand has poor AEO and needs an open-ended retainer. The first statement is bounded by evidence. The second turns a sample into a diagnosis.

    Give the client environment delivery-grade governance

    Once a prospect becomes a client, do not continue the pitch setup casually and call it production-ready. Convert it through a defined handoff. A full brand setup needs:

    • An approved list of brand names, products, former names, abbreviations, and commonly confused entities.
    • A scope statement covering markets, languages, audiences, product lines, and excluded areas.
    • A governed prompt library divided into stable monitoring questions and temporary exploratory questions.
    • Rules for selecting competitors, so the comparison set does not change whenever a surprising answer appears.
    • An evidence archive connected to each reported finding.
    • An action register with a diagnosis, owner, dependency, expected signal, and implementation status.
    • A change log linking live content, technical, reputation, or distribution work to later observations.
    • A reporting definition for presence, citation, recommendation, accuracy, and sentiment or positioning.

    The reusable asset is the structure, not the client’s assumptions. Reuse fields, classifications, quality checks, and reporting logic. Do not reuse another brand’s competitors, prompt wording, market boundaries, or definition of success.

    This is where Agency Mode can support real scale. Faster environment creation is valuable only if each new environment inherits a sound operating method and remains isolated from unrelated client context.

    Sell a decision ladder instead of a dashboard

    An agency offer becomes easier to buy when each stage answers a different question. It also becomes easier to deliver because the team knows where an engagement ends and what evidence is required before it expands.

    Service stageClient decisionRequired evidencePrimary deliverable
    Pitch auditIs there an AEO problem worth investigating?A bounded sample of buyer questions with preserved outputs and citationsAn evidence-backed opportunity brief with clear uncertainties
    Baseline diagnosticWhere is the brand underrepresented, misrepresented, or weakly supported?A governed question set, competitor rules, source patterns, and brand-position analysisA prioritized backlog tied to specific visibility problems
    Implementation programWhich changes should go live, and who owns them?Approved recommendations, dependencies, owners, and measurement criteriaPublished improvements plus a complete change log
    Managed AEO programIs representation changing, and does it support a business objective?Repeated observations gathered consistently and connected to available business dataTrend analysis, experiment decisions, and the next prioritized actions

    This ladder prevents two common scope failures. The first is giving away a full diagnostic under the label of a pitch audit. The second is selling recurring monitoring without responsibility for deciding or implementing what happens next.

    Clients with direct access to an entry plan can already inspect outputs. The agency must therefore define what its fee covers beyond software: research design, validation, interpretation, implementation, governance, cross-team coordination, and outcome analysis. Put those responsibilities in the scope rather than leaving the client to infer them.

    Three commercial boundaries should remain explicit:

    • Platform access is not an outcome. A subscription can provide observations, but it cannot guarantee that an answer engine will mention or recommend a brand.
    • An audit is not implementation. State whether your team will publish changes, advise the client’s team, coordinate other specialists, or stop after prioritization.
    • AI visibility is not conversion. A stronger presence may support discovery, but it should not be presented as revenue unless the measurement chain reaches a defensible business event.

    Before setting fees, verify the plan limits and operating costs that apply to the agency’s actual account. Model the staff time required for prompt governance, evidence review, client communication, and implementation. A tool can reduce setup effort without removing the expensive judgment work.

    Measure performance without pretending attribution is solved

    An analyst examines overlapping translucent paths between AI response signals and several business outcome objects.

    Profound’s G2 partnership points toward a performance-oriented view of AI search. That direction is commercially important, but the existence of a partnership does not by itself establish closed-loop attribution. An agency still needs to show exactly how an observation becomes a business claim.

    Use an evidence chain that a client can audit:

    1. Observation: preserve the exact question, answer surface, output, citations, and collection date.
    2. Classification: mark whether the brand was absent, mentioned, cited, described accurately, compared, or recommended. Keep the raw output available.
    3. Diagnosis: explain the likely mechanism and label it as a hypothesis until supporting evidence exists. An absent brand mention does not automatically prove a content problem.
    4. Intervention: record the content, technical, entity, reputation, or distribution change that went live, along with its owner and completion status.
    5. Leading response: repeat the governed observation process and report changes in presence, citation, accuracy, or positioning without claiming that the intervention was the sole cause.
    6. Business evidence: connect the work to qualified traffic, leads, pipeline, sales, or another agreed outcome only where analytics or customer data supports that connection.

    This chain protects the client and the agency from an attractive but misleading shortcut: turning a visibility movement into a revenue claim. Keep visibility, influence, and outcome as separate reporting layers.

    • Visibility asks whether and how the brand appeared.
    • Influence asks whether the representation could help or hinder a buyer’s evaluation. Unless user behavior is observed, this remains an interpretation rather than a measured action.
    • Outcome requires an observable business event connected through available analytics, CRM, commerce, or customer evidence.

    AI answers can vary even when a prompt does not. That makes reproducibility a method rather than a promise that every run will match. Preserve wording, keep market and language settings consistent where possible, document collection conditions, and look for patterns across the governed question set. Do not conceal variation by selecting only the output that supports the preferred story.

    Before expanding Profound across an agency, verify the operational details in the current product, account, and contract:

    • Which answer surfaces, markets, and languages are supported for the work you intend to sell?
    • What limits apply to brands, environments, users, prompts, or usage?
    • How do roles and permissions prevent unwanted access across client teams?
    • Can raw evidence, reports, and historical data be exported in a usable form?
    • What happens to a pitch environment when the prospect becomes a client?
    • How are metrics defined, and can your team inspect the observations beneath an aggregate score?
    • What data is retained, for how long, and under which controls?
    • What does the G2 partnership enable in practice, and which attribution steps still require the agency’s own data?

    These are not edge-case procurement questions. Their answers determine your delivery capacity, evidence quality, client confidentiality, margin, and ability to change platforms later.

    Key takeaways

    • Profound’s broader plans make software access easier, so agencies need to compete on methodology, interpretation, implementation, and governance.
    • Agency Mode is most useful when pitch audits and full client programs follow separate, documented workflows.
    • Build offers as a decision ladder: pitch audit, baseline diagnostic, implementation, and managed optimization should answer different client questions.
    • Do not merge citations, mentions, recommendations, and business outcomes into a single visibility claim.
    • Treat performance attribution as an evidence chain, and verify exactly what the platform and G2 partnership contribute before promising it to clients.

    Your next move is to run the operating model on one suitable prospect or existing client. Define the decision first, build the evidence ledger before collecting answers, and require every finding to lead to an owned action or an explicit uncertainty. That dry run will expose weaknesses in your scope, handoff, measurement, and margins before you multiply them across more brand environments.

    References