Tag: AEO

  • How to Defend Your Brand and Stay Visible in AI Search

    How to Defend Your Brand and Stay Visible in AI Search

    Your brand can appear in an AI answer and still lose the decision. The system may name you, then attach an outdated limitation, confuse your product with another company, cite a weak page, or frame a legitimate tradeoff as a reason to avoid you.

    If buyers use ChatGPT, Gemini, and Perplexity to evaluate brands, visibility and brand defense have to become one operating discipline. You need to know which questions matter, what the systems are saying, which public evidence supports those answers, and who will correct a problem when the narrative drifts.

    Key takeaways

    • Do not measure visibility as a simple mention. Separate presence, citations, factual accuracy, decision framing, and answer volatility.
    • Build your audit around the prompts buyers use to discover, compare, validate, question, and reject a brand.
    • Maintain a claim ledger that connects every important brand statement to a canonical page, supporting evidence, an owner, and a freshness trigger.
    • Use structured data to reinforce visible, consistent facts. Schema cannot repair weak evidence or persuade a system that your claims are true.
    • Treat accurate criticism, stale information, factual errors, subjective opinions, and identity confusion as different problems. Each requires a different response.
    • Judge progress by whether important answers become more accurate and supportable across a stable prompt set, not by whether one screenshot looks favorable.

    Map the prompts where your brand wins or loses the decision

    A conventional keyword list will miss much of the risk. Brand decisions often unfold through conversational prompts that combine a product, situation, objection, and desired outcome. A buyer may not search your name until late in that sequence.

    Prompt research for SEO and GEO starts by reconstructing that decision, not by adding question marks to existing keywords. Gather the language used in sales calls, support tickets, on-site search, reviews, community discussions, comparison pages, and customer interviews. Convert recurring needs and objections into prompts that sound like questions a buyer would actually ask.

    Cover the full decision journey

    Your prompt set should include several distinct jobs:

    • Discovery: Which products or providers solve a defined problem for a particular type of buyer?
    • Fit: Is your brand suitable for a specific use case, company size, location, budget, technical environment, or constraint?
    • Comparison: How does your brand differ from a named competitor or another category of solution?
    • Validation: Is the company legitimate, established, available, secure, compliant, reliable, or well supported where those criteria genuinely apply?
    • Objection: What are the disadvantages, complaints, limitations, cancellation terms, switching costs, or reasons not to choose it?
    • Change: Is an old criticism, discontinued feature, previous price, former policy, or earlier incident still relevant?

    Keep branded and unbranded prompts separate. Unbranded prompts reveal whether the system associates you with the category at all. Branded prompts reveal what happens after someone already knows your name. A strong branded answer does not compensate for absence during discovery, and a discovery mention does not protect you from a damaging validation answer.

    Prioritize by consequence, not prompt volume alone

    Give priority to prompts that combine a likely buyer action with a meaningful consequence. A broad question about your industry may produce an interesting answer but little business value. A question about whether your product meets a buyer’s non-negotiable requirement can decide the sale.

    For each prompt, record the intended audience, journey stage, decision at stake, correct answer, acceptable nuance, and evidence that should support it. This becomes the test specification. Without it, teams tend to label any positive mention a success even when the answer is incomplete, poorly cited, or aimed at the wrong customer.

    Do not quietly rewrite a difficult prompt until the answer improves. Preserve natural objections and hostile wording in the audit. Those are often the prompts that expose stale claims, unresolved complaints, and ambiguity in your public record.

    Audit AI answers as claims, not conventional rankings
    An overhead view shows an analyst inspecting translucent answer cards, evidence tokens, broken connections, and mismatched product shapes with a magnifying lens.

    An AI answer is not a fixed search result. Wording, source selection, context, and recommendations can change between sessions. One favorable response is an observation, not a durable position.

    Make each test reproducible enough to investigate. Record the platform, visible model or search mode, date, prompt text, language, location when relevant, sign-in state, and any preceding conversation. Save the complete answer and every visible citation. Run important prompts in fresh sessions as well as realistic follow-up conversations because prior context can change the result.

    Separate the failure types

    Observed resultWhat it may indicateFirst corrective move
    Your brand is absent from important discovery promptsThe public record may not connect the brand clearly enough to the use case, audience, or category.Strengthen the relevant use-case page and seek credible corroboration where buyers already research the category.
    Your brand is named without supporting citationsThe mention may be difficult for a buyer to verify and vulnerable to inconsistent framing.Make the underlying identity and product claims explicit on stable, accessible pages.
    The answer cites a page but states the fact incorrectlyThe cited passage may be ambiguous, stale, poorly qualified, or contradicted elsewhere.Correct the nearest authoritative page and remove conflicts between current and legacy content.
    The answer repeats an accurate negative factThe root problem is operational or reputational, not merely an optimization gap.Fix the underlying issue, then publish a precise account of the current state and any remaining limitation.
    The answer makes an unsupported harmful claimThe system may be mixing entities, extrapolating from weak evidence, or reproducing an external error.Preserve the test conditions, trace any cited origin, report the error where possible, and publish a narrowly evidenced correction.
    The facts are correct but the recommendation is unfavorableYour offer may be a poor fit for the stated need, or your differentiator may lack credible support.Clarify who the product is and is not for. Do not try to turn a genuine mismatch into a visibility problem.

    Use a scorecard that preserves the diagnosis

    A single visibility score hides too much. Track these dimensions separately:

    • Presence: whether the brand appears in the priority prompt set.
    • Citation coverage: whether material claims are accompanied by accessible sources that actually support them.
    • Claim accuracy: whether each identity, product, policy, price, availability, and qualification statement matches the current approved record.
    • Decision framing: whether the answer explains the brand’s fit, limitations, and differentiators fairly.
    • Source quality: whether the answer relies on canonical pages, credible independent evidence, low-quality aggregators, or irrelevant pages.
    • Volatility: whether the conclusion changes materially when the same documented test is repeated.
    • Correction status: whether a detected problem is unverified, confirmed, assigned, repaired at its origin, externally disputed, or resolved in later tests.

    Review citations claim by claim. A reputable domain can still be cited for a statement it does not support. A correct answer can also rest on a stale source and become wrong after your next product or policy change. The audit has to evaluate the evidence chain, not just the domain name or tone of the answer.

    Build a source-of-truth system that AI can reconcile
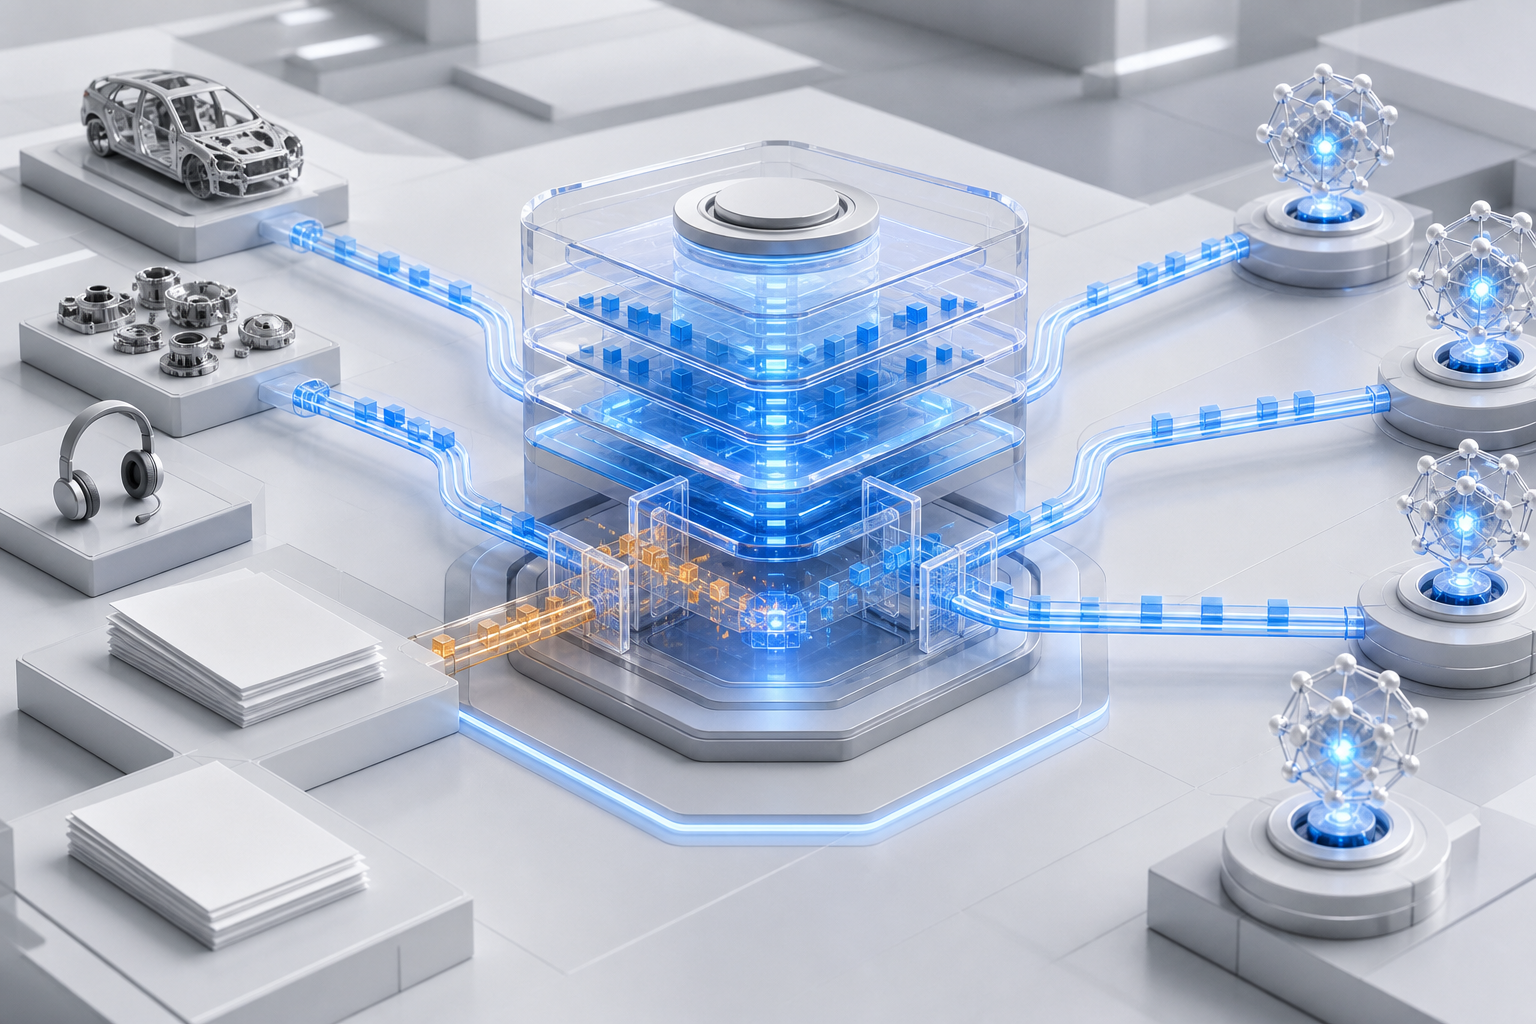
    A layered central repository connects product, policy, support, and review objects to several abstract AI nodes while conflicting fragments are reconciled.

    You cannot force a generative system to choose your preferred page. You can make the public record less ambiguous. The goal is a set of current, specific, mutually consistent facts that a buyer, publisher, search engine, or AI system can verify without guessing.

    Create a claim ledger before creating more content

    A claim ledger is a working inventory of statements that influence whether someone chooses or trusts the brand. Include identity, ownership, product capabilities, intended users, availability, pricing structure, service limits, cancellation or return terms, support, security, privacy, compliance, and performance claims where relevant.

    Each ledger entry should contain:

    • The exact claim and the qualifiers needed to keep it accurate.
    • The canonical public URL where a person can verify it.
    • The evidence behind the statement, including internal approval where required.
    • The owner responsible for maintaining the fact.
    • The event that makes the claim stale, such as a product release, policy revision, market exit, rebrand, or contract change.
    • Known third-party pages or old URLs that contradict the current position.
    • The priority prompts and audiences affected if the claim is wrong.

    The qualifiers matter. Available in one market is not the same as available everywhere. Supports a workflow is not the same as guaranteeing its outcome. Reviewed against a standard is not automatically the same as certified. Removing those distinctions may make copy sound cleaner, but it also creates the contradictions that brand-defense work later has to untangle.

    Give each fact a clear public home

    Do not scatter the only complete explanation across press releases, support replies, social profiles, and sales PDFs. Give durable claims a stable home on your site, then link supporting pages back to that canonical explanation.

    • Use an organization page for identity, official names, ownership where appropriate, contact paths, and the relationship between the company and its products.
    • Use product or service pages for capabilities, intended users, prerequisites, exclusions, and current availability.
    • Use pricing and policy pages for terms that affect a purchase or cancellation decision.
    • Use documentation and support pages for setup requirements, technical limits, integrations, and troubleshooting.
    • Use trust, security, privacy, or compliance pages only for claims your responsible teams have verified and approved.
    • Use status, incident, or change pages when the history of a material event needs a dated, factual record.

    Write the decisive answer in visible prose. Put the claim near the question it resolves, use the same product and company names used elsewhere, state important limits directly, and show when time-sensitive information was updated. A vague page surrounded by perfect metadata is still a vague page.

    Use schema as a consistency layer

    JSON-LD can help describe the entity and connect machine-readable properties to the page, but it is not a private channel for claims you chose not to show users. Mark up only facts supported by visible content.

    • Use Organization properties to reinforce the official name, URL, logo, and genuine sameAs profiles.
    • Use Product or Service types only when they accurately match the thing described on the page.
    • Use FAQPage only when the questions and complete answers are visible to the reader.
    • Keep names, URLs, identifiers, offers, authorship, and dates aligned with the page and the rest of the site.
    • Validate syntax, but also review semantics. Technically valid markup can still describe the wrong entity or overstate what the page proves.

    Structured data does not guarantee inclusion, citation, or a favorable answer. Its defensive value is precision: it reduces avoidable ambiguity when the markup, visible copy, internal links, and external profiles all describe the same entity.

    Seek corroboration, not manufactured consensus

    Your site is the appropriate authority for many first-party facts, but it cannot independently prove every claim about quality, reputation, or market standing. Earned coverage, accurate directory records, relevant reviews, partner documentation, and expert references can provide independent context when they are legitimate and specific.

    Do not flood low-quality sites with identical claims or disguise promotional placements as independent evidence. That creates a larger cleanup problem and gives buyers little reason to trust the result.

    If you hire outside help, assess AI visibility and LLM citation services by their actual deliverables: prompt mapping, source analysis, claim correction, structured-data review, credible authority building, monitoring, and handoff. A collection of favorable answer screenshots is not a defensible operating system.

    Defend the narrative without trying to erase criticism

    Defensive SEO for AI search is not reputation laundering. Its legitimate purpose is to keep consequential answers accurate, current, properly attributed, and proportionate to the available evidence.

    Classify the disputed claim before publishing a response:

    • Accurate criticism: Fix the underlying product, policy, or service issue. Explain what changed, when it changed, and what limitation remains. Content cannot substitute for the remedy.
    • Previously accurate but stale: Add date context and a clear current-state statement. If the old condition was once true, acknowledge the change instead of pretending the history never existed.
    • Factually wrong: Correct the exact proposition with direct evidence. A broad page claiming that the brand is trustworthy will not resolve a specific error about ownership, price, availability, or policy.
    • Subjective disagreement: Do not relabel opinion as misinformation. Publish fit criteria, tradeoffs, and a candid not-for-you explanation so the buyer can decide.
    • Entity confusion: Reconcile company names, product names, domains, profiles, logos, and relationships. Ask publishers and directory owners to correct records that merge separate entities.
    • Impersonation or materially harmful allegation: Preserve the complete answer, prompt context, date, visible citations, and origin pages. Route it promptly to communications and legal counsel rather than starting an improvised public dispute.

    For regulated, contractual, security, privacy, or financial claims, the accountable subject-matter owner should approve the correction before publication. An overconfident rebuttal can create more exposure than the original AI error. Counsel should decide whether a correction request, takedown request, formal response, or another remedy is appropriate when the allegation could create legal harm.

    Publish the answer a skeptical buyer actually needs

    A defensive page should resolve uncertainty, not demand trust. State the question plainly. Give the short answer. Present verifiable evidence. Explain scope and exceptions. Include the current date where the fact can change. Link to the policy, documentation, incident record, or independent corroboration that carries the detail.

    Comparison content deserves the same discipline. Use criteria a buyer can inspect, distinguish facts from judgments, date changeable details, and correct competitor information when you learn it is stale. A fair comparison is easier to defend and more useful than a page designed only to declare a winner.

    Avoid publishing a new rebuttal for every unfavorable phrase. That can spread the language, fragment your explanation, and create additional conflicting URLs. Repair the canonical source first. Create a dedicated response only when the issue has enough decision impact to need its own durable explanation.

    Turn monitoring into a correction workflow

    Monitoring has little value if every problem ends as a screenshot in a report. Each confirmed issue needs a class, an owner, a source-level repair, and a retest condition.

    Use the same correction loop every time

    1. Capture the answer. Preserve the complete prompt, conversation context, test conditions, response, and citations.
    2. Verify the problem. Compare each consequential claim with the ledger and repeat the test under documented conditions. Do not escalate a mere wording preference as a factual failure.
    3. Classify the cause. Decide whether you are dealing with absence, unsupported recall, stale evidence, source conflict, factual error, criticism, poor fit, or entity confusion.
    4. Repair the nearest authoritative source. Fix the product or policy first when the criticism is valid. Otherwise, update the canonical page, visible explanation, schema, internal links, and official profiles as appropriate.
    5. Address external origins. Request corrections from publishers, platforms, directories, partners, or review profiles when they carry demonstrably wrong facts. Keep an evidence trail and avoid pressuring anyone to remove legitimate opinion.
    6. Retest the prompt set. Look for accuracy across the affected prompt family, not just a favorable response to the exact wording that exposed the issue.
    7. Log the disposition. Record what changed, who approved it, which URLs were updated, which external requests remain open, and what evidence would count as resolution.

    AI answers may not reflect a correction on your preferred timetable. Do not promise an immediate model update. The controllable work is to remove contradictions, make the correction public and verifiable, pursue errors at their origin, and keep testing the decision prompts that matter.

    Assign ownership before an incident

    • Search or GEO owner: maintains the prompt set, test protocol, evidence captures, and scorecard.
    • Content owner: updates canonical explanations, internal links, page dates, and structured data.
    • Product, support, policy, or operations owner: verifies whether the underlying claim is true and fixes real customer problems.
    • Public relations or communications: manages corrections and context beyond owned channels.
    • Security, privacy, compliance, or legal: handles claims that fall within those functions and decides the appropriate escalation.
    • Executive owner: resolves conflicts when the preferred marketing message does not match the evidence.

    Run focused checks after events that can change the public narrative: a product launch, rebrand, price or policy revision, market expansion, service incident, leadership change, significant coverage, or a surge in customer complaints. Between those events, set the cadence according to decision volume and consequence. A prompt that affects a high-value or high-risk decision deserves closer attention than a broad informational query.

    Start with the prompt carrying the greatest commercial or reputational consequence. Capture the current answer, isolate the most important unsupported or incorrect claim, repair the evidence behind it, and retest the surrounding prompt family. That small loop will tell you more about your real AI visibility than a large dashboard built on undiagnosed mentions.
    References

  • Industry Barriers to AI Search Visibility and How to Fix Them

    Industry Barriers to AI Search Visibility and How to Fix Them

    You can make a page easy for conventional crawlers, add structured data, and still remain absent from AI-generated answers. That usually does not mean you need more content. It means your site is failing before, during, or after citation: AI systems cannot reliably reach the page, cannot justify using it, or can satisfy the user without sending them to you.

    Before you commission another AI SEO rewrite, identify which gate is failing. Access problems need engineering and security work. Trust problems need evidence. Utility problems need a stronger next step. Treating all three as copy problems wastes budget and can deepen the actual barrier.

    Your industry is usually failing at one of three gates

    Access is the first gate. Across 201 AI visibility audits covering ten industries, 38 audits returned errors, an error rate of 18.9%. Another eight scored zero because missing subscores pointed to extraction or rendering problems. Those sites did not merely have weak answers; they created doubt about whether the relevant content could be retrieved at all.

    Trust is the second gate. Among 163 successful audits, the average overall score was 61.6 and the median was 66. About 70.6% landed in the inconsistent-visibility range, only 4.9% had a strong foundation, and none reached the exceptional range. In practical terms, being readable was common. Being predictably usable as a citation was not.

    The ordering of the subscores explains the problem. Median structure was 92 and extractability was 74, while authority and evidence reached 48 and freshness reached 45. If your team responds by polishing headings, adding more schema, or rewriting introductions, it may be working on the two areas that are already strongest while leaving the proof deficit untouched.

    Utility is the third gate. A page can be accessible and defensible yet still produce no visit when the answer itself is the entire product. This is where an AI search problem becomes a business-model problem. Citation determines whether your brand participates in the answer; post-answer utility determines whether that participation can lead to a booking, application, purchase, enrollment, or other meaningful outcome.

    The figures are directional, not a universal benchmark. The sample leaned heavily toward homepages, which often contain more positioning language and less supporting evidence than articles, methodology pages, policies, and detailed listings. Use the pattern to choose what to inspect, not to assume that every site in a sector has the same score.

    Key takeaways

    • Test retrieval before optimizing prose or schema. A page cannot earn a citation when its useful content does not arrive reliably.
    • Separate readability from authority. Clear formatting helps extraction, but claims still need evidence, ownership, scope, and truthful freshness signals.
    • Design for what happens after the answer. If your entire value can be summarized, visibility may not create a visit or commercial outcome.
    • Audit representative page types and query journeys, not just your homepage or a single blended visibility score.

    Access barriers turn site architecture into exclusion

    An abstract website building has blocked corridors and sealed entrances, while one illuminated route reaches its central content chamber.

    Access failure is unevenly distributed. In the audited sample, job boards had a 40% error rate, legal directories 35%, travel booking sites 33.3%, online course marketplaces 30%, and coupon sites 20%. Local directories, by comparison, had a 5.3% error rate. These percentages do not diagnose your domain, but they show why access deserves its own workstream in sectors built around dynamic listings, defensive bot controls, or application-like interfaces.

    Three mechanisms deserve attention. A web application may place essential information behind client-side rendering. A web application firewall may treat an AI agent as hostile traffic. An interstitial, popup, or script may replace the useful response with a consent request, challenge, or empty shell. A human using a familiar browser can still see the page, so a normal visual check may miss all three.

    Run an access audit as a delivery test, not a design review:

    1. Choose representative URLs. Include the homepage, an editorial resource, a category or results page, a detailed listing, a methodology or policy page, and the page where the user completes an action. Do not let a working homepage stand in for the rest of the site.
    2. Inspect the raw response. Record whether the request succeeds, what content type returns, and whether the response body contains the page’s answer-bearing facts.
    3. Compare raw and rendered content. If titles, descriptions, prices, eligibility conditions, locations, dates, or supporting evidence appear only after scripts execute, document that dependency.
    4. Use a clean session. Confirm that the information appears without stored cookies, an existing login, dismissed popups, or a sequence of clicks that an automated retriever may never perform.
    5. Repeat the retrieval. A page that works once and fails on the next attempt is still unreliable. Check multiple URLs from each important template so you can distinguish an isolated page defect from a systemic one.
    6. Review delivery logs. Match failed requests to firewall challenges, blocked user agents, script dependencies, interstitials, or other delivery errors. Assign the fix to the system that actually caused the failure.

    Do not respond by broadly disabling bot protection or allowing every automated agent across the domain. That can create security, abuse, and infrastructure risks. Define the narrowest access rule that supports the agents you intend to serve, retain controls for sensitive and authenticated areas, and rerun the same retrieval tests after the change.

    For rendering problems, put the facts required to understand the page in the initial HTML or a reliably rendered response. Client-side code can still handle filtering, personalization, account functions, and transactions. It should not be the only place where an agent can find the identity and purpose of a listing.

    Structured data cannot rescue an empty document, a firewall challenge, or a blocked response. The access gate passes only when useful visible content and its supporting context can be retrieved consistently, not merely when the page looks correct in a logged-in employee’s browser.

    Trust barriers begin where polished marketing ends

    Once a page is reachable, the question changes from can it be read to can its claims be defended. Page type matters here. Articles had a median authority score of 76, compared with 45 for homepages. A homepage can establish what a company wants to be known for, but positioning statements rarely provide the methodology, citations, qualifications, and scope needed to support a factual answer.

    Freshness and evidence cues were also thin. A Last-Modified header was missing in 114 instances, while citations or outbound links were recorded only 13 times. A missing header does not prove that content is stale, and an outbound link does not automatically make a claim true. The practical problem is that a reviewer or retrieval system has fewer inspectable clues for determining when the information was checked and why it should be trusted.

    Turn important claims into citable units

    A citable unit is a compact passage that answers a specific question and carries enough context to survive extraction. Build each important unit from the following parts:

    • Direct answer: State the fact or conclusion clearly before expanding on it.
    • Scope: Explain where, when, and to whom the claim applies. Include relevant conditions such as location, eligibility, exclusions, or effective period.
    • Evidence: Show the calculation, comparison method, documented basis, or primary references that support the claim.
    • Stewardship: Identify the author, editor, reviewer, or organization responsible for maintaining the information.
    • Freshness: Display a truthful reviewed or updated date and align machine-readable dates or headers with the actual editorial change.
    • Continuation: Give the reader an exact next action when the answer alone does not complete the task.

    Apply this at the level where a decision is made. A coupon page needs more than a promise of savings; it needs the offer, conditions, applicable products, exclusions, and verification context. A legal directory needs more than claims about quality; it needs a transparent listing or ranking method, relevant jurisdictional information, profile ownership, and disclosures. A course marketplace needs more than aspirational outcomes; it needs a syllabus, prerequisites, instructor responsibility, and a clear explanation of what completion entails.

    Move proof out of generic brand language and into articles, detailed listings, methodology pages, editorial policies, and other resources where it can be inspected. Then link those resources at the claim they support. A distant policy in the footer is less useful than evidence attached to the decision in front of the user.

    Use JSON-LD as a map, not a substitute for evidence

    JSON-LD can identify entities, page types, authorship, dates, and relationships. It cannot manufacture authority that is absent from the visible page. Mark up facts that users can verify in the content, keep names and dates consistent, and use only types that accurately describe the page.

    A dateModified value should reflect a substantive review or change, not an automated date bump. Author and organization markup should resolve to real, maintained identities. Article, profile, offer, course, or other page-level markup should agree with the visible subject rather than describe the business more broadly than the page supports.

    Validation can tell you whether the markup is syntactically sound. It cannot tell you whether the claim is current, properly scoped, or supported. Treat structured data as an index to the evidence you have published, not as the evidence itself.

    Utility barriers decide whether visibility produces value

    Even a reachable, well-supported page can lose the click when its value ends with a short factual answer. If the page only answers the question, an AI system can summarize it; if the site completes the user’s task, the user may still need the business. That distinction is especially important for industries that historically monetized large volumes of informational visits.

    Use the following framework to separate the public answer from the value that requires an interaction:

    Industry patternCompressible answerProof that should remain publicUseful completion layer
    Coupons and dealsWhich code or offer provides a discountTerms, exclusions, applicable products, and verification contextA direct redemption path, relevant filtering, and a way to act on a valid offer
    Travel bookingWhere to go or how to plan a tripComparison assumptions, destination details, and planning constraintsCurrent availability, date-specific choices, and booking
    Job boardsRole descriptions and general career guidanceEmployer, location, requirements, posting status, and application conditionsApplication, saved searches, alerts, and employer interaction
    Legal directoriesBasic professional profiles or market comparisonsIdentity, jurisdiction, practice focus, listing method, and disclosuresFit screening and a clear contact or consultation path
    Online coursesA course overview or explanation of a skillSyllabus, prerequisites, outcomes, instructor responsibility, and policiesEnrollment, the learning environment, assessment, and completion process

    Do not try to manufacture utility by hiding the facts required to evaluate the offer. Gating a syllabus, job requirements, coupon conditions, or basic provider information may force an extra click, but it also weakens access and trust. Keep the answer layer public. Reserve the interaction layer for functionality that genuinely helps the user complete the task.

    Ask one blunt question for every important query: after the user knows the answer, what remains difficult or impossible without our site? If the honest answer is nothing, the page has an exposure problem that better formatting will not solve. You either need a real completion capability or a measurement model that values influence and brand inclusion without assuming a visit will follow.

    A citation without a downstream outcome is visibility, not yet business value. Conversely, a lower-volume page that moves someone from a complex answer into a useful tool, application, booking, or consultation may matter more than a highly summarized informational page. This is why AI search cannot be managed solely as a rankings project.

    Run the audit in dependency order

    Three connected diagnostic stations examine a reachable path, supporting evidence, and a useful destination in sequence.

    Industry averages can help you choose where to look first, but they cannot tell you why your own domain is absent. Build the diagnosis around query journeys and page templates:

    1. Define the query family. Group the questions that represent one user need, such as finding a job, comparing a course, validating an offer, or choosing a provider. Keep informational and transactional intentions separate.
    2. Map each question to a page. Identify the page that should supply the answer, the page where supporting evidence lives, and the next action you want the user to take.
    3. Grade the access gate. Mark it Pass, Mixed, or Fail based on repeated retrieval of the useful content. Do not average an unreachable page together with a strong content score.
    4. Grade the trust gate. For each consequential claim, check the answer, scope, evidence, stewardship, freshness, and consistency between visible content and structured data.
    5. Grade the utility gate. Decide whether the answer completes the need. If it does not, confirm that the next action is visible, relevant, and functional. If it does, reconsider what commercial role the page can realistically play.
    6. Fix in dependency order. Repair blocked delivery and rendering first, because no amount of editorial proof helps a page that cannot be reached. Then strengthen evidence and freshness. Finally, improve the answer-to-action path without hiding the answer.
    7. Measure the gates separately. Track retrieval success for representative URLs, mentions and citations for a stable set of queries, and the visits or completed actions that follow. A single visibility score cannot tell you which team owns the next fix.

    The pattern in the measurements tells you where to work. Strong retrieval with weak citation points toward trust. Strong citation with weak commercial outcomes points toward utility. Intermittent retrieval means the access problem is unresolved, even if the page occasionally appears in an answer.

    Start with one commercially important query family and one representative page template. If access fails, route the work to engineering and security. If trust fails, route it to editorial, subject-matter review, and structured-data owners. If utility fails, involve product and commercial strategy. Expand the program only after that first barrier has a named owner, a visible fix, and a repeatable test.

    References

  • Content Structure and Technical SEO for Machine Retrieval

    Content Structure and Technical SEO for Machine Retrieval

    If a page contains the right answer but rarely becomes the answer that search engines or AI systems retrieve, topic coverage may not be the problem. The useful passage could be buried in a multi-purpose paragraph, separated from a vague heading, added only after a click, or obscured by an unnecessarily complex DOM.

    You need two conditions to hold at the same time: the answer must form a clear unit of meaning, and the rendered page must expose that unit in a structure a crawler can reach and interpret. Here is how to build and test both without turning useful prose into disconnected fragments.

    Diagnose the content layer and delivery layer separately

    Machine retrieval can fail at either of two layers. A content-layer failure makes the answer hard to isolate. A delivery-layer failure prevents the machine from reliably receiving the answer at all. Rewriting copy will not repair content that never enters the crawler’s DOM, while a rendering fix will not clarify a paragraph that tries to answer four questions at once.

    LayerTypical failureFirst check
    Content structureThe answer is scattered across sections, introduced by a generic heading, or dependent on distant context.Copy the relevant heading and passage into a blank document. Check whether they still answer the target question clearly.
    DOM structureThe heading and answer have an unclear relationship because of excessive nesting, misplaced elements, or JavaScript changes.Inspect the live DOM and confirm that the passage sits under the intended heading in a logical hierarchy.
    Content deliveryImportant text or links appear only after a click, selection, or other user action.Reload the page and check what exists before any interaction.
    Crawler accessGoogle may render the content, but another crawler that does not execute JavaScript receives an incomplete page.Compare the initial HTML, the browser DOM, and the crawler-rendered HTML.

    Start with the layer that fails. If the passage is missing after a fresh load, fix delivery first. If it is present but ambiguous outside the full page, restructure it. If both tests pass, investigate relevance, authority, and other ranking factors rather than repeatedly editing an already retrievable answer.

    Build answer-sized sections without writing fragments

    A useful content chunk is a self-contained unit centered on one idea. It is not a fixed word count, a paragraph chopped at an arbitrary length, or a collection of terse statements written to resemble search snippets. Its boundary follows a change in the reader’s question.

    Build those boundaries into the outline before drafting:

    1. Assign one job to each section. An H2 can cover a major decision or task. Use an H3 only when that task divides into a distinct question that deserves its own answer.
    2. Write the heading as a promise. Replace labels such as Overview, Details, or Implementation with language that identifies what the reader will learn. A heading such as How JavaScript-loaded content affects crawling establishes a much clearer retrieval target.
    3. Answer the heading promptly. Put the direct answer in the opening sentence or paragraph, then add the mechanism, conditions, exceptions, and next action.
    4. Keep each paragraph on one idea. Start a new paragraph when you move from definition to consequence, from consequence to procedure, or from a general rule to an exception.
    5. Use a list only when the items are genuinely parallel. Steps, criteria, checks, and alternatives belong in lists. A connected explanation still belongs in prose.

    Run the self-contained passage test

    Copy a heading and the passage immediately below it into a blank document. Do not include the title, introduction, sidebar, or preceding section. Then ask:

    • Does the heading identify the actual question or decision?
    • Does the first sentence give a direct answer rather than a transition?
    • Are important nouns named, or does the passage rely on vague references such as this, that, it, or they?
    • Does the passage contain the condition that limits the advice?
    • Can a reader act without searching the rest of the page for a missing step?

    For example, Implementation considerations followed by This can create problems is not independently useful. How interaction-dependent content affects crawling followed by Content added only after a user action may be absent from a crawler’s initial view establishes the subject, mechanism, and risk immediately.

    Preserve the reading path between chunks

    Self-contained does not mean isolated. A section should carry enough context to survive retrieval while still advancing the page’s larger argument. Keep necessary transitions, define a term before relying on it, and let supporting paragraphs deepen the answer instead of restating it.

    Do not split one coherent explanation merely to manufacture more headings. The practical case for chunking is that clear sections help people scan and give machines more precise passages to interpret. If the result feels repetitive or jerky to a reader, the boundaries are too aggressive.

    Make the content hierarchy explicit in the DOM

    An isometric document structure shows orderly nested content blocks beside a smaller cluster of tangled and disconnected elements.

    A person sees a rendered page. A crawler works with a document structure. The DOM is the browser’s in-memory tree of elements and their parent, child, and sibling relationships. Those relationships help establish which paragraph belongs to which heading and which sections belong to the main article.

    Use HTML that expresses those relationships directly:

    • Place the primary editorial content in an <article> element rather than mixing it with navigation and unrelated interface components.
    • Use heading levels to represent hierarchy, not visual size. An H3 should describe a subsection of the preceding H2.
    • Group a coherent topic in a <section> when that grouping adds meaning to the document structure.
    • Use <p> for paragraphs and real <ul> or <ol> elements for lists instead of constructing their appearance from generic containers.
    • Remove empty wrappers and repeated layout containers that make the tree deeper without adding structure.

    Semantic markup is not a substitute for relevant content, and changing a <div> to a <section> does not guarantee a ranking gain. Its value is more basic: it reduces ambiguity and makes the intended hierarchy easier to preserve across browsers, templates, crawlers, and assistive systems.

    The HTML response is only the starting point. As the browser parses that HTML into nodes, JavaScript can pause construction, add elements, replace text, or change links. The result can be a final DOM that differs materially from the original HTML.

    Keep three versions of the page distinct

    • Initial HTML: the response returned by the server before client-side scripts modify it.
    • Current browser DOM: the live tree shown in the Elements panel after scripts have run and possibly after a person has interacted with the page.
    • Crawler-rendered HTML: the version a particular crawler produced with its own rendering capabilities, timing, and interaction limits.

    These versions can match, but you should not assume they do. That distinction matters whenever a template relies on client-side rendering, delayed components, tabs, expandable panels, or JavaScript navigation.

    Test retrieval on the rendered page before publishing

    A scanning probe traces a clear path through a rendered web page and illuminates one visible, self-contained content block.

    The safest delivery rule is simple: important content should enter the DOM during the initial page load. Googlebot can parse HTML, execute JavaScript, and evaluate a rendered DOM, but it does not interact with a page as a person would. Other crawlers may not render JavaScript at all.

    This creates an important distinction for tabs and accordions. If the text is already in the DOM and the control merely changes its presentation, the content is present for inspection. If clicking the control fetches or creates the text, a non-interacting crawler may never receive it. Move essential answers into the initial render or provide an ordinary crawlable page that contains them.

    Run this release check on every important template and on any page where machine visibility matters:

    1. Choose the target answer. Write down the exact question the page should answer and identify the heading and passage intended to answer it.
    2. Reload without interacting. Confirm that the complete answer appears without a click, scroll-triggered action, selection, or form submission.
    3. Inspect the live DOM. Open browser DevTools, select Elements, and use Ctrl+F or Cmd+F to search for a distinctive phrase from the answer. Confirm that it appears once, in the intended section, under the correct heading.
    4. Inspect internal links. Important navigation should use real <a> elements with usable destinations. JavaScript event handlers that merely imitate links create avoidable crawlability risk.
    5. Check the crawler’s render. Use Google Search Console’s URL Inspection tool to examine the rendered HTML available to Google. Search that output for the same distinctive phrase, heading, and essential internal links.
    6. Use a public fallback when needed. If you do not have Search Console access, the Rich Results Test can provide a rendered-page view for investigation. Treat it as a diagnostic aid, not proof of what has already been indexed.
    7. Review DOM size. In the browser console, document.querySelectorAll('*').length provides a simple element count. Treat about 1,500 nodes as a reason to investigate unnecessary complexity, not as a universal ranking cutoff. Remove redundant wrappers and duplicated components only after confirming they are not required by the interface.

    Choose legacy pages by expected return

    You do not need to rechunk an entire archive at once. Start with high-value pages where structure is most likely to be limiting performance:

    • Pages with meaningful traffic but weak engagement, especially when readers must hunt for the promised answer.
    • Pages that already rank for relevant queries but are not being surfaced or cited for the specific answers they contain.
    • Complex explanations where headings are generic and paragraphs routinely change subject midway through.
    • JavaScript-heavy pages where important text is absent from the initial response or appears only after interaction.

    For each candidate, record whether the failure is structural, technical, or both. That prevents a content team from rewriting material that actually needs a template fix, and it keeps developers from rebuilding components when clearer headings would solve the immediate retrieval problem.

    Key takeaways for machine-retrievable content

    • A retrievable answer needs both a clear unit of meaning and reliable delivery in the rendered page.
    • Let each heading make a specific promise, then answer it promptly in a focused passage.
    • Split content when the reader’s question changes, not when a paragraph reaches an arbitrary length.
    • Use semantic HTML and a logical heading hierarchy to make relationships explicit in the DOM.
    • Put important text and links in the initial page state rather than behind required interaction.
    • Compare the initial HTML, live DOM, and crawler-rendered HTML instead of assuming that one represents all three.
    • Use DOM size as an investigation signal, not as a standalone SEO score.

    Pick one commercially important URL and test one intended answer from outline to rendered DOM. Repair the first broken handoff you find, validate the crawler-visible result, and only then scale the same audit across the rest of the template or content set.

    References

  • AI Recommendation Pipeline Optimization, Gate by Gate

    AI Recommendation Pipeline Optimization, Gate by Gate

    Your page can rank, load correctly, and carry structured data yet still disappear when an AI system recommends a product, provider, or approach. Publishing more content will not fix that if the real failure happened earlier in the recommendation pipeline.

    You need to find the earliest gate your content cannot reliably pass. Fix that dependency first, then work forward until the system can retrieve, understand, trust, present, and ultimately prefer your answer.

    Think in gates, not one AI visibility score

    A practical AI recommendation pipeline contains 10 dependent gates: Discovered, Selected, Crawled, Rendered, Indexed, Annotated, Recruited, Grounded, Displayed, and Won. This is an operational model for diagnosis, not a claim that every AI engine exposes the same internal architecture.

    The distinction matters because a weak result does not identify its own cause. If your brand is absent from an answer, the underlying problem could be access, interpretation, credibility, relevance, or competitive fit. Treating every absence as a content-writing problem produces activity without revealing the bottleneck.

    The first five gates determine whether your material becomes technically eligible for use. The final five determine whether the system can understand and use it, verify it, show it, and choose it over alternatives. A hard failure upstream dominates everything downstream. A page that is not fetched cannot be rescued by better prose, and a page that is misunderstood cannot be rescued by stronger claims.

    Before you audit anything, define the recommendation you are trying to earn:

    • Decision: the question or task for which you want to be recommended.
    • Entity: the brand, product, service, location, person, or resource the system must recognize.
    • Canonical evidence page: the primary URL that explains why the entity fits the decision.
    • Qualifying facts: the attributes, limitations, audience, and use cases that make the recommendation accurate.
    • Desired outcome: an accurate citation, inclusion in a shortlist, a preferred recommendation, or another observable result.

    Do not audit an entire domain as one unit. A site can pass the pipeline for one entity and fail it for another. Your product page might be understood correctly while a location, plan, feature, or professional service remains invisible or ambiguously classified.

    Key takeaways

    • Find the earliest plausible failure instead of averaging every signal into one visibility score.
    • Separate technical eligibility from the later contest for recruitment, grounding, display, and preference.
    • Use observable evidence as a proxy. You usually cannot inspect an AI system’s internal gate state directly.
    • Treat visible copy, structured data, feeds, and supporting pages as representations of the same entity, not separate stories.
    • Keep post-decision reality aligned with the promise that earned the recommendation.

    Earn eligibility from discovery through indexing

    Exploration probes find a glowing content object that passes through a selective opening into an organized digital archive.

    Discovery, selection, crawling, rendering, and indexing form a dependency chain. Work through it in order. Checking only whether a URL loads in your own browser skips several different failure modes.

    Discovered: create legitimate paths to the entity

    Discovery asks whether a system can become aware that the entity and its supporting content exist. Start with the canonical page and trace every route that can expose it.

    • Link the page from a relevant navigation path, category page, hub, or related resource. Do not leave important evidence isolated behind a site search form.
    • Use descriptive internal links that identify the destination’s subject. Generic labels make the relationship less explicit.
    • Keep the canonical URL stable. If the same entity is scattered across temporary or duplicative URLs, choose a primary destination and make the hierarchy clear.
    • Inventory feeds, APIs, directories, and other structured distribution routes that legitimately carry the entity’s data.
    • Check whether site-level bot controls, security layers, or access policies unintentionally prevent discovery.

    Some platforms accept structured feeds or direct data pushes. Where those routes are available, they can bypass parts of the traditional discovery path. Use them as maintained representations of the same facts found on your site. A fast data route filled with stale names, prices, locations, or availability merely distributes the contradiction faster.

    Selected: make the page worth investigating

    Discovery creates awareness; selection determines whether the system has a reason to inspect the material. Open the page and look only at its title, opening paragraphs, headings, and internal-link context. Those elements should make the entity and its purpose unambiguous.

    • Name the entity and its category instead of relying on a slogan.
    • State the audience or situation the page serves.
    • Align the page with a specific decision rather than collecting loosely related keywords.
    • Separate genuinely different intents when combining them would make the primary answer unclear.
    • Resolve competing pages that make substantially different claims about the same entity.

    A page titled around broad thought leadership may be useful to a reader but still give a recommendation system no clear reason to retrieve it for a purchase, comparison, eligibility, or implementation question. Give each important page a recognizable job.

    Crawled, rendered, and indexed: verify access and interpretation separately

    A successful visit in your normal browser does not prove that an automated system received the same useful material. Test the page without a signed-in session, inspect available server or delivery logs, and separate these questions:

    • Crawled: Can an automated requester fetch the document without authentication, an unresolved challenge, or an interaction that never occurs?
    • Rendered: Does the resulting document contain the entity name, answer, qualifiers, and evidence as readable text?
    • Indexed: Is the page distinct, stable, and useful enough to be retained as a retrievable representation of the entity?

    Keep recommendation-critical facts out of image-only layouts, hover states, closed interface elements, and experiences that require a user action before any meaningful text appears. Interactive tools can remain valuable, but their core purpose, inputs, output meaning, and limitations should also be explained in text.

    Indexing is not something you can prove merely by finding a URL in one search interface. Use multiple proxies: a stable canonical destination, unique content, consistent internal references, successful fetch evidence where available, and downstream appearances that could not happen without retrieval. Record uncertainty instead of marking the gate as passed on weak evidence.

    Make the content usable for annotation, recruitment, and grounding

    Unlabeled modular content panels connect through semantic markers and evidence fragments to a transparent frame surrounding a glowing answer core.

    Passing the access gates only makes your content eligible. The next job is to remove ambiguity, package useful answers, and support the claims an AI system would have to repeat.

    Annotated: define the entity before decorating it with schema

    Annotation is where content is classified by meaning. Before editing JSON-LD, write an internal entity fact sheet that answers:

    • What is the entity’s exact name?
    • What type or category does it belong to?
    • What does it do, provide, or represent?
    • Who is it intended for, and who is it not intended for?
    • Which use cases does it support?
    • Which limitations, eligibility rules, locations, or availability conditions qualify the claims?
    • How does it relate to the parent brand, other offerings, locations, versions, or people?

    Then compare that sheet with visible copy, structured data, feeds, navigation labels, supporting pages, and external profiles you control. The facts do not need identical wording, but they should not describe different entities.

    Schema can clarify a page’s meaning. It cannot repair a missing explanation or safely substitute a stronger claim for the one a visitor can see. Treat JSON-LD as a structured representation of the visible entity. If a material attribute appears only in markup, either support it clearly on the page or remove it.

    Recruited: build answer units that remain clear when extracted

    Recruitment asks whether the system can use the content for the decision at hand. Long-form depth helps only when the relevant answer can be located and understood without reconstructing it from scattered sections.

    For every important question, create a self-contained answer unit with this sequence:

    <!– wp:list {
  • AI Search Content Optimization: A Practical Rewrite Method

    AI Search Content Optimization: A Practical Rewrite Method

    You have a page with real expertise, a useful answer, and a clear business purpose, yet AI-generated search results keep passing it over. The problem may not be the quality of the information. The answer may be buried in a long introduction, hidden behind a vague heading, or scattered across passages that make sense only when someone reads the whole page.

    The practical fix is to make that expertise easier to retrieve and combine. You do not need to flatten every page into robotic question-and-answer copy. You need to expose the answer, keep each important section understandable on its own, and connect the page to the rest of your topic coverage.

    Key takeaways

    • Prioritize pages that already contain valuable expertise but communicate their answers indirectly.
    • Build each important section around one question, claim, or decision so the passage still makes sense outside the page.
    • Use hub pages for topic orientation and spoke pages for focused, in-depth answers.
    • State the direct answer before adding reasoning, evidence, limitations, and exceptions.
    • Use titles, headings, descriptions, and internal links to reinforce the page’s purpose rather than compensate for unclear body copy.
    • Test whether an AI system can summarize the page accurately without losing the qualification that makes the answer trustworthy.

    Start with pages that already have answer value

    Traditional content refreshes often begin with declining traffic, outdated keywords, or slipping rankings. Those signals can still matter, but they do not tell you whether a page is a good candidate for AI search optimization. A page can receive modest traffic and still contain the clearest answer your organization has to an important customer question.

    For AI search, prioritize answer value. Look for pages that contain clear expertise, recurring customer questions, proprietary insight, durable reports, or evergreen explanations. Internal training material and pages that your sales, support, or subject-matter teams repeatedly share can also be strong candidates. Repeated internal use is a practical sign that the page already helps people understand something consequential.

    Create a revision queue with these fields:

    • Primary question: What exact question should this page answer?
    • Business purpose: What should a qualified reader understand, decide, or do after reading it?
    • Distinct value: What does this page contribute beyond a generic explanation of the topic?
    • Current answer: Where does the page actually state its main conclusion?
    • Extraction weakness: What would become confusing if a passage appeared without the introduction or surrounding sections?
    • Content relationship: Which broader hub and narrower related pages should connect to it?

    Then apply a simple screen. Can a reader identify the page’s question from the title and opening? Is the answer visible before the background material? Can a key passage be understood without reading the paragraphs above it? Are important qualifications attached to the claim they limit? Are the takeaways stated rather than left for the reader to infer?

    If the page is commercially or strategically important and those checks fail, move it up the queue. If it has no distinctive answer, rewriting the headings will not solve the deeper problem. Formatting can reveal expertise, but it cannot manufacture expertise that is not there.

    Rewrite the page as a set of standalone answer units

    A long layered document is separated into an orderly grid of distinct blank content cards.

    AI search systems do not always use a page as one indivisible document. They may retrieve a passage that appears relevant to a question and use it while constructing an answer. That makes chunk-level clarity a core editing requirement.

    An answer unit is a section centered on one idea. It should remain useful when separated from the page around it. A strong unit usually contains:

    1. A specific heading: Name the question, assertion, problem, or decision the section addresses.
    2. A direct opening answer: Give the conclusion before the history or explanation.
    3. The necessary qualification: State who, when, or under what conditions the answer applies.
    4. Support: Explain the reasoning, evidence, example, or mechanism behind the answer.
    5. A useful connection: Link to the next page a reader needs if the topic extends beyond this section.

    Consider a section headed Why it matters that begins, “This can also make the process easier.” Both the heading and sentence depend on missing context. A clearer version would use the heading Why does answer-first formatting help AI search? and open with, “Answer-first formatting exposes the section’s main claim before the supporting explanation and exceptions.” The revised passage names the subject and gives the reader an answer immediately.

    Run an isolation test on every important section. Copy the heading and its paragraphs into a blank document, then inspect the passage without the page title, introduction, sidebar, or preceding section. Look for words such as “it,” “this,” “that method,” “the issue,” and “these benefits.” If the missing context could change the meaning, replace the vague reference with the actual subject.

    This may require slightly more noun repetition than polished magazine prose. That is acceptable when the repetition removes ambiguity. You are not trying to make every sentence repetitive. You are making sure the passage does not become misleading when retrieved on its own.

    Do not confuse chunking with aggressive fragmentation. Create a new section when the reader’s question or decision changes, not whenever the page reaches a convenient visual break. If adjacent sections require the same setup before either one makes sense, they may belong in a single answer unit. If one section tries to define a term, compare options, describe implementation, and handle exceptions, it probably needs to be divided.

    Clarity also does not require oversimplification. Put the plain answer first, then preserve the conditions that make it accurate. A statement such as “Use this approach” is easy to extract but not useful if the real recommendation applies only to a particular audience or situation. Keep the recommendation and its boundary together.

    Build breadth with hubs and depth with spokes

    A single page should not carry every possible question about a broad topic. Trying to make one URL comprehensive often produces a long page with shallow sections, overlapping intent, and no obvious main answer. A hub-and-spoke structure gives each page a clearer job.

    The hub introduces the subject, establishes its major branches, and directs the reader to focused resources. Each spoke resolves one narrower question in greater depth. Linking the spokes back to the hub, and linking related spokes when the reader genuinely needs both, creates explicit signals about how the topics relate.

    Map the topic before rewriting individual paragraphs:

    1. Define the hub’s promise. Write one sentence describing what the reader should understand after using the hub.
    2. List the major question types. Separate definitions, reasons, processes, use cases, constraints, mistakes, and decision points where they require materially different answers.
    3. Assign an owner to each question. Choose one page that will provide the primary answer instead of allowing several URLs to compete with near-identical explanations.
    4. Find missing depth. Mark important questions that receive only a sentence on the hub but deserve a focused spoke.
    5. Find unnecessary overlap. Merge or reposition pages that answer the same question without contributing a distinct audience, condition, or level of detail.
    6. Add purposeful links. Connect pages where the relationship helps the reader continue the task, not merely because the pages share a keyword.

    Use descriptive internal-link text. “See our content audit process” gives the destination a clearer role than “learn more.” The surrounding sentence should explain why the linked page matters: it may supply the implementation steps, define a prerequisite, document an exception, or address the next decision.

    Keep the distinction between breadth and depth visible during editing. Breadth means your site covers the important branches of the subject. Depth means the responsible page answers its assigned question with enough explanation, support, and qualification to be useful. Adding more headings to the hub does not create depth if every section remains superficial.

    This structure also gives you a practical publishing decision. If a missing answer can be handled clearly within the existing page’s purpose, add it there. If it changes the audience, intent, or decision being addressed, create a separate spoke and connect it to the hub. That keeps the original page focused while expanding the site’s topical coverage.

    Make the answer easy to synthesize

    Retrieval is only part of the job. An AI system may need to combine definitions, conditions, examples, and limitations from different passages. Your copy should make those relationships explicit enough that the system does not have to rewrite the argument merely to understand it.

    For each important question, use an answer-first sequence:

    • Answer: State the conclusion in plain language.
    • Explain: Describe why the answer holds or how the process works.
    • Support: Add the evidence, example, or expertise that makes the answer worth using.
    • Bound: Identify limitations, exceptions, prerequisites, or cases where a different answer applies.
    • Direct: Tell the reader what to do next or where to find the connected detail.

    This order is not a ban on nuance. It is a decision about timing. Give the answer before the complexity, then add the complexity where it can refine the answer instead of delaying it.

    Use explicit labels when they help. “Summary,” “What this means,” and “When this does not apply” tell both the scanning reader and the retrieval system what a passage is doing. Avoid decorative labels such as “The road ahead” when the section is actually explaining implementation requirements. A heading should describe its information, not merely set a mood.

    Write title tags around purpose, not just topic

    A title tag that names only a broad keyword leaves the page’s contribution unclear. Add the question, decision, or scope that distinguishes the answer. For example, “Session replay software” identifies a topic, while “Session replay: what it shows, when to use it, and its limits” describes the page’s purpose.

    Use this working template: [Topic]: [main question, decision, or outcome]. Do not force every title into the same formula, and do not promise coverage the page does not provide. The title should be a faithful description of the answer below it.

    Turn headings into questions or useful assertions

    Readers should be able to scan the heading structure and understand the page’s argument. Replace labels such as “Overview,” “Benefits,” “Considerations,” and “More information” with the actual idea:

    • What is AI search content optimization?
    • Which pages should you optimize first?
    • Why does a self-contained passage improve retrievability?
    • When should a question become a separate spoke page?
    • What should you test before publishing the revision?

    You do not need to phrase every heading as a question. A clear assertion such as “A hub maps the topic while a spoke resolves one task” can be equally effective. What matters is that the heading exposes the section’s intent.

    Use the meta description as a compact intent statement

    The meta description should identify the audience, problem, and framing of the page. A practical drafting template is: For [audience], this page explains [problem or decision] in the context of [scope or condition].

    For example: “For content teams updating established pages, this workflow explains how to expose direct answers, improve passage clarity, and connect topic coverage for AI search.” That description does more than repeat the title. It clarifies who the page serves and how the subject is handled.

    Treat titles, headings, and descriptions as context anchors. They reinforce a clear page; they do not rescue an opaque one. If the body never states the promised answer, metadata will only make the mismatch more obvious.

    Preserve the expertise that makes the answer worth citing

    A clean structure can still produce forgettable content if the editing removes every specific judgement. Generic copy often defines a topic, lists familiar benefits, and ends before making a meaningful decision. Keep the material that demonstrates why your answer deserves attention.

    • Name the recommendation instead of implying that several options may be useful.
    • Explain the mechanism behind the recommendation, not just the expected benefit.
    • Retain accurate proprietary examples, original analysis, and subject-matter insight already present on the page.
    • Separate the default case from exceptions rather than blending them into vague language.
    • State what the method cannot solve, especially when a reader might otherwise apply it too broadly.
    • Delete introductions and transitions that delay the answer without adding context, evidence, or qualification.

    The goal is not to sound like a machine. It is to make your judgement legible. Human readers also benefit when a page names its conclusion, explains the reasoning, and makes exceptions easy to find.

    Test extraction before you publish the revision

    A transparent scanning frame lifts selected blank answer cards from a modular web page into a separate tray.

    Do not finish the refresh when the copy looks cleaner in the editor. Finish when the important answers survive extraction. Run the following editorial checks on the rendered page:

    1. Intent check: Read only the title, opening paragraphs, and headings. Confirm that they describe one coherent purpose and show where the reader’s main questions are answered.
    2. Isolation check: Move each critical section into a blank document. Restore any subject, condition, or definition that disappeared with the surrounding context.
    3. Answer check: Inspect the first sentence beneath each important heading. Rewrite openings that merely announce what the section will discuss.
    4. Qualification check: Confirm that limitations appear in the same answer unit as the claims they restrict. A caveat hidden several sections later is easy to lose.
    5. Overlap check: Compare sections and related URLs. Give each question one primary answer and remove duplicative passages that do not add a distinct condition or perspective.
    6. Relationship check: Follow every important internal link. Verify that the destination resolves the next question and that the anchor text names that relationship.
    7. Synthesis check: Ask an AI model to summarize the page and identify its main takeaways. Compare the output with what the page actually says, paying particular attention to missing conditions and overstated conclusions.
    8. Human-usefulness check: Read the page as someone making the decision it addresses. Make sure the answer is fast to locate, the reasoning is sufficient, and the next action is explicit.

    The synthesis check is diagnostic, not proof of visibility. AI output can vary with the question and context, so do not treat one response as a ranking report. Use a stable set of representative questions before and after the revision. Record whether the model identifies the correct main answer, preserves the important qualifications, and connects related concepts accurately.

    A useful final test is whether the model can quote or summarize the page accurately and find its answer quickly. If the summary is wrong, locate the passage that permitted the error. The cause is often an implicit subject, a conclusion delayed until the end, a missing boundary, or competing answers spread across the site.

    If the page passes the structural checks but still produces an empty or generic answer, stop reformatting. The next revision needs better substance: a clearer judgement, stronger support, a useful example, or a more precise explanation of when the recommendation applies. More headings will not fix an undifferentiated answer.

    Start with one page your team already relies on to answer a recurring question. Put its conclusion near the top, rebuild its important sections as standalone answer units, connect it to the right hub and spokes, and run the extraction checks. Once that page works, turn its structure and QA gate into the repeatable standard for your next revision.

    References

  • How to Build an AI Search Visibility and AEO Strategy

    How to Build an AI Search Visibility and AEO Strategy

    Your search rankings can look stable while your brand disappears from the decision. A buyer can ask an AI assistant to define the problem, assemble a shortlist, compare options, and identify objections before visiting a conventional search result.

    OpenAI has reported that ChatGPT surpassed 900 million weekly active users. That scale makes answer engines a discovery environment, not merely a different interface for search. Your job is no longer limited to earning a blue-link click. You need to make your brand understandable, retrievable, citable, and appropriate to recommend.

    Key takeaways

    • Choose the questions and decisions for which your brand has a credible right to appear. Broad visibility without decision relevance is mostly noise.
    • Treat brand mentions and URL citations as separate outcomes. Mentions build consideration; citations show that your material supplied part of the answer.
    • Build self-contained answer units with a clear scope, direct answer, evidence, limitations, and a useful next step.
    • Use taxonomy, internal links, and accurate schema to reinforce the same entities and relationships expressed in the visible content.
    • Measure AI visibility with a fixed prompt set, then connect the observations to branded search, qualified landing-page visits, and conversions.

    Define the answer you want your brand to own

    Do not start by asking, “How do we rank in ChatGPT?” That question is too broad to guide a page, an editorial calendar, or a measurement plan. Start with the decision your customer is trying to make and the conditions that change the right answer.

    An AI response can produce several materially different outcomes for your business. It can name your brand without linking to you, cite your page without recommending the brand, do both, or omit you entirely. Brand mentions and LLM citations are distinct forms of visibility, so each needs its own strategy and metric.

    • A mention is useful when your goal is to enter a shortlist or become associated with a product category, use case, or audience.
    • A citation is useful when you publish facts, definitions, methods, comparisons, or original information that an answer can reuse.
    • A mention plus a citation is strongest when the cited evidence directly supports the reason the brand was included.
    • An appearance in an irrelevant answer is not a win. It can create the wrong expectation and send poorly qualified visitors to the site.

    Build a query-to-answer map before you change any content. For every important customer decision, record the following:

    1. Audience: Who is asking? Include the role, level of knowledge, or use case that materially changes the answer.
    2. Decision: What are they choosing, rejecting, verifying, or trying to accomplish?
    3. Constraints: Note compatibility, location, budget class, risk, scale, physical requirements, or other conditions that narrow the valid choices.
    4. Evidence needed: Identify the facts a careful buyer would need before trusting the answer.
    5. Desired visibility: Decide whether you want a brand mention, a citation, or both.
    6. Best destination: Select the page that can satisfy the next step without forcing the visitor to restart the search.

    Consider the query “waterproof hiking boots for wide feet.” A generic hiking-boots category page matches some keywords, but it does not resolve the decision. A useful answer needs to define what “wide” means for the available products, distinguish waterproof construction from water resistance, explain relevant fit limitations, and lead to products that actually meet those conditions. That is the difference between topical proximity and answer eligibility.

    Prioritize questions where you can substantiate the answer. If your only support is a marketing adjective such as “leading,” “easy,” or “best,” you do not yet have an answer-engine asset. You have a claim that a retrieval system has little reason to trust or repeat.

    A published Google patent outlines a possible system that could generate organization-specific landing pages tailored to a user’s query. A patent is not a product announcement and may never become a search feature. The useful strategic signal is narrower: generic destination pages are vulnerable when they make a machine or a person perform too much work to connect the query, the entity, and the relevant offer. Make those relationships explicit on your own site now.

    Build pages from retrievable answer units

    A blank page-like slab separates into modular information blocks while selected blocks rise toward a translucent lens.

    Give every answer unit enough context to stand alone

    AI retrieval does not always treat a page as one indivisible object. Content can be segmented into chunks and evaluated against the user’s intent. That makes the section beneath a heading an important unit of work. Semantic depth and retrievable structure matter alongside keywords.

    A strong answer unit contains these elements:

    • Scope: Name the exact question, audience, product, process, or condition being addressed.
    • Direct answer: Resolve the main question early instead of delaying the answer behind a long introduction.
    • Reasoning or evidence: Explain why the answer holds and identify the facts that support it.
    • Boundaries: State the conditions under which the answer changes, does not apply, or needs qualification.
    • Next step: Link to the comparison, product, calculator, documentation, or action that logically follows.

    Use a simple extraction test during editing. Read the heading and its section without the page title or preceding paragraphs. If you encounter vague phrases such as “this solution,” “these benefits,” or “it depends” without enough local context to identify the subject and conditions, revise the section. The goal is not to repeat the entire page. It is to remove dependencies that make the passage ambiguous when retrieved on its own.

    Do the same test on tables, captions, comparison criteria, and FAQ answers. A technically correct fragment can still be unusable if its unit, timeframe, product version, geography, or comparison basis is missing.

    Increase context density without inflating word count

    Context density is not a request to make every page longer. It means that each section contributes a distinct piece of meaning around the primary topic. A useful contextual field includes the main entity, supporting concepts, user intent, relevant constraints, natural language variants, and relationships to other entities.

    • Use the primary topic as the page’s axis, not as a phrase that must be repeated mechanically.
    • Add secondary concepts only when they define a criterion, answer a real question, introduce evidence, or establish a necessary relationship.
    • Use the terms your audience uses, including legitimate variants, but do not create near-duplicate paragraphs to accommodate every phrasing.
    • Name entities precisely. Distinguish a company from its product, a product family from a model, and a feature from the outcome it may support.
    • Place qualifications beside the claim they constrain. Do not hide a critical exception in an unrelated section near the bottom of the page.

    A decision-oriented page will often need a direct answer, definitions, evaluation criteria, evidence, limitations, comparisons, and a next action. It does not need a ceremonial history lesson unless that history changes the decision. Precision is more useful than reaching an arbitrary word count.

    Make architecture and schema confirm the same meaning

    A good paragraph can be weakened by a site that sends contradictory signals. Taxonomy, internal links, canonical destinations, visible labels, and structured data should agree about what the page represents and how it relates to the rest of the site. Internal linking, taxonomy, and schema provide structural and entity context; they are not merely housekeeping.

    • Taxonomy: Group content by meaningful subjects and entities, not by every keyword variation. A category should help a visitor predict what belongs inside it.
    • Internal links: Link from explanatory content to the most relevant decision or product page. Use anchor text that describes the relationship rather than generic instructions such as “click here.”
    • Canonical destinations: Choose a clear primary page when several URLs compete to explain the same entity or intent.
    • JSON-LD: Use the most specific applicable schema type and describe the same organization, article, product, offer, or other entity that appears in the visible page.
    • Entity consistency: Keep names, URLs, product identifiers, authorship, and organizational relationships consistent wherever they are declared.
    • Validation: Check the deployed markup for syntax errors, missing required values, and discrepancies between structured data and visible content.

    Schema does not force an answer engine to mention or cite you. Its role is clarification. It reduces ambiguity about entity type, ownership, attributes, and relationships. Marking up a claim that the page cannot support does not create authority; it only expresses the unsupported claim more formally.

    Create evidence worth reusing and corroborating

    Answer engines need material they can use, not just language that says your company is good. Your content becomes more citable when it contributes information gain: original data, precise specifications, a transparent method, a clear definition, a useful comparison, or a well-supported explanation. Unique information creates a stronger opportunity for URL citations.

    Create a claim ledger for every commercially important page. For each claim, record the exact wording, the evidence that supports it, the page where that evidence is visible, the conditions or limitations, and the person responsible for keeping it current. This exposes a common content problem: a claim may appear throughout the site while its proof exists nowhere a reader can inspect.

    • Product and service facts: Publish exact attributes, compatibility, requirements, inclusions, exclusions, and operating conditions where they affect suitability.
    • Decision evidence: Explain the criteria a buyer should use and why those criteria matter.
    • Methods: When you publish an evaluation, test, survey, or benchmark, state how it was produced and what its limitations are.
    • Definitions: Define specialized terms before using them to support a commercial conclusion.
    • Limitations: Say who should not choose the option, where it does not fit, or which assumptions would change the recommendation.
    • Maintenance signals: Show when time-sensitive facts were reviewed and update or remove claims that can no longer be verified.

    For an ecommerce business, this work connects discovery to revenue. A useful product answer does more than repeat a product name. It connects the shopper’s constraint to verifiable attributes, explains the tradeoff, and leads to a suitable product or category. That is how answer-engine visibility can support trust and purchase consideration rather than producing an empty impression.

    Your website is only part of the entity environment. Relevant review platforms, professional communities, trade coverage, and other independent contexts can reinforce what your brand is known for. Consistent presence in the places your audience actually uses can support brand recognition and recommendation visibility. It also gives you an external consistency check: if independent descriptions of the brand differ sharply from your preferred positioning, the market may not understand the category or use case you are trying to own.

    Do not manufacture reviews, seed disguised endorsements, or flood communities with repetitive promotional copy. Besides the reputational risk, artificial repetition is weak evidence. Contribute useful explanations, accurate product information, expert participation, and material that other people have a legitimate reason to reference.

    Measure the dark funnel and improve the next cycle

    A buyer silhouette travels through a dark branching information tunnel toward a brightly lit group of product objects, with glowing observation points along the route.

    AI discovery can happen before any observable visit to your site. A person may encounter the brand in an answer, search for the brand later, and convert through a channel that receives all the credit. This ingestion-to-recommendation-to-verification path is difficult to reconstruct with conventional analytics. Traffic remains useful, but it cannot fully describe AI visibility.

    Create a repeatable prompt-monitoring set

    1. Select prompts from the query-to-answer map, including discovery, comparison, suitability, objection, and verification questions that matter to the business.
    2. Preserve the exact prompt wording. A rewritten prompt is a new observation, not a clean continuation of the old one.
    3. Run the set on a consistent schedule and record the answer engine, model or mode when visible, date, account state, and location when those variables may affect the result.
    4. Capture the complete answer. Record whether the brand appeared, how it was described, which URLs were cited, where the brand appeared in the response, and which competitors or alternatives were included.
    5. Annotate meaningful changes to content, schema, internal links, product information, digital PR, and third-party coverage.
    6. Compare repeated observations without treating a single changed response as proof that your intervention caused the change.

    Keep the reporting layers separate. Combining everything into a single AI visibility score can conceal the exact failure you need to fix.

    • Prompt coverage: The share of tracked, relevant prompts in which the brand appears.
    • Citation coverage: The share of tracked prompts that cite an owned URL.
    • Answer fit: Whether the brand appears for the intended audience, constraint, and use case rather than in a generic or inaccurate context.
    • Evidence reuse: Which claims, definitions, data points, or pages recur across answers.
    • Competitor context: Which entities appear beside your brand and which stated criteria seem to drive their inclusion.
    • Verification behavior: Changes in branded search, direct visits, visits to named product or service pages, and other signals that people may be checking an AI-assisted decision.
    • Business outcomes: Qualified leads, purchases, conversion rate, and revenue from the destinations most closely connected to the tracked decisions.

    Use the following combinations as working diagnoses, not as proof of how a model reached its answer:

    Observed resultWorking interpretationNext check
    Brand mentioned, owned URL not citedThe entity may be recognized, but your site is not supplying the reusable evidence.Inspect whether the relevant claim has a precise, indexable evidence page and a clear relationship to the brand.
    Owned URL cited, brand not recommendedThe content may be useful while the commercial entity remains weakly associated with the use case.Strengthen entity relationships, brand attribution, relevant internal links, and independent corroboration.
    Brand mentioned and URL citedThe answer connects the entity with evidence, but commercial value is not guaranteed.Check answer accuracy, destination relevance, qualified visits, and conversion behavior.
    Neither mention nor citationThe gap may involve relevance, retrieval, indexing, insufficient evidence, or a query the brand cannot credibly satisfy.Verify technical accessibility, intent alignment, answer-unit clarity, and the strength of the underlying claim.

    Turn the findings into a publishing cycle

    1. Establish the prompt and analytics baseline before making changes.
    2. Choose a commercially meaningful decision where the brand has credible evidence but weak mention or citation visibility.
    3. Audit the relevant page for answer completeness, extractable context, claim support, internal links, and accurate schema.
    4. Fill the evidence gap. Add facts, methodology, qualifications, comparisons, or product attributes that a careful answer would need.
    5. Align related pages and entity declarations so they reinforce rather than compete with the primary destination.
    6. Earn legitimate independent visibility in the communities, review environments, and publications relevant to that decision.
    7. Repeat the prompt set, inspect the resulting patterns, and compare them with branded demand, qualified visits, and business outcomes.

    Start with the customer decision closest to qualified demand. Make its answer explicit, make its evidence inspectable, and make the underlying entities consistent across content, links, and schema. Then measure whether answer engines begin to retrieve the page, cite the evidence, and place the brand in the right consideration set. That is a strategy you can improve, even when the full journey remains hidden.

    References

  • Local Business Contact Page SEO: A Practical Blueprint

    Local Business Contact Page SEO: A Practical Blueprint

    If your contact page contains only a phone number and a form, your customer still has work to do. They must find out when you are open, whether they can text you, where to park, which payment methods you accept, and what will happen after they submit an inquiry.

    Those missing details also make your business harder for search systems to interpret. Google can crawl and interpret a contact page to extract business details, so this page should function as a complete local business record as well as a conversion page.

    Give the contact page three clear jobs

    A useful contact page answers three questions without making the visitor search the rest of your site:

    • Have I found the right business? The page confirms your name, brand, location, and what you do.
    • Can this business meet my practical needs? The visitor can check hours, service options, amenities, directions, parking, and payment methods.
    • What should I do next? The page presents a visible action and explains what happens after the customer takes it.

    That makes the contact page closer to a focused local landing page than an administrative endpoint. It still needs to be concise, but concise does not mean incomplete. The goal is to put every fact needed for a call, visit, message, pickup, delivery, or appointment in one dependable place.

    Key takeaways

    • Publish a complete business identity, not just a name, address, and phone number.
    • Make shared details agree with your Google Business Profile.
    • Answer practical questions about contacting, visiting, buying, and arriving.
    • Support your claims with verifiable reviews, credentials, awards, and local involvement.
    • Use a prominent call to action, explain the follow-up process, and track completed actions.

    Publish one complete and consistent business record

    Illustration of a storefront linked to matching phone, location, hours, and email icons across a computer, smartphone, card, map tile, and directory panel.

    Start with facts before rewriting headlines or changing the design. Open the contact page beside your Google Business Profile and compare every field they share. A customer should not see one phone number on the page, another on the profile, and unexplained hours somewhere else.

    Make the business identity unmistakable

    Use the same recognizable logo that appears on your signage and other marketing materials. State the full customer-facing business name prominently. If you use a slogan, keep it accurate and useful; forcing location phrases or service keywords into it will make the page sound less credible.

    Follow the identity block with a short introduction that says what you do, where you operate, and why someone would choose you. A practical pattern is: business type, location, main area of expertise, and a genuine differentiator. This gives a first-time visitor enough context to confirm that they reached the intended company.

    Include the details customers otherwise have to hunt for

    • Full business name: Use the name customers encounter on your storefront, Google Business Profile, invoices, and other public materials.
    • Complete address: Include every part needed to reach the correct entrance or unit.
    • Phone number: Make it easy to select on a mobile device and label its purpose if you publish more than one number.
    • Text number: If texting is supported, say so explicitly. Do not leave visitors guessing whether the main number accepts messages.
    • Contact form and email address: Provide an alternative when the form fails, the request needs an attachment, or the visitor prefers email.
    • Operating hours: Publish normal hours and keep special or holiday variations current.
    • Social profiles: Link only to profiles you actively associate with the business.
    • Ways to buy: State whether you offer in-store shopping, curbside pickup, delivery, appointments, or another relevant arrangement.
    • Map and directions: Embed the Google Map connected to the business and include a direct link to its Google Maps listing. A generic pin for the street address can be less useful than the actual business listing.
    • Accepted payment methods: Tell customers what they can use before they arrive or place an order.
    • Parking information: Explain where customers can park and identify any instructions they need before reaching the entrance.

    The shared facts on this page and your Google Business Profile should agree. That does not mean every channel must contain identical prose. It means the business name, location, contact routes, hours, service options, and applicable attributes should not contradict one another.

    When something changes, update both records as part of the same task. Assign an owner for the page and include it in the workflow for holiday hours, phone changes, relocations, new payment methods, and revised pickup or appointment policies. A technically polished page with stale operational information still fails the customer.

    Remove friction from calling, visiting, and buying

    A customer holds a phone with icon-based contact actions while a clear route leads to an accessible local shop with parking, a bicycle rack, and welcoming staff.

    Visitors do not all arrive with the same intention. One wants to call immediately. Another needs directions. A third is checking whether curbside pickup is available. The page should support those paths without forcing everyone through the contact form.

    • For callers: Place the phone number near the primary call to action and show the hours during which a response is available.
    • For people who want to text: Label the text option and set an expectation for how the conversation continues.
    • For visitors traveling to you: Pair the address with the business map, a Google Maps link, parking instructions, and any arrival detail that prevents confusion.
    • For shoppers: State whether the relevant option is in-store service, pickup, curbside collection, delivery, an appointment, or some combination.
    • For people comparing fit: Publish relevant amenities and business attributes in plain language rather than assuming they will infer them from photos.
    • For written inquiries: Offer both the form and an email address, then explain what information will help your team respond.

    Put the most common action early on the page, but do not hide the supporting details below a long promotional introduction. Someone standing outside your building needs the address, hours, map, and parking information more than another paragraph about brand values.

    Amenities deserve particular attention because they often decide whether a customer can use a business at all. Review the attributes shown on your Google Business Profile, confirm which ones are still accurate, and reproduce the applicable facts on the page. Add other genuinely useful amenities that are specific to your location. Do not claim an attribute merely because it sounds desirable.

    If you operate multiple locations, do not mix several addresses, phone numbers, and sets of hours into an unlabeled block. Make the selected location obvious, separate its facts from every other branch, and ensure each call to action reaches the right team or destination.

    Put trust and local relevance beside the decision

    Reaching the contact page does not mean the visitor has decided to contact you. They may be looking for one final reason to proceed or one warning sign that tells them to leave. Place evidence close to the action instead of expecting them to visit a separate company-history page.

    Explain what happens after contact

    Uncertainty is a conversion barrier. State the expected response time, whether the visitor will receive a confirmation, and what the next step normally involves. If different channels have different processes, explain them separately. A form submission might lead to a callback, while an appointment request might require confirmation before the time is reserved.

    Make those expectations operationally honest. A vague promise such as “we respond quickly” gives the customer no usable information. A clearly stated response window is better, but only if your team can maintain it. If you cannot commit to a window, describe the sequence instead: confirmation, review, and follow-up.

    Use proof that a visitor can verify

    • Associations and memberships: Name relevant industry groups, chambers of commerce, professional organizations, neighborhood associations, and community groups. Link to your business entry on the organization’s site when one exists.
    • Ratings and credentials: Display current credentials and any applicable Better Business Bureau information without overstating what the rating or membership means.
    • Awards and press: Identify the award or coverage and link to the organization or publication that issued it.
    • Reviews and testimonials: Use external reviews or testimonials that include enough context to feel authentic, such as the reviewer’s name, photo, city, or public profile when you have permission to publish those details.

    Verification matters more than the number of badges. An unfamiliar logo with no explanation can become visual clutter. A named organization, a clear relationship, and a link to an independent listing give the visitor something they can evaluate.

    The page can also serve existing customers. Include a clear link for leaving a Google review where appropriate, especially for repeat customers who arrived looking for your contact details. Keep that request separate from the main inquiry action so a new customer does not mistake it for the contact route.

    Replace generic local copy with specific local evidence

    Calling yourself a trusted local business does not establish local relevance. Show it through details: team names and photographs, areas of expertise, the customer needs you handle, neighborhoods you serve, current guarantees, local events, volunteer work, and partnerships.

    Only include details that help someone decide or verify. A list of neighborhood names added solely for keyword coverage is not useful local content. A short explanation of where you work, which services are available there, and what a customer should expect is useful.

    Specificity also helps systems answer constrained questions about fit. Clear amenities and business attributes can help traditional and AI-powered search understand whether a location meets a particular need. That is not a guarantee of visibility or rankings. It is a reason to publish accurate facts that a search system does not have to infer.

    Make the next action obvious, reliable, and measurable

    Choose a primary call to action that matches the way the business actually converts inquiries. “Request an appointment,” “Call the store,” “Get directions,” and “Ask about pickup” each describe an outcome. “Submit” describes only what the button does.

    Repeat the primary action at sensible decision points: after the identity and contact details, after the trust evidence, and near the end. Keep its wording consistent. Secondary actions can support visitors with a different intent, but they should not make every option look equally important.

    Treat the form as a working contact channel

    • Pair the form with an email address so customers have a fallback.
    • Tell the visitor what happens after submission and how your team will respond.
    • Use an appropriate spam control, such as reCAPTCHA, a form plugin’s protection, a double opt-in process, or an obfuscated public email address.
    • Test the spam protection on a phone and with keyboard navigation so it does not block legitimate inquiries.
    • Send submissions to a monitored destination and verify that confirmation messages and internal notifications arrive.
    • Track a successful form completion as a conversion. Measuring a button click alone can count attempts that failed validation or never reached your team.

    Tracking should reflect the actions that matter to the business. At minimum, verify the form completion event. If calls, text messages, map visits, appointment requests, or pickup inquiries are important contact paths, decide which of those interactions should also be measured. Analytics cannot repair a broken contact experience, but it can reveal which routes customers use and whether a redesign disrupted them.

    Run this publishing audit from a customer’s point of view

    1. Confirm identity. Check the full name, logo, location, business description, and differentiator.
    2. Reconcile business data. Compare the address, phone and text numbers, hours, service options, and applicable attributes with the Google Business Profile.
    3. Test every contact route. Call the number, open the text option, send the form, use the email link, and confirm that each route reaches the intended destination.
    4. Test the visit. Open the embedded map and Google Maps link, then verify that they lead to the actual business listing. Read the parking and arrival instructions as though you have never visited.
    5. Check practical fit. Confirm that payment methods, shopping options, amenities, and appointment requirements are accurate.
    6. Verify the proof. Open association, award, press, review, and credential links. Remove expired claims and unexplained badges.
    7. Complete the primary action. Use both a mobile and a larger screen. Confirm that the call to action is visible, the form is usable, the confirmation appears, the inquiry reaches the team, and the conversion is recorded.
    8. Assign maintenance. Identify who will update the page when hours, staff, contact details, service methods, parking, amenities, or credentials change.

    Start your first pass with the facts, not the design. Reconcile the page with your Google Business Profile, fix every broken contact route, and then add the missing visit details and proof. Once a customer can identify you, assess fit, trust the business, and complete the next step without guessing, the contact page is doing its real job.

    References

  • AI Platform Citation Patterns: A Practical GEO Playbook

    AI Platform Citation Patterns: A Practical GEO Playbook

    You check an important prompt and get a frustrating result: your brand appears with a link on one AI platform, appears without a link on another, and disappears entirely on a third. That does not automatically mean your content is weak. ChatGPT, Google AI, and Perplexity show materially different citation patterns, so a single visibility score can hide the problem you actually need to solve.

    Replace the broad question, “How do we get cited by AI?” with a more useful one: “For which query, on which platform, and in support of which claim do we need to be cited?” Once you frame the work that way, citation optimization becomes an observable process rather than a guessing game.

    Treat citation visibility as a set of states, not a single score

    Four blank glass tiles depict citation visibility progressing from a linked source to recognition without a link, a faint source, and complete absence.

    An AI answer can mention your brand without linking to you. It can cite your page while leaving your brand name out of the answer. It can cite an independent publication for a claim about your product. Each result means something different, and each calls for a different response.

    What you observeWhat it may meanWhat to inspect next
    Your brand is mentioned and your page is citedThe answer connects the claim, your entity, and an owned sourceCheck whether the citation supports the right claim and points to the best page
    Your brand is mentioned but no owned page is citedYou have entity visibility without clear source attributionIdentify which source supports the mention and whether your site has a direct factual page for it
    Your page is cited but your brand is not mentionedYour information is visible while ownership of that information is mutedMake the entity behind the page explicit in the title, answer text, authorship, and structured data
    Your brand and pages are both absentThe gap could involve access, relevance, evidence, authority, entity clarity, or platform-specific source selectionCompare the cited pages before deciding what to change

    Track these states separately. If you collapse them into a generic “AI visibility” metric, you can improve the number while missing the outcome that matters. A brand mention may help recognition but send no referral traffic. An owned citation may expose your information while failing to associate it clearly with your brand. An independent citation may be valuable corroboration even when your own domain is absent.

    Your measurement set should distinguish at least these concepts:

    • Mention coverage: the monitored prompts in which the answer names your brand, product, person, or other target entity.
    • Owned citation coverage: the monitored prompts in which a page you control is cited.
    • Earned citation coverage: the prompts in which an independent page supports a relevant claim about you.
    • Claim fit: whether the linked page actually substantiates the sentence or passage beside the citation.
    • Page concentration: whether citations consistently resolve to the best canonical resource or scatter across weak, duplicated, or outdated URLs.

    Do not turn those measurements into a universal leaderboard. Citation performance belongs to a specific combination of prompt, intent, platform, mode, and observed answer. Preserve that context in every report.

    Map each platform’s pattern before changing your content

    A useful citation audit starts with prompts, not URLs. Your goal is to see which kinds of sources each platform selects for the questions that matter to your audience. You are building a map of observable behavior, not reverse-engineering a hidden algorithm.

    1. Build a representative prompt set. Use questions taken from actual customer research, search demand, sales conversations, support requests, and product evaluation. Include informational questions, comparisons, definitions, troubleshooting queries, and brand-specific questions when those intents matter to the business.
    2. Label the intent behind every prompt. Record what the user is trying to decide or accomplish. Prompts that share a keyword can still demand very different evidence, so the intent label is more useful than the phrase alone.
    3. Hold observable conditions steady. Save the exact wording, language, location context, platform, product or mode label, account state, and whether the prompt began a fresh conversation. Do not compare a fresh prompt on one platform with a heavily conditioned follow-up on another.
    4. Capture the complete answer. Save the response, every visible citation, the exact cited URL, and where the link appears. A citation in a source panel and a link attached to a particular claim should not be treated as interchangeable observations.
    5. Map each citation to the claim it supports. Ask what job the source is doing. It may define a term, verify a product fact, support a recommendation, provide evidence, or supply background context.
    6. Classify the cited source. Useful classes include owned pages, primary authorities, independent editorial coverage, community discussions, competitors, aggregators, and commercial listings. Use categories that reflect your market rather than forcing every domain into a generic authority score.
    7. Repeat comparable observations. Generated answers can vary. A single response is a snapshot, so look for recurring source and claim patterns before making a structural change to the site.

    A practical audit sheet should preserve the evidence needed to revisit a decision later:

    FieldWhat to record
    Prompt and intentExact prompt text plus the user’s underlying task or decision
    EnvironmentPlatform, visible mode or model label, language, location context, account state, and fresh or continuing conversation
    Answer outcomeBrand mention, owned citation, earned citation, competitor citation, or no relevant inclusion
    Citation targetExact domain and resolved page URL
    Supported claimThe answer sentence or idea for which the citation appears to provide support
    Source classOwned, primary authority, independent editorial, community, competitor, aggregator, or another market-specific class
    Quality notesWhether the page directly supports the claim, is current enough for the topic, and names the relevant entity clearly

    Read the sheet in both directions. Compare the same prompt across platforms to expose platform-specific differences. Then compare different prompt types within a platform to see whether its source mix changes with intent. A platform may appear favorable overall while consistently excluding you from the commercial questions that matter most.

    Keep branded and unbranded prompts in separate views. A system finding your official site after the user supplies your exact brand name does not establish visibility for category discovery. Likewise, an unbranded prompt is a poor test of whether the platform can resolve a precise company fact. The queries answer different business questions.

    Build citation-ready pages without writing for a machine

    Once you know the missing claim, improve the page that should substantiate it. Do not begin with a sitewide rewrite or a pile of generic AI-generated summaries. Citation readiness comes from making a specific answer easy to find, interpret, verify, and attribute.

    Make important claims self-contained

    A useful passage should still make sense when separated from the paragraphs around it. Name the entity instead of relying on a chain of pronouns. State the condition or scope alongside the claim. Put the supporting evidence close enough that a reader can tell what it validates.

    A simple writing pattern is: [Entity] does [specific thing] when [condition]. This applies to [scope]. The basis is [method, record, or primary evidence]. It does not establish [important limitation].

    This is not a template to fill with unsupported certainty. It is a check against vague sentences such as “it improves performance” or “this is the best option.” A citable answer identifies what changed, for whom, under what conditions, and on what basis.

    • Use a descriptive heading that matches the question the section answers.
    • Put the direct answer before the background needed to interpret it.
    • Name the relevant company, product, person, place, or concept in the answer itself.
    • Keep qualifiers attached to the claim they limit.
    • Link primary evidence beside the factual statement it supports.
    • Separate documented facts from editorial recommendations.
    • Give important facts a stable canonical URL rather than scattering variants across several near-duplicate pages.
    • Show authorship, publishing responsibility, and material update information where they help a reader evaluate the page.

    Original material should also explain its provenance. If you publish data, state what was measured and how. If you define a framework, explain its boundaries. If you recommend an option, expose the criteria behind the recommendation. The goal is not merely to sound quotable; it is to make the claim defensible after it is extracted from the page.

    Use JSON-LD as an alignment layer, not a citation switch

    Structured data should describe the same entities, relationships, authorship, and page purpose that a person can see in the content. Choose the most specific schema type that genuinely matches the page, connect stable entity identifiers where appropriate, and validate the markup after deployment.

    Do not use JSON-LD to make claims that the visible page does not support. Do not expect schema markup to compensate for thin evidence, unclear ownership, inaccessible content, or a page that answers a different question. Markup can reduce ambiguity; it cannot command an AI platform to cite a URL.

    Technical access still matters. Check that the preferred page returns successfully, declares the intended canonical target, is not accidentally excluded by robots directives or a noindex instruction, and exposes its core answer as readable page content. Preserve legitimate privacy, licensing, and access controls. Citation visibility is not a reason to publish material that should remain restricted.

    Entity consistency matters beyond your own domain as well. If independent profiles, partner pages, listings, interviews, and editorial coverage use conflicting names or outdated facts, the external record becomes harder to reconcile. Correct material inconsistencies and give third parties a stable official page they can verify. Earned coverage and an official source page solve different parts of the problem; you often need both.

    Turn observed citation patterns into a prioritized backlog

    Abstract AI output panels feed citation evidence tokens through filters into an ordered staircase of content improvement tasks.

    The cited pages are diagnostic clues. Compare their topic coverage, evidence, entity clarity, format, and relationship to the claim before deciding that you need more content or more links. The same symptom can have several causes, so treat every diagnosis as a hypothesis to test.

    Observed patternWorking hypothesisUseful next move
    Your page is cited on one platform but absent on anotherThe problem is unlikely to be a universal content-quality failureInspect the missing platform’s cited source types and compare how they support the target claim
    An independent page is cited for a fact about your brandThe answer may be relying on external corroboration or a clearer third-party explanationStrengthen the official fact page, correct external inaccuracies, and preserve credible independent coverage
    A competitor is repeatedly cited for a category questionIts page may answer the intent more directly or provide evidence your page lacksCompare the exact cited passages, then improve the missing answer or evidence rather than copying the page format blindly
    Your page is cited beside a claim it does not clearly supportThe page may contain ambiguous wording or loosely grouped factsSeparate claims, attach evidence to the right statement, and clarify scope
    Your brand is mentioned without an owned citationThe entity is visible, but the platform may not have selected an official page for that claimCreate or strengthen the authoritative page that directly verifies the fact
    Results change substantially across comparable runsThe apparent gap may not yet be a stable patternCollect more comparable observations before committing to a large change

    Prioritize work using business value and evidence, not raw citation volume. A useful backlog records:

    • Query value: does the prompt influence discovery, evaluation, trust, support, or another meaningful outcome?
    • Pattern consistency: does the gap recur under comparable conditions, or did it appear in an isolated answer?
    • Claim importance: is the missing citation attached to a central decision-making fact or incidental background?
    • Controllability: can you improve the owned page, technical access, entity record, or evidence path?
    • Cross-platform leverage: would the change improve the underlying resource even if citation behavior remains different among platforms?

    Run focused experiments. Rewrite a vague answer into a self-contained passage. Add missing evidence. Align structured data with the visible entity record. Fix an access or canonical problem. Improve the official page that third parties need to verify. Change a single major variable where practical, preserve the before-and-after captures, and rerun the same prompt set under comparable conditions.

    Do not promise a citation as the outcome of any individual change. You do not control platform selection, and a lack of immediate movement does not prove that the page became worse. Judge the work first by whether the resource is clearer, more supportable, more accessible, and better aligned with the query. Then use repeated platform observations to assess visibility.

    Key takeaways

    • AI citation visibility is platform-, prompt-, intent-, and mode-specific. There is no single citation ranking to optimize.
    • Track mentions, owned citations, earned citations, claim fit, and citation targets separately.
    • Map every citation to the claim it supports before changing content.
    • Make important answers self-contained, scoped, attributable, accessible, and backed by adjacent evidence.
    • Use JSON-LD to clarify visible entities and relationships, not as a substitute for evidence or authority.
    • Prioritize recurring gaps on valuable queries and test the most controllable explanation first.

    Your next move should be small and observable. Choose the prompts tied to a real audience decision, capture their citation patterns across the platforms that matter, and find the most consistent gap you can control. Improve that evidence path, then run the same audit again. That is how citation monitoring becomes a durable GEO program instead of a series of reactions to screenshots.

    References

  • SEO Fundamentals for Beginners: A Practical Workflow

    SEO Fundamentals for Beginners: A Practical Workflow

    You have a website, a list of keywords, and an audit full of warnings. The tempting move is to edit every title, install another tool, or chase backlinks. That usually creates activity without answering the question that matters: what should organic search help this business accomplish?

    SEO becomes manageable when you follow a clear chain: understand the business, identify the searcher’s intent, create the right page, remove technical barriers, and measure whether the page advances a real outcome. This workflow gives you a practical way to do that without letting tools or AI make decisions you aren’t yet equipped to judge.

    Start with the business outcome, not the keyword list

    A keyword is only useful when it connects the right person to something the business can genuinely provide. That is why business context belongs at the start of an SEO project, before metadata, links, or optimization scores.

    Write down the answers to these questions before opening a keyword tool:

    • What is being offered? Name the product, service, information, or action precisely.
    • Who is it for? Describe the audience by its situation and need, not just by a broad demographic label.
    • What should the visitor do next? The intended action might be buying, requesting a quote, booking, subscribing, visiting a location, or continuing to another resource.
    • Why should this business be chosen? Identify the relevant difference: expertise, availability, approach, specialization, location, evidence, or another defensible advantage.
    • What result matters to the business? Decide whether success means qualified leads, sales, registrations, store visits, product discovery, or another observable outcome.

    Turn those answers into one sentence: “We need to help [audience] find [offer] when they need [outcome], then move them toward [action].” If you cannot complete that sentence clearly, you are not ready to prioritize keywords. More traffic will not repair a mismatch between the visitor, the offer, and the desired action.

    This business statement also protects you from a common beginner mistake: treating every query with visible demand as an opportunity. A query may be popular but irrelevant to the customers the business can serve. Another query may attract fewer people but describe the exact problem that leads to a valuable action. Prioritize the overlap between audience need and business value.

    Read the search results as evidence of intent

    A magnifying glass examines blank result cards illustrated with learning, comparison, and shopping scenes, with the learning card highlighted.

    Search intent is the job a person expects the results to help them complete. The same subject can support very different jobs: learning how something works, comparing choices, finding a specific website, locating a nearby provider, or completing a purchase. A page can mention the right words and still fail because it serves the wrong job.

    Before creating or rewriting a page, search the target query in the context your audience would use. Then inspect the results manually. This is not about copying competitors. It is about seeing how the search engine currently interprets the request.

    1. Classify the dominant page type. Are the results tutorials, category pages, product pages, service pages, comparison pages, videos, local listings, or something else?
    2. Identify the task they support. Decide whether the searcher is trying to learn, evaluate, act, navigate, or find something nearby.
    3. Note the recurring questions. Repetition can reveal information people are likely to need before completing the task.
    4. Inspect the search features. Images, videos, products, maps, answer-style results, and other formats can indicate that the request is not best served by plain text alone. Search presentations continue to change, so learning the available result features is part of learning SEO.
    5. Look for unresolved friction. Notice where existing results are vague, outdated, difficult to navigate, poorly matched to the query, or missing an important decision point.

    Do not assume that every detail on a ranking page caused it to rank. Its presence tells you that the search engine is willing to show that kind of result for the query. It does not prove that its word count, layout, heading count, or every covered subtopic is a requirement.

    Create a small intent brief from what you observe:

    • Target topic or query: the request you want the page to serve.
    • Searcher situation: what the person likely knows and what has brought them to search.
    • Job to complete: the decision, answer, destination, or action they need.
    • Appropriate page type: the format that can complete that job without unnecessary friction.
    • Essential answer: what the visitor should understand immediately.
    • Supporting proof: the details, examples, specifications, process, or evidence needed to trust the answer.
    • Logical next action: what the visitor should be able to do after getting the answer.

    This brief is more useful than a loose keyword list because it gives every optimization decision a test: does this help the intended visitor complete the intended job?

    Build one page that deserves to satisfy the query

    A keyword is an input to the page, not its outline. Your real task is to make the page useful enough that a person can recognize its relevance, get the necessary answer, verify important claims, and take the next sensible step.

    Use this sequence when drafting or improving the page:

    1. State the answer or value early. Do not make the visitor read a long preamble to confirm that the page addresses the query.
    2. Follow the visitor’s decision path. Explain what they need now, then what they need to compare, verify, avoid, or do next.
    3. Add information that changes understanding or action. Definitions, steps, examples, limitations, specifications, and evidence belong only where they help complete the task.
    4. Use a descriptive page title and main heading. Both should identify the subject clearly and set an accurate expectation. Clever wording is less valuable than immediate recognition.
    5. Use subheadings as signposts. Each section should answer a distinct question or move the task forward. If two sections do the same job, combine them.
    6. Connect relevant internal pages. Link to the next useful explanation, category, service, product, or action with anchor text that describes the destination.
    7. Make the next step proportionate. A visitor who is still learning may need a comparison or supporting explanation before being asked to buy or enquire.

    Use the primary wording naturally in the title, introduction, and relevant headings when it accurately describes the page. Do not force a phrase into every paragraph or create repetitive variations for the sake of density. Clear topical language helps both the reader and the search system; mechanical repetition makes the page worse for both.

    There is also no useful universal length for an SEO page. Stop when the visitor can complete the intended task without an important unanswered question. A simple navigational need may require little explanation. A consequential comparison may require definitions, criteria, trade-offs, and evidence. Let intent determine depth.

    Run a manual content gap check

    Open several relevant results and make a simple worksheet. Record the main question each page answers, the proof it supplies, the next step it offers, and the friction it leaves unresolved. Then decide what your page can make clearer, more complete, more specific, or easier to use.

    Do this work yourself while you are learning. Independent research before relying on AI teaches you how intent, page type, evidence, and search presentation fit together. If an AI system produces the worksheet first, you may receive a polished answer without developing the judgment needed to spot a bad one.

    Learn enough technical SEO to rule out invisible blockers

    A technician inspects a model website and illuminates a disconnected path, closed gate, tangled cable, and dim page tile hidden beneath it.

    Useful content cannot perform in search if the system cannot reach it, is instructed not to index it, or understands another URL as the preferred version. You do not need to become a developer before doing SEO, but you do need to separate discovery, indexing, and ranking problems.

    StageQuestion to answerBeginner check
    CrawlingCan the search system reach the URL and follow a path to it?Open the public URL while logged out, confirm that a normal internal link leads to it, and check that access rules do not block the intended crawler.
    IndexingIs the page allowed to be stored and considered for search?Check for a noindex directive, an unintended canonical URL, a redirect, or a duplicate page that makes the preferred version unclear.
    RankingIs the eligible page a strong match for the query and its intent?Compare its page type, opening answer, supporting information, and usability with the needs revealed by the search results.

    That distinction prevents wasted work. Rewriting a page will not remove an accidental noindex directive. Fixing a canonical setting will not make a transactional page satisfy an informational query. Diagnose the stage before choosing the remedy.

    Use this basic technical pass for every important page:

    • The public URL loads without requiring a private account or internal session.
    • The page is reachable through the site’s internal navigation or contextual links.
    • The page is not unintentionally blocked from crawling or indexing.
    • The canonical reference points to the version you actually want treated as primary.
    • Redirects lead visitors and crawlers to the intended final destination without unnecessary detours.
    • The page works on a small screen without hiding its main content or action.
    • The title and main heading describe this page rather than repeating generic site-wide wording.
    • Important text is present in the page itself rather than available only through an unreliable interaction.

    Do not change noindex, canonical, redirect, or robots controls merely because an audit labels them as warnings. Those controls may be intentional. Changing them without identifying the preferred URL can expose pages that should remain out of search, split attention across duplicates, or remove the version that currently works.

    When you need development help, send a reproducible problem rather than saying “SEO is broken.” Include the affected URL, what you expected, what happened instead, how to reproduce it, which page should be primary, and the business consequence. Building enough technical fluency to collaborate with developers is a more durable skill than memorizing isolated fixes, and developer relationships can deepen that technical understanding.

    Measure the chain, then use AI and AEO as extensions

    Measure where progress stops

    Rankings are not the business outcome. Measure the sequence from search eligibility to useful action so you can see where the page is failing:

    • Access and indexability: can the intended page be discovered and considered?
    • Search visibility: does it appear for queries that match the intent brief?
    • Search engagement: do the page title and result presentation earn visits from the right searchers?
    • On-page engagement: do visitors reach the information or next step the page was designed to provide?
    • Business outcome: do qualified visitors complete the action that matters?

    Use the first weak stage to choose the next action. If the intended page is not eligible for search, inspect technical controls. If it appears for the wrong queries, revisit the intent and page focus. If it appears for appropriate queries but attracts little engagement, check whether the title and description accurately communicate its value. If relevant visitors arrive but do not act, inspect the offer, proof, usability, and next step.

    Keep a change log with the affected URL, the reason for the change, what was changed, and the outcome you expect. Avoid changing every page and every element at once. A smaller, documented change makes the result easier to interpret and the lesson easier to reuse.

    Let AI accelerate work you can already evaluate

    AI can help organize terms, suggest questions, restructure a draft, identify possible omissions, or produce a first pass at repetitive markup. It should not decide the audience, intent, business priority, evidence, or preferred technical outcome for you. Those decisions require context that a plausible-looking output may not capture.

    Before accepting AI-assisted work, check it against the same fundamentals:

    • Does it serve the audience named in the business brief?
    • Does it complete the job described in the intent brief?
    • Are its factual claims accurate and supported?
    • Does it add a useful explanation, distinction, example, or next step?
    • Does it represent the actual product, service, policy, and expertise accurately?
    • Would you publish it if no optimization tool had assigned it a score?

    Extend the foundation to AEO and GEO

    The labels are still used in varying ways, but the operational distinction is useful. Traditional SEO focuses on making pages discoverable, indexable, relevant, and competitive in search results. Answer engine optimization focuses on making an answer easy to identify and use in answer-oriented experiences. Generative engine optimization focuses on making information clear, attributable, and usable when generative systems assemble responses. Understanding how SEO differs from AEO and GEO helps you plan visibility across more than conventional result links.

    The practical work still begins with the same foundation:

    • Answer the central question directly rather than hiding it behind promotional language.
    • Name products, organizations, people, places, and relationships consistently so the subject is unambiguous.
    • Use descriptive headings, lists, tables, and concise definitions when those formats make information easier to extract and verify.
    • Support consequential claims with visible evidence and appropriate citations.
    • Keep authorship, business identity, policies, and areas of expertise clear.
    • Use schema and JSON-LD only to describe information that the page actually contains. Markup can clarify meaning, but it cannot replace missing content or guarantee inclusion in an answer.

    Key takeaways

    • Define the audience, offer, desired action, and business outcome before choosing keywords.
    • Treat search results as evidence of intent and acceptable formats, not as a template to copy.
    • Build each page around one clear visitor job, then supply the answer, proof, and next step that job requires.
    • Separate crawling, indexing, and ranking problems before changing content or technical controls.
    • Measure the full path from search eligibility to business outcome so you fix the stage that is actually weak.
    • Use AI, AEO, GEO, schema, and automation after the underlying business, intent, content, and technical decisions are sound.

    Choose one important page and complete the workflow from beginning to end: write the business statement, build the intent brief, improve the page, run the technical pass, and define the outcome you will watch. Once you can explain why each change helps both the visitor and the business, use tools to repeat the process more efficiently.

    References

  • How to Build an AI Search Visibility Content Strategy

    How to Build an AI Search Visibility Content Strategy

    You can rank well in conventional search and still disappear when a buyer asks ChatGPT or Google’s AI Mode to recommend an option. You can also appear in the answer and lose the opportunity because the system describes your business vaguely, assigns it to the wrong category, or repeats an outdated limitation.

    A useful AI search content strategy therefore has three jobs: place your brand in the buyer’s consideration set, make the right description easy to retrieve, and support that description with evidence an AI system can cite. Here is how to build that strategy around real buyer decisions rather than an unstable idea of “ranking first” in a generated answer.

    Optimize for consideration and representation, not one position

    A generated recommendation is not a fixed search results page. The order can change when the wording, context, platform, or response changes. Treating the first brand mentioned as the AI equivalent of Google’s first organic result gives you a fragile target and hides a more consequential question: does the answer present your brand as a credible fit?

    Observed sessions in ChatGPT and Google’s AI Mode found that users considered an average of 3.7 businesses. In the same dataset, 75% examined businesses shown in positions 2 through 8, and approximately 60% completed their decisions from the AI response without visiting a business website or returning to Google. Those figures come from one body of observational work, so they are not universal benchmarks. They do show why inclusion and message quality deserve more attention than mention order alone.

    Before you plan more content, write the description you want a qualified buyer to receive. A practical template is: [Brand] is a [specific category] for [specific audience] that needs [job or outcome]. It is strongest when [fit condition] and is not the right choice when [meaningful limitation]. If your team cannot agree on that statement, an AI system will have to reconcile inconsistent language scattered across your website and third-party pages.

    Key takeaways

    • Seek eligible inclusion: measure whether your brand appears when it genuinely fits the buyer’s request, not whether it always appears first.
    • Control the description: publish explicit category, audience, use-case, price, fit, and limitation information instead of expecting the system to infer your positioning.
    • Support the claim: combine a clear first-party fact base with accurate, legitimate third-party corroboration.
    • Measure the decision: track inclusion, message accuracy, citations, and commercial outcomes by buyer intent.

    This changes the content brief. “Rank for AI SEO agency” is a keyword objective. “Help a multi-location marketing team determine whether this service fits its reporting and governance needs” is an answer objective. The second version tells the writer which audience, decision, conditions, and tradeoffs must be explicit.

    Build your content map from the questions buyers use to decide

    A hand arranges blank cards, geometric icons, and colored connections into a branching map from a problem to a shortlist of options.

    Broad educational traffic can introduce a category, but recommendation prompts are often built from decision questions: What will this cost? What can go wrong? Which option suits my situation? How does one provider differ from another? Which choices are credible? If those answers are absent, vague, or hidden behind a sales form, the model must rely on whatever else it can find.

    Start with evidence of the language your buyers already use. Search Google Search Console queries, Google Business Profile activity, semantic question maps from tools such as AnswerThePublic, and competitive gaps found with Semrush or Ahrefs. Then add the higher-value material that keyword tools often miss: sales-call notes, live-chat transcripts, prospect emails, objections, support questions, customer feedback, and reasons a buyer rejected an option.

    Sort the questions into five decision categories. This answer-first framework is useful because each category resolves a different kind of buyer uncertainty:

    • Pricing and cost: Give a price, range, or pricing model when you can. Explain what changes the cost, what is included, what is excluded, and which buyer conditions produce a materially different quote. “Contact us” is not an answer.
    • Problems and limitations: Name the situations in which the product, service, or approach becomes difficult, expensive, slow, or unsuitable. Explain the cause, the consequence, and any available workaround. Acknowledging a real limitation makes the surrounding claims easier to trust.
    • Versus and comparisons: Compare options on criteria that affect the decision. State which option is better for which use case, where each creates a tradeoff, and what information the buyer should verify. Avoid declaring a universal winner when fit depends on context.
    • Reviews and evaluation: Help the buyer judge evidence rather than publishing unsupported praise. Describe the evaluation method, the relevant use case, what was observed, and what remains uncertain. Distinguish first-hand evidence from information collected elsewhere.
    • Best-in-class choices: Define the criteria before naming candidates. Include other businesses when they genuinely meet those criteria, explain the scenarios each suits, and disclose where your own offering does not win. The goal is to become a useful evaluator, not to turn every list into an advertisement.

    Prioritize a question when it is close to a purchase decision, repeatedly causes confusion, or exposes a material gap between your intended positioning and what AI answers currently say. Defer a question when you cannot support an answer with facts or when your business is not reasonably eligible for the recommendation. Publishing a confident page does not make an unsupported claim true.

    Give every planned page an answer brief with these fields: the exact buyer question, intended audience, direct answer, decision criteria, named entities, evidence, limitations, desired brand description, related questions, and external information that may confirm or contradict the answer. This keeps a content calendar from becoming a list of loosely related keywords.

    Write each page as a briefing that can stand on its own

    Do not make the reader or retrieval system cross an autobiographical introduction before reaching the answer. Open with the conclusion, identify the entity and context, and then supply the evidence and qualifications needed to use it correctly.

    A large citation analysis covering 1.2 million AI responses and 18,012 verified citations found that 44.2% of citations came from the opening 30% of the content. The middle portion supplied 31.1%, while the final portion supplied 24.7%. This does not mean the rest of a page is disposable. It means a conclusion saved for the final section has a weaker chance of framing how the page is interpreted and used.

    Use this sequence for an answer page:

    1. Answer the question immediately. Name the product, service, method, or category and state the conclusion in plain language.
    2. Qualify the answer. Identify the audience, conditions, version, location, plan, or use case that changes the conclusion.
    3. Expose the decision factors. Explain cost drivers, capabilities, limitations, dependencies, and meaningful alternatives.
    4. Support the important claims. Use first-party facts, transparent criteria, documented examples, and legitimate external corroboration. Remove claims you cannot substantiate.
    5. Resolve the next question. Link to the comparison, pricing, problem, review, or implementation answer the buyer will need next.

    A reusable opening can follow this pattern: [Offering] is best suited to [audience] when [condition]. It is a poor fit when [limitation]. The decision usually turns on [named criteria], so compare options using [evidence the buyer can verify]. Replace every bracket with a concrete fact. If the result still works for almost any competitor, the positioning is not specific enough.

    At paragraph level, the same citation analysis attributed 53% of matched citations to middle sentences, compared with 24.5% to opening sentences and 22.5% to closing sentences. Do not game that distribution by hiding every useful fact in sentence two. Page location and sentence location are different signals. The practical lesson is that the whole paragraph must carry meaning: lead with the claim, develop it with the condition or mechanism, and finish with the consequence instead of adding filler around one quotable sentence.

    Content that earned citations tended to use definitive language, question-and-answer organization, dense entity information, balanced sentiment, and business-grade clarity. Definitive does not mean absolute. “This platform is the best” is unsupported certainty. “This platform fits distributed teams that require these named controls, but it is unsuitable when these constraints apply” is a clear, bounded claim.

    Entity-rich writing is also different from keyword repetition. Name the company, product, category, audience, location, compatible systems, pricing model, and relevant alternatives where they affect the answer. Then keep those facts consistent across service pages, comparison pages, author information, policies, and structured data. If you use schema, align it with visible page content; do not ask markup to carry positioning or review claims that the reader cannot verify on the page.

    Connect your first-party facts to third-party trust

    A transparent bridge of evidence blocks connects a blue information hub with independent publication, laboratory, community, and library structures.

    Your website is the canonical place to explain what you sell, who it serves, how it is priced, and where it does not fit. It is not the only place an AI system may use to evaluate those facts. In wearable-technology queries, trusted third-party domains appeared more often than brand websites. That is a vertical-specific pattern, not proof that every market behaves identically, but it exposes a risk: a strong first-party explanation may still be outweighed by a better-established external account.

    Information layerIts jobWhat to inspect
    First-party websiteEstablish canonical facts and answer buyer questionsCategory, audience, capabilities, pricing, limitations, policies, authorship, and visible evidence
    Third-party ecosystemCorroborate, compare, review, or contextualize the brandAccuracy, recency, editorial independence, criteria, and conflicting descriptions
    AI responseSynthesize a recommendation for the buyerInclusion, message, omissions, errors, alternatives, and cited domains

    Audit these layers as one information system. Ask representative buyer questions, record the domains cited, and inspect what those pages say about your category and fit. Correct inaccurate pages you control. When a legitimate third-party page contains a material error, use its normal correction process and provide verifiable information. Do not manufacture reviews, disguised placements, or repetitive mentions; they do not create the independent trust you are trying to earn.

    Then look for honest gaps in external coverage. A reputable comparison may lack your category. A directory may use an obsolete description. An industry explainer may need a qualified expert contribution. A customer may be willing to document a real use case. Pursue only opportunities where your information improves the resource for its audience. The useful question is not “Where can we place our brand name?” but “Which independent pages help a buyer verify this claim?”

    Keep the facts synchronized. If your homepage calls the business an AI SEO platform, a service page calls it a content agency, and third-party profiles call it a WordPress plugin, the system has several plausible categories to choose from. Decide whether those are distinct offerings or inconsistent labels, then state the relationship explicitly on the relevant pages.

    Measure inclusion, message quality, citations, and outcomes

    A single screenshot showing your brand first for a favorable prompt is not a visibility report. Build the measurement set from the same buyer-question inventory that drives your content. Include prompts for cost, problems, comparisons, reviews, best-fit recommendations, and disqualifying conditions. Mark whether your brand is genuinely eligible for each prompt before judging the answer.

    For every check, record the platform, exact prompt, buyer intent, eligibility, whether the brand appeared, how it was described, any material error or omission, the alternatives mentioned, and the cited domains. Preserve the prompt wording because a response to a broad category request should not be compared casually with a response constrained by industry, budget, geography, or technical requirements.

    Use the resulting record to calculate and interpret these working KPIs:

    • Eligible inclusion rate: the share of prompts where the brand appeared among prompts for which it was a defensible recommendation.
    • Message accuracy rate: the share of appearances that contained no material category, audience, capability, price, or limitation error.
    • Positioning alignment: whether the response expressed the differentiators and fit conditions in your approved brand description.
    • Citation coverage: whether important claims were connected to accurate first-party or independent evidence rather than left unsupported.
    • Commercial contribution: qualified inquiries, assisted conversions, or customer-reported discovery connected to AI interactions. Add AI assistants as a selectable discovery path where you collect attribution, while allowing the buyer to describe the path in their own words.

    Keep mention position as a diagnostic field, not the primary success metric. If the brand is absent from eligible prompts, investigate answer coverage, entity clarity, discoverability, and external corroboration. If it appears with the wrong description, reconcile positioning and factual inconsistencies. If it appears accurately but buyers do not progress, inspect the offer, fit, proof, and next step rather than producing more visibility content by default.

    Review results by decision category. A healthy inclusion rate for broad educational prompts can conceal an absence from high-intent comparisons. Likewise, a citation win can conceal damaging language about price or suitability. The unit of analysis is the buyer decision, not the total number of mentions.

    Start with the high-intent question that has the weakest current answer. Rewrite its opening, add the missing fit and limitation facts, connect it to credible evidence, and check how the exact buyer question is answered. Record the first discrepancy and fix it at the layer where it originates. Expanding that disciplined pattern across your question map will do more for durable AI visibility than producing another collection of interchangeable keyword pages.

    References