Tag: Ad Optimization

  • Google AI Ads and Sales Lift: A Practical Testing Playbook

    Google AI Ads and Sales Lift: A Practical Testing Playbook

    You have probably seen the headline number: a retailer used Google AI advertising and revenue rose by 80%. The useful question is not whether AI ads can work. It is whether they can produce profitable, incremental sales for your business without weakening measurement or surrendering control of your brand.

    You can answer that question, but not by switching on every automated feature and comparing this month’s revenue with last month’s. Treat AI Max, Performance Max, reusable text rules, and recommendation reporting as separate tools inside a controlled commercial test. That gives you a result you can defend when someone asks what actually caused the lift.

    An 80% lift is a case result, not your forecast

    Google has highlighted Aritzia as having achieved an 80% increase in revenue with AI Max. That is evidence of possibility, not a transferable benchmark. It does not tell you what Aritzia would have earned without AI Max, how much media spend changed, which customers were new, or what happened to margin.

    Revenue lift can come from several places. An advertiser may reach previously missed queries, improve the match between a shopper and a product, spend more, capture demand that another campaign would have converted, or count conversions differently. Only the first two clearly demonstrate better advertising. Additional spend can still be worthwhile, but it is a different claim and should be judged against your allowable acquisition cost.

    Write your expected mechanism before starting. A useful hypothesis is specific: AI Max will find additional non-brand demand for selected products and increase contribution profit without pushing customer acquisition cost above our limit. A weak hypothesis is that AI will increase sales. The stronger version identifies the demand, the product scope, the business outcome, and the constraint.

    Set a budget boundary and stop conditions at the same time. Automation can spend into newly discovered demand quickly. Without a pre-agreed limit, higher expenditure can resemble growth even when each additional order is less valuable. Your own margins, return rates, sales cycle, and cash constraints should determine that limit; a vendor case result should not.

    AI changes matching, but your inputs set its ceiling

    Traditional search advertising starts with keywords chosen by the advertiser. Google’s newer systems place more weight on inferred intent. They assess the retailer’s website and creative assets, interpret a search, and dynamically match products and messages to that context. Performance Max and AI Max are designed to operate within this more intent-driven model.

    The opportunity is clearest in conversational search. Google says queries in AI Mode tend to be two to three times longer, giving the matching system more context. Google also says 15% of daily searches are novel. A rigid keyword list cannot anticipate every new formulation, while an intent model can potentially connect unfamiliar wording with an appropriate offer.

    That does not remove the need for optimization. It moves optimization upstream. The system cannot reliably distinguish two similar products if your pages use vague names, bury the differences, or contradict the creative. It cannot protect a nuanced brand position that has never been translated into operational rules.

    • Clarify the product: Make the product type, variant, intended buyer, availability, price, and material differences easy to identify on the landing page and in the product data you provide.
    • Align the promise: Check that advertising claims, promotions, shipping terms, and calls to action agree with the destination page. Automation can scale a mismatch as easily as it scales a good message.
    • Supply useful creative range: Give the system assets that express different legitimate benefits, use cases, and objections. Cosmetic variations of the same vague claim do not create meaningful choice.
    • Define the sale correctly: Confirm that the primary conversion represents a commercially useful outcome. If low-value actions sit beside completed purchases without a clear hierarchy, more reported conversions may not mean more revenue.
    • Separate brand rules from campaign ideas: Tone, prohibited language, required qualifications, product naming, and legal restrictions should remain stable. Offers and audience-specific messages can change by campaign.

    Google Ads is testing a beta capability that lets advertisers clone approved AI text guidelines from an existing campaign. If it is available in your account, use it to turn recurring brand decisions into reusable instructions. A practical rule set should cover voice, required product terminology, claims the system must not make, promotion wording, and acceptable calls to action.

    Cloning saves setup time; it does not eliminate review. Read the copied rules in the context of the destination campaign. A restriction written for one market, product category, or promotion can be incomplete or actively wrong elsewhere. Assign an owner and version the rules internally so your team knows which guidance was approved and why.

    Build a test that can explain where sales came from
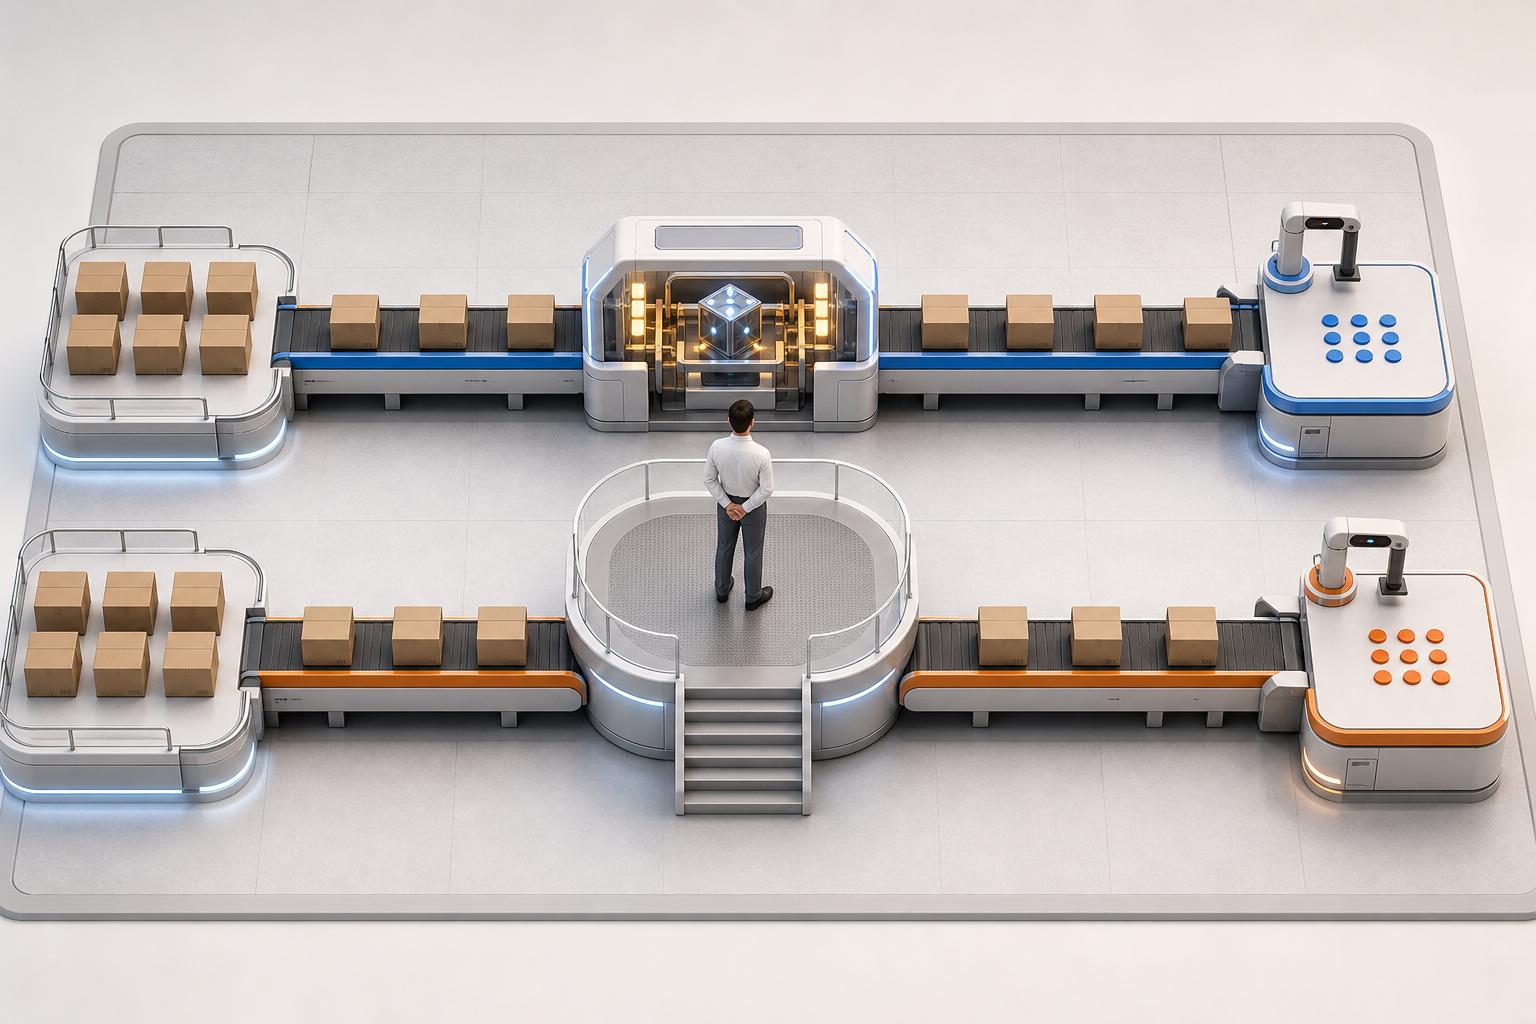
    Two matched groups of product boxes travel through separate treatment and control lanes toward individual checkout stations.

    The main measurement mistake is changing automation, budget, creative, offers, landing pages, and conversion tracking at once. A good result then produces enthusiasm but little knowledge. A bad result creates the same problem because you cannot identify which change failed.

    1. Choose one commercial hypothesis. Name the customer demand you expect AI matching to capture, the products included, the primary business metric, and the maximum cost you will tolerate.
    2. Set a clear boundary. Limit the first test to a defined campaign, product group, market, or customer cohort. Avoid exposing the entire account before you know how the system behaves with your inputs.
    3. Preserve a comparison. Keep a control when account structure and volume permit it. Otherwise, save the pre-change campaign data and identify a comparable product or market that will not receive the change.
    4. Reduce simultaneous changes. Hold pricing, promotions, landing pages, inventory policy, and conversion definitions steady where practical. Record anything that cannot be held steady, including stockouts and major merchandising events.
    5. Allow for conversion lag. Do not declare a winner while one group has had more time to accumulate purchases, cancellations, or returns. Read both groups over equivalent conversion windows.
    6. Review three layers of evidence. Check delivery, customer response, and business value separately. More reach may explain more orders, but only revenue quality and cost reveal whether the expansion was worthwhile.

    At the delivery layer, inspect spend, impressions, click volume, and the kinds of demand being reached. At the response layer, inspect purchases, conversion rate, and average order value. At the business layer, inspect net revenue, contribution margin, new-customer share where you can measure it, cancellations, and returns. A campaign can look strong in the advertising interface while failing the business layer.

    Split branded and non-branded demand in the analysis wherever your reporting allows. AI can appear efficient when it captures customers already searching for your company or products. That traffic may still deserve coverage, but it should not be presented as newly created demand. The same principle applies to returning customers: retained revenue and acquired revenue answer different questions.

    Google Ads has also added a Results tab intended to show the impact of recommendations. Use it to investigate what changed after a recommendation was applied, not as automatic proof that the recommendation caused incremental profit. Platform reporting can identify a useful correlation and shorten diagnosis, but it does not control for promotions, seasonality, inventory, competitor behavior, or sales that another campaign might have captured.

    Key takeaways

    • An 80% revenue increase from one retailer establishes potential, not an expected return for your account.
    • AI Max and Performance Max can interpret demand beyond a fixed keyword list, which matters as searches become longer and more conversational.
    • Clear product information, aligned landing pages, useful creative, and correctly defined conversions are inputs to the system, not cleanup tasks for later.
    • Reusable AI text rules can speed campaign setup, but every cloned rule set still needs market- and product-specific review.
    • Measure incremental business value rather than reported conversions alone. Separate brand demand, returning customers, media spend, returns, and margin.
    • Use recommendation results as diagnostic evidence. Validate causation with a control or the strongest comparable baseline available.

    Scale only after the result survives business checks
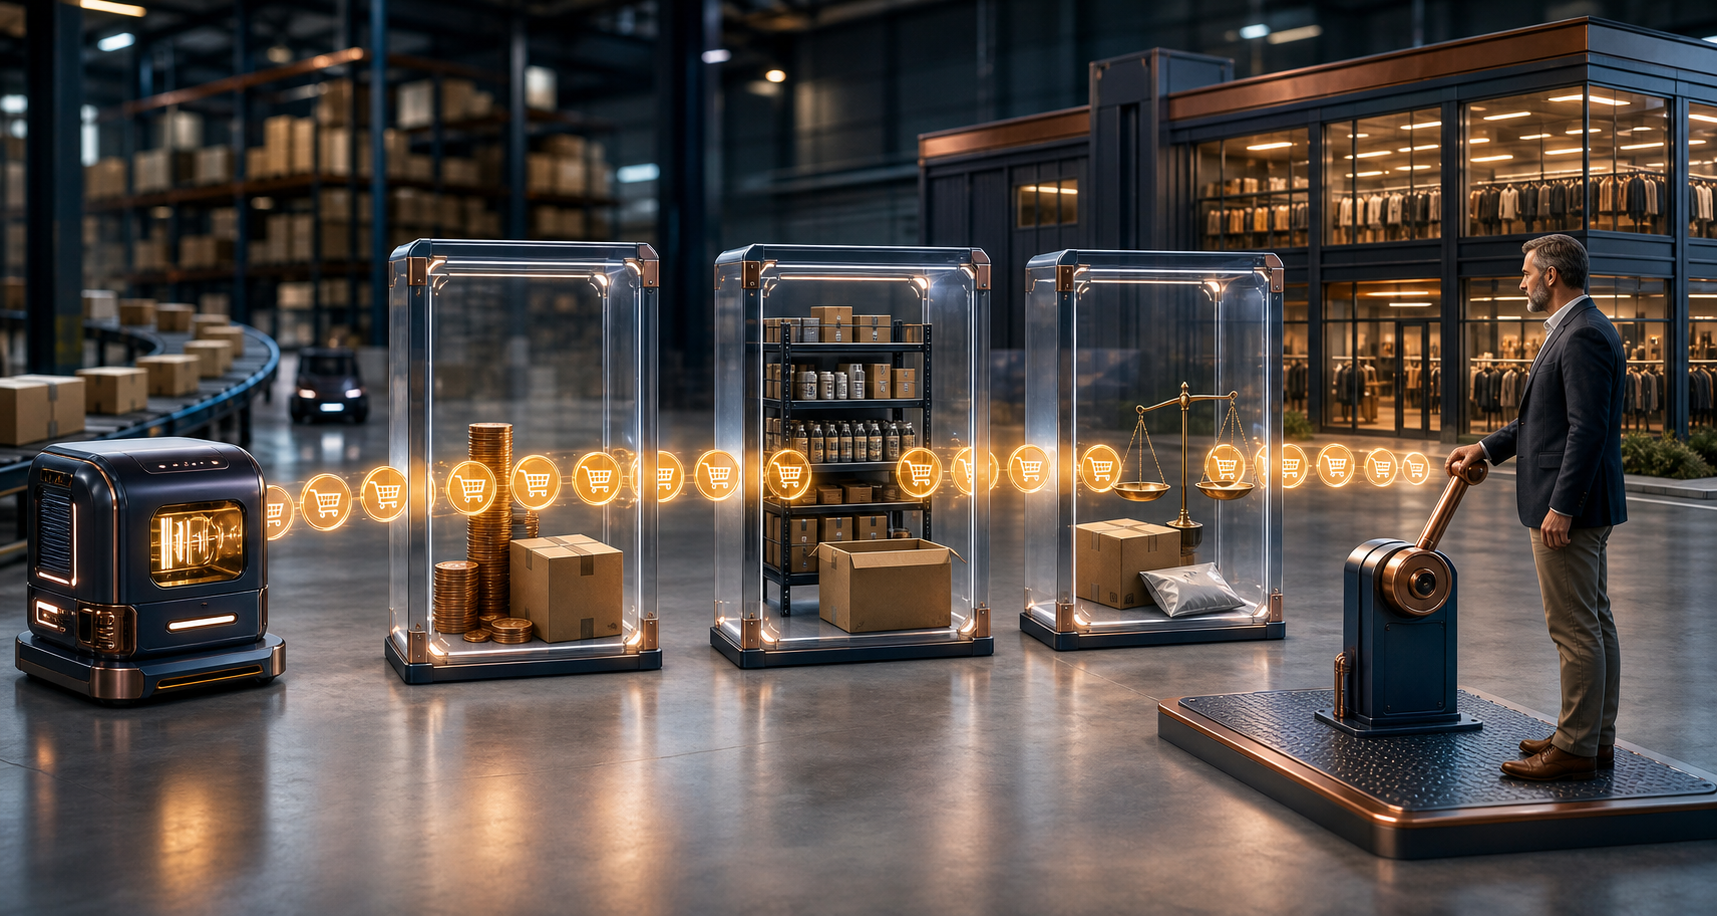
    A stream of purchase tokens passes through margin, inventory, and quality checkpoints before reaching a larger retail network.

    A successful test should answer more than whether sales rose. You should know which products gained, what type of demand expanded, how much spend changed, whether acquisition remained within your limit, and whether the revenue retained its value after discounts, cancellations, and returns.

    Before expanding the campaign, require the result to pass five checks:

    • Incrementality: The gain remains credible after separating branded demand and other traffic the campaign may have absorbed.
    • Economics: Acquisition cost and contribution margin stay within the limits set before the test.
    • Quality: Search intent, generated messaging, landing pages, and purchased products align with the hypothesis.
    • Durability: The outcome is not explained by a short promotion, inventory event, reporting delay, or one unusually strong segment.
    • Control: Brand and compliance reviews find no unacceptable claims, tone, targeting pattern, or customer experience.

    Scale in stages if those checks pass. Expand one boundary at a time, such as the eligible product set or budget, and keep the same business metrics visible. If revenue rises but margin, new-customer acquisition, or message quality deteriorates, pause the expansion and correct the input or objective before spending more.

    Google is also experimenting with personalized direct offers and supporting a broader move toward purchases inside AI interactions through the Universal Commerce Protocol developed with Shopify. Those developments point toward a shorter path from conversational discovery to checkout, but experiments and infrastructure plans are not guaranteed sales. Your immediate advantage comes from making your business legible to intent-matching systems and building measurement that can distinguish a real commercial gain from a persuasive dashboard.

    Start with one bounded campaign. Write the hypothesis, unit-economics limit, brand rules, comparison method, and stop conditions before enabling the change. That single page of decisions will do more for your eventual sales result than adopting every AI feature at once.
    References

  • How to Control Automated Paid Search for Commerce Growth

    How to Control Automated Paid Search for Commerce Growth

    You did not lose control of paid search when platforms automated bidding, audience expansion, and ad assembly. Control moved upstream. The expensive mistake is still managing the account as though a perfect keyword list can compensate for weak conversion data, muddled economics, thin creative, or a poor product page.

    Your job now is to give the system a clear commercial objective, reliable evidence, and firm boundaries. Do that well and automation can explore more demand than a person could manage manually. Do it poorly and it will scale the wrong outcome with impressive efficiency.

    Control the system through the inputs it learns from

    Keywords still matter, but they no longer carry the account on their own. In automated search, keywords function alongside conversion data, first-party audience information, creative assets, and landing-page content. The practical shift is simple: your campaign structure is no longer the whole strategy. It is one part of the training environment you create for the platform.

    That is why an automation feature should never be evaluated only by whether it finds additional conversions. Some AI Max campaigns have been credited with up to 27% more conversions, but that is a reason to run a controlled test, not a forecast you should put into a budget. More conversions help only when they are valid, incremental enough to matter, and economically acceptable.

    Control areaDecision you ownEvidence to inspect
    Business outcomeWhich conversion is primary and how it is valuedCompleted orders, revenue, margin proxy, cancellations, and returns
    Learning dataWhich customer and transaction signals are accurate enough to useDuplicate events, missing values, currency consistency, and match quality
    DemandHow discovery traffic is separated from proven demandSearch terms, product-level sales, conversion rate, ROAS, and ACOS
    ExperienceWhich product information, creative, and destination represent the offerMessage continuity, availability, price, page relevance, and purchase completion
    RiskWhere automation may spend and when a person must interveneBudgets, exclusions, brand traffic, inventory, and unexplained mix changes

    Start with a conversion contract: a short, explicit definition of what the bidding system is supposed to maximize. This is not a tracking implementation document. It is the agreement between marketing, commerce, and analytics about what counts as success.

    1. Name the primary event. For a commerce campaign, that will usually be a completed purchase. Add-to-cart, product-view, and checkout events can remain useful diagnostics without being treated as equivalent to revenue.
    2. Define the value. Decide whether the platform receives gross order revenue, a margin-weighted value, or another consistent commercial proxy. If two orders produce very different contribution margins, equal revenue values may teach the system to prefer the less profitable mix.
    3. Define validity. Document how duplicate purchases, cancellations, refunds, taxes, shipping, and currency are handled. A bidding model cannot infer that an inflated or duplicated value is wrong.
    4. Define the observation window. Review performance only after the normal conversion and reporting lag has had time to mature. Otherwise, recent traffic will look artificially weak and invite unnecessary changes.
    5. Name an owner. Someone must be accountable for detecting broken events, abrupt value changes, and gaps between platform reporting and the commerce system.

    Well-structured first-party data now does much of the strategic work once associated with exhaustive keyword research. It helps the platform distinguish valuable customers and transactions from activity that merely looks busy. But volume does not cure bad measurement. A larger stream of duplicated purchases is still bad data, and automation can magnify its effect faster than a manual bidder would.

    Before expanding automation across the account, validate the contract in a bounded campaign or product group. Changing conversion definitions, bidding targets, audience inputs, and creative at the same time can expose the business to avoidable spend while making the result impossible to interpret.

    Separate discovery from profitable scale

    An exploration area tests many generic products while a gated passage leads selected products into orderly fulfillment lanes.

    Commerce advertising has two jobs that pull in different directions. Discovery needs freedom to test unfamiliar queries, audiences, and products. Performance needs concentration: more budget behind combinations already linked to acceptable sales. Put both jobs in one undifferentiated campaign and the blended result hides what each dollar is doing.

    A stronger architecture creates a deliberate path from exploration to scale. Search environments are especially useful here because shoppers express intent in their queries, while Google Shopping and Amazon Ads can connect that demand to product-level or keyword-level revenue. That creates a feedback loop between search behavior, sales, and budget allocation.

    • Discovery captures uncertainty. It explores a wider set of eligible demand under its own budget and economic limits. Its purpose is to find useful search terms and product-demand combinations, not to look as efficient as a mature campaign.
    • Performance concentrates evidence. It gives proven converters dedicated budgets and targets so they do not have to compete with every exploratory term for spend.
    • Brand protection isolates known demand. Branded searches often behave differently from generic acquisition. Separate reporting prevents strong brand results from disguising weak prospecting.
    • Ranking activity has an explicit cost. If you spend more aggressively to improve visibility or marketplace position, keep that objective distinct from a profit-maximizing campaign.

    The handoff between discovery and performance should use written promotion rules. A term or product is not proven because it converted once, and it should not stay in discovery forever after building credible evidence. Define the minimum evidence your business needs, then test that evidence against four questions:

    • Has the query or product produced enough mature sales to reduce the chance that one unusual order controls the decision?
    • Does its ROAS or ACOS fit the contribution economics of that product after the costs the business actually bears?
    • Can inventory and fulfillment support more demand without creating cancellations or a poor customer experience?
    • Does the landing page or marketplace listing genuinely satisfy the intent that generated the sale?

    Use demotion rules as well. A proven term can return to discovery or lose budget when its economics deteriorate after a mature measurement window, when stock becomes unreliable, or when the offer no longer matches the query. Graduation is a status based on current evidence, not a permanent award.

    Do not impose one universal efficiency target on every layer. Discovery may operate under a stricter spending cap while accepting more variance. A performance campaign may receive more budget but face a firm profitability requirement. Brand and ranking campaigns need their own definitions of success. The crucial point is that each layer has a known job, budget, and exit condition.

    Use platform-specific structures without losing the common logic

    Google Shopping and Amazon Ads can share the same discovery-to-scale strategy, but their campaign mechanics and commercial roles are different. Reproducing the same campaign map on both platforms creates superficial consistency at the cost of useful control.

    Route Google Shopping demand through distinct layers

    A workable Google Shopping structure uses three layers: a branded layer, a catch-all discovery layer, and a dedicated layer for the strongest terms. Campaign priority and other routing controls can then help prevent exploratory demand from consuming the budget reserved for proven opportunities.

    • Branded layer: A shopping-focused, assetless Performance Max campaign can be used to concentrate on shopping inventory and reduce unintended expansion into other channels. Inspect the actual traffic and placement mix rather than assuming the setup label guarantees isolation.
    • Catch-all layer: Keep a wide net for search-term discovery, but contain it with a separate budget and lower bids or a suitably conservative target. Its output is evidence: which queries and products deserve focused investment.
    • Performance layer: Move reliable, high-intent demand into a dedicated campaign where budget and bidding can reflect its demonstrated economics.

    This structure is useful only if routing works as intended. Inspect search terms, product distribution, brand share, and channel mix. If the catch-all keeps taking proven demand, or the branded layer expands beyond its assignment, the labels on the campaigns are not describing the account you actually have.

    Performance Max can also operate alongside AI Max for Search, but overlap should have a reason. Decide which campaign is responsible for known product demand, which is exploring broader intent, and how you will detect duplication or channel substitution. Reach is not automatically incremental growth.

    Organize Amazon Ads around the SKU and the commercial objective

    Amazon gives you a different feedback loop. The shopper is already in a marketplace, reporting can be granular at the product and category level, and ad conversion can contribute to stronger organic position. The practical structure is therefore SKU-level research, performance, and ranking tiers.

    • Research tier: Explore broad keyword possibilities and collect evidence about how shoppers describe the need. Control the downside with a defined budget and ACOS boundary.
    • Performance tier: Concentrate proven converters and manage them toward the product’s profit requirement.
    • Ranking tier: Bid more aggressively only when improving organic position is a deliberate objective and the business has approved the cost of doing so.

    ROAS and ACOS describe the same relationship from opposite directions. ROAS is attributed revenue divided by ad spend. ACOS is ad spend divided by attributed revenue. Neither metric knows your profit. Set the acceptable range from contribution margin after relevant product costs, marketplace fees, fulfillment, discounts, and expected returns. A generic benchmark can make an unprofitable SKU look healthy or constrain a high-margin SKU that could support more growth.

    Higher conversion rates on Amazon can support organic ranking and reduce later acquisition pressure, but do not count that future benefit twice. Keep direct ad economics visible, document when ranking is the primary objective, and check whether organic position actually changes before continuing the extra spend.

    Across Google and Amazon, use the same product economics as the common language. The campaigns may optimize differently, but both should ultimately answer whether the next unit of spend creates acceptable commercial value.

    Make product data, creative, and landing pages part of targeting

    When automation assembles ads and expands matching, every customer-facing input can affect both eligibility and persuasion. Creative is not decoration added after targeting. Landing-page content is not merely the place traffic goes. These assets help the system interpret what you sell, who may want it, and which message belongs with a particular intent.

    Build a message system for each important product group before asking the platform to generate combinations. It should cover:

    • Product identity: What the item is, using the language a qualified shopper would recognize.
    • Use case: The job, occasion, or problem the product genuinely addresses.
    • Differentiator: A factual reason to choose it over a plausible alternative.
    • Proof: Verifiable product details, policies, or other substantiation available on the destination.
    • Offer conditions: Price, eligibility, availability, shipping, or promotional limits that could change the buying decision.

    That framework gives automation useful variety without inviting random claims. It also makes creative testing interpretable. If one asset emphasizes a use case and another emphasizes price, you can learn something from the difference. If every asset changes the product, audience, offer, and tone at once, a winning combination tells you little about why it worked.

    Then audit continuity from query to ad to destination. A shopper who searches for a specific variant should not land on a generic category page and be expected to restart the search. A promotion in an ad should be visible with the same conditions on the page. Product names, images, price, availability, and purchase options should agree across the feed, creative, and destination.

    Landing-page quality matters twice. It affects whether a visitor can complete the purchase, and automated systems can use the post-click experience and page content as relevance signals. Diagnose a weak product group accordingly. The problem may be bidding, but it may also be a page that sends an ambiguous signal or fails to finish the promise made by the ad.

    • Confirm that the destination resolves to the correct product or tightly matched category.
    • Keep price, inventory, variant, and promotion information synchronized with the advertisement.
    • Make the primary purchase action obvious and functional on the devices receiving paid traffic.
    • Remove claims from generated or assembled creative when the destination cannot substantiate them.
    • Separate products with materially different margins, availability, or buying intent instead of forcing them into one undifferentiated asset and bidding group.

    Do not compensate for a weak offer with broader automation. Broader matching can find more people, but it cannot make an unclear product, unavailable variant, or contradictory price more attractive. Fix the commercial experience before paying the system to expose it at greater scale.

    Run a human operating system around the automation

    Four professionals surround a circular control table, reviewing product, creative, storefront, and conversion inputs around an automated sorting mechanism.

    The human role is not to outbid the bidding model one adjustment at a time. It is to decide what the model should learn, recognize when the evidence has become unreliable, and intervene at the level that caused the problem.

    Use a repeatable review loop:

    1. Observe mature performance. Wait for the normal reporting and conversion lag, then compare actual results with the campaign’s stated job.
    2. Locate the failure class. Check measurement, demand mix, product economics, inventory, creative, destination, and campaign routing before changing bids.
    3. Change one class of input. For example, repair conversion values, adjust a budget boundary, refine routing, or replace weak assets. Avoid simultaneous changes that erase causal clarity.
    4. Write the expected effect. Record what should change, which metric should reveal it, what observation window is appropriate, and what would justify reversal.
    5. Promote, hold, demote, or stop. Use the rules established for discovery and performance rather than making a fresh subjective decision every time.

    Not every bad-looking period calls for intervention. Hold when conversion data is still immature and spend remains inside the approved boundary. Change the campaign when mature evidence shows a persistent problem with an identifiable input. Stop or contain it immediately when tracking breaks, spend escapes its guardrail, inventory cannot support orders, or an ad makes an inaccurate claim. Those failures can waste money or harm customers while the model continues optimizing against corrupted conditions.

    Your review should also distinguish a performance change from a mix change. A stable blended ROAS can conceal a shift from new-customer demand toward branded traffic, from high-margin products toward low-margin products, or from direct shopping placements toward less valuable inventory. Look below the account total before calling automation successful.

    Keep an intervention log. For every material change, record the campaign, business reason, affected products, input changed, expected outcome, and rollback condition. This turns account management into an accumulating decision system instead of a sequence of reactions. It also prevents one operator from undoing another operator’s test without knowing why it exists.

    Key takeaways

    • Keywords remain useful signals and diagnostics, but conversion quality, first-party data, creative, and landing pages increasingly determine what automated campaigns learn.
    • Define the primary conversion, its value, its validity rules, and its owner before expanding automation.
    • Give discovery, proven performance, branded demand, and ranking activity separate jobs, budgets, and exit conditions.
    • Use the same discovery-to-scale logic across Google Shopping and Amazon Ads, but adapt the campaign mechanics to each platform.
    • Judge ROAS and ACOS against product contribution economics rather than a generic account benchmark.
    • Let people own measurement, commercial judgment, guardrails, creative truth, and the decision to promote or stop an experiment.

    Start with one meaningful product group. Write its conversion contract, calculate its acceptable economics, identify which traffic is discovery and which is proven, and audit the message from query through purchase. Only then widen automation. If you cannot explain the value entering the bidding system, the system is not ready to scale it.

    References

  • How to Write Clearer ChatGPT Ads That Match User Intent

    Your ChatGPT ad may appear at the exact moment someone is comparing options, checking a price, or deciding what to do next. If the reader has to decode a slogan before understanding the offer, the useful answer around the ad will usually be more compelling.

    Treat the ad as a compact decision aid. Identify the brand, state the relevant benefit, support it with something concrete, and offer one sensible next action. Creativity still matters, but it has to make the decision easier rather than make the message harder to parse.

    Clarity fits the way people use a conversational interface

    A person asking ChatGPT for help is not necessarily browsing for entertainment or waiting to be intrigued. A prompt about pricing, alternatives, features, or suitability can signal that the person is already evaluating a decision. In that setting, the ad competes with an answer designed to be immediately useful.

    That changes the job of the copy. A conventional brand slogan can ask the audience to remember an idea now and understand its relevance later. A conversational ad has less room for that delay. It needs to explain who is speaking and why the offer belongs in this particular decision.

    Across an analysis covering more than 40,000 ChatGPT ad placements, the recurring style was concise, structured, contextual, and oriented toward high-intent users. The dominant headline pattern put the brand before the benefit, often separated by a colon.

    Think of this as paid search translated into dialogue. Relevance is still central, but matching a keyword is not enough. The copy must fit the question behind the prompt and sound like assistance rather than an interruption.

    This does not mean every ChatGPT user is ready to buy, or that short copy wins by itself. The placement observations show useful patterns, not a universal causal rule. Use them as a starting architecture, then validate them against your own audience, offer, and conversion data.

    Give the headline and body one job each

    The observed average headline was about 30 characters and five words. Body copy averaged roughly 116 characters and 19 words. Those are descriptive averages, not known platform limits. Do not remove a necessary condition or qualification merely to hit a character count.

    Use the averages as an editing discipline. If your message cannot fit near that range, the problem may be that the ad is trying to communicate several benefits, answer several objections, or serve several intents at once.

    1. Make the headline identify the choice. Start with [Brand]: [Primary benefit]. The brand tells the reader who is making the offer; the benefit explains why it deserves attention.
    2. Make the first body sentence substantiate the benefit. Use an applicable price, a defensible performance metric, or a precise description of what the offer provides.
    3. Make the second body sentence advance the decision. Ask for one direct action such as Compare, Shop now, or Book.

    The working template is simple:

    Headline: [Brand]: [Benefit]
    Body: [Concrete proof relevant to the prompt]. [Direct next action].

    Write the full, truthful claim before compressing it. Then label every phrase as brand, benefit, proof, action, or necessary qualification. Remove anything that does not perform one of those jobs. This protects the substance of the offer while exposing filler.

    A useful headline test is whether an unfamiliar reader can answer two questions immediately: who is offering this, and why should it be considered? A useful body test is whether each sentence either reduces uncertainty or moves the reader to the next step.

    Mirror the decision, not just the words in the prompt

    Context mirroring is more than repeating a term from the user’s question. You need to identify the decision the person is trying to make, then place the information required for that decision in the ad.

    If someone is comparing options, a broad awareness message is a mismatch even when it contains the right product keyword. If someone is checking cost, an abstract promise of value leaves the central question unanswered. The strongest observed messages reflected the query or conversational environment instead of relying on keyword overlap alone.

    Decision behind the promptWhat the ad should resolveSuitable action
    Comparing alternativesThe brand’s relevant differentiator, supported by concrete evidenceCompare
    Checking affordabilityThe price or priced term that actually appliesShop now, when an immediate purchase is possible
    Checking suitabilityThe capability that matches the stated requirementBook, when evaluation requires a conversation or demonstration
    Reducing commitmentA genuinely free trial or demo and the condition that defines itBook or the most direct available trial action

    Build separate messages for these decisions. One all-purpose ad usually becomes vague because it has to accommodate incompatible questions. A comparison message needs a differentiator. A price message needs a price. A suitability message needs evidence of fit.

    Do not mirror irrelevant details merely because they appear in the prompt. Repeat only the context that changes the recommendation or the next step. The goal is recognition – the reader should see that the offer addresses the task at hand – without producing copy that feels mechanically assembled.

    Use concrete proof and a low-friction action

    Specificity matters because a high-intent reader is trying to reduce uncertainty. Generic claims such as better, smarter, or leading do not provide much material for a comparison. A concrete price or measurable result can.

    Dollar signs and specific numerical claims, including prices and performance metrics, were associated with stronger performance than generic promises. That does not make any number persuasive. The figure must answer the user’s question, apply to the advertised offer, and remain consistent with the destination page.

    • Use a price when price affects the decision. State the applicable amount or pricing term instead of claiming that the offer is simply affordable.
    • Use a performance metric when it can be supported. Preserve the scope and qualification needed to keep the claim accurate.
    • Use a precise capability when no responsible number is available. A truthful, concrete description is more useful than numerical decoration.
    • Use free only when the offer is genuinely low-friction. Make any material limitation, required payment method, or conversion to a paid plan clear at the point where it matters.

    Free trials and demos can lower the commitment required from someone who is still evaluating. The word itself is not the strategy. The strategy is reducing the size of the next decision while accurately explaining what the reader receives.

    The call to action should name that next decision. Direct actions such as Shop now, Compare, and Book fit this format better than a vague Learn more prompt because they tell the reader what will happen next. Choose the verb that matches the destination. Do not use Shop now for a form that merely starts a sales conversation, or Book for a page with no scheduling path.

    Keep the tone calm. Heavy punctuation, inflated superlatives, and rhetorical questions make the ad sound less like useful guidance and more like an interruption. Confidence comes from a clear claim, relevant proof, and an honest next step.

    Test clarity as a message system, not a character count

    The observed averages give you a credible place to begin, but your own testing must determine what converts for your offer. A shorter variant is not automatically clearer. It can also be incomplete. Define the decision your ad must support before deciding which words to cut.

    Key takeaways

    • Put the brand and primary benefit in the headline so the reader can identify the choice immediately.
    • Use the body to provide one concrete proof point and one direct next action.
    • Match the message to the decision behind the prompt: comparison, price, suitability, or commitment.
    • Use numbers and free offers only when they are accurate, relevant, and consistent with the destination.
    • Treat 30 headline characters and 116 body characters as observed averages, not mandatory limits or guarantees of performance.

    A practical testing sequence

    1. Choose one intent group. Start with prompts that represent the same decision. Mixing price research, comparisons, and general discovery can conceal which message actually worked.
    2. Write a specific hypothesis. For example, test whether placing the brand before the benefit improves qualified actions, not whether a broadly different ad is better.
    3. Change one component. Test the headline structure, proof point, action, or contextual wording separately. Keep the offer, destination, and other controllable conditions consistent.
    4. Select the conversion before the test. Use the business action the ad is meant to produce as the primary measure. Treat clicks or other engagement signals as diagnostic measures when they do not represent the final objective.
    5. Inspect post-click quality. A curiosity-driven ad can attract attention without helping the right person act. Check whether the destination behavior supports the same conclusion as the initial engagement metric.
    6. Record the context with the result. Save the prompt intent, copy element changed, offer, destination, and outcome. A reusable lesson is more valuable than an isolated winning variant.

    Avoid changing the headline, proof, offer, and call to action in the same comparison. You may find a winner, but you will not know which decision to carry into the next campaign. Also avoid declaring success from an early fluctuation. Set the sample and decision rule appropriate to your traffic and analytics process before looking at the result.

    Start with the highest-intent prompt category you can identify. Rewrite one ad so the brand, benefit, proof, and action are visible without interpretation, then test whether that clarity improves the action that matters after the click. Expand the pattern only after it proves useful for your audience.

    References

  • Avoid These Costly Google Ads Mistakes for Ecommerce Success

    Avoid These Costly Google Ads Mistakes for Ecommerce Success

    Expanding beyond paid social? Discover how I learned to structure campaigns, control spend, and unlock demand without depending solely on the Meta playbook.

    My paid social campaigns were thriving. I understood my audience intimately, had a tight creative process, and watched results improve each year. Naturally, when leadership proposed expanding into Google Ads, I was thrilled—envisioning it as a new revenue channel.

    But sticking to our existing strategy only led to difficult conversations. Google demands different tactics—intent signals and campaign structures vary, and common budget-draining mistakes aren’t always obvious. Many brands mirroring their Meta strategy end up with flashy dashboards but disappointing balance sheets.

    From my experiences, six frequent mistakes can cause substantial damage before they’re even noticed. They’re what I’ve seen most often with ecommerce brands transitioning to Google Ads—and each error is reversible.

    Mistake 1: Treating Google like a retention channel

    Utilizing Google Ads for retention and brand defense is possible, but relying solely on it as a strategy is problematic. I often notice brands new to the platform diving straight into Performance Max. Initially, the ROAS shines bright, making everyone happy. However, when the right question surfaces—”Are we truly growing or just capturing purchases?”—issues arise.

    For example, a client approached me with branded search and retargeting doing most of the work in PMax—a mere tax on demand already created elsewhere, leading to stagnant revenue. Although ad spend was soaring, growth wasn’t.

    Acquiring new customers requires a different setup, like:

    • Shopping campaigns to highlight products to new audiences.
    • Search campaigns centered on non-branded, high-intent keywords.
    • Layered PMax configurations to bypass defaulting to easy conversions.

    When Google grants vast access to new audiences, focusing solely on closing disregards most of this opportunity.

    Dig deeper: Ecommerce PPC: 4 takeaways that shape how campaigns perform

    Mistake 2: Not knowing how to leverage Google’s core levers

    Although paid social expertise is somewhat transferable to Google, I’ve observed four major gaps. Let me share them with you in more detail.

    Search intent: Social media ads interrupt, but search ads meet users actively seeking your offerings, transforming campaign structure, ad copy, and keyword targeting entirely.

    Data feed optimization: An optimized product feed enhances visibility and targeting in Shopping or Performance Max campaigns.

    Keyword research: Understanding match types and search intent is critical for reach and cost efficiency.

    Landing pages: Engaging landing pages outperform product pages for high-intent but unfamiliar visitors.

    Dig deeper: 7 Google Ads search term filters to cut wasted spend

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    Mistake 3: Allowing operational issues to interrupt campaign momentum

    Consistent data is key for Google’s algorithms. Every unintended campaign pause can reset learning, causing weeks of degraded performance and wasted spend.

    Common disruptions include:

    • Payments: Bill lapses, leading to campaign pauses, overshadow the actual cost when factoring in downtime recovery.
    • Tracking and feed integrity: Broken pixels and feed errors silently degrade performance.

    Setting up automated alerts and regular audits can prevent these costly errors.

    Mistake 4: Overly granular campaign structures

    Detail-oriented advertisers may over-segment campaigns, believing it provides control. However, widespread budget allocation hinders Google’s automation from optimizing effectively.

    Instead, tight, well-funded campaigns optimize better and are more manageable.

    Dig deeper: How to find and fix the root cause of low conversions

    Mistake 5: Leaving campaigns on Max Conversion Value without ROAS targets

    Max Conversion Value aims for conversion volume, neglecting cost efficiency. A realistic ROAS goal encourages the algorithm to maximize efficiency. Setting this correctly is crucial.

    Dig deeper: How each Google Ads bid strategy influences campaign success

    Mistake 6: Underfunding campaigns, keeping them in learning mode

    Underfunding during the learning phase results in indefinite stalled progress. Adequately funding new campaigns from the outset fosters quicker, more accurate results.

    Expanding beyond Meta to include Google is a strategic move, accessing actively expressed demand. These pitfalls aren’t deterrents but guideposts for smoother transitions and optimized strategies.

    For early adopters, start with my guide on expanding from Meta to Google Ads. If seeking further optimization, learn how to sidestep Google’s automation traps.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • ChatGPT Ads Are Expanding: A Practical Marketer Plan

    ChatGPT Ads Are Expanding: A Practical Marketer Plan

    If you control a paid media budget, you now have a decision to make: prepare for ChatGPT advertising, run an early test, or wait until the channel becomes easier to evaluate. The wrong move is treating novelty as proof and shifting budget before you know what success should look like.

    The better move is to build a controlled entry plan. ChatGPT’s ad pilot has produced a meaningful commercial signal, but its limited rollout leaves major questions about inventory, buying controls, measurement and performance. You can prepare for those unknowns without betting your acquisition plan on them.

    The expansion is real, but the early numbers need context

    ChatGPT ads are appearing often enough to become a serious planning issue. The stronger signal comes from the pilot’s economics: it reached more than $100 million in annualized ad revenue within six weeks.

    Annualized revenue is a run rate, not $100 million already collected during the pilot. It projects a short period’s pace across a year. That distinction matters when you assess the maturity of the business. The figure demonstrates advertiser demand and monetization potential; it does not demonstrate return on ad spend for your company.

    The pilot was also deliberately narrow. Ads were shown daily to fewer than 20% of eligible US users on the Free and Go tiers, even though about 85% of those users qualified to receive them. More than 600 advertisers had participated. Those figures imply room for substantially more delivery if OpenAI increases exposure, but they do not tell you how much inventory will become available, how it will be priced or whether it will match your audience.

    OpenAI has said that users classified fewer than 7% of ads as low relevance. Treat that as an encouraging relevance signal, not a campaign-performance benchmark. A user can consider an ad relevant without clicking it, converting or becoming a profitable customer. Your own business outcomes still have to settle the question.

    Key takeaways

    • ChatGPT advertising has moved beyond a purely speculative format, but early revenue does not prove advertiser profitability.
    • Limited exposure creates expansion potential while making historical benchmarks less dependable.
    • Self-serve access lowers the operational barrier to entry; it does not remove the need for a test budget and predefined decision rules.
    • Measure ChatGPT campaigns with site and CRM outcomes, not relevance claims or platform activity alone.
    • Keep paid distribution separate from organic ChatGPT visibility. Buying an ad should not be treated as a way to earn citations or recommendations.

    Write your go-or-no-go plan before self-serve access

    A marketer considers three paths leading to a small ad test, a preparation workspace, and a closed access gate.

    The rollout plan identified an April opening for self-serve advertiser access. It also named Canada, Australia and New Zealand as intended expansion markets. Self-serve access changes who can participate: marketers no longer need to be among a relatively small group working through a managed pilot.

    It does not tell you that a particular geography, format or targeting control is available to your account. Treat every planned market as unavailable until you can confirm access inside the buying interface. Do not put forecasted ChatGPT conversions into a committed revenue plan merely because geographic expansion has been announced.

    Before anyone creates a campaign, write a one-page test brief covering the following decisions:

    1. Choose one commercial job. Decide whether the test is meant to generate qualified visits, leads, purchases, trial starts or another observable outcome. “Learn about ChatGPT ads” is an internal objective, not a business result.
    2. Define the user situation. Describe the problem, constraint or decision that should make your offer relevant. A broad demographic label is not enough. The creative team needs to know what the person is trying to accomplish.
    3. Set a loss ceiling. Fund the pilot from money the business can afford to use for channel learning. Do not remove budget from a revenue-critical campaign unless you have explicitly accepted the resulting demand risk.
    4. Name the economic threshold. Use your own margins, close rates, customer value and sales capacity to determine an acceptable acquisition outcome. An industry average cannot decide whether a customer is profitable for you.
    5. Select one conversion path. Send the visitor to a page built for the promise in the ad. If that page offers several unrelated actions, you will struggle to tell whether the message worked.
    6. Define stop and scale rules. State which evidence permits more spending, which result calls for a creative or landing-page change, and which result ends the test. Make those decisions before campaign data creates pressure to rationalize weak performance.
    7. Assign an owner. One person should reconcile platform activity, web analytics, CRM progression and actual revenue. Without that ownership, each system can appear successful while the commercial result remains unclear.

    You should also inspect the product before committing spend. Confirm the available geographic controls, audience or contextual controls, ad formats, placement disclosures, reporting fields, conversion measurement, exclusions, billing rules and brand-safety options. If a control you require does not exist, narrow the test or wait. Do not assume a mature search or social advertising feature has been carried into a new platform.

    More than 600 advertisers participating in the pilot validates interest in the channel. It does not mean you have already missed the inexpensive phase, nor does early entry guarantee lower acquisition costs. The defensible early-mover advantage is learning: discovering which problems, claims and landing experiences produce qualified behavior before the channel becomes a standard line in every media plan.

    Build creative for a conversation, not a copied search ad

    A search query often compresses intent into a few words. A ChatGPT prompt can contain a goal, constraints, context and follow-up questions. That does not mean an advertiser will necessarily receive the full prompt or be able to target every detail. It means your message has to make sense beside a more developed problem than a bare keyword might convey.

    Do not imitate the assistant’s voice or make paid placement look like an independent recommendation. The ad should be recognizably commercial and useful on its own terms. Its job is to connect a specific situation to a supportable proposition.

    Use a four-part message pattern

    1. Situation: Identify the problem or decision that makes the offer relevant.
    2. Claim: Make one concrete promise you can substantiate. Avoid stacking several product benefits into a single ad.
    3. Reason to believe: Point to the mechanism, evidence or distinguishing fact behind the claim.
    4. Next action: Ask for a step proportionate to the user’s intent, such as reviewing a method, seeing an example, checking eligibility or starting a purchase.

    A practical drafting template is: “For [specific situation], [offer] helps you [supportable outcome] through [clear mechanism]. [Evidence]. [next action].” The brackets force the writer to supply meaning. If the team cannot fill them without vague language, the proposition is not ready for paid distribution.

    Terms such as “innovative,” “powerful” and “next generation” consume space without reducing uncertainty for the reader. Replace them with a visible capability, a documented constraint or a concrete reason to continue. A conversational environment raises the standard for clarity because the surrounding answer may already be specific.

    Make the landing page finish the same thought

    The click is a handoff, not a completed outcome. The landing page should immediately confirm that the visitor has reached the promised destination. If the ad addresses one use case but the page opens with a generic company slogan, the visitor has to reconstruct the connection.

    • Repeat the problem and core proposition near the beginning of the page.
    • Place evidence beside the claim it supports rather than collecting unsupported superlatives in a separate section.
    • Explain important qualifications before the conversion action. Hidden limits may increase form starts while damaging lead quality and trust.
    • Use one primary call to action that matches the commitment requested in the ad.
    • Ensure the page works without the visitor having to understand the preceding ChatGPT conversation.
    • Use accurate structured data only where it describes visible page content. JSON-LD can clarify entities and relationships; it cannot repair a weak offer or guarantee visibility in an AI-generated answer.

    Create a dedicated page when the campaign promise differs materially from your existing page. Do not create a thin duplicate merely to insert the words “ChatGPT” or “AI.” Message match comes from answering the same need, not repeating a channel name.

    Measure paid results without confusing them with AI visibility

    A campaign card passes through two separate measurement lanes, one with budget and conversion objects and another with speech bubbles and connected knowledge symbols.

    A new channel invites two measurement mistakes. The first is accepting platform activity as proof of business value. The second is expecting it to behave like mature search advertising before you understand the context in which its ads are delivered.

    Start with site-side instrumentation you control. A consistent campaign taxonomy might use utm_source=chatgpt, utm_medium=paid_ai and a campaign name tied to the user situation or offer. The exact labels are yours to choose; consistency is what lets analysts separate paid ChatGPT visits from referrals, organic discovery and other paid channels.

    Follow the visitor through an outcome ladder:

    1. Arrival: Did the tagged session reach the intended page?
    2. Engagement: Did the visitor examine the promised material or begin the intended task?
    3. Conversion: Did the visitor complete the primary action?
    4. Qualification: Did the lead, trial or order fit the business’s acceptance criteria?
    5. Value: Did it create revenue, retained usage or another outcome connected to the original commercial goal?

    This sequence prevents a high click count from concealing low-quality demand. It also shows where to intervene. Weak arrival-to-engagement performance points toward message match or page experience. Strong engagement with weak conversion may indicate offer friction. Conversions that fail qualification point toward the audience definition, claim or form design. These are diagnostic interpretations, not automatic verdicts, so check the actual sessions and CRM records before changing the campaign.

    Do not judge the channel on cost per click alone. A cheaper visit is not useful if it produces fewer qualified outcomes, and an expensive visit can still work if it creates enough customer value. Compare channels at the deepest reliable stage available to your business. Where sales cycles prevent an immediate revenue view, label the interim metric clearly rather than presenting it as realized return.

    The claimed sub-7% low-relevance rate belongs near the top of this measurement ladder. It says something about user perception of ad fit. It does not replace your conversion rate, qualified acquisition cost or revenue evidence.

    Keep paid, owned and earned AI discovery distinct

    • Paid distribution buys eligible ad exposure under the platform’s available controls.
    • Owned content gives people and machines a clear, accurate destination for your claims, products and expertise.
    • Earned visibility includes citations, mentions and recommendations that are not purchased as ad placements.

    Do not assume that buying ChatGPT ads improves whether the assistant cites or recommends your brand in an unpaid answer. Treat any such relationship as unproven unless OpenAI documents it. Keep separate dashboards for paid campaign outcomes and organic AI visibility so an increase in one is not casually credited to the other.

    The work can still reinforce itself. Campaign planning forces you to name user problems precisely. Winning landing pages reveal which explanations and evidence help people act. Those lessons can improve product pages, comparison content, FAQs and structured data. If the ad platform exposes contextual or query-level insights, use them within its privacy and reporting limits; if it does not, rely on the post-click evidence you can observe.

    ChatGPT’s expansion into self-serve buying and additional markets gives you a reason to prepare, not a reason to abandon channel discipline. Write the one-page pilot brief now, verify the controls when your account receives access, and launch only when you can trace spend to a business outcome. That puts you in position to learn early without making the rest of your acquisition plan depend on an unproven channel.

    References


  • Google Performance Max Seasonal Theming: A Practical Workflow

    Google Performance Max Seasonal Theming: A Practical Workflow

    Your strongest Performance Max asset group is already doing useful work. A seasonal push creates an awkward choice: change proven creative under pressure, or build another variation from scratch.

    Google’s seasonal theming offers a more controlled route. You can clone an existing asset group, apply a theme to the copy, and review generated image and text variations while the original remains intact. The speed is useful, but the output still needs human judgment. Treat the feature as a production shortcut, not an automatic campaign strategy.

    Know what Google changes – and what it leaves alone

    Seasonal theming starts with assets you already have. It does not redesign the offer, replace every format, or resolve inconsistencies between the ad and its destination. That boundary matters because the generated version can look finished before it is ready to run.

    • Images: Google can reuse existing images and create variations with themed backgrounds. The product, person, or main subject is still inherited from your starting material, so inspect edges, scale, contrast, and composition rather than judging the background alone.
    • Text: The tool can suggest seasonal headlines and descriptions, but the text refresh is limited. Read the resulting assets as a set. A new seasonal headline can still be paired with older language that changes its meaning or weakens the message.
    • Video: Existing videos are not replaced. A winter image set beside an unmistakably summer video is not a minor aesthetic issue; it makes the asset group feel assembled rather than intentional.
    • The original asset group: The unthemed version remains intact. That gives you a safer starting point for experimentation and a clean asset set to return to if the seasonal treatment does not fit.

    The available themes cover promotional treatments, seasons, and specific cultural moments:

    Theme familyAvailable optionsBest planning question
    PromotionalSale; Studio/EditorialIs the message about a real offer, or only a different visual treatment?
    SeasonalWinter; Spring; Summer; FallDoes the season match the market, product use, and destination experience?
    Cultural momentsChristmas; Black Friday/Cyber Monday; Halloween; Valentine’s Day; Easter; Mother’s Day; Father’s Day; Hanukkah; New Year; Lunar New Year; Back to SchoolIs this moment genuinely relevant to the audience and the offer?

    Choose the narrowest accurate theme. A popular holiday is not automatically the right creative frame. If the product, promotion, or audience has no meaningful connection to it, a generic season or editorial treatment will usually be easier to keep coherent.

    Decide whether seasonal theming fits the job

    The feature works best when the campaign strategy is already sound and only the presentation needs to change. Before opening the theme menu, separate a creative refresh from a campaign rebuild.

    Use the shortcut when the underlying message is stable

    • The existing asset group already promotes the right product, audience need, value proposition, and action.
    • The seasonal idea can be communicated through backgrounds and a limited set of text changes.
    • The current video remains suitable, or the concept can tolerate video that is less seasonally explicit.
    • You have someone available to review every generated asset before it can spend campaign budget.
    • You want a variation of a proven concept while preserving the original group.

    Build or edit more manually when the campaign itself changes

    • The seasonal promotion introduces a different product, price, bundle, eligibility rule, or call to action.
    • The concept depends on new video, product photography, illustration, or a sequence that a background treatment cannot create.
    • Your brand system requires precise art direction that generated background variations are unlikely to preserve without substantial correction.
    • The promotion has legal, geographic, inventory, or timing conditions that must be expressed exactly.
    • The cultural moment requires nuance beyond familiar seasonal symbols.

    Access is also a practical constraint. The option can appear within Asset Groups ahead of major holidays, or as Apply theme to existing asset group while you set up a new one. If it is not visible in your account, do not make the launch depend on assumed access. Move to the manual creative route while there is still time to review it properly.

    Move from a proven asset group to a reviewed seasonal version

    An abstract workflow shows a proven advertising asset group being duplicated, seasonally restyled, and sent for human review.

    A disciplined workflow keeps the convenience from becoming a source of accidental claims, mismatched formats, or unclear test results.

    1. Write a one-sentence seasonal brief. Name the customer moment, the exact offer or message, the featured product, and the intended action. If you cannot state those four elements cleanly, generated creative will not solve the underlying ambiguity.
    2. Select the asset group for message fit. A high-performing group is a useful starting point only when its product and proposition belong in the seasonal promotion. Do not clone a winner whose success came from a different category or customer need.
    3. Apply one theme to the cloned version. Keep the first variation interpretable. Combining a holiday treatment, a new offer, a different product emphasis, and a rewritten brand voice makes it hard to identify what helped or hurt.
    4. Inventory what actually changed. List the image variations, new or revised headlines, descriptions, and untouched video assets. This turns a visually impressive preview into an auditable set of changes.
    5. Correct the gaps manually. Rewrite vague text, remove unsupported promotional language, replace unsuitable source imagery, and address video continuity. Generated output is a draft even when individual assets look polished.
    6. Check the destination experience. The landing page should continue the same season, product, offer, and timing. If the ad promises a seasonal sale but the page makes visitors hunt for it, the creative has moved faster than the customer journey.
    7. Launch it as a controlled change. Record the theme, manual edits, offer, destination, and activation period. Where operationally possible, avoid bundling unrelated campaign changes into the same evaluation window.

    Naming discipline helps once several moments overlap. Use an internal label that identifies the base asset group, theme, offer, and version. The label does not improve delivery, but it prevents your team from reviewing or activating the wrong seasonal copy.

    Review the combinations, not just the individual assets

    A reviewer compares a grid of assembled ad variations while individual image and copy components appear in a separate asset tray.

    A generated image can be attractive and still be commercially wrong. The most consequential failure is usually not an obvious visual artifact. It is a polished asset that implies the wrong offer, date, product use, or cultural context.

    Review areaWhat can go wrongWhat to do before launch
    Image fidelityThemed backgrounds create awkward edges, unrealistic scale, low contrast, or a setting that changes how the product appears to be used.Open every variation at a useful size. Check the main subject, logo, text embedded in the image, shadows, edges, and background context.
    Text combinationsA seasonal headline is paired with an older description that contradicts it, dilutes the offer, or changes the intended tone.Read plausible headline-description pairings as complete ads. Rewrite any asset that works only when viewed alone.
    Video continuityUntouched video communicates a different season, setting, product, or promotion from the new images.Supply a suitable video through normal asset editing, or make the overall theme neutral enough that the current video remains credible.
    Offer accuracySale-oriented language implies a discount, scope, or urgency that the business cannot substantiate.Match every promotional phrase against the approved offer. Confirm products, locations, exclusions, availability, and timing before spending begins.
    Landing-page continuityThe ad introduces a seasonal promise that disappears after the click.Verify that the destination visibly supports the same product and offer, and that the next action is immediately clear.
    Cultural fitFamiliar symbols are used for an audience or market where they feel irrelevant, inaccurate, or reductive.Have someone familiar with the intended audience review the treatment. If the context is uncertain, choose a broader seasonal or editorial theme.
    Brand and complianceGenerated backgrounds, language, or urgency fall outside brand rules or required approval processes.Run the cloned group through the same brand, legal, and promotional review used for manually produced advertising.

    Do not approve the group from a single preview. The feature changes only part of the asset set, so quality depends on how old and new elements coexist. The review unit is the complete seasonal asset group.

    Measure the seasonal version without overstating the result

    Seasonal periods change customer demand as well as creative. Better results during Black Friday, Christmas, or Back to School do not prove that the generated theme caused the improvement. Start by defining what success means for this campaign, then interpret performance in that commercial context.

    • Choose the decision metric in advance. Use the outcome that already governs the campaign, such as conversion value, return on ad spend, cost per acquisition, or qualified lead volume. Do not select whichever metric looks most flattering afterward.
    • Document the demand context. Record the promotion, product availability, destination changes, and seasonal period. These factors can move performance independently of creative quality.
    • Keep the claim proportional to the setup. If the original and themed asset groups run concurrently without controlled exposure, treat the comparison as directional. Do not describe ordinary automated delivery as a clean A/B test.
    • Use the available asset-group and asset reporting. Aggregate campaign performance can hide a weak seasonal variation if other assets continue to carry results.
    • Make an explicit post-season decision. Retire event-specific claims when they cease to be true. Preserve notes on the theme, manual corrections, and performance so the next seasonal build starts with evidence rather than memory.

    The original asset group remaining intact is operationally valuable, but it does not make every comparison controlled. Preservation reduces creative risk; measurement quality still depends on what else changed and how delivery was allocated.

    Key takeaways

    • Seasonal theming is best for changing the context around an already-correct message, not rebuilding campaign strategy.
    • Google can generate themed image backgrounds and suggest some seasonal text while leaving the original asset group intact.
    • Video is not replaced, and the text refresh is limited, so old and new assets must be reviewed together.
    • The right theme is the most accurate one for the product, market, offer, and audience – not necessarily the most prominent holiday.
    • A themed clone is not automatically an A/B test. Seasonal demand and automated delivery can affect the comparison.
    • Generated creative should pass the same offer, landing-page, cultural, brand, and compliance checks as manually produced advertising.

    Start with the asset group whose message best fits the seasonal opportunity, write the brief before opening the theme menu, and build the review checklist before anything goes live. If the idea cannot survive the unchanged video or an exact offer check, give it the manual creative work it needs.

    References


  • Performance Max Campaign Controls: A Practical Playbook

    Performance Max Campaign Controls: A Practical Playbook

    You do not need complete control of Performance Max to keep it accountable. You need to know which reports merely describe what happened, which settings impose hard limits, and which inputs steer the automation without guaranteeing an outcome.

    The most reliable approach is to work in that order: verify what the campaign is optimizing for, remove clearly unwanted traffic, apply narrow constraints where the evidence is strong, and then improve the creative, feed, budget, and bidding inputs. That gives you more control without excluding useful demand just because a report looks uncomfortable.

    Key takeaways

    • Campaign-level negative keywords, placement exclusions, ad schedules, demographic exclusions, and device controls are the clearest direct controls available in Performance Max.
    • A report is not automatically a control. Search terms can lead directly to negatives, but placement impressions do not tell you how much a placement spent or whether it produced conversions.
    • Use exclusions for traffic that is demonstrably irrelevant, ineligible, unsafe for the brand, or operationally impossible to serve. Do not use them as a reflex whenever performance is uncertain.
    • Creative assets, product feeds, conversion goals, bids, and budgets steer where automation looks for results. They usually deserve attention before you start narrowing reach aggressively.
    • Record each material change and its reason. If you change negatives, schedules, devices, assets, and bidding together, the next report cannot tell you which decision helped.

    Remove obvious waste with search terms and placement controls

    Geometric traffic signals pass through two filters while unwanted signals are diverted into a separate channel.

    The safest exclusions begin with a simple question: could this traffic ever produce the outcome you want? If the answer is clearly no, blocking it protects the budget. If the answer is merely uncertain, investigate before turning an observation into a permanent rule.

    Turn search-term visibility into a disciplined negative list

    Campaign-level negative keywords can be added from the Performance Max search terms report. This removes much of the friction that once separated finding an irrelevant query from blocking it.

    That convenience makes restraint more important. A query with no recorded conversion is not automatically irrelevant. It may have appeared too infrequently to judge, sit earlier in the buying journey, or suffer from a landing-page or offer problem. Negatives should remove unwanted meaning, not conceal a broader performance issue.

    Use this review sequence:

    1. Group terms by intent rather than reacting to isolated wording. Repeated patterns reveal more than one unusual query.
    2. Separate clearly impossible or irrelevant intent from ambiguous intent. Exclude the first group; investigate the second.
    3. Check whether a candidate negative could also match valuable searches. Use the narrowest exclusion that removes the unwanted concept without cutting into legitimate demand.
    4. Add the negative from the search terms report and record why it was added. A short reason makes later reversals much easier.
    5. Review the effect in the next stable comparison period, allowing for the conversion lag that normally applies to your account.

    Common candidates include searches for a service you do not provide, a product category you do not sell, or an intent that cannot become a qualified customer. A merely expensive term belongs in a different bucket. Before excluding it, check the conversion goal, landing page, offer, and query context.

    Use placement data for suitability before profitability

    Performance Max placement visibility now sits in the campaign’s expanded reporting and exclusion workflow, including the ‘Where ads have shown’ area. The placement report is particularly useful for spotting large volumes of impressions in contexts that do not fit the campaign, such as unintended mobile apps or children’s programming.

    The limitation matters: impression-level placement data is not a placement-level profit-and-loss statement. A placement with many impressions has not necessarily consumed an equivalent share of spend, generated the same share of clicks, or caused the campaign’s overall inefficiency. Treating impressions as cost can lead you to exclude inventory for the wrong reason.

    Placement exclusions are strongest when the decision is about relevance or brand suitability. If a context is plainly inappropriate, an account-level negative placement may be justified. Because that scope can affect more than the campaign you are reviewing, check which other campaigns rely on the same inventory before applying it.

    If the concern is performance rather than suitability, look for corroborating evidence first. Review the campaign’s search intent, channel distribution, assets, conversion goals, and landing pages. The placement report may identify where to investigate, but it does not always identify what to remove.

    Apply time, demographic, and device limits without choking reach

    Schedules, demographic exclusions, and device settings are genuine constraints. They can improve efficiency when they reflect how the business actually operates. They can also starve the campaign when they are used to compensate for weak data, a broken experience, or impatience with normal variation.

    Build an ad schedule around opportunity and operating capacity

    The ‘When and where ads showed’ reporting area provides hour-by-hour information even when the campaign began without a restricted schedule. You can apply a schedule under ‘Campaigns > Audiences, keywords, and content > Ad schedule’.

    Scheduling is most useful when budget is limited and there is a repeatable mismatch between ad delivery and the business’s ability to convert demand. A lead-driven company may struggle to handle inquiries during certain hours. A campaign with a constrained daily budget may spend during weak periods and lose access to stronger periods later. In either case, the schedule should reflect a demonstrated operating constraint, not a single quiet hour in a report.

    Before removing an hour or day, ask three questions:

    • Does the pattern repeat across comparable periods, or is it driven by one unusual day?
    • Was there enough activity to make the absence of conversions meaningful?
    • Could conversion lag, offline follow-up, or the sales process make the hour look weaker than it really is?

    If those checks support the same conclusion, restrict the weakest period first rather than rebuilding the entire week at once. A narrow change preserves more eligible inventory and gives you a cleaner result to evaluate.

    Reserve demographic exclusions for durable mismatches

    Campaign-level demographic exclusions are available under ‘Other settings’. They are appropriate when a group cannot reasonably use or qualify for the offering, or when a consistent body of campaign evidence supports the restriction.

    A weak short-term result is not the same as a durable mismatch. Demographic segments may receive different volumes and enter at different points in the customer journey. If you exclude a segment after a small amount of activity, the campaign loses the chance to learn whether better creative, a different landing page, or more complete conversion data would change the result.

    Use demographic controls as eligibility rules first and optimization rules second. When the decision is performance-based, document the evidence and plan a later review. An exclusion should remain reversible when the underlying audience or offer could change.

    Diagnose the device experience before excluding the device

    Device controls in ‘Other settings’ let you review which devices contribute to campaign goals and decide which devices to include or exclude. This is valuable, but device performance often exposes a site or journey problem rather than an audience problem.

    Before excluding a device, complete the conversion path on that device. Check whether the page loads cleanly, forms are usable, calls work, product information remains legible, and the final action can be completed without friction. If the experience is broken, repair it. Excluding the device may reduce visible waste, but it also hides the defect and abandons otherwise valid demand.

    A device restriction is easier to justify when the offering genuinely cannot be delivered there or when the performance gap persists after the experience and measurement have been checked. Apply the smallest defensible restriction, then monitor whether volume shifts into more valuable inventory or simply disappears.

    Steer channel delivery through assets, feeds, goals, and bids

    Creative, product, goal, budget, and bidding modules feed a central routing system that distributes light across several advertising channels.

    Not every useful lever is an exclusion. In Performance Max, the material you supply tells the system what it can advertise, which formats it can assemble, which customers it should value, and what outcome bidding should pursue. These inputs influence delivery without offering an exact channel allocation switch.

    Creative quality matters because Performance Max can serve across visual inventory including Display, YouTube, and Discover. Generic assets may technically make a campaign eligible for more formats while doing little to communicate the offer. Organize each asset group around one coherent product set, service, audience need, or landing-page promise. When several unrelated propositions share the same creative bundle, weak results become much harder to diagnose.

    AI-generated images and videos can help fill missing formats and create variants, including assets derived from Shopping feed products. They still require human quality control. Before approving an AI asset, check:

    • Whether the product, packaging, proportions, and important visual details remain accurate.
    • Whether text is readable in the expected crop and does not introduce unsupported claims.
    • Whether video motion, transitions, and product rendering remain coherent from beginning to end.
    • Whether the message matches the destination page closely enough that the click does not create a new expectation.
    • Whether the asset is acceptable for every type of inventory in which the campaign may use it.

    The channel reporting view can show where delivery is occurring, but its actionable controls remain limited. If the campaign is appearing in a channel you would prefer to reduce, first inspect the inputs that made that inventory attractive: the asset mix, product feed, conversion goal, bid strategy, and budget. Changing these does not guarantee a particular distribution, but it addresses the logic the campaign is using.

    When the business specifically needs Shopping-focused delivery, a feed-only campaign structure can concentrate the campaign on the product feed rather than supplying a complete cross-channel creative set. That choice trades broader creative reach for tighter inventory focus. Make it deliberately; do not remove assets simply because one channel report looks unfamiliar.

    Conversion goals deserve the earliest inspection. If the campaign is rewarded for shallow actions that do not represent business value, exclusions will not solve the central problem. It will continue finding more of the outcome it was told to value. Make sure the selected goal represents a meaningful result and that different conversion actions are not being treated as equivalent when the business values them differently.

    Bids and budgets are also steering mechanisms. They affect which opportunities the campaign can pursue and how aggressively it can compete, but they cannot repair an irrelevant goal or misleading creative. Fix the instruction before increasing the resources given to follow it.

    Run the controls in a repeatable order

    A control is useful only if you can connect it to a decision. Use one review sequence consistently so that urgent-looking reports do not pull you into random edits.

    1. Record the current conversion goals, bid strategy, budget, schedule, exclusions, asset setup, and feed configuration. This is the baseline against which later changes will be judged.
    2. Confirm that the campaign is optimizing for an outcome the business actually values. Resolve incomplete or misleading measurement before interpreting audience and inventory reports.
    3. Review search terms. Add negatives only for clearly irrelevant or impossible intent, and record the reason for each important exclusion.
    4. Review ‘Where ads have shown’. Use placement exclusions for documented suitability or relevance problems, remembering that an account-level action can affect other campaigns.
    5. Inspect hour-by-hour delivery. Tighten the ad schedule only when the pattern is repeatable and consistent with the way the business handles demand.
    6. Review demographic and device performance. Test whether the apparent gap comes from eligibility, the on-site experience, or measurement before removing reach.
    7. Audit asset groups and feed inputs. Replace generic, inaccurate, mismatched, or low-utility material, and verify every AI-generated asset before it can represent the brand.
    8. Use channel reporting to decide what to investigate. If strict Shopping focus is required, evaluate a feed-only structure; otherwise steer distribution through the available inputs.
    9. Change one control layer at a time where practical. Annotate what changed, when it changed, and what outcome you expected.
    10. Evaluate the next comparable period only after accounting for normal conversion lag. Keep changes that solve the stated problem; reverse those that merely reduce reach.

    Start your next review with the search terms and placement reports, but do not stop at what looks wasteful. Trace each symptom back to the closest controllable cause. One well-supported negative, schedule adjustment, device fix, or asset correction is more useful than a dozen exclusions you cannot later explain.

    References


  • How to Control Paid Advertising Costs Without Killing Growth

    How to Control Paid Advertising Costs Without Killing Growth

    Your click costs are rising, the budget is disappearing faster, and the obvious response is to cut bids or pause anything expensive. That may save cash this week. It can also remove the clicks that were most likely to become customers.

    The number you need to control is not CPC in isolation. It is the amount you pay for a qualified lead or customer within your margin, cash-flow, and growth constraints. Once that ceiling is explicit, you can distinguish a costly auction from a wasteful campaign and act on the right problem.

    Set your cost ceiling from the sale backward

    An unbranded customer parcel and coins are connected through transparent chambers that reduce the available amount toward the advertising end.

    A campaign is not efficient merely because its CPL is below an industry benchmark. A cheap lead that never reaches the sales team is expensive. A high-CPC click that becomes a profitable customer may be entirely acceptable.

    Start by defining exactly what your account calls a conversion. A form submission, a qualified lead, a booked meeting, an approved opportunity, and a sale are different outcomes. If several campaigns optimize toward different definitions while reporting one blended CPA, the resulting number cannot guide a budget decision.

    MetricBasic calculationWhat it helps you control
    Cost per clickMedia spend divided by clicksAuction and traffic-acquisition cost
    Click-to-lead rateLeads divided by clicksOffer, message, landing-page, and form performance
    Cost per leadMedia spend divided by leadsTop-of-funnel acquisition efficiency
    Lead-to-customer rateCustomers divided by leadsLead quality and sales conversion
    Customer acquisition costScoped acquisition cost divided by new customersActual business economics, provided you state which costs are included

    Work backward using your own mature conversion data:

    • Maximum customer acquisition cost: Set this from contribution margin, acceptable payback, retention confidence, and cash constraints. Do not base it on revenue alone. Revenue that disappears into fulfillment costs cannot fund acquisition.
    • Maximum CPL: Multiply maximum customer acquisition cost by your lead-to-customer rate.
    • Maximum CPC: Multiply maximum CPL by your click-to-lead rate. For a direct-purchase campaign, multiply maximum CPA by the click-to-purchase rate instead.
    • Affordable volume: Divide the available budget by the target cost for the outcome you are buying.

    Use completed cohorts, not the newest leads in your CRM. If your sales cycle is still open, recent leads will appear artificially weak. If retention is uncertain, use a conservative customer value rather than borrowing from an unproven lifetime-value forecast. The downside of optimism here is not a reporting error; it is a budget that scales unprofitable demand.

    External benchmarks provide context, not permission to spend. Google Ads click costs reached an average of $5.26 across sectors in 2025, while nearly 87% of industries experienced a year-over-year increase. Legal services averaged $8.58, and some competitive B2B segments reached $8 to $9. Those figures tell you that inflation is widespread. They do not tell you what a click is worth to your business.

    Higher CPC can coexist with stronger economics. Roughly 65% of industries also experienced higher conversion rates. A more expensive visitor who is further along in the buying process can produce a lower CPA than cheaper, low-intent traffic. Judge the complete equation.

    Find which part of the acquisition equation broke

    For a one-step conversion, CPA can be expressed as CPC divided by conversion rate. For a lead-generation funnel, customer acquisition cost is influenced by CPC, click-to-lead rate, lead qualification, and lead-to-customer rate. That decomposition turns a vague cost problem into a specific diagnosis.

    • CPC rose while conversion rate held: Inspect auction pressure, targeting breadth, search-query intent, placements, and bidding behavior. The landing page is unlikely to be the primary cause.
    • CPC held while click-to-lead rate fell: Check whether the ad promise still matches the offer, whether the traffic mix changed, and whether the page or form introduced friction.
    • CPL held while lead-to-customer rate fell: The account may be buying easier conversions rather than better prospects. Review qualification criteria, source mix, and the outcome being returned to the ad platform.
    • Platform CPA held while CRM acquisition cost rose: Audit duplicate events, attribution differences, missing offline outcomes, and the definition of a conversion. The bidding system may be optimizing toward an event that no longer represents business value.
    • Every stage weakened at once: Look for a structural change before making several tactical edits. A new market, altered offer, tracking release, inventory shift, or broad targeting change can affect the entire funnel.

    Run the diagnosis in a fixed order so that a measurement defect does not become a bidding decision:

    1. Validate the primary conversion. Confirm that it fires once, reaches the correct account, and represents the outcome named in the report.
    2. Reconcile advertising data with the CRM. Compare leads, qualified leads, opportunities, and customers by campaign. Return first-party outcomes to the bidding system when the platform and your consent framework support it.
    3. Separate unlike traffic. Split branded from nonbranded search, informational from transactional queries, prospecting from remarketing, and major audience or placement groups.
    4. Use mature cohorts. Allow enough time for the normal conversion and sales lag before declaring recent traffic unprofitable.
    5. Choose one failing stage. Apply the lever closest to that stage, then record the change so its effect is not confused with simultaneous edits.

    Query intent deserves special attention as search-result layouts change. Across 3,119 terms at 42 organizations in a late-2025 analysis, paid CTR on queries displaying AI Overviews declined by 68%, from 19.7% to 6.34%. That result does not establish the same decline for every account, but it identifies a mechanism worth checking: informational searches can expose fewer visible paid placements while satisfying more users directly on the results page.

    Label your search terms by intent rather than treating every keyword in an ad group as equivalent. Move budget away from informational queries that consume spend without producing qualified outcomes. Preserve transactional terms when their downstream CPA remains viable, even if their CPC looks unattractive beside cheaper research traffic.

    Reduce auction pressure you can actually control

    A marketing operator adjusts audience, timing, and creative controls beside a crowded stylized advertising auction.

    You cannot remove every competitor or reverse market-wide CPC inflation. You can decide which auctions to enter, what signal to optimize, how much loss an experiment may incur, and whether another party is unnecessarily raising the cost of your own demand.

    Start with branded search. Affiliates, partners, resellers, and competitors that bid on your trademarked terms add auction pressure to demand your organization already created. Unauthorized bidding can make you pay to generate awareness and then pay again to recover the resulting searcher.

    Do not rely on an occasional search from headquarters. Some unauthorized bidders may use geographic exclusions, device targeting, or schedules outside normal business hours to reduce the chance of detection. Monitor the locations, devices, and times where customers actually search. Preserve the query, ad copy, landing page, date, location, and device as evidence. If contractual or trademark rights are uncertain, route enforcement through the appropriate partner manager or legal adviser rather than improvising a threat.

    Then put guardrails around automated bidding. Auction-time systems can adjust bids using predicted conversion likelihood, but they can only optimize the outcomes and data you provide. If low-value and high-value conversions share the same signal, the system has no reason to prefer the one your finance team values.

    • Separate campaigns with different economics. Products with different margins, lead types with different close rates, and geographies with different service costs should not inherit one blended target merely for convenience.
    • Optimize toward the deepest reliable outcome. A qualified or completed outcome is more useful than a plentiful form event, provided you can send it back consistently and with enough timeliness to guide bidding.
    • Cap experimental exposure before launch. State the maximum spend or loss you will accept while testing an audience, query class, offer, or format. A budget is a risk boundary, not evidence that every dollar must be spent.
    • Write the stop rule in advance. Stop when tracking is invalid, the test reaches its loss limit, or a mature cohort remains above the economic ceiling. This prevents a weak campaign from surviving because the team has already invested in it.
    • Change one primary variable at a time. A simultaneous bid, audience, creative, and landing-page change may improve results, but it will not tell you which control worked.
    • Scale on qualified economics. Do not increase budget solely because the platform reports a cheaper conversion. Confirm qualification and downstream movement first.

    Manual bidding is not automatically safer, and automation is not automatically efficient. The right choice is the one that lets you enforce the campaign’s economic boundary while supplying a trustworthy conversion signal. The budget, target, exclusions, and outcome definition still belong to you.

    Make the offer absorb part of the cost pressure

    On paid social, cost control often begins before the auction. A weak offer forces the bidding system to buy more impressions and clicks to produce each lead. A useful, timely offer can raise response without requiring the cheapest inventory.

    A focused LinkedIn test illustrates the point. The campaign targeted about 54,000 B2B marketing decision-makers with a 23-page demand-generation playbook timed to the 2026 planning cycle. A document ad let people preview the material, and an autofilled lead form reduced the work required to download it.

    The campaign used a $600 lifetime budget and a $15 manual bid ceiling. It produced 60 qualified leads at less than $10 per lead, with an average CPC of $5.41 and a 76% lead-form completion rate. This was one controlled B2B campaign, not a universal LinkedIn benchmark. Its useful lesson is the relationship among audience knowledge, timing, content depth, previewability, and form friction.

    Build that relationship deliberately:

    1. Find the expensive problem before creating the asset. Mine customer questions, sales objections, client interactions, CRM notes, and audience behavior for a problem specific enough to support one clear promise.
    2. Match the offer to a decision window. A planning resource is more useful while the buyer is planning. Timing is part of relevance, not merely a scheduling setting.
    3. Show evidence of value before asking for data. A preview, concrete contents, or a precise explanation of what the buyer will be able to do reduces uncertainty around the exchange.
    4. Keep the ad and asset on the same promise. If the ad attracts curiosity that the asset does not satisfy, clicks may rise while form completion and lead quality fall.
    5. Ask only for fields you will use. Every required field adds friction. If a field does not affect routing, qualification, personalization, or follow-up, remove it.
    6. Define qualified before launch. Agree on the roles, company characteristics, need, or downstream action that makes a lead valuable. Report both raw CPL and qualified CPL.
    7. Use feedback to revise the offer. The first launch should reveal which sections people value, which questions remain unanswered, and whether the promised problem was important enough to justify follow-up.

    Do not copy the visible details mechanically. A 23-page asset is not better because it has 23 pages, and a $15 ceiling will not recreate a $5.41 CPC in another auction. Copy the operating logic: narrow audience research, a substantial answer to a current problem, low conversion friction, bounded spend, and qualification beyond the platform form.

    This is also where paid advertising and organic authority can support each other. The questions that earn qualified paid responses can inform deeper public content, structured explanations, and answer-ready pages. The purpose is not to disguise an ad as organic content. It is to reuse verified audience language so that your paid, search, and AI-discovery work answer the same real buyer need.

    Key takeaways

    • Set maximum CAC, CPL, and CPC from contribution economics and mature conversion rates, not an external CPC benchmark.
    • Treat CPC as a diagnostic input. The decision metric is the cost of the deepest trustworthy outcome your business can measure.
    • Decompose rising acquisition cost into auction cost, post-click conversion, qualification, and sales conversion before changing bids.
    • Separate branded, informational, and transactional traffic so cheap low-intent clicks cannot hide the value of higher-intent demand.
    • Protect branded auctions, improve first-party conversion signals, and impose test budgets and stop rules before spending begins.
    • On paid social, use audience-specific timing, a genuinely useful offer, and a low-friction path to improve qualified CPL without depending on cheap clicks.

    At your next account review, open the last complete conversion cohort and add three columns to the campaign report: the maximum allowable cost, the qualified conversion rate, and the downstream customer result. Split brand from nonbrand and high intent from informational traffic. Then choose the single stage with the largest economic gap and change the control closest to it. That is how cost control becomes a repeatable operating system instead of a recurring budget cut.

    References