Tag: Ad Innovation

  • How to Test Google Ads Visual Creative in Local Search

    How to Test Google Ads Visual Creative in Local Search

    If you advertise physical locations, Google’s local video experiment puts a practical decision in front of you: prepare visual assets now, or wait until the format is more established and rush production later. You don’t need to gamble your local budget or commission a polished brand film to get ready.

    The useful move is to build a small, reusable creative system around proof of place. Show what a nearby customer needs to see, connect each asset to the correct location, and test it against business outcomes. That approach remains valuable even while access to the emerging placement is uncertain.

    Local video should prove the place, not merely promote the brand
    A camera operator films the entrance, counter, staff, and customers inside an unbranded neighborhood cafe.

    Google has been testing video ads inside the local pack through an immersive, map-style experience. This puts paid visual creative in a context where the user is already comparing nearby businesses. The format is still preliminary, and its performance against conventional local ads hasn’t been established.

    That context changes the creative brief. A general brand montage may look polished but still leave the local decision unanswered. Your video should help the viewer confirm that this is the right place, understand what is available there, or feel confident about the next step.

    Give each asset a clear local job:

    • Confirm the place. Show a recognizable exterior, entrance, sign, storefront, or other accurate location detail.
    • Reduce arrival friction. Show the approach, parking arrangement, reception area, pickup point, or check-in process when that information matters.
    • Demonstrate the local offering. Show the product, service, equipment, room, menu item, or experience that is actually available at the advertised location.
    • Set an honest expectation. Let the viewer see the environment they will encounter rather than substituting generic stock imagery.
    • Support the next action. Align the ending with the action you want the customer to take, such as calling, booking, ordering, requesting directions, or visiting.

    Don’t force every job into the same edit. A short asset focused on finding the entrance can be more useful than a compressed tour of the brand, building, staff, services, offers, and history. If the customer uncertainty is specific, the creative answer should be specific too.

    Write the local promise before you choose footage

    Use a brief that can fit on a small card. Complete these fields before opening a production tool:

    • Search situation: What is the nearby customer trying to find or decide?
    • Question to answer: What uncertainty could stop that person from choosing this location?
    • Visual proof: What real image or sequence resolves that uncertainty?
    • Destination: Where should the ad send the person, and does that page continue the same promise?
    • Business outcome: Which available action or conversion will tell you the creative helped?

    A useful brief might be as simple as showing a first-time visitor where to enter and then sending them to that location’s booking page. It doesn’t need a cinematic concept. It needs continuity from search, to image, to arrival or conversion.

    Keep that promise location-specific. If footage shows the flagship branch’s amenities while the ad is attached to a smaller branch, the creative may win attention by creating an expectation the business can’t meet. Treat location accuracy as part of ad accuracy, not as a final production check.

    Make the location connection part of creative QA
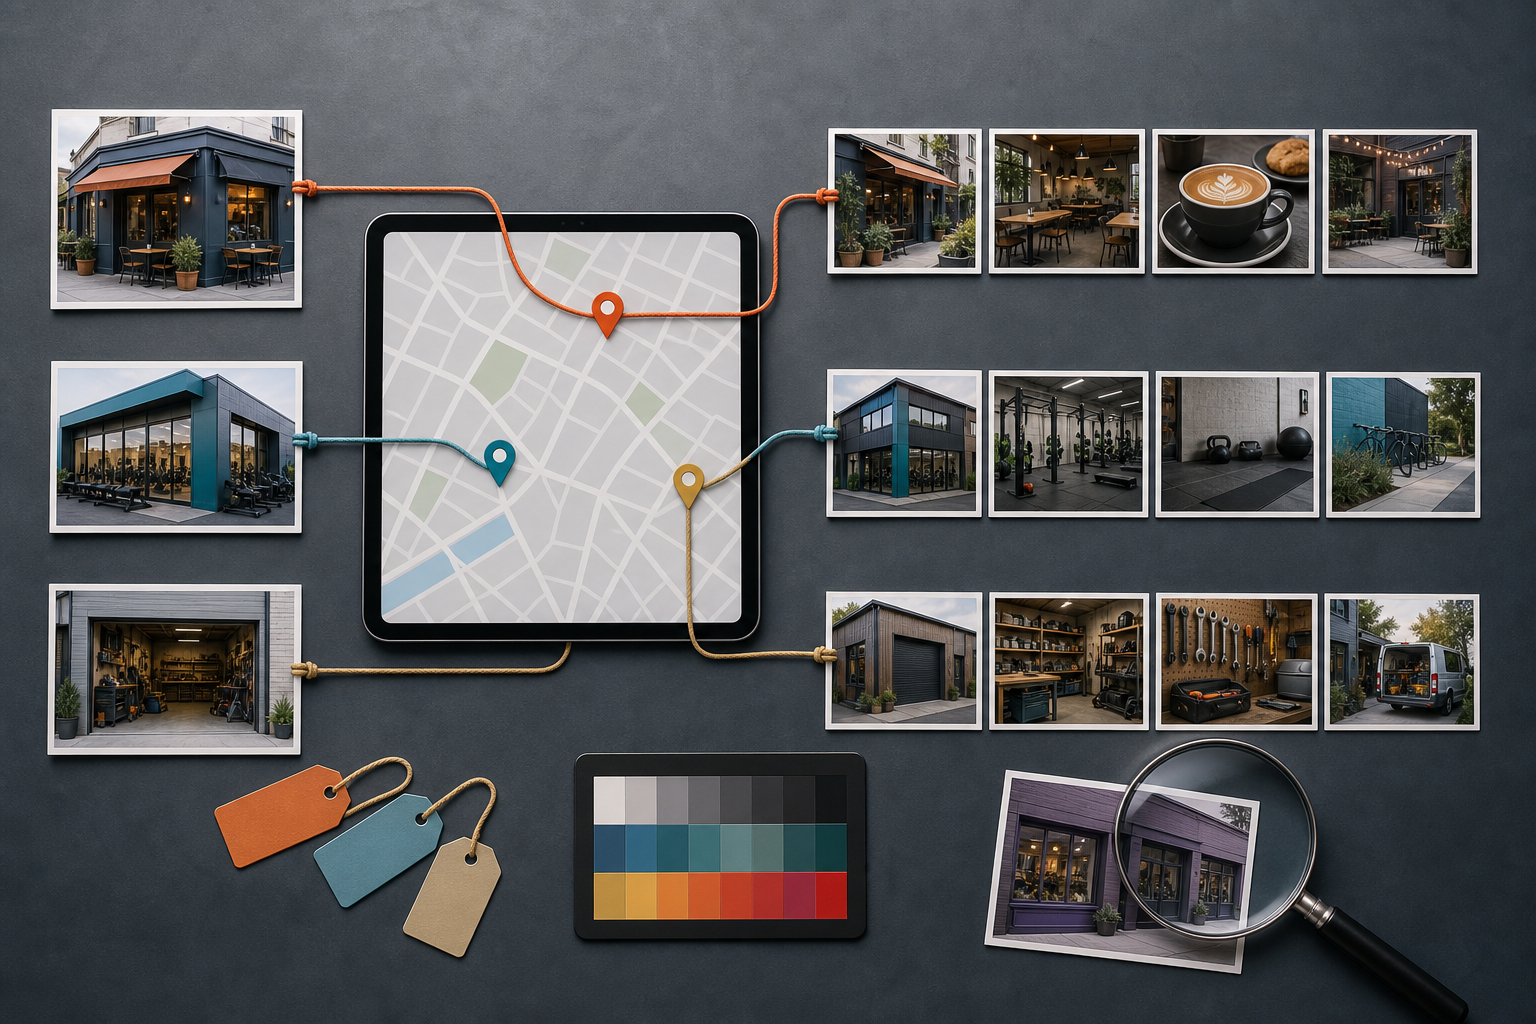
    Business photo thumbnails are connected by colored cords to matching pins on a generic map, while one mismatched image is set aside for review.

    The reported implementation appears connected to Google Ads Location Manager and may involve a pre-opted control in the Shared Library. Because the placement is experimental, you shouldn’t assume that uploading a video makes an account eligible, that every account exposes the same controls, or that an asset will appear in the local pack.

    Before changing a setting or adding assets, create a record of the current configuration. That gives you a clean way to distinguish a creative change from an account or location change.

    1. Document the existing setup. Record the location groups, business identities, campaigns, Location Manager configuration, and relevant Shared Library controls already in use.
    2. Map every asset to a physical location. Use a naming convention that includes the location, the creative job, and the version. A filename such as a generic video final is almost impossible to audit later.
    3. Verify visible facts. Check signage, entrances, products, services, prices, offers, opening information, and amenities represented in the creative. Remove anything that isn’t true for the linked location.
    4. Inspect the destination. The landing page should name or clearly represent the same location and make the intended local action easy to complete.
    5. Check the scope before enabling anything. If a control is already selected or its reach is unclear, determine which campaigns and locations it can affect before changing it across the account.
    6. Preserve a change log. Note when assets and settings were added, removed, or replaced so later performance shifts can be interpreted responsibly.

    An unfamiliar pre-enabled setting isn’t a reason to switch the entire account on or off. Use the smallest reversible scope the interface allows, and confirm which locations are included. The downside of a mismatched local ad isn’t merely a weaker click-through rate. It can send a customer toward the wrong branch, offer, entrance, or service.

    Also separate inventory from eligibility. Having an approved video in the account means you have an asset available; it doesn’t prove that the experimental local format served it. If delivery doesn’t occur, investigate placement access, campaign configuration, location linkage, and asset status before declaring the creative ineffective.

    Build a production system that survives Asset Studio’s limits

    Google Ads Asset Studio, available through Google Ads > Tools > Asset Studio, can manage visual assets and turn supplied images into video variations. AI-assisted features such as Veo and Nano Banana can make simple animation and versioning more accessible when you don’t have a full production workflow.

    Speed is not the same as direction, though. Asset Studio has shown limited scene-level control, errors involving face-like content, and constrained audio choices without custom-track uploads. Those constraints matter most when your concept depends on exact motion, a human performance, precise pacing, or a distinctive soundtrack.

    Use the tool as a production lane, not as the owner of your creative strategy. Decide what must be shown before generating anything, and choose the production route according to how much control the idea requires.

    Creative requirementRecommended starting routeWhat to verify
    Simple motion from accurate location or product imagesAsset Studio template or AI-assisted generationSigns, architecture, product details, sequence, and location identity
    Exact scene order, movement, or pacingA manually edited masterEvery required shot survives the final placement treatment
    Human-led demonstration or testimonialApproved original footage, with Asset Studio used only where the input is acceptedIdentity, consent, facial integrity, gestures, and spoken claims
    Custom music or a tightly timed audio conceptExternal production or editingAudio rights and whether the visual story remains understandable without relying on the score
    Fast variations of a stable conceptAsset Studio trimming, templates, or image-to-video toolsEach version still represents the same location and offer accurately

    Keep the master assets modular

    Start with a library of accurate source material rather than a single finished video. Capture or collect the exterior, entrance, arrival path, interior, product or service detail, staff activity where appropriate, and a clean ending image. Label every file by location and keep its usage approval with it.

    Then storyboard the sequence outside the generator. This can be plain language: establish the place, show the relevant proof, and support the next action. The storyboard becomes your acceptance test. If a generated version changes the order, invents a feature, deforms a sign, alters a product, or obscures the local proof, reject it rather than trying to justify the output after production.

    Keep original images and edited masters outside Asset Studio as well. A modular library lets you rebuild the ad when placement requirements change, a location is renovated, an offer expires, or the generator can’t reproduce an acceptable version. It also prevents the generated file from becoming the only surviving copy of your creative.

    If the available audio choices don’t fit, simplify the concept instead of attaching unsuitable music. The visual sequence should communicate the local point on its own. If sound is central to the idea, move that concept into a workflow that gives you the necessary audio control.

    Test business outcomes, not the novelty of video

    Performance for the emerging local format remains unclear, while easier production can create more assets than a team can evaluate responsibly. The right question isn’t whether Asset Studio produced a video quickly. It is whether the creative improved conversions, sales, or another meaningful campaign outcome without compromising accuracy.

    Set up the test so you can make a decision when the data arrives:

    1. State a local hypothesis. Describe the customer uncertainty and why the proposed visual proof may resolve it. Avoid a circular hypothesis such as video will perform better because it is video.
    2. Choose the primary outcome in advance. Use a local action or business conversion your existing setup can measure, such as an eligible call, booking, order, qualified lead, store action, or sale. Don’t select the winner afterward based on whichever metric happened to rise.
    3. Preserve a comparison. Keep a suitable existing asset or campaign state as a control where account settings allow it. If Google selects assets automatically and the format can’t be isolated, annotate the introduction date and describe the result as directional rather than causal.
    4. Change one creative idea at a time. Test proof of entrance against proof of service, for example, rather than changing the footage, destination, offer, audience, and bidding setup together.
    5. Read results by location when locations differ. A pooled average can hide a useful asset at one branch and a misleading one at another.
    6. Review quality alongside performance. Check the served or approved asset for visual errors, outdated facts, mismatched locations, and promises the destination doesn’t support.

    Use the pattern in the data to decide what to inspect next:

    • No meaningful delivery: investigate eligibility, settings, campaign scope, location linkage, and asset status before revising the creative concept.
    • Delivery without useful interaction: inspect the opening image, local relevance, clarity, and whether the asset answers a real customer question.
    • Interaction without a local action: inspect the gap between the visual promise, landing page, offer, and conversion path.
    • A higher click-through rate without better business outcomes: treat the video as attention-getting, not proven. Don’t scale it on clicks alone.
    • Better business outcomes with accurate creative: expand carefully to comparable locations, then verify that the result holds rather than assuming every branch will respond the same way.

    Production efficiency is still useful. Templates, trimming, and image-to-video generation can lower the effort required to reach a testable asset. But the time saved in production should be reinvested in location verification, experiment design, and outcome review. Otherwise, automation simply helps you publish weak creative faster.

    Key takeaways

    • Treat local video as proof of place: answer a nearby customer’s practical question with accurate visual evidence.
    • Audit Location Manager, Shared Library controls, campaign scope, and location-to-asset mapping before enabling an unfamiliar format.
    • Use Asset Studio when the concept can tolerate template and generation constraints; use controlled production when exact scenes, faces, pacing, or custom audio are essential.
    • Keep source images and masters modular, labeled by location, and available outside the generation tool.
    • Separate lack of delivery from creative failure, especially while the local placement remains an early test.
    • Choose winners by conversions, sales, or another preselected business outcome, not by novelty or click-through rate alone.

    Start with the location where you can verify the visual promise, destination, and business outcome most cleanly. Build one focused brief, prepare accurate source assets, and document the account state before launch. That gives you a controlled pilot without betting the wider local program on an unproven placement.

    References


  • YouTube Unskippable Ads on TV: What the 90-Second Test Means

    YouTube Unskippable Ads on TV: What the 90-Second Test Means

    You are planning or reviewing a YouTube campaign, and a 90-second unskippable break on a television sounds like either premium attention or an expensive way to irritate viewers. The reality is narrower: YouTube has been testing longer ad blocks for some viewers using TV devices, with the skip option delayed for roughly 90 seconds and, in some reported cases, even longer.

    That does not make 90 seconds the new rule for every YouTube impression. It also does not mean you should immediately commission a 90-second commercial. First separate the viewing device, the length of the ad break, and the length of any individual ad. Those are three different decisions.

    What the 90-second timer actually tells you

    Three television screens show different fictional commercials connected by one continuous visual progress indicator.

    The documented behavior concerns the period before a viewer can skip an ad block. Some TV viewers have waited as long as 90 seconds for that control to appear, while individual reported blocks have sometimes run beyond 90 seconds. Because the behavior is described at the ad-block level, you should not assume that one advertiser receives a single, uninterrupted 90-second placement.

    The phrase “YouTube TV ads” can also cause confusion. The test concerns YouTube watched on television devices. It is not, on the available evidence, a platform-wide change limited to or defined by the separate YouTube TV service. Initial observations were concentrated on TVs rather than mobile phones or desktop computers.

    What you observeWhat you can reasonably concludeWhat you should not assume
    A skip countdown approaching 90 seconds on a TVYou may be seeing the longer ad-block testEvery YouTube viewer now receives a 90-second unskippable ad
    Several ads before the skip control appearsThe timer may represent a combined breakOne advertiser owns the entire interval
    The break appears on a short videoThe test is not tied only to long-form contentThe video’s length determines the ad load
    The same behavior is absent on mobile or desktopThe experience may be specific to TV-device deliveryYour account, connection, or television is necessarily malfunctioning

    Reports have found the format on both shorter and longer videos. That matters when you diagnose what happened. A long break before a short clip is not proof that the video’s creator selected that ratio, and a long video is not a reliable predictor that the test will appear.

    Why YouTube is treating the living-room screen differently

    A television is not simply a larger phone. It is usually a lean-back viewing environment, often watched from across a room and sometimes shared by several people. YouTube can therefore package TV-screen viewing more like traditional television inventory: longer breaks, greater room for brand storytelling, and a prominent full-screen placement.

    For advertisers, the attraction is the combination of TV-like inventory with digital targeting and measurement. That can make YouTube more relevant to budgets previously reserved for conventional television. It does not make the format right for every objective.

    Give TV-device inventory serious consideration when your campaign needs broad visual reach, your creative works without an immediate click, and your reporting can separate television delivery from mobile and desktop performance. Be more cautious when success depends on a fast site visit, a small-screen interaction, or a direct comparison with highly clickable placements.

    The practical mistake is to treat all YouTube impressions as interchangeable. If TV-screen delivery is strategically important, give it its own hypothesis, creative review, and reporting view wherever your account data permits. Otherwise, aggregate campaign results can conceal whether the television portion added useful reach or merely added completed impressions.

    Build a TV campaign without confusing forced exposure with attention

    A media planner observes a test viewer who looks at a phone while a fictional commercial continues playing on a television.

    An unskippable placement guarantees an opportunity to be seen for a period of time. It does not guarantee that the viewer welcomed, understood, or remembered the message. Use that distinction to shape the campaign before you increase spending.

    1. Write a device-specific hypothesis. Define what television delivery is meant to add, such as incremental reach or stronger brand response. “More completed views” is not enough on its own when viewers cannot skip.
    2. Keep ad-break length separate from creative length. A timer approaching 90 seconds does not establish that advertisers have been given one 90-second commercial. Maintain a strong shorter edit, especially because 30-second unskippable formats are already part of YouTube’s TV-style approach. Only produce a longer version when the story genuinely needs it and the placement supports it.
    3. Review the creative from across a room. Use readable text, uncomplicated frames, and clear product or brand identification. Let sound improve the message, but do not make audio the only way to understand it.
    4. Set exposure guardrails. Use the frequency and sequencing controls available for your campaign type. Prepare more than one creative treatment when the campaign will run repeatedly. A longer break makes repetition more noticeable, not less.
    5. Measure more than completion. Pair delivery metrics with the business signal the campaign is supposed to influence. Depending on the tools available to you, that could include incremental reach, brand-lift evidence, branded search behavior, or downstream conversions. Treat an unskippable completion as proof of delivery, not proof of persuasion.
    6. Choose a tolerance signal before launch. Monitor frequency, creative fatigue, negative feedback, or another relevant indicator alongside your primary outcome. Decide in advance what would cause you to rotate creative, reduce exposure, or stop the test.

    This last step matters because early viewer reaction has been largely negative, with some people considering ad blockers or third-party viewing apps. That response does not prove the inventory is ineffective, but it does expose the central risk: purchased visibility can rise while willingness to pay attention falls.

    Do not use the skip timer as your proxy for engagement. If brand response remains flat while forced exposure and repetition climb, the campaign has not become more persuasive. It has only become harder to avoid.

    Questions about YouTube’s unskippable TV ads

    Are all YouTube ads on TVs now unskippable for 90 seconds?

    No. The available information describes a test affecting some TV-device viewers, not a universal rule for every viewer, video, market, or campaign. Treat a 90-second countdown as evidence of the tested experience, not evidence of a complete platform rollout.

    Is this specifically a change to the YouTube TV service?

    Not on the available evidence. The reported distinction is based on viewing through television devices rather than mobile or desktop. “YouTube on TV” and the separate YouTube TV service should not be used interchangeably when you document or analyze the change.

    Does a 90-second countdown mean one commercial lasts 90 seconds?

    Not necessarily. The documented experience is an extended ad block before skipping becomes available. That interval may contain more than one ad, so advertisers should not turn the countdown into a creative specification without confirming the placement they can actually buy.

    Why can the long break appear before a short video?

    The initial test was not tied consistently to video length. It appeared with both shorter and longer content. Do not use the duration of the selected video to predict whether a long unskippable block will appear.

    Before your next media plan is locked, label this correctly as a TV-device ad-block test. Keep a strong shorter creative cut, isolate TV-screen results where possible, and define both a success signal and a viewer-tolerance signal. That plan remains useful whether YouTube retires the test, keeps it limited, or expands it to more viewers.

    References


  • Google Ads AI Video: A Practical Workflow for Better Creative

    Google Ads AI Video: A Practical Workflow for Better Creative

    If your Google Ads account has plenty of product images but little usable video, Veo gives you a practical way to close that gap. You can turn existing visual assets into short YouTube ads without waiting for a conventional production cycle.

    The useful question isn’t whether AI can make a video. It can. The question is whether you can give it the right inputs, catch the wrong outputs, and measure the result without confusing generated creative with video your team produced. This workflow covers all three.

    What Veo changes inside Google Ads

    Veo reduces the smallest viable video project. Inside Google Ads Asset Studio, you can upload as many as three static images and generate a video of up to 10 seconds. The model adds motion, and customizable templates help turn the result into an ad suitable for YouTube.

    That is a meaningful capability, but it is a narrow one. Veo is well suited to a concise product demonstration, a visual benefit, or a single promotional idea. A 10-second output is not a substitute for a customer story, a detailed explanation, or a campaign concept that depends on dialogue and multiple narrative beats.

    Treat the tool as a creative multiplier, not a strategy generator. It can add movement to an idea you have already clarified. It cannot decide which customer problem matters, which claim is credible, or what the viewer should do next.

    The accompanying Nano Banana integration expands the editing layer. You can change backgrounds, adjust text, and tailor creative for different audience interests. That makes iteration faster, but each edit still needs the same brand, product, and claim review you would apply to work from a designer.

    Choose images that give the model a clear job

    An unbranded travel cup is photographed from multiple angles in a tabletop studio with a camera and soft lighting.

    The quality of the source images determines how much ambiguity the model must resolve. A clean product shot with an obvious foreground, stable proportions, and a plausible type of movement gives it a constrained problem. A dense collage with several focal points, embedded copy, and conflicting perspectives gives it several problems at once.

    Before uploading anything, score each candidate image against these criteria:

    • One unmistakable subject: A viewer should know what the ad is about without studying the frame.
    • Clear separation: The product, person, or focal object should be visually distinct from the background.
    • Plausible movement: You should be able to describe what could move in one sentence, such as a package rotating, fabric flowing, or a camera pushing toward a product.
    • Consistent product details: Packaging, colors, proportions, and visible features should agree across the images.
    • Minimal baked-in text: Important copy is easier to inspect and revise when it is handled as an ad element instead of being embedded in a busy image.
    • Enough visual space: Leave room for template copy, branding, or a call to action without covering the subject.
    • Accurate context: The setting must not imply a use, feature, size, or outcome the product cannot support.

    Do not upload three images merely because three are allowed. Every image should have a role. One might establish the product, another might show the relevant detail, and a third might place it in context. If two images contradict each other or compete for attention, use the stronger one and remove the ambiguity.

    Clean consumer-product imagery is a particularly sensible starting point. Early testing shared by Ameet Khabra indicated that brands with clean images and an obvious logic for movement may benefit most. That is an early practitioner observation, not a universal performance rule, so use it to select an initial test rather than to predict a result.

    Build a repeatable generation and review workflow

    Two creative team members compare generated product-video frames and inspect them for visual inconsistencies against a physical travel cup.

    Generating first and deciding what the ad means afterward produces a folder of clips, not a campaign. Write the creative brief before opening Asset Studio, even if the brief is only four lines.

    1. State the audience and problem. Name the person the ad is for and the single situation that makes the product relevant. Avoid a broad label such as “all shoppers.”
    2. Choose one promise. A short video rarely has room for a feature list. Select the one benefit the viewer should retain after the clip ends.
    3. Define the visible action. Describe what should move and why that movement helps communicate the promise. Motion should reveal, demonstrate, or focus attention; it should not exist only to make the image look active.
    4. Select up to three source images. Give each image a purpose, remove weak duplicates, and confirm that the product details agree across the set.
    5. Generate a restrained baseline. Start with the simplest version of the concept. A conservative baseline is easier to evaluate than an output containing simultaneous background, text, pacing, and visual-style changes.
    6. Create one deliberate variant. Change one meaningful element: the input image, the setting, the visual emphasis, or the template treatment. Do not change everything at once.
    7. Use Nano Banana for controlled edits. Swap a background or adjust the copy only after the core motion works. Treat each edit as a new creative that must pass review.
    8. Label the asset before launch. Put the concept, generation method, and variant in the name. A structure such as product, benefit, Veo, and variant number will be more useful later than a filename such as “final-video-3.”

    Inspect the output as an ad, not as a novelty

    Watch the generated clip several times with a different purpose on each pass. First judge the message. Then inspect the product. Finally, check every frame that contains copy, branding, or a transition.

    • Product identity: Does the same product remain recognizable from beginning to end?
    • Shape and scale: Do proportions stay stable as the camera or object moves?
    • Packaging and text: Are labels, logos, prices, and claims legible and accurate?
    • Physical behavior: Does the movement make sense for the material and setting?
    • Background integrity: Do shadows, reflections, edges, and contact points agree with the new environment?
    • Message hierarchy: Can a viewer understand the product, benefit, and next action without pausing?
    • Landing-page continuity: Will the person who clicks find the same product, offer, and promise on the destination page?

    If the product changes shape, the label mutates, or the setting creates a false impression, reject the output. A polished transition does not compensate for a misleading frame. When the defect affects the central subject, a new generation from a clearer image is usually a sounder decision than layering more edits onto the mistake.

    Separate creative testing from generation method

    AI-generated video creates two questions that are easy to collapse into one: did the creative idea work, and did the generation method help? You need to preserve the origin of each asset if you want to answer either question.

    Google Ads API v23.2 adds a VideoEnhancement resource that can distinguish Google-generated video from advertiser-provided video. If your team maintains a reporting pipeline, update the relevant client library and code before building analysis around that distinction. A dashboard cannot recover creative provenance later if the pipeline never captured it.

    Keep a corresponding field in the creative log used by marketers. Record the asset name, source images, generation method, concept, edited element, campaign, and launch status. The API classification tells you where a video came from; the creative log tells you what hypothesis it was meant to test.

    Run tests that lead to a decision

    Begin each test with a sentence that can be proved wrong. For example: “A product-in-use image will communicate the benefit more clearly than an isolated pack shot.” Then preserve everything you reasonably can except the element named in that sentence.

    • To test the generation method: Compare Google-generated and advertiser-provided videos with comparable messages, audiences, offers, and destinations.
    • To test an input image: Keep the template and message stable while changing the source visual.
    • To test a background: Keep the product, copy, and motion concept stable while changing only the setting.
    • To test a message: Keep the visual treatment stable while changing the benefit or call to action.
    • To test a template treatment: Use the same source images and promise, then vary the presentation rather than the underlying idea.

    Choose the campaign goal and evaluation metrics before launch. Do not declare a winner because one clip looks smoother or receives an early burst of delivery. Judge it against the action the campaign is intended to produce, and document the decision so the next generation builds on a finding rather than restarting the experiment.

    Google Ads AI video FAQ

    Can Veo replace a conventional video production?

    It can replace a narrow production task: turning up to three still images into a short, template-assisted video ad. It does not replace concept development, complex storytelling, accurate product demonstration, brand review, or footage that must document a real person, place, or event. Use it where the format matches the job.

    What should you test first?

    Start with a product that has clean photography, a single focal point, and an easily described motion concept. Generate one restrained baseline and one controlled variant. That pair will teach you more than a batch of unrelated outputs because you will know what changed.

    Do you need Google Ads API v23.2 to create Veo videos?

    No. Creation happens in Asset Studio. API v23.2 matters when you operate custom reporting and need programmatic visibility into whether a video was generated by Google or supplied by the advertiser. Teams that rely only on interface reporting can still adopt the same discipline by labeling assets and maintaining a creative log.

    Your next move should be small and auditable: choose one image-rich product, write one clear promise, generate a baseline plus one variant, and record the origin of both assets before they enter a campaign. That gives you a usable ad and a test you can learn from.

    References


  • How to Test Emerging High-Intent Advertising Channels

    How to Test Emerging High-Intent Advertising Channels

    You probably don’t need another place to buy impressions. You need access to moments when a buyer is already narrowing a choice: which product to trust, which offer is worth acting on, or which nearby business to visit.

    Reddit’s expanding shopping formats and the prospect of sponsored listings in Apple Maps create two very different ways to reach those moments. The practical question isn’t which channel sounds newer. It is whether the user’s decision, your conversion path, and your measurement system line up well enough to justify a controlled test.

    Start with the decision your customer is trying to make

    A high-intent channel places an ad inside an active decision. That is more useful than simply finding an audience with the right demographic profile, but it doesn’t automatically make every impression valuable. You still need to identify the decision being made and the distance between that decision and revenue.

    On Reddit, the valuable moment is often product investigation or validation. A shopper may already know the category but still be comparing alternatives, checking whether a claim holds up, or looking for reassurance from people with relevant experience. Reddit reports that shopping discussions increased 40% over the previous year and 84% of shoppers felt more confident after browsing the platform. Those are platform-supplied figures, so treat them as evidence of the use case rather than a forecast for your campaign.

    Apple Maps would capture a different decision. Someone searching a map is often choosing where to go, which nearby provider fits the need, or whether a location is practical. The proposed advertising model would allow retailers and brands to bid on search terms and appear as sponsored businesses in Maps results. That could put an advertiser close to a local action, but the channel should remain on your watchlist until Apple confirms availability, eligibility, targeting, reporting, and market coverage.

    The simplest distinction is useful: Reddit can influence what someone chooses, while a map can influence where someone goes. Before assigning budget, complete this sentence: “When the ad appears, the customer is deciding whether to _____.” If the blank contains only “notice our brand,” you haven’t established a high-intent use case.

    • For ecommerce, name the product decision: compare, validate, switch, replenish, buy a bundle, or respond to a deal.
    • For local campaigns, name the destination decision: visit, call, book, order, request directions, or confirm that a location can meet the need.
    • Define the next observable action. A vague goal such as engagement will not tell you whether the channel reached the intended decision.
    • Identify existing demand that could be recaptured by the ad. A branded map query or a loyal customer’s repeat purchase may look efficient without creating incremental revenue.

    Match the channel to your conversion geometry

    Two contrasting customer paths show online shoppers moving from a discussion to checkout and a mobile user following a map route to a storefront.

    Channel selection should follow the shape of your business. Reddit’s shopping tools are built around products, catalogs, visual context, social proof, and offers. A map-based auction would be built around queries, locations, and local actions. Those aren’t interchangeable forms of intent.

    Channel opportunityDecision momentStrongest initial fitCritical dependencyUseful outcome
    Reddit Dynamic Product and Collection AdsProduct discovery, comparison, validation, or deal evaluationEcommerce businesses with a maintained catalog and products that benefit from explanation, context, or community discussionAccurate product feed, functioning conversion measurement, suitable creative, and relevant product economicsIncremental orders and contribution margin from the exposed product set
    Proposed Apple Maps sponsored listingsSelection of a nearby business, retailer, service, or destinationBusinesses with physical locations or genuinely local conversion pathsAccurate location records, a fast route to calling or booking, store-level measurement, and confirmed platform accessIncremental qualified local actions and revenue attributable to participating locations

    Reddit is the clearer near-term candidate when revenue depends on a product catalog and buyers actively seek peer context. Collection Ads combine a lifestyle image with purchasable product tiles, while community and deal overlays can add platform-native proof or price information. That combination is most useful when the context helps a buyer choose among products; it is less compelling if your catalog is thin, your feed is unreliable, or the purchase requires no meaningful evaluation.

    Apple Maps is the stronger planning candidate when location is part of the conversion itself. A restaurant, clinic, retailer, repair service, or other location-based business can plausibly benefit from appearing while someone chooses a destination. An online-only business with no local fulfillment path would have a much weaker reason to prepare.

    Do not choose between them by comparing audience size or headline ROAS. Ask where your buyer experiences uncertainty. If the uncertainty is “Which product should I trust?”, test a product-research environment. If it is “Which nearby business should I use?”, prepare for a map environment. If neither question describes your customer, these channels may be interesting without being relevant.

    Make your data launch-ready before you buy traffic

    New ad inventory can be inexpensive because competition is limited. It can also be expensive to learn on because integrations, reporting, and optimization patterns are immature. The best early-mover advantage is operational readiness: you can run a clean test while other advertisers are still repairing feeds, location records, landing pages, and attribution.

    Prepare a product system for Reddit

    Reddit’s Shopify integration is intended to simplify catalog and pixel setup for Dynamic Product Ads, but it was described as an alpha-stage integration. Alpha status matters. It can imply limited access, changing behavior, or incomplete workflows, so don’t make the integration a dependency until your account is eligible and the setup works with your catalog.

    Before launching, inspect the records that determine which product can be shown and what happens after the click:

    • Use stable identifiers for products and variants so ad events can be reconciled with orders.
    • Check that titles distinguish products clearly without relying on internal naming conventions.
    • Verify that price, availability, destination URL, product image, and variant information agree across the feed and landing page.
    • Separate products with materially different margins, return patterns, or discount sensitivity. Revenue can hide a poor product-level result.
    • Confirm that view, product, cart, checkout, and purchase events occur in the expected sequence and do not fire twice.
    • Build creative around the buyer’s unresolved question. A lifestyle image should supply context, not merely duplicate the product tile.
    • Document which discounts are intentional before enabling deal-oriented messaging. An automated price signal can accelerate a bad promotion as easily as a good one.

    Community labels and deal overlays may reduce hesitation, but they should not carry the entire sales argument. The landing page still needs to answer the questions the ad raises: what the product is, who it suits, how variants differ, what it costs, and what the buyer should do next.

    Prepare a location system for Apple Maps

    Apple Maps sponsored listings remain a reported advertising plan, not inventory you should assume is universally available. Preparation should therefore concentrate on reusable local-search assets rather than speculative campaign settings.

    • Create a canonical record for every location: business name, category, address, phone number, operating hours, URL, and available services.
    • Assign ownership for temporary closures, holiday hours, relocations, and duplicate records. Stale location information wastes paid clicks and damages trust.
    • Give each location a destination page that helps the visitor complete a local action rather than dropping everyone on the home page.
    • Map non-branded local needs to eligible locations. Keep branded or navigational queries separate if the eventual campaign controls permit it.
    • Decide how calls, bookings, orders, visits, and store revenue will be connected to campaign exposure before spending begins.
    • Record your current store-level baseline. Without it, a future lift can be mistaken for seasonality, a promotion, or normal location variance.

    Do not design a detailed Apple Maps bidding structure around controls that Apple hasn’t confirmed. A keyword list, location inventory, conversion taxonomy, and baseline dataset are portable. Assumptions about match types, reporting windows, auction controls, or optimization goals are not.

    Keep ad data, page content, and structured data aligned

    Your advertising feed, visible page content, analytics events, and structured data should describe the same product or location. For products, align identifiers, variants, price, availability, currency, and canonical URLs. For locations, align the business identity, address, phone number, hours, service area, and destination URL.

    This is where SEO, AEO, GEO, and paid-media operations meet: not through a magical ranking shortcut, but through a shared factual layer. When the feed advertises one price, the page shows another, and Product markup exposes a third, performance diagnosis becomes needlessly difficult. The same problem appears when a local ad leads to an outdated location page.

    Treat Schema.org markup as data hygiene, not as an ad-auction lever. Unless a platform explicitly documents a connection, don’t promise that Product or LocalBusiness schema will create eligibility, improve ad rank, or lower media costs. Its practical value here is consistency, machine-readable context, and easier auditing across the discovery journey.

    Run an incrementality test, not a launch celebration

    An analyst observes two matching glass test environments, with campaign light applied to one group and the other kept neutral as a control.

    Emerging channels produce noisy early results. Tracking may be incomplete, algorithms have less account history, and a launch can coincide with promotions or seasonal demand. A narrow test protects your budget and gives you a better chance of learning what caused the result.

    1. Write a falsifiable thesis. Name the audience context, the decision moment, the promoted products or locations, the expected action, and the economic reason the channel could work.
    2. Choose a bounded test cell. Use a defined product group, location group, market, or campaign period rather than exposing the entire business on day one.
    3. Create a comparison. Depending on volume and operational constraints, use a matched product set, comparable locations, a geographic holdout, or a stable pre-test baseline. Document promotions and other media changes that could contaminate it.
    4. Set a budget cap and loss limit before launch. New inventory is not permission to spend indefinitely while waiting for optimization. The downside is real media cost plus the opportunity cost of staff time and promotional margin.
    5. Use a measurement window that reflects the actual buying cycle. Don’t force a local same-day action and a considered ecommerce purchase into the same evaluation rule.
    6. Evaluate incremental economics. Separate revenue that likely would have occurred anyway, especially branded queries, existing-customer purchases, and navigational searches.
    7. End with a decision. Scale, revise, pause, or reject the channel based on the original thesis. Avoid extending a weak test merely because the platform is new.

    Treat platform benchmarks as hypotheses

    Reddit reported that its Dynamic Product Ads generated 91% higher average ROAS year over year in Q4 2025. It also associated Collection Ads best practices with an 8% ROAS improvement. In the Liquid I.V. example, Dynamic Product Ads represented 33% of the brand’s Reddit revenue and outperformed other conversion campaigns by 40%.

    Those figures justify a test case, not a budget forecast. They combine platform-level reporting and a named advertiser example, neither of which tells you your likely incrementality, margin, product mix, audience saturation, or creative quality. Put them in the planning deck under “why investigate,” not under “expected result.”

    Read profit alongside ROAS

    ROAS divides attributed revenue by ad spend. It does not account for gross margin, discounts, returns, fulfillment, agency costs, or sales that would have happened without the ad. A channel can post attractive ROAS while destroying contribution margin.

    For ecommerce, compare incremental revenue with product margin, promotional cost, returns, and media spend at the product-set level. For local campaigns, connect qualified calls, bookings, orders, or visits with store-level revenue wherever your systems and consent framework allow it. If offline revenue cannot be connected reliably, say so in the result rather than replacing it with clicks.

    Watch branded demand separately. A sponsored result that intercepts someone already searching for your exact business may be useful defensively, but it is not equivalent to acquiring a new customer. Your report should distinguish demand creation, decision influence, and demand capture.

    Key takeaways

    • Reddit and Apple Maps represent different intent moments: product validation versus local destination selection.
    • Reddit is actionable for suitable ecommerce advertisers; Apple Maps should remain a prepared watchlist opportunity until launch details and access are confirmed.
    • Choose a channel by the customer’s unresolved decision and your measurable conversion path, not by novelty or audience size.
    • Repair catalog, location, event, landing-page, and structured-data inconsistencies before paying to amplify them.
    • Use vendor benchmarks to justify investigation, never to predict your own ROAS.
    • Judge the test on incremental contribution and qualified business outcomes, with branded or existing demand reported separately.

    Your next move is small and concrete. Write one channel thesis, choose one product or location cohort, audit the data that cohort depends on, and define the comparison you will use. If those four pieces don’t hold together on paper, keep the budget. If they do, you have a test worth running when the inventory is available.

    References


  • Google Video Ad Changes: What Advertisers Should Do Next

    Google Video Ad Changes: What Advertisers Should Do Next

    Your video plan now has two moving parts. Google Ads is giving you a clearer view of video inside Performance Max, while YouTube is testing an ad experience that may keep a brand visible after a viewer skips. One affects what you can measure. The other may affect what people continue to see.

    You don’t need to rebuild every campaign in response. You do need to separate observation from causation, audit whether your creative still works when the full video is not watched, and make budget decisions with more discipline than a single reporting split can provide.

    Two video changes require two different decisions

    Google Ads has added an “Ads using video” segment to Performance Max reporting. It lets you separate results according to whether video was used in the ad mix. That makes video easier to investigate without changing how the campaign itself is managed.

    YouTube is also testing a sticky branded banner that can remain after a viewer skips an ad. Instead of disappearing with the skipped video, the advertiser’s card stays visible in the player until the viewer dismisses it.

    These developments should not be folded into one vague “video is becoming more important” conclusion. The Performance Max segment is a reporting change. It helps you diagnose where video is associated with results. The YouTube experiment is a format change. If it expands, it could alter the creative value of a skipped impression.

    That distinction determines your next move: use the first change to improve analysis, and use the second to pressure-test creative. Neither one, by itself, justifies an immediate budget increase.

    Use the Performance Max segment as a diagnostic, not a verdict

    An analyst examines a video performance tile with a magnifying lens while it remains connected to audience, budget, and conversion evidence.

    The new segment answers a useful descriptive question: how do results differ when video is part of the ad mix? It does not answer the causal question: how much incremental performance did video create?

    That difference matters because campaigns or reporting rows can vary for reasons unrelated to format. Budget, products, offers, audience signals, seasonality, conversion setup and campaign maturity can all influence the result. Performance Max also automates delivery, so the advertiser is not holding every placement and exposure condition constant.

    Use this reporting workflow before you change creative or move spend:

    1. Write down the decision you are trying to make. “Should we expand video assets in this campaign?” is useful. “Is video good?” is too broad to test.
    2. Choose the business outcome before looking at the split. Use the campaign’s actual objective, such as qualified conversions, conversion value, cost per acquisition or return on ad spend.
    3. Apply the “Ads using video” segment and compare video-associated results with the relevant non-video results.
    4. Check whether the compared rows share the same campaign objective, conversion configuration, date range, market, offer and product mix. Treat a mismatch as a confounding factor, not a minor footnote.
    5. Read volume and efficiency together. More conversions at an unacceptable acquisition cost are not automatically an improvement. Better efficiency on negligible volume may not support expansion.
    6. Record the observation, your explanation for it and the smallest action that could test that explanation. Add a review date so the result does not become an unsupported permanent rule.

    What common result patterns should trigger

    • If video-associated results show stronger volume and acceptable efficiency, verify that the comparison is reasonably like-for-like. Then expand video in a limited, clearly identified set rather than across the account at once.
    • If volume rises but efficiency weakens, decide whether the marginal acquisition cost still fits your economics. Do not call the result a win solely because the conversion count is higher.
    • If efficiency improves but volume falls, inspect whether delivery is too limited to support a reliable operational decision.
    • If there is little difference, check whether the creative carries a distinct message and whether video was used enough to make the comparison meaningful. A flat result does not prove that format never matters.
    • If video-associated results are worse, inspect the offer, landing-page continuity and comparison conditions before blaming the video asset. The segment identifies a pattern; it does not isolate the cause.

    The safest budget rule is simple: do not move material spend on the strength of an observational split alone. Use the segment to find a promising hypothesis, then make a bounded change whose downside your account can absorb. This is especially important when a reporting difference could actually reflect a different product, audience or period.

    Design for a skip that may no longer end exposure

    A hand dismisses a video on a smartphone while a smaller tile with the same unbranded product silhouette remains visible at the screen edge.

    A skippable ad has traditionally created a clean mental boundary: the viewer skips, the video disappears and attention returns to the chosen content. A persistent branded card changes that boundary. The viewer may reject the video while still receiving a lighter, static brand exposure.

    This remains a test, so do not treat it as a universal YouTube format or redesign your entire asset library around it. Instead, use it as a reason to check whether your advertising can survive partial attention.

    Audit each active video in three passes:

    1. Watch only the opening portion. Can a viewer identify the brand, product category or problem being addressed without waiting for the full narrative?
    2. Pause on the clearest branded frame. Does the identity remain understandable as a compact visual, or does it depend on motion, narration or a later reveal?
    3. Review the destination and call to action. If a viewer engages after only partial exposure, will the landing page immediately confirm the same brand, offer and next step?

    Do not respond by squeezing every selling point into one frame. A residual banner has less room and less attention than a complete video. Prioritize recognition: a clear brand, one useful proposition and an intelligible action. Dense copy turns extended visibility into visual noise.

    You should also keep exposure and response separate in your analysis. A skip may no longer mean that every trace of the advertiser vanished, but it still does not demonstrate interest, recall or purchase intent. Do not relabel a skip as an engagement merely because a branded element may persist afterward.

    Until Google establishes how any wider release appears in standard reporting, keep completed views, skips, clicks, site visits and conversions distinct. For brand activity, persistent exposure may be a useful directional signal. For performance activity, downstream behavior still carries the decision.

    Turn the changes into a controlled account workflow

    The practical opportunity is not simply “make more video.” It is to connect creative decisions to a cleaner evidence trail. You want to know what changed, where it changed and which outcome would justify keeping it.

    1. Inventory Performance Max campaigns with and without meaningful video creative.
    2. Capture a baseline for the business metrics that govern each campaign before changing assets or budget.
    3. Use the video reporting segment to locate the campaigns with the clearest difference worth investigating.
    4. Check for alternative explanations, including different offers, products, markets, conversion actions or seasonal conditions.
    5. Select one bounded campaign or product group for the next creative change.
    6. Give the pilot an evaluation window consistent with your normal conversion cycle and decision process. Do not stop it early because of an isolated daily movement.
    7. Evaluate the business result alongside the delivery context, document the conclusion and decide whether to expand, revise or stop.

    If the sticky-banner experience appears in your inventory, document it separately from the Performance Max analysis. A YouTube interface test and a Performance Max reporting segment are not two stages of one controlled experiment. Combining them would make it harder to tell whether a result came from creative, delivery, format or measurement.

    Key takeaways

    • The “Ads using video” segment makes video easier to investigate inside Performance Max; it does not prove that video caused the reported difference.
    • Compare business outcomes under similar campaign conditions before changing budgets.
    • YouTube’s post-skip banner is a test, not a format you should assume every viewer will encounter.
    • Creative should communicate a recognizable brand and proposition even when the complete video is not watched.
    • Keep skips, persistent exposure, clicks and conversions conceptually separate until the platform provides enough reporting clarity to connect them responsibly.

    Start with one account audit: apply the video segment, identify one result that is worth explaining and write down the confounding factors before you touch the budget. Then review the corresponding video as if the viewer will see only a fragment. That gives you one defensible measurement decision and one concrete creative improvement, without pretending the platforms have given you more certainty than they have.

    References

  • A Marketer’s Playbook for Ads in AI-Assisted Discovery

    A Marketer’s Playbook for Ads in AI-Assisted Discovery

    Your next paid discovery brief may arrive before the format has a stable name. The ad might represent an entire store instead of a single product, while an AI assistant might capture useful engagement before the buyer ever visits your site. A campaign structure built around a keyword, a product, and a click will not give you enough control.

    You do not need to predict which interface will win. You need a preparation model that works across store-level placements, conversational environments, and whatever hybrid appears between them. That means strengthening the advertised object, the evidence around it, the routes a buyer can take, and the measurement required before you commit budget.

    The advertised object is getting larger

    Traditional shopping campaigns make the individual product the center of gravity. Google is testing Sponsored Shops, a Shopping block that groups several products from one retailer with the store name, ratings, and broader brand presence. The impression can therefore introduce an assortment and a merchant, not merely an item.

    Conversational discovery creates a different expansion. OpenAI has begun testing an Ads Manager dashboard with selected partners as it develops advertising around ChatGPT. The exact inventory, interaction model, and optimization system remain early. You should treat them as provisional rather than assume conversational ads will inherit the rules of paid search.

    The practical lesson is that the thing you advertise can sit at several levels. It might be a product, a coherent assortment, a store, or a solution to the need expressed in a conversation. Each level requires different proof and a different continuation after the impression.

    Add the following fields to your campaign planning before a new platform makes them mandatory:

    • User need: the problem, task, or buying situation that triggered discovery.
    • Advertised object: the product, collection, store, or solution path the unit represents.
    • Evidence: the ratings, product details, range, brand facts, and on-page claims that support the promise.
    • Possible interactions: product selection, brand selection, continued conversation, or a direct visit.
    • Continuation: the exact page or in-platform step that follows each interaction.
    • Business event: the observable action that would make the placement valuable.

    This prevents a common category error: treating a larger discovery unit as if it were merely a wider text ad. More visible products do not automatically create a coherent reason to choose the store. A conversational placement does not automatically produce a qualified visit. The advertised object must make sense as a whole.

    Build a discovery asset stack before you buy media

    A modular stack of storefront, product, evidence, inventory, and data elements connects to three abstract discovery interfaces.

    A store-level placement exposes the quality of the catalog as a portfolio. Sponsored Shops could favor merchants with stronger product feeds, useful assortment depth, and credible seller ratings, because several products and the retailer identity appear within the same unit. A weak item is no longer isolated; it can make the entire selection feel less relevant.

    Do not answer that pressure by putting more products into every group. Build an asset stack in which every layer has a defined job:

    1. Catalog facts establish what each product is, what it costs, whether it is available, and how it differs from nearby options.
    2. Assortment logic explains why a set of products belongs together for a particular need. Shared inventory is not enough; the group needs a shopper-facing reason to exist.
    3. Brand evidence gives the buyer a reason to trust the store behind the assortment. Ratings and consistent brand identity matter more when the merchant is part of the advertised object.
    4. Destination continuity carries the same promise from the ad into the next page. The buyer should not have to reconstruct the category, filter, or use case after clicking.
    5. Machine-readable agreement keeps feeds, visible page content, and structured data aligned. JSON-LD should repeat defensible facts shown to the user, not introduce a cleaner but contradictory version of the offer.

    Audit this stack by discovery theme rather than by campaign name. Write the buyer’s need in plain language, select the products that genuinely address it, and inspect every item in that set. Mark missing details, inconsistent naming, stale availability, weak images, unexplained variations, and claims that do not match the destination. Then decide whether the set deserves to be presented as a store-level recommendation.

    Keep product-level optimization intact while you do this. A broad assortment should not bury the strongest item or force unrelated products into the same story. You are adding a portfolio layer above the product layer, not replacing product relevance with brand reach.

    Give every interaction a deliberate next step

    A multi-element discovery unit creates more than one possible click. With Sponsored Shops, the split between clicks on the brand and clicks on individual products is an open measurement and usability question. If you only plan the final conversion page, you will miss the intent expressed by the element the buyer selected.

    Design a continuation for each route that the format exposes:

    • Store or brand interaction: use a focused storefront that confirms the range, positioning, and evidence shown in the unit. Avoid a generic homepage unless it already performs that job.
    • Collection interaction: preserve the discovery theme, relevant filters, and visible product set. Do not make the buyer rebuild the selection from a broad category page.
    • Product interaction: land on the exact item with its important facts, proof, availability, and next action easy to find.
    • In-assistant interaction: identify what the platform can report when the user continues the conversation without visiting your site. Treat unreported engagement as unknown, not as a click or a conversion.

    Put this destination map in the campaign brief before creative production. For every clickable element, record the likely intent, destination, page promise, and success event. If the platform allows distinct tracking parameters for different elements, use them. If it does not, record that limitation before deciding how much you are willing to spend.

    The first visible part of each destination should close the loop opened by the ad. A store-level promise about range should reveal that range. A product promise should show the exact product. A solution-oriented message should answer the need before introducing unrelated navigation. That continuity is more useful than repeating the ad headline word for word.

    Keep paid visibility separate from organic AI visibility in your reporting. Buying placement does not make an unclear page easier for an answer engine to understand elsewhere. Your AEO and GEO work still needs clear naming, consistent facts, direct answers, accessible evidence, and structured data that agrees with the visible page. Paid discovery adds distribution and control; it does not repair weak information architecture.

    Make measurement and budget pass the same gate

    A glowing interaction moves through a branching journey toward a product shelf, consultation doorway, or parcel while paired measurement and budget tokens pass through one gate.

    Use a measurement ladder, not a click counter

    Early ChatGPT advertisers have reportedly received weekly CSV reports containing impressions and clicks, while initial click-through rates have trailed Google Search. Delivery and click data can confirm that an ad ran. They cannot, on their own, tell you whether conversational discovery created valuable demand.

    Measure emerging discovery formats as a ladder:

    • Delivery: impressions, placement, advertised object, unit variant, and any available context about where the ad appeared.
    • Interaction: clicks by element, product selections, brand selections, or reported continuation inside the interface.
    • Progression: meaningful visits to product or collection pages, deeper product exploration, cart activity, lead starts, or another relevant journey event.
    • Outcome: completed purchases, qualified leads, revenue, or the business result attached to the campaign.
    • Incremental value: evidence that the new channel added outcomes rather than taking credit for demand another channel had already created.

    Mark unavailable fields as unavailable. Do not enter zero, because zero means the platform measured the event and found none. Missing element-level interaction data is itself a decision signal: it limits what you can learn about creative, assortment, and destination performance.

    Your tracking taxonomy should identify the platform, placement, advertised object, unit variant, and destination wherever the platform exposes those controls. Keep those dimensions separate. Otherwise, a store click and a product click can collapse into the same campaign total even though they represent different user decisions.

    Write the test decision before launch. State the hypothesis, the variable being changed, the primary business outcome, the supporting engagement signals, the acceptable downside, and the condition that will stop or expand the test. A low click-through rate is not automatically failure for an upper-funnel discovery unit, but it cannot be excused by vague claims about awareness. The downstream evidence must carry the argument.

    Set a budget gate that reflects platform maturity

    Some early ChatGPT advertisers have reportedly been asked for a minimum commitment of $200,000. That creates material financial exposure while reporting and optimization capabilities are still developing. Early access is not valuable merely because access is scarce.

    Before accepting a pilot, require clear answers to these questions:

    • Where can the ad appear, and how is sponsorship disclosed to the user?
    • Which audiences, contexts, placements, products, and destinations can you include or exclude?
    • Which delivery, interaction, conversion, and cost fields can you export, and at what reporting cadence?
    • Can you distinguish a brand interaction from a product interaction?
    • How will conversion measurement work when part of the journey remains inside the assistant?
    • Which campaign changes can you make during the pilot, and what are the stop conditions?

    Ring-fence money you can genuinely treat as experimental. Do not pull budget from a proven acquisition channel simply to claim first-mover status. If the minimum commitment is too large to absorb as a learning cost, or the reporting cannot connect delivery to business outcomes, observing the format is the disciplined choice.

    Move from observation to a pilot when destinations are traceable, controls are understandable, disclosures are clear, and the downside fits the approved test budget. Move from pilot to scale only when the outcome is repeatable and the reporting explains why it happened. Impressions and novelty are not scale criteria.

    Key takeaways for your next planning cycle

    • Plan around the advertised object, which may be a product, assortment, store, or solution path.
    • Treat catalog quality, assortment logic, brand evidence, landing pages, and structured data as one discovery asset stack.
    • Map separate continuations for brand, collection, product, and in-assistant interactions.
    • Measure delivery, interaction, journey progression, business outcomes, and incremental value as distinct layers.
    • Do not fund a large early pilot without exportable reporting, usable controls, explicit stop conditions, and a tolerable downside.

    Your next move is to choose a commercially important discovery theme and complete the advertised-object and destination map for it. Audit the supporting catalog, page evidence, and machine-readable facts before a platform representative puts a media proposal in front of you.

    When access becomes available, ask the platform to map every promised metric and control to that plan. If the gaps prevent a business decision, keep observing. If the path is traceable and the risk is bounded, run a focused pilot with written stop conditions. Emerging discovery inventory should earn its budget on evidence, just like any established channel.

    References

  • Modern PPC Operations: Formats, Feeds, and Reporting

    Modern PPC Operations: Formats, Feeds, and Reporting

    Your ads can look healthy while the business result quietly deteriorates. A visual asset may be winning clicks but sending the wrong audience. A feed delay may suppress eligible products while the campaign settings remain untouched. A polished dashboard may hide either problem because its blended totals still look plausible.

    Modern PPC needs an operating system, not a longer optimization checklist. You have to manage three connected layers: the experience people see, the inputs advertising systems use, and the reporting that tells you what to change. This framework will help you find the failing layer before you spend money fixing the wrong one.

    Key takeaways

    • Treat each image, headline, description, product record, and landing page as an independent campaign input. Automated systems cannot rescue an asset that lacks a clear message or role.
    • Monitor feed health as a delivery dependency. A feed problem can resemble weak demand, an auction change, or poor campaign management unless you inspect product eligibility separately.
    • Give each data system a defined responsibility. Ad platforms explain delivery, Merchant Center explains product eligibility, GA4 explains post-click behavior, and business systems explain realized value.
    • Build reports around decisions and exceptions, including budget variance, zero-conversion spend, feed degradation, weak post-click behavior, and creative fatigue.
    • Investigate performance in causal order: platform availability, item eligibility, ad delivery, on-site behavior, and business value. That order prevents downstream symptoms from being mistaken for upstream causes.

    Build campaigns around assets, not just ads

    The old keyword-to-text-ad model is no longer a sufficient mental model for PPC. Conversational discovery, interactive showroom ads, visual experiences, and emerging gaming placements create journeys in which a person may inspect, compare, and refine an idea before producing anything that resembles a conventional search click.

    That changes your unit of optimization. You are no longer managing only ads or campaigns. You are managing a library of components that an automated system can select, combine, and distribute across different contexts.

    Give every asset a specific job

    Start by assigning each asset a funnel role. A visual can orient someone to the category, demonstrate a product, make a comparison easier, establish trust, or support an action. If you label everything as generic creative, you will know which file received impressions but not why it worked.

    • Orientation: Show what the product or service is without requiring supporting copy to make it intelligible.
    • Context: Show the offer in the situation where someone would use, choose, or evaluate it.
    • Detail: Make an important feature, difference, or constraint visible.
    • Validation: Reinforce the brand, proof, or reason a buyer should trust the offer.
    • Action: Make the next step and the value of taking it unambiguous.

    Visuals belong across the funnel, not only in awareness or remarketing. At the same time, every asset should remain recognizably yours. Brand-forward visuals and curated creative libraries matter because automated distribution can place one component in contexts you did not manually assemble.

    Maintain an asset register beside the media plan. Record the asset identifier, concept, offer, format, funnel role, intended audience, landing page, launch point, and current status. Use stable identifiers in both the ad platform and the reporting layer. A filename such as image-final-new is useless when you need to connect a result to a creative decision.

    Use AI as a selection system, not a substitute for judgment

    Automation needs good inputs: first-party data, creative assets, copy, website content, goals, and budgets. It can evaluate combinations and expose niche winners, but it cannot decide what your brand should mean or whether an isolated claim is persuasive. Individual asset performance can reveal which components deserve replacement and which niche performers deserve closer attention.

    Do not respond by replacing the whole library at once. Preserve strong components, remove clearly weak ones, and introduce distinct alternatives. A bulk replacement destroys your ability to tell whether the concept, format, offer, or audience match caused the change.

    Before uploading an asset, ask:

    • Can someone understand the central promise if this component appears without its preferred companion asset?
    • Does it add a genuinely different concept, or is it a cosmetic variation of material already in the library?
    • Is the brand identifiable without overwhelming the useful part of the message?
    • Can the asset be mapped to one business objective and one landing-page experience?
    • Will its identifier survive exports, blended reports, and future creative revisions?

    This discipline reduces asset overlap. It also makes automated performance easier to interpret: the system may choose the components, but you retain control over what each component is capable of communicating.

    Treat product feeds as production infrastructure

    Retail products move through an automated feed pipeline with sorting, quality checks, synchronization, and a gate that catches one delayed item.

    A retail campaign cannot advertise a product reliably if the advertising system cannot ingest, approve, or refresh its record. That makes the feed part of campaign delivery, not a back-office file owned exclusively by merchandising or development.

    The operational risk is real even when campaign settings have not changed. In one Merchant Center service disruption, the feed incident began on February 4, 2026, and was still under investigation in the February 20 status update. The available notice did not establish the cause, affected scope, or resolution time. That uncertainty is exactly why your monitoring has to distinguish platform availability from a defect in your own data.

    Map the feed pipeline as four separate states:

    1. Source state: The catalog, inventory, price, availability, destination URL, and other product data are correct in the system that owns them.
    2. Export state: The scheduled file, API process, or connector emits the expected records and completes successfully.
    3. Ingestion state: Merchant Center receives and processes the feed without an abnormal delay or unexpected drop in item count.
    4. Eligibility and delivery state: Products remain approved, current, and able to participate in the campaigns and free listings that depend on them.

    A green export job proves only the second state. It does not prove that Merchant Center processed the file, that products remained eligible, or that campaigns continued serving them.

    Use a feed incident protocol that preserves evidence

    When product delivery falls unexpectedly, capture the current state before making repairs. Save the feed completion time, processed item count, approval and disapproval pattern, affected product segments, campaign delivery change, and any platform status notice. Without that snapshot, a later recovery can erase the evidence you need to identify the cause.

    1. Check scope. Determine whether the problem affects the entire catalog, one market, one destination, one product type, or a recently edited segment.
    2. Check timing. Compare the first visible delivery change with the last successful source update, export, ingestion event, and platform notice.
    3. Check the status dashboard. A broad service notice does not prove your account has the same problem, but it changes the order of investigation.
    4. Inspect diagnostics. Separate delayed processing from new disapprovals, missing products, and stale price or availability data.
    5. Limit intervention. If the evidence points to a platform disruption, avoid rewriting a previously valid feed merely to force a refresh. That can introduce a second failure and make recovery harder to interpret.
    6. Validate recovery by layer. Confirm processing, item counts, approval status, campaign delivery, and business outcomes before releasing a backlog of unrelated feed changes.

    A platform incident usually has broad timing and multiple affected records. A local transformation problem is more likely to follow a catalog or connector change and affect a coherent subset. Normal feed diagnostics combined with falling spend point you back toward campaign eligibility, auction conditions, budgets, or demand. Do not pause an entire account simply because revenue fell; first establish whether the feed is actually the failing layer.

    Build reporting that can identify the failing layer

    An analyst traces an amber fault through stacked creative, product-feed, and conversion layers in a three-dimensional reporting system.

    A useful PPC dashboard does more than reproduce platform totals. It connects delivery to post-click behavior and business outcomes while making missing or delayed inputs visible.

    GA4 and Looker Studio solve different parts of that problem. GA4 uses an event-based model for website and app interactions. Looker Studio is designed to combine and present data, with connections to more than 800 data sources, calculated fields, blending, interactive controls, and scheduled report delivery. Neither should be treated as the sole owner of PPC truth.

    Assign ownership before you blend anything

    • Advertising platforms: Own impressions, clicks, spend, placement, bidding, and platform-attributed actions.
    • Merchant Center diagnostics: Own feed processing, product approval, and product-level eligibility evidence.
    • GA4: Own the configured view of sessions, engagement, events, and other website or app behavior after the click.
    • CRM or commerce systems: Own qualified leads, orders, realized revenue, and other downstream business states.
    • Looker Studio: Presents and calculates across those systems. It does not repair inconsistent definitions in the underlying data.

    GA4 can natively import cost, click, and impression data from additional advertising platforms, including Meta and TikTok, but strict UTM matching and limited campaign-name cleanup can constrain the result. Native ingestion reduces manual work; it does not remove the need for a campaign naming standard.

    Write the join plan before building charts. Specify the date grain, channel definition, account identifier, campaign identifier, creative identifier, currency, time zone, and conversion definition. Normalize labels in a controlled field rather than editing historical campaign names to make a chart look tidy. If two datasets have multiple rows for the same join key, aggregate them to the intended grain before blending; otherwise cost or conversions can be duplicated.

    Organize the dashboard around decisions

    A decision-grade PPC report needs four views:

    1. Outcome and pacing: Show spend against plan, primary outcomes, efficiency, and downstream value. If the monthly plan is intentionally linear, the expected spend point halfway through the month is 50% of the budget. If demand or promotions are not linear, replace that line with the actual spending plan rather than pretending uniform pacing is desirable.
    2. Delivery and feed health: Show changes in eligible products, product diagnostics, impressions, clicks, and spend together. This view tells you whether falling revenue began before or after the click.
    3. Creative performance: Display the actual visual beside its stable asset identifier, spend, click response, conversion result, and post-click quality. Looker Studio’s IMAGE function can place creative previews inside a report table, making the discussion about the asset rather than an opaque ad-group name.
    4. Waste and post-click quality: Surface spend with no recorded conversion above a threshold chosen for the account. Pair click response with engagement and lead quality so a high click-through rate cannot disguise a poor landing-page or audience match.

    Calculated fields should translate platform activity into business language. Profit can be calculated by subtracting cost from revenue, while ROAS can connect CRM revenue with advertising cost. Document which revenue state you use. Booked revenue, collected revenue, predicted value, and platform-attributed conversion value answer different questions and should not share an unlabeled metric name.

    Add a trust panel to every report. Include the last successful refresh, source coverage, reporting time zone, currency treatment, primary conversion definition, attribution scope, exclusions, and known incidents. A viewer should be able to tell whether a flat line means no activity or failed data retrieval.

    Keep performance observations separate from explanations. An annotation such as “cost per lead increased after the promotion ended” records a sequence. “Competitor aggression caused the increase” is a hypothesis unless you have supporting evidence. Labeling the difference protects the dashboard from turning a plausible story into an accepted fact.

    Complex dashboards also create a reliability problem of their own. Heavy use of GA4 widgets and concurrent views can run into API quotas. For demanding reporting environments, extracting GA4 data to BigQuery before connecting Looker Studio can reduce quota pressure and improve report performance. Before adding another chart, ask what decision it changes; fewer meaningful queries are easier to trust than a wall of fragile widgets.

    Use one operating sequence for every performance anomaly

    The same symptom can come from several layers. A revenue decline might begin with product eligibility, creative-message mismatch, landing-page behavior, tracking, lead quality, or actual demand. Use the earliest reliable evidence to decide where to investigate.

    What you noticeCheck firstWhat to do next
    Product impressions and spend fall suddenlyFeed processing, item counts, diagnostics, eligibility, and platform statusIsolate the affected product set and preserve the last known valid feed configuration while you identify the failing state.
    Delivery is stable but click response weakensAsset, format, placement, audience, and offer breakdownsReplace a weak component with a meaningfully different alternative while retaining stable winners.
    Clicks remain stable but engagement or leads deteriorateLanding-page behavior, conversion collection, page-message continuity, and audience qualityInvestigate the post-click path before changing bids or product data.
    Spend is ahead of planPlanned pacing, current demand, outcome quality, and budget configurationDecide whether the variance is productive before reducing delivery solely to match a straight line.
    Platform ROAS falls while recorded business revenue is stableAttribution scope, conversion definitions, join logic, and data refresh timingReconcile measurement before reallocating budget on the assumption that demand collapsed.
    Several dashboard charts flatten or fail togetherConnector refreshes, source credentials, API quotas, and source coverageRestore reporting reliability and mark the affected period instead of interpreting missing data as zero performance.

    Work from cause to consequence

    1. Availability: Can each required platform and connector process or return data?
    2. Eligibility: Are the intended ads, products, assets, destinations, and audiences allowed to participate?
    3. Delivery: Did impressions, clicks, spend, format mix, or product coverage change?
    4. Behavior: Did people engage with the landing experience and complete the configured events?
    5. Value: Did those actions become qualified leads, orders, revenue, profit, or another business outcome?

    Keep a decision log beside the dashboard. Record the observed condition, affected scope, evidence, working hypothesis, action, owner, and validation signal. Where practical, change only one causal layer at a time. If you rewrite the feed, replace the creative library, alter bids, and edit conversion definitions together, even a recovery will teach you very little.

    Start with the report you already use. Add its last refresh, feed status, spend against plan, primary business outcome, and known incident state. Then make your next optimization only after you can name the layer that failed. That small change turns PPC reporting from a record of what happened into a control system for what you do next.

    References


  • Third-Party Endorsements in Google Search Ads: What to Do

    Third-Party Endorsements in Google Search Ads: What to Do

    If you buy Google Search ads, the immediate question is whether you can get a publisher quote into your own ad. For now, there is no disclosed setup path, eligibility rule, or request process. Rebuilding a campaign around this feature would be premature.

    You can still prepare intelligently. The useful work is to organize the independent evidence behind your brand, decide how you would measure an endorsement if one appeared, and avoid confusing an experimental ad treatment with an advertiser-controlled asset.

    What the endorsement test actually changes

    The experimental format places a short statement from an external publisher directly beneath the advertiser’s description. The treatment can include the publisher’s name, logo, and favicon, visually separating the statement from the copy supplied by the advertiser.

    One observed ad displayed the line “Best for Frequent Travelers” and attributed it to PCMag. That example matters because it shows the kind of claim involved: a concise editorial judgment about whom a product suits, rather than a generic customer rating or another promotional sentence written by the advertiser.

    This distinction changes how you should evaluate the feature. Your headline and description present your own proposition. A recognizable external endorsement could add a different kind of evidence at the moment someone is deciding which result deserves a click. It may make the ad resemble an editorial recommendation more closely, but that possible effect has not yet been established through disclosed performance data.

    Google has confirmed only that it is running a “small experiment” involving third-party endorsement content. Several operational questions remain unanswered:

    • Which advertisers, products, queries, or publishers are eligible.
    • Whether an advertiser can opt in or opt out.
    • Whether an advertiser can request, select, approve, or reject an endorsement.
    • How Google finds the content and decides which statement to display.
    • How old, changed, disputed, or removed publisher content would be handled.
    • Whether the experiment is connected to review-extension concepts, publisher partnerships, or broader trust-and-safety systems.

    Until those questions are answered, treat the endorsement as a possible search-result treatment, not as a new asset type you can add to a campaign. There is no documented basis for changing bids, budgets, campaign structure, or creative solely to obtain it.

    Prepare your brand without trying to game the experiment

    Hands organize blank press materials, a neutral medallion, and research documents beside a separate tray of generic ad cards.

    You cannot configure an undisclosed feature, but you can make your external reputation easier to understand and manage. Start with an endorsement inventory. A simple worksheet should contain the publisher, URL, covered brand or product, exact wording, publication date, current status, and the person responsible for checking it.

    1. Record exact claims, not flattering paraphrases. “Best for frequent travelers” is materially different from “best travel product.” Preserve the original wording and context internally so your team does not turn a narrow judgment into a broader claim.
    2. Classify the evidence correctly. Keep editorial endorsements separate from customer reviews, testimonials, awards, certifications, affiliate roundups, and paid placements. They may all support trust, but they are not interchangeable.
    3. Check the product and audience match. An endorsement for one plan, model, or use case should not be treated as validation for an entire company. Map each statement to the exact landing page and offer it describes.
    4. Make brand and product names consistent. If a product has several informal names across your site, campaign, and public coverage, document which names refer to the same thing. Clear naming helps your own team avoid attaching the wrong evidence to an ad or landing page.
    5. Create a correction route. Assign an owner who can contact a publisher when a factual detail is outdated or inaccurate. You may not be able to control what Google displays, but you can keep the underlying public information accurate.

    Do not copy publisher quotations or logos into your creative merely because Google displayed them in an experiment. A platform-generated treatment does not automatically give an advertiser permission to reuse editorial language or branding elsewhere. Keep the inventory as an evidence and monitoring tool unless your organization has the appropriate permission for direct reuse.

    It is also too early to commission coverage for the purpose of triggering this format. You do not know whether Google considers a particular publisher, whether paid or affiliate relationships affect selection, or whether advertisers will ever receive controls. Earn credible coverage because the coverage itself helps buyers evaluate you, not because you expect it to become an ad decoration.

    Measure an appearance without inventing causality

    A magnifying lens examines a blank search-ad card surrounded by separate contextual layers, while a broken link separates the observation from an outcome token.

    If an endorsement appears beneath one of your ads, a screenshot proves that the treatment rendered. It does not prove that the treatment improved performance. Queries, competitors, auction conditions, audience mix, devices, and campaign changes can all affect the same metrics.

    1. Capture the context. Save the screenshot along with the query, date, time, country, device type, displayed endorsement, publisher, ad copy, and destination URL.
    2. Annotate your reporting. Record when the first appearance was observed and note any simultaneous changes to bids, budgets, targeting, creative, landing pages, offers, or conversion tracking.
    3. Look for repeated exposure. Do not make a budget decision after one observation. Establish whether the treatment appears repeatedly and whether its wording stays consistent.
    4. Use business metrics in sequence. Examine click-through rate first, then conversion rate and the cost or return metric your campaign actually uses. A higher click-through rate with lower post-click quality is not automatically an improvement.
    5. Use the closest valid comparison. Compare similar queries, ads, audiences, and periods where possible. If Google does not provide an exposure field or experiment control, label any apparent difference as directional rather than causal.

    Avoid rewriting your description to imitate the endorsement. Repetition can waste limited ad space, and a line that looks independent loses its meaning when the advertiser makes the same claim about itself. Your copy should explain the offer; the external statement, if shown, should remain clearly external.

    Keep paid search, SEO, AEO, GEO, and schema in their proper lanes

    Third-party validation can support a broader visibility strategy, but this experiment does not establish a technical connection between Search ads and organic or AI-generated results. The selection process and its relationship to other Google systems remain undisclosed.

    • For paid search: the observed endorsement is an experimental element displayed with an ad. It is not currently a documented advertiser asset.
    • For SEO: there is no disclosed evidence that appearing in this treatment changes organic rankings.
    • For AEO and GEO: independent coverage can give people and answer systems public material with which to understand a brand, but this ad experiment does not prove that the same selection mechanism powers AI answers or citations.
    • For structured data: there is no disclosed evidence that JSON-LD or another schema type triggers the endorsement.

    Your safest cross-channel strategy is therefore straightforward: keep product facts precise, use consistent entity names, maintain the pages that substantiate your claims, and organize legitimate independent coverage. Those actions make your brand easier to verify even if this particular ad format never expands.

    Use a simple decision rule. If an activity makes your public evidence clearer, more accurate, or more useful to a prospective buyer, it is worth considering on its own merits. If its only purpose is to trigger an undocumented ad feature, defer it until Google publishes eligibility rules and advertiser controls.

    Key takeaways

    • Google is testing publisher quotations, names, logos, and favicons beneath some Search ad descriptions.
    • The confirmed example is part of a small experiment, not a generally available ad feature.
    • No public setup path, eligibility rule, opt-in mechanism, selection method, or performance reporting has been disclosed.
    • An endorsement inventory can help you manage external claims without assuming that you can submit them to Google.
    • If the treatment appears, document the exposure and assess the entire path from click to conversion before changing spend.
    • Do not treat SEO, AEO, GEO, or schema work as a shortcut into the experiment without evidence of a connection.

    Build the inventory now, add a place for endorsement observations to your campaign log, and leave campaign economics unchanged until repeated data or official controls give you something reliable to act on.

    References

  • How to Plan Conversational AI and Social Ad Budgets

    How to Plan Conversational AI and Social Ad Budgets

    You have one experimental budget and three names in the room: Threads, ChatGPT, and Gemini. Calling all three emerging ad opportunities hides the decision that matters. What can you buy, what can you measure, and what job should each surface do?

    Start with the buying mechanics. Threads can enter Meta’s established campaign workflow. Early ChatGPT inventory is a controlled, impression-based buy. Gemini has no paid placement under Google’s announced stance. Once you separate those models, the budget decision becomes much easier.

    Separate the opportunity into three different ad markets

    Conversational AI and social feeds may compete for the same experimental budget, but they do not sell the same product. One sells feed distribution through a mature advertising system. Another is testing sponsored exposure beside a generated answer. The third is withholding ads while it develops the assistant.

    SurfaceWhat advertisers can accessWhat that means for your plan
    ThreadsGlobal advertiser access, a rollout to users worldwide, Advantage+ campaign expansion, and image, video, and carousel formats. Campaigns can be managed within the wider Meta environment used for Facebook, Instagram, and WhatsApp.Treat it as a paid-social placement test. Use familiar campaign objectives, but require placement-level reporting before claiming that Threads caused the result.
    ChatGPTSelected-advertiser testing with impression-based pricing, initial advertiser commitments below $1 million, and no self-service buying. Sponsored units are placed at the bottom of responses and separated from the organic answer.Treat it as controlled innovation inventory. It may support reach, learning, and brand objectives before it can support a conventional performance case.
    GeminiNo planned ad product under the stated 2026 position. Google is prioritizing assistant quality, usefulness, and trust before monetization.Do not put Gemini impressions in a paid-media forecast. Keep it in your organic AI visibility program and on a product-monitoring list.

    Availability is the first gate, not the final reason to spend. Threads has a reported user base of more than 400 million, but that figure describes platform scale rather than the reach available to your account. Meta also indicated that delivery would begin modestly. Your forecast should therefore come from the inventory and placement estimates available during campaign setup, not from the platform-wide audience number.

    ChatGPT presents the opposite planning problem. A conversation can reveal strong intent, but impression-based billing does not prove that the user noticed the sponsored unit, asked about it, visited the advertiser, or converted. Pricing tells you what triggers the charge. It does not tell you whether the exposure worked.

    Key takeaways

    • Classify each opportunity by buying model and reporting capability before comparing audience size.
    • Use Threads as an additional paid-social placement, not as a proxy for conversational intent.
    • Use early ChatGPT inventory for an impression-led learning objective unless the buying agreement supplies stronger outcome measurement.
    • Keep Gemini out of paid-media budgets until an actual ad product defines access, formats, billing, reporting, and controls.
    • Report paid conversational exposure separately from organic mentions and citations in AI answers.

    Give each surface one job before you fund it

    A new placement becomes expensive when it is asked to prove everything at once. If the same test is supposed to create awareness, generate leads, establish brand safety, and teach you how the format works, almost any result can be rationalized after the fact. Assign one decision question to each surface before approving spend.

    Threads: test incremental paid-social distribution

    Threads is the most operationally familiar option because Meta can streamline campaign expansion through Advantage+. That convenience can also obscure what happened. A blended Meta result cannot tell you whether Threads earned its share of the budget unless your reporting isolates delivery and outcomes for that placement.

    1. Write one hypothesis. For example, test whether a specific audience and creative concept can produce acceptable traffic or conversion quality on Threads. Do not use a vague objective such as learning the platform.
    2. Select one primary outcome. Choose reach, traffic, leads, sales, or another campaign objective supported by your setup. Keep secondary metrics diagnostic rather than treating every metric as a success condition.
    3. Confirm placement visibility. Before launch, verify that your reporting can show Threads delivery, spend, and the outcome tied to your objective. If it cannot, treat the campaign as a broader Meta test rather than a Threads test.
    4. Control the creative comparison. Carry one existing paid-social concept into the test and pair it with one Threads-specific variation. Hold the offer and audience as steady as your controls permit so that the creative difference remains interpretable.
    5. Predefine the decision rule. Set the acceptable result from your own paid-social benchmark before seeing the data. Record what would justify scaling, revising creative, or stopping.

    Modest early delivery may reflect limited inventory rather than a failed message. Do not judge creative after a handful of impressions, but do not wait indefinitely either. Evaluate once the placement has delivered enough exposure for the metric in your prewritten rule, and document underdelivery as a separate finding.

    ChatGPT: buy access only when the learning is worth the ambiguity

    Do not copy a paid-search brief into ChatGPT. The user may be expressing a need in the conversation, but the initial commercial model emphasizes impressions and offers limited conventional performance reporting. That makes the first tests better suited to advertisers that can value exposure and format learning without manufacturing a direct-response conclusion.

    Access is itself a qualification step. Initial testing involves selected advertisers, spending below $1 million per advertiser, without a self-service interface. The announced audience configuration places ads in free access and the $8-per-month ChatGPT Go tier, while Plus, Pro, and Enterprise remain ad-free for the time being. Your buying brief should identify the audience you can actually reach rather than referring to ChatGPT users as one undifferentiated group.

    Get written answers to these questions before approving an insertion order or equivalent commitment:

    • What event counts as a billable impression, and which impression fields appear in reporting?
    • Which account tiers, geographies, devices, and conversation contexts are eligible?
    • Can the unit link to a destination, and how are clicks or other interactions defined?
    • Are reach, frequency, and repeat exposure available, or will you receive only aggregate impressions?
    • Can follow-up questions about the sponsored product be measured, and are they reported in aggregate without exposing private conversation content?
    • Which category exclusions, adjacency controls, and remediation procedures apply?
    • Can campaign data be exported for reconciliation with your analytics and customer systems?

    If those answers do not support your normal acquisition model, label the spend correctly: a brand and product-learning test. Do not place a cost-per-acquisition target in the approval document and then excuse its absence because the format is new.

    Gemini: define the trigger for reconsideration

    A no-ad position is not the same as a permanent ban, but it is enough to make the current budget decision. Google leadership has ruled out Gemini ads for 2026 under the stated plan, citing the need to protect helpfulness and trust.

    Do not reserve speculative Gemini media money merely to appear prepared. Put the surface on a watchlist with five activation triggers: buyer access, eligible audience, ad format, billing method, and reporting controls. Until all five are defined, the paid-media row should remain unavailable rather than carrying an invented forecast. Your organic work for Gemini belongs in a different plan and can continue without waiting for an ad product.

    Build a measurement contract before the campaign

    Two analysts examine an abstract advertising journey that passes through a series of measurement checkpoints from impression to conversion.

    The measurement plan should be short enough to read in one meeting and strict enough to prevent a weak result from being renamed a success. For every test, record the business question, the primary metric, supporting diagnostics, disqualifying conditions, evaluation window, data owner, and decision owner.

    Use a four-level measurement ladder:

    1. Delivery: Record spend, billable impressions, placement share, and reach or frequency when provided. Reconcile the purchased amount with the platform report before interpreting response.
    2. Observable response: Track clicks, destination sessions, or another defined interaction only when the format supports it. State exactly what the platform counts rather than assuming that similarly named metrics are equivalent.
    3. Business outcome: Connect qualified leads, purchases, or other approved outcomes through your normal analytics process. Separate directly observed conversions from modeled or assisted attribution.
    4. Incrementality: When the buying system and budget permit, use a holdout or controlled split to test whether the advertising changed behavior. Without a control, label changes in branded demand or direct traffic as directional rather than causal.

    For Threads, the crucial diagnostic is placement-level delivery. A campaign that performed well across Meta does not establish that Threads worked if Facebook or Instagram delivered most of the impressions. Compare the Threads result with the benchmark chosen before launch, and keep differences in audience, creative, and optimization settings visible.

    For ChatGPT, the minimum evidence is verified delivery under the contracted impression definition. OpenAI has indicated that follow-up questions about sponsored products could become an engagement signal, but that possibility is not a current performance guarantee. Do not make a future field the cornerstone of today’s business case. If follow-up reporting becomes available, document its definition, privacy treatment, and relationship to downstream action before using it as a KPI.

    Do not compare raw click-through rates across a feed ad and a unit beneath an AI answer as if the interfaces were interchangeable. Position, user task, billing, and available actions all differ. Compare each surface with the goal and benchmark assigned to that surface. Then compare investment decisions using business value and confidence in the evidence.

    Make trust and brand safety part of campaign acceptance

    A transparent safety gateway filters a sponsored content tile before it enters a field of conversational speech bubbles.

    An ad beside a generated answer carries a different trust burden from an ad in a familiar feed. The assistant is responding directly to the user’s words, so commercial influence can be mistaken for neutral help unless the boundary is obvious. Google’s reluctance to monetize Gemini reflects concern that advertising could compromise unbiased recommendations and user trust. OpenAI’s initial design addresses the same tension by marking sponsored units and separating them at the bottom of responses.

    Turn that principle into acceptance criteria. Before launch:

    • Review the actual unit or a faithful preview and confirm that the sponsorship label is visible without extra interaction.
    • Reject creative that imitates the assistant’s voice or implies that the organic answer endorsed the advertiser.
    • Check that every factual claim in the ad is supported on the destination page and remains accurate when removed from the surrounding conversation.
    • Document prohibited adjacencies, sensitive categories, escalation contacts, and the remedy available after an unsuitable placement.
    • Capture a dated preview or screenshot with the approved copy, destination, disclosure, and platform version so later changes can be audited.
    • For regulated or high-consequence claims, route the complete placement context through the appropriate legal or compliance review rather than submitting isolated ad copy.

    Threads offers a more familiar control layer. Meta is extending third-party brand-safety verification used on Facebook and Instagram to Threads. Confirm which verification provider, report, market, and placement your campaign can use. The existence of a verification program does not prove that it covers every impression in your specific setup.

    A trust failure also damages measurement. If users cannot tell whether a recommendation is paid, engagement may reflect mistaken endorsement rather than persuasive advertising. A high interaction count under that ambiguity is not a clean signal to scale.

    Keep paid exposure separate from organic AI visibility

    Your reporting should have three lanes: paid social distribution, paid conversational exposure, and organic AI visibility. Combining them in one AI channel bucket makes every number harder to interpret.

    • Paid social distribution: Put Threads spend, impressions, placement delivery, response, and conversions here.
    • Paid conversational exposure: Put ChatGPT sponsored impressions and any defined ad interactions here. Keep the sponsorship label and placement type in the campaign record.
    • Organic AI visibility: Track whether assistants mention or cite the brand for a maintained set of relevant questions. Record the model, access tier, prompt, answer date, cited destination, and repeated observations because generated answers can vary.

    A sponsored unit beneath a ChatGPT response does not mean the brand appeared in the organic answer. An organic Gemini citation is not paid delivery. Threads reach does not establish visibility in an AI assistant. Preserve those distinctions in campaign names, analytics dimensions, dashboards, and executive reporting.

    The same boundary applies to technical optimization. JSON-LD, schema, clear entity information, and answer-focused content can be evaluated as parts of organic discovery, but the available ad plans do not establish them as levers for ChatGPT ad eligibility, Threads delivery, or a future Gemini auction. Give structured-data work its own validation and visibility objectives instead of attributing paid-media effects to it.

    At your next budget meeting, create one row for each surface and fill in four fields: whether it is buyable, the single question the spend will answer, the evidence the platform can return, and the event that would unlock more budget. Fund Threads when you have a paid-social question and placement-level measurement. Fund ChatGPT when impression-led learning is valuable enough to justify limited performance evidence. Leave Gemini out of the paid forecast until a real product changes the decision. The useful early move is not simply being first; it is knowing what the first test must prove before you buy the second.

    References

  • ChatGPT Ads: What OpenAI’s Pause Means for Marketers

    ChatGPT Ads: What OpenAI’s Pause Means for Marketers

    If you’re deciding whether to reserve budget for ChatGPT ads, don’t treat OpenAI’s pause as either a canceled channel or an imminent launch. Neither conclusion is useful. The practical move is to prepare the parts you control while keeping activation spend conditional.

    The pause reveals an important constraint on OpenAI’s advertising strategy: the assistant has to retain attention and trust before it can carry a durable ad product. That changes what your team should build now, what it should leave blank, and which questions must be answered before you buy anything.

    The pause changes the sequence, not the long-term direction

    OpenAI has put its ChatGPT advertising plans on hold while it concentrates on speed, reliability, reasoning, and the broader user experience. The internal code red also directs attention toward reducing hallucinations and improving the assistant’s ability to complete complex tasks.

    That is a sequencing decision. Advertising remains part of the long-term strategy, but product stabilization comes first. For marketers, the distinction matters: a delayed channel deserves monitoring and preparation, not a committed media forecast built from assumptions.

    Do not plan around an unconfirmed launch date, inventory map, placement type, buying model, targeting system, or measurement specification. A pause does not answer any of those questions. It only shows that OpenAI currently considers product quality a prerequisite for monetization.

    Key takeaways

    • OpenAI has delayed ChatGPT advertising while it works on the assistant’s core performance and user experience.
    • The delay does not mean OpenAI has abandoned advertising as a revenue stream.
    • There is not enough confirmed detail to build a channel forecast around formats, targeting, pricing, or launch timing.
    • Your useful work now is measurement, intent mapping, content readiness, and launch governance.
    • Activation money should remain conditional until OpenAI publishes the operating details your team needs.

    Why assistant quality comes before ad inventory

    A person interacts with a glowing conversational orb while several unlit advertising tiles remain behind a translucent partition in the background.

    A ChatGPT ad product will inherit the trust conditions of the assistant around it. If an answer feels slow, fragmented, or unreliable, adding a commercial message creates more friction. If the assistant consistently helps users finish a task, an appropriately separated and relevant ad has a better chance of being useful.

    This is why the competitive pressure from Google matters to the advertising plan. Gemini’s advantage is presented as more than a benchmark contest: its integration with products such as Google Maps and Workspace can help it carry a user from a question into an action. OpenAI, meanwhile, is trying to make ChatGPT feel more like a dependable executor of tasks and less like a passive answer box.

    The commercial inference is straightforward. Useful task completion creates opportunities for relevant offers. Poor task completion makes advertising feel like an interruption. OpenAI therefore has two readiness gates to pass:

    • Assistant readiness: The product must be fast, dependable, coherent, and valuable enough that people continue using it.
    • Advertising readiness: OpenAI must define placements, labeling, targeting, controls, billing, reporting, privacy boundaries, and advertiser eligibility.

    The pause indicates that the first gate still commands attention. It tells you nothing conclusive about the maturity of the second. Ask for evidence that both gates are open before treating ChatGPT as an executable media channel.

    This also explains why a contextually relevant format is more plausible strategically than a generic display interruption, although no specific format should be treated as confirmed. OpenAI ultimately needs advertising that fits the user’s task without making the answer itself feel purchased or less trustworthy.

    Build readiness without buying imaginary inventory

    A marketing team organizes unbranded creative cards, audience tokens, and measurement blocks beside an empty media-placement frame under a transparent cover.

    You can prepare for ChatGPT advertising without pretending to know how it will work. Concentrate on assets that remain useful whether the launch arrives early, late, or in a form nobody predicted.

    1. Establish an AI traffic baseline. Create an analytics segment for visits whose referrer identifies ChatGPT. Record the landing page, engaged session, conversion, revenue where applicable, and assisted conversion. Keep the limitation visible: answers that influence a person without producing a click will not appear as referral traffic.
    2. Build a question-to-outcome map. Collect the questions customers ask in search data, sales calls, support tickets, reviews, and on-site search. Group them by the outcome the user wants: discover, compare, verify, choose, or act. Mark which questions have commercial intent and which require a neutral informational answer.
    3. Audit the pages that should support those outcomes. Each important page should identify the entity or product clearly, answer the central question directly, substantiate material claims, disclose meaningful constraints, and have an owner responsible for updates. Structured data should describe the visible page accurately; it should not introduce claims that users cannot verify on the page.
    4. Prepare modular messages and landing paths. Write short value propositions for each high-intent question, but do not build copy around a guessed ChatGPT placement. The message should still work if the eventual unit is adjacent to an answer, shown after a recommendation, or offered as an action.
    5. Define your evidence standard. Decide which product claims require documentation, which offers need current terms, and who approves regulated or high-risk language. A conversational interface can place a claim close to a user’s decision, so stale qualifications and ambiguous terms can become costly problems.
    6. Assign launch ownership now. Name the people responsible for media buying, analytics, privacy review, legal review, brand suitability, landing-page changes, and AI visibility. A new channel becomes hard to test when every unanswered question has to find an owner after launch.

    None of this guarantees paid eligibility, organic inclusion, or a citation in ChatGPT. It removes avoidable delays and gives you a clean baseline against which a future paid test can be judged.

    Require a complete launch brief before you spend

    The first announcement of inventory will not necessarily provide everything required for a responsible campaign. Product availability and campaign readiness are different events. Your team should be able to fill in the following brief from OpenAI’s actual documentation and platform controls, not from screenshots, rumors, or analogies to search ads.

    • Availability: Which countries, languages, account types, ChatGPT plans, devices, and assistant surfaces contain ads?
    • Placement: Does the unit appear inside an answer, beside it, after it, or as a separate recommended action? Can an ad affect the wording or ordering of the non-paid answer?
    • Disclosure: How is commercial content labeled, and does the label remain visible when an answer is shared, exported, or summarized?
    • Eligibility: Which industries, offers, destinations, and claims are restricted? What review process applies before an advertiser or campaign can run?
    • Targeting: Can advertisers select queries, topics, audiences, locations, tasks, or conversation contexts? Which controls prevent irrelevant matching?
    • Data boundaries: What conversational or account information can be used for targeting, optimization, reporting, and retargeting? What consent and retention rules apply?
    • Pricing and delivery: Is the campaign billed for impressions, clicks, actions, or another event? How are auctions, pacing, budgets, and delivery priority handled?
    • Advertiser control: Are exclusions, negative targets, frequency controls, suitability settings, placement reports, and blocklists available?
    • Measurement: Which impression, click, view, conversion, attribution, and incrementality reports exist? Can advertisers use independent analytics and conversion records?
    • User control: Can people dismiss an ad, correct an irrelevant assumption, change personalization settings, or understand why a commercial message appeared?

    Do not accept a familiar metric name without its definition. A click beside a conversational answer may represent a different level of intent from a click on a conventional search result. Likewise, an impression is not useful for planning until you know when the platform counts it and whether the ad was actually visible.

    A pilot is ready only when you can name its objective, eligible question set, conversion event, attribution window, landing experience, acceptable acquisition cost, and stop condition. Those values must come from your own economics. If the platform cannot provide the controls or reporting needed to enforce them, the campaign is not ready merely because inventory is available.

    Keep the initial allocation reversible. A controlled test budget protects you from locking an annual plan to a new interface whose user behavior, ad load, reporting quality, and optimization mechanics have not yet been demonstrated for your business.

    Keep paid ChatGPT ads separate from AI visibility

    Paid placement and inclusion in an assistant’s non-paid answer solve different problems. Until OpenAI explicitly documents a relationship between them, plan and report them separately. Buying an ad should not be treated as a shortcut to being cited, recommended, or described favorably in an organic response.

    Your organic preparation should make the brand easier to understand and verify regardless of the advertising timeline:

    • Maintain a clear canonical page for each important company, product, service, location, and policy.
    • Put the direct answer to a page’s main question near the beginning instead of burying it beneath promotional copy.
    • Support comparative, performance, safety, pricing, and availability claims with evidence appropriate to the claim.
    • Keep names, descriptions, relationships, and material product facts consistent across visible content and JSON-LD.
    • Make structured data specific enough to identify the entity while ensuring every marked-up claim is also present and accurate on the page.
    • Assign review dates and owners to pages containing details that can change.
    • Track brand presence and factual accuracy across a stable set of relevant prompts, but record the prompt, model, date, and context so the observations remain interpretable.

    This work is not a backdoor advertising tactic. It is content and entity hygiene. It helps you diagnose whether a future campaign is adding demand, capturing existing demand, or merely taking credit for users who already knew the brand.

    OpenAI’s decision to prioritize retention and product quality before ad deployment should shape your own planning sequence. Create three separate budget lines: market intelligence, channel readiness, and activation. Start the first two now. Release the third only when confirmed specifications pass your launch brief and a controlled pilot can answer a real business question.

    That leaves you ready without betting on a date. More importantly, it gives you the measurement discipline to recognize whether ChatGPT ads become a valuable acquisition channel or simply an expensive new place to appear.

    References