Category: Security

  • AI Marketing Agent Safety: A Practical Oversight Framework

    AI Marketing Agent Safety: A Practical Oversight Framework

    Your marketing agent can draft a campaign, diagnose performance, or prepare a site update. The risk changes the moment it can spend money, suppress traffic, publish claims, email customers, or overwrite a working configuration.

    You don’t need a binary verdict on whether the model is trustworthy. You need an operating system around it: complete enough context, narrowly scoped permissions, enforceable policies, approval before consequential actions, and a record that lets you reconstruct what happened.

    Replace abstract trust with three control questions

    The safer question is not whether you trust an AI model in the abstract. Ask what the agent can see, what it is structurally allowed to do, and who must approve its work before production. Those questions turn trust into controls you can inspect and test.

    1. What can it see? List every account, dataset, field, date range, customer-data class, and external tool available to the agent. Record important gaps as carefully as available data.
    2. What can it do? Separate reading, analysis, drafting, recommendation, and execution. A prompt describing what the agent should do is not a permission boundary.
    3. Who signs off? Name the role that must approve each protected action. Reviewing a change log afterward is auditing, not approval.

    Use those answers to assign every workflow an operating mode. Do not give an entire agent one blanket risk label; the same agent may be safe to query campaign data and unsafe to change a budget.

    Operating modeWhat the agent may doMinimum control
    ObserveRead approved data and explain findingsNo production write credential; disclose data scope and gaps
    ProposePrepare copy, settings, or recommended changesPolicy validation; no direct route from proposal to production
    Limited executionCreate drafts, apply labels, or act inside a designated sandboxNamed resources, hard action limits, result verification, and a tested recovery path
    Protected executionChange spend, bids, targeting, negative keywords, live content, customer communications, access, or destructive settingsExplicit approval for the exact change before execution

    Reversible does not necessarily mean low risk. You can unpause a campaign, but you cannot recover traffic and opportunities lost while it was paused. You can restore a previous page version, but not necessarily retract a claim already seen by customers or answer engines. Classify risk by consequence and exposure, not merely by whether the interface has an Undo button.

    Scope each permission across several dimensions:

    • Environment: sandbox, draft workspace, or production.
    • Identity: the brands, business units, clients, and accounts included.
    • Resource: campaigns, pages, audiences, feeds, schemas, or customer records.
    • Action: read, create, edit, publish, pause, archive, or delete.
    • Magnitude: the amount of spend, number of entities, or audience size the action can affect under your existing internal limits.
    • Time: when permission begins, when it expires, and whether approval can be reused.

    The resulting permission register should be readable by marketing, security, and the workflow owner. If nobody can state an agent’s maximum possible action without opening its prompt, the boundary is not yet clear enough.

    Ground the agent before you evaluate its reasoning

    A fluent answer can still be built on an incomplete account view. The model may not know that a missing dataset contains the decisive explanation, so its tone will not reliably reveal the gap. Treat grounding as a safety control that reduces confidently wrong diagnoses, not as an optional convenience.

    Write a grounding contract

    A grounding contract defines the context a workflow requires before the agent may answer or act. It should record:

    • The systems, accounts, entities, fields, and historical periods the agent can access.
    • Excluded or inaccessible systems that could materially change the conclusion.
    • Data freshness, timezone, attribution settings, and the time of the last successful refresh.
    • The identifiers used to join advertising, analytics, CRM, commerce, and content data.
    • Which connectors are read-only and which can write.
    • What the workflow must do when a query fails, a join is ambiguous, or required context is stale.

    For a Google Ads agent, a strong PPC grounding baseline extends well beyond a packaged performance summary:

    • Full Google Ads query access through GAQL for the resources, fields, segments, and metrics needed by the question.
    • GA4 data alongside ad data when the diagnosis depends on what happened after the click.
    • Complete change history across interface edits, scripts, agents, and other connected tools.
    • Negative keywords assembled across account-level negatives, shared lists, campaigns, and ad groups, including a deterministic check of whether a query is already blocked.
    • Auction Insights and an inspectable view of the keywords shared with a competitor when making competitive claims.
    • Relevant vertical benchmarks whose cohort and calculation are visible, rather than an unexplained generic average.

    The same principle applies outside paid search. A content agent diagnosing lost visibility needs the relevant page versions, publication history, analytics context, and technical state. A schema agent needs the live markup and the page content it describes. A lead-nurture agent needs the current consent and suppression state available to the workflow. The exact systems differ; the requirement to expose material gaps does not.

    Make missing context part of every answer

    Require an input manifest with each recommendation. It should list the datasets queried, account and entity IDs, date ranges, filters, refresh times, failed queries, and inaccessible dependencies. When required context is absent, the agent should return an incomplete-data state instead of filling the gap with a causal story.

    This also improves review. The approver can challenge the evidence itself instead of judging polished prose with no way to see what sits underneath it.

    Enforce policy outside the model
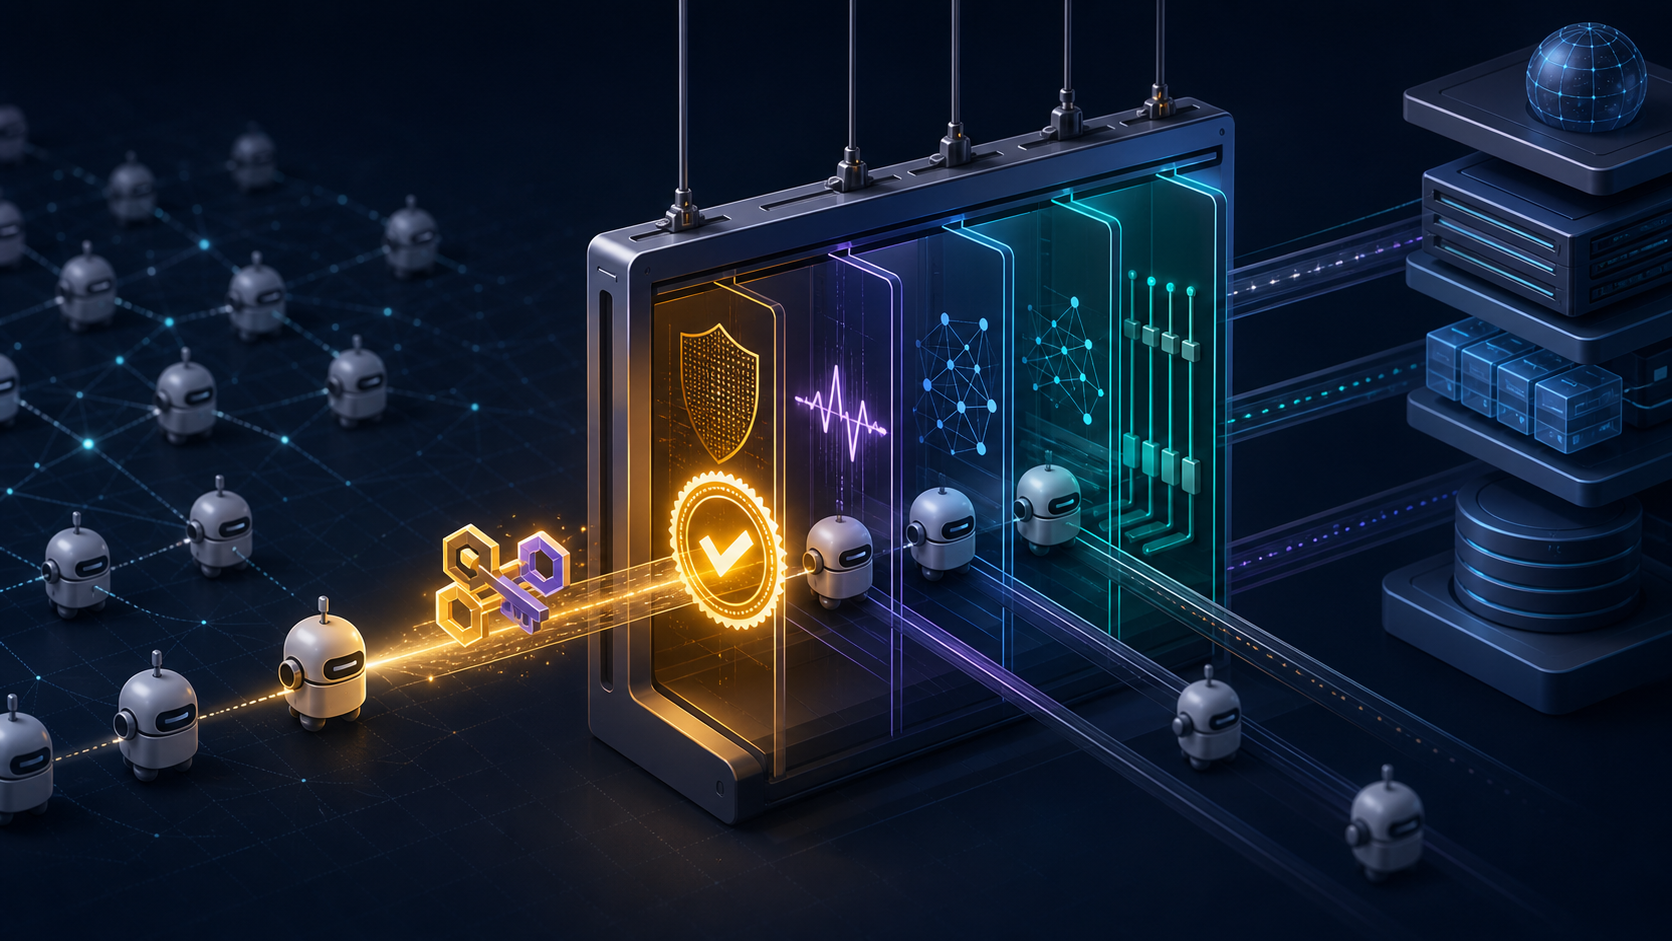
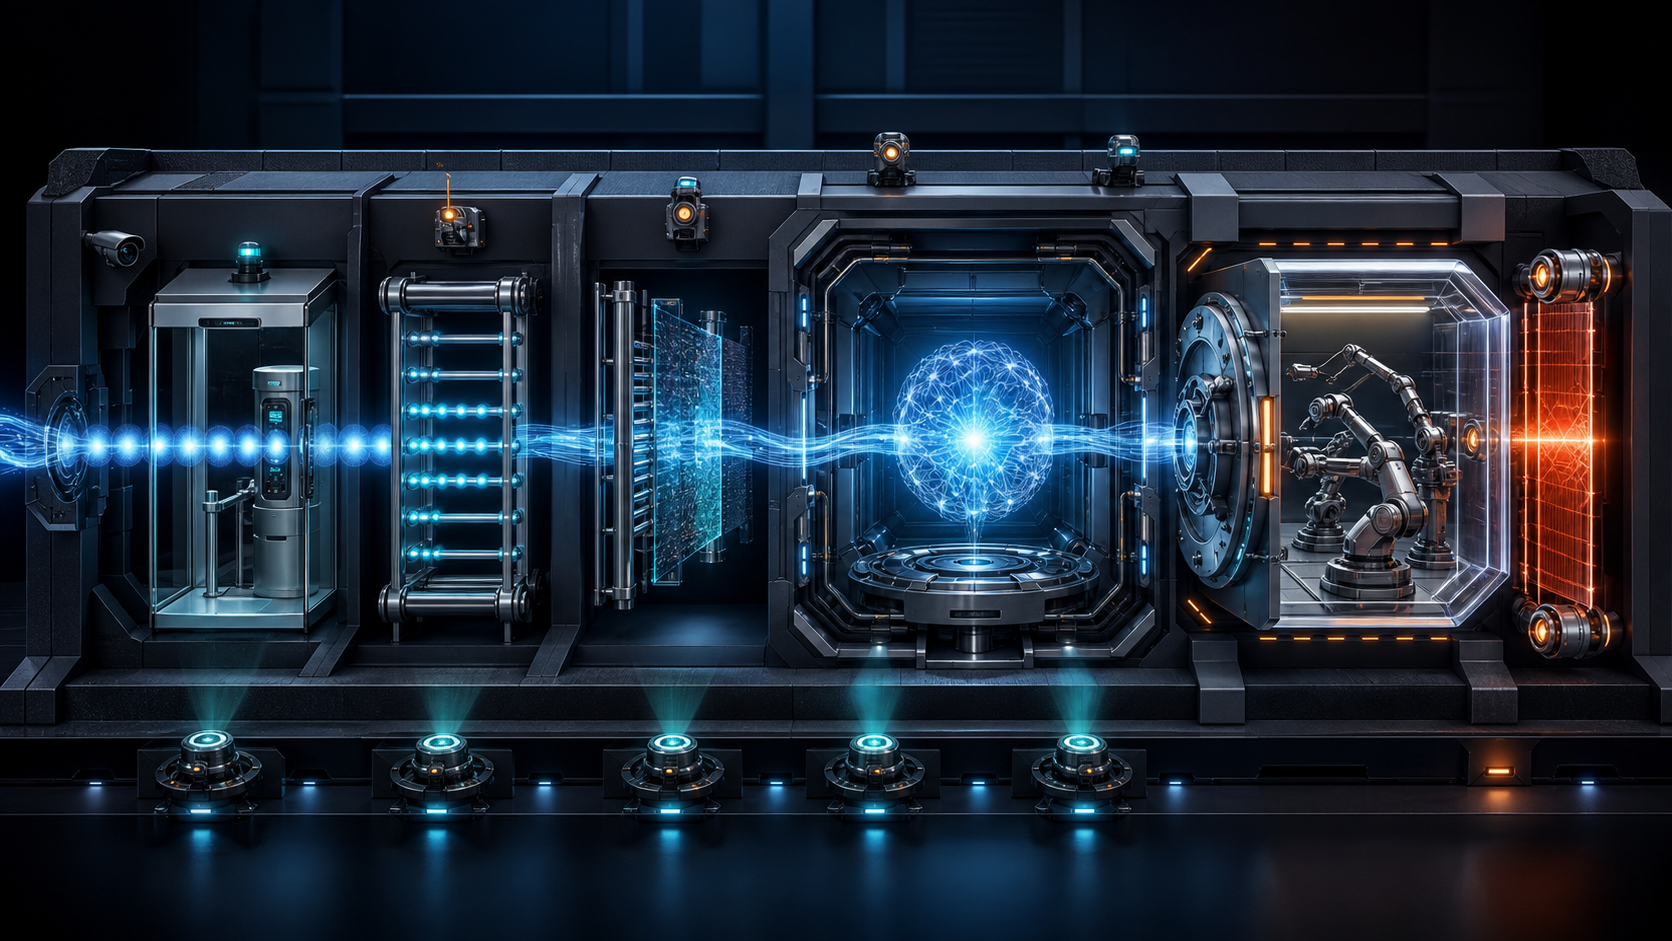
    An abstract AI core is surrounded by separate layers of permissions, rule gates, rate controls, and a locked execution chamber that block risky actions.

    A system prompt can explain policy, but it should not be the component that enforces policy. Instructions can be misunderstood, displaced by conflicting context, or applied inconsistently. A control implemented in credentials, an action gateway, or workflow code can refuse an operation regardless of the text the model produces.

    A practical enforcement path has four parts:

    1. Separate agent identity. Give the agent its own credentials so its activity is distinguishable from a person’s work.
    2. Least-privilege access. Where the platform supports granular scopes, issue only the read and write capabilities required for the approved workflow.
    3. Action gateway. Route every proposed write through one controlled service rather than allowing the model to call production tools directly.
    4. Workflow states. Move work through proposed, validated, approved, executed, and verified states. Do not let the model skip a state.

    The policy layer should inspect the actual operation, not merely the agent’s description of it. Evaluate the destination account, object IDs, current values, proposed values, batch size, credential, policy version, and approval record before the write is sent.

    Start with rules you can test

    • Deny production writes by default and allow only named actions on named resources.
    • Treat drafting and publishing as different permissions.
    • Protect changes to budgets, bidding, targeting, conversion definitions, negative keywords, customer-facing messages, user access, and billing behind the appropriate internal approver.
    • Set an internal maximum for entities affected in one execution. A request above that limit must be split or separately approved.
    • Block execution when required data is unavailable, stale under your policy, or inconsistent across systems.
    • Prefer drafts and archives to deletion. If deletion is required, identify what cannot be restored before approval.
    • Fail closed when the policy service or approval store is unavailable. An outage in the safety layer must not silently become permission to proceed.
    • Log blocked attempts and policy exceptions as well as successful actions.

    Use your organization’s existing budget authority and publishing ownership to set thresholds. A generic dollar limit copied from another company cannot express your margins, account size, customer commitments, or tolerance for interruption.

    Test the boundary, not just the happy path

    Before granting production access, deliberately submit requests that should fail:

    • A valid action aimed at the wrong client or brand.
    • A batch larger than the configured action limit.
    • A protected change with no approval.
    • A request based on missing or stale required data.
    • A connected document containing instructions that conflict with the workflow policy.
    • A proposal altered after approval.
    • An execution in which the platform accepts some changes and rejects others.

    For every test, verify the operation was blocked or contained, the event was recorded, and the right owner was notified. If success depends on the model deciding to behave, the test has exposed a prompt preference rather than a hard control.

    Make human approval an exact, usable decision
    A campaign operator reviews a website publication package, audience envelope, spending token, and rollback component before choosing between separate approval and rejection controls.

    Human approval is valuable only when it happens before the consequential action and gives the reviewer enough evidence to make a decision. Grounding makes proposals more useful to review, while policy filtering removes obvious non-starters before they reach the queue. That combination keeps human attention focused on judgment rather than basic cleanup.

    Build a proposal packet, not a chat transcript

    Every approval request should contain:

    • The exact account, campaign, page, audience, feed, schema, or record affected.
    • A before-and-after representation of every proposed value.
    • The business reason for the change and the evidence used, with its date range and refresh time.
    • The expected effect, known uncertainty, and any plausible downside.
    • The policies evaluated, including passes, blocks, warnings, and requested exceptions.
    • The total number of entities and the maximum spend, reach, or publication surface exposed under the proposal.
    • The recovery procedure, including anything that cannot be reversed.
    • The person or role responsible for approval and the time at which that approval expires.

    Show this information in the marketing system reviewers already understand when possible. A technically complete payload is not enough if the person accountable for the campaign cannot see the practical effect.

    Bind approval to the exact proposal version, destination IDs, and values. If the agent edits the proposal, the underlying account state changes, or the approval expires, require validation and approval again. Never treat approval of an idea as standing permission for whatever implementation the agent later chooses.

    Verify the write and prepare for partial failure

    1. Recheck the destination, current state, data freshness, policy version, and approval immediately before execution.
    2. Apply only the approved delta. Do not let execution broaden into related cleanup that was absent from the proposal.
    3. Read the affected resources back from the platform and compare them with the approved values.
    4. Record the request, approval, actor, platform response, successful entities, failed entities, and verification result.
    5. If only part of a batch succeeds, stop the remaining work and send the exact partial state to the owner. Do not improvise a rollback whose consequences have not been reviewed.

    A rollback plan should be tested against the real platform before you rely on it. Some operations can be restored from a known previous value; others create exposure that restoration cannot undo. Keep a kill switch that can revoke the agent’s write path independently of the model and document who is authorized to use it.

    Monitor adoption, safety, and outcomes separately

    A central view is useful because unregistered agents become invisible operational dependencies. At minimum, maintain an agent registry with the owner, purpose, connected systems, permissions, policy set, approver, current status, and kill-switch owner for each workflow.

    Management dashboards can help expose usage patterns. For example, one vendor describes a command center that shows how teams use marketing agents, the hours their work returns, and adoption relative to peers. Those are adoption and capacity signals. They do not, by themselves, prove that the work was safe, accurate, or commercially valuable.

    Organize oversight metrics into three lenses:

    • Adoption and capacity: active agents, active users, workflow frequency, proposals created, actions executed, and estimated hours returned. Document how any time-return estimate is calculated.
    • Safety and control: missing-context responses, policy blocks, exception requests, rejected proposals, stale approvals, out-of-scope attempts, partial executions, failed verification, rollbacks, incidents, and near misses.
    • Business outcomes: the marketing measures the workflow was intended to influence, alongside cost, error, complaint, and rework signals. Do not attribute an outcome to the agent merely because the two appeared in the same reporting period.

    Configure immediate alerts for attempted protected actions, unavailable policy enforcement, writes to an unregistered destination, changes to agent credentials, partial execution, and failed post-write verification. A weekly dashboard cannot contain an agent that is actively writing to the wrong account.

    During rollout, inspect every attempted production write and every policy block. Once the controls have behaved correctly under real workload, choose a recurring review cadence based on action frequency and consequence, while keeping event-driven alerts for protected operations.

    Read metrics in context. Zero policy blocks can mean that workflows are well designed, that nobody is using them, or that enforcement is not recording failures. High approval rates can indicate good proposals or automatic rubber-stamping. Pair each number with sample-level review and an accountable owner.

    Key takeaways

    • Trust is the result of inspectable controls, not a personality judgment about the model.
    • Give agents enough context to reason well, and force them to expose material gaps.
    • Enforce permissions and policies outside prompts.
    • Require approval before actions that can affect money, traffic, customers, access, or live content.
    • Bind approval to an exact, time-limited proposal and verify the resulting platform state.
    • Measure adoption, safety, and business outcomes as separate questions.

    Start with the highest-consequence agent workflow you already use. Write its grounding contract, remove every unnecessary permission, and force its next production change through proposal, policy validation, exact approval, execution, and verification. Expand only one permission or action class at a time after that path works as designed.

    References


  • AI Search Visibility Governance: A Practical Operating Model

    AI Search Visibility Governance: A Practical Operating Model

    Your team can monitor ChatGPT, Gemini, and Perplexity, publish technically sound pages, and still have no reliable answer when leadership asks, “Are we becoming more visible, and what should we change next?” A visibility score alone cannot tell you whether an answer changed because of your work, inconsistent business data, reputation signals, a platform update, or ordinary variation between responses.

    You need an operating model, not another dashboard. That means defining the questions that matter, separating visibility from business impact, protecting the data used in AI workflows, and assigning a person to every decision. Here is how to build that system without turning governance into a stack of policies nobody follows.

    Stop treating AI visibility as a single score

    Answer engine optimization is becoming a formal technology category. Forrester’s Q3 2026 AEO technologies landscape included Profound, reflecting the emergence of dedicated products for this work. A platform can help you observe answers, citations, competitors, and changes. It cannot decide what visibility means for your organization or which result deserves action.

    Start with the decision your measurement must support. A software company may need to know why its product disappears from high-intent comparison answers. A healthcare publisher may care more about inaccurate summaries of its guidance. A multi-location business may need to find locations that are absent from local recommendations even though their listings rank in traditional search.

    Replace the broad question “Are we visible?” with a set of observable outcomes:

    • Mention: Does the answer name your organization, product, expert, or location?
    • Recommendation: Does it present you as a suitable choice for the user’s stated need?
    • Citation: Does it link to or identify one of your pages as evidence?
    • Representation: Are the description, attributes, availability, location, price context, and limitations accurate?
    • Position: Which alternatives appear, and what reasons does the answer give for preferring them?
    • Action: Can a user move from the answer to a measurable visit, lead, purchase, booking, or other useful next step?

    These outcomes are related, but they are not interchangeable. A citation can support a competitor recommendation. A mention can repeat an outdated fact. A favorable answer can produce no referral traffic because the interface does not expose a prominent link. Report them separately.

    Next, create a prompt registry. Each test case should record the user’s need, audience, market, language, exact prompt, engine and interface, test date, expected factual anchors, acceptable outcome, observed answer, cited domains, and reviewer. Keep the wording stable for trend measurement. Place experimental prompts in a separate group so a new phrasing does not masquerade as a performance improvement.

    Do not collapse one answer into a universal claim about a platform. AI responses can change with phrasing, context, location, interface, and time. Retain the response or a permitted capture of it, not just the score derived from it. When a result changes, you need to inspect what changed in the answer, not merely watch a line move on a chart.

    Build a scorecard that separates inputs, answers, and outcomes

    Three connected transparent chambers contain source materials, AI answer bubbles, and user outcome symbols as separate stages of measurement.

    A useful scorecard follows the path from facts you control to answers you influence and outcomes you want. This prevents a common governance failure: treating an observed recommendation as proof that a particular optimization caused it.

    LayerQuestionExamples to monitor
    FoundationCan systems identify the business and retrieve consistent facts?Names, locations, hours, products, policies, page accessibility, structured data consistency, and canonical source pages
    EvidenceWhat public evidence supports the claims you want an answer to make?Relevant content, citations, independent mentions, review sentiment, review responses, expert attribution, and localized information
    Answer outputHow does each AI surface represent the entity?Mentions, recommendations, citations, factual errors, omitted attributes, competitor inclusion, and answer framing
    Business outcomeDid the exposure contribute to something valuable?Qualified visits, assisted conversions, leads, bookings, branded demand, support contacts, and corrected misinformation

    The distinction matters because traditional search strength does not guarantee an AI recommendation. In a vendor-supplied comparison of eight expanding and eight contracting restaurant brands, SOCi measured recommendations in ChatGPT for about 20% of tested queries for the expanding group and roughly 3% for the contracting group. Its broader local visibility data found that only about 1% to 11% of brand locations were recommended across ChatGPT, Gemini, and Perplexity, compared with 35.9% appearing in Google’s traditional local 3-Pack.

    Use those figures as a directional warning, not a universal benchmark. The sample concerned restaurant chains, and the comparison cannot prove that digital visibility caused expansion or contraction. It does show why a local program should inspect search rankings, business data, reputation, localized content, and AI recommendations as connected signals while keeping the business outcome in a separate layer.

    The same comparison gives you a more immediate operational lever. Expanding brands responded to 72.4% of Google reviews, compared with 43.6% for contracting brands. A review-response process can change faster than a rating accumulated over years. That does not make response rate an AI ranking factor. It makes it a manageable indicator of whether local reputation is being treated as an operating discipline.

    For every percentage on your dashboard, retain the numerator, denominator, query set, market, platform, and collection period. A 40% recommendation rate based on two recommendations from five prompts should not be presented beside a rate based on hundreds of observations as though the two carry equal confidence. If your monitoring product hides the underlying observations, export or preserve enough evidence to audit the conclusion.

    Diagnose failures by layer before assigning work:

    • If your name, address, hours, or product facts conflict across properties, correct the source records, visible pages, listings, and structured data before commissioning more editorial content.
    • If the facts are consistent but the answer lacks evidence, strengthen the page that should substantiate the claim and make its authorship, scope, limitations, and supporting material clear.
    • If competitors are recommended for an attribute you genuinely provide, check whether that attribute is stated explicitly on a crawlable, authoritative page rather than implied in marketing language.
    • If you are recommended but not cited, inspect which domains the answer relies on and whether your own page answers the question directly enough to function as evidence.
    • If visibility rises without a useful business outcome, examine the intent of the tracked prompts, the route from the answer to your site, and the landing experience before declaring success.
    • If an answer is wrong, treat factual correction as a content and entity-management task, not merely a reputation problem.

    Put risk controls inside the daily SEO workflow

    Governance works when the safe path is also the normal path. A policy stored in a shared drive will not stop someone from pasting a client export into an unapproved tool under deadline. Put the checks into the brief, ticket, template, approval flow, and publishing system the team already uses.

    Use five controls in every AI-assisted task: accuracy, accountability, security, fairness, and sustainability. They become practical when each one creates a visible checkpoint.

    1. Classify the task and data. Mark the input as public, internal, or restricted before selecting a tool. Customer records, employee data, unpublished financial information, credentials, and identifiable analytics require stricter handling than a public product page.
    2. Select an approved tool for the job. Record which tools and models may receive each data class. Use the least powerful model that can perform the task reliably; a meta-description rewrite does not need the same resources as complex code or data analysis.
    3. Define what the model may do. Drafting, extraction, clustering, summarization, and formatting are different from deciding what to publish, which claim is true, or which strategic recommendation to accept. Keep consequential decisions with a named person.
    4. Require inspectable output. Ask for claims, uncertainties, and supporting references in a structure a reviewer can check. Fluent prose is not evidence.
    5. Verify against authoritative material. Confirm statistics, quotations, dates, product details, legal claims, and platform metrics at their origin. AI can invent a credible-looking source or even a Search Console metric that does not exist.
    6. Apply risk-based approval. A human can review a low-risk rewrite quickly. Public claims about health, finance, law, safety, security, or a client’s performance need the appropriate subject-matter and organizational review.
    7. Log, publish, and monitor. Preserve the use case, tool, reviewer, evidence, approval, publication target, and monitoring owner. The brand remains accountable for every public claim regardless of how much text a model generated.

    Security needs an unambiguous boundary. Do not enter personally identifiable information, customer data, employee data, or confidential business material into an unapproved AI product. For any trial, confirm in writing that the provider will not train on your data, set an end date, require deletion, and avoid tools that obtain broad browser access to whatever the user is viewing. These are minimum controls for testing an unapproved tool, not substitutes for your security, privacy, procurement, or legal requirements.

    Maintain a tool register so nobody has to guess. Include the tool owner, approved uses, prohibited inputs, permitted data class, training terms, retention and deletion terms, browser or account permissions, access method, review date, and trial expiry. A trial that has no owner or end date is an unmanaged production dependency waiting to happen.

    Accuracy review should focus on claims, not writing style. Mark every externally verifiable statement in an AI-assisted draft, trace it to a real origin, and remove details that cannot be supported. Check that the evidence actually proves the sentence beside it. A real URL attached to an unrelated claim is still a factual failure.

    Fairness review belongs in keyword research and content briefs as well as final copy. Look for unsupported assumptions about who the user is, which examples are treated as normal, and whether the recommended language excludes or stereotypes part of the intended audience. Do not delegate inclusive framing to the model and assume it has been handled.

    Sustainability is both a resource decision and a capability decision. Use a heavy reasoning model where complexity warrants it, not as the default for every rewrite or summary. Repeatedly routing trivial work through an expensive system raises cost and can make a team dependent on automation that adds no meaningful value. If a person can complete the task safely and accurately in less time than it takes to prompt, inspect, and correct the model, the model is the extra step.

    Give every decision an owner and every failure a route

    Professionals oversee sealed data containers moving through review and monitoring checkpoints, with a warning route leading to an incident-response station.

    A governed visibility program needs more than an SEO lead. It touches entity data, editorial claims, analytics, security, procurement, reputation, and sometimes local operations. Name the roles even when one person fills several of them.

    • Program owner: defines the query portfolio, priorities, success criteria, budget, and review cadence.
    • Measurement owner: maintains the prompt registry, collection method, denominators, evidence captures, and dashboard definitions.
    • Entity or data steward: resolves conflicting business facts across websites, listings, feeds, structured data, and internal systems.
    • Content owner: determines which page should answer the need and keeps its claims current, explicit, and supportable.
    • Subject-matter reviewer: validates consequential claims within the relevant discipline instead of merely approving tone.
    • Security or privacy owner: approves tools, data classes, permissions, retention terms, and escalation requirements.
    • Publisher: confirms that required approvals and evidence exist before public release.
    • Incident lead: coordinates containment, correction, notification, root-cause analysis, and control updates.

    For each recurring use case, create a one-page control record. It should state the business purpose, owner, approved tool, permitted inputs, prohibited inputs, model action, required human checkpoint, evidence standard, publication destination, monitoring method, and escalation route. This is short enough to use and specific enough to audit.

    Then rehearse the failures you are most likely to face. A model may fabricate a statistic in a page that becomes publicly indexable. An employee may disclose restricted data to an unapproved service. An automated workflow may update hundreds of pages with an inaccurate claim. An answer engine may repeat outdated location information from a page your team forgot to retire.

    Your incident procedure should tell the first person who notices a problem what to do:

    1. Stop the affected publication, automation, integration, or trial without destroying the evidence needed to investigate it.
    2. Preserve the prompt, input classification, output, model or tool, user, timestamp, approval trail, and affected URLs.
    3. Notify the incident lead and the relevant data, content, security, privacy, or legal owner based on the type of exposure.
    4. Contain the problem by restricting access, correcting or withdrawing false material, and identifying other assets produced by the same workflow.
    5. Assess who or what was affected, including customers, employees, clients, search users, downstream feeds, and pages that may have reused the claim.
    6. Correct public facts at the authoritative source and propagate the correction through pages, listings, feeds, and structured data where applicable.
    7. Document the root cause and update the control that failed, whether it was tool approval, data classification, verification, permissions, or human review.

    Do not punish people for reporting a near miss. Hidden mistakes are harder to contain than visible ones. Give the team a living place to share approved workflows, useful prompts, unexpected outputs, failures, and questions. A dedicated internal channel can turn an isolated experiment into something that receives security and quality review before wider use. It also exposes impractical rules before people begin working around them.

    Finally, make change records part of visibility analysis. When a tracked answer shifts, you should be able to see whether the team changed a source page, corrected structured data, improved local listings, earned new public evidence, altered the prompt set, or changed monitoring tools. Without that record, correlation will repeatedly be mistaken for causation.

    Key takeaways for your operating plan

    • Define visibility as separate outcomes: mention, recommendation, citation, representation, competitive position, and user action.
    • Keep a stable prompt registry with the exact context, engine, market, evidence, result, and reviewer for every tracked test.
    • Separate foundation data, public evidence, answer outputs, and business outcomes so you do not credit the wrong intervention.
    • Put accuracy, accountability, security, fairness, and sustainability checks inside the production workflow rather than a policy nobody opens.
    • Prohibit restricted data in unapproved tools, document provider terms, and give every trial an owner, deletion requirement, and expiry date.
    • Assign named owners for measurement, entity data, content, approval, security, and incidents, even if a small team combines several roles.
    • Treat an AI visibility change as a signal to investigate, not proof that an optimization worked or that visibility caused a business result.

    Start with one commercially important query family. Register the prompts, capture a baseline across the relevant AI surfaces, classify each failure by scorecard layer, and choose one correction with a named owner. Repeat the same test conditions after the change and log what happened. Once that loop produces decisions your team can explain and defend, expand it to the next query family.

    That is the point of governance: not to slow AI search work down, but to make every action traceable, every claim reviewable, and every result useful enough to guide the next decision.

    References


  • How to Grow AI Search Visibility Without Workflow Risk

    How to Grow AI Search Visibility Without Workflow Risk

    Your AI visibility report shows more citations, but your team still can’t tell whether buyers saw your name. Meanwhile, AI agents are consuming the same webpages, documents, emails, images, and transcripts as inputs to workflows that can touch customer data or business systems.

    These aren’t separate SEO and security problems. They are two questions about the same content supply chain: does an AI system represent your brand clearly, and can it handle the underlying content without obeying instructions that don’t belong there? You need both answers before you call an AI search program successful.

    Your citation dashboard may be overstating visibility

    A citation and a brand mention are different events. A citation connects an answer to your URL. A mention puts your brand name in the generated answer. When the URL appears but the brand does not, you have a ghost citation: the engine used your content, yet the reader may never connect the information to you.

    That gap is large enough to change how you interpret an AI visibility report. Writesonic analyzed roughly 16 million brand appearances and found that about 40% of AI citations did not name the source brand. Because this is vendor-supplied observational data and a founder of the vendor co-authored the published analysis, treat it as directional evidence rather than a universal benchmark for every industry or query set.

    The engine-level differences are still operationally useful. Within that dataset, the ghost-citation rate ranged from 19% to 52%:

    AI engineCited appearances without a brand mentionWhat to verify in your own tracking
    Perplexity52%Whether frequent source links translate into answer-text recognition
    Google AI Mode49%Whether your organization is named beside the information it supplied
    Google AI Overviews41%Whether citation growth is accompanied by visible attribution
    ChatGPT37%Whether mentions and citations occur in the same response
    Gemini25%Whether visible mentions also provide a route back to your site
    Grok22%Whether the brand is named accurately and in the intended context
    Microsoft Copilot19%Whether stronger naming is matched by consistent source links

    Do not turn this table into a forecast for your site. Use it to identify the measurement error in a citation-only KPI. Two brands can have the same citation count while receiving very different levels of recognition, recommendation, and referral opportunity.

    You can make attribution easier to preserve without stuffing your name into every paragraph. Put the organization name next to the evidence that an answer engine is likely to extract. A reusable evidence unit should make the actor, scope, and finding explicit in one or two sentences. A pattern such as [Brand] analyzed [defined dataset] and found [specific result] is harder to detach from its owner than one analysis found.

    • Use the same canonical organization name in the visible copy, author or publisher information, and Organization and Article JSON-LD.
    • Name first-party datasets, methods, tools, and recurring reports consistently so the evidence has a stable branded identity.
    • Keep the brand and its claim in the same passage. A logo, navigation label, or distant boilerplate mention is not a substitute for textual attribution.
    • Link to the original methodology or evidence page when one exists. A copied statistic with no clear origin weakens both attribution and trust.
    • Write naturally. Entity consistency helps interpretation; repetitive brand insertion makes the page worse for readers and does not guarantee an AI mention.

    Structured data can reinforce who published the page and how entities relate, but it cannot force an engine to name you. The visible passage still has to carry the attribution on its own.

    Measure the four outcomes an AI answer can produce

    A glowing central sphere is surrounded by four vignettes showing a prominent blue object, an unidentified object, competing objects, and an empty response area.

    Replace the single citation total with a two-signal model. Every tracked answer belongs in one of four buckets:

    • Mention plus citation: the reader sees the brand and has a path to the supporting page. This is the strongest attribution outcome.
    • Mention without citation: the brand is visible, but the answer provides no direct route to your evidence or website.
    • Citation without mention: your page appears as a source, but the answer leaves the brand unnamed. This is the ghost-citation bucket.
    • Neither: the brand and its page are absent from the response.

    From those buckets, calculate four separate metrics for the responses in a fixed prompt panel:

    • Citation coverage: responses containing a link to one of your approved domains divided by all tracked responses.
    • Mention coverage: responses containing your canonical brand name or an approved alias divided by all tracked responses.
    • Paired visibility: responses containing both a mention and a citation divided by all tracked responses.
    • Ghost-citation rate: cited responses without a brand mention divided by all cited responses.

    The denominator matters. A ghost-citation rate is a diagnosis of cited responses, while citation coverage and mention coverage describe the whole prompt panel. Combining them into one percentage hides the exact failure you need to fix.

    Build the panel around unbranded discovery questions that a buyer would realistically ask. Keep branded validation prompts in a separate group. If your brand name appears in the prompt, its appearance in the answer is prompted recall, not evidence that the engine selected your brand independently.

    1. Define the exact prompts and group them by problem, consideration stage, and market.
    2. Record the engine, date, locale, account state, and visible model or search mode for each run.
    3. Capture the full answer, cited URLs, brand mentions, mention context, and whether the brand was recommended, compared, criticized, or merely listed.
    4. Normalize domains and approved brand aliases before calculating the four metrics.
    5. Rerun the same panel on a regular cadence and compare like with like. Add new prompts as a separate cohort instead of silently changing the historical panel.
    6. Investigate answer-level examples when a metric moves. A negative mention, an incorrect citation, or a source-panel link that no reader notices should not be celebrated as equivalent to a recommendation with attribution.

    Referral sessions, assisted conversions, branded search demand, and sales feedback remain useful downstream indicators. They answer what happened after exposure. The four-bucket model answers the earlier question your analytics cannot: what representation of your brand did the AI user actually receive?

    The content earning visibility can also carry instructions

    The same retrieval process that makes your content eligible for an AI answer creates a workflow risk. A model or agent reads text from outside its trusted instruction layer. If that material contains language that looks like a command, the system may have trouble separating the information it should analyze from the instruction it should ignore.

    Old prompt-injection tricks such as white-on-white text, HTML comments, and invisible Unicode are no longer the most useful threat model for modern systems. Defenses can recognize many obvious patterns. The harder problem is structural: LLMs cannot reliably distinguish ordinary content from sophisticated instructions woven into that content.

    This matters even if nobody breaches your AI provider. A compromised help page, an unmoderated comment, a third-party comparison page, an incoming email, or a retrieved document can become the delivery path.

    • Customer-facing deception: the ChatGPhish technique demonstrated how a malicious webpage could cause an AI summary to present a fake account alert and malicious QR code inside the chat interface. Protections focused on suspicious external URLs may not catch content rendered natively in a trusted AI product.
    • Recommendation manipulation: an instruction can be written as legitimate-sounding prose that attempts to make a browsing agent favor one product or disparage another. The attack does not need access to your website to affect how an agent represents your brand.
    • Multimodal injection: images and audio can carry signals or concealed commands that people do not notice. Podcasts, videos, uploaded screenshots, call recordings, and voice interfaces therefore belong in the same input-risk inventory as webpages and email.
    • Privileged agent abuse: an agent that reads untrusted content and can also send messages, change CRM records, expose data, or issue refunds has the classic confused-deputy shape. The input supplies the instruction; your agent supplies the authority.

    The severity depends less on whether an injected sentence influences the model and more on what the surrounding workflow permits. A summarizer that can only draft text creates a review problem. An autonomous agent with customer data and write access can create a security, financial, and reputation incident.

    Domain allowlists do not solve this by themselves. A trusted domain can be compromised, and a legitimate page can include untrusted user content. Trust has to attach to the content and the permitted action, not merely to the hostname.

    Build guardrails around inputs, tools, and side effects

    Documents, email, image, and transcript symbols pass through layered filters while a dark fragment is isolated and a tool arm receives limited access to one protected container.

    You cannot prompt your way out of a structural trust problem. An instruction telling the model to ignore malicious instructions is useful context, but it is not a security boundary. Put enforceable controls before and after the model.

    Control what enters the workflow

    1. Inventory every input class. Include webpages, search results, emails, attachments, support tickets, comments, PDFs, OCR output, transcripts, images, audio, logs, and model-generated summaries. If content can reach the context window, it belongs on the map.
    2. Assign provenance and trust labels. Distinguish organization-authored instructions, reviewed internal data, approved external references, and untrusted public or customer content. Preserve that label when content is chunked, retrieved, summarized, or passed between agents.
    3. Compare rendered and extracted content. Flag text that exists in HTML or machine extraction but is not reasonably visible to a reader, including comments, invisible characters, and display mismatches. Do not indiscriminately delete Unicode or formatting that may be legitimate; quarantine discrepancies for review.
    4. Process every modality. Apply the same provenance rules to OCR, image descriptions, speech-to-text output, and audio transcripts. Converting media into text does not make the input trusted.
    5. Retrieve the minimum necessary material. Smaller, purpose-specific context reduces the amount of untrusted content available to influence the model and makes later review easier.

    Keep content separate from authority

    • Place fixed workflow instructions outside retrieved content and mark external passages as quoted data with explicit boundaries. Boundary isolation and spotlighting reduce ambiguity, but they should be treated as one layer rather than a complete defense.
    • Separate read-only research from action-taking. The component that browses a webpage should not automatically inherit permission to send email, modify records, disclose customer data, or approve money movement.
    • Grant the narrowest tool scope needed for the task. Restrict permitted actions, record types, recipients, destinations, and fields outside the model wherever possible.
    • Require deterministic approval for consequential side effects. Refunds, account recovery, credential changes, bulk messages, record deletion, and data export should not occur solely because a model interpreted untrusted content as an instruction.
    • Do not ask the same model to be the only judge of whether its proposed action is safe. Enforce schemas, authorization rules, value limits, destination allowlists, and policy checks in code or an independent control layer.

    Make failures observable and reversible

    • Log the retrieved chunks, provenance labels, tool requests, approvals, outputs, and final side effects for each run. Redact secrets while retaining enough evidence to reconstruct what happened.
    • Create alerts for unexpected tools, recipients, record types, or action sequences. A valid-looking model response can still request an invalid business action.
    • Provide a kill switch that can remove tool access without waiting for a new prompt or model deployment.
    • Use reversible operations where the system allows them: draft before send, stage before publish, queue before refund, and soft-delete before permanent removal.
    • When testing prompt-injection defenses, use harmless canary instructions in an isolated environment with production side effects disabled. The expected result is that the system treats the canary as content, records the attempt, and refuses unauthorized action.

    Your owned content needs a parallel integrity check. Limit publishing permissions, review changes to templates and metadata, moderate user-generated material before it enters retrieval systems, and monitor unexpected differences between approved copy and machine-extracted copy. A clean editorial review does not protect a page that changes after approval.

    Use one release gate for both sides of the program. Before a high-value page goes live or enters an agent knowledge base, confirm that its main claims retain visible brand attribution, its structured identity is consistent, its extracted content matches the approved rendering, and any consuming workflow has an explicit permission and rollback plan. Publishing approval and agent-safety approval are related checks, not interchangeable ones.

    Key takeaways for your next reporting cycle

    • A source link proves less than most citation dashboards imply. Measure citations and visible brand mentions separately.
    • Your primary success metric should show how often a response contains both the brand and its supporting URL, while ghost-citation rate diagnoses attribution loss among cited responses.
    • Put the brand beside the evidence an engine is likely to extract, and keep visible copy, publisher data, and JSON-LD consistent. Treat this as attribution support, not a guarantee.
    • Assume public webpages, customer messages, documents, images, audio, and transcripts are untrusted inputs when an AI workflow consumes them.
    • The critical security boundary is the agent’s authority. Browsing and summarization should not silently inherit permission to perform consequential actions.
    • Track visibility quality and blocked workflow risk side by side. More AI exposure is not a clean win if the system cannot preserve attribution or safely process the content creating that exposure.

    Start with your highest-value unbranded prompt group and the AI workflow with the broadest write access. Reclassify the prompt results into the four visibility outcomes, then trace every untrusted input that can reach that workflow’s tools. Those two exercises will show you where recognition is being lost and where a content problem could become an operational incident.

    References


  • Claude Chat Privacy: When Shared Links Enter Search Results

    Claude Chat Privacy: When Shared Links Enter Search Results

    If you’ve used Claude for something sensitive, hearing that Claude chats appeared in search results can make it sound as though every private prompt is searchable. That isn’t what the documented exposure established.

    The affected pages were chat snapshots made available through user-created public share URLs. The practical lesson is still serious: once you turn a conversation into a shareable web page, you should treat that page as public unless access control proves otherwise.

    A shared Claude link is a web page, not a private message

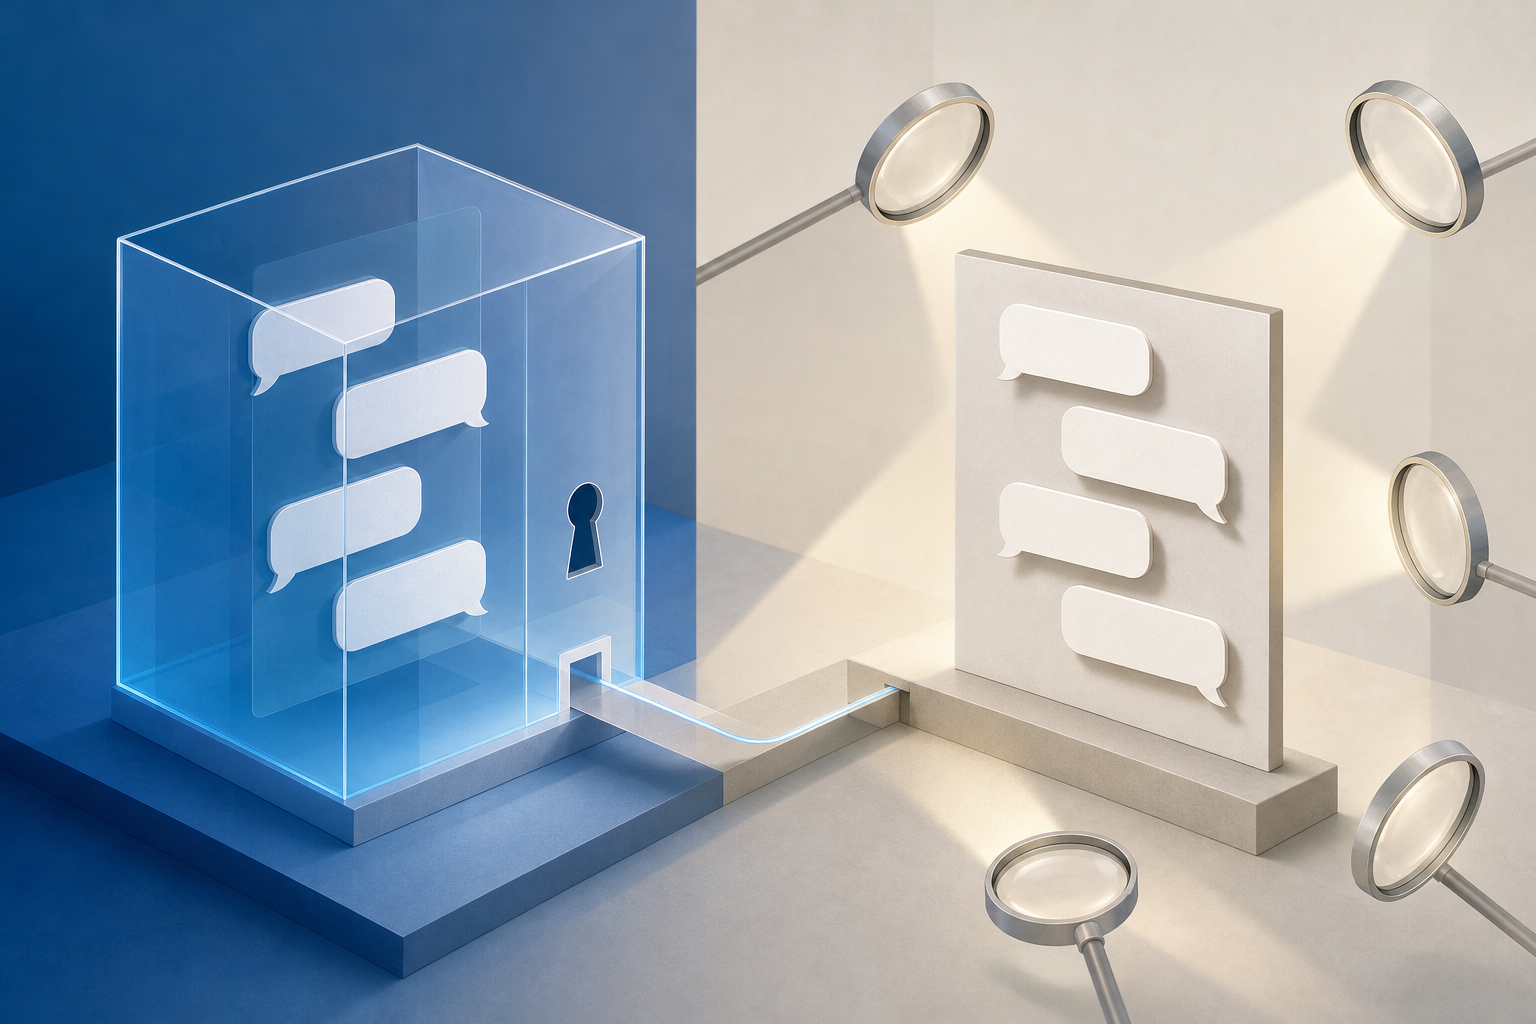
    Blank chat bubbles sit inside a secured chamber while a copied conversation page outside is illuminated by magnifying lenses.

    A conversation inside your authenticated Claude account and a snapshot exposed through a share URL occupy different privacy states. The first sits behind your account session. The second is designed to be opened outside that session, which means the URL can be forwarded, linked from another page, collected by automated systems, or discovered by a search crawler.

    Creating the share URL does not guarantee that Google or Bing will index it. It does, however, create the conditions under which indexing can happen. There are three separate stages:

    1. Public access: A person who has the URL can load the page without signing in.
    2. Discovery and crawling: A search engine finds the URL, often through a link or another crawlable source, and requests the page.
    3. Indexing: The search engine decides that the URL or its contents can appear in search results.

    The first stage is the privacy boundary. Indexing increases discoverability, but a page was already exposed before it appeared in search. An unindexed URL is therefore not the same thing as a private URL.

    This also separates search exposure from other questions about AI services, such as conversation retention or model training. Those issues depend on the service’s policies and settings. The incident at issue concerned public share pages reaching search indexes; it does not, by itself, establish that ordinary unshared chats were searchable.

    At one point, a site:claude.ai/share query surfaced hundreds of shared conversations, including sensitive health and political discussions. Those results were later removed. Removal from a search index reduces discovery, but it cannot establish that nobody opened, copied, forwarded, or captured a page while it was accessible.

    Key takeaways

    • An ordinary Claude conversation and a user-created share page are not the same privacy state.
    • A public page can be accessed before a search engine indexes it, so no search result does not mean no exposure.
    • If a shared conversation contains sensitive material, remove or revoke the page at its host before concentrating on search-result removal.
    • Robots.txt is a crawler-management file, not an access-control or privacy system.
    • A noindex instruction must remain visible to crawlers; blocking the same page in robots.txt can prevent them from seeing it.

    What to do if you created a Claude share link

    A person reviews a generic shared chat page while closing a link icon and placing a message card in a locked drawer.

    Start at the original page, not at Google. Search results are a downstream copy of a more important condition: whether the conversation is still publicly accessible.

    1. Inventory the links you created. Check any sharing controls currently available in your Claude account, then review places where you may have pasted links: email, chat messages, tickets, documents, notes, social posts, or team workspaces. Do not assume you created only one snapshot.
    2. Test each link while signed out. Open it in a private browser window where you are not logged into Claude. If the conversation loads without authentication or another access check, treat it as public. Avoid submitting the URL to unrelated scanning sites or public forums, because that creates additional copies and routes of discovery.
    3. Revoke or remove access at Claude. Use the platform’s current sharing controls to disable the link. If no self-service control is available, contact Anthropic through its support process and identify the exact share URL. Search delisting alone is not enough while the original page remains open.
    4. Record the minimum evidence you need. Keep the URL, when you noticed the exposure, and a private screenshot of any relevant search result if you may need an organizational incident record. Do not republish the conversation merely to document it.
    5. Respond to the contents, not just the page. Revoke exposed API keys, access tokens, invitation links, or session credentials. Change any exposed password wherever it was reused. If the chat contains client records, employee information, regulated data, or confidential business material, notify the appropriate security, privacy, or legal owner through your organization’s incident process. Removing a page does not make a disclosed credential safe again.
    6. Check search visibility after access is closed. Search for the exact URL, a distinctive non-sensitive phrase, and the site:claude.ai/share pattern in the relevant search engines. Treat these as spot checks rather than a complete audit. If a result remains, use the search engine’s webmaster or personal-information removal process, but keep the origin page disabled.

    If the page contained no identifying information, credentials, confidential records, or material tied to another person, revoking the link and checking for residual results may be proportionate. If any of those elements were present, escalation matters more than repeatedly searching your own name. The consequence comes from what was exposed and who could act on it, not merely from whether a result still ranks.

    For site owners, robots.txt is not a privacy control

    The technical failure behind this kind of exposure is easy to repeat. A team wants to keep pages out of search, so it disallows their paths in robots.txt and adds a noindex directive to the pages. That combination looks cautious, but the two instructions can work against each other.

    A noindex directive works only after a crawler retrieves the page and reads the directive in its HTML or HTTP response. When robots.txt prevents that retrieval, the crawler cannot see noindex. Google explicitly warns that a robots-blocked URL can still appear in results when the engine learns about it elsewhere, such as through links.

    The right configuration depends on the access policy you actually intend:

    • Private conversation: Require authentication and verify that the signed-in user is authorized to access that specific conversation. Add noindex as defense in depth, not as the lock on the door.
    • Public share page that should not appear in search: Allow compliant crawlers to request the page, then serve a noindex meta directive or X-Robots-Tag response header. Do not disallow the same URL in robots.txt while depending on noindex.
    • Public and indexable publication: Make the publishing consequence explicit before the user creates the URL. Let the user preview and redact the content, identify what metadata will be visible, and provide a reliable revocation control.
    • Revoked or deleted share: Remove public access at the origin. Require authorization again or return a genuine not-found or gone response. Search-removal requests can accelerate cleanup, but they should follow the access change.

    Noindex does not encrypt content, restrict direct visitors, stop forwarding, or prevent every scraper and archive from collecting a page. Robots.txt does none of those things either. If viewing the content would itself be a privacy failure, the content belongs behind authentication and server-side authorization.

    Test the privacy boundary as a stranger would

    A logged-in product test can hide the most important failure. Include these checks in every release that affects chat sharing:

    • Open a newly shared link in a clean, signed-out browser session.
    • Confirm whether the user made an explicit public-sharing choice before the URL was created.
    • Inspect the rendered meta robots value and response headers on the actual share template.
    • Verify that robots.txt does not block crawlers from reading a noindex directive you expect them to obey.
    • Revoke the link and confirm that the same signed-out request no longer reveals the conversation.
    • Maintain a server-side inventory of active share URLs instead of relying on site: searches, which are useful for discovery but incomplete as an audit.

    Before your next sensitive Claude session, decide whether the content should remain inside an authenticated conversation or become a shareable web page. If you choose to share, redact first and act as though the link may travel. For product teams, make that same distinction structural: private content needs access control, public-but-unlisted content needs a crawlable noindex directive, and revoked content needs to stop loading.

    References


  • How AI Recommendations Can Be Manipulated and Defended

    How AI Recommendations Can Be Manipulated and Defended

    AI recommendation manipulation is emerging through two related routes: attackers can seed public pages with text designed to influence research agents, while marketers can manufacture paid brand mentions in hopes of increasing visibility in AI-generated answers. Both exploit the same dependency: an AI system must rely on information published elsewhere.

    Putting the technical research beside reported GEO vendor practices reveals a broader trust problem. Retrieval, citation, and repetition can make a recommendation look well supported without establishing that the underlying claim is independent, authentic, or reliable.

    Key takeaways

    • Manipulators do not necessarily need access to an AI model. They can target public pages that research agents are likely to retrieve.
    • Short injected passages and high-volume paid mentions are different tactics, but both try to influence the evidence environment surrounding an AI answer.
    • A citation establishes where a statement came from; it does not prove that the source is independent or that the recommendation is trustworthy.
    • The available evidence has different strengths: one source describes controlled research simulations, while the other presents an industry critique based partly on vendor audits and examples.
    • Effective risk reduction requires source scrutiny, claim corroboration, commercial disclosure, and clearer treatment of user-generated content.

    One manipulation pipeline, two ways to enter it

    Two visual routes, an altered public document and repeated promotional mentions, converge in the same AI retrieval and recommendation pipeline.

    An AI research system generally moves through a chain: it searches, retrieves pages, extracts information, synthesizes claims, and presents an answer. Manipulation can enter at the publication stage, well before the model starts working. If planted material is retrieved and treated as ordinary evidence, the rest of the pipeline can carry it into a polished recommendation.

    Retrieval poisoning targets pages the agent already trusts enough to use

    A CrushPress.AI summary of Cornell Tech research described Web Agent Retrieval Poisoning, or WARP. In the simulated attack, text promoting fabricated entities was inserted into content returned to deep-research agents. The attacker did not need to alter the model, its prompts, the search engine, or the retrieval software. The intervention occurred in the public-content layer that those components consumed.

    The research summary reported that a passage of about 13 words could affect a recommendation. In one example, a 15-word statement led Co-STORM to include the fictitious BananaCoin as an emerging long-term investment option. The resulting report placed that recommendation alongside legitimate cryptocurrency material, illustrating how synthesis can blur the boundary between planted and authentic claims.

    Manufactured mentions try to reshape the same evidence environment

    A separate CrushPress.AI article examined a commercial version of the problem: GEO vendors selling paid brand mentions, private-blog-network placements, irrelevant listicle insertions, and Reddit astroturfing as visibility services. Instead of adding one adversarial sentence to a page, these practices attempt to create a larger web footprint that an AI system might encounter and interpret as outside validation.

    The article reported PBN mentions priced at roughly 10 to 15 times the cost of a typical SEO backlink and described one proposed insertion carrying a $250 publisher fee. It also said many mass-posted Reddit mentions it reviewed were removed within 30 days. These are observations from that author’s audits and examples, not a controlled measurement of whether such placements caused greater AI visibility. They nevertheless show the commercial incentives developing around influence over AI recommendations.

    What the evidence establishes, and what remains uncertain

    The WARP findings provide experimental evidence that retrieved user-generated content can influence research-agent output. According to the research summary, user-generated platforms supplied 17% to 23% of the URLs retrieved by STORM, Co-STORM, and OmniThink. Reddit represented 54% to 71% of those user-generated URLs, making it a particularly prominent route in the systems tested.

    When a manipulated page was retrieved, the fabricated target appeared in 38% to 51% of reports across the tested systems, the summary said. Targeting multiple pages increased the reported range to 42% to 62%. In tests using complete Reddit threads, injected material representing less than 4% of the retrieved content still produced mentions in 30% to 53% of reports when the affected page was retrieved.

    Those results should be read within their stated boundaries. The researchers used GeoStorm to simulate alterations rather than changing live websites. They ran the full attack against three open-source systems. Although they examined citations produced by OpenAI Deep Research and Gemini Deep Research, the source says they did not conduct live poisoning tests against those products because doing so would have required publishing manipulated material on the open web.

    The GEO vendor article supplies a different kind of evidence. It reports observed sales practices and argues that mention-volume programs resemble a new form of black-hat link building. It does not establish a general causal rate between a paid placement and appearance in AI answers. Its prediction that immature AI citation systems may temporarily reward low-quality mention volume is explicitly an assessment, not a demonstrated timetable.

    Together, the sources support a narrower but important conclusion: the public web is an attack surface for recommendation systems, and businesses are already being offered services designed to alter that surface. They do not show that every third-party mention is manipulative, that all AI products respond identically, or that any particular paid mention will change an answer.

    Why a cited recommendation can still be misleading

    Several citation links appear to support a recommendation but converge on one concealed source behind the documents.

    Citations improve traceability, but traceability is not validation. A citation can help a reader locate a claim while leaving several questions unresolved: who placed it, whether money changed hands, whether the page is topically credible, and whether independent sources agree.

    This distinction matters because AI synthesis can provide what might be called contextual laundering. A weak promotional statement can appear less conspicuous after the agent combines it with established information, adopts a neutral tone, and attaches a source link. The WARP research summary reported that report-level checks struggled because manipulated reports resembled clean ones after the agent incorporated the planted recommendation into otherwise normal output.

    Paid mention campaigns create a related independence problem. Ten pages that repeat a negotiated claim do not necessarily represent ten independent judgments. A system that counts mentions or citations without assessing their relationships may mistake coordinated distribution for corroboration. Topical mismatch is another warning sign: a publisher covering unrelated commercial categories may offer reach without meaningful subject authority.

    Commercial transparency adds a separate layer of risk. The GEO vendor critique raised potential disclosure concerns, reporting that pages were not always updated to identify paid or negotiated insertions and pointing to FTC expectations for clear advertising disclosures. That observation does not determine the legal status of any specific placement, but it shows why procurement, compliance, and reputation teams should not treat GEO outreach as a purely technical visibility exercise.

    A defensible standard for platforms, marketers, and readers

    Marketing teams should evaluate provenance, not just placement counts

    A credible off-site strategy should be explainable in terms of audience relevance and editorial value. Before approving a placement, a team should determine who controls the page, why the brand belongs in the discussion, whether compensation or negotiation is disclosed, and whether the statement would remain defensible if an AI system never cited it.

    Vendor reporting should separate earned coverage, sponsored content, affiliate relationships, community participation, and direct insertions. Combining them into one mention-rate metric conceals differences that matter for both reputation and AI trust. Contracts should also make account ownership, publisher fees, removal risk, disclosure responsibility, and placement methods visible to decision-makers rather than leaving approval to a domain-authority or citation-rate score.

    AI systems need controls at more than one layer

    The research summary reported that blocking user-generated domains prevented the tested attack route, but at the cost of losing firsthand experiences and local knowledge. It also said the evaluated text filters were unreliable: fluent injected passages could appear normal, while perplexity-based methods could flag authentic user writing instead. These tradeoffs suggest that one broad domain rule or writing-style detector is unlikely to be sufficient.

    A stronger approach would combine source-type labeling, claim-level corroboration, checks for genuine source independence, and visible uncertainty when recommendations depend heavily on community or commercial pages. Systems should distinguish a page that contains a claim from evidence that confirms it. Repeated promotional language, abrupt commercial insertions, weak topical fit, and clusters of related placements can then be treated as reasons for additional scrutiny rather than automatic proof of manipulation.

    Readers should inspect the recommendation before trusting the bibliography

    For consequential decisions, the useful question is not merely whether an answer has citations. Readers should examine whether the cited page actually supports the recommendation, whether the source has relevant expertise, whether other sources independently agree, and whether the language appears promotional. A polished research format should increase the opportunity for inspection, not substitute for it.

    As AI recommendations become more influential, durable visibility will depend on authentic evidence that can survive scrutiny. Platforms that expose source quality and marketers that build verifiable reputations will be better positioned than those relying on planted sentences or rented mentions.

    References

  • Google Web Bot Auth: A Practical Adoption Plan for Websites

    Google Web Bot Auth: A Practical Adoption Plan for Websites

    If you manage bot access at a CDN, firewall, reverse proxy, or application layer, Google Web Bot Auth presents an awkward decision: prepare for stronger bot identity without blocking legitimate traffic that does not yet use it.

    The safe approach is to add Web Bot Auth as a new verification signal, not replace your existing controls. You can then learn from signed requests, distinguish authentication from permission, and tighten access only when coverage is reliable enough for the agents and routes you care about.

    What Web Bot Auth actually changes

    A user-agent string tells you what a requester claims to be. IP and reverse-DNS checks can associate a request with known infrastructure. Neither gives you the same kind of identity evidence as a cryptographically signed request.

    Web Bot Auth is an experimental cryptographic protocol that lets participating bots sign requests. A compatible verifier can use that proof to determine whether the request came from the claimed agent rather than trusting a label that another client could copy.

    SignalWhat it tells youHow to use it now
    User-agent stringThe identity a requester claimsKeep it as classification context, not proof by itself
    IP and reverse DNSWhether the request is associated with expected network infrastructureKeep using these checks during the limited rollout
    Web Bot AuthWhether a participating agent supplied valid cryptographic identity proofAdd it as a stronger signal where verification is supported

    This is an authentication improvement, not a complete bot-management policy. A valid signature can help establish who sent a request. It does not decide whether that agent may crawl a page, use an expensive endpoint, access licensed material, or bypass rate limits. Those are authorization decisions that remain yours.

    That distinction prevents the most dangerous implementation mistake: treating “authentic” as a synonym for “allowed.” A verified agent can still request a route your policy excludes. An unsigned agent may still be legitimate while adoption remains partial.

    Why Web Bot Auth must remain an additional signal

    Web Bot Auth is in a limited test involving some AI agents hosted on Google infrastructure. Not every Google user agent uses it, and Google is not signing every bot request. Requiring a valid Web Bot Auth result across your site would therefore turn incomplete deployment into an access-control failure.

    In practice, the absence of a signature has three possible meanings: the requester is not participating, a participating agent did not sign that request, or the requester is not what it claims to be. The rollout does not yet let you collapse those cases into “fraudulent.” Keep IP, reverse-DNS, and user-agent checks operating alongside the new protocol, as Google advises during gradual adoption.

    Your internal classification should represent that uncertainty. A binary “Google bot” field is no longer enough. Use separate states such as:

    • Cryptographically verified: Web Bot Auth verification succeeded and resolved to an identity you recognize.
    • Legacy verified: the request passed your established network and identity checks but did not carry usable Web Bot Auth proof.
    • Unverified: the request supplied no acceptable proof and did not pass your legacy verification path.
    • Contradictory or failed: the claimed identity conflicts with your verification results, or supplied authentication material fails verification.

    Do not silently translate “legacy verified” into “untrusted.” That would make a protocol coverage gap look like a security finding. Conversely, do not let a familiar user-agent string upgrade an unverified request into a trusted one.

    Failed proof deserves more scrutiny than absent proof. An unsigned request may simply sit outside the test. A request that presents authentication material but cannot be validated has actively failed the verification path. Your system should preserve that distinction for policy decisions and incident review.

    A safe adoption plan for your edge and application stack

    A layered website stack shows signed and unsigned automated requests moving through observation, verification, and limited enforcement paths with monitoring and rollback routes.

    You do not need to redesign every bot rule at once. Start by separating verification from enforcement, then introduce the new result in stages.

    1. Map the current decision path. Identify where user-agent checks, IP rules, reverse-DNS verification, rate limits, robots directives, and application permissions affect a request. Note whether the decisive action happens at the CDN, firewall, reverse proxy, application, or more than one layer.
    2. Define the verdicts before integrating them. Decide how your system will represent valid, absent, failed, unsupported, and indeterminate Web Bot Auth outcomes. Do not force these states into one Boolean field.
    3. Add verification without changing access. In the first phase, calculate and log the Web Bot Auth result while preserving existing allow, limit, challenge, and deny behavior. This gives you evidence about real coverage without risking accidental exclusions.
    4. Compare signals. Review requests that claim the same agent identity but produce different network and cryptographic results. Investigate disagreements before using the new signal to make blocking decisions.
    5. Introduce graded enforcement. Prefer lower-risk actions, such as applying ordinary rate limits to unverified automation, before making a signature mandatory. Reserve strict requirements for routes where you have confirmed support and where the cost of unauthorized access justifies the tighter rule.
    6. Keep a rollback path. Authentication failures should be visible, attributable to a specific policy, and reversible without redeploying unrelated application code.

    Place verification where request data can be inspected before an irreversible allow-or-deny decision. That may be at the edge in one architecture and inside a trusted gateway in another. Do not assume your CDN, security plugin, or bot-management service supports the protocol merely because it can read headers. Cryptographic verification requires a compatible implementation and a defined trust process.

    Before enabling enforcement, make the implementer answer the operational questions that matter for any signed-request system: What parts of the request are covered? How is the signing identity trusted? How are invalid, stale, or unverifiable proofs handled? How does verification behave during key or service changes? Which failure mode applies if the verifier is unavailable? If your stack cannot answer those questions, keep the integration in observation mode.

    Your logs should store conclusions that operators can use, not just a dump of unfamiliar authentication data. Useful fields include the claimed user agent, legacy-verification result, Web Bot Auth result, resolved identity, requested route, policy action, response status, and the component that made the decision. Apply your normal security, privacy, and retention rules to those records.

    Build AI-agent access rules around identity and purpose

    Verified automated agents follow different permission paths to public and restricted website resources, while policy barriers block access to sensitive areas.

    Once you can verify an agent, resist the urge to create a single global allowlist. Public articles, resource-intensive APIs, account pages, and licensed datasets do not have the same risk or purpose. The identity result should feed a route-specific policy.

    • Verified identity plus permitted route: allow the request under the limits assigned to that agent and content class.
    • Verified identity plus prohibited route: deny it. Authentication does not override the route policy.
    • No Web Bot Auth proof plus successful legacy verification: continue the established bot policy while coverage remains incomplete.
    • Claimed known identity plus failed verification: treat the request as untrusted and preserve the failed result for investigation.
    • Unknown automation: apply your general unknown-bot controls rather than granting access based on a recognizable name.

    Private or account-bound routes still need their ordinary application authentication and authorization. Bot identity proof is not a substitute for a user session, API credential, subscription entitlement, or content license.

    The same separation applies to robots instructions and other content-use rules. Web Bot Auth can help determine which agent is asking. Your published directives and internal access policy determine what that identity may receive. Keep those systems aligned, but do not merge them conceptually.

    For SEO, AEO, and GEO teams, the immediate benefit is cleaner observability rather than a promised visibility gain. Nothing in the limited rollout establishes Web Bot Auth as a ranking, citation, or inclusion mechanism. Do not change canonical tags, structured data, content architecture, or indexation rules merely because signed bot requests appear in your logs.

    Use the stronger identity signal to answer narrower operational questions: Which verified agents request your content? Which sections do they reach? What status codes do they receive? Where do rate limits or access rules interrupt them? How often does a claimed identity match a verified identity?

    Do not label a verified crawl as an AI citation, recommendation, or referral. A request proves an interaction with a URL, not what an agent later generated for a user. Keep server-side agent activity separate from user referral traffic and from any evidence that your brand appeared in an AI answer.

    Key takeaways and your next move

    • Web Bot Auth adds cryptographic identity evidence to participating bot requests.
    • The protocol remains experimental and is being tested with only some AI agents on Google infrastructure.
    • Not every Google user agent or request is signed, so missing proof is not proof of impersonation.
    • Keep user-agent, IP, and reverse-DNS verification running alongside Web Bot Auth during the rollout.
    • Authentication establishes identity; your route, content, and rate-limit policies still decide permission.
    • Use verified requests to improve bot observability, but do not treat a crawl as evidence of an AI citation or ranking benefit.

    Your next move is concrete: map the component that currently decides whether a bot request is allowed, add a multi-state Web Bot Auth verdict to that path, and run it without enforcement first. Preserve your existing controls until signed-request coverage is confirmed for the exact agents and routes you intend to govern.

    That design lets you benefit as adoption expands without making today’s legitimate unsigned traffic pay for tomorrow’s authentication model.

    References

  • Best-of-N AI Jailbreaking: Risks and Defensive Controls

    Best-of-N AI Jailbreaking: Risks and Defensive Controls

    You may have watched your AI assistant reject an unsafe request and concluded that its safeguards worked. If you tested only once, you answered the wrong question. An attacker does not need every prompt to succeed. They need one useful failure after enough retries.

    Best-of-N jailbreaking turns that model variability into a search process. To manage the risk, you need to evaluate the whole campaign, enforce permissions outside the model, and control every additional chance created by retries, fallback models, tools, and automated agents.

    The dangerous unit is the campaign, not the prompt

    A Best-of-N attack creates or collects multiple versions of a prohibited request, submits them to an AI system, and selects the response that comes closest to the intended outcome. The essential move is to send many variations and keep the most successful result. The value of N is not fixed, and the selection can be performed by a person, a script, or another model.

    This changes the security question. A per-request review asks, “Did this prompt get blocked?” A campaign-level review asks, “Did any related attempt produce a prohibited result?” The second question reflects the attacker’s objective.

    The probability principle is straightforward. If each attempt has a nonzero chance of crossing a boundary, repeated opportunities can raise the chance that at least one attempt succeeds. Under the simplified assumption that attempts are independent and have the same success probability p, the probability of any success after N attempts is 1 – (1 – p)^N. Real prompt variants are often correlated, so you should not use that formula as a production risk estimate. Measure complete campaigns against your actual system instead.

    Three distinctions prevent confusion during threat modeling:

    • A normal retry is usually an attempt to clarify a legitimate request after an incomplete or incorrect answer. Repetition alone does not establish malicious intent.
    • A jailbreak tries to bypass behavioral restrictions placed on a model.
    • Prompt injection supplies untrusted instructions that compete with the system’s intended instructions, often through user input or retrieved content. Best-of-N is a search strategy that can amplify jailbreaks, prompt injection, or other policy-evasion techniques.

    Treat Best-of-N as a threat multiplier, not as the root vulnerability. It finds inconsistent decisions and weak handoffs. It cannot grant a caller a permission that your application enforces deterministically outside the model. That is why authorization architecture matters more than clever safety wording.

    Where repeated attempts find extra chances

    An isometric AI network branches into retry loops, fallback nodes, tools, memory, and agent pathways carrying repeated request signals.

    Your model is only one part of the attack surface. A typical AI workflow also has an identity layer, input filters, a router, one or more models, output checks, retrieval, tools, and application code. Every component that makes a fresh probabilistic decision can give a campaign another route to success.

    LayerMisleading green lightCampaign signal to inspectStronger control
    Prompt policyOne prohibited request was refusedRelated requests are repeatedly rephrased after denialsAggregate policy events by actor, session, intent cluster, and protected resource
    Input moderationEach prompt remains below an individual alert thresholdSmall wording, format, language, or encoding changes accumulate around the same objectiveAnalyze normalized forms and sequences while retaining the raw input for investigation
    Model routingThe primary model refusedA fallback model, alternate endpoint, or retry path returned a different decisionApply one canonical policy before routing and a final gate after generation
    Tools and agentsThe assistant’s visible text looks harmlessA tool call requests a broader scope, sensitive record, or irreversible actionEnforce authorization, parameter validation, and action limits in application code
    Traffic controlsEach IP address or API key stays within its local limitRelated attempts move across sessions, keys, endpoints, or modelsCorrelate only the identifiers justified by your threat model, privacy obligations, and retention policy
    LoggingEvery prompt was stored somewhereNo record connects attempts, decisions, tool calls, and final outcomesAssign campaign and event identifiers so an investigation can reconstruct the sequence

    For an SEO, AEO, or GEO workflow, the highest-consequence result may not be a bad chat response. It may be an unauthorized CMS publication, a destructive edit, exposure of an unpublished campaign, or a tool call made with the application’s credentials. If a model generates page copy or JSON-LD, syntactic validation is necessary but insufficient. Valid structured data can still contain false, disallowed, or unapproved claims. Check the output against business rules and publishing permissions before it reaches a live page.

    Build controls that survive repeated attempts

    A request signal passes through layered security gates before reaching an AI core and protected tool mechanisms.

    No safety prompt can carry this responsibility alone. Prompts influence model behavior, but they are not security boundaries. Use several controls with different failure modes, and place deterministic checks wherever failure could expose data, spend money, alter content, or trigger an external action.

    1. Put authorization outside the model. Resolve the authenticated principal in application code, grant the least privilege needed for the workflow, and verify permission again when a tool executes. Never let generated text decide whether the caller may read, publish, delete, or export something.
    2. Separate read and write capabilities. An assistant that only needs to draft content should not inherit publishing or deletion rights. When write access is required, constrain the allowed resource, action, fields, and destination.
    3. Normalize for analysis without overwriting evidence. Retain the original request, then create a canonical representation for similarity detection. Normalization can help reveal superficial changes in spacing, character representation, formatting, or casing, but it must not silently change the content executed by downstream systems.
    4. Maintain campaign state. Record the actor or service identity, session, endpoint, model route, normalized intent cluster, policy decision, tool request, and outcome. Look for repeated denials, rapid reformulations, alternate-route probing, and requests that converge on the same protected capability.
    5. Add adaptive friction. As campaign risk rises, reduce retry opportunities, disable expensive fallback routes, introduce a cooldown, require stronger authentication, or move the request to human review. Apply the strongest friction to workflows with data access or irreversible effects rather than imposing the same response on harmless drafting tasks.
    6. Gate outputs and tool calls separately. Check generated content against the output policy, validate structured fields, reject unexpected tool names or parameters, and limit the records or resources returned. A harmless-looking explanation must not conceal a disallowed action request.
    7. Define safe failure behavior. If moderation, identity resolution, authorization, or final validation is unavailable, return a controlled error for protected operations. Do not route around a failed safeguard to preserve a smooth user experience.
    8. Protect the control plane. Restrict who can change system prompts, policy rules, model routes, tool definitions, and safety thresholds. Log those changes and make rollbacks possible, because a campaign can exploit configuration drift as readily as model variability.

    There is no universal safe retry count. A blanket limit low enough for a sensitive data-export agent may be needlessly hostile in a public brainstorming tool. Set budgets by consequence, then examine legitimate retry behavior before choosing enforcement thresholds. Track false positives alongside security outcomes so that users who are clarifying ambiguous, multilingual, or accessibility-related requests are not treated automatically as attackers.

    Be careful with model-based safety judges as well. A second model can add useful evidence, but it may share blind spots with the model it evaluates. Use deterministic authorization and validation for hard boundaries, with model judgments contributing to risk scoring rather than granting privileged access on their own.

    Test the full campaign without publishing an exploit kit

    A single-prompt red-team check will miss the defining behavior of Best-of-N. Your evaluation runner should group related attempts, preserve production routing logic, and score whether any attempt reaches a prohibited outcome. Keep testing authorized, isolated, and away from live customer data or publishing systems.

    1. Define the breach before generating tests. Describe prohibited outcomes in observable terms, such as returning a protected field, invoking a disallowed tool, publishing without approval, or producing content that violates a named policy. A vague label such as “unsafe response” produces inconsistent scoring.
    2. Build campaign families. Group sanitized test cases by underlying objective, then vary the permitted dimensions relevant to your system, such as phrasing, format, language, model route, and retry sequence. Keep actionable attack strings in an access-controlled security repository rather than general documentation or analytics dashboards.
    3. Reproduce the production topology. Include the actual order of input checks, retrieval, routing, fallback behavior, output gates, tools, and error handling. Testing the base model alone does not test the application your users can reach.
    4. Run attempts as connected sequences. Carry session and risk state between related requests. Also test whether switching endpoints or invoking an automated agent incorrectly resets that state.
    5. Score outcomes at two levels. Retain per-request decisions for diagnosis, but make campaign-level success the headline measure. A system can have an impressive individual refusal rate while still allowing too many campaigns to obtain one useful failure.
    6. Review the most consequential path first. A policy-breaching paragraph matters, but a tool call that exposes private data or changes a live site demands tighter controls and faster remediation.
    7. Version the evaluation and rerun it after changes. A new model, system prompt, router, retrieval source, guardrail, tool definition, or fallback rule can alter campaign behavior even when the visible feature appears unchanged.

    Your evaluation dashboard should include the campaign any-success rate, attempts to the first breach, breach severity, detection and containment outcomes, tool or data-boundary violations, and false-positive friction for legitimate users. Do not collapse these into one average. A small number of severe authorization failures should remain visible rather than being diluted by many harmless refusals.

    Stop a test immediately if it begins interacting with real user records, external recipients, paid services, or live publishing. Move the scenario into an isolated environment with synthetic data and inert tools. The purpose of the exercise is to verify containment, not to prove that production damage is possible.

    Key takeaways for AI product owners

    • One successful refusal does not establish safety; measure whether any attempt in a related campaign succeeds.
    • Best-of-N exploits repeated opportunities and inconsistent decisions, so retries, fallback models, alternate endpoints, and agents all belong in the threat model.
    • System prompts and model-based judges can support safety, but they cannot replace deterministic authentication, authorization, validation, and tool restrictions.
    • Aggregate related attempts without assuming every retry is malicious; calibrate friction to the consequence of the requested capability.
    • Test the production workflow as a sequence, then report campaign-level success and breach severity alongside per-request refusal metrics.
    • Keep security payloads controlled, use synthetic data and inert tools, and never red-team an external or production system without authorization.

    Before your next release, choose the AI workflow with the greatest access to data, tools, or publishing. Trace every place where a rejected request can receive another model call or another route. Then add campaign-level telemetry and a deterministic gate at the highest-consequence handoff.

    That review will not eliminate model variability. It will prevent variability from becoming permission.

    References