Category: Generative Engine Optimization (GEO)

  • AI Search Visibility: A Practical 90-Day AEO Strategy

    AI Search Visibility: A Practical 90-Day AEO Strategy

    If your conventional rankings look respectable but your brand rarely appears in AI-generated answers, adding more pages or rolling out schema across the site is a poor first move. You first need to locate the break: can the system find your content, understand it, select it for the question, and represent it accurately?

    A useful answer engine optimization strategy connects those stages. It starts with the questions that matter to your audience, assigns each question to a credible page, removes technical barriers, and measures what actually appears across AI search surfaces. Here is how to build that system over a focused 90-day cycle.

    Key takeaways

    • AEO does not replace SEO. A page still needs to be accessible, indexable, relevant, and understandable before an answer engine can use it.
    • Optimize around question-and-answer relationships, not isolated keywords. Each priority question needs a canonical page, a direct answer, supporting evidence, and clear boundaries.
    • JSON-LD should confirm what a visitor can already see. It cannot compensate for thin content, contradictory facts, or blocked pages.
    • Measure brand mentions, cited URLs, answer accuracy, and useful visits separately. A single visibility score hides the reason you are winning or losing.
    • Use a 90-day cycle to establish a baseline, repair priority pages, rerun the same prompt set, and decide the next round of work.

    Diagnose the visibility failure before you optimize

    AI visibility is not one event. It is a chain of events, and each link can fail for a different reason:

    1. Discovery: the system must be able to reach or otherwise encounter the page.
    2. Interpretation: it must identify the subject, entities, claims, and relationships correctly.
    3. Selection: the content must be useful for the particular question, not merely related to its general topic.
    4. Composition: the answer must preserve your meaning while deciding whether to name or link to you.
    5. Conversion: the resulting mention or citation must help the reader take a relevant next step.

    You usually cannot see an AI product’s internal retrieval process. Work from observable signals instead. If the preferred page is missing from conventional search indexes, fix technical discovery first. If competing pages answer the question precisely while yours circles the topic, repair the answer. If your brand appears with the wrong description, resolve inconsistent entity information across the site. If you earn citations but visitors reach a generic page with no useful continuation, fix the landing experience.

    Keep these failure types separate in your reporting. A brand mention is not automatically a citation. A citation is not automatically an accurate recommendation. An accurate recommendation is not automatically a visit. Combining them into one score produces a number you can present, but not a diagnosis you can act on.

    Your baseline should record the exact question, the AI surface and mode used, the response, whether the brand appeared, whether a source link appeared, which URL was cited, whether the answer was materially accurate, and when the observation was captured. Visibility now spans environments such as ChatGPT, Google, Perplexity, and Meta AI, but their behavior and access to web material can differ. Record the surface rather than treating AI search as one interchangeable channel.

    Use the same wording and comparable conditions when you repeat a prompt. Even then, regard each response as an observation rather than a permanent ranking. Generated answers can vary, so a defensible trend comes from a consistent log, not a single favorable screenshot.

    Build an answer map around decisions, not keyword variants
    Hands connect decision symbols to individual content-page tiles on a clean strategy workspace.

    A keyword list tells you how people phrase a topic. An answer map tells you what they need to understand or decide. That distinction matters because an AI response normally resolves a question, combines supporting details, and anticipates a follow-up. A page targeting a broad phrase can rank conventionally yet still supply no clean answer to reuse.

    Build the map in this order:

    1. Choose the audience decision. Write down what the person is trying to choose, fix, verify, compare, or complete.
    2. State the core question in natural language. Use the wording a buyer, practitioner, or stakeholder would recognize, not an internal product label.
    3. Add the necessary follow-ups. Include the definition, criteria, process, limitations, alternatives, and failure conditions that affect the decision.
    4. Assign a canonical page. Decide which existing or planned URL should provide the strongest complete answer.
    5. Specify the required evidence. Mark which claims need primary citations, visible calculations, product documentation, examples, or a clear explanation of methodology.
    6. Define the next useful action. Decide what the reader should be able to inspect, compare, configure, or request after receiving the answer.

    For an AEO audit topic, for example, the cluster might include: What counts as an AI search appearance? Which questions should be monitored? What can prevent a page from being used? When does structured data help? How should an inaccurate brand description be corrected? What evidence would show that visibility improved? Those are connected information needs, not six excuses to publish near-duplicate pages.

    Give each page an answer contract

    Before revising a page, complete this sentence: For this audience making this decision, the page will answer this question using this evidence, while making these limits clear. If you cannot fill in every part, the brief is still too vague.

    The answer contract prevents three common forms of content sprawl. It stops one page from trying to serve unrelated intents. It stops several pages from competing to provide the same answer. It also exposes evidence gaps before polished copy disguises them.

    Do not create a separate URL for every prompt variation. Consolidate questions that share the same intent and evidence. Give a question its own page only when the answer, audience, proof, or next action is materially different. Otherwise, use descriptive subheadings and internal links to help readers and machines reach the relevant answer unit.

    Engineer pages that are extractable and hard to misread

    Clear technical access before rewriting copy

    Review the preferred URL as a retrievable document. Confirm that it loads successfully without authentication, is not excluded by a robots directive, does not carry an unintended noindex instruction, and declares the canonical URL you expect. Make sure the important answer is present in the rendered page and can be reached through ordinary internal links.

    Also look for contradictions created by migrations and templates: an old canonical pointing elsewhere, several live versions of the same answer, a title that names one product while the body describes another, or structured data carrying details that no longer appear on the page. Rewrite work will not solve those defects.

    For Google AI Overviews, indexation, relevance, useful structure, and well-supported information belong in the same optimization workflow. Treating AEO as a decorative layer applied after technical SEO leaves the discovery link unresolved.

    Write answer units that can stand on their own

    Place a direct response immediately after the heading that asks or frames the question. The opening sentence should name the subject explicitly and resolve the central point. Follow it with the qualification that changes how the answer should be used.

    For example, a weak opening says that modern brands need to adapt to a changing landscape. A usable opening says: Answer engine optimization is the practice of making content easier for answer systems to find, interpret, select, and represent when responding to a question. The second version defines the entity and its purpose without forcing a reader to reconstruct the meaning from surrounding copy.

    A strong answer unit usually contains:

    • The direct answer: a short passage that resolves the question without a promotional preamble.
    • The scope: the audience, platform, condition, or use case for which the answer holds.
    • The support: evidence or reasoning placed beside the claim it supports.
    • The boundary: an exception, limitation, or condition that prevents an overbroad interpretation.
    • The continuation: the next question or action a reader is likely to need.

    Resolve ambiguous pronouns and labels. Use the full brand, product, organization, or method name where a passage must remain understandable outside its surrounding paragraphs. Keep terminology consistent unless you are explicitly defining synonyms. If two terms mean different things, say where the boundary lies instead of rotating them for variety.

    Put evidence near the claim. Link material factual statements to the best available originating authority. Label proprietary observations as such, explain how internal figures were produced, and include the applicable date or version when a fact can change. Citation density is not the goal; claim-level traceability is.

    Use JSON-LD to corroborate the visible page

    Structured data works best as a machine-readable confirmation of content that is already clear to a visitor. Choose types and properties that accurately describe the page you have, not the search feature you hope to win. Keep names, URLs, organizational relationships, authorship, dates, and other shared facts aligned with the visible copy.

    Only mark up information that genuinely appears on the page. An FAQ structure should correspond to visible questions and answers. An organization relationship should agree with the site’s About and contact information. If the JSON-LD calls something a product while the page presents a general service or an editorial resource, correct the model rather than adding more properties.

    Validate syntax, but do not stop at syntax. A technically valid graph can still be semantically wrong. Review the rendered page and the JSON-LD side by side, compare identifiers and canonical URLs, and treat every mismatch as a data-quality defect. Schema can reduce ambiguity; it cannot manufacture authority, evidence, or relevance.

    Internal linking should reinforce the same model. Link from supporting pages to the canonical answer using anchor text that describes the relationship. Connect definitions to procedures, procedures to limitations, and comparisons to the underlying product or service facts. That creates a navigable information structure rather than a collection of isolated articles.

    Run the work as a 90-day AEO operating cycle
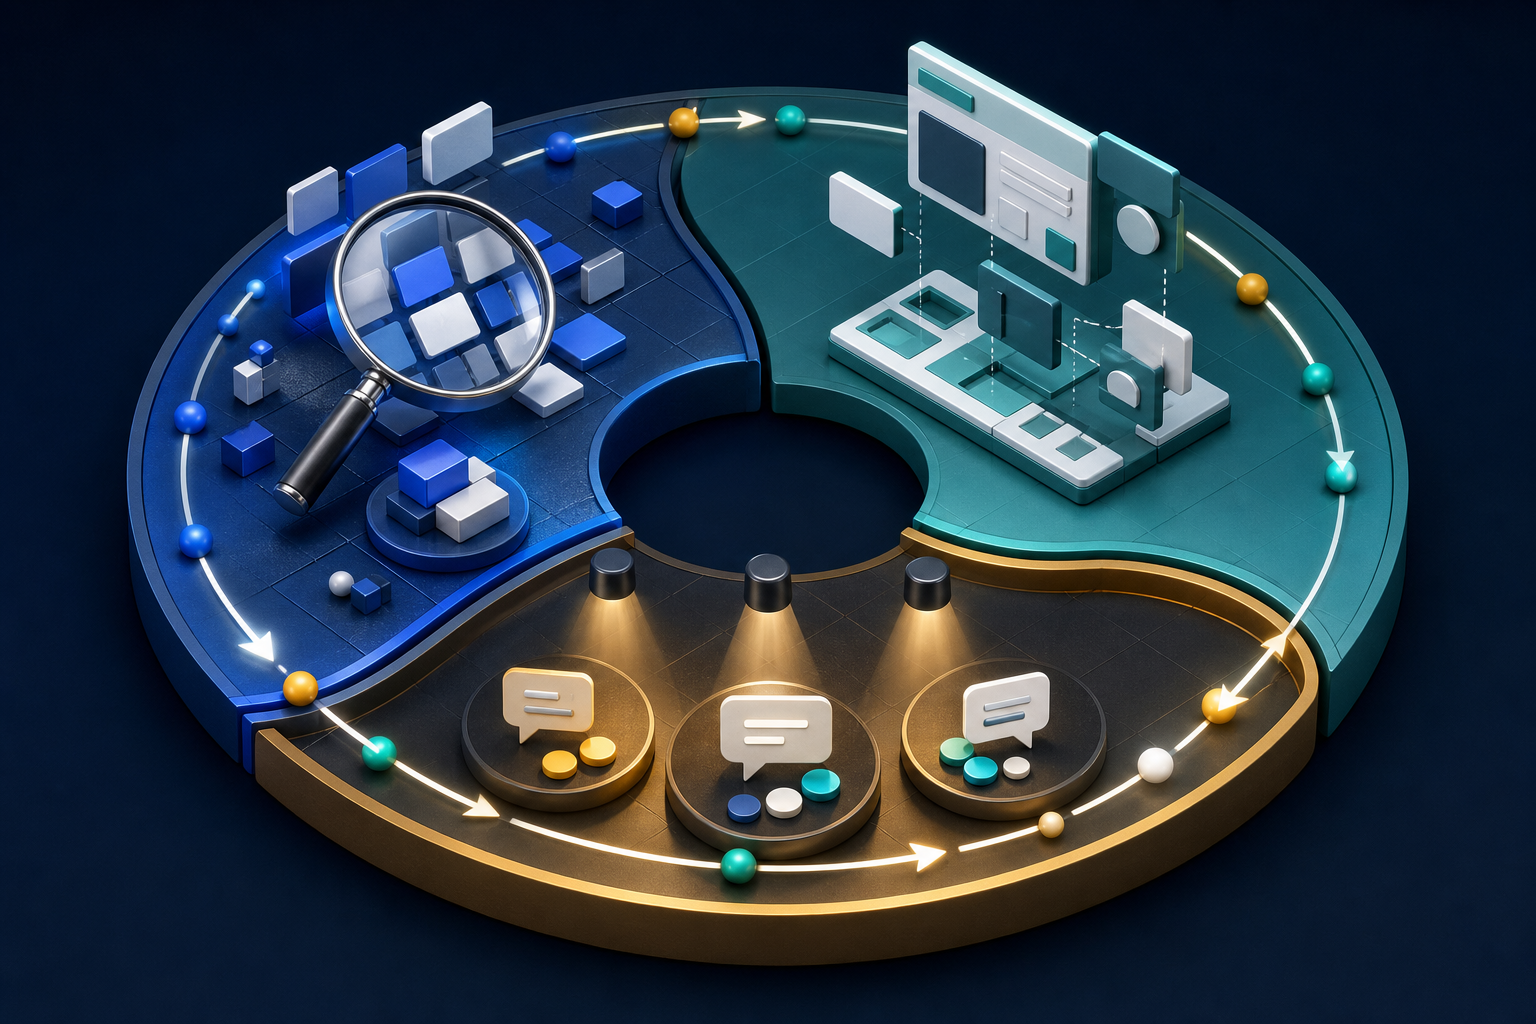
    A circular workspace links content diagnosis, modular page building, and evaluation of abstract answer bubbles in a repeating cycle.

    Use a 90-day operating window for AI-driven search visibility to separate diagnosis, implementation, and evaluation. This is a management cadence, not a promise that a particular system will cite you by a particular date.

    Days 1-30: establish the baseline and choose the work

    • Create the answer map for topics tied to meaningful audience decisions.
    • Freeze a prompt set you can repeat. Store the exact wording, surface, mode, conditions, response, mentions, citations, accuracy judgment, and capture date.
    • Identify which domains and pages are being cited for those questions. Compare their answer coverage and evidence with your assigned canonical pages.
    • Audit technical access, canonicalization, rendering, internal discovery, visible entity information, and structured-data consistency on the priority URLs.
    • Classify each gap as discovery, interpretation, selection, representation, or conversion. Prioritize the pages where the question matters and the failure is specific enough to fix.

    Do not begin by rewriting the entire site. A narrow baseline makes later movement interpretable. If you change templates, taxonomy, copy, schema, and internal links everywhere at once, you may improve the site while learning very little about what repaired the visibility chain.

    Days 31-60: repair canonical pages and supporting signals

    • Rewrite each priority page around its answer contract. Put the direct answer, scope, evidence, boundary, and continuation in a logical sequence.
    • Consolidate overlapping answers so one preferred URL carries the strongest version. Update internal links to point to it consistently.
    • Correct unsupported, stale, or contradictory claims. Add traceable citations where a factual claim requires them.
    • Align visible entity information with titles, headings, author or organization details, canonical URLs, and JSON-LD.
    • Add structured data only after the visible content is accurate. Validate both syntax and meaning.
    • Record what changed, where it changed, and when it was published. That change log is essential when you evaluate the next baseline.

    Keep the batch coherent. If several questions expose the same missing definition or entity conflict, repair the shared foundation once and then update the affected pages. If the questions require different evidence or serve different decisions, keep their answers separate even when the keywords overlap.

    Days 61-90: retest, classify movement, and set the next cycle

    • Repeat the baseline prompts under comparable conditions. Preserve the complete responses rather than recording only favorable mentions.
    • Compare brand presence, linked citations, cited URLs, answer accuracy, and landing-page relevance as separate fields.
    • Review results by question class and surface. An average can hide strong definition coverage alongside weak comparison or troubleshooting coverage.
    • Inspect newly cited pages to learn which answer units were selected and whether the surrounding context represented your position correctly.
    • For unchanged questions, return to the failure chain. Recheck access, answer completeness, evidence, entity consistency, and the strength of the competing material.
    • Carry unresolved gaps into the next cycle with a stated diagnosis and proposed change. Do not turn every absence into a demand for more content.

    Report outcomes in language the business can use. Named but not linked, cited and accurate, cited to the wrong URL, and visible but commercially irrelevant lead to different decisions. A visibility dashboard should preserve those distinctions.

    Your first action does not need to be a sitewide initiative. Take the highest-value unanswered question in your baseline, open the canonical page meant to resolve it, and inspect the entire chain from crawl access to the reader’s next step. Fix that chain, document the change, and retest it through the cycle. Once you can explain why a page is or is not being selected, you have an AEO operating system rather than a collection of guesses.
    References

  • How to Build and Measure AI Search Visibility with AEO

    How to Build and Measure AI Search Visibility with AEO

    If conventional search traffic still looks healthy but your brand disappears when someone asks an AI assistant for recommendations, the problem is not necessarily your rankings. A page can be discoverable yet difficult to reuse in an answer because its category is unclear, its claims are separated from their proof, or no passage directly resolves the question.

    Answer engine optimization gives you a practical way to close that gap. The goal is to make your expertise easy to retrieve, represent accurately, cite, and connect to a useful next step. That is when visibility inside AI-driven search systems becomes a business capability instead of an abstract marketing metric.

    Decide what a successful AI answer should contain

    Do not begin by asking how to rank in AI. An answer engine does not always produce a stable list of pages with a single position to improve. Begin with the customer decision you need to influence and define what a good response would look like.

    A useful answer brief contains five elements:

    • User context: the role, problem, market, or constraint that changes the answer.
    • Prompt family: several natural ways a person could ask the underlying question, including an unbranded version.
    • Accurate representation: the category, audience, use case, differentiator, and limitation the answer should get right.
    • Supporting evidence: the page, documentation, comparison criteria, or proof that justifies inclusion.
    • Useful destination: the next page a reader should reach if the answer creates interest.

    This brief prevents a common measurement error: treating every brand mention as a win. A recommendation based on the wrong category, audience, or capability can create poor-fit traffic and weaken trust. Correct representation comes before frequency.

    Start with unbranded questions such as Which type of solution handles this problem? or What should I compare before choosing a provider? A branded prompt mainly tells you whether the system can repeat facts about you. An unbranded prompt shows whether your brand is associated with the decision before the user already knows your name.

    Prioritize questions where you have a legitimate fit, a page that can prove it, and a meaningful next action. If you cannot support the inclusion you want, the task is not prompt optimization. It is an evidence gap.

    Build passages that can stand on their own

    A robotic arm selects illuminated capsules containing complete sets of connected information from a modular workbench.

    Many pages contain relevant information without containing a reusable answer. The explanation is spread across an opening story, several feature sections, and a conclusion. A human may assemble the point, but a retrieval system has to locate the right passage before a model can use it.

    For each priority question, create an answer unit with this sequence:

    1. Use a descriptive heading that names the actual question or decision.
    2. Answer it directly in the opening paragraph under that heading.
    3. Add the conditions that determine when the answer applies.
    4. Place the supporting explanation or evidence beside the claim.
    5. Point to the next relevant page without interrupting the answer with a premature sales pitch.

    The passage should remain understandable if someone reads only that section. Replace floating claims such as built for modern teams with explicit language: what the product is, who it is for, which task it supports, how it supports that task, and where its boundaries are.

    A reusable product statement can follow this pattern: [Product] is a [category] for [audience]. It supports [task] through [mechanism]. It is appropriate when [condition], but it does not [limitation]. [Evidence or documentation] explains the claim. This is not copy to repeat everywhere. It is a checklist for removing ambiguity.

    Evidence needs to be adjacent to the claim it supports. Do not make an answer engine infer that a case result on one page validates a broad promise on another. Distinguish product facts, editorial opinions, customer statements, and independently verifiable evidence. Precise attribution makes a passage easier for both readers and machines to evaluate.

    Keep entity details consistent as well. Your brand name, category, product names, audience, canonical URLs, and capability language should not change casually between the homepage, product pages, documentation, author profiles, and structured data. If different wording reflects a real distinction, explain that distinction instead of leaving conflicting labels unresolved.

    JSON-LD should mirror what a visitor can verify on the page. Use it to clarify identity, relationships, and page meaning, not to introduce invisible claims. Valid schema markup does not compel an answer engine to mention or cite you, and it cannot repair contradictory copy. Think of structured data as a verification layer built on clear content.

    Update stale facts when they change, but do not manufacture freshness by changing a date without reviewing the substance. A visible review process is useful only when it corresponds to a real check of the claims, links, examples, and product status on the page.

    Map content to decisions, not just keyword variations

    AEO content planning works best when it follows the decisions a buyer must make. Keyword variations often describe the same need, while two similar-looking prompts may require completely different evidence. Group questions by the job the answer must perform.

    DecisionPrompt shapeContent the answer needs
    Understand the problemWhat causes [problem], and how is it addressed?A plain-language explainer with scope, terminology, and limitations
    Choose an approachShould I use [approach A] or [approach B] for [constraint]?A comparison organized around explicit selection criteria
    Create a shortlistWhich solutions fit [audience] with [requirement]?A category or use-case page that states fit and supporting evidence
    Verify a providerDoes [brand] support [requirement]?Product documentation, capability details, and relevant boundaries
    Take actionHow do I implement [approach]?A procedural page with prerequisites, sequence, and a clear next step

    Build the map from questions people already ask in sales conversations, support requests, site search, community discussions, and conventional search data. For each question, record the current URL, the missing evidence, and whether the page should be improved, consolidated, or created. This keeps the plan tied to genuine decisions instead of producing dozens of near-duplicate pages.

    Use internal links to connect the sequence. An explainer should lead naturally to an approach comparison; the comparison should lead to proof of fit; the proof page should lead to documentation or an appropriate conversion path. Each page still needs to answer its own question before asking the reader to move elsewhere.

    Owned content can establish what you claim about yourself, but it should not pretend to be independent validation. Product capabilities belong in official documentation. Customer outcomes need clearly attributed proof. Broader category claims need evidence appropriate to their scope. Earned coverage and genuine brand mentions can corroborate your position, but fabricated reviews, planted endorsements, or undisclosed promotional content do not create trustworthy authority.

    This is also where AEO and conventional SEO support each other. A well-structured page still needs to be accessible, internally connected, indexable where appropriate, and useful after the click. Answer formatting cannot compensate for a page that search systems cannot retrieve or a visitor cannot understand.

    Measure representation, citations, and business impact separately

    Three illuminated channels separately inspect answer presence, source connections, and a path to a completed business action.

    AI visibility cannot be managed from occasional screenshots. A repeatable prompt panel lets you observe whether the brand appears, how it is represented, and what evidence supports the answer. This turns tracking brand mentions in Claude and AI search into a diagnostic process rather than a vanity check.

    Use a fixed prompt panel for the baseline

    Include prompts from several intent types: category discovery, approach comparison, provider shortlisting, requirement validation, and branded fact checking. Preserve the exact wording, audience, geography, and constraints used in each prompt. Test in a fresh conversation when possible, then record the interface, displayed model label, test date, session conditions, and whether the response showed citations.

    Save the complete response, not only the sentence containing your brand. The surrounding explanation reveals why the system included you, which competitors or alternatives framed the answer, and whether your positioning was central or incidental. Because generated responses can vary, treat an individual output as an observation. Repeated patterns are more useful than a single favorable or unfavorable result.

    Score each observation across separate fields:

    • Presence: absent, mentioned, or recommended.
    • Representation: correct, incomplete, or materially wrong.
    • Evidence: cited to an owned page, cited to an external page, uncited, or supported by an irrelevant URL.
    • Decision fit: central to the requested use case, a secondary option, or unrelated to the stated constraint.
    • Competitive context: which alternatives appear and which selection criteria distinguish them.
    • Action path: whether the cited or likely landing page resolves the same question and offers an appropriate next step.

    Do not collapse these fields into a blended visibility score too early. A prominent but inaccurate recommendation can look stronger than a modest, correct citation when reduced to a single number. The separate fields tell you what to fix.

    Match the failure pattern to the right intervention

    • The brand is absent: check whether you have a page that answers the exact decision, whether your category is explicit, and whether the claim has credible support. More keyword repetition will not fill a missing evidence gap.
    • The brand appears in the wrong category: reconcile conflicting descriptions across core pages, documentation, profiles, and structured data. State category boundaries directly.
    • The description is correct but uncited: make the supporting passage self-contained, move proof beside the claim, and ensure the most relevant page has a clear title and opening answer.
    • The citation lands on the wrong page: align headings, internal links, canonical choices, and page introductions so the strongest destination is unmistakable.
    • Visibility improves but qualified demand does not: inspect the prompt intent, landing-page match, offer, and conversion path. The problem may be audience fit rather than answer visibility.

    Connect the monitoring sheet to business evidence without pretending attribution is perfect. Review detectable referral traffic, behavior on cited landing pages, assisted conversions, branded demand, qualified inquiries, and self-reported discovery. The purpose is to learn where online visibility can become a business opportunity, not to assign every conversion to an answer that cannot be observed directly.

    When you make a change, log the hypothesis before editing. Change the smallest useful content unit, publish it, confirm that the revised page is publicly retrievable, and retest against the stable prompt panel. Add experimental prompts as a separate challenger set so the baseline does not drift. If several pages, claims, and external signals change together, you may see movement without knowing what caused it.

    Key takeaways

    • Define the customer decision and the correct brand representation before trying to increase mentions.
    • Create self-contained answer units with a direct response, applicable conditions, nearby proof, and a useful next step.
    • Organize coverage around discovery, comparison, validation, and action rather than publishing thin keyword variations.
    • Keep visible content, product documentation, entity details, internal links, and JSON-LD consistent.
    • Track presence, accuracy, citations, decision fit, and business outcomes as separate signals so each failure has a specific remedy.

    Your next move is narrow and concrete: choose the highest-value unbranded question for which your brand has a defensible fit. Write the target answer brief, audit the page that should support it, and establish a saved prompt baseline before editing. That gives you a real AEO loop: question, evidence, representation, measurement, and revision.

    References

  • SEO and AEO for AI Discovery: A Practical Playbook

    SEO and AEO for AI Discovery: A Practical Playbook

    Your team has a practical decision to make: keep investing in conventional SEO, redirect the budget toward answer engine optimization, or somehow do both without doubling the workload. Treating those as competing programs is the mistake.

    The stronger approach is one discovery system. SEO makes your pages eligible to be found and trusted. AEO makes their answers easier to extract, verify, cite, and recommend. The work overlaps, but the outcomes and measurements are not identical.

    Key takeaways: build one discovery system, not two

    • Protect the SEO fundamentals that still produce most discoverable traffic: query alignment, useful content, internal links, authority, freshness, performance, and conversion paths.
    • Give every important page a specific query, audience, intent, answer unit, supporting evidence, and next action.
    • Place direct answers near the headings that introduce them. Add conditions, evidence, and limitations close to the claims they support.
    • Use JSON-LD to clarify visible entities and relationships. It cannot compensate for thin content, ambiguous positioning, or unsupported claims.
    • For buying-intent queries, improve your presence on relevant review platforms, directories, publications, marketplaces, and video channels instead of relying only on your own domain.
    • Measure search performance, tested AI visibility, referral traffic, and conversions separately. A brand mention is not automatically a citation, a visit, or a sale.

    Start with the query and the decision behind it

    A professional considers several symbolic options as branching paths narrow toward one illuminated solution.

    ‘Optimize for AI’ is too vague to guide a page edit. A person asking for a definition needs a concise explanation. A person comparing vendors needs criteria, tradeoffs, and corroboration. A person ready to buy needs accurate product facts and a clear next step. Those are different retrieval tasks, even when they contain the same topic keyword.

    Before changing content, create a discovery brief for each query cluster:

    1. Write the actual query. Include the audience, use case, constraint, or purchase stage that changes the answer. ‘Payroll software’ is a topic; ‘payroll software for a small nonprofit’ expresses a decision.
    2. Label the intent. Decide whether the person wants an explanation, instructions, a comparison, reassurance, a shortlist, or a transaction.
    3. Define the answer unit. Choose the smallest useful form of the answer: a definition, ordered process, criteria list, comparison table, calculation, specification, or recommendation with conditions.
    4. Identify the required proof. List the facts, examples, first-party details, independent reviews, author credentials, or other evidence a reader would need before relying on the answer.
    5. Choose the next action. Decide what a satisfied visitor should do after receiving the answer. That could be reading a deeper explanation, checking compatibility, comparing plans, requesting a demonstration, or buying.

    This brief tells you whether an existing page should be improved, merged with an overlapping page, or replaced with a more appropriate format. It also prevents a common AEO failure: adding repetitive FAQ sections to pages that still do not resolve the underlying decision.

    Use the found-understood-extracted test

    Review the page in three passes. First, can a search system find and interpret it? Check crawl access, indexability, canonicalization, internal links, title, main heading, and the relationship between the query and the page. Second, can a reader or machine determine who and what the page is about? Check named entities, terminology, authorship, dates, and contextual links. Third, can the answer be lifted without losing a critical condition? Check whether the conclusion, evidence, scope, and caveats appear together.

    If the page fails the first pass, answer formatting will not rescue it. If it fails the third, it may rank and still be difficult to reuse in an AI-generated response.

    Fix the SEO layer that AEO still relies on

    AI discovery is growing, but it does not justify abandoning the channel already producing demand. One reported benchmark puts collective LLM referral volume at roughly 2%-3% of the organic traffic supplied by Google. That ratio is directional, not a universal forecast: it will vary by market, audience, attribution method, and the kinds of questions customers ask.

    The implication is straightforward. Fund AI visibility by extending sound SEO work, not by suspending it. Audit in this order:

    1. Align the title with the query and page promise. Include the language your audience uses when it accurately describes the page. A title should distinguish the page, not collect every keyword variation.
    2. Resolve intent near the top. The opening should confirm the audience’s problem and provide the core answer. Do not make a reader cross a long general introduction before learning whether the page applies.
    3. Strengthen the information architecture. Link to the page from relevant hub and supporting pages with descriptive anchor text. Link back to definitions or evidence when the current page depends on them.
    4. Refresh substance, not only dates. Correct stale facts, remove obsolete recommendations, improve weak examples, close missing subtopics, and preserve a useful URL when its purpose has not changed. Updating a timestamp by itself creates no new value.
    5. Resolve duplication. When several pages answer the same intent, choose the strongest destination and consolidate the useful material. Competing pages make it harder to establish a clear canonical answer.
    6. Protect the visit after the click. Keep pages fast and stable, make navigation predictable, and give the visitor a next step that matches the query. More visibility has limited value if the page cannot convert attention into progress.

    Make changes in identifiable batches and keep a log. If a title, internal-link module, content revision, and template redesign launch together, you will struggle to tell which intervention affected impressions, clicks, AI citations, or conversions.

    Use JSON-LD as clarification, not decoration

    Structured data should express what the page visibly contains. Mark up the real publisher, author, product, organization, or other applicable entity; keep identifiers consistent across templates; and connect related entities only when the relationship is supported on the page.

    • Select the most specific applicable schema type rather than attaching unrelated types in the hope of gaining visibility.
    • Keep names, URLs, dates, availability, prices, ratings, and other marked-up properties consistent with the visible content.
    • Do not manufacture reviews, ratings, authors, or credentials for markup.
    • Use stable identifiers for the same entity across pages instead of describing it as a new object on every URL.
    • Validate the generated JSON-LD after theme, plugin, field, or template changes. Correct source fields can still produce broken output when templates change.

    Schema can reduce ambiguity. It does not force a model to quote the page, make an unsupported claim credible, or turn a generic article into the best answer.

    Make text and images easy to extract without stripping context

    Structured content blocks lift from a complete web page into abstract search, AI answer, and image preview panels while remaining connected to their source.

    AEO is partly an information-design problem. A useful answer must be easy to locate, but it must also remain accurate when a system separates the passage from the rest of the page. That requires more than writing a short paragraph.

    Build answer units around complete claims

    For every important heading, place the direct answer in the first paragraph that follows it. Then add the evidence, method, conditions, exceptions, and next level of detail. A reader should be able to understand the short answer immediately and inspect the reasoning without leaving the section.

    • State the conclusion. Answer the heading in plain language before expanding it.
    • Carry the scope with the answer. If a recommendation applies only to a platform, audience, use case, geography, or time period, name that boundary in the same passage.
    • Put evidence beside the claim. Link the words that depend on external evidence rather than dropping an unexplained reference at the end of the page.
    • Define terms once. Use the same name for the same concept or entity throughout the page. Unnecessary synonyms can make relationships less clear.
    • Use the format the answer requires. Processes belong in ordered lists, criteria in lists, and genuine field-by-field comparisons in tables. Do not force prose into a table simply to appear structured.
    • Separate fact from judgement. Label editorial recommendations as recommendations, and explain the criteria used to reach them.

    This structure helps human readers scan while giving answer systems a coherent passage to reuse. It also reduces the risk that a caveat sits several paragraphs away from the claim it limits.

    Audit images for the machine eye

    Images now carry extractable information as well as visual appeal. OCR can read labels and annotations, while multimodal systems can interpret objects, context, and relationships inside a scene. Compression damage, tiny text, weak contrast, and ambiguous alt text can therefore change what a machine believes the image shows.

    Keep the established performance work: serve appropriately sized files, compress them carefully, reserve their display dimensions, and use lazy loading where it does not interfere with important above-the-fold media. Then add a machine-readability pass:

    • Inspect the image at its rendered size, not only in the original design file.
    • Use 30 pixels as an audit target for the height of critical embedded characters, not as a guarantee that every OCR system will read them correctly.
    • Increase contrast between text and its background. Avoid placing essential wording over glare, reflections, textures, or visually busy areas.
    • Write alt text that identifies the meaningful subject and context. Do not turn it into a list of target keywords.
    • Place a useful caption or nearby explanation beside images whose meaning is not obvious from the pixels alone.
    • Use original diagrams, screenshots, and product photography when they add evidence or experience that generic stock media cannot provide.
    • Repeat essential specifications, prices, warnings, and instructions as accessible page text. Do not make OCR the only route to important information.

    For a chart, annotated screenshot, or product label, perform a simple failure test: if the text inside the image vanished or was read incorrectly, would the surrounding page still communicate the fact? If not, add a textual equivalent.

    Earn third-party validation and measure the right outcome

    Informational visibility can often begin with a strong answer on your own site. Commercial recommendations are more dependent on corroboration. A model evaluating ‘best,’ ‘top,’ ‘most reliable,’ or ‘alternatives to’ queries may look for evidence beyond what a brand says about itself.

    Within one company-run 2025 dataset of 36,127 ChatGPT buying-intent queries, product-recommendation media received 7,642 citations, consumer-review platforms 5,983, traditional media 4,581, commercial or brand sites 2,208, and forum communities 674. Treat those figures as a directional snapshot of one methodology, query definition, model, and period. They do not establish permanent citation weights or prove that placement on a particular site causes inclusion.

    They do expose a useful planning error: publishing more brand copy is not the same as building recommendation evidence. For every high-intent query, create a citation-gap record with these fields:

    1. Prompt and purchase stage: record the exact question and whether the person is exploring, comparing, validating, or ready to choose.
    2. Named and cited brands: distinguish a brand mention from a linked or named supporting page.
    3. Evidence surfaces: classify the cited domains as publications, review platforms, directories, marketplaces, video channels, communities, institutions, or brand sites.
    4. Selection criteria: identify the features, reputation signals, use cases, or constraints used to justify the recommendation.
    5. Legitimate gap: determine whether your brand actually qualifies. If it does, correct inaccurate listings, complete relevant profiles, make verifiable product information available, or pursue editorial coverage on its merits.
    6. Owned-page correction: update the page that should act as the definitive first-party record for features, positioning, compatibility, policies, or other facts.

    Do not fabricate reviews, seed undisclosed endorsements, or force a brand into irrelevant directories. Those tactics create reputation risk and unreliable evidence. The goal is consistent, independently supportable information across the places a buyer would reasonably consult.

    Evaluate AEO vendors by the work behind the label

    The AEO label covers a wide range of services: 78 firms were screened to create one eight-company shortlist during a 2025 provider review. The size of that field is a reason to inspect methods, not a reason to accept a category label as proof.

    Ask a prospective provider to show how it handles technical SEO, answer architecture, structured data, entity consistency, off-site citations, reputation signals, image readability, controlled prompt tracking, and business attribution. Ask which changes happen on your site, which depend on third parties, which outputs you will own, and how it separates tested visibility from actual traffic and conversions. A single proprietary visibility score cannot answer all of those questions.

    Keep four measurements separate

    Search and AI discovery create different observable signals. Put them on one scorecard, but do not collapse them into one number.

    MeasurementWhat it can showWhat it cannot prove
    Search impressions, rankings, and clicksWhether pages are being surfaced and chosen in conventional results for tracked queriesWhether an answer engine mentions or cites the brand
    Mentions and citations across a fixed prompt setHow the brand appears for the specific models, versions, prompts, locations, and test dates recordedUniversal visibility across every user, prompt variation, or generated answer
    AI referral sessions and landing pagesWhich answer platforms send trackable visits and what those visitors do nextThe effect of unclicked mentions or answers whose referral data is missing or misclassified
    Qualified actions and conversionsWhether discovery produces meaningful business progress on the destination pageWhich individual edit caused the result when several changes launched together

    For prompt monitoring, store the exact prompt, model and version when available, test date, response, brand mention, cited URL, and recommendation context. Reuse the same core set after material changes. Generated answers can vary, so look for direction across repeated observations rather than treating one response as a stable rank.

    Start with one query cluster that matters to the business. Repair its titles and internal links, consolidate overlapping pages, rewrite the main answer units, validate the JSON-LD, audit the critical images, and map the third-party evidence gap. Record the baseline before publishing. Once that cluster gains stronger search visibility, more consistent answer inclusion, or better qualified actions, extend the same system to the next decision your customers need to make.

    References

  • How to Adapt Search Visibility and Customer Journeys for AI

    How to Adapt Search Visibility and Customer Journeys for AI

    Your rankings can look stable while part of your customer journey quietly moves elsewhere. A prospect can ask an AI assistant to define the problem, build a shortlist and challenge each option before visiting a website. They may then use Google to verify a detail, arrive through a branded search and convert on a page that receives all the credit.

    If your pages are inconsistent, duplicated or vague, the assistant may omit you, describe you incorrectly or send the prospect to an outdated URL. The answer is not a separate factory for AI content. You need one dependable set of business facts that search engines, AI systems, people and agents acting on their behalf can retrieve, evaluate and carry into a clear next step.

    Plan around the customer’s task, not the search platform

    Do not treat Google and AI assistants as interchangeable traffic sources. They often serve different parts of the same decision.

    One modeled estimate for Q4 2025 placed Google at 77.9% of global digital queries and ChatGPT at 17.1%. The intent split was more revealing: Google held an estimated 90% share of transactional queries, compared with 5% for ChatGPT, while ChatGPT had a much stronger position in generative and creative work. These are directional figures from a model combining client analytics, third-party data and anonymized logs, not a universal census of every query.

    The practical implication is straightforward. Do not dismantle the Google pages that capture high-intent demand. Strengthen the earlier stages where a person is framing a problem, learning terminology, comparing approaches or testing a recommendation. AI can influence the shortlist even when Google, direct traffic or a branded query produces the final visit.

    Start by sorting the questions around one commercially important journey into four jobs:

    • Discover: What kind of solution exists for this problem?
    • Compare: Which options fit my budget, use case, location or constraints?
    • Verify: Is this claim current, supported and applicable to me?
    • Act: What do I need to do next, and what will happen when I do it?

    For every job, name the page you want an AI system or search engine to select. If your team cannot agree on that URL, a retrieval system is unlikely to infer the right one consistently. That gap is more urgent than producing another loosely related blog post.

    Device behavior also affects the handoff. The same 2025 model put 62% of ChatGPT usage on desktop and 63% of Google usage on mobile. That does not establish a conversion pattern, but it is a useful warning: someone may research with AI at a desk and resume through search on a phone. Use stable names, URLs and claims across devices so that the second session confirms what the first one established.

    Map the human and AI journeys to the same pages

    A human and an abstract AI system follow connected paths through the same modular information hub.

    A conventional funnel describes what a person does. An AI-ready journey must also describe what a machine needs to retrieve and explain at each stage. Those are not separate funnels. They are two views of the same handoffs.

    Journey stageWhat the person needsWhat the AI system must resolveWhat the page should provide
    Problem framingLanguage for the problem and its possible causesWhether your entity and content are relevant to the questionA direct explanation, clear scope and links to the next decision
    Option discoveryA credible set of approaches or providersWhat you offer, who it is for and how it differsConsistent product or service names, use cases and qualification criteria
    EvaluationComparable facts, limitations and proofWhich claims apply under which conditionsExplicit criteria, evidence, exclusions, dates and current commercial details
    ActionA low-ambiguity next stepWhere to send the person or how to relay the taskA stable destination, visible prerequisites, a specific call to action and a confirmation path

    This map exposes two common failures. The first is an orphaned educational page that answers the question but never leads to a decision. The second is a conversion page that asks for a booking, trial or purchase without publishing enough information for the prospect to evaluate it. AI can compress several stages into one conversation, so both failures can remove you before a visit occurs.

    Key takeaways

    • Keep strong transactional SEO pages, but connect them to the informational and comparison questions AI assistants handle upstream.
    • Assign one preferred URL to every material intent. If several URLs appear equally valid, consolidate or differentiate them.
    • Put decision-critical facts in visible page content. Do not hide them only in images, downloads, scripts or structured data.
    • Use JSON-LD to mirror the page’s visible facts, not to introduce a second version of those facts.
    • Measure whether AI selects the correct page and represents it accurately, not just whether an identifiable referral arrives.

    Consolidate duplicate pages before expanding your coverage

    AI visibility becomes harder when several URLs compete to answer the same question. Repeated or near-identical pages weaken intent signals, and large language models may cluster the variants and select an outdated one. Publishing more versions can therefore reduce your control over the answer rather than expand your reach.

    Audit duplicates by intent, not just by matching text. Two pages can use different wording and still compete for the same customer task. Conversely, pages built from the same template may deserve to remain separate when they contain genuinely different local rules, prices, eligibility conditions or offers.

    Create a working sheet with one row per indexable URL and these columns: primary question, audience, product or service, location or language, preferred URL, canonical target, last meaningful update and intended next action. Then classify each overlapping page:

    1. Keep: It is the strongest, current page for a distinct intent. Make it the preferred destination and link to it consistently.
    2. Differentiate: It serves a real audience or intent that the primary page does not. Add meaningful differences in examples, terminology, regulations, eligibility, availability or pricing. A swapped place name is not a local strategy.
    3. Consolidate: It no longer deserves a separate destination. Move useful information into the preferred page and use a permanent redirect when the old URL is being retired.
    4. Canonicalize: The variant must remain accessible, but search systems should select another version. Point the canonical tag to the preferred page and keep internal linking consistent with that choice.
    5. Exclude: The page should not participate in discovery. This can apply to staging, archives and republished copies that exist for another operational purpose.

    Campaign pages need the same discipline. Keep a separate landing page when the campaign changes the offer, audience, season, location or other decision context. If only the tracking code and headline change, use one primary interaction page rather than creating a cluster of weak alternatives.

    Localization also requires more than duplicate translation or regional labels. Publish separate regional pages when the content answers a materially different need, use accurate language and regional targeting, and include the local facts a buyer must know. Otherwise, prefer a single strong page over multiple same-language pages serving an identical purpose.

    Syndication can create the same ambiguity across domains. Ask republishing partners to canonicalize to the original, publish a meaningfully reworked version or exclude the copy from indexing. A byline or backlink alone does not tell every retrieval system which full-text version should represent the claim.

    Do not apply redirects or canonical changes to a large group of valuable pages without checking what each URL currently serves. A page that looks repetitive in a crawl may still satisfy a distinct query, campaign or local need. Test the classification on a small group, verify indexing and landing behavior, and then expand the cleanup.

    Make the decision and action layers legible

    An AI guide organizes evidence for a customer beside a clear illuminated path from evaluation to action.

    Give every important page a decision block

    An AI system should not have to assemble your position from a slogan, an old comparison page and a footnote in a downloadable file. Put the minimum complete decision near the top of the preferred page. This is not a demand for simplistic writing. It is a demand for explicit relationships between the question, answer, conditions and evidence.

    A useful decision block contains:

    • Direct answer: State what the product, service or recommendation does in the language of the customer’s question.
    • Best-fit conditions: Name the use cases, audience or constraints under which the answer applies.
    • Exclusions: State when the offer is unavailable or when another approach would be more appropriate.
    • Decision facts: Show the specifications, coverage, requirements, pricing basis or process details needed to compare options.
    • Evidence: Connect important claims to visible support rather than relying on adjectives such as leading, advanced or seamless.
    • Freshness: Display a meaningful update date and revise dependent pages when the underlying fact changes.
    • Next action: Link to the exact place where the visitor can check, calculate, contact, book, buy or continue.

    Write headings that identify the decision being resolved. A heading such as “Eligibility and exclusions” gives both a hurried reader and a retrieval system more information than “What you need to know.” Use tables only for real comparisons, and keep each row based on the same criterion. A table that mixes pricing, brand claims and feature descriptions looks structured while remaining difficult to evaluate.

    JSON-LD belongs behind this visible decision layer. Use it to identify the entities and properties already stated on the page, with the same names, URLs and current values. Do not put an offer, rating, date or availability status in structured data if the visitor sees something different. Machine-readable markup can reduce ambiguity, but it cannot repair contradictory content or guarantee selection in an AI answer.

    Let agents relay or complete a task without guessing

    The machine visitor is usually an intermediary, not the person whose money, data or consent is at stake. Design the action path so an assistant can explain it clearly and an authorized agent can proceed only within the user’s intent.

    • Use stable action destinations. Send booking, checkout, application and contact traffic to durable URLs rather than temporary campaign variants.
    • Expose prerequisites before the action. State location limits, required documents, eligibility, fees, account requirements and expected next steps before asking for information.
    • Label controls by outcome. “Check availability” or “Request an assessment” is clearer than “Continue” because it describes what will happen.
    • Separate explanation from authorization. Public pages can make an offer understandable, while authenticated or consequential actions still require appropriate identity, consent and confirmation.
    • Return useful errors. If an option is unavailable, explain the failed condition and provide a valid alternative instead of sending the visitor back to a generic page.
    • Preserve a human route. Provide a clear support or contact path when the request is ambiguous, exceptional or too consequential to automate safely.

    This work also improves the human journey. Clear prerequisites reduce abandoned forms. Specific controls reduce misclicks. Visible constraints prevent a sales conversation from beginning with a misunderstanding. Agent readiness is largely the discipline of removing guesswork without removing safeguards.

    Measure selection, accuracy, handoff and outcome

    Referral traffic is useful but incomplete. Analytics can identify a source only when a visit arrives with recognizable referral information. It cannot see a recommendation that was copied, remembered or followed later through a branded search. Last-click reporting can therefore reward the final route while hiding the system that shaped the shortlist.

    Build a scorecard around four questions:

    LayerQuestionWhat to recordWhat a failure means
    SelectionDoes the brand appear for an eligible question?Prompt, platform, locale, date, brand inclusion and cited competitorsThe topic, entity or evidence may not be sufficiently clear or available
    AccuracyIs the answer current and supported?Correct claims, outdated claims, unsupported claims and missing conditionsImportant facts may be ambiguous, duplicated or stale
    HandoffDoes the answer lead to the preferred page?Cited URL, canonical status, landing experience and next actionThe system may be selecting a duplicate, weak or outdated destination
    OutcomeDoes the journey produce useful business activity?Identifiable AI referrals, qualified actions, conversions and self-reported discoveryVisibility may not align with intent, or the page may fail after retrieval

    Use a fixed, representative question set rather than collecting only flattering examples. Include discovery, comparison, verification and action questions. For each observation, preserve the exact wording and testing conditions so that later changes are interpretable. Separate questions for which your brand is genuinely eligible from questions where inclusion would be irrelevant.

    When an answer is wrong, diagnose the failure at the right layer:

    • If the correct page is absent, inspect crawlability, indexing, internal links, duplication and canonical signals.
    • If the page is selected but the claim is wrong, make the fact and its conditions explicit in visible content, then align structured data and dependent pages.
    • If the answer is accurate but cites an old URL, consolidate the old version and update internal destinations.
    • If the handoff is correct but nobody acts, inspect whether the page answers the comparison and qualification questions that precede the call to action.
    • If conversions appear without identifiable AI referrals, add a concise discovery question to sales or checkout research and treat the result as supporting evidence, not perfect attribution.

    Start with one high-value journey rather than rewriting the entire site. Choose a decision that already matters to the business, assign its preferred pages, consolidate competing versions, add the decision and action layers, and baseline the four-part scorecard. Expand only after an assistant can find the current page, describe its limits accurately and hand the person to a next step that requires no guesswork.

    References

  • How to Use Vertical GEO and AEO Agency Rankings in 2026

    How to Use Vertical GEO and AEO Agency Rankings in 2026

    If you are using a 2026 agency ranking to build your GEO or AEO shortlist, do not hand the top name a contract yet. A rank tells you who cleared someone else’s model. It does not tell you who understands your buyers, can work inside your approval process, or can connect an AI mention to a qualified opportunity.

    Use the rankings as a discovery layer. Then rebuild the order around your vertical, your revenue questions, and evidence you can verify. The process below gives you a vertical map, a complete fintech leaderboard as a worked example, and a scorecard you can use in procurement.

    Why the vertical comes before the rank

    For agency selection, it helps to give GEO and AEO separate jobs. AEO makes a page clear, complete, and extractable enough to answer a question. GEO improves the likelihood that a brand, entity, or page will be selected, mentioned, or cited in a generated response. A serious program needs both, but the proof of competence changes by industry.

    A fintech team may need compliance-aware editorial operations and defensible measurement. A B2B SaaS company needs product, category, and comparison answers tied to pipeline. An HVAC business depends on local entities, service areas, urgent intent, calls, and bookings. A university has program-level demand and decentralized approvals. An industrial manufacturer must translate specifications and engineering knowledge without sacrificing accuracy.

    Vertical2026 candidate coverageFirst proof to demand
    Fintech57 agencies evaluated; eight placed on the final leaderboardA compliance-aware content workflow, technical measurement, and a traceable path from prompts to qualified leads
    B2B SaaS59 firms evaluated from March through November 2025 with a six-factor modelResults for non-branded category, problem, comparison, and evaluation queries, connected to pipeline rather than traffic alone
    HVACA specialist 2026 agency rankingService-area coverage, consistent local entities, and reporting that reaches calls or bookings
    Higher education64 agencies evaluated from August 2024 through November 2025; eight selectedA program-level query map, an admissions measurement plan, and a workable approval process across departments
    Industrial51 firms evaluated from May through November 2025; eight selectedTechnically accurate content, subject-matter review, and lead-quality reporting for engineers, buyers, or distributors

    Those review counts describe the candidate pools that were examined, not the total number of agencies operating in each market. They also do not make positions portable across industries. A high-ranking B2B SaaS agency has not automatically proved that it can manage university governance, local HVAC demand, or regulated fintech claims.

    Start with the work your vertical makes difficult. That becomes your first qualification gate. Only compare scores after every candidate has passed it.

    The complete 2026 fintech leaderboard, with its caveat

    The final fintech order and reported scores are shown below. Keep the word reported in view: this is useful discovery data, not an independent audit.

    RankAgencyLocationAI visibilityReview scoreRetentionTechnical expertiseSpecialty
    1First Page SageSan Francisco, CA4.84.892%9.6Lead generation through SEO and GEO
    2Focus DigitalKernersville, NC4.24.684%8.2SMB SEO and PPC lead acquisition
    3Driven MetricsChicago, IL4.14.582%8.8Performance-oriented SEO systems
    4Siana MarketingMiami, FL4.44.788%8.5High-intent generative optimization
    5GenevateNew York, NY4.34.680%8.0GEO combined with PR-led authority
    6CSTMRAustin, TX3.94.578%7.4Fintech brand and product marketing
    7Growth GorillaLondon, UK3.84.476%7.0Fintech growth and acquisition
    8NinjaPromoNew York, NY3.74.375%6.9Multichannel fintech marketing

    First Page Sage hosts the leaderboard and ranks itself first, creating a conflict you should account for during due diligence. That does not make the candidate data useless. It means you should independently verify the references, retention claims, query set, baseline, and before-and-after evidence before approving a contract.

    The fintech model assigned 30% to average reviews, 25% to AI visibility, 20% to estimated client retention, 15% to technical expertise, 5% to location, and 5% to specialty. Reviews, visibility, and retention therefore control three quarters of the result, while vertical specialty contributes only 5%.

    That weighting is reasonable for finding firms with broad signs of delivery. It may be wrong for your decision. If a compliance failure, inaccurate product statement, or weak subject-matter process is your largest risk, vertical competence deserves more influence than the published model gives it.

    The inputs also need scrutiny. The reported retention rates were estimated from case studies, testimonials, and relationship maps. Review scores were aggregated and weighted from review sites and testimonials. Neither measure is equivalent to an audited client roster, verified renewal data, or a reference call with a comparable client.

    Rebuild the leaderboard around your buying problem

    Abstract agency candidate tokens are reordered across transparent evaluation layers on a procurement table with fintech and security objects.

    You do not need to discard a published ranking. Copy its useful structure, replace its assumptions, and require the same evidence from every candidate.

    1. Write the query brief before reviewing agency pitches. Group the questions that matter into problem discovery, category selection, comparisons, implementation, risk, and branded evaluation. Add the audience, market, language, and desired business action for each group. This prevents a vendor from demonstrating visibility on easy prompts that have little commercial value.
    2. Separate qualification gates from weighted factors. A gate is a requirement that cannot be offset by a strong review score. Examples include compliance workflow, access to the required analytics stack, support for your CMS, local-market competence, subject-matter review, or the ability to work within university governance. Eliminate candidates that miss a gate before calculating a score.
    3. Reweight the six fintech factors for your situation. Keep reviews, AI visibility, retention, technical expertise, location, and specialty if they help, but assign influence according to your actual risk. Location may matter when operating hours or regulatory familiarity affect delivery. It may deserve little weight when an experienced distributed team can meet the same requirements.
    4. Score evidence by strength, not presentation quality. Use plain labels such as absent, asserted, adjacent, directly relevant, and repeatable. A logo without a documented scope is an assertion. A conventional SEO case is adjacent evidence for GEO. A comparable vertical case with a fixed prompt set, baseline, change log, and business outcome is directly relevant.
    5. Normalize AI visibility measurement. Give every finalist the same prompt set and require the platform, model or surface, date, language, geography, and account context to be recorded. Archive the generated answer. Track a brand mention, a citation, a link, and a favorable recommendation as separate events because they are not interchangeable.
    6. Use a bounded paid pilot before expanding the engagement. Lock the baseline and prompts before work begins. Define the pages, technical changes, reporting access, approval responsibilities, and end-of-pilot decision criteria in the scope. The pilot should test whether the operating system works, not invite a promise that an agency controls model output.

    Recalculating the order often changes the winner. That is the point. You are not trying to reproduce someone else’s leaderboard; you are using it to avoid starting with an empty vendor list.

    Evidence that belongs in the pitch and the contract

    Transparent links connect discovery, source verification, analytics, approval, buyer, and revenue symbols on a dark tabletop.

    A capable agency should be able to show the machinery behind its visibility claim. In the fintech scoring, the named platforms included ChatGPT, Perplexity, and Gemini. Your measurement plan can cover other relevant surfaces, but it should always name them. A blended AI visibility number without its underlying platforms and prompts is not reproducible.

    • Prompt ledger: the exact question, audience, intent, market, language, and target action.
    • Answer archive: the generated response, run context, brand mentions, cited domains, linked URLs, and date of capture.
    • Baseline and change log: what was visible before the engagement and which content, technical, schema, internal-linking, entity, or authority changes were made afterward.
    • Outcome map: the path from visibility to the event your vertical values, such as a demo, qualified lead, call, booking, application, or request for quotation.
    • Editorial workflow: who supplies subject-matter knowledge, who verifies claims, who approves publication, and how corrections are handled.
    • Account ownership: your access to analytics, prompt records, dashboards, content, technical documentation, and exports during and after the engagement.
    • Comparable references: permission to verify the agency’s scope, working relationship, reporting quality, and continued retention with a relevant client.

    Put the definitions in the contract. If visibility means a brand mention, say so. If success requires a cited owned page or a qualified lead, say that instead. Specify the baseline, prompt set, reporting context, review cadence, deliverables, and data ownership. Without those definitions, an agency can report a rising proprietary score while your commercially important prompts remain unchanged.

    Several pitch patterns should stop the procurement process until the vendor supplies evidence:

    • A guarantee of inclusion, citation, or ranking in a generative response. Agencies can improve eligibility and authority; they do not control the output.
    • A visibility score with no prompt list, platform breakdown, baseline, or archived answers.
    • A schema-only plan. Structured data can clarify entities and page meaning, but markup cannot manufacture expertise, reputation, or supporting evidence.
    • Case studies that omit the original state, query scope, changes made, measurement context, or connection to a business outcome.
    • Retention and review claims that cannot be checked through a comparable reference or underlying record.
    • The same plan for fintech, SaaS, HVAC, higher education, and industrial clients with only the nouns changed.

    The last warning is especially revealing. A vertical agency should know where your facts originate, who can approve them, which questions carry commercial intent, and what a qualified outcome looks like. If those details never enter the plan, the vertical label is branding rather than operating competence.

    Key takeaways

    • Use an agency rank to discover candidates, not to outsource the final decision.
    • Compare agencies within the same vertical and against the same query, evidence, and measurement requirements.
    • The fintech leaderboard places First Page Sage, Focus Digital, Driven Metrics, Siana Marketing, Genevate, CSTMR, Growth Gorilla, and NinjaPromo in its top eight.
    • The fintech weighting gives reviews 30%, AI visibility 25%, retention 20%, technical expertise 15%, location 5%, and specialty 5%.
    • Increase the influence of vertical competence when compliance, technical accuracy, local intent, governance, or subject-matter review can determine whether the program succeeds.
    • Require prompt-level evidence, a locked baseline, a change log, business outcomes, and data ownership before committing to a broad retainer.

    Your next move is to copy the six ranking factors into your procurement sheet, mark the non-negotiable gates, reassign the weights, and request identical evidence from every candidate. The agency that survives that normalized comparison is a safer choice than the agency sitting at the top of a borrowed leaderboard.

    References

  • How to Build AI Search Visibility That Survives Change

    How to Build AI Search Visibility That Survives Change

    If your pages rank but rarely appear in AI answers, the obvious reaction is to chase the exact prompts that omitted you. That usually produces brittle content: one page for every wording, screenshots mistaken for measurement, and no clear connection to revenue, trials, or qualified leads.

    A stronger approach is to build enough topical depth to match related questions, make each answer easy to extract and verify, measure visibility without ignoring model variance, and run the work through a plan that can absorb change. You cannot control every generated response. You can improve how often your brand is a relevant, defensible choice.

    Key takeaways

    • Do not treat one headline keyword as the whole opportunity. AI systems can fan a prompt out into related searches, so coverage across the reader’s decision matters.
    • A citation and a top organic ranking are related but distinct outcomes. Measure both instead of using rankings as a proxy for AI visibility.
    • Make important passages self-contained: answer the question directly, state the scope, place evidence beside the claim, and link to the next relevant detail.
    • Track citations, mentions, recommendations, referral traffic, and business outcomes separately. They describe different kinds of visibility.
    • Use annual goals to set direction, then manage execution quarterly with named owners, dependencies, leading indicators, and capacity for interruptions.

    Build topic coverage around fan-out, not one headline keyword

    An abstract knowledge core branches into multiple interconnected clusters of smaller nodes in an overhead view.

    A broad prompt rarely represents one information need. Someone asking for the best software for a particular job may also need eligibility criteria, feature comparisons, implementation constraints, pricing logic, risks, alternatives, and proof. An AI system can search across those subordinate questions before composing its answer. Those searches are commonly called fan-out queries.

    The citation opportunity is therefore wider than the visible prompt. Across 10,000 keywords analyzed by Surfer SEO, 76% triggered AI Overviews and Gemini produced 33,000 fan-out queries. Pages ranking for the main query and at least one fan-out represented 51% of AI Overview citations, while pages ranking only for the main query represented just under 20%. Pages with fan-out rankings were 161% more likely to be cited than pages ranking exclusively for the main query.

    The relationship was strong – a Spearman correlation of 0.77 connected the number of fan-out queries a page ranked for with its likelihood of being cited – but it was still correlation, not proof of causation. Ranking for more related queries does not force an AI system to cite you. It is better read as evidence that broad, coherent topic relevance creates more chances to qualify.

    Fan-out is also unstable. Only about 27% of the generated fan-outs remained constant across test runs, with context and personalization affecting the rest. Do not turn one exported list into a permanent content calendar. Use fan-out as a model of the reader’s decision space, then build durable coverage around the questions that remain useful even when their wording changes.

    Traditional rankings still matter, but they do not define the citation pool. About 68% of cited pages were outside Google’s top 10 for both the main and fan-out queries. Among the three most prominent citations, that share fell to roughly 46%. The practical reading is not that rankings are irrelevant. Strong rankings may still help with prominent placement, while relevant pages outside the first page can remain citation candidates.

    Build a fan-out map from the reader’s decision

    1. Choose a business theme. Start with a product, service, or problem that can lead to an ecommerce purchase, SaaS trial, qualified lead, or another defined outcome. A broad traffic topic with no business role is a weak foundation.
    2. Write the core prompt in the reader’s language. Frame the decision or task they are trying to complete, not merely the keyword you want to rank for.
    3. Expand the hidden questions. Cover fit, criteria, comparisons, constraints, execution, exceptions, and validation. These categories are more durable than a list of minor keyword variations.
    4. Map each question to an existing URL before creating anything. Update a suitable page when the question serves the same reader and decision. Create a separate page when it requires a different task, audience, evidence set, or depth.
    5. Record what would make the answer complete. Specify the direct answer, required qualification, supporting evidence, relevant entity names, and the next page a reader should visit.
    Fan-out facetWhat the reader needs to resolveUseful content action
    Fit and scopeWhether the option applies to their situationState the intended audience, use case, exclusions, and prerequisites near the answer.
    Evaluation criteriaHow to judge competing optionsExplain each criterion and connect it to a practical consequence.
    ComparisonWhat changes between alternativesCompare the same attributes in the same order and explain the tradeoff, not just the winner.
    ConstraintsWhat could prevent adoption or change the recommendationCover compatibility, dependencies, limits, risks, and situations requiring a different path.
    ExecutionWhat to do after choosingProvide an ordered process with decision points, ownership, and verification.
    ValidationHow to know the choice or implementation workedName the observable result, the metric that represents it, and the next action if it is missing.

    This map should not automatically become one enormous page. Keep closely related questions together when they are steps in the same decision. Split them when the searcher has moved to a different job, such as moving from choosing a platform to implementing it. That gives each URL a clear purpose while allowing the site as a whole to demonstrate depth.

    Make each page easy to understand, extract, and trust

    Topic coverage gets a page into more relevant situations. Citation-ready writing gives a system a clear passage to use once the page is considered. The two jobs support each other, but neither substitutes for the other. A technically accessible page full of vague prose is weak evidence, while a precise answer hidden on an isolated page has too few opportunities to qualify.

    Write answer units that can stand on their own

    Treat every important subsection as a small answer unit. A reader arriving at its heading should understand the answer without reconstructing context from several earlier paragraphs.

    • Use a descriptive heading that names the actual question or decision.
    • Answer in the first sentence or short paragraph. Do not spend the opening announcing that the issue is complicated.
    • Name the entity, product, platform, audience, or condition the answer applies to. Pronouns and generic phrases become ambiguous when a passage is extracted.
    • Place the evidence and qualification beside the claim they support. A footnote-sized caveat several sections later is easy for readers and machines to miss.
    • Separate documented facts from editorial judgment. If you are recommending an option, state the criterion that drives the recommendation.
    • Link to the next supporting page where the reader’s task genuinely continues. Internal links should express a useful relationship, not merely repeat an exact-match phrase.

    Run a passage-level audit before publishing. Ask whether the answer still makes sense when copied without the introduction, whether every number has its scope, whether a comparison uses equivalent criteria, and whether two pages make conflicting claims about the same entity. Fixing those faults improves the page for human readers even when no AI citation follows.

    Build a stable association between your brand and a defined topic

    AI visibility is not only a passage-selection problem. It is also a brand-positioning problem. Brands identified as category leaders through Semrush’s AI Visibility Index showed less than 20% monthly volatility in AI share of voice, suggesting that established associations can become relatively stable. Newer challengers still gained traction, and niche relevance repeatedly created an opening.

    Do not adopt 20% as a universal benchmark. It came from a specific index built from more than 2,500 real prompts processed through ChatGPT and Google AI Mode across four industries. Your prompt set, category, market, and measurement method may behave differently. The useful lesson is narrower: competing for every broad prompt is less realistic than becoming consistently relevant to a well-defined set of decisions.

    • Write a plain positioning statement that names the audience, problem, and area of expertise you intend to own.
    • Use consistent names for the brand, products, features, and categories across product pages, editorial content, documentation, and public relations material.
    • Correct contradictory or stale claims instead of publishing another page that introduces a third version of the answer.
    • When you have original evidence, publish its method, scope, and limitations. Do not manufacture a statistic merely to make a paragraph look authoritative.
    • Choose narrower topics where you can provide complete, differentiated help before expanding into a larger category.

    Use JSON-LD as a consistency layer

    Structured data can clarify the page type and the entities represented on it, but it is not an AI citation switch. JSON-LD cannot repair thin coverage, unsupported claims, or an unclear brand position. Its job is to reinforce facts that the visible page already communicates.

    • Select schema types that truthfully match the visible page and its primary purpose.
    • Keep entity names, canonical URLs, and other identity fields consistent with the page and the rest of the site.
    • Do not place claims in markup that a visitor cannot find in the visible content.
    • Update or remove structured data when the underlying page changes. Stale markup creates another version of the truth to reconcile.
    • Validate the rendered result after deployment, especially when templates or plugins generate markup dynamically.

    Measure AI visibility without turning variance into a KPI

    A beam passes through rotating translucent lenses to create different light patterns on blank observation panels beside a separate golden outcome path.

    A screenshot of one favorable answer proves that the answer appeared once. It does not show stable visibility, competitive share, or business value. Measurement becomes useful only after you define the signals separately and observe them through a repeatable prompt set.

    Separate the outcomes you are currently blending together

    • Citation: the generated answer links to an owned page. Record the cited URL and the claim or section it supports.
    • Mention: the answer names the brand without linking to it. This is visibility, but it cannot be counted as an owned citation.
    • Recommendation: the brand is presented as a suitable option for the user’s stated need. Record the qualifying language and the alternatives that appeared beside it.
    • Referral: a person visits from the AI surface. Track the landing page and subsequent behavior where analytics can identify the session.
    • Business outcome: the activity contributes to revenue, a trial, a qualified lead, or the result your organization funds marketing to produce.

    A brand can gain mentions without citations, citations without measurable visits, and visits without conversions. Combining them into one visibility score hides the part of the system that needs work.

    Use a repeatable prompt-testing protocol

    1. Create a fixed core set. Group prompts by business theme and reader stage, including discovery, evaluation, comparison, and implementation where those stages apply.
    2. Record the testing context. Save the exact prompt, platform and surface, test date, available region or account context, answer, cited URLs, mentions, and recommendations.
    3. Keep the core stable. Add emerging customer questions as a separate cohort. If you substantially rewrite a prompt, version it instead of overwriting the historical test.
    4. Repeat at a consistent cadence. Compare like with like and treat an isolated gain or loss as a signal to retest, not an instruction to rewrite the roadmap immediately.
    5. Review by theme and page. Identify which subject areas earn citations, which URLs recur, which pages disappear, and which commercial themes remain absent.

    This protocol matters because generated searches and answers vary. The roughly 27% fan-out consistency observed across repeated runs makes a single test especially weak evidence. Logging the context does not eliminate variability, but it lets you distinguish a changed result from a changed method.

    Build a dashboard with three layers

    • Business performance: ecommerce revenue from organic discovery, SaaS trials, qualified service leads, or the equivalent outcome. This layer determines whether the work deserves continued investment.
    • Contextual visibility: organic keyword groups organized by business theme, citations and mentions across the fixed prompt set, recurring cited URLs, and competitive presence within the same decisions. This layer shows where discoverability is changing.
    • Leading indicators: publication and update throughput, unresolved indexation issues, fan-out coverage gaps, technical defects, and content or structured-data quality checks. This layer reveals execution problems before lagging outcomes fully respond.

    Use the layers diagnostically. If leading indicators are healthy and contextual visibility rises while business outcomes remain flat, inspect intent, offer fit, and conversion paths before commissioning more content. If publication slows or indexation problems grow before visibility falls, address the operating constraint. If citations fluctuate while the fixed prompts, organic visibility, and site coverage remain broadly stable, rerun the tests before treating the movement as a strategic change.

    Put visibility work into a resilient operating plan

    AI search changes too quickly for an annual plan built as a rigid list of deliverables. It does not change too quickly for an annual plan that sets business priorities, resource boundaries, and decision rules. Used as a direction and resource-allocation framework, the plan tells your team what to protect when a new interface, product launch, or urgent request changes the quarter.

    Establish a baseline before adding projects

    • Technical health: identify indexation failures, conflicting canonical signals, broken internal paths, and template defects that can prevent important pages from being discovered or understood.
    • Content coverage: map the core decision and fan-out facets for each commercially relevant theme. Mark useful existing pages, weak passages, contradictions, and genuine gaps.
    • Authority and positioning: check whether the brand is consistently associated with the intended topic and whether product, editorial, and public-facing claims agree.
    • Measurement: capture the current business outcome, theme-level organic visibility, fixed-prompt AI presence, cited URLs, and leading indicators.

    Keep the baseline at the business-theme level. A single sitewide score can improve while the product category that generates qualified demand loses visibility. Granularity tells you where resources should move.

    Convert annual direction into a quarterly cycle

    1. Choose the outcome and theme. State the business result the quarter should influence and the reader decision you intend to serve better.
    2. Prioritize by impact, effort, and dependency. A valuable content gap may still need to wait for product facts, engineering work, legal review, or a measurement fix. Make that constraint visible.
    3. Commit to verifiable deliverables. Name the pages to update or create, technical problems to repair, structured-data changes to make, prompt baseline to establish, and measurement work required.
    4. Assign one accountable owner. Contributors can span several teams, but every deliverable needs someone responsible for moving it through dependencies and review.
    5. Reserve capacity for change. Do not allocate the entire quarter before it begins. Unexpected launches, indexation failures, and platform changes otherwise displace the plan without an explicit decision.
    6. Review leading indicators during execution. Resolve blocked production, quality, and technical work while there is still time to affect the quarter.
    7. Reallocate at the reset. Continue work that improves the intended theme, repair work that is blocked but still valuable, and stop projects whose business rationale no longer holds.

    Avoid copying a competitor’s roadmap. Their authority, technical constraints, products, and conversion model are not yours. Competitor visibility can reveal a gap, but your baseline and business outcome should determine whether the gap deserves resources.

    Make cross-functional dependencies part of the plan

    SEO and AI visibility cannot be handed to the content team after the important decisions are already made. Product teams hold capability and launch facts. Editorial teams turn those facts into useful answers. Technical teams control templates, indexability, and structured-data implementation. Analytics teams connect visibility to behavior. Public relations teams help keep external positioning aligned with the claims the site can support.

    A practical quarterly brief should contain the business theme, reader decision, performance baseline, contextual visibility measure, leading indicators, committed pages and fixes, accountable owner, contributing teams, dependencies, reserved capacity, and next review point. If one of those fields is blank, the execution gap is already visible.

    Start with one theme tied to a real business outcome. Map its fan-outs, improve the strongest existing page at passage level, establish a fixed prompt baseline, and place the remaining gaps into the next quarterly cycle with owners and dependencies.

    The goal is not to appear in every generated answer. It is to become the clearest, best-supported choice for a defined set of decisions, then maintain an operating system capable of preserving that relevance as search interfaces change.

    References

  • Brand Visibility in Meta AI: A Practical Optimization Plan

    Brand Visibility in Meta AI: A Practical Optimization Plan

    Your Instagram and Facebook accounts can look active while your brand remains difficult for Meta AI to identify, explain or recommend. More posts won’t solve that problem if your name, category, offer and supporting evidence are inconsistent or buried inside promotional language.

    A better plan starts with the questions you want your brand to appear for. You then create a stable record of what the brand is, publish content that answers those questions, adapt that evidence to each Meta surface and test the resulting answers under repeatable conditions.

    Define the visibility outcome before you optimize

    “Brand visibility” is too broad to be a useful target. It can mean that Meta AI recognizes your name, understands what you sell, includes you in an unbranded recommendation or gives someone an accurate next step. Those are different outcomes, and each one exposes a different problem.

    Start with real user situations, not a generic goal such as “rank in Meta AI.” Group the questions that matter to your business by intent:

    • Discovery: Someone knows the problem or category but doesn’t know your brand.
    • Fit: Someone wants to know whether an option suits a particular audience, location, use case or constraint.
    • Evaluation: Someone is comparing approaches and needs meaningful differences, limitations and proof.
    • Validation: Someone has heard of your brand and wants to confirm what it does, whether it is credible or whether a claim is accurate.
    • Action: Someone wants the correct page, account, contact route or purchasing path.

    Write down the exact questions people are likely to ask. For each question, define what a satisfactory appearance would contain. A useful target might require the correct brand name, the right category, an accurate description of the offer, a relevant piece of evidence and a safe next step. “We should appear” isn’t specific enough to audit.

    Don’t make branded questions your only test. Asking “What is [Brand]?” measures whether the system can discuss a name the user has already supplied. Asking “Which providers solve [problem] for [audience]?” tests whether the brand can be discovered in the context that creates new demand.

    This distinction also prevents a common reporting mistake. Follower growth, feed reach and engagement can be useful channel metrics, but they don’t establish that Meta AI can represent the brand accurately. Track assistant visibility as its own outcome.

    Give Meta AI one coherent brand to understand

    A coordinated product box, bag and several blank social media content frames share the same teal-and-apricot geometric design.

    Before you create more content, establish a canonical brand record. This is the factual spine that should remain stable across your website, Instagram profile, Facebook presence and supporting content.

    Your internal record should settle the following points in plain language:

    • The exact brand name and any legitimate name variants.
    • The category the business belongs to.
    • The audience it serves and the problems it addresses.
    • The products, services or programs currently offered.
    • The geographic market or service area, where relevant.
    • The distinctions you can support with evidence.
    • The official website, social accounts and action paths.
    • Important boundaries, exclusions or eligibility conditions.

    Turn the core into a direct sentence: “[Brand] is a [category] for [audience] that provides [offer] in [market].” That sentence is an editorial control, not a slogan. It tells everyone producing content which facts must not drift.

    Consistency doesn’t require copying the same bio everywhere. It means the factual meaning survives every variation. One profile can be conversational and another can be detailed, but they shouldn’t assign the business to different categories, describe different audiences or send people to conflicting destinations.

    Run a contradiction audit before launching a new campaign. Compare your website, profile descriptions, About information, recurring captions and high-visibility explainers. Look specifically for:

    • Old names that remain in current-looking content.
    • Broad slogans that replace a clear category description.
    • Offers that have been renamed, narrowed or discontinued.
    • Different locations or service areas across properties.
    • Claims on social media that the website cannot substantiate.
    • Links that lead to obsolete pages or an unrelated homepage.
    • Third-party terminology that conflicts with the language you now use.

    Correct the properties you control before trying to overpower an error with more posts. Publishing new claims while prominent old claims remain live creates another version of the brand rather than a clearer one.

    Disambiguation matters when a name is generic, abbreviated or shared. Pair the name with its category, audience or location in visible text. A logo may tell a loyal customer who you are, but a sentence such as “[Brand] provides [service] for [audience]” gives both people and automated systems an explicit identity to work with.

    Publish evidence in a form that can answer a question

    A brand claim is not yet an answer. “Built for modern teams” doesn’t explain which teams, what the product does, when it fits or why anyone should believe the claim. If your content never resolves those points, an AI-generated answer has little dependable material to carry forward.

    Create a query-to-content map. Each priority question should have a clear, maintained destination that contains:

    • A direct answer: State the essential fact before the promotional explanation.
    • Scope: Identify the relevant audience, market, use case and conditions.
    • Support: Connect the claim to product details, documentation, policies, named credentials or other evidence you can verify.
    • Boundaries: Explain when the offer isn’t a fit or when the answer depends on a condition.
    • A next step: Point to the most relevant page or action rather than defaulting to a generic homepage.

    A practical content unit can follow this sequence: name the question, answer it in one plain sentence, explain the conditions, show the evidence, state the limitation and provide the appropriate action. The format works for product explanations, service-area pages, comparisons, policy answers and social captions because every element has a distinct job.

    Make important passages understandable on their own. Pronouns such as “it,” “this” and “they” become ambiguous when a sentence is separated from the surrounding post. Repeat the brand, product or service name where clarity requires it. This is useful writing, not keyword repetition.

    Apply the same rule to visual content. If a video or image contains an important product fact, include that fact in accessible supporting text such as the caption or transcript. The visual can carry the emotion and demonstration; the text should still identify the object, audience, claim and context. Essential meaning shouldn’t depend on a viewer recognizing an unlabeled product.

    Keep volatile facts maintainable. Pricing, availability, locations, eligibility and product status should have a clear canonical home. Update that destination when the fact changes, then align the social content that still receives attention. Scattering the same changing fact across many permanent assets makes contradictions more likely.

    If your website uses structured data, make sure the markup agrees with the visible page. Treat schema as a consistency and interpretation layer, not as proof of a direct Meta AI ranking lever. Perfect markup cannot repair vague copy, unsupported claims or conflicting brand information.

    Give each Meta surface a distinct content job

    Your brand can be encountered across Instagram, Facebook and the Meta AI chatbot. The factual spine should remain consistent, but the content unit that earns attention in a feed isn’t necessarily the one that resolves a detailed question.

    ContextPrimary content jobWhat to prepareFailure to catch
    InstagramMake the brand and its proof recognizable in a visual settingVisual demonstrations supported by captions that name the product, audience, use case and evidenced benefitThe content looks polished, but a new viewer cannot tell what is offered or for whom
    FacebookCarry fuller explanations, current business context and practical detailsMaintained profile information, clear explainers, question-led updates and links to canonical evidenceAn old description, link or offer conflicts with the current website
    Meta AI chatbotResolve a user’s question with an accurate brand representationDirect, self-contained answers and verifiable supporting pages for the prompts that matterThe brand is absent, placed in the wrong category, described inaccurately or mentioned without support
    Owned websiteAct as the canonical evidence layerStable brand facts, focused answer pages, clear ownership and aligned structured data where usedSocial claims have no durable destination where a person can verify them

    On Instagram, don’t force every caption to become a miniature landing page. Give the visual one clear proof job, then use the caption to identify what is being shown and why it matters. If the post demonstrates a workflow, name the workflow. If it shows a result, state what produced the result and avoid implying that one example is universal.

    On Facebook, use the room available to answer the questions that arise after initial interest: who the offer is for, what the process involves, where it is available and which conditions apply. Keep profile-level facts especially clean because they frame everything published beneath them.

    For chatbot visibility, work backward from the prompt. If someone asks for options in a category, can your public content connect the brand to that category without interpretation? If someone asks whether the offer fits a constraint, is the condition stated explicitly? If someone asks why the brand is credible, can they reach evidence rather than another assertion?

    Don’t clone every asset across every surface. Preserve the names, categories, claims and proof, then change the delivery. Instagram may demonstrate the claim, Facebook may explain its context and the website may hold the complete evidence. The message should become richer as the user needs more detail, not mutate into a different brand story.

    Audit prompts, diagnose the gap and fix it in order

    A laptop with a blank conversational interface sits beside organized brand evidence trays, while a magnifying glass highlights a broken connection in a chain of glowing nodes.

    AI visibility cannot be managed from a single screenshot. Wording and context can change an answer, so save the exact prompts you use and repeat them under comparable conditions. The goal isn’t to manufacture a universal score. It is to notice persistent omissions, factual errors and unsupported representations.

    Build the audit from your visibility brief. Include unbranded discovery questions, fit questions, comparison questions, brand-validation questions and action questions. Avoid leading every prompt with your desired answer. A test such as “Why is [Brand] the best option?” presupposes both inclusion and superiority; it tells you little about natural discovery.

    For every run, record:

    • The exact prompt and the user intent it represents.
    • The surface and testing context.
    • Whether the brand appeared without being named in the prompt.
    • Whether its category, audience, offer and location were correct.
    • Which material claim was present, missing or wrong.
    • Whether evidence or a useful path was surfaced, when the interface provided one.
    • Which controlled page or Meta asset should resolve the gap.
    • What you changed before the next comparable test.

    Use descriptive states instead of fake precision: absent, mentioned, accurately represented, supported and actionable. A brand can move through those states without becoming the first name in an answer. That movement still matters because correct representation is a prerequisite for trustworthy discovery.

    Read each pattern as a diagnostic hypothesis, not as proof of a hidden ranking factor:

    • Absent from unbranded prompts: Check whether your content explicitly connects the brand to the category, problem, audience and market in question.
    • Mentioned in the wrong category: Look for outdated bios, vague slogans, legacy pages and inconsistent third-party descriptions.
    • Correctly described but unsupported: Strengthen the evidence destination and connect relevant social claims to it.
    • Visible for the brand name but not the problem: Build content around the user’s situation instead of publishing more brand announcements.
    • Visible on a Meta profile but inaccurate in an answer: Compare prominent profile facts with the canonical website record and remove contradictions you control.
    • Accurate but not actionable: Replace generic links with a destination that matches the prompt’s intent.

    Fix gaps in a deliberate order. Accuracy comes first because additional distribution can spread an error. Resolve conflicting identity facts next. Then add the missing answer and evidence. Adapt it to the relevant Meta surface after the canonical version is sound. Amplification belongs at the end.

    1. Correct factual errors and potentially misleading claims.
    2. Align the canonical brand record across controlled properties.
    3. Create or improve the answer and its supporting evidence.
    4. Package the material for the relevant Meta context.
    5. Retest the same prompt before expanding the change.
    6. Apply the lesson to the next high-value query.

    Change one meaningful layer at a time when you want to learn from the result. If you rewrite the website, replace every profile description and launch a large campaign simultaneously, you may improve visibility but won’t know which gap mattered. Keep a simple change log tied to the prompt set.

    Key takeaways

    • Meta AI visibility is query-specific; define the user question and the acceptable answer before measuring it.
    • A stable brand record matters more than repeating identical promotional copy across channels.
    • Answer-ready content pairs a direct claim with scope, evidence, boundaries and a relevant next step.
    • Instagram, Facebook, the chatbot context and your website should perform different jobs while preserving the same facts.
    • Track absence, accuracy, support and actionability separately so you can fix the actual weakness.
    • Treat audit patterns as clues to investigate, not as proof that you have discovered Meta AI’s internal ranking formula.

    Start with the unbranded question that matters most to your next customer. Write the canonical answer, align the brand facts around it, publish evidence that can be checked and record a baseline response. Once that question is represented accurately, move to the next one. You will be building a maintainable visibility system rather than another stream of disconnected content.

    References

  • Legal GEO Agencies: How to Choose the Right Partner

    Legal GEO Agencies: How to Choose the Right Partner

    You are not choosing a legal GEO agency because your firm needs another marketing acronym. You are choosing one because prospective clients can now encounter an AI-generated answer before they see a search result, visit a practice-area page, or recognize your firm’s name. The right partner must improve that discovery path without weakening factual accuracy, attorney-advertising compliance, or your control over the firm’s digital assets.

    The market does not make that choice easy. By the first half of 2025, the field was crowded enough for 43 law firm GEO agency contenders to be evaluated. A large field creates apparent choice, but labels such as GEO, AEO, AI SEO, and AI visibility do not tell you what an agency actually delivers. You need to evaluate the operating model behind the label.

    Map the agency landscape to your actual bottleneck

    Generative engine optimization is the work of making an organization and its information easier for generative systems to retrieve, understand, verify, and use in an answer. It overlaps with SEO, content strategy, structured data, digital public relations, entity management, and reputation work. That overlap explains why very different agencies can all sell a service called GEO.

    Most legal GEO providers can be understood through four broad operating models. These are not rigid categories, and a capable agency may combine several. Use them to identify the provider’s center of gravity:

    • Legal SEO agencies with a GEO practice: These providers usually begin with crawlability, search demand, practice-area architecture, local visibility, and content. They are a sensible fit when your conventional search foundation is weak. Verify that GEO adds prompt research, citation analysis, entity work, and answer-level measurement rather than merely placing a new name on an existing SEO package.
    • GEO or AEO specialists: These agencies tend to start with generative answer surfaces, prompt sets, cited-source patterns, brand mentions, and entity clarity. They may suit a firm with mature SEO operations that needs a dedicated AI-search layer. Verify their understanding of legal review, local discovery, jurisdiction-specific content, and attorney-advertising restrictions.
    • Content and authority specialists: These providers concentrate on expert content, editorial positioning, third-party mentions, and digital PR. They can help when your website is technically sound but your firm lacks corroborating authority beyond its own domain. Verify that they can diagnose technical and entity problems rather than treating every visibility gap as a publishing problem.
    • Technical and structured-data consultancies: These providers focus on information architecture, structured data, feeds, entity reconciliation, and machine-readable consistency. They can resolve foundational ambiguity, but technical markup alone is not a complete GEO strategy. Verify who will improve the underlying legal content and build credible external corroboration.

    Choose the model that matches the constraint. If search systems cannot reliably crawl or interpret your pages, start with technical and entity work. If your pages are accessible but generic, stale, or jurisdictionally vague, prioritize legal editorial operations. If your firm publishes strong material but appears nowhere outside its own properties, authority development may matter most. If you cannot tell whether any of this is working, fix measurement before funding a larger content program.

    This diagnosis also prevents an expensive mismatch. A firm with contradictory attorney biographies does not primarily need more blog posts. A firm with accurate, useful content but weak independent recognition does not primarily need another schema deployment. Make each agency name the bottleneck it believes it is solving and show the evidence behind that diagnosis.

    Define success before an agency defines it for you

    A legal GEO program can generate impressive-looking reports without answering the commercial question: is the firm becoming easier for the right person to discover and evaluate? Avoid that trap by defining the measurement system in your brief, before you review proposals.

    Build a query portfolio, not a keyword list

    Traditional keywords remain useful, but generative searches often contain a situation, constraints, follow-up questions, and evaluation criteria. Build a prompt portfolio around the decisions your prospective clients make. It should cover:

    • Branded accuracy: Questions about your firm, attorneys, offices, services, credentials, and public contact information.
    • Problem discovery: Questions asked before a person knows the legal name of the relevant practice area.
    • Service evaluation: Questions comparing approaches, qualifications, jurisdictional coverage, or the factors involved in choosing counsel.
    • Local and jurisdictional intent: Questions in which location, court, governing law, licensing, or service area materially changes the answer.
    • High-consideration questions: Questions about process, possible costs, timelines, evidence, risk, and what information someone should prepare before contacting a lawyer.

    Do not put confidential intake facts or identifiable client information into this prompt set. Use public facts, redacted patterns, or hypothetical wording approved by the firm. If an agency wants real client material for testing, require a documented data-handling review before sharing anything.

    Keep a stable benchmark set for comparison while allowing a separate exploratory set for emerging questions. For every observation, record the exact prompt, product or answer surface, date, visible location or account context, response, cited pages, brand mentions, factual errors, and relevant call to action. Generative output can change between runs, so a visibility score without the underlying observations is not auditable evidence.

    Separate four outcomes that vendors often blur together

    • Retrievability: Can the system access and interpret the firm’s relevant information?
    • Visibility: Does the firm appear as a mention, cited source, or possible provider for the agreed prompt portfolio?
    • Accuracy: Are descriptions of attorneys, services, locations, qualifications, and legal topics correct and appropriately qualified?
    • Qualified demand: Does visibility contribute to relevant visits, consultations, or intake rather than merely producing more brand mentions?

    A mention is not necessarily a citation. A citation is not necessarily a recommendation. A recommendation is not necessarily a qualified inquiry. Your reporting should preserve those distinctions instead of compressing them into one proprietary score.

    There is also no single permanent AI rank equivalent to a fixed position you can purchase or guarantee. Responses can depend on the wording of the prompt, available sources, product behavior, user context, and changes outside the agency’s control. Treat a promise of guaranteed placement as a warning sign. A credible agency should commit to defined work, transparent evidence, and measurable coverage, not an answer it does not control.

    Inspect the complete GEO delivery system

    Researchers, legal reviewers, and technical specialists work across connected stations containing source materials, compliance checks, publishing tools, and analytics.

    A proposal should connect technical access, entity clarity, content quality, external corroboration, measurement, and legal governance. If any component is missing, ask who owns it. Work divided between your agency, web team, attorneys, public-relations provider, and intake team still needs one accountable workflow.

    Technical access and entity clarity

    The agency should examine whether important pages can be crawled, rendered, indexed, and reached through coherent internal links. It should identify conflicting canonical signals, accidental noindex rules, thin duplicates, broken redirects, fragmented office information, and practice pages that compete with one another. Publishing more content before resolving those issues can expand the ambiguity.

    For a law firm, entity work should reconcile the firm name, offices, attorneys, practice areas, jurisdictions, credentials, public profiles, and relationships between them. An agency should be able to explain which property is authoritative for each fact and how corrections move across the firm’s site and legitimate external profiles.

    Structured data can make those relationships more explicit, but it must describe visible, supportable information. Appropriate organization, legal-service, person, address, article, and breadcrumb markup may help machines interpret a page. Markup must not introduce awards, ratings, locations, services, or credentials that a user cannot verify on the page. Ask for validation results, a mapping between each field and its visible source, and a process for updating markup when attorneys or offices change.

    Legal content that is answerable and reviewable

    Good legal GEO content should answer a defined question directly, state the jurisdiction or scope where it matters, explain material conditions, and give the reader a sensible next step. It should also make authorship, legal review, and update responsibility clear. A disclaimer does not repair inaccurate or overbroad legal information.

    Ask how the agency turns one topic into a coherent information structure. The answer should address the main page, supporting questions, internal links, attorney and practice relationships, source maintenance, consolidation of overlapping pages, and updates when the underlying law or the firm’s services change. A publishing quota without a maintenance plan creates a growing accuracy liability.

    Require a firm-side lawyer or ethics reviewer familiar with the relevant jurisdiction to approve claims about results, specialization, credentials, testimonials, comparisons, and past matters. Attorney-advertising and professional-conduct requirements vary, and an outside marketing agency should not make the final compliance judgment. Unsupported superlatives and invented expertise are dangerous in page copy, structured data, directory profiles, and AI-generated drafts alike.

    External corroboration rather than manufactured signals

    Generative systems may encounter information about your firm on third-party sites as well as your own domain. The agency should therefore audit which external pages appear around your priority questions, which ones describe the firm, whether those descriptions are accurate, and where credible gaps exist.

    Ask how the provider distinguishes legitimate authority development from low-value placement. A relevant editorial mention, accurate professional profile, or genuinely useful expert contribution serves a different purpose from bulk links on unrelated sites. The plan should name the audience and information gap each placement is intended to address. “More backlinks” is not an adequate GEO rationale.

    Governance, correction, and data handling

    No agency can directly control every answer generated by a third-party model. It can, however, detect recurring errors, trace likely contributing pages, correct owned information, request appropriate corrections from external publishers, and document whether the error persists. Require a correction workflow with an owner, evidence log, escalation path, and closure rule.

    Ask which AI tools the agency uses, what it uploads, whether submitted material may be retained or used to improve third-party systems, who can access project data, and what happens to that data after the engagement. Do not permit confidential case files, privileged communications, unannounced matters, intake records, or personal information to be placed in external AI tools without an approved legal, privacy, and security process. Synthetic or redacted test data is the safer default.

    Select an agency with a proof-based procurement process

    Law-firm leaders review anonymized evidence folders, technical samples, ownership documents, and abstract performance dashboards during an agency selection meeting.

    Give every finalist the same brief. Include your priority practices, jurisdictions, office structure, target audiences, known technical constraints, approval requirements, prompt portfolio, and available analytics. Comparable inputs make it harder for polished presentations to hide weak diagnosis.

    Then ask each finalist to assess a small, public portion of your current footprint. The exercise should use no confidential data and require no production access. You are looking for the quality of its reasoning: what it notices, how it separates evidence from inference, which constraint it prioritizes, and how it would verify the result.

    Evaluation areaEvidence to requestWeak response to notice
    BaselineExact prompts, answer captures, cited URLs, factual-error log, and stated testing contextA single visibility percentage with no underlying observations
    DiagnosisA prioritized explanation connecting technical, entity, content, authority, and measurement findingsA generic recommendation to publish more content
    ImplementationNamed deliverables, responsible owners, dependencies, approval steps, and acceptance criteriaA list of activities with no definition of completion
    Legal quality controlA workflow for jurisdictional review, claims approval, corrections, and documented updatesReliance on AI drafting plus a general website disclaimer
    MeasurementRaw prompt-level evidence connected to citations, accuracy, site behavior, and qualified intake where measurableBrand mentions presented as leads or revenue
    Data and ownershipWritten terms covering credentials, content, structured data, dashboards, prompt sets, exports, retention, and deletionCritical assets available only inside the vendor’s account

    Your proposal review should force clear answers to the following questions:

    1. What does the agency’s GEO service add beyond its ordinary SEO, content, public-relations, or technical work?
    2. Which part of our current visibility problem does the agency believe is most important, and what evidence supports that conclusion?
    3. How will it distinguish a brand mention, a linked citation, a favorable description, a recommendation, a site visit, and a qualified inquiry?
    4. Which prompts and answer surfaces will be monitored, and will we receive the raw observations behind every aggregate score?
    5. Who writes, verifies, legally reviews, publishes, and maintains each deliverable?
    6. How are confidential information, personal data, prompts, drafts, account credentials, and third-party AI tools handled?
    7. Does the agency work with competing firms in the same practice and market, and what conflict or exclusivity terms apply?
    8. Which content, code, markup, accounts, dashboards, research, and historical data can we export if the engagement ends?

    Do not let a case study substitute for this examination. Even a real result may depend on a different practice area, market, domain history, brand, content library, or measurement method. Ask the agency to show the starting condition, work performed, evidence captured, and limits on what can be attributed to GEO. If it cannot explain the mechanism, the headline result is not useful for your decision.

    The contract should make the operating model concrete. Define deliverables and acceptance criteria; separate agency responsibilities from firm dependencies; identify third-party costs; preserve your approval rights; prohibit unsupported factual or performance claims; address conflicts, confidentiality, data retention, and AI-tool use; and guarantee usable exports of firm-owned assets at termination. Have qualified counsel review terms that affect confidentiality, intellectual property, professional obligations, privacy, or liability.

    Walk away from guarantees of permanent AI placement, schema-only “optimization,” undisclosed bulk AI publishing, unverifiable proprietary scores, fabricated citations, or a refusal to provide raw evidence. Also be cautious when an agency treats every unfavorable answer as a content-volume problem. Sometimes the correct action is to repair a fact, consolidate pages, clarify an entity relationship, improve an external profile, or stop publishing material that no longer deserves to exist.

    Key takeaways and your first move

    • Choose an agency for the bottleneck it can solve, not the GEO label it places on its services.
    • Define a prompt portfolio and preserve raw answer-level evidence before accepting any visibility score.
    • Measure retrievability, visibility, accuracy, and qualified demand separately.
    • Require technical access, entity clarity, useful legal content, external corroboration, and governance to work as one system.
    • Keep legal approval, sensitive data, account access, and ownership of project assets under firm control.
    • Reject guaranteed placements and demand a traceable connection between diagnosis, work performed, and observed change.

    Your next move is to write a one-page decision brief before contacting more agencies. Name the practices and jurisdictions in scope, the audiences you need to reach, the public facts that must remain accurate, the prompt categories you will test, the internal reviewers who can approve work, and the assets the firm must own. Send the same brief to each finalist and select the team that returns the clearest diagnosis, evidence trail, and operating plan. That discipline will tell you more than any agency ranking can.

    References

  • How to Track Brand Visibility Across AI Search Platforms

    How to Track Brand Visibility Across AI Search Platforms

    You ask an AI assistant for the best options in your category. Your brand appears. You change a few words, try another platform, or add a location, and it disappears. That is a useful spot check, but it is not visibility tracking.

    A defensible tracking program uses a fixed set of prompts, consistent labels, and saved answer evidence. It tells you where your brand is mentioned, whether it is recommended, which sources support the answer, which competitors occupy the same space, and whether the description is accurate. More importantly, it tells you what to fix next.

    Stop treating AI visibility like a single keyword rank

    A traditional rank tracker asks where a URL appears for a keyword. AI search often returns a synthesized answer instead of a stable list of links, and those answers may mention, recommend, or cite only a small selection of brands and sources. A position-based metric cannot describe all of those outcomes.

    Use a prompt-level definition instead: AI search visibility is your brand’s observable presence and representation across a controlled set of prompts, platforms, markets, and collection runs. The basic unit is not a keyword position. It is a platform-prompt-market observation with a saved response behind it.

    Each observation should distinguish several states:

    • Mention: The answer names your brand, product, service, or another recognized brand entity.
    • Recommendation: The answer explicitly presents the brand as a suitable choice, shortlist candidate, or conditional fit.
    • Citation: The answer links to or identifies a source associated with the brand. Record this only when the interface exposes citations.
    • Representation: The answer describes the brand favorably, neutrally, unfavorably, or with a meaningful qualification.
    • Accuracy: The claims about the brand are correct, incorrect, ambiguous, or too incomplete to evaluate.

    These states are not interchangeable. A mention can be negative. A citation can support a category fact without recommending the company that published it. A recommendation can rely on a third-party source rather than the brand’s own site. If your dashboard collapses all of them into a single visibility score, you will not know whether you have a discovery problem, an evidence problem, a positioning problem, or a reputation problem.

    That is also why a successful ChatGPT result cannot stand in for the entire market. Visibility can differ across ChatGPT, Claude, Gemini, and Perplexity. Report each surface separately before producing any aggregate view.

    Build a prompt set around real customer decisions

    Your prompt set determines what your visibility score means. If every prompt includes your brand name, the tracker measures how the systems describe a known entity. It does not measure whether the brand gets discovered when a buyer has not named it.

    Build separate prompt groups for the decisions you need to observe:

    • Category discovery: Which [category] options fit [audience or use case]?
    • Problem-led discovery: What is a good way to solve [specific problem] under [constraint]?
    • Comparison: How do [brand or product] and its alternatives differ for [use case]?
    • Requirement matching: Which options support [required capability, integration, market, or workflow]?
    • Branded validation: Is [brand] appropriate for [audience], and what are its limitations?
    • Factual verification: Does [brand] provide [specific feature, service, policy, or availability]?
    • Post-purchase help: How do users complete [task] with [brand or product]?

    Unbranded prompts measure discovery and category association. Branded prompts measure understanding, accuracy, and reputation. Keep their results separate. Otherwise, strong performance on easy branded questions can conceal absence from the category questions that introduce new buyers to a company.

    Use neutral wording. A prompt such as Why is [brand] the best choice? presupposes the result and cannot tell you whether the brand would appear naturally. Ask which options fit a defined need, then let the answer reveal the competitive set.

    Store enough metadata to reproduce each observation:

    • A stable prompt ID and the exact prompt text.
    • The intent group and business question behind the prompt.
    • Whether the brand was named in the prompt.
    • The platform and any model or search-surface label displayed to the user.
    • The market, location, and language used for the run when they matter.
    • The audience, product line, or use case being tested.
    • The prompt version and the date that version became active.

    Location deserves its own field rather than a note buried in the prompt. Tracking by location can expose market-specific gaps that disappear inside a global average. This is especially relevant when availability, terminology, regulations, service areas, or competitors differ between markets.

    Freeze the wording once a prompt enters the benchmark set. If you discover a better version, create a new version and establish a new baseline. Quietly rewriting prompts between runs makes a reporting change look like a visibility change.

    Record answer evidence, not just a visibility score

    Abstract AI response cards are organized with colored evidence markers, source tiles, and saved snapshots on a dark tabletop.

    Define every metric before collecting results. In particular, define an eligible answer as a completed response to an in-scope prompt. Log platform errors, refusals, and unavailable responses separately. Treating a failed run as a brand omission would contaminate the denominator.

    MetricOperational calculationWhat it helps you diagnoseMain caution
    Mention rateEligible answers naming the brand divided by all eligible answers in the segmentBasic discovery and entity recognitionA mention is not necessarily positive or prominent
    Recommendation rateEligible answers explicitly recommending or shortlisting the brand divided by all eligible answers in the segmentWhether the brand is presented as a viable choiceSeparate unconditional recommendations from recommendations limited by a caveat
    Citation rateEligible answers citing a brand-associated source divided by answers for which citations are exposedWhether the brand’s evidence is being selected as supportNot all interfaces expose citations; mark those cases unavailable rather than uncited
    AI share of voiceBrand mentions divided by mentions of the defined competitor set within the same prompt segmentRelative presence in competitive answersThe result depends on the prompt mix and competitor definition
    RepresentationDistribution of favorable, neutral, unfavorable, and qualified descriptionsPositioning, reputation, and recurring objectionsSave the exact claim and reason for the label; sentiment alone is too blunt
    Factual accuracyDistribution of accurate, inaccurate, ambiguous, and unevaluable brand claimsEntity consistency and misinformation riskReviewers need an approved factual reference for comparison
    Platform coveragePlatforms with an observed mention divided by platforms tested for the same prompt segmentCross-platform resilienceDo not let an aggregate hide a weak individual platform

    Citation frequency, brand visibility, AI share of voice, sentiment, and cross-platform coverage belong in the same scorecard because each answers a different question. If your tool supplies a composite visibility score, document its formula and retain the component metrics. A rising aggregate can otherwise conceal worsening accuracy or a loss of recommendations on commercially important prompts.

    Save the evidence needed to audit a result

    A row with only a yes-or-no mention field is not enough. Save the exact response, collection time, prompt version, platform label, market, citation URLs, cited domains, competitor mentions, recommendation wording, representation label, factual issues, and reviewer notes. Where the platform permits it, retain a response link or screenshot as well.

    Classify cited domains as owned, independent third-party, competitor-owned, or another relevant type. That distinction matters. An answer citing your documentation points to a different opportunity than an answer recommending your brand while relying entirely on an external review or directory.

    Human review remains important for conditional language. Suitable for small teams that do not need [capability] is not equivalent to a general endorsement. A tracker that counts both as positive recommendations may produce a clean chart and a misleading decision.

    Use a collection cadence you can reproduce

    Begin with a baseline run across the full prompt-platform-market matrix. Repeat the same matrix at a regular interval, and capture additional before-and-after runs around material content, product, or entity changes. Keep prompt versions and segments consistent during the comparison.

    Do not interpret one generated answer as a trend. Look for a pattern that repeats across related prompts, collection runs, platforms, or markets. A manual spreadsheet can establish this discipline while the prompt set is small. When the workload grows, evaluate GEO tracking tools on prompt control, raw-response retention, citation capture, platform and location segmentation, competitor grouping, historical comparisons, exports, and transparent metric definitions.

    Turn recurring patterns into specific GEO work

    A strategist turns repeated patterns from abstract AI answer chambers into website, source, location, and fact-checking work.

    Start with the pattern in the evidence, not with a general instruction to publish more. Different gaps call for different work.

    Your brand is absent from unbranded discovery prompts

    First, check whether the absence repeats across related prompts and whether competitors appear consistently. Then inspect the claims and sources used in those answers. You are looking for a missing association: a category, use case, audience, capability, problem, or market that competitors explain more clearly.

    Create or strengthen a focused page that answers the missing intent directly. State who the offering is for, which problem it solves, what it supports, where it applies, and what its meaningful limits are. Link that page to the relevant product and organization entities. Use appropriate structured data to reinforce names and relationships already visible in the content, but do not treat markup as a substitute for a clear answer.

    This is the practical meaning of expanding your semantic footprint, fact density, and entity authority: cover the relationships buyers ask about, make important claims explicit and supportable, and keep the identity of the organization and its offerings consistent.

    Your brand is mentioned but rarely cited or recommended

    A mention without a citation can indicate that the entity is recognized while its owned evidence is not being selected. Review which domains the answers do cite. If they consistently provide concise definitions, comparison criteria, specifications, or market facts that your pages obscure, improve the relevant evidence on your site and remove contradictions between pages.

    A citation without a recommendation is a different gap. Your content may be useful as evidence while the offering’s fit remains unclear. Strengthen the pages that explain the intended audience, requirements, tradeoffs, integrations, constraints, and differentiators. Do not manufacture praise. Give the system enough accurate context to determine when the brand is and is not a sensible option.

    The answer gets your brand wrong

    Record the exact incorrect claim rather than assigning only a negative sentiment label. Then identify whether your own site contains conflicting names, outdated facts, unclear availability, or ambiguous product relationships. Establish a canonical location for each important fact, correct internal contradictions, and align visible copy with structured entity information.

    If the claim comes from external coverage, the work may involve reputation management, clearer public documentation, or credible third-party corroboration. Do not try to suppress a valid limitation. Explain the current position accurately and address the underlying issue where possible.

    One platform or market underperforms

    Do not rewrite the entire site because one surface produced a weak answer. Confirm that the same prompt, language, location, and evaluation rules were used. Compare the source types and competitor claims selected by the stronger and weaker platforms. A platform-specific gap may point to missing evidence in the sources that surface retrieves, while a market-specific gap may point to unclear local availability, terminology, or entity information.

    Prioritize changes using business impact, repeatability, evidence, and control. A recurring absence on important unbranded prompts is more actionable than an isolated wording difference. A verified factual error on a decision-stage prompt deserves attention before a minor shift in a blended score. A gap tied to a page you control can usually be addressed more directly than a change in an opaque platform behavior.

    After making a change, measure both layers. The first layer is the AI response: mentions, citations, recommendations, representation, and accuracy. The second is the business outcome available in your analytics, such as relevant referral activity, branded interest, or qualified conversions. An AI mention is evidence of visibility, not proof of revenue.

    Key takeaways

    • Track platform-prompt-market observations, not a supposed universal AI rank.
    • Separate unbranded discovery prompts from branded reputation and accuracy prompts.
    • Measure mentions, recommendations, citations, share of voice, representation, accuracy, and platform coverage independently.
    • Preserve exact prompts and raw responses so every chart can be audited.
    • Diagnose repeated patterns before choosing a content, entity, technical, or reputation fix.
    • Keep AI visibility metrics connected to business outcomes without treating a mention as a conversion.

    Your next move is simple: open a tracking sheet, choose a small but balanced set of branded and unbranded prompts, run the same set across the platforms and markets that matter, and label each answer with the definitions above. Select the clearest recurring gap, make the narrowest relevant improvement, and preserve the prompt set for the next run. Once you can explain why a metric moved and what evidence changed, you are tracking visibility rather than collecting screenshots.

    References

  • Commercial Intent in AI Chats: Where Brands Should Focus

    Commercial Intent in AI Chats: Where Brands Should Focus

    If you are budgeting for AI visibility on the assumption that every product mention is close to a sale, stop and reclassify the opportunity. Commercial demand exists in AI chats, but much of it appears while people are framing a problem, weighing approaches, or trying to succeed with something they already bought.

    Your job is to recognize those moments without forcing a sales funnel onto every conversation. That changes which pages you prioritize, how you structure an answer, where you place the next action, and what you count as success.

    Commercial intent is a minority, but it is not one moment

    Across a corpus covering 4.4 billion characters, 613 million words, and 3.9 million conversation turns, people used AI heavily for tasks such as planning, brainstorming, analysis, learning, transformation, and creation. Those activities may happen at work or mention a product, but that does not automatically make them commercial.

    Within a categorized sample of 24,259 sessions spanning 42 intent categories, 64.6% did not fit a purchase funnel, while 35.4% showed some form of commercial intent. The useful correction is not that AI chats have no commercial value. It is that commercial value is distributed across several different jobs, most of which are not an immediate purchase request.

    Awareness accounted for 10% of the categorized sessions and consideration for 8.5%. Together, those early stages represented 18.5% of all sessions and the largest block of commercial activity. Discovery accounted for 4.1%, decision support for 2.8%, transactional support for 4.8%, and post-purchase needs for 5.1%.

    That distinction matters when you set priorities. If your AI strategy watches only prompts containing words such as buy, price, best, or demo, it will miss people who are still deciding what kind of solution they need. It will also miss existing customers asking how to configure, use, integrate, or repair what they own.

    Do not treat the percentages as a universal forecast for every market. They describe the analyzed corpus, not the exact intent mix for your category. Use them to challenge an overly transactional strategy, then classify the questions that appear in your own sales, support, search, and customer research.

    Classify the user’s job before choosing the content

    Four connected rooms show a user investigating a problem, exploring approaches, comparing products, and learning to use an owned device.

    A noun is not an intent signal. A user can mention your category while asking for writing help, summarization, technical instruction, product evaluation, or troubleshooting. Classify the job being done before deciding whether the conversation belongs in a commercial funnel.

    Intent classObserved shareWhat the user is trying to doWhat your content should accomplish
    Outside the purchase funnel64.6%Create, learn, analyze, plan, transform, or converse without making a product choiceComplete the requested task honestly; introduce a commercial path only when it is genuinely relevant
    Awareness10%Name a problem, understand its causes, or learn what kinds of solutions existDefine the problem, explain when it matters, and make the available approaches understandable
    Consideration8.5%Compare approaches, requirements, or tradeoffsProvide selection criteria, limitations, alternatives, and use-case fit
    Discovery4.1%Find products, providers, or options in a categoryHelp the user build a defensible shortlist without hiding eligibility criteria or constraints
    Decision support2.8%Choose among known optionsSupply verifiable details about fit, evidence, implementation, cost factors, and risk
    Transactional support4.8%Complete or manage a commercial actionRemove uncertainty about requirements, process, timing, and what happens next
    Post-purchase5.1%Set up, use, improve, or troubleshoot something already acquiredHelp the customer reach the intended result and recover from predictable failures

    The percentages in the table are rounded shares of the categorized sample. The user-job descriptions and content responses are practical applications of those intent classes.

    Context is decisive. Create a launch brief for this product is primarily a creation task. Which type of platform should our distributed team use to manage a launch? is consideration. Why did this feature stop working after setup? is post-purchase. The same category terms can appear in all three prompts, but only the latter two have an explicit relationship to choosing or owning a solution.

    Use a strict operational rule: label a conversation commercial only when the user is making an economic choice, evaluating a solution, completing a transaction, or seeking help with something already acquired. Do not inflate your opportunity estimate by treating every workplace task as latent demand.

    Build for exploration and ownership, not just selection

    Early-stage content should make the decision legible

    Awareness and consideration together accounted for 18.5% of all categorized sessions. This is where product-led content often arrives too early. A user who is still defining the problem does not need an unsupported claim that your product is the answer. They need enough structure to decide whether the category is relevant at all.

    A useful awareness or consideration page should do the following:

    • Answer the initiating question immediately. State the practical answer before company history, positioning, or a lead form.
    • Define the decision context. Identify who the advice applies to, the conditions that change it, and any prerequisites the user may not have mentioned.
    • Separate symptoms from causes. Help the user avoid buying a solution for the wrong problem.
    • Expose the criteria that change the choice. Explain requirements, constraints, tradeoffs, and cases in which a simpler approach is sufficient.
    • Include credible alternatives. A comparison is more useful when it covers different approaches, including doing nothing yet, rather than presenting a disguised product pitch.
    • Provide a natural next question. Link the problem explanation to criteria, the criteria to options, and the options to decision evidence.

    The first answer carries unusual weight. The median conversation in the corpus had two turns and 430 words, and more than 80% of chats stayed below 1,000 words. Many users therefore do not spend a long sequence teaching the assistant their context. Your page should state its audience, assumptions, constraints, and core answer clearly enough to survive a short exchange.

    This is also where answer-engine optimization and conversion writing need to part company for a moment. The strongest opening is the one that resolves the question accurately. The commercial handoff comes after the user can see why a category, method, or product deserves consideration.

    Post-purchase content belongs in the commercial strategy

    Post-purchase needs represented 5.1% of sessions, exceeding discovery at 4.1% and decision support at 2.8%. That is a clear reason not to limit AI optimization to comparison and product pages.

    Support content should be designed around the customer’s actual failure state, not your internal feature taxonomy. A page titled with the symptom a user can observe is more useful than one that assumes they already know which component caused it.

    • Name the symptom, task, or desired outcome in the title and opening.
    • State the applicable product state, configuration, prerequisites, and access requirements.
    • Put the resolution steps in the order the user must perform them.
    • Describe the expected result so the user can verify that each meaningful step worked.
    • Branch explicitly when different causes require different fixes.
    • Say when self-service should stop and what information support will need.
    • Connect the fix to related setup or usage guidance without turning the page into a sales pitch.

    Where security and account privacy allow it, publish general help in accessible, indexable page content. Keep account-specific data and privileged actions behind authentication. An AI visibility goal never justifies exposing information that should remain private.

    Audit AI demand by prompt, page, and outcome

    A strategist sorts abstract chat bubbles through webpage cards toward discovery, comparison, purchase, and customer-success outcomes.

    You do not need to guess whether your opportunity is mostly awareness, decision support, or ownership. Build an intent inventory from questions people already ask, then connect each question to a page and a measurable next step.

    1. Collect real questions. Pull wording from site search, sales conversations, support records, community discussions, product research, and known AI referrals. Preserve the original phrasing instead of rewriting everything as a target keyword.
    2. Assign one primary job. Label each question as non-funnel, awareness, consideration, discovery, decision, transactional support, or post-purchase. Record a secondary intent only when it changes the answer the user needs.
    3. Map the best existing page. Choose the page that should answer the question, not merely the page currently ranking for adjacent terms. A product page is not automatically the right destination.
    4. Find coverage and answer gaps. Mark questions with no page, pages that bury the answer, unsupported claims, missing limitations, stale instructions, or no sensible continuation.
    5. Repair the visible content first. Make the answer, scope, evidence, and next step explicit. Structured data should reflect what a user can actually see on the page; it cannot manufacture commercial intent or compensate for an evasive answer.
    6. Run repeatable prompt checks. Log the exact prompt, assistant, exposed model or version, date, language or market, answer, brand representation, and cited URLs. A single response is an observation, not a stable visibility benchmark.
    7. Measure the outcome appropriate to the stage. Evaluate awareness content by accurate inclusion and progression to deeper evaluation. Evaluate decision content by qualified actions. Evaluate post-purchase content by successful task completion and reduced escalation where those signals are available.

    Keep visibility and progression as separate measures. Visibility asks whether the assistant represents the right answer, entity, or page. Progression asks whether the user then reaches a useful next step. Combining them into one score hides whether you have a retrieval problem, an answer-quality problem, or a conversion-path problem.

    Referral traffic is also incomplete by definition. You can observe a visit only when a user follows a link; an interaction that ends inside the chat produces no referral session. Use AI referral data as evidence of visits and downstream behavior, not as a complete count of AI influence.

    Finally, compare like with like. Do not blend troubleshooting prompts and product-selection prompts into one visibility rate, then judge both by purchases. Segment the prompt set by intent, page type, market, and user state. The resulting report will tell you which content is failing and what kind of repair it needs.

    Key takeaways

    • Commercial intent appeared in 35.4% of the categorized AI chat sessions, while 64.6% did not fit a purchase funnel.
    • Awareness and consideration formed the largest commercial block, so problem framing and selection criteria deserve more attention than purchase language alone.
    • Post-purchase demand exceeded both discovery and decision support, making setup and troubleshooting content part of AI commerce strategy.
    • Classify the user’s job, not the presence of a product or business keyword.
    • Because the median chat was short, make the first answer self-contained, scoped, and useful before asking the user to take a commercial action.
    • Measure visibility, answer accuracy, progression, and business outcomes separately for each intent stage.

    Start with your own prompt inventory. Find an early-stage cluster and a post-purchase cluster with weak coverage, repair the answers and their handoffs, and retest them consistently. You will see where AI visibility can support demand and where usefulness should stand on its own.

    References