Category: Generative Engine Optimization (GEO)

  • How to Build Source Authority for Visibility in AI Search

    How to Build Source Authority for Visibility in AI Search

    Your pages rank well, yet ChatGPT, Google AI Overviews, and other answer engines rarely mention your brand. That gap usually isn’t solved by publishing another broad guide. You need to give AI systems a clear reason to use your page as evidence.

    The practical goal is to become the best available source for a specific claim, decision, or task. That means creating information worth citing, making it easy to verify, and measuring visibility as a trend rather than chasing a single generated answer.

    Key takeaways

    • Source authority comes from useful evidence, identifiable expertise, and claims that readers and machines can verify.
    • Original data, focused analysis, and named tools give AI systems more reason to cite you than interchangeable educational copy.
    • Put a direct answer near the top, then support it with methodology, examples, limitations, and a sensible next step.
    • Keep visible content, structured data, product feeds, internal links, and campaign assets consistent.
    • Measure recurring query pathways quarterly. Organic rankings and AI visibility overlap, but they are not the same performance system.

    Give AI systems something they cannot produce alone
    An expert documents a hands-on experiment while an abstract AI form observes the resulting evidence.

    An AI assistant can already explain a common concept by combining information it has encountered elsewhere. Rewriting that explanation at greater length rarely makes your domain essential. Your advantage begins where generic synthesis ends.

    Create material that depends on your access, experience, or product. Useful options include proprietary measurements, a transparent test, a customer-data pattern, a calculator, a benchmark, a decision framework, or an expert interpretation of a changing market. The asset does not need to be large. It needs to contain a defensible contribution that another answer can attribute to you.

    This distinction showed up sharply in a dataset covering 10 websites and 150,000 indexed pages. Trends and analysis content appeared in the citation pool 78% of the time, while educational how-to content accounted for 12%. Pages with unique data held a substantial advantage. Because these figures come from one dataset, treat them as a prioritization signal rather than a universal benchmark. The useful lesson is that distinct information gives a model a reason to retrieve your page.

    Before approving a new page, ask a hard editorial question: what will exist after publication that did not exist before? If the answer is only another explanation of established knowledge, narrow the topic until you can add a result, example, comparison, tool, or judgment that belongs to your organization.

    Build pages that are easy to quote and verify

    A useful page can still be difficult for an answer engine to use. The main claim may be buried beneath scene-setting, mixed with unsupported marketing language, or separated from the evidence that qualifies it. Reduce that extraction work.

    Start with an answer capsule: a short paragraph that states the answer, names the important condition, and tells the reader what to do next. Follow it with the supporting detail. This is not a detached summary written for bots. It is the fastest route into the page for a person who arrived with a precise question, and prominent, concise answers have also been associated with stronger LLM visibility.

    Then make the claim auditable. Identify what was measured, where the information came from, what the result applies to, and where uncertainty remains. If you publish an original dataset, describe the sample and method. If you make a recommendation, connect it to the observation behind it. If a claim comes from elsewhere, link to the primary material instead of a page that merely repeats it.

    Match each page to one clear search need. A research page should make its finding unmistakable. A tool page should name the tool, explain its input and output, and let the visitor use it without hunting. A service page should answer the commercial questions that determine fit. In the same 10-site dataset, service and product pages generated 29.4 LLM sessions per 1,000 organic sessions, compared with 23.4 for articles and 14.0 for FAQ or support pages. Tools also produced the strongest average LLM engagement at 146 seconds, reinforcing the value of pages that help visitors complete a task rather than merely read about it.

    Make authority consistent across every machine-readable input
    A central source connects to coordinated webpage, profile, data, research, and reference panels.

    Authority weakens when your page title promises one thing, the copy says another, and the structured data introduces facts a visitor cannot see. Treat each technical input as a consistent description of the same real-world page.

    Use schema that accurately matches the visible content. Keep names, URLs, product details, authorship information, and other important identifiers consistent wherever they appear. Do not use markup to imply a fact the page does not support. Structured data can clarify meaning, but it cannot manufacture credibility.

    Internal links should also communicate purpose. Link to the original research behind a claim, the relevant tool that applies it, and the service or product that solves the next problem. This creates a coherent evidence path instead of a collection of isolated pages.

    Apply the same discipline to paid visibility

    If you advertise in AI-assisted search, the landing page is only one of the inputs. Shopping relies heavily on product-feed quality, while Performance Max and AI Max can use page content, feeds, audience information, search intent, and creative assets to determine relevance. Clear product titles, complete descriptions, strong images, varied assets, and aligned landing-page copy therefore affect more than conversion after the click. They help the system understand which queries your offer can appropriately answer.

    Review the resulting search terms, selected landing pages, exclusions, and assets regularly. Automation expands reach, but your evidence, audience signals, and negative keywords still define the boundaries within which it operates.

    Build audience preference as well as algorithmic relevance

    Source authority is not confined to on-page optimization. It also grows when people recognize your name, choose your work, and refer others back to it. Google has made that relationship more visible by labeling user-selected preferred sources in AI experiences. More than 345,000 unique sources had been selected, and selected sources received twice the click-through rate.

    Do not treat preferred-source selection as a shortcut or assume it is a general ranking factor. Treat it as evidence that recognition matters after visibility is earned. Give readers a reason to remember where an insight came from: use a stable name for recurring research, make useful tools easy to revisit, update important pages visibly, and maintain a clear point of view within your field.

    The expansion of highly cited labels creates another incentive to publish the material others reference, not merely commentary derived from it. If your team has the primary numbers, the original reporting, or the working tool, place that asset on a durable URL and make it the canonical destination for future mentions.

    Measure query pathways instead of chasing one AI answer

    An AI response is not a fixed search ranking. Recommendations can change with the user’s wording, context, prior interaction, model, and interface. You usually cannot inspect the full chain that led to a mention. That makes a single prompt check a weak performance metric.

    Build a funnel query pathway instead. Define recurring query groups around the problems your buyers bring to AI systems: early discovery, evaluation, comparison, and action. Recheck the same groups quarterly with a stable method. Record whether your brand appears, which URL is cited, what role it plays in the answer, which competitors appear, and whether referrals lead to meaningful actions.

    Look for movement across the pathway rather than demanding precise rank tracking. Maintaining the same macro measurement method over eight quarters can reveal recommendation trends that isolated screenshots cannot.

    Keep organic and AI reporting separate. The top 10 organic pages in the 10-site dataset attracted more than half of organic sessions but only 29% of LLM sessions, and nearly half of the top 100 organic pages received no LLM traffic. Strong SEO remains valuable for discovery and technical accessibility, but it does not prove that an AI system will choose the same pages as answer material.

    Referral analytics also show only part of the picture. LLM crawlers can request pages before client-side analytics loads, so GA4 does not record those bot visits. Use referral sessions to understand human behavior, server-level evidence to inspect crawler access where available, and recurring prompt checks to observe recommendations. No one stream is a complete visibility score.

    For your next publishing cycle, choose a commercially important question for which your organization has evidence others do not. Publish the direct answer, expose the method, connect it to a useful tool or decision, and add the query to your quarterly measurement set. That is a manageable first step toward becoming a source AI systems can use and people can trust.

    References

  • SEO Strategy for AI Discovery: A Practical Operating Plan

    SEO Strategy for AI Discovery: A Practical Operating Plan

    You may still be earning rankings while becoming less visible at the moment a buyer forms a shortlist. SEO hasn’t stopped working. The path to a decision now runs through search results, AI-generated answers, brand verification, and sometimes a much later visit to your website.

    If your plan still equates success with sessions, publishes interchangeable answers, and treats every audit warning as urgent, your team will spend more without learning much. The practical shift is to make your knowledge easy for machines to extract, easy for people and systems to verify, and connected to pages where a buyer can act.

    Design for selection, verification, and action

    AI-driven discovery is not a separate funnel that replaces organic search. It is another layer in a fragmented journey. A buyer may investigate a category inside an assistant, verify a vendor through Google, visit a pricing or solution page, leave, and return through a branded search. That makes the eventual website session valuable, but it does not make the session a complete record of how the decision began.

    Your strategy therefore has to do more than win a position for a keyword. It has to help your brand become a plausible answer, provide evidence that the answer is accurate, and give the buyer a useful next step. Treat those as distinct jobs:

    JobWhat the buyer or system needsAssets to inspectQuestion for your team
    SelectionA clear match between a need, topic, entity, and answerEducational pages, category pages, definitions, and problem-led resourcesCan someone identify the subject and main answer without reconstructing it from vague copy?
    VerificationConsistent facts, boundaries, evidence, and relationshipsAbout pages, author information, methodologies, specifications, policies, and supporting evidenceCan an outside system check who made the claim, what it applies to, and why it is credible?
    ActionFit, cost, trade-offs, availability, and a sensible next stepHomepage, product pages, solution pages, pricing pages, and commercial contentDoes the page answer the questions that remain after basic research is complete?

    Assign every important page a primary job. A discovery page can support verification and action, but it should not try to perform every role equally. Once the role is clear, add contextual internal links to the evidence and decision pages a reader would logically need next.

    This also changes how you judge top-of-funnel content. Generic informational visits are increasingly vulnerable because buyers can get basic explanations without opening a website. Commercial and high-intent pages deserve their own reporting because a decline in broad informational traffic can coexist with stronger conversion performance. Discovery content is still useful when it establishes recognizable expertise, earns consideration, or moves a qualified reader toward verification. Traffic for its own sake is not enough.

    Turn expertise into machine-readable evidence

    Isometric illustration of an expert's source materials being organized into linked, verifiable information blocks.

    Many organizations already possess the knowledge needed to become useful answers. The problem is its form. Important facts can be trapped in PDFs, hidden behind forms, disconnected from structured data, or diluted by vague marketing language. A person with enough time may piece the meaning together. A retrieval system has a harder job.

    Run an extraction audit before adding more content

    Choose the entities, claims, and commercial facts that matter to a buying decision. Then inspect whether each one can be accessed, interpreted, and corroborated. Ask:

    • Is the essential information available in crawlable HTML, or does it exist only inside a PDF, image, gated download, script-dependent interface, or sales conversation?
    • Does the claim identify its subject, scope, audience, geography, conditions, and limitations?
    • Are company names, offering names, locations, credentials, and contact details consistent across the site?
    • Can a reader tell who is responsible for the information and what evidence or methodology supports it?
    • Do internal links connect the claim to the relevant organization, person, offering, location, and supporting material?
    • Does the structured data describe the same facts that a visitor can see, or has markup become a second and conflicting version of the business?

    When a critical document must remain a PDF, publish a useful HTML summary beside it. State what the document covers, expose the decisive facts in page text, and link to the full file for verification. Do not merely upload another copy and assume that availability equals understandability.

    Replace slogans with bounded statements. Innovative solutions for modern businesses gives a system almost nothing to work with. A stronger pattern is: the company provides a defined service, for a defined audience, in a defined market, with an explicit scope and boundary. The exact language will vary, but the statement should survive extraction without losing its subject or meaning.

    Use JSON-LD as a map, not as a substitute for evidence

    JSON-LD can make entities and relationships explicit. It cannot turn an unsupported assertion into a verified fact, rescue unclear page copy, or create authority by itself. Begin with visible, accurate information. Then use structured data to express the relationships among the business, its people, offerings, locations, and supporting material.

    Validation is only the syntax check. A technically valid graph can still be strategically empty. After validation, read every important property as if you were an unfamiliar buyer: Is the value specific? Is it consistent with the page? Does it distinguish the entity from similarly named entities? Does the relationship help explain why this business is relevant to the topic?

    Use descriptive headings, answer-first paragraphs, lists for criteria, and tables for genuine comparisons. This makes sections easier to retrieve without turning the page into disconnected fragments. Each section should identify its subject and answer a complete question, while internal links preserve the larger context.

    Treat platform-specific files as supporting infrastructure

    An llms.txt file may help systems that choose to use it even though Google does not require it. Treat it as a maintained navigation aid, not a universal ranking switch. It should point toward canonical, useful resources and stay aligned with the site. It does not replace crawlability, internal linking, structured data, or clear HTML content.

    The broader rule is important: do not let the requirements of a single platform define your entire discovery strategy. Preserve the technical foundations that conventional search needs, but evaluate additional systems on their own behavior, interfaces, and publisher support. AI discovery is multi-platform, and infrastructure that serves one system may be irrelevant to another.

    Put the next sprint behind the highest-leverage pages

    An AI discovery plan can quickly become a second backlog full of schema requests, content rewrites, technical warnings, monitoring tools, and speculative experiments. The cure is not a longer checklist. It is a stricter definition of impact.

    Start with pages that can influence a decision

    Review the homepage, pricing pages, product and solution pages, and other commercial content before commissioning another batch of generic explainers. These pages need to answer fit, scope, differentiation, evidence, limitations, and next-step questions. They are also where a late-stage visitor is most likely to arrive after researching elsewhere.

    Then look for existing demand you can compound. Pages already performing on the first results page and pages ranking in positions 11-30 can be stronger candidates than brand-new topics with no demonstrated traction. Refresh outdated sections, clarify the answer, add missing decision criteria, improve the search snippet, and link from relevant authoritative pages.

    When you do create content, ask what it contributes that an answer engine cannot reproduce from a collection of interchangeable pages. Useful differentiators include precise specifications, transparent methodology, original evidence, explicit limitations, expert reasoning, and decision criteria grounded in the actual offering. A page does not become non-commodity content merely because it is long.

    Filter every task through impact, reach, effort, and risk

    Audit software is good at detecting conditions and poor at understanding your commercial context. A warning affecting an abandoned legacy URL is not equivalent to a noindex directive on a revenue page. More importantly, a third-party audit score is not itself a ranking input.

    • Impact: Could the work materially improve qualified visibility, conversions, revenue, or the accuracy of how the brand is represented?
    • Reach: Does the issue affect an isolated legacy URL, an important page group, or the entire site?
    • Effort: What development, content, subject-matter, data, and approval work does the change require?
    • Risk: Could delay cause lost indexation, broken navigation, poor usability, compliance exposure, security problems, or an inaccurate public claim?

    Fix high-impact blockers immediately. These include serious crawlability and indexation failures, incorrect canonicals on important pages, server problems, migration defects, and issues with security or compliance implications. Schedule high-impact work that needs substantial resources. Bundle low-impact, low-effort cleanup with adjacent work. Deliberately leave low-impact, high-effort defects alone unless their context changes.

    That last choice is strategic neglect, not carelessness. Minor errors on non-indexable legacy URLs, insignificant redirect chains, non-critical HTML defects, and marginal performance refinements after a page reaches an acceptable state should not displace work on discoverability, evidence, internal linking, or conversion. Record the decision and its trigger for reconsideration so the same warning does not restart the debate every month.

    Measure influence without treating every click equally

    Conceptual illustration of a buyer moving through search, AI, verification, recommendation, and website touchpoints before a decision.

    Traffic remains useful, but it is no longer a sufficient definition of success. Even if the exact share varies by query and methodology, an estimated 60% of searches ending without a click to the open web makes session totals structurally incomplete. A missing click can mean the user received a satisfactory answer, never saw your brand, remembered your brand for later, or abandoned the task. Traffic alone cannot tell you which occurred.

    Separate your dashboard by page role and business intent. Do not blend a high-volume definition page with a pricing page and then judge both by the same traffic target.

    • Business outcomes: Track qualified leads, purchases, booked demonstrations, pipeline, and revenue where attribution is dependable.
    • Decision-page health: Monitor impressions, landing visits, engagement with meaningful next steps, and conversion rate for the homepage, pricing, product, solution, and commercial-content groups.
    • Discovery-page contribution: Track whether educational pages earn relevant visibility, attract qualified visitors, and lead people toward evidence or decision pages.
    • Visibility indicators: Watch branded search direction, detectable assistant referrals, and repeated appearance or citation across a stable set of buyer questions.
    • Technical eligibility: Monitor indexability, canonical behavior, server reliability, structured-data validity, and other conditions that can prevent an important page from being retrieved or trusted.

    Branded search volume can be a directional proxy for increased awareness, including awareness created inside AI systems, but it is not proof of AI attribution. Pair it with a stable prompt set. Use recurring discovery, evaluation, and decision questions; check the platforms your audience actually uses; and record whether your brand appears, which page is cited, whether the description is accurate, and which alternatives appear beside it. Look for repeated patterns rather than reacting to a single volatile answer.

    Your analytics may still miss the beginning of the journey. Add a simple first-heard-about-us field to an appropriate conversion flow, and include AI assistants among the response options when relevant. Self-reported attribution will not produce perfect channel accounting, but it can reveal influence that last-click reports hide.

    Most importantly, report trade-offs honestly. If broad organic sessions fall while qualified visits, decision-page conversions, and revenue rise, the program may be improving. If branded searches rise but the site cannot convert or verify the claims buyers encounter elsewhere, visibility is growing faster than readiness. Those are different problems and require different work.

    Key takeaways

    • Build for the full journey: selection as a possible answer, verification as a credible entity, and action on a decision-ready page.
    • Move decisive facts out of inaccessible files and vague copy into clear HTML, then use JSON-LD to describe the visible entities and relationships.
    • Prioritize commercial pages, proven search opportunities, differentiated evidence, and true technical blockers before broad cleanup.
    • Use impact, reach, effort, and risk to decide what enters the roadmap and what can be left alone.
    • Measure qualified outcomes, page-group health, branded demand, and repeatable AI visibility signals alongside traffic.

    For your next planning session, bring the page group closest to revenue, its recurring buyer questions, its extraction problems, and its conversion data into the same conversation. Fix the largest break in that chain first. That will tell you more about AI discovery readiness than another sitewide score ever could.

    References

  • How to Choose an Industry-Specific GEO Agency in 2026

    How to Choose an Industry-Specific GEO Agency in 2026

    You have a shortlist of GEO agencies, and every one claims to understand your industry. The hard part is deciding whether that specialization will change the work or merely decorate the proposal.

    Even bounded 2026 evaluations considered 68 environmental agencies, 42 hospitality agencies, and 38 entertainment agencies. Those counts are not a census of the market, but they make the procurement problem clear: an industry label is a weak filter. You need evidence that the agency understands your customers’ questions, your entities, your acceptable claims, and the business outcome behind AI visibility.

    Key takeaways

    • Industry specialization should change the agency’s query map, evidence requirements, entity strategy, content plan, and measurement model.
    • Ask for reproducible AI visibility evidence: the prompts, engines, outputs, cited URLs, recording conditions, and examples where the brand was absent.
    • Build your own evaluation scorecard. Environmental, hospitality, and entertainment evaluations assign different importance to specialization, leadership, reviews, client history, and media authority.
    • Treat structured data as supporting infrastructure. JSON-LD can clarify entities and relationships, but it cannot compensate for weak claims, missing evidence, or undifferentiated content.
    • Use a fixed-scope pilot with written acceptance criteria before committing to a broad retainer.

    Specialization begins with the industry’s decision process

    A specialist should be able to explain how people evaluate your category before discussing content volume. That explanation should identify the questions that lead to a shortlist, the facts needed to answer them, the entities involved, and the sources an AI system may encounter while forming an answer.

    The required knowledge changes materially by sector. The environmental category covers renewable energy firms, waste management facilities, and conservation nonprofits. Hospitality includes hotels, resorts, vacation rentals, hospitality groups, and travel brands. Entertainment spans venues, streaming platforms, production companies, festivals, and music labels. An agency that uses one generic playbook across those business models is selling a production method, not industry expertise.

    IndustryWhat the agency must modelProof to request
    EnvironmentalTechnical offerings, commercial buyers, public-interest questions, project evidence, and the distinctions among companies and nonprofitsA question map separated by organization type, audience, and decision stage, with the evidence required for each answer
    HospitalityProperties, brands, destinations, amenities, traveler intent, and the path from discovery to bookingA prompt map by traveler need and property type, plus an audit of property and brand entities across owned pages
    EntertainmentTitles, talent, venues, events, releases, distribution channels, reputation, and time-sensitive informationA content and authority plan tied to the actual titles, people, venues, events, or services the business needs audiences to discover

    Prepare a fit brief before speaking with an agency. State the commercial decisions you want to influence, the audiences making them, the entities that must be understood, the geographic or market boundaries, the claims you can substantiate, and the action that counts as business value. A specialist should refine that brief. If the proposal could be sent unchanged to a company in an adjacent sector, the claimed specialization has not affected the strategy.

    Score evidence, not the word “specialist”

    A strategy director examines case-study materials, entity tokens, source documents, a claim shield, and a customer decision path beside an empty presentation box.

    There is no universal agency-ranking formula. Environmental evaluations gave AI visibility a 25% weight and leadership experience 20%. Hospitality evaluations weighted AI visibility at 25%, industry specialization at 20%, notable clients at 15%, and GEO expertise at 15%. Entertainment evaluations placed 25% on leadership experience, 25% on reviews, 20% on founder involvement, 10% each on notable clients and media references, and 5% each on longevity and specialty.

    That variation matters. It means you should not borrow a published rank as your buying decision. Use it to find candidates, then score each candidate against your own constraint. Mark every area as Pass, Partial, or Fail and attach the evidence behind the mark.

    • Industry model: Can the team describe your buyers, entities, terminology, evidence standards, and decision journey without relying on your explanation? Ask it to map one commercially important question from initial prompt to final action.
    • AI visibility evidence: Request the prompt set, engine, captured response, cited URLs, brand treatment, recording date, and testing conditions. A favorable screenshot without the prompt and method is not an auditable result.
    • Sector work: A client logo proves a commercial relationship, not the quality or relevance of the work. Ask for a redacted artifact such as a query map, entity audit, citation analysis, content brief, or performance report from a comparable engagement.
    • Strategy-mechanism fit: Determine whether your bottleneck calls for content, technical cleanup, entity clarification, digital PR, reputation work, measurement, or a coordinated mix. The agency should diagnose the bottleneck before prescribing deliverables.
    • Measurement: Ask how the team distinguishes appearance in an AI response from a useful business outcome. The answer should cover visibility and citations as well as the downstream event that matters to you, such as an inquiry, booking, ticket sale, application, or qualified visit.
    • Delivery ownership: Find out who performs the analysis, who approves recommendations, and who joins reporting calls. Leadership credentials matter only if that expertise reaches your account.
    • Operating fit: Reviews, communication, onboarding, access requirements, and reporting quality affect whether the strategy can be implemented. Ask what the agency needs from your subject-matter experts, developers, communications team, and analytics owner before signing.

    Founder involvement can be useful, but it is not a substitute for a documented process. Likewise, a large number of media references may indicate authority, but it does not prove that the assigned team can diagnose your site or measure your priority outcomes. Score the evidence that will affect delivery, not the prestige of the label attached to it.

    Demand a GEO operating system, not a content package

    GEO does not produce a permanent position that an agency can own. AI answers can change with the engine, prompt wording, context, and available information. Your program therefore needs a repeatable process for observing answers, improving the underlying evidence, and checking what changed.

    The monitored engine set should reflect where your audience asks questions. Sector evaluations already examine visibility across ChatGPT, Perplexity, and Google Gemini, while hospitality work also includes Claude. Including every platform is not automatically better. The agency should explain why each platform belongs in your measurement plan and keep the testing method consistent enough to interpret the observations.

    1. Map decisions to questions. Begin with questions that precede a real choice: identifying options, checking suitability, comparing alternatives, resolving objections, and deciding what to do next.
    2. Establish the baseline. Record the prompt, engine, response, cited pages, brand inclusion or omission, competitors mentioned, and the language used to represent each entity.
    3. Audit the evidence layer. For each important answer, identify the factual claims you can support, where those facts live, whether the pages are accessible, and which claims lack a credible owned or independent source.
    4. Repair the entity and content layer. Improve the pages that define the organization, offerings, people, places, products, events, or other relevant entities. Resolve contradictions before expanding content.
    5. Build authority where the gap requires it. Some problems call for stronger third-party coverage or clearer brand representation, not another page targeting a variation of the same query.
    6. Measure visibility and consequence separately. Track whether the brand appears and receives citations, then connect that observation to qualified traffic and the commercial event named in your fit brief.

    One documented entertainment approach connects AI citations with ticket sales and customer acquisition costs. That is a useful model for procurement even when your outcome differs: visibility belongs in the report, but it should not be mistaken for the final result.

    Structured data belongs inside this operating system, not above it. Ask the agency which entity or relationship each schema property clarifies, which visible page statement supports it, and how it will be validated after deployment. Reject a schema-only plan that leaves thin content, contradictory facts, poor internal linking, or weak external authority untouched. Markup can make existing meaning easier to interpret; it cannot manufacture evidence.

    You should also expect different agency models. Entertainment specialists in 2026 ranged across GEO content strategy, multi-channel marketing, budget-conscious execution, analytics-led tracking, and PR-integrated GEO. None of those models is inherently right for every business. Choose the one that matches the bottleneck identified in your baseline.

    Use a fixed-scope pilot before a broad retainer

    A client and agency team observes a compact test chamber that moves source blocks through connected research, review, monitoring, and measurement modules before wider lanes are activated.

    A pilot should test the agency’s reasoning and operating discipline, not ask it to promise a ranking. Give every finalist the same fit brief and require written answers to the same procurement questions.

    1. Which customer decisions and prompt patterns would you prioritize for our business, and why do they matter commercially?
    2. How will you establish an observable baseline across the engines that matter to our audience?
    3. Which parts of the plan depend on owned content, technical changes, structured data, independent authority, digital PR, or reputation work?
    4. What facts and access do you need from our subject-matter experts, analytics owner, communications team, and developers?
    5. Who will perform each part of the work, and where will senior sector or GEO expertise enter the process?
    6. How will reporting separate captured AI outputs from interpretation, recommendations, and downstream business results?
    7. Which work products, prompt records, datasets, briefs, and account access will we retain if the engagement ends?

    Write the acceptance test into the pilot scope. The baseline should be reproducible from the recorded method. The priority questions should correspond to real customer decisions. Recommendations should identify the evidence behind each proposed claim. Every implementation item should have an owner. Reporting should distinguish visibility observations from business impact. The pilot can pass those tests even before meaningful visibility changes appear; its immediate purpose is to prove that the agency has built a credible system for producing and evaluating change.

    Several warning signs should stop the process before a long contract creates avoidable cost:

    • A guarantee that your brand will hold a particular position in an AI answer
    • A visibility claim supported only by selected screenshots
    • A generic sector case study with no inspectable artifact or method
    • A proposal measured mainly by content volume
    • A schema-only prescription offered before an entity, content, and evidence audit
    • No named delivery owner or no explanation of when senior experts participate
    • A broad retainer proposed before the agency has defined your query universe and baseline

    Your next move is simple: send the same written fit brief to every finalist and compare the mechanisms they propose. Choose the agency that can show why your industry’s questions, evidence, entities, and outcomes require a distinct plan. If nobody can do that, narrow the pilot rather than expanding the commitment.

    References

  • How to Measure AI Search Visibility Beyond a Single Score

    How to Measure AI Search Visibility Beyond a Single Score

    You need to know whether your brand is visible in AI search, but the available evidence rarely lines up neatly. A dashboard gives you a score, an assistant mentions you in one answer, analytics shows a few unfamiliar referrals, and nobody can say whether any of it matters.

    The way out is to stop treating AI visibility as one metric. Measure the path from technical eligibility to business response, preserve the evidence behind every observation, and make each metric answer a specific decision. That gives you a system you can improve, not another number to report.

    A visibility score cannot tell you what to fix

    A single score compresses several different questions into one value. Your brand might be absent because the system cannot interpret the relevant page, because your content does not address the prompt, because another source is cited instead, or because the answer names you incorrectly. Those failures require different fixes.

    Start by writing down the decision your measurement must support. Useful questions include:

    • Are AI systems able to retrieve and interpret the pages and assets that describe this offer?
    • Does the brand appear for the problems and buying situations that matter?
    • When it appears, is it prominent enough to influence the answer?
    • Are the claims, product relationships, limitations and differentiators represented accurately?
    • Does that visibility produce visits, inquiries, assisted conversions or other meaningful behavior?

    Your unit of analysis should also be explicit. Measure a brand or product against a defined prompt, intent, AI platform and mode, market, language and collection date. A result gathered in one environment should not silently stand in for every AI search experience.

    This is why a universal visibility score is usually less useful than a baseline built from your own commercial topics. The baseline does not need to prove that you lead the market. It needs to reveal which layer changed and where your team should act.

    Measure AI search through five connected layers

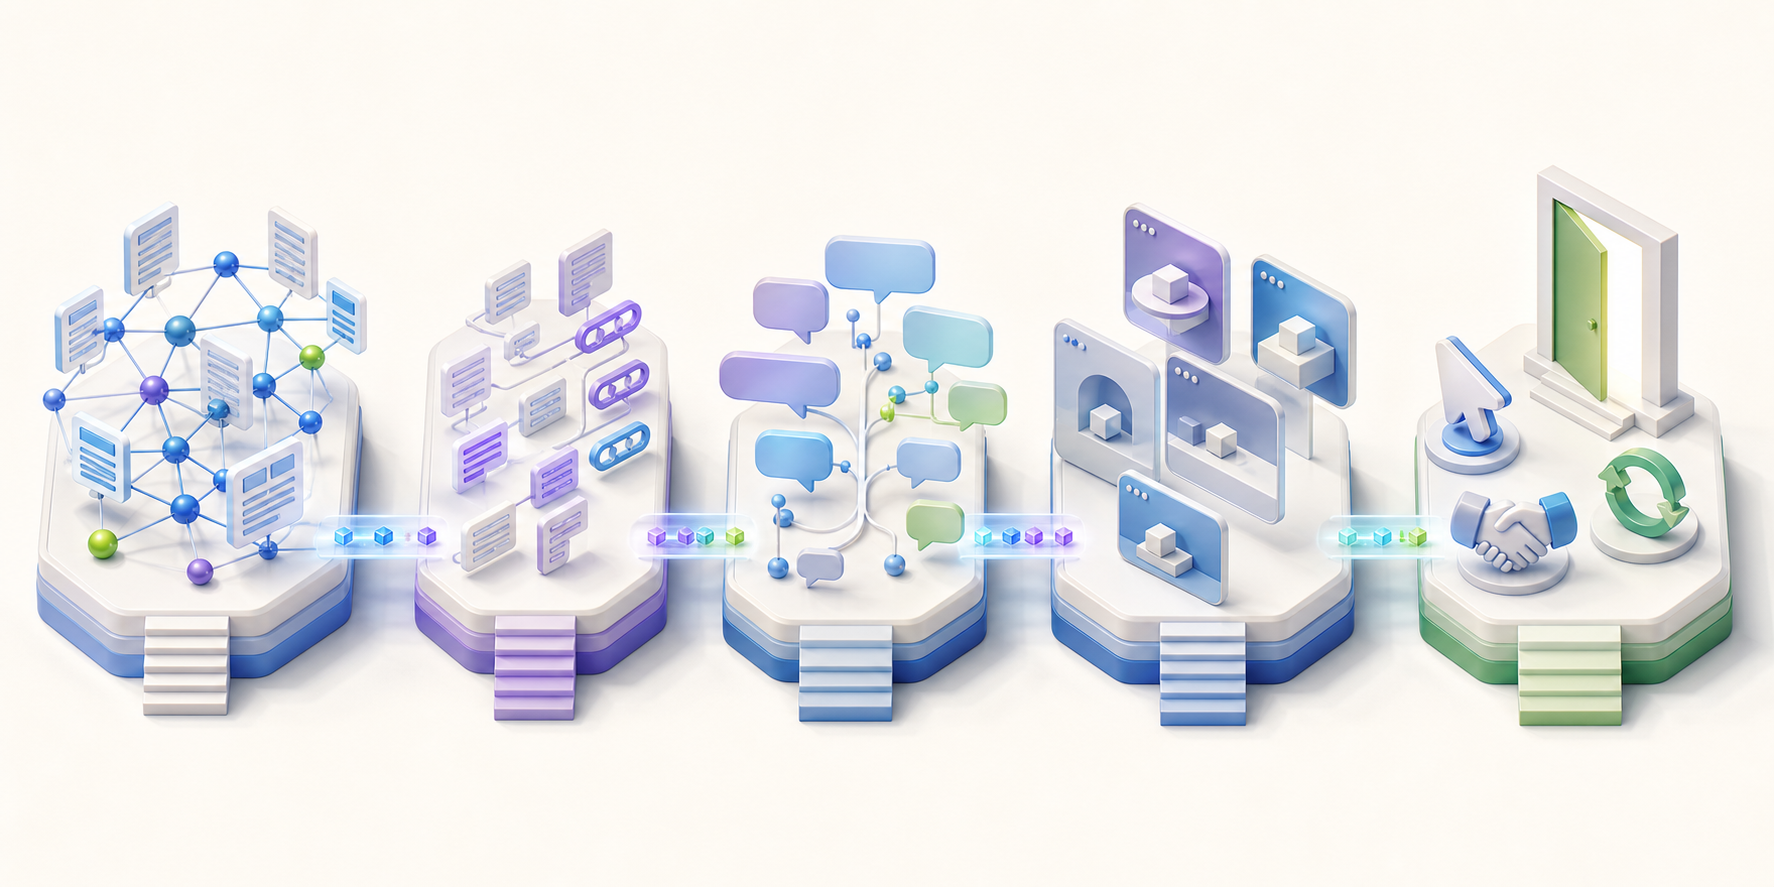
    Five connected isometric platforms depict technical access, source evidence, conversational prompts, AI responses, and human outcomes.

    A five-layer view of GEO performance prevents technical readiness, answer visibility and commercial impact from being collapsed into the same metric. Use the following operational model for each important prompt family.

    LayerQuestionEvidence to recordDecision it supports
    EligibilityCan the system retrieve and interpret the relevant entity, page or asset?Accessible destination, clear entity relationships, descriptive content, structured data and asset metadataWhether to fix technical access, ambiguity or machine-readable context
    PresenceDoes the brand, product or domain appear in an eligible response?Explicit mention, product mention, domain appearance and prompt-level mention frequencyWhether content coverage matches the intent being tested
    Prominence and citationWhat role does the brand play in the answer, and is supporting material cited?Recommendation position, amount of discussion, linked URL, cited domain and claim-to-citation relationshipWhether the brand is merely present or is being used as evidence
    RepresentationIs the answer accurate, current and aligned with the intended market position?Correct identity, supported claims, relevant use case, stated limitations and errorsWhether to repair conflicting facts, weak entity signals or missing explanatory content
    ResponseDoes the exposure contribute to useful behavior?Traceable referrals, engaged visits, inquiries, conversions, assisted signals and sales feedbackWhether visibility is reaching valuable demand rather than creating an impressive-looking count

    Keep the component metrics visible. A composite score can be useful for an executive trend line, but it should never replace the underlying measures. If a score rises, you should be able to tell whether the cause was broader prompt coverage, more citations, better accuracy or stronger outcomes.

    Define the core calculations before collection begins:

    • Mention rate: eligible responses containing an explicit brand or product mention divided by all eligible responses in the selected prompt set.
    • Citation rate: eligible responses citing your domain divided by eligible responses in which citations are present or expected under your protocol.
    • Owned citation share: citations to your controlled domains divided by all recorded citations for that prompt family.
    • Accurate-response rate: reviewed responses with no material factual error divided by all reviewed responses that discuss the entity.
    • Qualified-response rate: tracked outcomes meeting your agreed quality rule divided by the attributable visits or inquiries being evaluated.

    The denominator matters as much as the numerator. A refusal, an unrelated answer and a valid answer that omits your brand are not the same event. Establish eligibility rules in advance, retain excluded runs, and report the exclusion reason. Otherwise, a change in answer behavior can masquerade as a visibility improvement.

    Add an asset-level view for visual discovery

    Product discovery is not limited to text prompts. Images can become discovery inputs through experiences such as Google Lens, while alt text and structured product context help make product imagery more interpretable. If visual discovery matters to your business, add the image asset to the unit of analysis instead of reporting only at domain level.

    For each tested image, record whether the correct product or category is recognized, whether the result maps to the intended product page, whether the product name and attributes are accurate, and whether a competing or irrelevant item is returned. The existence of alt text or schema is an eligibility check, not proof of visibility. The result itself still needs to be observed.

    Build a prompt panel around real decisions, not keyword volume

    Your prompt panel is the measurement instrument. If it overrepresents branded prompts, broad informational questions or easy situations, the dashboard will look healthy while missing the decisions that create revenue.

    1. Choose the audience and decision. Identify who is asking and what they need to decide. A procurement lead comparing platforms requires different evidence from a customer troubleshooting a product.
    2. Group prompts by intent. Useful families include problem discovery, category education, comparison, suitability for a constraint, implementation, troubleshooting and local availability. Keep only the families that matter to the business.
    3. Separate branded and unbranded demand. A brand appearing when its name is already in the prompt measures representation. Appearing in an unbranded recommendation or comparison measures discovery. Do not combine the two rates.
    4. Include natural wording variants. Test how a person might express the same need with different context, constraints or levels of expertise. Preserve each exact prompt so later runs remain comparable.
    5. Maintain a fixed panel and an exploratory panel. The fixed panel provides trend continuity. The exploratory panel captures emerging questions, new product language and gaps found during qualitative review. Promote a prompt into the fixed panel only through a documented change.
    6. Define a valid response. Decide how to handle refusals, incomplete outputs, answers without citations, location mismatches and prompts that the system cannot answer in the selected mode.

    A prompt is not a proxy for search volume. It is a controlled test of whether the brand appears in a particular decision context. Label the panel as representative of the intents you selected, not as a census of everything people ask.

    AI answers can vary between runs, so treat a single response as an observation rather than a permanent rank. Repeat collection on a consistent cadence and report frequency across comparable runs. Do not rewrite a fixed prompt after seeing an unfavorable answer; that destroys the comparison you were trying to make.

    Control the environment as far as the interface allows. Record the platform and product mode, visible model label when available, date and time zone, market, language, account or personalization state, and whether web retrieval or citations were enabled. If any of those conditions change, annotate the series instead of presenting it as uninterrupted.

    Preserve enough evidence to explain every change

    An analyst traces colored connections among blank prompt cards, source documents, response panels, clocks, and change markers on a transparent evidence wall.

    A percentage without the underlying answer is difficult to audit. Store the raw response, cited URLs and scoring decisions with the run. Screenshots can help with presentation, but searchable response text and structured fields make investigation much faster.

    A practical run record should include:

    • A stable run ID and prompt ID.
    • The exact prompt and its intent family.
    • The platform, mode, visible model label and retrieval setting.
    • The collection date, time zone, market and language.
    • The complete response, not just the sentence mentioning the brand.
    • Every cited URL and its domain.
    • Brand, product and competitor mention fields.
    • Prominence, citation and representation judgments.
    • The reviewer, review date and reason for any manual override.
    • The associated landing page, analytics evidence and outcome when a connection is available.

    Manual judgments need a rubric. Define an explicit mention as the exact brand or product identity, not a generic category reference. Grade representation as accurate, partly accurate, materially wrong or unverifiable. For citations, check whether the linked page actually supports the nearby claim; a domain in a citation list does not automatically validate every statement in the answer.

    Maintain a ground-truth record for the facts you evaluate. It should contain the approved entity name, product relationships, supported capabilities, limitations, canonical URLs and the date each fact was checked. This separates an AI error from a disagreement inside your own website, feeds or structured data.

    When results change, compare like with like. Hold the fixed prompts and collection conditions steady, then inspect the affected layer:

    • If mention rate changes while eligibility and prompt mix stay stable, investigate the pages and citations used in the changed answers.
    • If citations improve but representation worsens, inspect whether outdated or contradictory pages are being cited.
    • If competitor share changes, review it within the same intent family. A brand that dominates troubleshooting prompts may still be absent from purchase comparisons.
    • If a content, schema or image change was released, annotate it and examine the relevant prompt segment. Do not credit the change for unrelated movement across the whole panel.
    • If the platform or retrieval mode changed, begin a new comparison segment or show the break visibly.

    Competitor mention share is useful context, but it is not market share. It describes what happened inside your selected prompts and collection protocol. Keep that limitation in the label so the metric is not reused as a broader commercial claim.

    Connect visibility to outcomes without overstating attribution

    An AI answer may influence a decision without producing a click. A visit may also arrive without a clean referrer, and a later conversion may be credited to another channel. That makes attribution incomplete, but it does not make measurement pointless. It means you should present evidence in levels of confidence.

    • Direct evidence: an identifiable AI referral reaches a landing page and completes a tracked engagement or conversion event.
    • Assisted evidence: visibility changes align with branded visits, branded search behavior, returning users or later conversions, but the path cannot be tied to one answer.
    • Qualitative evidence: inquiry forms, sales notes or customer conversations identify an AI assistant as part of discovery or evaluation.
    • Experimental evidence: a specific page, structured-data implementation or asset is changed, the release is annotated, and the affected prompt segment is compared while unrelated variables are kept as stable as practical.

    Do not merge those evidence levels into a single attributed-revenue figure. Report direct outcomes separately from assisted and qualitative signals. If several campaigns, site changes or product announcements occurred at the same time, describe the movement as an association rather than claiming the AI optimization caused it.

    The five layers also create clear decision rules:

    • Weak eligibility: fix access, page clarity, entity relationships, structured data and asset metadata before expanding the prompt panel.
    • Strong eligibility but weak presence: map missing prompt families to content gaps and determine whether the page actually answers the decision behind the prompt.
    • Presence without useful prominence or citations: strengthen the pages that substantiate the claim, clarify comparisons and make the relevant facts easy to locate.
    • Visibility with inaccurate representation: reconcile conflicting names, claims, feeds and canonical pages before pursuing more mentions.
    • Strong visibility with weak response: inspect intent quality, landing-page continuity and conversion friction. More mentions will not repair a mismatch between the answer and the offer.
    • Business movement without tracked visibility: expand the exploratory prompt set and review whether the relevant platform, market or use case is missing from the panel.

    Budget decisions should follow the weakest consequential layer. Improving citations is unlikely to help when the system cannot resolve the product correctly. Expanding visibility is a poor priority when the brand is already present but the answer misstates a material limitation. The diagnostic sequence protects you from spending against the wrong problem.

    Key takeaways for an actionable AI visibility dashboard

    • Measure eligibility, presence, prominence and citation, representation, and business response separately.
    • Use a fixed prompt panel for trends and a separate exploratory panel for discovery.
    • Keep branded and unbranded prompts, text and visual discovery, and different platform modes in distinct segments.
    • Store raw answers, URLs, run conditions and review decisions so every metric can be audited.
    • Define denominators and exclusion rules before collection begins.
    • Treat direct, assisted, qualitative and experimental evidence as different levels of attribution confidence.
    • Attach every metric to a corrective action; retire dashboard fields that cannot change a decision.

    Begin with one commercially important topic, one defined market and one platform mode. Build a small fixed prompt panel, write the scoring rules, capture the complete answers and take a baseline across all five layers. Your next optimization will then be chosen by evidence: the first weak layer that stands between eligibility and a useful business response.

    References

  • Building an AI-Ready SEO and GEO Program That Performs

    Building an AI-Ready SEO and GEO Program That Performs

    Your team may already have an SEO roadmap, a schema backlog, a content calendar, and a dashboard that checks whether your brand appears in generated answers. That can still leave you without a program. The work sits in separate queues, each team reports a different success metric, and nobody has a clear rule for deciding what to improve next.

    An AI-ready SEO and GEO program connects those pieces. It starts with the questions your audience asks, maps them to accessible and trustworthy pages, makes the meaning of those pages explicit, measures visibility across search and answer engines, and ties the result to a business decision. Here is how to build that operating system without turning GEO into a disconnected collection of tools and speculative tactics.

    Build the business case before you build the tool stack

    Do not begin with a GEO platform, a schema type, or a list of prompts. Begin with the decision the program is supposed to improve. Otherwise, you can produce impressive-looking citation charts without knowing whether the cited answers concern commercially relevant questions, reach the right audience, or contribute to a useful action.

    Your first document should be a short program charter. It needs to answer six practical questions:

    • Who are you trying to reach? Name the audience, market, language, and buying situation. A broad label such as business users is not enough to guide content or measurement.
    • Which questions matter? Define the topic areas and decisions for which you want to be discoverable. Include informational questions, comparison questions, validation questions, and action-oriented questions where they are relevant.
    • What should visibility accomplish? Choose the business outcome: qualified reach, revenue, conversion, market entry, customer education, or lower operating cost.
    • Which signals will show progress? Separate leading indicators such as technical eligibility, answer inclusion, and citations from outcomes such as qualified visits and conversions.
    • What is outside the program? State the markets, products, page types, and answer engines that you are not evaluating. A boundary keeps a pilot from becoming an unmanageable sitewide audit.
    • Who can approve and ship changes? Name the program owner and the people responsible for content, subject-matter review, development, analytics, and final approval.

    This framing matters because technical work rarely wins priority on terminology alone. Internal linking, index management, performance, hreflang, and schema markup become easier to fund when they are connected to revenue, conversion, reach, or cost reduction. If the company wants to grow in a particular region, for example, the case for correcting hreflang is not that hreflang is an SEO best practice. The case is that sending search engines to the wrong regional version works against the market-expansion goal.

    Use the same discipline with performance claims. The claim that a one-second delay can reduce conversions by up to 7% can illustrate why speed deserves attention, but it is not a forecast for your site. Your own page performance, traffic mix, and conversion data must determine the actual opportunity. A benchmark can open the conversation; it cannot replace measurement.

    Give every proposed initiative a simple value chain:

    • Change: What will be altered?
    • Mechanism: How should that alteration improve discovery, comprehension, selection, or user experience?
    • Leading signal: What should move first if the mechanism is working?
    • Business signal: Which meaningful outcome could move afterward?
    • Decision: What will you expand, revise, or stop when you see the result?

    That last field prevents reporting from becoming ceremonial. A metric belongs in the program only if a change in that metric could cause you to make a different decision.

    Design one workflow from audience question to measurable page

    Four specialists work along one illuminated path that turns an audience question into researched content, structured page elements, and a webpage displayed on several devices.

    SEO and GEO should not operate as rival channels. SEO helps your pages become accessible, indexable, relevant, and competitive in conventional search. GEO aims to make the same body of knowledge easier for generative systems to interpret, select, and cite when constructing answers. The practical unit of work is therefore not a GEO tactic. It is a question, the page that should answer it, the evidence on that page, and the systems that need to retrieve it.

    Build the workflow in the following order:

    1. Create a question inventory. Record the actual decision or uncertainty behind each question, not just a keyword. Add the intended audience, market, language, journey stage, and the kind of answer required.
    2. Group questions by intent and required evidence. Questions that use similar words may need different pages if one asks for a definition and another asks for a purchase comparison. Questions with different wording may belong together when the same page can answer them completely.
    3. Assign a destination page. Give every important question cluster an existing page to improve or a justified content gap to fill. If several pages compete to do the same job, decide which one should be canonical before producing more copy.
    4. Make the answer usable. Put a direct response close to the question it resolves, then supply the explanation, evidence, limitations, and next step the reader needs. Do not force a person or a retrieval system to assemble the central answer from scattered hints.
    5. Verify technical access. Check status codes, indexability, canonical signals, rendering, internal links, sitemap inclusion, and regional or language targeting where applicable. Content cannot perform reliably if the intended URL is inaccessible, duplicated, or poorly connected to the rest of the site.
    6. Describe the page accurately with structured data. Use JSON-LD and schema types that match the visible page and the real entities involved. Then validate the markup and monitor the deployed output rather than assuming the CMS generated it correctly.
    7. Measure and feed the result back into the backlog. Track which questions produce visibility, which URLs are cited, what qualified engagement follows, and where the answer remains absent or inaccurate.

    A content brief produced by this workflow should be much more precise than write an authoritative article about a topic. It should specify the audience question, the promised answer, the destination URL, the entities that need unambiguous names, the evidence required, the important qualifications, the internal links, the appropriate structured data, and the business action available after the answer.

    Use page-level acceptance criteria before publication:

    • The page answers its primary question in language the intended audience can understand.
    • Headings expose the page’s logic rather than merely repeating variations of a keyword.
    • Important claims have suitable evidence, context, and qualifications.
    • Names for the organization, product, service, people, and other entities remain consistent.
    • Internal links connect the page to relevant supporting and conversion content.
    • The canonical URL is accessible and returns the intended content.
    • JSON-LD describes what is visibly present and does not introduce unsupported claims.
    • The page offers a sensible next step without obstructing the answer.

    Structured data is useful here because it provides a machine-readable description of the page. It is not a substitute for clear content, technical access, or credible evidence, and it does not guarantee inclusion in a generated answer. If the visible page is vague, duplicated, or contradictory, adding more markup only gives you a more elaborate description of a weak asset.

    Choose a GEO platform after this workflow is defined. The practical value of these tools is their ability to help you observe AI visibility and citations in systems such as ChatGPT and Gemini. Your use case should determine which platform fits, not the length of its feature list.

    Evaluate a platform against the decisions in your charter:

    • Does it monitor the answer engines your audience actually uses?
    • Can you segment by topic, brand, product, market, language, or other necessary dimensions?
    • Does it show the cited URL, not merely whether the brand appeared?
    • Can you preserve a stable question set and compare results over time?
    • Does it retain enough response context for a person to judge whether a mention is accurate and relevant?
    • Can you export the data or connect it to your reporting workflow?
    • Can your team reproduce how a reported metric was calculated?
    • Do its access controls, data handling, and retention practices fit your organization’s requirements?

    No monitoring platform can tell you by itself why an answer changed. Models, retrieval behavior, citations, and interfaces can change outside your site. Treat the tool as an observation layer. Keep page changes, prompt definitions, engine settings, and measurement dates alongside the results so your team can interpret movement without inventing certainty.

    Make every AI-assisted audit pass the CaML test

    An AI-generated audit can be detailed, polished, and wrong. The most common failure occurs before the recommendations: the system never received the full page, reliable query information, a comparison set, or a definition of success. It fills the missing context with assumptions and presents those assumptions in the same confident tone as verified findings.

    Use the CaML framework: Context, Methodology, and Human in the Loop. If any element is missing, the output is a draft for investigation, not an audit you should send to a writer or developer.

    Context: give the system the evidence it needs

    Start by retrieving the actual page content. A search snippet is not an adequate substitute: it may omit most of the answer, qualifications, internal links, structured data, or even the wording the audit intends to change. Supply the canonical URL, rendered content where relevant, page purpose, intended audience, target questions, business goal, and any constraints the recommendation must respect.

    Where the task depends on demand or competition, provide appropriate keyword data and the relevant top-ranking URLs rather than asking the model to guess. If you use a structured content outline, include it. The AI should know what evidence it has, what it does not have, and which fields came from tools rather than model inference.

    Mark an audit as incomplete when the system cannot access the page or a required dataset. That is a useful finding. A fabricated recommendation is not.

    Methodology: define how a finding becomes a recommendation

    A repeatable audit needs a declared method. State the checks, comparison set, evidence standard, prioritization fields, and output format before the model evaluates anything. Otherwise, two runs can produce different backlogs without revealing why.

    A page-level SEO and GEO method might ask:

    • Can search and retrieval systems access the canonical content?
    • Does the page resolve the intended question clearly and early enough?
    • Are the central claims supported, qualified, and internally consistent?
    • Are important entities named consistently on the page and across related pages?
    • Does the internal-link structure help a visitor and a crawler find necessary supporting material?
    • Does the structured data match the visible content and page type?
    • Does the page differ meaningfully from competing answers, or does it merely restate common material?
    • Is there an appropriate next action for the intended visitor?

    Prioritize each finding by expected business impact, confidence in the evidence, implementation effort, and dependencies. Do not collapse those fields into an unexplained score. A high-impact idea supported by weak evidence needs validation; a well-proven defect blocked by a template migration needs coordination; a trivial wording preference may not deserve a ticket at all.

    Human in the loop: make the recommendation fit reality

    A knowledgeable reviewer should verify factual accuracy, search intent, brand language, technical feasibility, and business priority. The reviewer also needs to catch conflicts that a page-level agent may not see, such as a recommendation that duplicates another URL, breaks a shared template, contradicts product policy, or creates more maintenance than value.

    Turn approved findings into small implementation tickets. Each ticket should contain:

    • Finding: the specific defect or opportunity.
    • Evidence: the page element, query data, comparison, or technical observation supporting it.
    • Consequence: the audience or business problem created by the current state.
    • Action: the smallest clear change that addresses the problem.
    • Owner and dependency: the person who can ship it and anything that must happen first.
    • Validation: how you will confirm that the change deployed correctly.
    • Outcome check: which leading and business signals you will revisit afterward.

    This format is intentionally shorter than a long narrative audit. Writers and developers need decisions they can act on. Keep the full evidence available for review, but do not bury the required change inside pages of generic commentary.

    Measure visibility as a funnel, not a citation trophy

    Glowing signals from search and conversational interfaces pass through a transparent funnel toward completed actions, while a small trophy sits apart in the background.

    A citation is useful evidence that a system selected a URL while producing an answer. It is not, by itself, proof of qualified reach, favorable representation, traffic, conversion, or revenue. Your scorecard needs to show the path from implementation to visibility and from visibility to business effect.

    Measurement layerWhat to recordDecision it supports
    DeliveryPages changed, technical fixes deployed, structured data validated, and content approvedWhether the planned work actually reached production
    EligibilityCanonical accessibility, indexability, rendering, internal-link coverage, and other relevant technical statesWhether a technical barrier needs to be removed before judging content performance
    AI visibilityAnswer presence, brand mention, citation presence, cited URL, question, engine, market, language, and observation dateWhich topics and pages are being selected, omitted, or represented inaccurately
    Search and site engagementRelevant landing-page visits, referral information where available, engagement, and conversion-path behaviorWhether discoverability is producing useful site activity
    Business outcomeQualified conversions, revenue where observable, market reach, or documented cost reductionWhether to expand, revise, or stop the initiative
    Answer qualityAccuracy, citation relevance, outdated claims, missing qualifications, and brand representationWhich content or entity problems require correction even when raw visibility is high

    Create a baseline before changing the pages. Preserve the monitored questions, wording, engine, market, language, date, response, cited URLs, and relevant settings. Separate branded questions from non-branded questions because they represent different discovery conditions. Group results by topic and destination page so you can diagnose an asset instead of reacting to an isolated answer.

    Define every calculated metric. If you report citation rate, specify the denominator: the fixed set of monitored question runs for which a citation was checked. If you report share of visibility, state which brands, questions, engines, markets, and dates were included. A percentage without its measurement universe is not a decision-ready metric.

    Treat referral traffic as partial evidence. A generated answer can influence a person without producing a click, and a click may not preserve all the attribution detail you want. Do not respond by claiming every mention as an assisted conversion. Report what you can observe, label what you infer, and keep the two separate.

    Use patterns across the funnel to decide what to do:

    • Implementation rose, but eligibility did not: check deployment, rendering, canonical behavior, templates, and validation before rewriting content.
    • Eligibility is sound, but visibility remains absent: revisit question-to-page fit, answer clarity, evidence, entity consistency, and whether another URL is competing for the same role.
    • Mentions appear, but citations do not: inspect whether the brand is being discussed through third-party material, whether your destination page is sufficiently clear and supportable, and whether the monitored answer normally provides links.
    • Citations rise, but qualified engagement does not: check the intent of the monitored questions, the relevance of the cited page, and the next action available to the visitor. You may be winning visibility that has little business value.
    • Traffic or conversions improve without a matching visibility change: look for conventional search gains, campaigns, seasonality, site changes, or measurement gaps before crediting GEO.
    • Visibility rises while answer quality declines: prioritize factual correction and clearer qualifications. More exposure to an inaccurate answer is not a successful outcome.

    Annotate content releases, migrations, template changes, internal-link updates, and schema deployments. Where feasible, compare changed pages with a suitable unchanged group. Even then, describe causality carefully because external systems can change at the same time. The aim is to prove impact over time, not to assign every favorable movement to the most recent SEO ticket.

    Close each reporting cycle with decisions, not just charts: what will be expanded, what needs another test, what is blocked, what should be stopped, and which assumption was disproved. That creates institutional knowledge and makes the next request for engineering or editorial support much easier to evaluate.

    Key takeaways

    • Start with an audience question and a business decision, then select pages, tactics, and tools that serve them.
    • Run SEO, content, JSON-LD, and GEO measurement as one workflow around a canonical destination page.
    • Do not accept an AI audit unless it has sufficient context, a declared methodology, and a qualified human reviewer.
    • Measure delivery, technical eligibility, AI visibility, engagement, answer quality, and business outcomes as separate layers.
    • Keep a stable, documented question set so changes in visibility can be interpreted instead of merely observed.
    • Turn every report into an explicit choice to expand, revise, validate, defer, or stop work.

    Start with a commercially important topic rather than the entire site. Write the charter, map its questions to destination pages, establish the baseline, run a CaML-based audit, and ship the smallest defensible set of changes. Once the measurement loop produces decisions your content, development, and business teams trust, you have a program worth scaling.

    References

  • How to Measure Brand Visibility in AI-Mediated Journeys

    How to Measure Brand Visibility in AI-Mediated Journeys

    You may already be appearing inside AI answers while your organic dashboard says little has changed. Or AI bots may be crawling your site without your brand ever making the shortlist. If you count only clicks, both situations become an attribution mystery.

    You need to separate machine access, brand selection, human handoff, and business outcome. That gives you a measurement system that can locate the weak point in an AI-mediated journey and tell you what to test next.

    Decide what brand visibility means before scoring it

    A visit is no longer the only useful sign that a brand won. Depending on how much of the journey a person delegates, a win can be a click, an AI recommendation, or an action completed by an agent. A single traffic metric cannot represent all three.

    Start by classifying the journey into search, assistive, and agentic modes. These modes can coexist within the same purchase. Someone might discover a category through search, ask an assistant to compare the options, and then let an agent find a qualifying seller. Your measurement should follow that movement instead of assigning the whole journey to its last observable click.

    Journey modeWhat visibility looks likePrimary evidenceCommon misreading
    SearchYour page or brand is presented as an option the user can inspect.Search impressions, result position, clicks, landing sessions, and subsequent actions.Treating a high position as proof that the result influenced a decision.
    AssistiveAn AI answer names, explains, compares, cites, or recommends your brand.Observed mentions, recommendation role, cited URLs, claim accuracy, and answer-engine referrals.Counting an incidental mention as a recommendation.
    AgenticAn agent recruits your brand as an eligible option, selects it, or completes an action through it.Selection records where available, agent referrals, API or commerce events, and confirmed business outcomes.Assuming a bot request means the agent selected your brand.

    Define a qualifying visibility event before collecting data. At minimum, the brand must be correctly identified and relevant to the prompt. Record whether it was merely named, used as supporting evidence, included in a shortlist, explicitly recommended, or selected for action. Those roles have different commercial meaning.

    Set an eligibility rule for the denominator as well. A prompt belongs in your visibility rate only if your brand could reasonably satisfy the stated need, market, audience, and constraints. Including irrelevant prompts depresses the score. Excluding difficult but commercially important prompts inflates it.

    Measure each layer from machine access to business outcome

    Four connected transparent chambers depict machine access, AI selection, human handoff, and a business outcome, with observation points between them.

    AI visibility is a sequence, not an isolated mention. A useful diagnostic model follows ten gates: discovered, selected, crawled, rendered, indexed, annotated, recruited, grounded, displayed, and won. The early gates make your information available to machines. The later gates determine whether the system can understand, use, present, and act on it.

    You will not observe every gate directly. Server logs can show that a crawler requested a URL, but they cannot prove that the page was indexed, understood correctly, or used in a response. A citation can show that a URL supported an answer, but it does not reveal every internal retrieval or ranking decision. Label each measurement as observed or inferred so your dashboard does not manufacture certainty.

    Measurement layerQuestion it answersUseful measuresWhat it does not prove
    Machine accessCan qualifying bots reach and process the pages that matter?Priority URLs requested, response status, rendered content availability, repeat access, and crawler identity confidence.That the information was indexed, trusted, or selected.
    Entity understandingDoes the answer associate your brand with the correct category, products, locations, capabilities, and constraints?Entity accuracy, attribute accuracy, category association, and contradiction frequency.That the brand will be recruited for a particular decision.
    Recruitment and groundingDoes the system use your brand or content when constructing an answer?Qualifying mention rate, citation rate, cited-page coverage, claim usage, and competitor co-mentions.That the user saw a meaningful recommendation.
    PresentationHow is the brand shown to the user?Recommendation rate, shortlist inclusion, order when a genuine ranking exists, description, caveats, and next action offered.That the user followed the recommendation.
    Handoff and outcomeDid the journey reach your property or produce a business event?Answer-engine referrals, engaged sessions, leads, account creation, purchases, bookings, and other confirmed outcomes.That one observed AI answer caused the outcome.

    Keep these layers separate before creating any composite score. A blended score can rise because crawler activity increased even while recommendation visibility fell. That looks like progress until you inspect the components.

    Use a small metric dictionary so everyone calculates the same thing:

    • Qualifying mention rate: eligible prompt runs containing a valid brand mention divided by all eligible prompt runs.
    • Recommendation rate: eligible prompt runs in which the brand is positively recruited as an option divided by all eligible prompt runs.
    • Citation rate: eligible prompt runs citing an owned or controlled page divided by all eligible prompt runs. Report third-party citations separately.
    • Claim accuracy rate: checked brand claims that are materially correct divided by all checked brand claims.
    • Priority-page bot coverage: priority URLs receiving a qualifying bot request divided by all URLs in the defined priority set.
    • AI referral engagement rate: qualifying answer-engine sessions that complete your chosen engagement event divided by all qualifying answer-engine sessions.
    • AI-attributed outcome rate: confirmed outcomes with an observable AI referral or another declared attribution signal divided by the applicable set of outcomes.

    Always display the numerator and denominator next to each rate. A clean percentage built from a tiny or changing prompt set is less informative than a modest rate calculated from a stable, representative panel.

    Build a prompt panel around real decisions

    A prompt tracker is useful only when its prompts resemble the decisions your audience delegates. A list of branded questions will tell you whether an engine can repeat known facts about you. It will not tell you whether the brand is discoverable when the user has not chosen it yet.

    Build the panel from intent and constraints:

    1. Map the decisions. Include discovery, comparison, validation, troubleshooting, and action-oriented needs. Connect each need to a product line, audience, market, or journey stage.
    2. Add realistic constraints. Use the factors that can change eligibility, such as use case, compatibility, location, availability, delivery requirement, organizational size, or risk tolerance. Do not add a constraint merely to make the prompt longer.
    3. Balance non-branded and branded prompts. Non-branded prompts measure discovery and recruitment. Branded prompts measure entity understanding, accuracy, and competitive positioning.
    4. Define matching rules. List the canonical brand name, legitimate variants, product names, and exclusions that could create false positives. Decide how acquisitions, resellers, and similarly named entities will be handled before scoring begins.
    5. Fix the test conditions. Preserve the prompt wording, engine, model label, account state, location, language, and personalization state when those variables are available. Record any condition you cannot control.
    6. Review the full answer. A string match cannot tell whether the brand was recommended, dismissed, confused with another entity, or mentioned only inside a citation title.

    Useful prompt templates include:

    • What are suitable ways to solve [problem] for [audience or situation]?
    • Which providers meet [requirement] and [constraint]?
    • Compare options for [use case], especially [decision factor].
    • Is [brand or product] suitable for [specific scenario]?
    • Find an option for [need] that can satisfy [action constraint].

    Do not average every prompt into one headline number. Segment results by intent, journey mode, market, product, and engine. A brand can be highly visible in informational answers yet absent when the prompt moves to comparison or action. That boundary is where the commercial problem usually becomes diagnosable.

    For every run, capture the prompt ID, intent cluster, test conditions, brand presence, mention role, recommendation strength, cited domains, cited URLs, claims made, claim accuracy, competitors named, caveats, and proposed next action. Preserve the answer itself when your governance rules permit it. Otherwise, retain a structured review and enough metadata to reproduce the test.

    Model outputs can vary with wording, context, model changes, and personalization. Treat an individual answer as an observation, not a stable market fact. Repeated runs and a fixed protocol help you distinguish a persistent visibility pattern from an isolated output. When an engine or model changes, mark the break in the time series instead of presenting the new results as a clean continuation.

    Join prompt observations, bot visits, referrals, and outcomes

    Four colored streams of prompt observations, bot activity, referral paths, and outcome signals converge in a transparent measurement hub.

    No single analytics system sees the entire AI-mediated journey. Prompt monitoring observes the answer. Server logs observe requests to your site. Web analytics observes some human handoffs. Product, commerce, and customer systems observe downstream outcomes. Your job is to connect those views without pretending they form a deterministic user-level trail.

    Some agent analytics workflows now make bot visits and human referrals available as separate inputs. Keep that separation in your own model. Bot activity is evidence of machine access. Human referral activity is evidence of a visible handoff. Neither is a substitute for the other.

    Evidence streamMinimum fields to retainBest useImportant limitation
    Prompt observationsTimestamp, engine and model label, prompt ID, intent, market, mention role, citation, recommendation, claims, and competitors.Measuring whether and how the brand appears in AI responses.The observed answer cannot reveal every internal retrieval step or every answer shown to other users.
    Server and edge logsTimestamp, requested URL, response status, user agent, verified bot classification where possible, and rendering outcome.Diagnosing whether relevant machines can access priority content.User-agent labels can be spoofed, and a request does not establish indexing or use.
    Referral analyticsReferral class, referring domain when exposed, landing URL, session ID, campaign parameters, and engagement events.Measuring observable human handoffs from answer engines.Not every app or handoff exposes a usable referrer, so measured referrals are not the whole audience.
    On-site behaviorLanding page, content path, engagement event, lead event, account event, and transaction event.Finding friction after an AI-mediated arrival.On-site behavior alone does not establish which answer or prompt influenced the visit.
    Business outcomesOutcome type, timestamp, product or service, market, value where appropriate, and declared acquisition signal.Connecting visibility work to decisions the organization values.Self-reported and last-touch signals are useful but incomplete attribution evidence.

    Join these streams at an aggregate level using the safest shared dimensions: time period, landing URL, product, market, intent cluster, and engine class. For example, you can compare a change in citation coverage for a product cluster with bot access to its priority pages, referrals landing on those pages, and relevant conversions. That creates a defensible sequence of evidence without claiming that an anonymous conversion came from a particular monitored prompt.

    Use explicit evidence labels in every analysis:

    • Observed: a monitored answer named the brand, a known bot requested a page, a referrer identified an answer engine, or a tracked session completed an event.
    • Inferred: a page probably contributed to an answer, a referral may have followed a particular prompt, or an AI mention may have influenced a later direct visit.
    • Unknown: the platform did not expose enough information to connect the events responsibly.

    This distinction matters most when direct traffic or branded search rises after AI visibility improves. That movement may support an influence hypothesis, but it does not identify the original answer or prove causation. A post-conversion question about how the person found you can add directional evidence, provided you keep self-reported responses separate from observed referrals.

    Use the dashboard to choose the next intervention

    Your dashboard should help someone decide what to change. Organize it by the measurement layers rather than by whichever tool supplied the data:

    • Access: priority-page bot coverage, response failures, blocked resources, and rendering problems.
    • Understanding: entity confusion, missing attributes, inaccurate claims, and contradictory descriptions.
    • Selection: qualifying mention rate, recommendation rate, citation rate, cited-page distribution, and competitor overlap.
    • Handoff: answer-engine referrals, landing-page distribution, engaged sessions, and return behavior.
    • Outcome: leads, registrations, purchases, bookings, and other confirmed business events by relevant cohort.

    Read combinations of signals rather than reacting to one chart:

    Observed patternLikely failure areaNext test
    Priority pages receive qualifying bot visits, but the brand is rarely mentioned.Entity understanding, recruitment, or grounding rather than basic access.Clarify who the brand serves, what it offers, where it operates, and the constraints it satisfies. Align structured data with visible page claims, then rerun the same prompt cluster.
    The brand is mentioned, but descriptions are inaccurate or inconsistent.Entity reconciliation and claim clarity.Consolidate canonical facts, remove contradictory copy, make relationships between the organization and its products explicit, and track the disputed claims individually.
    The brand is mentioned but seldom recommended for high-intent prompts.Weak evidence for the decision criteria used in comparison.Add verifiable information about fit, limitations, availability, compatibility, or policies on the most relevant pages. Do not present unsupported superiority claims.
    Owned pages are cited, but referrals remain low.The answer may satisfy the need without a click, or the brand may be functioning as evidence rather than the chosen option.Inspect the mention role and next action before treating this as failure. Strengthen the path to a useful next step where the user genuinely needs one.
    Answer-engine referrals rise, but conversions do not.Landing-page intent mismatch or on-site friction.Compare the answer’s promise and constraints with the landing page. Preserve context, answer the next likely question, and test the relevant conversion path.
    Conversions rise without identifiable AI referrals.An attribution gap rather than confirmed absence of AI influence.Improve referral classification, retain landing context, add a carefully worded self-report field, and analyze direct and branded-search cohorts without relabeling them as AI traffic.

    Run improvement work as a controlled diagnostic. Choose one intent cluster and one suspected failure layer. Preserve the prompt panel and test conditions. Record a baseline, make the narrowest relevant change, and then observe the nearest layer as well as downstream effects. If you changed entity and product facts, claim accuracy and recruitment should move before you expect a clean conversion effect.

    Possible interventions include correcting crawl barriers, consolidating entity information, adding decision-critical details, improving citation-worthy evidence, aligning JSON-LD with visible content, or repairing an AI referral landing path. Structured data can make explicit facts easier to interpret, but it does not guarantee retrieval, citation, recommendation, or display. Measure the relevant output after implementation.

    Record platform and model changes beside your experiments. If the engine changes during the test, you have a confound, not a clean before-and-after result. Keep the observation, mark the limitation, and repeat under the new condition rather than forcing the numbers into an unsupported success claim.

    Key takeaways

    • AI visibility has distinct access, understanding, selection, presentation, handoff, and outcome layers.
    • A brand mention, an owned citation, a recommendation, a referral, and a completed action are separate events.
    • A stable, decision-based prompt panel is the foundation of comparable visibility measurement.
    • Bot visits show machine access, not brand preference or human demand.
    • Aggregate evidence can support a journey hypothesis, but anonymous events should not be turned into deterministic user-level attribution.
    • The best next optimization is the one aimed at the first layer where the evidence weakens.

    Start with one commercially important journey and map its evidence from prompt to outcome. You do not need perfect attribution before acting. You need a clear boundary between what you observed, what you inferred, and which failure point your next change is designed to address.

    References

  • How to Build AI Search Visibility Through Brand Recognition

    How to Build AI Search Visibility Through Brand Recognition

    Your pages rank, your traffic reports look respectable, yet your brand disappears when a prospect asks an AI assistant for options. That gap is not just a reporting curiosity. Your content may be discoverable while your brand remains absent from the answer that shapes the decision.

    Fixing that gap starts by changing what you measure. You need to know whether AI systems recognize your brand in the right unbranded conversations, describe it accurately, and do so often enough that one lucky mention cannot fool you.

    Recognition is the outcome; rankings are one input

    Traditional rank tracking asks whether a page earned a particular position for a query. AI visibility adds a harder question: when a system assembles an answer, does it connect your brand with the category, problem, product attribute, or recommendation context that matters?

    That distinction matters because brand recognition increasingly matters alongside conventional rankings. A strong organic position can help people and machines discover your information, but it does not guarantee that an AI response will name your brand, frame it correctly, or use it as a preferred example.

    Recognition is more specific than general awareness. For AI search measurement, treat it as the repeated and accurate association of your brand with a relevant topic or decision. A mention is useful only when the surrounding answer helps the user understand why your brand belongs there.

    • Topical fit: The brand appears for a problem or category it genuinely serves.
    • Accurate framing: The response describes what the brand does without confusing its audience, offer, or positioning.
    • Decision relevance: The mention appears where a user is discovering, evaluating, or selecting an option, not in an unrelated aside.
    • Credible support: The response connects the claim to a useful citation or supporting context when the interface provides one.
    • Repeatability: The result survives repeated runs instead of appearing in one favorable screenshot.

    This is why a mention count by itself is weak. A brand can be named frequently but described as the wrong type of company. It can appear in a long list without any explanation. It can also be cited as an information source while a competitor receives the actual recommendation. Record those outcomes separately.

    Rankings still matter, but their role changes. They are part of the evidence and discovery layer, not the final visibility score. The practical endpoint is whether your brand becomes a clear, trusted part of the answer, especially when users can receive an answer without visiting a result page.

    Build a prompt panel that represents real decisions

    A research team arranges illustrated scenario cards around a compass on a large table.

    You cannot measure AI visibility with whichever prompt happens to come to mind during a meeting. A useful baseline needs a fixed prompt panel: a time-stamped collection of exact questions that represent the situations in which you want to be recognized.

    Start with unbranded prompts. If the prompt already contains your name, the resulting mention says little about discovery. Keep branded prompts in a separate diagnostic set for checking factual accuracy, positioning, and direct brand understanding.

    Organize the unbranded panel into three intent buckets:

    • Category discovery: Questions asking which tools, companies, services, or approaches exist for a defined need.
    • Requirement-led research: Questions built around a feature, constraint, audience, use case, or product specification.
    • Evaluation and selection: Questions asking for suitable options, trade-offs, or criteria before a decision.

    A practical coverage panel can contain 25 exact prompts in each bucket, producing 75 queries. That is a testing design, not a universal minimum. If 75 prompts are too costly to repeat, preserve the three-bucket balance and select a smaller experimental cohort from the full panel. For a focused change, a cohort of 5-10 target prompts run daily across seven consecutive days gives you a more defensible baseline than a single session.

    Do not rewrite prompts between the baseline and measurement periods. A change from a broad category question to a product-specific question is not a harmless variation; it changes what the system is being asked to retrieve and compare. Save alternate phrasings as separate prompt records.

    For every run, record the exact prompt, model, displayed model version when available, date, environment, login state, location or locale, and response. Use a consistent testing environment. A logged-out browser with a cleared cache is one option; an API or synthetic testing platform can provide tighter control where available. The aim is not to create a perfectly sterile laboratory. It is to keep avoidable differences from becoming explanations for the result.

    Then label each response using the same fields:

    SignalWhat to recordWhat it tells you
    InclusionWhether the brand appears in the responseHow often the model associates the brand with the prompt context
    Position in responseWhere the first substantive mention appearsWhether the brand is central to the answer or peripheral
    FramingRecommended, neutral, compared, cautioned against, or merely citedWhether visibility is helping the intended positioning
    AccuracyCorrect or incorrect category, audience, capabilities, and limitationsWhether the model recognizes the right entity and facts
    CitationThe linked or named supporting page, when citations are exposedWhich evidence appears to support the mention

    Calculate inclusion rate as the number of eligible runs that mention the brand divided by the total number of eligible runs. Keep the raw labels as well as the percentage. A single combined score can conceal an important failure, such as higher inclusion paired with inaccurate framing.

    Break results out by model and prompt bucket. An average across every system and intent can make a brand look moderately visible when it is actually strong in category discovery, absent during evaluation, and misrepresented by one model. That is not one problem; it is three different problems requiring different changes.

    Strengthen the signals that make your brand understandable

    Linked pages, profiles, books, seals, and network nodes converge to form one clear blue geometric object.

    AI recognition is not created by repeating a brand name more often. It grows when the web contains clear, consistent evidence about what the brand is, which topics it belongs to, what it offers, and why it is relevant in a particular context.

    Make the visible content answer a precise question

    Generic claims leave little for a system to connect with a detailed prompt. Replace vague category language with facts that resolve a real requirement: the product type, intended user, model, offer, relevant specifications, supported use case, and meaningful constraints. The goal is not maximal detail on every page. It is enough detail for the page to answer the prompt it is meant to support.

    For example, if your prompt panel contains requirement-led questions and the relevant page never states those requirements explicitly, that is the first gap to fix. Add one self-contained paragraph that connects the brand, product, and requirement in plain language. Do not simultaneously rewrite the introduction, change the page template, and add schema if you want to know whether that paragraph mattered.

    Keep core entity facts consistent across your own pages. The canonical brand name, category, audience, product naming, and relationship between the company and its offers should not shift according to which team wrote the copy. Consistency reduces ambiguity; mechanical repetition does not.

    Use structured data to clarify, not to invent

    Structured data can make relationships such as brand, model, and offer explicit in a machine-readable layer. Its effect on AI answers should still be tested rather than assumed. Schema is not a guarantee of selection, and it cannot create authority or factual support that the visible page lacks.

    Markup should describe information that users can already verify on the page. If a page has a visible question-and-answer section, adding the corresponding FAQ markup creates a clean experiment: the visible answers stay fixed while the explicit structured-data signal changes. Likewise, brand, model, or offer properties can be added without rewriting the HTML copy when you want to isolate the machine-readable layer.

    Do not add unsupported claims to JSON-LD because you want an AI system to repeat them. At best, the test becomes uninterpretable because the markup and page disagree. At worst, you make inaccurate information easier to reproduce. Treat structured data as a precise description of the page, not a hidden promotional channel.

    Build recognition beyond your own domain

    Your website can define the entity, but self-description is only one part of recognition. Brands become easier to identify when they appear consistently in meaningful external contexts and are cited for topics they genuinely cover. That makes public relations, content distribution, industry participation, and reputation work part of AI search strategy rather than separate activities.

    Audit external mentions for context, not just volume. A mention is more useful when it associates the right brand with the right category and a concrete area of expertise. Repeated mentions that use obsolete product names, vague descriptors, or the wrong category can reinforce confusion instead of authority.

    For each important prompt cluster, create an evidence map with four lines:

    <!– wp:list {
  • How to Measure AI Search Visibility and Make It Actionable

    How to Measure AI Search Visibility and Make It Actionable

    You can have a healthy SEO dashboard and still be nearly invisible when a buyer asks an AI assistant what to choose. The difficult part isn’t collecting another visibility score. It’s knowing whether a change reflects stronger retrieval, a different mix of prompts, or noise in the answers you sampled.

    A useful measurement system starts with a repeatable prompt panel, distinguishes mentions from citations, checks whether your brand is represented accurately, and connects that evidence to business outcomes. Here is how to build one without turning a handful of AI responses into false precision.

    Measure what happens inside the answer, not just after the click

    Traditional search measurement follows a familiar sequence: query, ranking, impression, click, session, conversion. Generative search compresses much of that journey into an answer. A user can discover your brand, compare it with alternatives, absorb a claim about it, and make a decision without visiting your site.

    That makes traffic an incomplete visibility measure. Some studies cited in current GEO coverage put traditional-result clicks at only 8% when AI-generated summaries are present. Treat that figure as a warning about measurement gaps, not as a universal click-through benchmark for your site. The practical point is that an off-site answer can influence demand even when analytics records no session.

    Measure AI search visibility across four layers. Presence tells you whether the brand appears. Use tells you whether an owned page is retrieved or cited. Representation tells you whether the answer describes the brand accurately and in the right context. Impact tells you whether that exposure is associated with qualified visits, branded demand, leads, sales, or another business outcome.

    These layers prevent a common reporting error. A brand mention is not automatically an owned-content citation. A citation is not proof that the answer framed the brand correctly. Visibility is not proof of commercial influence. Each is useful, but each answers a different question.

    Key takeaways

    • Use a stable set of prompts so one reporting period can be compared with another.
    • Keep mentions, citations, observable retrieval, entity accuracy, sentiment, and conversions as separate measures.
    • Report results by platform, topic, intent, and prompt cohort before calculating an overall score.
    • Save the underlying answer and its citations. A percentage without evidence cannot be audited.
    • Use visibility metrics to choose an action, then judge that action by the specific metric it was intended to change.

    Build a prompt panel you can rerun without moving the goalposts

    A controlled grid of abstract prompt tiles feeds into parallel answer chambers, with one displaced tile showing a changed test condition.

    Your prompt panel is the measurement instrument. If the prompts change whenever a campaign changes, the resulting trend line cannot tell you whether visibility improved or the test simply became easier.

    Start with topics and decisions that matter

    List the topics your brand should credibly be associated with, then map the questions a real buyer asks while learning, solving, comparing, choosing, and validating. This creates a panel that covers informational discovery as well as decision-stage visibility.

    • Learn: What is the category, process, or concept?
    • Solve: How should someone handle a defined problem or constraint?
    • Compare: What are the meaningful differences between available approaches?
    • Choose: Which options fit a particular use case, audience, budget, or requirement?
    • Validate: Is a named brand suitable, credible, compatible, or known for the relevant capability?

    Include branded and unbranded prompts, but don’t blend their results. An unbranded prompt tests discovery and competitive consideration. A branded prompt tests entity recognition, factual accuracy, and reputation. A dashboard that combines them can look strong simply because the model answers direct questions about a brand that the user already named.

    Apply audience, industry, location, or product qualifiers only when they change the decision. Keep them in dedicated cohorts. Otherwise, an increasingly narrow prompt may manufacture visibility that does not exist for the broader market question.

    Create a prompt registry before collecting answers

    Give every prompt a permanent record. At minimum, store its ID, exact wording, topic, intent, audience qualifier, branded or unbranded status, platform and mode, relevant competitor set, target page, and the brand facts you expect an accurate answer to preserve.

    Freeze the wording used for your baseline. If you improve a prompt later, create a new version instead of overwriting the old one. Keep retired prompts in the registry so historical rates retain their original denominator. This is less convenient than editing a shared list in place, but it prevents an invisible change in the test from masquerading as an improvement in performance.

    Use a consistent collection protocol

    1. Run the exact registered prompt in the intended platform and mode, such as an answer with web search enabled rather than a model-only response.
    2. Record the platform, mode, timestamp, prompt version, full response, visible citations, cited URLs, and any named competitors.
    3. Score the answer with a written rubric. Preserve the raw response so another reviewer can check the decision.
    4. Repeat the panel on a fixed cadence. If resources permit, run prompts more than once so a single response is not mistaken for a stable pattern.
    5. Log failed captures, blocked responses, and unavailable features separately. Do not score a technical failure as brand absence.

    Keep platform results separate. Google AI Overviews, ChatGPT search, and other answer systems are different surfaces with different retrieval and citation behavior. You can create a portfolio view later, but first calculate each platform’s rate against its own eligible observations.

    If you do publish an aggregate, state its weighting. An unweighted average gives every prompt-platform pair the same influence. A business-weighted score gives priority cohorts more influence. Neither is inherently correct; an unexplained blend is the problem.

    Use a metric stack instead of one opaque visibility score

    A practical GEO measurement stack separates eight signals across presence, representation, retrieval, competition, and impact. The definitions below turn those ideas into auditable calculations. They are operational definitions, not universal standards, so document them and resist changing them midstream.

    MetricOperational definitionQuestion it answers
    Answer inclusion rateEligible answers containing a qualifying brand mention or traceable use of owned content, divided by all eligible answers in the cohort.Does the brand enter the answer at all?
    AI citation frequencyEligible answers containing a visible citation connected to the brand, divided by all eligible answers. Report any-brand citation and owned-domain citation separately.Is the answer visibly supported by material associated with the brand, and does it cite the brand’s own site?
    Share of model voiceThe brand’s unique inclusions divided by unique inclusions for the entire predefined competitor set. Count a brand once per answer so repetition does not inflate share.How much of the observable category conversation does the brand occupy?
    Entity recognition accuracyBrand-discussing answers that preserve the required facts divided by all answers that discuss the brand.Does the system understand who the brand is, what it offers, and how its entities relate?
    Sentiment and framingCounts of favorable, neutral, critical, or mixed descriptions, paired with issue codes and the exact claim being evaluated.How is the brand characterized before the user reaches its site?
    Prompt coveragePriority prompt cells with at least one qualifying inclusion divided by all eligible priority prompt cells.Across how much of the intended buyer journey is the brand visible?
    Observable retrieval successRuns in which a relevant owned page is visibly retrieved or cited, divided by runs where that page is an eligible answer source.Can the system access and use the content you expected it to use?
    Conversion influenceQualified visits, conversions, lead quality, revenue, branded demand, or other outcomes associated with AI referrals and visibility changes.Is AI visibility connected to business value?

    The denominator matters as much as the numerator. Show both on every metric card. A 50% inclusion rate based on two eligible answers carries very different weight from the same rate across a broad, repeated panel.

    Keep citation frequency and retrieval success distinct. A brand can be mentioned because a third-party page was retrieved. An owned page can be cited without the brand becoming a recommended option. A model may also name the brand without exposing any source. Consumer-facing outputs rarely reveal every internal retrieval step, so call the measure observable retrieval rather than claiming access to hidden model behavior.

    Share of model voice also needs a locked competitor set. Adding weak competitors lowers everyone’s apparent share; removing a dominant competitor raises it. Version the set just as you version prompts, and show absolute inclusion alongside share. If absolute visibility holds steady while share falls, competitors may be gaining rather than your brand disappearing.

    For entity accuracy, write the answer key before scoring responses. Include only facts the brand can substantiate, such as its official name, category, product relationships, supported markets, or current positioning. Record each error type separately. A single accuracy percentage will not tell your content team whether the problem is an outdated name, a category mismatch, a confused product relationship, or a claim that is too broad.

    Sentiment needs the same discipline. A neutral answer that omits the brand’s relevant capability is different from a critical answer containing a factual error. Save the exact sentence, its context, the issue code, and the affected prompt. Automated labels can help sort a large collection, but consequential or ambiguous cases still need human review.

    Read metric combinations as a diagnostic system

    No metric tells you what to change by itself. The useful signal comes from combinations. Start with the smallest cohort where the problem appears, then diagnose the layer most likely to be responsible.

    Low inclusion plus low observable retrieval

    Begin with access and extractability. Check whether the intended page can be crawled, whether the primary answer is available in parseable text, whether important information is current, and whether structured data accurately describes the visible content and entity relationships. Crawlability, schema use, freshness, and parsing quality all belong in a retrieval-success investigation.

    Do not add schema merely to produce more markup. Structured data can clarify supported facts; it cannot make a thin, contradictory, or inaccessible page authoritative. Validate the markup, align it with what users can see, and retest the affected prompt cohort after the page can be revisited.

    Inclusion without owned citations

    The system recognizes the category connection, but your site is not supplying the visible evidence. Inspect which domains are cited instead and what those pages make easy to extract. Then improve the relevant owned page with a direct answer, clear definitions, explicit comparison dimensions, supported claims, and enough surrounding context for a passage to stand on its own.

    Do not treat matching wording as proof that the model used your page. Unless the interface exposes a citation or retrieval record, hidden sourcing remains unknown. Score what you can observe and use citation gains as the validation target for this change.

    Strong visibility with weak entity accuracy

    This is a representation problem, not an awareness problem. Compare the wrong claim with the corresponding signals on your site, structured data, product pages, and corroborating profiles. Standardize names and relationships, remove obsolete descriptions, and make the canonical explanation explicit. Retest the prompts that produced the error rather than waiting for the global score to move.

    Informational coverage without decision-stage visibility

    The brand may be recognized as an educator but absent from the consideration set. Examine compare, choose, and validate prompts. If the cited pages answer selection questions that your pages avoid, create or improve content around fit, limitations, use cases, evaluation criteria, and meaningful alternatives. The goal is not to declare yourself the best. It is to supply the facts an answer system needs to explain when the offering is or is not a fit.

    Visibility gains without measurable business impact

    First check intent. More citations on broad educational prompts may be valuable without creating immediate demand. Next check whether the cited or visited page offers a sensible next step for that query. Then inspect referral classification, landing-page engagement, conversion quality, direct traffic, and branded search movement.

    Do not force a revenue claim from a coincident trend. Off-site AI interactions are often not connected to an identifiable user journey. Call the result influence unless you have instrumentation that supports stronger attribution.

    Change one measurement layer at a time

    Turn each diagnosis into a recorded experiment. State the affected cohort, observed gap, proposed change, page or entity being changed, metric expected to move, business guardrail, and next review point. If you rewrite the prompts, replace the target pages, and change the scoring rubric together, you will not know which change produced the new result.

    Keep a control cohort of unchanged prompts when practical. It gives you context when visibility moves across the platform rather than only on the pages you changed.

    Report evidence, decisions, and business influence in one workflow

    Abstract answer signals pass through a diagnostic prism and flow into content, source, customer-journey, and business-outcome elements.

    A dashboard should shorten the distance between an observed gap and the person who can address it. Clutch, for example, places Conductor-powered visibility analysis inside its AI Visibility Dashboard. The useful principle is workflow integration: a report creates more value when operators can move from the trend to the affected prompt, answer, citation, topic, and page.

    Give each audience the view it needs

    • Leadership view: priority-topic inclusion, share of model voice, entity accuracy, major reputation issues, qualified AI traffic, and conversion influence.
    • Operator view: platform, topic, intent, prompt, target page, cited domain, competitor, issue code, and experiment status.
    • Evidence view: exact prompt, full response, visible links, scoring decision, timestamp, reviewer, and prompt version.

    Every summary card should show the current value, comparison baseline, numerator, denominator, included cohort, and last collection date. Avoid a global visibility score that cannot be traced to those components. It may look tidy, but it cannot tell a content, technical SEO, brand, or analytics team what to do next.

    Keep the collection cadence and the decision cadence separate

    Collect on a consistent schedule that your team can sustain. Review urgent factual errors when they appear, but make strategic decisions only after you have enough comparable observations to distinguish a pattern from one answer. Annotate changes to prompts, pages, structured data, competitor sets, platform modes, and scoring rules directly on the timeline.

    When a platform introduces a materially different mode or answer experience, create a new cohort. Do not splice it into the old series as if the measurement environment stayed constant.

    Triangulate AI visibility with analytics and search data

    No single product captures the complete path. Combine controlled prompt testing with analytics, server or referral evidence where available, Search Console, traditional SEO tools, technical audits, and business data. This mixed approach reflects the reality that GEO measurement currently requires multiple tools and methods.

    In GA4, isolate known AI-platform referrals and compare their landing pages, engagement, conversion rate, conversion value, and lead quality with relevant baselines. Keep the referral rules documented because platforms and referrer behavior can change. Review direct and branded-search demand alongside those sessions, but present the relationship as supporting evidence rather than proof that every change came from AI exposure.

    Search Console still helps you see traditional query demand, page performance, and technical conditions around the topics in your prompt panel. It will not expose every AI interaction, but it can reveal whether a page has a broader indexing, relevance, or demand problem that also limits its usefulness to generative systems.

    Evaluate tools by the decisions they support

    Before buying an AI visibility platform, ask whether it supports the exact environments you need to measure and whether you can audit its results. A useful evaluation checklist includes:

    • Named platforms and modes rather than a generic claim of model coverage.
    • Exact prompt storage, prompt versioning, cohort management, and repeatable scheduling.
    • Preservation or export of full responses, citations, cited URLs, timestamps, and scoring evidence.
    • Transparent definitions and denominators for inclusion, citations, share of voice, sentiment, and coverage.
    • A configurable competitor set and the ability to retain historical versions of that set.
    • Segmentation by topic, intent, platform, geography where relevant, brand, competitor, and target page.
    • Human review, issue coding, annotations, ownership, and an audit trail for score changes.
    • Connections to analytics and business outcomes rather than visibility reporting alone.

    Do not compare vendor scores as though they were interchangeable. One may count every mention, another only cited mentions, and another may use a proprietary weighted index. Compare the underlying prompts, observations, scoring rules, and denominators before comparing the headline numbers.

    Start with one commercially important topic. Freeze its prompts, capture a baseline, and identify the largest localized gap: presence, citation, retrieval, accuracy, competitive share, or impact. Assign one change to that gap and name the metric that should respond. When the dashboard can tell your team what to inspect next, AI search visibility stops being a vanity score and becomes an operating system for better decisions.

    References

  • AI-Driven SEO Strategy: Build Visibility Beyond Your Site

    AI-Driven SEO Strategy: Build Visibility Beyond Your Site

    If your rankings look respectable but your brand rarely appears in AI-generated answers, publishing more keyword-targeted pages may not solve the problem. You may already have enough content. What you lack is a connected body of facts, answers, and independent evidence that an AI system can find and reconcile.

    An effective AI-driven SEO strategy connects five things: the questions your audience asks, the answers you want associated with your brand, the evidence supporting those answers, the places that evidence appears, and the business outcomes you measure. Here is how to build that system without abandoning the SEO work that still matters.

    Key takeaways

    • AI-driven SEO is not simply using AI to produce more content. It is designing your search presence for discovery, interpretation, and corroboration across multiple surfaces.
    • Your website remains the canonical home for your facts and expertise, but it cannot be the only place where your brand is represented.
    • Plan around audience questions and the proof needed to answer them, not isolated keywords or publishing quotas.
    • Keep important claims consistent across pages, structured data, official profiles, directories, contributed content, and earned mentions.
    • Measure whether AI answers include, describe, and support your brand accurately, then connect that visibility to qualified visits, leads, and revenue.

    Treat your website as the center, not the entire strategy

    Traditional SEO concentrates much of its effort on the website: improve crawlability, target relevant queries, earn links, and move pages up the results. Those jobs still matter. If your pages cannot be discovered, understood, or trusted, they are unlikely to become useful inputs for any search experience.

    The strategic boundary has expanded, however. AI search can form its understanding of a brand from multiple inputs, including articles, brand mentions, social activity, third-party profiles, directories, press material, and other published content. Your site is a critical input within that environment, not a substitute for it.

    This changes the unit you optimize. A page is still an SEO asset, but the larger unit is an evidence network: several discoverable representations that agree about who you are, what you do, who you serve, and why a particular claim should be believed.

    Audit three separate visibility layers

    • Discovery: Can a search system find a relevant page, profile, mention, or listing when it investigates the subject?
    • Understanding: Do those surfaces use clear language for your brand, category, offering, audience, people, and locations?
    • Corroboration: Does the available evidence support your important claims, or does everything lead back to an unsupported statement on your own site?

    Run the audit for a small set of commercially important questions. For each one, search your site, review your official profiles, inspect prominent third-party pages, and examine representative AI answers. Record whether the brand is absent, present but vaguely described, accurately represented, or supported with useful evidence. Those are different failures and require different fixes.

    An absent brand may need stronger topical coverage or distribution. A misdescribed brand needs clearer entity facts and correction of conflicting profiles. A correctly named brand that is never recommended may have an evidence problem rather than a content-volume problem.

    Build the plan from questions, claims, and proof

    Abstract audience questions, claim modules, source folders, document stacks, and verification tokens converge into one organized structure on a table.

    A keyword list tells you which phrases people type. It does not tell you what an AI answer must resolve before it can mention your brand responsibly. Add a prompt-to-proof map beside your keyword research so that each priority question has a defensible answer and a clear evidence requirement.

    Create a prompt-to-proof map

    Use one row for each question family and include these fields:

    • Audience situation: Who is asking, and what decision are they trying to make?
    • Question family: Group alternate phrasings that seek the same underlying answer.
    • Desired brand association: State the accurate role your brand should occupy, without promotional superlatives.
    • Answer requirements: List the facts, distinctions, caveats, and comparison criteria a useful response must cover.
    • Proof required: Identify the documentation, demonstrated expertise, verifiable credentials, product information, or independent recognition needed to support the answer.
    • Canonical asset: Choose the page that should contain the most complete and current explanation.
    • Corroborating surfaces: Record the profiles, directories, partner pages, publications, communities, or social channels where related evidence legitimately belongs.
    • Current failure: Label the gap as missing answer, weak proof, inconsistent facts, limited distribution, or poor technical access.
    • Next action and owner: Give the row a concrete change and a person responsible for maintaining it.

    Suppose a buyer asks which platform is appropriate for an international ecommerce team. A page that repeats the phrase “international ecommerce platform” is not a complete answer. The buyer may need to understand market support, language handling, operational constraints, integrations, and the situations in which the product is not a fit. Your map should expose which of those decision criteria you can answer and prove.

    This also prevents indiscriminate content generation. If several prompts require the same underlying evidence, strengthen one definitive resource and distribute its verified claims appropriately. If you have no proof for a desired claim, do not turn it into a larger publishing campaign. Change the claim, obtain the evidence, or deprioritize the question.

    Prioritize gaps, not content formats

    Choose work by business relevance, answer weakness, and available proof. A commercially important question with a weak existing answer and strong internal evidence is usually a better target than a high-volume topic where your brand has nothing distinctive or verifiable to contribute.

    The required fix may be a service page, comparison framework, technical explainer, expert biography, directory correction, original documentation, or stronger distribution. Starting with the gap keeps the team from prescribing a blog post before it understands the problem.

    Make important facts consistent and machine-readable

    AI visibility becomes fragile when every channel describes the same company differently. A rebrand appears on the homepage but not the executive profiles. A service is available in one market, while an old directory implies global availability. Structured data names one organization, while the visible page uses another variation without explaining the relationship.

    Consistency does not mean publishing identical sentences everywhere. It means maintaining agreement on the facts that determine identity, relevance, and qualification.

    Maintain a canonical fact and claim register

    • Official brand name, accepted name variations, and the relationship between parent brands, divisions, and products.
    • Plain-language descriptions of the categories and problems the organization addresses.
    • Current offerings, intended audiences, locations served, and material limitations.
    • Named people, roles, credentials, and areas of expertise that can be verified.
    • Important performance, leadership, or differentiation claims, each paired with its evidence and necessary qualifier.
    • The canonical URL for each fact or claim, plus the profiles and external pages where it also appears.
    • An owner and a review trigger, such as a product change, market launch, rebrand, leadership change, or expired credential.

    Use the register during content briefs, profile updates, public relations work, partnership reviews, and schema implementation. It gives every channel the same factual foundation while allowing each one to use language appropriate to its audience.

    Use JSON-LD as a translation layer, not as evidence

    Structured data should represent the facts a visitor can verify on the page and clarify the relationships among the entities discussed there. It should not introduce unsupported awards, ratings, credentials, prices, or organizational relationships. Markup can make a fact easier for a machine to interpret; it cannot make the fact credible by itself.

    For each priority page, compare the visible copy, metadata, internal links, and JSON-LD. Names, descriptions, identifiers, authorship, dates, availability, and entity relationships should not contradict one another. Validate the markup, but also perform a human fact check. Technically valid schema can still describe the wrong thing.

    Make the main answer easy to extract without stripping away the reasoning that makes it trustworthy. Use a descriptive heading, answer the central question directly, define important terms, state qualifications near the claim they limit, and place evidence beside the statement it supports. Then link to deeper documentation where a reader or retrieval system may need more context.

    Repeat the audit for every language-market pair

    For international SEO and AI visibility, do not assume a strong global page settles the question everywhere. Search language, market terminology, local offerings, recognized experts, relevant directories, and available proof can differ. Create a market-level version of the prompt-to-proof map, while keeping the underlying brand identity reconciled with the global register.

    Do not translate unsupported claims into additional languages. Confirm that the offering, evidence, and qualification apply in the target market first. If they do not, adapt the answer rather than forcing global copy into a local search context.

    Publish and distribute proof as one coordinated system

    Matching evidence travels from one source package to several digital platforms and is gathered by a translucent AI retrieval lens.

    A broader footprint does not mean opening every channel or syndicating the same paragraph across the web. Choose surfaces because they help a particular audience discover, understand, or verify something important about the brand.

    SurfacePrimary jobWhat to publish or correct
    Canonical website pageProvide the complete answerDefinitions, decision criteria, qualifications, evidence, ownership, and update context
    Official profilesConfirm identityCurrent name, category, description, location, people, offering, and canonical link
    Relevant directoriesSupport category or market discoveryAccurate classification, service details, credentials, location data, and current links
    Partner or association pagesVerify a real relationshipThe nature of the relationship, applicable expertise, and supporting resources
    Earned coverage and contributed expertiseAdd independent contextNewsworthy developments, attributable expertise, original explanations, and defensible claims
    Social and community channelsExpose timely expertise and audience languageUseful explanations, answers to recurring questions, and links to definitive resources when needed

    A fragmented channel strategy produces weaker signals when messaging and expertise do not align. Solve that operationally. Give SEO, content, social, public relations, partnerships, and brand teams access to the same question map and claim register. Plan campaigns around the evidence you need to establish, not separate channel quotas.

    A practical distribution sequence looks like this:

    1. Publish or update the canonical explanation on a page you control.
    2. Bring official profiles and structured data into factual agreement with that page.
    3. Update legitimate directories and partner records where the same facts are relevant.
    4. Develop earned or contributed material only when there is independent value: genuine news, attributable expertise, useful analysis, or a verifiable relationship.
    5. Use social and community content to answer narrower questions and lead interested readers to the deeper resource.
    6. Record every material claim and placement so later changes can be propagated without recreating the audit.

    Press releases and directory listings are not automatic authority. A release needs actual news, and a listing needs relevance and accurate information. Publishing either solely to create another mention can add noise without supplying meaningful corroboration.

    When you find a conflict, correct the canonical page, structured data, and official profiles first. Then update controlled listings and request corrections from third parties. Keep a record of pages you cannot change so the team understands why an outdated description may continue to surface.

    Measure whether AI can find, understand, and support you

    Rankings, organic sessions, and conversions remain necessary, but they do not reveal how a generative answer represents your brand. AI mention counts alone have the opposite weakness: they can show exposure without showing accuracy, influence, or business value. Use both diagnostic and outcome measures.

    Build a repeatable visibility record

    Keep a stable set of priority questions organized by journey stage, audience, language, and market. When you review an AI search surface, record:

    • The exact question and the context needed to interpret it.
    • The platform, search mode, language, market, and review date.
    • Whether your brand appears and what role it occupies in the response.
    • Whether the description is accurate, incomplete, outdated, or wrong.
    • Which pages or external references support the answer, when references are shown.
    • Which competitors appear and what claims or evidence distinguish them.
    • The specific gap exposed: missing content, weak evidence, entity confusion, poor distribution, or inaccessible information.
    • The action taken and the canonical asset expected to change.

    Do not treat a single generated response as a trend. Repeat the same controlled review over time and look for persistent patterns across the question family. Separate a one-off omission from a recurring inability to associate the brand with the subject.

    Connect visibility to business outcomes

    Pair the visibility record with qualified organic and referral visits, assisted conversions, leads, sales, and branded demand where your analytics can support those connections. The purpose is not to claim that every mention caused a conversion. It is to see whether stronger representation around high-value questions accompanies useful audience behavior.

    Review failures before celebrating totals. Being mentioned for an irrelevant use case, described with an outdated feature, or attached to an unsupported claim can create more work than being absent. Accuracy, relevance, and evidence quality belong beside visibility on the dashboard.

    Start with one question cluster tied to a real buying or evaluation decision. Build its prompt-to-proof map, repair the canonical facts, strengthen the best page, align the surrounding profiles, and establish a repeatable baseline. Once that workflow holds together, extend it to the next cluster. That is how AI-driven SEO becomes an operating system rather than another publishing campaign.

    References

  • Top GEO Agencies Transforming Home Services in 2026

    Top GEO Agencies Transforming Home Services in 2026

    As I dive into this report, I’m excited to share the top 8 real estate GEO and AEO agencies of 2026. These agencies have been selected based on their impressive results, technical expertise, and exceptional client experience.

    Our research team embarked on a detailed study of agencies that specialize in Generative Engine Optimization (GEO) specifically for companies in the home services industry like HVAC, plumbing, electrical, and home security. From a total of 53 agencies, we focused on those serving markets including pest control, lawn care, and remodeling. Here’s how we analyzed them:

    • Home Services Client Experience (30%): I found agencies with proven success in understanding the unique landscape of seasonal demand, emergency calls, and local search.
    • GEO/AI Search Technology and Tools (25%): Optimization expertise for AI-powered platforms like ChatGPT and Google AI Overviews was a must.
    • Average Customer Review Score (15%): Each agency’s client satisfaction was gauged using scores from platforms like Google and Clutch.
    • Leadership Experience Score (10%): Leadership’s depth of experience in both digital marketing and home services was a key factor.
    • Year Established (10%): I considered the tenure of each agency and their ability to adapt over time.
    • Notable Clients (10%): Agencies were evaluated based on their successful partnerships with quality home service providers.

    After an in-depth analysis using data from company websites, reviews, and direct outreach, I’ve ranked these firms. The table below showcases the leading home services GEO agencies to keep companies visible across both traditional and AI-powered platforms.

    The Top Home Services GEO Agencies of 2026

    RankCompanyEstablishedFounder LedLeadership ExperienceAverage Review ScoreHome Services FocusNotable ClientsSpecialty
    1First Page Sage2009Yes4.84.9HVAC, Electrical, Plumbing, RoofingMighty Dog Roofing, iFOAM InsulationHigh-impact lead-gen focused GEO and SEO
    2Siana Marketing2021Yes4.64.8100% construction and home servicesCorcoran, HomeVestorsConstruction-only GEO agency

    First Page Sage

    Under the guidance of CEO Evan Bailyn, First Page Sage has developed a robust GEO strategy that elevates home services companies. They’ve propelled names like Mighty Dog Roofing and Pipe Restoration Solutions to the top of search results by creating service-specific landing pages and geotargeted content.

    Their strategic focus on building a network of high-quality content ensures recommendations by AI platforms like ChatGPT. When homeowners inquire about the best local services, First Page Sage clients confidently come up as top recommendations.

    • Year Founded: 2009
    • Founder Led: Yes
    • Leadership Experience Score: 4.8
    • Average Review Score: 4.9
    • Home Service Focus: Broad home services experience
    • Notable Clients: Mighty Dog Roofing, iFOAM Insulation
    • Specialty: Lead gen-focused GEO and SEO
    Summary of Online Reviews
    Clients rave about First Page Sage’s “fastidious understanding of home services GEO” and “organized, communicative teams.” While their strategies drive quality leads, some mention the need for a longer ramp-up period for business research.

    Siana Marketing

    Founded in 2021, Siana Marketing directs its focus on GEO for construction and home services. Despite being young, they excel in securing appearances for architects and contractors in both traditional search and AI-generated results.

    The leadership team brings deep industry knowledge, with a strong grasp on sales cycles and influencing homeowner decisions. This expertise has helped maintain solid client retention, which is impressive for their relatively short tenure.

    • Year Founded: 2021
    • Founder Led: Yes
    • Leadership Experience Score: 4.6
    • Average Review Score: 4.8
    • Home Service Focus: 100% construction and home services
    • Notable Clients: Corcoran, HomeVestors
    • Specialty: Construction-only GEO agency
    Summary of Online Reviews
    Clients highlight Siana’s “industry knowledge” and understanding of the AEC sector’s growth strategies. There’s high demand and selective client acceptance due to their expertise.

    Focus Digital

    Focus Digital offers high-quality SEO and GEO support at prices accessible to smaller operations. They’ve built credibility by focusing on personalized client attention and staying ahead with innovative strategies.

    What makes them unique is their ability to provide premium strategic advice and execution, making them a top choice for businesses with tighter budgets seeking sophisticated search solutions.

    • Year Founded: 2018
    • Founder Led: Yes
    • Leadership Experience Score: 4.5
    • Average Review Score: 4.8
    • Home Service Focus: Small business contractors
    • Notable Clients: Stego Wrap, Twin Home Experts
    • Specialty: Budget-friendly SEO and GEO solutions
    Summary of Online Reviews
    Focus Digital’s clients commend their meticulous focus and state of constant innovation. They’re seen as “punching above their weight,” delivering value usually associated with bigger firms.

    Inspired by this post on First Page Sage Blog.


    crushpress.ai community screenshot