Author: shivamcrushpressai

  • Google Display to Demand Gen Migration: A Practical Runbook

    Google Display to Demand Gen Migration: A Practical Runbook

    If your standalone Google Display campaigns depend on Manual CPC, portfolio bidding, HTML5 ads or tightly constrained audience targeting, the move to Demand Gen is not a simple campaign rename. Some of those controls will not survive the migration, and pretending they will can leave you diagnosing a strategy change as if it were a temporary performance dip.

    Your safest approach is to separate migration from expansion. First reproduce the campaign as closely as Demand Gen allows. Confirm that bidding, creative, audiences, conversion signals and spending behave as expected. Only then test Discover, Maps, additional formats or other Demand Gen capabilities.

    The deadline matters, but the unspecified date matters more

    The ability to create new standalone Display campaigns will be disabled permanently in January 2027. Google expects automatic migrations later in 2027, but it has not specified when those migrations will begin.

    That gap is a planning risk. Waiting for automatic migration means you may lose control over whether the change lands near a product launch, seasonal promotion, reporting deadline or peak sales period. Migrating deliberately gives you a chance to resolve incompatibilities and choose a period when your team can watch the account closely.

    The migration tool began appearing through a phased rollout in June after the May announcement, so availability can differ between accounts. When the tool is available, it can update a live campaign while preserving the previous 42 days of performance history. That continuity is intended to reduce the new campaign’s learning period, not eliminate performance volatility.

    You also do not have to adopt every Demand Gen network during the move. Demand Gen supports individual network selection, and the migration tool initially creates a Google Display Network-only Demand Gen campaign. Other networks can be added afterward. Use that separation: migration should answer whether the replacement works; expansion should answer whether new inventory adds value.

    Audit the features that will not transfer cleanly

    Campaign components are sorted on a workbench, with compatible modules passing through an inspection gate and incompatible controls set aside in amber trays.

    Build a compatibility sheet before touching the migration control. For every Display campaign, record its current bid strategy, targeting logic, creative formats, data dependencies, measurement studies and business objective. Then mark every feature that requires a replacement.

    Display campaign dependencyDemand Gen statusDecision to make before migration
    Target CPA, Target ROAS or Maximize ClicksSupportedConfirm the selected strategy still matches the campaign objective and that its conversion inputs remain appropriate.
    Manual CPC, Viewable Impressions or Pay for ConversionsNot supportedSelect a replacement strategy and document how success will now be judged.
    Bid adjustments, seasonality adjustments or portfolio biddingNot supportedIdentify what business rule each control handled and decide how you will manage that requirement without it.
    Business Data feedsNot currently supportedDo not migrate a feed-dependent execution until you have a supported alternative. Availability has been described as coming, but without a specific date.
    Uploaded HTML5 ads or third-party adsNot currently supportedRebuild the creative in a supported format or wait. Support is planned for late 2026, but a roadmap date should not be treated as a delivery guarantee.
    Brand Lift or Search Lift studies for GDNNot supportedDecide whether the campaign can move without those studies or requires a different measurement plan.

    The supported bidding options are Target CPA, Target ROAS and Maximize Clicks. That does not make them interchangeable. Maximize Clicks is aligned with traffic acquisition. Target CPA requires a meaningful conversion action and a cost-per-acquisition objective. Target ROAS makes sense only when the conversion values being supplied reflect the value you actually want the system to pursue.

    Do not choose the nearest-looking setting just to clear the migration screen. Write down what the old strategy controlled and what the replacement will optimize. A campaign moving from Manual CPC to automated conversion bidding, for example, is undergoing a buying-strategy change as well as a platform change. Its before-and-after results need to be interpreted accordingly.

    Creative needs the same discipline. Business Data feeds, uploaded HTML5 ads and third-party ads are not currently supported. HTML5 and third-party ad support is planned for late 2026, while no precise availability date is stated for Business Data feeds. If one of those formats is essential to the campaign, the missing replacement is a migration blocker, not a minor setup detail.

    Use a controlled six-step migration runbook

    Six connected workstations show campaign inventory, duplication, configuration, verification, launch, and monitoring while the original setup remains on a parallel rail.

    A controlled migration gives you a clean baseline and limits the number of explanations for any change in performance. Use the same runbook for each campaign so that results are comparable across the account.

    1. Capture the baseline. Export at least the same 42-day performance window the migration tool can retain. Record the campaign budget, bidding method and target, conversion actions, audiences, creative formats and any account-level process that depends on the campaign. Save the date and time of the export.
    2. Map every unsupported dependency. Use the compatibility table above. Assign a replacement, owner and decision date to each unsupported bid strategy, adjustment, feed, creative format or lift study. Do not begin while an essential dependency remains unresolved.
    3. Choose the cutover window. Performance may fluctuate after migration, so avoid placing the first move immediately before a peak trading period. Pick a time when someone can inspect delivery and spending during the rest of that day and over the following reporting periods.
    4. Account for same-day spending. The newly migrated campaign will not respect the amount the old campaign already spent earlier that day. That creates a risk of more combined same-day spend than you expected. Watch total account spend at the cutover rather than assuming the new campaign knows how much daily budget has already been consumed.
    5. Verify the migrated campaign before expanding it. Confirm that the new Demand Gen campaign is restricted to Google Display Network inventory, as the migration tool is designed to configure it. Check the budget, bid strategy, conversion inputs, audience setup and live creative against your migration sheet.
    6. Hold expansion until the replacement is interpretable. Let the Display-only campaign establish a usable post-migration pattern before adding Discover, Maps or materially different creative. When you do expand, change one major dimension at a time and record the date.

    The fourth step deserves special attention. If a Display campaign has spent a large portion of its daily budget before migration, the new campaign can still begin without credit for that earlier spending. You do not need to predict the exact effect. You do need an operator watching the combined spend and authorized to respond if delivery departs from the day’s plan.

    During the first post-migration review, compare more than totals. Look at spend, delivery, conversion volume, conversion value and the metric tied to the chosen bid strategy. Annotate the migration so nobody later mistakes the cutover for an unexplained market movement. If you change the bid target, network mix and creative simultaneously, you will have no reliable way to tell which change produced the result.

    Rebuild audience and measurement assumptions for Demand Gen

    The deepest change is not in the interface. Demand Gen uses audiences and conversion signals as inputs to a more automated buying system, so controls that once acted as boundaries may now act as guidance.

    Treat Lookalike Audiences as signals, not fences

    As of March 2026, Lookalike Audiences changed from restrictive targeting to audience suggestions. Your first-party seed still informs the model, but Google can reach high-intent users outside the similarity thresholds associated with the seed.

    If you previously relied on a Lookalike segment to define who could receive an ad, revise that assumption before migration. The segment now supplies direction rather than a hard perimeter. Judge it by the outcomes it helps generate, and use the campaign’s available network controls to govern where ads can run.

    Create required Lookalike segments well before the campaign needs them. A new segment can take up to 96 hours to populate. Building it on the day of migration can leave you troubleshooting a campaign whose intended audience signal is not yet ready.

    Decide whether view-through conversions belong in optimization

    Demand Gen can optimize bids toward users who view a YouTube or Discover ad, do not click it, and convert later. This view-through-conversion optimization can provide an additional signal when click-led conversion volume is too limited for conversion-focused bidding.

    That capability is not automatically an improvement for every account. Decide whether a later conversion following an ad view represents an outcome you want the bidding system to pursue. Make the decision explicitly, document it and avoid comparing a view-through-optimized campaign with a click-focused predecessor as though their optimization inputs were identical.

    Billing also changes in a specific configuration. Google has announced that Demand Gen campaigns running on Discover with view-through-conversion optimization will move from CPC to CPM billing. In other words, cost is tied to impressions rather than clicks. This does not affect a Demand Gen campaign serving only on the Display network, but it becomes relevant as soon as you add Discover under that optimization setup.

    Before enabling that combination, update the reporting brief. Stakeholders should know that a change in click volume or CPC no longer describes the entire buying model. Mark the billing transition date and evaluate delivery, cost and conversions within the new setup rather than forcing a direct CPC-era comparison.

    Add new reach as a test, not a migration default

    Demand Gen can extend reach into Discover and Maps, offers formats unavailable in standalone Display, and includes additional generative image tools. It also provides more ways to use YouTube creative. An Affiliate Partnership boost for organic YouTube affiliate videos is in pilot, so it should be treated as an emerging option rather than a dependency in your migration plan.

    Test those capabilities after the Display replacement is stable. State one hypothesis for each expansion: the audience you expect to reach, the conversion signal the campaign will optimize and the result that would justify continued spend. Add one network or major creative approach at a time. Otherwise, Demand Gen’s wider inventory can obscure whether the migration itself succeeded.

    Key takeaways

    • New standalone Display campaign creation ends in January 2027; automatic migration is expected later in 2027, but its start date remains unspecified.
    • The migration tool can retain 42 days of history and initially creates a Display Network-only Demand Gen campaign.
    • Manual CPC, Viewable Impressions, Pay for Conversions, bid adjustments, seasonality adjustments and portfolio bidding require alternatives.
    • Business Data feeds, uploaded HTML5 ads, third-party ads, Brand Lift studies and Search Lift studies have support gaps that may block some migrations.
    • Same-day spend from the old campaign is not credited against the newly migrated campaign’s budget, so the cutover needs active spending oversight.
    • Lookalike Audiences are suggestions rather than restrictive targeting, and a new segment can take up to 96 hours to populate.
    • Discover inventory using view-through-conversion optimization is moving from CPC to CPM billing; Display-only delivery is not affected by that billing change.

    Start by opening your highest-spend standalone Display campaign and marking every compatibility-table row as supported, replaceable or blocked. If a blocked item has no approved alternative, solve that first. If the campaign is clear, choose a monitored migration window, preserve the Display-only network setup and put any Discover, Maps or creative expansion into a separate test plan.

    References


  • AI Watermarks: What Actually Matters for Search Quality

    AI Watermarks: What Actually Matters for Search Quality

    You are about to publish an AI-assisted page, and a watermark or detector score has turned an editorial decision into an SEO worry. The useful question is not whether a machine touched the draft. It is whether the finished page earns its place in search results and AI-generated answers.

    Treat the watermark as a clue about production, then audit the work itself. That keeps your attention on the failure modes that can damage visibility and trust: unsupported claims, recycled ideas, generic advice, near-duplicate pages, and automation without accountable review.

    A watermark describes provenance, not quality

    A machine-readable watermark associated with Claude-generated text can indicate that AI participated in the production process. It cannot tell a reader who originated the idea, how much of the finished work came from the model, whether its claims are correct, or whether the page is useful.

    Those questions belong to three separate layers:

    SignalWhat it can tell youWhat it cannot establish
    AI watermark or provenance markerAn AI system participated somewhere in generationOriginality, accuracy, usefulness, or the extent of human contribution
    AI detector scoreA tool estimates that the text resembles patterns it checksCertain authorship, reader value, or search quality
    Byline or author markupA named person or organization accepts ownershipThat the information is distinctive or deserves citation

    Conflating these layers leads to the wrong work. A team may rewrite sound sentences solely to reduce a detector percentage while leaving weak reasoning, unverified claims, and duplicated ideas untouched. The page then looks less detectable without becoming more valuable.

    AI use also is not one uniform editorial practice. Asking a model to organize your notes, challenge an argument, expose missing questions, or improve a draft is materially different from publishing its first response. In both cases, however, the publisher remains responsible for the result. If you would be uncomfortable defending the page once its AI involvement became visible, send it back through editorial review instead of trying to disguise the workflow.

    Search risk comes from low-value automation, not AI involvement alone

    Google has not treated AI authorship as an automatic reason to penalize content. Its relevant distinction is what automation produces and why it was produced. Generative AI can help with research and structure. The problem emerges when automation is used to manufacture large amounts of low-value material primarily to manipulate rankings.

    That is the mechanism behind the SEO risk. Giving a model broad publishing autonomy makes it cheap to produce generic recommendations, unsupported assertions, lightly altered pages, and summaries of information already present throughout the search results. Scaling those defects does not create authority. It multiplies reasons for search systems and readers to ignore the site.

    There is likewise no universal rule that a Claude watermark excludes a page from AI-generated answers. Answer engines still need material worth retrieving, citing, or synthesizing. A process signal does not erase original evidence, firsthand knowledge, a useful framework, or a defensible opinion. It also cannot rescue a page that merely repeats the prevailing consensus in slightly different words.

    Hold publication when any of these conditions is true:

    • Your editor cannot name the page’s unique contribution in one sentence.
    • A group of pages differs mainly by replacing a location, product, industry, or target keyword.
    • The copy makes factual claims that no reviewer has traced and verified.
    • The only reason for creating the page is that a keyword exists, not that a defined reader needs the answer.
    • No named person owns the final decision to publish, correct, or withdraw the content.
    • The page would lose nothing important if it were replaced by a generic search-results summary.

    This test applies equally to human and AI writing. A human-written page does not gain a competitive advantage merely by being human if it offers the same information as a thousand other pages. A watermarked page does not lose a genuine advantage merely because AI helped shape its presentation.

    Use a citation-worthiness audit before publication

    An article page surrounded by reference materials, with visual lines linking parts of the page to supporting sources and one area under a magnifying lens.

    A normal copy edit is not enough for AI-assisted work. You need a release process that tests why the page should exist, which claims deserve trust, and what an answer engine could retrieve from it. Use this sequence for every page, whether AI wrote one sentence or most of the first draft.

    1. Define the page’s job. Complete this sentence before drafting: This page helps a specific reader complete a specific task under a specific constraint. A broad topic such as AI content quality is not a job. Deciding whether to publish an AI-assisted landing page after detecting a watermark is.
    2. Name the unique contribution. Write down what the reader can obtain here that is difficult to obtain elsewhere. It could be original data you actually collected, a documented procedure, firsthand operational knowledge, a new comparison, or a reasoned interpretation. New wording is not new value.
    3. Build an evidence ledger. Record the support for every claim on which the reader might base a decision. Include the relevant URL, named authority, date or product version when needed, verification status, and reviewer. Do not ask a model to invent citations or treat its confidence as verification.
    4. Give AI bounded roles. Decide in advance whether the model may organize notes, propose an outline, challenge assumptions, generate alternatives, or improve clarity. Do not let the same automated process generate a claim, declare it verified, approve the page, and publish it without independent review.
    5. Run the genericity test. Replace the important nouns with those from another company or topic. If the paragraph still sounds equally plausible, it probably contains interchangeable advice. Cut it or add the missing evidence, constraint, example, or point of view.
    6. Make the useful answer retrievable. Put the direct answer close to the heading that asks the question. Keep its supporting evidence adjacent. Use stable entity names, descriptive headings, and a table only when the reader is genuinely comparing fields. Appropriate structured data can clarify what a page contains, but it cannot turn recycled copy into evidence.
    7. Assign a real owner. Name the person responsible for checking the claims and maintaining the page. Use a byline, credentials, and author markup only when they accurately represent that ownership. A byline can support identity consistency for AI crawlers, but it cannot make repetitive information citation-worthy.

    The release gate: can you defend the finished page?

    Before the page enters your CMS workflow, require clear answers to four questions:

    • Is it accurate? Every consequential claim has traceable support, and uncertainty is visible instead of being edited away.
    • Is it original enough to justify existing? The unique contribution is information, reasoning, or experience, not merely different phrasing.
    • Is it useful to the intended reader? That reader can make a decision, complete a task, avoid a mistake, or understand a meaningful distinction after reading it.
    • Will someone stand behind it? A named owner is prepared to explain the reasoning, correct errors, and accept scrutiny of the production process.

    If one answer is missing, the page is not ready. A lower AI score would not change that decision.

    Measure the finished page instead of chasing an AI percentage

    A layered page passing through a transparent inspection frame while a stack of nearly identical thin pages fades into the background.

    An AI score cannot tell you whether a reader finished the page, trusted it, shared it, subscribed, or completed the intended action. It also cannot tell you whether an answer engine cited the page accurately. Those are outcomes a detector percentage does not measure.

    Build reporting around the page’s actual job:

    OutcomeWhat to observeWhat to do when it fails
    Search discoveryIndex status, impressions for relevant queries, and qualified organic visitsCheck technical access, intent alignment, internal discovery, and whether the page adds enough value to compete
    AI-answer visibilityWhether relevant answer surfaces cite, link to, or accurately represent the pageStrengthen distinctive facts, make the answer easier to extract, and keep evidence beside the claim it supports
    Reader usefulnessCompletion of the action the page was designed to support, plus meaningful shares, subscriptions, or return visits where relevantFind the unanswered question, missing proof, or unnecessary friction instead of adding more generic copy
    Editorial trustCorrections, challenged claims, review failures, and substantive reader feedbackRepair the evidence and workflow before increasing production volume

    Do not mislabel all of these observations as direct ranking factors. They serve different purposes: search metrics show discoverability, citation checks show retrievability, and reader or business outcomes show whether the page fulfilled its intended role. Together, they provide a more useful diagnosis than a single AI-likelihood score.

    A detector result can still trigger a process check. An unexpected score may prompt you to confirm how a draft was produced, whether your editorial policy was followed, and whether required review occurred. It should not become a target that writers optimize at the expense of clarity. Rewriting accurate text until a detector approves its style is not content improvement.

    The same logic applies to watermark-removal tools. If removal is the only change, the page gains no new evidence, insight, or usefulness. Review the claims, eliminate sameness, add the missing contribution, and document accountable ownership before spending effort on the provenance signal.

    Key takeaways

    • An AI watermark can indicate something about production; it cannot determine accuracy, originality, usefulness, or search quality.
    • AI involvement is not an automatic search penalty. Low-value content produced at scale to manipulate rankings is the relevant risk.
    • Use AI for bounded tasks such as organization, critique, and editing, while keeping evidence checks and publication approval independent.
    • Bylines, author markup, headings, and schema can clarify ownership and meaning, but they cannot make generic information worth citing.
    • Judge a page by search discovery, answer-engine citations, reader usefulness, and editorial trust rather than an AI detector percentage.
    • If revealing AI involvement would make your team reluctant to defend the work, improve the work before publishing it.

    For your next AI-assisted page, require four fields before publication: the intended reader, the unique contribution, the evidence ledger, and the accountable owner. Leave the page in draft if any field is blank. If all four withstand scrutiny, publish the work and stand behind it, watermark or not.

    References

  • Google Search Result URL Redirects: What SEOs Should Check

    Google Search Result URL Redirects: What SEOs Should Check

    If your rank tracker suddenly disagrees with what you can see in Google, pause before changing the page. Google is inserting a Google-owned redirect between some search results and their destination pages, and that can disrupt the measurement layer without changing the ranking itself.

    Your first job is to identify which link in the chain changed: Google’s result, your tracking provider’s collection process, or your site’s actual search performance. A short, structured audit can keep a reporting incident from turning into an unnecessary content, schema, or technical SEO project.

    Read this as a link-delivery change, not a site redirect

    A conventional organic result used to expose the destination page’s full URL as its clickable target. Under the new behavior, the result can point first to a Google URL resembling google.com/goto?url=[hashURL]. Google processes that intermediate request and then sends the searcher to the destination.

    That extra hop matters because software inspecting the result may initially see a Google-owned URL instead of your page URL. The searcher can still see the displayed site URL under the result title, but the browser’s link preview may no longer reveal the complete destination before the click.

    Google describes the rollout as part of its technical response to evolving abuse and an effort to protect its services and users. That explanation is broad. It does not identify every type of abuse involved, so claims about one specific target or enforcement method should be treated as interpretation rather than confirmed implementation detail.

    Most importantly, this is not a redirect configured on your server. It does not, by itself, show that Google changed your canonical URL, replaced your indexed page, altered your structured data, or applied a ranking penalty. Your 301 and 302 rules remain separate from the redirect Google places inside its own result interface.

    • Do not add a site redirect to compensate. You cannot remove Google’s intermediate hop from your server, and another redirect would only add complexity to the destination path.
    • Do not change canonical tags or JSON-LD because a tracker exposes a Google URL. First confirm whether the tool is merely failing to resolve the final destination.
    • Do not treat the redirect as evidence of an algorithm update. A ranking change requires ranking evidence; a changed link target is not enough.

    Identify which part of your search stack is exposed

    A layered search stack shows a result link, a collection device encountering a redirect gate, and a healthy destination server.

    The effect depends on how you interact with the result. A person clicking normally may notice little beyond the obscured link preview. A system that parses result-page links, classifies domains, or associates positions with landing URLs has more ways to fail.

    • Searchers: Watch for the displayed domain and page label under the result title. The visible destination cue remains available even when the clickable target is routed through Google.
    • SEO teams: Expect possible discontinuities in third-party rank, visibility, competitor, and landing-page reports. An abrupt dashboard change may reflect collection behavior rather than a change to your pages.
    • Rank-tracking providers: A parser that assumes every organic link exposes the publisher’s URL may return a Google URL, an unknown destination, or no recognized result. Tools that resolve the redirect may face a different collection path than tools that only inspect the original markup.
    • SERP scrapers and AI systems: The redirect can create additional friction for systems gathering destinations from Google results. That does not automatically affect an AI crawler visiting your website directly; the two access paths are different.
    • Google Search Console users: The working expectation is that Search Console is not affected by this result-link change, but Google’s public confirmation does not provide an explicit guarantee. Use it as an independent comparison signal, not as proof that every third-party observation is wrong.

    This distinction is especially important for AI visibility reporting. If a platform builds part of its dataset by scraping Google results, its measurements may inherit the redirect problem. A decline in that platform does not establish that your pages became less accessible to ChatGPT, other frontier models, or direct web crawlers. Ask how the vendor collects each reported signal before you combine those signals into one visibility score.

    Audit tracker anomalies before changing the site

    The redirect is being rolled out rather than appearing as a single universal switch. Different providers, locations, and collection environments may encounter it at different points. That makes the shape and timing of the anomaly more useful than one isolated keyword check.

    1. Preserve the last clean comparison. Export the affected dashboard before filters, recalculation, or vendor corrections change the historical view. Record the date you first noticed the discrepancy, the search engine, market, device configuration, project, and affected keyword set.
    2. Localize the break. Check whether the anomaly affects every tracked keyword or only one market, device type, project, or provider. A sitewide overnight gap confined to one tool looks different from a gradual decline concentrated in a group of pages.
    3. Separate position collection from URL resolution. Determine whether the tool lost the result entirely, still reports a position but cannot identify the landing page, or now attributes the result to google.com. Those are different failures and should not be combined into a generic rankings-down label.
    4. Inspect a small set of affected results manually. Confirm that the result is visible, the displayed domain is yours, the click reaches the intended page, and the underlying result link uses the new Google redirect. Manual checks are samples, not a replacement for tracking, but they can expose an obvious collection mismatch.
    5. Compare independent signals by direction, not exact totals. Review Search Console queries, pages, clicks, impressions, and average position around the same period. Search Console and a rank tracker measure search differently, so their numbers need not match. You are looking for a shared break in timing and scope.
    6. Send the provider reproducible evidence. Include the first affected date, search engine, market, device setting, several example queries, the expected destination, the reported destination, and screenshots or exports. Ask whether the goto redirect affects position detection, landing-page resolution, or both.

    Avoid making broad on-page changes while this audit is open. Rewriting titles, altering internal links, replacing schema, and changing canonicals at the same time will create new variables. If the original problem is external data collection, those edits cannot repair it and may make the real diagnosis harder.

    Separate a collection failure from an SEO loss

    A split illustration shows a broken monitoring signal beside an unchanged search position and a working monitor beside a falling result.

    No single metric settles the diagnosis. Use several observations to decide which explanation currently has the strongest support.

    • The result appears manually, the click reaches the right page, and only one tracker loses it: a collection or parsing problem is more plausible than a ranking loss.
    • The tracker still reports a position but loses the landing URL: destination resolution is the leading suspect. Check whether the reported URL is a Google goto address before touching your canonical setup.
    • Several third-party reports change at the same time but share a collection provider: they may not be independent confirmations. Establish whether the products depend on the same underlying data source.
    • Search Console and third-party visibility decline across similar queries and pages: investigate a genuine search-performance problem. The goto redirect alone is not a sufficient explanation for agreement across independent signals.
    • The result is present but the click fails or lands on the wrong page: treat that as a user-facing path problem. Verify your own redirects, final response, and destination separately from the tracker issue.
    • Nothing changed outside the underlying link target: document the rollout and keep monitoring. A technical change in Google’s interface does not require a technical change on your site.

    Be equally careful with competitive reporting. If a tool starts classifying goto URLs as Google domains, domain-level share-of-voice data can become distorted across many sites at once. Before concluding that a competitor gained visibility, check whether the report also shows more unknown URLs, missing domains, or unresolved landing pages.

    Your schema strategy does not need a special markup response. Structured data describes entities and page content on your site; it does not control the outbound link wrapper Google uses on its own search page. Continue validating schema for its intended purpose, but do not use a JSON-LD deployment as a remedy for off-site rank-tracker collection.

    Key takeaways

    • Google can route an organic result through a google.com/goto URL before sending the searcher to the publisher’s page.
    • The redirect is a Google-side link-delivery measure, not a redirect you need to reproduce or counteract on your server.
    • Third-party tools that extract or resolve result URLs have more direct exposure than ordinary searchers or your site’s canonical configuration.
    • A tracker anomaly becomes actionable SEO evidence only when independent signals support the same timing, pages, and queries.
    • Preserve the affected data, classify the failure, compare Search Console directionally, and give your provider reproducible examples before editing the site.

    Add the rollout to your measurement-change log and keep first-party performance signals separate from vendor-collected visibility data. If a discrepancy appears, ask the provider whether it can recognize the result and whether it can resolve the final URL. Those two answers will tell you whether you have a reporting repair to wait for or an SEO problem to investigate.

    Until the evidence points to your site, leave the content, internal links, canonicals, redirects, and structured data alone. The safest next move is a cleaner diagnosis, not a larger deployment.

    References


  • Google Discover Mechanics: How Content Gets Chosen and Amplified

    Google Discover Mechanics: How Content Gets Chosen and Amplified

    If one story surges in Google Discover while the next one disappears, it is tempting to blame timing, the headline, or luck. That diagnosis is usually too blunt. A page can miss the candidate pool, win attention but lose engagement, or satisfy readers yet reach too few people because the system has weak evidence that this audience and your publication belong together.

    The useful shift is to treat Discover as a recommendation funnel with distinct jobs. Once you separate candidate retrieval, user-content prediction, final ranking, and learned affinity, you can identify the weak transition and work on the right problem.

    Discover is a four-part recommendation system

    A four-stage abstract machine selects, matches, ranks, and distributes content cards to groups of readers.

    Google groups Discover ranking work around retrieval, prediction, ranking, and embedding. These are not four optimization factors or a checklist for publishers. They are four technical jobs within a recommendation system:

    1. Retrieval assembles a set of articles, videos, and other items that might suit the user.
    2. Embeddings represent users and content in a form that allows the system to estimate similarity or relevance.
    3. Prediction estimates what may happen if a particular card is shown to a particular user.
    4. Ranking resolves the competing candidates into the feed the user actually receives.

    The jobs interact rather than forming one simple, publicly documented sequence. Embeddings can support retrieval as well as prediction, and ranking can use information that publishers cannot observe. The model is still valuable because it stops you from treating every distribution problem as a headline problem.

    Retrieval is especially easy to overlook. You cannot rank well inside a candidate set you never entered. Across 42 million monitored cards, about 20 candidate pipelines have been mapped, including candidate sampling, cluster-profile retrieval, trend-embedding retrieval, item-to-item collaborative filtering, and a post-retrieval pipeline heavily populated by YouTube and X content. The labels expose multiple routes into Discover, although they do not disclose the precise rule set behind each route.

    A channel labeled as generative retrieval also appeared in September 2025 in roughly 0.03% of the French Discover feed. That tiny footprint is consistent with a limited test of model-driven candidate selection, not evidence that generative retrieval has replaced the broader system.

    Observed user representations add another clue. Their names cover durable Discover interests, a short-term interest variant, trends, real-time behavior, and shopping-related behavior. This is consistent with a two-tower design in which user and content representations are compared in a shared vector space. The visible labels are real observations; the exact architecture and purpose of each representation remain interpretations rather than confirmed Google documentation.

    Your practical response is to add an audience-state map to your keyword and topic planning. Before approving a Discover-oriented pitch, record:

    • The intended reader: Name the person and existing interest the story serves. A broad demographic is less useful than a recognizable need or content habit.
    • The time horizon: Decide whether the story serves an enduring interest, a developing trend, or an immediate event. Do not judge all three by the same distribution pattern.
    • The relationship to previous coverage: Identify whether the story begins a subject, extends a cluster, or follows an item readers already encountered.
    • The next useful item: Plan what a satisfied reader would reasonably want from your publication after finishing this page.

    None of those fields forces retrieval. They make your publishing intent coherent enough to evaluate. If your team cannot explain who a story is for, why it matters at that moment, or how it relates to your established coverage, changing a few keywords is unlikely to solve the underlying recommendation mismatch.

    Attention and deep engagement are separate predictions

    Discover does not appear to reduce content quality to one universal score. About nine observed prediction values collapse into two nearly independent dimensions: whether a person is likely to stop on a card, and whether that particular person is likely to click and read deeply.

    The correlation between those dimensions is close to zero. A card can be highly effective at interrupting the scroll while being a poor match for sustained reading. That is the mechanical form of clickbait: the promise wins attention, but the experience does not hold it.

    The predictions also correspond with observed behavior. Interaction roughly doubled from the bottom to the top of the deep-engagement score range and declined as the predicted likelihood of scrolling past increased. These measurements do not reveal every ranking input, but they are strong enough to justify separating your own attention and engagement diagnostics.

    Diagnostic layerQuestion to answerPublisher evidence to inspectWhat to change if it is weak
    AttentionDid the card make the right person stop and click?Impression-to-click response, segmented by topic and audience where possibleTest the headline, visual, and topic framing while preserving an accurate promise
    Deep engagementDid the landing experience hold the reader?Engaged time, meaningful scroll, completion, related-content actions, and return behaviorImprove audience fit, opening clarity, structure, depth, and promise fulfillment
    UsefulnessDid the content deliver a result worth the reader’s time?Task completion, use of relevant tools or links, saves, qualified follow-on actions, and direct feedbackAnswer the real question sooner, remove padding, support decisions, and make the next step explicit

    Those publisher metrics are diagnostic proxies, not a list of disclosed Google ranking inputs. An increase in engaged time, for example, does not prove that one metric directly caused more Discover distribution. The purpose of the table is to locate the leak in your own experience before you prescribe a fix.

    If impressions are meaningful but card response is weak, examine attention and candidate-to-reader fit. If clicks are healthy but readers leave quickly, the problem is downstream: the audience may be wrong, the opening may delay the payoff, or the content may not fulfill the card’s promise. If both look healthy but amplification remains limited, a more aggressive title is not the obvious next move. Retrieval, reader-source affinity, and usefulness still need investigation.

    This distinction should change how you run headline tests. Evaluate the card response and the post-click session together. A variation that increases clicks while reducing reading depth may have widened the promise-content gap rather than improving the story’s overall Discover potential.

    Reader-source affinity can outweigh topic potential

    A reader has a strong glowing connection to one familiar content source while weaker paths lead to other topic cards.

    Topic relevance gets a page into the conversation, but personalization can determine how loudly it is heard. Reader-source affinity is the learned relationship between a specific person and a specific publisher. It is not identical to general popularity, topical relevance, or the number of people who pressed Follow.

    A small comparison involving two French sports publishers with nearly equal topic potential illustrates the possible size of that effect. The publisher with deep-engagement predictions about twice as high received amplification on the order of eight times as strong. It also had fewer explicit follows among the test accounts, making raw Follow counts an inadequate explanation for the difference.

    A separate test within one technology publisher found deep-engagement predictions nearly twice as high for accounts that followed the publisher. A United States comparison between ESPN and NFL.com produced a smaller amplification gap of 1.28 times. These were small samples, so none of the figures should become a traffic forecast or universal benchmark. They do support a narrower operational conclusion: learned affinity can materially change distribution even when topic potential is similar, and Follow appears to be one contributing signal rather than a guaranteed reach switch.

    You cannot manufacture reader-source affinity with a metadata field. You can, however, make your publication easier for readers and recommendation systems to understand:

    • Define a repeatable audience contract. Complete this sentence for each content line: We publish this coverage for this reader at this moment so they can achieve this outcome. If the ending changes radically from one story to the next, the content line may be too diffuse.
    • Build continuity, not isolated hits. Connect breaking stories to explainers, updates, recurring series, and logical follow-ups. Item-to-item retrieval and learned source relationships both make continuity more strategically useful than a pile of unrelated traffic bets.
    • Protect expectation accuracy. A headline can attract a broad audience that the body was never designed to serve. That may improve the attention layer while weakening evidence of a durable user-source fit.
    • Use Follow as reinforcement. Invite readers to follow when you can name the continuing benefit they will receive. Treat the action as an affinity input, not a promise that every follower will see every story.
    • Analyze cohorts rather than article averages. Compare returning readers with unfamiliar readers, and compare established coverage areas with occasional topics. A single sitewide average can hide the audience-source combinations that consistently work.

    This does not mean your publication must stay inside one narrow subject forever. It means expansion should have a reader bridge. When you enter an adjacent topic, explain why it matters to the audience you already serve and create enough connected coverage to establish a recognizable promise. A one-off article aimed at an unrelated trend may earn attention without building the relationship that supports future distribution.

    A practical Google Discover diagnosis FAQ

    Why did a strong page receive almost no Discover distribution?

    First distinguish low exposure from low response. If the page received few meaningful impressions, you do not yet have a clean headline test; the card had too little opportunity to win attention. Examine whether the story matches a known audience interest, whether its timing fits an enduring or short-term need, and whether it belongs to a recognizable coverage cluster. Because Discover is personalized, absence from one person’s feed is not proof that the page failed retrieval everywhere.

    Why did impressions increase while clicks stayed weak?

    The page may have entered a candidate pool but failed to earn attention, or it may have been retrieved for people who were not a good fit. Segment the response by topic, reader cohort, and content line before rewriting the title. Then test card packaging that clarifies the subject and payoff without making the promise broader than the page.

    Why did clicks rise while reading depth fell?

    You likely improved the attention layer without improving the user-content match. Compare the card’s promise with the first screen and the page’s actual depth. Put the central answer or development earlier, remove generic setup, and ensure the rest of the page delivers what caused the click. Continue tracking post-click behavior during packaging tests so a higher click rate does not disguise a weaker experience.

    Does asking readers to Follow improve Discover reach?

    Follow can contribute to affinity, but it does not guarantee distribution. The strongest time to ask is when a reader has just received value and you can state what future coverage will continue that value. A generic request adds less strategic clarity than an invitation tied to a recurring subject, update cycle, or series.

    For your next Discover review, build one funnel view: meaningful exposure, card response, post-click depth, and the difference between returning and unfamiliar readers. Fix the first weak transition instead of blending retrieval, packaging, content quality, and audience strategy into one vague Discover problem.

    References


  • How to Earn AI Search Citations and Measure Source Visibility

    How to Earn AI Search Citations and Measure Source Visibility

    You can rank for a query, appear somewhere in an AI-generated answer, and still lose the citation to another site. The system may name your brand without linking to you, cite a competing page, or display your link without sending a measurable visit.

    If you want to improve that outcome, stop treating AI visibility as one metric. You need a page that can be retrieved, an answer passage that can stand on its own, a defensible reason to select your URL, and a measurement process that separates citations from mentions and clicks.

    Separate citations, mentions, and visits before optimizing

    Teams often report that they appeared in AI search without recording what actually appeared. That makes the next content decision guesswork. For practical measurement, use three distinct working definitions.

    SignalWhat you observedWhat it does not prove
    CitationThe answer identifies or links to a page on your domain as support.That the user clicked, read, or converted.
    Brand mentionThe answer names your company, product, author, or other entity.That an owned page received attribution.
    VisitA user reached your site after interacting with an AI search experience.That every preceding citation was visible or measurable.

    A citation is usually the right primary outcome for publishers and information-led SEO because it exposes the supporting page. A mention can still strengthen brand visibility, but it does not give the reader a route to inspect your evidence. A visit is the commercial opportunity, yet it sits one step later and depends on whether the link gives the reader a reason to leave the generated answer.

    Set the goal at the page level. A definition page may be successful when it earns repeated citations. A product page may need qualified visits rather than broad mentions. A developing-topic page may need visibility in a prominent link module while attention is concentrated on the event. Do not combine these outcomes into a single AI visibility score unless the underlying signals remain available separately.

    Build answer passages that survive extraction

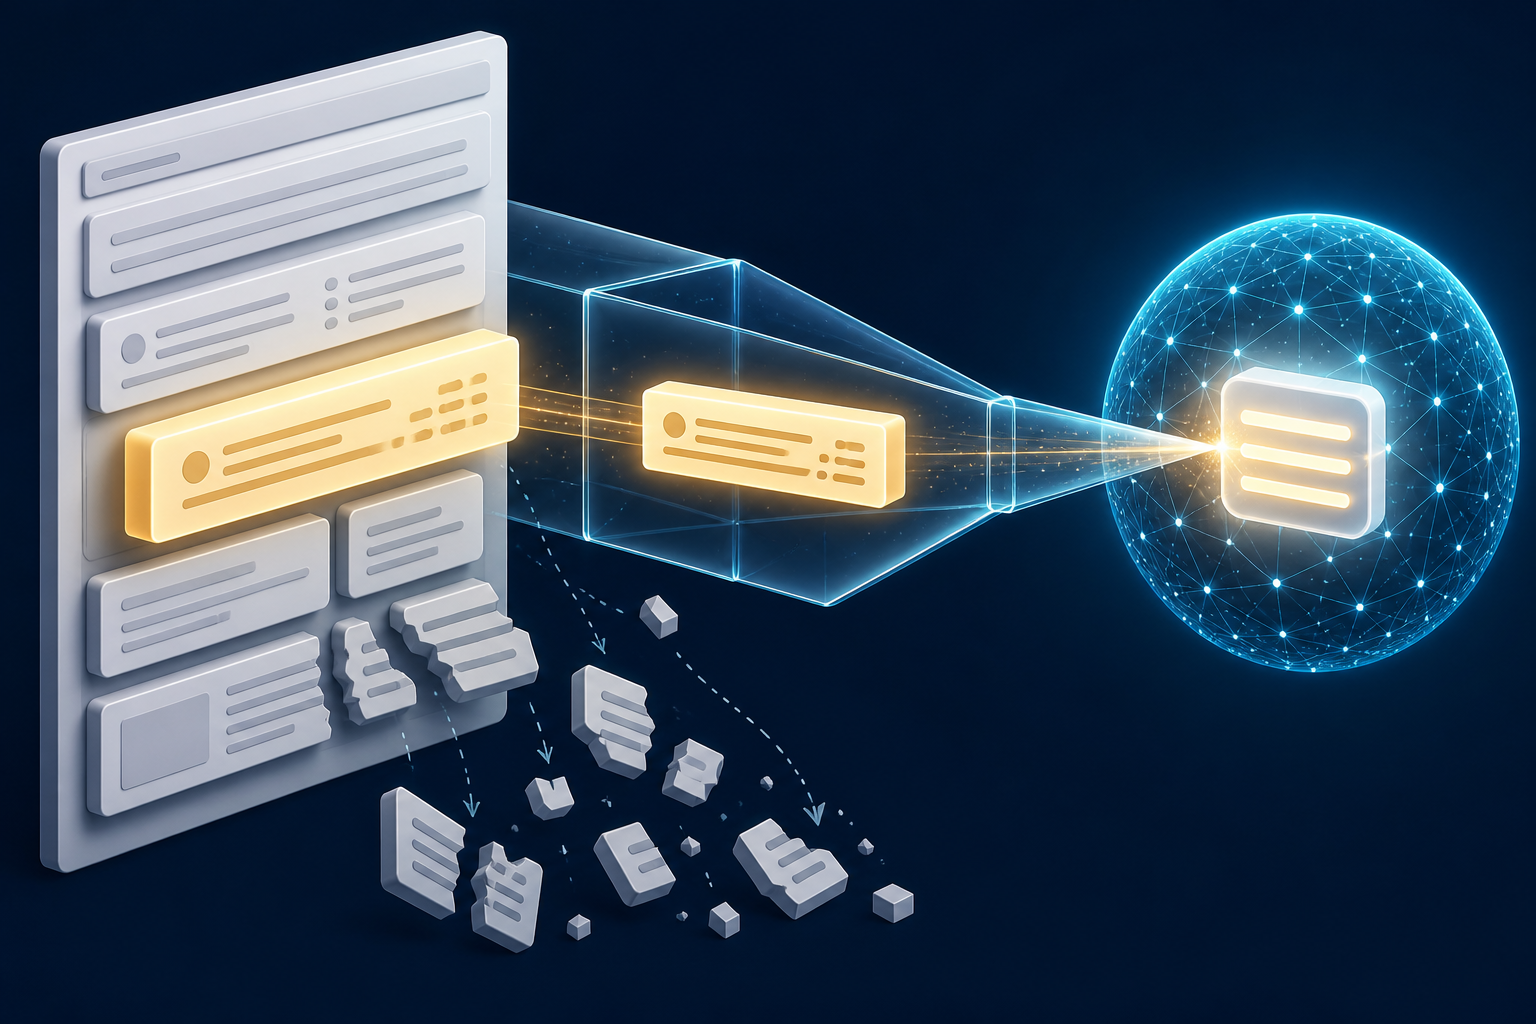
    One intact content block moves from an abstract web page through a transparent funnel toward a glowing sphere while fragmented blocks fall away.

    A polished draft is not necessarily a citable draft. The more useful standard is whether the page contains a citation-ready answer that remains accurate when lifted out of its surrounding introduction.

    Treat the passage, not the word count, as your basic unit of work. Each important query should map to a bounded section with a descriptive heading. The opening sentence should resolve the question directly. The following sentences should carry the qualification, evidence, and consequence needed to prevent the answer from becoming misleading.

    Use a four-part answer block

    1. Answer: State the conclusion in the first sentence. Do not make the reader cross an anecdote, mission statement, or definition they already know.
    2. Boundary: Name the situation in which the answer applies. Keep material qualifiers in the same paragraph as the claim they limit.
    3. Support: Explain the mechanism or attach the relevant evidence. Link factual claims to their originating evidence rather than to a page that merely repeats them.
    4. Next step: Give the reader useful depth that the short answer cannot contain, such as implementation steps, decision criteria, exceptions, or a worked example.

    Consider the difference between these two passages:

    Weak: AI visibility is changing quickly, so brands need a comprehensive strategy that improves their presence across emerging platforms.

    Citable: An AI search citation identifies a supporting page or domain inside a generated answer. A brand mention without an owned link is visibility, but not citation visibility. Track the two separately so a rise in mentions does not hide a decline in attributed pages.

    The second version makes a bounded claim, defines the distinction, and tells the reader what to do with it. It does not need promotional language to sound authoritative.

    Create a claim ledger before expanding the page

    For every section you expect to earn citations, record the following fields in your content brief:

    • The exact question the section answers.
    • The answer in one plain sentence.
    • The qualifier that would make the sentence inaccurate if omitted.
    • The evidence that supports the claim.
    • The contribution that is original to your page.
    • The person responsible for checking whether the answer is still current.

    This ledger catches a common failure before publication: a section sounds complete but has no supportable claim. It also prevents an editor from separating a caveat from the sentence it qualifies. If you cannot fill the evidence field, rewrite the statement as analysis, label the uncertainty, or remove it.

    Run a final extractability pass after the normal edit. Replace vague pronouns with named entities where context could be lost. Remove unsupported superlatives. Use one term consistently for the same concept. Keep the evidence link next to the claim it supports. Make each heading specific enough that a reader can predict the answer below it.

    Give AI systems a defensible reason to select your page

    Clear formatting makes content easier to reuse, but clarity alone does not make your URL preferable. If your page is an interchangeable paraphrase of information already available elsewhere, formatting only makes the duplication easier to see.

    Strengthen the page with a contribution that another answer can reasonably attribute to you. That contribution might be first-party data with a disclosed method, original documentation, a comparison built from explicit criteria, a verified chronology, or analysis that shows its reasoning. Do not manufacture novelty by renaming a familiar idea or presenting an unsourced opinion as a finding.

    For evergreen questions, optimize the decision

    An evergreen page should do more than provide a dictionary answer. After the direct response, help the reader choose, implement, diagnose, or verify something. State the criteria that change the recommendation. Include exceptions where they materially affect the outcome. Keep the page on a stable URL so references, internal links, and structured data continue to identify the same resource.

    A useful test is to remove your brand name from the draft and compare the remaining value with a generic summary. If nothing distinctive remains, add evidence or decision support before adding more prose.

    For developing topics, make the update verifiable

    Google has introduced AI Mode link carousels for developing topics. These modules can place relevant pages, including a user’s Preferred Sources, prominently in the result. Google frames the feature around connecting people with original coverage and a range of perspectives.

    That creates a specific opportunity for publishers covering active events, but only when the page makes its contribution easy to verify. Put the material change near the top. Separate confirmed facts from interpretation. Identify what remains unknown. Link claims to the originating evidence. Show readers when the page was updated, and do not silently replace an earlier conclusion without explaining what changed.

    A prominent carousel may make links easier to notice and click, but it does not justify forecasting the click-through rates you received before AI-generated search experiences. Give the reader a reason to continue: the underlying evidence, a complete timeline, a tool, detailed methodology, or analysis that cannot fit inside the generated answer.

    Make the page retrievable, stable, and unambiguous

    Content cannot earn a reliable citation if the system cannot retrieve the useful version or determine which URL represents it. Run a technical pass after the claim-level edit.

    • Accessibility: Keep the substantive answer available in the page’s rendered content. Do not require a form submission, account, tab interaction, or client-side event merely to reveal the core response.
    • Indexability: Check that robots rules and page-level directives do not exclude the URL from the search systems you expect to surface it.
    • Canonical consistency: Use one preferred URL across canonical signals, internal links, sitemaps, and structured data. Consolidate accidental duplicates rather than asking systems to choose among them.
    • Information structure: Give the page a descriptive title, question-aligned headings, and internal links from relevant pages. The hierarchy should reveal the main answer and its supporting sections without relying on visual styling.
    • Entity consistency: Use the same names for your organization, product, person, and core concepts in visible copy, metadata, and structured data.
    • Maintenance: Preserve the URL when the underlying resource remains the same. When the facts change, update the answer, its evidence, and any visible freshness information together.

    Use JSON-LD to clarify, not to manufacture authority

    Structured data can describe what a page represents and connect it with relevant entities. It cannot force an AI system to cite the URL, turn an unsupported assertion into evidence, or compensate for an answer buried in vague copy.

    Add markup only for information supported by the visible page. Make sure the structured entity uses the same preferred name and canonical URL as the rest of the site. If the markup describes a different page purpose, organization name, or content relationship than the reader sees, correct the inconsistency instead of adding more properties.

    Then perform two separate checks. First, read the rendered page as if you had landed directly on the relevant heading: can you identify the answer, boundary, and evidence without reconstructing missing context? Second, validate the structured data on its own terms. Passing the second check does not excuse failing the first.

    Measure source visibility with a prompt-level scorecard

    A seated researcher examines a glowing matrix of blank tiles and colored visual markers on a large analysis display.

    AI answers can vary with prompt wording, search surface, location, session context, and observation time. A screenshot from one query can prove that a citation occurred, but it cannot show how consistently your domain appears. Build a repeatable prompt set around real audience intents and keep the exact wording available for later observations.

    Include question types that expose different citation opportunities: definitions, procedures, comparisons, verification questions, and developing-topic queries where they fit your business. Do not insert your brand into every prompt. A branded prompt measures retrieval of a known entity; it does not tell you whether the brand is discoverable in an unbranded answer.

    Record the evidence behind every visibility claim

    • The exact prompt and the intent it represents.
    • The AI search surface and relevant session conditions.
    • The time of the observation.
    • Whether the brand appeared.
    • Whether an owned URL was cited.
    • The linked page and the claim it supported.
    • Whether the link appeared inline, in a citation area, or in a carousel.
    • Which competing domains were cited for the same answer.
    • Any identifiable landing-page visit or downstream conversion.

    From that record, calculate separate directional metrics. Citation presence is the share of observations containing an owned citation. Citation coverage is the share of monitored prompt families in which the domain appears at all. The mention-to-citation gap counts observations that name the brand but provide no owned link. Landing-page concentration shows whether visibility depends on one URL or is distributed across the site.

    Keep those metrics distinct from traffic. Google does not provide clean AI Mode click reporting through Search Console’s generative AI reporting, so an absent click record does not prove that no citation appeared. Conversely, a visible citation does not prove that a visit occurred. Use Search Console and analytics for the signals they expose, then retain your prompt observations as a separate evidence set.

    When you change a page, keep the monitored prompt set stable, log what changed, and repeat the observations after the updated page has had a chance to be rediscovered. Change a bounded element such as the answer block, evidence structure, or page consolidation before rewriting everything at once. Treat movement as directional unless it persists across repeated observations; generated results are too variable for a single before-and-after response to establish causation.

    Key takeaways

    • Measure citations, brand mentions, and visits separately because each proves a different outcome.
    • Write claim-level answer blocks with the conclusion, boundary, support, and useful next step kept together.
    • Give the page an attributable contribution instead of publishing an interchangeable summary.
    • Treat developing-topic visibility as a freshness and verification task, especially where AI Mode displays link carousels.
    • Use JSON-LD to reinforce visible meaning and entity relationships, not as a substitute for evidence.
    • Track exact prompts and cited URLs over repeated observations; do not infer source visibility from incomplete click data alone.

    Start with one commercially or editorially important page that should be cited but is not. Build its claim ledger, rewrite the main answer block, verify retrieval and canonical signals, and record a prompt-level baseline. That turns a vague visibility problem into a controlled content, technical, and measurement task.

    References


  • How to Build SEO Content Across the Conversion Funnel

    How to Build SEO Content Across the Conversion Funnel

    Your SEO pages rank and organic sessions rise, but visits to product, pricing, or service pages stay flat. Publishing more content under the same model will make the traffic chart look better without fixing the business result. The missing piece is usually not another keyword. It is a useful next step.

    Semrush estimated that about 68% of traditional searches end without a click. When you do earn a visit, the page has to answer the immediate question and help the reader make the next decision. That is what turns SEO content from a collection of entrances into a conversion system.

    Build the funnel around the reader’s next decision

    Top-of-funnel, middle-of-funnel, and bottom-of-funnel labels are useful, but they are not intent by themselves. A broad query can come from an experienced buyer confirming terminology. A branded query can come from someone who has only just discovered the category. AI-mediated discovery has also contributed to more branded and direct traffic, fewer conventional search entrances, and visitors arriving at different funnel stages.

    Assign a page to a funnel stage by the decision it helps the reader make, not by a keyword modifier such as what, best, or versus. The practical question is: what remains unresolved when this person arrives?

    Reader stateQuestion to resolveContent jobUseful next step
    Discovering or diagnosingWhat is happening, and does it matter to me?Define the problem, establish its boundaries, and help the reader recognize whether it appliesA diagnostic, practical checklist, deeper implementation page, or relevant tool
    Exploring solutionsWhat approaches could solve this?Explain options, tradeoffs, requirements, and selection criteriaA comparison, use-case page, service page, or product capability
    Validating a choiceWill this option work under my constraints?Resolve objections around fit, process, effort, risk, and expected handoffPricing, implementation details, trial information, or a demo
    Ready to actWhat happens if I start?Make the offer, requirements, and next action unambiguousA focused form, trial, purchase path, or scheduled conversation

    Write the conversion path before you write the outline. A useful content brief should answer the following questions in order:

    1. Who is arriving? Name the role, situation, constraints, and level of knowledge. Use language from sales conversations, support questions, reviews, and customer interviews rather than relying only on keyword tools.
    2. What must the page resolve? State one decision the reader should be better equipped to make after reading.
    3. What would make the answer credible? Identify the explanation, evidence, example, comparison, or process detail needed to remove uncertainty.
    4. What should happen next? Choose the smallest sensible action that advances the reader without demanding a commitment the page has not earned.
    5. How will you observe progress? Define the primary action and the supporting signals before publication.

    If you cannot name the next decision, the page is not ready for production. It may still rank, but you will have no defensible reason to expect it to move anyone through the funnel.

    Give every page one primary job and several useful exits

    An SEO brief often stops after the target query, search intent, headings, and internal-link suggestions. Add a page contract: the specific value the page must deliver, the primary next action it supports, and the alternative route for readers who arrive earlier or later than expected.

    The page should satisfy five conditions:

    • Answer: Give the reader a direct response near the top. Do not make them work through a generic preamble to confirm that they are in the right place.
    • Advance: Add information that improves a decision, such as criteria, tradeoffs, limitations, prerequisites, or a concrete process.
    • Prove: Support important claims with evidence appropriate to the decision. A commercial claim needs more than polished wording.
    • Route: Link to the resource that resolves the next question. The destination should continue the same line of thought instead of dropping the reader on a generic homepage.
    • Convert: Present a commitment-level action only when the page has supplied enough context to make it reasonable.

    The primary call to action should match the reader’s likely readiness. An educational page might offer an implementation checklist or diagnostic. A solution-exploration page might link to a comparison or use case. A decision page can reasonably offer pricing, a trial, or a demo. Sending every reader straight to Contact us is not a funnel strategy; it is a refusal to account for intent.

    Add a secondary route when the audience can plausibly arrive in more than one state. Someone who is not yet ready for a demo may still want to see the evaluation criteria. Someone already familiar with the category should not have to read an introductory guide before finding pricing or implementation requirements.

    Structure matters because readers do not need to consume every word before acting. Use descriptive headings, a short answer near the opening, lists for criteria, and tables only when they clarify real comparisons. Place the CTA after the section that creates readiness, then repeat the primary action near the end. A reader should be able to scan the page and still understand the problem, the decision, and the next step.

    Friction is not limited to slow forms. Jargon, inflated language, vague link labels, buried requirements, and a CTA that appears before its value is clear all interrupt progress. Clear CTAs, scannable structure, and simpler forms help the reader act without searching the page for instructions.

    Decide where top-of-funnel content still earns its budget

    The decline of informational clicks does not justify deleting top-of-funnel content or moving the entire budget to commercial keywords. The pressure is not distributed evenly, and changing the funnel label does not necessarily change the outcome.

    In a directional sample of 30 major publishers across nine industries, top- and middle-of-funnel traffic moved in the same direction within every reviewed industry. Every sampled finance, healthcare, legal, and consumer-tech publisher lost top-of-funnel traffic, while every sampled cybersecurity and marketing or sales software domain improved; cloud infrastructure was collectively positive. Because the comparison used third-party estimates and rough keyword and URL groupings, treat the pattern as directional rather than a universal forecast.

    The operational lesson is sharper than simply write less TOFU. Industry, audience behavior, decision complexity, and the usefulness of the page can matter more than the nominal funnel stage. Moving a weak YMYL strategy from definitions to best-of lists will not automatically escape the same search environment. In B2B technology, a buyer evaluating a costly migration, security platform, or infrastructure decision may still need current detail and deeper expertise than a short generated answer can provide.

    Before commissioning an informational page, require a clear answer to each of these tests:

    • Click necessity: Does the question require nuance, implementation detail, current information, an interactive tool, or local knowledge that cannot be usefully compressed into a short answer?
    • Commercial adjacency: Does solving this question naturally create a later question your product, service, or expertise can answer?
    • Differentiated value: Can you contribute a process, framework, example, decision aid, or point of view beyond a generic definition?
    • Journey fit: Is there a credible next page for the reader, and does that destination continue the problem introduced here?
    • Maintenance ownership: Can someone keep the page accurate as the subject changes?

    Local content and interactive tools deserve particular attention because they can create a reason to visit rather than merely a reason to read a summary. Local queries have shown more consistent traffic, while digital tools remain a promising TOFU format. The useful distinction is not article versus tool. It is replaceable answer versus experience that helps the reader do something.

    Do not evaluate an informational page on raw sessions alone, and do not remove it solely because clicks declined. Check whether it contributes qualified onward visits, return visits, branded demand, assisted conversions, links, or visibility around an important category. If it has no meaningful audience, no distinctive value, and no route into the rest of the journey, then consolidating, redirecting, or retiring it may be justified. Review any existing links and destinations before changing the URL so you do not discard value accidentally.

    Connect pages into a journey instead of a content archive

    A visitor travels across illuminated bridges connecting discovery, comparison, product, and consultation rooms.

    A funnel does not require readers to follow a rigid sequence. People leave, return through branded search, ask an AI assistant, compare alternatives, and share pages internally. Your job is to make the next useful move available whenever they arrive.

    Start with a URL-level journey audit:

    1. Inventory meaningful landing pages. For each URL, record the target audience, unresolved question, likely reader state, primary CTA, intended destination, and measurable action.
    2. Find dead ends. Flag pages that receive relevant entrances but offer no contextual onward path, pages whose CTA does not match their intent, and destinations that do not continue the promise.
    3. Choose the immediate successor. Link to the page that answers the next question, not merely the page with the greatest commercial value.
    4. Make the bridge explicit. Tell the reader why the next resource matters. Descriptive language such as Compare the implementation approaches communicates more than Learn more.
    5. Preserve alternate paths. Give advanced readers a route to commercial detail and earlier-stage readers a route to definitions or criteria without making either group backtrack.
    6. Check destination continuity. Reuse the relevant vocabulary and carry the same problem into the destination. A sudden change of audience, promise, or terminology makes even a technically correct link feel wrong.

    Consider a reader who lands on a page explaining generative engine optimization. The next decision may be whether their current visibility can be measured, so an audit checklist or measurement framework is a natural bridge. That resource can lead to an evaluation page covering methods or solution requirements. Only after the reader understands the gap and the available approach does a product, service, or demo page become the obvious destination.

    The sequence works because each page closes one information gap and opens the next relevant one. It does not withhold the answer or manufacture anxiety. It makes progress easier.

    Apply the same continuity inside the page. The opening should confirm the problem. The middle should provide the answer and decision criteria. A contextual CTA should appear where the reader is likely to ask what to do with that information. The ending should state the next action plainly and offer a lower-commitment alternative when appropriate.

    Measure movement, then test the point of friction

    A strategist uses a transparent lens to inspect a bottleneck where glowing spheres pause along a pathway.

    Traffic is a diagnostic measure. It tells you that a page attracted attention, not that it helped the business. Give every important page one progression metric and connect that metric to a later outcome.

    • Search capture: impressions, click-through rate, and relevant organic entrances show whether the page is being discovered by the intended audience.
    • Page progression: contextual CTA clicks, qualified internal-link clicks, and movement to the intended destination show whether the page creates a next step.
    • Journey progression: return visits, branded searches, and later visits to product, service, or pricing pages show whether interest is developing across sessions.
    • Business outcome: trials, demo requests, purchases, qualified leads, and sales outcomes show whether that movement eventually creates value.

    A discovery page should not be judged by the same immediate conversion rate as a pricing page. Its primary measure may be qualified onward movement, with assisted conversion as the downstream check. A decision page should carry a much closer outcome. Return visitors, branded search growth, assisted conversions in GA4, and organic leads reported by sales are useful signs that SEO is influencing more than the first click.

    Diagnose the break before changing the page:

    • Strong impressions but weak click-through: check whether the title and search appearance promise what the query actually needs.
    • Relevant entrances but immediate abandonment: check whether the opening answers the query, identifies the intended reader, and matches the promise that earned the click.
    • Reading or scrolling without CTA clicks: check the relevance, wording, visibility, and timing of the next step.
    • Onward clicks without final conversions: inspect the destination page, offer clarity, proof, form burden, and continuity. The landing content may be doing its job while the next page fails.
    • Conversions that sales rejects: revisit audience targeting, qualification language, and the expectations created before the form.

    Once you have a specific diagnosis, test one meaningful variable at a time: CTA promise, placement, page structure, proof, destination, or form requirement. Write the hypothesis and primary outcome before launching the test. Keep diagnostic measures alongside the main outcome so a higher click rate does not hide a drop in lead quality or completed conversions.

    Key takeaways

    • Assign funnel stages by the reader’s unresolved decision, not by keyword modifiers alone.
    • Define the next action and its destination before outlining the page.
    • Match CTA commitment to the context the page has earned, while preserving routes for earlier- and later-stage readers.
    • Fund top-of-funnel content when it offers depth, utility, local relevance, or a credible route to a commercial problem.
    • Measure progression from search entrance to onward action, assisted journey, and business outcome.
    • Test the diagnosed point of friction instead of rewriting a page merely because traffic did not convert.

    Start with the pages that already attract relevant visitors or sit closest to a meaningful conversion. Choose one obvious dead end, write down the reader’s next decision, add the right bridge, verify the destination, and instrument the action. Once that connection works, extend the same logic across the rest of the journey.

    References


  • Google Ads AI Transparency: A Practical Audit Framework

    Google Ads AI Transparency: A Practical Audit Framework

    When Google Ads can rewrite the product title a shopper sees, knowing what you entered in Merchant Center is no longer enough. And when an AI coding assistant can generate integrations, troubleshoot failures, and query a live advertising account, working code is no longer sufficient proof that the work is correct.

    You need an evidence chain: what the AI changed, what rules or schema supported the change, what actually ran or served, and what happened afterward. Two Google Ads developments make that easier: reporting for AI-generated Shopping titles and a schema-aware Google Ads API assistant. Used carefully, they let you audit automation without giving up its speed.

    Treat Google Ads AI as two separate control problems

    Google Ads AI acts at more than one point in the advertising workflow. The control you need depends on where the automation operates.

    AI layerWhat can changeEvidence availableYour control decision
    Ad deliveryThe product title presented in a Shopping adOriginal and customized titles plus impressions, product clicks, CTR, cost, and average CPCDetermine whether the generated wording preserves product identity and attracts useful traffic
    API developmentIntegration code, GAQL queries, diagnostics, and reporting workflowsGoogle Ads-specific rules, GAQL validation, Protobuf schema inspection, and live query resultsDetermine whether the implementation is valid for the intended API version, account, and business question

    The first layer is a message-governance problem. The second is a software-governance problem. Combining them under a vague instruction to “monitor the AI” produces weak reviews because the artifacts, risks, and owners are different.

    Use the same principle for both: never approve an AI output without identifying the input, the transformation, and the observed result. A generated title is an output. So is a valid GAQL query. Neither tells you by itself whether the outcome serves your commercial intent.

    Audit the product title shoppers actually see

    A magnifying glass compares a source product record with an AI-processed shopping listing shown on a smartphone.

    Google AI can create a customized product title and serve it when it considers that version more relevant than the advertiser-provided title. The original remains eligible to appear when Google considers it more relevant. The practical consequence is simple: your feed title is an input to ad delivery, not a guarantee of the final wording.

    The Product titles report is beginning to appear in Google Ads, so availability may not be uniform across every account. Where it is available, it can place the original and AI-customized titles beside delivery and traffic metrics. That gives you something much more useful than a general notice that automation may alter copy: it gives you inspectable examples.

    Review meaning before performance

    Start by checking whether the generated title still identifies the product accurately. A higher CTR cannot repair a title that creates the wrong expectation.

    1. Compare the identifying details. Check whether the generated wording preserves the brand, model, product type, variant, size, material, compatibility, or other detail a buyer needs to distinguish the item.
    2. Look for a change in promise. Flag wording that implies a feature, bundle, use case, audience, or level of compatibility that the product page does not support.
    3. Check brand and legal sensitivity. Route regulated claims, trademarks, guarantees, and tightly controlled brand language to the appropriate reviewer before treating the title as acceptable.
    4. Inspect the landing-page match. A title may be technically accurate but still emphasize something the landing page does not make easy to find. That mismatch can attract a click while weakening the visit.
    5. Classify the change. Record whether the generated title clarifies the product, rearranges existing details, introduces a new interpretation, or removes a distinguishing detail. This turns isolated examples into patterns you can act on.

    When generated titles repeatedly clarify information that was buried or absent in your originals, treat that as a feed-quality hypothesis. Do not merely admire the AI version. Ask whether the original titles should communicate the same useful distinction more directly.

    Read the metrics as observation, not a controlled test

    The report can include impressions, product clicks, CTR, cost, and average CPC. Those measures answer different questions:

    • Impressions show how much exposure a title received. A dramatic-looking CTR difference attached to limited exposure deserves caution.
    • Product clicks show traffic volume, but not whether those visitors produced valuable outcomes.
    • CTR describes the rate at which impressions produced clicks. It can help you spot wording that attracts attention, but it does not establish why the difference occurred.
    • Cost and average CPC show the price of the traffic. They do not, by themselves, establish revenue, margin, lead quality, or profitability.

    Do not label this comparison an A/B test unless you have a genuinely controlled experimental design. Google may select an original or customized title because it considers one more relevant in a particular serving context. Different contexts can therefore influence both which title appears and how it performs. The report reveals an association between a served title and its results; it does not automatically isolate the title as the cause.

    Your decision should combine three checks: semantic accuracy, sufficient exposure, and downstream business value from your existing measurement setup. A title that earns more clicks but brings poorly matched visitors is not an improvement.

    Make the API assistant prove technical validity

    Google Ads API Developer Assistant v4.0.0 moves from the earlier standalone local-workspace structure to a globally available plugin architecture. It can supply Google Ads-specific rules, skills, and diagnostic commands across projects. The architecture is not compatible with previous releases, so adopting version 4 should be treated as a migration rather than a routine in-place update.

    The assistant supports AI coding workflows in Antigravity and Claude Code. It can generate integration code for Python, Java, PHP, .NET, and Ruby. More importantly for reliability, it can inspect local Protobuf schemas and client-library code instead of depending entirely on what the underlying model remembers about Google Ads.

    That grounding is most useful when you require it as part of the workflow. Use this review sequence:

    1. Identify the intended API version. Record it with the task so a reviewer can distinguish current fields and enums from suggestions that belong to another version.
    2. Inspect the relevant schema before accepting generated code. Confirm resource names, available fields, data types, and enum values against the active version.
    3. Validate every GAQL query before execution. The local validator can check syntax, field compatibility, date segmentation, resources, metrics, date clauses, and zero-impression rules in one pass.
    4. Review account and time context. Before a natural-language request runs against live data, verify the customer ID, manager-account relationship where relevant, date range, segments, metrics, and expected level of aggregation.
    5. Read the generated code as code. Schema validity does not replace review of authentication, account selection, data handling, error paths, and whether the integration performs only the operations you intended.
    6. Save a reproducible result. The assistant can return live results as a formatted table and can save ad hoc reporting output as CSV. Preserve the validated query with the output so another person can reproduce what was retrieved.

    This approach is faster than asking a general-purpose model to guess at a broken query over multiple attempts. It is also safer because the query is checked against Google Ads-specific constraints before it reaches the account.

    Use conversational troubleshooting as triage

    The assistant can investigate offline conversion upload failures, manager-account hierarchy problems, and Performance Max listing filters. It can also help answer broader questions, such as which ads have problems and how those problems might be addressed.

    Treat the response as structured triage. Ask it to identify the failing object, inspect the applicable schema, show the relevant error or rule, and separate confirmed findings from proposed fixes. Then review the recommendation before changing production code or campaign configuration. A conversational explanation is easier to consume than a raw error, but readability is not evidence.

    Know what grounding does not prove

    Schema inspection and local validation reduce a specific class of AI failure: invented fields, incompatible combinations, and version-mismatched configurations. They do not prove that the request reflects the business question you meant to ask.

    • Syntactic validity: Can the query be parsed? The validator can address this.
    • Schema validity: Do the resources, fields, metrics, types, and enums exist and work together for the active version? Schema inspection and Google Ads-specific rules can address much of this.
    • Account validity: Is the query running for the correct customer, through the intended manager hierarchy, over the correct dates? The assistant can help retrieve customer IDs and diagnose hierarchy issues, but you still need to confirm the intended account context.
    • Business validity: Does the output answer the decision you need to make? A perfectly valid cost query is still wrong if the decision depends on profitable conversions or qualified leads.

    The same distinction applies to Shopping titles. Transparency shows you the generated wording and associated performance. It does not prove the wording is accurate, brand-safe, incrementally better, or responsible for the observed result.

    Google says the plugin architecture improves speed and reduces resource and token consumption by loading only the rules and schemas needed for a task, with caching to avoid repeated lookups. Those efficiency claims are useful for adoption planning, but they are separate from auditability. Faster generation changes how quickly work arrives; it does not lower the review standard.

    Build one evidence trail across marketing and development

    Marketing and engineering specialists inspect a connected evidence trail linking product data, validated code, live advertising outputs, and archived outcomes.

    You do not need a large governance program to make these tools accountable. You need a compact record that joins the AI output to the decision made about it.

    For AI-generated product titles, record the product or internal SKU, original title, generated title, review classification, impressions, product clicks, CTR, cost, average CPC, relevant downstream outcome from your measurement system, reviewer, and decision. This is your internal audit log; it should not be confused with a claim that every field appears in the Product titles report.

    For API work, record the customer context, intended API version, client language, user request, generated GAQL or code, validation result, schema fields inspected, date clauses, output location, reviewer, and deployment decision. If the work concerns an offline conversion upload, account hierarchy, or Performance Max listing filter, preserve the original failure details with the diagnosis.

    Assign ownership by artifact:

    • The feed owner is accountable for the original product data and for recurring weaknesses exposed by generated titles.
    • The performance marketer assesses title accuracy, delivery metrics, traffic quality, and the business relevance of the comparison.
    • The developer owns API-version selection, schema verification, query validation, code review, and reproducibility.
    • The appropriate brand, compliance, or business owner approves wording or implementation decisions that exceed the marketer’s or developer’s authority.

    Use event-based reviews instead of checking everything indiscriminately. Review when customized titles first appear, after meaningful feed changes, when a high-impression title changes the product’s meaning, before adopting the incompatible version 4 plugin architecture, before deploying generated integration code, and when a known troubleshooting case affects reporting or conversion data.

    Key takeaways

    • Google may serve an AI-customized Shopping title instead of the title you supplied, so audit the message that appeared rather than assuming feed copy reached the shopper unchanged.
    • Use the Product titles report to inspect original and generated titles with impressions, product clicks, CTR, cost, and average CPC, but do not mistake an observational comparison for a controlled experiment.
    • Check semantic accuracy before celebrating performance. More clicks are not useful when the title attracts the wrong buyer or changes the product promise.
    • Require the Google Ads API Developer Assistant to inspect the active schema and validate GAQL before execution. A fluent answer without those checks is weaker evidence.
    • Separate syntax, schema, account context, and business intent. An implementation can pass the first two tests while still answering the wrong question.
    • Keep an internal record connecting each AI output to its input, validation evidence, reviewer, observed result, and final decision.

    Start with the Shopping products receiving the most impressions and one API workflow where validation failures currently consume time. Establish the evidence record there, assign an owner, and make approval depend on inspectable proof. The aim is not to block automation. It is to shorten the distance between an AI-made change and your ability to understand, verify, and correct it.

    References


  • Google Listicle SEO: When Roundups Rank and When They Fail

    Google Listicle SEO: When Roundups Rank and When They Fail

    If a once-reliable roundup has slipped in Google, deleting every numbered page is the wrong first move. Listicles still rank widely. The more useful question is whether each page matches a real request for options and gives Google and the reader enough reason to trust its selections.

    You can answer that question without guessing about a sitewide penalty. Classify the page correctly, inspect the language people use to find it, expose any commercial conflict, and then decide whether to keep the list, rebuild it, or replace it with a better format.

    A listicle has to pass the reorderability test

    Six blank recommendation cards with different generic objects are arranged as movable tiles, with two cards shown swapping positions.

    A listicle is an article in which the list is the main content. Its entries are comparable things of the same general type, each entry receives a self-contained treatment, and rearranging the entries would not break the page’s logic.

    That last condition is the quickest diagnostic. Ten payroll tools can be reordered and remain useful. Ten steps for running payroll cannot, because later steps depend on earlier ones. The second page is a tutorial, even if its title contains a number.

    • Are the entries comparable items, such as tools, ideas, examples, providers, or options?
    • Can you rearrange them without making the page incoherent?
    • Can a reader understand one entry without reading the previous entry?

    If the answer to any of these is no, do not diagnose the page as a failed listicle. It may be a process guide, directory, product grid, single-item review, or loosely structured explainer that needs a different kind of repair.

    Titles alone are especially misleading. A broad number-or-list-word test found those cues on 85.9% of search results pages, while stricter classification confirmed an actual listicle on 55.1%. Auditing every URL containing terms such as best, top, ideas, or alternatives will therefore mix several page types and obscure the real pattern.

    There is no evidence here of a universal format penalty. Across 60,000 US-English desktop queries in 15 verticals, 55.1% had at least one listicle in the top 10 and 32.3% had one in the top three. A format that appears in more than half of the sampled top tens has not disappeared from Google.

    Those figures establish prevalence, not causation. They came from one 47-hour crawl wave in August 2026 covering 5.32 million organic-result rows. The analysis was observational, and although its automated classifier achieved 100% precision and recall in an initial 30-query check, an untouched production holdout was still pending. Use the figures to challenge the claim that all listicles were demoted, not to declare that every list page is safe.

    Key takeaways

    • Classify a page by how its content works, not by the number or list word in its title.
    • Choose a roundup when the searcher explicitly wants several peer options; use a tutorial or direct answer when the task is sequential or singular.
    • Apply the most scrutiny to pages on which your brand selects, evaluates, and ranks itself.
    • Measure Google rankings and AI citations separately because movement in one channel does not prove the same change in the other.

    Query wording should choose the page format

    The strongest signal is not the number of entries, the publication date, or the word count. It is whether the query asks for a set.

    Google displayed 4.5 times more listicles when searchers explicitly requested options. Listicles reached the top three for 54.5% of explicit-list queries, compared with 10.2% of implicit category or comparison queries. That gap is large enough to change how you plan and audit content.

    Searcher’s wordingUnderlying jobFormat to test first
    Best payroll tools for a small businessFind a bounded set of optionsRanked or use-case-based roundup with a disclosed method
    Payroll software comparisonUnderstand differences and tradeoffsComparison-led analysis; include a list only if it supports the decision
    How to run payrollComplete a sequence correctlyStep-by-step tutorial
    Payroll tax deadlineGet one direct fact or explanationDirect-answer page with the necessary context

    This does not mean an implicit query can never rank a list. It means list structure no longer has an automatic advantage when the wording does not request one. Forcing ten entries onto a query that needs a decision framework can leave the reader with more choices but less help.

    Audit the query-page relationship in this order:

    1. Open the query report for the landing page and collect the searches producing meaningful impressions or clicks.
    2. Label each query explicit-list, implicit-comparison, sequential, or direct-answer. Do not use a miscellaneous label until you have read the query literally.
    3. Inspect the current first page for the priority queries. Note whether Google is returning roundups, individual product pages, tutorials, category pages, or a mixed result.
    4. Choose one primary job for the URL. A page trying to be a roundup, tutorial, product pitch, and category definition at the same time usually makes every part harder to evaluate.
    5. Rewrite the structure around that job before changing individual sentences or adding more entries.

    Run this analysis at the query and URL level. A sitewide decline can contain two very different problems: a genuine loss on explicit-list searches and an intent mismatch on pages that never should have been listicles. Those problems require different fixes.

    Self-serving roundups carry the real visibility risk

    A balance scale tips toward a glossy generic product and unmarked coins while several other products sit on the raised side.

    The concern about listicles did not appear from nowhere. Several SaaS brands built heavily around self-promotional roundups recorded organic visibility losses of 29% to 49% within weeks beginning in January 2026. The timing is a warning for brands that routinely award themselves first place, but it does not isolate the page format as the cause.

    A broader ranking sample points to a narrower interpretation. When a publisher listicle and a brand or vendor listicle appeared on the same results page, publishers won 54.0% of 4,026 direct matchups. Their average position in those matchups was 4.24, compared with 4.71 for brands and vendors.

    That is an edge, not a wipeout. A brand or vendor still won 46% of those head-to-head matchups, and website type is not the same variable as editorial independence. Some publishers have affiliate incentives; some brands publish rigorous category education. The comparison supports greater caution around conflicted selection, not a rule that publishers rank and brands cannot.

    The market is also less concentrated than a few dominant ranking sites can make it appear. The top 10 domains supplied 18.3% of top-10 listicle leaders, and the top 50 supplied 36.5%. The remaining 5,715 domains supplied 63.5%. That distribution does not promise a ranking to a smaller site, but it does show that listicle visibility is not reserved for a tiny group of domains.

    Your practical problem is the evidence burden. When a software company publishes the best software in its own category and crowns its own product, the conclusion is commercially convenient before the reader sees a single criterion. More adjectives will not resolve that conflict. A transparent, consistently applied selection method might.

    Keep Google and AI-search conclusions separate as well. ChatGPT listicle citations fell by 30% from December 2025 to January 2026 while Wikipedia and Reddit gained the displaced share. That change matters to generative search visibility, but it is not proof of the same ranking change in Google. Maintain separate tracking for Google queries, ChatGPT citations, and any other answer engine you care about.

    Make every recommendation defensible

    A useful roundup lets the reader reconstruct how an option qualified, why it occupies its position, and which tradeoff might disqualify it. You should be able to answer those questions before polishing the title.

    Use this page blueprint:

    1. Opening answer and scope. State who the list is for, what decision it supports, and any important group it does not cover. A roundup for enterprise procurement should not quietly present itself as universal advice.
    2. Eligibility rules. Explain what an option had to be or do to enter the candidate set. Name meaningful exclusions instead of implying that every possible product, provider, or idea was evaluated.
    3. Evaluation method. Define the criteria before revealing the winner. Use factors that a competing option could also satisfy; criteria reverse-engineered around your product do not create a fair comparison.
    4. Comparable evidence. Give each entry the same core treatment. If you discuss price structure, intended user, notable limitation, and a key capability for one option, cover those fields for the others where the information is available.
    5. Decision-relevant tradeoffs. Say who should consider each option and who should not. A weakness that would change the purchase decision is more useful than another paragraph of generic benefits.
    6. Ordering rule. Explain why the first entry is first. If the evidence supports several use-case winners but no universal winner, organize the page by use case instead of manufacturing a single ranking.
    7. Commercial disclosure. Identify your own product, affiliate relationships, sponsorships, or other material incentives plainly. Disclosure does not remove bias, but hiding the relationship makes the recommendation harder to trust.

    Place the method before the first recommendation, where the reader can use it to interpret the list. A methodology added below the final entry looks like a defense of a conclusion already made.

    If your brand belongs in the list, include it under the same rules as every other candidate. Do not award it first place merely because you control the page. If you cannot document a neutral ordering, make the set unranked or choose winners for clearly defined use cases.

    Do not inflate the item count to make the title look more substantial. A bounded set should reflect the scope you can support. Every weak entry introduces another unsupported claim, another maintenance obligation, and another chance for the reader to wonder whether inclusion was arbitrary.

    These are editorial controls, not guaranteed ranking factors. Their job is to make the page’s logic visible, limit conflicts, and produce an answer that remains useful even after the reader notices who published it.

    Audit the portfolio page by page

    A mass rewrite based on the word listicle is too blunt. Build an inventory and make one of three decisions for each URL: keep, rebuild, or reformat.

    1. Inventory true listicles. Apply the reorderability test to pages, rather than filtering only for numbers or words such as best and top.
    2. Map query intent. Group each page’s meaningful queries into explicit-list, implicit-comparison, sequential, and direct-answer intent.
    3. Validate the result format. Inspect the current result mix for the priority queries. Record whether listicles are present and whether the strongest pages come from publishers, vendors, communities, or another site type.
    4. Check the incentive. Flag pages where your company selects itself, ranks itself first, hides a commercial relationship, or uses criteria that favor only its offer.
    5. Choose the action. Keep a page when explicit list intent is strong and the selections are defensible. Rebuild it when list intent is strong but the method or evidence is weak. Reformat it when the reader primarily needs a sequence, one answer, or a comparison framework.
    6. Measure at the same level you diagnosed. Track impressions, clicks, and position for the relevant query group after a change. Keep AI citations in a separate view so movement in ChatGPT or another answer engine does not get mistaken for a Google outcome.

    Preserve useful URLs while you test substantive revisions; do not bulk-delete a content class because several sites lost visibility. Start with the clearest intent mismatches and the pages carrying the most obvious commercial conflict. Those are the cases where a structural change has a reason behind it, rather than a theory about numbers in titles.

    The durable rule is simple: publish a list when the reader is asking for a set, and make every inclusion survive scrutiny. When the reader is asking for something else, give them the format that completes that job.

    References


  • Meta Ad Creative Diversity: A Practical Testing System

    Meta Ad Creative Diversity: A Practical Testing System

    You have plenty of Meta ads, but the campaign still leans on one winner, costs rise as that ad ages, and every replacement seems to be a weaker version of the same idea. The problem may not be production volume. It may be that your assets are different files without being different creative concepts.

    The fix is to give Meta several meaningfully different ways to sell the same product. That means varying the reason to care, the person delivering it, the problem being addressed, the emotional appeal and the visual experience. Here is how to build that diversity without turning your creative workflow into an uncontrolled content factory.

    Count distinct concepts, not uploaded ads

    Creative diversity is not an ad count. If you upload 20 ads built around the same product image, opening frame, spokesperson, headline and claim, you have probably produced minor edits of one concept. A new crop, caption or background color can be useful for polishing an execution, but it does not give the system a fundamentally new way to connect with someone.

    A quick audit can reveal this kind of false variety. Place your current ads side by side and ignore filenames, dimensions and placement. For each one, record the following:

    • The first idea a person sees or hears.
    • The customer problem being named.
    • The outcome or promise being offered.
    • The person or voice delivering the message.
    • The proof used to make the claim credible.
    • The emotional appeal, such as relief, aspiration, curiosity or recognition.
    • The visual style and format.
    • The offer and call to action.

    If most of those fields remain the same across a group of ads, treat that group as one creative family. The assets may look different in Ads Manager, but they are asking the audience to respond to the same argument.

    It helps to separate three levels of change. A cosmetic variation changes the crop, color, caption length or other surface detail. An execution variation changes how an idea is presented, perhaps by moving it from a static image to a short video. A conceptual variation changes the hook, customer pain point, messenger, promise, proof, emotion or offer. You need all three at times, but the conceptual layer does most of the work when your goal is genuine diversity.

    Use one simple test before approving a new asset: what does this ad let Meta learn that the existing family cannot? If the answer is only that it has a different background or a shorter edit, label it as an execution variant rather than a new concept.

    Build creative around different reasons to care

    Five people use the same compact blender in scenes emphasizing performance, convenience, simplicity, freshness, and space saving.

    Meta’s machine learning has taken on more of the work that advertisers once tried to perform through tightly divided audience structures. Broader targeting makes the creative itself a more important signal: different hooks, creators, messages and offers give the system more ways to find a productive match between an ad and a person.

    Start with message families rather than formats. A message family is a distinct answer to the question, “Why should this person care now?” For a moisturizer, for example, one family could focus on avoiding a greasy finish. Another could teach people about mistakes in their current routine. A third could use a hindsight story from someone who wishes they had understood their skin earlier. The product is unchanged, but the entry point, motivation and stage of awareness are different.

    Develop each family across several dimensions:

    • Hook: Lead with a desired result, a familiar frustration, a mistake, a question, a point of view or an unexpected observation.
    • Pain point: Name a specific difficulty instead of treating every buyer as if they share one generic problem.
    • Messaging angle: Emphasize the outcome, the product experience, the problem being removed, the reason the product exists or the identity the customer wants to express.
    • Messenger: Use a founder, customer, creator, subject-matter voice or product-led presentation where each is credible.
    • Proof: Show the product in use, a customer testimonial, a review, social proof or a clear problem-and-solution sequence.
    • Emotional appeal: Decide whether the concept should create recognition, curiosity, reassurance, aspiration, amusement or urgency. Do not try to force every emotion into one script.
    • Visual language: Choose product photography, lifestyle imagery, educational graphics, user-generated content, an unboxing, a reaction, a meme-style execution or another treatment that fits the message.
    • Offer: Test a genuinely different commercial proposition when one is available, rather than presenting identical terms with new punctuation.
    • Format: Select video, static image or carousel because it serves the concept, not merely to check a format box.

    Do not confuse format coverage with strategic diversity. A video, image and carousel can all repeat the same opening idea, product shot and promise. Conversely, two videos can be meaningfully different when one is a founder explanation and the other is a customer’s problem-and-solution story. Strong portfolios diversify across multiple dimensions, not just file types.

    Organize the portfolio in layers. At the top are message families: the distinct reasons to care. Under each family are executions: founder video, testimonial, product demonstration, lifestyle image or carousel. Under each execution are refinements such as alternate hooks, captions and calls to action. This structure prevents ten small edits from being mistaken for ten independent ideas.

    Turn one video into a modular creative system

    A small production crew films an unbranded skincare bottle using interchangeable sets, presenters, props, and camera angles.

    You do not need to film a completely new production for every hypothesis. In video, the opening deserves special attention because the first few seconds influence whether someone keeps watching or scrolls on. Several openings can lead into the same useful body, demonstration or testimonial.

    Build the video as modules:

    1. Write the stable core. Capture the part that explains the problem, shows the product, supplies proof and connects the solution to the desired outcome.
    2. Record distinct hooks. Create openings that perform different jobs. One can state a point of view, one can expose a common mistake, and one can begin with a hindsight lesson. Changing only the first adjective is not a new hook.
    3. Change the messenger where it adds meaning. A founder can explain why the product exists, a customer can describe the lived problem, and a creator can show how the product fits into a routine. Merely giving several people an identical script produces less diversity than giving each person a credible role.
    4. Capture alternate endings. Match the call to action to the concept. An educational video may invite the viewer to learn more, while a product demonstration may move directly toward the offer.
    5. Translate the idea selectively. Adapt a strong concept into a static image or carousel only when the new format improves how the idea is understood. Re-exporting a video frame as an image adds an asset, but not necessarily a new experience.

    This modular approach lets you preserve what works while testing what changes attention and relevance. It also makes production briefs clearer. Instead of asking a creator for “more content,” specify the customer problem, hook job, messenger role, proof, visual treatment and ending required for each family.

    Keep a concept sheet next to the production plan. Give every asset a concept ID and record its message family, hook, messenger, pain point, proof, emotion, style, format, offer and call to action. You will be able to see whether the next shoot expands the portfolio or simply adds more members to an already crowded family.

    Use Meta’s diversity rating as a prompt, not a verdict

    Meta has added a Creative diversity column to Ads Manager. You can find it through Columns, Customize columns, then Creative diversity. The metric is labeled in development, estimates the visual variety of images and videos, and returns Low, Medium or High.

    Treat that rating as a diagnostic prompt. It is not a campaign objective, a complete description of message diversity or a reason to stop a profitable ad. Its thresholds and underlying signals have not been fully disclosed, and apparently varied portfolios containing static images, different videos, user-generated content, partnership ads, organic posts and carousels have still received Low ratings. That uncertainty matters while the metric remains in development.

    The metric also appears to focus on visual similarity. Your strategic audit has to go further. A portfolio may look varied while repeating one promise, one pain point and one emotional appeal. The reverse is possible too: executions can share brand elements while making substantially different arguments. Read the platform rating alongside your concept sheet rather than allowing either one to stand alone.

    Creative fatigue provides a more practical reason to expand the pool. When Meta has only a few similar choices, delivery can concentrate on the strongest one. As the same ad is shown repeatedly, frequency can rise while performance declines and costs increase. More meaningful options give the system somewhere else to move as response patterns change.

    When you suspect fatigue, do not respond with an arbitrary batch of resizes. Work through this sequence:

    1. Check whether delivery has become concentrated in one ad or one concept family.
    2. Look for the accompanying pattern: rising frequency, weaker performance and higher costs.
    3. Identify which strategic dimensions are missing from the portfolio. The gap may be a new customer problem, messenger, hook, proof type or emotional appeal.
    4. Commission a distinct concept that fills the gap while keeping the product and campaign objective coherent.
    5. Preserve the existing winner until performance evidence gives you a reason to change it. Diversity is an expansion strategy, not an instruction to discard an effective asset.

    A Low rating should therefore trigger questions, not panic. Ask whether the first frames are alike, whether the same person dominates the videos, whether every concept makes the same claim and whether your apparent variety comes mainly from formats. Those answers lead to a better brief than chasing a platform label by itself.

    Run a repeatable diversity sprint around every winner

    A winning ad is not just an asset to duplicate. It is evidence that a product story can work. Your next task is to preserve the truth of that story while finding new ways into it.

    A useful creative brief is to reinterpret the winner in 10 genuinely different ways. These are not ten new crops. They are ten assignments with different communication jobs:

    1. Open with the customer’s immediate pain point in a point-of-view hook.
    2. Turn the underlying problem into an educational mistakes concept.
    3. Frame the lesson as something the speaker wishes they had known earlier.
    4. Have the founder explain why the product or solution was created.
    5. Build a customer testimonial around the problem and the change that mattered.
    6. Ask a creator to demonstrate how the product fits into a real routine.
    7. Lead with lifestyle imagery that makes the desired outcome easy to recognize.
    8. Use a product-focused demonstration or unboxing to make the experience concrete.
    9. Build the concept around reviews or another appropriate form of social proof.
    10. Translate the core tension into a reaction, meme-style treatment or clear problem-and-solution sequence.

    Not every assignment will fit every product. Remove any that would feel forced or unsupported. The point is to make each brief change a meaningful element: who speaks, which problem leads, what is promised, how credibility is established, what emotion is used or how the story is experienced.

    Review the completed concepts before production, not after upload. Put them in rows and compare the hook, messenger, pain point, angle, proof, emotion, visual language, format and offer. If several rows are nearly identical, rewrite those briefs while changes are still inexpensive. This is where creative diversity becomes a workflow rather than a rescue operation.

    After launch, evaluate both outcomes and portfolio coverage. Which message families receive delivery? Which concepts attract attention but fail to move toward the objective? Which messenger or proof type appears useful enough to develop further? Which family is absorbing production resources without adding a new reason to care? Use those answers to decide what to expand, refine or retire.

    Key takeaways

    • Count concept families, not files. Twenty cosmetic variants can still represent one idea.
    • Vary the hook, customer problem, messenger, message, proof, emotion, offer, visual style and format.
    • Use modular production to create distinct openings, speakers and endings around a reusable core.
    • Read Meta’s in-development diversity rating as one visual signal, not as a complete quality score.
    • When fatigue appears, add a missing strategic angle instead of another resize of the tired concept.

    Open Ads Manager, add the Creative diversity column, and audit your current ads by concept family. Keep the winner working while you brief the first idea that gives someone a genuinely different reason to care. That is the next creative your campaign needs.

    References


  • AI Training Data Licensing: A Practical Guide for Brands

    AI Training Data Licensing: A Practical Guide for Brands

    If an AI company asks to train on your content archive, the first question should not be, “What should we charge?” It should be, “What exactly would we be allowing, and do we control every item we plan to deliver?” Pricing before answering those questions is how a promising data deal becomes a rights problem.

    You need a way to separate legitimate commercial value from vague promises about “AI exposure.” The process below will help you audit the material, define the permitted uses, structure compensation, protect your brand, and decide whether the proposed license deserves to move forward.

    First determine whether your content is actually licensable

    The commercial backdrop is changing: AI labs are paying for curated, high-quality data instead of depending only on scraping. That does not make every large archive a valuable training corpus. A buyer needs content it can lawfully use, reliably process, and connect to a defined model or product objective.

    Start with a rights inventory, not a page count. Your CMS may contain material created under several different arrangements, even when all of it carries your branding. Employee-written copy, commissioned work, syndicated material, customer submissions, licensed photography, embedded media, and acquired archives can each carry different permissions.

    1. Divide the archive into meaningful content classes, such as editorial text, product data, customer questions, reviews, research records, images, audio, and video transcripts.
    2. Identify who created each class and the agreement that governs it. Record whether you own the relevant rights or merely have permission to publish it in a particular channel.
    3. Mark third-party elements inside otherwise original pages. A page you own can still contain a photograph, quotation, data table, or embedded asset that is outside your licensing authority.
    4. Separate confidential, personal, regulated, and user-submitted information from content already approved for commercial reuse. Public visibility is not proof of permission for model training.
    5. Create an exclusion list for anything with missing agreements, disputed ownership, unclear consent, contractual restrictions, or an unacceptable privacy risk.

    Do not rely on a copyright notice, a byline, or administrative access to the CMS as evidence that you can license an item for machine learning. If ownership, privacy, or consent is unclear, hold the material out until qualified intellectual-property or privacy counsel confirms how it may be used. Otherwise, you may be promising rights that your organization does not possess.

    Audit usefulness as well as ownership

    A legally clean collection can still be difficult to use. Training-data buyers benefit from records that are consistent, attributable, documented, and easy to update. Before discussing a license, examine whether you can deliver the following:

    • A stable identifier for every record, independent of a changeable page title or URL.
    • Clean primary content separated from navigation, advertising, comments, and duplicated boilerplate.
    • Reliable metadata for content type, language, publication date, revision date, author or publisher, and canonical URL.
    • A documented origin and rights basis for each content class.
    • Version history that shows what changed and when.
    • A consistent method for issuing additions, corrections, withdrawals, and deletions.
    • Clear definitions for fields, labels, categories, and any editorial annotations.
    • A manifest that lets both parties confirm exactly which records appeared in each delivery.

    This work affects both value and risk. A smaller corpus with dependable rights and metadata may be more usable than a much larger archive full of duplicates, unexplained fields, and uncertain ownership. It also lets you create separate licensing tiers instead of placing the entire archive into one irreversible package.

    Separate the AI permissions that vague contracts bundle together

    A sealed archive case connects to five separate transparent pathways, each controlled by its own valve and lock.

    “Use our content for AI” is not a workable grant of rights. A single URL can be crawled for discovery, stored in a retrieval index, used to evaluate answers, included in model training, displayed as a quotation, or transformed into another dataset. Those activities have different commercial consequences and should not be treated as one permission.

    ActivityWhat you need to define
    Public crawling and indexingWhich properties may be fetched, how often access occurs, what may be cached, and whether the purpose is search, retrieval, or another named function.
    Retrieval for generated answersWhat content may be stored and retrieved, how current it must remain, how excerpts are displayed, and whether answers include attribution and a link.
    Foundation-model trainingWhich model families, versions, products, and purposes may learn from the corpus, including whether commercial deployment is permitted.
    Fine-tuning or adaptationWhich named model or application may be adapted, who may operate it, and whether the adapted model may be transferred or reused elsewhere.
    Evaluation and safety testingWhat tests may use the data, how long test copies are retained, who can review outputs, and whether the material can later move into training.
    Output displayWhether the product may quote, summarize, reproduce, translate, or otherwise present the content, along with attribution and linking requirements.
    Synthetic or derivative dataWhether transformed records may be created, retained, combined with other datasets, sublicensed, or used after the original license ends.

    These distinctions also matter for AI search visibility. Training does not, by itself, guarantee that a model will cite your site, link to a page, use the current version, or represent your brand faithfully. If your business goal is discoverability, retrieval and output-display terms may matter more than a broad training grant.

    Turn the permission into a bounded scope

    A usable proposal should identify the parties, the data, the technology, the purpose, and the duration without forcing you to infer any of them. Require clear answers to these questions before quoting a price:

    • Which legal entity receives the license, and may its affiliates, contractors, hosting providers, or customers access the data?
    • Which records and versions are included? Does the grant cover one delivery, scheduled updates, or everything you publish in the future?
    • Which model families, checkpoints, applications, and product surfaces may use the corpus?
    • Is the use limited to internal development, or does it include commercial products offered to customers?
    • May the buyer combine the corpus with other data, create embeddings, produce annotations, or generate derivative datasets?
    • May the data or anything derived from it be transferred, assigned, sold, or sublicensed?
    • Is the license exclusive? If so, what subject, market, product, geography, language, and time period does the exclusivity cover?
    • What uses are expressly prohibited, including products designed to replace your publication, impersonate your brand, or expose restricted material?
    • What survives expiration or termination: raw files, retrieval indexes, embeddings, trained models, checkpoints, backups, derived datasets, or deployed products?

    A phrase such as “all artificial-intelligence purposes” gives the buyer flexibility by moving uncertainty onto you. Replace it with named uses and named products. If the buyer cannot identify the intended model, purpose, retention period, or downstream recipients, you do not yet have enough information to assess the risk or calculate a defensible fee.

    Price the defined scope, not the size of the archive

    There is no responsible universal price per page, word, or record. Volume affects processing costs, but it does not capture scarcity, freshness, rights quality, exclusivity, labeling, or the commercial freedom a license gives the buyer.

    Build your internal price floor from the work and exposure the deal creates. Include rights review, data cleaning, redaction, formatting, secure delivery, engineering support, update handling, reporting, contract administration, and the opportunity cost of restrictions placed on future deals. Then evaluate the buyer’s requested scope separately.

    • Uniqueness: Is the information readily available elsewhere, or does your organization hold a difficult-to-recreate collection?
    • Quality: Is the material edited, labeled, deduplicated, and accompanied by dependable metadata?
    • Freshness: Is this a historical delivery, or will your team provide continuing corrections and new records?
    • Rights assurance: How much review has been completed, and how broad a warranty is the buyer requesting?
    • Permitted use: Evaluation carries a different commercial footprint from unrestricted commercial training and deployment.
    • Downstream reach: Will one team use the corpus, or can affiliates, customers, contractors, and sublicensees benefit from it?
    • Exclusivity: What future buyers, products, markets, or partnerships would you be giving up?
    • Duration and survival: Does the buyer receive temporary access, or can trained and derived assets remain in service indefinitely?
    • Operational burden: How much continuing delivery, support, auditing, correction, and incident response will your team owe?

    Compensation can take several forms. A fixed fee is simple but must be tied to a fixed scope. A usage-based fee can expand with deliveries, records, model runs, or products, but only if the usage can be measured and audited. A minimum guarantee plus variable payments can cover your baseline work while preserving participation in broader use. Revenue sharing can align incentives, but it becomes fragile when revenue attribution is vague. Whichever structure you choose, define the measurement method, reporting schedule, audit rights, payment trigger, and treatment of disputed calculations.

    Negotiate in an order that preserves leverage

    1. Set your non-negotiable exclusions, privacy boundaries, brand protections, and prohibited uses.
    2. Obtain the buyer’s written description of the model, product, users, purpose, and data flow.
    3. Offer a specific corpus tier rather than opening the entire archive by default.
    4. Price the narrow base use first.
    5. Price additional models, products, affiliates, territories, updates, derivative data, and exclusivity as separate expansions.
    6. Require written approval and additional compensation before the buyer crosses from one tier into another.

    Watch for terms that make a seemingly attractive payment disproportionate to the rights surrendered. Common warning signs include perpetual and irrevocable use across undefined AI systems, automatic rights to all future content, unrestricted sublicensing, vague exclusivity, unilateral changes to the use case, broad warranties about third-party material, and liability that is uncapped or disconnected from your control. These are legal and financial exposure points, so have qualified counsel assess the actual agreement rather than relying on a commercial checklist alone.

    Build operational controls around the contract

    A legal, content, and technical team monitors a controlled data transfer into a locked server enclosure in a secure data room.

    A signed license is only useful if both parties can administer it. The contract may say that one content class is excluded, for example, while the export pipeline quietly delivers it with everything else. Connect each important term to a technical control, an owner, and a record that can later show what happened.

    • Attach a dataset schedule describing included content classes, excluded classes, fields, formats, languages, and delivery frequency.
    • Generate a manifest for every delivery with stable record IDs, versions, timestamps, and license status.
    • Keep approval records for additions and document every correction, withdrawal, and deletion request.
    • Specify access controls, approved storage locations, security duties, incident notification, and whether the corpus must remain segregated from other collections.
    • Require usage reports that correspond to the pricing and scope terms, including the models, products, recipients, and dataset versions involved.
    • Assign responsibility for rights questions, privacy requests, technical delivery, invoices, audits, brand issues, and termination.
    • Create a change process for new products, model families, acquisitions, corporate reorganizations, and transfers to another operator.
    • Schedule periodic reviews so a narrow experiment does not quietly become a broader production use without new approval.

    Deleting delivered files does not by itself reverse model training that has already occurred. Treat raw data, embeddings, derivative datasets, model checkpoints, future model releases, backups, and deployed products as separate post-termination states. The agreement should say which states may continue, which must stop, which must be deleted where technically applicable, and what evidence the buyer must provide. Resolve this before delivery, because the available remedies may be narrower after training begins.

    Protect AI visibility as a separate outcome

    If your objective includes visibility in AI answers, put that outcome into the deal rather than assuming it follows from training access. Consider terms covering attribution wording, canonical links, use of your current brand and entity names, update handling, correction escalation, and reporting on answer displays or citations where the product can measure them.

    You may also want a retrieval feed that remains distinct from the training corpus. A retrieval system can consult current records when producing an answer, while a trained model reflects an earlier training process. Keeping those permissions separate lets you negotiate freshness, citation, withdrawal, and link behavior without granting every training right at the same time.

    Your publishing infrastructure still matters outside the license. Maintain stable canonical URLs, explicit publisher and author information, clear publication and revision dates, consistent entity names, and structured data that agrees with the visible page. Provide machine-readable correction and withdrawal signals where your workflow supports them. Monitor priority questions to see whether AI products identify your brand, use current facts, and link to the intended page.

    Keep the three control layers distinct. Structured data describes the meaning and relationships on a page; it does not transfer content rights. Site access controls regulate automated access; they are not a substitute for negotiated permission. The license defines authorized uses between the contracting parties. Treating any one layer as if it performs all three jobs creates gaps.

    Key takeaways

    • Audit ownership, third-party rights, consent, privacy, and contractual restrictions before offering an archive.
    • Exclude uncertain material instead of representing that you control rights you may not have.
    • Separate crawling, retrieval, training, fine-tuning, evaluation, output display, and derivative-data permissions.
    • Define the receiving entities, dataset versions, models, products, purposes, duration, downstream users, and post-termination treatment.
    • Price legal review, preparation, delivery, governance, commercial scope, exclusivity, and continuing obligations rather than relying on content volume alone.
    • Connect every important contract restriction to a technical control, responsible owner, usage record, and review process.
    • Negotiate citation, linking, freshness, brand representation, and correction workflows explicitly when AI visibility is part of the business case.

    Your next move is to create a one-page licensing brief before discussing price. List the proposed corpus, excluded material, rights basis, permitted AI activities, prohibited uses, buyer entities, model or product scope, delivery schedule, duration, post-termination states, visibility requirements, and internal approval owners. Have the appropriate rights, privacy, technical, commercial, and legal stakeholders review that brief.

    If the buyer can answer those points, you can negotiate a bounded transaction. If it cannot, keep narrowing the request. The valuable asset is not merely a large body of content. It is a defensible, structured, maintainable corpus offered under terms your organization can actually enforce.

    References