Author: shivamcrushpressai

  • How to Evaluate Conductor’s Unified SEO Intelligence Platform

    How to Evaluate Conductor’s Unified SEO Intelligence Platform

    If your rankings, content work, and website changes live in separate tools, the expensive part is not collecting another chart. It is deciding which page to change, why the change deserves priority, who owns it, and whether it worked.

    That is the right lens for evaluating Conductor’s unified SEO intelligence platform. Do not start with how much data it can display. Start with whether your team can move from evidence to a governed action without rebuilding the context at every handoff.

    Define what “unified” must mean for your team

    Conductor is positioning unified data and SERP visuals as connected parts of SEO decision-making. Its partnership with Acquia also points toward bringing AI-powered SEO insights closer to website optimization. Those are useful signals about the platform’s direction, but they are not proof that its workflow will fit your organization.

    A unified screen is not necessarily a unified operating model. If a marketer still has to export a chart, explain it in a meeting, rewrite the recommendation in a project tool, and ask a publisher to reconstruct the reasoning, the interface has consolidated information without unifying the work.

    Use this chain to define what you actually need:

    • Evidence: The team can see where an observation came from, what it measures, and when it was captured.
    • Context: The evidence retains the relevant page, query, market, device, search surface, and business objective.
    • Interpretation: A recommendation explains the observed problem and the assumption connecting that problem to the proposed change.
    • Action: The recommendation reaches a named owner with an approval state, publishing route, and preserved rationale.
    • Learning: The team can return to the same decision after publication and compare the outcome with the original expectation.

    Data aggregation only completes the evidence layer. SEO intelligence begins when the rest of the chain remains intact. Write these requirements down before a demonstration or pilot. Otherwise, polished dashboards will pull the conversation toward what is easy to show rather than what your team needs to decide.

    Test Conductor with a real decision from your backlog
    An analyst reviews visual search evidence around one highlighted webpage while a queue of other task cards remains in the background.

    A generic product tour is a weak test because the vendor controls the query, pages, narrative, and desired conclusion. Bring a live page group with a known owner and an unresolved decision. Choose work that matters but does not require exposing sensitive customer or commercial data.

    Frame the decision before anyone opens the platform. A useful prompt might be: “Should we refresh these pages, consolidate them, change their format, or leave them alone?” That forces the platform to support a choice rather than merely surface movement in a metric.

    1. State the business purpose. Identify what the page group is meant to produce, such as qualified demand, transactions, product discovery, or support resolution.
    2. Establish the observation. Ask the operator to show the performance change and the definitions, filters, and date context behind it.
    3. Inspect the search environment. Use the SERP view to determine whether the results page, competing page types, or visible search features changed alongside your metric.
    4. Create a recommendation. Require a clear proposed action, affected page scope, expected result, alternative explanation, and accountable owner.
    5. Route the work. Send the recommendation through the workflow your content, SEO, development, and compliance teams would actually use.
    6. Preserve the decision. Make sure someone returning later can see the original evidence, what was approved, what was published, and what outcome followed.

    The platform passes this test when a teammate who did not perform the analysis can understand the decision without asking for a separate slide deck. It fails when the rationale disappears between analysis and execution, even if every individual feature looks capable.

    Pay particular attention to definitions. “Visibility,” “rank,” “traffic,” and “conversion” are not interchangeable. Ask which metric is canonical for each decision, which filters are applied, and whether an export preserves the same definitions. A unified platform can still produce conflicting answers when teams use different segments or quietly change the denominator.

    Use SERP visuals as evidence, not decoration

    A rank value tells you where a result appeared under a defined observation. It does not, by itself, show what surrounded that result or whether the search page changed shape. SERP visuals can add that missing context, but only if your team treats them as evidence with a timestamp, market, device, and query attached.

    For a query connected to a meaningful page group, ask:

    • Which page types are prominent: product pages, category pages, editorial explanations, videos, local results, or another format?
    • Which search features occupy attention before or around the organic listings?
    • Does your page satisfy the same apparent intent as the visible results, or is it competing with a different kind of answer?
    • Did your ranking move while the surrounding result composition stayed stable, or did both change?
    • Can the team retrieve the visual evidence that supported an earlier recommendation, rather than seeing only the latest state?

    Record each interpretation as an observation, implication, and next test. For example: the visible results favor category pages over long-form explanations; that may indicate a page-type mismatch; compare the affected template and intent before rewriting copy. This wording matters. It keeps a visual pattern from turning into an unsupported claim about causation.

    Do not collapse conventional SERP visibility and AI visibility into one label. AI answers, citations, brand mentions, and standard search listings are different observations. Ask exactly which surfaces Conductor captures, how each metric is defined, which markets or response modes are included, and whether historical evidence is retained. If a surface is not measured, a conventional ranking or SERP image cannot stand in for it.

    This distinction is especially important for AEO and GEO programs. A page can be technically discoverable, rank conventionally, and still fail to provide the concise claims, explicit entities, supporting detail, and clear provenance that answer systems need to interpret it. Conversely, an AI mention does not prove that the underlying page attracts qualified visits or supports a business outcome. Keep those findings connected, but do not pretend they are the same metric.

    Put governance between AI insight and publication
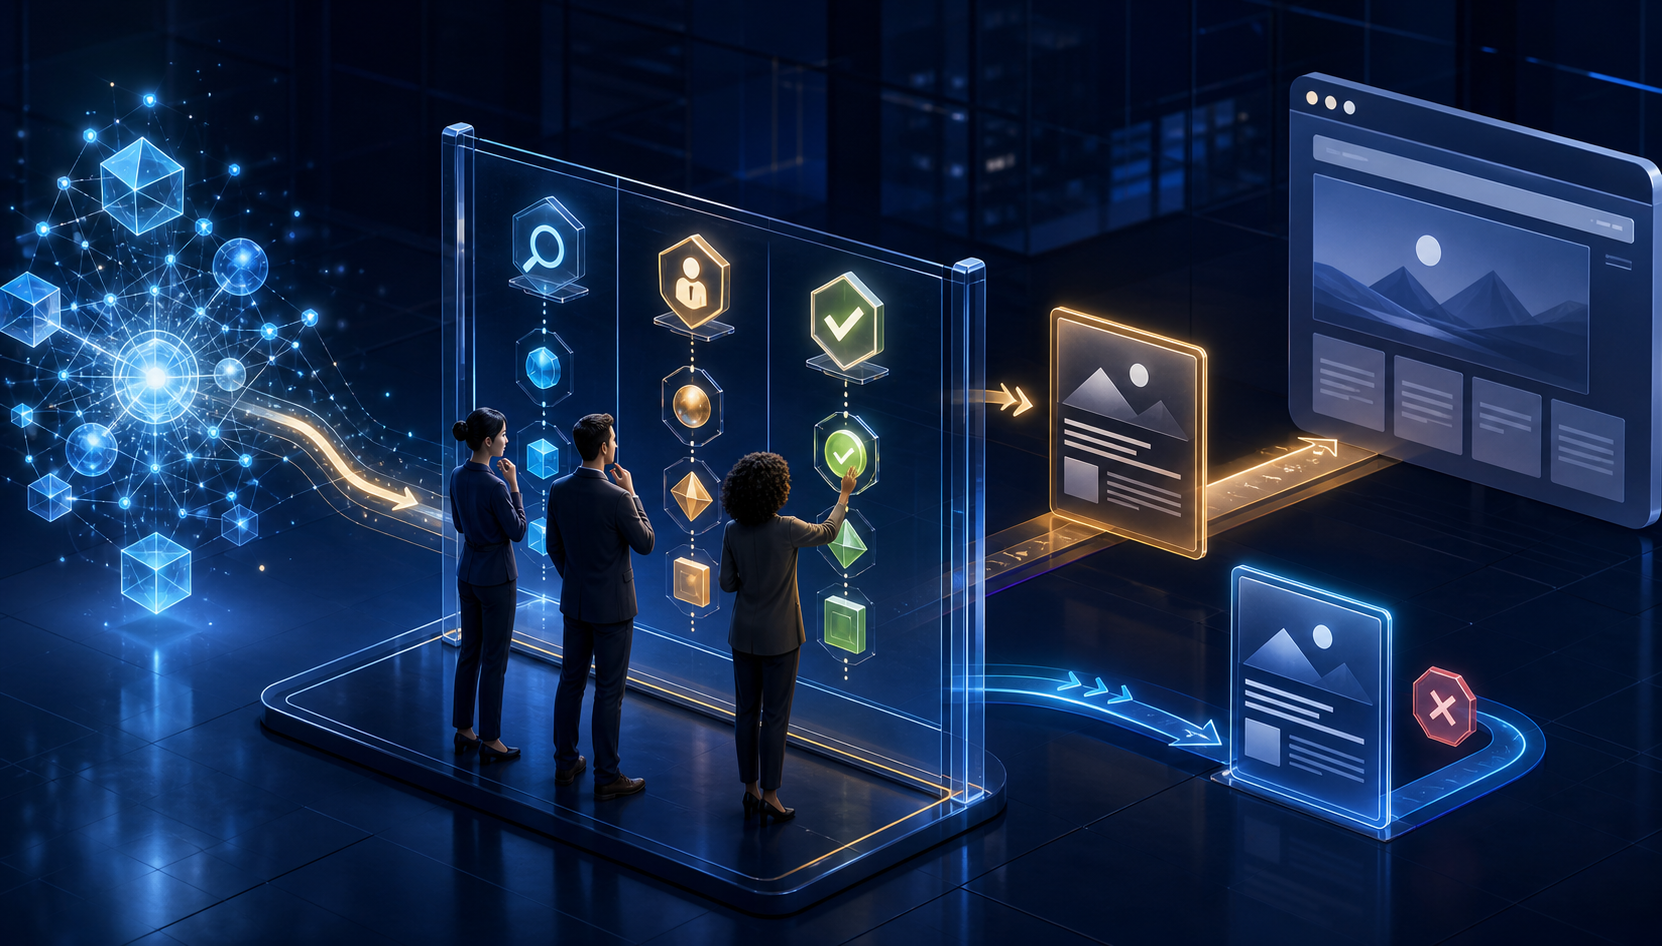
    Three reviewers inspect an AI-generated insight at an approval checkpoint before a webpage is allowed to move toward publication.

    An AI-generated recommendation should enter your workflow as a hypothesis, not an approval. The useful question is not whether the system can produce suggestions quickly. It is whether a reviewer can inspect the evidence, understand the proposed change, limit its scope, and reject it without losing the surrounding analysis.

    The connection between AI SEO insights and the Acquia environment could reduce the distance between analysis and website work. A shorter handoff can be valuable, but it can also move a weak recommendation toward production faster. Evaluate the control layer with the same care as the insight layer.

    Separate automation permissions by action:

    • Observe: Read data and identify patterns without creating work or changing content.
    • Recommend: Create a documented suggestion or task for a human owner.
    • Draft: Prepare a proposed edit in a reviewable environment without publishing it.
    • Publish: Change the live website only after the required approval and validation.

    Require visible permissions, preview, version history, and approval states before granting write access. Redirects, canonical tags, robots directives, structured data, and shared templates deserve production-release controls because one mistake can affect many URLs. Keep those changes staged and reviewable; do not allow a plausible-sounding recommendation to trigger a broad live edit automatically.

    Apply the same discipline to JSON-LD and other schema work. A generated schema recommendation must match the page’s visible content and actual meaning. Being generated inside an SEO platform does not make the markup accurate, eligible, or appropriate. The reviewer should be able to see the proposed properties, the content supporting them, the affected templates, and the validation result before publication.

    Finally, decide where the permanent record lives. Conductor may hold the evidence and recommendation while your CMS, project system, or governance tool holds approval and deployment state. That division is acceptable if identifiers and links survive the handoff. It becomes a problem when each system contains a different version of why the change was made.

    Key takeaways for your platform decision

    • A unified platform should preserve the chain from evidence through interpretation, ownership, publication, and outcome; a shared dashboard alone is not enough.
    • Evaluate Conductor with a live SEO decision and your real handoff process, not only a vendor-controlled demonstration.
    • Use SERP visuals to examine search-result context, while keeping observation separate from causal explanation.
    • Ask for distinct definitions and coverage for conventional search, AI answers, citations, brand mentions, traffic, and business outcomes.
    • Treat AI recommendations as reviewable hypotheses and assign automation permissions according to the risk of the proposed action.
    • Choose the platform only if another teammate can reconstruct why a change was made without relying on an analyst’s memory or a separate presentation.

    For your next evaluation session, take a real page group and an unresolved decision into Conductor. Ask the team to carry that decision from raw evidence through SERP context, recommendation, approval, publishing, and measurement. If the context survives every handoff, the platform is doing intelligence work. If your team still exports screenshots and rewrites the rationale elsewhere, you are buying consolidation rather than a unified decision system.
    References

  • How to Protect Brand Authenticity in AI-Assisted Content

    How to Protect Brand Authenticity in AI-Assisted Content

    You need to publish more useful content without turning your brand into a production line of polished, interchangeable pages. AI can remove hours of mechanical work, but it can also remove the judgment, specificity, and recognizable point of view that make your content worth choosing.

    The answer is not to keep AI out of the workflow. It is to decide where efficiency belongs, where a human must remain accountable, and what every page has to prove before you publish it.

    Content quality must serve the reader and the retrieval system

    AI is valuable because it can increase speed and automate repeatable work. The problem begins when a team treats faster production as evidence of better content.

    A page can be grammatically clean, keyword-aware, and structurally complete while still failing the reader. It may repeat familiar advice, hide the answer beneath an introduction, make claims it cannot support, or sound as though no identifiable organization chose the words.

    In the AI era, useful content has to pass several different tests:

    • Accuracy: Can you trace every meaningful factual claim to reliable evidence, and have you preserved any necessary limits or uncertainty?
    • Usefulness: Can the reader make a decision, complete a task, or notice a problem they would otherwise miss?
    • Specificity: Does the page explain the mechanism, constraint, sequence, example, or trade-off behind its advice?
    • Distinctiveness: Does it contain a judgment, method, explanation, or framing that reflects what your brand actually knows and believes?
    • Retrieval clarity: Can a relevant passage stand on its own when a search engine or answer system extracts it from the surrounding page?
    • Brand coherence: Do the vocabulary, promises, evidence standards, and level of certainty match the rest of your site?

    These tests catch different failures. Accurate but generic content is forgettable. Distinctive but unsupported content is risky. Search-ready content that reads like a machine-generated template may earn an impression without earning trust. A page is ready only when it is useful, supportable, recognizable, and easy to interpret.

    Keep human judgment where trust is created

    The safest division of labor is based on accountability, not on whether a task appears easy. Let AI transform approved material. Keep people responsible for deciding what is true, what matters, what the brand believes, and what the reader should do.

    AI is well suited to bounded transformations such as reorganizing notes, proposing outlines, generating headline alternatives, turning a long explanation into a checklist, identifying repeated language, and adapting an approved passage to another format. Those tasks have visible inputs and reviewable outputs.

    Human ownership matters most at the points where an error would change meaning or weaken trust:

    • Selecting the audience, search intent, and decision the page must support.
    • Choosing evidence and deciding which claims the evidence can genuinely carry.
    • Contributing subject expertise, exceptions, operational details, and a defensible point of view.
    • Setting the boundary between established fact, editorial judgment, inference, and uncertainty.
    • Approving promises about products, outcomes, customers, compliance, or performance.
    • Accepting final responsibility for the published page and its structured data.

    For claims that need proof, do not treat model memory as evidence. A fluent sentence can still be unsupported, overgeneralized, or detached from the conditions that made the original claim true.

    Give the model a content contract, not a loose prompt

    A prompt that asks for an authoritative SEO page leaves the important decisions unresolved. Before drafting, create a short content contract with fields an editor can inspect:

    • Reader situation: What has brought this person to the page, and what do they already understand?
    • Reader job: What should they be able to decide or do after reading?
    • Primary claim: What is the clearest answer you are prepared to defend?
    • Evidence packet: Which approved facts, documents, examples, and internal expertise may the draft use?
    • Brand position: What does your organization believe that a generic overview would not say?
    • Claim boundaries: What must not be asserted, implied, invented, or generalized?
    • Voice constraints: Which language patterns should appear, and which should be removed?
    • Retrieval target: Which question deserves a concise, self-contained answer within the page?
    • Next action: What useful step should the reader take, even if they never become a customer?

    Then run the work in an explicit sequence:

    1. A subject owner approves the reader job, primary claim, evidence, and brand position.
    2. AI proposes an outline in which every section resolves a distinct reader question.
    3. An editor removes sections that exist only to make the page look comprehensive.
    4. AI drafts from the approved contract and evidence packet.
    5. A factual pass checks claims, qualifiers, entity names, citations, and unsupported implications.
    6. A separate brand pass checks judgment, vocabulary, tone, repetition, and generic phrasing.
    7. An optimization pass improves headings, answer units, internal links, metadata, and relevant structured data without changing the approved meaning.
    8. A named human owner approves the visible content and machine-readable representation together.

    Separating the passes matters. If one reviewer tries to verify facts, improve voice, shorten sentences, and inspect schema at the same time, the visible polish can distract from a weak claim or an unhelpful answer.

    Turn brand voice into an editing system

    An editor adjusts an unlabeled instrument that turns plain gray tiles into varied designs with a consistent color palette and material style.

    Authenticity does not depend on a human typing every sentence. It comes from a consistent relationship between what your brand knows, what it believes, what it promises, and what it publishes. AI can help express that relationship, but it cannot invent it responsibly.

    Labels such as friendly, expert, bold, or conversational are too subjective to guide a draft. Replace them with observable editorial rules:

    • Beliefs: Record the principles that shape your recommendations. For example, visible content should answer the question before structured data describes the answer.
    • Audience contract: State what you owe the reader. This might include explaining constraints, separating evidence from opinion, and never hiding the practical answer behind a sales pitch.
    • Proof habits: Define when claims need links, examples, named entities, qualifications, or review by a subject expert.
    • Language choices: List preferred terminology, prohibited hype, acceptable contractions, sentence-length tendencies, and the technical terms that must remain precise.
    • Boundaries: Document claims the brand will not make, including guarantees, fabricated experience, invented customer stories, and unsupported comparisons.
    • Approved examples: Save real passages that demonstrate the voice and annotate why they work. A model needs patterns, not just adjectives.

    Consider the difference between a generic claim and an owned editorial position.

    Generic: AI is transforming content marketing and helping businesses improve efficiency.

    Owned: Use AI to compress mechanical work. Keep evidence selection, claim boundaries, and final judgment with an accountable editor.

    The second version is not stronger because it sounds more colorful. It makes a decision, draws a boundary, and tells the reader what to do differently. That is the material from which a recognizable brand voice is built.

    Use a swap test during editing: if a competitor could publish the paragraph unchanged, it probably lacks an owned insight. Do not add a slogan merely to make it sound branded. Add the missing judgment, mechanism, example, limitation, or operating rule.

    Also remove simulated experience. If your organization did not run a test, interview a customer, inspect an account, or observe a result, the draft must not imply that it did. Explain what you know and how you know it. Honest limits are part of brand voice.

    Make content easy for people and answer systems to use

    Optimization for AI search does not require stripping personality from the page. It requires making the important meaning easy to locate, interpret, and reuse without distortion.

    Build important sections as self-contained answer units:

    1. Use a heading that names the actual question or decision.
    2. Answer it in the opening sentence without forcing the reader through background first.
    3. Explain why the answer holds or how the mechanism works.
    4. Name the condition, exception, version, audience, or limitation that changes the advice.
    5. Give the reader a concrete next action.
    6. Link the words carrying an evidence-dependent claim, rather than attaching an unexplained list of links.

    The opening answer provides clarity. The mechanism and limitation provide trust. The recommended action is where brand judgment becomes visible. You can therefore write a passage that is both extractable and distinctly yours.

    Run a context test on each candidate answer unit. Copy the passage into a blank document and ask:

    • Is the subject named, or does the passage depend on a vague pronoun?
    • Can a reader tell whether the statement is a fact, recommendation, definition, or opinion?
    • Are material conditions and exceptions still present?
    • Does the passage identify the product, organization, feature, standard, or audience precisely?
    • Would the passage remain accurate if displayed without the preceding paragraph?

    If the answer unit fails outside its original context, revise the language rather than stuffing more keywords into it.

    Consistency also matters across the site. Use one canonical name for your organization, products, services, features, and authors. Explain genuine synonyms, but do not rotate terminology simply to create lexical variety. Unnecessary variation makes it harder for a person or system to determine whether two passages refer to the same entity.

    Apply the same discipline to JSON-LD and other structured data. Markup should represent the visible page accurately. It should not introduce credentials, ratings, offers, authorship, answers, or relationships that the reader cannot verify in the content. Schema can clarify a strong page; it cannot supply the substance the page is missing.

    Finally, use internal links to connect a concise answer with the deeper proof behind it. A summary page can resolve the immediate question, while a supporting page explains the method, terminology, evidence, or implementation. This creates a useful path for readers without forcing every page to become an exhaustive encyclopedia.

    Replace output metrics with a publish gate and feedback loop

    A circular track carries blank page-shaped objects through a human review station, with one sent back for revision and another released to waiting readers.

    Traditional quality metrics are not enough for AI-first content. Word count, production volume, grammar checks, and a passing optimization score can describe the artifact or workflow, but they cannot establish that the page is accurate, useful, distinctive, or trusted.

    A useful measurement system separates four kinds of signals:

    • Production signals: Track drafting time, approval loops, substantial rewrites, and where work repeatedly returns to an earlier stage. These reveal workflow efficiency, not content quality by themselves.
    • Integrity signals: Track unsupported-claim flags, citation gaps, correction requests, entity inconsistencies, and mismatches between visible content and structured data.
    • Brand signals: Track prohibited language, failed swap tests, unapproved promises, simulated experience, and sections that lack an identifiable editorial position.
    • Discovery signals: Where your tools can observe them, track the queries that surface the page, branded and non-branded visibility, citations or mentions in answer experiences, and referrals from AI interfaces.
    • Outcome signals: Match the page to its intended job, such as a completed setup, qualified inquiry, subscription, product comparison, or movement to a deeper supporting page.

    Read these signals together. Faster production accompanied by more factual corrections means the workflow moved effort downstream rather than removing it. Strong visibility with weak outcomes may indicate that the page answers the query but does not help with the decision behind it. Good engagement with repeated swap-test failures means the page may be useful while doing little to build brand recognition.

    A composite quality score can help you prioritize review, but it should not own the publishing decision. Use a simple editorial gate:

    • Block: A material claim lacks evidence, the page invents experience, a required limitation is missing, an entity is misrepresented, or structured data asserts something the visible page does not support.
    • Revise: The answer is buried, advice remains generic, sections repeat one another, the next action is unclear, or the language fails the brand’s documented rules.
    • Publish: The page answers a real reader need, important claims are supportable, brand judgment is visible, answer units survive the context test, and a named owner accepts responsibility.

    After publication, feed what you learn back into the system. Log corrections with their causes. Add strong and weak passages to the annotated voice examples. Update the content contract when reviewers keep fixing the same omission. Revisit important pages when the offer, evidence, entity information, or reader decision changes.

    Key takeaways

    • Use AI for bounded, reviewable transformations; keep people accountable for evidence, judgment, promises, and approval.
    • Define brand voice through beliefs, proof habits, language rules, boundaries, and annotated examples rather than vague tone adjectives.
    • Write self-contained answer units that give a direct answer, explain the mechanism, preserve limitations, and recommend a useful action.
    • Keep entity language, visible content, internal links, and structured data consistent.
    • Measure production efficiency separately from integrity, brand distinctiveness, discovery, and reader outcomes.
    • Block publication when a material claim, implied experience, or machine-readable assertion cannot be supported.

    Start with one commercially important page. Write its content contract, mark every evidence-dependent claim, run the swap and context tests, and compare its structured data with what a reader can actually see. The weaknesses you find will tell you exactly which rules your wider AI content workflow needs next.

    References

  • How to Measure AI Search Visibility, Traffic, and Results

    How to Measure AI Search Visibility, Traffic, and Results

    Your AI search dashboard can look healthy while telling you almost nothing. A brand mention is not a citation, a citation is not a visit, and a visit is not a business result. Some visits are also hidden inside direct traffic, so even the traffic line is incomplete.

    You need a measurement system that keeps exposure, traffic, and outcomes separate until the evidence connects them. That gives you defensible reporting, reveals attribution gaps, and tells your content team what to improve next.

    Measure visibility, traffic, and outcomes as separate layers

    The first mistake is forcing AI search into a single channel metric. Conventional analytics starts when somebody reaches your site. AI visibility starts earlier, when an answer engine decides whether to mention your brand, cite your page, or use another domain instead.

    That distinction matters because AI search optimization depends on understanding intent and satisfying the underlying need. A useful answer may earn visibility without earning a click. Conversely, a person may encounter your brand in an AI answer and visit later through branded search, a bookmark, or an untagged direct session.

    Measurement layerWhat you recordQuestion it answers
    VisibilityPrompt observations, brand mentions, citations, cited URLs, answer accuracy, competing domainsAre AI systems representing and recommending you?
    TrafficRecognized AI referrals, landing pages, engagement, and unattributed visits kept in a separate uncertainty cohortWhich observable visits came from AI experiences?
    OutcomesQualified actions, leads, sales, subscriptions, assisted conversions, or another result matched to the page’s purposeDid the exposure or visit create value?

    Do not add these layers into one score. They have different denominators and different blind spots. Report them together, but preserve the path from observation to result.

    Keep individual surfaces separate as well. Google AI Overviews and AI Mode can be measured as distinct environments; the same principle applies whenever platforms offer materially different answer experiences. A combined “AI visibility” total can hide a gain on one surface and a loss on another.

    Build a repeatable AI visibility panel

    A circular monitoring instrument repeatedly samples blank query cards, web-page tiles, citation symbols, and geometric brand tokens arranged in a grid.

    A visibility score only means something when it comes from a stable observation panel. If the prompts, locations, devices, or account conditions change between runs, a rising score may reflect a different sample rather than better performance.

    Start with the questions that matter to the customer’s decision, not a large list of convenient keywords. Include the different jobs an answer engine may be asked to perform:

    • Problem discovery: questions describing the pain, task, or desired outcome before the customer knows the category name.
    • Category evaluation: requests for approaches, tools, providers, or methods that could solve the problem.
    • Comparison: prompts asking about differences, trade-offs, alternatives, or selection criteria.
    • Validation: questions about implementation, compatibility, limitations, trust, or evidence.
    • Brand and entity checks: prompts that test whether the system understands what your organization does and when it is relevant.

    Group those prompts by topic and intent. Assign each prompt a permanent identifier so wording changes do not break the historical series. When you add, remove, or rewrite prompts, version the panel and mark the change on the dashboard.

    For every observation, retain enough context to reproduce or explain it:

    • Platform and answer surface
    • Exact prompt and prompt identifier
    • Observation time
    • Country, language, device class, and account state when those conditions can affect the answer
    • Full answer or a durable capture of it
    • Whether the brand appears
    • Whether the brand is recommended, merely listed, or mentioned in another context
    • Every cited domain and URL
    • Whether an owned page receives a clickable citation
    • Competing brands and domains appearing in the same answer
    • Whether important claims about the brand are accurate, incomplete, or wrong

    The raw observation is essential. A dashboard total cannot explain whether a lost citation resulted from answer variability, a changed prompt, a removed page, or a competitor becoming more useful for the question.

    Use metrics with explicit denominators

    Define every visibility metric in the measurement specification before publishing it. Useful definitions include:

    • Answer presence rate: observations in which the brand appears, divided by eligible observations in the tracked panel.
    • Citation rate: observations containing a link to any supporting page, divided by eligible observations.
    • Owned citation rate: observations citing an owned URL, divided by eligible observations.
    • Recommendation rate: observations that recommend or shortlist the brand, divided by observations in which a recommendation could reasonably occur.
    • Cited-page distribution: the owned URLs receiving citations and their share of all observed owned citations.
    • Accuracy rate: brand-containing observations without a material factual problem, divided by all brand-containing observations reviewed for accuracy.

    Label these as observed rates within your tracked panel. They are not market-wide shares. A prompt set weighted toward your strongest topics will naturally produce a better result than one weighted toward unfamiliar categories.

    Mentions and citations also need separate fields. A brand can be visible without receiving a link, while an owned page can be cited without the brand playing a prominent role in the answer. Treating both as “wins” prevents you from knowing whether to strengthen entity clarity, improve page-level evidence, or fix a specific claim.

    Repeat observations under declared conditions and preserve the individual results. AI answers can vary, so one response should not become a permanent ranking claim. Any platform used to monitor brand visibility and authority in AI search should let you inspect the observations behind its aggregate score and export them for independent analysis.

    Recover AI referral traffic without relabeling direct visits

    Tagged and untagged visit particles flow through a website gateway, where an analysis device reconnects some hidden visits to their referral source.

    Referral reporting gives you a useful lower bound, not a complete count. When an AI experience passes a recognizable referrer, analytics can map that visit into an AI referral channel. When it does not, the session may land in direct traffic.

    This is particularly important on mobile: clicks from LLM apps such as ChatGPT can appear as direct traffic. That behavior creates an attribution gap, but it does not make every mobile direct visit an AI visit. Direct traffic also contains other sessions with missing or unavailable acquisition information.

    Create a known AI referral channel

    Build the channel from acquisition values you can actually observe. The implementation should be auditable:

    1. Preserve the original referrer, source, medium, landing URL, device class, and timestamp before applying channel rules.
    2. Maintain a version-controlled mapping of observed AI-related referrer hostnames and acquisition values. Record when each rule becomes active.
    3. Normalize matching visits into a “Known AI referral” channel while retaining the original value for investigation.
    4. Separate human referral sessions from crawler or bot requests. A request from an AI crawler is not evidence that a person saw or clicked an answer.
    5. Review unmatched referrals and sudden direct-traffic changes as part of routine data quality work. Update the mapping only when the evidence supports the classification.

    Never overwrite the raw acquisition field. Platform naming and referral behavior can change, and you will need the original value when rebuilding historical classifications.

    Keep possible AI visits in an uncertainty cohort

    You can create a diagnostic cohort for unattributed visits that have characteristics consistent with AI discovery. For example, a direct session may land on a deep informational page shortly after that page begins appearing as a citation in your visibility panel. That is a useful investigation signal, not proof of origin.

    Name the cohort honestly, such as “Unattributed direct visits to AI-visible pages.” Show it beside known AI referrals, not inside them. Do not use the entire cohort as an upper estimate of AI traffic unless you have a validated model that accounts for the other reasons referrer data may be absent.

    UTM parameters help only on links you control. Use consistent utm_source, utm_medium, and utm_campaign values in owned assistant experiences, profile links, campaigns, or other placements where you set the destination URL. You cannot reliably retrofit tracking parameters onto citations independently generated by a third-party answer engine.

    This produces two honest traffic views: confirmed referrals and a separately labeled attribution gap. That is less dramatic than claiming every unexplained session, but it gives analytics, SEO, and leadership a number they can defend.

    Connect AI exposure to business outcomes

    Visibility is useful only in relation to the job the page and brand need to perform. An informational page may be expected to move a reader toward another resource. A product page may need to generate a trial, purchase, or sales conversation. A support page may need to resolve a task without creating another contact.

    Assign a primary outcome to every URL that appears in the visibility panel. Then inspect the complete path:

    • Observed exposure: the brand or owned page appears in an answer.
    • Citation opportunity: the answer includes a clickable owned URL.
    • Attributable visit: analytics records a known AI referral.
    • Qualified action: the visitor completes the action appropriate to that page.
    • Commercial or operational outcome: the action becomes revenue, pipeline, retention, resolution, or another defined business result.

    Preserve the denominator at each transition. Referral conversion rate uses known referral sessions, not all visibility observations. Citation click-through cannot be calculated unless you know both the eligible citation exposures and the resulting clicks. When the exposure count is unavailable, call the visit count a referral count rather than a click-through rate.

    Use page and query cohorts when evaluating broader search effects. AI Overviews can affect website traffic, but a before-and-after change in total organic sessions does not isolate that effect. Rankings, demand, seasonality, site releases, measurement changes, and competing search features can move at the same time.

    A more defensible impact analysis follows this sequence:

    1. Define the event you are evaluating, such as an AI Overview beginning to appear for a tracked query group or an owned page gaining citations.
    2. Freeze the affected query and landing-page cohort so its membership does not drift during the comparison.
    3. Select a comparison cohort with similar intent or page type that did not experience the same observed change.
    4. Compare trends by query group, landing page, device, and geography where the data supports those cuts.
    5. Annotate ranking changes, content releases, tracking changes, campaigns, and demand shifts that could explain movement.
    6. Report the result as an observed association unless the design supports a stronger causal conclusion.

    Low traffic does not automatically mean low value. An unclicked mention can still influence later discovery, while a high referral count can fail to produce qualified actions. Keep brand representation, referral performance, and business contribution visible as separate outcomes.

    Your operating dashboard should therefore include the panel version and observation conditions, mention and citation metrics, known referral sessions, the unattributed diagnostic cohort, landing-page outcomes, and annotations for material changes. Set alerts from your own historical variation rather than adopting a generic threshold that ignores the size and stability of your prompt panel.

    Key takeaways

    • Measure AI visibility, referral traffic, and business outcomes as connected but distinct layers.
    • Use a fixed, versioned prompt panel and retain the raw answers behind every aggregate score.
    • Separate brand mentions, recommendations, citations, and owned-page citations because each calls for a different optimization decision.
    • Treat recognized AI referrals as a defensible lower bound. Keep suspicious direct visits in a clearly labeled uncertainty cohort rather than reclassifying them as confirmed AI traffic.
    • Evaluate traffic changes with fixed page and query cohorts, comparison groups, and annotations for other changes that could affect performance.

    Start with a high-value topic cluster and write the measurement specification before building the dashboard. Capture the prompts, answer conditions, cited pages, known referrals, and page-level outcomes in the same workflow. Once that chain is visible, your next content decision will come from evidence instead of a single opaque AI visibility score.

    References

  • Google SERP Changes: How to Keep Rank Tracking Reliable

    Google SERP Changes: How to Keep Rank Tracking Reliable

    Your ranking report drops overnight, dozens of keywords disappear, and the obvious reaction is to start fixing pages. Pause there. If Google changed what a rank tracker can collect, the chart may be showing a measurement break rather than a search-performance loss.

    You need to establish which system changed before you rewrite content, alter internal links, or escalate the result to stakeholders. The process below will help you separate collection failures from genuine ranking movement, preserve usable history, and rebuild a baseline you can trust.

    First decide whether search visibility or measurement changed

    A tracked rank is an observation, not a permanent property of a page. A tool submits a query with a defined location, language, device, and collection method, then records what it can retrieve and parse. The resulting position depends on both Google’s SERP and the tracker’s ability to observe it.

    When Google changes how a 100-result SERP can be collected, a tracker designed around the previous result set may receive different structure, shallower coverage, or incomplete observations. That can make keywords appear to fall out of the tracked range even when the underlying pages have not suffered an equivalent loss.

    This distinction matters because “not found” is not a rank. It means the tracker did not observe the URL within the result set it successfully collected. The page may have moved lower, the collection may have ended sooner, parsing may have failed, or a different URL may have appeared. Treating every missing observation as the worst possible position turns a technical unknown into a false SEO conclusion.

    Clues that point to a collection problem

    • The change begins on the same crawl or reporting date across unrelated keyword groups, directories, and sites.
    • Most of the apparent losses come from keywords that previously sat near the deepest part of the collected result set.
    • Missing, unknown, timeout, or error statuses rise at the same time as reported visibility falls.
    • The maximum observed depth changes, or the tracker stops returning URLs that used to appear below the most visible result bands.
    • Several unrelated competitors also seem to disappear rather than replace one another.
    • Google Search Console impressions, clicks, and landing-page patterns do not show a comparable break.

    Clues that point to genuine ranking movement

    • Fresh SERPs are collected successfully, and other domains consistently occupy the positions your pages lost.
    • The decline clusters around a meaningful unit such as a template, directory, page type, topic, market, or search intent.
    • The same URLs lose impressions or clicks in Google Search Console, after accounting for changes in search demand.
    • Multiple observations made with equivalent settings reproduce the movement.
    • The loss appears in the visible result bands, not only at the collection boundary.

    Google Search Console and a rank tracker should corroborate one another, but they will not match exactly. Search Console aggregates positions from real impressions across users and contexts. A tracker records controlled snapshots under its configured conditions. Use Search Console to test whether the direction and affected pages make sense, not to force a one-to-one position match.

    Audit the measurement contract behind every ranking chart

    An open data-collection device is inspected beside symbols for device type, location, language, browser, and time.

    Before changing a tool, project, or keyword set, preserve the evidence. Export the raw observations, keyword configuration, tags, error statuses, and latest unaffected report. Overwriting the setup first can erase the information you need to locate the break. A dated export is the safer starting point.

    Next, write down the measurement contract for the project. This is the exact set of conditions under which a rank is considered comparable. Because Google’s search environment and operational guidance continue to evolve, this contract should be versioned like any other analytics configuration.

    • Search engine and search property being queried.
    • Country, language, and city or regional targeting.
    • Desktop or mobile device profile.
    • Keyword universe, tags, exclusions, and ownership rules.
    • Collection cadence and the timing of scheduled runs.
    • Maximum depth the tracker attempts to inspect.
    • Whether organic results and SERP features are counted separately.
    • How canonical URLs, redirects, parameters, and alternate URLs are consolidated.
    • How missing results, collection errors, and successful no-rank observations are stored.
    • The provider, collector, or configuration version used for the run.

    If one of these dimensions changes, the observation series may no longer be directly comparable. A switch from desktop to mobile is not a continuation of the same experiment. Neither is a change in location, checked depth, keyword membership, URL consolidation, or SERP-feature handling.

    Run a controlled side-by-side check

    1. Select a stable basket containing branded and non-branded queries, visible and deep-ranking pages, and more than one site section.
    2. Run the queries with the same location, language, device, and search property used in the historical project.
    3. If the old and revised collection methods are both available, run them close enough together that normal SERP movement is unlikely to dominate the comparison.
    4. Compare observation coverage, maximum collected depth, returned URL, organic position, error status, and visible SERP features.
    5. Open a manual sample only as a diagnostic check. Match the tracker’s settings as closely as possible and do not treat your personalized browser view as a definitive benchmark.

    A clear pattern is more useful than a large sample with mixed settings. If the revised method repeatedly finds the same URLs while the historical method returns missing observations, you have evidence of a collection discontinuity. If both methods collect valid SERPs and show competitors replacing your pages, investigate an actual visibility loss.

    Rebaseline the data without erasing useful history

    Once a collection change is confirmed, resist the temptation to splice the new numbers onto the old chart as if nothing happened. Keep the historical series, mark the discontinuity, and establish which metrics remain comparable.

    Your data model should distinguish these states:

    • Observed and ranked: the SERP was collected successfully and the tracked URL was found.
    • Observed but not ranked within the configured depth: collection succeeded, but the URL was not present in the checked range.
    • Unobserved because collection failed: no valid ranking conclusion can be made.
    • Not scheduled or excluded: the keyword was intentionally absent from that run.

    Store an unknown observation as null with a separate status code. Do not convert it to a worst rank, carry the previous rank forward, or quietly remove the keyword from the denominator. Each shortcut changes the meaning of the metric and can manufacture a trend.

    Use these rules when establishing the revised baseline:

    • Annotate the first affected crawl and the first run made with the revised method.
    • Preserve raw pre-change and post-change data in separate views, even if the dashboard presents a continuous timeline.
    • Calculate comparable visibility using only keywords observed under equivalent device, location, depth, and processing rules.
    • Keep a fixed keyword cohort for trend reporting. Report additions and removals separately so keyword-set churn does not masquerade as growth.
    • Show “not comparable” for position deltas that cross the method boundary unless you have validated equivalence.
    • Backfill only when the historical collection conditions can genuinely be reproduced. A modeled reconstruction is not an observed historical rank and should be labelled accordingly.
    • Recalculate alert thresholds after the revised method has completed the normal reporting cadence used for decisions. Thresholds based on the previous distribution may trigger false alarms.

    You can still retain a long-term view. Present the historical series with a visible method-change marker, then use a separate comparable cohort for trend analysis. This preserves context without pretending the two measurement regimes are identical.

    Report coverage, visibility, and business outcomes separately

    Three connected chambers depict data collection, search-result visibility, and customer outcomes as separate measures.

    A single average rank cannot tell you whether the collector failed, positions moved, demand changed, or clicks fell. A defensible report separates those questions so the reader can see both the SEO result and the quality of the measurement.

    SignalQuestion it answersReporting rule
    Collection coverageCould the tracker observe the scheduled SERPs?Show valid observations against scheduled observations, with collection errors reported separately.
    Comparable visibilityDid rankings move for a consistently measurable keyword set?Use the intersection of keywords collected under equivalent depth, device, location, and processing rules.
    Position distributionWhere did movement occur?Show visible, deeper, and unobserved bands instead of relying only on an overall average.
    Search demandDid the available opportunity change?Review Google Search Console impressions by query, page, country, and device using consistent filters.
    Search outcomesDid organic visits or valuable actions change?Review clicks, click-through rate, landing-page sessions, and relevant conversions alongside rankings.
    Competitor replacementDid another domain take the observed space?Count actual replacements in valid SERPs; do not interpret shared missing data as a competitive gain.
    SERP compositionDid the result layout change around the organic listings?Track result features separately from organic position so layout changes remain visible.

    Lead each recurring report with collection coverage. If coverage is unhealthy, qualify every downstream ranking metric. Then show comparable visibility and position distribution, followed by Search Console and conversion outcomes. This order prevents a broken collector from becoming an unsupported story about traffic or revenue.

    Use an explicit note when the method changes: “Measurement note: On [date], the SERP collection method changed. Pre-change and post-change positions are shown for context, while trend calculations use the validated comparable keyword cohort. Coverage errors are excluded from ranking-loss counts.” Replace the placeholders with the actual date, scope, and treatment.

    Do not bury that explanation in a dashboard footnote. Anyone deciding whether to change content, budgets, forecasts, or team priorities needs to know where measurement comparability ends.

    Key takeaways for your next rank-tracking review

    • Diagnose the collection layer before treating a sudden visibility decline as an SEO loss.
    • Keep “not ranked” separate from “not observed”; they describe different events and require different responses.
    • Version the location, device, depth, keyword set, URL rules, and collection method behind every ranking series.
    • Preserve raw history, annotate the method boundary, and compare only observations gathered under equivalent conditions.
    • Pair rank data with collection coverage, Google Search Console signals, competitor replacements, and business outcomes.
    • Explain measurement changes in the main report so stakeholders do not act on a false trend.

    Before your next scheduled report, export the last clean dataset, mark the suspected transition date, and rerun a stable keyword basket under matched settings. That gives you the evidence to decide whether the next task belongs in your content backlog or your measurement pipeline.

    References

  • How to Choose AI Visibility and AEO Tools That Pay Off

    How to Choose AI Visibility and AEO Tools That Pay Off

    You have a shortlist of AI visibility tools, but every dashboard appears to promise the same thing: better presence in AI-generated answers. The difficult part is determining whether a platform will help you make better decisions or simply give you another score to report.

    The right choice starts with a narrower question: what must the tool help you observe, explain, or change? Once you define that job, you can test coverage, evidence quality, workflow fit, pricing, and business value without relying on a polished demo.

    Key takeaways

    • Choose the primary job first: monitoring AI answers, diagnosing visibility gaps, or implementing content and product-data changes.
    • Require the underlying answer, citation, query, surface, and observation time behind every visibility score.
    • Keep mentions, citations, recommendations, sentiment, and factual accuracy as separate measures. They answer different questions.
    • Evaluate pricing against your actual workload: queries, AI surfaces, markets, observation frequency, users, exports, and implementation needs.
    • Run a controlled pilot on a fixed query set before committing. Measure both AI visibility signals and the business outcomes the work is supposed to support.
    • For ecommerce, test whether the platform can keep product pages, structured data, and commercial facts consistent across ChatGPT, Google, and Amazon workflows.

    Match the tool to the job you actually need done

    AEO now spans tools, software, and broader platforms. That wide label can hide important differences. A visibility monitor, a content recommendation system, and a product-page optimizer may all call themselves AEO tools, even though they solve different operational problems.

    We find it useful to divide the market into three jobs:

    Primary jobWhat the tool should produceWhat should make you cautious
    ObserveCaptured AI answers, mentions, citations, linked domains, query context, and changes over timeA proprietary visibility score with no underlying responses
    ExplainQuery-level and page-level evidence showing where coverage, accuracy, authority, or content is weakGeneric advice that could apply to any page or brand
    ActSpecific edits, structured-data changes, product-data corrections, workflow assignments, or implementation exportsAutomated publishing without a preview, approval record, or rollback path

    A single platform may do more than one job. That is useful only if each capability is strong enough for your workflow. A content optimizer with a small tracking widget is not automatically a robust monitoring system. A tracker that identifies a weak answer is not automatically capable of fixing the page behind it.

    Write your primary use case in one sentence before you attend a demo. For example: “We need to see when our brand is cited for high-intent category questions, identify which competing domains are cited instead, and assign the affected pages to the content team.” That sentence gives you a testable requirement. “We need better AI visibility” does not.

    Ask which surfaces are truly covered

    Do not treat “AI search” as one channel. Name the surfaces that matter to your audience and ask the vendor to demonstrate each one. For an ecommerce company, that might include ChatGPT, Google, and Amazon. For another business, the relevant set may be different.

    • Which named AI experiences can the platform observe directly?
    • Does it store the complete generated answer or only a derived score?
    • Can you see the cited URL and domain, rather than a citation count alone?
    • Can results be segmented by brand, product line, market, language, and query group?
    • Does the tool distinguish a brand mention from a linked citation or explicit recommendation?
    • Can you export the observations and their metadata for independent analysis?

    Ask the salesperson to run one of your real queries and open the evidence behind the result. If the platform cannot move from a summary chart to the captured answer, you will struggle to investigate changes or defend the number internally.

    Normalize pricing to your workload

    The practical buying decision includes both feature fit and pricing fit. Sticker prices are difficult to compare until you identify what consumes the allowance. A “query” might mean a saved prompt, one observation on one AI surface, or a recurring set of observations. Those are not equivalent units.

    Build a workload estimate using the variables you control: your tracked query set, required AI surfaces, markets or languages, observation frequency, team seats, reporting needs, and implementation volume. Then ask for the cost of that workload, including exports, API access, onboarding, additional projects, and overages where applicable.

    The least expensive plan can become the wrong choice if it forces you to remove important query segments or makes raw evidence inaccessible. The most expensive plan can also be wasteful if your immediate need is a focused baseline and a content workflow. Buy enough coverage to support a decision, not the largest dashboard available.

    Require evidence you can audit and explain

    An analyst traces glowing connections from an abstract AI response to source documents and examines the evidence with a magnifying lens.

    A visibility score is a summary, not a fact by itself. Before you trust it, you need to understand the observations underneath it and the denominator used to calculate it.

    At minimum, each observation should let you recover:

    • The exact query or prompt.
    • The AI surface on which it was checked.
    • The complete answer captured by the platform.
    • The brand, product, or entity detected in that answer.
    • Any cited or linked URLs and domains.
    • The time of the observation.
    • The market, language, and other execution context you asked the platform to control.
    • The rule used to classify the result.

    This record matters because several different events are often compressed into the word “visibility.” Your brand can be mentioned without being cited. Your page can be cited without the answer describing your product accurately. Your competitor can appear more often while your own brand receives the stronger recommendation. One blended score can conceal all of those situations.

    Define each metric before the dashboard defines it for you

    You do not need an elaborate measurement model at the beginning. You do need stable definitions. A workable starting set is:

    • Mention rate: eligible observations in which the brand appears, divided by all eligible observations.
    • Citation rate: eligible observations that cite an owned URL, divided by all eligible observations.
    • Recommendation rate: eligible observations in which the brand is presented as a suitable choice, divided by all eligible observations.
    • Answer accuracy: assessed brand or product claims that match your approved facts, divided by all assessed claims.
    • Query coverage: tracked intents with usable observations, divided by the full query set you intended to monitor.
    • Cited-domain distribution: the domains receiving citations within each query segment, shown separately from brand mentions.

    Document what “eligible” means for every measure. A navigational query containing your brand name should not be allowed to inflate performance for non-branded discovery questions. Likewise, a category query and a product-support question represent different jobs for the reader and should not be blended without segmentation.

    Accuracy deserves its own review process. Automated classification can help sort a large queue, but a human should assess claims that could misrepresent the product, price, availability, compatibility, policy, or regulated information. A highly visible wrong answer is not a successful outcome.

    Demand recommendations tied to evidence

    A useful recommendation identifies the affected query, the observed answer, the competing or cited material, the relevant page, and the proposed change. “Add more authority” is not an actionable diagnosis. “Clarify the compatibility requirements on this product page because the tracked answer describes the supported model incorrectly” gives a team something it can verify and fix.

    Apply the same standard to schema recommendations. The tool should identify the page, property, current value, proposed value, and reason for the change. Structured data must remain consistent with the information a visitor can see. Schema is not a safe place to insert claims that the page itself cannot support.

    Run a controlled pilot before making the tool operational

    A demo shows whether a platform can tell a convincing story. A pilot shows whether your team can use it to improve a real workflow. Keep the pilot narrow enough that you can trace an observation to a decision, an implementation, and a measured result.

    1. Freeze the query set. Group questions by intent, such as category discovery, comparison, brand validation, product detail, purchase support, and post-purchase support. Keep branded and non-branded questions separate.
    2. Capture a baseline. Store multiple observations before editing pages. Generated answers can vary, so a single before-and-after pair is weak evidence.
    3. Select a focused page group. Choose pages connected to the tracked queries. Keep a comparable group unchanged where practical so normal movement is easier to distinguish from the effect of your work.
    4. Change one class of problem at a time. Examples include correcting product attributes, making an answer explicit in visible copy, resolving conflicting descriptions, or aligning structured data with the page.
    5. Record the implementation. Log the page, previous value, new value, publication time, owner, approval, and reason. Without that record, later movement is difficult to interpret.
    6. Repeat the same measurement. Use the same queries, segments, surfaces, and review rules. Do not quietly replace difficult prompts with easier ones after the baseline.
    7. Evaluate AI and business outcomes separately. Look at mentions, citations, recommendations, and accuracy, then compare those changes with the relevant onsite behavior or conversion measure available in your analytics.

    Set the pass conditions before the pilot begins. A reasonable decision rule should specify which query groups matter, which visibility signals must improve, which accuracy checks must pass, and what workflow burden is acceptable. This prevents a vendor’s strongest dashboard movement from becoming the success criterion after the fact.

    Do not call a pilot successful merely because the tool generated a long task list. Judge whether your team could understand the recommendation, approve the right change, publish it safely, and see the resulting evidence. A tool that creates more tickets without improving decisions is adding activity, not capability.

    Check operational fit while the pilot is running

    The best analysis still fails if it cannot enter your production process. During the pilot, ask the people who will use the platform to test the full handoff:

    • Can an analyst assign an issue to the correct page and owner?
    • Can an editor see the observed answer and the evidence behind the proposed change?
    • Can technical teams export or integrate the required data without rebuilding the report manually?
    • Can reviewers approve, reject, or amend generated recommendations?
    • Can the team see who changed what and restore the previous version?
    • Can reports preserve query segments instead of collapsing everything into one brand score?

    These are not secondary conveniences. They determine whether insight survives the handoff from an SEO or AEO specialist to content, engineering, ecommerce, legal review, or product operations.

    Ecommerce needs a product-data workflow, not just tracking

    Unbranded products move through linked data-validation stations before reaching digital answer channels and online shoppers.

    Ecommerce raises the cost of vague or stale information. A customer may ask about a product’s fit, specification, variant, availability, or use case rather than searching for the product name alone. The optimization workflow therefore has to connect AI observations with the product detail page and the system that owns each commercial fact.

    Some commerce-focused products are explicitly positioned around AI visibility, product detail page improvement, and conversion support across ChatGPT, Google, and Amazon. Treat that positioning as a use-case claim to test, not proof of an outcome. Better conversion performance requires measurement in your own commerce analytics; an AI visibility dashboard cannot establish it by assertion.

    For every product included in a pilot, review the information AI systems and shoppers are expected to reconcile:

    • Entity identity: the product name, brand, model, category, and relationship to variants or bundles.
    • Core attributes: dimensions, materials, compatibility, intended use, limitations, and other facts that affect the purchase decision.
    • Commercial facts: price, availability, shipping information, and return conditions, with clear ownership for keeping them current.
    • Variant boundaries: which attributes belong to the parent product and which change by size, color, model, region, or configuration.
    • Visible explanations: concise page copy that answers important product questions without requiring an inference from scattered fields.
    • Structured representation: schema and feed values that agree with the visible page and the approved product record.
    • Supporting evidence: documentation or approved internal material that lets an editor verify claims before publishing them.

    Ask the tool to show how it handles a conflict. If the page description, structured data, and product feed disagree, does it identify the conflicting values and their locations? Can it route the problem to the owner of the authoritative product record? An optimizer that simply rewrites the description may make the conflict harder to detect.

    Also test each target surface independently. Coverage in ChatGPT does not demonstrate coverage in Google or Amazon, and an improvement on one surface does not prove the same change caused movement on another. Keep observations segmented, then look for changes that improve product clarity everywhere without creating channel-specific contradictions.

    Put guardrails around automated changes

    Automation is most useful after your ownership and approval rules are clear. Require a preview or diff before publication, retain the previous value, and route high-impact fields through the appropriate reviewer. Price, availability, compatibility, safety language, policies, and regulated claims should not be silently rewritten from an AI recommendation.

    Your next move is simple: write the one-sentence job for the tool, build a fixed query set around that job, and ask each shortlisted vendor to demonstrate the underlying evidence with your data. If it cannot connect an AI answer to a defensible action and a measurable outcome, remove it from the shortlist.

    References

  • AEO Visibility Strategy: Build Authority and Measure Results

    AEO Visibility Strategy: Build Authority and Measure Results

    You can publish technically clean, accurate content and still disappear from AI answers. Standard web analytics may not explain why. An answer can omit your brand, describe it incorrectly, mention it without a link, or cite a competitor without sending anyone to your site.

    The practical fix is to stop treating answer engine optimization as a publishing checklist. Connect the questions you want to own, the evidence an answer engine can use, the authority supporting that evidence, and repeated measurement of the answers themselves. You can then tell whether you have a discovery problem, an authority problem, a citation problem, or simply a measurement gap.

    Define visibility as an answer-level outcome

    A goal such as rank in AI search is too loose to manage. It doesn’t identify the audience, the relevant questions, the surfaces being measured, or what a successful answer should contain.

    Write a testable goal instead: when a defined audience asks a defined class of questions on a named AI surface, your organization should be accurately associated with the relevant category, included when it is genuinely eligible, and supported by an appropriate citation when the interface provides citations.

    That qualification matters. Not every answer should mention your brand, and not every interface displays links in the same way. Decide which prompts make your brand eligible before you inspect the results. Otherwise, teams tend to label irrelevant omissions as failures and flattering but commercially useless mentions as wins.

    The V3 AEO Periodic Table organizes 15 visibility elements from 2.2 million live prompts across platforms including ChatGPT, Gemini, and Claude. Treat that breadth as an important warning: visibility is a multivariable outcome. It is not proof that one fixed checklist controls every engine or interface.

    Keep the following measures separate in your scorecard:

    • Eligible mention rate: Of the tracked prompts where your brand could reasonably help, how often is it named?
    • Owned citation rate: How often does the answer link to a relevant page you control when citations are displayed?
    • Corroborating citation rate: How often does an independent reference support the claim or association you want to establish?
    • Framing accuracy: Are your category, capabilities, limitations, audience, and other material facts represented correctly?
    • Prominence: Is the brand a primary recommendation, one item in a longer set, a passing example, or a caution?
    • Competitive inclusion: Which eligible competitors appear when you do not, and what evidence is cited for them?
    • Action quality: Does the answer expose a useful next step, such as a relevant page, branded lookup, qualified referral, or measurable conversion path?

    Do not collapse those measures into one opaque visibility score. A brand can have a healthy mention rate and poor factual accuracy. It can earn citations for informational questions while disappearing from purchase-oriented comparisons. One average conceals both problems.

    Preserve the raw evidence behind every result. Record the exact prompt, query group, platform and interface, visible model label when available, language, market, date, session conditions, full answer, displayed URLs, competitors, sentiment or recommendation type, factual errors, and reviewer notes. A percentage without the underlying answers cannot tell your content, technical, or PR teams what to change.

    Build a prompt portfolio around real decisions

    AEO measurement starts with prompts, not keywords. A keyword can indicate a subject; a prompt exposes the decision, constraints, and evidence the user expects. Your tracked set should represent the questions that move someone from recognizing a problem to evaluating a solution and verifying a choice.

    Organize prompts into decision groups so that a gain in one part of the journey cannot disguise a loss elsewhere:

    • Problem discovery: Questions about symptoms, risks, causes, or ways to approach a problem without naming a product category.
    • Category education: Questions asking what a type of solution is, how it works, or when it is appropriate.
    • Criteria and comparison: Questions about alternatives, tradeoffs, required capabilities, and fit under specific constraints.
    • Validation: Questions about credibility, evidence, safety, compatibility, implementation, limitations, or reputation.
    • Branded facts: Questions about your entity, offering, policies, integrations, leadership, or other facts you should be able to support directly.
    • Post-selection use: Questions a customer asks while adopting, operating, troubleshooting, or expanding the solution.

    Use two prompt sets. Keep a core set unchanged so you can compare performance over time. Maintain a separate exploratory set for new customer language, competitor movements, emerging objections, and product changes. If a core prompt needs revision, create a new version and retain the old wording in the record. Silently rewriting a prompt after an unfavorable result destroys the trend line.

    Brand-heavy prompts are useful for checking entity accuracy, but they are a poor proxy for discovery. A system may repeat your name correctly when the user supplies it and still fail to associate you with the unbranded problem you solve. Report branded and unbranded results separately.

    Keep test conditions as consistent as the interface permits. Use the same language, market, session state, and prompt wording for trend checks. If repeated runs produce different answers, preserve the variation instead of selecting the most favorable response. Likewise, do not merge ChatGPT, Gemini, Claude, and other surfaces into one trend line. A change on one surface is a finding about that surface until the others confirm it.

    Match monitoring speed to consequence. Reputation-sensitive inaccuracies and active launches justify alert-oriented observation, while stable category prompts can be evaluated in consistent batches. The value of real-time content monitoring is faster response to meaningful changes, not a busier dashboard. An alert should identify the affected prompt, changed claim, cited URL, and responsible owner.

    Turn your content into an authority system

    A modular knowledge hub connects blank document tiles, research materials, experts, independent source nodes, and glowing answer orbs.

    Authority is not a confident tone, a high word count, or a page labeled definitive. For AEO, a useful authority system makes important claims explicit, gives those claims verifiable support, defines their scope, and keeps the same entity facts consistent wherever they appear. Trust and earned citations are central to authoritative GEO content because an answer needs more than a sentence it can extract; it needs a reason to rely on that sentence.

    Start with a claim-evidence ledger. For every answer you want your brand to influence, record:

    • the audience question and intent;
    • the precise claim you are qualified to make;
    • the canonical page responsible for that claim;
    • the evidence, method, policy, documentation, or primary record supporting it;
    • the conditions and limitations that prevent overstatement;
    • the person or team accountable for accuracy;
    • the last meaningful verification date;
    • independent corroboration, where it exists; and
    • the structured data that accurately describes the visible page.

    This ledger exposes a common failure: several pages make slightly different versions of the same claim, while none is clearly maintained as the source of truth. Consolidate the fact on one canonical destination. Let supporting pages summarize it accurately and link back rather than inventing another formulation.

    Audit each priority page for citation readiness:

    • Answer the primary question directly near the relevant heading.
    • Name the entity, category, audience, and scope without forcing the reader to infer their relationship.
    • Place supporting evidence and necessary caveats beside the claim they qualify.
    • Identify the author, editor, reviewer, organization, or accountable team where that context affects credibility.
    • Use descriptive headings and stable URLs so a specific section can be found and referenced.
    • Make important facts available as text rather than hiding them only in images, interactive elements, or downloadable files.
    • Connect the page to related definitions, methodology, documentation, comparison criteria, and entity pages through purposeful internal links.
    • Show a meaningful updated date only when the underlying information has actually changed.
    • Ensure JSON-LD describes the visible content and uses the appropriate entity relationships.

    JSON-LD can clarify what a page and its entities represent. It cannot turn an unsupported assertion into evidence, repair contradictory facts across your site, or force an answer engine to cite you. Treat schema as a precise description layer over trustworthy content, not as a substitute for it.

    A citation-ready passage should still make sense when read outside the surrounding page. A practical pattern is: [Entity] is a [category] for [audience]. It provides [capability] within [defined scope]. The claim is supported by [method, documentation, or primary record], current to [date or version]. Replace every placeholder with information you can substantiate. If you cannot complete the evidence field, narrow the claim before publishing it.

    Self-contained does not mean stripped of nuance. Put material qualifications next to the sentence they constrain. If the caveat is several screens away, the extracted claim may become broader than your evidence allows.

    Use PR to close corroboration gaps

    Your website can establish what you say about yourself. It cannot create independent agreement by repeating the same claim across more owned pages. When an important answer requires outside confirmation, PR and content distribution should be planned around the evidence gap rather than raw mention volume.

    AI-assisted media monitoring can connect PR activity with AEO visibility, but the connection only becomes useful when both teams work from the same target claims. A publicity report counting every mention will not show whether the market now associates your brand with the right category or whether an answer engine has found stronger evidence.

    Use this workflow for each priority claim:

    1. Write the target answer. State the accurate association or fact you want an eligible user to find.
    2. Inspect current answers. Note which entities are included, how they are framed, and which URLs provide support.
    3. Identify the proof gap. Decide whether you lack an owned source, independent corroboration, current evidence, clear category language, or consistent entity facts.
    4. Create a referenceable asset. Publish the methodology, documentation, data, definition, criteria, or other evidence needed to support the claim.
    5. Distribute the evidence. Brief relevant external channels on the substantiated finding or resource, not a stack of unsupported superlatives.
    6. Monitor the resulting language. Check whether coverage preserves the correct entity, scope, caveats, and canonical link.
    7. Reconcile your owned content. Update the claim-evidence ledger and correct conflicting pages or structured data.

    Evaluate an external mention by asking whether it names the entity and category correctly, carries a verifiable fact, links to the appropriate evidence, appears in a context relevant to your tracked prompts, and remains publicly accessible. A vague brand name-drop may increase a PR count while adding almost no authority to the answers you care about.

    Do not manufacture apparent consensus by syndicating an unproven statement or publishing near-duplicate claims on low-relevance sites. That creates more copies of the weakness. Strengthen the underlying evidence, correct inaccurate profiles or references where appropriate, and seek coverage from contexts that genuinely understand the subject.

    Operate AEO as a measured evidence loop

    A circular system moves abstract question tokens through an answer chamber, an observation lens, evidence markers, and refined source modules before looping back.

    The useful question after a monitoring run is not simply whether the score went up. Ask where the path from prompt to answer failed, then choose the smallest intervention that tests that diagnosis.

    What you observeLikely constraint to testNext action
    No mention on an eligible promptMissing topic coverage, weak entity-category association, discovery difficulty, or insufficient corroborationMap the prompt to a canonical page, make the relevant relationship explicit, improve purposeful internal links, and examine the outside evidence available for competitors.
    Your brand is mentioned but a competitor is citedYour page may be less specific, supportable, current, or citation-readyCompare the cited evidence with your own. Strengthen the precise claim, provenance, scope, and stable passage instead of merely adding more copy.
    Your brand is cited but described inaccuratelyConflicting, ambiguous, or stale entity factsDesignate a canonical source of truth, reconcile visible content and schema, correct material external errors where possible, and monitor the affected prompt.
    You appear on branded prompts but not category promptsWeak unbranded problem or category authorityBuild content around problem definitions, selection criteria, use-case constraints, and comparisons, then pursue corroboration for the claims those pages make.
    Visibility rises without useful business activityThe prompt portfolio or destination path may be commercially misalignedReclassify prompts by business relevance, inspect cited destinations, and connect identifiable AI referrals and assisted outcomes without claiming attribution you cannot prove.
    One platform improves while others stay flatA surface-specific retrieval, selection, or presentation differencePreserve separate platform trends and verify the change elsewhere before declaring a general AEO gain.

    Modern search visibility depends on multiple kinds of AI algorithms and applications. The operational inference is straightforward: do not assume an intervention that changes one surface will transfer unchanged to every other surface. Observe the transfer.

    Use a controlled improvement cycle:

    1. Capture a baseline with raw answers, citations, and test conditions.
    2. Classify each material failure as coverage, discovery, entity clarity, authority, citation readiness, framing, or business alignment.
    3. Choose one primary intervention for the affected prompt group.
    4. Annotate exactly what changed, where it changed, and which claim it was meant to improve.
    5. Run the unchanged core prompts under comparable conditions.
    6. Compare the answer, cited evidence, framing, and competitors rather than checking only the aggregate score.
    7. Retain the change when the intended signal improves without introducing factual or user-experience problems; otherwise revise the diagnosis.

    Your reporting should have separate executive and diagnostic views. The executive view can show eligible coverage, citation, accuracy, prominence, and commercially relevant outcomes by platform and prompt group. The diagnostic view should expose the raw answer, cited URLs, unsupported or incorrect claims, competing entities, proposed intervention, owner, and status. Without that second layer, the dashboard describes the problem but cannot run the work.

    Keep business attribution honest. AI-referred sessions and conversions are useful when they can be identified, but they do not capture answers that influence a later branded search, direct visit, or offline decision. Report answer-level visibility and observable business activity as connected but distinct evidence. Do not assign revenue to an AEO change merely because both moved in the same period.

    Key takeaways

    • Define success for eligible prompts, named surfaces, accurate framing, and appropriate citations before collecting results.
    • Track mentions, owned citations, independent corroboration, accuracy, prominence, and business activity separately.
    • Preserve a fixed core prompt set for trends and a separate exploratory set for discovery.
    • Build authority through explicit claims, verifiable evidence, clear scope, consistent entities, and schema that matches visible content.
    • Use PR to close specific corroboration gaps, not to accumulate undifferentiated mentions.
    • Diagnose the failed stage, change one primary layer, annotate it, and rerun comparable tests.

    Start with one commercially meaningful query group. Freeze its core prompts, capture the baseline across the surfaces your audience uses, and build a claim-evidence ledger for the pages that should support those answers. Your first valuable result is not a larger score. It is knowing why your brand was omitted, misframed, or passed over for a citation, and having a specific piece of evidence to improve next.

    References

  • AI Search Adoption, Referrals and Customer Journey Tracking

    AI Search Adoption, Referrals and Customer Journey Tracking

    Your analytics may show almost no traffic from AI assistants even when buyers are using them to define their problem, compare options and build a shortlist. The reverse can happen too: an AI referral can reach your site without becoming a qualified customer.

    If you are deciding whether AI search deserves time and budget, referral sessions alone will mislead you. You need an evidence chain that separates market adoption, answer visibility, identifiable visits, assisted influence and commercial outcomes.

    Adoption, visibility, referrals and revenue answer different questions

    AI search reporting becomes confusing when unlike metrics share one chart. Active-user growth and referral leadership are separate measures. A widely used platform may send little identifiable traffic to your site, while a smaller platform may produce a more noticeable referral stream.

    The same discipline applies to market reports. Use statistics about user behavior, LLM adoption and industry forecasts to form hypotheses about where discovery is moving. Do not treat them as evidence that your audience uses a particular platform or that its traffic will convert.

    Measurement layerQuestion it answersUseful evidenceWhat it cannot prove
    AdoptionAre people using this platform or search experience?Platform usage data, market reports and direct customer researchThat your brand is visible or that users will visit your site
    VisibilityDoes your brand appear for relevant questions?Mentions, citations and links across a controlled prompt setThat the appearance influenced a purchase
    ReferralDid a recognizable AI surface send a visit?Referrer data, landing pages and session-level eventsZero-click exposure or a later direct or branded visit
    Qualified outcomeDid the visit produce a meaningful action?Qualified leads, trials, purchases, bookings or other defined conversionsRevenue until the outcome has matured
    Commercial impactDid AI-related activity contribute to business value?Opportunities, pipeline, revenue, retention and closed-won outcomesThe precise contribution of AI when several touches shaped the decision

    Name the layer whenever you report a result. Say “recognized AI referral sessions,” not “AI performance.” Say “brand mentions in our tracked prompts,” not “AI market share.” This prevents a top-of-funnel signal from being mistaken for revenue.

    Every rate also needs a visible numerator and denominator. A referral conversion rate should mean qualified conversions divided by recognized AI referral sessions. Visibility coverage should mean prompts in which the brand appeared divided by prompts tested. If the underlying counts are small, show them beside the percentage; otherwise one visit or one deal can create a dramatic but fragile change.

    The AI-influenced journey rarely fits a last-click report

    A buyer is surrounded by connected AI, content, peer, website and sales touchpoints arranged in a looping journey.

    AI can shape discovery, decision-making and loyalty, not just the moment before a click. A useful journey map therefore starts before the website session and continues after the initial conversion.

    1. Problem recognition: The buyer asks what is causing a problem, whether it matters and what kind of solution exists.
    2. Category discovery: The buyer requests approaches, products, providers or a shortlist that fits stated constraints.
    3. Evaluation: Follow-up questions test features, tradeoffs, pricing logic, integrations, risks and suitability.
    4. Validation: The buyer visits websites, checks evidence, searches for the brand and verifies details supplied by the answer.
    5. Conversion: The buyer purchases, signs up, books, applies or starts a sales conversation.
    6. Experience and loyalty: The customer returns to AI or search for setup, support, troubleshooting, renewal and adjacent needs.

    A buyer can move through several of those stages inside one conversation. Clicks, search refinements and feedback can help AI systems adapt their results, so the follow-up question matters as much as the opening prompt. Content that answers only a broad category question may earn awareness but disappear when the buyer asks about implementation constraints.

    The surfaces also overlap. ChatGPT, Perplexity and Gemini can introduce or evaluate brands, while Google’s AI Mode brings an AI-mediated experience into Google search. A reporting model that defines everything from Google as traditional search and everything else as AI will miss that convergence.

    A recognizable referral is only one observable path. An AI answer may influence a buyer who later types your URL, searches your brand, responds to an ad or talks to a salesperson. Standard last-click reporting will credit that later touch. That does not justify relabeling every direct or branded visit as AI-assisted; it means you need another evidence layer.

    Add a short, optional discovery question to high-value forms and sales qualification: “Where did you first hear about us?” Include AI assistant as a distinct choice alongside search engine, social media, colleague, publication, event and other relevant channels. Follow it with an optional free-text question such as “What were you trying to find out?” Preserve the original response in your CRM. Use it as evidence of influence, not as a replacement for behavioral analytics.

    Build a measurement chain from prompt to closed outcome

    A luminous thread connects an abstract AI question, answer panels, website visits, lead qualification and a completed business agreement.

    You do not need perfect attribution before you can make a better decision. You need consistent definitions and enough connection between discovery, visit and outcome to see where the chain breaks.

    1. Choose the business outcome first. Define the action that matters: a qualified lead, completed purchase, activated account, booked appointment or another outcome your team already recognizes. Do not create an easier AI-only conversion definition.
    2. Define the surfaces in scope. Name the assistants and AI-enabled search experiences you will monitor. ChatGPT, Perplexity, Gemini and Google AI Mode are valid starting points when they match your audience, but the list should come from customer behavior rather than platform publicity.
    3. Create a fixed prompt library. We’d start with 30 prompts split across problem recognition, category discovery, comparison, requirements and branded validation. Thirty is a manageable operating set, not a representative estimate of the entire market.
    4. Track recognizable referral traffic. Group known AI referrers in your analytics platform while preserving the raw source, landing page and conversion events. Keep this channel separate from organic search, direct and referral traffic so definitions do not drift between reports.
    5. Connect visits to downstream outcomes. Pass the relevant session or lead identifier into your CRM or commerce reporting. Measure qualification, opportunity creation, pipeline, purchases, revenue and closed outcomes with the same definitions and maturation windows used for other channels.
    6. Capture assisted influence. Combine voluntary discovery responses, sales notes and other documented customer evidence in a separate AI-influenced field. Never merge inferred influence into known referrals; report the two views side by side.

    Use a prompt log you can rerun

    For each prompt, record the exact wording, intended journey stage, audience, region, language, platform, date and any material session conditions. Then capture whether your brand appeared, whether it was linked or cited, which page was referenced, the surrounding claim, the competitors present and whether the answer represented your offer accurately.

    Do not quietly replace weak prompts with easier ones. Maintain a stable core set for trend comparison and a separate experimental set for newly discovered questions. If you change the platform, wording, geography or evaluation criteria, annotate the change so a methodology shift is not reported as a visibility gain.

    Keep one funnel, with clearly labeled AI signals

    • Prompt visibility coverage: tracked prompts with a brand appearance divided by prompts tested.
    • Linked visibility coverage: tracked prompts containing a link or citation to your domain divided by prompts tested.
    • Recognized AI referrals: sessions carrying a referrer that matches your documented AI channel rules.
    • AI referral qualification rate: qualified outcomes from those sessions divided by recognized AI referral sessions.
    • Known AI-sourced pipeline: opportunities and value attached to leads whose recorded source meets your AI referral definition.
    • Documented AI influence: outcomes with an explicit customer or sales signal showing that an AI tool contributed to discovery or evaluation.

    Lead volume is not the verdict. A comparison covering more than 117,000 leads examined pipeline quality and closed-won outcomes, which is the commercial layer your own analysis should reach. It does not give you permission to assume that AI referrals will outperform another channel in your business.

    Compare equivalent cohorts. A new AI referral cohort should not be judged on closed-won rate while an older organic cohort has had months to progress. Use the same qualification rules, sales stages and outcome windows. When counts remain low, inspect the individual journeys and report the uncertainty instead of declaring a winner.

    Match content to the next decision the buyer must make

    Measurement tells you where the gap is. Content should close that specific gap. Publishing more broad educational pages will not help if your brand appears during discovery but disappears when buyers ask who the product is for, what it integrates with or where its limits are.

    • For discovery: Give the problem and category a clear name. Answer the main question early, define necessary terms and explain the criteria a buyer should use to decide whether the category is relevant.
    • For evaluation: Publish concrete capabilities, requirements, tradeoffs, exclusions and implementation details. Organize comparisons around buyer criteria rather than unsupported claims of superiority.
    • For validation: Make authorship, evidence, update dates, policies, company identity and contact details easy to verify. Correct contradictions between product pages, documentation and third-party profiles.
    • For conversion: Align the landing page with the question that earned the visit. A buyer asking about compatibility should land on compatibility information with a relevant next step, not a generic homepage.
    • For retention: Keep setup instructions, troubleshooting, support policies and product facts current. AI-assisted customer journeys continue after acquisition, and inaccurate support information can damage trust as readily as an inaccurate recommendation.

    Use structured data to clarify content that already exists. Select the most specific applicable schema types, such as Organization, Product, Service, Article or FAQPage, and make sure the JSON-LD agrees with the visible page. Connect the correct entities and identifiers. Do not mark up claims, reviews, prices or FAQs that users cannot see, and do not treat valid markup as a guarantee that an AI system will mention or cite the page.

    Before publishing or refreshing a target page, ask five practical questions: Can a reader find the direct answer without decoding marketing language? Does the page say who the offer is and is not for? Are important claims supported on the page? Are names, attributes and relationships consistent across the site? Is the next action appropriate for the buyer’s current stage? A page that fails those checks is likely to create journey friction even if it earns a citation.

    Key takeaways: your first 12 weeks

    • Measure adoption, prompt visibility, referrals, qualified outcomes and commercial impact as separate layers.
    • Use external adoption data to choose where to investigate, then validate the choice with customer and first-party evidence.
    • Track a stable prompt set and a separate experimental set so methodology changes do not masquerade as performance changes.
    • Keep recognized AI referrals separate from documented AI influence throughout analytics and CRM reporting.
    • Judge traffic on qualification, pipeline and mature outcomes, not visits or lead counts alone.
    • Build or improve the page that answers the buyer’s next decision, then rerun the relevant prompts and inspect downstream behavior.

    We’d run the initial measurement system for 12 weeks. That is an operating window, not a universal performance benchmark. Establish definitions and a baseline in week zero, rerun the stable prompt set weekly, review referral and assisted-journey evidence every four weeks, and make the first allocation decision after week 12. If your sales cycle is longer, continue following the same cohorts until their outcomes are mature.

    Let the location of the break determine the next action. Low visibility calls for better question coverage and entity clarity. Visibility without visits calls for stronger citation-worthy detail, relevant landing pages and better influence capture. Visits without qualified outcomes call for a prompt-to-page alignment and conversion review. Qualified opportunities without mature revenue call for patience, not a premature channel verdict.

    Start by choosing one valuable journey, one defined outcome and one controlled prompt set. Once you can trace that chain honestly, you can expand the program without turning every unexplained customer touch into an AI success story.

    References

  • Enhance Content Visibility with AEO Content Score

    Enhance Content Visibility with AEO Content Score

    I’m excited to introduce the Profound AEO Content Score, a groundbreaking metric powered by machine learning. This tool is a game-changer for marketers, helping us gauge how well our content is optimized for AI search results.

    Leveraging data from millions of top-cited pages across AI platforms, the AEO Content Score evaluates the likelihood of your content being referenced in AI searches. This score lays the groundwork for our newest version of Content Optimization, offering real-time insights and benchmarks.

    With clear recommendations to enhance your visibility in AI-generated answers, you’ll gain a competitive edge in the digital landscape. Let’s dive into how this powerful tool can propel your content strategy to new heights.


    Inspired by this post on Try Profound Blog.


    Support Dharma Renaissance
  • Profound’s $35M Funding and Its Developer Ecosystem

    Profound’s $35M Funding and Its Developer Ecosystem

    If you’re deciding whether Profound belongs in your AI-search stack, the funding number is the least useful place to stop. A financing round can give a vendor room to build. It cannot tell you whether its data is trustworthy, its package fits your application, or its integration is safe to run in production.

    Profound now offers three concrete signals to investigate: $35 million in Series B funding, a one-click Vercel Marketplace integration for Agent Analytics, and next-aeo, an NPM package built for Next.js applications. That combination shows where an ecosystem may be forming. It does not remove the need for technical due diligence.

    Read the $35 million as capacity, not product proof

    Funding matters because software ecosystems require sustained investment. The core product is only one expense. A useful developer platform also needs documentation, integrations, package maintenance, support, security work, infrastructure, and compatibility testing.

    Profound’s $35 million raise creates capacity for that work. It does not prove that every part has already been delivered, nor does it guarantee product quality, vendor longevity, or a particular roadmap. A financing event is not a service-level agreement.

    Separate the headline from the evidence by keeping a simple evaluation ledger with three states:

    • Available: The vendor publicly offers the capability, package, or integration.
    • Verified: Your team has confirmed how it behaves in your own environment.
    • Unknown: The answer depends on documentation, testing, a contractual commitment, or a response from the vendor.

    The funding belongs in the available column as evidence of new financial capacity. The Vercel integration and next-aeo package also belong there until you test them. Do not quietly promote an available feature to verified merely because installation looks simple.

    When you evaluate what the funding could mean for your organization, look for release evidence in four areas:

    • Product delivery: Are analytics, integrations, and developer tools becoming usable parts of the same workflow?
    • Maintenance: Can you find version requirements, release notes, upgrade guidance, and a clear support path?
    • Operational depth: Are permissions, exports, retention, failure modes, and rollback procedures explained?
    • Developer adoption: Can an engineer install, inspect, test, and remove the tooling without relying on a sales demonstration?

    This keeps the decision grounded. Capital can accelerate an ecosystem, but only maintained interfaces make that ecosystem useful to your team.

    The ecosystem has three layers with different jobs

    An isometric three-level system connects AI-search analytics, a cloud integration gateway, and modular web application components.

    Profound’s current footprint spans company capacity, deployment distribution, and application-level tooling. Those layers answer different questions, so they should not be treated as interchangeable proof.

    LayerVerified public signalWhat it helps you assessWhat it does not establish
    Company capacity$35 million Series B fundingAccess to new capital for expansionProduct accuracy, profitability, long-term availability, or service quality
    Deployment distributionAgent Analytics on the Vercel Marketplace with a one-click connectionWhether a supported installation path exists for a Vercel workflowProduction permissions, data handling, metric definitions, or setup after authorization
    Application toolingnext-aeo as an NPM package for Next.jsWhether developers have a framework-specific AEO entry pointExact output, version compatibility, ranking effects, or maintenance quality

    The important question is whether these layers form a closed operating loop. Your application produces content and machine-readable signals. Analytics helps you observe how AI systems interact with the site. Those observations should lead to a specific content, code, or distribution decision. If your team cannot identify that final decision, the stack may create another dashboard without improving the workflow.

    One-click installation is not one-click operation

    The Vercel Marketplace integration is meaningful because it brings Agent Analytics into a deployment channel developers may already use. For a Vercel-based team, a marketplace connection can reduce custom setup work.

    But one-click describes the start of the connection, not the quality of the outcome. Before calling the integration production-ready, determine:

    • Which Vercel projects, environments, accounts, and resources it can access.
    • Which credentials or tokens it creates, where they are stored, and how they are revoked.
    • What data leaves your environment and whether prompts, URLs, responses, or user-related fields can be included.
    • How an AI interaction is identified, filtered, deduplicated, and attributed.
    • What happens when the integration fails, is disconnected, or encounters a deployment change.
    • Whether data can be exported before you remove the integration.

    Treat the marketplace listing as evidence of distribution maturity. Treat data quality, security, and operational fit as separate tests.

    next-aeo moves AEO into the application layer

    The next-aeo package targets Next.js developers and frames answer engine optimization as an implementation concern, not only an editorial checklist. That is useful because developers can potentially review AEO-related behavior alongside application code, dependencies, builds, and deployments.

    Do not infer its exact behavior from the package name. Before adoption, inspect whether it changes rendered HTML, metadata, structured data, routes, configuration, server behavior, or the build pipeline. Establish which Next.js versions and routing models it supports. Check whether the package behaves differently with static generation, server rendering, incremental regeneration, or client-rendered content where those patterns exist in your application.

    If next-aeo emits or transforms JSON-LD, inspect the final rendered markup rather than the source configuration alone. Look for invalid syntax, duplicate entities, conflicting identifiers, missing required properties, and differences between development and production builds. If it modifies metadata, compare canonical URLs, robots directives, titles, descriptions, and social metadata before and after installation.

    AEO does not create a guaranteed position in an AI-generated answer. Use the package to improve implementation discipline only after you can explain what it produces and why that output should help answer-oriented systems understand the page.

    Use a production-readiness checklist before connecting data

    A data pipeline passes through privacy, validation, testing, monitoring, and final approval gates before reaching a production application.

    The fastest way to make a weak platform decision is to install first and define success later. Write the test contract before the package or integration changes your environment.

    Define the measurement contract

    Agent Analytics is intended to provide insight into AI interactions with a site. That description is a starting point, not a metric definition. Your team should be able to answer these questions before using the data for strategy:

    • What event qualifies as an AI interaction?
    • How are agents distinguished from ordinary browsers, crawlers, proxies, automation, and spoofed user agents?
    • Which fields are observed directly, and which are inferred?
    • How are repeated requests, retries, cached responses, and internal traffic handled?
    • Which dimensions are available for filtering and comparison?
    • How far back does the data go, and can a methodology change alter historical comparisons?
    • Can the underlying records be exported for independent validation?

    Write the accepted definition beside every metric you plan to report. If a stakeholder asks what changed, you should be able to explain both the number and the collection mechanism. A polished dashboard label is not a substitute for a documented definition.

    Test application compatibility at the rendered-output level

    Record the exact Next.js version, router, rendering modes, deployment configuration, package manager, and existing SEO or schema tooling in the test environment. Then compare the application before and after installation at several points:

    • Dependency resolution and installation output.
    • Local and production-mode build logs.
    • Generated artifacts and server output.
    • Rendered HTML, metadata, response headers, and structured data.
    • Representative static, dynamic, localized, canonicalized, and authenticated routes used by your application.
    • Deployment logs, runtime errors, and page behavior after release.

    Pin the version you test and preserve a rollback path. An automatic package upgrade can change sitewide output, so do not leave a production AEO dependency floating across unreviewed releases.

    Review permissions and data handling before production

    Do not connect a production project until you understand the integration’s access scopes, network destinations, credential lifecycle, retention behavior, deletion process, and administrative controls. If prompts, URLs, responses, or user-related fields can be collected, involve the people responsible for security, privacy, and consent before enabling that collection.

    A mis-scoped credential can expose more infrastructure than the tool needs. Unexpected collection can create privacy or contractual exposure. Use a staging environment or a non-sensitive project while those questions remain unresolved, and grant the narrowest access that still supports the test.

    Assign operational ownership

    An ecosystem becomes expensive when every component exists but nobody owns the handoffs. Name the person or team responsible for each recurring task:

    • Reviewing package releases and compatibility changes.
    • Approving integration permissions and credential rotation.
    • Investigating analytics anomalies and methodology changes.
    • Turning observations into content or engineering work.
    • Maintaining documentation for installation, rollback, export, and removal.
    • Deciding whether the tooling still earns its place in the stack.

    If these responsibilities fall between SEO, engineering, analytics, and security, the integration will eventually become unowned infrastructure. Resolve that before rollout.

    Run a staged pilot that ends with a decision

    Your first pilot should establish operational fit. Do not promise an AI-visibility lift before the implementation and measurement definitions are stable. A narrow, reversible test will tell you more than a broad installation with no baseline.

    1. Name the decision. State whether you are evaluating Profound for measurement, application-level AEO implementation, or the combined workflow. Define what would lead to adoption, a hold, or rejection.
    2. Capture the baseline. Record the application version, deployment settings, representative routes, current HTML and metadata, existing JSON-LD, current analytics, and known errors before making a change.
    3. Review the artifacts. Check package requirements, permissions, data handling, release information, support paths, and removal steps. Put unresolved questions in the unknown column of your evidence ledger.
    4. Use a non-production environment. Connect the Vercel integration only after reviewing its requested access. Scope the next-aeo change as narrowly as the package and application architecture permit.
    5. Inspect every layer. Verify that the application installs and builds, that rendered output changes only as expected, and that analytics records can be explained using a documented definition.
    6. Roll back and repeat. Remove the package or integration, confirm that the environment returns to its baseline state, and repeat the installation from written instructions. This exposes hidden manual steps and configuration drift.
    7. Write the decision record. List what was verified, what remains unknown, who owns the workflow, and what would trigger reevaluation. Keep funding and roadmap expectations separate from tested behavior.

    Use explicit gates for approval. A credible pilot should produce a repeatable installation, understandable data, no unexplained output changes, acceptable permissions, a named operational owner, and a tested exit path. If one of those is missing, document the gap instead of averaging it away with strengths elsewhere.

    The combined stack earns a broader rollout only when the loop works: application changes are inspectable, analytics is explainable, and the resulting evidence leads to a concrete optimization decision. That is the difference between owning an ecosystem and merely accumulating tools.

    Key takeaways

    • Profound’s $35 million Series B provides capacity to invest, but it does not validate product performance, security, or long-term fit.
    • The Vercel Marketplace integration reduces initial connection friction; one-click installation does not settle permissions, data quality, retention, or operational ownership.
    • The next-aeo NPM package gives Next.js teams a framework-specific AEO entry point, but you still need to verify compatibility and inspect its rendered output.
    • Evaluate funding, analytics, deployment integration, and application tooling as separate layers before testing whether they form a useful workflow.
    • Use a narrow staging pilot, written measurement definitions, pinned dependencies, and a tested rollback path before committing production data or sitewide output.

    If Profound is on your shortlist, pair an engineer with the person who owns AI-search performance and complete the evidence ledger before procurement or production access. Let reproducible installation, explainable data, and safe removal make the decision.

    References

  • CrushPress AI Actions: Reliable Workflow Automation

    CrushPress AI Actions: Reliable Workflow Automation

    If your AI visibility process ends with a crowded inbox, an unassigned alert, or a spreadsheet nobody revisits, automating it will only produce clutter faster. A useful Action must turn a meaningful signal into an owned decision, preserve the evidence behind it, and define how you will know the work is finished.

    The practical promise behind Actions is to reduce repetitive handling and make AI visibility work more efficient. Real reliability, however, comes from the workflow around the automation: the trigger, decision rule, evidence, owner, review gate, and verification step.

    Define the decision before you automate the task

    Start with a recurring decision that currently requires someone to collect the same information, apply the same rule, and route the result. Do not start with a vague goal such as “improve AI visibility.” An Action cannot execute that goal because it does not identify what changed, what should happen next, or who can approve the response.

    A better starting question is: “What decision keeps waiting because the evidence is scattered?” In an AI visibility workflow, that might be whether a new brand claim needs correction, whether a missing citation points to a content gap, whether a tracked answer changed enough to investigate, or whether an observation is merely noise that should be logged without creating work.

    Write a workflow contract before configuring the Action. It should contain:

    • Outcome: The operational result you want, such as an approved correction task or a content brief ready for review.
    • Trigger: The observable event that starts the workflow. Describe the event, not the desired conclusion.
    • Required evidence: The fields that must exist before the workflow is allowed to continue.
    • Decision rule: The condition that separates “act,” “review,” “observe again,” and “ignore.”
    • Output: One bounded deliverable with a predictable structure.
    • Owner: The role responsible for accepting, rejecting, or completing the output.
    • Stop condition: The point at which the Action must end rather than starting another loop.
    • Verification rule: The evidence required to mark the result as checked, not merely completed.

    For example, “alert the SEO team when visibility drops” is not yet a workflow. “When a tracked query produces a materially different answer, capture the old and new observations, classify the change, and create an investigation brief for the named owner” is much closer. It specifies a trigger, evidence, classification, output, and destination without pretending the automation already knows the cause.

    Use a simple readiness test: can the owner make the intended decision from the Action’s output without reopening every tool used upstream? If not, the automation has moved the repetitive work rather than removed it.

    Build a closed loop for AI visibility changes

    Glowing signals converge into a beacon that moves through a circular observation, action, and verification system.

    AI-generated answers can vary across runs, models, interfaces, languages, and locations. A single observation is therefore evidence of what appeared in that context, not automatic proof of a durable visibility trend. Your workflow should preserve that context before it attempts to classify the result.

    A practical visibility loop

    1. Observe: Start from a defined query or query set on a chosen AI surface. Avoid mixing unrelated prompts into one trigger.
    2. Capture: Save the exact prompt, answer, model or interface, observed time, relevant language or market, cited pages, and any brand or competitor mentions needed for review.
    3. Compare: Evaluate the observation against a declared expectation or earlier observation. Keep the raw evidence alongside the comparison.
    4. Classify: Route the result into a limited set of operational states, such as no meaningful change, uncertain result, incorrect claim, missing mention, citation gap, content gap, or competitor displacement.
    5. Act: Produce one appropriate output. That might be a correction task, investigation brief, content brief, structured-data review, escalation, or no-action record.
    6. Verify: Recheck the same success criterion in a planned observation window, while retaining the model and interface context.

    The separation between observation and classification matters. If an Action turns every changed answer into an optimization task, ordinary output variation becomes a queue of false emergencies. A classification stage lets you require more evidence when the result is ambiguous and reserve immediate action for clear, consequential problems.

    Example: route a potentially incorrect brand claim

    Suppose a tracked answer contains a claim that conflicts with your approved brand facts. The Action should not jump directly to rewriting a page or publishing corrective content. Design the loop like this:

    • Trigger: A captured answer contains a claim that appears inconsistent with the approved fact set.
    • Evidence packet: Include the exact prompt, complete surrounding answer text, AI surface, cited URLs, observation context, conflicting approved fact, and link to the canonical internal record.
    • Decision gate: A reviewer confirms whether the statements actually conflict and whether the issue is consequential.
    • Action: Create a correction plan that identifies the canonical page, structured data, documentation, or third-party information requiring investigation.
    • Approval: Require an authorized owner to approve any public edit, deletion, or external response.
    • Verification: Confirm that the approved source of truth was corrected, then record later AI observations separately from the operational completion.

    This distinction prevents an important reporting error. Completing a content or data correction proves that your team performed the approved work. It does not prove that the correction caused a particular model to change its answer. Track “work completed” and “visibility outcome observed” as separate states.

    Verification should test the original condition

    A generic “done” status tells you that a task moved through the system. It does not tell you whether the initiating problem was resolved. Write the verification rule when you create the workflow, using the same language as the trigger.

    If the trigger is an incorrect brand claim, verification asks whether the approved source of truth is now accurate and whether later observations still contain the claim. If the trigger is a citation gap, verification asks whether the target page became a stronger, accessible source and whether subsequent answers cite it. If the trigger is a visibility change, verification repeats the planned observation method rather than substituting a different prompt or surface.

    Make every handoff carry its own evidence

    A brittle automation often fails at the handoff. The Action detects something real, but the destination receives a title such as “Check AI visibility” with no prompt, answer, comparison, or reason for the priority. The assignee must reconstruct the investigation before making a decision.

    Prevent that failure by treating the evidence packet as part of the deliverable. Every routed item should answer these questions:

    • What was observed? Preserve the exact text or structured result, not only a generated summary.
    • Where did it occur? Identify the AI surface, model or interface when available, query, language, market, and relevant source URLs.
    • What changed? Show the comparison or rule that activated the workflow.
    • Why was it classified this way? Expose the decision rule instead of presenting the label as unquestionable.
    • What remains uncertain? Label suspected causes as hypotheses. Do not let generated explanations masquerade as established facts.
    • What should the owner decide? Ask for a specific approval, rejection, prioritization, correction, or investigation decision.
    • What would close the item? State both the operational completion condition and the later visibility check.

    Route by issue type before routing by team. “Content,” “technical,” or “communications” may describe a destination, but they do not explain the problem. A useful classification identifies the issue first: unsupported claim, stale canonical fact, inaccessible source, weak answer coverage, structured-data inconsistency, or uncertain observation. The destination can then follow from that diagnosis.

    Measure decision quality, not automation volume

    Task count is a poor success metric. A noisy workflow can create many tasks while making the team slower. Use operational measures that reveal whether the Action improves the decision process:

    • Useful-signal rate: How often reviewers agree that a routed item deserved attention.
    • Time to ownership: How long a valid signal remains unassigned or undecided.
    • Rework: How often the owner must retrieve missing evidence, change the classification, or rebuild the requested output.
    • Closure quality: How often completed items include the required approval and verification record.
    • Repeated failure: Which triggers, fields, or destinations create the same rejection or exception pattern.
    • Observed outcome: Whether later checks satisfy the declared visibility criterion, recorded without claiming unsupported causation.

    Review rejected and corrected outputs as design feedback. If reviewers repeatedly change the same classification, the rule is probably ambiguous. If they repeatedly ask for the same missing field, add it to the evidence contract. If valid items stall after assignment, the problem is ownership rather than detection.

    Add review gates and failure controls before scaling

    Two professionals pass a transparent evidence case through a guarded review checkpoint with inspection and recovery controls.

    The right automation boundary depends on the consequence of being wrong. Capturing evidence is reversible. Publishing a factual claim, deleting content, changing structured data, contacting an external party, or altering permissions can create reputational, technical, or legal exposure. Put explicit approval in front of those actions and provide the reviewer with a preview or difference view wherever possible.

    Automate preparation before irreversible choices

    A sensible responsibility split looks like this:

    • Safe to automate: Evidence capture, formatting, deterministic field validation, duplicate detection, status updates, routing, and creation of a reviewable draft.
    • Automate with review: Intent grouping, issue classification, priority suggestions, root-cause hypotheses, content recommendations, and proposed schema changes.
    • Require explicit approval: Publishing, deletion, public corrections, external outreach, access changes, and any claim whose accuracy or wording carries material consequences.

    Generated drafts should remain drafts until an accountable person approves them. This is especially important when the input is an AI-generated answer: the workflow is processing an output that may itself be incomplete, variable, or wrong.

    Give failures a visible destination

    An Action is not ready merely because its successful path works. It is ready when a failed run is legible, contained, and recoverable. Build or document these controls around it:

    • Required-field validation: Stop the workflow when the evidence needed for a decision is missing.
    • Duplicate protection: Use a stable combination of query, observation, issue, and destination so repeated detection does not create competing tasks.
    • Scoped permissions: Give the workflow access only to the systems and operations it needs.
    • Bounded retries: Prevent a failing destination from producing an uncontrolled loop of repeated attempts.
    • Visible exceptions: Send failed and uncertain runs to a named owner with the input, error state, and last successful step intact.
    • Versioned rules: Record which prompt, classification logic, template, and approval policy produced each output.
    • Recovery path: Preserve the prior state or require a reversible draft when an automated step could change content or data.

    If a particular control is not available inside the Action itself, put it in the surrounding operating process. Do not assume that a successful status means the destination accepted the right data, that a retry is harmless, or that a generated classification is safe to publish.

    Roll out with known cases before live expansion

    1. Replay resolved cases: Feed the workflow examples whose correct routing and outcome are already known. Include ambiguous, duplicate, incomplete, and no-action cases.
    2. Run in shadow mode: Let the Action produce a log or draft without changing production content or contacting anyone externally.
    3. Limit the live scope: Start with one trigger family, one output type, and a named owner who can inspect exceptions.
    4. Correct the contract: Update missing fields, ambiguous rules, permissions, and failure handling based on actual review patterns.
    5. Expand by pattern: Reuse the proven structure for adjacent workflows while keeping each Action’s trigger, owner, and success condition explicit.

    Name each workflow so its behavior is obvious: “trigger → decision → outcome.” A name such as “tracked claim conflict → reviewer confirmation → correction plan” is easier to operate than “AI monitoring automation.” It also makes overlapping or redundant Actions easier to spot.

    Key takeaways

    • Automate a recurring decision with a defined outcome, not a broad ambition such as improving visibility.
    • Preserve the prompt, answer, AI surface, comparison, and source context before classifying a visibility change.
    • Keep operational completion separate from later AI visibility observations; the latter does not automatically prove causation.
    • Make the evidence packet complete enough for the owner to decide without reconstructing the investigation.
    • Require human approval for publishing, deletion, external communication, permissions, and consequential factual or structured-data changes.
    • Scale only after duplicate handling, visible exceptions, ownership, verification, and recovery work on known cases.

    Your best first CrushPress AI Action is the recurring visibility decision that consumes attention without requiring novel judgment every time. Define its evidence packet, make its output reviewable, and test its failure path. Once that loop closes reliably, use the same contract to automate the next decision.

    References