I remember when a few strategic links from niche-related sites could consistently boost organic traffic. Those days have passed.
Now, with Google’s AI Overviews and the emergence of answer engines like ChatGPT, the visibility stakes are higher. Hiring a seasoned link building agency is critical to navigating this challenge effectively.
Choosing the right partner is a vital investment. It’s not just about link building; it’s about establishing your brand as a trusted authority in this AI-dominated landscape.
So, how do you find the ideal agency for your business?
Despite changes in interfaces, core ranking signals are largely unchanged, though their priorities have shifted.
Large Language Models (LLMs) require credible sources for accurate answers, making authoritative link building more crucial than ever.
In this article, I’ll guide you through vetting and selecting a link building agency that comprehends these new priorities and aids your brand in earning AI trust in the evolving SEO landscape.
How Link Building and SEO Are Changing
Gartner forecasts a 25% decline in search engine volume by 2026 due to AI chatbots taking over more answers. Partnering with an agency that grasps AI SEO is essential.
But how can you be sure they actually do?
The key indicators lie in holistic authority and AI visibility. According to an Authoritas study, only 1 in 5 links in Google’s AI Overviews aligned with a top-10 organic result, and 62.1% of cited links didn’t rank in the top 10 at all.
The conclusion is clear. AI systems and search engines assess websites differently now. We’re no longer just building links for Google’s crawler.
Link equity alone won’t suffice. Sites must establish topical authority, brand mentions, and a genuine market presence, aiming to build a footprint recognizable and unavoidable by AI models.
The New Criteria: Evaluating a Link Building Agency for AI SEO
Choosing the ideal link building agency depends on their alignment with current priority factors.
Here’s what to focus on.
Prioritizing Quality, Relevance, and Traffic
I’ve seen many marketing directors judge link quality solely by Domain Rating (DR).
While high DR is important, at uSERP, we recognize it’s not the ultimate measure. Additional factors to consider include:
Relevance: A niche-specific site with a DR of 60 often provides more value than a DR 80 general news site that covers diverse topics.
Minimum traffic standards: A site’s ranking for keywords and real traffic are critical; hence, strict traffic minimums are essential.
When vetting an agency, request contractual site-traffic guarantees.
An agency confident in their capabilities will gladly sign a Statement of Work guaranteeing each link comes from a site with a traffic threshold, such as 5,000+ monthly organic visitors.
If they refuse to document traffic minimums, they may intend to place links on “ghost town” sites—domains appearing robust but lacking a real audience, safeguarding their margins rather than fostering your growth.
Look for a Content-Driven Approach and Digital PR
Links thrive as part of genuine conversations.
Leading agencies now function like content marketing and digital PR teams, not traditional link builders.
Instead of requesting links, they craft linkworthy assets—data studies, expert commentary, and in-depth guides publishers want to cite, understanding that:
Google’s algorithms and AI models are adept at spotting paid placements, making a content-led approach crucial for ensuring links remain natural and valuable.
Guest posting in the AI SEO era is about thought leadership, not throwaway articles, positioning your CEO as a credible expert.
Your stories can keep ranking and still deliver fewer visits. When an AI answer absorbs the headline fact, definition, or short explanation, the reader may finish the task without opening your page. That changes the value of a ranking, but it does not make search irrelevant.
If you run a publishing operation, the wrong response is to produce more interchangeable articles and hope volume compensates for a lower click-through rate. You need to identify the pages AI can replace, make your distinctive work easier to cite, preserve a compelling reason to visit, and connect that visibility to revenue.
Key takeaways
Do not treat every lost organic visit as the same problem. Separate easily answered queries from stories that provide original evidence, continuing updates, analysis, or utility.
AEO and GEO should make your claims easier to understand and attribute. They cannot make generic content distinctive or guarantee inclusion in an AI answer.
Give readers the direct answer, then earn the visit with proof, depth, freshness, tools, or an ongoing relationship.
Measure search visibility, AI citations, referral traffic, audience retention, and revenue as separate stages. A citation is not a visit, and a visit is not a business result.
Keep investing in technical SEO while reducing your dependence on any single distribution platform.
Find the search traffic AI can replace
A 43% decline in publisher search referrals by 2029 has been projected. That is a planning estimate, not a guaranteed result for every publisher. Your actual exposure depends on what people search for, what your pages provide, and whether an AI interface can satisfy the need without sending the reader elsewhere.
Start with a page-level exposure map. Export your organic landing pages with their impressions, clicks, entrances, conversions, and revenue contribution where available. Group pages by template and query purpose rather than reviewing thousands of URLs as unrelated items.
If you lead SEO or content discovery, Apple’s deal with Google changes what you should prepare for, but not what you can claim to measure. A more capable, personalized Siri could answer more questions inside Apple’s interface, leaving fewer searches that begin with a conventional results page.
Your job now isn’t to chase a secret Siri ranking factor. It is to make your best information easy for an answer system to retrieve, understand, verify, and hand off, then preserve enough evidence to recognize when the upgraded Siri actually changes discovery.
What Apple has confirmed, and what remains unknown
Apple and Google have entered a multi-year collaboration covering Gemini models and cloud technology. Apple’s next generation of foundation models will be based on that technology and will help power future Apple Intelligence features, including a more personalized Siri expected later this year. Apple says Apple Intelligence will continue to run on its devices and through Private Cloud Compute.
The architecture matters. Calling the upgrade “Gemini-powered Siri” is convenient shorthand, but it can create the wrong mental model. The confirmed relationship places Gemini beneath Apple’s next generation of foundation models. It does not establish that every Siri request will go directly to the public Gemini service, that Siri will become a reskinned Gemini app, or that Google will control the Siri experience.
Area
Confirmed
Not yet confirmed
Model foundation
Apple’s next-generation foundation models will be based on Google’s Gemini models and cloud technology.
The exact Gemini model, request-routing logic, and division of work between models.
Siri upgrade
A more personalized Siri is among the future Apple Intelligence features the collaboration will help power.
An exact release date, supported-device list, language coverage, and regional availability.
Privacy architecture
Apple says Apple Intelligence will continue to operate on Apple devices and Private Cloud Compute.
How each category of Siri request will be partitioned across device, private cloud, and underlying model infrastructure.
Content discovery
No Siri-specific ranking, citation, or publisher-reporting mechanism has been disclosed.
Which indexes Siri will use, how sources will be selected, when links will appear, and what referral data publishers will receive.
Use that boundary in your roadmap. Put confirmed capabilities in the planning column and everything else in a testing backlog. If a proposed project depends on Siri supporting a particular schema type, exposing citations, or copying Google rankings, it is not ready to become a production requirement.
Treat Siri as a distribution layer, not a Google ranking tab
Gemini beneath Apple’s model stack does not mean Siri will inherit the Google Search index, ranking system, or citation behavior. A model can formulate an answer without owning the retrieval system that found the facts. Apple can also apply its own interfaces, policies, personalization, and privacy controls after a model generates or interprets information.
That distinction changes the goal. A traditional search program often treats the ranked page and the resulting visit as the main units of success. An assistant can split that journey into three separate outcomes:
Selection: Your information helps form the answer, whether or not the page is shown.
Attribution: Siri names your organization, product, expert, or page as the source of a claim.
Action: The user visits, calls, navigates, subscribes, buys, books, or completes another useful next step.
Do not collapse those outcomes into a vague idea of “ranking in Siri.” A page could influence an answer without receiving a visit. A brand could be named without a clickable citation. A linked page could earn traffic while contributing little to the generated wording. Each outcome needs its own observation and objective.
Assign the objective by task. For an educational question, prioritize factual inclusion, accuracy, and attribution. For a commercial comparison, prioritize correct qualification and a useful destination page. For a local or service task, prioritize accurate entity data and a low-friction handoff. This keeps your strategy useful even if Apple’s final interface differs from current AI answer products.
Build content Siri can extract, verify, and hand off
You do not need a speculative Siri optimization layer. You need pages whose important facts survive when separated from navigation, brand language, and surrounding prose. Audit the pages closest to a decision or action in this order:
Start with assistant-shaped tasks. Collect the questions people ask before contacting support, choosing a product, visiting a location, or completing a purchase. Preserve the natural wording instead of converting every task into a short keyword. “Does this work with my current plan?” carries conditions that a generic phrase such as “plan compatibility” loses.
Put the decisive answer before the sales argument. The first relevant subsection should identify the subject and answer the question directly. Follow it with conditions, exceptions, evidence, and the next step. Avoid introductions that require an answer system to infer the conclusion from several paragraphs of positioning.
Scope every fact that can change. Name the product edition, software version, location, audience, availability condition, or effective date when it affects the answer. Replace floating statements such as “it is included” with language that identifies what is included, for whom, and under which plan or version.
Align visible content with JSON-LD. Use structured data to label facts a visitor can verify on the page, not to insert claims that the page does not make. Names, descriptions, relationships, availability, authorship, locations, and other entity details should agree across markup and visible copy. More schema is not automatically better; accurate schema attached to a clear page is the useful target.
Give important entities a stable home. Maintain a canonical page for the organization, product, service, location, or expert that matters to the query. Use consistent names and internal links so an answer system does not have to guess whether abbreviations, old product names, and near-duplicate pages describe the same entity.
Make proof adjacent to the claim. Link consequential claims to the primary policy, specification, methodology, or other supporting material. Identify who owns the information and when it was last reviewed where freshness matters. A generic references page is less useful than evidence connected to the exact statement it supports.
Remove retrieval barriers. Check that the intended page returns a successful response, is not accidentally excluded from indexing, declares the correct canonical URL, and exposes its main answer without requiring a login or an interaction. Do not place an essential fact only inside an image, video, downloadable file, or script-dependent interface when it can also appear as clear HTML text.
Design the handoff. When a user needs to continue, provide a destination that matches the answer: the relevant booking screen, product configuration, support procedure, location page, or contact route. A generic homepage forces both the assistant and the user to reconstruct the journey.
This work is not a guarantee of inclusion in Siri. It improves the properties that any retrieval-and-answer system needs: identifiable entities, explicit facts, credible support, accessible pages, and a coherent next action. It also strengthens your content before Apple reveals any Siri-specific controls.
Measure Siri visibility without inventing a rank
No query-level Siri reporting, citation rule, or referral format has been confirmed. A single “Siri rank” is therefore not a defensible key performance indicator. Build a repeatable observation system instead.
Create a query ledger before the rollout
Save the tasks that matter while your team still has a clean baseline. Record the exact prompt, not just its topic. Because Apple is promising a more personalized Siri, context will matter when you compare results. Keep test conditions consistent where possible and record meaningful differences rather than treating every response as universal.
Field
What to record
Business task
The decision or action the user is trying to complete.
Exact prompt
The full wording, including follow-up questions in a multi-turn interaction.
Test context
Date, device, operating-system version, language, region, and any relevant account state that can be documented safely.
Observed answer
The material claims, recommendations, omissions, and errors in the response.
Attribution
Whether the brand, expert, page, or another source is named or linked.
Handoff
The page, app, action, or service offered as the next step.
Outcome
Whether the user could complete the intended task accurately and with reasonable effort.
Classify each result rather than assigning an improvised position. Was your information included? Was the entity identified correctly? Was there visible attribution? Did the handoff reach the right destination? Was the task completed? Those questions reveal where the discovery chain works and where it breaks.
Use web analytics conservatively. A recognizable referral can support attribution when one is exposed, but missing referral data does not prove that Siri had no influence. An unexplained increase in direct traffic does not prove Siri caused it either. Corroborate analytics with captured responses, destination-page changes, and repeated tests from your defined query set.
Once the upgraded Siri reaches the devices, languages, and regions relevant to your audience, rerun the same tasks before changing your content strategy. Look for stable patterns across repeated observations. One surprising answer is a test case, not an algorithm update.
FAQ for SEO and AI visibility teams
Will strong Google rankings automatically produce Siri visibility?
No automatic relationship has been confirmed. Gemini is part of the model foundation in Apple’s plan, but a model foundation is not the same thing as a search index or ranking pipeline. Keep improving conventional search performance, but measure Siri selection, attribution, and handoffs independently when the upgrade becomes available.
Do you need special Siri schema markup?
No Siri-specific schema requirement has been announced. Use the schema vocabulary that accurately describes the visible page and validate the resulting JSON-LD. Do not add irrelevant types, invented properties, or hidden claims merely to mention Apple, Siri, Gemini, or AI.
Should you change traffic forecasts before Siri launches?
No. Model the upgrade as a discovery scenario, not a booked traffic gain or loss. Fund improvements that help across search and answer systems now, such as entity cleanup, answer-focused editing, evidence mapping, technical accessibility, and baseline testing. Wait for observable Siri behavior before attaching a platform-specific forecast.
In your next planning cycle, choose the assistant-shaped questions tied to real decisions, audit the pages responsible for answering them, and start the query ledger. When the upgraded Siri reaches your audience, test those same tasks first. Let observed selection, attribution, and action patterns determine the next investment, not the presence of the Gemini name.
Your 2026 Google Ads plan can fail while the dashboard looks healthy. If a bidding system is rewarded for generating cheap leads, it will find cheap leads. It will not infer which leads became profitable customers unless that outcome returns to the platform as a usable signal.
The practical job is to decide where automation has earned freedom, where manual control still protects your budget, and which business result settles each spending decision. Use the framework below to audit an existing account or build your next planning cycle.
Set the optimization contract before changing campaigns
Every campaign needs an optimization contract: the business result you want, the event the platform can observe, the delay between those two events, and the guardrails that limit spending while the system learns. If those fields are vague, changing bids, match types, audiences, or creative only changes how efficiently Google pursues an undefined goal.
Separate the metric used to diagnose delivery from the metric used to allocate money. Cost per lead can tell you how cheaply a campaign generates leads. Customer acquisition cost tells you whether those leads become customers at an acceptable cost. ROAS can guide revenue-oriented decisions, but it still needs to reflect the revenue that matters to the business rather than an intermediate action.
A €2 range in lead cost concealed a €1,666 difference between the lowest and highest acquisition costs. The platform was not malfunctioning. It was following the cheaper-lead objective it had been given. This does not prove that exact match is always superior. It proves that a low-cost proxy was not safe enough to control budget in that account.
Build your optimization contract in this order:
Name the economic outcome. Decide whether the account must acquire customers, produce revenue, protect margin, or support another business-level result.
Identify the observable conversion. Write down what Google receives: a lead, qualified lead, completed purchase, subscription, or another recorded event.
Map the gap. Note what can happen between the recorded event and the economic outcome, including lead rejection, cancellation, discounting, or delayed sales qualification.
Record the reporting delay. Automation cannot respond promptly to a result that reaches the platform late. The longer the delay, the more carefully you need to control short-term interpretation.
Assign each metric a job. Use delivery metrics to diagnose auctions, business metrics to allocate budget, and financial metrics to judge whether growth is worth buying.
Set a spending boundary. Decide how much exposure you can tolerate while testing a new structure, signal, audience, or channel.
Do not increase live budgets while the account is optimizing toward a proxy you already know is weak. That turns a reporting gap into a real cash loss. Keep the test capped, improve the downstream signal, or stay with a structure you can inspect until the business outcome is visible.
Relevance: Does the conversion represent the result you actually want, or merely a convenient action such as an unqualified form submission?
Signal quality: Are duplicate, accidental, low-value, or rejected outcomes being counted in the same way as valuable ones?
Signal sufficiency: Does the campaign produce enough meaningful outcomes for the system to distinguish a pattern? Low-volume lead generation often needs more manual intervention than purchase-heavy ecommerce.
Signal speed: Does the platform receive the outcome soon enough to connect it with the decisions that produced it?
If a campaign fails any gate, do not pretend the answer is simply more automation. Improve the conversion path, return a better business event, consolidate fragmented signal where appropriate, or use tighter keyword and audience controls. Traditional structures remain useful when they expose differences that an account-level average hides.
Run a controlled graduation test
A graduation test should answer one question: can the more automated setup improve the business KPI without exceeding the risk you approved?
Choose a baseline whose tracking and economics you understand.
Define the candidate change, such as broader targeting or greater bidding freedom.
Keep the conversion definition, offer, and business KPI consistent enough to make the result interpretable.
Protect a comparison group or another credible baseline where the account structure permits it.
Judge the result on CAC, ROAS, margin, or the chosen business outcome. Use CPL and other platform metrics to explain the result, not replace it.
Expand only after the candidate passes. If it fails, diagnose the signal or structure before increasing spend.
This framing prevents a common mistake: letting the automated campaign grade itself using the same proxy it was instructed to maximize. The platform can report that it produced more conversions, but your business records must decide whether those conversions were worth buying.
Build measurement that can settle a budget decision
Delivery layer: Use platform data to understand spend, auction participation, search impression share, and the actions recorded by the campaign.
Acquisition layer: Connect leads and purchases to qualified prospects, customers, revenue, and the CAC or ROAS used to manage the account.
Financial layer: Check whether the acquired business preserves enough margin to justify further investment.
Write down the system of record for each layer. Then document why the figures may differ. A platform may credit an ad interaction while your business system counts only a completed customer. Those numbers answer different questions; forcing them to match can be less useful than making the difference explicit.
Reporting delay deserves its own field in your dashboard. A campaign can appear efficient before rejected leads, cancellations, or downstream sales outcomes arrive. Mark results as preliminary until the business outcome has had time to mature, and compare like-for-like reporting windows when making allocation decisions.
Use MMM only when the business has earned the complexity
Do you have reliable business outcomes rather than only platform conversions?
Is there enough meaningful variation across channels and periods to support useful analysis?
Will the model change a real budget decision that simpler reporting cannot answer?
Have you already fixed known tracking, CRO, and conversion-path problems?
If the answer is no, spend the next measurement dollar on the data foundation. Clean conversion definitions, stronger downstream reporting, and a better path from click to customer create value whether or not you eventually adopt advanced modeling.
Spend the next dollar on the constraint, not the trend
Give every creative test a decision card before production starts:
Question: What uncertainty will this test resolve?
Audience and context: Who should see the message, and in what situation?
Variable: Are you testing the pain point, proof, offer, format, or another defined element?
Business metric: Which downstream result determines the winner?
Next action: What will you pause, revise, or scale after the result?
If you cannot fill in those fields, pause production. The bottleneck may be tracking, conversion rate, offer clarity, customer journey, or product margin rather than a shortage of ads. Fixing that constraint can also produce better signals for the automation already running.
Turn 2026 Shopping promotion rules into an offer test
Google’s January 2026 Shopping policy expansion created practical room for merchants to compete on offer structure, not just the displayed price. Subscription promotions can include a free trial or a discount on initial billing cycles. Merchants can select Subscribe and save in Merchant Center or use the subscribe_and_save redemption option in a promotion feed.
Common retail abbreviations including BOGO, B1G1, MRP, and MSRP also became eligible. In Brazil, promotions can be restricted to particular payment methods, including digital-wallet cashback, by choosing Forms of payment in Merchant Center or using the forms_of_payment redemption restriction. That payment-method option was limited to Brazil, with no wider rollout announced at the time.
Use the additional eligibility as a disciplined merchandising test:
Choose an offer that fits the buying model, such as a subscription incentive for a genuine recurring product.
Calculate the effect of the free period, discount, or cashback on acquisition cost and margin before launching.
Configure the matching redemption type in Merchant Center or the promotion feed.
Make the ad, promotion data, price, and landing experience agree so the customer receives the offer they were shown.
Compare the business result with the existing offer, including customer quality and margin rather than conversion rate alone.
Verify the current Merchant Center policy before launch because eligibility rules can change.
Policy eligibility is not evidence that an offer is profitable. A discount can improve conversion while weakening margin or attracting customers who do not continue after an introductory subscription period. Let the business outcome, not the promotion badge, decide whether the offer remains funded.
The available capabilities include Google audience activation, reach across connected TV and YouTube, household-level frequency management, curated sports packages, and platform-reported links between CTV impressions and purchases. These controls make a test more manageable; they do not make the inventory automatically incremental or profitable.
Before moving money into live sports or other premium CTV inventory, require clear answers:
Are you trying to reach households that the current mix does not reach, or merely buying a more prestigious placement?
Does the creative make sense on the large screen and connect coherently with the follow-up experience on YouTube or another Google surface?
Can your measurement distinguish platform-attributed purchases from a credible business lift?
Is the test budget ring-fenced so a disappointing result does not weaken proven demand-capture campaigns?
What result will cause you to expand, revise, or stop the buy?
Live sports is outside narrow search PPC, but it belongs in the same portfolio decision when one team manages Google investment across screens. Do not move money from a profitable search campaign simply because premium inventory has become easier to buy. Fund it when the account has a reach problem, suitable creative, usable measurement, and an approved loss limit.
Key takeaways for your 2026 PPC plan
Make a business KPI such as CAC, ROAS, or margin the authority for budget allocation; use platform metrics to diagnose how campaigns produced the result.
Grant automation more freedom only when conversion signals are relevant, clean, sufficiently frequent, and returned promptly.
Keep manual keyword, audience, and budget controls when low volume or weak downstream data prevents reliable automation.
Do not scale creative output without a defined hypothesis, business metric, and decision that the test will unlock.
Repair tracking, CRO, and conversion paths before adding MMM or another layer of measurement complexity.
Use expanded Shopping promotions and biddable CTV inventory as controlled business experiments, not automatic claims on incremental budget.
Before your next budget meeting, create a one-page contract for every major campaign: economic outcome, observable conversion, reporting delay, and spending boundary. Any proposed expansion should explain how it improves one of those fields or why the existing contract is strong enough to support more risk.
Your team can produce more words than ever, yet your homepage may still leave a buyer asking three basic questions: Is this meant for me? Does it solve my problem? Why should I believe you?
That gap is where copywriting matters in AI-era marketing. You do not need another layer of generic content. You need language that makes your offer easy for a person to choose and easy for a generative system to match to the right buying situation.
Key takeaways
AI has reduced the value of generic explanation, not the value of persuasion. Information can be compressed; a credible reason to choose you still has to be established.
Write from the buyer’s situation rather than from a broad description of your company. State who the offer is for, what problem it solves, how it works, and what supports the claim.
Generative engine optimization is partly a positioning problem. Your brand must be available as a relevant solution when a person describes a need, not merely visible for a category keyword.
Create separate pages only for meaningfully different decisions. If the audience, offer, proof, and next step are unchanged, changing a few nouns does not justify another page.
Use AI to organize evidence, expose gaps, and produce controlled variations. Keep positioning, promises, exclusions, and factual approval under human control.
Judge copy by commercial movement: qualified visits, revenue-page actions, lead quality, conversions, and branded demand. Raw traffic is not the final objective.
Start with the decision, not the draft
A page can be accurate, readable, and optimized without helping anyone decide. That usually happens when the writing explains a category but never establishes a position inside it.
AI is particularly capable of summarizing, synthesizing, matching patterns, and compressing familiar information. That makes undifferentiated publishing easier to reproduce and easier to replace. It does not remove the need to influence a real choice. In practice, AI exposed the difference between informational production and persuasive copywriting.
Before writing a headline, complete a positioning brief. If your team cannot agree on the brief, polishing sentences will only conceal the disagreement.
You have a budget decision to make, channel data in hand, and four prominent open-source names on your shortlist: Robyn, Meridian, Orbit, and Prophet. The expensive mistake is not choosing the least sophisticated model. It is choosing a framework your team cannot validate, explain, refresh, or use when the next allocation decision arrives.
The first question is not which tool is best. It is whether you need a working marketing mix modeling system or a forecasting component from which your team will build one. Once you make that distinction, the shortlist becomes much clearer.
First, separate MMM systems from forecasting components
Marketing mix modeling uses aggregated business, marketing, and contextual data to estimate how different factors relate to an outcome such as revenue, orders, or qualified leads. A useful MMM workflow must do more than forecast that outcome. It also has to represent delayed advertising effects, account for diminishing returns, estimate channel contributions, communicate uncertainty, and turn the result into a budget scenario.
Automated MMM model exploration, channel response analysis, and budget optimization
A marketing analytics team that wants a relatively direct route from prepared data to actionable scenarios
You still have to choose among plausible models, validate the attribution, and monitor whether performance relationships have changed
Meridian
Bayesian MMM with geo-level modeling and budget-reallocation scenarios
A team with statistical expertise, geographic data, and market-specific allocation questions
The methodology, diagnostics, assumptions, and uncertainty require informed statistical ownership
Orbit
Bayesian time-series forecasting with time-varying coefficients
Engineers and data scientists building a custom measurement system
Your team must add MMM-specific transformations, attribution logic, validation, reporting, and optimization
Prophet
Forecasting and separation of trend and seasonal patterns
A team that needs a temporal modeling component inside a broader pipeline
It does not provide a complete channel-attribution or budget-allocation system
This is more than a feature comparison. A model can predict next period’s sales accurately while assigning the wrong reason for those sales. Forecasting performance does not, by itself, establish credible marketing attribution. If your question is where to move budget, start with an MMM framework. If your goal is to build proprietary measurement infrastructure, a forecasting library may be the more flexible foundation.
Open source removes a software-licensing barrier. It does not remove the cost of data preparation, statistical review, engineering, documentation, or ongoing model ownership. Include those jobs in your tool decision from the start.
Match the tool to the way your team will operate it
Choose Robyn when the priority is a usable MMM workflow
Multiple solutions are a strength only if you have a rule for choosing among them. Do not automatically select the model with the most attractive return on ad spend or the most aggressive budget recommendation. Require acceptable overall fit, plausible channel behavior, stability across candidate models, and consistency with any experimental evidence you possess.
Robyn also carries an important operating assumption: marketing performance is treated as reasonably consistent over the modeled period. A product launch, pricing change, tracking migration, major distribution shift, or campaign redesign can break that assumption. Mark known structural changes in the data and revalidate the relevant period before treating an old channel coefficient as current.
Choose Meridian for geo-level questions and Bayesian depth
Meridian is better suited to teams that want an advanced Bayesian model and can use geographic variation in their analysis. Its geo-level orientation is valuable when the real decision is not simply how much to spend by channel, but how channel performance and allocation may differ across markets.
Do not choose Meridian merely because Bayesian sounds more rigorous. Bayesian modeling moves important judgment into model structure, prior assumptions, diagnostics, and interpretation of uncertainty. The right team should be able to explain those choices to the budget owner and rerun the analysis without depending on one person who understands the implementation.
Meridian’s scenarios describe what may happen under the fitted model and its assumptions. They are not promises about the next planning period. That distinction should remain visible in every budget recommendation.
Choose Orbit when you intend to build the MMM yourself
Orbit is a forecasting foundation, not a shortcut to a finished MMM program. Its Bayesian time-varying coefficients are useful when relationships may evolve, but your team must still design the marketing-specific parts of the system. That includes carryover and saturation transformations, channel-contribution logic, scenario generation, validation, reporting, and an interface that planners can actually use.
Orbit makes sense when custom behavior is the requirement and you have engineers and statisticians who will own the framework as a maintained product. If the custom build is only a way to avoid adapting to an existing MMM workflow, the maintenance burden will probably exceed the benefit.
Use Prophet for temporal structure, not standalone attribution
Prophet can help separate trend and seasonal patterns from a time series. That can make it useful in preprocessing, baseline forecasting, or another supporting role. It does not independently tell you how much incremental revenue a channel created or how the next budget should be allocated.
If a proposed Prophet implementation ends with channel-level return figures, ask where the attribution assumptions, response curves, delayed effects, and optimization rules enter the pipeline. If those layers have not been designed and validated, you have a forecast labeled as an MMM.
Build the minimum viable measurement plan before installing a tool
An MMM project should begin with a decision specification, not a package installation. The specification prevents a technically valid model from answering a question no one needs to ask.
Write the allocation decision in one sentence. Name the business outcome, the budget that can move, the channels or markets in scope, and the planning decision the model must support. A request to understand marketing is too broad to determine the right model.
Fix the unit, calendar, and boundaries. Choose one outcome definition and one consistent time interval. Align spend, exposure, business outcomes, promotions, and other controls to the same calendar and market coverage. Mismatched cutoffs can make an ordinary timing error look like an advertising lag.
Create a channel dictionary. Record what each column includes, whether it represents spend or exposure, how platform names map to planning channels, and where definitions changed. Grouping should be detailed enough to support a decision but not so fragmented that several nearly identical series compete to explain the same movement.
Identify demand drivers and structural breaks. Marketing is not the only reason an outcome changes. Record known effects such as promotions, price changes, distribution changes, launches, and tracking migrations. A model cannot infer a business event that is absent or incorrectly encoded in its inputs.
Decide how delayed effects and saturation should behave. Advertising may continue to influence outcomes after the spend occurs, and additional spend may produce progressively smaller gains. Robyn and Meridian include mechanisms for these behaviors, but the resulting curves still need to make sense for the channel and the observed data.
Define acceptance checks before seeing ROI estimates. Specify how you will assess fit, channel plausibility, stability across acceptable models, agreement with experiments, and sensitivity to changed assumptions. Setting the rules first reduces the temptation to accept whichever model supports the preferred budget narrative.
Assign an operating owner. Name who refreshes the data, investigates failed checks, approves model changes, documents assumptions, and translates scenarios into planning constraints. If no one owns the second run, the first run is a demonstration rather than a measurement capability.
Data variation matters throughout this process. A channel that barely changes cannot reveal much about how different spending levels affect the outcome. Two channels that always rise and fall together are difficult to separate cleanly. The tool may still return precise-looking contributions, but interface precision cannot create information the data does not contain.
The budget optimizer belongs at the end of this workflow. If the outcome, calendar, channel definitions, or response assumptions are wrong, optimization simply reallocates the error with greater confidence.
Treat allocation outputs as testable scenarios, not account ledgers
MMM contributions are model-conditioned estimates. They are not transaction records showing exactly which channel caused each sale. This matters because the most visually convincing output is often the optimizer: it turns uncertain relationships into a clean allocation. The neatness of that recommendation can hide the uncertainty underneath it.
Run four checks before moving material budget
Check direction across acceptable models. If one credible model says to increase a channel and another says to decrease it, the decision is not robust. Report the disagreement instead of averaging it into false certainty.
Separate interpolation from extrapolation. A response curve is more defensible within spending levels represented in the data. A recommendation far beyond that range depends heavily on the assumed curve shape. Label that dependence and use a staged change rather than treating the estimate as observed behavior.
Use experimental outcomes where available. Robyn can incorporate real-world experiment results. Treat those results as calibration evidence and investigate meaningful conflicts between the experiment and the observational model rather than selecting the answer with the better financial story.
Apply real planning constraints. Contracts, minimum brand presence, inventory, market capacity, and operational limits do not disappear because an unconstrained optimizer prefers a different allocation. Put those constraints into scenario design or apply them before presenting the recommendation.
A full reallocation based on a first model can waste budget if the model has learned a temporary correlation or extrapolated beyond the available evidence. Stage consequential changes where possible, observe the outcome, and feed that evidence into the next model cycle. The objective is not to obey an optimizer. It is to make a better decision and create evidence for the decision after it.
Your final output should show more than a single return estimate. Keep the modeled period, outcome definition, channel mapping, major assumptions, candidate-model uncertainty, scenario constraints, and known structural breaks beside the recommendation. A planner should be able to see why the number may change before acting on it.
Key takeaways
Robyn is the practical default when you need an accessible, end-to-end MMM workflow and can actively validate its candidate models.
Meridian fits geo-level allocation questions when your team has the statistical depth to own a Bayesian model and explain its uncertainty.
Orbit is a foundation for a custom time-series and MMM system, not a ready-made attribution and optimization product.
Prophet can model trend and seasonality, but it does not become a complete MMM simply because marketing variables are added.
Choose the tool only after defining the budget decision, data boundaries, validation checks, planning constraints, and long-term owner.
If you need a usable MMM workflow, start by testing Robyn against one clearly defined allocation decision. Evaluate Meridian instead when geographic variation is central and Bayesian expertise is available. Reserve Orbit for a deliberate custom build, and use Prophet only for the supporting forecasting job it is designed to do.
Before installing anything, complete this sentence: We will use [outcome] at [time and geographic level] to decide [specific budget action], and we will trust the result only if it passes [named validation checks]. If your team cannot fill in those four blanks, tool selection is premature.
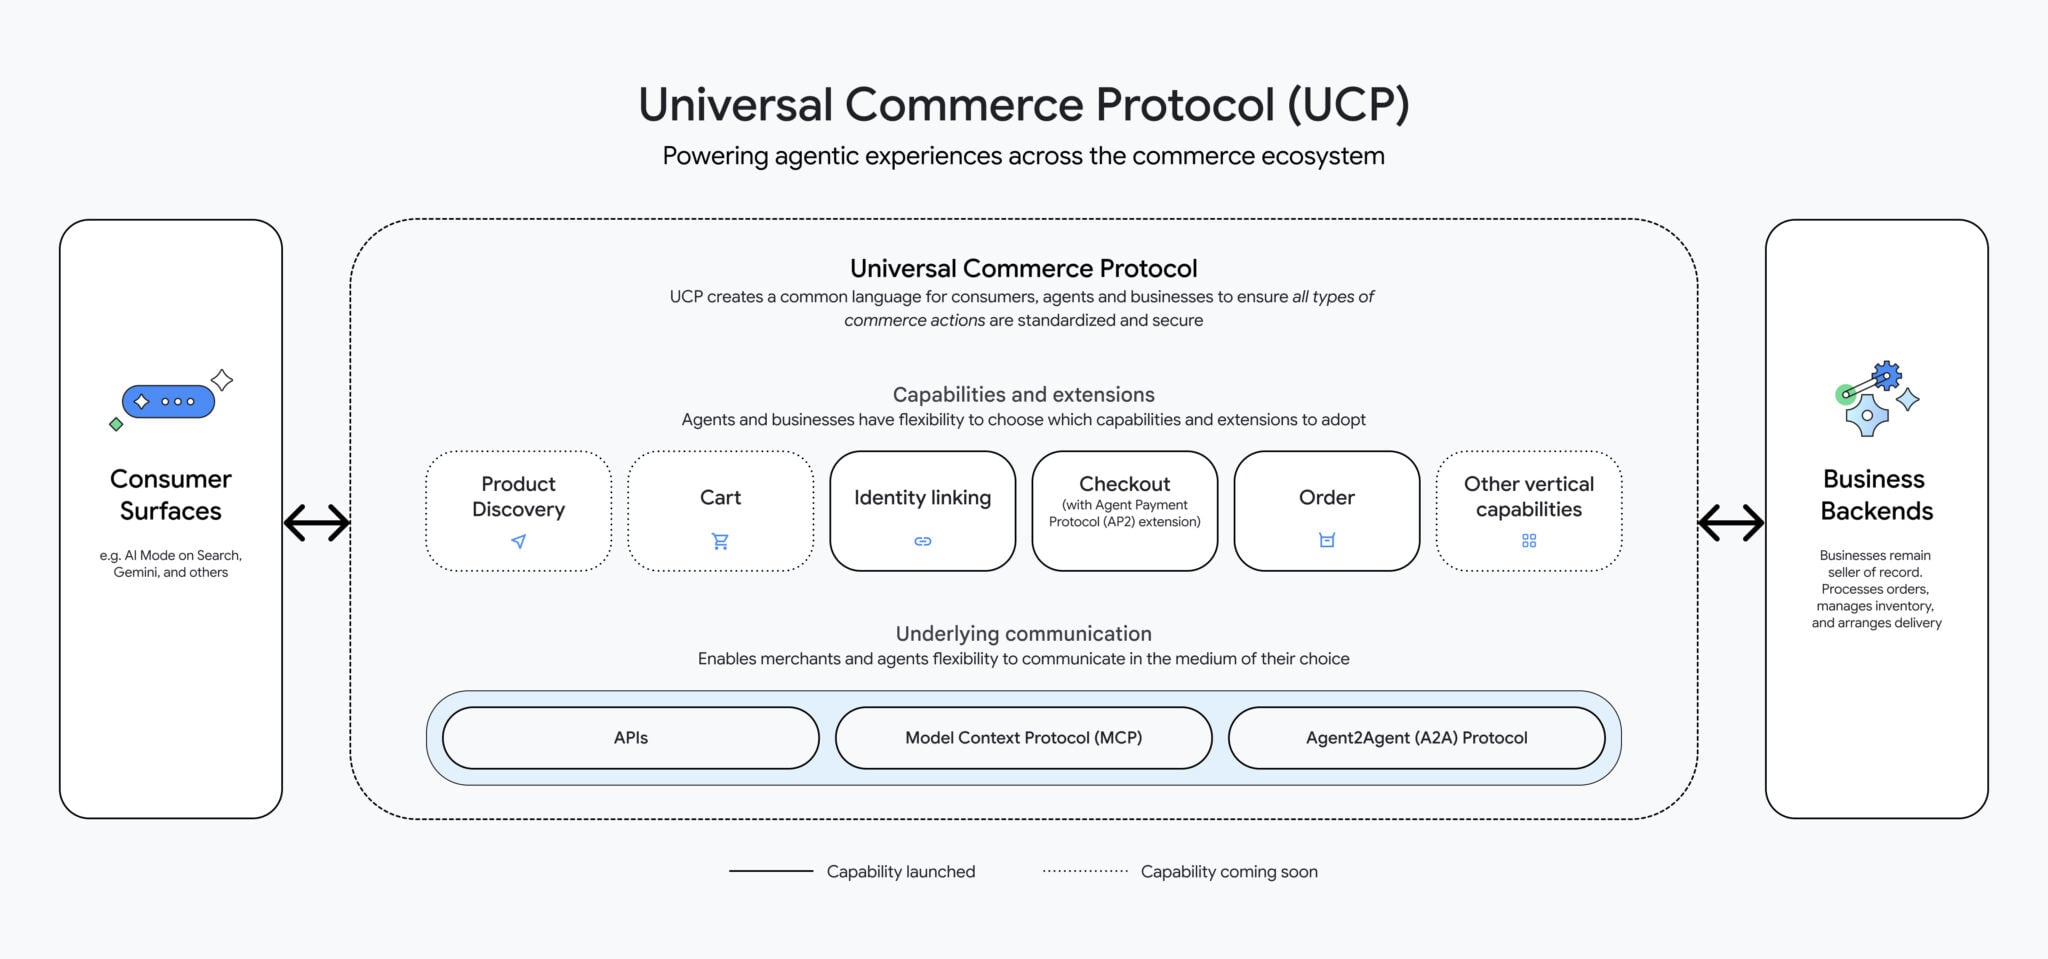
Have you heard the news? Google has just launched the Universal Commerce Protocol (UCP), an innovative open standard that integrates AI agents throughout the entire shopping experience. From discovering products to making purchases and even receiving support after the sale, UCP facilitates it all.
In exciting developments for retailers, Google is also rolling out new AI tools. These include branded shopping agents and ad formats that enhance AI-driven discovery, making the shopping experience more streamlined and engaging.
About UCP
This protocol offers a common language for AI agents and commerce systems, greatly simplifying the need for custom integrations across different platforms.
UCP is compatible with existing standards like Agent2Agent and the Model Context Protocol.
The protocol was co-developed with prominent partners such as Shopify, Etsy, Wayfair, and Target.
It’s already endorsed by over 20 additional companies in the retail and payments sectors.
What’s Changing
The UCP is set to enhance the checkout experience for Google product listings via AI Mode in Search and the Gemini app. Shoppers can make purchases through Google Pay, with options to use saved payment and shipping details. Integration with PayPal is also on the horizon.
Google aims to lower cart abandonment and provide retailers with tailored integration options suited to their needs.
Upcoming features include loyalty rewards and personalized shopping experiences.
Business Agent
In tandem with UCP, Google is unveiling the Business Agent, a branded AI assistant that provides shoppers with direct interaction opportunities on Search. Think of it as a virtual sales associate offering real-time responses in your brand’s own tone.
Major retailers like Lowe’s, Michael’s, Poshmark, and Reebok are already on board. Future capabilities may include deeper customization, data training, and a seamless agent-led checkout.
Direct Offer
Google is also testing Direct Offers, a fresh initiative within Google Ads tailored for AI adoption. When AI senses that a shopper is likely to make a purchase, a special discount can be presented.
This pilot will soon expand to incorporate offers such as product bundles, complimentary shipping, and more enticing incentives.
Why It Matters
The rise of agent-led shopping reshapes where and how buying choices are made. Google’s new AI tools and protocols are taking the lead, allowing advertisers to influence these pivotal moments during an AI-driven shopping journey.
Tools like Direct Offers and branded agents create new pathways for advertisers to finalize sales efficiently, all while safeguarding profit margins. The balance between conversion improvements and losses in direct site traffic remains an open discussion.
Bottom Line
According to Google, agentic shopping is unstoppable. With innovations like UCP and its complementary retail tools, Google ensures that AI-driven commerce remains inclusive and accessible, keeping retailers engaged as agents transform the buying landscape.
You can make financial research easy for an AI system to find, summarize, and cite. The harder question is whether the answer remains trustworthy after the system compresses it. A careful analysis can become a dangerously confident sentence when its evidence, assumptions, or limits disappear.
Your job is therefore larger than increasing AI visibility. You need to publish answers whose meaning survives extraction: the claim stays connected to its evidence, the reasoning can be inspected, and the boundary between general research and personal financial advice remains unmistakable.
Key takeaways
Optimize financial research for verification before visibility. Search exposure cannot make an unsupported conclusion reliable.
Place the evidence, reasoning, relevant date, and limiting condition close to every consequential claim.
Connect technical signals, fundamentals, alternative data, and portfolio context without forcing them into artificial agreement.
Write important qualifiers into the sentence an AI system is most likely to extract, not into a distant disclaimer.
Use structured data and on-page optimization to describe trustworthy content, never to manufacture the appearance of authority.
Trust begins where the answer can be checked
Financial information has a short trust fuse because weak or inaccurate research can produce fast, measurable consequences. A vague answer about an ordinary purchase might waste time. A vague answer that influences a trade, allocation, credit decision, or risk assessment can lose money.
That changes the minimum standard for a useful page. A reader should be able to identify what you know, how you know it, what you inferred, and what could invalidate the inference. An AI-generated summary should preserve those distinctions instead of presenting every sentence as an equally established fact.
Use a six-field answer card
Before drafting a financial answer, complete these six fields. They can live in your editorial brief, content management system, or review checklist:
User question: Record the exact decision or uncertainty the page will address. A broad topic such as market risk is not yet a usable question.
Bounded answer: Write the shortest conclusion the available evidence can support. Include the market, asset, period, or scenario that limits the claim.
Evidence: Identify the underlying observations and where they came from. Preserve relevant dates, units, definitions, and methodology.
Reasoning: Show how the evidence leads to the conclusion. Name any assumption that the argument needs in order to hold.
Limit: State what the evidence does not establish, which alternative explanation remains possible, and what would change the conclusion.
Ownership: Assign responsibility for reviewing, updating, correcting, or withdrawing the answer when its basis changes.
If you cannot complete the evidence or limit field, do not ask a language model to fill the gap. Its fluent transition may disguise the absence of support. Publish a narrower answer, label the uncertainty, or withhold the conclusion until it can be checked.
Separate observation, calculation, and interpretation
A trustworthy answer distinguishes three layers that are often blended together:
Observation: What was measured, reported, or recorded?
Calculation: What transformation or comparison did you apply to those observations?
Interpretation: Why might the result matter, and which assumptions connect it to that meaning?
Labeling these layers prevents an interpretation from inheriting the apparent certainty of the underlying data. It also gives an AI system clearer units of meaning to retrieve. Instead of receiving a paragraph that mixes facts and forecasts, the system encounters an explicit evidence chain.
Keep the safety boundary close to the consequential statement. If a conclusion could influence an individual’s financial decision, present it as general research and direct the reader to a qualified financial professional for advice based on their circumstances. A footer disclaimer does not repair personalized or overly certain language in the main answer.
Connect the evidence without hiding disagreement
Trust weakens when readers have to assemble an answer from unrelated dashboards, definitions, charts, and commentary. Each extra handoff introduces another opportunity to misread the period, use a different definition, or miss an important qualification. Fragmentation also makes it harder to demonstrate that you understand how the pieces relate.
For a consequential research question, organize that route in this order:
Answer: Give the bounded conclusion and its main limitation.
Change: Show what happened and the comparison that makes the change meaningful.
Drivers: Explain the mechanisms that could account for it.
Cross-checks: Show which other evidence supports, weakens, or contradicts the interpretation.
Relevance: Explain how the finding may affect a general research or portfolio question without turning it into personal advice.
Method: Make definitions, provenance, calculations, and update information available where the reader needs them.
The cross-check stage matters. Connected research is not research in which every indicator agrees. If a technical signal points one way while fundamentals or alternative data point another, preserve the disagreement. Explain whether the measures cover different time horizons, definitions, or mechanisms. If you cannot reconcile them, say that plainly.
A useful explanation answers five questions: What happened? Compared with what? Through which mechanism could it matter? What else could explain it? What evidence would make us revise the conclusion? Those questions turn a data display into reasoning the reader can inspect.
Centralization can be achieved without creating an enormous page. Use shared definitions, consistent labels, visible dates, stable identifiers, and direct links between related modules. The goal is continuity of meaning. A reader moving from a chart to a methodology note should not have to guess whether the same term, period, or calculation still applies.
Optimize for AI retrieval without manufacturing authority
Can a search or AI system reach and read the main answer?
Keep the substantive answer in accessible page content, maintain clear internal links, and make machine-readable descriptions consistent with what users can see.
Missing evidence or an unsupported conclusion.
Semantic extraction
Can a passage retain its meaning when removed from the page?
Use descriptive headings, stable terminology, explicit relationships, and short passages that keep claims beside their qualifiers.
Ambiguous reasoning or conflicting definitions.
Epistemic credibility
Can a reader inspect why the claim should be believed?
Expose provenance, calculations, assumptions, counterevidence, limitations, and review ownership.
Stale, inaccurate, or fabricated inputs.
Decision safety
Could the answer be mistaken for individualized advice?
Define the intended use, avoid prescriptive language about personal circumstances, and place warnings beside the relevant conclusion.
A risky claim hidden behind a general disclaimer.
Apply these layers in order. Making weak analysis easier to crawl only distributes the weakness. Adding structured data to vague content only describes the vagueness more efficiently. Technical optimization should expose a sound evidence structure that already exists on the page.
At the page level, use these rules:
Lead with the bounded answer. State the conclusion, scope, and main qualification before expanding the analysis.
Use headings that describe the reasoning. A heading such as “Why the indicators disagree” carries more information than “Analysis.”
Keep one main claim per paragraph. This makes extraction cleaner and reduces the chance that a qualifier will attach to the wrong conclusion.
Put evidence links beside the supported claim. A generic bibliography forces readers and machines to reconstruct the relationship.
Keep critical qualifiers in the same sentence. Write “under these assumptions” or “for this period” where the conclusion appears.
Define terms once and use them consistently. If two metrics sound similar but differ, explain the distinction before comparing them.
Make visible content and machine-readable markup agree. Structured data should reflect the answer, authorial responsibility, and other information actually available to the reader.
Avoid producing thin pages for every wording of the same query. Financial authority emerges from linking concepts and showing their relationships in a comprehensive answer. One well-maintained explanation with clear subtopics is usually a stronger foundation than a collection of near-duplicates that omit context.
Run a trust audit before the page becomes an AI answer
Your final review should test more than grammar, keyword use, and formatting. It should simulate what happens when a search engine, assistant, analyst, or hurried reader extracts only the most quotable part of the page.
Build a claim ledger. Copy each consequential claim into a review sheet. Label it as an observation, calculation, interpretation, scenario, or recommendation. If the label is unclear, the sentence probably blends categories.
Trace the evidence. Confirm that every observation has identifiable provenance and that the relevant date, definition, unit, and scope remain available. Do not accept a citation that merely discusses the same topic.
Reperform the reasoning. Follow the path from evidence to conclusion without relying on the prose’s confidence. Check whether a missing assumption or alternative explanation breaks the chain.
Test the qualifier. Copy the key conclusion into a blank document. If it becomes misleading without a nearby paragraph, rewrite the sentence so its essential boundary travels with it.
Look for forced agreement. Identify evidence that conflicts with the conclusion. Explain the disagreement, narrow the claim, or state that the result is unresolved.
Check the decision boundary. Ask whether a reasonable reader could mistake general research for an instruction tailored to their finances. If so, revise the language and position professional-help guidance next to the risk.
Assign the next review. Record what type of change would trigger reassessment and who can correct or withdraw the conclusion. Trust depends on how you handle changed information, not only how carefully you launch a page.
Use a simple release gate. Publish when the evidence, reasoning, scope, and limits are all inspectable. Revise when the evidence is sound but the extracted answer could mislead. Hold the page when a consequential conclusion cannot be verified. Do not let polished AI-generated prose turn that third condition into the second.
Start with one financial page that already attracts an important question. Rebuild it around the six-field answer card, connect the evidence that a reader would otherwise have to assemble, and run every key sentence through the extraction test. Once it passes, use that page as the editorial pattern for your wider AI search strategy.
I recently spoke with Anthony Higman, the CEO of AdSquire, on episode 336 of PPC Live The Podcast. Anthony’s remarkable journey took him from the mailroom of a law firm to the helm of his own company with a panoramic view of Philadelphia. His story exemplifies how dedication, learning from missteps, and perseverance can forge a successful career path.
Learning from Client Missteps
Anthony opened up about one of his early blunders with a client, where he allowed them to chase after quick-win promises in numerous emails. Though some were outright scams, others were genuine but unaligned with the client’s goals. His decision to let a client engage with an ineffective SEO agency resulted in subpar outcomes and a revolving door of agencies for the client.
The lesson learned was clear: building trust with clients is vital, but it’s equally important to provide them with strategic guidance. Striking a balance between educating them and respecting their autonomy is key.
A Career Lesson from ‘Cowboy Moves’
Recalling another early career incident at a large advertising agency managing car dealership accounts, Anthony described how he took independent action to correct widespread account mismanagement, considerably enhancing results. However, his proactive steps clashed with company norms, leading to his dismissal.
This taught him invaluable lessons: knowing one’s values and finding workplaces aligned with them is crucial. Moreover, balancing client success with company expectations is crucial. Today, at AdSquire, he emphasizes consistent account management and clear communication within his team.
Managing Client Expectations in a Complex Industry
Anthony highlighted the challenges of managing expectations in competitive industries like legal marketing. While clients often seek various services like SEO and social media, focusing on core strengths rather than spreading resources thin is essential for achieving the best results.
The Role of Mistakes in Growth
He believes that mistakes are fundamental to growth. At AdSquire, he encourages his team to learn from their errors without fear of losing their jobs, as long as they remain honest and aligned with the company’s vision. This approach cultivates a culture of learning, accountability, and innovation.
Common Mistakes in Modern Paid Search
With AI advancements in Google Ads, Anthony has noticed frequent mistakes such as improper search partner and location settings, automated assets misuse, and auto-apply recommendations. While AI can streamline processes, strategic oversight is essential to avoid undermining performance.
Key Takeaways from Anthony’s Stories
Anthony’s experiences offer two main insights:
Guide clients strategically, steering them away from scams while presenting genuine growth opportunities.
Understand your values and choose environments where your ethics and skills align. Never compromise on your principles.
His philosophy illustrates that mistakes can lead not to failure but to redemption, innovation, and enduring success.
Looking Ahead: AI and the Future of Google Ads
Anthony envisions continued AI integration in Google Ads by 2026. While some tools may falter or conflict with specific needs, maintaining strategic oversight and adding a personal touch will remain crucial. Misguided use of AI, such as automated video inventory creation, can yield inconsistent results and demands vigilant monitoring.
Conclusion: F-Ups Lead to Redemption
Reflecting on his career, Anthony draws parallels with The Shawshank Redemption. Every misstep contributed to future opportunities, eventually enabling him to establish AdSquire and earn recognition as a top PPC influencer. The overarching lesson: embrace your mistakes, learn from them, and let them serve as pathways to success.
If you manage Performance Max, the uncomfortable choice can seem to be full automation or a maze of duplicated campaigns. That is the wrong choice. You can give the system better creative and stronger intent signals without rebuilding the account every time a limit changes.
The useful distinction is simple: video assets shape what Performance Max can show, while search themes help steer the demand it should explore. Neither gives you deterministic control. Each gives the automation better inputs, and each needs a different plan.
Know which Performance Max controls are signals
Performance Max controls do not all behave like conventional campaign settings. A hard limit determines what you can upload. A signal communicates what matters to your business. Confusing those roles leads to two common mistakes: treating themes like exact-match keywords and treating every new asset slot as an instruction to create another variation.
Control
What it changes
What it does not guarantee
Decision to make
Video assets
The creative ideas, formats, and ratios available within an asset group
That every upload becomes an isolated or equally weighted test
Which missing asset would add meaningful coverage or test a clear idea?
Search themes
The queries and intent patterns you want automation to prioritize
A strict keyword boundary around the traffic the campaign can pursue
Which customer intents deserve a stronger signal?
Audience signals
Additional context about the people likely to matter
A fixed audience that automation can never move beyond
Which customer characteristics improve the meaning of the intent signal?
This distinction gives you a useful operating rule: diagnose whether the campaign lacks material to show, clarity about demand, or a coherent asset-group structure. Add the control that addresses that specific deficit.
Expand video coverage without filling slots for its own sake
Google has been testing a change from a five-video limit to as many as 15 videos per asset group. The observed option had not received a formal announcement, so treat it as a test or gradual rollout until your own interface exposes it. Do not restructure a live campaign in anticipation of capacity your account does not yet have.
If the larger limit is available, use the extra room in this order: