Month: August 2026

  • Google Business Profile Ranking Factors: What to Fix First

    Google Business Profile Ranking Factors: What to Fix First

    Your Google Business Profile can look finished and still be poorly aligned with the searches that matter. If it is not appearing where you expect, resist the urge to rewrite every field. Start with a narrower question: does the primary category accurately describe the service behind the query you want to rank for?

    Category relevance, category specificity, and basic Profile completeness give you a practical order of operations. They do not guarantee a top-three Maps position, but they can help you correct clear mismatches before you spend time on less certain changes.

    Key takeaways

    • Your primary category should be the most specific accurate match for the main service or business type you want Google to associate with the Profile.
    • Specific primary categories were associated with a 12.5% top-10 presence, compared with 9.2% for generic categories.
    • Relevant additional categories can clarify real secondary services, but broad filler categories do not provide the same advantage.
    • A claimed Profile with a website, description, hours, and photos has a stronger baseline than an incomplete Profile, although completeness alone is not enough to secure visibility.
    • The available numbers are correlations. Use them to prioritize your audit, not to predict an exact ranking gain.

    Start with the query, then choose the primary category

    A category is a classification of the business, not a place to list every service you might sell. The primary category has to do two jobs at once: represent what the business genuinely is and align with the customer need behind the target query.

    The distinction between generic and specific categories is substantial. Across 1.8 million Google Business Profiles spanning 4,209 categories, businesses using specific primary categories had a better average rank and appeared in the top 10 more often than businesses using generic categories.

    Primary category typeProfilesAverage rankTop-10 presence
    Generic55,09150.09.2%
    Specific1,664,73345.812.5%

    Lower average rank is better in this table. The relative increase from 9.2% to 12.5% is about 36%, but the more important lesson is not the percentage. It is the direction of the decision: when an accurate specialist category exists, defaulting to a broad umbrella category can weaken the match between your Profile and a specific search.

    The pattern becomes clearer at the query level. For searches related to hair salons, the exact primary category Hair salon appeared in the top 10 in 11.3% of observations. Adjacent categories performed less well: Hairdresser reached 6.0%, Beauty salon 3.2%, Barber shop 1.3%, and Nail salon 0.0%. Those labels may all sound relevant to a human, but they describe different entities to the ranking system.

    Competition also matters. A specific category usually puts the business into a smaller and more relevant competitive set. A plumber is competing as a plumber rather than as every possible type of contractor. That does not make a specific category an automatic shortcut; it makes the business-to-query relationship clearer.

    Use this decision process when reviewing your primary category:

    1. Write down the single local query that represents the most important customer need you can genuinely satisfy.
    2. Identify the business type that most directly answers that need. Focus on what the business is, not a phrase you merely want to rank for.
    3. Choose the narrowest available category that remains fully accurate for the core business.
    4. If two categories are accurate, reserve the primary position for the service or business type you most need the Profile to represent. Consider the other for an additional category.
    5. Reject any category that would create the wrong expectation when a customer calls, books, or arrives.

    Do not treat category performance tables as a leaderboard. A restaurant cannot become a tapas restaurant because that category has less competition, and a general contractor should not select plumber unless plumbing accurately describes the business. Ranking alignment is useful only when the category is truthful.

    Use additional categories to sharpen the Profile
    Illustration of a storefront with one large primary category card and three smaller supporting category cards.

    The primary category establishes the main identity. Additional categories can cover distinct services or specialisms that are genuinely part of the business. Their purpose is to extend the entity without blurring it.

    Profiles with carefully aligned additional categories were associated with better rankings than single-category Profiles. Across the broader dataset, the difference was commonly between 6 and 17 ranking positions. The examples below show how a specific secondary category compared with no additional category and with the broad Service establishment category.

    Primary categoryRelevant additional categoryAverage rank with relevant additionAverage rank with no additionAverage rank with Service establishment
    VeterinarianEmergency veterinarian service33.951.275.6
    ElectricianEV charging station contractor38.247.563.5
    PlumberDrainage service47.354.062.3
    RoofingGutter service47.152.170.3
    DentistCosmetic dentist47.657.653.7

    The specific additional category produced the best average rank in every combination shown. The generic category did not. That does not prove that adding a category caused the entire difference. Businesses that maintain thoughtful category selections may also be more diligent about reviews, Profile maintenance, and local SEO outside the Profile.

    Even with that limitation, the decision rule is useful: add a secondary category when it names a real and meaningful part of the business. Do not add categories merely because they are adjacent to your industry or broad enough to sound harmless.

    • Add a category when it represents an established service line, specialty, or operating identity that customers can actually choose.
    • Keep it secondary when it is accurate but less central than the business represented by the primary category.
    • Leave it out when it describes an aspiration, an occasional exception, or a service you cannot consistently deliver.
    • Question generic labels when a more precise category communicates the same part of the business.

    Read the complete category stack as one statement. A primary category of Plumber with Drainage service as an additional category describes a coherent business. A long collection of loosely related categories makes the entity harder to interpret and gives you no reliable basis for diagnosing which query each category is meant to support.

    Complete the five measured basics without overreading them

    A Profile cannot communicate much if its essential fields are absent. Five basic elements provide a useful completeness check: claimed status, a website, a business description, operating hours, and photos.

    This five-point checklist is an analytical index, not an official Google completeness score. One point was assigned for the presence of each element. It did not measure the accuracy, depth, freshness, or persuasive quality of the information.

    Completeness scoreAverage rankTop-10 presence
    0 of 5624%
    1 of 5585%
    2 of 5547%
    3 of 5509%
    4 of 54711%
    5 of 54313%

    Moving from zero to five completed elements was associated with an average-rank improvement of about 19 positions. Top-10 presence rose from 4% to 13%, more than tripling. The progression is consistent at every step, which makes basic completion an obvious part of a Profile audit.

    It also shows why completeness should not be mistaken for a complete ranking strategy. Even among Profiles scoring five out of five, only 13% appeared in the top 10. Completion removed obvious deficiencies; it did not erase competition or make every business relevant to every query.

    Check the five elements for both presence and usefulness:

    1. Claimed status: confirm the business controls the Profile rather than leaving it unclaimed.
    2. Website: make sure a working, appropriate business page is connected.
    3. Description: explain the actual business and its important services plainly. Presence earned the point in the index; repetition and keyword density were not measured.
    4. Hours: provide the operating hours customers need in order to make a visit or contact decision.
    5. Photos: include images that genuinely represent the business. The index recorded whether photos existed, not how many were uploaded.

    The distinction between presence and quality matters. The numbers do not establish that a longer description ranks better, that adding more photos produces a ranking increase, or that repeated edits create an advantage. They support completing the fields, not inventing an optimization formula inside each one.

    The index also did not include every field available in a Google Business Profile. Services, products, attributes, and other Profile data were outside its scope. You can maintain those fields for accuracy and customer usefulness, but this particular evidence cannot tell you what ranking weight they carry.

    Separate a ranking signal from a ranking promise

    Ranking-factor discussions become misleading when an association is converted into a guarantee. The category and completeness patterns are useful because they are large, consistent, and operational. They still come from observational data.

    The primary-category result has the clearest practical mechanism. An exact, specific category describes a closer match to a specific query and often competes within a narrower group. That gives you a strong reason to correct a generic or mismatched primary category. It does not tell you that changing the category will move your Profile a fixed number of positions.

    The evidence for additional categories requires more caution. A business owner who selects a precise set of additional categories is also more likely to maintain the rest of the Profile, seek reviews, and work on local visibility elsewhere. Some of the observed ranking difference may come from that broader effort.

    Completeness has the same limitation. Complete Profiles ranked better on average, but completion may also identify businesses that take local search more seriously. The five-point index measured whether fields existed, not whether Google treated each field as an independent ranking signal.

    Average rank is not a forecast for your business either. It combines businesses operating in categories with different levels of competition. Use the averages to decide which obvious problems deserve attention first. Judge your own result against the query, category, and competitive market you actually face.

    • Strongly supported action: replace a generic primary category with a more specific category when the specific category accurately represents the core business.
    • Reasonable action with a caveat: add relevant secondary categories for genuine specialties, knowing that broader optimization habits may account for part of the ranking difference.
    • Foundational action: claim the Profile and add its website, description, hours, and photos.
    • Unsupported leap: assume that one category change, a longer description, or a higher photo count guarantees a particular Maps position.

    Run your Google Business Profile audit in this order
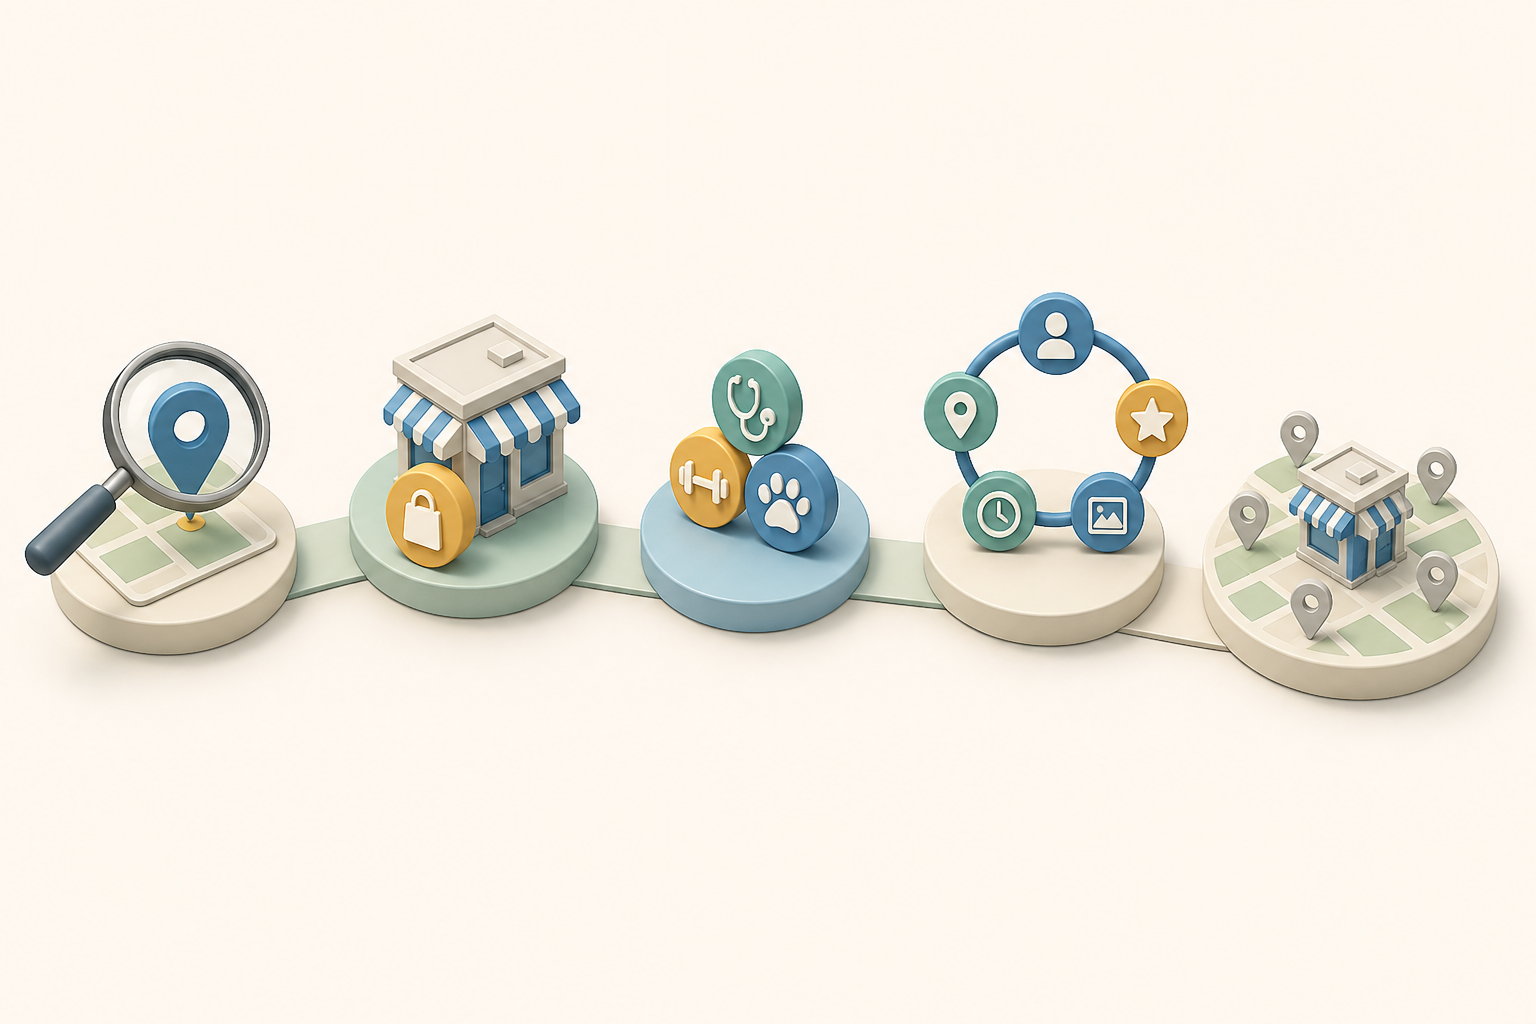
    Isometric audit path with checkpoints for a search query, primary category, supporting categories, five profile details, and map visibility.

    A useful audit begins with search intent and ends with a clean record of what you changed. This order prevents basic category problems from being buried under cosmetic edits.

    1. Select one priority query. Choose a customer need that matters to the business and that the business is fully qualified to satisfy. Do not begin with a vague goal such as ranking for everything in the industry.
    2. Compare the query with the current primary category. If the category is generic while a truthful specialist category exists, evaluate the specialist category first.
    3. Map secondary lines of business. List the distinct services or specialties that deserve representation, then match only those to relevant additional categories.
    4. Remove ambiguity. Question broad filler categories, unsupported specialties, and combinations that make the Profile describe several different businesses at once.
    5. Complete the five-field baseline. Confirm claimed status, website, description, hours, and photos. Correct inaccurate information instead of merely filling empty fields.
    6. Keep a change log. Record the target query, old and new primary categories, additional-category changes, and missing fields you completed. If you need to understand what made a difference, avoid changing every available field in the same batch.
    7. Evaluate the result query by query. A stronger match for one service does not mean the Profile will improve for every adjacent search. Measure the outcome against the intent that drove the category decision.

    If the Profile still uses a broad category such as Contractor while the business is specifically an electrician, plumber, roofer, or HVAC contractor, begin with the primary category. Generic contractors had an average rank of 57.7 and an 8.0% top-10 presence, while the specific contractor categories in the same comparison produced better average ranks and top-10 rates ranging from 10.4% to 12.6%.

    If the primary category is already precise but the business has a meaningful specialty, review additional categories next. A plumber offering drainage work has a clearer reason to consider Drainage service than to add Service establishment.

    If the categories are coherent but one or more of the five basic elements is absent, complete the Profile before interpreting disappointing visibility as a subtler ranking problem. An unclaimed or nearly empty Profile introduces a preventable weakness.

    If the primary category is accurate, additional categories are relevant, and all five basics are present, stop endlessly rewriting fields that were measured only for their presence. Your remaining visibility problem may sit outside this narrow set of Profile variables and requires a broader local SEO diagnosis.

    Begin with one valuable query. Give the Profile the narrowest truthful primary category for that need, add only categories that represent real specialties, and complete the essential fields. The goal is not to make the Profile look busy. It is to make the business unmistakably clear.

    References


  • SEO Roadmap Planning: From Backlog to Measurable Outcomes

    SEO Roadmap Planning: From Backlog to Measurable Outcomes

    Your SEO plan probably is not short on work. The problem starts when leadership asks what will ship, which result it should change, and why it should receive scarce content, product, or engineering capacity.

    A useful roadmap answers those questions before work begins. It turns SEO from a stream of recommendations into a set of deliverable, measurable commitments without pretending that every good idea is ready to be scheduled.

    Key takeaways

    • Keep the backlog as your intake system. Reserve the roadmap for initiatives that have a business outcome, an owner, a delivery path, and a measurement plan.
    • Qualify initiatives with SCOPE: strategic alignment, confidence in delivery, ownership of execution, potential impact, and effort plus elapsed time.
    • Run quick, high-confidence work alongside longer initiatives so early results do not come at the cost of future growth.
    • Turn unresolved dependencies into discovery milestones. Do not present an initiative as committed delivery until the required team has accepted the work.
    • Report outcome evidence, not just task completion. Shipping is a milestone; it is not proof that SEO performance changed.

    First, separate roadmap commitments from backlog ideas

    A backlog and a roadmap solve different problems. Your backlog stores ideas, defects, requests, maintenance work, and opportunities that may deserve attention. Your roadmap communicates what SEO is expected to deliver, why it matters, who will deliver it, and how success will be judged.

    That distinction matters because an activity can be sensible without being roadmap-ready. Fixing canonical tags, adding schema, updating category pages, and building a programmatic directory can all be valid ideas. Their presence on a list tells you nothing about whether they support the current business goal, can obtain the necessary capacity, or should happen before something else.

    Before an initiative enters the roadmap, make its row answer these questions:

    1. What business outcome does this support? Name the commercial, customer, or risk-reduction result rather than using SEO improvement as the outcome.
    2. What will change? Define the affected templates, page groups, systems, or workflows precisely enough for another team to estimate the work.
    3. Why should it happen in this planning period? State the opportunity, problem, or dependency that makes the timing matter.
    4. What happens if it slips a quarter? Distinguish a genuine cost of delay from a preference to finish sooner.
    5. Who owns execution? Name the accountable team and confirm that it has capacity. A department mentioned in a spreadsheet is not an accepted commitment.
    6. What must happen first? Record technical, editorial, legal, data, design, and approval dependencies.
    7. What kind of impact do you expect? Label it as direct growth, protection of existing performance, or an enabler for later work. Do not force every initiative into a net-new traffic claim.
    8. How will you know whether it worked? Choose a delivery measure and an outcome measure before implementation starts.

    If you cannot answer those questions, keep the item in the backlog. The next action may be research, estimation, stakeholder alignment, or a technical proof rather than full delivery.

    Rewrite tasks as outcome-bearing initiative cards

    A weak roadmap row says rebuild internal linking. A usable initiative card says that the team will improve authority flow toward priority commercial pages through a CMS-supported linking system; SEO owns the analysis, development owns implementation, CMS support is a dependency, and success will be assessed through implementation coverage and subsequent search and business performance across the target page set.

    The wording exposes the real plan. If development has not accepted the dependency, the roadmap should commit to validating the linking design and securing an implementation estimate. It should not promise the completed system.

    Apply the same test to content and structured-data work. Adding schema is a deliverable, not an outcome. Publishing category copy is a deliverable, not an outcome. The roadmap needs to identify what the change is intended to influence and the evidence you will examine afterward.

    Use SCOPE to decide what is ready for the roadmap

    Project tiles move through a five-part inspection mechanism, with complete tiles advancing and incomplete tiles remaining in a holding area.

    SCOPE provides a practical qualification layer between collecting an idea and scheduling it. It evaluates strategic alignment, confidence in delivery, ownership of execution, potential impact, and effort plus elapsed time.

    DimensionQuestion to answerEvidence that makes the initiative roadmap-readyWarning sign
    Strategic alignmentWhich current business goal does this support?A named goal, audience, page group, and intended business effectThe only rationale is that the work is an SEO best practice
    Confidence in deliveryCan the work ship as designed?Known technical path, accepted dependencies, and clear acceptance criteriaThe plan assumes CMS, data, or engineering support that has not been validated
    Ownership of executionWho is accountable, and do they have capacity?A named owner for each material handoff and an agreed delivery windowSeveral teams are listed, but none has accepted responsibility
    Potential impactWhat value could the work create or protect?A defensible impact mechanism, affected scope, and relevant outcome measureHigh impact is asserted without explaining what should move or why
    Effort and elapsed timeWhat will the work consume, and how long will delivery take?An estimate that includes implementation, queues, reviews, QA, and observationOnly hands-on SEO time is counted while cross-team waiting time is ignored

    Score each dimension with a simple scale such as high, medium, or low, but always include a one-sentence rationale. The explanation is more useful than the label. It lets a reviewer challenge an assumption without reopening the entire strategy.

    Treat SCOPE as a set of gates, not a points contest

    Do not let a large potential impact conceal a missing owner or an impossible delivery path. Averaging all five dimensions into one number can make a speculative initiative look deceptively ready.

    Use three decision states instead:

    • Commit: The outcome matters, the delivery route is credible, ownership is accepted, and measurement is defined.
    • Investigate: The opportunity may be valuable, but feasibility, impact, effort, or dependency questions still need answers. Put the investigation itself on the roadmap when resolving that uncertainty is strategically important.
    • Backlog: The work may be useful, but it lacks sufficient alignment, urgency, evidence, or capacity for the current planning period.

    This prevents false precision. A programmatic SEO directory, for example, may have substantial upside while still belonging in the investigate state because engineering capacity, data quality, template design, or quality assurance remains unresolved.

    Sequence quick wins beside long-horizon initiatives

    Prioritization decides what deserves attention. Sequencing decides what starts first, what runs in parallel, and which dependency must clear before another team can act.

    The following delivery windows are illustrative planning examples, not universal benchmarks. Your architecture, review process, release cycle, and team capacity can change them substantially.

    Illustrative initiativePrimary valueIllustrative delivery patternLikely roadmap role
    Correct canonical tags on product pagesProtect or recover existing ranking signalsLow effort; about two weeks in the exampleHigh-confidence quick win
    Add schema to priority commercial pagesSupport search visibility and click-through performanceLow effort; about three weeks in the exampleQuick win with incremental upside
    Consolidate thin category pagesReduce cannibalization and prevent additional problemsMedium effort; about six weeks in the exampleProtective work requiring stakeholder alignment
    Rebuild internal linking architectureImprove authority flow across the siteMedium effort; roughly one quarter for data-led analysis in the exampleLonger, compounding initiative
    Build a programmatic directory from product dataCapture net-new organic demand at scaleHigh effort; about half a year in the exampleLarge bet with engineering and QA dependencies

    A balanced roadmap usually needs three lanes:

    • Ship-now work: Low-effort, high-confidence improvements that can produce evidence while larger projects are still moving through their dependencies.
    • Compounding work: Initiatives such as internal-linking architecture or scalable landing-page systems whose effects arrive later but can influence a much larger part of the site.
    • Risk-reduction work: Technical discovery, prototypes, data validation, stakeholder decisions, and estimates that convert an uncertain opportunity into a deliverable initiative.

    Start the dependency path for the long bet while the quick wins are being delivered. Waiting until every small task is finished creates a gap: early wins become exhausted before the larger work is ready to produce an effect. A plan dominated by short tasks can encounter an outcome wall around the fourth month while initiatives with compounding potential are still waiting to begin.

    Sequence by the critical path, not by the apparent size of the SEO task. If a CMS change needs an architecture review, begin that conversation before completing analysis that depends on the proposed implementation. If a content consolidation needs commercial approval, obtain agreement on the decision criteria before writers revise pages that stakeholders may later insist on keeping.

    Also separate protection from growth. Canonical corrections may recover or preserve existing equity without creating new search demand. A new directory may address demand that the site cannot currently capture. Both can deserve investment, but they should not carry the same outcome claim.

    Plan around the capacity and dependencies you really have

    SEO initiatives do not compete only with one another. They compete with product features, platform maintenance, design work, content commitments, and engineering priorities. A technically sound recommendation can still be a poor roadmap commitment when the delivery team cannot accept it.

    Before assigning a delivery period, complete a dependency handshake with every team whose work is essential:

    • Name the person or team accountable for the handoff.
    • Confirm the earliest realistic point at which the work can enter that team’s queue.
    • Provide the inputs they need to estimate it, including affected templates, business rules, data requirements, and acceptance criteria.
    • Include review, release, rollback, and QA requirements in elapsed time.
    • Record what the SEO team can progress independently while the dependency is pending.
    • Define what changes in the roadmap if the dependency moves.

    If that handshake has not happened, change the commitment. Replace launch a dynamic internal-linking system with validate the CMS approach, complete the specification, and obtain an accepted engineering estimate. This is not weaker planning. It is an accurate description of the outcome the team can control.

    Use stage gates for programmatic SEO

    Programmatic SEO exposes unrealistic roadmaps quickly. Generating useful pages from a database can require data work, page logic, reusable components, editorial standards, engineering, and quality assurance. Scaling before those pieces are proven can produce large numbers of thin pages rather than a useful directory.

    Structure the initiative as a sequence of decisions:

    1. Validate the opportunity. Define the demand, intended user task, page entities, and reason each page deserves to exist.
    2. Audit the data. Identify which fields are complete, reliable, unique, and suitable for public presentation.
    3. Prototype representative pages. Prove the template, content logic, useful components, and internal-linking path before committing to scale.
    4. Set quality acceptance criteria. Specify what makes a page complete and useful, which conditions prevent publication, and how exceptions will be handled.
    5. Confirm production ownership. Assign responsibility for data changes, template defects, QA, and ongoing maintenance after launch.
    6. Authorize scale only after the gates pass. A large inventory is not valuable merely because it can be generated. The roadmap should prioritize rich, differentiated pages and explicitly manage the quality risk of producing thin pages at scale.

    This approach lets you preserve a high-upside idea without disguising uncertainty. Early roadmap periods can contain the work required to earn a scale decision; later delivery remains conditional on what that work reveals.

    Run the roadmap as a measurement and decision system

    A team studies connected initiative blocks on a circular table as signals flow to options for continuing, adjusting, or pausing the work.

    A roadmap becomes another task tracker if its reporting stops at done. Every initiative needs a baseline, a delivery signal, an SEO outcome signal, and a business measure that matches the type of impact being claimed.

    • Canonical correction: Track implementation across the affected template or URL set, then examine canonical selection, indexation behavior, organic landing-page performance, and the business results of affected pages. Frame the expected value as protection or recovery unless the change also creates new eligible pages.
    • Schema implementation: Track valid deployment on the intended commercial pages, eligibility for the relevant search appearance, impressions and click-through behavior where measurable, and downstream qualified visits or conversions. Do not promise an appearance that a search engine controls.
    • Category consolidation: Track redirects, canonicalization, content migration, and internal-link updates, then assess whether competing URLs have been reduced and whether the retained pages are capturing the intended queries and business activity.
    • Internal-linking architecture: Track whether the target page set receives the intended links and paths, then assess crawl and discovery signals, relevant rankings, organic entry traffic, and conversions on priority pages.
    • Programmatic directory: Track template quality, data completeness, published inventory, and QA outcomes, then assess indexation, organic demand captured by the directory, engagement with its useful features, and attributable business results.

    Write the measurement plan before work starts. Record the affected scope and baseline date, the expected direction of change, the evidence needed to continue investing, and the conditions that would trigger revision or cancellation. This reduces the temptation to select a flattering metric after launch.

    Your roadmap review should answer five questions for each active initiative:

    1. What changed since the previous review?
    2. What evidence do we have from delivery, search performance, and business performance?
    3. Which assumption has been confirmed or weakened?
    4. What decision follows from that evidence?
    5. Which dependency or capacity risk could change the next commitment?

    This changes the status conversation. Instead of reporting that schema was added or category pages were updated, you can state whether deployment is complete, whether the expected search behavior is observable, whether business impact can yet be evaluated, and what the team will do next.

    Start with your current backlog. Move only the initiatives with a clear outcome, credible owner, understood dependencies, honest impact claim, feasible delivery path, and measurement plan into the roadmap. Put a quick, high-confidence improvement in motion while beginning the dependency work for a larger bet. Everything else can wait in the backlog or become a defined investigation until it is ready to earn a commitment.

    References

  • Paid Media Profitability: How to Measure Incremental Growth

    Paid Media Profitability: How to Measure Incremental Growth

    Your ad platform reports a 5x return. Your CRM reports 2x. Finance says profit barely moved after the budget increase. Choosing the most flattering number will not resolve the disagreement, because each system is answering a different question.

    You need three separate views: a financial ledger that establishes what the business earned, attribution that helps you navigate campaigns, and incrementality testing that estimates what the advertising actually added. Once those jobs are separated, you can stop rewarding campaigns for claiming revenue and start funding the ones that create profitable demand.

    A 5x platform ROAS and a 2x backend ROAS can both be wrong

    Platform ROAS is attributed revenue divided by ad spend. It is not automatically incremental revenue divided by ad spend, and it is certainly not profit.

    An advertising platform may count view-through, engaged-view, modeled, and long-window conversions. Those methods can recognize influence that a click-only system misses, but the platform also has an incentive to resolve ambiguous journeys in its own favor. Its dashboard is best understood as the platform’s attribution estimate, not an independent financial statement.

    Your backend usually leans the other way. A CRM or ecommerce analytics system often assigns an order to the last observable visit. If an ad introduced the customer and a branded search completed the journey later, the last-click record can give the search or direct visit all the credit. This becomes a structural blind spot for social, display, video, and connected TV campaigns that influence people without generating an immediate click.

    Consider a customer who sees a Meta ad, searches for your brand, clicks a Google ad, and purchases. Meta may claim the order through a view-through window. Google may claim it after the paid click. The backend may assign it to Google because that was the last recorded touch. You made one sale, but the systems produced three different explanations. Adding the platform-reported revenue together can therefore count the same sale more than once.

    Do not average those numbers. Averaging incompatible attribution rules produces another attribution number, not a better estimate of causality. Ask four distinct questions instead:

    • How much net revenue and contribution did the business record?
    • Which observable touches appeared along converting journeys?
    • Which campaigns give an ad platform useful signals for day-to-day optimization?
    • How much of the outcome would disappear if the advertising were withheld?

    The fourth question is incrementality. Its target is the counterfactual: what the same eligible market would have done without the media. No attribution model can observe that alternative history directly. You have to estimate it with a credible control group.

    Build a profit ledger before changing bids

    An open ledger uses coins and expense trays to show revenue being reduced by costs before reaching a bid-control dial.

    Incrementality tells you whether advertising changed behavior. Profitability tells you whether the change was worth buying. You cannot answer either question cleanly while campaign identifiers, customer outcomes, and commercial costs live in disconnected systems.

    For ecommerce, move from gross sales to contribution

    Start with a deduplicated order ledger. Keep one durable order identifier and record the campaign information available at acquisition, the order date, customer status, gross sales, discounts, cancellations, refunds, and the variable costs required to fulfill the order. Those costs may include product cost, payment charges, shipping subsidies, and other expenses that increase when another order is placed.

    A practical decision metric is:

    Contribution after media = net revenue – variable product and fulfillment costs – media spend.

    If product mix varies substantially by campaign, calculate contribution at the order or product level rather than multiplying all attributed revenue by one blended margin. A campaign that sells a low-margin product can show the same revenue ROAS as one that sells a high-margin product while producing far less cash for the business.

    Lifetime value can improve the picture when repeat purchases matter, but only when it is grounded in observed retention, recurring revenue, and upsell behavior. Connecting initial revenue, recurring revenue, retention, and later purchases gives you a fuller economic view than first-order revenue alone. Compare mature customer cohorts on the same follow-up window, and keep projected value separate from revenue already realized. Otherwise a generous lifetime-value assumption can turn an unprofitable campaign into a profitable one on paper.

    For lead generation, value the stages that predict a sale

    A form completion is not the commercial outcome. Build the measurable path from initial lead to marketing-qualified lead, sales-qualified lead, sale, and retained customer where retention is material. Report the conversion rate and cost at every stage. A source with an expensive initial lead can still win if those leads qualify and close at a much higher rate.

    When final sales are too infrequent or the sales cycle is too long for useful bidding signals, assign intermediate values from recent downstream performance. If an average sale produces $1,000 in revenue and 10% of sales-qualified leads close, the expected revenue value of a sales-qualified lead is $100. That is a revenue proxy, not a profit value. For profitability decisions, repeat the calculation with expected contribution per sale after the variable costs of delivering it.

    Recalculate stage values when close rates, prices, margins, or lead definitions change. A value-based bidding system will faithfully optimize toward stale values if stale values are what you send it.

    The plumbing matters here. Preserve consistent UTMs and any identifiers needed to connect an ad interaction, website session, CRM record, qualification event, and eventual sale. Verify that those values survive redirects and form submissions, and do not overwrite the original acquisition fields every time a lead returns. Where supported and appropriate for your data practices, Enhanced Conversions for Leads and platform conversion APIs can return deeper funnel outcomes to advertising systems.

    Before trusting the ledger, check for duplicate orders, duplicated leads, inconsistent currencies and time zones, missing returns, failed payments, reopened opportunities, and stage changes that were applied retroactively. Incrementality testing cannot repair an outcome table that counts the underlying business events incorrectly.

    Use attribution for navigation and incrementality for proof

    Attribution is useful. The mistake is asking it to prove something it was not designed to prove. Give each measurement layer a specific job and stop forcing one number to serve every decision.

    Measurement layerQuestion it answersBest useMain limitation
    Financial ledgerWhat did the business record?Deduplicated revenue, contribution, cash, and customer outcomesDoes not reveal what caused an outcome
    Backend attributionWhich recorded touch received credit?Journey analysis, reconciliation, and directional reportingOften misses impressions and earlier touches
    Platform attributionWhich outcomes can this platform associate with its ads?Campaign diagnostics and bidding feedbackCan claim shared conversions and modeled influence
    Incrementality testWhat changed because eligible people were exposed to the advertising?Budget allocation, causal validation, and calibrationApplies to the tested scope, spend level, audience, and period

    Use the backend ledger as the boundary for total business results, not as an infallible channel judge. It can tell you that the business recorded one order even when two platforms claim it. It cannot necessarily identify the ad that created the customer’s initial interest, especially when there was no click to connect.

    Use platform attribution to compare creatives, audiences, queries, placements, and campaign settings within a platform, provided the measurement configuration is consistent. Treat a sudden platform ROAS change as a signal to investigate, not immediate proof that underlying profit changed.

    Do not add Google, Meta, TikTok, Microsoft, and other platform-reported conversions to produce a company total. The platforms do not have a shared mechanism that automatically divides one sale among all claimants. Reconcile company totals in the ledger, then use controlled tests to estimate how much each material investment adds.

    This division of labor also prevents a common channel mistake. Click-oriented channels tend to sit closer to a recorded purchase, while impression-led channels can affect later branded searches or direct visits. Judging all of them by last-click backend revenue rewards visibility to the measurement system, not necessarily value to the business.

    Run an incrementality test that can survive scrutiny

    Two matched miniature market regions form an advertising test and holdout group, with purchase tokens collected separately to reveal a small difference.

    A useful test begins with a budget decision, not a request to prove that marketing works. Narrow the scope until the result can change a real action: whether to continue prospecting in an audience, whether branded search is adding enough value, whether a retargeting layer deserves its budget, or whether an impression-led channel is producing demand the backend cannot see.

    1. Write the decision and hypothesis first. State which spend could increase, decrease, or move if the measured lift is strong, weak, or inconclusive.
    2. Define the eligible population before assignment. The population should match the people, accounts, or regions to which you intend to apply the decision.
    3. Choose the assignment unit. Randomize individual users or accounts when exposure and suppression can be enforced reliably. Use geographic units when person-level assignment is unavailable. Use simple before-and-after comparisons only as a last resort because time introduces seasonality, trend, promotion, and competitive effects.
    4. Create a treatment and a credible control. The treatment receives the media being evaluated; the control is withheld from it. Suppress the control across overlapping campaigns where possible, or document the remaining exposure as contamination.
    5. Select one primary business outcome from the same backend system for both groups. For ecommerce, that may be net revenue or contribution. For B2B, it may be closed sales; a qualified stage can serve as a nearer-term proxy when the sale lag is too long, but label it as a proxy.
    6. Fix the analysis rules before inspecting the result. Record the test period, attribution-independent outcome window, exclusions, treatment definition, primary metric, guardrails, and statistical method. Determine the required sample and duration from the expected baseline, decision threshold, and power analysis rather than choosing a universal rule of thumb.
    7. Keep participants in their assigned groups for the main analysis. Moving converters, noncompliers, or unexposed treatment members after assignment breaks the comparability created by randomization.
    8. Estimate lift, economic value, and uncertainty. A point estimate alone does not tell you whether an apparent gain is distinguishable from ordinary variation.

    For a simple individually randomized test, calculate the control outcome rate and apply it to the treatment population to estimate what treatment would have produced without the ads. The difference between the observed treatment outcome and that counterfactual estimate is incremental lift.

    Then translate lift into the measures the budget owner needs:

    • Incremental conversions = observed treatment conversions – expected treatment conversions at the control rate.
    • Incremental net revenue = observed treatment net revenue – expected treatment net revenue without the tested media.
    • Incremental revenue ROAS = incremental net revenue / incremental media spend.
    • Incremental contribution ROAS = incremental contribution before media / incremental media spend.
    • Incremental profit after media = incremental contribution before media – incremental media spend.

    Use incremental spend, meaning the spend difference between treatment and control. This matters when the control receives a reduced media level instead of no media at all. It also lets you test the marginal value of an additional budget layer rather than comparing maximum spend with complete silence.

    A geographic test needs extra care. Match or balance regions using pre-test business outcomes, keep major pricing and promotional changes aligned where possible, and analyze the geographic units as the units of assignment. A large number of transactions inside a small number of regions does not magically create a large number of independent experimental units. Watch for spillover as well: people can travel, share offers, or encounter media outside their assigned region.

    Catch the failure modes before the test starts

    • The control group can still receive the tested campaign through another audience, account, or platform.
    • The treatment and control use different checkout, CRM, qualification, or sales processes.
    • A promotion, price change, inventory problem, or sales-team change affects one group differently.
    • The campaign expands or contracts eligibility after assignment, changing who can enter each group.
    • The outcome window closes before delayed purchases or sales opportunities mature.
    • The team uses platform-attributed conversions as the primary outcome, allowing the measurement system being tested to define its own success.
    • Results are checked repeatedly and the test is stopped as soon as a favorable fluctuation appears.
    • Cross-channel budgets change during the test in a way that substitutes for the media being withheld.

    If the estimate is too uncertain to distinguish a commercially useful lift from no lift, call the test inconclusive. That is not the same result as evidence of zero incrementality. Extend or redesign the test if the decision is valuable enough, or make a smaller reversible budget change while you gather stronger evidence.

    Turn lift and profit into budget decisions

    Set your definitions of strong and weak before looking at the quadrant below. The thresholds should come from your contribution margin, cash constraints, growth target, and acceptable uncertainty. There is no universal ROAS that makes every business profitable.

    Attributed performanceIncremental resultWhat it usually meansNext decision
    StrongStrong and profitableThe campaign both receives observable credit and creates additional valueScale in controlled steps and measure marginal returns
    StrongWeak with a precise estimateThe campaign may be harvesting demand that would have converted anywayReduce, narrow, or redesign it; test branded and retargeting layers separately
    WeakStrong and profitableClick-based attribution is probably missing part of the campaign’s influenceProtect the budget, improve journey measurement, and use lift for calibration
    WeakWeak with a precise estimateNeither attribution nor the experiment supports the investmentVerify tracking, then pause or rebuild the campaign
    Any resultInconclusiveThe test cannot resolve the decision at the required levelDo not describe it as success or failure; improve power, design, or scope

    Do not assume the average incremental return at the current budget will survive a large increase. The next portion of spend may reach less responsive people, buy more expensive inventory, or increase frequency without adding enough new customers. Scale gradually and compare adjacent spend levels so that budget decisions reflect marginal value, not only the historical average.

    Within campaigns, keep CTR, CPC, conversion rate, and initial CPA in their proper place. They are diagnostic measures. A very high CTR can come from unqualified traffic, bots, or accidental mobile clicks. A higher CPC can buy access to a query with stronger purchase intent. A low form-fill CPA can produce poor economics when those leads fail to qualify or close.

    Optimize toward the deepest reliable outcome your volume and sales cycle support. If final sales provide enough timely signal, use them. If they do not, send meaningful intermediate stages with values based on current progression rates. Monitor cost per qualified lead, cost per sale, sale conversion rate, net revenue, and contribution alongside the platform’s operational metrics. This keeps the bidding system informed without pretending every form submission is equally valuable.

    Your report should follow the same hierarchy. Put the business decision, incremental estimate, contribution result, and uncertainty first. Follow with deduplicated revenue and the qualified funnel. Put CTR and CPC lower down as explanations of delivery, not headlines. When a diagnostic moves sharply, provide context: rising CPC can be acceptable when downstream sale conversion and profit remain healthy. Reports that prioritize qualified-lead cost and conversion to final sale keep the discussion attached to commercial outcomes.

    Key takeaways

    • Platform ROAS, backend ROAS, and incremental ROAS answer different questions; do not average them or use the terms interchangeably.
    • Reconcile total revenue and contribution in a deduplicated business ledger, but do not mistake last-click attribution for causal truth.
    • Measure lead quality through qualification and sale stages instead of optimizing only for the cheapest initial conversion.
    • Estimate incrementality with a predefined treatment and control, a shared backend outcome, preserved assignment, and an explicit measure of uncertainty.
    • Translate incremental lift into contribution after media. Revenue lift can still be unprofitable when margins and variable costs are ignored.
    • Use experiments to calibrate attribution and allocate budgets, while using platform metrics for faster campaign-level navigation.
    • Scale according to marginal incremental profit. A profitable average at one spend level does not guarantee that the next budget increase will perform the same way.

    Start with one material decision rather than trying to perfect attribution across the entire account. Choose a campaign whose budget could genuinely change, reconcile its downstream economics, define a control the campaign cannot reach, and write the success rule before launch. That test will teach you more about profitable growth than another round of reconciling incompatible ROAS dashboards.

    References


  • How to Test ChatGPT Ads Bidding and Platform Targeting

    How to Test ChatGPT Ads Bidding and Platform Targeting

    You are deciding whether to turn on Maximize results, separate iOS, Android and Web traffic, or trust a larger conversion total. Those look like three independent choices. They are actually one measurement problem: automated bidding can only optimize the goal and conversion signals you give it.

    The safest rollout is deliberate. Use platform controls to isolate meaningful behavior differences, automate bids only after the outcome is trustworthy, and keep view-through attribution separate from evidence of incremental growth.

    Platform targeting controls surfaces, not audiences

    A single crowd connects through separate illuminated routes to smartphone, mobile device, and desktop surfaces.

    The Eligible platforms setting lets you choose one or more of the iOS app, Android app and Web when creating a campaign. This answers where an eligible ad can appear. It does not tell the system which customer is valuable, make the conversion event more reliable or replace your campaign goal.

    That distinction matters because platform selection can look more precise than it is. Excluding Android, for example, is not an audience strategy. It is a distribution decision that removes Android opportunities from that campaign. You need evidence that the surface itself changes the economics or user journey before you make that trade.

    What you knowPractical campaign structureMain risk
    You have no reliable evidence that iOS, Android and Web perform differentlyKeep the eligible surfaces together and report them separately where possibleAggregated results can conceal a weak surface
    A surface has a repeatable difference in conversion quality, customer value or user behaviorCreate a separate campaign for that surface so its eligibility and budget decisions can be managed independentlyEach campaign receives a smaller pool of conversion signals
    Conversion tracking is inconsistent between an app and the WebRepair and validate the measurement path before using reported performance to exclude or scale either surfaceAutomated bidding may optimize toward a tracking difference rather than a business difference

    Do not split campaigns because one platform has a lower click-through rate. First compare the result that matters after the click or view: accepted leads, completed purchases, retained customers or another outcome your business can verify. A surface can attract fewer clicks yet produce better customers. It can also produce cheap conversions that your sales or fulfillment systems later reject.

    Before separating platforms, write down the hypothesis in a falsifiable form. For example: Web traffic produces a higher rate of accepted applications than app traffic when both use the same qualification rules. Then confirm that the conversion event, attribution treatment and downstream acceptance rule are comparable. If you cannot make that comparison cleanly, segmentation will create more campaign controls without creating more knowledge.

    Maximize results needs a business constraint outside the algorithm

    Maximize results automatically sets and adjusts bids toward the campaign’s selected goal, with the aim of generating as many results as possible from the available budget. That is a volume objective. It should not be read as a promise to maximize profit, customer lifetime value or qualified pipeline.

    The selected conversion therefore becomes an operating instruction. If you optimize for a shallow event because it happens frequently, the system can become efficient at producing that shallow event. The campaign dashboard may improve while the commercial outcome stays flat.

    Write a short optimization contract before enabling automation:

    • Primary result: Name the exact event the campaign will optimize. Avoid labels such as qualified conversion unless the qualification rule is explicit.
    • Business acceptance rule: Define what makes the result useful after it enters your CRM, commerce system or other system of record.
    • Quality metric: Choose the downstream rate or value you will inspect alongside campaign conversion volume.
    • Budget boundary: Decide how much spend you are willing to treat as test exposure before the business outcome is validated.
    • Scale rule: State what must improve before you increase the allocation. A higher platform-attributed conversion count is not sufficient by itself.
    • Stop rule: Identify the signal that will pause the test, such as deteriorating accepted-result cost or a measurement failure.

    Because automated bidding spends real money, start with a deliberately limited test allocation. Do not use an amount that would create a material problem if the selected event turns out to be a poor proxy for revenue or qualified demand.

    Change one major variable at a time. Expanding platform eligibility and enabling Maximize results in the same test makes a positive result ambiguous: you will not know whether the improvement came from new inventory, different bids or a changed conversion mix. Test the platform structure while holding the bidding approach steady, then test the bid strategy while preserving the chosen platform mix. Keep the goal, creative, offer, landing experience and conversion implementation as stable as the campaign permits.

    Evaluate the test over a period that covers your normal conversion delay and business cycle. There is no universal number of days that makes a low-volume campaign conclusive. If the campaign produces too little verified outcome data to distinguish improvement from ordinary variation, keep the decision provisional rather than inventing certainty from percentages.

    View-through conversions change the report, not necessarily demand

    ChatGPT Ads Manager reports one-day view-through conversions at the campaign, ad group and ad levels. A view-through conversion is attributed when a person converts within one day of seeing an eligible ad and no qualifying ad click receives credit for that conversion.

    A view-through conversion is not automatically invalid. It answers a different question from a click-through conversion. It shows that an ad exposure preceded the conversion within the defined window. It does not, by itself, establish that the ad caused a conversion that otherwise would not have happened.

    Keep three measurement questions separate

    • Did the person click before converting? Use click-through conversion reporting to understand the measurable engagement path.
    • Did an eligible ad view precede the conversion? Use the one-day view-through metric to understand attributed exposure without a credited click.
    • Did advertising create additional business? Use a controlled incrementality method where the decision warrants it. Attribution reporting alone cannot answer this causal question.

    The addition of view-through reporting means more conversions can be attributed beyond conversions generated directly from clicks. Annotate the point at which this reporting became visible in your account. Otherwise, a pre-and-post chart may look like campaign performance improved when only the attribution coverage changed.

    Build a compact scorecard with four lines:

    • Click-through conversions and their cost.
    • One-day view-through conversions and their share of all ChatGPT-attributed conversions.
    • Verified business outcomes from your system of record and their cost.
    • The acceptance rate or realized value of the results attributed to the campaign.

    The view-through share is a diagnostic, not a quality score. Calculate it by dividing view-through conversions by all ChatGPT Ads-attributed conversions for the same scope and period. If that share rises sharply, investigate the composition before declaring better performance. Ask whether the eligible platform mix, ad exposure, reporting availability or customer behavior changed.

    Use conversion integrations to improve signals, not inflate counts

    Advertisers can connect WorkMagic to view ChatGPT campaign performance with other channels and send conversion signals to OpenAI through the Conversions API. That can make downstream outcomes more useful to campaign measurement, but connecting systems does not validate the data automatically.

    Document each event name, timestamp, originating system, business definition and rejection rule. Confirm how the same real-world outcome is handled if it can arrive through more than one measurement route. A cross-channel dashboard is useful for reconciliation, but it does not turn overlapping attribution claims into incremental customers.

    Use a staged rollout that preserves a readable baseline

    Four separated testing chambers show a baseline, added device traffic, constrained automation, and distinct conversion signals.

    A clean rollout gives each new control one job. Use this sequence:

    1. Record the baseline. Save the current bid approach, eligible surfaces, goal, conversion definitions, spend and downstream outcome metrics. Include a representative period that covers your usual conversion lag.
    2. Validate the goal event. Trace reported conversions into the system of record. Check that the event fires at the intended moment and maps to the business result named in your optimization contract.
    3. Form a platform hypothesis. Decide whether iOS, Android or Web should differ based on repeatable outcome quality or customer value, not a single top-of-funnel metric.
    4. Test platform eligibility first. Hold the bid strategy and other major inputs steady while you learn whether a surface warrants separate management.
    5. Test Maximize results second. Preserve the selected platform structure so you can judge the automated bidding change against a readable reference.
    6. Separate attribution types. Review click-through and one-day view-through conversions independently, then reconcile both with verified business outcomes.
    7. Scale on commercial evidence. Increase the allocation only when volume and downstream quality support the decision. If they disagree, repair the goal or signal before giving the system more budget.

    ChatGPT Ads is also expanding into Brazil and Mexico. If either market is part of your plan, treat geographic expansion as another major variable. Launching a new market while changing platforms and bidding creates several plausible explanations for any movement in performance. Keep the market, offer, language, conversion path and bid test documented separately so you know what you are scaling.

    Keep paid ChatGPT performance separate from organic AI visibility as well. Ad-attributed conversions tell you about the paid campaign under its attribution rules. They do not measure whether your brand is cited, recommended or discovered organically in AI-generated answers. Use distinct reporting for those two jobs.

    Key takeaways

    • Platform targeting determines whether a campaign can run on iOS, Android, Web or a combination; it is not a substitute for audience or conversion strategy.
    • Separate platforms only when repeatable differences in business outcomes justify smaller data pools and additional campaign management.
    • Maximize results seeks more results from the available budget, so the quality of the selected goal determines what the automation learns to pursue.
    • Test platform eligibility and bidding changes separately. Changing both at once makes the outcome difficult to interpret.
    • Report one-day view-through conversions separately from click-through conversions, and do not label attributed exposure as incremental lift.
    • Scale only when campaign metrics agree with accepted leads, revenue or another verified outcome in your system of record.

    Your next move should be a measurement decision, not a settings decision. Name one verified business result, confirm how it reaches ChatGPT Ads, and choose the eligible platform structure that gives you a clean test. Only then should Maximize results receive more budget to optimize.

    References


  • How to Optimize for Claude and Claude Code as Answer Engines

    How to Optimize for Claude and Claude Code as Answer Engines

    If your brand performs well in Claude, do not assume Claude Code will carry that visibility into a developer’s workflow. The shared Claude name is a product-family label, not a reliable unit of measurement for answer-engine optimization.

    You need to answer two separate questions: can Claude explain or recommend your brand in a conversational response, and can Claude Code find useful information about it while helping someone complete technical work? That distinction changes your prompt research, content priorities, structured data, and reporting.

    Why one Claude visibility score can hide the real problem

    Across 24,135 observed responses and related agent traffic, Claude and Claude Code searched at different rates, mentioned different brands, and visited different kinds of webpages. That is enough divergence to treat them as separate answer-engine surfaces rather than two interfaces feeding one interchangeable visibility score.

    The finding is observational. It does not prove that every prompt will produce different behavior, that one type of page always wins, or that a particular optimization guarantees inclusion. It does show why an aggregate Claude metric can mislead you: improvement on one surface can conceal a decline or persistent gap on the other.

    Separate three layers when you evaluate performance:

    • Retrieval behavior: Did the surface search or otherwise fetch current web information during the run?
    • Answer selection: Which brands, products, libraries, or approaches appeared in the response?
    • Page use: Which pages were linked, cited, or visited, and what job did those pages perform?

    A brand mention is not automatically a citation. A citation is not automatically an agent visit. A visit is not automatically a successful recommendation. Preserve those distinctions in your data instead of compressing them into a single percentage.

    Key takeaways

    • Track Claude and Claude Code as separate answer engines, even when they address related demand.
    • Pair prompts by underlying intent rather than copying the same wording into both surfaces.
    • Give Claude clear decision and explanation pages; give Claude Code implementation-ready technical material.
    • Measure searches, mentions, citations, visits, and page types separately so you know which failure you are fixing.
    • Use JSON-LD to clarify entities and page meaning, but do not treat schema as a proven ranking switch for either surface.

    Separate conversational demand from implementation demand

    A researcher explores conversational recommendations while a developer uses an AI assistant to connect documentation and software components.

    Start with the task behind the prompt. Claude often meets a person at an explanation, evaluation, or planning stage. Claude Code meets that person inside a technical workflow. The topics may overlap, but the information needed to complete the task is different.

    Do not create two unrelated keyword lists. Build paired prompt clusters around the same underlying demand:

    Underlying needClaude prompt angleClaude Code prompt angleContent required
    Understand a categoryWhat the category does, who needs it, and where it fitsHow the category maps to a stack, workflow, or architectureCategory explainer linked to technical documentation
    Choose an approachSelection criteria, tradeoffs, alternatives, and fitCompatibility, dependencies, constraints, and implementation costDecision page plus compatibility and integration pages
    Adopt a productCapabilities, intended audience, limitations, and evidenceInstallation, authentication, configuration, and a working exampleCanonical product page plus task-specific setup documentation
    Fix a problemLikely causes and a diagnostic pathError-specific checks, commands, configuration changes, and expected outputTroubleshooting pages with stable headings and explicit error states
    Compare optionsMeaningful differences and situations where each option fitsVersion support, migration implications, API differences, and operational constraintsEvidence-based comparison connected to migration and reference material

    For example, a conversational template might ask: Which [category] fits a [type of team] that needs [outcome], and what are the tradeoffs? Its Claude Code counterpart might ask: I need to add [capability] to [stack] under [constraint]. Which [tool or library] fits, and how should it be configured?

    Those prompts express related demand without pretending the two environments are identical. Keep the audience, desired outcome, and major constraint aligned across each pair. That gives you a defensible comparison when one surface mentions your brand and the other does not.

    Build content that can finish each kind of task

    You do not need doorway pages that merely insert Claude or Claude Code into a heading. You need pages that resolve the jobs represented by your paired prompts. The strongest content architecture connects decision material to implementation material so an answer engine can move from what your product is to how someone uses it.

    For Claude, make the decision legible

    A conversational answer needs a concise, extractable explanation before it needs a long brand narrative. Put the core answer near the top of the relevant page, then support it with the criteria a person would use to make a decision.

    • State what the product, service, or concept is in direct language.
    • Name the intended user and the problem it addresses.
    • Explain where it fits and where it does not fit.
    • Describe material tradeoffs instead of declaring the option best for everyone.
    • Connect important claims to visible evidence on the page.
    • Keep product names, company names, and category language consistent across canonical pages.
    • Show when time-sensitive material was last reviewed or changed.

    If a page makes readers scroll through positioning language before revealing what the product does, the problem is not merely tone. The page has failed to expose a usable answer unit. Rewrite the opening so the entity, audience, function, and differentiator can be understood without reconstructing them from several sections.

    For Claude Code, make the implementation executable

    Technical content must survive contact with a real implementation. A conceptual feature description is not a substitute for the details needed to install, configure, test, or debug something.

    • Declare prerequisites and version scope beside the instructions they qualify.
    • Provide a minimal working example before presenting advanced variations.
    • Show package names, imports, configuration keys, and required environment inputs exactly.
    • Explain authentication without exposing real secrets or encouraging unsafe credential handling.
    • Show the expected result so the user can tell whether the step worked.
    • Document common failure states with the relevant error text, likely cause, and corrective action.
    • Link conceptual product claims to the canonical API, integration, migration, and troubleshooting pages that substantiate them.
    • Remove or clearly label obsolete instructions instead of leaving contradictory versions discoverable.

    A snippet should agree with the prose around it. If the command uses one package name while the explanation names another, or the example requires an unstated dependency, the page is not implementation-ready. Test documentation as a sequence: prerequisites, setup, execution, expected output, failure recovery, and next step.

    Use JSON-LD as a shared entity layer

    Structured data can make the relationship among your organization, software, documentation, authorship, and canonical URLs clearer. It should describe what a visitor can verify on the page; it should not introduce unsupported versions, reviews, features, or relationships that are absent from the visible content.

    • Use Organization markup for the organization entity and connect only genuine official profiles through sameAs.
    • Use SoftwareApplication when the page actually describes a software application, including applicable details such as application category, operating system, or software version when those facts are visible.
    • Use TechArticle for genuine technical documentation and keep its headline, author, modification date, and canonical relationship consistent with the page.
    • Use BreadcrumbList to represent the visible documentation hierarchy when breadcrumbs are present.
    • Give the same entity a stable name and canonical URL across relevant markup instead of generating isolated identities on every page.

    Validate the markup, but keep your claim modest: valid schema removes ambiguity; it does not prove that Claude or Claude Code will retrieve, cite, or rank the page. If visibility changes after several content and schema edits, do not assign causation to JSON-LD without a test that isolates it.

    Measure each surface with a repeatable visibility test

    Two parallel testing chambers process identical blank prompt tiles and produce conversational and technical outputs.

    A useful test must tell you what happened, where it happened, and which content could have influenced the result. Screenshots of favorable answers are evidence of individual runs, not a measurement system.

    Set up the test

    1. Define the entities. Record the official organization, product, feature, package, and category names you expect to recognize in an answer.
    2. Create paired prompt clusters. Cover explanation, selection, implementation, troubleshooting, comparison, and branded validation where those tasks apply to your business.
    3. Label every run by surface. Claude and Claude Code must occupy separate fields, views, and trend lines.
    4. Freeze the important variables. Save the exact prompt, date, account or workspace context that may matter, and any visible search or tool state. Do not quietly rewrite a prompt and treat it as the same test.
    5. Repeat on a fixed cadence. Generative responses can vary, so compare repeated runs rather than promoting one favorable output into a benchmark.
    6. Capture the whole response. Record brands mentioned, links shown, claims made, apparent search activity, and the position and context of each mention.
    7. Classify destination pages. Use a stable taxonomy such as homepage, product page, comparison, editorial content, documentation, API reference, repository, community page, or troubleshooting page.
    8. Corroborate with traffic data where possible. If agent traffic can be identified reliably in your logs or analytics, connect it to the page and time window. Do not relabel ordinary direct traffic as Claude traffic without evidence.

    Keep the metrics interpretable

    • Search activation rate: runs with visible search or retrieval activity divided by all comparable runs.
    • Brand mention rate: runs naming the target brand divided by all comparable runs.
    • Linked citation rate: runs linking to a brand-owned page divided by all comparable runs.
    • Third-party citation rate: runs that substantiate a brand mention through an independent page divided by all comparable runs.
    • Owned-page visit rate: identifiable agent visits to owned pages divided by the relevant tracked runs, when that connection can be made responsibly.
    • Page-type distribution: the share of observed citations or visits going to each page class.
    • Task coverage: prompt intents for which the brand receives an accurate, useful mention divided by the tested prompt intents.
    • Cross-surface overlap: brands appearing on both surfaces compared with all brands appearing on either surface.

    Do not average these into an opaque score before examining them separately. A brand can have a high mention rate and a low citation rate. Claude Code can visit documentation while Claude cites a category explainer. Those are different states requiring different work.

    Turn patterns into a diagnosis queue

    Observed patternReasonable hypothesis to investigateNext action
    Strong in Claude, weak in Claude CodeThe brand is understandable at the category level but lacks accessible implementation evidence, or the coding surface forms a different candidate set.Audit setup, compatibility, API, migration, and troubleshooting pages against the failed Claude Code prompts.
    Strong in Claude Code, weak in ClaudeThe technical material is useful, but the category, audience, or decision context is unclear.Create or improve an answer-first product or category page and connect it directly to the technical documentation.
    Mentioned without a linkThe brand is known in the response context, but the run does not demonstrate referral to a current page.Track it as a mention, not a citation or visit, and strengthen canonical pages that verify the claims being made.
    Search occurs, but competitors receive the citationsCompeting pages may match the task or provide more readily usable evidence.Compare page intent, claim clarity, technical completeness, and destination type; fill the specific information gap rather than copying wording.
    Documentation is visited, but the brand is not recommendedThe page may resolve a narrow technical step without establishing product fit.Improve links and language connecting the documented task to the relevant capability and canonical product entity.
    No visible search occursThe surface may be answering from existing context, so current-page retrieval cannot be confirmed for that run.Report zero-search runs separately and test natural variations of the same intent before diagnosing a page-level retrieval failure.

    Each row is a hypothesis, not a verdict. Check the actual response, destination page, and traffic evidence before deciding what caused the pattern. This keeps you from rebuilding documentation to solve a category-positioning problem, or rewriting a commercial page when the missing asset is a version-specific integration guide.

    Begin with the small set of tasks closest to adoption or implementation. Establish separate baselines for Claude and Claude Code, fix the clearest page-type gap, and rerun the same paired prompts. Once you can name the surface, task, metric, and page that changed, you have an answer-engine optimization program instead of a collection of Claude screenshots.

    References


  • How to Design an AI-Assisted Content Workflow That Holds Up

    How to Design an AI-Assisted Content Workflow That Holds Up

    You probably do not need a better writing prompt. You need a production system that knows what can be published, which evidence it may use, and when a human must stop the run.

    If your current workflow produces fluent drafts followed by unpredictable rewrites, the model is not necessarily the bottleneck. The missing layer is usually an explicit definition of done. Build that first, then require every stage to prove that its output is ready for the next one.

    Begin with a publishable-content contract

    Start at the end. Work backward from the finished result and describe what an editor must see before approving it. This turns quality from a subjective reaction into a set of decisions your workflow can enforce.

    A publishable-content contract should cover at least six dimensions:

    • Reader value: The page resolves a defined question, problem, worry, or decision for a named audience. It does not merely cover a keyword.
    • Original contribution: The draft contains an insight, example, methodology, case study, internal finding, or point of view that is not interchangeable with every other result.
    • Factual integrity: Every material claim can be traced to approved evidence. Uncertainty is visible, and missing support stops publication.
    • Brand and product accuracy: Descriptions of your company, services, products, and methods match an approved source of truth.
    • Editorial fit: The language follows demonstrated voice patterns, structural rules, and publication standards.
    • Search and answer readiness: The page answers the central question early, uses descriptive headings, supports claims with nearby citations, and includes appropriate metadata and internal links.

    Write each requirement so that an editor can pass or return it. Useful criteria describe observable evidence: the opening answers the primary question; every number has a supporting link; the product description matches the approved product document; the page does not duplicate the intent of an existing URL. Vague criteria such as compelling, natural, authoritative, or optimized cannot control a workflow because two reviewers can interpret them differently.

    Your contract should also separate outputs from outcomes. A correct meta description is an output. A ranking is an outcome. A clearly supported answer passage is an output. Being cited by an AI system is an outcome. Your workflow can require the former and improve the potential for the latter, but it cannot guarantee rankings, traffic, or citations.

    Voice needs the same treatment. A list of adjectives is not enough. Instead of telling the model to sound friendly and expert, provide approved examples, counterexamples, and editing rules. Specify how quickly the writing reaches the answer, how technical terms are introduced, which claims require qualification, and which verbal habits should be removed. Examples of what to imitate and what to avoid give the system something concrete to compare.

    Separate permanent context from run-specific inputs

    An AI workflow becomes unreliable when every run begins with a different pile of documents. Divide your inputs into two groups: stable context that governs all work and a job packet that defines the current assignment.

    Permanent context

    Keep these assets under version control or in another clearly governed location. Give each one an owner and a review process so the workflow does not keep repeating outdated claims.

    • Brand explainer: Who you are, who you serve, the problems you address, and the boundaries of what you offer. For B2B content, include the relevant industries, roles, seniority levels, and pain points.
    • Voice guide: Approved passages, before-and-after edits, prohibited patterns, formatting preferences, and examples of language that sounds wrong for the brand.
    • Gold-standard work: Strong briefs, outlines, and published pages that demonstrate the expected depth and structure.
    • Product and methodology records: Approved descriptions, capabilities, limitations, terminology, and positioning. Sales collateral may help, but editorially sensitive claims still need verification.
    • Content inventory: Live URLs, titles, target topics, and summaries. A sitemap or crawl export can support internal-link suggestions and duplication checks.
    • Proprietary evidence: Internal research, case studies, approved customer evidence, and subject-matter expertise that can make the output distinct.
    • Publication rules: Requirements for citations, answer-forward passages, headings, paragraph structure, keyword use, metadata, URL slugs, internal links, and pre-publication review.

    Do not treat this library as one enormous prompt. The orchestrator should supply each stage with the context it needs. A research stage may need the audience definition and content inventory. A drafting stage needs the approved brief, evidence packet, voice examples, and product record. A metadata stage does not need every sales document your company has produced.

    Run-specific job packet

    Require the person starting a run to complete a small set of fields. If a field is essential and ambiguous, block the run instead of inviting the model to guess.

    • Content type and intended publication destination
    • Primary reader and the decision or task the page should support
    • Primary question, topic, or keyword
    • Angle, thesis, or intended distinction from existing content
    • Concepts that must be covered without forcing exact-match phrasing
    • Product, service, or methodology to mention, if any
    • Required internal evidence, examples, links, or subject-matter input
    • Constraints, reviewer, and final approver

    The angle deserves special attention. A keyword tells the system what territory to enter; it does not tell the system what useful contribution to make. If the angle is not known at kickoff, research should propose and test one before an outline is approved.

    Build a gated pipeline, not a chain of prompts

    An isometric five-stage pipeline moves source materials through drafting and verification chambers, with gates and revision trays between each stage.

    A sequence of prompts can produce text. A workflow produces controlled state changes. Each stage should have a defined input, task, output format, acceptance test, and failure route. An orchestrator should describe the full order of operations and the responsibility of every agent, then be updated whenever those responsibilities change.

    1. Kickoff: Validate the job packet. Confirm that the reader, question, content type, and angle are sufficiently specific. Return incomplete requests before they consume research or editing time.
    2. Research: Build an evidence packet, not a loose collection of links. Record the claim each reference can support, relevant qualifications, and any gaps that prevent the proposed angle from working. Review current site content so the new page has a distinct job.
    3. Brief: Define the search intent, reader outcome, central answer, differentiating contribution, required claims, evidence boundaries, internal-link opportunities, and optimization requirements. A researcher should be able to explain why the proposed page deserves to exist.
    4. Outline: Give every section one job. Put the answer before extended context, eliminate headings that merely restate the topic, and identify where evidence, examples, or proprietary material must appear.
    5. Draft: Write only from the approved brief and evidence packet. Preserve qualifications from the evidence. Mark unresolved claims for verification rather than filling gaps with plausible language.
    6. Factual review: Extract material claims from the draft and check each one against its supporting evidence. Return unsupported, overstated, time-sensitive, or internally contradictory claims.
    7. Editorial review: Check usefulness, structure, repetition, voice, product accuracy, and readability. This should be a distinct pass from factual review because a polished sentence can still be false, and a correct sentence can still be unhelpful.
    8. SEO, AEO, and GEO review: Verify that the page answers its main question clearly, uses descriptive headings, keeps citations close to supported claims, integrates concepts naturally, and does not sacrifice accuracy for phrasing. This pass may restructure existing information but should not introduce new facts.
    9. Publication preparation: Generate the meta description, proposed slug, internal links, and any other required CMS fields. If structured data is prepared, every represented claim must also be supported by the visible page.
    10. Human approval: Resolve remaining flags, verify consequential claims against the underlying evidence, and make the final publish-or-return decision.

    Make every handoff inspectable

    A stage should never report that it is done without showing what it produced and why it passed. The following contract makes failures easier to diagnose:

    StageRequired inputRequired outputReturn condition
    KickoffCompleted job packetValidated assignmentReader, question, or angle is missing
    ResearchAssignment and approved contextEvidence packet and gap listThe central answer lacks support or duplicates an existing page
    BriefEvidence packet and quality contractApproved content specificationThe proposed claims exceed the evidence
    DraftBrief, evidence, and voice examplesDraft and claim ledgerA required section is absent or a specific claim is unsupported
    Quality assuranceDraft and acceptance criteriaPass, return, or blocked reportAny publication-critical issue remains unresolved

    Use explicit statuses such as pass, return, and blocked. Pass sends the output forward. Return sends it to a named earlier stage with a reason code and requested correction. Blocked means the workflow cannot continue without new evidence or a human decision. This is more useful than letting an orchestrator silently rewrite failed work, because silent rewrites hide the stage that needs improvement.

    Keep the claim ledger attached to the job throughout the run. It should identify each material claim, its supporting reference, relevant qualification, and verification status. That record gives the factual reviewer a finite checklist and gives the human approver a direct path back to the evidence.

    Place human gates where errors become expensive

    A human editor compares a draft with source documents at an illuminated checkpoint before opening the final publication gate.

    Human review should not be one hurried read after the system has made every consequential decision. Put gates before expensive downstream work and before publication.

    • After research: A human confirms that the angle is worth pursuing, the evidence can support it, and the proposed page is sufficiently different from existing content. Stopping here is cheaper than rewriting a complete draft.
    • After the outline: A human checks whether the structure answers the reader’s actual question, whether each section earns its place, and whether proprietary material appears where it can change the value of the page.
    • Before publication: A human verifies unresolved claims, product statements, sensitive assertions, and any facts whose meaning depends on date, version, market, or audience. The approver also decides whether the page meets the quality contract as a whole.

    AI-assisted fact-checking can extract claims, compare wording with supplied evidence, and surface inconsistencies. It should not be allowed to convert missing support into confidence. Configure the check to return an unresolved claim when the evidence is absent, ambiguous, or narrower than the draft.

    Give factual review a precise set of questions:

    • What exact claim is being made?
    • Which approved evidence supports it?
    • Does that evidence support the whole claim or only part of it?
    • Has a qualification, limitation, or condition been removed?
    • Could the claim depend on a date, product version, geography, or audience?
    • Does the wording imply causation, certainty, consensus, or performance that the evidence does not establish?
    • Is the claim about your company or product consistent with the approved source of truth?

    Run the voice check separately. Asking a model to make a draft sound more human is too open-ended and can change meaning while polishing the prose. Instead, compare the draft with approved examples and enforce observable rules: opening length, sentence patterns, terminology, banned filler, level of explanation, use of first person, and how uncertainty is expressed.

    The optimization pass needs its own boundary as well. It may improve answer placement, heading clarity, internal linking, metadata, and concept coverage. It may not add a statistic, broaden a product claim, manufacture a consensus, or create structured data that says more than the visible content. When optimization changes meaning, the draft must return to factual review.

    Start narrow and improve the system from its failures

    Do not begin with a universal engine for blog posts, landing pages, social posts, newsletters, and external contributions. Get one content type working before adding conditional branches for others. Different formats have different definitions of done, so premature flexibility makes failures harder to locate.

    A sensible first implementation has one content type, one primary audience, one quality contract, one approved context library, and one accountable human owner. Run real assignments through it and record every intervention. The corrections tell you what to improve:

    • Repeated research gaps mean the kickoff fields, approved references, or research instructions are insufficient.
    • Repeated outline changes mean the brief does not define the reader outcome or differentiating angle clearly enough.
    • Repeated factual corrections mean the evidence packet, claim ledger, or factual-review rules need work.
    • Repeated voice edits mean the voice guide needs better examples and counterexamples.
    • Repeated internal-link errors mean the content inventory is incomplete, stale, or not being retrieved correctly.
    • Repeated optimization rewrites mean search requirements are arriving too late and should move into the brief or outline.

    Measure the workflow separately from published performance. For the workflow, track which gate returns work, why it returns, how often humans correct each error category, and which stage creates the delay. For published pages, track the business and search outcomes that matter to you. Do not let a later ranking obscure a broken factual process, and do not assume a correctly executed workflow guarantees a ranking.

    Not every team needs a coded, multi-agent system. A smaller prompt set and human checklist may be the better choice when volume is low, the offer changes frequently, source-of-truth documents do not exist, or no qualified reviewer is available. Building the pipeline is substantive work, and it can be assembled in stages. Automation should follow a stable editorial process, not substitute for one.

    Key takeaways

    • Define publishable quality before choosing models, agents, or prompts.
    • Separate permanent brand context from the job packet supplied on each run.
    • Give every stage a required input, output schema, acceptance test, and failure route.
    • Maintain a claim ledger so factual review can trace assertions to approved evidence.
    • Use humans to approve the angle, structure, consequential claims, and final publication decision.
    • Start with one content type and improve the workflow from recorded failure patterns.

    Your next move is not to add another agent. Choose one recently published page your team considers strong. Convert it into an acceptance checklist, trace every criterion back to the input needed to satisfy it, and run one real assignment through the stages manually.

    Automate only after the gates produce repeatable decisions. By then, you should be able to say why a run passed, where a failed run must return, and who owns the next decision. If any of those answers is unclear, keep that part of the workflow visible and manual for another cycle.

    References


  • Google LSA Category Expansion: Your Migration Action Plan

    Google LSA Category Expansion: Your Migration Action Plan

    If your Local Services Ads account still describes a specialist business with a broad label, this is the time to inspect it. Google is introducing more precise categories while preparing to move LSA campaign management into Google Ads, so the choices you make before migration can affect both lead relevance and your ability to diagnose performance afterward.

    You do not need to rebuild a working campaign. You do need a clean record of what it targets, an honest category-to-service map, and a plan for separating migration effects from ordinary business changes.

    Separate the category expansion from the platform migration

    Two changes are arriving together, but they solve different problems. The category expansion gives Google a more precise description of your business. The migration changes where you manage the campaign.

    Restaurants that once sat inside broad restaurant or dessert-and-coffee groupings can now use classifications such as American, Chinese, Italian, pizza, steak house, sushi or vegan restaurant. Automotive advertisers have options including Auto Air Conditioning Service, Auto Glass Repair Service, Brake Shop, Car Battery Store, Car Inspection Service, Oil Change Service, Tire Shop and Transmission Shop. Beauty categories have also become more detailed. This added category specificity is intended to help businesses represent their actual services and potentially connect with customers seeking those services.

    The platform move does not turn LSAs into a conventional keyword campaign. Google says advertisers will continue to pay for valid leads rather than clicks. Campaigns will remain keywordless, and their existing local placements will remain on Google Search and Google Maps.

    Key takeaways

    • Review newly available categories before your account moves, especially if a broad label currently hides a specialist service.
    • Select only categories that describe services you genuinely provide; the category menu is not a keyword list.
    • Expect campaign management to move into Google Ads, but do not rebuild an existing setup solely because of that change.
    • Prepare to receive real leads if Google allows your business to advertise before completing full badge onboarding.
    • Do not treat an LSA category as proof of an organic, local-pack or AI-search ranking factor.

    Choose the narrowest truthful description of the business

    A plumbing specialist matches a pipe-joint symbol card to the tools on a workshop bench while broader service cards sit aside.

    A more precise category is useful only when it matches the job a customer can actually buy. A transmission specialist should not have to look identical to a general maintenance shop. A sushi restaurant should not have to rely on a generic restaurant label. That distinction can reduce ambiguity at the moment a searcher is deciding whom to contact.

    It does not follow that selecting every available category will produce better leads. LSAs are still keywordless, so categories should describe the business rather than function as a collection of search terms. An unsupported category can attract inquiries your team cannot serve, waste response time and make lead-quality reporting harder to interpret.

    Use this category audit:

    1. List the services customers can purchase now. Use operational language, not aspirational offerings. Include the specialist jobs, cuisines or treatments that materially define why someone contacts you.
    2. Match each offering to the most precise available LSA category. If an exact category now exists, compare it with the broad classification you previously used.
    3. Check the edge of every category. Ask what a reasonable customer would expect after seeing that label. Remove a category if the business cannot consistently meet that expectation.
    4. Confirm the handoff. Make sure the employee, location or call-routing process receiving the lead knows which service generated it and can qualify it correctly.
    5. Record the decision. Save the selected category, the services supporting it, the date and the reason for the change. That record becomes your baseline during migration.

    Then compare the promise across your customer-facing properties. Your LSA profile, website, Google Business Profile and phone response do not need to use identical taxonomies, because each product may offer different labels. They should describe the same underlying business. If your ad says Transmission Shop while your site mentions only general maintenance and the receptionist routes every call to a general-service queue, the problem is not wording alone. The customer is encountering three different versions of the company.

    Prioritize category changes that resolve a real mismatch. A specialist hidden in a broad category has a stronger reason to update than a business whose current classification already describes what customers buy. Precision is the goal; novelty is not.

    Treat pre-badge leads as paid demand, not test traffic

    Eligible businesses that pass preliminary checks may be allowed to receive leads while completing the remaining onboarding requirements for the Google Verified badge. These pre-badge ads appear below fully onboarded providers, so earlier activation comes with a placement limitation.

    The operational consequence matters more than the label. Those inquiries enter a pay-per-valid-lead system. If you activate before your intake process is ready, you can spend money learning that no one owns the phone, the service-area rules are unclear or employees do not know which new category produced the inquiry.

    Before accepting pre-badge leads, put four controls in place:

    • Assign an owner. One person should be responsible for lead receipt, response and disposition rather than assuming a shared inbox will manage itself.
    • Write a category-specific qualification prompt. For an automotive category, confirm the requested system or repair. For a restaurant category, confirm the relevant dining, menu or order need. Keep the prompt short enough to use on every inquiry.
    • Define your internal outcomes. At minimum, distinguish a valid inquiry, a qualified opportunity, a booking or order, and a request for something the business does not provide.
    • Log the reason for poor fit. Separate taxonomy mismatch from service-area, availability, pricing and response problems. Otherwise every failure gets mislabeled as low-quality traffic.

    Do not use the badge itself as a universal readiness check. The Verified badge is unavailable for auto, beauty and dining categories. If you operate in one of those verticals, the badge’s absence is not evidence that the account failed to complete the same path as a badge-eligible provider. Train staff and stakeholders on that distinction so they do not promise a badge customers will never see.

    Build a migration baseline instead of rebuilding the campaign

    A business operator transfers matching campaign tokens from a preserved setup into a new modular workspace.

    The first migration phase begins with select U.S. home and storefront service advertisers in August 2026. Additional advertisers follow later in 2026, while non-U.S. accounts and remaining categories move in 2027. Your country and category therefore matter more than the broad announcement date when planning internal work.

    Existing setups are expected to migrate automatically into Google Ads. Do not create a duplicate campaign just to prepare for the new interface. A duplicate can fragment your measurement and introduce overlapping changes precisely when you need a stable comparison.

    Create a compact migration record before your account receives its cutover:

    • Account name, business location, country and responsible owner.
    • Current LSA categories and the real services supporting each one.
    • Service area, operating hours, budget and lead-routing destination as configured in the account.
    • Onboarding state, including whether the business is fully onboarded, operating through a pre-badge path or in a category where the badge is unavailable.
    • Spend, total leads, valid leads, cost per valid lead and the share of leads that become qualified opportunities or bookings.
    • Any category, budget, service-area, staffing or hours change made near the migration date.

    Use comparable periods when you review performance. A week with a holiday, temporary closure or staffing problem is not a clean baseline for an ordinary week. Platform metrics also cannot tell you whether a lead became revenue unless your own intake process records the outcome.

    When your migration notice arrives, verify who can access the destination Google Ads account and who is authorized to change the campaign. Then avoid stacking unrelated edits into the same observation window. If you change categories, budget, hours and call routing at the same time as migration, a later performance shift will have too many plausible causes.

    Diagnose post-migration changes in a fixed order:

    1. Confirm that categories, services, service area, hours, budget and lead routing match the saved baseline.
    2. Check whether verification or pre-badge status changed.
    3. Review valid-lead volume and cost before examining downstream booking performance.
    4. Check staffing, response handling, availability and other operational changes.
    5. Only then treat an unexplained difference as a migration-related issue requiring escalation.

    Do not respond to the new Google Ads location by building keyword lists or optimizing toward clicks. The underlying campaign remains keywordless and lead-based. The interface is moving; the commercial unit you are buying is not.

    Use the new taxonomy as a content map, not an SEO shortcut

    The expanded category list can reveal where your website describes a real service too vaguely. It does not establish LSA category selection as an organic ranking factor, a local-pack signal or a direct path into AI-generated answers. Keep paid eligibility and organic visibility separate in your measurement.

    A category deserves supporting content when it represents a distinct customer intent and a service you genuinely deliver. A transmission shop can explain transmission diagnosis, repair scope, customer eligibility and location coverage. A sushi restaurant can make its cuisine, service format, hours and location explicit. A generic page that merely repeats every new label adds no comparable clarity.

    For each important category, check whether the corresponding page clearly answers:

    • What exactly does the business provide?
    • Which customer need or request does the offering address?
    • Where is it available?
    • What is included, excluded or subject to confirmation?
    • How can a customer take the next step?

    Apply the same discipline to structured data. An LSA category label is not automatically a valid Schema.org type. Use an established LocalBusiness subtype that accurately describes the entity, and support it with visible page content. Do not invent a schema type by copying a newly available advertising label into the type field. For restaurants, cuisine details should be accurate and visible to users as well as represented in supported structured-data properties. For automotive businesses, specific services can be described in page content even when Schema.org offers a broader business subtype.

    For AEO and GEO work, aim for consistent, machine-readable facts rather than assuming Google’s advertising taxonomy is fed directly into frontier models. The business category, visible service description, location facts, structured data and conversion path should reinforce one another. That alignment makes the entity easier to understand without turning an ad configuration into an unsupported ranking claim.

    Start with one account. Save its current configuration, identify the narrowest category the business can honestly support, and document a before-migration performance baseline. When the management change reaches you, you will be comparing evidence instead of reconstructing the past from memory.

    References


  • How to Build Situation-Based Content Briefs for SEO and AI

    How to Build Situation-Based Content Briefs for SEO and AI

    You have the keyword list, competitor headings and target word count. The writer follows the instructions. The finished draft is still generic, because nobody defined the moment that brought the reader to the page.

    A situation-based content brief fixes that gap. It identifies what changed for the reader, what they need to decide, what constrains them and what useful progress looks like. Keywords still matter, but they support the assignment instead of becoming the assignment.

    Key takeaways

    • Start with one recognizable audience situation, not a cluster of loosely related keywords.
    • Document the situation through seven lenses: why, when, where, while, with whom, with or for what, and how the reader is feeling.
    • Record where each audience insight came from so writers and subject-matter experts can verify it.
    • Use keywords to capture audience language and discoverability, not as a substitute for intent, context or editorial judgment.
    • Measure whether the content helped the intended reader progress, using visibility and engagement metrics as supporting evidence.

    A keyword is evidence, not the assignment

    A keyword tells you that a phrase may be searched. It rarely tells you why this person is searching now, what they already understand or what they will do with the answer.

    Consider the keyword content brief template. It could come from an SEO lead trying to standardize agency output, an in-house marketer repairing a disappointing draft, a freelancer preparing for a new client or an editor evaluating a briefing tool. The words are similar. The work each reader needs to complete is not.

    If you brief all of those readers at once, the writer has to average them together. That usually produces a long introduction, a universal checklist and little help at the point of decision. Pick one primary situation. Treat other situations as separate assignments unless they require substantially the same answer.

    Broad informational queries create another trap. A basic factual question may be more credibly answered by the organization that defines the rule, standard or process. Chasing that query can bring impressions without demonstrating the specialist expertise your prospective customer needs. Before approving it, ask why your brand deserves to answer, which qualified audience it serves and what meaningful next question you can resolve.

    This distinction matters even more in conversational search. People can describe the trigger, constraints and desired outcome in a full prompt rather than compressing everything into a short phrase. Content planned around that situation is better equipped to answer the main question and the follow-up questions that naturally accompany it.

    Use this gate before a topic becomes a brief:

    • Trigger: What happened that made the reader seek help now?
    • Decision: What must they choose, understand, fix or complete?
    • Constraint: What limits their options, confidence, time or authority?
    • Consequence: What goes wrong if they get an incomplete answer?
    • Brand fit: What relevant expertise, evidence or tool can your organization contribute?

    If you cannot answer those questions, you have a keyword opportunity but not yet a defensible content assignment.

    Capture the situation through seven practical lenses

    Seven translucent lenses reveal different details around a person standing in a constrained decision situation.

    The most useful briefs describe the audience moment through seven situational prompts. They force you to move beyond a persona label and document the conditions shaping the reader’s need.

    LensQuestion to answerWhat belongs in the brief
    WhyWhy is the reader looking for help?The trigger, desired progress and consequence of getting it wrong.
    WhenAt what point in a process or decision does the need appear?The stage, deadline pressure or event that changes the answer.
    WhereIn what environment will the reader find or use the information?The relevant channel, workplace, device context or operational setting.
    WhileWhat else is happening at the same time?Competing tasks, interruptions, dependencies or parallel decisions.
    With whomWho else affects the decision?Approvers, collaborators, customers, advisers or family members who shape the outcome.
    With or for whatWhat object, task or outcome is involved?The product, service, document, system or goal the reader is working with.
    How feelingWhat is the reader’s emotional state?The level of confidence, urgency or caution the tone and ordering should respect.

    Keep each answer short enough to guide a writer. Panicked is not useful by itself. Panicked because the filing deadline is close and the records are incomplete tells the writer to lead with triage, separate urgent actions from later improvements and avoid a leisurely history lesson.

    Emotion should change the delivery, not become an excuse for melodrama. A cautious evaluator needs explicit trade-offs and verification points. A beginner needs terminology introduced before it is used. A reader in the middle of a live failure needs the recovery sequence before background explanation.

    Get the answers from people close to the audience

    Sales, support, account management, in-store staff and public-facing specialists hear the language people use before it is cleaned up for a keyword tool. Ask them for recurring questions, misunderstood terms, objections, failed attempts and the point at which people usually request help.

    Capture traceability beside the insight. Record the team or role that supplied it, the evidence window and any place where the wording can be checked. If an entry is an assumption, label it as an assumption and assign someone to validate it. An unsupported guess does not become audience research merely because it appears in a template.

    Analytics and search data can then validate or refine the language. Internal site search, relevant query data and on-page behavior may reveal how people phrase the need or where an existing answer loses them. They cannot independently explain the entire situation, so interpret them alongside frontline evidence.

    Choose which situations deserve content

    You do not need a page for every situation your team can name. Prioritize a situation when four conditions line up:

    • There is credible evidence that the situation occurs among people the organization wants to serve.
    • The reader has a consequential question or decision, not merely passing curiosity.
    • Your organization has a legitimate reason to answer through expertise, evidence, experience or a relevant offering.
    • Existing content does not already solve the same problem adequately.

    Review search demand after those conditions, not before them. Demand can help you choose vocabulary, estimate discoverability and prioritize between otherwise worthwhile opportunities. It cannot make a poorly matched audience situation strategically useful.

    Turn the situation into a production-ready brief

    A strategist and writer connect an audience decision scenario to evidence, content modules, and a structured blank brief across a workspace.

    A persona describes who someone generally is. A situation explains why that person needs this content now. Your writer needs both only when both alter the answer; a broad demographic profile that changes nothing should not occupy half the brief.

    Write the core scenario as a single sentence using this pattern: person + trigger + progress needed + important constraint.

    For example: An in-house content lead has received another generic draft from an external writer and needs to repair the briefing process before assigning the next topic, without replacing the team’s existing keyword workflow.

    That sentence gives the assignment boundaries. The reader does not need a beginner’s definition of keyword research or a wholesale content-operations redesign. They need to identify what their brief is missing and update it before the next handoff.

    Copy this structure into your briefing system

    1. Primary scenario: State the person, trigger, desired progress and constraint in one sentence.
    2. Audience evidence: List the relevant questions, objections or failure points, with the team or evidence source attached to each.
    3. Seven situational lenses: Complete why, when, where, while, with whom, with or for what, and how feeling.
    4. Content job: Label the assignment informational, consideration or transactional, then explain what that means for this reader.
    5. Reader outcome: Define what the reader should be able to do, decide or notice after using the content.
    6. Primary and follow-up questions: Write the central question and the next questions that arise once it is answered.
    7. Scope boundaries: State what belongs, what does not and which adjacent situations need separate coverage.
    8. Suggested outline: Order sections by the reader’s decision process, not by competitor heading frequency.
    9. Evidence requirements: Identify claims that need subject-matter review, primary documentation, examples or qualification.
    10. Search language: Add the primary query, useful variants, named entities and terminology the audience actually uses.
    11. Answer design: Specify where a direct answer, ordered process, comparison, definition, example or caveat would help.
    12. Existing coverage: Note pages to update, consolidate, distinguish or link rather than creating an isolated duplicate.
    13. Tone and depth: Explain what the reader already knows, how urgent the need is and which details would be excessive.
    14. Next action: Give the writer a useful, situation-appropriate destination for the reader.
    15. Success measure: Name the primary outcome and the supporting signals you will inspect.

    Length guidance comes after the content job and outline. A fixed word count chosen before the situation is understood encourages padding or omission. Give a range only when your workflow requires one, and make completion of the reader’s task the controlling requirement.

    Use SEO, AEO and GEO requirements without flattening the brief

    Search requirements should make the answer easier to discover and interpret. They should not drag the writer back to a keyword-shaped page.

    • Use the primary query and variants to represent audience language, then map each phrase to a real question in the scenario.
    • Name important entities and relationships explicitly instead of relying on vague pronouns or implied context.
    • Place a concise answer close to the question it resolves, then add reasoning, conditions and examples.
    • Turn genuine sequences into ordered lists and genuine comparisons into tables. Do not impose those formats on ideas that require prose.
    • State assumptions and limits where the correct answer changes by stage, system or circumstance.
    • Connect the page to earlier and later journey content through relevant internal links.
    • Add structured data only when it accurately represents visible content. Schema cannot compensate for an answer the page never provides.

    This structure can help a search engine or AI system identify a direct answer and its supporting context, but it does not guarantee a ranking, citation or recommendation. The brief still needs credible evidence, clear language and a reason for your brand to be included.

    Measure whether the intended reader made progress

    Traffic is not the same as success. A broad page can collect impressions from people outside the intended situation, while a narrower page may help a smaller but more relevant audience take the next step. Define that step before publication.

    Choose one primary measure tied to the scenario, then use diagnostic metrics to understand the result:

    • Visibility: Inspect impressions and discovery for the relevant query family, not only the highest-volume phrase.
    • Engagement: Review scroll depth and interaction with the section, template, comparison or tool that performs the content’s main job.
    • Progress: Track the next action that fits the situation, such as continuing to a decision page, using a resource or beginning an appropriate contact path.
    • Operational usefulness: Ask the frontline team whether the content answers the recurring concern accurately and whether important questions remain unresolved.
    • AI visibility: If GEO is part of the goal, use a fixed set of prompts that represent the scenario and record whether the page or brand appears in a relevant answer. Treat individual outputs as directional observations rather than a guaranteed result.

    To test the briefing method, create a conventional keyword-led brief and a situation-led brief for comparable assignments. Evaluate the resulting drafts against the same rubric: scenario clarity, answer order, scope control, evidence requirements, search usefulness and next-step fit. If your website experimentation setup supports a valid split, you can also compare on-page behavior. Otherwise, avoid calling unlike pages an A/B test.

    Do not select a winner from raw impressions alone. Different topics can have different demand, and an impression does not show that the right reader received a useful answer. Read visibility, engagement and progress together, then document what changed in the next brief.

    Take one topic already waiting in your editorial queue and pause before outlining it. Complete the seven situational lenses, name the evidence behind them and choose the reader’s next decision. If your team cannot do that yet, the next task is an audience conversation, not another keyword export.

    References


  • AI Search Terminology: What Marketers Should Call the Work

    AI Search Terminology: What Marketers Should Call the Work

    You need a name for the work. It might be a budget line, a strategy deck, a job description, a service page, or the agenda for a meeting between SEO, content, PR, and analytics. Should you call it SEO, AI SEO, AEO, GEO, LLM optimization, or AI search optimization?

    Use SEO as the organizational umbrella and AI search optimization as the plain-language qualifier. Reserve AEO, GEO, and similar terms for a defined workstream. That gives familiar language to the person approving the work without hiding what has changed.

    The practical naming default: SEO plus AI search visibility

    Marketers have not abandoned SEO as quickly as specialist vocabulary might imply. Among 343 U.S. marketing decision-makers surveyed, 81% still called their internal AI search visibility strategy SEO. When searching online for help, 46% said they would use “AI search optimization” and 24% would use “SEO.” Together, those two understandable phrases accounted for 70% of the reported demand.

    Formal terminology is even less settled inside teams. Only 27% had adopted a term beyond SEO, while 42% had decided against doing so and 31% remained undecided. Treat those percentages as a directional view of one U.S. sample, not a universal naming law. They are self-reported choices from 343 decision-makers, not a census of every market or industry.

    Slow vocabulary adoption does not mean the work is being ignored. Respondents allocated an average of 24% of their search or content budgets to AI search visibility. Up to 82% reported committing at least some budget, and 43% allocated more than 20%. The label is lagging behind the investment.

    This creates a useful naming hierarchy:

    • SEO is the established program or department under which the work can sit.
    • AI search visibility names the business outcome: whether and how the brand appears in AI-mediated discovery.
    • AI search optimization names the work intended to improve that outcome.
    • AEO, GEO, LLM optimization, and agentic search optimization name narrower approaches or environments, but only after you define their scope.

    A practical strategy title is therefore “SEO and AI Search Visibility.” A defensible budget line is “SEO, including AI search optimization.” Both acknowledge the new surface without asking every stakeholder to learn an unsettled taxonomy before approving the work.

    A working glossary that distinguishes outcomes from methods

    A glowing destination and audience symbols are connected by a bridge to an arrangement of tools, content blocks, and linked source nodes.

    The category now spans AI search, answer engine optimization, and agentic-web terminology. These labels are useful, but they are not interchangeable and they are not universally standardized. Adopt working definitions inside your organization so the same acronym does not describe three different plans.

    TermUseful working definitionUse it whenCommon failure
    SEOThe established program for improving organic discovery, site accessibility, relevance, authority, and search performance.You need an umbrella understood by executives, practitioners, procurement teams, and job candidates.Treating AI-generated discovery as merely another ranking report, with no attention to answers, citations, or brand representation.
    AI search visibilityThe observable outcome of whether, where, and how a brand, product, person, or idea appears in AI-mediated search and answers.You are discussing goals, reporting, competitive presence, or reputation rather than a specific technique.Reducing visibility to a single score without examining accuracy, prominence, cited evidence, or business relevance.
    AI search optimizationThe broad set of activities intended to improve discovery, accurate representation, citations, and useful visibility across AI-generated search experiences.You need a buyer-friendly name for a cross-functional program that extends existing SEO.Using the phrase as a vague replacement for SEO without specifying platforms, prompts, owners, or measurements.
    AEOAnswer engine optimization: making relevant information clear, retrievable, well-supported, and suitable for systems that resolve questions with direct answers.The work focuses on question coverage, answer clarity, content structure, entity facts, and supporting evidence.Presenting AEO as a schema-only project. Structured data can clarify machine-readable facts, but it does not create authority or make weak content worthy of use.
    GEOGenerative engine optimization: improving the chance that a brand or its information is accurately represented, supported, and cited in generated responses.The scope includes generated answer behavior, third-party authority, citations, brand mentions, and source influence.Using GEO as an unexplained synonym for all SEO work or implying that optimization can guarantee a model recommendation.
    LLM optimizationA label centered on visibility or representation in products powered by large language models.The analysis genuinely concerns LLM-powered outputs, model-specific behavior, or the information environments those products use.Implying that a marketer can directly optimize an underlying model in the same way a page can be edited.
    Agentic search optimizationWork intended to help AI agents discover, evaluate, and use information while researching or completing tasks.Agent behavior and task completion are explicitly in scope, not merely the display of an answer.Using an early, specialized label as a general buyer-facing umbrella without defining what the agent is expected to do.

    The boundaries will overlap. An authoritative comparison page can support SEO, answer retrieval, generative citations, and agent research at the same time. That overlap is a reason to define the terms, not a reason to build separate teams around every acronym.

    For each term you adopt, write one sentence that answers three questions: Which discovery surface is in scope? What outcome are you trying to change? What work will the team perform? If the definition cannot answer all three, the term is branding rather than an operating instruction.

    Choose the term by the decision it needs to unlock

    The best label depends less on who has the newest vocabulary and more on what the recipient must decide. An executive deciding whether to fund the program needs a different level of detail from an analyst designing a prompt-monitoring workflow.

    1. For a strategy title, use “SEO and AI Search Visibility.” It connects the established function to the new outcome. Follow it with a scope statement naming the relevant answer surfaces, content, authority, technical foundations, and measurement.
    2. For a budget line, use “SEO, including AI search optimization.” State which existing budget funds it and which additional work the allocation covers. This prevents a terminology change from quietly becoming duplicate spending.
    3. For a vendor brief, ask for “AI search visibility across named buyer journeys and platforms.” Require the response to explain prompt selection, source analysis, content and authority work, measurement, and ownership. Do not award points merely for using GEO or AEO.
    4. For a dashboard, report “Organic Search” and “AI Search Visibility” as related views. Keep familiar SEO measures where they remain useful, then add AI-specific observations such as brand presence, answer accuracy, cited URLs, third-party source inclusion, referral quality, and assisted outcomes.
    5. For a specialist workstream, use the narrow acronym and define it. “AEO for support questions” or “GEO for category-comparison prompts” gives the term an object, a surface, and a purpose.
    6. For a job description, lead with the established function. A title such as “SEO Manager, AI Search” is easier to interpret than an acronym-only role. Put the changed responsibilities in the job scope: prompt research, answer-surface monitoring, entity consistency, structured content, external authority, and cross-channel measurement.

    Seniority changes the vocabulary but does not eliminate confusion. C-suite respondents used GEO at 28% and AEO at 17%, compared with 9% and 3% among individual contributors. Yet 56% of C-suite respondents also reported looking up an unfamiliar term. An executive using GEO may be signaling interest in the category, not agreement on a detailed operating model.

    Meet that interest with a definition, not another acronym. The most useful copy-ready version is:

    AI search optimization is the part of our SEO program that improves how our brand is discovered, represented, and cited in AI-generated search and answers. It combines technical accessibility, useful content, credible external signals, and measurement across the platforms our buyers use.

    That statement connects the emerging category to work a team can assign. It also avoids promising control over an AI system’s output.

    Clear language matters in vendor selection. Excessive buzzwords without explanations were the leading red flag for 36% of respondents. When GEO or AEO appeared in a pitch, 42% said their reaction depended on the context provided, 30% considered the language innovative, 22% said it had no effect, and 7% considered the vendor less trustworthy. The acronym can open a conversation, but it cannot carry the business case.

    Any internal proposal or vendor pitch should explain four things before introducing a specialized term:

    • Outcome: What should become more visible, accurate, authoritative, or useful?
    • Surface: Which search experiences, AI products, and buyer questions are included?
    • Method: What will change on owned pages, technical systems, structured data, external publications, community sources, or measurement workflows?
    • Evidence: What baseline, observations, and business measures will show whether the work helped?

    Turn terminology into an operating model

    Four teams at connected workstations contribute content, search, relationship, and measurement elements to a shared central hub.

    A new term earns its place only when it makes execution clearer. If GEO appears in a deck but nobody can identify the prompts, sources, owners, or measures attached to it, the team has renamed the problem rather than organized the work.

    Do not begin by creating a separate strategy for every platform. Reported priorities were fragmented: 34% prioritized ChatGPT, 16% Gemini, 6% Claude, 5% Copilot or Bing AI, and 1% Perplexity, while 14% had not selected a target platform. Those figures describe stated priorities in the U.S. sample, not platform usage or market share. They show why your own buyer behavior must determine scope.

    Build a scope from prompts and evidence sources

    1. Start with buyer decisions. Build a prompt set around the questions that precede discovery, comparison, validation, purchase, implementation, and troubleshooting. Include branded and unbranded questions. A list of head keywords alone will miss the context carried through a conversational query.
    2. Select surfaces based on those buyers. Test the relevant prompts across ChatGPT, Gemini, Google AI Overviews, Claude, Copilot or Bing AI, Perplexity, and any category-specific experience that matters to your market. You do not need to prioritize every surface equally.
    3. Record the answer, not just presence or absence. Capture whether the brand appears, how it is characterized, which alternatives appear, what factual errors matter, which URLs or publishers are cited, and whether the response satisfies the intended question.
    4. Map the information environment. Generated answers may draw influence from your own site, competitor content, list articles, trade publications, analyst pages, community discussions, Reddit threads, and YouTube transcripts. Mark each recurring source as owned, earnable, partner-controlled, community-controlled, or outside your realistic influence.
    5. Assign work by lever. SEO can own crawlability, internal architecture, canonical signals, and search demand. Content can own question coverage, clarity, evidence, and maintenance. PR and brand teams can build credible third-party mentions. Subject-matter experts can validate factual claims. Analytics can connect answer visibility to referral and downstream behavior.
    6. Name the workstream last. Once the team can see the surface, outcome, and activities, decide whether it is best described as SEO, AI search optimization, AEO, GEO, reputation work, digital PR, content operations, or a combination.

    This sequence prevents a label from dictating tactics. A query audit might reveal that a technical indexing problem is limiting discoverability, that weak comparison content is leaving an answer gap, or that authoritative third-party pages consistently omit the brand. Those are different problems even when all three reduce AI visibility.

    Measure the representation, the evidence, and the outcome

    No single metric can represent the entire program. An AI visibility score may help summarize repeated observations, but it can hide whether the brand is being recommended accurately, criticized, cited only for irrelevant questions, or mentioned without a path to the business.

    Use a compact scorecard with four layers:

    • Presence: How often does the brand appear for the defined prompt set, and which competitors appear beside it?
    • Representation: Are important facts, positioning, limitations, and differentiators described accurately?
    • Evidence: Which owned and third-party pages support the response? Are the citations relevant, credible, current enough for the question, and realistically influenceable?
    • Business effect: Do AI referrals, branded searches, qualified visits, assisted conversions, sales conversations, or other appropriate outcomes change alongside visibility?

    Keep the prompt set, platform set, capture method, and scoring rules documented. Otherwise, an apparent gain may come from changing the questions or evaluation method rather than changing market visibility. Generated responses can vary, so repeated observations and saved evidence are more useful than treating one answer as a permanent ranking.

    The naming debate should not consume the strategy. In the same decision-maker group, 28% named the pace of change as their leading challenge, ahead of measuring AI-result performance or visibility at 17%, choosing platforms at 15%, and the lack of standards or best practices at 13%. A durable operating model should therefore preserve familiar ownership while allowing the tested platforms, prompts, sources, and measures to change.

    Key takeaways

    • Keep SEO as the default organizational umbrella unless a different label solves a specific ownership or budgeting problem.
    • Use AI search optimization when you need a clear external or cross-functional name for the work.
    • Use AI search visibility for the outcome you measure, not as a substitute for defining the work.
    • Use AEO, GEO, LLM optimization, or agentic search optimization only with a one-sentence definition of the surface, outcome, and activities.
    • Do not mistake slow acronym adoption for weak investment. Teams can fund new work while keeping the familiar SEO label.
    • Evaluate a strategy by its prompts, evidence sources, owners, and measurements. Terminology is useful only when it makes those elements easier to understand.

    Open your current strategy document and inspect the first mention of the program. If it contains only an acronym, replace it with “SEO and AI Search Visibility” and add one sentence defining the surfaces, outcomes, and work included. If a term cannot be mapped to an owner, an activity, and a measure, remove it until it can.

    References